Search Results: "will"

15 November 2015

Manuel A. Fernandez Montecelo: Work on aptitude

Midsummer for me is also known as Noite do Lume Novo (literally New Fire Night ), one of the big calendar events of the year, marking the end of the school year and the beginning of summer. On this day, there are celebrations not very unlike the bonfires in the Guy Fawkes Night in England or Britain [1]. It is a bit different in that it is not a single event for the masses, more of a friends and neighbours thing, and that it lasts for a big chunk of the night (sometimes until morning). Perhaps for some people, or outside bigger towns or cities, Guy Fawkes Night is also celebrated in that way and that's why during the first days of November there are fireworks rocketing and cracking in the neighbourhoods all around. Like many other celebrations around the world involving bonfires, many of them also happening around the summer solstice, it is supposed to be a time of renewal of cycles, purification and keeping the evil spirits away; with rituals to that effect like jumping over the fire when the flames are not high and it is safe enough. So it was fitting that, in the middle of June (almost Midsummer in the northern hemisphere), I learnt that I was about to leave my now-previous job, which is a pretty big signal and precursor for renewal (and it might have something to do with purifying and keeping the evil away as well ;-) ). Whatever... But what does all of this have to do with aptitude or Debian, anyway? For one, it was a question of timing. While looking for a new job (and I am still at it), I had more spare time than usual. DebConf 15 @ Heidelberg was within sight, and for the first time circumstances allowed me to attend this event. It also coincided with the time when I re-gained access to commit to aptitude on the 19th of June. Which means Renewal. End of June was also the time of the announcement of the colossal GCC-5/C++11 ABI transition in Debian, that was scheduled to start on the 1st of August, just before the DebConf. Between 2 and 3 thousand source packages in Debian were affected by this transition, which a few months later is not yet finished (although the most important parts were completed by mid-end September). aptitude itself is written in C++, and depends on several libraries written in C++, like Boost, Xapian and SigC++. All of them had to be compiled with the new C++11 ABI of GCC-5, in unison and in a particular order, for aptitude to continue to work (and for minimal breakage). aptitude and some dependencies did not even compile straight away, so this transition meant that aptitude needed attention just to keep working. Having recently being awarded again with the Aptitude Hat, attending DebConf for the first time and sailing towards the Transition Maelstrom, it was a clear sign that Something Had to Be Done (to avoid the sideways looks and consequent shame at DebConf, if nothing else). Happily (or a bit unhappily for me, but let's pretend...), with the unexpected free time in my hands, I changed the plans that I had before re-gaining the Aptitude Hat (some of them involving Debian, but in other ways maybe I will post about that soon). In July I worked to fix the problems before the transition started, so aptitude would be (mostly) ready, or in the worst case broken only for a few days, while the chain of dependencies was rebuilt. But apart from the changes needed for the new GCC-5, it was decided at the last minute that Boost 1.55 would not be rebuilt with the new ABI, and that the only version with the new ABI would be 1.58 (which caused further breakage in aptitude, was added to experimental only a few days before, and was moved to unstable after the transition had started). Later, in the first days of the transition, aptitude was affected for a few days by breakage in the dependencies, due to not being compiled in sequence according to the transition levels (so with a mix of old and new ABI). With the critical intervention of Axel Beckert (abe / XTaran), things were not so bad as they could have been. He was busy testing and uploading in the critical days when I was enjoying a small holiday on my way to DebConf, with minimal internet access and communicating almost exclusively with him; and he promptly tended the complaints arriving in the Bug Tracking System and asked for rebuilds of the dependencies with the new ABI. He also brought the packaging up to shape, which had decayed a bit in the last few years. Gruesome Challenges But not all was solved yet, more storms were brewing and started to appear in the horizon, in the form of clouds of fire coming from nearby realms. The APT Deities, which had long ago spilled out their secret, inner challenge (just the initial paragraphs), were relentless. Moreover, they were present at Heidelberg in full force, in or close to their home grounds, and they were Marching Decidedly towards Victory: apt BTS Graph, 2015-11-15 In the talk @ DebConf This APT has Super Cow Powers (video available), by David Kalnischkies, they told us about the niceties of apt 1.1 (still in experimental but hopefully coming to unstable soon), and they boasted about getting the lead in our arms race (should I say bugs race?) by a few open bug reports. This act of provocation further escalated the tensions. The fierce competition which had been going on for some time gained new heights. So much so that APT Deities and our team had to sit together in the outdoor areas of the venue and have many a weissbier together, while discussing and fixing bugs. But beneath the calm on the surface, and while pretending to keep good diplomatic relations, I knew that Something Had to Be Done, again. So I could only do one thing jump over the bonfire and Keep the Evil away, be that Keep Evil bugs Away or Keep Evil APT Deities Away from winning the challenge, or both. After returning from DebConf I continued to dedicate time to the project, more than a full time job in some weeks, and this is what happened in the last few months, summarised in another graph, showing the evolution of the BTS for aptitude: aptitude BTS Graph, 2015-11-15 The numbers for apt right now (15th November 2015) are: The numbers for aptitude right now are: The Aftermath As we can see, for the time being I could keep the Evil at bay, both in terms of bugs themselves and re-gaining the lead in the bugs race the Evil APT Deities were thwarted again in their efforts. ... More seriously, as most of you suspected, the graph above is not the whole truth, so I don't want to boast too much. A big part of the reduction in the number of bugs is because of merging duplicates, closing obsolete bugs, applying translations coming from multiple contributors, or simple fixes like typos and useful suggestions needing minor changes. Many of remaining problems are comparatively more difficult or time consuming that the ones addressed so far (except perhaps avoiding the immediate breakage of the transition, that took weeks to solve), and there are many important problems still there, chief among those is aptitude offering very poor solutions to resolve conflicts. Still, even the simplest of the changes takes effort, and triaging hundreds of bugs is not fun at all and mostly a thankless effort althought there is the occasionally kind soul that thanks you for handling a decade-old bug. If being subjected to the rigours of the BTS and reading and solving hundreds of bug reports is not Purification, I don't know what it is. Apart from the triaging, there were 118 bugs closed (or pending) due to changes made in the upstream part or the packaging in the last few months, and there are many changes that are not reflected in bugs closed (like most of the changes needed due to the C++11 ABI transition, bugs and problems fixed that had no report, and general rejuvenation or improvement of some parts of the code). How long this will last, I cannot know. I hope to find a job at some point, which obviously will reduce the time available to work on this. But in the meantime, for all aptitude users: Enjoy the fixes and new features! Notes [1] ^ Some visitors of the recent mini-DebConf @ Cambridge perhaps thought that the fireworks and throngs gathered were in honour of our mighty Universal Operating System, but sadly they were not. They might be, some day. In any case, the reports say that the visitors enjoyed the fireworks.

Lunar: Reproducible builds: week 29 in Stretch cycle

What happened in the reproducible builds effort this week: Toolchain fixes Emmanuel Bourg uploaded eigenbase-resgen/1.3.0.13768-2 which uses of the scm-safe comment style by default to make them deterministic. Mattia Rizzolo started a new thread on debian-devel to ask a wider audience for issues about the -Wdate-time compile time flag. When enabled, GCC and clang print warnings when __DATE__, __TIME__, or __TIMESTAMP__ are used. Having the flag set by default would prompt maintainers to remove these source of unreproducibility from the sources. Packages fixed The following packages have become reproducible due to changes in their build dependencies: bmake, cyrus-imapd-2.4, drobo-utils, eigenbase-farrago, fhist, fstrcmp, git-dpm, intercal, libexplain, libtemplates-parser, mcl, openimageio, pcal, powstatd, ruby-aggregate, ruby-archive-tar-minitar, ruby-bert, ruby-dbd-odbc, ruby-dbd-pg, ruby-extendmatrix, ruby-rack-mobile-detect, ruby-remcached, ruby-stomp, ruby-test-declarative, ruby-wirble, vtprint. The following packages became reproducible after getting fixed: Some uploads fixed some reproducibility issues, but not all of them: Patches submitted which have not made their way to the archive yet: reproducible.debian.net The fifth and sixth armhf build nodes have been set up, resulting in five more builder jobs for armhf. More than 10,000 packages have now been identified as reproducible with the reproducible toolchain on armhf. (Vagrant Cascadian, h01ger) Helmut Grohne and Mattia Rizzolo now have root access on all 12 build nodes used by reproducible.debian.net and jenkins.debian.net. (h01ger) reproducible-builds.org is now linked from all package pages and the reproducible.debian.net dashboard. (h01ger) profitbricks-build5-amd64 and profitbricks-build6-amd64, responsible for running amd64 tests now run 398.26 days in the future. This means that one of the two builds that are being compared will be run on a different minute, hour, day, month, and year. This is not yet the case for armhf. FreeBSD tests are also done with 398.26 days difference. (h01ger) The design of the Arch Linux test page has been greatly improved. (Levente Polyak) diffoscope development Three releases of diffoscope happened this week numbered 39 to 41. It includes support for EPUB files (Reiner Herrmann) and Free Pascal unit files, usually having .ppu as extension (Paul Gevers). The rest of the changes were mostly targetting at making it easier to run diffoscope on other systems. The tlsh, rpm, and debian modules are now all optional. The test suite will properly skip tests that need optional tools or modules when they are not available. As a result, diffosope is now available on PyPI and thanks to the work of Levente Polyak in Arch Linux. Getting these versions in Debian was a bit cumbersome. Version 39 was uploaded with an expired key (according to the keyring on ftp.debian.org which will hopefully be updated soon) which is currently handled by keeping the files in the queue without REJECTing them. This prevented any other Debian Developpers to upload the same version. Version 40 was uploaded as a source-only upload but failed to build from source which had the undesirable side effect of removing the previous version from unstable. The package faild to build from source because it was built passing -I to debbuild. This excluded the ELF object files and static archives used by the test suite from the archive, preventing the test suite to work correctly. Hopefully, in a nearby future it will be possible to implement a sanity check to prevent such mistakes in the future. It has also been identified that ppudump outputs time in the system timezone without considering the TZ environment variable. Zachary Vance and Paul Gevers raised the issue on the appropriate channels. strip-nondeterminism development Chris Lamb released strip-nondeterminism version 0.014-1 which disables stripping Mono binaries as it is too aggressive and the source of the problem is being worked on by Mono upstream. Package reviews 133 reviews have been removed, 115 added and 103 updated this week. Chris West and Chris Lamb reported 57 new FTBFS bugs. Misc. The video of h01ger and Chris Lamb's talk at MiniDebConf Cambridge is now available. h01ger gave a talk at CCC Hamburg on November 13th, which was well received and sparked some interest among Gentoo folks. Slides and video should be available shortly. Frederick Kautz has started to revive Dhiru Kholia's work on testing Fedora packages. Your editor wish to once again thank #debian-reproducible regulars for reviewing these reports weeks after weeks.

Simon McVittie: Discworld Noir in a Windows 98 virtual machine on Linux

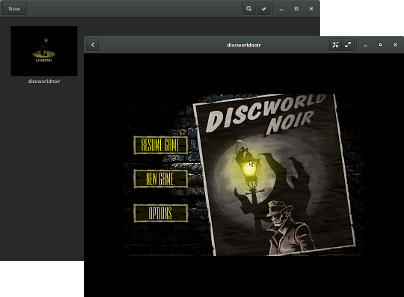
Discworld Noir was a superb adventure game, but is also notoriously unreliable, even in Windows on real hardware; using Wine is just not going to work. After many attempts at bringing it back into working order, I've settled on an approach that seems to work: now that qemu and libvirt have made virtualization and emulation easy, I can run it in a version of Windows that was current at the time of its release. Unfortunately, Windows 98 doesn't virtualize particularly well either, so this still became a relatively extensive yak-shaving exercise. discworldnoir-boxes.jpg These instructions assume that /srv/virt is a suitable place to put disk images, but you can use anywhere you want. The emulated PC After some trial and error, it seems to work if I configure qemu to emulate the following: A modern laptop CPU is an order of magnitude faster than what Discworld Noir needs, so full emulation isn't a problem, despite being inefficient. There is deliberately no networking, because Discworld Noir doesn't need it, and a 17 year old operating system with no privilege separation is very much not safe to use on the modern Internet! Software needed Windows 98 installation It seems to be easiest to do this bit by running qemu-system-i386 manually:
qemu-img create -f qcow2 /srv/virt/discworldnoir.qcow2 30G
qemu-system-i386 -hda /srv/virt/discworldnoir.qcow2 \
    -drive media=cdrom,format=raw,file=/srv/virt/windows98.iso \
    -no-kvm -vga cirrus -m 256 -cpu pentium3 -localtime
Don't start the installation immediately. Instead, boot the installation CD to a DOS prompt with CD-ROM support. From here, run
fdisk
and create a single partition filling the emulated hard disk. When finished, hard-reboot the virtual machine (press Ctrl+C on the qemu-system-i386 process and run it again). The DOS FORMAT.COM utility is on the Windows CD-ROM but not in the root directory or the default %PATH%, so you'll have to run:
d:\win98\format c:
to create the FAT filesystem. You might have to reboot again at this point. The reason for doing this the hard way is that the Windows 98 installer doesn't detect qemu as supporting ACPI. You want ACPI support, so that Windows will issue IDLE instructions from its idle loop, instead of occupying a CPU core with a busy-loop. To get that, boot to a DOS prompt again, and use:
setup /p j /iv
/p j forces ACPI support (Thanks to "Richard S" on the Virtualbox forums for this tip.) /iv is unimportant, but it disables the annoying "billboards" during installation, which advertised once-exciting features like support for dial-up modems and JPEG wallpaper. I used a "Typical" installation; there didn't seem to be much point in tweaking the installed package set when everything is so small by modern standards. Windows 98 has built-in support for the Cirrus VGA card that we're emulating, so after a few reboots, it should be able to run in a semi-modern resolution and colour depth. Discworld Noir apparently prefers a 640 480 16-bit video mode, so right-click on the desktop background, choose Properties and set that up. Audio drivers This is the part that took me the longest to get working. Of the sound cards that qemu can emulate, Windows 98 only supports the SoundBlaster 16 out of the box. Unfortunately, the Soundblaster 16 emulation in qemu is incomplete, and in particular version 2.1 (as shipped in Debian 8) has a tendency to make Windows lock up during boot. I've seen advice in various places to emulate an Eqsonic ES1370 (SoundBlaster AWE 64), but that didn't work for me: one of the drivers I tried caused Windows to lock up at a black screen during boot, and the other didn't detect the emulated hardware. The next-oldest sound card that qemu can emulate is a Realtek AC97, which was often found integrated into motherboards in the late 1990s. This one seems to work, with the "A400" driver bundle linked above. For Windows 98 first edition, you need a driver bundle that includes the old "VXD" drivers, not just the "WDM" drivers supported by Second Edition and newer. The easiest way to get that into qemu seems to be to turn it into a CD image:
genisoimage -o /srv/virt/discworldnoir-drivers.iso WDM_A400.exe
qemu-system-i386 -hda /srv/virt/discworldnoir.qcow2 \
    -drive media=cdrom,format=raw,file=/srv/virt/windows98.iso \
    -drive media=cdrom,format=raw,file=/srv/virt/discworldnoir-drivers.iso \
    -no-kvm -vga cirrus -m 256 -cpu pentium3 -localtime -soundhw ac97
Run the installer from E:, then reboot with the Windows 98 CD inserted, and Windows should install the driver. Installing Discworld Noir Boot up the virtual machine with CD 1 in the emulated drive:
qemu-system-i386 -hda /srv/virt/discworldnoir.qcow2 \
    -drive media=cdrom,format=raw,file=/srv/virt/DWN_ENG_1.iso \
    -no-kvm -vga cirrus -m 256 -cpu pentium3 -localtime -soundhw ac97
You might be thinking "... why not insert all three CDs into D:, E: and F:?" but the installer expects subsequent disks to appear in the same drive where CD 1 was initially, so that won't work. Instead, when prompted for a new CD, switch to the qemu monitor with Ctrl+Alt+2 (note that this is 2, not F2). At the (qemu) prompt, use info block to see a list of emulated drives, then issue a command like
change ide0-cd1 /srv/virt/DWN_ENG_2.iso
to swap the CD. Then switch back to Windows' console with Ctrl+Alt+1 and continue installation. I used a Full installation of Discworld Noir. Transferring the virtual machine to GNOME Boxes Having finished the "control freak" phase of installation, I wanted a slightly more user-friendly way to run this game, so I transferred the virtual machine to be used by libvirtd, which is the backend for both GNOME Boxes and virt-manager:
virsh create discworldnoir.xml
Here is the configuration I used. It's a mixture of automatic configuration from virt-manager, and hand-edited configuration to make it match the qemu-system-i386 command-line. Running the game If all goes well, you should now see a discworldnoir virtual machine in GNOME Boxes, in which you can boot Windows 98 and play the game. Have fun!

14 November 2015

Daniel Pocock: Migrating data from Windows phones

Many of the people who have bought Windows phones seek relief sooner or later. Sometimes this comes about due to peer pressure or the feeling of isolation, in other cases it is the frustration of the user interface or the realization that they can't run cool apps like Lumicall. Frequently, the user has been given the phone as a complimentary upgrade when extending a contract without perceiving the time, effort and potential cost involved in getting their data out of the phone, especially if they never owned a smartphone before. When a Windows phone user does decide to cut their losses, they are usually looking to a friend or colleague with technical expertise to help them out. Personally, I'm not sure that anybody I would regard as an IT expert has ever had a Windows phone though, meaning that many experts are probably also going to be scratching their heads when somebody asks them for help. Therefore, I've put together this brief guide to help deal with these phones more expediently when they are encountered. The Windows phones have really bad support for things like CalDAV and WebDAV so don't get your hopes up about using such methods to backup the data to any arbitrary server. Searching online you can find some hacks that involve creating a Google or iCloud account in the phone and then modifying the advanced settings to send the data to an arbitrary server. These techniques vary a lot between specific versions of the Windows Phone OS and so the techniques I've described below are probably easier. Identify the Windows Live / Hotmail account The user may not remember or realize that a Microsoft account was created when they first obtained the phone. It may have been created for them by the phone, a friend or the salesperson in the phone shop. Look in the settings (Accounts) to find the account ID / email address. If the user hasn't been using this account, they may not recognize it and probably won't know the password for it. It is essential to try and obtain (or reset) the password before going any further, so start with the password recovery process. Microsoft may insist on sending a password reset email to some other email address that the user has previously provided or linked to their phone. Extracting data from the phone In many cases, the easiest way to extract the data is to download it from Microsoft live.com rather than extracting it from the phone. Even if the user doesn't realize it, the data is probably all replicated in live.com and so there is no further loss of privacy by logging in there to extract it. Set up an IMAP mail client An IMAP client will be used to download the user's emails (from the live.com account they may never have used) and SMS. Install Mozilla Thunderbird (IceDove on Debian), GNOME Evolution or a similar program on the user's PC. Configure the IMAP mail client to connect to the live.com account. Some clients, like Thunderbird, will automatically set up all the server details when you enter the live.com account ID. For manual account setup, the details here may help. Email backup If the user was not using the live.com account ID for email correspondence, there may not be a lot of mail in it. There may be some billing receipts or other things that are worth keeping though. Create a new folder (or set of folders) in the user's preferred email account and drag and drop the messages from the live.com Inbox to the new folder(s). SMS backup SMS backup can also be done through live.com. It is slightly more complicated than email backup, but similar.
  • In the live.com Outlook email index page, look for the settings button and click Manage Categories.
  • Enable the Contacts and Photos categories with a tick in each of them.
  • Go back to the main Inbox page and look for the categories section on the bottom left-hand side of the screen, under the folder list. Click the Contacts category.
  • The page may now appear blank. That is normal.
  • On the top right-hand corner of the page, click the Arrange menu and choose Conversation.
  • All the SMS messages should now appear on the screen.
  • Under the mail folders list on the left-hand side of the page, click to create a new folder with a name like SMS.
  • Select all the SMS messages and look for the option to move them to a folder. Send them to the SMS folder you created.
  • Now use the IMAP mail client to locate the SMS folder and copy everything from there to a new folder in the user's preferred mail server or local disk.
Contacts backup On the top left-hand corner of the live.com email page, there is a chooser to select other live.com applications. Select People. You should now see a list of all the user's contacts. Look for the option to export them to Outlook and other programs. This will export them as a CSV file. You can now import the CSV file into another application. GNOME Evolution has an import wizard with an option for Outlook file format. To load the contacts into a WebDAV address book, such as DAViCal, configure the address book in Evolution and then select it as the destination when running the CSV import wizard. WARNING: beware of using the Mozilla Thunderbird address book with contact data from mobile devices and other sources. It can't handle more than two email addresses per contact and this can lead to silent data loss if contacts are not fully saved. Calendar backup Now go to the live.com application chooser again and select the calendar application. Microsoft provides instructions to extract the calendar, summarised here:
  • Look for the Share button at the top somewhere and click it.
  • On the left-hand side of the page, click Get a link
  • On the right-hand side, choose Show event details to ensure you get a full calendar and then click Create underneath it.
  • Look for the link with a webcals prefix. If you are downloading with a tool like wget, change the scheme prefix to https. Fetch the file from this link and save it with an ics extension.
  • Inspect the ics calendar file to make sure it looks like real iCalendar data.
You can now import the ics file into another application. GNOME Evolution has an import wizard with an option for iCalendar file format. To load the calendar entries into a CalDAV server, such as DAViCal, configure the calendar server in Evolution and then select it as the destination when running the import wizard. Backup the user's photos, videos and other data files Hopefully you will be able to do this step without going through live.com. Try enabling the MTP or PTP mode in the phone and attach it to the computer using the USB cable. Hopefully the computer will recognize it in at least one of those modes. Use the computer's file manager or another tool to simply backup the entire directory structure. Reset the phone to factory defaults Once the user has their hands on a real phone, it is likely they will never want to look at that Windows phone again. It is time to erase the Windows phone, there is no going back. Go to the Settings and About and tap the factory reset option. It is important to do this before obliterating the live.com account, otherwise there are scenarios where you could be locked out of the phone and unable to erase it. Erasing may take some time. The phone will reboot and then display an animation of some gears spinning around for a few minutes and then reboot again. Wait for it to completely erase. Permanently close the Microsoft live.com account Keeping track of multiple accounts and other services is tedious and frustrating for most people, especially with services that try to force the user to receive email in different places. You can help eliminate user fatigue by helping them permanently close the live.com account so they never have to worry about it again. Follow the instructions on the Microsoft site. At some point it will suggest certain actions you should take before closing the account, most can be ignored. One thing you should do is remove the link between the live.com account ID and the phone. It is a good idea to do this as otherwise you may have problems erasing the device, if you haven't already done so. Before completely closing the account, also verify that the factory reset of the phone completed successfully. Dispose of the Windows phone safely If you can identify any faults with the phone, the user may be able to return it under the terms of the warranty. Some phone companies may allow the user to exchange it for something more desirable when it fails under warranty. It may be tempting to sell the phone to a complete stranger on eBay or install a custom ROM on it. In practice, neither option may be worth the time and effort involved. You may be tempted to put it beyond use so nobody else will suffer with it, but please try to do so in a way that is respectful of the environment. Putting the data into a new phone Prepare the new phone with a suitable ROM such as Replicant or Cyanogenmod. Install the F-Droid app on the new phone. From F-droid, install the DAVdroid app. DAVdroid will allow you to quickly sync the new phone against any arbitrary CalDAV and WebDAV server to populate it with the user's calendar and contact / address book data. Now is a good time to install other interesting apps like Lumicall, Conversations and K-9 Mail.

Juliana Louback: PaperTrail - Powered by IBM Watson

On the final semester of my MSc program at Columbia SEAS, I was lucky enough to be able to attend a seminar course taught by Alfio Gliozzo entitled Q&A with IBM Watson. A significant part of the course is dedicated to learning how to leverage the services and resources available on the Watson Developer Cloud. This post describes the course project my team developed, the PaperTrail application.

Project Proposal Create an application to assist in the development of future academic papers. Based on a paper s initial proposal, Paper Trail predicts publications to be used as references or acknowledgement of prior art and provides a trend analysis of major topics and methods. The objective is to speed the discovery of relevant papers early in the research process, and allow for early assessment of the depth of prior research concerning the initial proposal.

Meet the Team Wesley Bruning, Software Engineer, MSc. in Computer Science Xavier Gonzalez, Industrial Engineer, MSc. in Data Science Juliana Louback, Software Engineer, MSc. in Computer Science Aaron Zakem, Patent Attorney, MSc. in Computer Science

Prior Art A significant amount of attention has been given to this topic over the past few decades. The table below shows the work the team deemed most relevant due to recency, accuracy and similarity of functionality. priorArt The variation in accuracy displayed is a result of experimentation with different dataset sizes and algorithm variations. More information and details can be found in the prior art report. The main differential of PaperTrail is providing a form of access to the citation prediciton and trend analysis algorithm. With the exception of the project by McNee et al., these algorithmns aren t currently available for general use. The application on researchindex.net is open to use but its objective is to rank publications and authors for given topics.

Algorithm Citation Prediction: PaperTrail builds on the work done by Wolski s team in Fall 2014. This algorithmn builds a reference graph used to define research communities, with an associated vector of topic scores generated by an LDA model. The papers in each research community are then ranked by importance within the community with a custom ranking algorithm. When a target document is given to algorithm as input, the LDA model is used to generate a vector of topics that are present in the document. The communities with the most similar topic vectors are selected and the publications within these communities with highest rank and greatest similarity to the input document are recommended as references. A more detailed description can be found here. Trend Analysis: Initially, the idea was to use the AlchemyData News API to obtain statistics pertaining to the amount of publications on a given topic over time. However, with the exception of buzz-words (i.e. big data ), many more specialized topics appeared very infrequently in news articles, if at all. This isn t entirely surprising given the target audience of PaperTrail. As a work around, we use the Alchemy Language API to extract keywords from the abstracts in the dataset, in addition to relevance scores. The PaperTrail database could then be queried for entry counts for a given year and keyword to provide an indication of publication trends in academia. Note that the Alchemy Language API extracts multiple-word keywords as well as single words.

Data To maintain consistency with Wolski s project, we are using the DBLP data as made available on aminer.org. The DBLP-Citation-network V5 dataset contains 1,572,277 entries; we are limited to the use of entries that contain both abstracts and citations, bringing the dataset size down to 265,865 entries.

Architecture A high-level visualization of the project architecture is displayed below. Before launching PaperTrail, it s necessary to train Wolski s algorithm offline. Currently any documentation with regard to the performance of said algorithm is unavailable; the PaperTrail project will include an evaluation phase and report the findings made. The PaperTrail app and database will be hosted on the Bluemix Platform. ptArchitecture

Status Report Phases completed:
  • Project design
  • Prior art research
  • Data cleansing
  • Development and deployment of an alpha version of the PaperTrail app
Phases under development:
  • Algorithm training and evaluation
  • Keyword extraction
  • MapReduce of publication frequency by year and topic
  • Data visualization component

13 November 2015

Francois Marier: How Tracking Protection works in Firefox

Firefox 42, which was released last week, introduced a new feature in its Private Browsing mode: tracking protection. If you are interested in how this list is put together and then used in Firefox, this post is for you.

Safe Browsing lists There are many possible ways to download URL lists to the browser and check against that list before loading anything. One of those is already implemented as part of our malware and phishing protection. It uses the Safe Browsing v2.2 protocol. In a nutshell, the way that this works is that each URL on the block list is hashed (using SHA-256) and then that list of hashes is downloaded by Firefox and stored into a data structure on disk:
  • ~/.cache/mozilla/firefox/XXXX/safebrowsing/mozstd-track* on Linux
  • ~/Library/Caches/Firefox/Profiles/XXXX/safebrowsing/mozstd-track* on Mac
  • C:\Users\XXXX\AppData\Local\mozilla\firefox\profiles\XXXX\safebrowsing\mozstd-track* on Windows
This sbdbdump script can be used to extract the hashes contained in these files and will output something like this:
$ ~/sbdbdump/dump.py -v .
- Reading sbstore: mozstd-track-digest256
[mozstd-track-digest256] magic 1231AF3B Version 3 NumAddChunk: 1 NumSubChunk: 0 NumAddPrefix: 0 NumSubPrefix: 0 NumAddComplete: 1696 NumSubComplete: 0
[mozstd-track-digest256] AddChunks: 1445465225
[mozstd-track-digest256] SubChunks:
...
[mozstd-track-digest256] addComplete[chunk:1445465225] e48768b0ce59561e5bc141a52061dd45524e75b66cad7d59dd92e4307625bdc5
...
[mozstd-track-digest256] MD5: 81a8becb0903de19351427b24921a772
The name of the blocklist being dumped here (mozstd-track-digest256) is set in the urlclassifier.trackingTable preference which you can find in about:config. The most important part of the output shown above is the addComplete line which contains a hash that we will see again in a later section.

List lookups Once it's time to load a resource, Firefox hashes the URL, as well as a few variations of it, and then looks for it in the local lists. If there's no match, then the load proceeds. If there's a match, then we do an additional check against a pairwise allowlist. The pairwise allowlist (hardcoded in the urlclassifier.trackingWhitelistTable pref) is designed to encode what we call "entity relationships". The list groups related domains together for the purpose of checking whether a load is first or third party (e.g. twitter.com and twimg.com both belong to the same entity). Entries on this list (named mozstd-trackwhite-digest256) look like this:
twitter.com/?resource=twimg.com
which translates to "if you're on the twitter.com site, then don't block resources from twimg.com. If there's a match on the second list, we don't block the load. It's only when we get a match on the first list and not the second one that we go ahead and cancel the network load. If you visit our test page, you will see tracking protection in action with a shield icon in the URL bar. Opening the developer tool console will expose the URL of the resource that was blocked:
The resource at "https://trackertest.org/tracker.js" was blocked because tracking protection is enabled.

Creating the lists The blocklist is created by Disconnect according to their definition of tracking. The Disconnect list is on their Github page, but the copy we use in Firefox is the copy we have in our own repository. Similarly the Disconnect entity list is from here but our copy is in our repository. Should you wish to be notified of any changes to the lists, you can simply subscribe to this Atom feed. To convert this JSON-formatted list into the binary format needed by the Safe Browsing code, we run a custom list generation script whenever the list changes on GitHub. If you run that script locally using the same configuration as our server stack, you can see the conversion from the original list to the binary hashes. Here's a sample entry from the mozstd-track-digest256.log file:
[m] twimg.com >> twimg.com/
[canonicalized] twimg.com/
[hash] e48768b0ce59561e5bc141a52061dd45524e75b66cad7d59dd92e4307625bdc5
and one from mozstd-trackwhite-digest256.log:
[entity] Twitter >> (canonicalized) twitter.com/?resource=twimg.com, hash a8e9e3456f46dbe49551c7da3860f64393d8f9d96f42b5ae86927722467577df
This in combination with the sbdbdump script mentioned earlier, will allow you to audit the contents of the local lists.

Serving the lists The way that the binary lists are served to Firefox is through a custom server component written by Mozilla: shavar. Every hour, Firefox requests updates from shavar.services.mozilla.com. If new data is available, then the whole list is downloaded again. Otherwise, all it receives in return is an empty 204 response. Should you want to play with it and run your own server, follow the installation instructions and then go into about:config to change these preferences to point to your own instance:
browser.trackingprotection.gethashURL
browser.trackingprotection.updateURL
Note that on Firefox 43 and later, these prefs have been renamed to:
browser.safebrowsing.provider.mozilla.gethashURL
browser.safebrowsing.provider.mozilla.updateURL

Learn more If you want to learn more about how tracking protection works in Firefox, you can find all of the technical details on the Mozilla wiki or you can ask questions on our mailing list. Thanks to Tanvi Vyas for reviewing a draft of this post.

Raphaël Hertzog: Freexian s report about Debian Long Term Support, October 2015

A Debian LTS logoLike each month, here comes a report about the work of paid contributors to Debian LTS. Individual reports In September, 85.50 work hours have been dispatched among 8 paid contributors. Their reports are available: Evolution of the situation November crossed a new record with 114.5 hours funded. This is mainly thanks to our first Platinum sponsor: TOSHIBA (through Toshiba Software Development Vietnam). They don t know yet if they can sponsor us in the long term (they hope so), but it s still a nice news as we jumped from 50% to 65% of the objective of the equivalent of a full-time position with a single new sponsor. Currently no change is expected for next month as we don t have any other new sponsor in the process of joining us. We still need more support to be able to support all the packages we could not afford to support during the squeeze cycle. We are currently discussing which package we can or cannot support on the LTS list, see the thread Unsupported packages for Wheezy LTS for the current situation. In terms of security updates waiting to be handled, the situation is close to last month: the dla-needed.txt file lists 21 packages awaiting an update (6 more than last month), the list of open vulnerabilities in Squeeze shows about 23 affected packages in total (exactly like last month). Thanks to our sponsors The new sponsors are in bold.

No comment Liked this article? Click here. My blog is Flattr-enabled.

Jaldhar Vyas: New Year Resolutions

Now this could just be the prodigious amounts of sugar and ghee I've been eating the past few days, but I'm bursting with energy for working on Debian so here is a list of things I want to do in the upcoming year. This will happen soon. Sooner if you people will stop filing bugs all the time. The rest of the items are more long term. To keep all of this on track, I shall adopt the practice lately seen on Debian Planet of periodically posting a report of my Debian activities.
12 November 2015

Carl Chenet: db2twitter 0.2 released

db2twitter 0.2 was just released! If you missed my last post about it, db2twitter automatically extracts fields from your database, use them to feed a template of tweet and send the tweet. db2twitter is developed by and run for LinuxJobs.fr, the job board of th french-speaking Free Software and Opensource community. banner-linuxjobs-small The main new feature allows to send tweets only during authorized days/hours with the following content in your db2twitter.ini file :
[timer]
days=mon-fri,
hours=0-11,14-17,
Given the fact db2twitter will mostly be launched via cron, it allows sending tweets detected since the last db2twitter run during user-defined hours. And that s cool! db2twitter is coded in Python 3.4, uses SQlAlchemy (see supported database types) and Tweepy. The official documentation is available on readthedocs.

10 November 2015

Jaldhar Vyas: Happy Diwali and Sal Mubarak 2072

Wishing you all a happy Diwali and Gujarati New Year (V.S. 2072 called Plavanga.)Instead of being something sane like a flat disk supported by four elephants standing on a tortoise, the Earth is an oblate spheroid in heliocentric orbit. The Moon too offends by maintaining an unreasonably non-epicyclic orbit. Combined this means that the Americas (plus Iceland if there any Hindus there) observe Diwali today whereas in India and the rest of the world it is tomorrow. Technically in these longitudes the Ashvayuja amavasya tithi pervades both Tuesday and Wednesday but as Lakshmi Puja takes place at the pradosha kala it means it should be celebrated today though no doubt most of the non-astronomically minded people will just follow India any way. The New Year is on Thursday all over the world.Regardless of when you celebrate, may your year be full of happiness, good fortune and prosperity.

John Goerzen: Wow. I did that!

It s now official: I m a pilot. This has been one of the most challenging, and also most rewarding, journeys I ve been on. It had its moments of struggle, moments of joy, moments of poetry. I wrote about the poetry of flying at night recently. Here is the story of my first landing on a grass runway, a few months ago. Grass
Where the air is so pure, the zephyrs so free,
The breezes so balmy and light,
That I would not exchange my home on the range
For all of the cities so bright. John A. Lomax
We are used to seeing planes in these massive palaces of infrastructure we call airports. We have huge parking garages, giant terminals, security lines hundreds of people deep, baggage carts, jetways, video screens, restaurants, and miles and miles of concrete. But most of the world s airports are not like that. A pilot of a small plane gets to see the big airports, sure, but we also get to use the smaller airports hidden in plain sight to most. Have you ever taken off from a strip of grass? As I told my flight instructor when I tried it for the first time, I know this will work, but somehow I will still be amazed if it actually does. I took off from a strip of grass not long ago. The airport there had one paved runway, and the rest were grass. Short runways, narrow runways, grass runways. No lights. No paint. No signs. No trucks, no jetways, nothing massive. In fact, no people. Just a mowed path and a couple of yellow or white markers. I taxied down the grass runway, being careful to never let the plane s wheels stop moving lest the nose gear get stuck in a pothole. I felt all the bumps in the ground as we moved. End of runway. Turn the plane around. A little bit of flap for more lift, full throttle, mind the centerline imaginary centerline, this time. It starts picking up speed, slower than usual, bump bump bump. Those buildings at the end of the runway are staring me down. More speed, and suddenly the runway feels smooth; it has enough lift to keep from falling into every bump. Then we lift off just a touch; I carefully keep the plane down until we pick up enough speed to ascend farther, then up we go. I keep a watchful eye on those buildings straight ahead and that water tower just slightly off to the one side. We climb over a lake as I watch that water tower pass safely below and to the side of the plane. It had worked, and I had a smile of amazement. With a half mile of grass, you really can go anywhere. Many times I had driven within half a mile of that runway, but never seen it. Never wondered where people go after using it. Never realizing that, although it s a 45-minute drive from my house, it s really pretty close. Never understanding that where people go after taking off from that runway is everywhere .

Norbert Preining: Music check: Google versus Apple Is that all? You can do better, Google!

Ok, I have been an iPhone user since I moved to Japan and got my first smart-phone ever. First a 3s, then a 4s, then a 5s that I dropped into the toilet, so I switched the SIM back into the 4s to have a working phone. Furthermore, I am a heavy music listener and used iTunes Radio for 3 months. Since I am planning to change phones to an Android phone (being fed up with Apple s super-closed environment), I tried out Google Music Plus for about 3 months, too. Here is my verict Google Music is a big pain, far from iTunes in comfort and user friendliness. music-check-google-vs-apple My move to Android is not very much in danger. General description of the service In principle, iTunes Radio and Google Music Subscription do the same things: There are slight differences, that often create confusion, especially with Apple s services: If you are only signed in, you can listen to music stations and can skip some music (limited), but you cannot listen to arbitrary songs from the whole Apple Music library. Then there is another service from Apple, called iTunes Match, that only allows you to upload your music library to the cloud, but other than that again only listening to normal radio stations. Google Music is much simpler, there are only two options: By default it is free to have your music (up to 25000 songs) in the cloud, but if you want to listen to radio stations or any other music in the Google music store, you need a subscription. Prizes and features overview:
Apple Google
No subscription iTunes Match iTunes Radio No subscription With subscription
Prize 0 25$/year 10$/month 0 10$/month
(early access 8$)
Cloud space 0 100000 25000
Extra service Radio stations Radio stations Radio/all music Nothing Radio/all music
Music on the go the application Let us first consider the applications provided to listen to music on your smart phone: Apple Music can of course only be used on Apple devices, and uses the built-in Music application. Start up time is about a few seconds after a cold boot (all on my 4s), and music streaming starts with hardly any delay. Responsiveness is good, and the user interface is clear and easy. Google s application is available on iOS and Android. I have tested the latest version on iOS, but it is a pain in the butt: Managing your library Here iTunes is the way to go, bit of a pain when using Linux, but there are other reasons I have a Windows installation in parallel, so I don t mind to boot now and then into Windows. iTunes gives you very powerful tools to change all kind of data. Google gives you a few options: Use your iTunes library in this case all your playlists and ratings (but see later) are also uploaded. I am not sure what happens if I retag a song in iTunes, or change anything else in there. I guess the song will not be re-uploaded, but who knows for sure. Furthermore, you can edit your library via the web interface, but this is rather poor. Searching your library Over times your library grows and there are hundreds if not thousands of artists. So you want to search them. The natural way would be to scroll to the first letter of the artist you are searching, and then look it up. Well, that works perfectly in both Apple s and Google s application unless you are having artists written in some strange script like Japanese or Korean. iTunes allows you to set a field called something like Artist name for sorting , which allows me to put for example or into the artist field, and into the sort field Tomokawa Kazuki and Kim Doo Soo . This way I find the artists in the correct place. Google on the other hand uses simple Unicode order sorting how could you do that? This is simply plain wrong, and everyone should know that by now. Japanese people will never be able to find anything in their list. And in contrast to Goole Contacts Google Music does not support phonetic name fields (similar to the order sort artist) for artists. What I had to do now is to rename all the artists to include first the phonetic name, followed by the proper name, like in Tomokawa Kazuki ( ) . Something I strongly detest! Radio stations I might have a slightly peculiar music taste, but the radio stations mixed by Google are simply a pain. The reason is easy to explain: I live in Japan, and so what Google does is mixing about 80% of J-Pop into the radio, all those happy yodeling girlies I really dislike (see my Anti J-Pop campaign for alternatives yes, they do exist also in Japan!). iTunes radio is here more relaxed it seems. I appreciate Google s trial to cater to local (dis)taste, but besides voting down each and every song I hear I don t see any other option. And honestly, I cannot go through all this voting down without dying from pain inflicted by J-Pop. Other than this, the two radio stations are probably more or less the same but as I said, due to the local colorit it is hard to compare. Rating Ohhh, what a dire point. So there you have you well curated iTunes library with 5-star ratings. I used the ratings in a way that those songs I like get 1 star, those I even like more get 2 stars, and my absolute favorites got 5 stars. I didn t do any negative ratings. iTunes/iOS Music app allows you to easily adjust rating, and they are synced between devices. All as you would expect. Now for Google they did have a 5-star rating system at some time, but:
Thank you for your feedback. We ve decided to remove the 5-star Rating lab. This decision wasn t made lightly, but Thumbs Up/Down is integral for the future vision for Play Music and will be a central design point for our future releases. Please note that we ll continue to store your ratings that you ve set via the star lab or via iTunes, and we ll translate them to thumbs up/down (1-2 stars = thumbs down, 4-5 stars = thumbs up).
Here we go with the move to a new design they threw away the 5-star system, without any reason but integral for future vision rubbish sales speak. Besides being a very very poor rating system to have only an up and down (good-bad-don t care), the translation from my rating system to the thumbs up-down is just plain wrong. <rant>
Why on earth is the current movement to reduce functionality and rob users of control? Gnome 3 is the prime example of how we stupiditize users by taken any freedom from them in the name of simple design. Google now does the same. I am so sick of getting patronized this way, so Gnome3 was completely banished from my computer and replaced by Cinnamon, which uses the same (good) underlying technique, but takes users seriously!
</rant> Overall verdict As much as I would like to see Google Music a valid alternative to iTunes, by now it makes the impression of a quickly hacked together rotten piece of code that tries to get a share of the market without providing equivalent service. Google is using its market presence and convenience to convert people, not features and quality. I can only hope that this changes in the future. That still leaves me with the question move to Android or remain with iOS

9 November 2015

Ben Armstrong: The passing of Debian Live

Debian Live has passed on. And it has done so in not happy circumstances. (You can search the list archives for more if you are confused.) I have reposted here my response to this one thread because it s all I really want to say, after all of the years of working with the team. I d like to add as a postscript, that while the focus of this article was to remain positive in the face of Daniel s announcement of the closure of his project, that event has left a lot of users confused about the status of live support in Debian going forward. Read my posts here and here addressing that confusion.
On 09/11/15 12:47 PM, Daniel Baumann wrote:
> So long, and thanks for all the fish[7].
>
> Daniel
>
> [7] http://live.debian.net/project/downstream/ Enough bitter words have been said. I don t want to add any more. So: I m proud. Indeed, that long list of downstreams does speak to the impact you ve had in inspiring and equipping people to make their own live images. I m proud to have been a small part of this project. I m thankful. I m thankful that I was able to, through this project, contribute to something for a while that had a positive impact on many people, and made Debian more awesome. I remember the good times. I remember fondly the good times we had in the project s heyday. I certainly found your enthusiasm and vision for the project, Daniel, personally inspiring. It motivated me to contribute. Debconf10 was a highlight among those experiences, but also I had many good times and made many friendships online, too. I m sad. I m sad, because although I made some attempts to liaise between Debian Live and the CD and Installer teams, I don t feel I did an effective job there, and that contributed to the situation we now find ourselves in. If I did you or the project injury in trying to fulfill that role, please forgive me. I m hopeful. I m hopeful that whichever way we all go from here, that the bitterness will not be forever. That we ll heal. That we ll have learned. That we ll move on to accomplish new things, bigger and better things. Thank you, Daniel. Thank you, Debian Live team. Ben
facebooktwittergoogle_plusredditpinterestlinkedinmail

Jonathan McDowell: The Joy of Recruiters

Last week Simon retweeted a link to Don t Feed the Beast the Great Tech Recruiter Infestation. Which reminded me I d been meaning to comment on my own experiences from earlier in the year. I don t entertain the same level of bile as displayed in the post, but I do have a significant level of disappointment in the recruitment industry. I had conversations with 3 different agencies, all of whom were geographically relevant. One contacted me, the other 2 (one I d dealt with before, one that was recommended to me) I contacted myself. All managed to fail to communicate with any level of acceptability. The agency hat contacted me eventually went quiet, after having asked if they could put my CV forward for a role and pushing very hard about when I could interview. The contact in the agency I d dealt with before replied to say I was being passed to someone else who would get in contact. Who of course didn t. And the final agency, who had been recommended, passed me between 3 different people, said they were confident they could find me something, and then went dark except for signing me up to their generic jobs list which failed to have anything of relevance on it. As it happens my availability and skill set were not conducive to results at that point in time, so my beef isn t with the inability to find a role. Instead it s with the poor levels of communication presented by an industry which seems, to me, to have communication as part of the core value it should be offering. If anyone had said at the start Look, it s going to be tricky, we ll see what we can do or Look, that s not what we really deal in, we can t help , that would have been fine. I m fine with explanations. I get really miffed when I m just left hanging. I d love to be able to say I ll never deal with a recruiter again, but the fact of the matter is they do serve a purpose. There s only so far a company can get with word of mouth recruitment; eventually that network of personal connections from existing employees who are considering moving dries up. Advertising might get you some more people, but it can also result in people who are hugely inappropriate for the role. From the company point of view recruiters nominally fulfil 2 roles. Firstly they connect the prospective employer with a potentially wider base of candidates. Secondly they should be able to do some sort of, at least basic, filtering of whether a candidate is appropriate for a role. From the candidate point of view the recruiter hopefully has a better knowledge of what roles are out there. However the incentives to please each side are hugely unbalanced. The candidate isn t paying the recruiter. If you re not paying for it, you re the product may be bandied around too often, but I believe this is one of the instances where it s very applicable. A recruiter is paid by their ability to deliver viable candidates to prospective employers. The delivery of these candidates is the service. Whether or not the candidate is happy with the job is irrelevant beyond them staying long enough that the placement fee can be claimed. The lengthy commercial relationship is ideally between the company and the recruitment agency, not the candidate and the agency. A recruiter wants to be able to say Look at the fine candidate I provided last time, you should always come to me first in future . There s a certain element of wanting the candidate to come back if/when they are looking for a new role, but it s not a primary concern. It is notable that the recommendations I d received were from people who had been on the hiring side of things. The recruiter has a vested interest in keeping the employer happy, in the hope of a sustained relationship. There is little motivation for keeping the candidate happy, as long as you don t manage to scare them off. And, in fact, if you scare some off, who cares? A recruiter doesn t get paid for providing the best possible candidate. Or indeed a candidate who will fully engage with the role. All they re required to provide is a hire-able candidate who takes the role. I m not sure what the resolution is to this. Word of mouth only scales so far for both employer and candidate. Many of the big job websites seem to be full of recruiters rather than real employers. And I m sure there are some decent recruiters out there doing a good job, keeping both sides happy and earning their significant cut. I m sad to say I can t foresee any big change any time soon. [Note I m not currently looking for employment.] [No recruitment agencies were harmed in the writing of this post. I have deliberately tried to avoid outing anyone in particular.]

Ben Hutchings: Debian LTS work, October 2015

For my 11th month working on Debian LTS, I carried over 5.5 hours from September and was assigned another 13.5 hours of work by Freexian's Debian LTS initiative. I worked 14 of a possible 19 hours. As I mentioned in the report for September, I uploaded binutils and issued DLA-324-1 early in October. I fixed a few security issues in the kernel, uploaded and issued DLA-325-1. I had some email discussions about long-term support of the Linux kernel with Willy Tarreau (Linux 2.6.32 maintainer) and Greg Kroah-Hartman (overall stable maintainer). Greg normally selects one version per year to maintain as a 'longterm' branch for 2 years, after which he may hand it over to another maintainer. A few upstream versions have received long-term support entirely from another developer. We were in agreement that it's desirable to have fewer of these branches with more developers and distributions contributing to each, but didn't come to a conclusion about how to coordinate this. The topic came up again at the Kernel Summit, and Greg then agreed to select the first kernel version of each calendar year, starting with Linux 4.4 (expected in January). This doesn't fit well with Debian's current release schedule, but I mean to discuss with the release team whether the freeze date can be set to allow inclusion of 2017's LTS kernel. I spent another week in the 'front desk' role, where I triaged new security issues for squeeze. There was a mixture of serious and trivial, old and new (not affecting squeeze) issues. The many ntp issues announced in October were fixed in unstable by a new upstream release. I spent a long time digging out the specific commits that fixed them and comparing with the older version in squeeze. Several of the issues had been introduced in ntp 4.2.7 or 4.2.8 and therefore didn't affect squeeze (or the newer stable releases). Of the fixes that were needed, most applied with minimal changes. Having prepared an update, I asked the ntp maintainer, Kurt Roeckx, to review my work. (The package has a limited test suite and none of the fixes added new tests.) Following this review he added a few more patches, uploaded and issued DLA-335-1. MySQL 5.1, as shipped in squeeze, no longer receives security support from upstream, and the security fixes they do issue are mixed with other changes that make it impractical to backport them. The LTS team is planning to backport the mysql-5.5 package to squeeze while avoiding conflicts with the binaries built from mysql-5.1. Santiago Ruano Rinc n has prepared a backport and I spent some time reviewing this, but haven't yet sent my review comments.

Daniel Pocock: debian.org RTC: announcing XMPP, SIP presence and more

Announced 7 November 2015 on the debian-devel-announce mailing list. The Debian Project now has an XMPP service available to all Debian Developers. Your Debian.org email identity can be used as your XMPP address. The SIP service has also been upgraded and now supports presence. SIP and XMPP presence, rosters and messaging are not currently integrated. The Lumicall app has been improved to enable rapid setup for Debian.org SIP users. This announcement concludes the maintenance window on the RTC services. All services are now running on jessie (using packages from jessie-backports). XMPP and SIP enable a whole new world of real-time multimedia communications possibilities: video/webcam, VoIP, chat messaging, desktop sharing and distributed, federated communication are the most common use cases. Details about how to get started and get support are explained in the User Guide in the Debian wiki. As it is a wiki, you are completely welcome to help it evolve. Several of the people involved in the RTC team were also at the Cambridge mini-DebConf (7-8 November). The password for all these real time communication services can be set via the LDAP control panel. Please note that this password needs to be different to any of your other existing debian.org passwords. Please use a strong password and please keep it secure. Some of the infrastructure, like the TURN server, is shared by clients of both SIP and XMPP. Please configure your XMPP and SIP clients to use the TURN server for audio or video streaming to work most reliably through NAT. A key feature of both our XMPP and SIP services is that they support federated inter-connectivity with other domains. Please try it. The FedRTC service for Fedora developers is one example of another SIP service that supports federation. For details of how it works and how we establish trust between domains, please see the RTC Quick Start Guide. Please reach out to other communities you are involved with and help them consider enabling SIP and XMPP federation of their own communities/domains: as Metcalfe's law suggests, each extra person or community who embraces open standards like SIP and XMPP has far more than just an incremental impact on the value of these standards and makes them more pervasive. If you are keen to support and collaborate on the wider use of Free RTC technology, please consider joining the Free RTC mailing list sponsored by FSF Europe. There will also be a dedicated debian-rtc list for discussion of these technologies within Debian and derivatives. This service has been made possible by the efforts of the DSA team in the original SIP+WebRTC project and the more recent jessie upgrades and XMPP project. Real-time communications systems have specific expectations for network latency, connectivity, authentication schemes and various other things. Therefore, it is a great endorsement of the caliber of the team and the quality of the systems they have in place that they have been able to host this largely within their existing framework for Debian services. Feedback from the DSA team has also been helpful in improving the upstream software and packaging to make them convenient for system administrators everywhere. Special thanks to Peter Palfrader and Luca Filipozzi from the DSA team, Matthew Wild from the Prosody XMPP server project, Scott Godin from the reSIProcate project, Juliana Louback for her contributions to JSCommunicator during GSoC 2014, Iain Learmonth for helping get the RTC team up and running, Enrico Tassi, Sergei Golovan and Victor Seva for the Prosody and prosody-modules packaging and also the Debian backports team, especially Alexander Wirt, helping us ensure that rapidly evolving packages like those used in RTC are available on a stable Debian system.

Vasudev Kamath: Taming systemd-nspawn for running containers

I've been trying to run containers using systemd-nspawn for quite some time. I was always bumping to one or other dead end. This is not systemd-nspawn's fault, rather my impatience stopping me from reading manual pages properly lack of good tutorial like article available online. Compared to this LXC has a quite a lot of good tutorials and howto's available online. This article is my effort to create a notes putting all required information in one place.

Creating a Debian Base Install First step is to have a minimal Debian system some where on your hard disk. This can be easily done using debootsrap. I wrote a custom script to avoid reading manual every time I want to run debootstrap. Parts of this script (mostly packages and the root password generation) is stolen from lxc-debian template provided by lxc package.
#!/bin/sh
set -e
set -x
usage ()  
    echo "$ 0##/*  [options] <suite> <target> [<mirror>]"
    echo "Bootstrap rootfs for Debian"
    echo
    cat <<EOF
    --arch         set the architecture to install
    --root-passwd  set the root password for bootstrapped rootfs
    EOF
 
# copied from the lxc-debian template
packages=ifupdown,\
locales,\
libui-dialog-perl,\
dialog,\
isc-dhcp-client,\
netbase,\
net-tools,\
iproute,\
openssh-server,\
dbus
if [ $(id -u) -ne 0 ]; then
    echo "You must be root to execute this command"
    exit 2
fi
if [ $# -lt 2 ]; then
   usage $0
fi
while true; do
    case "$1" in
        --root-passwd --root-passwd=?*)
            if [ "$1" = "--root-passwd" -a -n "$2" ]; then
                ROOT_PASSWD="$2"
                shift 2
            elif [ "$1" != "$ 1#--root-passwd= " ]; then
                ROOT_PASSWD="$ 1#--root-passwd= "
                shift 1
            else
                # copied from lxc-debian template
                ROOT_PASSWD="$(dd if=/dev/urandom bs=6 count=1 2>/dev/null base64)"
                ECHO_PASSWD="yes"
            fi
            ;;
        --arch --arch=?*)
            if [ "$1" = "--arch" -a -n "$2" ]; then
                ARCHITECTURE="$2"
                shift 2
            elif [ "$1" != "$ 1#--arch= " ]; then
                ARCHITECTURE="$ 1#--arch= "
                shift 1
            else
                ARCHITECTURE="$(dpkg-architecture -q DEB_HOST_ARCH)"
            fi
            ;;
        *)
            break
            ;;
    esac
done
release="$1"
target="$2"
if [ -z "$1" ]   [ -z "$2" ]; then
    echo "You must specify suite and target"
    exit 1
fi
if [ -n "$3" ]; then
    MIRROR="$3"
fi
MIRROR=$ MIRROR:-http://httpredir.debian.org/debian 
echo "Downloading Debian $release ..."
debootstrap --verbose --variant=minbase --arch=$ARCHITECTURE \
             --include=$packages \
             "$release" "$target" "$MIRROR"
if [ -n "$ROOT_PASSWD" ]; then
    echo "root:$ROOT_PASSWD"   chroot "$target" chpasswd
    echo "Root password is '$ROOT_PASSWRD', please change!"
fi
It just gets my needs done, if you don't like it feel free to modify or use debootstrap directly. !NB Please install dbus package in the minimal base install, otherwise you will not be able to control the container using machinectl
Manually Running Container and then persisting it Next we need to run the container manually. This is done by using following command.
systemd-nspawn -bD   /path/to/container --network-veth \
     --network-bridge=natbr0 --machine=Machinename
--machine option is not mandatory, if not specified systemd-nspawn will take the directory name as machine name, and if you have characters like - in the directory name it translates to hexcode x2d and controlling container with name becomes difficult. --network-veth specifies the systemd-nspawn to enable virtual ethernet based networking and --network-bridge tells the bridge interface on host system to be used by systemd-nspawn. These options together constitutes private networking for container. If not specified container can use host systems interface there by removing network isolation of container. Once you run this command container comes up. You can now run machinectl to control the container. Container can be persisted using following command
machinectl enable container-name
This will create a symbolic link of /lib/systemd/system/systemd-nspawn@service to /etc/systemd/system/machine.target.wants/. This allows you to start or stop container using machinectl or systemctl command. Only catch here is your base install should be in /var/lib/machines/. What I do in my case is create a symbolic link from my base container to /var/lib/machines/container-name. !NB Note that symbolic link name under /var/lib/machines should be same as the container name you gave using --machine switch or the directory name if you didn't specify --machine
Persisting Container Networking We did persist the container in above step, but this doesn't persist the networking options we provided in command line. systemd-nspawn@.service provides following command to invoke container.
ExecStart=/usr/bin/systemd-nspawn --quiet --keep-unit --boot --link-journal=try-guest --network-veth --settings=override --machine=%I
To persist the bridge networking configuration we did in command line, we need the help of systemd-networkd. So first we need to enable the systemd-networkd.service on both container and the host system.
systemctl enable systemd-networkd.service
Now inside the container, interfaces will be named as hostN. Depending on how many interfaces we have N increments. In our example case we had single interface, hence it will named as host0. By default network interfaces will be down inside container, hence systemd-networkd is needed to put it up. We put the following in /etc/systemd/network/host0.network file inside the container.
[Match]
Name=host0
[Network]
Description=Container wired interface host0
DHCP=yes
And in the host system we just configure the bridge interface using systemd-nspawn. I put following in natbr0.netdev in /etc/systemd/network/
[NetDev]
Description=Bridge natbr0
Name=natbr0
Kind=bridge
In my case I already had configured the bridge using /etc/network/interfaces file for lxc. I think its not really needed to use systemd-networkd in this case. Since systemd-networkd doesn't do anything if network / virtual device is already present I safely put above configuration and enabled systemd-networkd. Just for the notes here is my natbr0 configuration in interfaces file.
auto natbr0
iface natbr0 inet static
   address 172.16.10.1
   netmask 255.255.255.0
   pre-up brctl addbr natbr0
   post-down brctl delbr natbr0
   post-down sysctl net.ipv4.ip_forward=0
   post-down sysctl net.ipv6.conf.all.forwarding=0
   post-up sysctl net.ipv4.ip_forward=1
   post-up sysctl net.ipv6.conf.all.forwarding=1
   post-up iptables -A POSTROUTING -t mangle -p udp --dport bootpc -s 172.16.0.0/16 -j CHECKSUM --checksum-fill
   pre-down iptables -D POSTROUTING -t mangle -p udp --dport bootpc -s 172.16.0.0/16 -j CHECKSUM --checksum-fill
Once this is done just reload the systemd-networkd and make sure you have dnsmasq or any other DHCP server running in your system. Now the last part is to tell systemd-nspawn to use the bridge networking interface we have defined. This is done using container-name.nspawn file. Put this file under /etc/systemd/nspawn folder.
[Exec]
Boot=on
[Files]
Bind=/home/vasudev/Documents/Python/upstream/apt-offline/
[Network]
VirtualEthernet=yes
Bridge=natbr0
Here you can specify networking, and files mounting section of the container. For full list please refer the systemd.nspawn manual page. Now all this is done you can happily do
machinectl start container-name
#or
systemctl start systemd-nspawn@container-name
Resource Control Now all things said and done, one last part remains. Yes what is the point if we can't control how much resource does the container use. Atleast it is more important for me, because I use old and bit low powered laptop. Systemd provides way to control the resource using Control interface. To see all the the interfaces exposed by systemd please refer systemd.resource-control manual page. The way to control the resource is using systemctl. Once container starts running we can run following command.
systemctl set-property container-name CPUShares=200 CPUQuota=30% MemoryLimit=500M
The manual page does say that these things can be put under [Slice] section of unit files. Now I don't have clear idea if this can be put under .nspawn files or not. For the sake of persisting the container I manually wrote the service file for container by copying systemd-nspawn@.service and adding [Slice] section. But if I don't know how to find out if this had any effect or not. If some one knows about this please share your suggestions to me and I will update this section with your provided information.
Conclussion All in all I like systemd-nspawn a lot. I use it to run container for development of apt-offline. I previously used lxc where all can be controlled using a single config file. But I feel systemd-nspawn is more tightly integrated with system than lxc. There is definitely more in systemd-nspawn than I've currently figured out. Only thing is its not as popular as other alternatives and definitely lacks good howto documentation.For now only way out is dig the manual pages, scratch your head, pull your hair out and figure out new possibilities in systemd-nspawn. ;-)

8 November 2015

Andrew Cater: MiniDebconf Cambridge - ARM, Cambridge 1115 8 November

Just had a really good couple of sessions: one from the DPL including Q&A, then a good overview of reproducible builds and where we are today from Holger Levsen (h0lger) and Chris Lamb (lamby)

Then a 2 minute silence at 11.00 as is customary in the UK on this date.

Now Lucy Wayland - who says she has a brainful of IEEE754 from a few years ago working on safety-critical systems so she's unburdening by sharing with all of us - everything you wanted to know about floating point but were afraid to ask (and including a primer on signed/unsigned and fixed point as part of the explanation)

Steve Capper's Java presentation is unfortunately not going to take place, so this afternoon's live stream schedule will be different.

Coffee going down well.

7 November 2015

Stig Sandbeck Mathisen: Let's Encrypt with Hitch and Varnish

Let's Encrypt is now in beta. Here's how to use the automated CA with Hitch TLS proxy, and Varnish HTTP accelerator as a backend for Hitch.
Let's Encrypt Let's Encrypt is a free, automated and open Certificate Authority (CA), run for the public's benefit.
Varnish Varnish is a HTTP accelerator. I use it as a web server, and it serves content from various backends. Varnish is used on a lot of high-traffic web servers, and supports simple and complex web site configurations.
Hitch Hitch is a TLS proxy, by Varnish Software. It terminates TLS connections, and forwards them to a backend, unencrypted. The TLS proxy is simple to configure, and handles many thousands of requests per second on commodity hardware. Hitch was originally called stud and was written by Jamie Turner at Bump.com.
Varnish plugin for Let's Encrypt Let's Encrypt Varnish Plugin is needed for the Let's Encrypt client to authenticate against their service, for getting the certificates. You can skip this if you have the option of temporarily disabling your web service, when registering and renewing your certificates.
Hitch TLS proxy Hitch must be configured to listen on the https port (TCP/443), with a list of strong ciphers. To get Forward Secrecy, we need ciphers with EECDH or EDH. To use these, we need to generate a set of DH Parameters. In /etc/hitch/hitch.conf:
      
# Listening
frontend = "[*]:443"
ciphers  = "EECDH+AESGCM:EDH+AESGCM:AES256+EECDH:AES256+EDH"
      
    
Varnish as backend for Hitch Hitch will forward traffic to Varnish on localhost:6082, using the PROXY protocol. Here's a snippet for /etc/hitch/hitch.conf to do this:
      
# Send traffic to the varnish backend
backend        = "[::1]:6086"
write-proxy-v2 = on
      
    
For varnish, I've added a separate port for the "PROXY" protocol, by adding an extra "-a" argument for port 6086. The -a :80 handles the existing http traffic, while the -a '[::1]:6086,PROXY' adds a listener on localhost, which will be used by hitch.
      
/usr/sbin/varnishd -j unix,user=vcache -a :80 -a '[::1]:6086,PROXY' ...
      
    
Let's Encrypt install letsencrypt First, install the letsencrypt client. The beta program sends you a mail with instructions. When it is generally available, I suspect it'll be something like:
      
apt install letsencrypt
      
    
install varnish plugin Then, get the let's encrypt varnish plugin. The plugin will extend the letsencrypt software to be able to rewrite the VCL and reload Varnish to satisfy the authentication challenge of the Let's Encrypt server.
      
cd /usr/local/src
git clone http://git.sesse.net/letsencrypt-varnish-plugin
. ~/.local/share/letsencrypt/bin/activate
pip install -e /usr/local/src/letsencrypt-varnish-plugin
      
    
get certificate Get certificates. Let's Encrypt is still in beta, so I had to add a few more command line arguments than the documentation specifies:
      
~/.local/share/letsencrypt/bin/letsencrypt --agree-dev-preview \
    --server https://acme-v01.api.letsencrypt.org/directory \
    -a letsencrypt-varnish-plugin:varnish -d example.org certonly
      
    
Adding certificates to Hitch Hitch requires one PEM file per domain we serve. Each .pem file contains the private key, the signed certificate and any required intermediates. Create a file with DH parameters:
      
openssl dhparam -out /etc/hitch/dhparam.pem 2048
      
    
This file may take a long while to generate. Combine the key, the signed certificate, and the dhparam file to something hitch can use:
      
cat \
    /etc/letsencrypt/live/example.org/privkey.pem \
    /etc/letsencrypt/live/example.org/fullchain.pem \
    /etc/hitch/dhparam.pem \
    > /etc/hitch/example.org.pem
chmod 0600 /etc/hitch/example.org.pem
      
    
and configure hitch to use the file, by adding it to /etc/hitch/hitch.conf:
      
# List of PEM files, each with key, certificates and dhparams
pem-file = "/etc/hitch/example.org.pem"
pem-file = "/etc/hitch/www.example.org.pem"
pem-file = "/etc/hitch/example.com.pem"
pem-file = "/etc/hitch/www.example.com.pem"


Mart n Ferrari: Tales from the SRE trenches: Coda

This is the fifth -and last- part in a series of articles about SRE, based on the talk I gave in the Romanian Association for Better Software. Previous articles can be found here: part 1, part 2, part 3, and part 4.

Other lessons learned Apart from these guidelines for SRE I have described in previous posts, there were a few other practices I learned at google that I believe could benefit most operations teams out there (and developers too!).

Automate everything It's worth repeating, it is not sustainable to do things manually. When your manual work grows linearly with your usage, either your service is not growing enough, or you will need to hire more people than there are available in the market.

Involve Ops in systems design Nobody knows better than Ops the challenges of a real production environment, getting early feedback from your operations team can save you a lot of trouble down the road. They might give you insights about scalability, capacity planning, redundancy, and the very real limitations of hardware.

Give Ops time and space to innovate If there is so much emphasis on limiting the amount of operational load put on SRE, that freed time is not only used for creating monitoring dashboards or writing documentation. As I said in the beginning, SRE is an engineering team. And when engineers are not running around putting fires off all day long, they get creative. Many interesting innovations come from SREs even when there is no requirement for them.

Write design documents Design documents are not only useful for writing software. Fleshing out the details of any system on paper is a very useful way to find problems early in the process, communicate with your team exactly what are you building, and convince them why it is a great idea.

Review your code, version your changes This is something that is ubiquitous at Google, and not exclusive to SRE: everything is committed into source control: big systems, small scripts, configuration files. It might not seem worth it at the beginning, but having complete history of all your production environment is invaluable. And with source control, another rule comes into play: no change is committed without first being reviewed by a peer. It can be frustrating having to find a reviewer and wait for the approval for every small change, and some times reviews will be suboptimal, but once you get used to it, the benefits greatly out-weights any annoyances.

Before touching, measure Monitoring is not only for sending alerts, it is an essential tool of SRE. It allows you to gauge your availability, evaluate trends, forecast growth, perform forensic analysis. Also very importantly, it should give you the data needed to take decisions based on reality and not on guesses. Before optimising, find really where the bottleneck is; do not decide which database instance to use until you saw the utilisation of the past few months, etc. And speaking of that... We really need to have a chat about your current monitoring system. But that's for another day.
I hope I did not bore you too much with these walls of text! Some people told me directly they were enjoying these posts, so soon I will be writing more about related topics. In particular I would like to write about modern monitoring and Prometheus. I would love to hear your comments, questions, and criticisms. Comment

Next.

Previous.