I had been thinking of doing a blog post on RCEP which China signed with 14 countries a week and a day back but this new story has broken and is being viraled a bit on the interwebs, especially twitter and is pretty much in our domain so thought would be better to do a blog post about it. Also, there is quite a lot packed so quite a bit of unpacking to do.
Whitehat, Greyhat and Blackhat
For those of you who may not, there are actually three terms especially in computer science that one comes across. Those are white hats, grey hats and black hats. Now clinically white hats are like the fiery angels or the good guys who basically take permissions to try and find out weakness in an application, program, website, organization and so on and so forth. A somewhat dated reference to hacker could be Sandra Bullock (The Net 1995) , Sneakers (1992), Live Free or Die Hard (2007) . Of the three one could argue that Sandra was actually into viruses which are part of computer security but still she showed some bad-ass skills, but then that is what actors are paid to do Sneakers was much more interesting for me because in that you got the best key which can unlock any lock, something like quantum computing is supposed to do. One could equate both the first movies in either as a White hat or a Grey hat . A Grey hat is more flexible in his/her moral values, and they are plenty of such people. For e.g. Julius Assange could be described as a Grey hat, but as you can see and understand those are moral issues.
A black hat on the other hand is one who does things for profit even if it harms the others. The easiest fictitious examples are all Die Hard series, all of them except the 4th one, all had bad guys or black hats. The 4th also had but is the odd one out as it had Matthew Farell (Justin Long) as a Grey hat hacker. In real life Kevin Mitnick, Kevin Poulsen, Robert Tappan Morris, George Hotz, Gary McKinnon are some examples of hackers, most of whom were black hats, most of them reformed into white hats and security specialists. There are many other groups and names but that perhaps is best for another day altogether.
Now why am I sharing this. Because in all of the above, the people who are using and working with the systems have better than average understanding of systems and they arguably would be better than most people at securing their networks, systems etc. but as we shall see in this case there has been lots of issues in the company.
WhiteHat Jr. and 300 Million Dollars
Before I start this, I would like to share that for me this suit in many ways seems to be similar to the suit filed against Krishnaraj Rao . Although the difference is that Krishnaraj Rao s case/suit is that it was in real estate while this one is in education although many things are similar to those cases but also differ in some obvious ways. For e.g. in the suit against Krishnaraj Rao, the plaintiff s first approached the High Court and then the Supreme Court. Of course Krishnaraj Rao won in the High Court and then in the SC plaintiff s agreed to Krishnaraj Rao s demands as they knew they could not win in SC. In that case, a compromise was reached by the plaintiff just before judgement was to be delivered.
In this case, the plaintiff have directly approached the Delhi High Court. The charges against Mr. Poonia (the defendant in this case) are very much similar to those which were made in Krishnaraj Rao s suit hence won t be going into those details. They have claimed defamation and filed a 20 crore suit. The idea is basically to silence any whistle-blowers.
Fictional Character Wolf Gupta
The first issue in this case or perhaps one of the most famous or infamous character is an unknown. While he has been reportedly hired by Google India, BJYU, Chandigarh. This has been reported by Yahoo News. I did a cursory search on LinkedIn to see if there indeed is a wolf gupta but wasn t able to find any person with such a name. I am not even talking the amount of money/salary the fictitious gentleman is supposed to have got and the various variations on the salary figures at different times and the different ads.
If I wanted to, I could have asked few of the kind souls whom I know are working in Google to see if they can find such a person using their own credentials but it probably would have been a waste of time. When you show a LinkedIn profile in your social media, it should come up in the results, in this case it doesn t. I also tried to find out if somehow BJYU was a partner to Google and came up empty there as well. There is another story done by Kan India but as I m not a subscriber, I don t know what they have written but the beginning of the story itself does not bode well.
While I can understand marketing, there is a line between marketing something and being misleading. At least to me, all of the references shared seems misleading at least to me.
Taking down dissent
One of the big no-nos at least from what I perceive, you cannot and should not take down dissent or critique. Indians, like most people elsewhere around the world, critique and criticize day and night. Social media like twitter, mastodon and many others would not exist in the place if criticisms are not there. In fact, one could argue that Twitter and most social media is used to drive engagements to a person, brand etc. It is even an official policy in Twitter. Now you can t drive engagements without also being open to critique and this is true of all the web, including of WordPress and me . What has been happening is that whitehatjr with help of bjyu have been taking out content of people citing copyright violation which seems laughable.
When citizens critique anything, we are obviously going to take the name of the product otherwise people would have to start using new names similar to how Tom Riddle was known as Dark Lord , Voldemort and He who shall not be named . There have been quite a few takedowns, I just provide one for reference, the rest of the takedowns would probably come in the ongoing suit/case.
Whitehat Jr. ad showing investors fighting Now a brief synopsis of what the ad. is about. The ad is about a kid named Chintu who makes an app. The app. Is so good that investors come to his house and right in the lawn and start fighting each other. The parents are enjoying looking at the fight and to add to the whole thing there is also a nosy neighbor who has his own observations. Simply speaking, it is a juvenile ad but it works as most parents in India, as elsewhere are insecure.
Jihan critiquing the whitehatjr ad
Before starting, let me assure that I asked Jihan s parents if it s ok to share his ad on my blog and they agreed. What he has done is broken down the ad and showed how juvenile the ad is and using logic and humor as a template for the same. He does make sure to state that he does not know how the product is as he hasn t used it. His critique was about the ad and not the product as he hasn t used that.
The Website
If you look at the website, sadly, most of the site only talks about itself rather than giving examples that people can look in detail. For e.g. they say they have few apps. on Google play-store but no link to confirm the same. The same is true of quite a few other things. In another ad a Paralympic star says don t get into sports and get into coding. Which athlete in their right mind would say that? And it isn t that we (India) are brimming with athletes at the international level. In the last outing which was had in 2016, India sent a stunning 117 athletes but that was an exception as we had the women s hockey squad which was of 16 women, and even then they were overshadowed in numbers by the bureaucratic and support staff. There was criticism about the staff bit but that is probably a story for another date.
Most of the site doesn t really give much value and the point seems to be driving sales to their courses. This is pressurizing small kids as well as teenagers and better who are in the second and third year science-engineering whose parents don t get that it is advertising and it is fake and think that their kids are incompetent. So this pressurizes both small kids as well as those who are learning, doing in whatever college or educational institution . The teenagers more often than not are unable to tell/share with them that this is advertising and fake. Also most of us have been on a a good diet of ads. Fair and lovely still sells even though we know it doesn t work.
This does remind me of a similar fake academy which used very much similar symptoms and now nobody remembers them today. There used to be an academy called Wings Academy or some similar name. They used to advertise that you come to us and we will make you into a pilot or an airhostess and it was only much later that it was found out that most kids were doing laundry work in hotels and other such work. Many had taken loans, went bankrupt and even committed suicide because they were unable to pay off the loans due to the dreams given by the company and the harsh realities that awaited them. They were sued in court but dunno what happened but soon they were off the radar so we never came to know what happened to those million of kids whose life dreams were shattered.
Security
Now comes the security part. They have alleged that Mr. Poonia broke into their systems. While this may be true, what I find funny is that with the name Whitehat, how can they justify it? If you are saying you are white hat you are supposed to be much better than this. And while I have not tried to penetrate their systems, I did find it laughable that the site is using an expired https:// certificate. I could have tried further to figure out the systems but I chose not to. How they could not have an automated script to get the certificate fixed is beyond me, this is known as certificate outage and is very well understood in the industry. There are tools like Let s Encrypt and Certbot (both EFF) and many others. But that is their concern, not mine.
Comparison
A similar offering would be unacademy but as can be seen they neither try to push you in any way and nor do they make any ridiculous claims. In fact how genuine unacademy is can be gauged from the fact that many of its learning resources are available to people to see on YT and if they have tools they can also download it. Now, does this mean that every educational website should have their content for free, of course not. But when a channel has 80% 90% of it YT content as ads and testimonials then they surely should give a reason to pause both for parents and students alike. But if parents had done that much research, then things would not be where they are now.
Allegations
Just to complete, there are allegations by Mr. Poonia with some screenshots which show the company has been doing a lot of bad things. For e.g. they were harassing an employee at night 2 a.m. who was frustrated and working in the company at the time. Many of the company staff routinely made sexist and offensive, sexual abusive remarks privately between themselves for prospective women who came to interview via webcam (due to the pandemic). There also seems to be a bit of porn on the web/mobile server of the company as well. There also have been allegations that while the company says refund is done next day, many parents who have demanded those refunds have not got it. Now while Mr. Poonia has shared some quotations of the staff while hiding the identities of both the victims and the perpetrators, the language being used in itself tells a lot. I am in two minds whether to share those photos or not hence atm choosing not to. Poonia has also contended that all teachers do not know programming, and they are given scripts to share. There have been some people who did share that experience with him
Suruchi Sethi
From the company s side they are alleging he has hacked the company servers and would probably be using the Fruit of the poisonous tree argument which we have seen have been used in many arguments.
Conclusion
Now that lies in the eyes of the Court whether the single bench chooses the literal meaning or use the spirit of the law or the genuine concerns of the people concerned. While in today s hearing while the company asked for a complete sweeping injunction they were unable to get it. Whatever may happen, we may hope to see some fireworks in the second hearing which is slated to be on 6.01.2021 where all of this plays out. Till later.
By essence, QSoas works with \(y = f(x)\) datasets. However, in practice, when working with experimental data (or data generated from simulations), one has often more than one experimental parameter (\(x\)). For instance, one could record series of spectra (\(A = f(\lambda)\)) for different pH values, so that the absorbance is in fact a function of both the pH and \(\lambda\). QSoas has different ways to deal with such situations, and we'll describe one today, using meta-data.
Setting meta-data
Meta-data are simply series of name/values attached to a dataset. It can be numbers, dates or just text. Some of these are automatically detected from certain type of data files (but that is the topic for another day). The simplest way to set meta-data is to use the set-meta command:
QSoas> set-meta pH 7.5
This command sets the meta-data pH to the value 7.5. Keep in mind that QSoas does not know anything about the meaning of the meta-data[1]. It can keep track of the meta-data you give, and manipulate them, but it will not interpret them for you. You can set several meta-data by repeating calls to set-meta, and you can display the meta-data attached to a dataset using the command show. Here is an example:
Note here the use of quotes around My sample since there is a space inside the value.
Using meta-data
There are many ways to use meta-data in QSoas. In this post, we will discuss just one: using meta-data in the output file. The output file can collect data from several commands, like peak data, statistics and so on. For instance, each time the command 1 is run, a line with the information about the largest peak of the current dataset is written to the output file. It is possible to automatically add meta-data to those lines by using the /meta= option of the output command. Just listing the names of the meta-data will add them to each line of the output file.
As a full example, we'll see how one can take advantage of meta-data to determine the position of the peak of the function \(x^2 \exp (-a\,x)\) depends on \(a\). For that, we first create a script that generates the function for a certain value of \(a\), sets the meta-data a to the corresponding value, and find the peak. Let's call this file do-one.cmds (all the script files can be found in the GitHub repository):
This script takes a single argument, the value of \(a\), generates the appropriate dataset, sets the meta-data a and writes the data about the largest (and only in this case) peak to the output file. Let's now run this script with 1 as an argument:
QSoas> @ do-one.cmds 1
This command generates a file out.dat containing the following data:
## buffer       what    x       y       index   width   left_width      right_width     area
generated.dat   max     2.002002002     0.541340590883  100     3.4034034034    1.24124124124   2.162162162161.99999908761
This gives various information about the peak found: the name of the dataset it was found in, whether it's a maximum or minimum, the x and y positions of the peak, the index in the file, the widths of the peak and its area. We are interested here mainly in the x position.
Then, we just run this script for several values of \(a\) using run-for-each, and in particular the option /range-type=lin that makes it interpret values like 0.5..5:80 as 80 values evenly spread between 0.5 and 5. The script is called run-all.cmds:
output peaks.dat /overwrite=true /meta=a
run-for-each do-one.cmds /range-type=lin 0.5..5:80
V all /style=red-to-blue
The first line sets up the output to the output file peaks.dat. The option /meta=a makes sure the meta a is added to each line of the output file, and /overwrite=true make sure the file is overwritten just before the first data is written to it, in order to avoid accumulating the results of different runs of the script. The last line just displays all the curves with a color gradient. It looks like this:
Running this script (with @ run-all.cmds) creates a new file peaks.dat, whose first line looks like this:
## buffer what x y index width left_width right_width area a
The column x (the 3rd) contains the position of the peaks, and the column a (the 10th) contains the meta a (this column wasn't present in the output we described above, because we had not used yet the output /meta=a command). Therefore, to load the peak position as a function of a, one has just to run:
QSoas> load peaks.dat /columns=10,3
This looks like this:
Et voil !
To train further, you can:
improve the resolution in x;
improve the resolution in y;
plot the magnitude of the peak;
extend the range;
derive the analytical formula for the position of the peak and verify it !
[1] this is not exactly true. For instance, some commands like unwrap interpret the sr meta-data as a voltammetric scan rate if it is present. But this is the exception.
About QSoasQSoas is a powerful open source data analysis program that focuses on flexibility and powerful fitting capacities. It is released under the GNU General Public License. It is described in Fourmond, Anal. Chem., 2016, 88 (10), pp 5050 5052. Current version is 2.2. You can download its source code there (or clone from the GitHub repository) and compile it yourself, or buy precompiled versions for MacOS and Windows there.
Twice this week I was asked how it can be okay to work on free software when there are issues like climate change and racial injustice. I have a few answers for that.
You can work on injustice while working on free software.
A world in which all technology is just cannot exist under capitalism. It cannot exist under racism or sexism or ableism. It cannot exist in a world that does not exist if we are ravaged by the effects of climate change. At the same time, free software is part of the story of each of these. The modern technology state fuels capitalism, and capitalism fuels it. It cannot exist without transparency at all levels of the creation process. Proprietary software and algorithms reinforce racial and gender injustice. Technology is very guilty of its contributions to the climate crisis. By working on making technology more just, by making it more free, we are working to address these issues. Software makes the world work, and oppressive software creates an oppressive world.
You can work on free software while working on injustice.
Let s say you do want to devote your time to working on climate justice full time. Activism doesn t have to only happen in the streets or in legislative buildings. Being a body in a protest is activism, and so is running servers for your community s federated social network, providing wiki support, developing custom software, and otherwise bringing your free software skills into new environments. As long as your work is being accomplished under an ethos of free software, with free software, and under free software licenses, you re working on free software issues while saving the world in other ways too!
Not everyone needs to work on everything all the time.
When your house in on fire, you need to put out the fire. However, maybe you can t help put out the first. Maybe You don t have the skills or knowledge or physical ability. Maybe your house is on fire, but there s also an earthquake and a meteor and a airborn toxic event all coming at once. When that happens, we have to split up our efforts and that s okay.
One of the most interesting (and possibly unknown) features of the nftables framework is the native
python interface, which allows python programs to access all nft features programmatically, from
the source code.
There is a high-level library, libnftables, which is responsible for translating the human-readable
syntax from the nft binary into low-level expressions that the nf_tables kernel subsystem can
run. The nft command line utility basically wraps this library, where all actual nftables logic
lives. You can only imagine how powerful this library is. Originally written in C, ctypes is used
to allow native wrapping of the shared lib object using pure python.
To use nftables in your python script or program, first you have to install the libnftables library
and the python bindings. In Debian systems, installing the python3-nftables package should be
enough to have everything ready to go.
To interact with libnftables you have 2 options, either use the standard nft syntax or the JSON
format. The standard format allows you to send commands exactly like you would do using the nft
binary. That format is intended for humans and it doesn t make a lot of sense in a programmatic
interaction. Whereas JSON is pretty convenient, specially in a python environment, where there
are direct data structure equivalents.
The following code snippet gives you an example of how easy this is to use:
This is functionally equivalent to running nft -j list ruleset. Basically, all you have to do in
your python code is:
import the nftables & json modules
init the libnftables instance
configure library behavior
run commands and parse the output (ideally using JSON)
The key here is to use the JSON format. It allows adding ruleset modification in batches, i.e.
to create tables, chains, rules, sets, stateful counters, etc in a single atomic transaction, which
is the proper way to update firewalling and NAT policies in the kernel and to avoid inconsistent
intermediate states.
The JSON schema is pretty well documented in the libnftables-json(5) manpage.
The following example is copy/pasted from there, and illustrates the basic idea behind the JSON
format. The structure accepts an arbitrary amount of commands which are interpreted in order of
appearance. For instance, the following standard syntax input:
I encourage you to take a look at the manpage if you want to know about how powerful this interface
is. I ve created a git repository to host several source code examples using different features of
the library: https://github.com/aborrero/python-nftables-tutorial. I plan to introduce
more code examples as I learn and create them.
There are several relevant projects out there using this nftables python integration already. One
of the most important pieces of software is firewalld. They
started using the JSON format back in 2019.
In the past, people interacting with iptables programmatically would either call the iptables
binary directly or, in the case of some C programs, hack libiptc/libxtables libraries into their
source code. The native python approach to use libnftables is a huge step forward, which should
come handy for developers, network engineers, integrators and other folks using the nftables
framework in a pythonic environment.
If you are interested to know how this python binding works, I invite you to take a look at the
upstream source code, nftables.py, which contains all the magic behind the scenes.
Welcome to gambaru.de. Here is my monthly report (+ the first week in November) that covers what I have been doing for Debian. If you re interested in Java, Games and LTS topics, this might be interesting for you.
Debian Games
I released a new version of debian-games, a collection of metapackages for games. As expected the Python 2 removal takes its toll on games in Debian that depend on pygame or other Python 2 libraries. Currently we have lost more games in 2020 than could be newly introduced to the archive. All in all it could be better but also a lot worse.
New upstream releases were packaged for freeorion and xaos.
Most of the time was spent on upgrading the bullet physics library to version 3.06, testing all reverse-dependencies and requesting a transition for it. (#972395) Similar to bullet I also updated box2d, the 2D counterpart. The only reverse-dependency, caveexpress fails to build from source with box2d 2.4.1, so unless I can fix it, it doesn t make much sense to upload the package to unstable.
Some package polishing: I could fix two bugs in stormbaancoureur, patch by Helmut Grohne, and ardentryst that required a dependency on python3-future to start.
I sponsored mgba and pekka-kana-2 for Ryan Tandy and Carlos Donizete Froes
and started to work on porting childsplay to Python 3.
Finally I did a NMU for bygfoot to work around a GCC 10 FTBFS.
Debian Java
I uploaded pdfsam and its related sejda libraries to unstable and applied an upstream patch to fix an error with Debian s jackson-jr version. Everything should be usable and up-to-date now.
I updated mina2 and investigated a related build failure in apache-directory-server, packaged a new upstream release of commons-io and undertow and fixed a security vulnerability in junit4 by upgrading to version 4.13.1.
The upgrade of jflex to version 1.8.2 took a while. The package is available in experimental now but regression tests with ratt showed, that several reverse-dependencies FTBFS with 1.8.2. Since all of these projects work fine with 1.7.0, I intend to postpone the upload to unstable. No need to break something.
Misc
This month also saw new upstream versions of wabt and binaryen.
I intend to update ublock-origin in Buster but I haven t heard back from the release team yet. (#973695)
Debian LTS
This was my 56. month as a paid contributor and I have been paid to work 20,75 hours on Debian LTS, a project started by Rapha l Hertzog. In that time I did the following:
DLA-2440-1. Issued a security update for poppler fixing 9 CVE.
DLA-2445-1. Issued a security update for libmaxminddb fixing 1 CVE.
DLA-2447-1. Issued a security update for pacemaker fixing 1 CVE. The update had to be reverted because of an unexpected permission problem. I am in contact with one of the users who reported the regression and my intention is to update pacemaker to the latest supported release in the 1.x branch. If further tests show no regressions anymore, a new update will follow shortly.
Investigated CVE-2020-24614 in fossil and marked the issue as no-dsa because the impact for Debian users was low.
Investigated the open security vulnerabilities in ansible (11) and prepared some preliminary patches. The work is ongoing.
Fixed the remaining zsh vulnerabilities in Stretch in line with Debian 8 Jessie , so that all versions in Debian are equally protected.
ELTS
Extended Long Term Support (ELTS) is a project led by Freexian to further extend the lifetime of Debian releases. It is not an official Debian project but all Debian users benefit from it without cost. The current ELTS release is Debian 8 Jessie . This was my 29. month and I have been paid to work 15 hours on ELTS.
ELA-302-1. Issued a security update for poppler fixing 2 CVE. Investigated Debian bug #942391, identified the root cause and reverted the patch for CVE-2018-13988.
ELA-303-1. Issued a security update for junit4 fixing 1 CVE.
ELA-316-1. Issued a security update for zsh fixing 7 CVE.
As every C and C++ programmer knows far too well, if you dereference a
pointer that points outside of the space mapped on your process'
memory, you get a segmentation fault and your programs crashes. As far
as the language itself is concerned, you don't have a second chance
and you cannot know in advance whether that dereferencing operation is
going to set a bomb off or not. In technical terms, you are invoking
undefined behaviour, and you should never do that: you are
responsible for knowing in advance if your pointers are valid, and if
they are not you keep the pieces.
However, turns out that most actual operating system give you a second
chance, although with a lot of fine print attached. So I tried to
implement a function that tries to dereference a pointer: if it can,
it gives you the value; if it can't, it tells you it couldn't. Again,
I stress this should never happen in a real program, except possibly
for debugging (or for having fun).
The prototype is
word_tpeek(word_t*addr,int*success);
The function is basically equivalent to return *addr, except that if
addr is not mapped it doesn't crash, and if success is not NULL it
is set to 0 or 1 to indicate that addr was not mapped or
mapped. If addr was not mapped the return value is meaningless.
I won't explain it in detail to leave you some fun. Basically the idea
is to install a handler for SIGSEGV: if the address is invalid, the
handler is called, which basically fixes everything by advancing a
little bit the instruction pointer, in order to skip the faulting
instruction. The dereferencing instruction is written as hardcoded
Assembly bytes, so that I know exactly how many bytes I need to skip.
Of course this is very architecture-dependent: I wrote the i386 and
amd64 variants (no x32). And I don't guarantee there are no bugs
or subtelties!
Another solution would have been to just parse /proc/self/maps
before dereferencing and check whether the pointer is in a mapped
area, but it would have suffered of a
TOCTTOU
problem: another thread might have changed the mappings between the
time when /proc/self/maps was parsed and when the pointer was
dereferenced (also, parsing that file can take a relatively long
amount of time). Another less architecture-dependent but still not
pure-C approach would have been to establish a setjmp before
attempting the dereference and longjmp-ing back from the signal
handler (but again you would need to use different setjmp contexts
in different threads to exclude race conditions).
Have fun! (and again, don't try this in real programs)
EDIT I realized I should specify the language for source code
highlighting to work decently. Now it's better!
EDIT 2 I also realized that my version of peek has problems when
there are other threads, because signal actions are per-process, not
per-thread (as I initially thought). See the comments for a better
version (though not perfect).
This post is hard to write, both in the emotional sense but also in the I would
have written a shorter letter, but I didn t have the time sense. Hence, please
assume the best of intentions when reading it it is not my intention to make
anyone feel bad about their contributions, but rather to provide some insight
into why my frustration level ultimately exceeded the threshold.
Debian has been in my life for well over 10 years at this point.
A few weeks ago, I have visited some old friends at the Z rich Debian meetup
after a multi-year period of absence. On my bike ride home, it occurred to me
that the topics of our discussions had remarkable overlap with my last visit. We
had a discussion about the merits of systemd, which took a detour to respect in
open source communities, returned to processes in Debian and eventually
culminated in democracies and their theoretical/practical failings. Admittedly,
that last one might be a Swiss thing.
I say this not to knock on the Debian meetup, but because it prompted me to
reflect on what feelings Debian is invoking lately and whether it s still a good
fit for me.
So I m finally making a decision that I should have made a long time ago: I am
winding down my involvement in Debian to a minimum.
What does this mean?
Over the coming weeks, I will:
transition packages to be team-maintained where it makes sense
remove myself from the Uploaders field on packages with other maintainers
orphan packages where I am the sole maintainer
I will try to keep up best-effort maintenance of the
manpages.debian.org service and the
codesearch.debian.net service, but any help
would be much appreciated.
For all intents and purposes, please treat me as permanently on vacation. I will
try to be around for administrative issues (e.g. permission transfers) and
questions addressed directly to me, permitted they are easy enough to answer.
Why?
When I joined Debian, I was still studying, i.e. I had luxurious amounts of
spare time. Now, over 5 years of full time work later, my day job taught me a
lot, both about what works in large software engineering projects and how I
personally like my computer systems. I am very conscious of how I spend the
little spare time that I have these days.
The following sections each deal with what I consider a major pain point, in no
particular order. Some of them influence each other for example, if changes
worked better, we could have a chance at transitioning packages to be more
easily machine readable.
Change process in Debian
The last few years, my current team at work conducted various smaller and larger
refactorings across the entire code base (touching thousands of projects), so we
have learnt a lot of valuable lessons about how to effectively do these
changes. It irks me that Debian works almost the opposite way in every regard. I
appreciate that every organization is different, but I think a lot of my points
do actually apply to Debian.
In Debian, packages are nudged in the right direction by a document called the
Debian Policy, or its programmatic
embodiment, lintian.
While it is great to have a lint tool (for quick, local/offline feedback), it is
even better to not require a lint tool at all. The team conducting the change
(e.g. the C++ team introduces a new hardening flag for all packages) should be
able to do their work transparent to me.
Instead, currently, all packages become lint-unclean, all maintainers need to
read up on what the new thing is, how it might break, whether/how it affects
them, manually run some tests, and finally decide to opt in. This causes a lot
of overhead and manually executed mechanical changes across packages.
Notably, the cost of each change is distributed onto the package maintainers in
the Debian model. At work, we have found that the opposite works better: if the
team behind the change is put in power to do the change for as many users as
possible, they can be significantly more efficient at it, which reduces the
total cost and time a lot. Of course, exceptions (e.g. a large project abusing a
language feature) should still be taken care of by the respective owners, but
the important bit is that the default should be the other way around.
Debian is lacking tooling for large changes: it is hard to programmatically
deal with packages and repositories (see the section below). The closest to
sending out a change for review is to open a bug report with an attached
patch. I thought the workflow for accepting a change from a bug report was too
complicated and started mergebot, but only Guido
ever signaled interest in the project.
Culturally, reviews and reactions are slow. There are no deadlines. I literally
sometimes get emails notifying me that a patch I sent out a few years ago (!!)
is now merged. This turns projects from a small number of weeks into many years,
which is a huge demotivator for me.
Interestingly enough, you can see artifacts of the slow online activity manifest
itself in the offline culture as well: I don t want to be discussing systemd s
merits 10 years after I first heard about it.
Lastly, changes can easily be slowed down significantly by holdouts who refuse
to collaborate. My canonical example for this is rsync, whose maintainer refused
my patches to make the package use debhelper purely out of personal preference.
Granting so much personal freedom to individual maintainers prevents us as a
project from raising the abstraction level for building Debian packages, which
in turn makes tooling harder.
How would things look like in a better world?
As a project, we should strive towards more unification. Uniformity still
does not rule out experimentation, it just changes the trade-off from easier
experimentation and harder automation to harder experimentation and easier
automation.
Our culture needs to shift from this package is my domain, how dare you
touch it to a shared sense of ownership, where anyone in the project can
easily contribute (reviewed) changes without necessarily even involving
individual maintainers.
Fragmented workflow and infrastructure
Debian generally seems to prefer decentralized approaches over centralized
ones. For example, individual packages are maintained in separate repositories
(as opposed to in one repository), each repository can use any SCM (git and svn
are common ones) or no SCM at all, and each repository can be hosted on a
different site. Of course, what you do in such a repository also varies subtly
from team to team, and even within teams.
In practice, non-standard hosting options are used rarely enough to not justify
their cost, but frequently enough to be a huge pain when trying to automate
changes to packages. Instead of using GitLab s API to create a merge request,
you have to design an entirely different, more complex system, which deals with
intermittently (or permanently!) unreachable repositories and abstracts away
differences in patch delivery (bug reports, merge requests, pull requests,
email, ).
Wildly diverging workflows is not just a temporary problem either. I
participated in long discussions about different git workflows during DebConf
13, and gather that there were similar discussions in the meantime.
Personally, I cannot keep enough details of the different workflows in my
head. Every time I touch a package that works differently than mine, it
frustrates me immensely to re-learn aspects of my day-to-day.
After noticing workflow fragmentation in the Go packaging team (which I
started), I tried fixing this with the workflow changes
proposal, but did not
succeed in implementing it. The lack of effective automation and slow pace of
changes in the surrounding tooling despite my willingness to contribute time and
energy killed any motivation I had.
Old infrastructure: package uploads
When you want to make a package available in Debian, you upload GPG-signed files
via anonymous FTP. There are several batch jobs (the queue daemon, unchecked,
dinstall, possibly others) which run on fixed schedules (e.g. dinstall runs
at 01:52 UTC, 07:52 UTC, 13:52 UTC and 19:52 UTC).
Depending on timing, I estimated that you might wait for over 7 hours (!!)
before your package is actually installable.
What s worse for me is that feedback to your upload is asynchronous. I like to
do one thing, be done with it, move to the next thing. The current setup
requires a many-minute wait and costly task switch for no good technical
reason. You might think a few minutes aren t a big deal, but when all the time I
can spend on Debian per day is measured in minutes, this makes a huge difference
in perceived productivity and fun.
The last communication I can find about speeding up this process is ganneff s
post from 2008.
How would things look like in a better world?
Anonymous FTP would be replaced by a web service which ingests my package and
returns an authoritative accept or reject decision in its response.
For accepted packages, there would be a status page displaying the build
status and when the package will be available via the mirror network.
Packages should be available within a few minutes after the build completed.
Old infrastructure: bug tracker
I dread interacting with the Debian bug
tracker. debbugs is a piece of software
(from 1994) which is only used by Debian and the GNU project these days.
Debbugs processes emails, which is to say it is asynchronous and cumbersome to
deal with. Despite running on the fastest machines we have available in Debian
(or so I was told when the subject last came up), its web interface loads very
slowly.
Notably, the web interface at bugs.debian.org is read-only. Setting up a working
email setup for
reportbug(1)
or manually dealing with attachments is a rather big hurdle.
For reasons I don t understand, every interaction with debbugs results in many
different email threads.
Aside from the technical implementation, I also can never remember the different
ways that Debian uses pseudo-packages for bugs and processes. I need them rarely
enough to establish a mental model of how they are set up, or working memory of
how they are used, but frequently enough to be annoyed by this.
How would things look like in a better world?
Debian would switch from a custom bug tracker to a (any) well-established
one.
Debian would offer automation around processes. It is great to have a
paper-trail and artifacts of the process in the form of a bug report, but the
primary interface should be more convenient (e.g. a web form).
Old infrastructure: mailing list archives
It baffles me that in 2019, we still don t have a conveniently browsable
threaded archive of mailing list discussions. Email and threading is more widely
used in Debian than anywhere else, so this is somewhat
ironic. Gmane used to paper over this
issue, but Gmane s availability over the last few years has been spotty, to say
the least (it is down as I write this).
I tried to contribute a threaded list archive, but our listmasters didn t seem
to care or want to support the project.
Debian is hard to machine-read
While it is obviously possible to deal with Debian packages programmatically,
the experience is far from pleasant. Everything seems slow and cumbersome. I
have picked just 3 quick examples to illustrate my point.
debiman needs help from
piuparts in analyzing the
alternatives mechanism of each package to display the manpages of
e.g. psql(1). This
is because maintainer scripts modify the alternatives database by calling shell
scripts. Without actually installing a package, you cannot know which changes it
does to the alternatives database.
pk4 needs to maintain its own cache to look up
package metadata based on the package name. Other tools parse the apt database
from scratch on every invocation. A proper database format, or at least a binary
interchange format, would go a long way.
Debian Code Search wants to ingest new
packages as quickly as possible. There used to be a
fedmsg instance for Debian, but it no
longer seems to exist. It is unclear where to get notifications from for new
packages, and where best to fetch those packages.
Complicated build stack
See my Debian package build tools post. It
really bugs me that the sprawl of tools is not seen as a problem by others.
Developer experience pretty painful
Most of the points discussed so far deal with the experience in developing
Debian, but as I recently described in my post Debugging experience in
Debian , the experience when
developing using Debian leaves a lot to be desired, too.
I have more ideas
At this point, the article is getting pretty long, and hopefully you got a rough
idea of my motivation.
While I described a number of specific shortcomings above, the final nail in the
coffin is actually the lack of a positive outlook. I have more ideas that seem
really compelling to me, but, based on how my previous projects have been going,
I don t think I can make any of these ideas happen within the Debian project.
I intend to publish a few more posts about specific ideas for improving
operating systems here. Stay tuned.
Lastly, I hope this post inspires someone, ideally a group of people, to improve
the developer experience within Debian.
I measured how long the most popular Linux distribution s package manager take
to install small and large packages (the
ack(1p) source code search Perl script
and qemu, respectively).
Where required, my measurements include metadata updates such as transferring an
up-to-date package list. For me, requiring a metadata update is the more common
case, particularly on live systems or within Docker containers.
All measurements were taken on an Intel(R) Core(TM) i9-9900K CPU @ 3.60GHz
running Docker 1.13.1 on Linux 4.19, backed by a Samsung 970 Pro NVMe drive
boasting many hundreds of MB/s write performance. The machine is located in
Z rich and connected to the Internet with a 1 Gigabit fiber connection, so the
expected top download speed is 115 MB/s.
See Appendix C for details on the measurement method and command
outputs.
Measurements
Keep in mind that these are one-time measurements. They should be indicative of
actual performance, but your experience may vary.
ack (small Perl program)
distribution
package manager
data
wall-clock time
rate
Fedora
dnf
114 MB
33s
3.4 MB/s
Debian
apt
16 MB
10s
1.6 MB/s
NixOS
Nix
15 MB
5s
3.0 MB/s
Arch Linux
pacman
6.5 MB
3s
2.1 MB/s
Alpine
apk
10 MB
1s
10.0 MB/s
qemu (large C program)
distribution
package manager
data
wall-clock time
rate
Fedora
dnf
226 MB
4m37s
1.2 MB/s
Debian
apt
224 MB
1m35s
2.3 MB/s
Arch Linux
pacman
142 MB
44s
3.2 MB/s
NixOS
Nix
180 MB
34s
5.2 MB/s
Alpine
apk
26 MB
2.4s
10.8 MB/s
(Looking for older measurements? See Appendix B (2019).
The difference between the slowest and fastest package managers is 30x!
How can Alpine s apk and Arch Linux s pacman be an order of magnitude faster
than the rest? They are doing a lot less than the others, and more efficiently,
too.
Pain point: too much metadata
For example, Fedora transfers a lot more data than others because its main
package list is 60 MB (compressed!) alone. Compare that with Alpine s 734 KB
APKINDEX.tar.gz.
Of course the extra metadata which Fedora provides helps some use case,
otherwise they hopefully would have removed it altogether. The amount of
metadata seems excessive for the use case of installing a single package, which
I consider the main use-case of an interactive package manager.
I expect any modern Linux distribution to only transfer absolutely required
data to complete my task.
Pain point: no concurrency
Because they need to sequence executing arbitrary package maintainer-provided
code (hooks and triggers), all tested package managers need to install packages
sequentially (one after the other) instead of concurrently (all at the same
time).
In my blog post Can we do without hooks and
triggers? , I outline that hooks and
triggers are not strictly necessary to build a working Linux distribution.
Thought experiment: further speed-ups
Strictly speaking, the only required feature of a package manager is to make
available the package contents so that the package can be used: a program can be
started, a kernel module can be loaded, etc.
By only implementing what s needed for this feature, and nothing more, a package
manager could likely beat apk s performance. It could, for example:
skip archive extraction by mounting file system images (like AppImage or snappy)
use compression which is light on CPU, as networks are fast (like apk)
skip fsync when it is safe to do so, i.e.:
package installations don t modify system state
atomic package installation (e.g. an append-only package store)
automatically clean up the package store after crashes
Conclusion
As per the current landscape, there is no
distribution-scoped package manager which uses images and leaves out hooks and
triggers, not even in smaller Linux distributions.
I think that space is really interesting, as it uses a minimal design to achieve
significant real-world speed-ups.
I have explored this idea in much more detail, and am happy to talk more about
it in my post Introducing the distri research linux distribution".
Appendix A: related work
There are a couple of recent developments going into the same direction:
NixOS s Nix takes a little over 5s to fetch and unpack 15 MB.
% docker run -t -i nixos/nix
39e9186422ba:/# time sh -c 'nix-channel --update && nix-env -iA nixpkgs.ack'
unpacking channels...
created 1 symlinks in user environment
installing 'perl5.32.0-ack-3.3.1'
these paths will be fetched (15.55 MiB download, 85.51 MiB unpacked):
  /nix/store/34l8jdg76kmwl1nbbq84r2gka0kw6rc8-perl5.32.0-ack-3.3.1-man
  /nix/store/9df65igwjmf2wbw0gbrrgair6piqjgmi-glibc-2.31
  /nix/store/9fd4pjaxpjyyxvvmxy43y392l7yvcwy1-perl5.32.0-File-Next-1.18
  /nix/store/czc3c1apx55s37qx4vadqhn3fhikchxi-libunistring-0.9.10
  /nix/store/dj6n505iqrk7srn96a27jfp3i0zgwa1l-acl-2.2.53
  /nix/store/ifayp0kvijq0n4x0bv51iqrb0yzyz77g-perl-5.32.0
  /nix/store/w9wc0d31p4z93cbgxijws03j5s2c4gyf-coreutils-8.31
  /nix/store/xim9l8hym4iga6d4azam4m0k0p1nw2rm-libidn2-2.3.0
  /nix/store/y7i47qjmf10i1ngpnsavv88zjagypycd-attr-2.4.48
  /nix/store/z45mp61h51ksxz28gds5110rf3wmqpdc-perl5.32.0-ack-3.3.1
copying path '/nix/store/34l8jdg76kmwl1nbbq84r2gka0kw6rc8-perl5.32.0-ack-3.3.1-man' from 'https://cache.nixos.org'...
copying path '/nix/store/czc3c1apx55s37qx4vadqhn3fhikchxi-libunistring-0.9.10' from 'https://cache.nixos.org'...
copying path '/nix/store/9fd4pjaxpjyyxvvmxy43y392l7yvcwy1-perl5.32.0-File-Next-1.18' from 'https://cache.nixos.org'...
copying path '/nix/store/xim9l8hym4iga6d4azam4m0k0p1nw2rm-libidn2-2.3.0' from 'https://cache.nixos.org'...
copying path '/nix/store/9df65igwjmf2wbw0gbrrgair6piqjgmi-glibc-2.31' from 'https://cache.nixos.org'...
copying path '/nix/store/y7i47qjmf10i1ngpnsavv88zjagypycd-attr-2.4.48' from 'https://cache.nixos.org'...
copying path '/nix/store/dj6n505iqrk7srn96a27jfp3i0zgwa1l-acl-2.2.53' from 'https://cache.nixos.org'...
copying path '/nix/store/w9wc0d31p4z93cbgxijws03j5s2c4gyf-coreutils-8.31' from 'https://cache.nixos.org'...
copying path '/nix/store/ifayp0kvijq0n4x0bv51iqrb0yzyz77g-perl-5.32.0' from 'https://cache.nixos.org'...
copying path '/nix/store/z45mp61h51ksxz28gds5110rf3wmqpdc-perl5.32.0-ack-3.3.1' from 'https://cache.nixos.org'...
building '/nix/store/m0rl62grplq7w7k3zqhlcz2hs99y332l-user-environment.drv'...
created 49 symlinks in user environment
real	0m 5.60s
user	0m 3.21s
sys	0m 1.66s
Debian s apt takes almost 10 seconds to fetch and unpack 16 MB.
% docker run -t -i debian:sid
root@1996bb94a2d1:/# time (apt update && apt install -y ack-grep)
Get:1 http://deb.debian.org/debian sid InRelease [146 kB]
Get:2 http://deb.debian.org/debian sid/main amd64 Packages [8400 kB]
Fetched 8546 kB in 1s (8088 kB/s)
[ ]
The following NEW packages will be installed:
  ack libfile-next-perl libgdbm-compat4 libgdbm6 libperl5.30 netbase perl perl-modules-5.30
0 upgraded, 8 newly installed, 0 to remove and 23 not upgraded.
Need to get 7341 kB of archives.
After this operation, 46.7 MB of additional disk space will be used.
[ ]
real	0m9.544s
user	0m2.839s
sys	0m0.775s
Arch Linux s pacman takes a little under 3s to fetch and unpack 6.5 MB.
% docker run -t -i archlinux/base
[root@9f6672688a64 /]# time (pacman -Sy && pacman -S --noconfirm ack)
:: Synchronizing package databases...
 core            130.8 KiB  1090 KiB/s 00:00
 extra          1655.8 KiB  3.48 MiB/s 00:00
 community         5.2 MiB  6.11 MiB/s 00:01
resolving dependencies...
looking for conflicting packages...
Packages (2) perl-file-next-1.18-2  ack-3.4.0-1
Total Download Size:   0.07 MiB
Total Installed Size:  0.19 MiB
[ ]
real	0m2.936s
user	0m0.375s
sys	0m0.160s
Alpine s apk takes a little over 1 second to fetch and unpack 10 MB.
NixOS s Nix takes almost 34s to fetch and unpack 180 MB.
% docker run -t -i nixos/nix
83971cf79f7e:/# time sh -c 'nix-channel --update && nix-env -iA nixpkgs.qemu'
unpacking channels...
created 1 symlinks in user environment
installing 'qemu-5.1.0'
these paths will be fetched (180.70 MiB download, 1146.92 MiB unpacked):
[ ]
real	0m 33.64s
user	0m 16.96s
sys	0m 3.05s
Debian s apt takes over 95 seconds to fetch and unpack 224 MB.
% docker run -t -i debian:sid
root@b7cc25a927ab:/# time (apt update && apt install -y qemu-system-x86)
Get:1 http://deb.debian.org/debian sid InRelease [146 kB]
Get:2 http://deb.debian.org/debian sid/main amd64 Packages [8400 kB]
Fetched 8546 kB in 1s (5998 kB/s)
[ ]
Fetched 216 MB in 43s (5006 kB/s)
[ ]
real	1m25.375s
user	0m29.163s
sys	0m12.835s
Arch Linux s pacman takes almost 44s to fetch and unpack 142 MB.
% docker run -t -i archlinux/base
[root@58c78bda08e8 /]# time (pacman -Sy && pacman -S --noconfirm qemu)
:: Synchronizing package databases...
 core          130.8 KiB  1055 KiB/s 00:00
 extra        1655.8 KiB  3.70 MiB/s 00:00
 community       5.2 MiB  7.89 MiB/s 00:01
[ ]
Total Download Size:   135.46 MiB
Total Installed Size:  661.05 MiB
[ ]
real	0m43.901s
user	0m4.980s
sys	0m2.615s
Alpine s apk takes only about 2.4 seconds to fetch and unpack 26 MB.
% docker run -t -i alpine
/ # time apk add qemu-system-x86_64
fetch http://dl-cdn.alpinelinux.org/alpine/v3.10/main/x86_64/APKINDEX.tar.gz
fetch http://dl-cdn.alpinelinux.org/alpine/v3.10/community/x86_64/APKINDEX.tar.gz
[ ]
OK: 78 MiB in 95 packages
real	0m 2.43s
user	0m 0.46s
sys	0m 0.09s
Appendix B: measurement details (2019)
ack
You can expand each of these:
Fedora s dnf takes almost 30 seconds to fetch and unpack 107 MB.
% docker run -t -i nixos/nix
39e9186422ba:/# time sh -c 'nix-channel --update && nix-env -i perl5.28.2-ack-2.28'
unpacking channels...
created 2 symlinks in user environment
installing 'perl5.28.2-ack-2.28'
these paths will be fetched (14.91 MiB download, 80.83 MiB unpacked):
  /nix/store/57iv2vch31v8plcjrk97lcw1zbwb2n9r-perl-5.28.2
  /nix/store/89gi8cbp8l5sf0m8pgynp2mh1c6pk1gk-attr-2.4.48
  /nix/store/gkrpl3k6s43fkg71n0269yq3p1f0al88-perl5.28.2-ack-2.28-man
  /nix/store/iykxb0bmfjmi7s53kfg6pjbfpd8jmza6-glibc-2.27
  /nix/store/k8lhqzpaaymshchz8ky3z4653h4kln9d-coreutils-8.31
  /nix/store/svgkibi7105pm151prywndsgvmc4qvzs-acl-2.2.53
  /nix/store/x4knf14z1p0ci72gl314i7vza93iy7yc-perl5.28.2-File-Next-1.16
  /nix/store/zfj7ria2kwqzqj9dh91kj9kwsynxdfk0-perl5.28.2-ack-2.28
copying path '/nix/store/gkrpl3k6s43fkg71n0269yq3p1f0al88-perl5.28.2-ack-2.28-man' from 'https://cache.nixos.org'...
copying path '/nix/store/iykxb0bmfjmi7s53kfg6pjbfpd8jmza6-glibc-2.27' from 'https://cache.nixos.org'...
copying path '/nix/store/x4knf14z1p0ci72gl314i7vza93iy7yc-perl5.28.2-File-Next-1.16' from 'https://cache.nixos.org'...
copying path '/nix/store/89gi8cbp8l5sf0m8pgynp2mh1c6pk1gk-attr-2.4.48' from 'https://cache.nixos.org'...
copying path '/nix/store/svgkibi7105pm151prywndsgvmc4qvzs-acl-2.2.53' from 'https://cache.nixos.org'...
copying path '/nix/store/k8lhqzpaaymshchz8ky3z4653h4kln9d-coreutils-8.31' from 'https://cache.nixos.org'...
copying path '/nix/store/57iv2vch31v8plcjrk97lcw1zbwb2n9r-perl-5.28.2' from 'https://cache.nixos.org'...
copying path '/nix/store/zfj7ria2kwqzqj9dh91kj9kwsynxdfk0-perl5.28.2-ack-2.28' from 'https://cache.nixos.org'...
building '/nix/store/q3243sjg91x1m8ipl0sj5gjzpnbgxrqw-user-environment.drv'...
created 56 symlinks in user environment
real	0m 14.02s
user	0m 8.83s
sys	0m 2.69s
Debian s apt takes almost 10 seconds to fetch and unpack 16 MB.
% docker run -t -i debian:sid
root@b7cc25a927ab:/# time (apt update && apt install -y ack-grep)
Get:1 http://cdn-fastly.deb.debian.org/debian sid InRelease [233 kB]
Get:2 http://cdn-fastly.deb.debian.org/debian sid/main amd64 Packages [8270 kB]
Fetched 8502 kB in 2s (4764 kB/s)
[ ]
The following NEW packages will be installed:
  ack ack-grep libfile-next-perl libgdbm-compat4 libgdbm5 libperl5.26 netbase perl perl-modules-5.26
The following packages will be upgraded:
  perl-base
1 upgraded, 9 newly installed, 0 to remove and 60 not upgraded.
Need to get 8238 kB of archives.
After this operation, 42.3 MB of additional disk space will be used.
[ ]
real	0m9.096s
user	0m2.616s
sys	0m0.441s
Arch Linux s pacman takes a little over 3s to fetch and unpack 6.5 MB.
% docker run -t -i archlinux/base
[root@9604e4ae2367 /]# time (pacman -Sy && pacman -S --noconfirm ack)
:: Synchronizing package databases...
 core            132.2 KiB  1033K/s 00:00
 extra          1629.6 KiB  2.95M/s 00:01
 community         4.9 MiB  5.75M/s 00:01
[ ]
Total Download Size:   0.07 MiB
Total Installed Size:  0.19 MiB
[ ]
real	0m3.354s
user	0m0.224s
sys	0m0.049s
Alpine s apk takes only about 1 second to fetch and unpack 10 MB.
% docker run -t -i alpine
/ # time apk add ack
fetch http://dl-cdn.alpinelinux.org/alpine/v3.10/main/x86_64/APKINDEX.tar.gz
fetch http://dl-cdn.alpinelinux.org/alpine/v3.10/community/x86_64/APKINDEX.tar.gz
(1/4) Installing perl-file-next (1.16-r0)
(2/4) Installing libbz2 (1.0.6-r7)
(3/4) Installing perl (5.28.2-r1)
(4/4) Installing ack (3.0.0-r0)
Executing busybox-1.30.1-r2.trigger
OK: 44 MiB in 18 packages
real	0m 0.96s
user	0m 0.25s
sys	0m 0.07s
qemu
You can expand each of these:
Fedora s dnf takes over a minute to fetch and unpack 266 MB.
% docker run -t -i nixos/nix
39e9186422ba:/# time sh -c 'nix-channel --update && nix-env -i qemu-4.0.0'
unpacking channels...
created 2 symlinks in user environment
installing 'qemu-4.0.0'
these paths will be fetched (262.18 MiB download, 1364.54 MiB unpacked):
[ ]
real	0m 38.49s
user	0m 26.52s
sys	0m 4.43s
Debian s apt takes 51 seconds to fetch and unpack 159 MB.
% docker run -t -i debian:sid
root@b7cc25a927ab:/# time (apt update && apt install -y qemu-system-x86)
Get:1 http://cdn-fastly.deb.debian.org/debian sid InRelease [149 kB]
Get:2 http://cdn-fastly.deb.debian.org/debian sid/main amd64 Packages [8426 kB]
Fetched 8574 kB in 1s (6716 kB/s)
[ ]
Fetched 151 MB in 2s (64.6 MB/s)
[ ]
real	0m51.583s
user	0m15.671s
sys	0m3.732s
Arch Linux s pacman takes 1m2s to fetch and unpack 124 MB.
% docker run -t -i archlinux/base
[root@9604e4ae2367 /]# time (pacman -Sy && pacman -S --noconfirm qemu)
:: Synchronizing package databases...
 core       132.2 KiB   751K/s 00:00
 extra     1629.6 KiB  3.04M/s 00:01
 community    4.9 MiB  6.16M/s 00:01
[ ]
Total Download Size:   123.20 MiB
Total Installed Size:  587.84 MiB
[ ]
real	1m2.475s
user	0m9.272s
sys	0m2.458s
Alpine s apk takes only about 2.4 seconds to fetch and unpack 26 MB.
% docker run -t -i alpine
/ # time apk add qemu-system-x86_64
fetch http://dl-cdn.alpinelinux.org/alpine/v3.10/main/x86_64/APKINDEX.tar.gz
fetch http://dl-cdn.alpinelinux.org/alpine/v3.10/community/x86_64/APKINDEX.tar.gz
[ ]
OK: 78 MiB in 95 packages
real	0m 2.43s
user	0m 0.46s
sys	0m 0.09s
See the Conclusion for a summary if you re impatient :-)
Motivation
Over the last few months, I have been developing a new index format for Debian
Code Search. This required a lot of careful refactoring, re-implementation,
debug tool creation and debugging.
Multiple factors motivated my work on a new index format:
The existing index format has a 2G size limit, into which we have bumped a
few times, requiring manual intervention to keep the system running.
Debugging the existing system required creating ad-hoc debugging tools, which
made debugging sessions unnecessarily lengthy and painful.
I wanted to check whether storing positions with the posting lists would
improve performance of identifier queries (= queries which are not using any
regular expression features), which make up 78.2% of all Debian Code Search
queries (it does).
I figured building a new index from scratch was the easiest approach, compared
to refactoring the existing index to increase the size limit (point ).
I also figured it would be a good idea to develop the debugging tool in lock
step with the index format so that I can be sure the tool works and is useful
(point ).
Integer compression: TurboPFor
As a quick refresher, search engines typically store document IDs (representing
source code files, in our case) in an ordered list ( posting list ). It usually
makes sense to apply at least a rudimentary level of compression: our existing
system used variable integer encoding.
TurboPFor, the self-proclaimed Fastest
Integer Compression library, combines an advanced on-disk format with a
carefully tuned SIMD implementation to reach better speeds (in micro benchmarks)
at less disk usage than Russ Cox s varint implementation in
github.com/google/codesearch.
If you are curious about its inner workings, check out my TurboPFor: an
analysis .
Applied on the Debian Code Search index, TurboPFor indeed compresses integers better:
Disk space
8.9G
codesearch varint index
5.5G
TurboPFor index
Switching to TurboPFor (via cgo) for storing and reading the index results in a
slight speed-up of a dcs replay benchmark, which is more pronounced the more
i/o is required.
Query speed (regexp, cold page cache)
18s
codesearch varint index
14s
TurboPFor index (cgo)
Query speed (regexp, warm page cache)
15s
codesearch varint index
14s
TurboPFor index (cgo)
Overall, TurboPFor is an all-around improvement in efficiency, albeit with a
high cost in implementation complexity.
Positional index: trade more disk for faster queries
This section builds on the previous section: all figures come from the TurboPFor
index, which can optionally support positions.
Conceptually, we re going from:
type docid uint32
type index map[trigram][]docid
to:
type occurrence struct
    doc docid
    pos uint32 // byte offset in doc

type index map[trigram][]occurrence
The resulting index consumes more disk space, but can be queried faster:
We can do fewer queries: instead of reading all the posting lists for all
the trigrams, we can read the posting lists for the query s first and last
trigram only.
This is one of the tricks described in the paper
AS-Index: A
Structure For String Search Using n-grams and Algebraic Signatures
(PDF), and goes a long way without incurring the complexity, computational
cost and additional disk usage of calculating algebraic signatures.
Verifying the delta between the last and first position matches the length
of the query term significantly reduces the number of files to read (lower
false positive rate).
The matching phase is quicker: instead of locating the query term in the
file, we only need to compare a few bytes at a known offset for equality.
More data is read sequentially (from the index), which is faster.
Disk space
A positional index consumes significantly more disk space, but not so much as
to pose a challenge: a Hetzner EX61-NVME dedicated server ( 64 /month)
provides 1 TB worth of fast NVMe flash storage.
6.5G
non-positional
123G
positional
93G
positional (posrel)
The idea behind the positional index (posrel) is to not store a (doc,pos)
tuple on disk, but to store positions, accompanied by a stream of doc/pos
relationship bits: 1 means this position belongs to the next document, 0 means
this position belongs to the current document.
This is an easy way of saving some space without modifying the TurboPFor
on-disk format: the posrel technique reduces the index size to about .
With the increase in size, the Linux page cache hit ratio will be lower for
the positional index, i.e. more data will need to be fetched from disk for
querying the index.
As long as the disk can deliver data as fast as you can decompress posting
lists, this only translates into one disk seek s worth of additional
latency. This is the case with modern NVMe disks that deliver thousands of MB/s,
e.g. the Samsung 960 Pro (used in Hetzner s aforementioned EX61-NVME server).
The values were measured by running dcs du -h /srv/dcs/shard*/full
without and with the -pos argument.
Bytes read
A positional index requires fewer queries: reading only the first and last
trigram s posting lists and positions is sufficient to achieve a lower (!) false
positive rate than evaluating all trigram s posting lists in a
non-positional index.
As a consequence, fewer files need to be read, resulting in fewer bytes required
to read from disk overall.
As an additional bonus, in a positional index, more data is read sequentially
(index), which is faster than random i/o, regardless of the underlying disk.
1.2G
19.8G
21.0G
regexp queries
4.2G (index)
10.8G (files)
15.0G
identifier queries
The values were measured by running iostat -d 25 just before running
bench.zsh
on an otherwise idle system.
Query speed
Even though the positional index is larger and requires more data to be read at
query time (see above), thanks to the C TurboPFor library, the 2 queries on a
positional index are roughly as fast as the n queries on a non-positional index
( 4s instead of 3s).
This is more than made up for by the combined i/o matching stage, which shrinks
from 18.5s (7.1s i/o + 11.4s matching) to 1.3s.
3.3s (index)
7.1s (i/o)
11.4s (matching)
21.8s
regexp queries
3.92s (index)
1.3s
5.22s
identifier queries
Note that identifier query i/o was sped up not just by needing to read fewer
bytes, but also by only having to verify bytes at a known offset instead of
needing to locate the identifier within the file.
Conclusion
The new index format is overall slightly more efficient. This disk space
efficiency allows us to introduce a positional index section for the first
time.
Most Debian Code Search queries are positional queries (78.2%) and will be
answered much quicker by leveraging the positions.
Bottomline, it is beneficial to use a positional index on disk over a
non-positional index in RAM.
I've make a presentation about "How to hack debexpo (mentors.debian.net)" at Tokyo Debian (local Debian meeting) 21, November 2020.
Here is the agenda about presentation.
In some ways it is sad and interesting to see how personal liberty is viewed in India. And how it differs from those having the highest fame and power can get a different kind of justice then the rest cannot.
Arnab Goswami
This particular gentleman is a class apart. He is the editor as well as Republic TV, a right-leaning channel which demonizes the minority, women whatever is antithesis to the Central Govt. of India. As a result there have been a spate of cases against him in the past few months. But surprisingly, in each of them he got hearing the day after the suit was filed. This is unique in Indian legal history so much so that a popular legal site which publishes on-going cases put up a post sharing how he was getting prompt hearings. That post itself needs to be updated as there have been 3 more hearings which have been done back to back for him. This is unusual as there have been so many cases pending for the SC attention, some arguably more important than this gentleman . So many precedents have been set which will send a wrong message. The biggest one, that even though a trial is taking place in the sessions court (below High Court) the SC can interject on matters. What this will do to the morale of both lawyers as well as judges of the various Sessions Court is a matter of speculation and yet as shared unprecedented. The saddest part was when Justice Chandrachud said
Justice Chandrachud If you don t like a channel then don t watch it. 11th November 2020 .
This is basically giving a free rope to hate speech. How can a SC say like that ? And this is the Same Supreme Court which could not take two tweets from Shri Prashant Bhushan when he made remarks against the judiciary .
J&K pleas in Supreme Court pending since August 2019 (Abrogation 370)
After abrogation of 370, citizens of Jammu and Kashmir, the population of which is 13.6 million people including 4 million Hindus have been stuck with reduced rights and their land being taken away due to new laws. Many of the Hindus which regionally are a minority now rue the fact that they supported the abrogation of 370A . Imagine, a whole state whose answers and prayers have not been heard by the Supreme Court and the people need to move a prayer stating the same.
100 Journalists, activists languishing in Jail without even a hearing
55 Journalists alone have been threatened, booked and in jail for reporting of pandemic . Their fault, they were bring the irregularities, corruption made during the pandemic early months. Activists such as Sudha Bharadwaj, who giving up her American citizenship and settling to fight for tribals is in jail for 2 years without any charges. There are many like her, There are several more petitions lying in the Supreme Court, for e.g. Varavara Rao, not a single hearing from last couple of years, even though he has taken part in so many national movements including the emergency as well as part-responsible for creation of Telengana state out of Andhra Pradesh .
Then there is Devangana kalita who works for gender rights. Similar to Sudha Bharadwaj, she had an opportunity to go to UK and settle here. She did her master s and came back. And now she is in jail for the things that she studied. While she took part in Anti-CAA sittings, none of her speeches were incendiary but she still is locked up under UAPA (Unlawful Practises Act) . I could go on and on but at the moment these should suffice.
Petitions for Hate Speech which resulted in riots in Delhi are pending, Citizen s Amendment Act (controversial) no hearings till date. All of the best has been explained in a newspaper article which articulates perhaps all that I wanted to articulate and more. It is and was amazing to see how in certain cases Article 32 is valid and in many it is not. Also a fair reading of Justice Bobde s article tells you a lot how the SC is functioning. I would like to point out that barandbench along with livelawindia makes it easier for never non-lawyers and public to know how arguments are done in court, what evidences are taken as well as give some clue about judicial orders and judgements. Both of these resources are providing an invaluable service and more often than not, free of charge.
Student Suicide and High Cost of Education
For quite sometime now, the cost of education has been shooting up. While I have visited this topic earlier as well, recently a young girl committed suicide because she was unable to pay the fees as well as additional costs due to pandemic. Further investigations show that this is the case with many of the students who are unable to buy laptops. Now while one could think it is limited to one college then it would be wrong. It is almost across all India and this will continue for months and years. People do know that the pandemic is going to last a significant time and it would be a long time before R value becomes zero . Even the promising vaccine from Pfizer need constant refrigeration which is sort of next to impossible in India. It is going to make things very costly.
Last Nail on Indian Media
Just today the last nail on India has been put. Thankfully Freedom Gazette India did a much better job so just pasting that
Information and Broadcasting Ministry bringing OTT services as well as news within its ambit.
With this, projects like Scam 1992, The Harshad Mehta Story or Bad Boy Billionaires:India, Test Case, Delhi Crime, Laakhon Mein Ek etc. etc. such kind of series, investigative journalism would be still-births. Many of these web-series also shared tales of woman empowerment while at the same time showed some of the hard choices that women had to contend to live with.
Even western media may be censored where it finds the political discourse not to its liking. There had been so many accounts of Mr. Ravish Kumar, the winner of Ramon Magsaysay, how in his shows the electricity was cut in many places. I too have been the victim when the BJP governed in Maharashtra as almost all Puneities experienced it. Light would go for just half or 45 minutes at the exact time.
There is another aspect to it. The U.S. elections showed how independent media was able to counter Mr. Trump s various falsehoods and give rise to alternative ideas which lead the team of Bernie Sanders, Joe Biden and Kamala Harris, Biden now being the President-elect while Kamala Harris being the vice-president elect. Although the journey to the white house seems as tough as before. Let s see what happens.
Hopefully 2021 will bring in some good news.
Update On 27th November 2020 Martin who runs the planet got an e-mail/notice by a Mr. Nikhil Sethi who runs the wikibio.com property. Mr. Sethi asked to remove the link pointing Devangana Kalita from my blog post to his site as he has used the no follow link. On inquiring further, the gentleman stated that it is an Updated mandate (his exact quote) from Google algorithm. To further understand the issue, I went to SERP as they are one of the more known ones on the subject. I also looked it up on Google as well. Found that the gentleman was BSing the whole time. The page basically talks about weightage of a page/site and authoritativeness which is known and yet highly contested ideas. In any case, the point for me was for whatever reason (could be fear, could be something else entirely), Mr. Sethi did not want me to link the content. Hence, I have complied above. I could have dragged it out but I do not wish Mr. Sethi any ill-being or/and further harm unduly and unintentionally caused by me. Hence, have taken down the link.
Technology must be transparent in order to be knowable. Technology must be knowable in order for us to be able to consent to it in good faith. Good faith informed consent is necessary to preserving our (digital) autonomy.
Let s now look at this in reverse, considering first why informed consent is necessary to our digital autonomy.
Let s take the concept of our digital autonomy as being one of the highest goods. It is necessary to preserve and respect the value of each individual, and the collectives we choose to form. It is a right to which we are entitled by our very nature, and a prerequisite for building the lives we want, that fulfill us. This is something that we have generally agreed on as important or even sacred. Our autonomy, in whatever form it takes, in whatever part of our life it governs, is necessary and must be protected.
One of the things we must do in order to accomplish this is to build a practice and culture of consent. Giving consent saying yes is not enough. This consent must come from a place of understand to that which one is consenting. Informed consent is consenting to the unknowable. (1)
Looking at sexual consent as a parallel, even when we have a partner who discloses their sexual history and activities, we cannot know whether they are being truthful and complete. Let s even say they are and that we can trust this, there is a limit to how much even they know about their body, health, and experience. They might not know the extent of their other partners experience. They might be carrying HPV without symptoms; we rarely test for herpes.
Arguably, we have more potential to definitely know what is occurring when it comes to technological consent. Technology can be broken apart. We can share and examine code, schematics, and design documentation. Certainly, lots of information is being hidden from us a lot of code is proprietary, technical documentation unavailable, and the skills to process these things is treated as special, arcane, and even magical. Tracing the resource pipelines for the minerals and metals essential to building circuit boards is not possible for the average person. Knowing the labor practices of each step of this process, and understanding what those imply for individuals, societies, and the environments they exist in seems improbable at best.
Even though true informed consent might not be possible, it is an ideal towards which we must strive. We must work with what we have, and we must be provided as much as possible.
A periodic conversation that arises in the consideration of technology rights is whether companies should build backdoors into technology for the purpose of government exploitation. A backdoor is a hidden vulnerability in a piece of technology that, when used, would afford someone else access to your device or work or cloud storage or whatever. As long as the source code that powers computing technology is proprietary and opaque, we cannot truly know whether backdoors exist and how secure we are in our digital spaces and even our own computers, phones, and other mobile devices.
We must commit wholly to transparency and openness in order to create the possibility of as-informed-as-possible consent in order to protect our digital autonomy. We cannot exist in a vacuum and practical autonomy relies on networks of truth in order to provide the opportunity for the ideal of informed consent. These networks of truth are created through the open availability and sharing of information, relating to how and why technology works the way it does.
(1) Heintzman, Kit. 2020.
Unfortunately, in Debian in particular, libgit2 is undergoing a transition
which is blocked by gall. Despite having had over a month to deal with this,
I've not managed to summon the tuits to update Gall to the new libgit2 which
means, nominally, I ought to withdraw it from testing and possibly even from
unstable given that I'm not really prepared to look after Gitano and friends in
Debian any longer.
However, I'd love for Gitano to remain in Debian if it's useful to people.
Gall isn't exactly a large piece of C code, and so probably won't be a huge job
to do the port, I simply don't have the desire/energy to do it myself.
If someone wanted to do the work and provide a patch / "pull request" to me,
then I'd happily take on the change and upload a new package, or if someone
wanted to NMU the gall package in Debian I'll take the change they make and
import it into upstream. I just don't have the energy to reload all that context
and do the change myself.
If you want to do this, email me and let me know, so I can support you and take
on the change when it's done. Otherwise I probably will go down the lines of
requesting Gitano's removal from Debian in the next week or so.
Like each month, here comes a report about the work of paid contributors to Debian LTS.
Individual reports
In October, 221.50 work hours have been dispatched among 13 paid contributors. Their reports are available:
Abhijith PA did 16.0h (out of 14h assigned and 2h from September).
Adrian Bunk did 7h (out of 20.75h assigned and 5.75h from September), thus carrying over 19.5h to November.
Ben Hutchings did 11.5h (out of 6.25h assigned and 9.75h from September), thus carrying over 4.5h to November.
Evolution of the situation
October was a regular LTS month with a LTS team meeting done via video chat
thus there s no log to be shared.
After more than five years of contributing to LTS (and ELTS), Mike Gabriel announced
that he founded a new company called Frei(e)
Software GmbH and thus would leave us to concentrate on this new endeavor.
Best of luck with that, Mike!
So, once again, this is a good moment to remind that we are constantly looking
for new contributors. Please contact Holger
if you are interested!
The security tracker currently lists 42 packages with a known CVE and the dla-needed.txt file has 39 packages needing an update.
Thanks to our sponsors
Sponsors that joined recently are in bold.
A few days ago I wrote a quick patch and missed a dumb mistake that made the
program crash. When reviewing the merge request on Salsa, the problem became
immediately apparent; Gitlab's diff is much better than what git diff shows by
default in a terminal.
Well, it turns out since version 2.9, git bundles a better pager,
diff-highlight. la Gitlab, it will highlight what changed in the line.
Sadly, even though diff-highlight comes with the git package in Debian, it is
not built by default (925288). You will need to:
$ sudo make --directory /usr/share/doc/git/contrib/diff-highlight
You can then add this line to your .gitconfig file:
[core]pager=/usr/share/doc/git/contrib/diff-highlight/diff-highlight less --tabs=4 -RFX
If you use tig, you'll also need to add this line in your tigrc:
set diff-highlight = /usr/share/doc/git/contrib/diff-highlight/diff-highlight
Armadillo is a powerful and expressive C++ template library for linear algebra aiming towards a good balance between speed and ease of use with a syntax deliberately close to a Matlab. RcppArmadillo integrates this library with the R environment and language and is widely used by (currently) 779 other packages on CRAN.
This release ties up a few loose ends from the recent 0.10.1.0.0.
Changes in RcppArmadillo version 0.10.1.2.0 (2020-11-15)
Upgraded to Armadillo release 10.1.2 (Orchid Ambush)
A new release 0.0.17 of RcppAnnoy is now on CRAN. RcppAnnoy is the Rcpp-based R integration of the nifty Annoy library by Erik Bernhardsson. Annoy is a small and lightweight C++ template header library for very fast approximate nearest neighbours originally developed to drive the famous Spotify music discovery algorithm.
This release brings a new upstream version 1.17, released a few weeks ago, which adds multithreaded index building. This changes the API by adding a new threading policy parameter requiring code using the main Annoy header to update. For this reason we waited a little for the dust to settle on the BioConductor 3.12 release before bringing the changes to BiocNeighbors via this commit and to uwot via this simple PR. Aaron and James updated their packages accordingly so by the time I uploaded RcppAnnoy it made for very smooth sailing as we all had done our homework with proper conditional builds, and the package had no other issue preventing automated processing at CRAN. Yay. I also added a (somewhat overdue one may argue) header file RcppAnnoy.h regrouping defines and includes which should help going forward.
Detailed changes follow below.
Changes in version 0.0.17 (2020-11-15)
Upgrade to Annoy 1.17, but default to serial use.
Add new header file to regroup includes and defines.
There are many blogs and tutorials with nice shortcuts providing the necessary
openssl commands to create and sign x509 certficates.
However, there is precious few instructions for how to easily create your own
certificate authority.
You probably never want to do this in a production environment, but in a
development environment it will make your life signficantly easier.
Create the certificate authority
Create the key and certificate
Pick a directory to store things in. Then, make your certificate authority key and certificate:
You will be prompted to enter some information about your certificate
authoirty. Provide the minimum information - i.e., only overwrite the
defaults. So, provide a value for Country, State or Province, and
Organization Name and leave the rest blank.
You probably want to leave the password blank if this is a
development/testing environment.
Want to review what you created?
openssl x509 -text -noout -in cacert.pem
Prepare your directory
You can create your own /etc/ssl/openssl.cnf file and really customize things. But I
find it safer to use your distribution's default file so you can benefit from
changes to it every time you upgrade.
If you do take the default file, you may have the dir option coded to
demoCA (in Debian at least, maybe it's the upstream default too).
So, to avoid changing any configuration files, let's just use this value. Which
means... you'll need to create that directory. The setting is relative - so you
can create this directory in the same directory you have your keys.
mkdir demoCA
Lastly, you have to have a file that keeps track of your certificates. If it
doesn't exist, you get an error:
touch demoCA/index.txt
That's it! Your certificate authority is ready to go.
Create a key and ceritificate signing request
First, pick your domain names (aka "common" names). For example, example.org
and www.example.org.
Set those values in an environment variable. If you just have one:
Again, you will be prompted for some values (country, state, etc) - be sure to
choose the same values you used with your certficiate authority! I honestly
don't understand why this is necessary (when I set different values I get an
error on the signing request step below). Maybe someone can add a comment to
this post explaining why these values have to match?
Also, you must provide a common name for your certificate - you can choose the
same name as the altSubjectNames value you set above (but just one domain).
Want to review what you created?
openssl req -in new.csr -text -noout
Sign it!
At last the momenet we have been waiting for.
Now yu have a new.crt and new.csr that you can install via your web browser,
mail server, etc specification.
Sanity check it
This command will confirm that the certificate is trusted by your certificate
authority.
But wait, there's still a question of trust
You probably want to tell your computer or browser that you want to trust your
certificate signing authority.
Command line tools
Most tools in linux by default will trust all the certificates in
/etc/ssl/certs/ca-certificates.crt. (If that file doesn't exist, try
installing the ca-certificates package). If you want to add your certificate
to that file:
Want to know what's funny? Ok, not really funny. If the certificate name ends
with .pem the command above won't work. Seriously.
Once your certificate is installed with your web server you can now test to
make sure it's all working with:
Both will report errors if the certificate can't be verified by a system
certificate.
If you really want to narrow down the cause of error (maybe reconfiguring
ca-certificates didn't work)?
Those arguments tell curl to use your certificate authority file and not to
load any other certificate authority files (well, unless you have some
installed in the temp directory).
Web browsers
Firefox and Chrome have their own store of trusted certificates - you'll have
to import your cacert.pem file into each browser that you want to trust your
key.
Juniper s official documentation on ZTP explains how to configure
the ISC DHCP Server to automatically upgrade and configure on
first boot a Juniper device. However, the proposed configuration could
be a bit more elegant. This note explains how.
TL;DR
Do not redefine option 43. Instead, specify the vendor
option space to use to encode parameters with vendor-option-space.
When booting for the first time, a Juniper device requests its IP
address through a DHCP discover message, then request additional
parameters for autoconfiguration through a DHCP request
message:
Dynamic Host Configuration Protocol (Request)
    Message type: Boot Request (1)
    Hardware type: Ethernet (0x01)
    Hardware address length: 6
    Hops: 0
    Transaction ID: 0x44e3a7c9
    Seconds elapsed: 0
    Bootp flags: 0x8000, Broadcast flag (Broadcast)
    Client IP address: 0.0.0.0
    Your (client) IP address: 0.0.0.0
    Next server IP address: 0.0.0.0
    Relay agent IP address: 0.0.0.0
    Client MAC address: 02:00:00:00:00:01 (02:00:00:00:00:01)
    Client hardware address padding: 00000000000000000000
    Server host name not given
    Boot file name not given
    Magic cookie: DHCP
    Option: (54) DHCP Server Identifier (10.0.2.2)
    Option: (55) Parameter Request List
        Length: 14
        Parameter Request List Item: (3) Router
        Parameter Request List Item: (51) IP Address Lease Time
        Parameter Request List Item: (1) Subnet Mask
        Parameter Request List Item: (15) Domain Name
        Parameter Request List Item: (6) Domain Name Server
        Parameter Request List Item: (66) TFTP Server Name
        Parameter Request List Item: (67) Bootfile name
        Parameter Request List Item: (120) SIP Servers
        Parameter Request List Item: (44) NetBIOS over TCP/IP Name Server
        Parameter Request List Item: (43) Vendor-Specific Information
        Parameter Request List Item: (150) TFTP Server Address
        Parameter Request List Item: (12) Host Name
        Parameter Request List Item: (7) Log Server
        Parameter Request List Item: (42) Network Time Protocol Servers
    Option: (50) Requested IP Address (10.0.2.15)
    Option: (53) DHCP Message Type (Request)
    Option: (60) Vendor class identifier
        Length: 15
        Vendor class identifier: Juniper-mx10003
    Option: (51) IP Address Lease Time
    Option: (12) Host Name
    Option: (255) End
    Padding: 00
It requests several options, including the TFTP server address option
150, and the Vendor-Specific Information Option 43 or VSIO. The
DHCP server can use option 60 to identify the vendor-specific
information to send. For Juniper devices, option 43 encodes the image
name and the configuration file name. They are fetched from the IP
address provided in option 150.
The official documentation on ZTP provides a valid configuration
to answer such a request. However, it does not leverage the ability of
the ISC DHCP Server to support several vendors and redefines option 43
to be Juniper-specific:
Dynamic Host Configuration Protocol (ACK)
    Message type: Boot Reply (2)
    Hardware type: Ethernet (0x01)
    Hardware address length: 6
    Hops: 0
    Transaction ID: 0x44e3a7c9
    Seconds elapsed: 0
    Bootp flags: 0x8000, Broadcast flag (Broadcast)
    Client IP address: 0.0.0.0
    Your (client) IP address: 10.0.2.15
    Next server IP address: 0.0.0.0
    Relay agent IP address: 0.0.0.0
    Client MAC address: 02:00:00:00:00:01 (02:00:00:00:00:01)
    Client hardware address padding: 00000000000000000000
    Server host name not given
    Boot file name not given
    Magic cookie: DHCP
    Option: (53) DHCP Message Type (ACK)
    Option: (54) DHCP Server Identifier (10.0.2.2)
    Option: (51) IP Address Lease Time
    Option: (1) Subnet Mask (255.255.255.0)
    Option: (3) Router
    Option: (6) Domain Name Server
    Option: (43) Vendor-Specific Information
        Length: 89
        Value: 00362f696d616765732f6a756e6f732d766d686f73742d69
    Option: (150) TFTP Server Address
    Option: (255) End
Using vendor-option-space directive allows you to make different ZTP
implementations coexist. For example, you can add the option space for
PXE:
 I had been thinking of doing a blog post on RCEP which China signed with 14 countries a week and a day back but this new story has broken and is being viraled a bit on the interwebs, especially twitter and is pretty much in our domain so thought would be better to do a blog post about it. Also, there is quite a lot packed so quite a bit of unpacking to do.
 Sneakers was much more interesting for me because in that you got the best key which can unlock any lock, something like quantum computing is supposed to do. One could equate both the first movies in either as a White hat or a Grey hat . A Grey hat is more flexible in his/her moral values, and they are plenty of such people. For e.g. Julius Assange could be described as a Grey hat, but as you can see and understand those are moral issues.
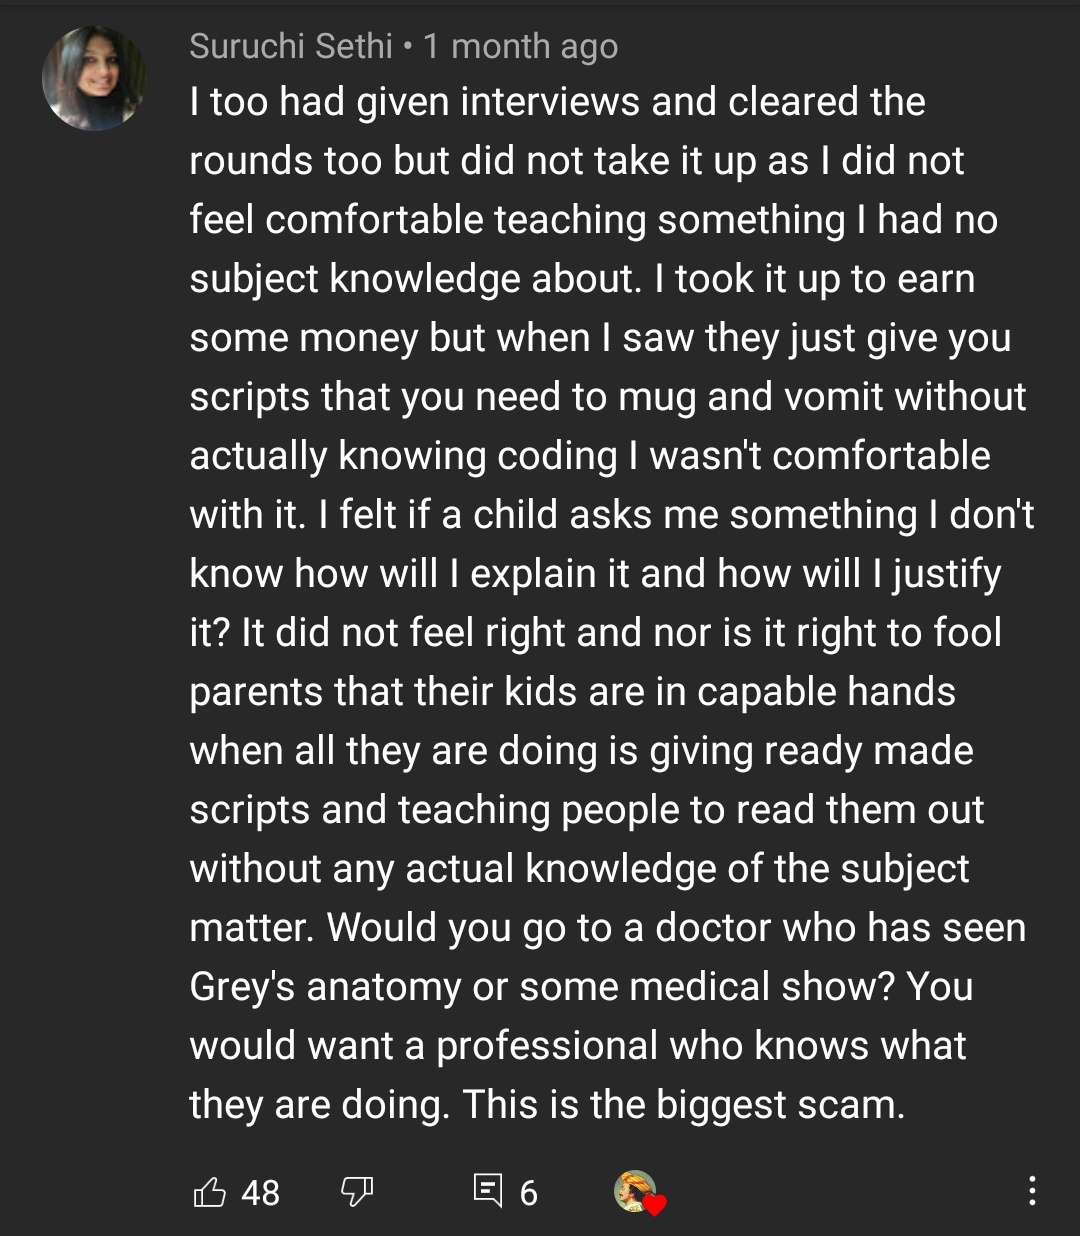 Suruchi Sethi


 One of the most interesting (and possibly unknown) features of the nftables framework is the native
python interface, which allows python programs to access all nft features programmatically, from
the source code.
There is a high-level library, libnftables, which is responsible for translating the human-readable
syntax from the
 Welcome to gambaru.de. Here is my monthly report (+ the first week in November) that covers what I have been doing for Debian. If you re interested in Java, Games and LTS topics, this might be interesting for you.
Debian Games
 I've make a presentation about "How to hack debexpo (mentors.
 Justice Chandrachud If you don t like a channel then don t watch it. 11th November 2020 .
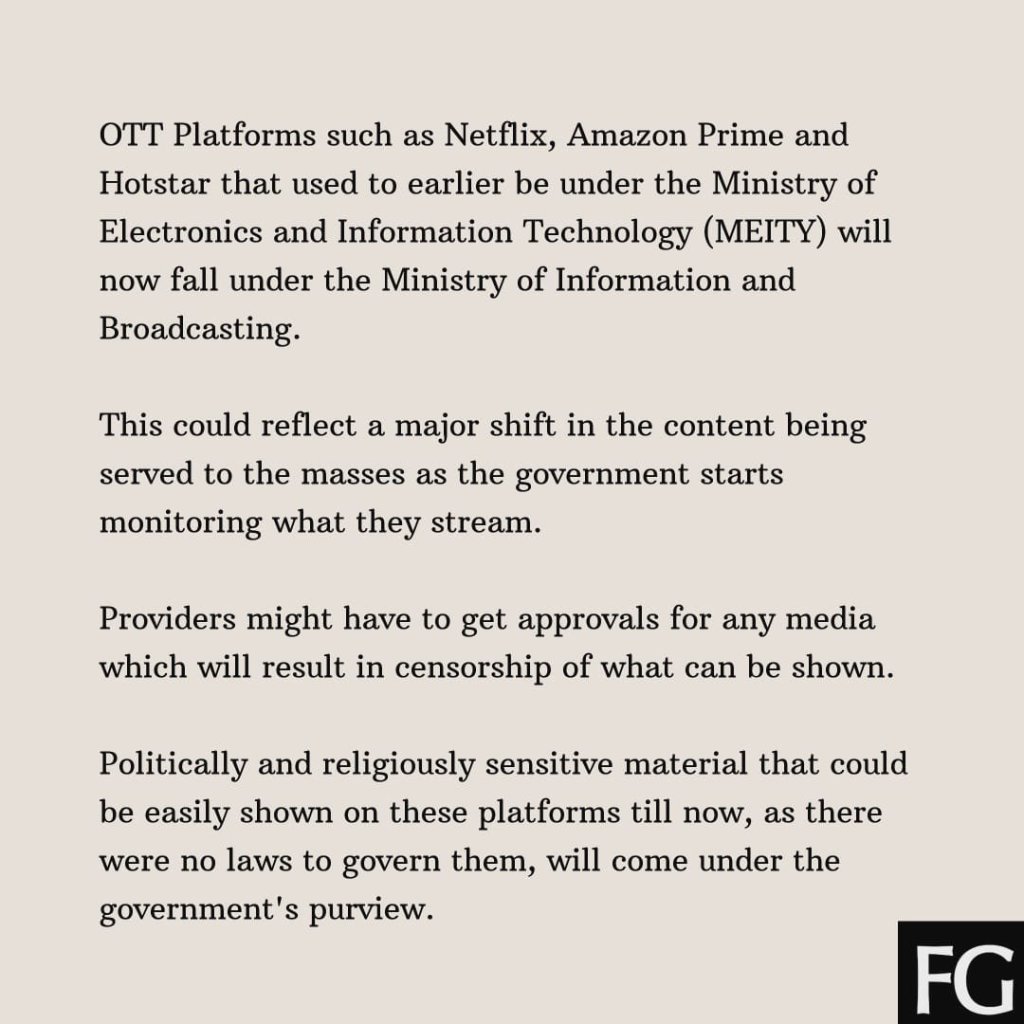 Information and Broadcasting Ministry bringing OTT services as well as news within its ambit.
 Unfortunately, in Debian in particular, libgit2 is undergoing a

 Like


 Best wishes to the entire Debian world for a happy, prosperous and safe Gujarati new year, Vikram Samvat 2077 named Paridhawi.
 A few days ago I wrote a quick patch and missed a dumb mistake that made the
program crash. When reviewing the merge request on Salsa, the problem became
immediately apparent; Gitlab's diff is much better than what
 Sadly, even though


 A new release 0.0.17 of