Search Results: "tar"

7 January 2016

Rhonda D'Vine: Chipzel

Happy new year everyone! Let's start with another round of nice music, this time it is coming from Chipzel who is a great chiptune composer. Given that I'm coming from a c64 background I love chip tunes, and she does a really great job in that area. Check it out! And like always, enjoy!

/music permanent link Comments: 0 Flattr this

Enrico Zini: downgrading-network-manager

Downgrading network-manager This morning I woke up. Bad idea. I find in the work mail a compiler error that I cannot reproduce, so I need to log into a machine at work. But #809195. I decided to downgrade network-manager. I recall there was a tool to download packages from snapshots.debian.org, I discussed it recently on IRC, let's sync the IRC logs from my server. Or not (#810212). Never mind, I'll log into the server and grep. Ooh, it's debsnap. However, it doesn't quite do what I hoped (#667712). After some help from #debian-devel (thanks jcristau and LebedevRI), here is how to downgrade network-manager:
# echo "deb http://snapshot.debian.org/archive/debian/20151125T155830Z/ sid main" >> /etc/apt/sources.list.d/tmp-downgrade-nm.list
# apt -o Acquire::Check-Valid-Until=false update
# apt -o Acquire::Check-Valid-Until=false install network-manager=1.0.6-1
# rm /etc/apt/sources.list.d/tmp-downgrade-nm.list
# service network-manager restart
And as user:
$ killall nm-applet
$ nm-applet &
The yak is now nice and shaved, I can now go and see what those compiler errors are all about. Actually, no, there was still an unshaved patch on the yak, and now we have a debcya script.

Thorsten Glaser: git find published; test, review, fix it please

I just published the first version of git find on gh/mirabilos/git-find for easy collaboration. The repository deliberately only contains the script and the manual page so it can easily be merged into git.git with complete history later, should they accept it. git find is MirOS licenced. It does require a recent mksh (Update: I did start it in POSIX sh first, but it eventually turned out to require arrays, and I don t know perl(1) and am not going to rewrite it in C) and some common utility extensions to deal with NUL-separated lines (sort -z, grep -z, git ls-tree -z); also, support for '\0' in tr(1) and a comm(1) that does not choke on embedded NULs in lines.

To install or uninstall it, run

	$ git clone git@github.com:mirabilos/git-find.git
	$ cd git-find
	$ sudo ln -sf $PWD/git-find /usr/lib/git-core/
	$ sudo cp git-find.1 /usr/local/share/man/man1/
	  hack  
	$ sudo rm /usr/lib/git-core/git-find \
	    /usr/local/share/man/man1/git-find.1

then you can call it as git find and look at the documentation with git help find , as is customary. The idea behind this utility is to have a tool like git grep that acts on the list of files known to git (and not e.g. ignored files) to quickly search for, say, all PNG files in the repository (but not the generated ones). git find acts on the index for the HEAD, i.e. whatever commit is currently checked-out (unlike git grep which also knows about git add ed files; fix welcome) and then offers a filter syntax similar to find(1) to follow up: parenthes s, ! for negation, -a and -o for boolean are supported, as well as -name, -regex and -wholename and their case-insensitive variants, although regex uses grep(1) without (or, if the global option -E is given, with) -E, and the pattern matches use mksh(1) s, which ignores the locale and doesn t do [[:alpha:]] character classes yet. On the plus side, the output is guaranteed to be sorted; on the minus side, it is rather wastefully using temporary files (under $TMPDIR of course, so use of tmpfs is recommended). -print0 is the only output option (-print being the default). Another mode forwards the file list to the system find; since it doesn t support DOS-style response files, this only works if the amount of files is smaller than the operating system s limit; this mode supports the full range (except -maxdepth) of the system find(1) filters, e.g. -mmin -1 and -ls, but it occurs filesystem access penalty for the entire tree and doesn t sort the output, but can do -ls or even -exec. The idea here is that it can collaboratively be improved, reviewed, fixed, etc. and then, should they agree, with the entire history, subtree-merged into git.git and shipped to the world. Part of the development was sponsored by tarent solutions GmbH, the rest and the entire manual page were done in my vacation.

6 January 2016

Steinar H. Gunderson: IPv6 non-alternatives: DJB's article, 13 years later

With the world passing 10% IPv6 penetration over the weekend, we see the same old debates coming up again; people claiming IPv6 will never happen (despite several years now of exponential growth!), and that if they had only designed it differently, it would have been all over by now. In particular, people like to point to a 2002 3 article by D. J. Bernstein, complete with rants about how Google would never set up useless IPv6 addresses (and then they did that in 2007 I was involved). It's difficult to understand exactly what the article proposes since it's heavy on calling people idiots and light on actual implementation details (as opposed to when DJB's gotten involved in other fields; e.g. thanks to him we now have elliptical curve crypto that doesn't suck, even if the reference implementation was sort of a pain to build), but I will try to go through it nevertheless and show how I cannot find any way it would work well in practice. One thing first, though: Sorry, guys, the ship has sailed. Whatever genius solution DJB may have thought up that I'm missing, and whatever IPv6's shortcomings (they're certainly there), IPv6 is what we have. By now, you can not expect anything else to arise and take over the momentum; we will either live with IPv6 or die with IPv4. So, let's see what DJB says. As far as I can see, his primary call is for a version of IPv6 where the address space is an extension of the IPv4 space. For sake of discussion, let's call that IPv4+ , although it would share a number of properties with IPv6. In particular, his proposal requires changing the OS and other software on every single end host out there, just as IPv6; he readily admits that and outlines how it's done in rough terms (change all structs, change all configuration files, change all databases, change all OS APIs, etc.). From what I can see, he also readily admits that IPv4 and IPv4+ hosts cannot talk to each other, or more clearly, we cannot start using the extended address space before almost everybody has IPv4+ capable software. (E.g., quote: Once these software upgrades have been done on practically every Internet computer, we'll have reached the magic moment: people can start relying on public IPv6 addresses as replacements for public IPv4 addresses. ) So, exactly how does the IPv4 address space fit into the IPv4+ address space? The article doesn't really say anything about this, but I can imagine only two strategies: Build the IPv4+ space around the IPv4 space (ie., the IPv4 space occupies a little corner of the IPv4+ space, similar to how v4-mapped addresses are used within software but not on the wire today, to let applications do unified treatment of IPv4 addresses as a sort of special IPv6 address), or build it as a hierarchical extension. Let's look at the former first; one IPv4 address gives you one IPv4+ addresses. Somehow this seems to give you all the disadvantages of IPv4 and all the disadvantages of IPv6. The ISP is not supposed to give you any more IPv4+ addresses (or at least DJB doesn't want to contact his ISP about more also saying that the fact that automatic address distribution does not change his argument), so if you have one, you're stuck with one. So you still need NAT. (DJB talks about proxies , but I guess that the way things evolved, this either actually means NAT, or it talks about the practice of application-level proxies such as Squid or SOCKS proxies to reach the Internet, which really isn't commonplace anymore, so I'll assume for the sake of discussion it means NAT.) However, we already do NAT. The IPv4 crunch happened despite ubiquitous NAT everywhere; we're actually pretty empty. So we will need to hand out IPv4+ addresses at the very least to new deployments, and also probably reconfigure every site that wants to expand and is out of IPv4 addresses. ( Site here could mean any organizational unit, such as if your neighborhood gets too many new subscribers for your ISP's local addressing scheme to have enough addresses for you.) A much more difficult problem is that we now need to route these addresses on the wire. Ironically, the least clear part of DJB's plan is step 1, saying we will extend the format of IP packets to allow 16-byte addresses ; how exactly will this happen? For this scheme, I can only assume some sort of IPv4 option that says the stuff in the dstaddr field is just the start and doesn't make sense as an IPv4 address on its own; here are the remaining 12 bytes to complete the IPv4+ address . But now your routers need to understand that format, so you cannot do with only upgrading the end hosts; you also need to upgrade every single router out there, not just the end hosts. (Note that many of these do routing in hardware, so you can't just upgrade the software and call it a day.) And until that's done, you're exactly in the same situation as with IPv4/IPv6 today; it's incompatible. I do believe this option is what DJB talks about. However, I fail to see exactly how it is much better than the IPv6 we got ourselves into; you still need to upgrade all software on the planet and all routers on the planet. The benefit is supposedly that a company or user that doesn't care can just keep doing nothing, but they do need to care, since they need to upgrade 100% of their stuff to understand IPv4+ before we can start even deploying it alongside IPv4 (in contrast with IPv6, where we now have lots of experience in running production networks). The single benefit is that they won't have to renumber until they need to grow, at which point they need to anyway. However, let me also discuss the other possible interpretation, namely that of the IPv4+ address space being an extension of IPv4, ie. if you have 1.2.3.4 in IPv4, you have 1.2.3.4.x.x.x.x or similar in IPv4+. (DJB's article mentions 128-bit addresses and not 64-bit, though; we'll get to that in a moment.) People keep bringing this up, too; it's occasionally been called BangIP (probably jokingly, as in this April Fool's joke) due to the similarity with how explicit mail routing would work before SMTP became commonplace. I'll use that name, even though others have been proposed. The main advantage of BangIP is that you can keep your Internet core routing infrastructure. One way or the other, they will keep seeing IPv4 addresses and IPv4 packets; you need no new peering arrangements etc.. The exact details are unclear, though; I've seen people suggest GRE tunneling, ignoring problems they have through NAT, and I've seen suggestions of IPv4 options for source/destination addresses, also ignoring that someting as innocious as setting the ECN bits has been known to break middleboxes left and right. But let's assume you can pull that off, because your middlebox will almost certainly need to be the point that decapsulates BangIP anyway and converts it to IPv4 on the inside, presumably with a 10.0.0.0/8 address space so that your internal routing can keep using IPv4 without an IPv4+ forklift upgrade. (Note that you now lose the supposed security benefit of NAT, by the way, although you could probably encrypt the address.) Of course, your hosts will need to support IPv4+ still, and you will need some way of communicating that you are on the inside of the BangIP boundary. And you will need to know what the inside is, so that when you communicate on this side, you'll send IPv4 and not IPv4+. (For a home network with no routing, you could probably even just do IPv4+ on the inside, although I can imagine complications.) But like I wrote above, experience has shown us that 32 extra bits isn't enough. One layer of NAT isn't doing it, we need two. You could imagine the inter-block routability of BangIP helping a fair bit here (e.g., a company with too many machines for 10.0.0.0/8 could probably easily get more addresses for more external IPv4 addresses, yielding 10.0.0.0/8 blocks), but ultimately, it is a problem that you chop the Internet off in two distinct halves that work very differently. My ISP will probably want to use BangIP for itself, meaning I'm on the outside of the core; how many of those extra bits will they allocate for me? Any at all? Having multiple levels of bang sounds like pain; effectively we're creating a variable-length address. Does anyone ever want that? From experience, when we're creating protocols with variable-length addresses, people just tend to use the maximum level anyway, so why not design it with 128-bit to begin with? (The original IP protocol proposals actually had variable-length addresses, by the way.) So we can create our 32/96 BangIP , where the first 32 bits are for the existing public Internet, and then every IPv4 address gives you a 2^96 addresses to play with. (In a sense, it reminds me of 6to4, which never worked very well and is now thankfully dead.) However, this makes the inside/outside-core problem even worse. I now need two very different wire protocols coexisting on the Internet; IPv4+ (which looks like regular IPv4 to the core) for the core, and a sort of IPv4+-for-the-outside (similar to IPv6) outside it. If I build a company network, I need to make sure all of my routers are IPv4+-for-the-outside and talk that, while if I build the Internet core, I need to make sure all of my connections are IPv4 since I have no guarantee that I will be routable on the Internet otherwise. Furthermore, I have a fixed prefix that I cannot really get out of, defined by my IPv4 address(es). This is called hierarchical routing , and the IPv6 world gave it up relatively early despite it sounding like a great idea at first, because it makes multihoming a complete pain: If I have an address 1.2.3.4 from ISP A and 5.6.7.8 from ISP B, which one do I use as the first 32 bits of my IPv4+ network if I want it routable on the public Internet? You could argue that the solution for me is to get an IPv4 PI netblock (supposedly a /24, since we're not changing the Internet core), but we're already out of those, which is why we started this thing to begin with. Furthermore, if the IPv4/IPv4+ boundary is above my immediate connection to the Internet (say, ISP A doesn't have an IPv4 address, just IPv4+), I'm pretty hosed; I cannot announce an IPv4 netblock in BGP. The fact that the Internet runs on largely the same protocol everywhere is a very nice thing; in contrast, what is described here really would be a mess! So, well. I honestly don't think it's as easy to just do extension instead of alternative when it comes to the address spaces. We'll just need to deal with the pain and realize that upgrading the equipment and software is the larger part of the job anyway, and we'll need to do that no matter what solution we go with. Congrats on reaching 10%! Now get to work with the remaining 90%.

Ingo Juergensmann: Letsencrypt: challenging challenges

On December 3rd 2015 the Letsencrypt project went to public beta and this is a good thing! Having more and more websites running on good and valid SSL certificates for their HTTPS is a good thing, especially because Letsencrypt takes care of renewing the certs every now and then. But there are still some issues with Letsencrypt. Some people criticize the Python client needing root priviledges and such. Others complain that Letsencrypt currently only supports webservers. Well, I think for a public beta this is what we could have expected from the start: the Letsencrypt project focussed on a reference implementation and there are already other implementations being available. But one thing seems to a problem within the design of how Letsencrypt works as it uses a challenge response method to verify that the requesting user is controlling the domain for which the certificate shall be issued. This might work well in simple deployments, but what about a little more complex setups like multiple virtual machines and different protocols involved. For example: you're using domain A for your communication like user@example.net for your mail, XMPP and SIP. Your mailserver runs on one virtual machine, whereas the webserver is running on a different virtual machine. The same for XMPP and SIP: a seperate VM as well. Usually the Letsencrypt approach would be that you configure your webserver (by configure /.well-known/acme-challenge/* location or use a standalone server on port 443) to handle the challenge response requests. This would give you a SSL cert for your webserver example.net. Of course you could copy this cert to your mail-, XMPP- and SIP-server, but then again you have to do this everytime the SSL cert gets renewed. Another challenge is of course that you are not only have one or two domains, but a bunch of domains. In my case I host approximately >60 domains. Basically the mail for all domains are handled by my mailserver running on its own virtual machine. The webserver is located on a different VM. For some domains I offer XMPP accounts on a third VM. What is the best way to solve this problem? Moving everything to just one virtual machine? Naaah! Writing some scripts to copy the certs as needed? Not very smart as well. Using a network share for the certs between all VMs? Hmmm... would that work? And what about TLSA entries of your DNSSEC setup? When a SSL cert is renewed than the fingerprint might need an update in your DNS zone - for several protocols like mail, XMPP, SIP and HTTPS. At least the Bash implementation of Letsencrypt offers a "hook" which is called after the SSL cert has been issued. What are you ways to deal with this kind of handling the ACME protocol challenges and multi-domain, multi-VM setup?
Kategorie:

Daniel Pocock: Want to use free software to communicate with your family in Christmas 2016?

Was there a friend or family member who you could only communicate with using a proprietary, privacy-eroding solution like Skype or Facebook this Christmas? Would you like to be only using completely free and open solutions to communicate with those people next Christmas? Developers Even if you are not developing communications software, could the software you maintain make it easier for people to use "sip:" and "xmpp:" links to launch other applications? Would this approach make your own software more convenient at the same time? If your software already processes email addresses or telephone numbers in any way, you could do this. If you are a web developer, could you make WebRTC part of your product? If you already have some kind of messaging or chat facility in your website, WebRTC is the next logical step. If you are involved with the Debian or Fedora projects, please give rtc.debian.org and FedRTC.org a go and share your feedback. If you are involved with other free software communities, please come to the Free-RTC mailing list and ask how you can run something similar. Everybody can help Do you know any students who could work on RTC under Google Summer of Code, Outreachy or any other student projects? We are particularly keen on students with previous experience of Git and at least one of Java, C++ or Python. If you have contacts in any universities who can refer talented students, that can also help a lot. Please encourage them to contact me directly. In your workplace or any other organization where you participate, ask your system administrator or developers if they are planning to support SIP, XMPP and WebRTC. Refer them to the RTC Quick Start Guide. If your company web site is built with the Drupal CMS, refer them to the DruCall module, it can be installed by most webmasters without any coding. If you are using Debian or Ubuntu in your personal computer or office and trying to get best results with the RTC and VoIP packages on those platforms, please feel free to join the new debian-rtc mailing list to discuss your experiences and get advice on which packages to use. Everybody is welcome to ask questions and share their experiences on the Free-RTC mailing list. Please also come and talk to us at FOSDEM 2016, where RTC is in the main track again. FOSDEM is on 30-31 January 2016 in Brussels, attendance is free and no registration is necessary. This mission can be achieved with lots of people making small contributions along the way.

Norbert Preining: TeX Live security improvements

Today I committed a set of changes to the TeX Live subversion repository that should pave the way for better security handling in the future. Work is underway to use strong cryptographic signatures to verify that packages downloaded and installed into a TeX Live installation have not been tinkered with. texlive2015 While there is still a long way to go and to figure out, the current changes already improve the situation considerably. Status up to now Although we did ship size and checksum information within the TeX Live database, these information were only considered by the installer when re-starting an installation to make sure that the downloaded packages are the ones we should use. Neither the installer nor tlmgr did use the checksum to verify that the downloaded packages is correct, relying mostly on the fact that the packages are xz-compressed and would create rubbish when there is a transfer error. Although none of us believes that there is a serious interest in tinkering with the TeX Live distribution maybe to steal just another boring scientific paper? the door was still open. Changes implemented The changes committed to the repository today, which will be in a testing phase to get rid of bugs, consists of the following: Together these two changes will allow install-tl/tlmgr to verify that a package (.tar.xz) is according to the information in the accompanying texlive.tlpdb. This still leaves the option of tampering with a package and updating the texlive.tlpdb for the fixes checksums/sizes. Upcoming changes For the future we do plan mostly two things: The last step above will give a very high level of security, as it will be not practically possible to alter the information in the texlive.tlpdb, thus no tampering with the checksum information of the containers, and in turn no tampering with the actual containers will be possible. Restrictions Due to the wide range of supported architectures and operating systems, we will not make verification obligatory, but if a gpg binary is found, it will be used to verify the downloaded texlive.tlpdb.checksum. Details have to be hammered out and the actual programming has to be done, but we are on the way. Enjoy.
Gunnar Wolf: Starting work / call for help: Debianizing Drupal 8

I have helped maintain Drupal 7.x in Debian for several years (and am now the leading maintainer). During this last year, I got a small article published in the Drupal Watchdog, where I stated:
What About Drupal 8? Now... With all the hype set in the future, it might seem striking that throughout this article I only talked about Drupal 7. This is because Debian seeks to ship only production ready software: as of this writing, Drupal 8 is still in beta. Not too long ago, we still saw internal reorganizations of its directory structure. Once Drupal 8 is released, of course, we will take care to package it. And although Drupal 8 will not be a part of Debian 8, it will be offered through the Backports archive, following all of Debian's security and stability requirements.
Time passes, and I have to take care of following what I promise. Drupal 8 was released on November 18, so I must get my act together and put it in shape for Debian! So, prompted by a mail by a fellow Debian Developer, I pushed today to Alioth the (very little) work I have so far done to this effect; every DD can now step in and help (and I guess DMs and other non-formally-affiliated contributors, but I frankly haven't really read how you can be a part of collab-maint). So, what has been done? What needs to be done? Although the code bases are massively different, I took the (un?)wise step to base off the Drupal7 packaging, and start solving Lintian problems and installation woes. So far, I have an install that looks sane (but has not yet been tested), but has lots of Lintian warnings and errors. The errors are mostly of missing sources, as Drupal8 inlines many unrelated projects (fortunately documented and frozen to known-good versions) in it; there are two possible courses of action:
  1. Prefered way: Find which already made Debian package provides each of them, remove from the binary package, declare dependency.
  2. Pragmatic way: As the compatibility must sometimes be to a specific version level, just provide the needed sources in debian/missing-sources
We can, of course, first go pragmatic and later start reviewing what can be safely depended upon. But for this, we need people with better PHP experience than me (which is not much to talk about). This cleanup will correspond with cleaning up the extra license file Lintian warnings, as there is one for each such project Of course, documenting each such license in debian/copyright is also a must. Anyway, there is quite a bit of work to do. And later, we have to check that things work reliably. And also, quite probably, adapt any bits of dh-make-drupal to work with v8 as well as v7 (and I am not sure if I already deprecated v6, quite probably I have). So... If you are interested in working on this, please contact me directly. If we get more than a handful, building a proper packaging team might be in place, otherwise we can just go on working as part of collab-maint. I am very short on time, so any extra hands will be most helpful!

5 January 2016

Lior Kaplan: PHP 5 Support Timeline

With the new year starting the PHP project is being asked to decide about the PHP 5 support timeline. While Aligning PHP 5.6 support timeline with the release date of PHP 7.0 seems like common sense to keep the support schedule continuous, there s a big question whether to extend it further to an additional one year of security support till the end of 2018. This would make PHP 5.6, the last of the PHP 5 branch, to have 2 years of security support and de facto getting the same life span as PHP 7.0 would (ending support of both in Dec 2018). But beside of support issues, this also affects adoption rate of PHP 7.0, serving as a catalyst due to end of support for the PHP 5 branch. My concerns are that with the additional security support the project would need to deal with the many branches (5.6, 7.0, 7.1, 7.2 and then to be 7.3 branch). I think we should limit what we guarantee (meaning keeping only one year of security support till end of 2017), and encourage project members and the eco-system (e.g. Linux distributions) to maintain further security based on best effort. This is already the case for out of official support releases like the 5.3 and 5.4 branches (examples for backports done by Debian: 5.3 and 5.4). And of course, we also have companies that make their money out of long term support (e.g. RedHat). On the other hand, we should help the eco system in doing such extended support, and hosting backported fixes in the project s git repo instead of having each Linux disto do the same patch work on its own.
Filed under: PHP

Benjamin Mako Hill: Celebrate Aaron Swartz in Seattle (or Atlanta, Chicago, Dallas, NYC, SF)

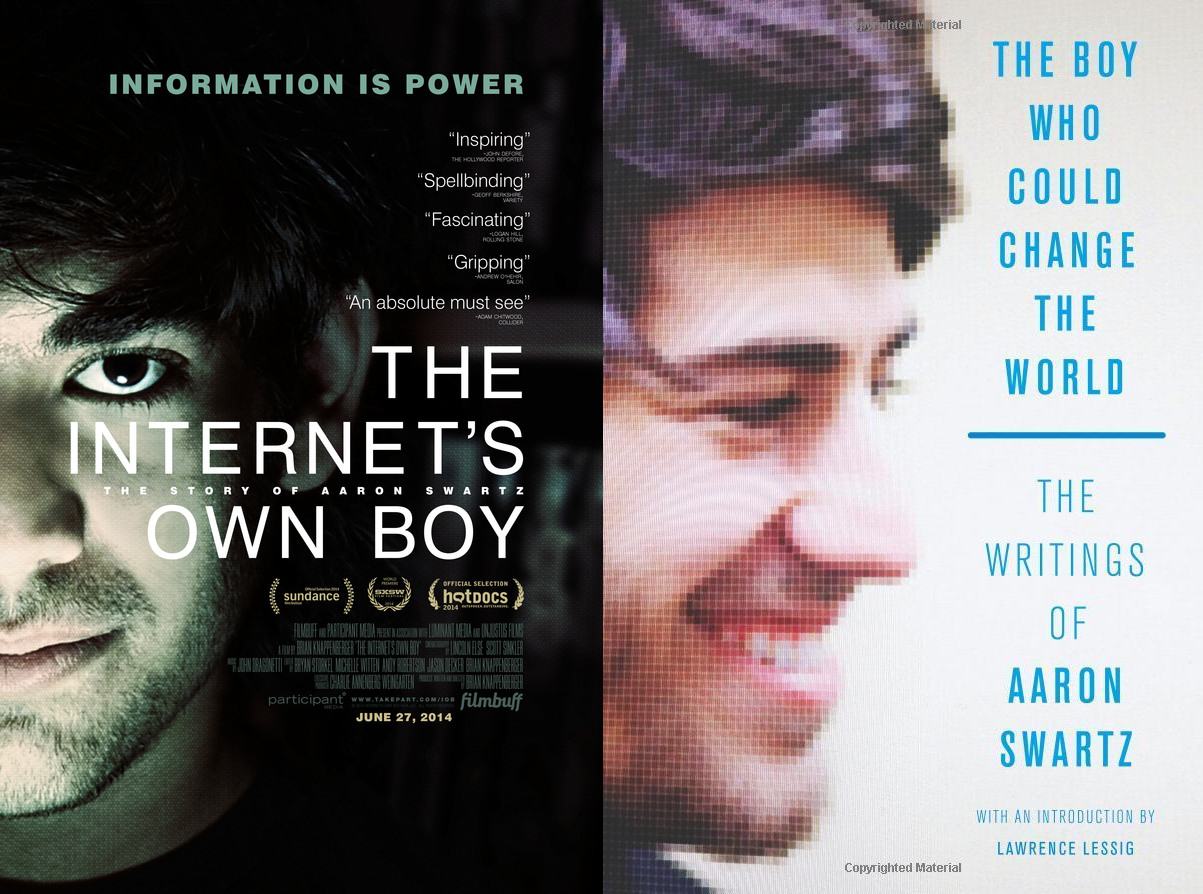
I m organizing an event at the University of Washington in Seattle that involves a reading, the screening of a documentary film, and a Q&A about Aaron Swartz. The event coincides with the third anniversary of Aaron s death and the release of a new book of Swartz s writing that I contributed to. aaronsw-tiob_bwcstw The event is free and open the public and details are below:

WHEN: Wednesday, January 13 at 6:30-9:30 p.m.

WHERE: Communications Building (CMU) 120, University of Washington

We invite you to celebrate the life and activism efforts of Aaron Swartz, hosted by UW Communication professor Benjamin Mako Hill. The event is next week and will consist of a short book reading, a screening of a documentary about Aaron s life, and a Q&A with Mako who knew Aaron well details are below. No RSVP required; we hope you can join us.

Aaron Swartz was a programming prodigy, entrepreneur, and information activist who contributed to the core Internet protocol RSS and co-founded Reddit, among other groundbreaking work. However, it was his efforts in social justice and political organizing combined with his aggressive approach to promoting increased access to information that entangled him in a two-year legal nightmare that ended with the taking of his own life at the age of 26.

January 11, 2016 marks the third anniversary of his death. Join us two days later for a reading from a new posthumous collection of Swartz s writing published by New Press, a showing of The Internet s Own Boy (a documentary about his life), and a Q&A with UW Communication professor Benjamin Mako Hill a former roommate and friend of Swartz and a contributor to and co-editor of the first section of the new book. If you re not in Seattle, there are events with similar programs being organized in Atlanta, Chicago, Dallas, New York, and San Francisco. All of these other events will be on Monday January 11 and registration is required for all of them. I will be speaking at the event in San Francisco.

4 January 2016

Mike Gabriel: My FLOSS activities in December 2015

December 2015 was a month mainly dedicated to work for local contractors (local schools mainly) and my employer (University of Kiel, Git server migration). At the end of the month I had the privilege of attending the 32c3 ([1]) where we had a little sprint for the Arctica Project. Thanks to my family and esp. to my wonderful wife for letting me attend this always fascinating event at the end of each year. Horde Hacking One of my local customers is really interested in using a non-gated-community mail provider, so he asked me to host his company's mail addresses on my mail company's server. Something I regularly don't offer (anymore) except for dear friends and very patient customers. This customer sponsored several more work hours on hacking on the Kolab_Storage code in Horde and proposing bug fixes upstream [2,3,4,5,6,7,8]. Thanks for supporting my work on the Horde Groupware Framework. Thanks to Horde upstream maintainers (esp. Michael Rubinsky) for reacting on my bug submissions so promptly. Debian and Debian LTS Locally, I did a lot of work for our Debian Edu / Skolelinux customers again this months. read more

Mike Gabriel: MATE 1.12 landed in Debian unstable

Yesterday, I did a bundle upload of all MATE 1.12 related packages to Debian unstable. Packages are currently building for the 22 architectures supported by Debian, build status can be viewed on the DDPO page of the Debian MATE Packaging Team [1] Again a big thanks to the packaging team. Martin Wimpress amongst others did a fabulous job in bumping all packages towards the 1.12 release series before the Christmas holidays. Over the holidays, I was able to review his work (99% perfect) and upload all binary packages to a staging repository. @Martin Wimpress: It is really time that we make a DM (Debian Maintainer) out of you!!! After testing all MATE 1.12 packages on a Debian unstable system, I decided to do a bundle upload yesterday. Lessons learned about bundling Debian uploads It absolutely makes sense to hold back package uploads of a project like the MATE desktop until all relevant packages are reviewed, pre-built and tested. When releasing MATE packages via the team's packaging Git [2], there are normally two actions to be taken on a package release: When reviewing so many Git projects, it is always problematic that people commit something else during the review phase. Especially, if the review work involves many packages (i.e., Git packaging repos) and requires several days or even weeks to get finished. read more

Benjamin Mako Hill: The Boy Who Could Change the World: The Writings of Aaron Swartz

The New Press has published a new collection of Aaron Swartz s writing called The Boy Who Could Change the World: The Writings of Aaron Swartz. I worked with Seth Schoen to introduce and help edit the opening section of book that includes Aaron s writings on free culture, access to information and knowledge, and copyright. Seth and I have put our introduction online under an appropriately free license (CC BY-SA). aaronsw_book_coverOver the last week, I ve read the whole book again. I think the book really is a wonderful snapshot of Aaron s thought and personality. It s got bits that make me roll my eyes, bits that make me want to shout in support, and bits that continue to challenge me. It all makes me miss Aaron terribly. I strongly recommend the book. Because the publication is post-humous, it s meant that folks like me are doing media work for the book. In honor of naming the book their progressive pick of the week, Truthout has also published an interview with me about Aaron and the book. Other folks who introduced and/or edited topical sections in the book are David Auerbach (Computers), David Segal (Politics), Cory Doctorow (Media), James Grimmelmann (Books and Culture), and Astra Taylor (Unschool). The book is introduced by Larry Lessig.

John Goerzen: Hiking a mountain with Ian Murdock

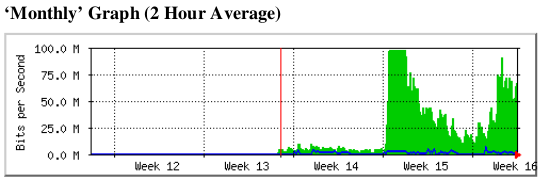
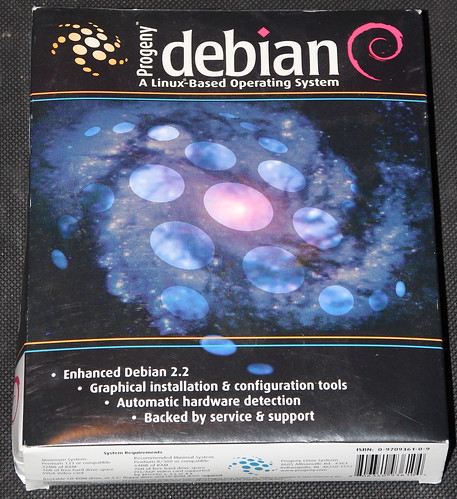
Would you like to hike a mountain? That question caught me by surprise. It was early in 2000, and I had flown to Tucson for a job interview. Ian Murdock was starting a new company, Progeny, and I was being interviewed for their first hire. Well, I thought, hiking will be fun. So we rode a bus or something to the top of the mountain and then hiked down. Our hike was full of well, everything. Ian talked about Tucson and the mountains, about his time as the Debian project leader, about his college days. I asked about the plants and such we were walking past. We talked about the plans for Progeny, my background, how I might fit in. It was part interview, part hike, part two geeks chatting. Ian had no HR telling him you can t go hiking down a mountain with a job candidate, as I m sure HR would have. And I am glad of it, because even 16 years later, that is still by far the best time I ever had at a job interview, despite the fact that it ruined the only pair of shoes I had brought along I had foolishly brought dress shoes for a, well, job interview. I guess it worked, too, because I was hired. Ian wanted to start up the company in Indianapolis, so over the next little while there was the busy work of moving myself and setting up an office. I remember those early days Ian and I went computer shopping at a local shop more than once to get the first workstations and servers for the company. Somehow he had found a deal on some office space in a high-rent office building. I still remember the puzzlement on the faces of accountants and lawyers dressed up in suits riding in the elevators with us in our shorts and sandals, or tie-die, next to them. Progeny s story was to be a complicated one. We set out to rock the world. We didn t. We didn t set out to make lasting friendships, but we often did. We set out to accomplish great things, and we did some of that, too. We experienced a full range of emotions there elation when we got hardware auto-detection working well or when our downloads looked very popular, despair when our funding didn t come through as we had hoped, being lost when our strategy had to change multiple times. And, as is the case everywhere, none of us were perfect. I still remember the excitement after we published our first release on the Internet. Our little server that could got pegged at 100Mb of outbound bandwidth (that was something for a small company in those days.) The moment must have meant something, because I still have the mrtg chart from that day on my computer, 15 years later. Progeny's Bandwidth Chart We made a good Linux distribution, an excellent Debian derivative, but commercial success did not flow from it. In the succeeding months, Ian and the company tried hard to find a strategy that would stick and make our big break. But that never happened. We had several rounds of layoffs when hoped-for funding never materialized. Ian eventually lost control of the company, and despite a few years of Itanium contract work after I left, closed for good. Looking back, Progeny was life compressed. During the good times, we had joy, sense of accomplishment, a sense of purpose at doing something well that was worth doing. I had what was my dream job back then: working on Debian as I loved to do, making the world a better place through Free Software, and getting paid to do it. And during the bad times, different people at Progeny experienced anger, cynicism, apathy, sorrow for the loss of our friends or plans, or simply a feeling to soldier on. All of the emotions, good or bad, were warranted in their own way. Bruce Byfield, one of my co-workers at Progeny, recently wrote a wonderful memoriam of Ian. He wrote, More than anything, he wanted to repeat his accomplishment with Debian, and, naturally he wondered if he could live up to his own expectations of himself. That, I think, was Ian s personal tragedy that he had succeeded early in life, and nothing else he did with his life could quite measure up to his expectations and memories. Ian was not the only one to have some guilt over Progeny. I, for years, wondered if I should have done more for the company, could have saved things by doing something more, or different. But I always came back to the conclusion I had at the time: that there was nothing I could do a terribly sad realization. In the years since, I watched Ubuntu take the mantle of easy-to-install Debian derivative. I saw them reprise some of the ideas we had, and even some of our mistakes. But by that time, Progeny was so thoroughly forgotten that I doubt they even realized they were doing it. I had long looked at our work at Progeny as a failure. Our main goal was never accomplished, our big product never sold many copies, our company eventually shuttered, our rock-the-world plan crumpled and forgotten. And by those traditional measurements, you could say it was a failure. But I have come to learn in the years since that success is a lot more that those things. Success is also about finding meaning and purpose through our work. As a programmer, success is nailing that algorithm that lets the application scale 10x more than before, or solving that difficult problem. As a manager, success is helping team members thrive, watching pieces come together on projects that no one person could ever do themselves. And as a person, success comes from learning from our experiences, and especially our mistakes. As J. Michael Straczynski wrote in a Babylon 5 episode, loosely paraphrased: Maybe this experience will be a good lesson. Too bad it was so painful, but there ain t no other kind. The thing about Progeny is this Ian built a group of people that wanted to change the world for the better. We gave it our all. And there s nothing wrong with that. Progeny did change the world. As us Progeny alumni have scattered around the country, we benefit from the lessons we learned there. And many of us were different , sort of out of place before Progeny, and there we found others that loved C compilers, bootloaders, and GPL licenses just as much as we did. We belonged, not just online but in life, and we went on to pull confidence and skill out of our experience at Progeny and use them in all sorts of ways over the years. And so did Ian. Who could have imagined the founder of Debian and Progeny would one day lead the cause of an old-guard Unix turning Open Source? I run ZFS on my Debian system today, and Ian is partly responsible for that and his time at Progeny is too. So I can remember Ian, and Progeny, as a success. And I leave you with a photo of my best memento from the time there: an original unopened boxed copy of Progeny Linux. IMG_6197_v1

3 January 2016

Carl Chenet: To be alerted if no more tweet is sent from your Twitter account: Twitterwatch

This version 0.1 of Twitterwatch is dedicated to Ian Murdock, Debian project Founder. If you use an automated system like Feed2tweet in order to feed your Twitter account from your website of any RSS feed, it is of the utmost important to know when this system is broken, because you are losing traffic because of this malfunction. At the Journal du hacker, a French-speaking FOSS website where people contribute weblinks like Hacker News or Lobste.rs, every new contribution is sent through the RSS feed to the Twitter account of the Journal du hacker. A lot of our readers only follow the news on Twitter. So if the link breaks, our readers are not fed any more :) To be alerted to this issue, I wrote a small self hosted and documented app. I m proud to introduce Twitterwatch ! It runs with Python 3.4 and the Tweepy library. You can install it from PyPI or from sources. The documentation is available on Readthedocs. You can read about how to install it, configure it and use it. It s the first release but the main features do the job already. In order to use it, you need a twitterwatch.ini file as following:
[twitter]
consumer_key=ml6jaiBnf3pkU9uIrKNIxAr3o
consumer_secret=4Cmljklzerkhfer4hlj3ljl2hfvc123rezrfsdatpokaelzerp
access_token=213416790-jgJnrJG5gz132nzerl5zerwi1ahmnwkfJFN9nr2j
access_token_secret=WjanlPgqDKlunJ4Knr11k2bnfk3jfnwkFjeriFZERj16Z
[schedule]
; duration between 2 checks in minutes
check_interval=60
[mail]
host=localhost
from=admin@myserver.org
to=foo@mylaptop.org
The most difficult part is now complete. To launch Twitterwatch, just launch the following command:
$ twitterwatch /path/to/twitterwatch.ini
Whenever no more new tweet is sent from your Twitter account during 60 minutes, you ll receive the following mail (here the user is @journalduhacker):
Title: Twitter stream of journalduhacker has stopped
Body: Twitter stream of journalduhacker has stopped since 23/12/2015 - 14:49:23
It is still pretty rough, but it does the job. New features will come whenever I need them (or if you require/open bugs/submit push requests ;) ). Write a comment to tell me what you think of it or why you use it!

Lunar: Reproducible builds: week 35 in Stretch cycle

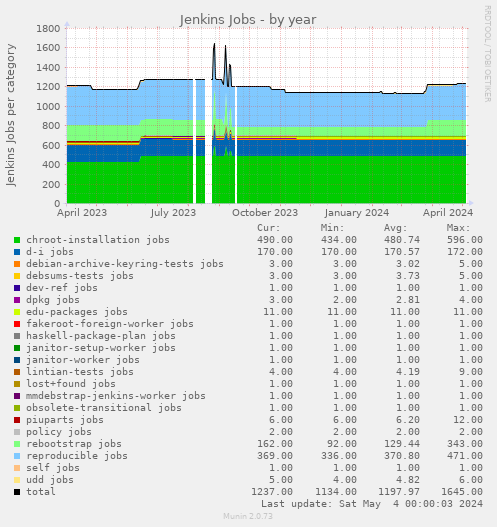
What happened in the reproducible builds effort between December 20th to December 26th: Toolchain fixes Mattia Rizzolo rebased our experimental versions of debhelper (twice!) and dpkg on top of the latest releases. Reiner Herrmann submited a patch for mozilla-devscripts to sort the file list in generated preferences.js files. To be able to lift the restriction that packages must be built in the same path, translation support for the __FILE__ C pre-processor macro would also be required. Joerg Sonnenberger submitted a patch back in 2010 that would still be useful today. Chris Lamb started work on providing a deterministic mode for debootstrap. Packages fixed The following packages have become reproducible due to changes in their build dependencies: bouncycastle, cairo-dock-plug-ins, darktable, gshare, libgpod, pafy, ruby-redis-namespace, ruby-rouge, sparkleshare. The following packages became reproducible after getting fixed: Some uploads fixed some reproducibility issues, but not all of them: Patches submitted which have not made their way to the archive yet: reproducible.debian.net Statistics for package sets are now visible for the armhf architecture. (h01ger) The second build now has a longer timeout (18 hours) than the first build (12 hours). This should prevent wasting resources when a machine is loaded. (h01ger) Builds of Arch Linux packages are now done using a tmpfs. (h01ger) 200 GiB have been added to jenkins.debian.net (thanks to ProfitBricks!) to make room for new jobs. The current count is at 962 and growing! diffoscope development Aside from some minor bugs that have been fixed, a one-line change made huge memory (and time) savings as the output of transformation tool is now streamed line by line instead of loaded entirely in memory at once. disorderfs development Andrew Ayer released disorderfs version 0.4.2-1 on December 22th. It fixes a memory corruption error when processing command line arguments that could cause command line options to be ignored. Documentation update Many small improvements for the documentation on reproducible-builds.org sent by Georg Koppen were merged. Package reviews 666 (!) reviews have been removed, 189 added and 162 updated in the previous week. 151 new fail to build from source reports have been made by Chris West, Chris Lamb, Mattia Rizzolo, and Niko Tyni. New issues identified: unsorted_filelist_in_xul_ext_preferences, nondeterminstic_output_generated_by_moarvm. Misc. Steven Chamberlain drew our attention to one analysis of the Juniper ScreenOS Authentication Backdoor: Whilst this may have been added in source code, it was well-disguised in the disassembly and just 7 instructions long. I thought this was a good example of the current state-of-the-art, and why we'd like our binaries and eventually, installer and VM images reproducible IMHO. Joanna Rutkowska has mentioned possible ways for Qubes to become reproducible on their development mailing-list.

Niels Thykier: Tor enabled MTA

As I posted earlier, I have migrated to use tor on my machine. Though I had a couple of unsolved issues back then. One of them being my Mail Transport Agent (MTA) did not support tor. A regular user might not have a lot of use for a MTA on their laptop. However, it is needed for a lot of Debian development scripts (bts, mass-bug, nmudiff), if they are to file/manipulate bugs for you. I have some requirements for my MTA I also have some non-requirements: Originally, I used postfix, which supported most of these requirements. Except: Per suggestion of Jakub Wilk, I tried msmtp, which turned out do what I wanted. The only feature I will probably miss is having a local queue, which can be rate limited. But all in all, I am quite happy with it so far. :)
Filed under: Debian

Iustin Pop: Orcas Island day trip, June 2015

I just finished going through my last set of pending-review pictures from 2015, so I'm starting 2016 with a post about the past. In June 2015 I travelled to Seattle/Kirkland area for work purposes, and took advantage of a weekend to plan some more outdoors stuff. After looking around on maps, I settled on the San Juan islands, so I started looking at hiking possibilities, and in the end Orcas island looked the best choice - all the others had much lower elevations. So, early in the morning, I started driving from Kirkland to Anacortes ferry terminal. The drive itself is quite nice: after getting past the more populated areas, passing Everett, the the view are very nice, especially in the early morning hours and with very few traffic. At Anacortes, there was already a small queue, fortunately I had a pre-ordered ticket, and there was not much to do until the ferry arrived except to look forward at the day, and hope that the weather will stay nice. On the ferry then, crossing the straits and enjoying the very nice views: Perfect blue Catching the morning wind The ferry stops at Orcas (is it a town or just the terminal), and the next stop is Eastsound town. I pre-planned here a stop to get a second mini-breakfast: however, I misjudged what the portion sizes are and got myself a maxi-cinnamon roll at Caffe Olga: Second breakfast :) At least I knew I wasn't going to be hungry for a while :) Driving on, briefly stopping at Cascade Lake (I also stopped on the way back, the view is nice), then reaching the parking at the Twin Lakes trail on the shore of Mountain Lake. Good think I arrived somewhat early the parking was quite full already. I also got a bit confused on which way the hike starts, since it's not well marked, but after that I started the hike. It's also possible to drive up to Mount Constitution, but that's just lame; hiking from the base it's quite easy, if you find how to start the hike. Anyway: Starting to climb Finished the steepest part At one point, one meets this particular sign: Which way now? Beware the Little Summit is not to be missed! After ~40 minutes of hiking, with some parts a tiny bit strenuous, the view is really breathtaking. It's definitely worth stopping by, as the view is (IMHO) nicer than the view from the top of Mt. Constitution: Wow! The reason I say this is better is because you look towards ocean, whereas later the view is back towards the continent. And looking towards the big ocean is just perfect! Plus, the many small island, fully covered with forest are also nice. Onwards then towards the peak of Mount Constitution. You cross the "ridge" of the island, and your view shifts to the other side. Which means you see back to the Mountain Lake where the hike starts: Loocking back towards the start Here the path is more exposed, not through tall forest like at the beginning: Watching the horizon Right before reaching the peak, you pass through an interesting forest: A different kind of forest And then you're finally reaching the peak. Compared to Switzerland, it's very much not impressive (730m), but nevertheless, being so close to the ocean results in some very nice views: Couldn't have asked for better weather You can go into the small tower, and read through the history of the location, including the personal life of Robert Moran (shipbuilder), who retired in 1905 to Orcas island to live what (his doctors said to be) his last months, and who instead ended living until 1943. Not bad! To be filled under "too much stress is bad, nature is good" heading, I think. After eating a small packed lunch, I started back. At the beginning the forest is similar to the one back at the beginning of the hike, but then, as you reach the level of lakes, it is slightly different. More tall (old?) trees, more moss and ferns: Afternoon sun in the forest I passed briefly by the Twin Lakes, which were interesting (lots of submerged trunks), and then finally on the Twin Lakes trail back to the start. The views of Mountain Lake from here are also nice, especially in the less harsh afternoon sun: Reached Mountain Lake How did those trees get there? And then the hike was over. I still had some time to spend before the ferry I had a ticket on was scheduled, so I drove down to Olga town, as I was curious what was at the end of "Olga Road". Not much, but again nice views, and this very picturesque pier: Nice pier in Olga And then it was back to the ferry, waiting in line, getting on the ferry, and crossing back: Goodbye Orcas! Overall, it was a day well spent, part different, part similar to last year's mostly road trip. Definitely recommended if you're in the area, and there are a couple of other hikes on Orcas Island, plus all the other islands which make up the San Juans. However, traffic on the way back was not that awesome :/ Small price though!

2 January 2016

Daniel Pocock: The great life of Ian Murdock and police brutality in context

Tributes: (You can Follow or Tweet about this blog on Twitter) Over the last week, people have been saying a lot about the wonderful life of Ian Murdock and his contributions to Debian and the world of free software. According to one news site, a San Francisco police officer, Grace Gatpandan, has been doing the opposite, starting a PR spin operation, leaking snippets of information about what may have happened during Ian's final 24 hours. Sadly, these things are now starting to be regurgitated without proper scrutiny by the mainstream press (note the erroneous reference to SFGate with link to SFBay.ca, this is British tabloid media at its best). The report talks about somebody (no suggestion that it was even Ian) "trying to break into a residence". Let's translate that from the spin-doctor-speak back to English: it is the silly season, when many people have a couple of extra drinks and do silly things like losing their keys. "a residence", or just their own home perhaps? Maybe some AirBNB guest arriving late to the irritation of annoyed neighbours? Doesn't the choice of words make the motive sound so much more sinister? Nobody knows the full story and nobody knows if this was Ian, so snippets of information like this are inappropriate, especially when somebody is deceased. Did they really mean to leave people with the impression that one of the greatest visionaries of the Linux world was also a cat burglar? That somebody who spent his life giving selflessly and generously for the benefit of the whole world (his legacy is far greater than Steve Jobs, as Debian comes with no strings attached) spends the Christmas weekend taking things from other people's houses in the dark of the night? The report doesn't mention any evidence of a break-in or any charges for breaking-in. If having a few drinks and losing your keys in December is such a sorry state to be in, many of us could potentially be framed in the same terms at some point in our lives. That is one of the reasons I feel so compelled to write this: somebody else could be going through exactly the same experience at the moment you are reading this. Any of us could end up facing an assault as unpleasant as the tweets imply at some point in the future. At least I can console myself that as a privileged white male, the risk to myself is much lower than for those with mental illness, the homeless, transgender, Muslim or black people but as the tweets suggest, it could be any of us. The story reports that officers didn't actually come across Ian breaking in to anything, they encountered him at a nearby street corner. If he had weapons or drugs or he was known to police that would have almost certainly been emphasized. Is it right to rush in and deprive somebody of their liberties without first giving them an opportunity to identify themselves and possibly confirm if they had a reason to be there? The report goes on, "he was belligerent", "he became violent", "banging his head" all by himself. How often do you see intelligent and successful people like Ian Murdock spontaneously harming themselves in that way? Can you find anything like that in any of the 4,390 Ian Murdock videos on YouTube? How much more frequently do you see reports that somebody "banged their head", all by themselves of course, during some encounter with law enforcement? Do police never make mistakes like other human beings? If any person was genuinely trying to spontaneously inflict a head injury on himself, as the police have suggested, why wouldn't the police leave them in the hospital or other suitable care? Do they really think that when people are displaying signs of self-harm, rounding them up and taking them to jail will be in their best interests? Now, I'm not suggesting this started out with some sort of conspiracy. Police may have been at the end of a long shift (and it is a disgrace that many US police are not paid for their overtime) or just had a rough experience with somebody far more sinister. On the other hand, there may have been a mistake, gaps in police training or an inappropriate use of a procedure that is not always justified, like a strip search, that causes profound suffering for many victims. A select number of US police forces have been shamed around the world for a series of incidents of extreme violence in recent times, including the death of Michael Brown in Ferguson, shooting Walter Scott in the back, death of Freddie Gray in Baltimore and the attempts of Chicago's police to run an on-shore version of Guantanamo Bay. Beyond those highly violent incidents, the world has also seen the abuse of Ahmed Mohamed, the Muslim schoolboy arrested for his interest in electronics and in 2013, the suicide of Aaron Swartz which appears to be a direct consequence of the "Justice" department's obsession with him. What have the police learned from all this bad publicity? Are they changing their methods, or just hiring more spin doctors? If that is their response, then doesn't it leave them with a cruel advantage over those people who were deceased? Isn't it standard practice for some police to simply round up anybody who is a bit lost and write up a charge sheet for resisting arrest or assaulting an officer as insurance against questions about their own excessive use of force? When British police executed Jean Charles de Menezes on a crowded tube train and realized they had just done something incredibly outrageous, their PR office went to great lengths to try and protect their image, even photoshopping images of Menezes to make him look more like some other suspect in a wanted poster. To this day, they continue to refer to Menezes as a victim of the terrorists, could they be any more arrogant? While nobody believes the police woke up that morning thinking "let's kill some random guy on the tube", it is clear they made a mistake and like many people (not just police), they immediately prioritized protecting their reputation over protecting the truth. Nobody else knows exactly what Ian was doing and exactly what the police did to him. We may never know. However, any disparaging or irrelevant comments from the police should be viewed with some caution. The horrors of incarceration It would be hard for any of us to understand everything that an innocent person goes through when detained by the police. The recently released movie about The Stanford Prison Experiment may be an interesting place to start, a German version produced in 2001, Das Experiment, is also very highly respected. The United States has the largest prison population in the world and the second-highest per-capita incarceration rate. Many, including some on death row, are actually innocent, in the wrong place at the wrong time, without the funds to hire an attorney. The system, and the police and prison officers who operate it, treat these people as packages on a conveyor belt, without even the most basic human dignity. Whether their encounter lasts for just a few hours or decades, is it any surprise that something dies inside them when they discover this cruel side of American society? Worldwide, there is an increasing trend to make incarceration as degrading as possible. People may be innocent until proven guilty, but this hasn't stopped police in the UK from locking up and strip-searching over 4,500 children in a five year period, would these children go away feeling any different than if they had an encounter with Jimmy Saville or Rolf Harris? One can only wonder what they do to adults. What all this boils down to is that people shouldn't really be incarcerated unless it is clear the danger they pose to society is greater than the danger they may face in a prison. What can people do for Ian and for justice? Now that these unfortunate smears have appeared, it would be great to try and fill the Internet with stories of the great things Ian has done for the world. Write whatever you feel about Ian's work and your own experience of Debian. While the circumstances of the final tweets from his Twitter account are confusing, the tweets appear to be consistent with many other complaints about US law enforcement. Are there positive things that people can do in their community to help reduce the harm? Sending books to prisoners (the UK tried to ban this) can make a difference. Treat them like humans, even if the system doesn't. Recording incidents of police activities can also make a huge difference, such as the video of the shooting of Walter Scott or the UK police making a brutal unprovoked attack on a newspaper vendor. Don't just walk past a situation and assume everything is under control. People making recordings may find themselves in danger, it is recommended to use software that automatically duplicates each recording, preferably to the cloud, so that if the police ask you to delete such evidence, you can let them watch you delete it and still have a copy. Can anybody think of awards that Ian Murdock should be nominated for, either in free software, computing or engineering in general? Some, like the prestigious Queen Elizabeth Prize for Engineering can't be awarded posthumously but others may be within reach. Come and share your ideas on the debian-project mailing list, there are already some here. Best of all, Ian didn't just build software, he built an organization, Debian. Debian's principles have helped to unite many people from otherwise different backgrounds and carry on those principles even when Ian is no longer among us. Find out more, install it on your computer or even look for ways to participate in the project.

Lunar: Reproducible builds: week 33 in Stretch cycle

What happened in the reproducible builds effort between December 6th and December 12th: Toolchain fixes Reiner Herrmann rebased our experimental version of doxygen on version 1.8.9.1-6. Chris Lamb submitted a patch to make the manpages generated by ruby-ronn reproducible by using the locale-agnostic %Y-%m-%d for the dates. Daniel Kahn Gillmor took another shot at the issue of source path captured in DWARF symbols. A patch has been sent for review by GCC upstream to add the ability to read an environment variable with -fdebug-prefix-map. Packages fixed The following 24 packages have become reproducible due to changes in their build dependencies: gkeyfile-sharp, gprbuild, graphmonkey, gthumb, haskell-yi-language, ion, jackson-databind, jackson-dataformat-smile, jackson-dataformat-xml, jnr-ffi, libcommons-net-java, libproxy, maven-shared-utils, monodevelop-database, mydumper, ndesk-dbus, nini, notify-sharp, pixz, protozero, python-rtslib-fb, slurm-llnl, taglib-sharp, tomboy-latex. The following packages became reproducible after getting fixed: Some uploads fixed some reproducibility issues, but not all of them: These uploads might have fixed reproducibility issues but could not be tested yet: Patches submitted which have not made their way to the archive yet: reproducible.debian.net Files created with diffoscope now have diffoscope in their name instead debbindiff. (h01ger) Hostnames of first and second build node are now recorded and shown in the build history. (Mattia Rizzolo) Exchanges have started with F-Droid developers to better understand what would be required to test F-Droid applications. (h01ger) A first small set of Fedora 23 packages is now also being tested while development on a new framework for testing RPMs in general has begun. A new Jenkins job has been added to set up to mock, the build system used by Fedora. Another new job takes care of testing RPMs from Fedora 23 on x86_64. So far only 151 packages from the buildsys-build group are tested (currently all unreproducible), but the plan is to build all 17,000 source packages in Fedora 23 and rawhide. The page presenting the results should also soon be improved. (h01ger, Dhiru Kholia) For Arch Linux, all 2223 packages from the extra repository will also be tested from now on. Packages in extra" are tested every four weeks, while those from core every week. Statistics are now displayed alongside the results. (h01ger) jenkins.debian.net has been updated to jenkins-job-builder version 1.3.0. Many job configurations have been simplified and refactored using features of the new version. This was another milestone for the jenkins.debian.org migration. (Phil Hands, h01ger) diffoscope development Chris Lamb announced try.diffoscope.org: an online service that runs diffoscope on user provided files. Screenshot of try.diffoscope.org Improvements are welcome. The application is licensed under the AGPLv3. On diffoscope itself, most pending patches have now been merged. Expect a release soon! Most of the code implementing parallel processing has been polished. Sadly, unpacking archive is CPU-bound in most cases, so the current thread-only implementation does not offer much gain on big packages. More work is still require to also add concurrent processes. Documentation update Ximin Luo has started to write a specification for buildinfo files that could become a larger platform than the limited set of features that were thought so far for Debian .buildinfo. Package reviews 113 reviews have been removed, 111 added and 56 updated in the previous week. 42 new FTBFS bugs were opened by Chris Lamb and Niko Tyni. New issues identified this week: timestamps_in_documentation_generated_by_docbook_dbtimestamp, timestamps_in_sym_l_files_generated_by_malaga, timestamps_in_edj_files_generated_by_edje_cc. Misc. Chris Lamb presented reproducible builds at skroutz.gr.

Next.

Previous.