Search Results: "spa"

20 February 2013

Daniel Pocock: Automatically mirroring SVN repositories to git and github

Updated 21 February 2013: the scripts below have now been adapted to run conveniently from cron and mirror multiple repositories. You can find full scripts and documentation on github There are a number of scripts around, including an earlier blog post of my own, for making a once-off conversion of an SVN repository to a Git repository. However, what if the project team is not yet ready for a full move to git? You may want to start benefiting from git (e.g. using the project as a submodule of another git project, or using Travis-CI.org for automated builds) while development officially continues to take place in SVN. If you don't need to make commits into git just now, you can set up a mirror and refresh it periodically from SVN. This process can be used with various SVN repositories, including Sourceforge and Google Code SVN repositories. Process overview
  • An authors.txt file is created manually before the first run.
  • A git-svn clone of the SVN repository is created. This clone needs to be retained between replication runs.
  • On each run, a temporary git repository is created. The svn-clone is rebased and pushed to the fresh git repository.
  • Fixes (e.g. branch renames and tagging) are made in the temporary git repository.
  • The final results are then pushed from the temporary repository to the real git mirror that is being maintained.
  • Finally, the temporary git repository is deleted, but the svn-clone is kept.
Here is a diagram of the workflow: Config file Here is a sample config file for the script, it mirrors the rather complicated reSIProcate repository with 10,000 commits:
PROJECT_ROOT=/home/daniel/svn-mirror/resiprocate
AUTHORS_FILE=$ PROJECT_ROOT /authors.txt
SVN_REPO=https://svn.resiprocate.org/rep/resiprocate
SVN_LAYOUT="--trunk=main --branches=branches --tags=tags"
GIT_REPO=git@github.com:resiprocate/resiprocate.git
Of particular note here:
  • The $PROJECT_ROOT is where the svn-clone and the temporary repositories will be created
  • $GIT_REPO is the final destination repository. For testing, it could just be a local directory initialised with git init --bare .
  • In this repository, our trunk is actually called main, hence we have the layout argument --trunk=main. Many projects would just use --trunk=trunk
The script The script itself is below. I'd suggest running it manually a few times first and observing how it behaves, disk space requirements, etc.
#!/bin/bash
set -e
if [ ! $# -eq 1 ];
then
  echo "Usage:"
  echo "$0 <config-file>"
  exit 1
fi
CONFIG_FILE="$1"
. "$ CONFIG_FILE "   exit 1
SVN_CLONE="$ PROJECT_ROOT /svn-clone"
GIT_BARE="$ PROJECT_ROOT /git-bare-tmp"
if [ ! -d "$ PROJECT_ROOT " ];
then
  mkdir -p "$ PROJECT_ROOT "
fi
cd "$ PROJECT_ROOT "
if [ ! -d "$ SVN_CLONE " ];
then
  git svn clone \
    "$ SVN_REPO " \
    -A "$ AUTHORS_FILE " \
    $ SVN_LAYOUT  \
    "$ SVN_CLONE "
  cd "$ SVN_CLONE "
else
  cd "$ SVN_CLONE "
  git remote rm bare   echo "failed to delete remote:bare, proceeding anyway"
  git svn rebase \
    --fetch-all \
    -A "$ AUTHORS_FILE "
fi
git remote add bare "$ GIT_BARE "
git config remote.bare.push 'refs/remotes/*:refs/heads/*'
if [ -d "$ GIT_BARE " ];
then
  rm -rf "$ GIT_BARE "
fi
mkdir -p "$ GIT_BARE "
cd "$ GIT_BARE "
git init --bare .
git symbolic-ref HEAD refs/heads/trunk
cd "$ SVN_CLONE "
git push bare
cd "$ GIT_BARE "
git branch -m trunk master
git for-each-ref --format='%(refname)' refs/heads/tags   \
   cut -d / -f 4   \
   while read ref;
   do
      git tag "$ref" "refs/heads/tags/$ref"
      git branch -D "tags/$ref"
   done
git remote add origin "$ GIT_REPO "
git config branch.master.remote origin
git config branch.master.merge refs/heads/master
git push --tags origin master
git push --all
rm -rf "$ GIT_BARE "
</config-file>
AttachmentSize
svn-mirror.png32.65 KB

Daniel Pocock: Automatically mirroring SVN repositories to git and github

Updated 21 February 2013: the scripts below have now been adapted to run conveniently from cron and mirror multiple repositories. You can find full scripts and documentation on github There are a number of scripts around, including an earlier blog post of my own, for making a once-off conversion of an SVN repository to a Git repository. However, what if the project team is not yet ready for a full move to git? You may want to start benefiting from git (e.g. using the project as a submodule of another git project, or using Travis-CI.org for automated builds) while development officially continues to take place in SVN. If you don't need to make commits into git just now, you can set up a mirror and refresh it periodically from SVN. This process can be used with various SVN repositories, including Sourceforge and Google Code SVN repositories. Process overview
  • An authors.txt file is created manually before the first run - see my other blog entry for convenient scripts to help generate authors.txt
  • A git-svn clone of the SVN repository is created. This clone needs to be retained between replication runs.
  • On each run, a temporary git repository is created. The svn-clone is rebased and pushed to the fresh git repository.
  • Fixes (e.g. branch renames and tagging) are made in the temporary git repository.
  • The final results are then pushed from the temporary repository to the real git mirror that is being maintained.
  • Finally, the temporary git repository is deleted, but the svn-clone is kept.
Here is a diagram of the workflow: Config file Here is a sample config file for the script, it mirrors the rather complicated reSIProcate repository with 10,000 commits:
PROJECT_ROOT=/home/daniel/svn-mirror/resiprocate
AUTHORS_FILE=$ PROJECT_ROOT /authors.txt
SVN_REPO=https://svn.resiprocate.org/rep/resiprocate
SVN_LAYOUT="--trunk=main --branches=branches --tags=tags"
GIT_REPO=git@github.com:resiprocate/resiprocate.git
Of particular note here:
  • The $PROJECT_ROOT is where the svn-clone and the temporary repositories will be created
  • $GIT_REPO is the final destination repository. For testing, it could just be a local directory initialised with git init --bare .
  • In this repository, our trunk is actually called main, hence we have the layout argument --trunk=main. Many projects would just use --trunk=trunk
The script The script itself is below. I'd suggest running it manually a few times first and observing how it behaves, disk space requirements, etc.
#!/bin/bash
set -e
if [ ! $# -eq 1 ];
then
  echo "Usage:"
  echo "$0 <config-file>"
  exit 1
fi
CONFIG_FILE="$1"
. "$ CONFIG_FILE "   exit 1
SVN_CLONE="$ PROJECT_ROOT /svn-clone"
GIT_BARE="$ PROJECT_ROOT /git-bare-tmp"
if [ ! -d "$ PROJECT_ROOT " ];
then
  mkdir -p "$ PROJECT_ROOT "
fi
cd "$ PROJECT_ROOT "
if [ ! -d "$ SVN_CLONE " ];
then
  git svn clone \
    "$ SVN_REPO " \
    -A "$ AUTHORS_FILE " \
    $ SVN_LAYOUT  \
    "$ SVN_CLONE "
  cd "$ SVN_CLONE "
else
  cd "$ SVN_CLONE "
  git remote rm bare   echo "failed to delete remote:bare, proceeding anyway"
  git svn rebase \
    --fetch-all \
    -A "$ AUTHORS_FILE "
fi
git remote add bare "$ GIT_BARE "
git config remote.bare.push 'refs/remotes/*:refs/heads/*'
if [ -d "$ GIT_BARE " ];
then
  rm -rf "$ GIT_BARE "
fi
mkdir -p "$ GIT_BARE "
cd "$ GIT_BARE "
git init --bare .
git symbolic-ref HEAD refs/heads/trunk
cd "$ SVN_CLONE "
git push bare
cd "$ GIT_BARE "
git branch -m trunk master
git for-each-ref --format='%(refname)' refs/heads/tags   \
   cut -d / -f 4   \
   while read ref;
   do
      git tag "$ref" "refs/heads/tags/$ref"
      git branch -D "tags/$ref"
   done
git remote add origin "$ GIT_REPO "
git config branch.master.remote origin
git config branch.master.merge refs/heads/master
git push --tags origin master
git push --all
rm -rf "$ GIT_BARE "
</config-file>
AttachmentSize
svn-mirror.png32.65 KB

Ryan Kavanagh: Search RCS and CVS ",v" files with rcsgrep

A few years ago I was doing research comparing how large software distributions handled shared object libraries, and studied Debian, FreeBSD, and Ubuntu. Extracting data about Debian packages was easy thanks to Peter Palfrader s snapshot.debian.org service, which provides a machine-usable interface to Debian s package history. FreeBSD s data is equally accessible, albeit in a less pleasant format: their ports tree was stored in CVS until July 2012. One could easily rsync a copy of the ports tree s CVS repository to a local machine to analyze the data. This left you with a local tree full of ,v files, each corresponding to the history of a given file with at that location. I needed to extract all kinds of data from a tree full of these files, such as what revisions contained lines matching a regex, when these revisions were checked in, any tags associated with it, etc. To make things easier, it also helped to know the line numbers of the matching lines. Hence the birth of rcsgrep. rcsgrep is a Python script that makes use of Paul McGuire s fabulous pyparsing library. It allows you to search a RCS file (the ,v file format used by RCS and CVS to store revision history) using a Python regex, and the output format is customizable to allow printing only certain kinds of information, such as the revision number, the line number, the matching line, the line s author, the date it appeared, any tags associated with the line, and (useful when running over a large number of files) the file name. To make machine parsing (using AWK of course) easier, you can also specify the column separator. For example, I entered the lines The quick brown , fox jumped over , the lazy dog. Woof! into the file abc, checking in the changes after each line. The invocation ./rcsgrep -s ' ' -f rlLda '.*' abc,v, with spaces for column separation, and format options r is for revision, l for line number, L for line contents, d for date, and a for author, outputs:
1.3    1    The quick brown    2013.02.20.14.24.09    ryan
1.3    2    jumped over the    2013.02.20.14.24.09    ryan
1.3    3    lazy dog. Woof!    2013.02.20.14.24.09    ryan
1.2    1    The quick brown    2013.02.20.14.23.48    ryan
1.2    2    jumped over the    2013.02.20.14.23.48    ryan
1.1    1    The quick brown    2013.02.20.14.23.25    ryan
I m particularly proud about my grep() function in rcsfile.py, which goes through each revision, tracking additions and deletions, but only keeping the lines matching the regex in memory. In any case, rcsgrep is licensed under the ISC license and can be found on github. Addendum: I learned after the fact that O Reilly s UNIX Power Tools offers something similar by the same name, except that it is runs several processes, such as co, grep and sed, as opposed to a single Python script.

Vincent Bernat: lldpd 0.7.1

A few weeks ago, a new version of lldpd, a 802.1AB (aka LLDP) implementation for various Unices, has been released. LLDP is an industry standard protocol designed to supplant proprietary Link-Layer protocols such as EDP or CDP. The goal of LLDP is to provide an inter-vendor compatible mechanism to deliver Link-Layer notifications to adjacent network devices. In short, LLDP allows you to know exactly on which port is a server (and reciprocally). To illustrate its use, I have made a xkcd-like strip: xkcd-like strip for the use of LLDP If you would like more information about lldpd, please have a look at its new dedicated website. This blog post is an insight of various technical changes that have affected lldpd since its latest major release one year ago. Lots of C stuff ahead!

Version & changelog UPDATED: Guillem Jover told me how he met the same goals for libbsd :
  1. Save the version from git into .dist-version and use this file if it exists. This allows one to rebuild ./configure from the published tarball without losing the version. This also handles Thorsten Glaser s critic.
  2. Include CHANGELOG in DISTCLEANFILES variable.
Since this is a better solution, I have adopted the appropriate line of codes from libbsd. The two following sections are partly technically outdated.

Automated version In configure.ac, I was previously using a static version number that I had to increase when releasing:
AC_INIT([lldpd], [0.5.7], [bernat@luffy.cx])
Since the information is present in the git tree, this seems a bit redundant (and easy to forget). Taking the version from the git tree is easy:
AC_INIT([lldpd],
        [m4_esyscmd_s([git describe --tags --always --match [0-9]* 2> /dev/null   date +%F])],
        [bernat@luffy.cx])
If the head of the git tree is tagged, you get the exact tag (0.7.1 for example). If it is not, you get the nearest one, the number of commits since it and part of the current hash (0.7.1-29-g2909519 for example). The drawback of this approach is that if you rebuild configure from the released tarball, you don t have the git tree and the version will be a date. Just don t do that.

Automated changelog Generating the changelog from git is a common practice. I had some difficulties to make it right. Here is my attempt (I am using automake):
dist_doc_DATA = README.md NEWS ChangeLog
.PHONY: $(distdir)/ChangeLog
dist-hook: $(distdir)/ChangeLog
$(distdir)/ChangeLog:
        $(AM_V_GEN)if test -d $(top_srcdir)/.git; then \
          prev=$$(git describe --tags --always --match [0-9]* 2> /dev/null) ; \
          for tag in $$(git tag   grep -E '^[0-9]+(\.[0-9]+) 1, $$'   sort -rn); do \
            if [ x"$$prev" = x ]; then prev=$$tag ; fi ; \
            if [ x"$$prev" = x"$$tag" ]; then continue; fi ; \
            echo "$$prev [$$(git log $$prev -1 --pretty=format:'%ai')]:" ; \
            echo "" ; \
            git log --pretty=' - [%h] %s (%an)' $$tag..$$prev ; \
            echo "" ; \
            prev=$$tag ; \
          done > $@ ; \
        else \
          touch $@ ; \
        fi
ChangeLog:
        touch $@
Changelog entries are grouped by version. Since it is a bit verbose, I still maintain a NEWS file with important changes.

Core

C99 I have recently read 21st Century C which has some good bits and also handles the ecosystem around C. I have definitively adopted designated initializers in my coding style. Being a GCC extension since a long time, this is not a major compatibility problem. Without designated initializers:
struct netlink_req req;
struct iovec iov;
struct sockaddr_nl peer;
struct msghdr rtnl_msg;
memset(&req, 0, sizeof(req));
memset(&iov, 0, sizeof(iov));
memset(&peer, 0, sizeof(peer));
memset(&rtnl_msg, 0, sizeof(rtnl_msg));
req.hdr.nlmsg_len = NLMSG_LENGTH(sizeof(struct rtgenmsg));
req.hdr.nlmsg_type = RTM_GETLINK;
req.hdr.nlmsg_flags = NLM_F_REQUEST   NLM_F_DUMP;
req.hdr.nlmsg_seq = 1;
req.hdr.nlmsg_pid = getpid();
req.gen.rtgen_family = AF_PACKET;
iov.iov_base = &req;
iov.iov_len = req.hdr.nlmsg_len;
peer.nl_family = AF_NETLINK;
rtnl_msg.msg_iov = &iov;
rtnl_msg.msg_iovlen = 1;
rtnl_msg.msg_name = &peer;
rtnl_msg.msg_namelen = sizeof(struct sockaddr_nl);
With designated initializers:
struct netlink_req req =  
    .hdr =  
        .nlmsg_len = NLMSG_LENGTH(sizeof(struct rtgenmsg)),
        .nlmsg_type = RTM_GETLINK,
        .nlmsg_flags = NLM_F_REQUEST   NLM_F_DUMP,
        .nlmsg_seq = 1,
        .nlmsg_pid = getpid()  ,
    .gen =   .rtgen_family = AF_PACKET  
 ;
struct iovec iov =  
    .iov_base = &req,
    .iov_len = req.hdr.nlmsg_len
 ;
struct sockaddr_nl peer =   .nl_family = AF_NETLINK  ;
struct msghdr rtnl_msg =  
    .msg_iov = &iov,
    .msg_iovlen = 1,
    .msg_name = &peer,
    .msg_namelen = sizeof(struct sockaddr_nl)
 ;

Logging Logging in lldpd was not extensive. Usually, when receiving a bug report, I asked the reporter to add some additional printf() calls to determine where the problem was. This was clearly suboptimal. Therefore, I have added many log_debug() calls with the ability to filter out some of them. For example, to debug interface discovery, one can run lldpd with lldpd -ddd -D interface. Moreover, I have added colors when logging to a terminal. This may seem pointless but it is now far easier to spot warning messages from debug ones. logging output of lldpd

libevent In lldpd 0.5.7, I was using my own select()-based event loop. It worked but I didn t want to grow a full-featured event loop inside lldpd. Therefore, I switched to libevent. The minimal required version of libevent is 2.0.5. A convenient way to check the changes in API is to use Upstream Tracker, a website tracking API and ABI changes for various libraries. This version of libevent is not available in many stable distributions. For example, Debian Squeeze or Ubuntu Lucid only have 1.4.13. I am also trying to keep compatibility with very old distributions, like RHEL 2, which does not have a packaged libevent at all. For some users, it may be a burden to compile additional libraries. Therefore, I have included libevent source code in lldpd source tree (as a git submodule) and I am only using it if no suitable system libevent is available. Have a look at m4/libevent.m4 and src/daemon/Makefile.am to see how this is done.

Client

Serialization lldpctl is a client querying lldpd to display discovered neighbors. The communication is done through an Unix socket. Each structure to be serialized over this socket should be described with a string. For example:
#define STRUCT_LLDPD_DOT3_MACPHY "(bbww)"
struct lldpd_dot3_macphy  
        u_int8_t                 autoneg_support;
        u_int8_t                 autoneg_enabled;
        u_int16_t                autoneg_advertised;
        u_int16_t                mau_type;
 ;
I did not want to use stuff like Protocol Buffers because I didn t want to copy the existing structures to other structures before serialization (and the other way after deserialization). However, the serializer in lldpd did not allow to handle reference to other structures, lists or circular references. I have written another one which works by annotating a structure with some macros:
struct lldpd_chassis  
    TAILQ_ENTRY(lldpd_chassis) c_entries;
    u_int16_t        c_index;
    u_int8_t         c_protocol;
    u_int8_t         c_id_subtype;
    char            *c_id;
    int              c_id_len;
    char            *c_name;
    char            *c_descr;
    u_int16_t        c_cap_available;
    u_int16_t        c_cap_enabled;
    u_int16_t        c_ttl;
    TAILQ_HEAD(, lldpd_mgmt) c_mgmt;
 ;
MARSHAL_BEGIN(lldpd_chassis)
MARSHAL_TQE  (lldpd_chassis, c_entries)
MARSHAL_FSTR (lldpd_chassis, c_id, c_id_len)
MARSHAL_STR  (lldpd_chassis, c_name)
MARSHAL_STR  (lldpd_chassis, c_descr)
MARSHAL_SUBTQ(lldpd_chassis, lldpd_mgmt, c_mgmt)
MARSHAL_END;
Only pointers need to be annotated. The remaining of the structure can be serialized with just memcpy()1. I think there is still room for improvement. It should be possible to add annotations inside the structure and avoid some duplication. Or maybe, using a C parser? Or using the AST output from LLVM?

Library In lldpd 0.5.7, there are two possible entry points to interact with the daemon:
  1. Through SNMP support. Only information available in LLDP-MIB are exported. Therefore, implementation-specific values are not available. Moreover, SNMP support is currently read-only.
  2. Through lldpctl. Thanks to a contribution from Andreas Hofmeister, the output can be requested to be formatted as an XML document.
Integration of lldpd into a network stack was therefore limited to one of those two channels. As an exemple, you can have a look at how Vyatta made the integration using the second solution. To provide a more robust solution, I have added a shared library, liblldpctl, with a stable and well-defined API. lldpctl is now using it. I have followed those directions2:
  • Consistent naming (all exported symbols are prefixed by lldpctl_). No pollution of the global namespace.
  • Consistent return codes (on errors, all functions returning pointers are returning NULL, all functions returning integers are returning -1).
  • Reentrant and thread-safe. No global variables.
  • One well-documented include file.
  • Reduce the use of boilerplate code. Don t segfault on NULL, accept integer input as string, provide easy iterators,
  • Asynchronous API for input/output. The library delegates reading and writing by calling user-provided functions. Those functions can yield their effects. In this case, the user has to callback the library when data is available for reading or writing. It is therefore possible to integrate the library with any existing event-loop. A thin synchronous layer is provided on top of this API.
  • Opaque types with accessor functions.
Accessing bits of information is done through atoms which are opaque containers of type lldpctl_atom_t. From an atom, you can extract some properties as integers, strings, buffers or other atoms. The list of ports is an atom. A port in this list is also an atom. The list of VLAN present on this port is an atom, as well as each VLAN in this list. The VLAN name is a NULL-terminated string living in the scope of an atom. Accessing a property is done by a handful of functions, like lldpctl_atom_get_str(), using a specific key. For example, here is how to display the list of VLAN assuming you have one port as an atom:
vlans = lldpctl_atom_get(port, lldpctl_k_port_vlans);
lldpctl_atom_foreach(vlans, vlan)  
    vid = lldpctl_atom_get_int(vlan,
                               lldpctl_k_vlan_id));
    name = lldpctl_atom_get_str(vlan,
                                lldpctl_k_vlan_name));
    if (vid && name)
        printf("VLAN %d: %s\n", vid, name);
 
lldpctl_atom_dec_ref(vlans);
Internally, an atom is typed and reference counted. The size of the API is greatly limited thanks to this concept. There are currently more than one hundred pieces of information that can be retrieved from lldpd. Ultimately, the library will also enable the full configuration of lldpd. Currently, many aspects can only be configured through command-line flags. The use of the library does not replace lldpctl which will still be available and be the primary client of the library.

CLI Having a configuration file was requested since a long time. I didn t want to include a parser in lldpd: I am trying to keep it small. It was already possible to configure lldpd through lldpctl. Locations, network policies and power policies were the three items that could be configured this way. So, the next step was to enable lldpctl to read a configuration file, parse it and send the result to lldpd. As a bonus, why not provide a full CLI accepting the same statements with inline help and completion?

Parsing & completion Because of completion, it is difficult to use a YACC generated parser. Instead, I define a tree where each node accepts a word. A node is defined with this function:
struct cmd_node *commands_new(
    struct cmd_node *,
    const char *,
    const char *,
    int(*validate)(struct cmd_env*, void *),
    int(*execute)(struct lldpctl_conn_t*, struct writer*,
        struct cmd_env*, void *),
    void *);
A node is defined by:
  • its parent,
  • an optional accepted static token,
  • an help string,
  • an optional validation function and
  • an optional function to execute if the current token is accepted.
When walking the tree, we maintain an environment which is both a key-value store and a stack of positions in the tree. The validation function can check the environment to see if we are in the right context (we want to accept the keyword foo only once, for example). The execution function can add the current token as a value in the environment but it can also pop the current position in the tree to resume walk from a previous node. As an example, see how nodes for configuration of a coordinate-based location are registered:
/* Our root node */
struct cmd_node *configure_medloc_coord = commands_new(
    configure_medlocation,
    "coordinate", "MED location coordinate configuration",
    NULL, NULL, NULL);
/* The exit node.
   The validate function will check if we have both
   latitude and longitude. */
commands_new(configure_medloc_coord,
    NEWLINE, "Configure MED location coordinates",
    cmd_check_env, cmd_medlocation_coordinate,
    "latitude,longitude");
/* Store latitude. Once stored, we pop two positions
   to go back to the "root" node. The user can only
   enter latitude once. */
commands_new(
    commands_new(
        configure_medloc_coord,
        "latitude", "Specify latitude",
        cmd_check_no_env, NULL, "latitude"),
    NULL, "Latitude as xx.yyyyN or xx.yyyyS",
    NULL, cmd_store_env_value_and_pop2, "latitude");
/* Same thing for longitude */
commands_new(
    commands_new(
        configure_medloc_coord,
        "longitude", "Specify longitude",
        cmd_check_no_env, NULL, "longitude"),
    NULL, "Longitude as xx.yyyyE or xx.yyyyW",
    NULL, cmd_store_env_value_and_pop2, "longitude");
The definition of all commands is still a bit verbose but the system is simple enough yet powerful enough to cover all needed cases.

Readline When faced with a CLI, we usually expect some perks like completion, history handling and help. The most used library to provide such features is the GNU Readline Library. Because this is a GPL library, I have first searched an alternative. There are several of them: From an API point of view, the first three libraries support the GNU Readline API. They also have a common native API. Moreover, this native API also handles tokenization. Therefore, I have developed the first version of the CLI with this API3. Unfortunately, I noticed later this library is not very common in the Linux world and is not available in RHEL. Since I have used the native API, it was not possible to fallback to the GNU Readline library. So, let s switch! Thanks to the appropriate macro from the Autoconf Archive (with small modifications), the compilation and linking differences between the libraries are taken care of. Because GNU Readline library does not come with a tokenizer, I had to write one myself. The API is also badly documented and it is difficult to know which symbol is available in which version. I have limited myself to:
  • readline(), addhistory(),
  • rl_insert_text(),
  • rl_forced_update_display(),
  • rl_bind_key()
  • rl_line_buffer and rl_point.
Unfortunately, the various libedit libraries have a noop for rl_bind_key(). Therefore, completion and online help is not available with them. I have noticed that most BSD come with GNU Readline library preinstalled, so it could be considered as a system library. Nonetheless, linking with libedit to avoid licensing issues is possible and help can be obtained by prefixing the command with help.

OS specific support

BSD support Until version 0.7, lldpd was Linux-only. The rewrite to use Netlink was the occasion to abstract interfaces and to port to other OS. The first port was for Debian GNU/kFreeBSD, then for FreeBSD, OpenBSD and NetBSD. They all share the same source code:
  • getifaddrs() to get the list of interfaces,
  • bpf(4) to attach to an interface to receive and send packets,
  • PF_ROUTE socket to be notified when a change happens.
Each BSD has its own ioctl() to retrieve VLAN, bridging and bonding bits but they are quite similar. The code was usually adapted from ifconfig.c. The BSD ports have the same functionalities than the Linux port, except for NetBSD which lacks support for LLDP-MED inventory since I didn t find a simple way to retrieve DMI related information. They also offer greater security by filtering packets sent. Moreover, OpenBSD allows to lock the filters set on the socket:
/* Install write filter (optional) */
if (ioctl(fd, BIOCSETWF, (caddr_t)&fprog) < 0)  
    rc = errno;
    log_info("privsep", "unable to setup write BPF filter for %s",
        name);
    goto end;
 
/* Lock interface */
if (ioctl(fd, BIOCLOCK, (caddr_t)&enable) < 0)  
    rc = errno;
    log_info("privsep", "unable to lock BPF interface %s",
        name);
    goto end;
 
This is a very nice feature. lldpd is using a privileged process to open the raw socket. The socket is then transmitted to an unprivileged process. Without this feature, the unprivileged process can remove the BPF filters. I have ported the ability to lock a socket filter program to Linux. However, I still have to add a write filter.

OS X support Once FreeBSD was supported, supporting OS X seemed easy. I got sponsored by xcloud.me which provided a virtual Mac server. Making lldpd work with OS X took only two days, including a full hour to guess how to get Apple Xcode without providing a credit card. To help people installing lldpd on OS X, I have also written a lldpd formula for Homebrew which seems to be the most popular package manager for OS X.

Upstart and systemd support Many distributions propose upstart and systemd as a replacement or an alternative for the classic SysV init. Like most daemons, lldpd detaches itself from the terminal and run in the background, by forking twice, once it is ready (for lldpd, this just means we have setup the control socket). While both upstart and systemd can accommodate daemons that behave like this, it is recommended to not fork. How to advertise readiness in this case? With upstart, lldpd will send itself the SIGSTOP signal. upstart will detect this, resume lldpd with SIGCONT and assume it is ready. The code to support upstart is therefore quite simple. Instead of calling daemon(), do this:
const char *upstartjob = getenv("UPSTART_JOB");
if (!(upstartjob && !strcmp(upstartjob, "lldpd")))
    return 0;
log_debug("main", "running with upstart, don't fork but stop");
raise(SIGSTOP);
The job configuration file looks like this:
# lldpd - LLDP daemon
description "LLDP daemon"
start on net-device-up IFACE=lo
stop on runlevel [06]
expect stop
respawn
script
  . /etc/default/lldpd
  exec lldpd $DAEMON_ARGS
end script
systemd provides a socket to achieve the same goal. An application is expected to write READY=1 to the socket when it is ready. With the provided library, this is just a matter of calling sd_notify("READY=1\n"). Since sd_notify() has less than 30 lines of code, I have rewritten it to avoid an external dependency. The appropriate unit file is:
[Unit]
Description=LLDP daemon
Documentation=man:lldpd(8)
[Service]
Type=notify
NotifyAccess=main
EnvironmentFile=-/etc/default/lldpd
ExecStart=/usr/sbin/lldpd $DAEMON_ARGS
Restart=on-failure
[Install]
WantedBy=multi-user.target

OS include files Linux-specific include files were a major pain in previous versions of lldpd. The problems range from missing header files (like linux/if_bonding.h) to the use of kernel-only types. Those headers have a difficult history. They were first shipped with the C library but were rarely synced and almost always outdated. They were then extracted from kernel version with almost no change and lagged behind the kernel version used by the released distribution4. Today, the problem is acknowledged and is being solved by both the distributions which extract the headers from the packaged kernel and by kernel developers with a separation of kernel-only headers from user-space API headers. However, we still need to handle legacy. A good case is linux/ethtool.h:
  • It can just be absent.
  • It can use u8, u16 types which are kernel-only types. To work around this issue, type munging can be setup.
  • It can miss some definition, like SPEED_10000. In this case, you either define the missing bits and find yourself with a long copy of the original header interleaved with #ifdef or conditionally use each symbol. The latest solution is a burden by itself but it also hinders some functionalities that can be available in the running kernel.
The easy solution to all this mess is to just include the appropriate kernel headers into the source tree of the project. Thanks to Google ripping them for its Bionic C library, we know that copying kernel headers into a program does not create a derivative work.

  1. Therefore, the use of u_int16_t and u_int8_t types is a left-over of the previous serializer where the size of all members was important.
  2. For more comprehensive guidelines, be sure to check Writing a C library.
  3. Tokenization is not the only advantage of libedit native API. The API is also cleaner, does not have a global state and has a better documentation. All the implementations are also BSD licensed.
  4. For example, in Debian Sarge, the Linux kernel was a 2.6.8 (2004) while the kernel headers were extracted from some pre-2.6 kernel.

Gunnar Wolf: "No al voto electr nico", Triple W, W Radio

Title"No al voto electr nico", Triple W, W Radio
Publication TypeBroadcast
Year of Publication2013
AuthorsWolf G, Ruiz O
Refereed DesignationNon-Refereed
Keywordse-vote
URLhttp://www.wradio.com.mx/escucha/programas/voto-electronico-octavio-ruiz-y-kunar-wolf-analistas-190213/20130219/programa/1789792.aspx?au=1845636
Full TextIn yet another episode where we push for the population to be aware of the perils that electronic voting represents, Octavio Ruiz (@tacvbo) and me were invited to (briefly) talk about the topic in W Radio, one of the largest radio networks in Mexico.
The interview was short-ish, but we managed to get several points accross. And, of course, one of the best ways to do so is via a radio show with tens of thousands of listeners. So, we were quite happy to be there!
Here is the audio of the segment we presented in Fernanda Tapia's radio show "Triple W", in W Radio, Mexico.
AttachmentSize
Tripe W - Entrevista: no al voto electronico9.97 MB

19 February 2013

Ingo Juergensmann: LVM on RAID5 broken - how to fix?

Some time ago one of my disks in my Software RAID5 failed. No big problem as I had two spare A08U-C2412 available to replace that single 1 TB SATA disk. I can't remember any details but somewhat went wrong and I ended up with a non-booting system. I think I tried to add the HW-RAID as a physical volume to the LVM and thought of migrating the SW-RAID to the HW-RAID or do mirroring or such. Anyway: I booted into my rescue system that was on a RAID1 partition on those disks, but LVM didn't came up anymore, because the SW-RAID5 wasn't recognized during boot. So I re-created the md device and discovered that my PV was gone as well. =:-0 No, big deal, I thought, because I have a backup of that machine on another host. I restored /etc/lvm and tried to do a vgcfgrestore after I re-created the PV with pvcreate. First I didn't use the old UUID, so vgcfgrestore complained. After creating the proper PV with UUID LVM did recognize the PV, VG and LVs. Unfortunately I can't mount any of the LVs. Something seems to be broken:
hahn-rescue:~# mount /dev/vg/sys /mnt
mount: you must specify the filesystem type
Feb 19 07:50:02 hahn-rescue kernel: [748288.740949] XFS (dm-0): bad magic number
Feb 19 07:50:02 hahn-rescue kernel: [748288.741009] XFS (dm-0): SB validate failed
Running a gpart scan on my SW-RAID5 did gave me some results:
hahn-rescue:~# gpart /dev/md3
Begin scan...
Possible partition(SGI XFS filesystem), size(20470mb), offset(5120mb)
Possible partition(SGI XFS filesystem), size(51175mb), offset(28160mb)
Possible partition(SGI XFS filesystem), size(1048476mb), offset(117760mb)
Possible partition(SGI XFS filesystem), size(204787mb), offset(1168640mb)
Possible partition(SGI XFS filesystem), size(204787mb), offset(1418240mb)
Possible partition(SGI XFS filesystem), size(1048476mb), offset(1626112mb)
*** Fatal error: dev(/dev/md3): seek failure.
These is not the complete lists of VM as a comparison to the output of lvs shows:
hahn-rescue:~# lvs
  LV                 VG   Attr     LSize   Pool Origin Data%  Move Log Copy%  Convert
  storage1           lv   -wi-ao--   1.00t                                          
  AmigaSeagateElite3 vg   -wi-a---   3.00g                                          
  audio              vg   -wi-a---  70.00g                                          
  backup             vg   -wi-a---   1.00t                                          
  data               vg   -wi-a---  50.00g                                          
  hochzeit           vg   -wi-a---  40.00g                                          
  home               vg   -wi-a---   5.00g                                          
  pics               vg   -wi-a--- 200.00g                                          
  sys                vg   -wi-a---  20.00g                                          
  video              vg   -wi-a--- 100.00g                                          
  windata            vg   -wi-a--- 100.00g   
Please notice that /dev/lv/storage1 is my HW-RAID where I stored the images of /dev/vg/-LVs to run xfs_repair and such on. Anyway, the sizes of the recognized XFS partitions by gpart is mostly correct, but some a missing and xfs_repair can not do anything good on the backup images on storage1. Everything ends up in /lost+found, because the blocks seem to be mixed up somehow. What I figured out is, that my old RAID5 device was in metaformat=1.2 whereas the new one is in format 0.9. My best guess is now to recreate the RAID5 device with format 1.2, do a vgcfgrestore on that and have (hopefully!) a working LVM with working LVs back that I can then mount again. If there's anything else I might be able to try, dear Lazyweb, please tell me. Please see the attached config files/tarballs for a complete overview. Side note: except for AmigaSeagateElite3, which is a dd image of an old Amiga SCSI disk, I should have a fairly complete backup on my second backup location, so there's not much lost, but I would be a real timesaver when I would be able to recover the lost LVs. Both systems are behind DSL/cable and have a limit of 10 Mbps upstream. It would take weeks to transfer the data and sending an USB disk would be faster.
AttachmentSize
mdadm.conf_.txt954 bytes
hahn-lvm-restore.tar.gz14.7 KB
Kategorie:

18 February 2013

Dirk Eddelbuettel: RQuantLib 0.3.10

A new minor release RQuantLib 0.3.10 is now on CRAN and in Debian. RQuantLib combines (some of) the quantitative analytics of QuantLib with the R statistical computing environment and language. The discount curve building code in QuantLib has shown some overly large numerical instabilities. We have used the same example parameters (taken from the Swap example in QuantLib) for years; it currently fails to solve for a rate at some term further out the curve. So I made the decistion to disable this just in the examples in order to not upset the CRAN testing framework. The examples now use a flat curve instead. I also updated one function to silence some new warnings from R-devel about symbols from another packages's namespace (in this case rgl, and it is just for surface plots, a purely cosmetic function). Thanks to CRANberries, there is also a diff to the previous release 0.3.9. Full changelog details, examples and more details about this package are at my RQuantLib page.

15 February 2013

Robert Collins: More subunit needs

Of course, as happens sadly often, the scope creeps.. Additional pain points Zope s test runner runs things that are not tests, but which users want to know about layers . At the moment these are reported as individual tests, but this is problematic in a couple of ways. Firstly, the same test runs on multiple backend runners, so timing and stats get more complex. Secondly, if a layer fails to setup or teardown, tools like testrepository that have watched the stream will think a test failed, and on the next run try to explicitly run that test but that test doesn t really exist, so it won t run [unless an actual test that needs the layer is being run]. Openstack uses python coverage to gather coverage statistics during test runs. Each worker running tests needs to gather and return such statistics. The current subunit protocol has no space to hand this around, without it pretending to be a test [see a pattern here?]. And that has the same negative side effect test runners like testrepository will try to run that test . While testrepository doesn t want to know about coverage itself, it would be nice to be able to pass everything around and have a local hook handle the aggregation of that data. The way TAP is reflected into subunit today is to mangle each tap test into a subunit test , but for full benefits subunit tests have a higher bar they are individually addressable and runnable. So a TAP test script is much more equivalent to a subunit test. A similar concept is landing in Python s unittest soon subtests which will give very lightweight additional assertions within a larger test concept. Many C test runners that emit individual tests as simple assertions have this property as well there may be 5 or 10 executables each with dozens of assertions, but only the executables are individually addressable there is no way to run just one assertion from an executable as a test . It would be nice to avoid the friction that currently exists when dealing with that situation. Minimum requirements to support these Layers can be supported via timestamped stdout output, or fake tests. Neither is compelling, as the former requires special casing in subunit processors to data mine it, and the latter confuses test runners. A way to record something that is structured like a test (has an id the layer, an outcome in progress / ok / failed, and attachment data for showing failure details) but isn t a test would allow the data to flow around without causing confusion in the system. TAP support could change to just show the entire output as progress on one test and then fail or not at the end. This would result in a cognitive mismatch for folk from the TAP world, as TAP runners report each assertion as a test , and this would be hidden from subunit. Having a way to record something that is associated with an actual test, and has a name, status, attachment content for the TAP comments field that would let subunit processors report both the addressable tests (each TAP script) and the individual items, but know that only the overall scripts are runnable. Python subtests could use a unique test for each subtest, but that has the same issue has layers. Python will ensure a top level test errors if a subtest errors, so strictly speaking we probably don t need an associated-with concept, but we do need to be able to say that a test-like thing happened that isn t actually addressable. Coverage information could be about a single test, or even a subtest, or it could be about the entire work undertaken by the test process. I don t think we need a single standardised format for Coverage data (though that might be an excellent project for someone to undertake). It is also possible to overthink things :) . We have the idea of arbitrary attachments for tests. Perhaps arbitrary attachments outside of test scope would be better than specifying stdout/stderr as specific things. On the other hand stdout and stderr are well known things. Proposal version 2 A packetised length prefixed binary protocol, with each packet containing a small signature, length, routing code, a binary timestamp in UTC, a set of UTF8 tags (active only, no negative tags), a content tag one of (estimate + number, stdin, stdout, stderr, file, test), test-id, runnable, test-status (one of exists/inprogress/xfail/xsuccess/success/fail/skip), an attachment name, mime type, a last-block marker and a block of bytes. The std/stdout/stderr content tags are gone, replaced with file. The names stdin,stdout,stderr can be placed in the attachment name field to signal those well known files, and any other files that the test process wants to hand over can be simply embedded. Processors that don t expect them can just pass them on. Runnable is a boolean, indicating whether this packet is describing a test that can be executed deliberately (vs an individual TAP assertion, Python sub-test etc). This permits describing things like zope layers which are top level test-like things (they start, stop and can error) though they cannot be run.. and it doesn t explicitly model the setup/teardown aspect that they have. Should we do that? Testid is for identifying tests. With the runnable flag to indicate whether a test really is a test, subtests can just be namespaced by the generator reporters can choose whether to be naive and report every test , or whether to use simple string prefix-with-non-character-seperator to infer child elements. Impact on Python API If we change the API to:
class TestInfo(object):
    id = unicode
    status = ('exists', 'inprogress', 'xfail', 'xsuccess', 'success', 'fail', 'error', 'skip')
    runnable = boolean
class StreamingResult(object):
    def startTestRun(self):
        pass
    def stopTestRun(self):
        passs
    def estimate(self, count, route_code=None, timestamp=None):
        pass
    def file(self, name, bytes, eof=False, mime=None, test_info=None, route_code=None, timestamp=None):
        """Inform the result about the contents of an attachment."""
    def status(self, test_info, route_code=None, timestamp=None):
        """Inform the result about a test status with no attached data."""
This would permit the full semantics of a subunit stream to be represented I think, while being a narrow interface that should be easy to implement. Please provide feedback! I ll probably start implementing this soon.

14 February 2013

Russell Coker: Conversion of Video Files

To convert video files between formats I use Makefiles, this means I can run make -j2 on my dual-core server to get both cores going at once. avconv uses 8 threads for it s computation and I ve seen it take up to 190% CPU time for brief periods of time, but overall it seems to average a lot less, if nothing else then running two copies at once allows one to calculate while the other is waiting for disk IO. Here is a basic Makefile to generate a subdirectory full of mp4 files from a directory full of flv files. I used to use this to convert my Youtube music archive for my Android devices until I installed MX Player which can play every type of video file you can imagine [1]. I ll probably encounter some situation where this script becomes necessary again so I keep it around. It s also a very simple example of how to run a batch conversion of video files. MP4S:=$(shell for n in *.flv ; do echo $$n sed -e s/^/mp4\\// -e s/flv$$/mp4/ ; done)

all: $(MP4S)

mp4/%.mp4: %.flv
avconv -i $< -strict experimental -b $$(~/bin/video-encoding-rate $<) $@ > /dev/null Here is a more complex Makefile. I use it on my directory of big videos (more than 1280*720 resolution) and scales them down for my favorite Android devices (Samsung Galaxy S3, Samsung Galaxy S, and Sony Ericsson Xperia X10). My Galaxy S3 can t play a FullHD version of Gangnam Style without going slow so I need to do this even for the fastest phones. This makefile generates three subdirectories of mp4 files for the three devices. S3MP4S:=$(shell for n in *.mp4 ; do echo $$n sed -e s/^/s3\\// -e s/.mp4$$/-s3.mp4/ -e s/.flv$$/-s3.mp4/; done)
XPERIAMP4S:=$(shell for n in *.mp4 ; do echo $$n sed -e s/^/xperiax10\\// -e s/.mp4$$/-xperiax10.mp4/ -e s/.flv$$/-xperiax10.mp4/; done)
SMP4S:=$(shell for n in *.mp4 ; do echo $$n sed -e s/^/galaxys\\// -e s/.mp4$$/-galaxys.mp4/ -e s/.flv$$/-galaxys.mp4/; done)

all: $(S3MP4S) $(XPERIAMP4S) $(SMP4S)

s3/%-s3.mp4: %.mp4
avconv -i $< -strict experimental -s $(shell ~/bin/video-scale-resolution 1280 720 $<) $@ > /dev/null

galaxys/%-galaxys.mp4: %.mp4
echo avconv -i $< -strict experimental -s $(shell ~/bin/video-scale-resolution 800 480 $<) $@ > /dev/null

xperiax10/%-xperiax10.mp4: %.mp4
echo avconv -i $< -strict experimental -s $(shell ~/bin/video-scale-resolution 854 480 $<) $@ > /dev/null The following script is used by the above Makefile to determine the resolution to use. Some Youtube videos have unusual combinations of width and height (Linkin Park seems to like doing this) so I scale them down so it fits the phone in one dimension and the other dimension is scaled appropriately. This requires a script from the Mplayer package and expects it to be in the location that it s used in the Debian package, for distributions other than Debian a minor change will be required. #!/bin/bash
set -e
OUT_VIDEO_WIDTH=$1
OUT_VIDEO_HEIGHT=$2

eval $(/usr/share/mplayer/midentify.sh $3)
XMULT=$(echo $ID_VIDEO_WIDTH*100/$OUT_VIDEO_WIDTH bc)
YMULT=$(echo $ID_VIDEO_HEIGHT*100/$OUT_VIDEO_HEIGHT bc)
if [ $XMULT -gt $YMULT ]; then
NEWX=$OUT_VIDEO_WIDTH
NEWY=$(echo $OUT_VIDEO_WIDTH*$ID_VIDEO_HEIGHT/$ID_VIDEO_WIDTH/2*2 bc)
else
NEWX=$(echo $OUT_VIDEO_HEIGHT*$ID_VIDEO_WIDTH/$ID_VIDEO_HEIGHT/2*2 bc)
NEWY=$OUT_VIDEO_HEIGHT
fi
echo $ NEWX x$ NEWY Note that I can t preserve TAB characters in a blog post. So those Makefiles won t work until you replace strings of 8 spaces with a TAB character.

Ian Campbell: FOSDEM 2013

So as previously mentioned I gave a talk at FOSDEM this year on the future of paravirtualisation under Xen. I thought the talk was reasonably well attended despite being at six o'clock in the evening. In the end I underran my half hour slot but fortunately people had plenty of interesting questions! I've posted my slides on my xenbits space. I spent a fair chunk of the rest of the time on the Xen.org booth, which is hard work but it is always nice to speak to users and other developers. I also managed to catch up with various friends from other projects and managed to meet a few folks who I've only ever met in email before. I didn't get to see as many talks as I wanted (for example I missed pretty much all of the ARM track :-() due to clashes with my stints on the booth, my own talk, and talks clashing with each other. Still it was all in all a worthwhile, hopefully I'll be able to make it again next year! Next up: LinaroConnect in Hong Kong!

Robert Collins: Time to revise the subunit protocol

Subunit is seven and a half years old now Conrad Parker and I first sketched it up at a CodeCon camping and coding, a brilliant combination in mid 2005.
revno: 1
committer: Robert Collins <robertc@robertcollins.net>
timestamp: Sat 2005-08-27 15:01:20 +1000
message:  design up a protocol with kfish
It has proved remarkably resilient as a protocol the basic nature hasn t changed at all, even though we ve added tags, timestamps, support for attachments of arbitrary size. However a growing number of irritations have been building up with it. I think it is time to design another iteration of the protocol, one that will retain the positive qualities of the current protocol, while helping it become suitable for the next 7 years. Ideally we can keep compatibility and make it possible for a single stream to be represented in any format. Existing design The existing design is a mostly human readable line orientated protocol that can be sniffed out from the regular output of make or other build systems. Binary attachments are done using HTTP chunking, and the parser has to maintain state about the current test, tags, timing data and test progression [a simple stack of progress counters]. How to arrange subunit output is undefined, how to select tests to run is undefined. This makes writing a parser quite easy, and the tagging and timestamp facility allow multiplexing streams from two or more concurrent test runs into one with good fidelity but also requires that state be buffered until the end of a test, as two tests cannot be executing at once. Dealing with debuggers The initial protocol was intended to support dropping into a debugger just pass each line read through to stdout, and connect stdin to the test process, and voila, you have a working debugger connection. This works, but the current line based parsers make using it tedious the line buffered nature of it makes feedback on what has been typed fiddly, and stdout tends to be buffered, leading to an inability to see print statements and the like. All in-principle fixable, right ? When running two or more test processes, which test process should stdin be connected to? What if two or more drop into a debugger at once? What is being typed to which process is more luck than anything else. We ve added some idioms in testrepository that control test execution by a similar but different format one test per line to list tests, and have runners permit listing and selecting by a list. This works well, but the inconsistency with subunit itself is a little annoying you need two parsers, and two output formats. Good points The current protocol is extremely easy to implement for emitters, and the arbitrary attachments and tagging features have worked extremely well. There is a comprehensive Python parser which maps everything into Python unittest API calls (an extended version of the standard, with good backwards compatibility). Pain points The debugging support was a total failure, and the way the parser depraminates it s toys when a test process corrupts an outcome line is extremely frustrating. (other tests execute but the parser sees them as non-subunit chatter and passes the lines on through stdout). Dealing with concurrency The original design didn t cater for concurrency. There are three concurrency issues the corruption issue (see below for more detail) and multiplexing. Consider two levels of nested concurrency: A supervisor process such as testrepository starts 2 (or more but 2 is sufficient to reason about the issue) subsidiary worker processes (I1 and I2), each of which starts 2 subsidiary processes of their own (W1, W2, W3, W4). Each of the 4 leaf processes is outputting subunit which gets multiplexed in the 2 intermediary processes, and then again in the supervisor. Why would there be two layers? A concrete example is using testrepository to coordinate test runs on multiple machines at once, with each machine running a local testrepository to broker tests amongst the local CPUs. This could be done with 4 separate ssh sessions and no intermediaries, but that only removes a fraction of the issues. What issues? Well, consider some stdout chatter that W1 outputs. That will get passed to I1 and from there to the supervisor and captured. But there is nothing marking the chatter as belonging to W1: there is no way to tell where it came from. If W1 happened to fail, and there was a diagnostic message printed, we ve lost information. Or at best muddled it all up. Secondly, buffering imagine that a test on W1 hangs. I1 will know that W1 is running a test, but has no way to tell the supervisor (and thus the user) that this is the case, without writing to stdout [and causing a *lot* of noise if that happens a lot]. We could have I1 write to stdout only if W1 s test is taking more than 5 seconds or something but this is a workaround for a limitation of the protocol. Adding to the confusion, the clock on W1 and W3 may be very skewed, so timestamps for everything have to be carefully synchronised by the multiplexer. Thirdly, scheduling if W1/W2 are on a faster machine than W3/W4 then a partition of equal-timed tests onto each machine will lead one idle before the other finishes. It would be nice to be able to pass tests to run to the faster machine when it goes idle, rather than having to start a new runner each time. Lastly, what to do when W1 and W2 both wait for user input on stdin (e.g. passphrases, debugger input, $other). Naively connecting stdin to all processes doesn t work well. A GUI supervisor could connect a separate fd to each of I1 and I2, but that doesn t help when it is W1 and W2 reading from stdin. So additional requirement over baseline subunit:
  1. make it possible for stdout and stderr output to be captured from W1 and routed through I1 to the supervisor without losing its origin. It might be chatter from a noisy test, or it might be build output. Either way, the user probably will benefit if we can capture it and show it to them later when they review the test run. The supervisor should probably show it immediately as well the protocol doesn t need to care about that, just make it possible.
  2. make it possible to pass information about tests that have not completed through one subunit stream while they are still incomplete.
  3. make it possible (but optional) to pass tests to run to a running process that accepts subunit.
  4. make it possible to route stdin to a specific currently process like W1. This and point 3 suggest that we need a bidirectional protocol rather than the solely unidirectional protocol we have today. I don t know of a reliable portable way to tell when some process is seeking such input, so that will be up to the user I think. (e.g. printing (pdb) to stdout might be a sufficiently good indicator.)
Dealing with corruption Consider the following subunit fragment:
test: foo
starting serversuccess:foo
This is a classic example of corruption: the test foo started a server and helpfully wrote to stdout explaining that it did that, but missed the newline. As a result the success message for the test wasn t printed on a line of its own, and the subunit parser will believe that foo never completed. Every subsequent test is then ignored. This is usually easy to identify and fix, but its a head-scratcher when it happens. Another way it can happen is when a build tool like make runs tests in parallel, and they output subunit onto the same stdout file handle. A third way is when a build tool like make runs two separate test scripts serially, and the first one starts a test but errors hard and doesn t finish it. That looks like:
test: foo
test: bar
success: bar
One way that this sort of corruption can be mitigated is to put subunit on it s own file descriptor, but this has several caveats: it is harder to tunnel through things like ssh and it doesn t solve the failing test script case. I think it is unreasonable to require a protocol where arbitrary interleaving of bytes between different test runner streams will work so the make -j2 case can be ignored at the wire level though we should create a simple way to safely mux the output from such tests when the execute. The root of the issue is that a dropped update leaves bad state in the parser and it never recovers. So some way to recover, or less state to carry in the parser, would neatly solve things. I favour reducing parser state as that should shift stateful complexity onto end nodes / complex processors, rather than being carried by every node in the transmission path. Dependencies Various suggestions have been made JSON, Protobufs, etc A key design goal of the first subunit was a low barrier to entry. We keep that by being backward compatible, but being easy to work with for the new revision is also a worthy goal. High level proposal A packetised length prefixed binary protocol, with each packet containing a small signature, length, routing code, a binary timestamp in UTC, a set of UTF8 tags (active only, no negative tags), a content tag one of (estimate + number, stdin, stdout, stderr, test- + test id), test status (one of exists/inprogress/xfail/xsuccess/success/fail/skip), an attachment name, mime type, a last-block marker and a block of bytes. The content tags: Test status values are pretty ordinary. Exists is used to indicate a test that can be run when listing tests, and inprogress is used to report a test that has started but not necessarily completed. Attachment names must be unique per routing code + testid. So how does this line up? Interleaving and recovery We could dispense with interleaving and say the streams are wholly binary, or we can say that packets can start either after a \n or directly after another packet. If we say that binary-only is the approach to take, it would be possible to write a filter that would apply the newline heuristic (or even look for packet headers at every byte offset. I think mandating adjacent to a packet or after \n is a small concession to make and will avoid tools like testrepository forcing users to always configure a heuristic filter. Non-subunit content can be wrapped in subunit for forwarding (the I1 in W1->I1->Supervisor chain would do the wrapping). This won t eliminate corruption but it will localise it and permit the stream to recover: the test that was corrupted will show up as incomplete, or with incomplete attachment data. listing Test listing would emit many small non-timestamped packets. It may be useful to have a wrapper packet for bulk amounts of fine grained data like listing is, or for multiplexers with many input streams that will often have multiple data packets available to write at once. Selecting tests to run Same as for listing while passing regexes down to the test runner to select groups of tests is a valid use case, thats not something subunit needs to worry about : if the selection is not the result of the supervisor selecting by test id, then it is known at the start of the test run and can just be a command line parameter to the backend : subunit is relevant for passing instructions to a runner mid-execution. Because the supervisor cannot just hand out some tests and wait for the thing it ran to report that it can accept incremental tests on stdin, supervisor processes will need to be informed about that out of band. Debugging Debugging is straight forward . The parser can read the first 4 or so bytes of a packet one at a time to determine if it is a packet or a line of stdout/stderr, and then either read to end of line, or the binary length of the packet. So, we combine a few things; non-subunit output should be wrapped and presented to the user. Subunit that is being multiplexed and forwarded should prepend a routing code to the packet (e.g. I1 would append 1 or 2 to select which of W1/W2 the content came from, and then forward the packet. S would append 1 or 2 to indicate I1/I2 the routing code is a path through the tree of forwarding processes). The UI the user is using needs to supply some means to switch where stdin is attached. And stdin input should be routed via stdin packets. When there is no routing code left, the packet should be entirely unwrapped and presented as raw bytes to the process in question. Multiplexing Very straight forward unwrap the outer layer of the packet, add or adjust the routing code, serialise a header + adjusted length + rest of packet as-is. No buffering is needed, so the supervisor can show in-progress tests (and how long they have been running for). Parsing / representation in Python or other languages The parser should be very simple to write. Once parsed, this will be fundamentally different to the existing Python TestCase->TestResult API that is in used today. However it should be easy to write two adapters: old-style <-> this new-style. old-style -> new-style is useful for running existing tests suites and generating subunit, because thats way the subunit generation is transparent. new-style->old-style is useful for using existing test reporting facilities (such as junitxml or html TestResult objects) with subunit streams. Importantly though, a new TestResult style that supports the features of this protocol would enable some useful features for regular Python test suites: The API might be something like:
class StreamingResult(object):
    def startTestRun(self):
        pass
    def stopTestRun(self):
        pass
    def estimate(self, count, route_code=None):
        pass
    def stdin(self, bytes, route_code=None):
        pass
    def stdout(self, bytes, route_code=None):
        pass
    def test(self, test_id, status, attachment_name=None, attachment_mime=None, attachment_eof=None, attachment_bytes=None):
        pass
This would support just-in-time debugging by wiring up pdb to the stdin/stdout handlers of the result object, rather than actual stdin/stdout of the process a simple matter once written. Alternatively, the test runner could replace sys.stdin/stdout etc with thunk file-like objects, which might be a good idea anyway to capture spurious output happening during a test run. That would permit pdb to Just Work (even if the test process is internally running concurrent tests.. until it has two pdb objects running concurrently :) Generation new streams Should be very easy in anything except shell. For shell, we can have a command line tool that when invoked outputs a subunit stream for one instruction. E.g. test foo completed + some attachments or test foo starting .

Michal &#268;iha&#345;: phpMyAdmin translations status

Next round of phpMyAdmin 4.0 translation status report is coming. So let's look at which translations are at 100% right now (some changes this week due to new strings to translate): There are also several languages which need just few strings to be complete: As you can see, there is still lot of languages missing, this might be your opportunity to contribute to phpMyAdmin. Also you are welcome to translate phpMyAdmin 4.0 using translation server. If your language is already fully translated and you want to help as well, you can translate our documentation as well.

Filed under: English Phpmyadmin 0 comments Flattr this!

13 February 2013

Julien Danjou: Cloud tools for Debian

Recently, I've worked on the cloud utilities that are provided as standard in Ubuntu, and I ported them to Debian. Let's see how that brings Debian to the cloud! Basics of a cloud image When starting an instance on a IaaS platform, your instance image is raw, un-configured. Therefore, you need to have a way to configure it automagically at boot time, based on what you want to do with it. Usually, IaaS platforms provides for this a metadata server, like Amazon EC2 does. It's a special HTTP server listening on a special and hard-coded IP address that your instance can request to know basic information about itself, like its hostname, and retrieve basic user metadata to auto-configure itself. You can check the documentation about the OpenStack metadata service for more information. Also, image have a predefined size at upload time. So when you run it on a platform, the disk size you request is usually bigger than the size of your image disk: you mayneed to resize and grow your image to use the full disk space that is allocated to your instance. Needed tools
To run a cloud platform, and especially Amazon EC2 or OpenStack, you need to configure and update your image based on the context you're started in. This also includes extending your template image disk to use the full available disk size provided to the running instance. Ubuntu provides a set of cloud utils, which is actually composed of different source packages (cloud-init, cloud-utils and clout-initiramfs-tools). Combined, these 3 packages will allow you to run a number of step, from disk resize at boot time to Puppet configuration handling. So Ubuntu got this working right a long time ago, but unfortunately, Debian was really late on that. Until now. I've worked on getting these into Debian, and you can now find these 3 packages adapted and uploaded to Debian sid. All you need to do, is to build a Debian image and then run:
apt-get install cloud-init cloud-tools cloud-initiramfs-growroot

And voil : at the next reboot, your instance will extend its root partition size to the full available disk size, and ask the metadata server to configure things like its hostname. The packages sources are available on Debian's git server for cloud-utils and cloud-initramfs-tools and you can build them yourself until the packages are processed by ftp-master and get out of the NEW queue. cloud-init on the other hand is directly available in sid. One of next steps would probably be to build or enhance a tool like vmbuilder to be able to build cloud-compatible Debian images with a simple command line.

Jan Wagner: Searching painting: Strawberry and Man on Pumps with Sparkling wine

We are searching a motive for a painting or a painting itself for a quite while now. This should find it's place in our living room. Unfortunately we didn't found one, which matched our both prospect and/or wasn't compatible with the rest of our living room. Yesterday we stumbled upon a motive which was quite nice, but was too small and it was neighter possible to get it in a bigger size nor to find out who was the origin painter of the picture. Now we are searching for the name of the picture and/or the painter. Any hints appreciated at 'blog - at - waja - dot - info'. A photo with higher resolution can be found here Update: Okay ... an unknown people (many thanks) hinted me, that google image search is the tool that could be very usefull. Google revealed that the painter is Inna Panasenko. P.S. Is it noticeable that I'm in vacation mode? ;)

12 February 2013

Martin Pitt: umockdev: record and mock hardware for debugging and testing

What is this? umockdev is a set of tools and a library to mock hardware devices for programs that handle Linux hardware devices. It also provides tools to record the properties and behaviour of particular devices, and to run a program or test suite under a test bed with the previously recorded devices loaded. This allows developers of software like gphoto or libmtp to receive these records in bug reports and recreate the problem on their system without having access to the affected hardware, as well as writing regression tests for those that do not need any particular privileges and thus are capable of running in standard make check. After working on it for several weeks and lots of rumbling on G+, it s now useful and documented enough for the first release 0.1! Component overview umockdev consists of the following parts: Example: Record and replay PtP/MTP USB devices So how do you use umockdev? For the debug a problem use case you usually don t want to write a program that uses libumockdev, but just use the command line tools. Let s capture some runs from libmtp tools, and replay them in a mock environment: Example: using the library to fake a battery If you want to write regression tests, it s usually more flexible to use the library instead of calling everything through umockdev-run. As a simple example, let s pretend we want to write tests for upower. Batteries, and power supplies in general, are simple devices in the sense that userspace programs such as upower only communicate with them through sysfs and uevents. No /dev nor ioctls are necessary. docs/examples/ has two example programs how to use libumockdev to create a fake battery device, change it to low charge, sending an uevent, and running upower on a local test system D-BUS in the testbed, with watching what happens with upower --monitor-detail. battery.c shows how to do that with plain GObject in C, battery.py is the equivalent program in Python that uses the GI binding. You can just run the latter like this:
  umockdev-wrapper python3 docs/examples/battery.py
and you will see that upowerd (which runs on a temporary local system D-BUS in the test bed) will report a single battery with 75% charge, which gets down to 2.5% a second later. The gist of it is that you create a test bed with
  UMockdevTestbed *testbed = umockdev_testbed_new ();
and add a device with certain sysfs attributes and udev properties with
    gchar *sys_bat = umockdev_testbed_add_device (
            testbed, "power_supply", "fakeBAT0", NULL,
            /* attributes */
            "type", "Battery",
            "present", "1",
            "status", "Discharging",
            "energy_full", "60000000",
            "energy_full_design", "80000000",
            "energy_now", "48000000",
            "voltage_now", "12000000",
            NULL,
            /* properties */
            "POWER_SUPPLY_ONLINE", "1",
            NULL);
You can then e. g. change an attribute and synthesize a change uevent with
  umockdev_testbed_set_attribute (testbed, sys_bat, "energy_now", "1500000");
  umockdev_testbed_uevent (testbed, sys_bat, "change");
With Python or other introspected languages, or in Vala it works the same way, except that it looks a bit leaner due to proper object semantics. Packages I have a packaging branch for Ubuntu and a recipe to do daily builds with the latest upstream code into my daily builds PPA (for 12.10 and raring). I will soon upload it to Raring proper, too. What s next? The current set of features should already get you quite far for a range of devices. I d love to get feedback from you if you use this for anything useful, in particular how to improve the API, the command line tools, or the text dump format. I m not really happy with the split between umockdev (sys/dev) and ioctl files and the relatively complicated CLI syntax of umockdev-record, so any suggestion is welcome. One use case that I have for myself is to extend the coverage of ioctls for input devices such as touch screens and wacom tablets, so that we can write some tests for gnome-settings-daemon plugins. I also want to find a way to pass ioctls back to the test suite/calling program instead of having to handle them all in the preload library, which would make it a lot more flexible. However, due to the nature of the ioctl ABI this is not easy. Where to go to The code is hosted on github in the umockdev project; this started out as a systemd branch to add this functionality to libudev, but after a discussion with Kay we decided to keep it separate. But I kept it in git anyway, given how popular it is today. For the bzr lovers, Launchpad has an import at lp:umockdev. Release tarballs will be on Launchpad as well. Please file bugs and enhancement requests in the git hub tracker. Finally, if you have questions or want to discuss something, you can always find me on IRC (pitti on Freenode or GNOME). Thanks for your attention and happy testing!

11 February 2013

Jon Dowland: Steam for Debian

So you can download Steam for Linux now!. Or at least Ubuntu. The 1.0.0.22-version package needs a bit of tweaking to make it installable on Debian. There's a good writeup of some of the issues in this blog post (more recent packages seem to have much more simple dependencies). I run amd64 with multiarch enabled for i386. I chose to update my libc to the version in experimental rather than embed a newer version in a private steam directory. The remaining issues are mostly package version differences between Ubuntu (who seem to be very epoch-happy, I guess they've made a lot more packaging mistakes) and Debian. I wrote the following script to do the work. It takes two arguments: the original steam .deb and then the output filename to write a modified .deb to. Feel free to try it.
#!/bin/sh
set -u
set -e
[ $# -eq 2 ]     echo "$0 <in-deb> <out-deb>" >&2; exit 1;  
wd=$(mktemp -td $0.XXXXXX)
trap "rm -r '$wd'" INT QUIT EXIT
dpkg-deb -x "$1" "$wd/steam"
dpkg-deb -e "$1" "$wd/steam/DEBIAN"
sed -i  -e 's/\(libpulse0 (>= \)1:/\1/' -e '# remove ubuntu epoch' \
    -e 's/^\(Version:.*\)$/\1+jmtd/' \
    -e 's/xterm   gnome-terminal,//' -e '# seems to be an apt bug here' \
    -e 's/\(multiarch-support (>= 2.15\)[^)]*/\1/' -e '# remove ubuntu epoch' \
    "$wd/steam/DEBIAN/control"
mv "$wd/steam/usr/bin/steamdeps" "$wd/steam/usr/bin/steamdeps.orig"
ln -s "/bin/true" "$wd/steam/usr/bin/steamdeps"
fakeroot dpkg-deb -b "$wd/steam" "$2"
The most interesting (to me, anyway) package foible was the dependency on xterm gnome-terminal. I have both installed, but neither for i386. Of course, steam doesn't need a 32 bit terminal emulator, it can spawn the 64 bit one perfectly well. It turns out that you can't express such a dependency at the moment. Even changing that to a virtual package x-terminal-emulator didn't work: aptitude still wanted to pull in a 32 bit match and all the supporting libraries. For this package I just delete the dependency outright.

Vasudev Kamath: CDBS Packaging : copyright file support

One of the thing CDBS provides is support for verifying / generating debian/copyright file. This feature will be help full if new files show up in newer releases. It can also be helpful to generate the first version of copyright file. But don't blindly follow this feature, you need to cross verify the things it generates. To use this feature add the following line to your debian/rules file first
include /usr/share/cdbs/1/rules/utils.mk 
 
Now create a file called debian/copyright_hints using touch command
touch debian/copyright_hints
Now run the following command to allow CDBS to do its magic and generate a new file called debian/copyright_newhints
DEB_MAINTAINER_MODE=1 fakeroot debian/rules build
As you see we set the variable DEB_MAINTAINER_MODE which means this is feature to help the maintainer rather than targeted for automatic builds. So if there is no new things added to the new release you should see something like this in the build log.
Scanning upstream source for new/changed copyright notices...
licensecheck -c '.*' -r --copyright -i '^debian/(changelog copyright( _hints _newhints))' -l '99999' *   /usr/lib/cdbs/licensecheck2dep5 > debian/co$
yright_newhints
19 combinations of copyright and licensing found.
No new copyright notices found - assuming no news is good news...
In case there are new files added you should get output similar to below
Scanning upstream source for new/changed copyright notices...
licensecheck -c '.*' -r --copyright -i '^debian/(changelog copyright( _hints _newhints))' -l '99999' *   /usr/lib/cdbs/licensecheck2dep5 > debian/co$
yright_newhints
0 combinations of copyright and licensing found.
Format: http://www.debian.org/doc/packaging-manuals/ 
Upstream-Name: FIXME
Upstream-Contact: FIXME
Source: FIXME
Disclaimer: Autogenerated by CDBS
...
To fix the situation please do the following:
  1) Fully compare debian/copyright_hints with debian/copyright_newhints
  2) Update debian/copyright as needed
  3) Replace debian/copyright_hints with debian/copyright_newhints
So as the last 3 points says you need to compare your copyright_hints and the newly generated file by CDBS copyright_newhints for difference and update the debian/copyright as required and replace the existing debian/copyright_hints with debian/copyright_newhints. Tips
  1. This feature can be used to generate the copyright file for the first time you need a copyright file with only debian/* copyright in it.
  2. If you are using it to generate copyright file for the first time be sure to cross verify the things mentioned in the file than just blindly copy pasting.
  3. If there are binary files like images are involved in your project be sure to clean up those from your copyright_hints before trying to build the package. Because of too much of binary cruft in any files means dpkg-source will be angry at you :-).
Last but not the least, I know CDBS provides some really cool features which we will explore with next few posts but always keep in mind this quote by Jonas. (Of course don't ask me to prove that Jonas did say it as there is no pgp signature of him with quote to verify ;-) )
CDBS is tool to help packagers and does not involve any magic.

10 February 2013

David Bremner: First Steps with Argyll and ColorHug

In April of 2012 I bought a ColorHug colorimeter. I got a bit discouraged when the first thing I realized was that one of my monitors needed replacing, and put the the colorhug in a drawer until today. With quite a lot of help and encouragment from Pascal de Bruijn, I finally got it going. Pascal has written an informative blog post on color management. That's a good place to look for background. This is more of a "write down the commands so I don't forget" sort of blog post, but it might help somebody else trying to calibrate their monitor using argyll on the command line. I'm not running gnome, so using gnome color manager turns out to be a bit of a hassle. I run Debian Wheezy on this machine, and I'll mention the packages I used, even though I didn't install most of them today.
  1. Find the masking tape, and tear off a long enough strip to hold the ColorHug on the monitor. This is probably the real reason I gave up last time; it takes about 45minutes to run the calibration, and I lack the attention span/upper-arm-strength to hold the sensor up for that long. Apparently new ColorHugs are shipping with some elastic.
  2. Update the firmware on the colorhug. This is a gui-wizard kindof thing.
     % apt-get install colorhug-client
     % colorhug-flash 
    
  3. Set the monitor to factory defaults. On this ASUS PA238QR, that is brightness 100, contrast 80, R=G=B=100. I adjusted the brightness down to about 70; 100 is kindof eye-burning IMHO.
  4. Figure out which display is which; I have two monitors.
     % dispwin -\?
    
    Look under "-d n"
  5. Do the calibration. This is really verbatim from Pascal, except I added the ENABLE_COLORHUG=true and -d 2 bits.
     % apt-get install argyll
     % ENABLE_COLORHUG=true dispcal -v -d 2 -m -q m -y l -t 6500 -g 2.2 test
     % targen -v -d 3 -G -f 128 test
     % ENABLE_COLORHUG=true dispread -v -d 2 -y l -k test.cal test
     % colprof -v -A "make" -M "model" -D "make model desc" -C   "copyright" -q m -a G test
    
  6. Load the profile
     % dispwin -d 2 -I test.icc           
    
    It seems this only loads the x property _ICC_PROFILE_1 instead of _ICC_PROFILE; whether this works for a particular application seems to be not 100% guaranteed. It seems ok for darktable and gimp.

9 February 2013

Matthew Garrett: Samsung laptop bug is not Linux specific

I bricked a Samsung laptop today. Unlike most of the reported cases of Samsung laptops refusing to boot, I never booted Linux on it - all experimentation was performed under Windows. It seems that the bug we've been seeing is simultaneously simpler in some ways and more complicated in others than we'd previously realised.

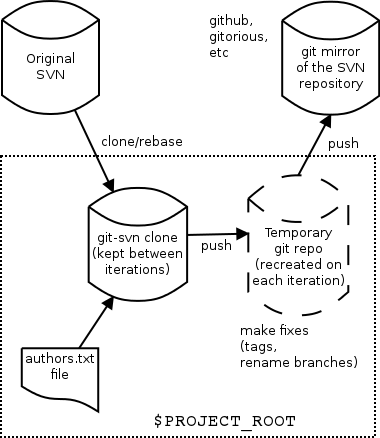
So, some background. The original belief was that the samsung-laptop driver was doing something that caused the system to stop working. This driver was coded to a Samsung specification in order to support certain laptop features that weren't accessible via any standardised mechanism. It works by searching a specific area of memory for a Samsung-specific signature. If it finds it, it follows a pointer to a table that contains various magic values that need to be written in order to trigger some system management code that actually performs the requested change. This is unusual in this day and age, but not unique. The problem is that the magic signature is still present on UEFI systems, but attempting to use the data contained in the table causes problems.

We're not quite sure what those problems are yet. Originally we assumed that the magic values we wrote were causing the problem, so the samsung-laptop driver was patched to disable it on UEFI systems. Unfortunately, this doesn't actually fix the problem - it just avoids the easiest way of triggering it. It turns out that it wasn't the writes that caused the problem, it was what happened next. Performing the writes triggered a hardware error of some description. The Linux kernel caught and logged this. In the old days, people would often never see these logs - the system would then be frozen and it would be impossible to access the hard drive, so they never got written to disk. There's code in the kernel to make this easier on UEFI systems. Whenever a severe error is encountered, the kernel copies recent messages to the UEFI variable storage space. They're then available to userspace after a reboot, allowing more accurate diagnostics of what caused the crash.

That crash dump takes about 10K of UEFI storage space. Microsoft require that Windows 8 systems have at least 64K of storage space available. We only keep one crash dump - if the system crashes again it'll simply overwrite the existing one rather than creating another. This is all completely compatible with the UEFI specification, and Apple actually do something very similar on their hardware. Unfortunately, it turns out that some Samsung laptops will fail to boot if too much of the variable storage space is used. We don't know what "too much" is yet, but writing a bunch of variables from Windows is enough to trigger it. I put some sample code here - it writes out 36 variables each containing a kilobyte of random data. I ran this as an administrator under Windows and then rebooted the system. It never came back.

This is pretty obviously a firmware bug. Writing UEFI variables is expressly permitted by the specification, and there should never be a situation in which an OS can fill the variable store in such a way that the firmware refuses to boot the system. We've seen similar bugs in Intel's reference code in the past, but they were all fixed early last year. For now the safest thing to do is not to use UEFI on any Samsung laptops. Unfortunately, if you're using Windows, that'll require you to reinstall it from scratch.

comment count unavailable comments

8 February 2013

Olivier Berger: RDF development in PHP with a PostGreSQL triple store thanks to the LibRDF OO wrapper for redland/librdf

Redland/librdf offers powerful features like being able to persist an RDF model to a relational database (only PostGreSQL seems to work on my setup with 1.0.16, but I may have misconfigured it). You can then do SPARQL queries over the model, and lots of other nice things. Unfortunately, the default PHP bindings are not really object-oriented, so the code isn t looking so good. But thanks to a gentleman named David Shea, there is an object-oriented library named LibRDF (case is sensitive), that helps write nice looking PHP. I discovered it via the blog post of Felix Ostrowski, who took over the maintenance of the LibRDF library (still the docs live on the original author s site). In his post, Felix illustrates how you may use it to parse Richard Cyganiak s FOAF profile. But the examples he gives don t illustrate the full potential of persistence of the RDF graph into the DB. Here s my contribution in 2 examples that will hopefully help : first, one that load Richard s FOAF to the DB, and one, that later retrieve the saved model and perform the same query (both pushed to my github clone of the library). There may be some problems with the use of librdf, including its availability, as it is not full PHP of course and I ve heard of memory management problems, but, depening on your needs, this may be quite handy for writing Linked Data applications.

Next.

Previous.


