Search Results: "ron"

28 November 2013

Debian Med: Bits from Debian Med team (by Andreas Tille)

Some of these bits are a bit outdated but there is no point in hiding this information just because it is old. FOSDEM talkAndreas Tille had a talk at FOSDEM which is also Video recorded. A quite similar but updated talk was held at DebConf 13 (see below). Jabber interview by reporter from IndiaThere was an interesting interview between Rajeev Nair and Andreas Tille at So, 17.02.2013 Rajeev Nair is Business head of an health care journal in India held via jabber. Since this might serve as some nice FAQ about Debian Med here is a complete log of this interview (permission to publish it was granted). Article about Debian MedAs a consequence of the interview above the Debian Med team has assembled an article which was originally intended to be published in the Health Cafe journal but somehow this never happened. So we ended up with a nice article targeting at interested readers about Free Software in medicine with not necessarily informatics background. Since the article is considered to be of good quality and has consumed some time of several team members we are seeking for ideas for relevant places where to publish it. It is available as PDFas well as in SVN. Yearly sprint of Debian Med teamThis year we had our third sprint of the Debian Med team and all participants consider it a great success again. The sprint was in end of February and the individual reports are linked from the according wiki page. Since Andreas Tille was able to prove the nice effect of having face to face meetings in Debian teams in the team metrics graphs presented in his talks at DebConf (see below) we will keep on with this good tradition. The next sprint is scheduled for Friday 31st January until Sunday 2nd February in Stonehaven near Aberdeen. If you are interested to meet the people behind Debian Med and want to join us in developing packages which are helpful in health care and bioinformatics you are invited to join us. DebConf 13 in VaumarcusAndreas Tille had two talks with specific influence to Debian Med development(Debian Med as a success story for other Blends, How to attract new developers for your team (MoM, SoB). For those who want to read a full (and lengthy) report about DebConf 13 by Andreas Tille this is online in this blog article. Codefest of the Open Bioinformatics FoundationIvo Maintz and Steffen M ller organised the Codefest of the Open Bioinformatics Foundation in Berlin. About 40 contributors from all over the world attended, connecting the Debian community strongly with upstream. The event triggered a joint paper of participants to Sprints, Codefests and Hackathons alike, presented at the Nettab conference on Semantic, Social, and Mobile Applications for Bioinformatics and Biomedical Laboratories in Venice. Reupload unattended packagesAndreas Tille has mentored the GSoC student Emmanouil Kiagias and as a byproduct some Blends metadata were now kept in UDD. This has inspired some new tools and one of this was an UDD query to return all packages in the interest of the Blend ordered by date when they were uploaded. It has shown that there were packages hanging around in the package pool since five years. So some effort was done to check those packages which were not necessarily "buggy" according to BTS entries and so we were able to fix the following issues in about 20-30 packages: Since it was impressive how many things that deserve fixing are hidden in such long unattended packages it is recommended also to other teams to spend some time into these. The UDD query can be easily tweaked for a team maintainer address. Debian Med Bug Squashing Advent Calendar 2013The Debian Med team will again do the Bug Squashing Advent Calendar. Feel free to join us in our bug squashing effort where we close bugs while other people are opening doors. :-) Kind regards and see you at Debian Med sprint
Andreas.

27 November 2013

Steinar H. Gunderson: Stockfish

The open-source chess program Stockfish recently climbed to the top of the TCEC rating lists. Even though it does not seem likely to win the actual TCEC tournament (it is 15.5 11.5 down in the 48-game superfinal against Komodo, a closed-source commercial program, after winning 4, losing 8 and drawing 15), this is a tremendeous achievement. This is not only because it is highly unusual that the strongest chess program is open-source (it's naturally hard to keep a competitive edge when everybody can see your secrets!), but also because it is a mere 9000 lines of C++ code. (This is without a GUI; it interfaces through a standardized protocol known as UCI.) In comparison, Crafty, a far weaker open-source program, is about four times that, GNU Chess is above 40000, and I seem to recall that the Deep Blue program was something like 65000 lines (in addition to, of course, all the code for the ASIC chess chips it contained, and stood for the majority of its chess strength!). So, the development team is really to be commended. It should also be said that TCEC is testing the latest beta versions of most of these engines and while Stockfish is developed in the open, on GitHub, the latest versions of e.g. Komodo and Houdini are private. (This is probably one of the reasons why Stockfish is slightly lower on e.g. the CCRL list, which also computes chess program rating lists by playing games between them.) Now, why does anyone care? Only a very small handful of players would be able to score even a draw against any of these programs in a 10-game match, so does it really matter which one we choose? Or is this some obscure pissing contest? The answer, of course, is that these engines are not primarily useful for competitive play; they are useful for analysis. Almost any player, right down from beginners to the very top players, can benefit from having someone stronger than them look at their games (or others' games!) and say where things went wrong. (Somehow analyzing losses always seem more instructive than analyzing wins. Nobody ever got better by winning, as the saying goes.) And the better a program is at playing chess, the more likely is its analysis to be correct. Of course, for the weaker players, a chess coach is likely to produce much more understandable guidance ( this creates a weak square on c7 is much more palatable than after these 18 moves here, white is 0.48 pawns stronger than you, so this was a bad move , and engines produce the latter sort of output), but they are always available, incredibly strong, and cost much less than a coach. :-) They also add a lot to the otherwise quite hard-to-comprehend activity of watching high-level human players; while the computers do not understand every kind of position equally well, they at least provide some sort of objective verdict on which player has the upper hand, something which can be really hard to discern unless you have very strong players around for commentary. So, in trying to improve my skills a bit, I've been analyzing my games with engines for a while, and recently I've switched from Rybka to Stockfish. (Rybka, a closed-source program, used to be the clear leader of the pack, but after a huge amount of drama involving accusations of who has copied code from who, it seems no longer to be actively developed, and Stockfish is now somewhat stronger.) This, unfortunately, brings me to the things I don't like too much about Stockfish; it seems to behave more erratically than Rybka did in interactive analysis mode. Its score jumps a lot more around when I move something (worse at remember the analysis from the previous position?), and sometimes, it changes its mind a lot when I move back and forth between moves maybe the huge selectivity that makes chess engines so strong these days also make them behave less usefully when only looking at a move for a few seconds. So, even though Stockfish is a fantastic chess engine, and will only get better in the future, maybe I'll go back to Rybka at some point. But then again, maybe I should then check out Komodo or any of the other engines out there or maybe talk to someone who actually knows chess, that would help a lot, too =)

Timo Jyrinki: Workaround for setting Full RGB when Intel driver's Automatic setting does not work

Background I upgraded from Linux 3.8 to 3.11 among with newer Mesa, X.Org and Intel driver recently and I found a small workaround was needed because of upstream changes.

The upstream change was the Add "Automatic" mode for "Broadcast RGB" property, and defaulting to the Automatic. This is a sensible default, since many (most?) TVs default to the more limited 16-235, and continuing to default to Full from the driver side would mean wrong colors on the TV. I've set my screen to support the full 0-255 range available to not cut the amount of available shades of colors down.

Unfortunately it seems the Automatic setting does not work for my HDMI input, ie blacks become grey since the driver still outputs the more limited range. Maybe there could be something to improve on the driver side, but I'd guess it's more about my 2008 Sony TV actually having a mode that the standard suggests limited range for. I remember the TV did default to limited range, so maybe the EDID data from TV does not change when setting the RGB range to Full.

I hope the Automatic setting works to offer full range on newer screens and the modes they have, but that's probably up to the manufacturers and standards.

Below is an illustration of the correct setting on my Haswell CPU. When the Broadcast RGB is left to its default Automatic setting, the above image is displayed. When set to Full, the image below with deeper blacks is seen instead. I used manual settings on my camera so it's the same exposure.


Workaround For me the workaround has evolved to the following so far. Create a /etc/X11/Xsession.d/95fullrgb file:

if [ "$(/usr/bin/xrandr -q --prop   grep 'Broadcast RGB: Full'   wc -l)" = "0" ] ; then
/usr/bin/xrandr --output HDMI3 --set "Broadcast RGB" "Full"
fi
And since I'm using lightdm, adding the following to /etc/lightdm/lightdm.conf means the flicker only happens once during bootup:

display-setup-script=/etc/X11/Xsession.d/95fullrgb

Important: when using the LightDM setting, enable executable bits (chmod +x) to /etc/X11/Xsession.d/95fullrgb for it to work. Obviously also check your output, for me it was HDMI3.

If there is no situation where it'd set back to "Limited 16:235" setting on its own, the display manager script should be enough and having it in /etc/X11/Xsession.d is redundant and slows login time down. I think for me it maybe went from 2 seconds to 3 seconds since executing xrandr query is not cheap.
Misc Note that unrelated to Full range usage, the Limited range at the moment behaves incorrectly on Haswell until the patch in bug #71769 is accepted. That means, the blacks are grey in Limited mode even if the screen is also set to Limited.

I'd prefer there would be a kernel parameter for the Broadcast RGB setting, although my Haswell machine does boot so fast I don't get to see too many seconds of wrong colors...

26 November 2013

Daniel Pocock: The free software country?

Loch Ness Monster, Scotland There is big news in Europe right now, especially the UK, about the Scottish nation's manifesto for independence. I thought this was really amazing, a country that is going to move to free software and protect its citizens from horrors like DRM. I couldn't wait to find out more, for example, will they use Linux or *BSD? After all, how many nations today can really consider themselves independent when they are trapped in the use of complex and opaque systems that require ongoing royalty payments to a foreign corporation, much like ancient villages paying their tithes to Rome? Today it is actually worse: these independent nations are not just sacrificing their cash - the new Rome is also using those same secret, proprietary systems to raid their subjects' privacy. So I went to the manifesto's web site to get the details. I couldn't even find the words "software" or "technology" listed in the policy index on the front page - and software doesn't even appear in the search results. A section on Culture, Communications and Digital only really looks at the issues for the media (BBC after independence). They don't even make any comment about the British Telecom (BT) pension crisis and whether Scotland will abandon BT's services, leaving only those customers south of the border to continue subsidising the deficit through higher phone bills. There is some hope, with the dot scot (.scot) top level domain coming in 2015 regardless of the referendum outcome. Does this mean an independent Scotland is going to be run without technology at all then? That could be an interesting way to avoid the type of infiltration of communications technology that has been taking place in Brussels. Or do the people calling the shots simply fail to realise the impact of software and communications technology on a modern day concept of independence? Party date set For those who just care about gatecrashing the post-independence party, start booking your leave for March 2016.

25 November 2013

Jan Wagner: Crossbuilding Debian packages with sbuild (for Raspbian)

Yesterday I asked myself, how to setup a crossbuild environment on a Debian wheezy/amd64 to build binary packages compatible for Raspbian. After digging around it seemed to be the easiest way to use mk-sbuild to setup such a build environment.
We just need to install sbuild (>= 0.64.0-1) and ubuntu-dev-tools (>= 0.146), both packages are available since jessie:
aptitude install sbuild ubuntu-dev-tools
Some more packages are needed for crossbuilding:
aptitude install qemu-user-static binfmt-support linux-image-amd64
Setting up the chroot is quite easy with:
mk-sbuild --arch=armhf --debootstrap-mirror=http://archive.raspbian.org/raspbian jessie
Unfortunately you get thrown an error about bad signing key:
Release signed by unknown key (key id 9165938D90FDDD2E)
This happens cause debootstrap is using per default /usr/share/keyrings/$ DISTRO -archive-keyring.gpg, which doesn't ship the Raspbian signing key indeed. After looking how to solve that problem, I decided to use a quik&dirty fix:
echo 'DEBOOTSTRAP_KEYRING="--keyring=/usr/share/keyrings/raspbian-archive-keyring.gpg"' >> \
    /root/.mk-sbuild.rc
cp -a /usr/bin/mk-sbuild /tmp/mk-sbuild
patch -p0<./mk-sbuild_raspbian.diff /tmp/mk-sbuild
<noscript><pre><code>&lt;html&gt;&lt;body&gt;You are being &lt;a href=&quot;https://github.com/gist/7639011&quot;&gt;redirected&lt;/a&gt;.&lt;/body&gt;&lt;/html&gt;</code></pre></noscript>
mk-sbuild_raspbian.diff Now you should be able to setup your Raspbian sbuild chroot via:
/tmp/mk-sbuild --arch=armhf --debootstrap-mirror=http://archive.raspbian.org/raspbian wheezy

24 November 2013

Jan Wagner: Running icinga with lighttpd on Debian whezzy (and a Raspberry)

At first we need to install Icinga and lighttpd:
aptitude install icinga lighttpd
We need to enable the lighttpd cgi and authentication module:
lighttpd-enable-mod cgi && ighttpd-enable-mod auth
Let's create a config for Icinga (in a subdir of the default vHost). As you can see, you don't need any 'setenv.add-environment' on wheezy (at least):
vi /etc/lighttpd/conf-available/50-icinga.conf
<noscript><pre><code>&lt;html&gt;&lt;body&gt;You are being &lt;a href=&quot;https://github.com/gist/7602246&quot;&gt;redirected&lt;/a&gt;.&lt;/body&gt;&lt;/html&gt;</code></pre></noscript>
50-icinga.conf Let's create a config file with credentials for the user icingaadmin:
htpasswd -c /etc/icinga/htpasswd.users icingaadmin
Now we just need to enable the icinga config and reload the lighttpd:
lighttpd-enable-mod icinga && /etc/init.d/lighttpd force-reload
At this point you should find a working Icinga setup at http://yourip/icinga P.S. Does anybody know how to setup a buildenv (preferable as crossbuild on amd64) for Raspbian, as the Debian armhf packages are not compatible to raspbian and so there is no access to the Backports repository? Cool would be to get a sbuild env running, so it can be integrated into a buildd.

Petter Reinholdtsen: New chrpath release 0.15

After many years break from the package and a vain hope that development would be continued by someone else, I finally pulled my acts together this morning and wrapped up a new release of chrpath, the command line tool to modify the rpath and runpath of already compiled ELF programs. The update was triggered by the persistence of Isha Vishnoi at IBM, which needed a new config.guess file to get support for the ppc64le architecture (powerpc 64-bit Little Endian) he is working on. I checked the Debian, Ubuntu and Fedora packages for interesting patches (failed to find the source from OpenSUSE and Mandriva packages), and found quite a few nice fixes. These are the release notes: New in 0.15 released 2013-11-24: You can download the new version 0.15 from alioth. Please let us know via the Alioth project if something is wrong with the new release. The test suite did not discover any old errors, so if you find a new one, please also include a testsuite check.

23 November 2013

Russell Coker: Failures of Intelligence Agencies

There s been an ongoing news issue related to the NSA that I m not going to directly comment on, Charles Stross has one of the more interesting comments about it [1]. One of his major points is that any success at government secrecy relies on the type of work environment that existed 40+ years ago. Corporatism has killed government secrecy now it s a matter of time before corporate whistle-blowers start seriously leaking documents. One article that Charles links to is an interesting and insightful blog post Adam Curtis wrote for the BBC about the many failures of MI5 [2]. I think that everyone is aware of their biggest failures but from Adam s article it seems that they have only failed and never succeeded in anything. I wonder whether ASIO is any better, it s probably not (the Wikipedia page notes the involvement of MI5 in creating ASIO). It seems that the best way of achieving the goals of ASIO and MI5 would be to disband those organisations and assign regular police to do such work, after all it s been proven that British police are better at catching spies than MI5.

22 November 2013

Iustin Pop: Z rich at night

Last weekend I realised that one of the advantages of winter is that it gets dark quite early - so I took a short walk through Z rich at night to take a set of pictures. I usually only shoot handheld at night, which has its limitations, and this time I took a tripod with me. It's a very cheap tripod which I have for many years now and I don't really use - and the test was to see if it's actually usable for long exposures. The results can be seen on my Smugmug gallery. Some of the pictures I really like, but that's not the main point - I learned a lot in just an hour or so. First, the tripod worked. Well, it's cheap and plasticky, so "mirror delay 3" was absolutely needed, but with that the pictures got out reasonably sharp, even at 30s exposure. Second, I forgot my cable release at home, even though I explicitly wanted to take it, so "mirror delay 3" became my remote release. Logistics aside, the most interesting thing was that in the dark, the enemy is light, and not darkness. In the city, the contrast between darkness and strong lights results in a large dynamic range requirement, and - to me - that was a surprising realisation. As an example, in this picture, I had to use f/22 to get the desired exposure time, as the light was too strong. Another surprising realisation was that, if you're shooting with 30s exposure time, a person passing in front of the camera (but not staying in the same place) will leave no trace. At shorter exposures, or when the person has a low transversal speed, then it will show, but otherwise, you don't have to care too much . Something that I knew but it was not nice to be reminded of is how "broken" auto white balance is in presence of artificial lighting (basically low temperature). Add the fact that in a non-trivial scene you have multiple lights with different temperatures makes any night scene interesting - I had to manually fix white balance for the entire album, and I don't think I got it right. And finally - light pollution. The sky above Z rich was cloudy, and the clouds were glowing orange/reddish. I can't wait to get somewhere a bit far from civilisation with a nice, dark sky

Vincent Sanders: Error analysis is the sweet spot for improvement

Although Don Norman was discussing designers attitude to user errors I assert the same is true for programmers when we use static program analysis tools.

The errors, or rather defects in the jargon, that a static analysis tools produce can be considered low cost well formed bug reports available very early in the development process.

When I say low cost it is because they can be found by a machine without a user or fellow developer wasting their time finding them. Well formed comes because the machine can describe exactly how it came to the logical deduction leading to the defect.
IntroductionStatic analysis is in general terms using the computer to examine a program for logic errors beyond those of pure syntax before it is executed. Examining a running program for defects is known as dynamic program analysis and while a powerful tool in its own right is not the topic of discussion.

This analysis has historically been confined to compiled languages as their compilers already had the Abstract Syntax Tree (AST) of the code available for analysis. As an example the C language (released in 1972) had the lint tool (released in 1979) based on the PCC compiler.

Practical early compilers (I am generalising here as the 19070s were a time of white hot innovation in computing and examples of just about any innovation in the field could probably be found) were pretty primitive and produced executables which were less good than hand written assembler output. Due to practical constraints the progress of optimising compilers was not as rapid as might be desired so static analysis was largely used as an external process.

Before progressing I ought to explain why I just mixed the concept of an optimising compiler and static analysis. The act of optimisation within those compilers requires program analysis, from which they can generate defect reports which we all know and love as compiler warnings, also explaining why many warnings only appear at higher optimisation levels where deeper analysis is required.

The attentive reader may now enquire as to why we would need external analysis tools when our compilers already perform the task. The answer stems from the issue that a compiler is trying to reconcile many desirable traits including:
The slow progress in creating optimising compilers initially centred around the problem of getting the compiled output in a reasonable time to allow for a practical edit-compile-run-debug cycle although the issues more recently have moved more towards the compiler implementation costs.

Because the output generation time is still a significant factor compilers limit the level of static analysis performed to that strictly required to produce good output. In standard operation optimising compilers do not do the extended analysis necessary to find all the defects that might be detectable.

An example: compiling one 200,000 line C program with the clang (v3.3) compiler producing x86 instruction binaries at optimisation level 2 takes 70 seconds but using the clang based scan-build static analysis tool took 517 seconds or more than seven times as long.
Using static analysis
As already described warnings are a by-product of an optimising compilers analysis and most good programmers will endeavour to remove all warnings from a project. Thus almost all programmers are already using static analysis to some degree.

The external analysis tools available can produce many more defect reports than the compiler alone as long as the developer is prepared to wait for the output. Because of this delay static analysis is often done outside the usual developers cycle and often integrated into a projects Continuous Integration (CI) system.

The resulting defects are usually presented as annotated source code with a numbered list of logical steps which shows how the defect can present. For example the steps might highlight where a line of code allocates memory from the heap and then an exit path where no reference to the allocated memory is kept resulting in a resource leak.

Once the analysis has been performed and a list of defects generated the main problem with this technology rears its ugly head, that of so called "false positives". The analysis is fundamentally an undecidable problem (it is a variation of the halting problem) and relies on algorithms to generate approximate solutions. Because of this some of the identified defects are erroneous.

The level of erroneous defect reports varies depending on the codebase being analysed and how good the analysis tool being used is. It is not uncommon to see false positive rates, even with the best tools, in excess of 10%

Good tools allow for this and provide ways to supply additional context through model files or hints in the source code to suppress the incorrect defect reports. This is analogous to using asserts to explicitly constrain variable values or a type cast to suppress a type warning.

Even once the false positives have been dealt with there comes the problem of defects which while they may be theoretically possible take so many steps to achieve that their probability is remote at best. These defects are often better categorized as a missing constraint and the better analysis tools generate fewer than the more naive implementations.

An issue with some defect reports is that often defects will appear in a small number of modules within programs, generally where the developers already know the code is of poor quality, thus not adding useful knowledge about a project.

As with all code quality tools static analysis can be helpful but is not a panacea code may be completely defect free but still fail to function correctly.
Defect DensityA term that is often used as a metric for code quality is the defect density. This is nothing more than the ratio of defect to thousands of lines of code e.g. a defect density of 0.9 means that there is approximately one defect found in every 1100 lines of code.

The often quoted industry average defect density value is 1, as with all software metrics this can be a useful indicator but should not be used without understanding.

The value will be affected by improvements in the tool as well as how lines of code are counted so is exceptionally susceptible to gaming and long term trends must be treated with scepticism.
Practical examplesI have integrated two distinct static analysis tools into the development workflow for the NetSurf project which I shall present as case studies. These examples show a good open source solution and a commercial offering highlighting the issues with each.

Several other solutions, both open source and commercial, exist many of which have been examined and discarded as either impractical or proving less useful than those selected. However the investigation was not comprehensive and only considered what was practical for the project at the time.
clangThe clang project is a frontend to the LLVM project providing an optimising compiler for the C, C++ and objective C languages. As part of this project the compiler has been enhanced to run a collection of "checkers" which implement various methods of analysis on the code being compiled.

The "scan-build" tool is provided to make the using these features straightforward. This tool generates defect reports as a series of html files which show the analysis results.


NetSurf CI system scan-build overview
Because the scan-build takes in excess of eight minutes on powerful hardware the NetSurf developers are not going to run this tool themselves as a matter of course. To get the useful output without the downsides it was decided to integrate the scan into the CI system code quality checks.

NetSurf CI system scan-build result list
Whenever a git commit happens to the mainline branch and the standard check build completes successfully on all target architectures the scan is performed and the results are published as a list of defects.

The list is accessible directly through the CI interface and also incorporates a trend graph showing how many defects were detected in each build.

A scan-build report showing an extremely unlikely path to a defect
Each defect listed has a detail link which reveals the full analysis and logic necessary to cause the defect to occur.

Unfortunately even NetSurf which is a relatively small piece of software (around 200,000 lines of code at time of writing) causes 107 defects to be emitted by scan-build.

All but 25 of the defects are however "Dead Store" where the code has a value assigned but is never checked. These errors are simply not interesting to the developers and are occurring in code generated by a tool.

Of the remaining defects identified the majority are false positives and several (like the example in the image above) are simply improbable requiring a large number of steps to reach.

This shows up the main problem with the scan-build tool in that there is no way to suppress certain checks, mark defects as erroneous or avoid false positives using a model file. This reduces the usefulness of these builds because the developers all need to remember that this list of defects is not relevant.

Most of the NetSurf developers know that the project currently has 107 outstanding issues and if a code change or tool improvement were to change that value we have to manually work through the defect list one by one to check what had changed.
CoverityThe coverity SAVE tool is a commercial offering from a company founded in the Computer Systems Laboratory at Stanford University in Palo Alto, California. The results of the original novel research has produced a good solution which improved on analysis tools previously available.

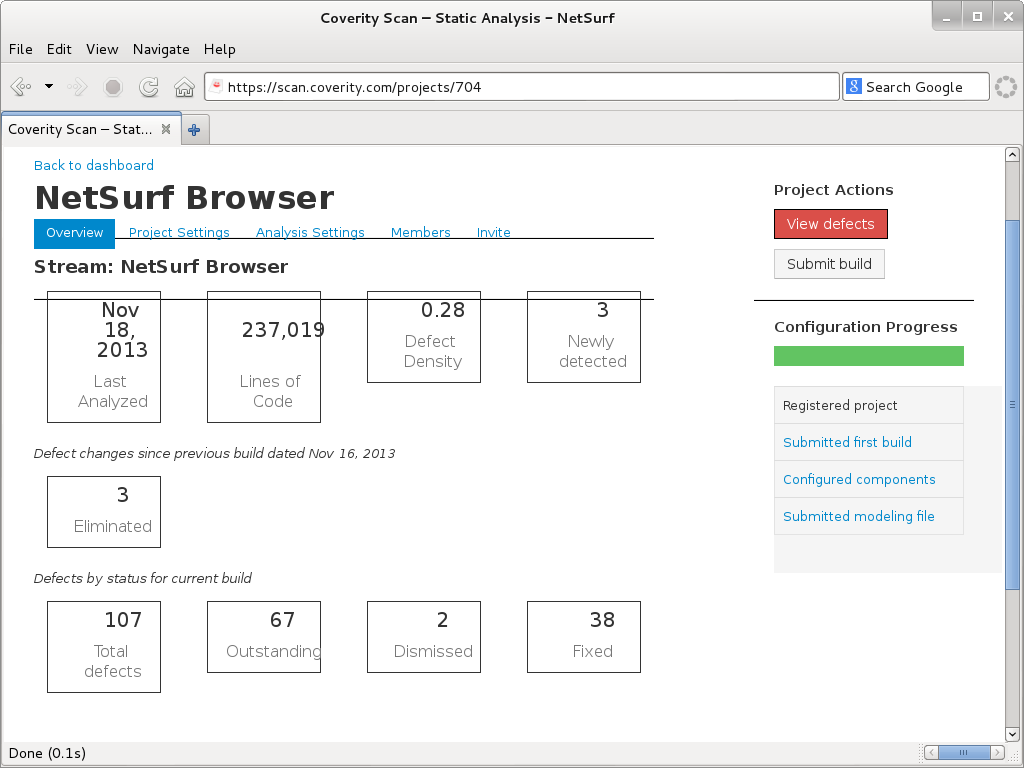
Coverity Interface showing summary of NetSurf analysis. Layout issues are a NetSurf bug
The company hosts a gratis service for open source projects, they even provide scans for the Linux kernel so project size does not appear to be an issue.

The challenges faced integrating the coverity tool into the build process differed from clang however the issue of execution time remained and the CI service was used.

The coverity scanning tool is a binary executable which collects data on the build which is then submitted to the coverity service to be analysed. This tool obviously relies upon the developer running the executable to trust coverity to some degree.

A basic examination of the binary was performed and determined the executable was not establishing network connections or performing and observably undesirable behaviour. From this investigation the decision was made that running the tool inside a sandbox environment on a CI build slave was safe. The CI system also submits the collected results in a compressed form directly to the coverity scan service.

Care must be taken to only submit builds according to the services Acceptable Use Policy which limits the submission frequency of NetSurf scans to every other day. To ensure the project stays within the rules the build performed by the CI system is manually controlled and confined to a subset of NetSurf developers.
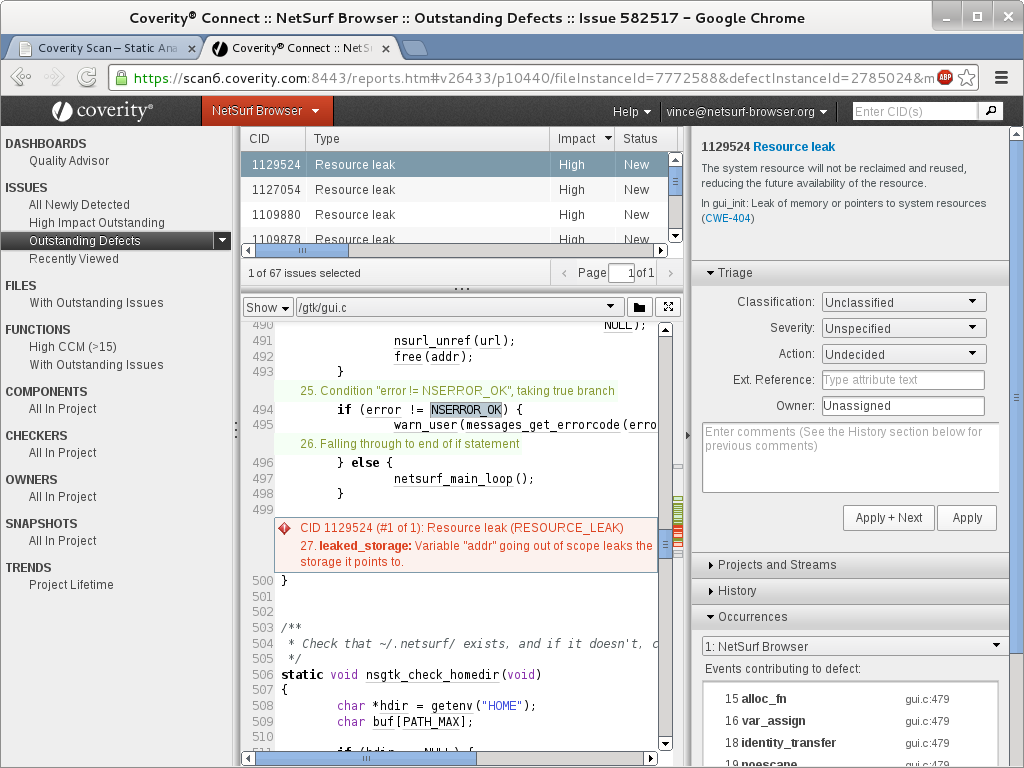
Coverity connect defect management console for NetSurfThe results are presented using the coverity connect web technology based defect management tool. Access to the coverity connect interface is controlled by a user management system which precludes publicly publishing the results within the CI system.

Unfortunately NetSurf itself does not currently have good enough JavaScript DOM bindings to support this interface so another browser must be used to view it.

Despite the drawbacks the quality of the analysis results is greatly superior to the clang solution. The false positive rate is very low while finding many real issues which had not been previously detected.

The analysis can be enhanced by use of collection configuration and modelling files which remove intended constructions from consideration reducing the false positive rate to very low levels. The ability to easily and persistently suppress false positives through the web interface is also available.

The false positive management capabilities coupled with a user interface that makes understanding the defect path simple make this solution very practical and indeed the NetSurf developers have removed over 50 actual issues within a relatively short period since the introduction of the tool.

Not all of those defects could be considered serious but they had the effect of encouraging deeper inspection of some very dubious smelling source.
ConclusionsThe principle conclusions of implementing and using static analysis have been:

When I started looking at this technology I was somewhat dubious about its usefulness but I have definitely changed my mind. It is a useful addition to any non-trivial project and the return on time and effort should be repaid handsomely in all but already perfect code (if you believe you have such code I have a bridge to sell you).

Russ Allbery: Review: The Pathway to Awesomeness

Review: The Pathway to Awesomeness, by Mark Forster
Publisher: Hyperink
Copyright: October 2013
ASIN: B00FXGXMPQ
Format: Kindle
Pages: 97
Mark Forster is probably my favorite time management (or, if you prefer, attention management) writer. The place to start with Forster if you're not familiar with him is Do It Tomorrow, not here. Unlike the other books by him I've reviewed, this is just an edited collection of blog posts presented in a convenient ebook form, without even an ISBN number. But if you've read his books (at least the ones that aren't out of print and cost a fortune), this is a convenient way to not have to trawl back through his blog and read the articles in a more convenient fashion. For me, it was also an easy way to give him a bit of money for his blog. Unless you have a similar motive, I don't think the content to price ratio is worth it. But I think everything is still up at Get Everything Done in case anything here strikes your fancy. As with most blog compilations, The Pathway to Awesomeness (I really hate that title) is composed of a whole bunch of fairly short articles, rarely more than three pages each, vaguely collected by topic. The first few are rather general and focused on the normal self-help platitudes that try to build up your sense that you're in control of your own life. But Forster doesn't take too long to get to what he's best at: short ideas, mental tools, interesting tricks, and simple techniques. Even more so than his books, due to the nature of this collection, there's a huge variety here, which means you can probably find something that strikes a chord no matter what attention management problem you've been running into. That's one of the main reasons why I prefer his writing: he tries to provide a giant toolbox instead of a single, streamlined System For Everyone. The other thing I like about Forster is that he is much more blunt than many authors about the biggest problem I have with attention management: trying to do more than anyone could possibly do given the available time. There are some more essays here about that, and several of them are quite good. I think my favorite is the short essay in which he points out how often people decide to do some task for a particular reason, and then get so engrossed in the performance of that task that they forget the original reason, risking sinking far more energy into that task than is actually warranted. Like a lot of Forster's observations, it's obvious in retrospect, but he has a way of phrasing those observation so that they shake the right thing loose in my head and let me re-evaluate something I was doing. Regular readers of Forster's blog know that he loves playing around with different simple to-do list management systems. Unfortunately, none of those are here, so don't pick this up expecting a collection of articles about Superfocus, Autofocus, etc. It makes sense given the topic of this collection, which is more general advice rather than systems, but this collection is so short that I wish he'd added a section on system development. I would have enjoyed reading a collection of all of his miniature systems together in one place and showing how he tweaked and changed them over time, particularly if he'd added some discussion of why he made each change and what goals he was trying to meet with each system. Ah well. If you aren't already familiar with Forster, there's no point in this, but if you are, I got a few new tidbits out of it and will probably skim through it a few more times. Buying it is mostly an exercise in putting money in the tip jar, and his writing is much less polished here (and more prone to cliches), but I still enjoyed reading through it. Rating: 7 out of 10

21 November 2013

Gunnar Wolf: Back aches...

This year, I had slowly taken again running. It's an activity I enjoy, even though I'm far from the condition I had when I did it every day My maximum was running about 8Km four days a week (ocassionally up to 15Km, say, on weekends)... But I slowly drifted out of it over the last three years. Yes, I have taken it up now and then, but dropped out again after a few weeks. Well, this year it felt I was getting back in the routine. Not without some gaps, but I had ran most weeks since July at least once, but usually two times. I started slowly, doing about 3Km close to home, but didn't take much to go back to my usual routes inside UNAM, doing a modest average of 4.5-5Km per run, and averaging somewhat over 8Km/h (6.5 min/Km). But... Well, I cannot relate precisely what happened on this Exactly a month ago, after a very average run (even a short one, 3.6Km), I had a lower back ache. Didn't pay too much attention to it, but it was strange since the first day, as I often have upper back aches Never lower. The pain came and went slowly several times. I kept cycling to work, although not every day. On October 27th, I even took the time to do the Ciclot n, a nice 38Km (including the ~5Km distance from home) around central Mexico City. I enjoyed the ride, even though every stop and re-start of the bike was a bit painful what hurts is to get off and on the bike: The posture change. But the pain has been almost constantly there. When I stand up, or when I sit down, it's about five minutes until the body gets used to the new position and stops hurting. Another strange data point: This last weekend (together with a national holiday) we went to a small conference in Guadalajara, and then to visit our friends in Guanajuato. So, we spent 12 hours on the bus there (12 Yes, there was an accident on the road, and we could not pass... So many hours were wasted there, and going back to a junction to take an alternative, longer road), then one night in a hotel bed, and two nights in our friends' guest mattresses which are not precisely luxury-grade. And Sunday night... I had no pain at all! Came back home, and after only one night back in our bed... I just could not move. I had the strongest pain so far. Could not even walk without some help. We went to the orthopedist a friend recommended, and I was seriously bending my posture: While that part of my posture is usually stable, my right hip was about 2cm higher than the left one, and my shoulders were almost 7cm displaced from my hips! So... Well, I'm having a cocktail of painkillers and antiinflamatories. The doctor says next week he wants me to have a tomography taken to better understand the causes for this. And, of course, tomorrow I'm leaving for Festival de Software Libre in Puerto Vallarta. I'm going there by plane, so no big hassle. But the way back, it will be 12 more hours on a bus. I'm... not precisely looking forward to this bus ride :( Anyway... I sorely miss my bike+running :(

Petter Reinholdtsen: All drones should be radio marked with what they do and who they belong to

Drones, flying robots, are getting more and more popular. The most know ones are the killer drones used by some government to murder people they do not like without giving them the chance of a fair trial, but the technology have many good uses too, from mapping and forest maintenance to photography and search and rescue. I am sure it is just a question of time before "bad drones" are in the hands of private enterprises and not only state criminals but petty criminals too. The drone technology is very useful and very dangerous. To have some control over the use of drones, I agree with Daniel Suarez in his TED talk "The kill decision shouldn't belong to a robot", where he suggested this little gem to keep the good while limiting the bad use of drones:
Each robot and drone should have a cryptographically signed I.D. burned in at the factory that can be used to track its movement through public spaces. We have license plates on cars, tail numbers on aircraft. This is no different. And every citizen should be able to download an app that shows the population of drones and autonomous vehicles moving through public spaces around them, both right now and historically. And civic leaders should deploy sensors and civic drones to detect rogue drones, and instead of sending killer drones of their own up to shoot them down, they should notify humans to their presence. And in certain very high-security areas, perhaps civic drones would snare them and drag them off to a bomb disposal facility. But notice, this is more an immune system than a weapons system. It would allow us to avail ourselves of the use of autonomous vehicles and drones while still preserving our open, civil society.
The key is that every citizen should be able to read the radio beacons sent from the drones in the area, to be able to check both the government and others use of drones. For such control to be effective, everyone must be able to do it. What should such beacon contain? At least formal owner, purpose, contact information and GPS location. Probably also the origin and target position of the current flight. And perhaps some registration number to be able to look up the drone in a central database tracking their movement. Robots should not have privacy. It is people who need privacy.

20 November 2013

Matt Zimmerman: Scaling Human Systems: Management

This is part 6 in a series on organizational design and growth.
The change from a business that the owner-entrepreneur can run with helpers to a business that requires management is a sweeping change. [...] One can compare the two kinds of business to two different kinds of organism: the insect, which is held together by a tough, hard skin, and the vertebrate animal, which has a skeleton. Land animals that are supported by a hard skin cannot grow beyond a few inches in size. To be larger, animals must have a skeleton. Yet the skeleton has not evolved out of the hard skin of the insect; for it is a different organ with different antecedents. Similarly, management becomes necessary when an organization reaches a certain size and complexity. But management, while it replaces the hard-skin structure of the owner-entrepreneur, is not its successor. It is, rather, its replacement. Peter Drucker
What it means Management is the art of enabling people to cooperate in achieving shared goals. I ve written elsewhere about what management is not. Management is a multifaceted discipline which is centered on people and the environment in which they work. Why it s important In very small organizations, management can be comparatively easy, and happen somewhat automatically, especially between people who have worked together before. But as organizations grow, management becomes a first-class concern, requiring dedicated practice and a higher degree of skill. Without due attention to management, coordination becomes excessively difficult, working systems are outgrown and become strained, and much of the important work described in this series just won t happen. Management is part of the infrastructure of the organization, and specifically the part which enables it to adapt and change as it grows. Old Status Quo People generally just do stuff , meaning there is little conscious understanding of the system in which people are working. If explicit managers exist, their jobs are poorly understood. Managers themselves may be confused or uncertain about what their purpose is, particularly if they are in such a role for the first time. The organization itself has probably developed more through accretion than deliberate design. New Status Quo People work within systems which help coordinate their work. These systems are consciously designed, explicitly communicated, and changed as often as necessary. Managers guide and coordinate the development and continuous improvement of these systems. The role of managers in the organization is broadly understood, and managers receive the training, support and coaching they need to be successful. Behaviors that help Obstacles that stand in our way

19 November 2013

Carl Chenet: Yarn: a scenario testing tool

Follow me also on Twitter Those who follow me on Twitter may have read my recent tweet about Yarn, a really nice software by Lars Wirzenius I discovered the last week-end while attending the Mini-Debconf UK in Cambridge. To make a long story short, Yarn allows the user to write scenarios of the executions of softwares. This scenario will be automatically played by Yarn which also returns the overview of the execution, with the goal to test the behaviour of these softwares. 1. Small example of how to use Yarn Let s have a look of how to use Yarn with a real example. The scenario will test if the software Brebis, a fully automatized backup checker, executes in an expected way. We can proceed as follow :
  1. set up the test environment
  2. launch a command with the software under test in the test environment
  3. verify the execution of the test
This is an example of a Yarn scenario file, the file is formatted using the Markdown syntax:
    SCENARIO basic brebis execution
    GIVEN setting up brebis
    AND generating backup configuration with brebis
    WHEN brebis verifies a backup
    THEN verify brebis output
    IMPLEMENTS GIVEN setting up brebis
    hg clone http://hg.brebisproject.org $DATADIR/brebis
    mkdir -p $DATADIR/brebis/yarn-test
    cp $DATADIR/brebis/functional-tests/expected-generated-list-for-tar-archive/expected-generated-list-for-tar-archive.tar.gz $DATADIR/brebis/yarn-test
    IMPLEMENTS GIVEN generating backup configuration with brebis
    $DATADIR/brebis/brebis.py -G $DATADIR/brebis/yarn-test/expected-generated-list-for-tar-archive.tar.gz
    IMPLEMENTS WHEN brebis verifies a backup
    $DATADIR/brebis/brebis.py -c $DATADIR/brebis/yarn-test -l $DATADIR/brebis/yarn-test/brebis.log
    IMPLEMENTS THEN verify brebis output
    if [ -s $DATADIR/brebis/yarn-test/brebis.log ]; then return 1; else return 0; fi
2. Result of the execution of the Yarn scenario Yarn provides at the end of the scenario an overview of the execution, as show below: $ yarn brebis-scenario
Scenario test suite PASS, with 1 scenarios (4 total steps), in 16.4 seconds 3. Details of the Yarn scenarios The five first lines are basically your scenario. Each step takes a keyword and a sentence to identify a step. You define a name with the SCENARIO keyword. The next step, GIVEN, allows generally the setup of the test environment. It is possible of course to define different steps with the keywork AND. Once the environment setup has been completed, we launch the test with the keyword WHEN. At last we check the result of the execution with THEN. It is worth noting that if you need further steps after checking the result of the execution, you can use FINALLY. Very helpful while setting up the test environment is the variable $DATADIR, automatically initialized by Yarn. It provides the path to a temporary directory where you can store files during the execution of your scenario. This directory is by default removed at the end of the scenario. Now the real trick: at each step I described above is associated shell commands to execute thanks to the IMPLEMENTS keyword.It s in my opinion a great way to increase the understanding of what the scenario really does. In a short glance of the first lines, if the names of the steps are carefully chosen, you will understand what the scenario does without needing to read the actual shell code. Simple and efficient. 4. More about Yarn Yarn is written in Python and now available in Debian in the package cmdtest. The sources are available here. In my opinion, if you were looking for this kind of tool, Yarn is in a really good direction. This project is still young but the core features do the job and the upstream is eager to receive feedbacks (and patches) :) Some links: Interested in Yarn? What do you think about it? Let us know in the comments of this post.

Luca Falavigna: Cross-architecture Linux containers in Debian

I wanted to create a Deb-o-Matic environment to testbuild packages for a different architecture. Taking inspiration on St phane s excellent blog post, I tried to replicate the creation of a cross-architecture Linux container in Debian. Here are the steps I made: Load binfmt_misc module:
# modprobe binfmt_misc Install the required packages:
# apt-get install lxc debootstrap rsync qemu-user-static binfmt-support Mount the cgroup virtual filesystem:
# mkdir /cgroup
# echo "none /cgroup cgroup defaults 0 0" >> /etc/fstab
# mount -a
I needed a specific template to create a cross-architecture container. I used the excellent one by Laurent Vivier. Download it, rename it as lxc-cross-debian, mark it executable, and store it under /usr/share/lxc/templates. Create the cross-architecture container, an armhf one in this case:
# lxc-create -t cross-debian -n debian-armhf -- --arch armhf --suite sid --interpreter-path /usr/bin/qemu-arm-static After a while, the container was created and I enjoyed my brand new armhf test machine :)

Rapha&#235;l Hertzog: Will Debian s technical committee coopt Keith Packard or Philipp Kern?

The process has been ongoing for more than a year but the Debian technical committee is about to select a candidate to recommend for its vacant seat. The Debian Project Leader will then (likely) appoint him (looks like it won t be a women). According to recent discussions on debian-ctte@lists.debian.org, it seems that either Keith Packard or Philipp Kern will join the committee. If you look at the current membership of the committee, you will see:
  • Bdale Garbee: USA
  • Russ Allbery: USA
  • Don Armstrong: USA
  • Andreas Barth: Germany
  • Ian Jackson: United Kingdom
  • Steve Langasek: USA
  • Colin Watson: United Kingdom
That s very Anglo-Saxon centric (6 out of 7 members). While I trust the current members and while I know that they are open-minded people, it still bothers me to see this important body with so few diversity. Coming back to the choice at hand, Keith Packard is American and Philipp Kern is German. No new country in the mix. I can only hope that Philipp will be picked to bring some more balance in the body.

9 comments Liked this article? Click here. My blog is Flattr-enabled.

Francois Marier: Things that work well with Tor

Tor is a proxy server which allows its users to hide their IP address from the websites they connect to. In order to provide this level of anonymity however, it introduces latency into these connections, an unfortunate performance-privacy trade-off which means that few users choose to do all of their browsing through Tor. Here are a few things that I have found work quite well through Tor. If there are any other interesting use cases I've missed, please leave a comment!

Tor setup There are already great docs on how to install and configure the Tor server and the only thing I would add is that I've found that having a Polipo proxy around is quite useful for those applications that support HTTP proxies but not SOCKS proxies. On Debian, it's just a matter of installing the polipo package and then configuring it as it used to be recommended by the Tor project.

RSS feeds The whole idea behind RSS feeds is that articles are downloaded in batch ahead of time. In other words, latency doesn't matter. I use akregator to read blogs and the way to make it fetch articles over Tor is to change the KDE-wide proxy server using systemsettings and setting a manual proxy of localhost on port 8008 (i.e. the local instance of Polipo). Similarly, I use podget to automatically fetch podcasts through this cron job in /etc/cron.d/podget-francois:
0 12 * * 1-5 francois   http_proxy=http://localhost:8008/ https_proxy=http://localhost:8008/ nocache nice ionice -n7 /usr/bin/podget -s
Prior to that, I was using hpodder and had the following in ~/.hpodder/curlrc:
proxy=socks4a://localhost:9050

GnuPG For those of us using the GNU Privacy Guard to exchange encrypted emails, keeping our public keyring up to date is important since it's the only way to ensure that revoked keys are taken into account. The script I use for this runs once a day and has the unfortunate side effect of revealing the contents of my address book to the keyserver I use. Therefore, I figured that I should at least hide my IP address by putting the following in ~/.gnupg/gpg.conf:
keyserver-options http-proxy=http://127.0.0.1:8008
However, that tends to makes key submission fail and so I created a key submission alias in my ~/.bashrc which avoids sending keys through Tor:
alias gpgsendkeys='gpg --send-keys --keyserver-options http-proxy=""'

Instant messaging Communication via XMPP is another use case that's not affected much by a bit of extra latency. To get Pidgin to talk to an XMPP server over Tor, simply open "Tools Preferences" and set a SOCKS5 (not Tor/Privacy) proxy of localhost on port 9050.

GMail Finally, I found that since I am running GMail in a separate browser profile, I can take advantage of GMail's excellent caching and preloading and run the whole thing over Tor by setting that entire browser profile to run its traffic through the Tor SOCKS proxy on port 9050.

18 November 2013

Daniel Pocock: $75,000 to explore free software during maternity leave?

A number of countries offer women various social benefits during maternity leave. A new scheme in Australia promises to give virtually all women one hundred percent of their salary (capped at a whopping $12,500 per month) and extend maternity leave to 6 months. Some believe it has been funded by abolishing fibre-to-the-home, but that is another topic... This is a dramatic upgrade - in both cash and time - from the existing scheme where women have 18 weeks leave at the minimum wage. In Australia, the "minimum wage" figure is a fantasy, well below the real cost of living. In practice, the existing scheme and economic pressure force many women back into their job in less than 18 weeks. The new scheme with a one hundred percent salary replacement eliminates much of that pressure. Many European countries offer women some payment that pays the real cost of living, for example, EUR 2,400 per month in France. That is more than the minimum wage in Australia, enough to cover food, clothing and rent in most French cities. Australia's new system, in comparison, will give women on high salaries enough cash to immediately hire a nanny and other discretionary expenses that will maintain their lifestyle as much as they can within reason while dealing with a new baby. The cap is 300% higher than in France and it is 100% wage replacement, whereas many European schemes only give women a percentage of their salary. For this reason, many people have described it as the "Rolls Royce" of maternity pay. Just who are the women in these higher salary brackets? It is hardly any surprise that many of them are in IT and engineering professions. The upper salary range of the new maternity leave scheme appears to squarely match with the cashflows of female software developers, web designers, project managers and potentially many other professionals with a background in science or engineering. Many women worry about being out of the workforce for too long and the potential impact on their skills and professional networks. In computing jobs, technology can change a lot in 6 months. There are many men and women who enjoy computing in their free time as much as in their job. For female developers with this time out of the office, the world's most comfortable maternity leave scheme could be an opportunity to spend a little time exploring the free software world. Just to be clear, I'm not suggesting that women should be reaching for the laptop when they first go into labor and getting plugged in to the web before the umbilical cord has been severed. Some people find technology to be a rewarding pursuit throughout their whole life, while others simply see it as a job. For those who find free software interesting, some may simply pursue something creative that has no relation to the IT projects in their job, some may bring some new experiences back to their job. Others may choose to reconsider their career, performing free software development work on a freelance basis rather than going back to an office environment. The "Rolls Royce" maternity pay scheme could provide a comfortable buffer for them as they evaluate their next steps and make such decisions.

Russ Allbery: Review: Anathem

Review: Anathem, by Neal Stephenson
Publisher: William Morrow
Copyright: 2008
ISBN: 0-06-147409-6
Format: Hardcover
Pages: 935
Fraa Erasmas is a little less than twenty years old and is an avout of the decade math of the Concent of Saunt Edhar. As Anathem opens, he's approaching his first apert. All of those words are left for the reader to puzzle out for themselves, unless you cheat and read the glossary (which I would recommend doing only with caution, but more on that in a moment), since Erasmas, the first-person narrator of this story, writes (mostly) as if the reader is familiar with the mathic world and its concepts. Translated into English, it means that Erasmas was brought into something akin to a scientific monastery (the "math") at around the age of nine and has been there for ten years, since his math is a decade math and therefore remains closed to all outside (s cular) ideas and contact for periods of ten years at a time. He is still a student there, not yet declaring allegiance to one of the chapters. That's something that he will be expected to do after the first apert. Every ten years, the decade math opens its doors to the outside world for a period of ten days (apert), and the fraas and suurs can leave the math and travel through the outside world as they wish. The start of Anathem is an exercise in alienation and reorientation. Stephenson has constructed a complex society with a long history and its own specific technical jargon and throws the reader into it with a minimum of orientation. Despite being familiar with SF novels that use this technique, I did read the preface and recommend that other readers do as well unless they particularly love piecing together a world from hints and clues. The timeline, in particular, was invaluable and something I referred to throughout the story. But even with the preface, you should expect to read the first part of Anathem interpolating meanings from context or just letting things slip past until you later come to understand them. A lot of people bounce off of Anathem here, and it's one of the reasons why I'd been postponing reading it (the other being that it's a substantial doorstop and I wanted to give it my undivided attention). But it's really not as bad as I feared. One gets a feel for the terms fairly quickly, and the more difficult ones Stephenson defines as he goes with excerpts from a dictionary of the mathic world. I found it slightly disorienting for a chapter or two, and then it started growing on me. The terminology is sometimes different just for the sake of being different (jeejahs are indistinguishable from smartphones for all practical purposes), but usually the invented words provide either important links to the past of the constructed world of Arbre or are technical terms that add precision and clarity once you know their meanings. It can be a little bit frustrating to remember the mapping of famous theories and theorems to the Orth names, but only mildly. (And Diax's Rake is so useful of a name for something that English doesn't name that I may start using it myself.) This is also why I recommend against reading the glossary. The definitions of terms are linked to important parts of history, which are, in turn, linked to important parts of the plot, and the glossary therefore risks spoilers. I liked having the term introduced by the frequent dictionary excerpts scattered through the chapters, and enjoyed the feeling of the terminology unfolding with the plot. The glossary is there if you really get lost, but I think the experienced SF reader (particularly if you have enough history background to pick up on the obvious parallels and start mapping bits to Greece, Rome, the Catholic Church, etc.) will be able to navigate the language without that much difficulty. I also stopped caring about the terminology because the story is so engrossing that it pulled me right into the book, closed over me, and made Erasmas's world feel real, precious, and fascinating. Whether that's going to be true of other people is a surprisingly difficult question, and one that I'll try to tackle as part of this review. But I will say up-front that I think this is the best book that Stephenson has ever written, even better than Snow Crash, despite some undeniable flab and one extremely irritating choice. Anathem is, at its heart, a novel about the scientific method. I think it's the first book by Stephenson that elegantly mingles his tendencies (and obsessions) as a writer with the interests (and obsessions) of the characters and makes the whole novel feel coherent. All of Stephenson's books are prone to discursive infodumps, but they've usually had to be shoehorned in around the characters. Even with the Baroque Cycle, a series full of natural philosophers, the digressions are jammed in around the plot like the filling of an over-packed box and frequently stick out at odd angles or dribble out on the floor. With Anathem, Stephenson has populated a book full of characters who have completely believable and engrossing reasons to digress into scientific debate and analysis, can put them into dialogue and thereby avoid some of the strain of the infodump, and (most importantly) largely restrains himself from narrative digressions via first-person narration and careful attention to when the characters themselves would follow the same digression. In short, this is a book full of very smart and very well-educated people who figure things out from first principles using agreed-upon theory, thrown into an unknown and dangerous situation that requires a great deal of deep thinking, science, engineering, and philosophy. All of Stephenson's quirks are still here, on prominent display, but rarely have I ever seen a better match of writer, characters, plot, and world background than this book. I would go so far as to say that, if you don't like this book, you're unlikely to like any long Stephenson. I haven't said a lot about the plot. Erasmas's apert is only the first part, and barely touches on any significant plot elements. It's mostly there to set some groundwork, introduce characters, and get the reader oriented. I'm not going to say much more, since the way the novel transitions from routine to unusual to emergency, and the resulting scramble to understand the emergency, is the heart and soul of this book and should not be spoiled. (I spoiled myself slightly by reading some analysis that I shouldn't have and regretted it, although it wasn't too much of a problem.) This is one of Stephenson's best-plotted novels. It develops slowly enough for the reader (and the characters) to think hard about it and make some good and bad guesses, but fast enough to stay engrossing. Most of it is very well-paced provided that you find the background of science and philosophy of science interesting. (If you don't, this is probably not a book you're going to enjoy.) I say "most of it" because, as mentioned earlier, this book is a bit flabby. There are a couple of sections where the theory and analysis are pushed aside by exigent circumstances and more action-oriented plot elements, both of which reminded me that Stephenson is very bad at writing action sequences and both of which I wished were shorter. And there are a couple of sections where Erasmas is getting oriented to a new situation or working up the courage to do something where I wished he'd get on with it already. But for a novel of nearly 1,000 pages, the amount of tension and reader interest Stephenson maintained for me was quite impressive. But as good as the plot is, the best part of this book is its full-bore, no-apologies embrace of understanding things. This is a book about making sense of the world, and about what it means to make sense of the world, and how you go about it, and what preconditions are required to do so. It is not, contrary to so much science fiction, a book about knowing things. The people who are already experts appear in this book, but generally only in the context of figuring out new things they've not previously been exposed to. Rather, it's a book about learning things, the thrill that comes from applying theory to understand something new, and the satisfaction of working through something from first principles or previously-established theory, arriving at testable predictions, and then testing them. It's the first novel I've read that captures some of the joy and delight that I got from reading George Gamow's One Two Three... Infinity as a child. Stephenson novels have always been about showing the reader neat things he learned, but I think previous books relied on the reader to bring their own enthusiasm. Anathem, at least for me, goes a step farther and uses the passion and approach of its characters to create that enthusiasm. It's one of those books that I not only enjoyed but went away from feeling like it made me a better person in some subtle but detectable way. Sadly, this is also where the irritating part comes in. I'm going to be very careful and indirect here, since the details are all extremely significant spoilers. You may want to skip to the last paragraph of this review if you want to avoid any knowledge about the end of Anathem. Stephenson pulls several rabbits out of the hat in this book, but most of them are well-defended and nicely handled bits of misdirection. There are a few where I thought the science or engineering was dubious, but even those are usually backed with enough hand-waving about Arbre technology that I could swallow it enough for the purposes of this book. (The timeline here is very helpful in allowing one to write off a few things as unknown technology.) But he puts, at the core of the plot, one of the most scientifically dubious bits of the whole book, and there's simply no avoiding that by the end of the story. Now, this doesn't mean that he just expects the reader to swallow it. Much of Anathem is a carefully-constructed defense of the bits he uses for the plot, and the defense is not half-bad within his fictional world. There are substantial in-book justifications for believing these techniques will work on Arbre even if they wouldn't in our scientific domain. So it's not so much the plausibility that bothered me; the idea is at least as plausible as some of the FTL drive concepts that I've swallowed without complaint. I do hold Anathem to a higher standard because the book is about science in a way that most science fiction isn't, but even with that, I think Stephenson mostly managed to dance across the thin ice he built. The problem is more subtle but more serious: if taken seriously on its own terms, the approach Stephenson takes to the plot destroys science in his universe. I can't really say more than that, since all of the details are huge spoilers, but the more I thought about it, the more irritated and annoyed I got. Anathem is otherwise a brilliant defense of the scientific method, and it felt like Stephenson injected a poison pill in the center of it, leading necessarily to a world where the scientific method no longer works. This does not happen on camera, or even between the pages of the book; you have to think about the implications for a while before you realize that's what happened. But once you do, it's a bitter pill to swallow, and it's hard to escape the feeling that it fundamentally undermines Stephenson's whole project here. And, to make it worse (although also oddly better in a way), I think it was unnecessary. He would have had to reconstruct the ending, but I can't shake the feeling that there were ways to write the ending, even maintaining the same character strengths, without having to pull that particular rabbit out of the hat. Because I think it's, in the end, unnecessary, I was still able to enjoy the whole book, including the ending, despite this, but while the rest of Anathem is a wholehearted 10, that choice knocked a full point off my impression of the book. It's profoundly irritating precisely because Stephenson did such an excellent job with the rest of it. But, that said, this book is still exceptional. I think it's the book that Stephenson was meant to write. Not only did he get the overall construction nearly perfect, he gets so many of the details right, from the history (which for a while I thought was merely clever, once I started seeing the correspondences that moved it out of the realm of pure invention, but which transitioned back to profound with later revelations in the book) to the language to the way that he excerpted some theoretic digressions into very well-done appendices. If you've ever thought of a theory as beautiful, or like reading about smart people debating the nature of understanding and knowledge, I cannot recommend this book too highly. Despite the highly irritating flaw at its center, and despite a few sections that show Stephenson is not a well-rounded writer, I think it's brilliant. Rating: 9 out of 10

Next.

Previous.