Search Results: "pm"

18 September 2008

Isaac Clerencia: Sketching words

Some months ago I came across Sketch Engine. Sketch Engine is a website that offers a collection of pre-loaded corpora in several languages and the ability to automatically extract collocation information from them among other things. You can get a 30-day free trial account if you want to check it out, the point is that I thought it was really cool, but it was a bit pricy, 55 euros/year for an individual and 1080 euros/year for a site (up to 50 employees and students) and these were the academic licenses!!! And I don’t even have any real need for it :P So I thought it would be an interesting project to do something similar, albeit just focusing in the ‘word sketching’ part, as described in this paper. After a weekend I got it working although I didn’t devote any second to make it look good as you can appreciate: Collocations and other stuff. For now only the corpus of the state of the union addresses is loaded, with almost 400000 words. You can select that corpus, click on sketch and get the sketch of any word, for example, the ‘word sketch’ for problem. We can see that the adjective used more times with ‘problem’ is ’serious’, although if we look at the relative frequency it’s ‘complex’. The verb which has ‘problem’ as object more times is ’solve’ followed by ‘approach’, ‘address’ and ‘deal’. You can also click on the numbers to see the actual sentences in which these words appear, for example, ’serious problem’. So how does it work? First of all it does part of speech tagging using Apertium. Once the text is POS-tagged we apply a set of ‘regular expression’-like rules to identify the relation between words, such as:

*DUAL
=a_modifier/modifies
2:[tag=adj] [tag=n] 0,2 1:[tag=n] [tag!=n]
This rule expresses the relation between adjectives and the nouns they modify, matching sentences like ‘the red ball‘ and ‘the red football ball‘. Each relation is stored in the database with extra info about position in the text. Once the database is created accessing it to display the sketch and concordance information is really simple. The site and auxiliary tools were written in around 1400 lines of Python/Django. I am still not sure about what to do with this, if there is anyone interested on adding some corpora to it, continue development or anything else, please let me know.

17 September 2008

Chris Lamb: Debian Developer

A few days ago I was awarded official Debian Developer status. Many thanks to: For posterity, my first experience with the Debian development process was with #400550. Never underestimate the importance of giving credit in changelog entries.

Lior Kaplan: Big Buck Bunny


What is common to The Gimp, Python, Inkscape, SVN and Ubuntu ? They are all part of Big Buck Bunny’s subtitles. I was very amused finding free software programs/projects in the subtitles (although expected in an open source movie). Except from the result of a funny movie, one of the things I like the most about the Peach project (and the Orange project who proceeded it), is the idea of developing the software in parallel to the creation of the movie and for the movie by adding missing capabilities or features. I’ve seen some of the new developments (mostly the particle engine) in Shlomi Israel’s lecture (in Hebrew) about Blender during August Penguin, and I really been impressed. Especially since I first heard about the new capabilities, and got a demonstration and only them saw the movie and understood where the particle engine was used. I’ve also seen similar behavior in my community by Guy Sheffer who developed two small tools for Cinelerra during the editing of the August Penguin videos. To conclude, I think there is room for similar projects in other areas for free software. Although a movie production is something non-technical people can understand, other projects can also select simple (but ambitious) objectives. Defining to where you want to go, or where you want to be is an important part of getting there. This might sound trivial, but a lot of people aren’t sure about the big picture of what they’re doing. That’s way I’m so happy to see such projects succeeding in fulfilling their objectives.

Miriam Ruiz: Indirect aggression is NOT a female form of aggression

A research conducted by Noel A. Card at the Universities of North Carolina and Kansas, that appears in the September / October issue of journal Child Development, challenges the popular misconception that indirect aggression is a female form of aggression. The meta-analysis is based on 148 studies of aggression in children and adolescents in schools, involving on the whole about 74,000 children and adolescents. Direct aggression is what we might call physical aggression, and indirect aggression includes covert behaviour designed to damage another individual’s social standing in his or her peer group. Based on the analysis, the researchers suggest that children who carry out one form of aggression may be inclined to carry out the other form. This is seen more in boys than in girls. The popular myth that girls are more likely to be socially aggressive has been proven wrong by this analysis, even though it has persisted among teachers, parents, and even among researchers, probably because of social expectations and recent movies and books portraying girls as mean and socially aggressive. They also found ties between both forms of aggression and adjustment problems. Direct aggression is related to problems like delinquency and ADHD-type symptoms, poor relationships with peers, and low prosocial behaviour such as helping and sharing, while indirect aggression is related to problems like depression and low self-esteem, as well as higher prosocial behaviour (perhaps because a child must use prosocial skills to encourage peers to exclude or gossip about others).

Russell Coker: Debugging as a Demonstration Sport

I was watching So You Think You Can Dance [1] and thinking about the benefits that it provides to the dancing industry. The increase in public appreciation for the sport will increase the amount of money that is available to professionals, and getting more people interested in dancing as a profession will increase the level of skill in the entire industry. While the show hasn’t interested me much (I prefer to watch dancing in the context of music videos and avoid the reality TV aspect) I appreciate what it is doing. On a more general note I think that anything which promotes interest in the arts is a good thing. I have been wondering whether similar benefits can be provided to the IT industry through competitions. There are some well established programming contests aimed at university level students and computer conferences often have contests. But the down-side of them in terms of audience interest is that they are either performed in exam conditions or performed over the course of days - neither of which makes for good viewing. The audience interaction is generally limited to the award ceremony and maybe some blog posts by the winners explaining their work. There are a number of real-world coding tasks that can be performed in a moderate amount of time. One example is debugging certain classes of bugs, this includes memory leaks, SEGVs, and certain types of performance and reliability problems. Another is fixing man pages. A way of running such a contest might be to have a dozen contestants on stage with their laptops connected to a KVM switch. They could choose tasks from the bug list of their favorite distribution, and when they completed a task (built a deb or rpm package with the bug fixed and updated the bug report with a patch) they could request to have their port on the KVM switch and their microphone enabled so that they could explain to the audience what they did. Points would be awarded based on the apparent difficulty of the bug and the clarify of the explanation to the audience. A major aim of such an exercise would be to encourage members of the audience to spend some of their spare time fixing bugs! Basically it would be a public Bug Squashing Party (BSP) but with points awarded and some minor prizes (it would be best to avoid significant prizes as that can lead to hostility).

16 September 2008

Biella Coleman: Playing for social good

When I was in Montreal in August, I got to spend some time with Simon Law, one of the first Free Software/Debian developers I met in full flesh and blood back in 2002. In August he was a bit worn but there was a definite sparkle in his eye. He was working at a new company doing some interesting development but he could not reveal just what had been up to. Just recently he clued me into what he was spending his night, days, and dreams working on. I have to admit, I am at once intrigued, puzzled, and surprised by this new reality based game, which won’t fully come out until 2009 but they are accepting beta testers. As you can read here, Akoha it is a social reality game which uses real world, mobile, and web technologies to engage people in game, play, and do-good type activities. As many others have written about, games are not just about play but they are economically lucrative enterprises. But economies are not only built around finances, money, and gold but can be moral economies based on reputation and also doing good. Akoha is thus directing the energies of fun and play in a combined digital and non-digital environment to build up just this playful moral economy. I look forward to seeing its path develop once it is finally released. If you are still confused as to what Akoha is, this video will shed some additional light on this social experiment.

Christoph Haas: MySQL to PostgreSQL - a Bacula conversion odyssey

Why is it that always the seemingly most simple things turn out to be the most annoying? This time I “just” wanted to get rid of one of my last MySQL databases and move it over to PostgreSQL. The Bacula catalog that saves which file I backed up when and to which storage medium. I tried with MySQL’s “mysqldump” and it’s PostgreSQL compatibility option - but apparently MySQL developers know nothing about PostgreSQL. Then I tried with “sqlfairy” - and found myself booting my system hard after it ate 2 GB of swap and died while converting 500 MB of data. So finally I asked in #bacula and was told to try CSV (comma-seperated values) as an intermediate format. Yuck… that satan-spawned format that reminds me of my dark past? Okay. First dump the catalog from MySQL: for table in BaseFiles CDImages Client Counters Device File Filename FileSet Job JobMedia Location LocationLog Log Media MediaType Path Pool Status Storage UnsavedFiles Version ; do mysqldump -u root -pmypassword -T. bacula $table; done (Okay, okay, this is not comma- but tab-seperated. But that’s even better for running the COPY-FROM command later.) This creates an ‘.sql’ (the schema) and a ‘.txt’ (the rows/records) file for each table in the current directory. Just don’t try to apply the schema to PostgreSQL. Instead better create a new schema. Bacula ships with a script for that purpose. Unless you have the PostgreSQL database for Bacula ready you should run something like… /usr/share/bacula-director/make_postgresql_tables -h localhost -U bacula …and… /usr/share/bacula-director/grant_postgresql_privileges -h localhost -U bacula Now on to read the tab-delimited data into PostgreSQL. The importing via the COPY command must be done with administrator privileges! And it’s important to explicitly state which columns correspond to which table columns (see the respective ‘.sql’ files) or otherwise you’ll get chaos. Of course this only has to be done for .txt files larger than 0 bytes. Oh, and the filename has to be absolute. Example: Unfortunately my “Job.txt” and “Media.txt” contained datestamp entries like “0000-00-00 00:00:00″ which are not valid for PostgreSQL. So I went into Vim and replaced it: s/0000-00-00 00:00:00/1970-01-01 00:00:00/g. Clear the table (DELETE FROM job) and import again. And finally it’s important to get the sequence numbers right as described in the Bacula manual. Morale: spend two extra-minutes to start with PostgreSQL right away instead of bothering about conversions later. And never assume converting from one database to another would work - just because both have “SQL” in their names.

14 September 2008

Russell Coker: The Problem is Too Many Remote Controls

I am often asked for advice about purchasing TVs and consumer electronics. Not that I am any great expert in those areas, but my general experience in specifying and purchasing electronics goods in related to my computer work does translate to other areas (and I know where to find advice on the net). As part of this I get to closely observe what happens when people install new home entertainment systems. I have not observed anyone who uses anywhere near the full function of their system, even using the bare minimum functionality in all areas is very rare. I believe that the first problem with this is the input devices. A remote control is designed around the idea of one button for each high-level command, this can be compared to languages such as Chinese and Japanese which have one character per word. In terms of language evolution it seems that the benefits of having multiple characters became apparent and widely accepted thousands of years ago. Now for a simple input device having one button for each high-level operation makes sense. For the basic functions of a VCR you have PLAY, STOP, Fast-Forward, Rewind, Record, and Eject - 6 buttons is quite reasonable. But then you want slightly advanced features such as “record from 8PM to 9PM on channel A and then record from 10PM to 11PM on channel B” and things become unreasonably difficult. More than 10 years ago I was recommending that people just buy 5 hour tapes and press record before leaving home, getting the full functionality out of a VCR was just too hard. Jokes are often made about people who leave their VCR flashing 12:00 (because it’s too difficult to set the time), I only set the time on a VCR to stop the flashing (flashing lights annoy me). Since programmable VCRs became popular things have only continued to develop. Now it’s not uncommon to have separate remote controls for the TV, VCR, DVD player, and the Cable TV box - a total of four remote controls! This is obviously a problem, and the solution that some people are adopting is to have a single more complex remote control - this is an example of problems not being solved by the same type of thinking that caused them. One of the attempts to solve this is to have everything controlled by a PVR [1]. This means that you have one device recording content (maybe from multiple sources or multiple channels), playing recorded content or live content, and maybe playing DVDs and CDs. Of course then you have a complex remote control for that device which just shifts the problem. To solve these problems we need to consider the entire problem space from a high-level. We start with the signal that is displayed by the TV, it can come from cable TV, digital TV, analogue TV, VCR, or DVD - these input sources have names such as “Composite”, “RCA1″, “RCA2″, “RCA3″, “DTV”, and “ATV”. Often people have written instructions near their TV to map these names to what they do. Obviously the TV needs to be able to be programmed with human friendly names, and as these names are not of much use on their own it should be possible to use compound names and abbreviations. If I want to watch ABC (the Australian Government sponsored TV channel) then I would rather type “ABC” on a keyboard and then have the entertainment system determine whether that maps to “cable:abc”, “dtv:abc”, or “atv:abc” depending on what options are available. The current process of choosing an input source (such as RCA1 mapping to cable TV) and then choosing a channel (102 mapping to ABC) means among other things that it is essentially impossible for a guest to control the TV. A further problem is the lack of available output. While it might seem that a large-screen HDTV has adequate output available, it’s often the case that you don’t want to stop watching one show while trying to find another. When something of wide interest is happening (another war or an election) it’s common for several people in one room to want to watch the news. Having everyone stop watching while someone goes through menus to find a different news channel is not well accepted. It seems to me that we need a separate output mechanism for controlling the entire system from that which is used for the main display. This of course requires integration between all parts of the entertainment system, which shouldn’t be that difficult given the complexity of all the components (every one of which has more compute power than a typical server of 20 years ago). It is currently quite common for PVRs and DVD players to support playing videos from USB and SD devices, so the next logical step is to get an Ethernet port in each device (and maybe have Ethernet switches built in to some of the high-end entertainment hardware). Then XML transferred over HTTP could be used for controlling the different components from a single web server which provides a web-based GUI. While a random guest would not get much functionality out of my TV configuration (or that of most homes where I have assisted in the configuration of new hardware), they shuold be able to use a web-based GUI with ease. For controlling the entire system a NetBook [2] computer such as the EeePC should do well. As high-end TVs cost over $5,000 an EeePC which costs $500 (list price - surely less in bulk) could easily be bundled without much impact on the overall price in the same way that companies selling computers in the $1,000,000 price range used to bundle $10,000 workstations to manage them. An EeePC has abut the same size and mass as four remote controls (so it wouldn’t be inconvenient to use). Also the built-in wifi could be used for the remote control (wires are inconvenient and Infra-Red has limited bandwidth so probably wouldn’t provide a good web based GUI). Also someone who wanted to save some money could instead choose to use an old laptop on a coffee table (any web browser would do). I have deployed Linux desktop machines for some people who had no trouble using it, but who then had trouble using TVs that I configured for them - so I conclude that a modern Linux distribution is significantly more user friendly than the equipment that you find in a modern lounge room. Cable TV companies all seem to be ISPs and often provide compelling value as an ISP service if you want to use the TV service. So it seems that the “Cable Modem” could be built in to the Cable TV box for added savings in hardware purchase and less boxes to manage in the home. This of course would increase the value of a NetBook [2] as a remote control as it could also be used for general Internet access at the same time. TV shows often promote their web sites to their customers and TV advertising also often includes a URL. If the URLs were distributed by VideoText then that would provide more information for the viewers, a better reach for advertisers and people who create the TV shows, and it when it became popular it would save us fom those stupid scrolling news tickers that appear on the bottom of most cable new shows! Some of these benefits are currently achieved by people running MythTV. The first problem with Myth is that it is still largely stuck to the bad old UI paradigm (which of course can be fixed as it’s free software). The next problem is that getting a result of comparable quality to the dedicated hardware is expensive, difficult, or both. A regular PC makes more noise than you desire in your lounge room and configuring a Myth machine for your choice of DTV hardware and the frequencies used in your location is a pain. You can buy a preconfigured machine which solves these problems, but it will be more expensive. For most lounge rooms the cheap Chinese hardware is what will be used. Ultimately I believe that TV will be killed by the Internet. The range of content on the net is increasing and the rate of acceleration is also increasing. TV seems to have not made any significant changes since the introduction of cable and satellite TV (both of which happened a long time ago and were not significant changes). But I don’t expect it to happen soon. I predict another 10 years of the current TV business model. I believe that better integration of home entertainment hardware so that it can obey simpler commands from the user in a more friendly manner while not getting in the way of the main purpose (displaying the TV picture) has the potential to extend the life of the current TV business model. Not that I care whether the TV industry dies sooner or later. I just want to escape from having to provide phone-support to people who can’t get their TV to work correctly!

13 September 2008

Meike Reichle: More Blatant Advertising: Eleonore Digital

Here's one more post for my own little "advertising section", where I introduce gender-related projects that I think are a good idea but deserve some more publicity. So, last time we had geekspeakr.com, this time I'd like to introduce to you the Eleonore Digital Project. In a nutshell they are organising a project where groups of students all over Europe work together in creating an educational 3D computer game that deals with the life of Eleanor of Aquitaine. Each team is assigned an episode or a certain aspect of Eleonore's life and they will research this, draft a concept and finally create their respective part or episode of the game. Doing this they will only work with free software, namely Debian as the Operating System, OOo, Blender etc. A longer (and better) description of what they want to do and the motivation behind all of this can be found in their project description or on the Eleonore Project site itself. In my opinion the project seems to be a really good idea and I wish them the best of luck! What I like most about it is that it is not exclusively for girls, so that it does not create a kind of "artificial biotope" for girls to work in. Instead it aims to rise the girls ratio by means of a project topic that (so I assume) mostly appeals to girls. And I am especially happy that when looking for a topic that appeals to girls they came up with something better than fan homepages, foto love stories, and what else you find in "girls IT projects" these days. I am pretty sure that reading and researching on the life of one of the most influential women in European history is going to do them much more good that creating princess-themes webpages! I am also quite happy that they picked Debian as their operating system. I think Debian being used in a school project is a nice example that it is in fact not as "user-unfriendly" as it is often claimed to be! I've also introduced the project to the Debian Women Project and Miriam had the very good idea to also forward it to the Debian Games Team, so I hope we'll get some good cooperation here.

Bastian Blank: Smallest UTF32 to UTF8 converter

I found some weird opcodes in the s390 instruction set some time ago. I finally want to use it as I have access to such a machine. The result is rather slim:
.globl cu41
        .type   cu41, @function
cu41:
.L2:
        cu41    %r2,%r4
        ipm     %r1
        srl     %r1,28
        chi     %r1,3
        je      .L2
        ltr     %r1,%r1
        je      .L3
        lcr     %r1,%r1
        lgfr    %r3,%r1
.L3:
        lgr     %r2,%r3
        br      %r14
The cu41 opcode translates UTF32 to UTF8. Each "parameter" is a register pair [1], which describes address and length of the buffer. This opcode will return after a not specified number of translated characters. The rest is boiler plate code for condition code checking. The loop makes sure that anything is converted within the function unless another error occured.
[1]An even pair. gcc is not yet able to allocate such pairs on its own, so it is hardcoded.

10 September 2008

Michal Čihař: Gammu test version 1.20.91

New testing version of Gammu was just born. It brings quite a lot of fixes -- I simply release it because changelog got too big :-). Full list of changes: You can download from usual place: http://cihar.com/gammu/, Debian users will find packages in experimental soon. PS: I still have about 50 unread mails about Gammu, so please be patient.

Russell Coker: Efficiency of Cooling Servers

One thing I had wondered was why home air-conditioning systems are more efficient than air-conditioning systems for server rooms. I received some advice on this matter from the manager of a small server room (which houses about 30 racks of very powerful and power hungry servers). The first issue is terminology, the efficiency of a “chiller” is regarded as the number of Watts of heat energy removed divided by the number of Watts of electricity consumed by the chiller. For example when using a 200% efficient air cooling plant, a 100W light bulb is rated as being a 150W heat source. 100W to Heat it, 50W from the cooling plant to cool it. For domestic cooling I believe that 300% is fairly common for modern “split systems” (it’s the specifications for the air-conditioning on my house and the other air-conditioners on display had similar ratings). For high-density server rooms with free air cooling I have been told that a typical efficiency range is between 80% and 110%! So it’s possible to use MORE electricity on cooling than on running the servers! One difficulty in cooling a server room is that the air often can’t flow freely (unlike a big open space such as the lounge room of your house). Another is the range of temperatures and the density of heat production in some parts (a 2RU server can dissipate 1000W of heat in a small space). These factors can be minimised by extracting hot air at the top and/or rear of racks and forcing cold air in the bottom and/or the front and by being very careful when planning where to place equipment. HP offers some services related to designing a server room to increase cooling efficiency, one of the services is using computational fluid dynamics to simulate the air-flow in the server-room [1]! CFD is difficult and expensive (the complete package from HP for a small server room costs more than some new cars), I believe that the fact that it is necessary for correct operation of some server rooms is an indication of the difficulty of the problem. The most effective ways of cooling servers involve tight coupling of chillers and servers. This often means using chilled water or another liquid to extract the heat. Chilled water refrigeration systems largely remove the problem of being unable to extract the heat from the right places, but instead you have some inefficiency in pumping the water and the servers are fixed in place. I have not seen or heard of chilled water being used for 2RU servers (I’m not saying that it doesn’t get used or that it wouldn’t make sense - merely that I haven’t seen it). When installing smaller servers (2RU and below) there is often a desire to move them and attaching a chilled-water cooling system would make such a move more difficult and expensive. When a server weighs a ton or more then you aren’t going to move it in a hurry (big servers have to be mostly disassembled before the shell can be moved, and the shell might require the efforts of four men to move it). Another issue related to water cooling is the weight. Managing a moderate amount of water involves a lot of heavy pipes (a leak would be really bad) and the water itself can weigh a lot. A server room that is based around 20Kg servers might have some issues with the extra weight of water cooling (particularly the older rooms), but a server room designed for a single rack that weighs a ton can probably cope. I have been told that the cooling systems for low density server rooms are typically as efficient as those used for houses, and may even be more efficient. I expect that when designing an air-conditioner the engineering trade-offs when designing for home use favor low purchase price. But someone who approves the purchase of an industrial cooling system will be more concerned about the overall cost of operations and will be prepared to spend some extra money up-front and recover it over the course of a few years. The fact that server rooms run 24*7 also gives more opportunity to recover the money spent on the purchase (my home A-C system runs for about 3 months a year for considerably less than 24 hours a day). So it seems that the way to cool servers efficiently is to have low density server rooms (to the largest extent possible). One step towards this goal would be to have servers nearer the end users. For example having workgroup servers near the workgroup (instead of in the server room). Of course physical security of those servers would be more challenging - but if all the users have regular desktop PCs that can be easily 0wned then having the server for them in the same room probably doesn’t make things any worse. Modern tower servers are more powerful than rack mounted servers that were available a few years ago while also being very quiet. A typical rack-mounted server is not something you would want near your desk, but one of the quiet tower servers works quite well.

9 September 2008

Russell Coker: SE Linux in Lenny status - Achieved Level 1

I previously described the goals for SE Linux development in Lenny and assigned numbers to the levels of support [1]. I have just uploaded a new policy to unstable which I hope to get in Lenny that will solve all the major issues for level 1 of support (default configuration with the unconfined_t domain for all user sessions - much like the old “targeted” policy). The policy in question is in my Lenny SE Linux repository [2] (for those who don’t want to wait for it to get into Unstable or Lenny).

Erich Schubert: Increasing your privacy

Many people are already aware of the amount of data Google can (and does) collect on them. Some people therefore refuse to use certain google applications altogether. Others just like them too much.There are some services that won't work with heavy ad blocking and anonymizing services - others will work just fine. A prime example everybody uses is Google search.Google search will work just fine if you use anonymizers. Google Mail won't.Privoxy and TOR is a great combination for anonymizing, however you won't want to use them for bandwidth-heavy web surfing, and there is little benefit of using them for web sites where you authenticate anyway.Here's a way to do a compromise:
  1. Install and configure Privoxy and TOR. Make sure they work.
  2. Setup a proxy.pac file (proxy autoconfiguration) for your browser like this:
    function FindProxyForURL(url, host)  
        var google = /https?:\/\/([^/]*\.)?google\.[a-z]*($ \/)/;
        var tor = /https?:\/\/([^/]*)\.(exit onion)($ \/)/;
        if (google.test(url))  
            if (shExpMatch(url, "*.google.com/mail*"))  
                return "DIRECT";
             
            return "PROXY 127.0.0.1:8118";
         
        if (tor.test(url))  
            return "PROXY 127.0.0.1:8118";
         
        if (shExpMatch(host, "config.privoxy.org"))  
            return "PROXY 127.0.0.1:8118";
         
        return "DIRECT";
     
    
    and point your browser to it.
  3. Add the following to your privoxy/user.action file:
      +client-header-filter hide-tor-exit-notation   
    .exit
      +filter js-events  +crunch-all-cookies  
    .google./(search blogsearch scholar images)
    
    And don't forget to reload privoxy.
You should now be able to access Google search with enhanced privacy (I can't guarantee you they won't be able to track you though!) while at the same time you can access your Gmail account at full speed.When using Google Search (including image, blog and scholar search, feel free to add additional services) you should be seeing a login button, while you could be accessing Google Mail at the same time in another tab.This list is of course not exhaustive. You might want to actually use privoxy and TOR by default, and only disable it for certain sites (or configure privoxy accordingly). You get the idea: this is just a very minimal approach to disable tracking exactly by the Google search site. It all depends on how serious you are about privacy and how important data throughput is for you.Also it will allow you to access certain TOR functionality (such as hidden services) without running TOR all the time (after all, it is and will always be slower than direct access).[Update: apparently some TOR exit nodes trigger a spam protection on Google, and without cookies you can't solve the captcha. So the use of TOR doesn't work well with Google. All the privoxy cookie blocking however is still recommended.]

8 September 2008

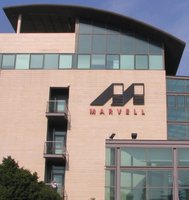
Martin Michlmayr: Visiting Marvell in Yoqne'am

Marvell in Yoqne'am Since I'm spending the summer in Israel, I used the opportunity yesterday to visit the Marvell site in Yoqne'am where the majority of the NAS software engineering team is located. They first gave me a tour through the hardware labs which I found incredibly interesting. It's amazing what equipment those folks use to perform QA tests of new chips, how they can reverse engineer chips and even make some modifications to test their theories about hardware bugs. I found it really amazing and at the same time felt glad that changing things in software is so easy. Later they showed me the software lab where they had an exhibition of various devices based on the Orion chip, including NAS devices, but also printers, wifi APs and game machines. They also told me some details of their product roadmap but unfortunately I cannot share that information. The only thing I can say is that we'll see a lot of new devices to which it would be cool to port Debian.

7 September 2008

Michal Čihař: More fun with phpMyAdmin package in Debian

When finishing series of articles about Debian packaging and writing about dbconfig-common, I just had to ask myself, why it is not used in phpMyAdmin package. I did not find any reason and as Thijs did not have any objections, I hacked it together this evening. So what you will get? All fancy features where phpMyAdmin requires it's database to manage some additional features. For example you can create PDF pages with structure of your database, add additional comments to databases, notice relations between MyISAM tables, etc. Simply see wiki for more details. Besides this, phpMyAdmin is now automatically configured to use database you choose using dbconfig-common, so you can also connect to remote MySQL server without manually configuring anything. The only thing which scares me a bit is that we now increased a lot number of debconf questions user has to reply by this...

5 September 2008

Gunnar Wolf: Awesome!

For about eight years, I was a very happy WindowMaker user. It was very lightweight, aesthetically pleasing, and I had interiorized its behaviour and keybindings so much, I didn't feel I'd ever switch away. I periodically tried (forced myself even!) to use any of the other, more en vogue environments... Experimented using Gnome for a week, KDE for a week, XFCE for a week (so I would have enough time to learn their ways)... And always came back to my good, well-known wmaker.

In 2006, when we held DebConf6 in Mexico, I saw how other people worked with ion3. I fell immediately in love with it. Not because it is prettier, snappier or has nicer widgets than other window managers - but because it is enormously more usable. Quoting Tuomo Valkonen, the ion3 author,
Ion is not perfect and certainly not for everyone, but neither is any user interface. Usability is subjective.
Using a keyboard-oriented, tiling window manager represented -for the first time in 20 years (I had my first contact with a Macintosh in 1986)- a radical user interface change. For my way of working, I just don't need a desktop, I don't need having a background space or overlapping windows. What I need is a way to functionally organize the windows I have open at any given time, quickly switch between them (and not depending on the mouse, please!), maximizing screen space and all that. ion3 was godsent.
Now, in 2007 there was (yet another) huge flamefest. Valkonen basically does not want distributors distributing any version of ion3 that's not the latest, and introducing changes not approved by him - He basically demands ion to be non-free. So, it was moved to the non-free section of Debian where only Womble decided to keep giving it support. And, of course, by September 2007 Julien Danjou announced he had written another window manager: Awesome.
My main motivation for switching away from ion3 is that... I don't want to use non-free software. But I was very comfortable with ion3. It was only after I saw many other people using Awesome at DebConf8 I decided to bite the bullet and switch. It looked at least as comfortable as ion3.
But... Well, I cannot come up with better phrasing than what Joey said when he switched to Awesome, almost exactly a month ago. When changing between the mainstream window managers, the differences are mostly cosmetic. But with these really different window managers... I cannot but reproduce Joey's words:
I wish I had a good analogy to explain to my nontechnical readers what changing to a new window manager is about.
One way to think about it is that it's like driving a car down the road, and suddenly swapping the steering wheel and brakes out for a tiller and gear shifter. And having to downshift for braking until you learn that the brakes moved to the turn indicator lever. By trial and error.
But that's really only part of it. Another way to look at it is adopting a new philosophy. Or, in some cases a cult. (In some cases, with crazy cult leaders.) Whether they use Windows or a Mac, or Linux, most computer users are members of a big established religion, with some implicit assumptions, like "thy windows shall be overlapping, like papers on the desktop, and thou shalt move them with thy mouse".
So, changing to a new window manager is a process of being dumped into a different environment, where nothing works like you've come to expect, and trying to construct a mental model that you can use to make sense of it. But it's also a process of modifying that environment to behave the way you like.
And when done whole-heartedly, this doesn't just mean trying to make it like the environment you were used to before. It means trying to absorb the underlying philosopy of the window manager, and think up new ways of doing things, inspired by that philosopy, and modify the environment to allow doing those things.
So ideally, "I switched to a new window manager" doesn't mean "my screen has some different widgets on it now". It means "I'm looking at the screen with new eyes."
So, what's so different?
Besides learning some new keybindings (expected, of course), Awesome has several suggested layouts to help you organize your workflow, usually (although not always) consisting of a main area and a side area, tiled side by side (or one above the other, or several stranger ways). This sounds rigid, but it is incredibly comfortable - and I've only been an Awesome user for three days!
But what sets Awesome apart from basically anything else is the concept of tags. Whey you see an Awesome session, you recognize something similar to the very well known workspaces concept we have had in any Unix-like environment for many years, right? Well, but they are not workspaces. They are tags. What is the difference?
When I work with workspace, each of my windows can be in a different workspace. So in one, I'll have my mail-related stuff. In another one, I might be browsing. In another one, I have my development things, and I might be following some logfiles in yet another one.
Awesome allows you to use tags for categorization in much a more flexible way.
For example: I am mostly a web-oriented developer. I usually need four things when developing a system: A browser, Emacs, the log for my development server, and a console where I can peek and poke at my objects and interactions. Of course, cramming them all into the same screen makes no sense - It would be better to follow the good ol' desktop metaphore, and just switch the focus and raise the window, right?
In Awesome, I can have them all set to the maximum screen size - _and_ use the most common combinations as well. Each of the windows can be tagged to more than one workspace (and yes, this is immensely more flexible than the always visible hint on traditional WMs).
To begin with, I'll give each major process a tag to itself, to work full-screen. Emacs is on tag 1, my browser on tag 2. The log and the console share a terminal (i.e. via screen or terminator).
This console by itself is not too useful, so I'll set it to tag 4, and we will go back to it later.
So if I'm building a view or following online documentation, I will add tag 3 to both Emacs and the browser.
I'm also setting tag 4 to the browser - That allows me to use it next to my terminal, following the results of my website-clicking.
And, of course, tag 5 will be set to Emacs and to the console, so I can quickly check any quick API-related question that does not need the documentation or look at a newly written method.
By the way, have you noticed CapsLock is the most stupid key invented, ever? Ok, I gave a good use to it: It's called Mod4. Imagine it is just an extra Ctrl, Alt or Meta key.
So, Mod4-1 gives me Emacs. Mod4-2 gives me the browser. Mod4-3 gives Emacs+browser, Mod4-4 gives browser+console, and Mod4-5 gives Emacs+console. And, of course, the handy Mod4-0 gives me all of my open windows tiled side by side.
Even this is a pattern of being a newbie, I know - I could keep 4 and 5 free, and just tag several simultaneous tags to be active. How? Switch to tag 1 exclusively (Mod4-1), and activate tag2 as well (Ctrl-Mod4-2). There, I have Emacs and browser side by side. Want to get the console instead of the browser? Simple. Ctrl-Mod4-2 (toggle off tag 2), Ctrl-Mod4-3 (toggle on tag 3).
Anyway - As you can see, I am excited at finding a very new and nice tool to help me work better. Today I was playing a bit with the Awesome widgets, but that's something to be talked about later.
In Debian, we are at a crossing point: Awesome is just reaching ion3's popularity. And I'm adding my two main machines' votes to Awesome.
This is Awesome. Quoting (yes, one last quote) the official Awesome site, This gonna be LEGEN... wait for it... DARY!.

Matthew Garrett: Power management and graphics

It's the X Development Summit in Edinburgh this week, so I've been hanging out with the graphics crowd. There hasn't been a huge amount of work done in the field of power management in graphics so far - Intel have framebuffer compression and there's the lvds reclocking patch I wrote (I've cleaned this up somewhat since then, but it probably wants some refactoring to avoid increasing CPU usage based on its use of damage for update notifications). That still leaves us with some fun things to look at, though.

The most obvious issue is the gpu clock. Intel's chipset implements clock gating, where unused sections of chip automatically unclock themselves. This is pleasingly transparent to the OS, and we get power savings without any complexity we have to care about. However, there's no way to control the core clock of the GPU - it's part of the northbridge and fiddling with the clocking of that would be likely to upset things. Nvidia and Radeon hardware is more interesting in this respect, since we can control the gpu clock independently of anything else. The problem is trying to do so in a reasonable way.

In an ideal universe, we can change these clock frequencies quickly and without any visual artifacts. That way it's possible to leave it in the lowest state and clock it up as load develops. There's a couple of problems with this - non ideal hardware, and the software in the first place. Jerome's been testing a little on Radeon and discovered that changing the memory clock through Atom results in visual corruption. It's conceivable that this is due to some memory transaction cycles getting corrupted as the clock gets changed. If we could ensure that the reclock happens during the vertical blank interval, that's something that could potentially be avoided (of course, then we have the entertainment of working out when the vertical blank interval actually is when you have a dual head output...). The other problem is that 3D software tends to consume as many resources as are available. Games will produce as many frames per second as possible. Demand-based clocking will simply ramp the gpu to full speed in that situation, which isn't necessarily what you want in the battery case (as the number of frames per second goes up, so does the cpu usage - even more power draw) but is probably pretty reasonable in the powered case.

Handwavy testing suggests that this can save a pretty significant amount of power, so it's something that I'm planning on working on. Further optimisations include things like making sure that we're not running any PLLs that aren't being used at the time (oscillators chew power), not powering up output ports when you're not outputting to them and enabling any hardware-level features that we're currently ignoring. And, ideally, doing all of this without causing the machine to hang on a regular basis.

MJ Ray: Friday Opinion Request 2: Are Your Free Software T-Shirts Ethical?

News reports have described the use of forced child labour for cotton harvesting in Uzbekistan, which is then used in t-shirts and so on, including those sold by some major shops in England like Asda/Wal-Mart, as I mentioned on the debian-project email list last autumn. When you buy badly-produced T-shirts to support free software projects, you may be helping provide freedom for more software users in your country, but you may also be helping to enslave vulnerable workers in other countries. If you buy Debian T-shirts from the UK, you’re probably OK. This is something that the Debian UK Society seems to do right. Their buyer (and current Debian Project Leader) Steve McIntyre wrote:
“[Fruit of the Loom premium Ts, Kustom Kit Augusta/405 polo shirts ...] both FotL and KK have ethics statements that describe their standards. The KK one is linked off the front page of their website; the FotL details I have in .doc format that I’ll pass on if people would like to see them.” (original)
I also asked my local perl mongers group to do similar but there’s been no response to that yet (or any t-shirts AFAIK). I’ve been told that all of the FSF Europe gear is Fair Trade but it doesn’t say that on their web shop. How about other free software projects? Have you asked about your T-shirts? Is there a central site for this sort of information?

Next.

Previous.