Search Results: "ron"

23 December 2013

B lint R czey: Introducing XBMC from Debian

available from unstable, and hopefully soon from testing, too! The longer story: The xbmc package has been uninstallable and unbuildable in Debian unstable for quite some time. Mainly due to differing preferences of the XBMC project and Debian. Original XBMC source includes several embedded libraries, some patched to work with XBMC perfectly and to provide the best user experience the XBMC project prefers building XBMC with those libraries. In Debian, on the other hand, the recommended practice is not embedding libraries, but using the packaged versions instead to reduce the amount of security updates in case a library needs a security related fix, to save space on mirrors and to avoid divergence between the embedded versions of the libraries. One consequence of using externally packaged libraries is the need for making XMBC work with newer versions of the external libraries even when the embedded one would still work perfectly or (in some cases) there are even breakages due to changing APIs or new bugs in the library. XBMC depends on many libraries and the changes to them in Debian used to break one or another XBMC use case from time to time. The XBMC project received many direct bug reports from users of the Debian-shipped XBMC package which were harder than necessary to handle due to the lack of clear differentiation from the .deb packages provided directly by
them and using the embedded libraries. To help both users and developers the xbmc package starts using the XBMC from Debian name on the main screen and in the logs, the version number used inside the application is set to the Debian package s version, and README.Debian directs users of the package to Debian s BTS instead of XBMC s forums. The most notable difference between XBMC and XBMC from Debian is that XBMC uses
its embedded patched FFmpeg, while XBMC from Debian uses libav. If movies play too slow, too fast, without sound or too loud, you should definitely check BTS first. ;-) Happy Holidays and don t stay too much in front of the screen if XBMC from Debian happens to work for hours without any crash! :-)

Russell Coker: The Nexus 5

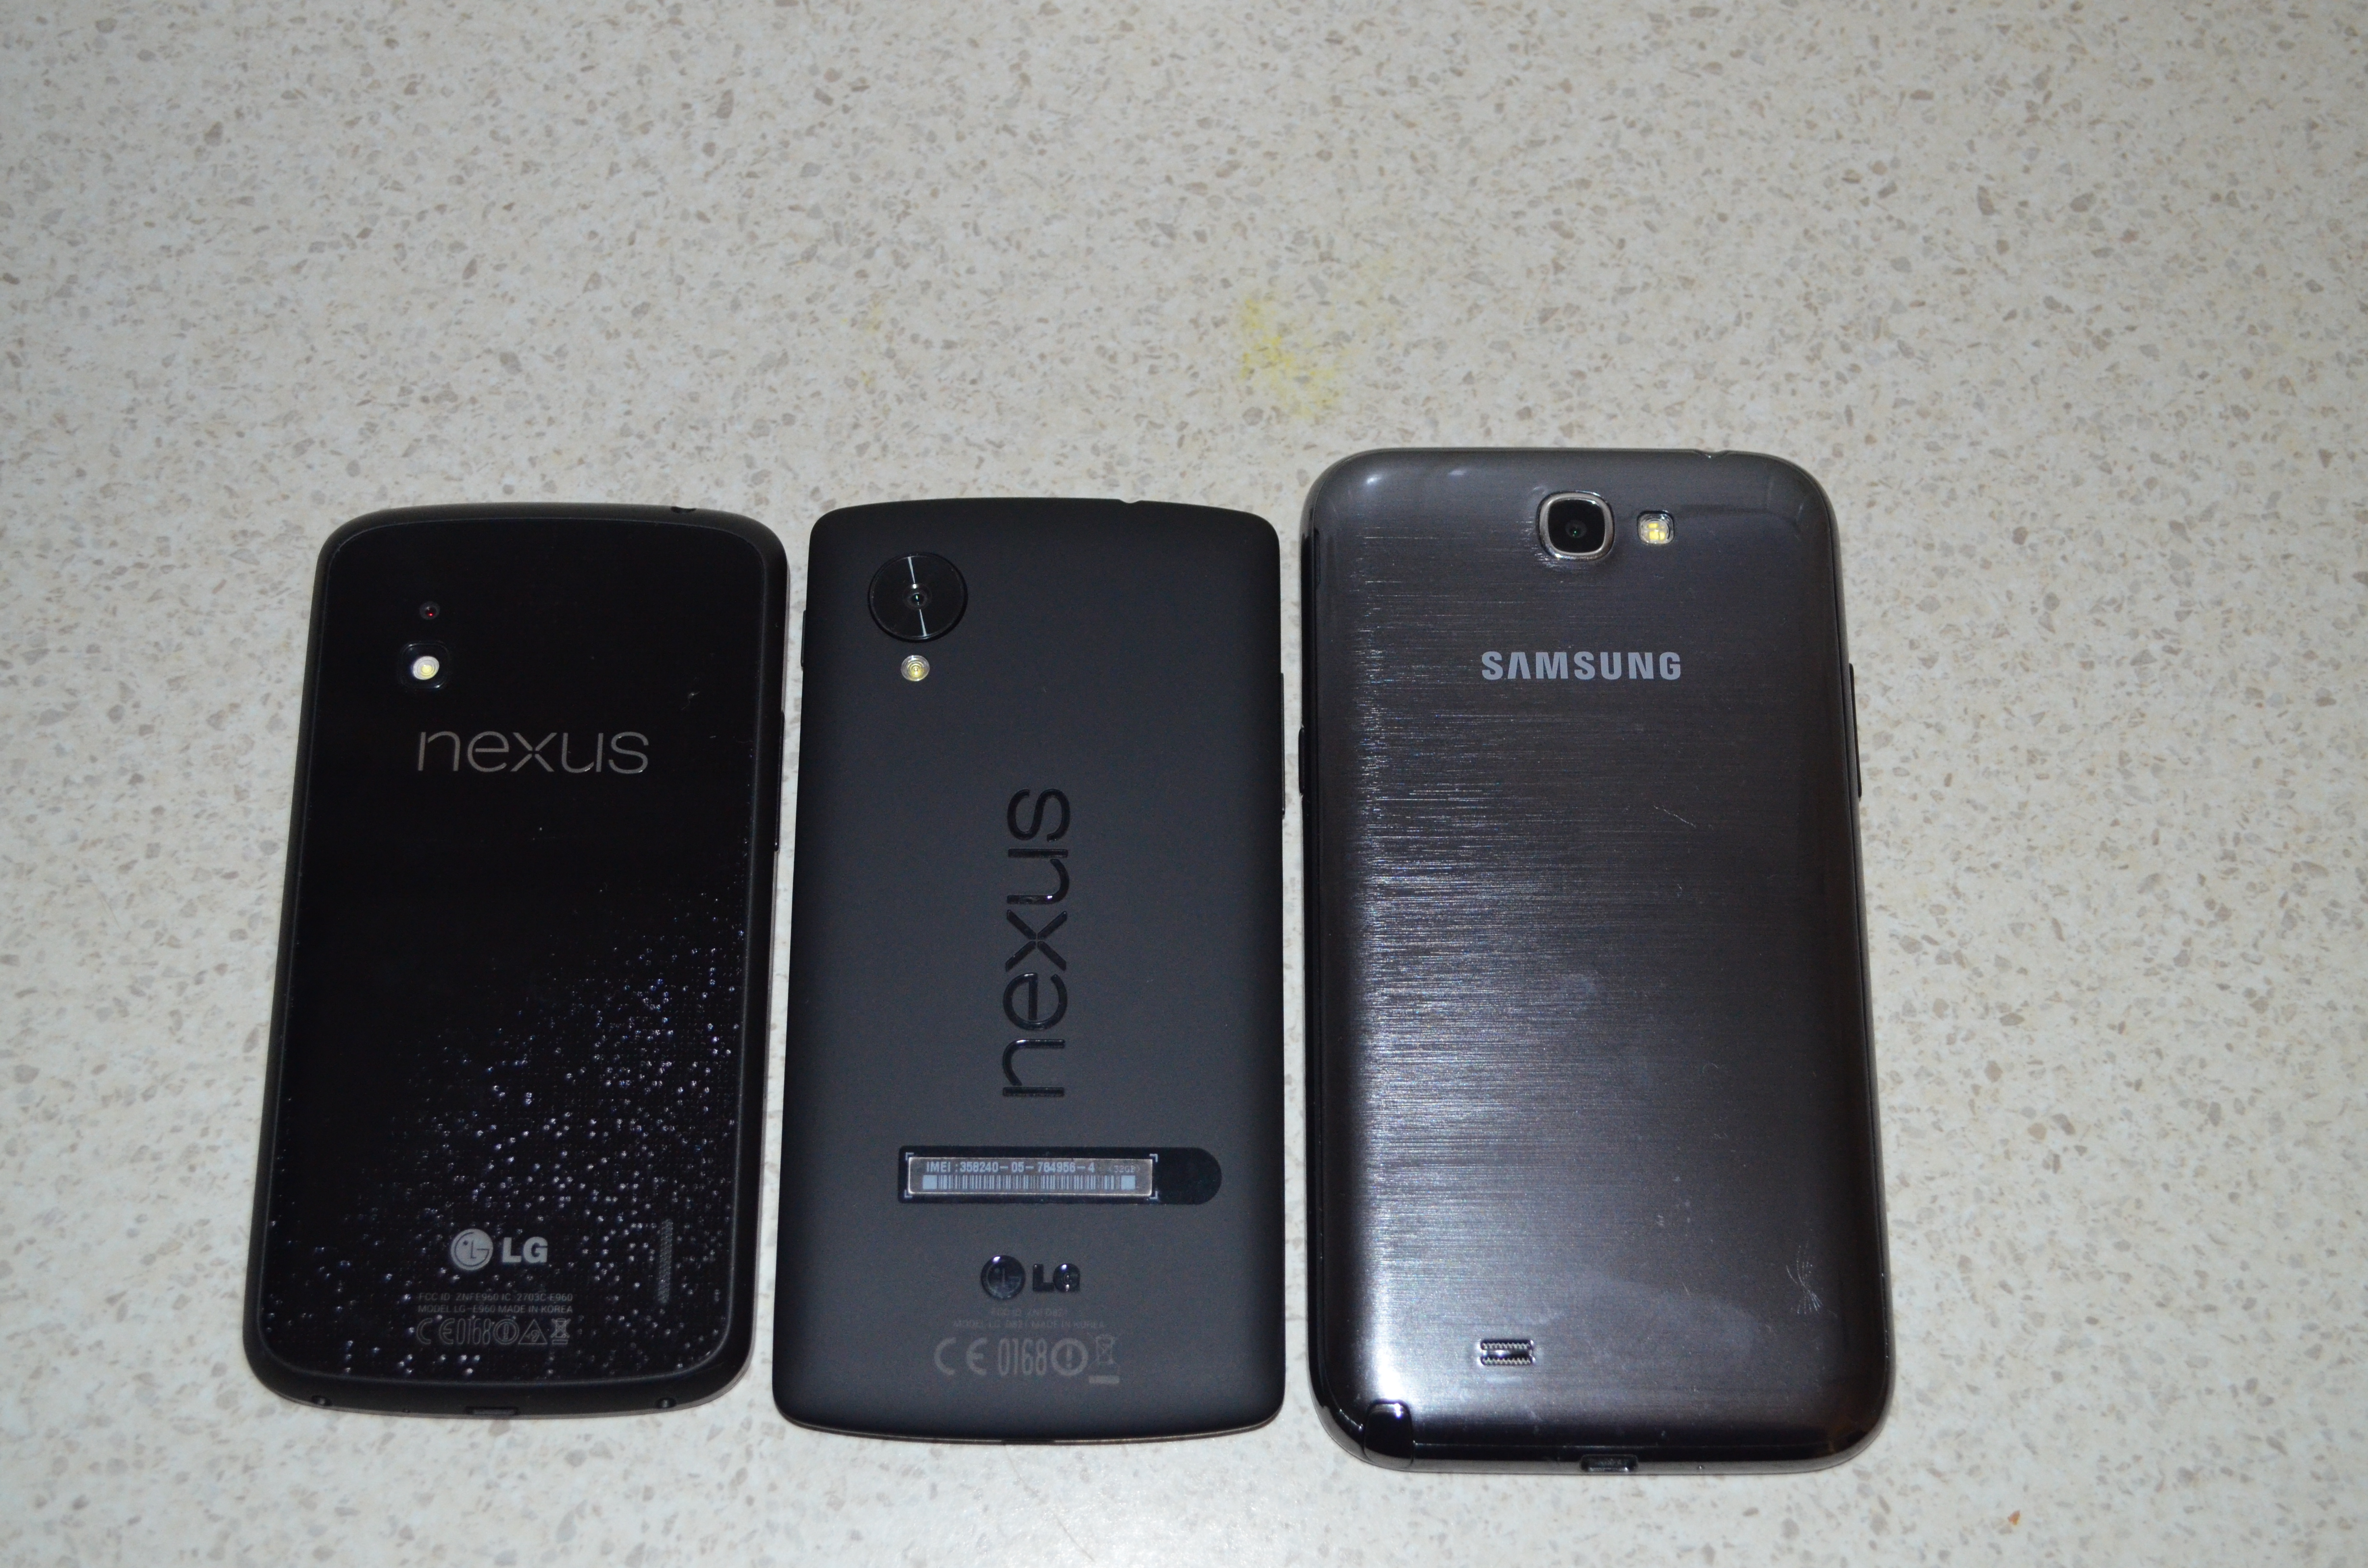
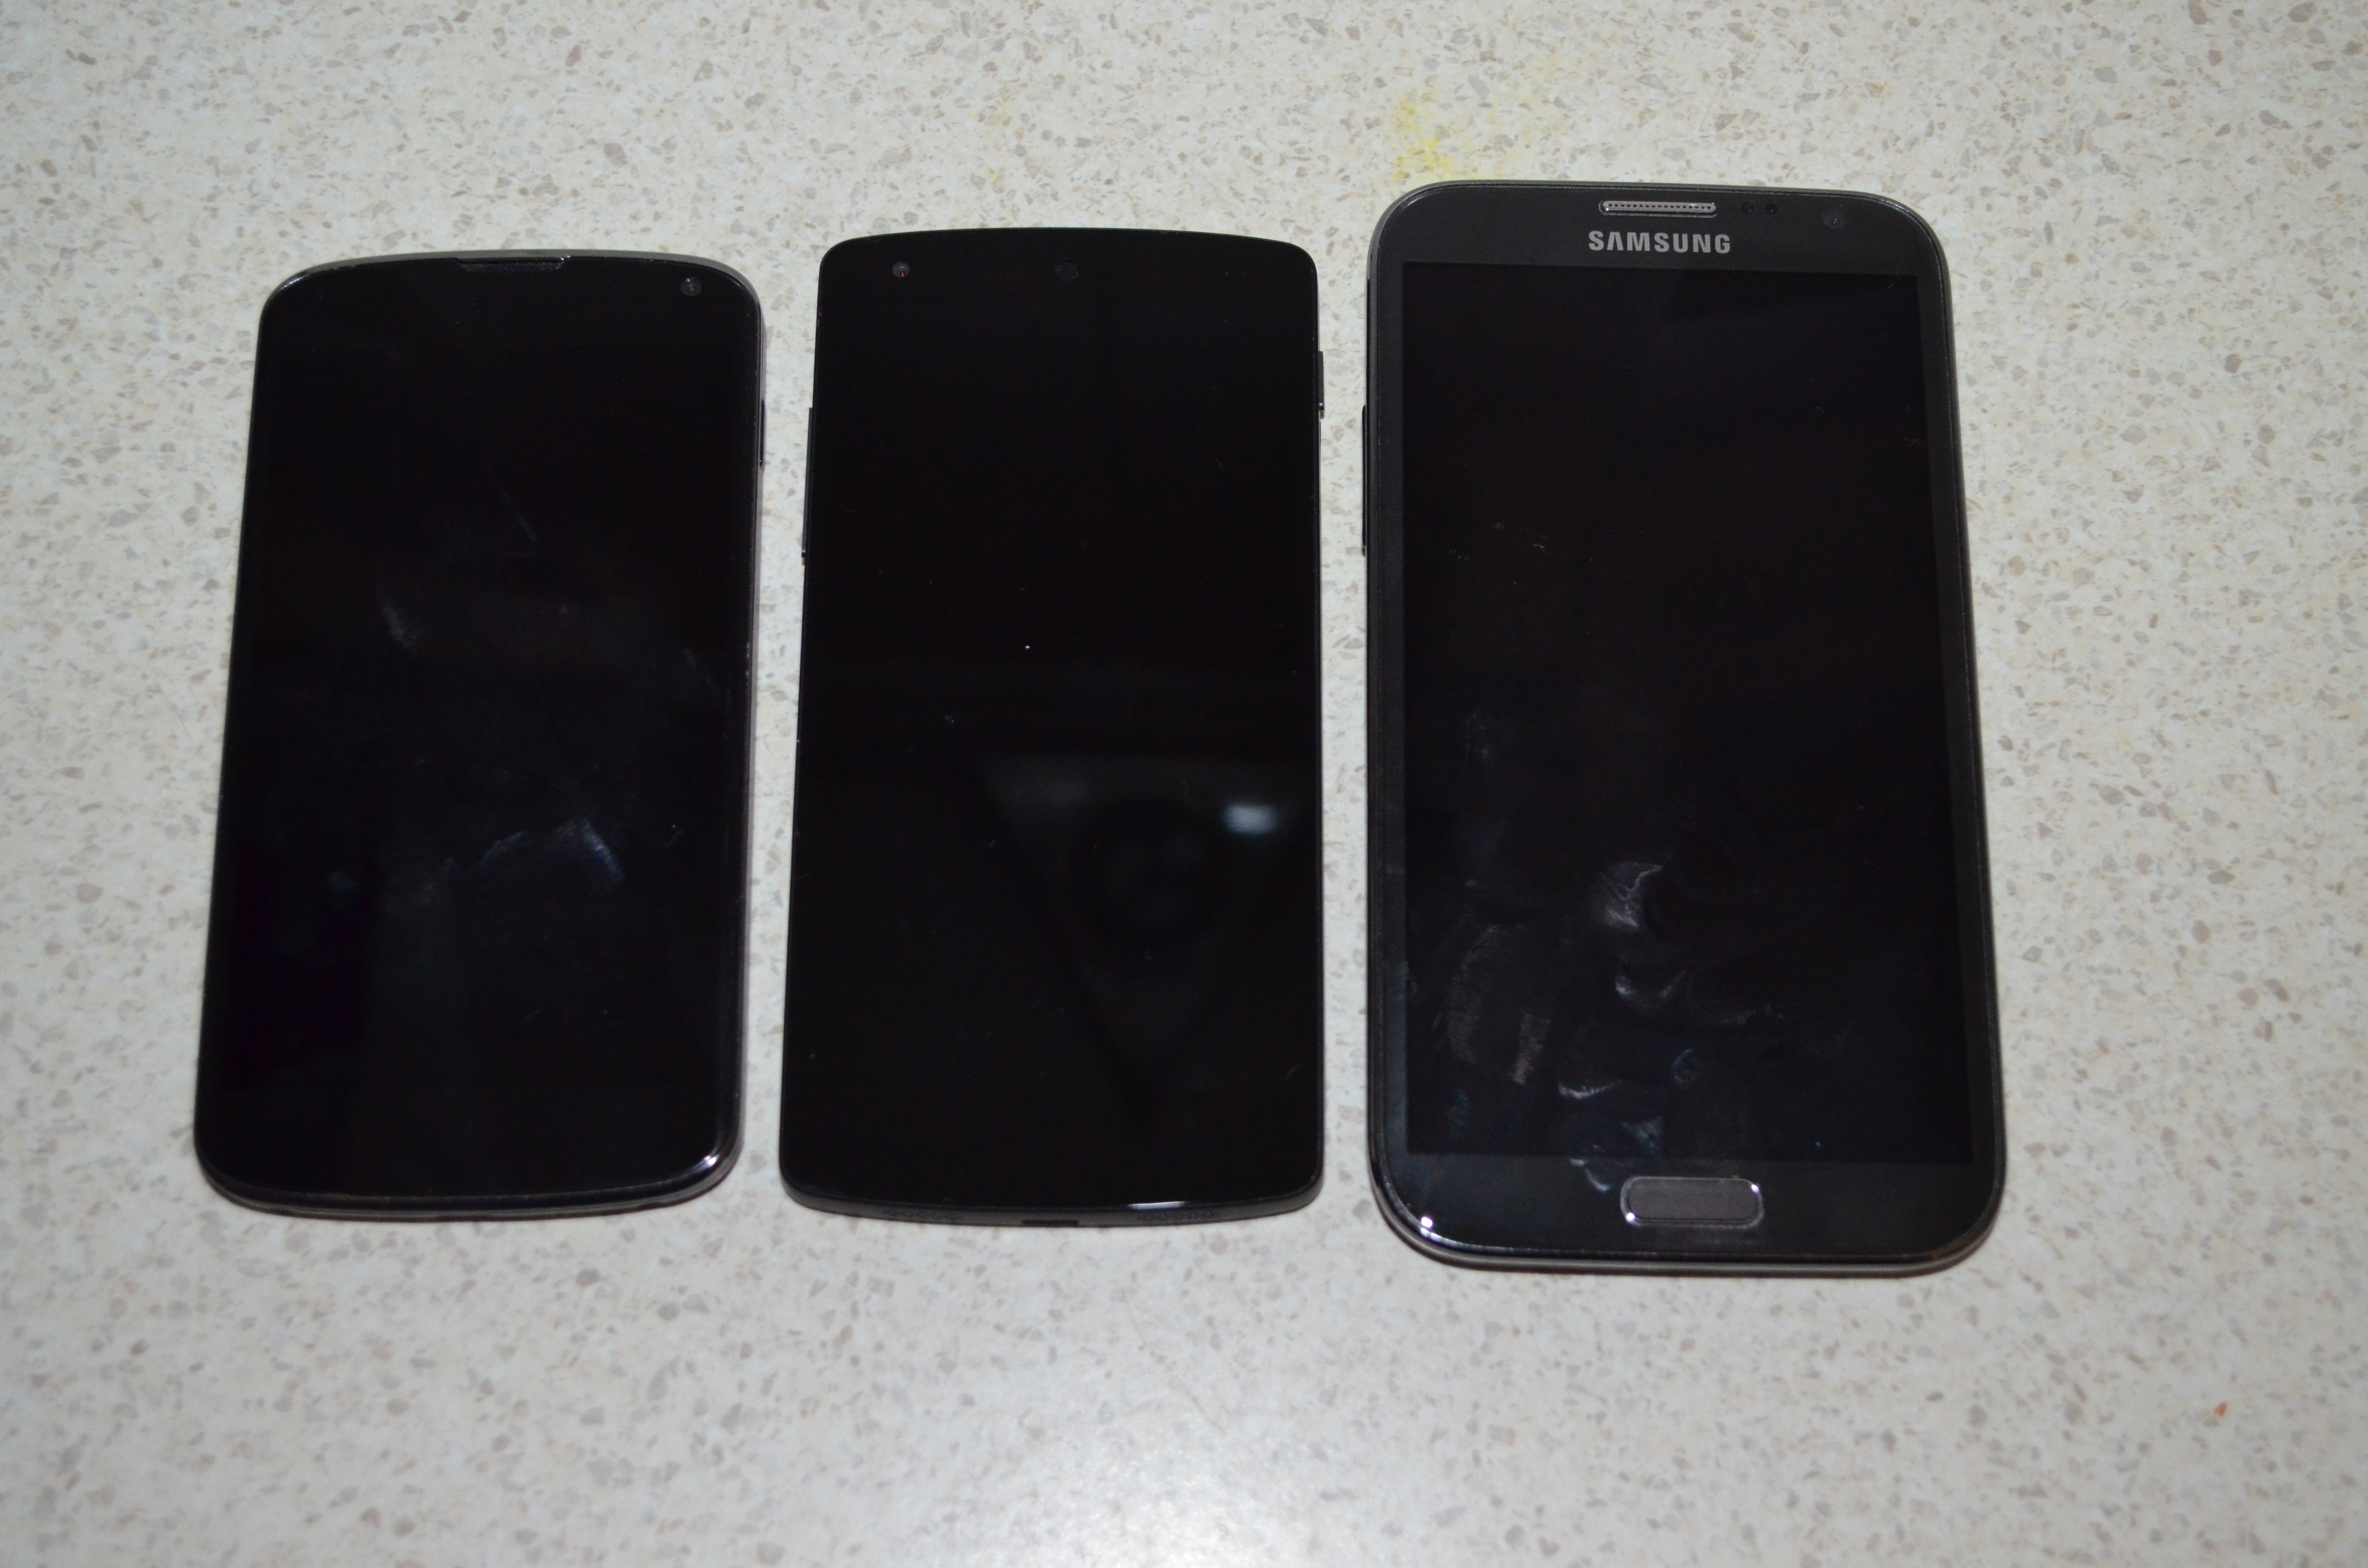
The Nexus 5 is the latest Android phone to be endorsed by Google (and manufactured by LG). It s getting good reviews and the price is good for the specs. I just bought one for my wife, I got her the 32G version because when I bought her a Nexus 4 at the start of the year [1] I chose the 8G version and regretted it ever since. The size of apps is always increasing (some Android games need more than 1G of storage) and higher resolution screens drives the use of high resolution video. Appearance back of Nexus 4, Nexus 5, and Samsung Galaxy Note 2front of Nexus 4, Nexus 5, and Samsung Galaxy Note 2 Above I have pictures of the Nexus 4, the Nexus 5, and the Samsung Galaxy Note 2. The photo of the phone backs captures part of the sparkling pattern on the back of the Nexus 4 and it looks much better in real life (IMHO) because it shimmers as you move the phone. The Nexus 4 looks so good that there s even a transparent case specifically designed to show off the rear panel [2]. It doesn t seem likely that anyone will design such a transparent case for the Nexus 5, it s a good phone to cover up IMHO. The Note 2 isn t the most attractive phone, but I think it has a streamlined elegance of being optimised for it s function. The Nexus 5 has it s camera sticking out, it would be better if they had just made the entire phone thicker and given it a bigger battery but for people who don t want good battery life I guess it s a way of providing a better focal length without making the phone thicker. Sticking the IMEI number on the back of the phone will be useful on rare occasions (and might be a security issue on more occasions) but it definitely makes the phone less attractive. Full HD The quality of the Full HD (1920*1080) display is obvious. The text is slightly clearer when viewing maps and the graphics in Ingress look nicer. Before I used the Nexus 5 I didn t think that there would be any benefit in having such a high resolution in a phone but now I realise that I was wrong. The higher resolution is clearly better. Chris Chavez wrote an article for Phandroid about a rumored Samsung phone with a 2560*1440 display [3]. If such a device had a 6.6 display (IE a new version of the Galaxy Mega) then it would have the same dot-pitch as the Nexus 5. If such a device had a 5.5 display (like the Galaxy Note 3) then it would have a 15% greater DPI than the Nexus 5. It seems that a higher DPI provides a real benefit and this is probably the biggest reason to choose the Nexus 5 over the Nexus 4 and most other Android devices. Comparing with the Nexus 4 The Nexus 5 has the same amount of RAM (2G), a slightly larger display (4.95 vs 4.7 ), higher resolution (a big deal), faster CPU and GPU, and optical zoom. Faster CPU isn t usually going to be a big deal (apart from the fact that more CPU power is needed as well as more GPU power to drive the higher resolution display). The Nexus 5 can come with 16G or 32G of storage while the Nexus 4 has options of 8G and 16G. If you want more than 16G of storage then that s a real benefit for the Nexus 5, but if you only need 16G then it s not an issue. It seems that when playing Ingress on a Nexus 5 it s more likely that running another program (such as Google Hangouts) will cause Ingress to be reloaded than it does on a Nexus 4 or a Galaxy Note 2. While I haven t done a good comparison of the Nexus 4 and the Nexus 5 in this regard I ve compared the Galaxy Note 2 and the Nexus 5 well. My Galaxy Note 2 (which has many daemons running) is much less likely to cause a reload of Ingress (IE have run low on memory and terminated Ingress) than the Nexus 5 my wife is using (which has very little running). So it seems that the OS build on the Nexus 5 uses more memory than the Galaxy Note 2. The Nexus 5 has Gorilla Glass 3 vs Gorilla Glass 2 on the Nexus 4. As my older Android phones with Gorilla Glass 1 (Galaxy S and Sony Ericsson Xperia X10i) didn t get any scratches that matter I don t think this is a benefit for me. Maybe if I lived near a beach I d care more about this. I think that the most significant benefit of the Nexus 5 over the Nexus 4 is the higher resolution display. The optical zoom should provide a theoretical benefit when taking photos, whether that results in better pictures in practice would probably depend on how you hold your phone, the available light, and other factors. I think that if it was possible to buy a Nexus 4 at a sensible price (IE something less than the $250 that Google last charged) then for most people the Nexus 4 would be a better choice than the Nexus 5. But as ebay is full of Nexus 4 phones selling for a higher prices than the Nexus 5 it seems that buying a Nexus 5 is the only option. The range of phones that Kogan sells [4] doesn t have anything for the same price that compares on features. Heat The heat produced by the Nexus 5 is significant and noticable. After some light Ingress playing on a cold day my Galaxy Note 2 with a gel case (that keeps it warm) reported itself as having a battery temperature of 34C. My wife s Nexus 5 reported a temperature of 43C. While the thermometer in the phone might not be the most accurate I don t think there was an accuracy problem, holding my wife s phone was unpleasant and felt like it could burn my hand if I held it tight (40C is the minimum temperature for burns). It seems that a Nexus 5 isn t a good choice if you want to play Ingress in a warm part of the world (EG most of Australia in summer). Also heat dissipated is directly proportional to power use which is going to be a problem for a phone that doesn t permit replacing it s battery. Conclusion I m quite disappointed with the Nexus 5. I expected it to be at least as good as the Nexus 4 in every way and better in many ways. Instead it s not always as good as the Nexus 4 and the ways that it is better won t necessarily provide benefits for everyone. The heat and power use problems are really going to hurt the use of it. But I guess we can always hope that Google release a new Android build that reduces the power use, they might even have a new build that uses less RAM too. I would not consider getting a Nexus 5 for my own use. For my use the Note 2 is clearly more suitable, the larger screen more than compensates for the clarity that the Nexus 5 gets from it s high resolution display. Also I REALLY like having a hardware home button. I ll probably get a Note 3 when the price drops, I m not interested in paying $649 for a phone and I m also not interested in replacing a phone that s less than a year old. So maybe I ll get a Note 3 in the second half of next year.

22 December 2013

Russ Allbery: Review: They Had to Go Out

Review: They Had to Go Out, by Gary J. Hudson
Publisher: Xlibris
Copyright: 2008
ISBN: 1-4363-8132-0
Format: Trade paperback
Pages: 165
They Had to Go Out, as noted on the cover, is the story of the tragedy of the Triumph and the Mermaid, a marine incident that occurred off the Oregon coast of the United States near the mouth of the Columbia River on January 12, 1961. But it's also much more than that. It's a detailed and thoroughly-researched account of a Coast Guard rescue operation, starting with background on the two coastal lifeboat stations and the types of ships involved. It covers everything from crew backgrounds to equipment issues to the general shape of the subsequent inquiry, and in the process provides a wealth of detailed information about the nature of Coast Guard rescue operations and the technology and equipment available at the time. But, beyond that, it's a gripping story, in part because of the authenticity of the authorial voice. Gary Hudson spent twenty years in the Coast Guard, ten on coastal lifeboat stations like the ones in this book, and was assigned to Point Adams (the primary station involved in this story) until 12 days before the incident, when he transferred to a light station for unrelated reasons. The writing is rough, the paragraphs are not always well-organized, the punctuation doesn't always end up in the right place, and it could have used an editor (Xlibris is a printing service company for self-publishing). But he understands the subject matter completely, and he clearly spent years of effort putting together all the details of the story. The first few chapters, where he establishes the necessary background and tells a few related stories, feel quite rough, but once he gets into the heart of the story, the rough prose stops mattering. Obviously, one of the things that makes this story so appealing is that it's a gripping human story, with the unconstructed and unexpected twists and turns of reality rather than a plot. Hudson has lived the life of the people he's writing about and can put many of their fears and thoughts into words. He captures some of what it would feel like to be out on the water in the middle of the worst seas that most of them had ever seen. And reality is unpredictable. I'm avoiding giving the exact details of what happened and I would recommend not researching the incident on Google if you plan to read this book; there's a lot of drama here, and spoilers are possible. Hudson's factual, detailed narrative style gives the reader a lot of material with which to build mental pictures, and he preserves the drama and the human impact of the story by telling it in straight chronological order. The writing is rough, but he shows a talent for pacing and perspective in the way he weaves together the viewpoints of multiple Coast Guard stations and ship crews. This is also a case study and an accident report, put together with extensive research and scope, but made approachable for the average reader. Hudson takes out the dryness and technical language and weaves the events into a narrative, but he doesn't lose much of the detail. You can know nothing at all about ships or Coast Guard operations and come away from this book with strong opinions about self-righting capabilities (and, more to the point, accurate communication to crews of the capabilities of their vessels). And, by showing a full day of Coast Guard operations (admittedly, a very unusual and difficult day), Hudson also provides the previously unfamiliar reader with a great "day in the life" picture of what Coast Guard lifesaving operations at their most dangerous look like (or at least looked like; one also gets a sense of just how much has improved, and how important the improvements are, in the final chapters). Finally, unlike most accident reports, Hudson carries the story through to the immediate family impact (which may well bring you to tears) and then, given forty years of hindsight, some of the subsequent effects on the people involved. I really liked this. One of the aspects of stories like this that often gets short shrift is that the people involved carry the incident with them for the rest of their lives, often with profound impact. Unlike a movie, where the movie ends and the characters disappear as soon as the primary action is complete, real life has messy and lingering endings, and I think Hudson manages to capture some of that feeling. Some of the best non-fiction books are not written by professional writers. Instead, they're written by people who have both expertise and passion for a particular topic and who know or teach themselves enough about telling a story to manage to get that expertise and passion out on paper. Hudson puts every aspect of this day into the book, from the people to the family impact, from the questionable decisions to the equipment failures and shortages, from the initial conditions through the inquiry and up to the subsequent impact on the lives of the people involved (including, sadly, the Coast Guard's lack of understanding of how to help people with traumatic stress). Some of the paragraphs clunk, some of the sentence construction is awkward, and some of the short biographies are a bit lost in details, but Hudson's desire to tell the complete truth as he was able to reconstruct it, and his deep empathy and understanding of how it felt to the people involved, shine through and carry this book. This is great stuff, and worth seeking out. Recommended. Rating: 9 out of 10

21 December 2013

Russell Coker: Links December 2013

Andres Lozano gave an interesting TED talk about the use of electrodes inside the brain (deep brain stimulation) to treat Alzheimers disease, Parkinson s disease, and depression [1]. Daniel Pocock wrote an interesting post commenting on some bad political decisions being made in Australia titled Evacuating Australia [2]. You can read that as a suggestion to leave Australia or to try and make Australia better. Marco Tempest gave an interesting TED talk about Nikola Tesla [3]. The presentation method is one that I ve never seen before so I recommend watching the talk even if you already know all about Tesla. Charmian Gooch gave an interesting TED talk about global corruption [4]. I think we need people to send the information on shell company ownership to organisations like Wikileaks. The punishment for leaking such information would be a lot less than Chelsea Manning is getting and the chance of getting caught is also low. Rich Mogul wrote an interesting and insightful article for Macworld about the Apple approach to security problems [5]. To avoid the problem of users disabling security features they work to make the secure way of doing things EASIER for the user. That won t work with all security problems but it s something we need to think about when working on computer security. Ray Raphael gave an interesting TED talk about the parts of the US revolution that don t appear in history books [6]. He warns the listener to beware of the narrative forms, but another way to interpret his talk is that you should present your version of history in the narrative form that is best accepted. That lesson is well known and it s easy to see history being deliberately distorted in most media outlets. Will Wright gave an interesting TED talk about how he designed the game Spore and his ideas about games in general [7]. Spore is a really good game. Chris Lintott gave an interesting TED talk about crowd-sourced astronomy titled How to Discover a Planet from Your Sofa [8]. He referenced the Zooniverse.org site which lists many crowd-sourced science projects [9]. Jake Socha gave an interesting TED talk about flying snakes, you have to see this to believe it [10]. Nikita Bier gave an interesting TED talk about his webapp to analyse economic policies [11]. Apparently 60% of people were going to vote in their best economic interest before seeing his site and 66% would do so afterwards that could change an election result. Anya Kamenetz wrote an interesting article for Salon about The Iliad Project which aims to use Indigogo to help identify new anti-biotics [12]. The current ways of discovering anti-biotics aren t working, lets hope this one does. Peter Finocchiaro wrote an interesting Salon article about how right-wing politicians in the US were opposed to Nelson Mandela [13] racism meets anti-communism. Katie McDonough wrote an interesting Salon article about Rick Santorum and Bill O Reilly comparing Obamacare to apartheid while supposedly honoring Nelson Mandela [14], Katie also notes that Nelson enshrined universal healthcare in the South African constitution something all countries should do. Mary Elizabeth Williams wrote a Salon article about Susan Boyle s announcement about being diagnosed with Asperger Syndrome [15]. Not a surprise though, some people can be diagnosed with Autism by merely watching them on TV. Amelia Hill wrote an article for The Guardian/The Observer about the educational results of Home Schooling [16]. Apparently Home-Schooled kids learn significantly more and home-educated children of working-class parents achieved considerably higher marks in tests than the children of professional, middle-class parents and that gender differences in exam results disappear among home-taught children . Wow, Home Schooling beats gender and class problems! I m sure it s even better for GLBT kids too. Robert Reich wrote an interesting Salon article about the way rich people in the US give tax-deductable (taxpayer supported) donations to charities that benefit themselves [17]. Dan Savage wrote a very funny review of Sarah Palin s latest Christmas book, one classic quote is why should I have to read the whole thing? Lord knows Sarah Palin didn t write the whole thing [18]. He makes a good point that we should use the term happy holidays instead of happy Christmas just to show that we aren t assholes.

Daniel Kahn Gillmor: Kevin M. Igoe should step down from CFRG Co-chair

I've said recently that pervasive surveillance is wrong. I don't think anyone from the NSA should have a leadership position in the development or deployment of Internet communications, because their interests are at odds with the interest of the rest of the Internet. But someone at the NSA is in exactly such a position. They ought to step down. Here's the background: The Internet Research Task Force (IRTF) is a body tasked with research into underlying concepts, themes, and technologies related to the Internet as a whole. They act as a research organization that cooperates and complements the engineering and standards-setting activities of the Internet Engineering Task Force (IETF). The IRTF is divided into issue-specific research groups, each of which has a Chair or Co-Chairs who have "wide discretion in the conduct of Research Group business", and are tasked with organizing the research and discussion, ensuring that the group makes progress on the relevant issues, and communicating the general sense of the results back to the rest of the IRTF and the IETF. One of the IRTF's research groups specializes in cryptography: the Crypto Forum Research Group (CFRG). There are two current chairs of the CFRG: David McGrew <mcgrew@cisco.com> and Kevin M. Igoe <kmigoe@nsa.gov>. As you can see from his e-mail address, Kevin M. Igoe is affiliated with the National Security Agency (NSA). The NSA itself actively tries to weaken cryptography on the Internet so that they can improve their surveillance, and one of the ways they try to do so is to "influence policies, standards, and specifications". On the CFRG list yesterday, Trevor Perrin requested the removal of Kevin M. Igoe from his position as Co-chair of the CFRG. Trevor's specific arguments rest heavily on the technical merits of a proposed cryptographic mechanism called Dragonfly key exchange, but I think the focus on Dragonfly itself is the least of the concerns for the IRTF. I've seconded Trevor's proposal, and asked Kevin directly to step down and to provide us with information about any attempts by the NSA to interfere with or subvert recommendations coming from these standards bodies. Below is my letter in full:
From: Daniel Kahn Gillmor <dkg@fifthhorseman.net>
To: cfrg@ietf.org, Kevin M. Igoe <kmigoe@nsa.gov>
Date: Sat, 21 Dec 2013 16:29:13 -0500
Subject: Re: [Cfrg] Requesting removal of CFRG co-chair
On 12/20/2013 11:01 AM, Trevor Perrin wrote:
> I'd like to request the removal of Kevin Igoe from CFRG co-chair.
Regardless of the conclusions that anyone comes to about Dragonfly
itself, I agree with Trevor that Kevin M. Igoe, as an employee of the
NSA, should not remain in the role of CFRG co-chair.
While the NSA clearly has a wealth of cryptographic knowledge and
experience that would be useful for the CFRG, the NSA is apparently
engaged in a series of attempts to weaken cryptographic standards and
tools in ways that would facilitate pervasive surveillance of
communication on the Internet.
The IETF's public position in favor of privacy and security rightly
identifies pervasive surveillance on the Internet as a serious problem:
https://www.ietf.org/media/2013-11-07-internet-privacy-and-security.html
The documents Trevor points to (and others from similar stories)
indicate that the NSA is an organization at odds with the goals of the IETF.
While I want the IETF to continue welcoming technical insight and
discussion from everyone, I do not think it is appropriate for anyone
from the NSA to be in a position of coordination or leadership.
----
Kevin, the responsible action for anyone in your position is to
acknowledge the conflict of interest, and step down promptly from the
position of Co-Chair of the CFRG.
If you happen to also subscribe to the broad consensus described in the
IETF's recent announcement -- that is, if you care about privacy and
security on the Internet -- then you should also reveal any NSA activity
you know about that attempts to subvert or weaken the cryptographic
underpinnings of IETF protocols.
Regards,
	--dkg
I'm aware that an abdication by Kevin (or his removal by the IETF chair) would probably not end the NSA's attempts to subvert standards bodies or weaken encryption. They could continue to do so by subterfuge, for example, or by private influence on other public members. We may not be able to stop them from doing this in secret, and the knowledge that they may do so seems likely to cast a pall of suspicion over any IETF and IRTF proceedings in the future. This social damage is serious and troubling, and it marks yet another cost to the NSA's reckless institutional disregard for civil liberties and free communication. But even if we cannot rule out private NSA influence over standards bodies and discussion, we can certainly explicitly reject any public influence over these critical communications standards by members of an institution so at odds with the core principles of a free society. Kevin M. Igoe, please step down from the CFRG Co-chair position. And to anyone (including Kevin) who knows about specific attempts by the NSA to undermine the communications standards we all rely on: please blow the whistle on this kind of activity. Alert a friend, a colleague, or a journalist. Pervasive surveillance is an attack on all of us, and those who resist it are heroes.

Kees Cook: DOM scraping

For a long time now I ve used mechanize (via either Perl or Python) for doing website interaction automation. Stuff like playing web games, checking the weather, or reviewing my balance at the bank. However, as the use of javascript continues to increase, it s getting harder and harder to screen-scrape without actually processing DOM events. To do that, really only browsers are doing the right thing, so getting attached to an actual browser DOM is generally the only way to do any kind of web interaction automation. It seems the thing furthest along this path is Selenium. Initially, I spent some time trying to make it work with Firefox, but gave up. Instead, this seems to work nicely with Chrome via the Chrome WebDriver. And even better, all of this works out of the box on Ubuntu 13.10 via python-selenium and chromium-chromedriver. Running /usr/lib/chromium-browser/chromedriver2_server from chromium-chromedriver starts a network listener on port 9515. This is the WebDriver API that Selenium can talk to. When requests are made, chromedriver2_server spawns Chrome, and all the interactions happen against that browser. Since I prefer Python, I avoided the Java interfaces and focused on the Python bindings:
#!/usr/bin/env python
import sys
from selenium import webdriver
from selenium.common.exceptions import NoSuchElementException
from selenium.webdriver.common.keys import Keys
caps = webdriver.DesiredCapabilities.CHROME
browser = webdriver.Remote("http://localhost:9515", caps)
browser.get("https://bank.example.com/")
assert "My Bank" in browser.title
try:
    elem = browser.find_element_by_name("userid")
    elem.send_keys("username")
    elem = browser.find_element_by_name("password")
    elem.send_keys("wheee my password" + Keys.RETURN)
except NoSuchElementException:
    print "Could not find login elements"
    sys.exit(1)
assert "Account Balances" in browser.title
xpath = "//div[text()='Balance']/../../td[2]/div[contains(text(),'$')]"
balance = browser.find_element_by_xpath(xpath).text
print balance
browser.close()
This would work pretty great, but if you need to save any state between sessions, you ll want to be able to change where Chrome stores data (since by default in this configuration, it uses an empty temporary directory via --user-data-dir=). Happily, various things about the browser environment can be controlled, including the command line arguments. This is configurable by expanding the desired capabilities variable:
caps = webdriver.DesiredCapabilities.CHROME
caps["chromeOptions"] =  
        "args": ["--user-data-dir=/home/user/somewhere/to/store/your/session"],
     
A great thing about this is that you get to actually watch the browser do its work. However, in cases where this interaction is going to be fully automated, you likely won t have a Xorg session running, so you ll need to wrap the WebDriver in one (since it launches Chrome). I used Xvfb for this:
#!/bin/bash
# Start WebDriver under fake X and wait for it to be listening
xvfb-run /usr/lib/chromium-browser/chromedriver2_server &
pid=$!
while ! nc -q0 -w0 localhost 9515; do
    sleep 1
done
the-chrome-script
rc=$?
# Shut down WebDriver
kill $pid
exit $rc
Alternatively, all of this could be done in the python script too, but I figured it s easier to keep the support infrastructure separate from the actual test script itself. I actually leave the xvfb-run call external too, so it s easier to debug the browser in my own X session. One bug I encountered was that the WebDriver s cache of the browser s DOM can sometimes get out of sync with the actual browser s DOM. I didn t find a solution to this, but managed to work around it. I m hoping later versions fix this. :)

2013, Kees Cook. This work is licensed under a Creative Commons Attribution-ShareAlike 3.0 License.
Creative Commons License

20 December 2013

Lars Wirzenius: Configuring gitano

I recently set up a Gitano instance as http://git.liw.fi/. Gitano is a very nice git server, which adds user and group management and access control in front of git itself, and keeps all configuration in git, where it's traceable and auditable nicely. It's also a command line based thing, rather than a slow, resource-hungry web application, and so much more to my liking. Daniel, the Gitano upstream, has a "gitano-all" source tree for creating an unofficial Gitano Debian package, which includes cgit, a fast git web interface. This is not ever going to be accepted in Debian, of course, but it makes it easier to install Gitano on your server. This hanky-panky is needed because Gitano and cgit both use libgit2, and that's a library without a stable API at this time. This makes is difficult to package for Debian. cgit seems to embed other such projects as well. Anyway, once you've installed the Gitano software (and cgit, if you want that), there's the matter of setting up a Gitano instance. Each Gitano instance is its own Unix user, accessed over ssh. Thus, one machine can host any number of Gitano instances, and they'll be nicely isolated from each other by normal Unix setup. Each instance manages its own set of Gitano users and group, which only exist within that instance. Users are identified by ssh public keys: there are no passwords. Here's my slightly edited checklist for setting up a Gitano instance. It assumes Gitano and cgit and their dependencies are installed. Setup Gitano itself: Setup a git daemon for public git repositories:
git stream tcp nowait nobody /usr/bin/git 
git daemon --inetd 
--interpolated-path=/home/git/repos/%D /home/git/repos
Setup cgit and Apache:
# CGIT stuff
DirectoryIndex /cgi-bin/cgit/cgit.cgi
Alias /cgit.png /usr/share/cgit/htdocs/cgit.png
Alias /cgit.css /usr/share/cgit/htdocs/cgit.css
<Directory "/home/git/repos">
    Options FollowSymlinks Indexes
    Allow from all
    AllowOverride none
    Order allow,deny
</Directory>
# Enable caching of up to 1000 output entriess
cache-size=1000
# Specify some default clone prefixes
clone-prefix=git://testgit
# Specify the css url
css=/cgit.css
# Specify the logo url
logo=/cgit.png
# Show extra links for each repository on the index page
enable-index-links=1
# Show number of affected files per commit on the log pages
enable-log-filecount=1
# Show number of added/removed lines per commit on the log pages
enable-log-linecount=1
# Set the title and heading of the repository index page
root-title=testgit
root-desc=Lars's test git repositories
# Allow download of tar.gz, tar.bz2 and zip-files
snapshots=tar.gz
#source-filter=/usr/lib/cgit/filters/syntax-highlighting.sh
remove-suffix=1
enable-git-config=1
strict-export=git-daemon-export-ok
scan-path=/home/git/repos
##
## List of common mimetypes
##
mimetype.git=image/git
mimetype.html=text/html
mimetype.jpg=image/jpeg
mimetype.pdf=application/pdf
mimetype.png=image/png
mimetype.svg=image/svg+xml
Finally, you should review, and possibly alter, Gitano access control rules. Some Gitano commands: Happy hacking. PS. I wrote a yarn test suite for my Gitano ACL, which may be interesting if you're new to Gitano.

Christoph Egger

Greetings from the FAU Security Team (FAUST), the Uni Erlangen CTF group. We were participating in the RuCTFe competition and made it to 4th place. Following is my write-up on the nsaless service, the main crypto challenge in the competition. nsaless is a nodejs webservice providing a short message service. People can post messages and their followers receive the message encrypted to their individual RSA key.

About the gameserver protocol
The gameserver created groups of 8 users on the service 7 were just following the first user (and authorized by the first user to do so) while the first user sent a tweet containing the flag. The service used 512bit RSA with 7 as public exponent. While RSA512 is certainly weak, it's strong enough to make it unfeasible to break directly.

Attacking RSA
There are some known attacks against RSA with small exponents if no proper padding is done. The most straightforward version just takes the e-th root of the cipher-text and, if the clear message was small enough, outputs that root as plain-text. As the flag was long enough to make this attack impossible, we need a somewhat improved Attack.

H stad's Broadcast Attack
Reminder:
  • In RSA, given a plain-text A, the sender computes A mod N to build the cipher-text B.
  • Given simultaneous congruences we can efficiently compute a x such that x satisfies all congruences using the Chinese remainder theorem.
For NSAless we actually get several such B for different N (each belonging to different users receiving the tweet because they follow the poster). This effectively means we get A in mod N for different N. Using the Chinese remainder theorem we can now compute a x A mod N . If we use at least e different B for this we are guaranteed that x actually equals A (in ): A needs to be smaller than N for all N used (otherwise we lose information during encryption), therefore A needs to be smaller than N . Computing now the e-th root of x we get the plain-text A the flag.

Fix
Fixing your service is easy enough, just increase e to an suitable number > 8. At the end of the contest 5 Teams had fixed this vulnerability by either using 17 or 65537.

EXPLOIT
The basic exploit is shown below. Unfortunately it needs to retrieve all tweets for all users the compute the flags which just takes too long to be feasible (at least at the end of the competition where tons of users already existed) so you would need some caching to make it actually work. Would have been a great idea to have users expire after an hour or two in the service!
#!/usr/bin/python
import httplib
import urllib
import re
import json
import pprint
import gmpy
import sys
userparse_re = re.compile('<a [^>]*>([^<]*)</a></div>\s*<div>([^<]*)</div>')
tweetparse_re = re.compile("<div id='last_tweet'>([0-9]+)</div>")
followingparse_re = re.compile('<div><a href="/[0-9]+">([0-9]+)</a></div>')
def my_parse_number(number):
    string = "%x" % number
    if len(string) != 64:
        return ""
    erg = []
    while string != '':
        erg = erg + [chr(int(string[:2], 16))]
        string = string[2:]
    return ''.join(erg)
def extended_gcd(a, b):
    x,y = 0, 1
    lastx, lasty = 1, 0
    while b:
        a, (q, b) = b, divmod(a,b)
        x, lastx = lastx-q*x, x
        y, lasty = lasty-q*y, y
    return (lastx, lasty, a)
def chinese_remainder_theorem(items):
  N = 1
  for a, n in items:
    N *= n
  result = 0
  for a, n in items:
    m = N/n
    r, s, d = extended_gcd(n, m)
    if d != 1:
      raise "Input not pairwise co-prime"
    result += a*s*m
  return result % N, N
def get_tweet(uid):
    try:
        conn = httplib.HTTPConnection("%s:48879" % sys.argv[1], timeout=60)
        conn.request("GET", "/%s" % uid)
        r1 = conn.getresponse()
        data = r1.read()
        tweet = re.findall(tweetparse_re, data)
        if len(tweet) != 1:
            return None
        followers = re.findall(followingparse_re, data)
        return tweet[0], followers
    except:
        return None
def get_users():
    conn = httplib.HTTPConnection("%s:48879" % sys.argv[1], timeout=60)
    conn.request("GET", "/users")
    r1 = conn.getresponse()
    data1 = r1.read(1024 * 1024)
    data = dict()
    for i in re.findall(userparse_re, data1)[:100]:
        userinfo = get_tweet(i[0])
        if userinfo != None:
            data[i[0]] = (json.loads(i[1].replace('&quot;', '"'))['n'], userinfo)
    return data
users = get_users()
allusers = users.keys()
masters = [ user for user in allusers if len(users[user][1][1]) > 0 ]
for test in masters:
    try:
        followers = users[test][1][1]
        data = []
        for fol in followers:
            n = int(users[fol][0])
            tweet = int(users[fol][1][0])
            data = data + [(tweet, n)]
        x, n = chinese_remainder_theorem(data)
        realnum = gmpy.mpz(x).root(7)[0].digits()
        print my_parse_number(int(realnum))
    except:
        pass

19 December 2013

Keith Packard: Altos1.3

AltOS 1.3 TeleMega and EasyMini support Bdale and I are pleased to announce the release of AltOS version 1.3. AltOS is the core of the software for all of the Altus Metrum products. It consists of firmware for our cc1111, STM32L151, LPC11U14 and ATtiny85 based electronics and Java-based ground station software. This is a major release of AltOS as it includes support for both of our brand new flight computers, TeleMega and EasyMini. AltOS Firmware New hardware, new features and fixes Our new advanced flight computer, TeleMega, required a lot of new firmware features, including: Our new easy-to-use flight computer, EasyMini also uses a new processor, the LPC11U14, which is an ARM Cortex-M0 part. For our existing cc1111 devices, there are some minor bug fixes for the flight software, so you should plan on re-flashing flight units at some point. However, there aren t any incompatible changes, so you don t have to do it all at once. Bug fixes: AltosUI Redesigned for TeleMega and EasyMini support AltosUI has also seen quite a bit of work for the 1.3 release, but almost all of that was a massive internal restructuring necessary to support flight computers with a wide range of sensors. From the user s perspective, it s pretty similar with a few changes:

18 December 2013

Daniel Pocock: Embedding Python in multi-threaded C++ applications

Embedding Python into other applications to provide a scripting mechanism is a popular practice. Ganglia can run user-supplied Python scripts for metric collection and the Blender project does it too, allowing users to develop custom tools and use script code to direct their animations. There are various reasons people choose Python:
  • Modern, object orientated style of programming
  • Interpreted language (no need to compile things, just edit and run the code)
  • Python has a vast array of modules providing many features such as database and network access, data processing, etc
The bottom line is that the application developer who chooses to embed Python in their existing application can benefit from the product of all this existing code multiplied by the imagination of their users. Enter repro repro is the SIP proxy of the reSIProcate project. reSIProcate is an advanced SIP implementation developed in C++. repro is a multi-threaded process. repro's most serious competitor is the Kamailio SIP proxy. Kamailio has its own bespoke scripting language that it has inherited from the SIP Express Router (SER) family of projects. repro has always been far more rigid in its capabilities than Kamailio. On the other hand, while Kamailio has given users great flexibility, it has also come at a cost: users can easily build configurations that are not valid or may not do what they really intend if they don't understand the intricacies of the SIP protocol. Here is an example of the Kamailio configuration script (from Daniel's excellent blog about building a Skype-like service in less than an hour) Kamailio also has a wide array of plugins for things like database and LDAP access. repro only had embedded bdb and MySQL support. Embedding Python into repro appears to be a quick way to fill many of these gaps and allow users to combine the power of the reSIProcate stack with their own custom routing logic. On the other hand, it is not simply copying the Kamailio scripting solution: rather, it provides a distinctive alternative. Starting the integration Embedding Python is such a popular practice that there is even dedicated documentation on the subject. As well as looking there, I also looked over the example provided by the embedded Python module for Ganglia. Looking over the Ganglia mod_python code I noticed a lot of boilerplate code for reference counting and other tedious activities. Given that reSIProcate is C++ code, I thought I would look for a C++ solution to this and I came across PyCXX. PyCXX is licensed under BSD-like terms similar to reSIProcate itself so it is a good fit. There is also the alternative Boost.Python API, however, reSIProcate has been built without Boost dependencies so I decided to stick with PyCXX. I looked over the PyCXX examples and the documentation and was able to complete a first cut of the embedded Python scripting feature very quickly. Using PyCXX One unusual thing I noticed about PyCXX is that the Debian package, python-cxx-dev does not provide any shared library. Instead, some uncompiled source files are provided and each project using PyCXX must compile them and link them statically itself. Here is how I do that in the Makefile.am for pyroute in repro:
AM_CXXFLAGS = -I $(top_srcdir)
reproplugin_LTLIBRARIES = libpyroute.la
libpyroute_la_SOURCES = PyRoutePlugin.cxx
libpyroute_la_SOURCES += PyRouteWorker.cxx
libpyroute_la_SOURCES += $(PYCXX_SRCDIR)/cxxextensions.c
libpyroute_la_SOURCES += $(PYCXX_SRCDIR)/cxx_extensions.cxx
libpyroute_la_SOURCES += $(PYCXX_SRCDIR)/cxxsupport.cxx
libpyroute_la_SOURCES += $(PYCXX_SRCDIR)/../IndirectPythonInterface.cxx
libpyroute_la_CPPFLAGS = $(DEPS_PYTHON_CFLAGS)
libpyroute_la_LDFLAGS = -module -avoid-version
libpyroute_la_LDFLAGS += $(DEPS_PYTHON_LIBS)
EXTRA_DIST = example.py
noinst_HEADERS = PyRouteWorker.hxx
noinst_HEADERS += PyThreadSupport.hxx
The value PYCXX_SRCDIR must be provided on the configure command line. On Debian, it is /usr/share/python2.7/CXX/Python2 Going multi-threaded My initial implementation simply invoked the Python method from the main routing thread of the repro SIP proxy. This meant that it would only be suitable for executing functions that complete quickly, ruling out the use of any Python scripts that talk to network servers or other slow activities. When the proxy becomes heavily loaded, it is important that it can complete many tasks asynchronously, such as forwarding chat messages between users in real-time. Therefore, it was essential to extend the solution to run the Python scripts in a pool of worker threads. At this point, I had an initial feeling that there may be danger in just calling the Python methods from some other random threads started by my own code. I went to see the manual and I came across this specific documentation about the subject. It looks quite easy, just wrap the call to the user-supplied Python code in something like this:
PyGILState_STATE gstate;
gstate = PyGILState_Ensure();
/* Perform Python actions here. */
result = CallSomeFunction();
/* evaluate result or handle exception */
/* Release the thread. No Python API allowed beyond this point. */
PyGILState_Release(gstate);
Unfortunately, I found that this would not work and that one of two problems occur when using this code:
  • The thread blocks on the call to PyGILState_Ensure()
  • The program crashes with a segmentation fault when the call to a Python method was invoked
Exactly which of these outcomes I experienced seemed to depend on whether I tried to explicitly call PyEval_ReleaseThread() from the main thread after doing the Py_Initialize() and other setup tasks. I tried various permutations of using PyGILState_Ensure()PyGILState_Release() and/or PyEval_SaveThread()/PyEval_ReleaseThread() but I always had one of the same problems. The next thing that occurred to me is that maybe PyCXX provides some framework for thread integration: I had a look through the code and couldn't find any reference to the threading functionality from the C API. I went looking for more articles and mailing list discussions and found implementation notes such as this one in Linux Journal and this wiki from the Blender developers. Most of them just appeared to be repeating what was in the manual, with a few subtle differences, but none of this provided an immediate solution. Eventually, I discovered this other blog about concurrency with embedded Python and it suggests something not highlighted in any of the other resources: calling PyThreadState_New(m_interpreterState) in each thread after it starts and before it does anything else. Combining this with the use of PyEval_SaveThread()/PyEval_ReleaseThread() fixed the problem: the use of PyThreadState_New() was not otherwise mentioned in the relevant section of the Python guide. I decided to take this solution a step further and create a convenient C++ class to encapsulate the logic, you can see this in PyThreadSupport.hxx:
class PyExternalUser
 
   public:
      PyExternalUser(PyInterpreterState* interpreterState)
       : mInterpreterState(interpreterState),
         mThreadState(PyThreadState_New(mInterpreterState))  ;
   class Use
    
      public:
         Use(PyExternalUser& user)
          : mUser(user)
           PyEval_RestoreThread(mUser.getThreadState());  ;
         ~Use()   mUser.setThreadState(PyEval_SaveThread());  ;
      private:
         PyExternalUser& mUser;
    ;
   friend class Use;
   protected:
      PyThreadState* getThreadState()   return mThreadState;  ;
      void setThreadState(PyThreadState* threadState)   mThreadState = threadState;  ;
   private:
      PyInterpreterState* mInterpreterState;
      PyThreadState* mThreadState;
 ;
and the way to use it is demonstrated in the PyRouteWorker class. Observe how PyExternalUser::Use is instantiated in the PyRouteWorker::process() method: when it goes out of scope (either due to a normal return, an error or an exception) the necessary call to PyEval_SaveThread() is made in the PyExternalUser::Use::~Use() destructor. Using other Python modules and DSO problems All of the above worked for basic Python such as this trivial example script:
def on_load():
    '''Do initialisation when module loads'''
    print 'example: on_load invoked'
def provide_route(method, request_uri, headers):
    '''Process a request URI and return the target URI(s)'''
    print 'example: method = ' + method
    print 'example: request_uri = ' + request_uri
    print 'example: From = ' + headers["From"]
    print 'example: To = ' + headers["To"]
    routes = list()
    routes.append('sip:bob@example.org')
    routes.append('sip:alice@example.org')
    return routes
However, it needs a more credible and useful test: using the python-ldap module to try and query an LDAP server appears like a good choice. Upon trying to use import ldap in the Python script, repro would refuse to load the Python script, choking on an error like this:
Traceback (most recent call last):
  File "/usr/lib/python2.7/dist-packages/ldap/__init__.py", line 22, in 
    import _ldap
ImportError: /usr/lib/python2.7/dist-packages/_ldap.so: undefined symbol: PyExc_SystemError
I looked at the file _ldap.so and discovered that it is linked with the LDAP libraries but not explicitly linked to any version of the Python runtime libraries. It expects the application hosting it to provide the Python symbols globally. In my own implementation, my embedded Python encapsulation code is provide as a DSO plugin, similar to the way plugins are loaded in Ganglia or Apache. The DSO links to Python: the DSO is loaded by a dlopen() call from the main process. The main repro binary has no direct link to Python libraries. Adding RTLD_GLOBAL to the top-level dlopen() call for loading the plugin is one way to ensure the Python symbols are made available to the Python modules loaded indirectly by the Python interpreter. This solution may be suitable for applications that don't mix and match many different components. Doing something useful with it Now it was all working nicely, I took a boilerplate LDAP Python example and used it for making a trivial script that converts sip:user@example.org to something like sip:9001@pbx.example.org, assuming that 9001 is the telephoneNumber associated with the user@ email address in LDAP. It is surprisingly simple and easily adaptable to local requirements depending upon the local LDAP structures:
import ldap
from urlparse import urlparse
def on_load():
    '''Do initialisation when module loads'''
    #print 'ldap router: on_load invoked'
def provide_route(method, request_uri, headers):
    '''Process a request URI and return the target URI(s)'''
    #print 'ldap router: request_uri = ' + request_uri
    _request_uri = urlparse(request_uri)
    routes = list()
    
    # Basic LDAP server parameters:
    server_uri = 'ldaps://ldap.example.org'
    base_dn = "dc=example,dc=org"
    # this domain will be appended to the phone numbers when creating
    # the target URI:
    phone_domain = 'pbx.example.org'
    # urlparse is not great for "sip:" URIs,
    # the user@host portion is in the 'path' element:
    filter = "(&(objectClass=inetOrgPerson)(mail=%s))" % _request_uri.path
    #print "Using filter: %s" % filter
    try:
        con = ldap.initialize(server_uri)
        scope = ldap.SCOPE_SUBTREE
        retrieve_attributes = None
        result_id = con.search(base_dn, scope, filter, retrieve_attributes)
        result_set = []
        while 1:
            timeout = 1
            result_type, result_data = con.result(result_id, 0, None)
            if (result_data == []):
                break
            else:
                if result_type == ldap.RES_SEARCH_ENTRY:
                    result_set.append(result_data)
        if len(result_set) == 0:
            #print "No Results."
            return routes
        for i in range(len(result_set)):
            for entry in result_set[i]:
                if entry[1].has_key('telephoneNumber'):
                    phone = entry[1]['telephoneNumber'][0]
                    routes.append('sip:' + phone + '@' + phone_domain)
    except ldap.LDAPError, error_message:
        print "Couldn't Connect. %s " % error_message
    return routes
Embedded Python opens up a world of possibilities After Ganglia 3.1.0 introduced an embedded Python scripting facility, dozens of new modules started appearing in github. Python scripting lowers the barrier for new contributors to a project and makes it much easier to fine tune free software projects to meet local requirements: hopefully we will see similar trends with the repro SIP proxy and other projects that choose Python. The code is committed here in the reSIProcate repository. These features will appear in the next beta release of reSIProcate and Debian packages will be available in unstable in a few days.

Ingo Juergensmann: Debian donation to m68k arrived

The Debian m68k port has been entitled by the DPL to receive a donation of five memory expansion cards for the m68k autobuilders. The cards arrived two weeks ago and are now being shipped to the appropriate buildd admins. Adding those 256 MB memory expansion will have a huge effect to the m68k buildds, because most of them are Amigas that are currently running with "just" 128 MB. The problem with those expansion cards is to make use of them. Sounds strange but this is the story behind it.... Those memory expansion cards, namely it is the BigRamPlus from Individual Computers, are Zorro III bus cards, which has some speed limitations. The Amiga memory model is best described in the Amiga Hardware Reference Manual. For Zorro III based Amigas this is described in the section "A3000 memory map", where you can see that the memory model is divided into different address space. The most important address space is the "Coprocessor Slot Expansion" space, starting at $0800 0000. This is where the memory on the CPU accelerator cards will be found and which runs at full CPU speed. The BigRamPlus, however, is located within "Zorro III Expansion" address space at $1000 0000 and will have transfer rates of about 13 MB/s. Then again there's still the motherboard expansion memory and others like Zorro II expansion memory. Unfortunately the current kernel does not support SPARSEMEM on m68k, but is using DISCONTIGMEM as Geert Uytterhoven explained. In short: we need SPARSEMEM support to easily make use of all available memory chunks that can be found. To make it a little more difficult, Amigas do use some kind of memory priority. Memory on accelerator cards usually has a priority of 40, motherboard expansion memory has a priority of, let's say, 20 and chip memory a pri of 0. This priority usually is equivalent to speed of memory. So, we want to have the kernel loaded to accelerator memory, of course. Basically we could do that by using a memfile and define the different memory chunks in the appropriate priority list like this one:
2097152
0x08000000 67108864
0x07400000 12582912
0x05000000 268435424
Would be an easy solution, right? Except that this doesn't work out. Currently the kernel will be loaded into the first memory chunk that is defined and ignore all memory chunks before that address space. As you can see 0x07400000 and 0x05000000 would be ignored because of this. Getting confused? No problem! It will get worse! ;) There's another method of accessing memory for Amigas: it's called z2ram and will use Zorro II as, let's say, swapping area. But maybe you guessed it: z2ram does not work for Zorro III memory (yet). So, this won't work either. Geert suggested to use that Zorro III memory as mtd device and finally this worked out! You'll need these modules in your kernel:
CONFIG_MTD=m
CONFIG_MTD_CMDLINE_PARTS=m
CONFIG_MTD_BLKDEVS=m
CONFIG_MTD_SWAP=m
CONFIG_MTD_MAP_BANK_WIDTH_1=y
CONFIG_MTD_MAP_BANK_WIDTH_2=y
CONFIG_MTD_MAP_BANK_WIDTH_4=y
CONFIG_MTD_CFI_I1=y
CONFIG_MTD_CFI_I2=y
CONFIG_MTD_SLRAM=m
CONFIG_MTD_PHRAM=m
Then you just need to create the mtd device and configure it as swap space:
/sbin/modprobe phram phram=bigram0,0x50000000,0xfffffe0
/sbin/modprobe mtdblock
/sbin/mkswap /dev/mtdblock0
/sbin/swapon -p 5 /dev/mtdblock0
And then you're done:
# swapon -s
Filename Type Size Used Priority
/dev/sda3 partition 205932 8 1
/dev/sdb3 partition 875536 16 1
/dev/mtdblock0 partition 262136 53952 5
To make it even worse (yes, there's still room for that! ;)) you can put two memory expansion cards into one box:
# lszorro -v
00: MacroSystems USA Warp Engine 40xx [Accelerator, SCSI Host Adapter and RAM Expansion]
40000000 (512K) 01: Unknown device 0e3b:20:00
50000000 (256M) 02: Village Tronic Picasso II/II+ RAM [Graphics Card]
00200000 (2M) 03: Village Tronic Picasso II/II+ [Graphics Card]
00e90000 (64K) 04: Hydra Systems Amiganet [Ethernet Card]
00ea0000 (64K) 05: Unknown device 0e3b:20:00
60000000 (256M)
The two "Unknown device" entries are the two BigRamPlus cards. As you can see card #1 starts at 0x50000000 and card #2 starts at 0x60000000. Unfortunately the phram kernel module can be loaded twice with different start addresses, but the idea to start at 0x50000000 with a size of 512M won't work either as there seems to be a reserved 0x20 bytes a range at the beginning of each card. Anyway... So, to make a very long and weird story short: the donated memory cards from Debian can now be used as additional and fast swap space for the buildds as long as it takes to get SPARSEMEM support working. Thanks again for donating the money for those memory expansion cards for the good old m68k port. Once done SPARSEMEM support in the m68k will benefit not only these cards in Amigas but Ataris as well.
Kategorie:

Antoine Beaupr : Password reset of Speedstream 5200 modems

After an extended downtime on my ADSL uplink at home during a nice snowstorm, I got curious and wanted to find out the SNR (Signal to Noise Ratio) I had on my line, to try to explain why it was down. It turned out it was more complicated than I thought, because the modem was locked down by Bell Canada (even though I am not a customer). There was a Windows utility, but since I haven't been running this pathetic operating system in years, I had to find an alternative. Fortunately, the author of that utility posted a description of the packet format used for the password reset, and here I was trying to send raw ethernet frames using Linux (for testing and, why not!) and FreeBSD (because I use FreeBSD for routing, because I dislike iptables). The result is this somewhat poorly written C program, available in this git repository. It uses raw sockets in Linux but the BPF (Berkeley Packet Filter) in FreeBSD, as their interface is a little broken for raw sockets. See the README file for more information. Enjoy.

17 December 2013

Joey Hess: completely linux distribution-independent packaging

Sometimes it makes sense to ship a program to linux users in ready-to-run form that will work no matter what distribution they are using. This is hard. Often a commerical linux game will bundle up a few of the more problimatic libraries, and ship a dynamic executable that still depends on other system libaries. These days they're building and shipping entire Debian derivatives instead, to avoid needing to deal with that. There have been a few efforts to provide so-called one click install package systems that AFAIK, have not been widely used. I don't know if they generally solved the problem. More modern appoaches seem to be things like docker, which move the application bundle into a containerized environment. I have not looked at these, but so far it does not seem to have spread widely enough to be a practical choice if you're wanting to provide something that will work for a majority of linux users. So, I'm surprised that I seem to have managed to solve this problem using nothing more than some ugly shell scripts. My standalone tarballs of git-annex now seem fairly good at running on a very wide variety of systems. For example, I unpacked the tarball into the Debian-Installer initramfs and git-annex could run there. I can delete all of /usr and it keeps working! All it needs is a basic sh, which even busybox provides. Looks likely that the new armel standalone tarball of git-annex will soon be working on embedded systems as odd as the Synology NAS, and it's already been verified to work on Raspbian. (I'm curious if it would work on Android, but that might be a stretch.) Currently these tarballs are built for a specific architecture, but there's no particular reason a single one couldn't combine binaries built for each supported architecture. technical details The main trick is to ship a copy of ld-linux.so, as well as all the glibc libraries and associated files, and of course every other library and file the application needs. Shipping ld-linux.so lets a shell script wrapper be made around each binary, that runs ld-linux.so and passes it the library directories to search. This way the binary can be run, bypassing the system's own dynamic linker (which might not like it) and using the included glibc. For example a shell script that runs the git binary from the bundle:

exec "$GIT_ANNEX_LINKER" --library-path "$GIT_ANNEX_LD_LIBRARY_PATH" "$GIT_ANNEX_SHIMMED/git/git" "$@"
I have to set quite a lot of environment variables, to avoid using any files from the system and instead use ones from my tarball. One important one is GCONV_PATH. Note that LD_LIBRARY_PATH does not have to be set, and this is nice because it allows running a few programs from the host system, such as its web browser. worse is better Of course I'll take a proper distribution package anytime over this. Still, it seems to work quite well, in all the horrible cases that require it.

16 December 2013

Erich Schubert: Java Hotspot Compiler - a heavily underappreciated technology

When I had my first contacts with Java, probably around Java 1.1 or Java 1.2, it felt all clumsy and slow. And this is still the reputation that Java has to many developers: bloated source code and slow performance.
The last years I've worked a lot with Java; it would not have been my personal first choice, but as this is usually the language the students know best, it was the best choice for this project, the data mining framework ELKI.
I've learned a lot on Java since, also on debugging and optimizing Java code. ELKI contains a number of tasks that require a good number chrunching performance; something where Java particularly had the reputation of being slow.
I must say, this is not entirely fair. Sure, the pure matrix multiplication performance of Java is not up to Fortran (BLAS libraries are usually implemented in Fortran, and many tools such as R or NumPy will use them for the heavy lifting). But there are other tasks than matrix multiplication, too!
There is a number of things where Java could be improved a lot. Some of this will be coming with Java 8, others is still missing. I'd particularly like to see native BLAS support and multi-valued on-stack returns (to allow intrinsic sincos, for example).

In this post, I want to emphasize that usually the Hotspot compiler does an excellent job.
A few years ago, I have always been laughing at those that claimed "Java code can even be faster than C code"; because the Java JVM is written in C. Having had a deeper look at what the hotspot compiler does, I'm now saying: I'm not surprised that quite often, reasonably good Java code outperforms reasonably good C code.
In fact, I'd love to see a "hotspot" optimizer for C.
So what is it what makes Hotspot so fast? In my opinion, the key ingredient to hotspot performance is aggressive inlining. And this is exactly why "reasonably well written" Java code can be faster than C code written at a similar level.
Let me explain this at an example. Assuming we want to compute a pariwise distance matrix; but we want the code to be able to support arbitrary distance functions. The code will roughly look like this (not heavily optimized):
for (int i = 0; i < size; i++)  
  for (int j = i + 1; j < size; j++)  
    matrix[i][j] = computeDistance(data[i], data[j]);
   
 
In C, if you want to be able to choose computeDistance at runtime, you would likely make it a function pointer, or in C++ use e.g. boost::function or a virtual method. In Java, you would use an interface method instead, i.e. distanceFunction.distance().
In C, your compiler will most likely emit a jmp *%eax instruction to jump to the method to compute the distance; with virtual methods in C++, it would load the target method from the vtable and then jmp there. Technically, it will likely be a "register-indirect absolute jump". Java will, however, try to inline this code at runtime, i.e. it will often insert the actual distance function used at the location of this call.
Why does this make a difference? CPUs have become quite good at speculative execution, prefetching and caching. Yet, it can still pay off to save those jmps as far as I can tell; and if it is just to allow the CPU to apply these techniques to predict another branch better. But there is also a second effect: the hotspot compiler will be optimizing the inlined version of the code, whereas the C compiler has to optimize the two functions independently (as it cannot know they will be only used in this combination).
Hotspot can be quite aggressive there. It will even inline and optimize when it is not 100% sure that these assumptions are correct. It will just add simple tests (e.g. adding some type checks) and jump back to the interpreter/compiler when these assumptions fail and then reoptimize again.
You can see the inlining effect in Java when you use the -Xcomp flag, telling the Java VM to compile everything at load time. It cannot do as much speculative inlining there, as it does not know which method will be called and which class will be seen. Instead, it will have to compile the code using virtual method invocations, just like C++ would use for executing this. Except that in Java, every single method will be virtual (in C++, you have to be explicit). You will likely see a substantial performance drop when using this flag, it is not recommended to use. Instead, let hotspot perform its inlining magic. It will inline a lot by default - in particular tiny methods such as getters and setters.
I'd love to see something similar in C or C++. There are some optimizations that can only be done at runtime, not at compile time. Maybe not even at linking time; but only with runtime type information, and that may also change over time (e.g. the user first computes a distance matrix for Euclidean distance, then for Manhattan distance).

Don't get me wrong. I'm not saying Java is perfect. There are a lot of common mistakes, such as using java.util.Collections for primitive types, which comes at a massive memory cost and garbage collection overhead. The first thing to debug when optimizing Java applications is to check for memory usage overhead. But all in all, good Java code can indeed perform well, and may even outperform C code, due to the inlining optimization I just discussed; in particular on large projects where you cannot fine-tune inlining in C anymore.

Sometimes, Hotspot may also fail. Which is largely why I've been investigating these issues recently. In ELKI 0.6.0 I'm facing a severe performance regression with linear scans (which is actually the simpler codepath, not using indexes but using a simple loop as seen above). I had this with 0.5.0 before, but back then I was able to revert back to an earlier version that still performed good (even though the code was much more redundant). This time, I would have had to revert a larger refactoring that I wanted to keep, unfortunately.
Because the regression was quite severe - from 600 seconds to 1500-2500 seconds (still clearly better than -Xcomp) - I first assumed I was facing an actual programming bug. Careful inspection down to the assembler code produced by the hotspot VM did not reveal any such error. Then I tried Java 8, and the regression was gone.
So apparently, it is not a programming error, but Java 7 failed at optimizing it remotely as good as it did with the previous ELKI version!
If you are an Java guru, interested at tracking down this regression, feel free to contact me. It's in an open source project, ELKI. I'd be happy to have good performance even for linear-scans, and Java 7. But I don't want to waste any more hours on this, but instead plan to move on to Java 8 for other reasons (lambda expressions, which will greatly reduce the amount of glue coded needed), too. Plus, Java 8 is faster in my benchmarks.

Dirk Eddelbuettel: RProtoBuf 0.3.2

A new version 0.3.2 of RProtoBuf, is now on CRAN. RProtoBuf provides GNU R bindings for the Google Protobuf data encoding library used and released by Google. As for the last few releases, Murray took charge of most changes. The NEWS file entry follows:
Changes in RProtoBuf version 0.3.2 (2013-12-15)
  • Fixed a bug that erroneously prevented users from setting raw byte fields in protocol buffers under certain circumstances.
  • Give a user friendly error message when seting an extension to a message of the wrong type instead of causing a C++ check failure that terminates the Rsession.
  • Change object table lookup slightly to allow users to use the <<- operator in code using RProtoBuf without hitting a stop() error in the lookup routine.
  • Add missing enum_type method and improve show method for EnumValueDescriptors.
  • Improve documentation and tests for all of the above.
  • Rewrote tests/ script calling RUnit tests
CRANberries also provides a diff to the previous release 0.3.1. More information is at the RProtoBuf page which has a draft package vignette, a 'quick' overview vignette and a unit test summary vignette. Questions, comments etc should go to the rprotobuf mailing list off the RProtoBuf page at R-Forge.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

Craig Sanders: shopping online whinge of the day

There are numerous benefits to shopping online you can order stuff and pay for it from the comfort of your own home and it ll arrive on your doorstep in just a few days. wonderful, and so many words have been written about the benefits over the years that there s no need to belabour the point, But there are some things about it that really suck and make me NOT want to order stuff online most of the time my distaste for the privacy and delivery problems is enough to dissauade me from buying anything, helped by the fact that I live a fairly non-consumerist lifestyle (and for a geek, I have an almost non-existent gadget-fetish) but occasionally I want or need something that isn t available locally or which my ill-health makes impractical to buy in person (i ve been effectively housebound or in hospital for most of the year) so here are the things that piss me off most about shopping online.
  1. Loss of anonymity and privacy. You can walk into any shop and pay cash for whatever you want, they don t need to know who you are or where you live, and they don t get to accidentally add you to a mailing list against your express wishes oh, we didn t realise that when you said DO NOT SPAM ME, you actually meant DO NOT SPAM ME we ll just keep spamming you for another six months until we get around to processing your removal request . partial solution: use a different email address with each online shop. boycott the shop and destroy the address if they spam. what sucks is that this is actually necessary. it doesn t matter how loudly I say DO NOT SPAM ME. DO NOT ADD ME TO ANY MAILING LISTS. DO NOT ASK ME TO COMPLETE A SURVEY. DO NOT CONTACT ME FOR ANY REASON NOT DIRECTLY RELATED TO DELIVERING MY ORDER. MY PERSONAL INFORMATION IS PROVIDED SOLELY SO THAT YOU CAN SHIP MY ORDER TO ME AND MAY NOT BE USED FOR ANY OTHER PURPOSE. FAILURE TO RESPECT MY PRIVACY WILL RESULT IN IMMEDIATE AND PERMANENT BOYCOTT (yes, that IS the text I use in the comments/instructions field of every order I place), marketing vermin will decide that I really want their spam after all because their spam is super interesting and important and isn t really spam at all.
  2. nosy demands for unneccessary information. OK, they need your addresss to ship your parcel but they don t need your phone number, and they don t need to tie your order to your facebook or other bullshit social-spam account. most online order forms have phone number as a required field. Fortunately, they usually accept 0000000 or some other bogus non-phone number as a valid number .if not, i give them their own phone number.
  3. the thing that really shits me the most about online shopping is that both couriers and australia post suck. the lazy fuckers usually don t even bother attempting to deliver to residential addressess. at best, they just stick a non-delivery card in your letterbox without even attempting to knock on the door ..and sometimes they don t even bother doing that. the delivery driver just files a bogus failed to deliver or recipient refused delivery with their office.
i ve made four online purchases in the last month and a half. only one of them was delivered correctly to my door, even though I was sitting at my desk in the front room of the house, a few feet from my front door, and regularly monitoring the parcel s tracking web page so I knew it was arriving. parcel 1 (Nov 16): DHL from NZ to AU. delivered perfectly. delivered in about two days for $17. order value: around $35. parcel 2 (Nov 20): Aust Post from WA to Vic, Express Post (costs a few bucks more than standard post). order value: around $80. lazy driver didn t bother to attempt delivery. left card in letter box. i had to pick it up 2 days later from a post office the next suburb over (it wasn t there yet on the first attempt to pick up, the next day). Aust Post offered to maybe put me in touch with their re-delivery people who might possibly be able to re-deliver the parcel next week sometime maybe, if they felt like it. knowing that I had another hospital appt the next week, I declined (if i hadn t, it would have been an absolute certainty that they would try to deliver it while i was out). parcel 3 (nov 29): DHL from NZ to AU. order value: around $85. lazy courier didn t even bother to leave a card, just logged it as Recipient refused delivery . This refused delivery lie infuriated me when i saw it on the tracking page so i phoned and yelled at them a lot. DHL delivered it later the same day. if they hadn t I would have had to get myself over to the other side of town during business hours and pick it up from their South Melbourne depot. parcel 4 (today, Dec 16): Aust Post from NSW to Vic, Express Post . order value: around $160. lazy driver didn t even bother to leave a card, just logged it as Attempted delivery being carded to Australia Post outlet . Complete bullshit. There was no delivery attempt, not even a card in the letterbox, let alone a knock on the door with my parcel. Rang Aust Post on 8847 9045 (a phone number curiously absent from their tracking page, but which I had written down after their failure to deliver on Nov 20) and complained. they claim that they will try to deliver it today. i ll believe it when I see it. UPDATE @4.30pm: no, it s not going to be delivered today. they say they might choose to deliver it tomorrow or sometime in the future, if the delivery center manager feels like it. i told them that this is not an option my parcel WILL be delivered, it is what they were paid to do so it is what they ARE going to do. btw, the tracking page says that they attempted delivery at 12.15 today (they didn t not even a card in the letterbox), but the tracking page wasn t updated with that until about 2.30pm. by a complete non-coincidence their delivery center allegedly closes at 2pm, so it s impossible to complain about non-delivery in time for the complaint to do any good. Score so far: DHL 50% delivery rate. Aust Post: 100% failure rate. Annoyance Rate: extremely high. Desire to repeat the experience: non-existent. The Australia Post delivery problems are particularly annoying. I ve always thought of the network of local post offices to be a huge advantage for parcel delivery if i m not home, my parcel will go to a local post office and I can pick it up from there. And this is a great advantage. I used to take advantage of it when I was well enough to work. In fact, I d insist on delivery by Aust. Post rather than by a courier for exactly this reason, a local post office is far more convenient than some courier s depot on the other side of town or out in some far outer-suburban hellhole. But when it s used as an excuse to not even bother attempting delivery, it sucks. I m not well, and I should have been lying in bed reading or sleeping today, not wasting what little energy I have waiting for a parcel that never arrived and I certainly shouldn t have to phone Aust Post or DHL to yell at them for failing to do the job that they have been paid to do. shopping online whinge of the day is a post from: Errata

15 December 2013

Russell Coker: Dell PowerEdge T110

In June 2008 I received a Dell PowerEdge T105 server to run in my home for a client [1]. That system has run well for over 5 years for the purposes of my client and also as my own home fileserver and as a workstation. But now it s getting a bit old, while it was still basically working the cooling fans were getting noisy, faster systems are available, and it was crashing occasionally which could have been due to hardware or software. On the 7th of November I got a new Dell PowerEdge T110. It s got a i3-3220 CPU (speed of 4218 according to cpubenchmark.net) which is a lot better than the AMD 1212 (speed of 982). It takes up to 4*3.5 SATA disks (as opposed to 2 disks) and has more options for memory expansion. Next time I run out of disk space I ll add another RAID-1 pair of disks instead of buying new disks. Generally this system is much the same as the one it replaces. It s a cheap server which unfortunately lacks sound hardware and usable video hardware. Sound is a problem I already solved with USB speakers but for the new system I bought a PCIe video card. Fortunately the system has PCIe*16 sockets (which apparently only have PCIe*8 wires) which avoids the problem I had in the past trying to obtain a suitable video card. The crashes turned out to be due to BTRFS and now that I ve made some tweaks everything is running well. I ll probably buy another Dell PowerEdge in about 5 years time.

Hideki Yamane: my Desktop Environment broken - any help?


Recently, my GNOME environment was broken suddenly. Startup GNOME Shell cause segfault and die. I cannot use GDM3 at all.

henrich@hp:~ $ grep gnome-shell /var/log/syslog
Dec 15 10:51:12 hp kernel: [34944.969581] gnome-shell[10054]: segfault at 84 ip 00007f6c6186a7b9 sp 00007fff59f1dbc0 error 4 in libcogl.so.12.1.1[7f6c61821000+97000]
Dec 15 10:51:12 hp gnome-session[9565]: WARNING: Application 'gnome-shell.desktop' killed by signal 11
Dec 15 10:51:14 hp kernel: [34946.429046] gnome-shell[10202]: segfault at 84 ip 00007ffa2ae877b9 sp 00007fff2bc5c7d0 error 4 in libcogl.so.12.1.1[7ffa2ae3e000+97000]
Dec 15 10:51:14 hp gnome-session[9565]: WARNING: Application 'gnome-shell.desktop' killed by signal 11
Dec 15 10:51:14 hp gnome-session[9565]: WARNING: App 'gnome-shell.desktop' respawning too quickly
So, I've switched to KDM, and install xfce4. However, I faced to another problem - it cannot show any icons (desktop and panel).


Odd Chromium window (why red?).


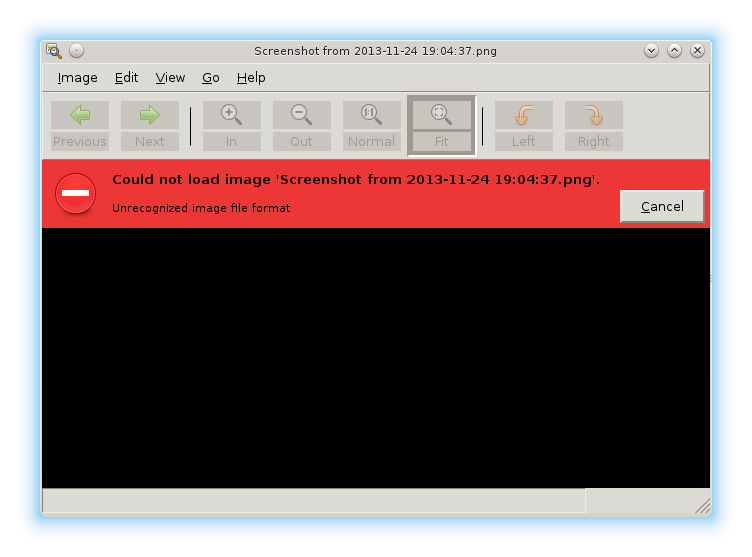
Also eog says "Could not load image" "Unrecognized image file format" - Well, why? It's just a .png file. (screenshot on KDE4)
Shotwell cause segfault, too :-( (and some other GTK applications)

I cannot point out broken component. Dear lazyweb, could you tell me how to fix this situation, please?


13 December 2013

Daniel Pocock: xWiki: 10 years and a WebRTC success story

Six months ago, I wrote to the leaders of several open source web frameworks and asked them about their vision for WebRTC and if they would come to the WebRTC Conference in Paris this week (now finished). The most promising response was from Ludovic Dubost, founder of the xWiki project. Ludovic successfully demonstrated their shiny new WebRTC capabilities today in front of an audience including many far more experienced telephony operators who are still only getting to terms with this technology. What is xWiki? Don't let the wiki name limit your perception of this project. xWiki is a lot more than just another wiki hosting framework. As a bare minimum, you can certainly use it in the same way as other wikis, doing lightweight markup that is easier than HTML. On the other hand, xWiki really shines when it comes to extensibility. The xWiki team are Java developers and so xWiki appeals most to other Java developers who may want to leverage some library code from their web portal from time to time, without even having to compile anything. Here are some examples and here is one of the most trivial ones:
 velocity 
Your username is $xcontext.getUser(), welcome to the site.
 /velocity 
WebRTC capabilities The xWiki team chose XMPP as a chat protocol (using the Candy XMPP JavaScript chat) as the foundation for real-time communication. They have then extended this by creating a custom signalling mechanism and making it convenient for users of a chat session to upgrade the session to voice/video with a mouseclick. The whole experience works within the browser without any plugins. 10 years of xWiki It was also xWiki's 10th birthday today and this provided the perfect opportunity for a party: cjdns and enigmabox While at the xWiki office, it was interesting to see a lot of innovative work taking place, including this VoIP setup where a Grandstream phone is attached to an Enigmabox operated by Caleb from the cjdns project.
11 December 2013

Daniel Pocock: Get WebRTC going faster

On Saturday, Lumicall began offering free calls from browser to mobile using the free and open WebRTC technology. It should be no surprise that the service has been popular. Is it really free and open? The only way to prove this technology is free is to help people implement this for themself. On Monday, I uploaded reSIProcate v1.9.0 beta7 packages to Debian. The reSIProcate SIP proxy, repro, is one of the core components of the solution behind the free Lumicall service. Simply install the repro and resiprocate-turn-server packages using apt-get and make the following changes to the configuration (use your own IP addresses of course). I've taken this diff from my own runtime environment, only hiding my passwords, so that you can see exactly how I got it working:
--- repro.config.orig	2013-12-11 17:36:27.179228324 +0100
+++ repro-ws.sip5060.net.config	2013-12-11 17:48:24.159938649 +0100
@@ -143,6 +143,41 @@
 # Transport6TlsClientVerification = None
 # Transport6RecordRouteUri = sip:h1.sipdomain.com;transport=WS
 
+Transport1Interface = 195.8.117.57:80
+Transport1Type = WS
+Transport1RecordRouteUri = auto
+
+Transport2Interface = 2001:67c:1388:1000::57:80
+Transport2Type = WS
+Transport2RecordRouteUri = auto
+
+Transport3Interface = 195.8.117.57:5060
+Transport3Type = TCP
+Transport3RecordRouteUri = auto
+
+Transport4Interface = 2001:67c:1388:1000::57:5060
+Transport4Type = TCP
+Transport4RecordRouteUri = auto
+
+Transport5Interface = 195.8.117.57:443
+Transport5Type = WSS
+#Transport5RecordRouteUri = auto
+Transport5TlsDomain = ws.sip5060.net
+Transport5TlsClientVerification = None
+Transport5RecordRouteUri = sip:ws.sip5060.net;transport=WSS
+Transport5TlsCertificate = /etc/ssl/ssl.crt/ws.sip5060.net-bundle.crt
+Transport5TlsPrivateKey = /etc/ssl/private/ws.sip5060.net-key.pem
+
+Transport6Interface = 2001:67c:1388:1000::57:443
+Transport6Type = WSS
+#Transport6RecordRouteUri = auto
+Transport6TlsDomain = ws.sip5060.net
+Transport6TlsClientVerification = None
+Transport6RecordRouteUri = sip:ws.sip5060.net;transport=WSS
+Transport6TlsCertificate = /etc/ssl/ssl.crt/ws.sip5060.net-bundle.crt
+Transport6TlsPrivateKey = /etc/ssl/private/ws.sip5060.net-key.pem
+
+
 # Comma separated list of DNS servers, overrides default OS detected list (leave blank 
 # for default)
 DNSServers =
@@ -455,7 +490,7 @@
 ForceRecordRouting = false
 
 # Assume path option
-AssumePath = false
+AssumePath = true
 
 # Disable registrar
 DisableRegistrar = false
@@ -481,7 +516,7 @@
 # WARNING: Before enabling this, ensure you have a RecordRouteUri setup, or are using
 # the alternate transport specification mechanism and defining a RecordRouteUri per
 # transport: TransportXRecordRouteUri
-DisableOutbound = true
+DisableOutbound = false
 
 # Set the draft version of outbound to support (default: RFC5626)
 # Other accepted values are the versions of the IETF drafts, before RFC5626 was issued
@@ -505,7 +540,7 @@
 # WARNING: Before enabling this, ensure you have a RecordRouteUri setup, or are using
 # the alternate transport specification mechanism and defining a RecordRouteUri per
 # transport: TransportXRecordRouteUri
-EnableFlowTokens = false
+EnableFlowTokens = true
 
 # Enable use of flow-tokens in non-outbound cases for clients detected to be behind a NAT.  
 # This a more selective flow token hack mode for clients not supporting RFC5626.  The 

This is a diff against the /etc/repro/repro.config file distributed in the Debian package version 1.9.0~beta7-1. In the example above, I've included WSS transport defintions for WebSockets over TLS. Use the standard procedure for creating webserver SSL certificates to create certificates for repro and make sure you insert the correct filenames in the TLS parameters above. I've also duplicated every transport for IPv6. If you don't want TLS/WSS or IPv6, just comment those entries out (and renumber the remaining transports). Web-based SIP proxy setup Once you have repro running, go to the web admin interface (port 5080, username: admin, password: admin) and finish the setup using the web UI. The following steps are essential:
  • Add your domain (and restart the repro daemon after adding your domain)
  • Add some users
  • Add any routes to external services (optional - in my next blog I'll demonstrate how to route WebRTC calls to Asterisk using the Debian packages and less than 20 lines of configuration)
Set up reTurn, the TURN server Just put your IP addresses in /etc/reTurnServer.config and add the following line to /etc/reTurnServer-users.txt:
test:notasecret:reTurn:authorized
IMPORTANT: the realm in the users file (reTurn in the example and default config) must be identical to the AuthenticationRealm in the /etc/reTurnServer.config file. On your own web site Simply install your own apache server and clone the webrtc.lumicall.org demo site. Modify the file js/custom.js and include the settings for your own server.
# cd /var/www
# mkdir webcall
# cd webcall
# wget -r -nH http://webrtc.lumicall.org
# vi js/custom.js
In the custom.js, make sure you use a ws:// URL if you didn't set up SSL certificates and use a wss:// URL if you did. The IP or domain of your repro server must be in the ws:// or wss:// URL. Now navigate to the URL ending with /webcall on your server. For RHEL, Fedora and other RPM users Can somebody please assist with the review of the cajun-jsonapi dependency package so I can upload this new version of reSIProcate to Fedora? I'm also planning to make v1.9.0 available in EPEL6 when it is released in January. Questions? Please come and ask questions or discuss your experiences on the Free RTC mailing list sponsored by FSF Europe.

Next.

Previous.