Here s my (fifteenth) monthly update about the activities I ve done in the F/L/OSS world.
Debian
This was my 24th month of contributing to Debian.
I became a DM in late March last year and a DD last Christmas! \o/
Amongs a lot of things, this was month was crazy, hectic, adventerous, and the last of 2020 more on some parts later this month.
I finally finished my 7th semester (FTW!) and moved onto my last one! That said, I had been busy with other things but still did a bunch of Debian stuff
Here are the following things I did this month:
Debian (E)LTS
Debian Long Term Support (LTS) is a project to extend the lifetime of all Debian stable releases to (at least) 5 years. Debian LTS is not handled by the Debian security team, but by a separate group of volunteers and companies interested in making it a success.
And Debian Extended LTS (ELTS) is its sister project, extending support to the Jessie release (+2 years after LTS support).
This was my fifteenth month as a Debian LTS and sixth month as a Debian ELTS paid contributor.
I was assigned 26.00 hours for LTS and 38.25 hours for ELTS and worked on the following things:
LTS CVE Fixes and Announcements:
Issued DLA 2474-1, fixing CVE-2020-28928, for musl.
For Debian 9 Stretch, these problems have been fixed in version 1.1.16-3+deb9u1.
Issued DLA 2484-1, fixing #969126, for python-certbot.
For Debian 9 Stretch, these problems have been fixed in version 0.28.0-1~deb9u3.
Issued DLA 2487-1, fixing CVE-2020-27350, for apt.
For Debian 9 Stretch, these problems have been fixed in version 1.4.11. The update was prepared by the maintainer, Julian.
Issued DLA 2488-1, fixing CVE-2020-27351, for python-apt.
For Debian 9 Stretch, these problems have been fixed in version 1.4.2. The update was prepared by the maintainer, Julian.
Issued DLA 2495-1, fixing CVE-2020-17527, for tomcat8.
For Debian 9 Stretch, these problems have been fixed in version 8.5.54-0+deb9u5.
Issued DLA 2488-2, for python-apt.
For Debian 9 Stretch, these problems have been fixed in version 1.4.3. The update was prepared by the maintainer, Julian.
Issued DLA 2508-1, fixing CVE-2020-35730, for roundcube.
For Debian 9 Stretch, these problems have been fixed in version 1.2.3+dfsg.1-4+deb9u8. The update was prepared by the maintainer, Guilhem.
ELTS CVE Fixes and Announcements:
Issued ELA 324-1, fixing CVE-2020-28928, for musl.
For Debian 8 Jessie, these problems have been fixed in version 1.1.5-2+deb8u2.
Issued ELA 325-1, fixing CVE-2020-28896, for mutt.
For Debian 8 Jessie, these problems have been fixed in version 1.5.23-3+deb8u4.
Marked CVE-2020-17527/tomcat8 as not-affected for jessie.
Marked CVE-2020-28052/bountycastle as not-affected for jessie.
Marked CVE-2020-14394/qemu as postponed for jessie.
Marked CVE-2020-35738/wavpack as not-affected for jessie.
Marked CVE-2020-3550 3-6 /qemu as postponed for jessie.
Marked CVE-2020-3550 3-6 /qemu as postponed for stretch.
Marked CVE-2020-16093/lemonldap-ng as no-dsa for stretch.
Marked CVE-2020-27837/gdm3 as no-dsa for stretch.
Marked CVE-2020- 13987, 13988, 17437 /open-iscsi as no-dsa for stretch.
Marked CVE-2020-35450/gobby as no-dsa for stretch.
Marked CVE-2020-35728/jackson-databind as no-dsa for stretch.
Marked CVE-2020-28935/nsd as no-dsa for stretch.
Auto EOL ed libpam-tacplus, open-iscsi, wireshark, gdm3, golang-go.crypto, jackson-databind, spotweb, python-autobahn, asterisk, nsd, ruby-nokogiri, linux, and motion for jessie.
Bugs and Patches
Well, I did report some bugs and issues and also sent some patches:
Issue #44 for github-activity-readme, asking for a feature request to set custom committer s email address.
Issue #711 for git2go, reporting build failure for the library.
PR #89 for rubocop-rails_config, bumping RuboCop::Packaging to v0.5.
Issue #36 for rubocop-packaging, asking to try out mutant :)
PR #212 for cucumber-ruby-core, bumping RuboCop::Packaging to v0.5.
PR #213 for cucumber-ruby-core, enabling RuboCop::Packaging.
Issue #19 for behance, asking to relax constraints on faraday and faraday_middleware.
PR #37 for rubocop-packaging, enabling tests against ruby3.0! \o/
PR #489 for cucumber-rails, bumping RuboCop::Packaging to v0.5.
Issue #362 for nheko, reporting a crash when opening the application.
PR #1282 for paper_trail, adding RuboCop::Packaging amongst other used extensions.
Bug #978640 for nheko Debian package, reporting a crash, as a result of libfmt7 regression.
Misc and Fun
Besides squashing bugs and submitting patches, I did some other things as well!
Participated in my first Advent of Code event! :)
Whilst it was indeed fun, I didn t really complete it. No reason, really. But I ll definitely come back stronger next year, heh! :)
All the solutions thus far could be found here.
Did a couple of reviews for some PRs and triaged some bugs here and there, meh.
Also did some cloud debugging, not so fun if you ask me, but cool enough to make me want to do it again! ^_^
Worked along with pollo, zigo, ehashman, rlb, et al for puppet and puppetserver in Debian. OMG, they re so lovely! <3
Ordered some interesting books to read January onward. New year resolution? Meh, not really. Or maybe. But nah.
Also did some interesting stuff this month but can t really talk about it now. Hopefully sooooon.
As you may know, I am Qt 5 maintainer in Debian. Maintaning Qt means not only
bumping the version each time a new version is released, but also making sure
Qt builds successfully on all architectures that are supported in Debian (and
for some submodules, the automatic tests pass).
An important sort of build failures are endianness specific failures. Most
widely used architectures (x86_64, aarch64) are little endian. However, Debian
officially supports one big endian architecture (s390x), and unofficially
a few more ports are provided, such as ppc64 and sparc64.
Unfortunately, Qt upstream does not have any big endian machine in their CI
system, so endianness issues get noticed only when the packages fail to build
on our build daemons. In the last years I have discovered and fixed some such
issues in various parts of Qt, so I decided to write a post to illustrate how
to write really cross-platform C/C++ code.
Issue 1: the WebP image format handler (code review)
The relevant code snippet is:
The code here is serializing the images into QImage::Format_ARGB32 format, and
then passing the bytes into WebP s import function. With this format, the image
is stored using a 32-bit ARGB format (0xAARRGGBB). This means that the bytes
will be 0xBB, 0xGG, 0xRR, 0xAA or little endian and 0xAA, 0xRR, 0xGG, 0xBB on
big endian. However, WebPPictureImportBGRA expects the first format on all
architectures.
The fix was to use QImage::Format_RGBA8888. As the QImage documentation
says, with this format the order of the colors is the same on any architecture
if read as bytes 0xRR, 0xGG, 0xBB, 0xAA.
Issue 2: qimage_converter_map structure (code review)
The code seems to already support big endian. But maybe you can spot the error?
It is the missing comma! It is present in the little endian block, but not in
the big endian one. This was fixed trivially.
Issue 3: QHandle, part of Qt 3D module (code review)
QHandle class uses a union that is declared as follows:
The sizes are declared such as IndexBits + CounterBits + 2 is always
equal to 32 (four bytes).
Then we have a constructor that sets the values of Data struct:
The value of m_handle will be different depending on endianness!
So the test that was expecting a particular value with given constructor
arguments was failing. I fixed it by using the following macro:
Issue 4: QML compiler (code review)
The QML compiler used a helper class named LEUInt32 (based on QLEInteger)
that always stored the numbers in little endian internally. This class
can be safely mixed with native quint32 on little endian systems, but not
on big endian.
Usually the compiler would warn about type mismatch, but here the code used
reinterpret_cast, such as:
So this was not noticed on build time, but the compiler was crashing. The fix
was trivial again, replacing quint32 with QLEUInt32.
Issue 5: QModbusPdu, part of Qt Serial Bus module (code review)
The code snippet is simple:
QModbusPdu::FunctionCode is an enum, so code is a multi-byte value (even if
only one byte is significant). However, (char *) (&code) returns a pointer to
the first byte of it. It is the needed byte on little endian systems, but it is
the wrong byte on big endian ones!
The correct fix was using a temporary one-byte variable:
Issue 6: qt_is_ascii (code review)
This function, as the name says, checks whether a string is ASCII. It does
that by splitting the string into 4-byte chunks:
idx / 8 is the number of trailing zero bytes. However, the bytes which are
trailing on little endian are actually leading on big endian! So we can use
qCountLeadingZeroBits there.
Issue 7: the bundled copy of tinycbor (upstream pull request)
Similar to issue 5, the code was reading into the wrong byte:
extra has type uint16_t, so it has two bytes. When we need only one byte,
we read into the wrong byte, so the resulting number is 256 times higher on
big endian than it should be. Adding a temporary one-byte variable fixed it.
Issue 8: perfparser, part of Qt Creator (code review)
Here it is not trivial to find the issue just looking at the code:
undefined reference to QDataStream::Version qbswap(QDataStream::Version)'
On little endian systems, qToLittleEndian is a no-op, but on big endian
systems, it is a template function defined for some known types. But it turns
out we need to explicitly convert enum values to a simple type, so the fix
was passing qint32(QDataStream::Qt_DefaultCompiledVersion) to that function.
Issue 9: Qt Personal Information Management (code review)
The code in test was trying to represent a number as a sequence of bytes,
using reinterpret_cast:
The order of bytes will be different on little endian and big endian systems!
The fix was adding this line to the beginning of the function:
id=qToLittleEndian(id);
This will cause the bytes to be reversed on big endian systems.
What remains unfixed
There are still some bugs, which require deeper investigation, for example:
Review: A Wizard's Guide to Defensive Baking, by T. Kingfisher
Publisher:
Red Wombat Studio
Copyright:
July 2020
ASIN:
B08CJ86Y1W
Format:
Kindle
Pages:
287
Mona is fourteen, an orphan, and works in the bakery owned by her Aunt
Tabitha. She's also a magicker, although a very minor one. She can tell
bread to do things, like bake properly or slice itself, and can make
gingerbread men dance. Also, there's Bob, her sourdough starter, into
whom she put a bit too much panicked magic when she was ten. Her magic is
a useful small talent for a baker, but nothing all that exceptional.
The dead body she finds in the kitchen when opening the bakery is
certainly exceptional.
A Wizard's Guide to Defensive Baking starts as a minor murder
mystery. There are constables and sweet buns and Mona is accused of
murder by an officious inquisitor, which was rather terrifying, but
everything seems like it will work out and get back to normal. Except it
won't, because someone is murdering magickers and the authorities who are
supposed to be helping Mona don't appear to be on her side.
This is a very Ursula Vernon sort of book. (T. Kingfisher is the
pseudonym that Vernon uses when not writing children's books.) The
protagonist is brave, scared, and stubborn, the first-person narration has
a stream-of-consciousness feel and an undercurrent of constant curiosity,
and the story has a strong "this is awful but moping about it won't help
so we may as well get on with it" energy. It is (as you might guess from
the age of the protagonist) pitched a bit younger than Vernon's other
recent Kingfisher work. If I had to classify it, I'd call it young adult
possibly edging into middle grade.
It's also a book about creative use of magic powers. If you're the sort
of person who liked analyzing an apparently unimpressive superpower and
thinking up all the creative ways in which it could be quite powerful,
well, that's a lot of the plot here. Vernon sticks to the rules of the
game: Mona can only affect bread and dough and maybe icing in tiny ways if
she tries very hard (but it gives her a headache). But there are a lot of
creative ways that one can use dough and cookies, particularly once you
get some help.
The other interesting and unusual thing about this book is its attitude
towards authorities and heroism. Authorities who try to do good and
authorities who are evil and corrupt are both common in fantasy.
Authorities who let themselves get caught up in a tangle of small
decisions and minor fears until they become ineffective are not quite as
common, and usually fantasy dispenses with that sort of power by calling
it weak and inviting the heroes to take over. This book does not go in
that direction at all. It's startling and thought-provoking to see a
fantasy novel treat Mona's elevation into unwanted heroism as an
indefensible societal failure that is not excused by gratitude. This more
than any other story element made this feel like a 2020 book.
I won't spoil the ending, but it caught me by surprise, was extremely
moving, and further broadens that questioning of what heroism is and why
we celebrate it.
This is not a book full of complex plotting or moral ambiguity. The
villain is awful, the threat he provokes is rather thoroughly dehumanized,
and the plot is a reasonably straightforward sequence of events. One
reads this book for Mona's flustered first-person voice, Vernon's humor
and no-nonsense morality, and the creative exploration of the limits of
what one can do with bread magic and a seriously irritated sourdough
starter. And the thoughtfulness about heroism, and the recognition that
heroism comes with an impact that the rest of society doesn't want to
think about.
To be clear, that thoughtfulness doesn't go beyond questioning here. This
is still a heroism book. But it made me want to read the fantasy novel in
which people work collectively to remake a society so that it won't need
to have heroes again.
I think whether you like Vernon's previous Kingfisher books, particularly
the more young adult ones, will strongly predict whether you like A
Wizard's Guide to Defensive Baking. If you like her protagonists,
recommended.
Rating: 7 out of 10
Reviving Very Old X Code
I've taken the week between Christmas and New Year's off this year. I
didn't really have anything serious planned, just taking a break from
the usual routine. As often happens, I got sucked into doing a project
when I received this simple bug report
Debian Bug #974011
I have been researching old terminal and X games recently, and realized
that much of the code from 'xmille' originated from the terminal game
'mille', which is part of bsdgames.
...
[The copyright and license information] has been stripped out of all
code in the xmille distribution.  Also, none of the included materials
give credit to the original author, Ken Arnold.
The reason the 'xmille' source is missing copyright and license
information from the 'mille' files is that they were copied in
before that information was added upstream. Xmille forked from Mille
around 1987 or so. I wrote the UI parts for the system I had at the
time, which was running X10R4. A very basic port to X11 was done at
some point, and that's what Debian has in the archive today.
At some point in the 90s, I ported Xmille to the
Athena widget set,
including several custom widgets in an Xaw extension library,
Xkw. It's a lot better than the version in Debian, including displaying the
cards correctly (the Debian version has some pretty bad color issues).
Here's what the current Debian version looks like:
Fixing The Bug
To fix the missing copyright and license information, I imported the
mille source code into the "latest" Xaw-based version. The updated
mille code had a number of bug fixes and improvements, along with the
copyright information.
That should have been sufficient to resolve the issue and I could have
constructed a suitable source package from whatever bits were needed
and and uploaded that as a replacement 'xmille' package.
However, at some later point, I had actually merged xmille into a
larger package, 'kgames', which also included a number of other
games, including Reversi, Dominoes, Cribbage and ten Solitaire/Patience
variants. (as an aside, those last ten games formed the basis for my
Patience Palm Pilot application, which seems to have inspired an
Android App of the same name...)
So began my
yak shaving holiday.
Building Kgames in 2020
Ok, so getting this old source code running should be easy, right?
It's just a bunch of C code designed in the 80s and 90s to work on
VAXen and their kin. How hard could it be?
Everything was a 32-bit computer back then; pointers and ints were
both 32 bits, so you could cast them with wild abandon and cause
no problems. Today, testing revealed segfaults in some corners of
the code.
It's K&R C code. Remember that the first version of ANSI-C didn't
come out until 1989, and it was years later that we could reliably
expect to find an ANSI compiler with a random Unix box.
It's X11 code. Fortunately (?), X11 hasn't changed since these
applications were written, so at least that part still works just
fine. Imagine trying to build Windows or Mac OS code from the early
90's on a modern OS...
I decided to dig in and add prototypes everywhere; that found a lot of
pointer/int casting issues, as well as several lurking bugs where the
code was just plain broken.
After a day or so, I had things building and running and was no
longer hitting crashes.
Kgames 1.0 uploaded to Debian New Queue
With that done, I decided I could at least upload the working bits to
the Debian archive and close the bug reported above.
kgames 1.0-2
may eventually get into unstable, presumably once the Debian
FTP team realizes just how important fixing this bug is. Or something.
Here's what xmille looks like in this version:
And here's my favorite solitaire variant too:
But They Look So Old
Yeah, Xaw applications have a rustic appearance which may appeal to
some, but for people with higher resolution monitors and well
seasoned eyesight, squinting at the tiny images and text makes it
difficult to enjoy these games today.
How hard could it be to update them to use larger cards and scalable
fonts?
Xkw version 2.0
I decided to dig in and start hacking the code, starting by adding new
widgets to the Xkw library that used cairo for drawing instead of core
X calls. Fortunately, the needs of the games were pretty limited, so I
only needed to implement a handful of widgets:
KLabel. Shows a text string. It allows the string to be left,
center or right justified. And that's about it.
KCommand. A push button, which uses KLabel for the underlying
presentation.
KToggle. A push-on/push-off button, which uses KCommand for most of
the implementation. Also supports 'radio groups' where pushing one
on makes the others in the group turn off.
KMenuButton. A button for bringing up a menu widget; this is some
pretty simple behavior built on top of KCommand.
KSimpleMenu, KSmeBSB, KSmeLine. These three create pop-up menus;
KSimpleMenu creates a container which can hold any number of
KSmeBSB (string) and KSmeLine (separator lines) objects).
KTextLine. A single line text entry widget.
The other Xkw widgets all got their rendering switched to using cairo,
plus using double buffering to make updates look better.
SVG Playing Cards
Looking on wikimedia,
I found a
page referencing a large number of playing cards in SVG form
That led me to Adrian Kennard's playing card web site
that let me customize and download a deck of cards,
licensed using the
CC0 Public Domain license.
With these cards, I set about rewriting the Xkw playing card widget,
stripping out three different versions of bitmap playing cards and
replacing them with just these new SVG versions.
SVG Xmille Cards
Ok, so getting regular playing cards was good, but the original goal
was to update Xmille, and that has cards hand drawn by me. I could
just use those images, import them into cairo and let it scale them to
suit on the screen. I decided to experiment with
inkscape's bitmap tracing code to see what it
could do with them.
First, I had to get them into a format that inkscape could parse. That
turned out to be a bit tricky; the original format is as a set of X
bitmap layers; each layer painting a single color. I ended up hacking
the Xmille source code to generate the images using X, then fetching
them with XGetImage and walking them to construct XPM format files
which could then be fed into the portable bitmap tools to create PNG
files that inkscape could handle.
The resulting images have a certain charm:
I did replace the text in the images to make it readable, otherwise
these are untouched from what inkscape generated.
The Results
Remember that all of these are applications built using the venerable
X toolkit; there are still some non-antialiased graphics visible as
the shaped buttons use the X Shape extension. But, all rendering is
now done with cairo, so it's all anti-aliased and all scalable.
Here's what Xmille looks like after the upgrades:
And here's spider:
Once kgames 1.0 reaches Debian unstable, I'll upload these new
versions.
Here is my monthly update covering what I have been doing in the free software world during December 2020 (previous month):
Reviewed and merged a contribution from Peter Law to my django-cache-toolbox library for Django-based web applications, including explicitly requiring that cached relations are primary keys (#23) and improving the example in the README (#25).
I took part in an interview with Vladimir Bejdo, an intern at the Software Freedom Conservancy, in order to talk about the Reproducible Builds project, my participation in software freedom, the importance of reproducibility in software development, and to have a brief discussion on the issues facing free software as a whole. The full interview can be found on Conservancy's webpages.
As part of my duties of being on the board of directors of the Open Source Initiative, I attended its monthly meeting and participated in various licensing and other related discussions occurring on the internet. Unfortunately, I could not attend the parallel meeting for Software in the Public Interest this month.
Reproducible Builds
One of the original promises of open source software is that distributed peer review and transparency of process results in enhanced end-user security. However, whilst anyone may inspect the source code of free and open source software for malicious flaws, almost all software today is distributed as pre-compiled binaries. This allows nefarious third-parties to compromise systems by injecting malicious code into ostensibly secure software during the various compilation and distribution processes.
The motivation behind the Reproducible Builds effort is to ensure no flaws have been introduced during this compilation process by promising identical results are always generated from a given source, thus allowing multiple third-parties to come to a consensus on whether a build was compromised.
This month, I:
Submitted a draft academic paper to IEEE Software. The article (co-written by Stefano Zacchiroli) is aimed a fairly general audience. It first defines the overal problem and then provides insight into the challenges of actually making real-world software reproducible. It then outlines the experiences of the Reproducible Builds project in making large-scale software collections/supply-chains/ecosystems reproducible and concludes by describing the affinity between reproducibility efforts and quality assurance.
Categorised a huge number of packages and issues in the Reproducible Builds 'notes' repository.
For disorderfs (our FUSE-based filesystem that deliberately introduces non-determinism into directory system calls in order to flush out reproducibility issues), I made the following changes:
I also made a large number of changes to the main Reproducible Builds website and documentation, including applying a typo fix from Roland Clobus [...], fixed the draft detection logic (#28), added more academic articles to our list [...] and corrected a number of grammar issues [...][...].
I also made the following changes to diffoscope, our in-depth and content-aware diff utility that can locate and diagnose reproducibility issues, including releasing version 163:
New features & bug fixes:
Normalise ret to retq in objdump output in order to support multiple versions of GNU binutils. (#976760)
Don't show any progress indicators when running zstd. (#226)
Correct the grammatical tense in the --debug log output. [...]
Codebase improvements:
Update the debian/copyright file to match the copyright notices in the source tree. (#224)
Update various years across the codebase in .py copyright headers. [...]
Rewrite the filter routine that post-processes the output from readelf(1). [...]
Remove unnecessary PEP 263 encoding header lines; unnecessary after PEP 3120. [...]
Use minimal instead of basic as a variable name to match the underlying package name. [...]
I also sponsored an upload of adminer (4.7.8-2) on behalf of Alexandre Rossi and performed two QA uploads of sendfile (2.1b.20080616-7 and 2.1b.20080616-8) to make the build the build reproducible (#776938) and to fix a number of other unrelated issues.
Debian LTS
This month I have worked 18 hours on Debian Long Term Support (LTS) and 12 hours on its sister Extended LTS project.
Frontdesk duties, responding to user/developer questions, reviewing others' packages, participating in mailing list discussions, etc.
Issued DLA 2477-1 for the Jupyter Notebook interactive notebook system, where a maliciously-crafted link could redirect the browser to a malicious/spoofed website. (CVE-2020-26215)
Issued DLA 2503-1 as it was discovered that there was an issue in node-ini, an .ini configuration file format parser/serialiser for Node.js, where an application could be exploited by a malicious input file.
You can find out more about the Debian LTS project via the following video:
Formal sector issues
Just today it was published that output from eight formal sectors of the economy who make the bulk of the Indian economy were down on a month to month basis . This means all those apologists for the Government who said that it was ok that the Govt. didn t give the 20 lakh crore package which was announced. In fact, a businessman from my own city, a certain Prafull Sarda had asked via RTI what happened to the 20 lakh crore package which was announced? The answers were in all media as well as newspapers but on the inside pages. You can see one of the article sharing the details here. No wonder Vivek Kaul also shared his take on the way things will hopefully go for the next quarter which seems to be a tad optimistic from where we are atm.
Eight Sectors declining in Indian Economy month-on-month CNBC TV 18The Informal economy
The informal economy has been strangulated by the current party in power since it came into power. And this has resulted many small businesses which informal are and were part of culture of cities and towns. I share an article from 2018 which only shows how good and on the mark it has aged in the last two years. The damage is all to real to ignore as I would share more of an anecdotes and experiences because sadly there never has been any interest shown especially by GOI to seek any stats. about informal economy. Although CMIE has done some good work in that even though they majorly look at formal, usually blue-collar work where again there is not good data. Sharing an anecdote and a learning from these small businesses which probably an MBA guy wouldn t know and in all honesty wouldn t even care.
Khau galli
Few years back, circa 2014 and on wards, when the present Govt. came into power, it did come with lot of promises. One of which was that lot of informal businesses would be encouraged to grow their businesses and in time hopefully, they become part of the formal economy. Or at least that was the story that all of us were told. Due to that they did lot of promises and also named quite a few places where street food was in abundance. Such lanes were named Khau galli for those who are from North India, it was be easily known and understood. This was just saying that here are some places where you could get a variety of food without paying obscene prices as you would have to vis-a-vis a restaurant. Slowly, they raised the rates of inputs (food grains), gas cylinder etc. which we know of as food inflation and via GST made sure that the restaurants were able to absorb some of the increased inputs (input credit) while still being more than competitive to the street food person/s. The restaurant F&B model is pretty well known so not going there at all. It is however, important to point out that they didn t make any new khau gallis or such, most or all the places existed for years and even decades before that. They also didn t take any extra effort either in marketing the khau gallis or get them with chefs or marketing folks so that the traditional can marry to the anew. They just named them, that was the only gain to be seen on the ground.
In its heyday, the khau galli near my home used to have anywhere between 20-30 Thelas or food carts. Most of the food carts would be of wood and having very limited steel. Such food carts would cost anywhere around INR 15-20k instead of the food cart you see here. The only reason I shared that link is to show how a somewhat typical thela or food cart looks in India. Of course YouTube or any other media platform would show many. On top of it, you need and needed permission from the municipality a license for the same which would be auctioned. Now that license could well run from thousands into lakhs depending on various factors or you gave something to the Municipal worker when he did his rounds/beat much like a constable every day or week. Apart from those, you also have raw material expenditure which could easily run into few thousands depending upon what sort of food you are vending. You also would typically have 2-3 workers so a typical Thela would feed not only its customers but also 2-3 families who are the laborer families as well as surrounding businesses.
As I used to be loyal and usually go to few whom I found to be either tasty or somehow they were good for me. In either case, a relationship was formed. As I have been never fond of crowds, I usually used to in their off-beat hours either when they are close to packing up of when I know they usually have a lull. That way I knew I would get complete attention of the vendor/s. Many a times I used to see money change hands between the vendors themselves and used to see both camaraderie as well as competition between them. This is years ago, once while sharing a chai (tea) with one of the street vendors I casually asked I have often seen you guys exchanging money with each other and most of the time quite a bit of the money is also given to the guy who didn t make that much sales or any sales at all.
The vendor replied sharing practical symbiotic knowledge. All of us are bound by a single thing called poverty. All of us are struggle. Do you know why so many people come here, because they know that there would be a variety of food to be had. Now if we stopped helping each other, the number of people who would make the effort would be also less, we know we are not the only game in town. Also whatever we give, sooner or later it gets adjusted. Also if one of us has good days, he knows hardship days are not far. Why, simply because people change tastes or want variety. So irrespective of good or bad the skills of the vendor is, she or he is bound to make some sales. The vendor either shares the food with us or whatever. Somehow these things just work out. And that doesn t mean we don t have our fights, we do have our fights, but we also understand this. Now you see this and you understand that these guys have and had a community. Even if they changed places due to one reason or the other, they kept themselves connected. Unlike many of us, who even find a hard time keeping up with friends let alone relatives.
Now cut to 2020, and where there used to be 20-30 thelas near my home, there are only 4-5. Of course, multiple reasons, but one of the biggest was of course demonetization. That was a huge shock to which many of thela walas succumbed. Their entire savings and capital were turned to dust. Many of their customers will turn up with either a INR 500 or INR 2000/- Re note where at the most a dish costed INR 100/- most times half or even 1/3rd of that amount. How and from where the thela walas could get that kind of cash. These are people who only if they earn, they and their family will have bread at night. Most of the loose change was tied up at middle to higher tier restaurants where they were giving between INR 20/- 30/- for every INR 100/- change of rupees and coins. Quite a few bankers made money by that as well as other means where the thela walas just could not compete. These guys also didn t have any black money even though they were and are part of the black/informal economy. Sadly, till date no economist or even sociologist as far as I know has attempted or done any work from what I know on this industry. If you want to formalize such businesses then at the very least understand their problems and devise solutions. And I suspect, what is and has happened near my house has also happened everywhere else, at least within the geographical confines of the Indian state. Whether it was the 2016 demonetization or the pandemic, the results and effects have been similar the same all over. Some states did do well and still do, the suffering still continues.
With the hope that the new year brings cheer to you as well some more ideas to remain in business by the thela walas, I bid you adieu and see you in new year
On doing 540 no-source-change source-only uploads in two weeks
So I've been doing 540 no-source-change source-only uploads in the last two weeks
and am planning to do 3000 more in January 2021. We'll see how that goes
Let me explain what I have been doing and why.
So, starting
with the Bullseye release cycle the Release Team changed policy: only packages which were
build on buildds are allowed to migrate to testing.
Which is pretty nice for reproducible builds
as this also ensures that a .buildinfo file is available for anyone wanting to reproduce the
binaries of that package.
However, there are many binary (and source) packages in Debian which were
uploaded before 2016 (which is when .buildinfo files were introduced) or
were uploaded with binaries until that change in release policy July 2019.
Then Ivo De Decker scheduled binNMUs for all the affected packages but due
to the way binNMUs work, he couldn't do anything about arch:all packages
as they currently cannot be rebuilt with binNMUs.
Ivo and myself discussed what could be done about the remaining packages
and (besides long complicated changes to Debian's workflows) the only thing
deemed possible was doing many many source uploads with just a new changelog
entry:
  * Non maintainer upload by the Reproducible Builds team.
  * No source change upload to rebuild on buildd with .buildinfo files.
These packages are all inherently buggy, because Debian policy mandates that
packages should be reproducible and without .buildinfo files one cannot
reproducibly rebuild packages. So instead of filing many many bugs we've decided
to just fix these bugs by doing a no-source-change source uploads. One nice
aspect of these uploads is that there's no follow-up work imposed on the
maintainer: whether they keep that changelog entry or whether they discard it,
it does not matter.
So Ivo had developed an SQL query which showed 570 packages needing an update
roughly two weeks ago, on December 18 and so I started slowly. This is the amount
of NMUs I did in the last days:
for i in $(seq 18 30) ; do echo -n "Dec $i: " ; ls -lart1 done/*upload grep -c "Dec $i" ; done
Dec 18: 12
Dec 19: 0
Dec 20: 3
Dec 21: 13
Dec 22: 13
Dec 23: 16
Dec 24: 4
Dec 25: 28
Dec 26: 0
Dec 27: 38
Dec 28: 198
Dec 29: 206
Dec 30: 9
About ten packages had FTBFS bugs preventing an upload and seven packages
were uploaded by the maintainer before me. I've seen two cases of sudden
maintainer uploads after 8 and 10 years of no activity!
So what did I do for each upload?
pre upload work:
test build with pbuilder in sid
check PTS for last upload date (and having arch:all binaries) and open RC bugs
modify d/changelog
check debdiff between two sources (should be only the changelog entry!)
upload
(some times filing bugs or modifying bug meta data etc)
post upload:
check PTS for testing migration, so for this I've had >500 browser tabs open and I'll keep each of them open until the packages migrates...
Much to my surprise I didn't get much feedback, there were like 6 people
on the #debian-reproducible channel cheering and one on #debian-qa,
though that person is a Release Team member so that was kind of important
cheering. And I've seen some maintainer uploads to packages which haven't
seen uploads since some years. And really nice: no-one complained so far.
I hope this will stay this way with the plan to do 3000 more uploads of this kind:
Those 570 packages were only key packages but there are 3000 more source packages
which have a binary in bullseye for which no .buildinfo file
exists. So I plan to upload them all in January 2021 and you can
help me doing so, by uploading your packages before me - and maybe fixing
some other bugs in the process!
I've posted the list of packages (sorted by ddlist) to debian-devel@lists.d.o,
see https://lists.debian.org/debian-devel/2020/12/msg00419.html.
Many thanks to Ivo and the whole Release Team for their support of Reproducible
Builds and generally speaking for the many many enhancements to the release
process we've seen over the years. Debian in 2021 will rock'n'roll more than ever!
So thank you all, once again, for making Debian what it is and what it will be!
dkg's 2021 OpenPGP transition
As 2021 begins, I'm changing to a new OpenPGP certificate.
I did a similar transition two years ago, and a fair amount has changed since then.
You might know my old OpenPGP certificate as:
You can find a signed transition statement if you're into that sort of thing.
If you're interested in the rationale for why I'm making this transition, read on.
Dangers of Offline Primary Secret Keys
There are several reasons for transitioning, but one i simply couldn't argue with was my own technical failure.
I put the primary secret key into offline storage some time ago for "safety", and used ext4's filesystem-level encryption layered on top of dm-crypt for additional security.
But either the tools changed out from under me, or there were failures on the storage medium, or I've failed to remember my passphrase correctly, because I am unable to regain access to the cleartext of the secret key.
In particular, I find myself unable to use e4crypt add_key with the passphrase I know to get a usable working directory.
I confess I still find e4crypt pretty difficult to use and I don't use it often, so the problem may entirely be user error (either now, or two years ago when I did the initial setup).
Anyway, lesson learned: don't use cryptosystems that you're not comfortable with to encrypt data that you care about recovering.
This is a lesson I'm pretty sure I've learned before, sigh, but it's a good reminder.
Split User IDs
I'm trying to split out my User IDs again -- this way if you know me by e-mail address, you don't have to think/worry about certifying my name, and if you know me by name, you don't have to think/worry about certifying my e-mail address.
I think that's simpler and more sensible.
It's also nice because e-mail address-only User IDs can be used effectively in contexts like Autocrypt, which I think are increasingly important if we want to have usable encrypted e-mail.
Last time around I initially tried split User IDs but rolled them back and I think most of the bugs I discovered then have been fixed.
Certificate Flooding
Another reason for making a transition to a new certificate is that my older certificate is one of the ones that was "flooded" on the SKS keyserver network last year, which was one of the final straws for that teetering project.
Transitioning to a new certificate lets that old flooded cert expire and people can just simply move on from it, ideally deleting it from their local keyrings.
Hopefully as a community we can move on from SKS to key distribution mechanisms like WKD, Autocrypt, DANE, and keys.openpgp.org, all of which address some of the known problems with keyserver abuse.
Trying New Tools
Finally, I'm also interested in thinking about how key and certificate management might be handled in different ways.
While I'm reasonably competent in handling GnuPG, the larger OpenPGP community (which I'm a part of) has done a lot of thinking and a lot of work about how people can use OpenPGP.
I'm particularly happy with the collaborative work that has gone into the Stateless OpenPGP CLI (aka sop), which helps to generate a powerful interoperability test suite.
While sop doesn't offer the level of certificate management I'd need to use it to manage this new certificate in full, I wish something like it would!
Starting from a fresh certificate and actually using it helps me to think through what I might actually need from a tool that is roughly as straightforward and opinionated as sop is.
If you're a software developer who might use or implement OpenPGP, or a protocol designer, and you haven't played around with anyofthevariousimplementationsofsop yet, I recommend taking a look.
And feedback on the specification is always welcome, too, including ideas for new functionality (maybe even like certificate management).
Next Steps
If you're the kind of person who's into making OpenPGP certifications, feel free to check in with me via whatever channels you're used to using to verify that this transition is legit.
If you think it is, and you're comfortable, please send me (e-mail is probably best) your certifications over the new certficate.
I'll keep on working to make OpenPGP more usable and acceptable.
Hopefully, 2021 will be a better year ahead for all of us.
WeWork was founded in 2010 by Adam Neumann and Miguel McKelvey as a
successor company to their similar 2008 GreenDesk business. (Adam's wife
Rebekah is now presented as a co-founder. This seems dubious in
Wiedeman's account, although Rebekah's role in the company is murky,
ever-changing, and hard to pin down.) Its business model in reality was
to provide turn-key, pre-furnished and stocked co-working and small office
space to individuals and businesses on flexible, short-term leases. Its
business model in Neumann's speeches and dreams, and represented by the
later renaming of the company to the We Corporation, was nothing less than
to transform the way people worked, learned, and lived.
Through aggressive, money-losing expansion, WeWork grew rapidly to over
500 locations in 29 countries and became the largest office tenant in New
York City. Based primarily on massive financial support from Masayoshi
Son, CEO of Japanese holding company SoftBank, WeWork's private valuation
rose to $47 billion. In 2019, the company attempted to go public, but its
IPO collapsed, in part due to deeper analysis of the company's books.
Neumann was forced out of the company (with an individual payout valued at
$1.7 billion), the IPO was withdrawn, SoftBank wrote down 90% of their
investment in the company and took control of it, and WeWork laid off more
than 20% of its workforce.
This book is a detailed history of WeWork's rise and fall, joining a genre
that includes The Smartest Guys in the
Room (Enron), Bad Blood (Theranos),
and Super Pumped (Uber). I believe it's
the first full book on WeWork, although it was preceded by several
long-form stories, including
"The
I In We" by Wiedeman for New York magazine. As the first history,
it's a somewhat incomplete cut: litigation between Neumann and WeWork is
still pending, WeWork staggered into 2020 and a world-wide pandemic that
made cramped open-plan offices an epidemiological disaster, and there will
doubtless be new revelations yet to come. The discovery process of
lawsuits tends to be good for journalists. But despite being the first
out of the gate, Billion Dollar Loser reaches a satisfying
conclusion with the ouster of Neumann, who had defined WeWork both
internally and externally.
I'm fascinated by stories of failed venture capital start-ups in general,
but the specific question about WeWork that interested me, and to which
Wiedeman provides a partial answer, is why so many people gave Neumann
money in the first place. Explaining that question requires a digression
into why I thought WeWork's valuation was absurd.
The basic problem WeWork had when justifying its sky-high valuation is
competition. WeWork didn't own real estate; it rented properties from
landlords with long-term leases and then re-rented them with short-term
leases. If its business was so successful, why wouldn't the landlords cut
out the middle man, do what WeWork was doing directly, and pocket all the
profit? Or why wouldn't some other company simply copy WeWork and drive
the profit margins down? Normally with startups the answer revolves
around something proprietary: an app, a server technology, patents, a
secret manufacturing technique, etc. But nothing WeWork was doing was
different from what innumerable tech companies and partner landlords had
been doing with their office space for a decade, and none of it was
secret.
There are two decent answers to that question. One is simple outsourcing:
landlords like being passive rent collectors, so an opportunity to pay
someone else to do the market research on office layouts, arrange all the
remodeling, adapt to changing desires for how office space should be
equipped and stocked, advertise for short-term tenants, and deal with the
tenant churn is attractive. The landlord can sit back and pocket the
stable long-term rent.
The second answer is related: WeWork is essentially doing rental arbitrage
between long-term and short-term rents and thus is taking on most of the
risk of a commercial real estate downturn. If no one is renting office
space, WeWork is still on the hook for the long-term rent. The landlord
is outsourcing risk, at least unless WeWork goes bankrupt. (One
infuriating tidbit from this book is that Neumann's explicit and
often-stated goal was to make WeWork so large that its bankruptcy would be
sufficiently devastating to the real estate industry that it would get a
bailout.)
There's a legitimate business here. But that business looks like a
quietly profitable real estate company that builds very efficient systems
for managing short-term leases, remodeling buildings, and handling the
supply chain of stocking an office. That looks nothing like WeWork's
business, has nothing to do with transforming the world of work, and
certainly doesn't warrant sky-high valuations. WeWork didn't build an
efficient anything. It relied on weekend labor from underpaid employees
and an IT person who was still in high school. And WeWork actively
resisted being called a real estate company and claimed it was a tech
company or a lifestyle company on the basis of essentially nothing.
Wiedeman seems almost as baffled by this as I am, but it's clear from the
history he tells that part of the funding answer is the Ponzi scheme of
start-up investing. People gave Neumann money because other people had
previously given Neumann money, and the earlier investors cashed out at
the expense of the later ones. Like any Ponzi scheme, it looks like a
great investment until it doesn't, and then the last sucker is left
holding the bag. That sucker was Masayoshi Son, who in Wiedeman's telling
is an astonishingly casual and undisciplined investor who trusted
knee-jerk personal reactions to founders over business model analysis and
historically (mostly) got away with it by getting extremely lucky.
(I now want to read one of these books about SoftBank, since both this
book and Super Pumped make it look like a company that makes
numerous wild gambles for the flimsiest of reasons, pushes for completely
unsustainable growth, and relies on the sheer volume of investments
catching some lucky jackpots and cashing out in IPOs. Unfortunately, the
only book currently available seems to be a fawning hagiography of Son.)
On one hand, the IPO process worked properly this time. The sheer madness
of WeWork's valuation scared off enough institutional investors that it
collapsed. On the other hand, it's startling how close it came to
success. If WeWork had kept the Ponzi scheme going a bit longer, the last
sucker could have been the general investing public.
Another interesting question that Billion Dollar Loser answers is
how Neumann got enough money to start his rapid growth strategy. The
answer appears to be the oldest and most obvious explanation: He made
friends with rich people. The initial connections appear to have been
through his sister, Adi Neumann, who is a model and hosted parties in her
New York apartment (and also started dating a Rothschild heir). Adam met
his wealthy wife Rebekah, cousin to actress and "wellness" scam marketer
Gwyneth Paltrow, via a connection at a party. He built social connections
with other parts of the New York real estate scene and tapped them for
investment money.
The strong impression one gets from the book is that all of these people
have way more money than sense and we should raise their taxes. It won't
come as a surprise that Adam and Rebekah Neumann are good friends of Jared
Kushner and Ivanka Trump.
Those are the questions I was the most curious about, but there's much
more here. Wiedeman's style is nearly straight chronological reporting
with little analysis, but the story is so wild and absurd that it doesn't
need much embellishment. Neumann is obviously a megalomaniac whose
delusions of grandeur got worse and worse as WeWork was apparently
succeeding. Rebekah Neumann is if anything even less in touch with
reality than he is, although in her case that appears to stem from having
so much money that reality is an inconvenient speed bump. Miguel
McKelvey, Neumann's co-founder, is an odd and interesting side note to the
story; he appears to have balanced Adam out a bit in the early going but
then wisely started to cash out and pocket his winnings while letting Adam
dominate the stage.
There are some places where I don't think Wiedeman pushed hard enough, and
which cut against the view of Neumann as a true believer in his impossible
growth vision. Neumann took several investment opportunities to cash out
large amounts of his stock even while WeWork employees were being
underpaid and told their stock options would make up for it. He clearly
used WeWork as a personal piggy bank on multiple occasions. And Wiedeman
documents but doesn't, at least in my opinion, make nearly enough of
Neumann's self-dealing: buying real estate that WeWork then rented as a
tenant, or paying himself for a license for the name We Holdings (although
there at least he later returned the money). I think a good argument
could be made that Neumann was embezzling from WeWork, at least morally if
not legally, and I wish Wiedeman would have pressed harder on that point.
But that aside, this is a great first history of the company, told in a
clean, readable, and engaging style, and with a lot more detail here than
I've touched on (such as Rebekah Neumann's WeGrow school). It's not as
good as Bad Blood (what is), but it's a respectable entry in the
corporate collapse genre. If you like this sort of thing, recommended.
Rating: 7 out of 10
I ve just made my blog available on the Fediverse, at least partially.
Yesterday while browsing Hacker News, I saw Carl Schwan s post Adding comments to your static blog with Mastodon(m) about him replacing Disqus with replies posted at Mastodon. Just on Monday I was thinking, why can t blogs participate in Fediverse? I tried to use WriteFreely as a replacement for Pelican, only to find it very limited, so I thought I might write a gateway to expose the Atom feed using ActivityPub. Turns out, someone already did that: Bridgy, a service connecting websites to Twitter, Mastodon and other social media, also has a Fediverse counterpart, Fed.brid.gy just what I was looking for!
I won t go deeply into the details, but just outline issues I had to deal with:
Bridgy relies on microformats. While I had some microformats and Schema.org microdata already at both blog and the homepage, they were not sufficiently good for Bridgy to use.
I ran into an issue with Mastodon being more picky about signatures which the author Ryan Barrett promptly fixed.
The end result is not fully working yet, since posts don t appear yet, but I can be found and followed as @shadura.me@shadura.me.
As a bonus I enabled IndieAuth at my website, so I can log into compatible services with just the URL of my website.
In my previous articles in the series on asynchronous communication with the modern NNCP tool, I talked about its use for asynchronous, potentially airgapped, backups. The first article, How & Why To Use Airgapped Backups laid out the foundations for this. Now let s dig into the details.
Today s post will cover ZFS, because it has a lot of features that make it very easy to support in this setup. Non-ZFS backups will be covered later.
The setup is actually about as simple as it is for SSH, but since people are less familiar with this kind of communication, I m going to try to go into more detail here.
Assumptions
I am assuming a setup where:
The machines being backed up run ZFS
The disk(s) that hold the backups are also running ZFS
zfs send / receive is desired as an efficient way to transport the backups
The machine that holds the backups may have no network connection whatsoever
Backups will be sent encrypted over some sort of network to a spooling machine, which temporarily holds them until they are transported to the destination backup system and ingested there. This system will be unable to decrypt the data streams it temporarily stores.
Hardware
Let s start with hardware for the machine to hold the backups. I initially considered a Raspberry Pi 4 with 8GB of RAM. That would probably have been a suitable machine, at least for smaller backup sets. However, none of the Raspberry Pi machines support hardware AES encryption acceleration, and my Pi4 benchmarks as about 60MB/s for AES encryption. I want my backups to be encrypted, and decided this would just be too slow for my purposes. Again, if you don t need encrypted backups or don t care that much about performance may people probably fall into this category you can have a fully-functional Raspberry Pi 4 system for under $100 that would make a fantastic backup server.
I wound up purchasing a Qotom-Q355G4 micro PC with a Core i5 for about $315. It has USB 3 ports and is designed as a rugged, long-lasting system. I have been using one of their older Celeron-based models as my router/firewall for a number of years now and it s been quite reliable.
For backup storage, you can get a USB 3 external drive. My own preference is to get a USB 3 toaster (device that lets me plug in SATA drives) so that I have more control over the underlying medium and can save the expense and hassle of a bunch of power supplies. In a future post, I will discuss drive rotation so you always have an offline drive.
Then, there is the question of transport to the backup machine. A simple solution would be to have a heavily-firewalled backup system that has no incoming ports open but makes occasional outgoing connections to one specific NNCP daemon on the spooling machine. However, for airgapped operation, it would also be very simple to use nncp-xfer to transport the data across on a USB stick or some such. You could set up automounting for a specific USB stick plug it in, all the spooled data is moved over, then plug it in to the backup system and it s processed, and any outbound email traffic or whatever is copied to the USB stick at that point too. The NNCP page has some more commentary about this kind of setup.
Both are fairly easy to set up, and NNCP is designed to be transport-agnostic, so in this article I m going to focus on how to integrate ZFS with NNCP.
Operating System
Of course, it should be no surprise that I set this up on Debian.
As an added step, I did all the configuration in Ansible stored in a local git repo. This adds a lot of work, but it means that it is trivial to periodically wipe and reinstall if any security issue is suspected. The git repo can be copied off to another system for storage and takes the system from freshly-installed to ready-to-use state.
Security
There is, of course, nothing preventing you from running NNCP as root. The zfs commands, obviously, need to be run as root. However, from a privilege separation standpoint, I have chosen to run everything relating to NNCP as a nncp user. NNCP already does encryption, but if you prefer to have zero knowledge of the data even to NNCP, it s trivial to add gpg to the pipeline as well, and in fact I ll be demonstrating that in a future post for other reasons.
Software
Besides NNCP, there needs to be a system that generates the zfs send streams. For this project, I looked at quite a few. Most were designed to inspect the list of snapshots on a remote end, compare it to a list on the local end, and calculate a difference from there. This, of course, won t work for this situation.
I realized my own simplesnap project was very close to being able to do this. It already used an algorithm of using specially-named snapshots on the machine being backed up, so never needed any communication about what snapshots were present where. All it needed was a few more options to permit sending to a stream instead of zfs receive. I made those changes and they are available in simplesnap 2.0.0 or above. That version has also been uploaded to sid, and will work fine as-is on buster as well.
Preparing NNCP
I m going to assume three hosts in this setup:
laptop is the machine being backed up. Of course, you may have quite a few of these.
spooler holds the backup data until the backup system picks it up
backupsvr holds the backups
The basic NNCP workflow documentation covers the basic steps. You ll need to run nncp-cfgnew on each machine. This generates a basic configuration, along with public and private keys for that machine. You ll copy the public key sets to the configurations of the other machines as usual. On the laptop, you ll add a via line like this:
This tells NNCP that data destined for backupsvr should always be sent via spooler first.
You can then arrange for the nncp-daemon to run on the spooler, and nncp-caller or nncp-call on the backupsvr. Or, alternatively, airgapped between the two with nncp-xfer.
Generating Backup Data
Now, on the laptop, install simplesnap (2.0.0 or above). Although you won t be backing up to the local system, simplesnap still maintains a hostlock in ZFS. Prepate a dataset for it:
zfs create tank/simplesnap
zfs set org.complete.simplesnap:exclude=on tank/simplesnap
Then, create a script /usr/local/bin/runsimplesnap like this:
#!/bin/bash
set -e
simplesnap --store tank/simplesnap --setname backups --local --host  hostname  \
   --receivecmd /usr/local/bin/simplesnap-queue \
   --noreap
su nncp -c '/usr/local/nncp/bin/nncp-toss -noprogress -quiet'
if ip addr   grep -q 192.168.65.64; then
  su nncp -c '/usr/local/nncp/bin/nncp-call -noprogress -quiet -onlinedeadline 1 spooler'
fi
The call to simplesnap sets it up to send the data to simplesnap-queue, which we ll create in a moment. The receivmd, plus noreap, sets it up to run without ZFS on the local system.
The call to nncp-toss will process any previously-received inbound NNCP packets, if there are any. Then, in this example, we do a very basic check to see if we re on the LAN (checking 192.168.65.64), and if so, will establish a connection to the spooler to transmit the data. If course, you could also do this over the Internet, with tor, or whatever, but in my case, I don t want to automatically do this in case I m tethered to mobile. I figure if I want to send backups in that case, I can fire up nncp-call myself. You can also use nncp-caller to set up automated connections on other schedules; there are a lot of options.
Now, here s what /usr/local/bin/simplesnap-queue looks like:
#!/bin/bash
set -e
set -o pipefail
DEST=" echo $1   sed 's,^tank/simplesnap/,,' "
echo "Processing $DEST" >&2
# stdin piped to this
su nncp -c "/usr/local/nncp/bin/nncp-exec -nice B -noprogress backupsvr zfsreceive '$DEST'" >&2
echo "Queued for $DEST" >&2
This is a pretty simple script. simplesnap will call it with a path based on the store, with the hostname after; so, for instance, tank/simplesnap/laptop/root or some such. This script strips off the leading tank/simplesnap (which is a local fragment), leaving the host and dataset paths. Then it just pipes it to nncp-exec. -nice B classifies it as low-priority bulk data (so if you have some more important interactive data, it would be sent first), then passes it to whatever the backupsvr defines as zfsreceive.
Receiving ZFS backups
In the NNCP configuration on the recipient s side, in the laptop section, we define what command it s allowed to run as zfsreceive:
The NNCP_SENDER is the public key ID of the sending node when nncp-toss processes the incoming data. We can use that for sanity checking later.
Now, here s a basic nncp-zfs-receive script:
#!/bin/bash
set -e
set -o pipefail
STORE=backups/simplesnap
DEST="$1"
# now process stdin
runcommand zfs receive -o readonly=on -x mountpoint "$STORE/$DEST"
And there you have it all the basics are in place.
Update 2020-12-30: An earlier version of this article had zfs receive -F instead of zfs receive -o readonly=on -x mountpoint . These changed arguments are more robust.
Update 2021-01-04: I am now recommending zfs receive -u -o readonly=on ; see my successor article for more.
Enhancements
You could enhance the nncp-zfs-receive script to improve logging and error handling. For instance:
#!/bin/bash
set -e
set -o pipefail
STORE=backups/simplesnap
# $1 will be the host/dataset
DEST="$1"
HOST=" echo "$1"   sed 's,/.*,,g' "
if [ -z "$HOST" ]; then
   echo "Malformed command line"
   exit 5
fi
# Log a message
logit ()
   logger -p info -t " basename "$0" [$$]" "$1"

# Log an error message
logerror ()
   logger -p err -t " basename "$0" [$$]" "$1"

# Log stdin with the given code.  Used normally to log stderr.
logstdin ()
   logger -p info -t " basename "$0" [$$/$1]"

# Run command, logging stderr and exit code
runcommand ()
   logit "Running $*"
   if "$@" 2> >(logstdin "$1") ; then
      logit "$1 exited successfully"
      return 0
   else
       RETVAL="$?"
       logerror "$1 exited with error $RETVAL"
       return "$RETVAL"
   fi

exiterror ()
   logerror "$1"
   echo "$1" 1>&2
   exit 10

# Sanity check
if [ "$HOST" = "laptop" ]; then
  if [ "$NNCP_SENDER" != "12345678" ]; then
    exiterror "Host $HOST doesn't match sender $NNCP_SENDER"
  fi
else
  exiterror "Unknown host $HOST"
fi
runcommand zfs receive -F "$STORE/$DEST"
Now you ll capture the ZFS receive output in syslog in a friendly way, so you can look back later why things failed if they did.
Further notes on NNCP
nncp-toss will examine the exit code from an invocation. If it is nonzero, it will keep the command (and associated stdin) in the queue and retry it on the next invocation. NNCP does not guarantee order of execution, so it is possible in some cases that ZFS streams may be received in the wrong order. That is fine here; zfs receive will exit with an error, and nncp-toss will just run it again after the dependent snapshots have been received. For non-ZFS backups, a simple sequence number can handle this issue.
Review: The House in the Cerulean Sea, by TJ Klune
Publisher:
Tor
Copyright:
March 2020
ISBN:
1-250-21732-6
Format:
Kindle
Pages:
398
Linus Baker is a case worker for the Department in Charge of Magical
Youth. His job is to evaluate the orphanages to which children with
magical powers are sent and ensure those children are treated properly.
This must be done properly, with professional care and detachment and
careful documentation so that his superiors can make the correct choices.
Linus has no ambition or desire to be anything other than a case worker.
He does his job meticulously by the book, namely the DICOMY Rules
and Regulations, which he studies religiously. Linus is therefore caught
entirely by surprise when he is summoned without explanation to the
offices of Extremely Upper Management on the intimidating 5th floor. That
summons turns out to be a new assignment for which Extremely Upper
Management believes Linus to be ideal: an orphanage on an island far from
the city, home to some highly unusual (and, in one case, disturbing)
children and a headmaster who is as odd as his charges.
Management is correct about Linus up to a point. He is a bureaucrat and a
stickler for rules. However, Extremely Upper Management did not account
for the possibility that Linus does the work that he does because he cares
deeply about children, or that, if the two come into conflict, the
children might matter more than the rules.
The House in the Cerulean Sea is the sort of book that tells you
exactly what it's doing, assures you that you'll enjoy it anyway, and then
you actually do. The plot developments are obvious well in advance, the
tugs on the heart-strings are telegraphed and obvious, and there are very
few surprises. But the story is told with such charm and feeling that I
at least didn't mind at all, and indeed would have been furious at the
author if he hadn't delivered the expected ending.
This is not the book to read if you want to delve deep into the
implications of the world-building. It follows children's book logic in
several important places: intentions matter more than institutional
structure, sincerity is persuasive, and courage is rewarded. A few
reviews compare it to Nineteen Eighty-Four, but this is wildly
misleading beyond a few trappings of the setting. The internal logic of
the book is closer to a cross between Good Omens and Dr. Seuss.
It's a "good people are rewarded" sort of book and wears that on its
sleeve.
One of the things that Klune does extremely well is subtlety of
characterization despite the relative lack of subtlety in the plot. Linus
starts the book as a caricature whose life is nearly a blank canvas, and
by the end of the book he feels like someone you know. Klune pulls this
off less by filling in the canvas than by making careful use of all that
negative space to put emotional weight and depth behind a few telling
details like Linus's pyjamas, records, and cat. He also does an
exceptional job with the mannerisms and habits of speech of both Linus and
the headmaster of the orphanage. To say much more would be a spoiler;
suffice it to say that Klune captures an interaction style that I have
rarely seen in novels and certainly not in a fantasy novel of this type,
and does it so well that I was strongly reminded of people I've known.
Anyone who knows me is unlikely to be surprised that my favorite character
in the book is Zoe, the sarcastic and fiercely protective sprite who owns
the island on which the orphanage is located, but almost all of the
characters are wonderful. One or two of the children are a bit one-note,
but the group dynamics make up for that, and the suspicious, thoughtful,
and respectful interplay between the three adults is beautifully done. My
only real complaints on the characterization front are that some of the
confrontations in the nearby village felt a bit strained, and I think
Helen got short shrift and could have been fleshed out some more. I will
say that the motives of the villains never made much sense, but they
didn't have to; they're essentially monsters in Linus's story, and they do
enough to serve that purpose.
I now want to read the story of how Zoe and the headmaster met, although
I'm not sure Klune is the right person to write it, and I'm not sure he
left enough emotional space for another novel.
Sometimes I want to read a positive, hopeful book in which people learn
and grow and good things happen to good people, one where the author is
unapologetically manipulating my emotions and I don't care because I want
these people to be happy. If you feel the same way, I cannot recommend
this book highly enough. It's lovely.
Rating: 9 out of 10
Creating Beautiful Github Streaks
Github streaks are a pretty fun and harmless way of visualizing your
contributions on github or gitlab. Some people use them to brag a little, some
companies use them to check out potential candidates. It s all good as long as
everyone is aware how easily you can manipulate them.
In order to fake a commit date in the past, you have to set the
GIT_AUTHOR_DATE and GIT_COMMITTER_DATE environment variables on git
commit both, RFC 2822 and ISO 8601 formats are accepted (for more info see
here).
When generating hundreds of commits, the --allow-empty flag is very useful,
as we don t have to actually change the source tree in order to generate a commit.
So the command to generate a fake commit looks like this:
execute it on an empty git repository and push to github or gitlab and you ll
se the result after some time.
To automate this, I wrote me a little python script (github,
pypi). You can simply install it via:
pip install python-streak
and run it with:
streak
in an empty git repository. By default, streak will create 3 commits per day
with a probability of ~71% per commit for 100 years, starting from 1980-05-09.
These parameters can be tuned with:
--start START: Beginning of the commits (Format: YYYY-MM-DD)
--end END: End of the commits (Format: YYYY-MM-DD)
--max MAX: Maximum number of commits per day.
--proba PROBA: Probability for a commit to happen.
Generating a few commits per day for the range of 10 years, took roughly 2
minutes on my computer, and man was I a busy beaver in the 80s!
I know, I m for sure not the first one to discover this kind of thing, but it
was a fun afternoon project anyways!
Creating Beautiful Github Streaks
Github streaks are a pretty fun and harmless way of visualizing your
contributions on github or gitlab. Some people use them to brag a little, some
companies use them to check out potential candidates. It s all good as long as
everyone is aware how easily you can manipulate them.
In order to fake a commit date in the past, you have to set the
GIT_AUTHOR_DATE and GIT_COMMITTER_DATE environment variables on git
commit both, RFC 2822 and ISO 8601 formats are accepted (for more info see
here).
When generating hundreds of commits, the --allow-empty flag is very useful,
as we don t have to actually change the source tree in order to generate a commit.
So the command to generate a fake commit looks like this:
execute it on an empty git repository and push to github or gitlab and you ll
se the result after some time.
To automate this, I wrote me a little python script (github,
pypi). You can simply install it via:
pip install python-streak
and run it with:
streak
in an empty git repository. By default, streak will create 3 commits per day
with a probability of ~71% per commit for 100 years, starting from 1980-05-09.
These parameters can be tuned with:
--start START: Beginning of the commits (Format: YYYY-MM-DD)
--end END: End of the commits (Format: YYYY-MM-DD)
--max MAX: Maximum number of commits per day.
--proba PROBA: Probability for a commit to happen.
Generating a few commits per day for the range of 10 years, took roughly 2
minutes on my computer, and man was I a busy beaver in the 80s!
I know, I m for sure not the first one to discover this kind of thing, but it
was a fun afternoon project anyways!
I am no longer maintaining github-backup.
I'll contine hosting its website and git repo for the time being, but it needs
a new maintainer if it's going to survive.
I don't really think it needs to survive. If the farce of youtube-dl being
removed from github, thus losing access to all its issues and pull
requests, taught us anything, it's that having that happen does not make
many people reconsider their dependence on github. (Not even youtube-dl it
turns out, which is back on there.) Clearly people don't generally
have any interest in backing that stuff up.
As far as the git repositories on Github, they are getting archived very
effectively by softwareheritage.org
which vaccumes up all git repositories from Github. Which points to a
problem, because the same can't be said for git repositories not hosted on
Github. There's a
form to submit them
but the submissions often get hung up needing manual review, and it doesn't
seem to pull in new commits actively if at all, based on the few git
repositories I've had archived there so far.
That seems like something it might be worth building some software to manage.
But it's also just another case of Github's mass bending reality around it;
the average Github user doesn't care about this and still gets archived;
the average self-hosting git user may care about this slightly more, but most
won't get archived, even if that software did get built.
Farmer on-going protests
Before I start with the education system in India which I have talked about many times in the past, first let me share couple of pieces about the farmer movement which is still at Sanghu Delhi border.
<Manjeet Kaur,62 at farmer protest with her friends.
The above picture became somewhat viral as it showed Manjeet Kaur, who drove down from Patiala, Punjab to Sanghu border along with her friends to take part in the on-going protests. The picture not only shares how the women are part and parcel of this protest but also they are independently taking part in the protest.
The other were two articles I read today, first was an article in tribune which questions that if the policy worked, why it didn t work in the state of Bihar. The other by a young law student who had to go from Chandigarh to Delhi with family for some work and her experience with the ongoing protest. In fact, an interesting observation was made by the CJI in the many suits against farmer protests in the SC. This makes for much more interesting read when you see an RTI query filed by Saket Gokhale to NHAI , a Central Govt. agency which is supposed to be independent and asks if they had filed an FIR and asked compensation from Haryana State and Haryana State Police which had dug up National Highway 44 and if any permission was asked for the same from NHAI. And NHAI unable to take any action for the same. If this isn t shameful, I dunno what is
Saket Gokhale s RTI query on digging up NH44
NHAI response to Saket Gokhale s query.
Sadly, the way the response has been worded makes it impossible for NHAI to discharge its own responsibilities and this becomes a precedent for other states now that know that NHAI is vulnerable. A pretty sad turn on events.
Indian Education can t go online
There was a recent article on scroll which shared how Indian education can t go online as only a few have computers with decent netlink speeds as well as other factors which are needed for online education. But there are also many things that the article doesn t take into account which actually make the task more difficult and raise the boundary more.
Now in most schools and colleges, the number of students to teacher ratio could be anywhere between 70-150 or even more. In the last few years, a lot of schools have been closed down by various Governments, including and not limited to the ruling Govt. They have in fact intensified closures of public schools wherever their Govt. has been in power. Closing to 5000+ schools in one state in a year is a dramatic shift and such has been happening time and again. In fact, the rising costs of Indian education has made many to leave Indian shores and do studies abroad. And once they do their masters or whatever, the chances of them coming back to India become more and more remote. In India the costs have been becoming so bad that NBFC s have started products targeting the same. How NBFC and Banks have (both public and private) have fared with respect to Indian consumers needs its own blog post but one word to describe it is bad . But as shared above, needs its own blog post.
Coming to the Indian context though, what has not been captured in that article is that the responsibility of making new content also raises huge barriers for teachers. My own experience in teacher s trainings for ICT usage has shown that most teachers do not know and use internet effectively both to sustain their own curiosity as well as their students. Part of which is whether you are private employee or a public school teacher, the teacher is not paid enough. I have had multiple conversations with friends over the years who are teachers who shared that they get 50% salary in-hand while they sign for 100%. This is more in the case or private schools though. In Govt. schools, the teachers apart from their regular administrative duties apart from teaching duties are also unpaid labor for Govt. policy. Take the recent covid crisis, it was the teachers who for months together went from door-to-door asking if they had a covid patient. This was all over India. Even for voter registration, census, polio and various other immunization efforts, the teachers are roped in. So apart from that, they somehow have to figure out how to make ends meet and also boost student morale. Hence the attention is only limited to the first couple of benches rather than the whole as a 45-minute to an hr. session is just not enough to go through a class of 70-150 school students giving individual attention. And this is when for most teachers, teaching is a means to an end and not the end itself.
I am going to take one example of science and sort of break-it-down in multiple steps and how I would have approached that topic for say the 5th-6th standard students in say a public school in Pune and especially if Covid would not have been an issue so you have face-to-face meetup.
There was recent news about a mysterious radio signal which came from one of our closest galactic neighbors Proxima Centauri. Now let s say there was a class I was teaching/sharing which I had shared before and there already is trust formed.
So before coming to the news, I would tell the students about frequency and more generally the notation of why we like to measure things and how we measure things. There is so much beautiful history which could be acted and enacted which can show and remains in mind why measurement is needed. Once that is understood, discussed and an underpinning is established, we could move to human perception or the lack of it. We know that humans have lots of limits in almost everything, whether it is talking, touching, hearing, all of our five senses are pretty limited with what we know of spectrum available in the immediate family kingdom as well as in the Universe. I would start with how far can a person throw his voice and be heard without using any other means. There does come a point where they need to use anything from a megaphone to a loudspeaker and what it actually does.
The other thing I would then talk is about the radio and ask the students to find more about the internals of a radio. If possible to bring an old radio to school where it could be disassembled. After they are familiar with some names of the electronic components and what they do, take them to the electronics market where they try to source all the things needed to make a radio and whatever they encounter. This would allow the students to try and do bargain shopping as well as learn from where to source things. Some might even get a copy or two of electronic projects where the shop themselves sell blueprints to hobbyists so that they can tinker.
If there is a place in the school where soldering can be done, then all can try and sooner or later we come to know if something works or not. There is also possibility of talking about noise cancellation and then the topic of ITU can also be bought up and how they do frequency allocation. Last but not the least then the topic can be approached about an alien civilization and an unknown radio signal and what it means and what it can mean.
Now if just one topic can give such a wide range of things to do and develop an understanding about not the subject itself but surrounding subjects as well I see no reason why teachers can t do this except they are handcuffed to lot of policy as well as real-life constraints.
For e.g. I remember in my school days, we used to go out once or twice a year and that used to be either a school picnic or something similar. The only other I know is going to Mumbai for Nehru planetarium and Nehru science Centre. Unfortunately, I didn t go at that time because the school was taking students via air and the tickets were super costly at the time and that too for a 10 minute journey between the two cities. Those were different days, today you can t have a direct flight between the two cities as it doesn t make an economic sense. It makes more sense to go to Mumbai via train or bus as you will reach Mumbai in about couple of hrs. Of course, Pune does have its own planetarium at New English school and there are a few amateur astronomy clubs in Pune but nothing on the scale that what Mumbai has, but then this is getting off-topic.
Now, again in an online world could this be done? Not without both the teacher and the student both spending lot of resources online and even then will be a lower understanding as both the hands-on experience as well as interacting with other students and learning from other students (aping) would be hugely limited. Even the social skills that students develop in a school setting will be rusted. My own social skills probably have weakened and rusted as I have very limited interaction with people over the past few months due to Covid fears and would be at least for the next few years till a large enough population is not vaccinated.
phosh is graphical shell for mobile, touch based devices like
smart phones. It's the default graphical shell on Purism's
Librem 5 (and that's where
it came to life) but projects like postmarketOS,
Mobian and
Debian have picked it up
putting it into use on other devices as well and contributing patches.
This post is meant as a short overview how things are tied together so
further posts can provide more details.
A PHone SHell
As mobile shell phosh provides the interface components commonly
found on mobile devices to
launch applications
switch between running applications and close them
lock and unlock the screen
display status information (e.g. network connectivity, battery level)
provide quick access to things like torch or Bluetooth
show notifications
It uses
GObject object system and
GTK to build up the user
interface components. Mobile specific patterns are brought in via
libhandy.
Since phosh is meant to blend into GNOME as seamlessly as possible it
uses the common interfaces present there via
D-Bus like
org.gnome.Screensaver or org.gnome.keyring.SystemPrompter and
retrieves user configuration like keybindings via
GSettings from preexisting
schema.
The components of a running graphical session roughly look like this:
The blue boxes are the very same found on GNOME desktop sessions
while the white ones are currently only found on
phones.
feedbackd is explained
quickly: It's used for providing haptic or visual user feedback and
makes your phone rumble and blink when applications (or the shell)
want to notify the user about certain events like incoming phone calls
or new messages. What about phoc and squeekboard?
phoc and squeekboard
Although some stacks combine the graphical shell with the display server
(the component responsible for drawing applications and handling user
input) this isn't the case for phosh. phosh relies on a
Wayland
compositor to be present for that. Keeping shell and compositor apart
has some advantages like being able to restart the shell without
affecting other applications but also adds the need for some
additional communication between compositor and shell. This additional
communication is implemented via Wayland protocols. The Wayland
compositor used with phosh is called
phoc for PHone
Compositor.
One of these additional protocols is wlr-layer-shell.
It allows the shell to reserve space on the screen that is not used
by other applications and allows it to draw things like the top and
bottom bar or lock screen. Other protocols used by phosh (and hence implemented by phoc) are
wlr-output-management
to get information on and control properties of monitors or
wlr-foreign-toplevel-management
to get information about other windows on the display. The later
is used to allow to switch between running applications.
However these (and other) Wayland protocols are not implemented in
phoc from scratch. phoc leverages the
wlroots library for that. The library
also handles many other compositor parts like interacting with the
video and input hardware.
The details on how phoc actually puts things up on the screen deserves
a separate post. For the moment it's sufficient to note that phosh
requires a Wayland compositor like phoc.
We've not talked about entering text without a physical keyboard yet -
phosh itself does not handle that either.
squeekboard is the on
screen keyboard for text (and emoji) input. It again uses Wayland
protocols to talk to the Wayland compositor and it's (like phosh) a
component that wants exclusive access to some areas of the screen
(where the keyboard is drawn) and hence leverages the layer-shell
protocol. Very roughly speaking it turns touch input in that area into
text and sends that back to the compositor that then passes it back to
the application that currently gets the text input. squeekboard's main
author dcz has some more details
here.
The session
So how does the graphical session in the picture above come into existence?
As this is meant to be close to a regular GNOME session it's done via
gnome-session that is
invoked somewhat like:
phoc -E 'gnome-session --session=phosh'
So the compositor phoc is started up, launches gnome-session which
then looks at phosh.session for the session's components. These are
phosh, squeekboard and gnome-settings-daemon.
These then either connect to already running services via D-Bus
(e.g. NetworkManager, ModemManager, ...) or spawn them via D-Bus
activation when required (e.g. feedbackd).
Calling conventions
So when talking about phosh it's good to keep several things apart:
phosh - the graphical shell
phoc - the compositor
squeekboard - the on screen keyboard
phosh.session: The session that ties these and GNOME together
On top of that people sometimes refer to 'Phosh' as the software
collection consisting of the above plus more components from GNOME
(Settings, Contacs, Clocks, Weather, Evince, ...) and components that
currently aren't part of GNOME but adapt to small screen sizes, use
the same technologies and are needed to make a phone fun to use
e.g. Geary for email, Calls for making phone calls and Chats for SMS
handling.
Since just overloading the term Phosh is confusing GNOME/Phosh
Mobile Environment or Phosh Mobile Environment have been used
to describe the above collection of software and I've contacted GNOME on how to name
this properly, to not infringe on the GNOME trademark but also give proper credit
and hopefully being able to move things upstream that can live upstream.
That's it for a start. phosh's development documentation can be
browsed here but is
also available in the source code.
Besides the projects mentioned above credits go to
Purism for allowing me and others to work on the
above and other parts related to moving Free Software on mobile Linux
forward.
The virtual version of the annual CCC Congress is underway and feels like a huge playground. Things are bumpy but the participants are still having fun. Of course, we have IRC as a save heaven. That always works.
The virtual world (which is the only thing the sold out tickets are needed for) is really fun. It feels like debugging a DOS game in the 80/90s. Not much works but it is engaging enough to keep poking at things.
The data formats are 2020 though, the main "lobby map" is a 3 MB json file:
The virtual version of the annual CCC Congress is underway and feels like a huge playground. Things are bumpy but the participants are still having fun. Of course, we have IRC as a save heaven. That always works.
The virtual world (which is the only thing the sold out tickets are needed for) is really fun. It feels like debugging a DOS game in the 80/90s. Not much works but it is engaging enough to keep poking at things.
The data formats are 2020 though, the main "lobby map" is a 3 MB json file:
In case you're wondering why I would pick up a self-help book with such an
uninspiring title, it's because this book was originally published in
Canada with the title Relax, Damnit! Why Caulfield's US publishers
would have changed that title is beyond me. Canada clearly got the better
end of this deal. (I'm hoping it's not because they thought "damn" would
scare someone off, but it probably is.)
The topic of this book is a scientific take on all the little decisions
that you may worry about throughout the day: whether to eat breakfast, how
much water to drink, whether public toilet seats are risky, whether to
weigh yourself, how important flossing is, and much more. Caulfield is a
law professor at the University of Alberta specializing in health law and
scientific ethics, but the hat he's wearing when writing this book is that
of professional skeptic. I found out about this book through
Dr. Jen Gunter, a connection that you
won't find surprising when I mention that one of Caulfield's earlier books
is titled Is Gwyneth Paltrow Wrong About Everything?. (Spoiler:
yes.)
Caulfield chose to organize this collection of random essays around the
timeline of a single day, starting with waking up (how long should you
sleep?) and morning routines (what do scientific studies say about
brushing your teeth?), going through a work day (there's a chapter on
multitasking and why you really shouldn't do it), and concluding with
dinner (no, you can't taste the difference between most wines even if you
think you can), evening routines, and sleep. This worked for me. It's
still a bit arbitrary, but it's hard to organize random bits of
skepticism, and this layout let Caulfield make a point about how
frequently most people check their phones. (Stop doomscrolling. It makes
you feel bad. Yes, I'm talking to myself.)
I've now read several books, and considerably more essays, on scientific
skepticism of this type. They're all a bit the same, and unless you enjoy
this general genre of writing, there aren't many compelling reasons to
read this specific entry. (Ben Goldacre's Bad Science is still my favorite.) I think the only tidbit that
I found surprising and hadn't heard elsewhere is that the science on
flossing is meh at best. The rest is the standard mix of mainstream
scientific advice (don't drink raw milk, you're not going to catch
something from a public toilet seat, multivitamins just give you expensive
urine), advice that's scientifically correct but that I'm still not going
to follow (there's no scientific reason to wash your hair daily but I
still prefer how it feels), and advice to not worry about things with no
evidence on either side (it doesn't matter whether you eat breakfast, ten
thousand steps is a marketing gimmick, drink water when you're thirsty and
don't worry about how much). Caulfield does have a particularly good
debunking of the myth that angry ranting helps you calm down and feel
better (it does the exact opposite), but if you're reasonably well-read on
scientific trivia, nothing here will be that novel.
If you don't follow scientific trivia and want a good collection of
debunking essays, this book is fine. I certainly won't discourage you
from reading it. Caulfield is engaging and succinct, and there's a
balanced mix of odd trivia, debunking of pseudoscience, and good public
health advice, all comfortably in line with what I've read elsewhere.
That said, I found it striking to read this book shortly after
Can't Even. I was hoping that Caulfield
would tackle the larger problem of anxiety and overload that is in part
created by the proliferation of arbitrary standards and rules to which we
hold ourselves. He does tackle some related topics, such as our bizarre
belief in the US (and apparently Canada) that it is unsafe to let children
walk to school without adult supervision, but Caulfield's solutions are
nearly all individual. He wants to inform the reader, he wants to show
you how to analyze scientific research and notice when news articles are
scaring you unnecessarily, and he wants you to become more immune to
fear-mongering.
Petersen's salient point in Can't Even is that many of us are
burned out already and this is even more work. In order to avoid being
gratuitously frightened and deceived by con artists and sensational news
stories, we have to run a mental checklist of evidence evaluation and go
do independent research. Sure, this works, makes you better at risk
analysis, and may thus make you feel calmer, but this takes a lot of time
and energy. Wasn't a point of having the news media that other people
would do some of that work for you? Once again, everything that's wrong
with the world becomes another chore or energy expenditure that we all
have to independently make.
I know, it's asking too much of a harmless book on the scientific evidence
behind daily life decisions to make a political point about individual
versus collective effort. But it's hard to shake the feeling that asking
individuals to try harder to ignore intentionally deceptive and
well-funded propaganda campaigns doesn't scale. Not everyone enjoys
skepticism as a hobby, and there's only so much individual energy to go
around.
Relax, Damnit! is good advice as far as it goes. But I'm more in
the mood for the books that look at who is making us so anxious in the
first place and how we can (collectively) get them to stop. I don't know
what that looks like (there are obvious free speech concerns), but we need
reliable sources of information that don't make us anxious.
Rating: 6 out of 10


 Reviving Very Old X Code
I've taken the week between Christmas and New Year's off this year. I
didn't really have anything serious planned, just taking a break from
the usual routine. As often happens, I got sucked into doing a project
when I received this simple bug report
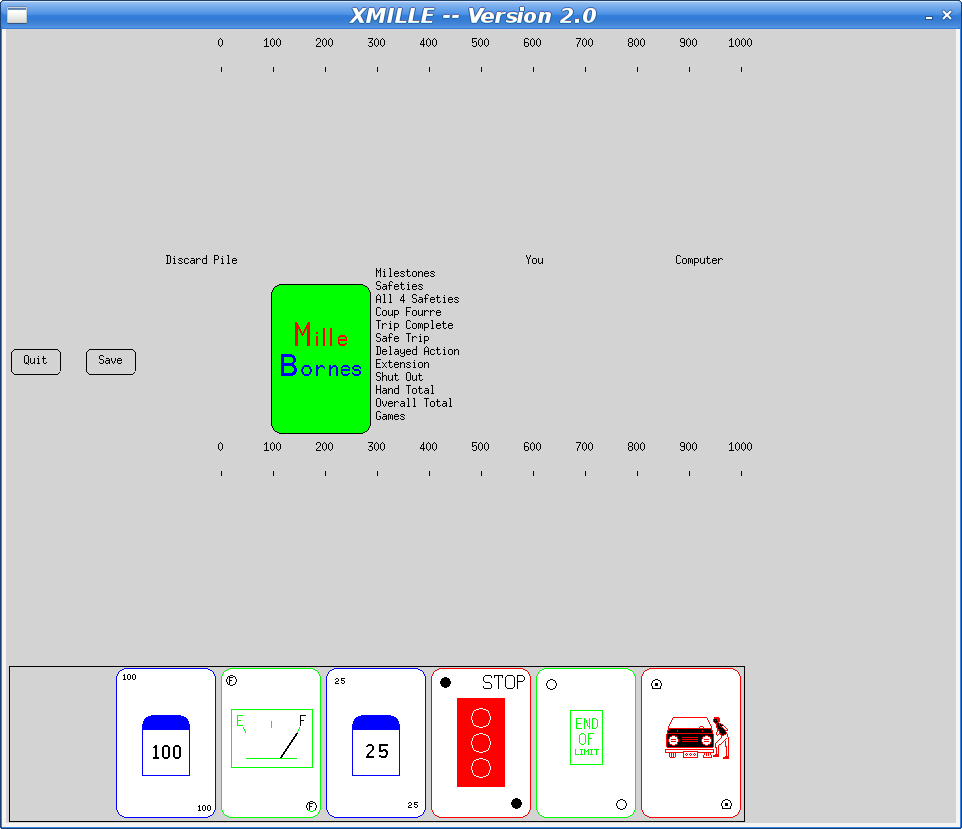
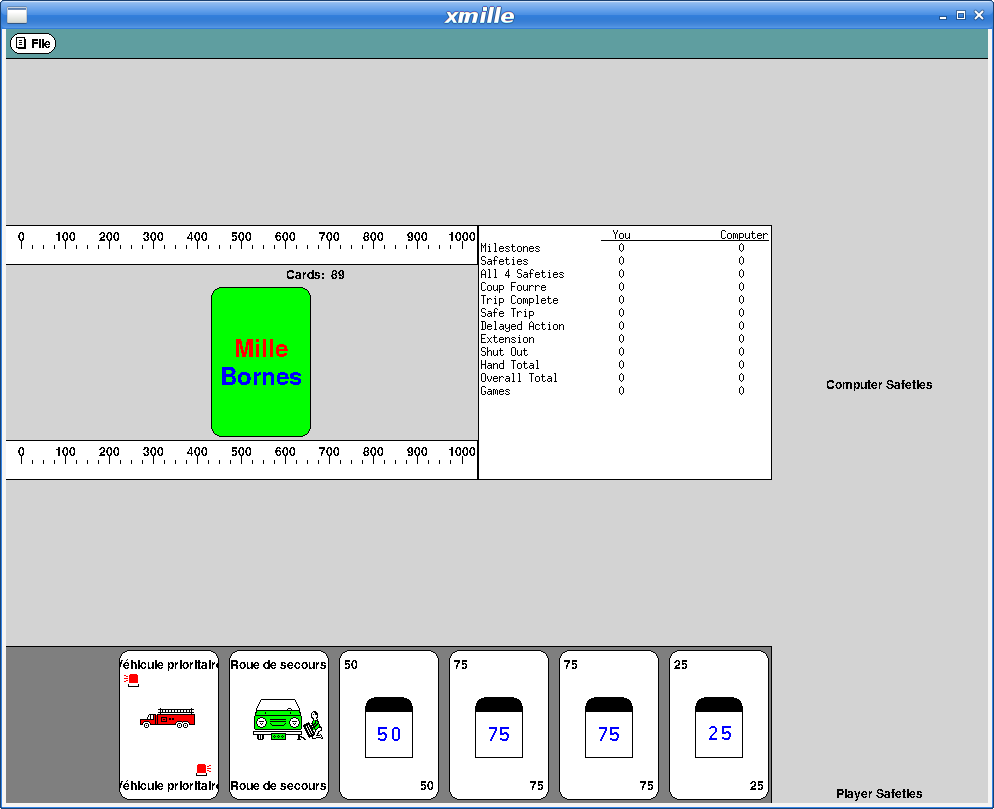
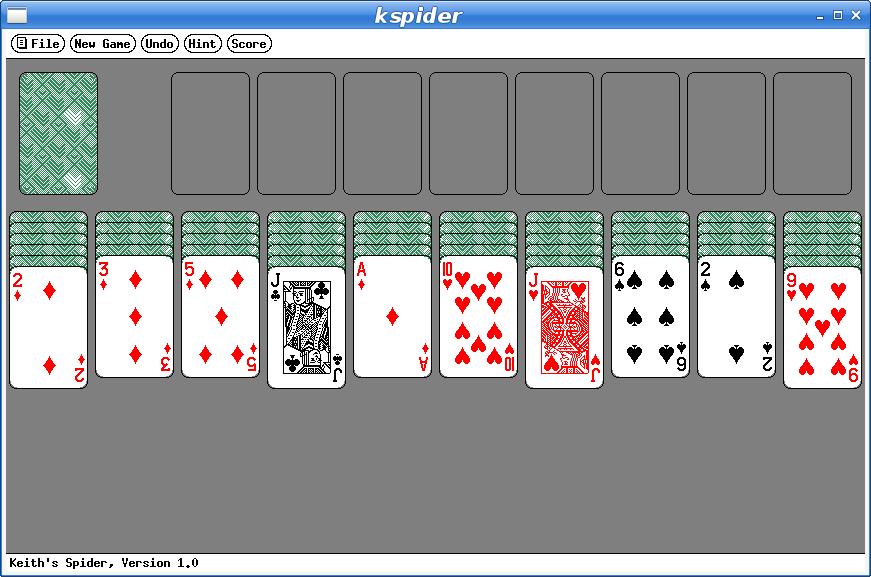

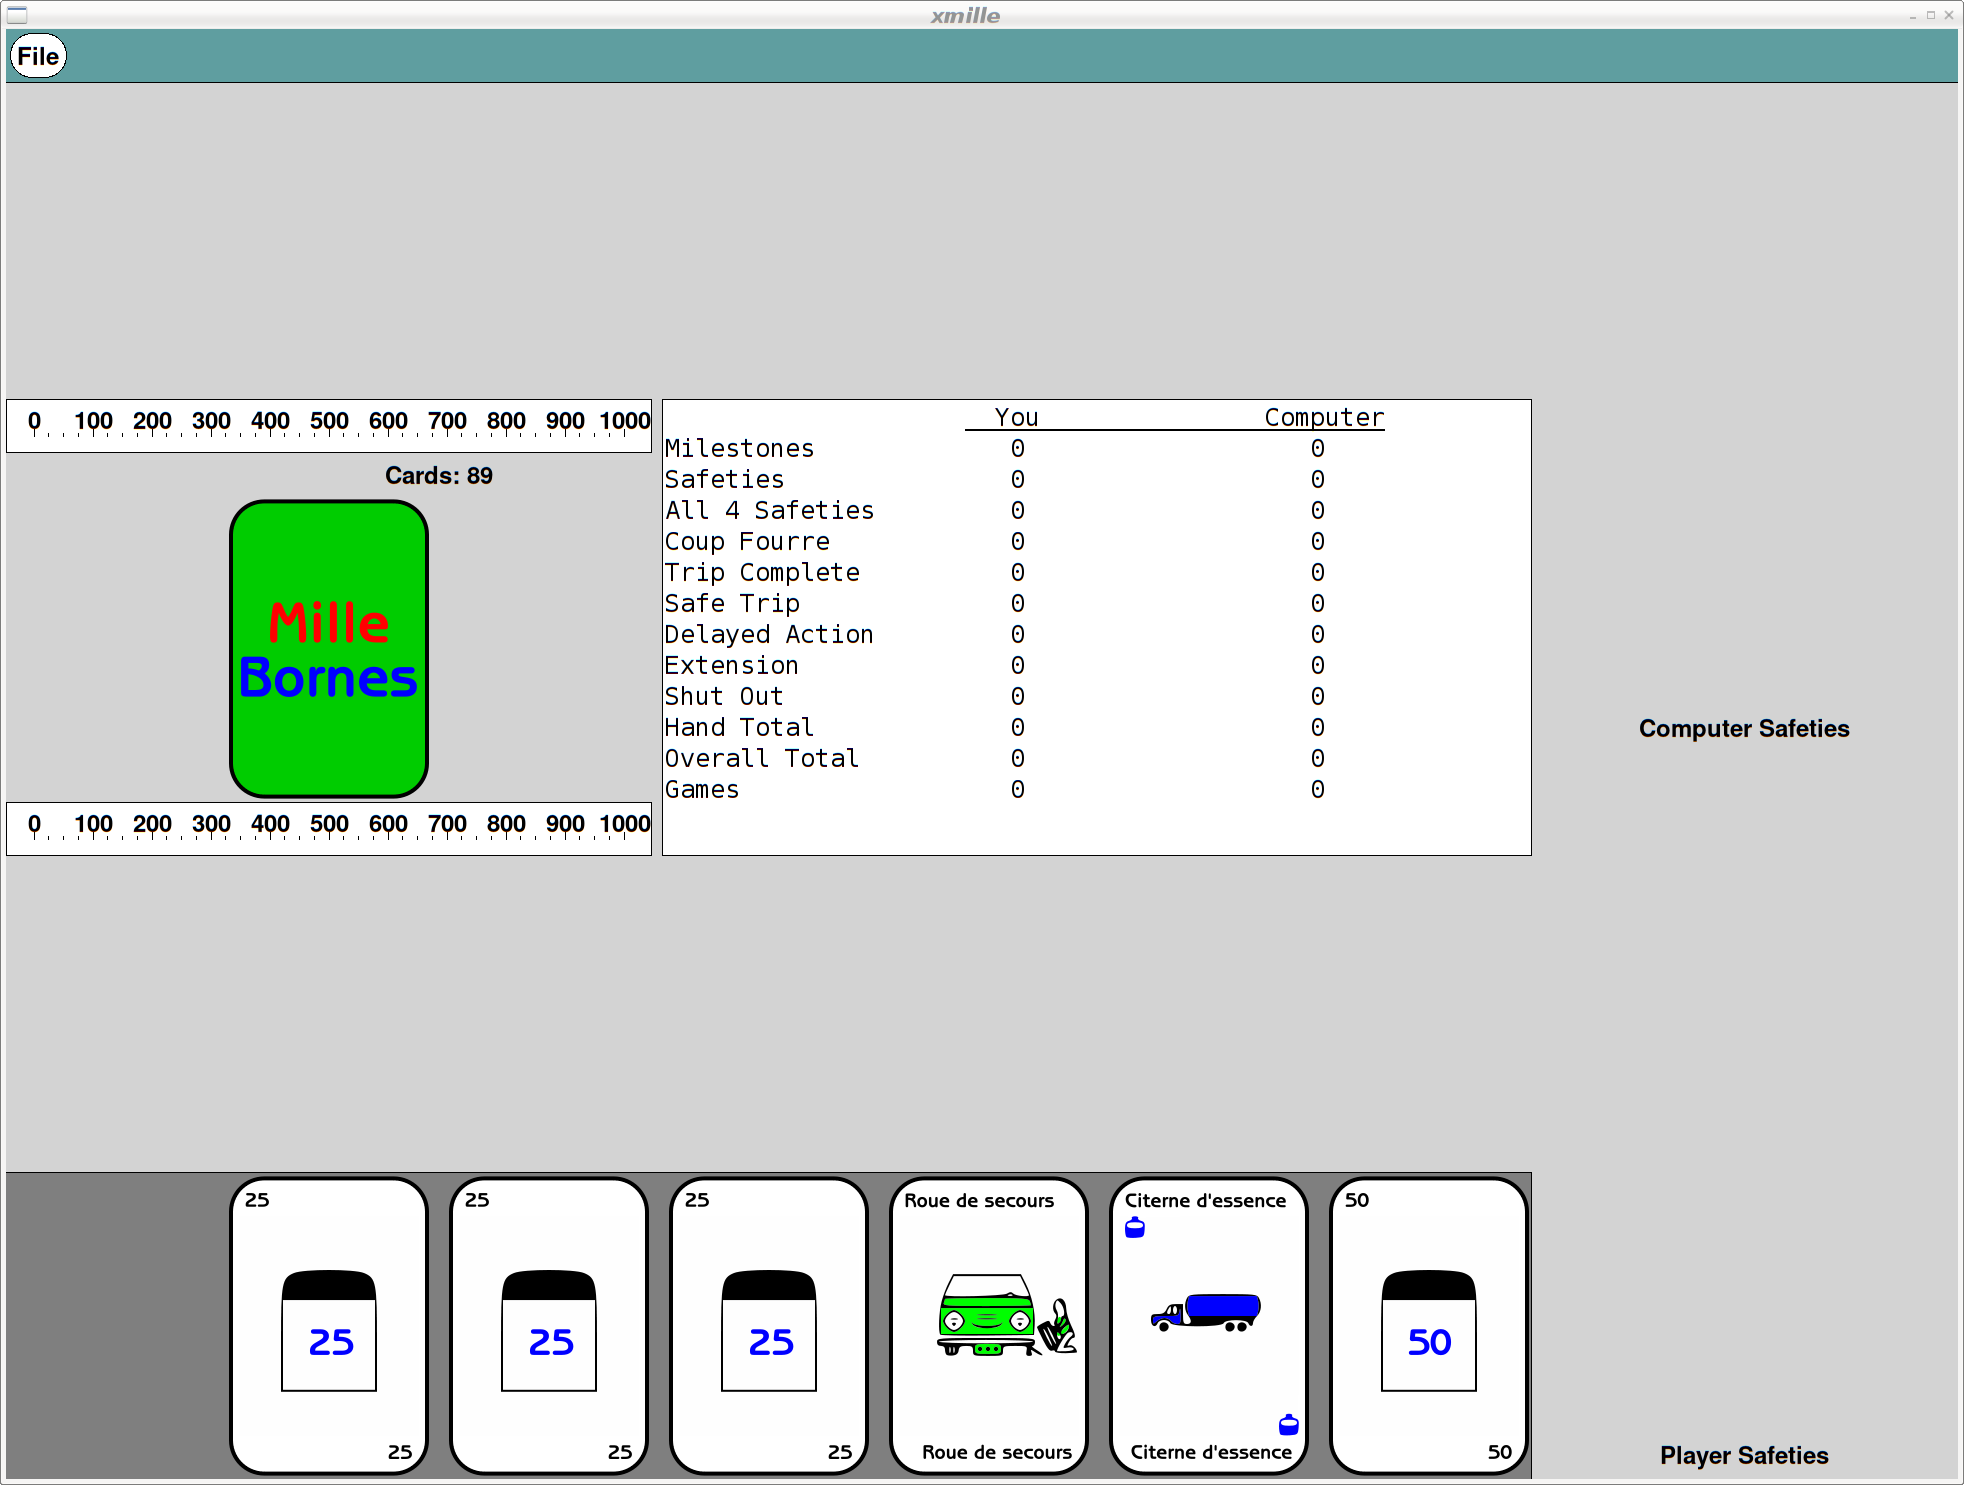
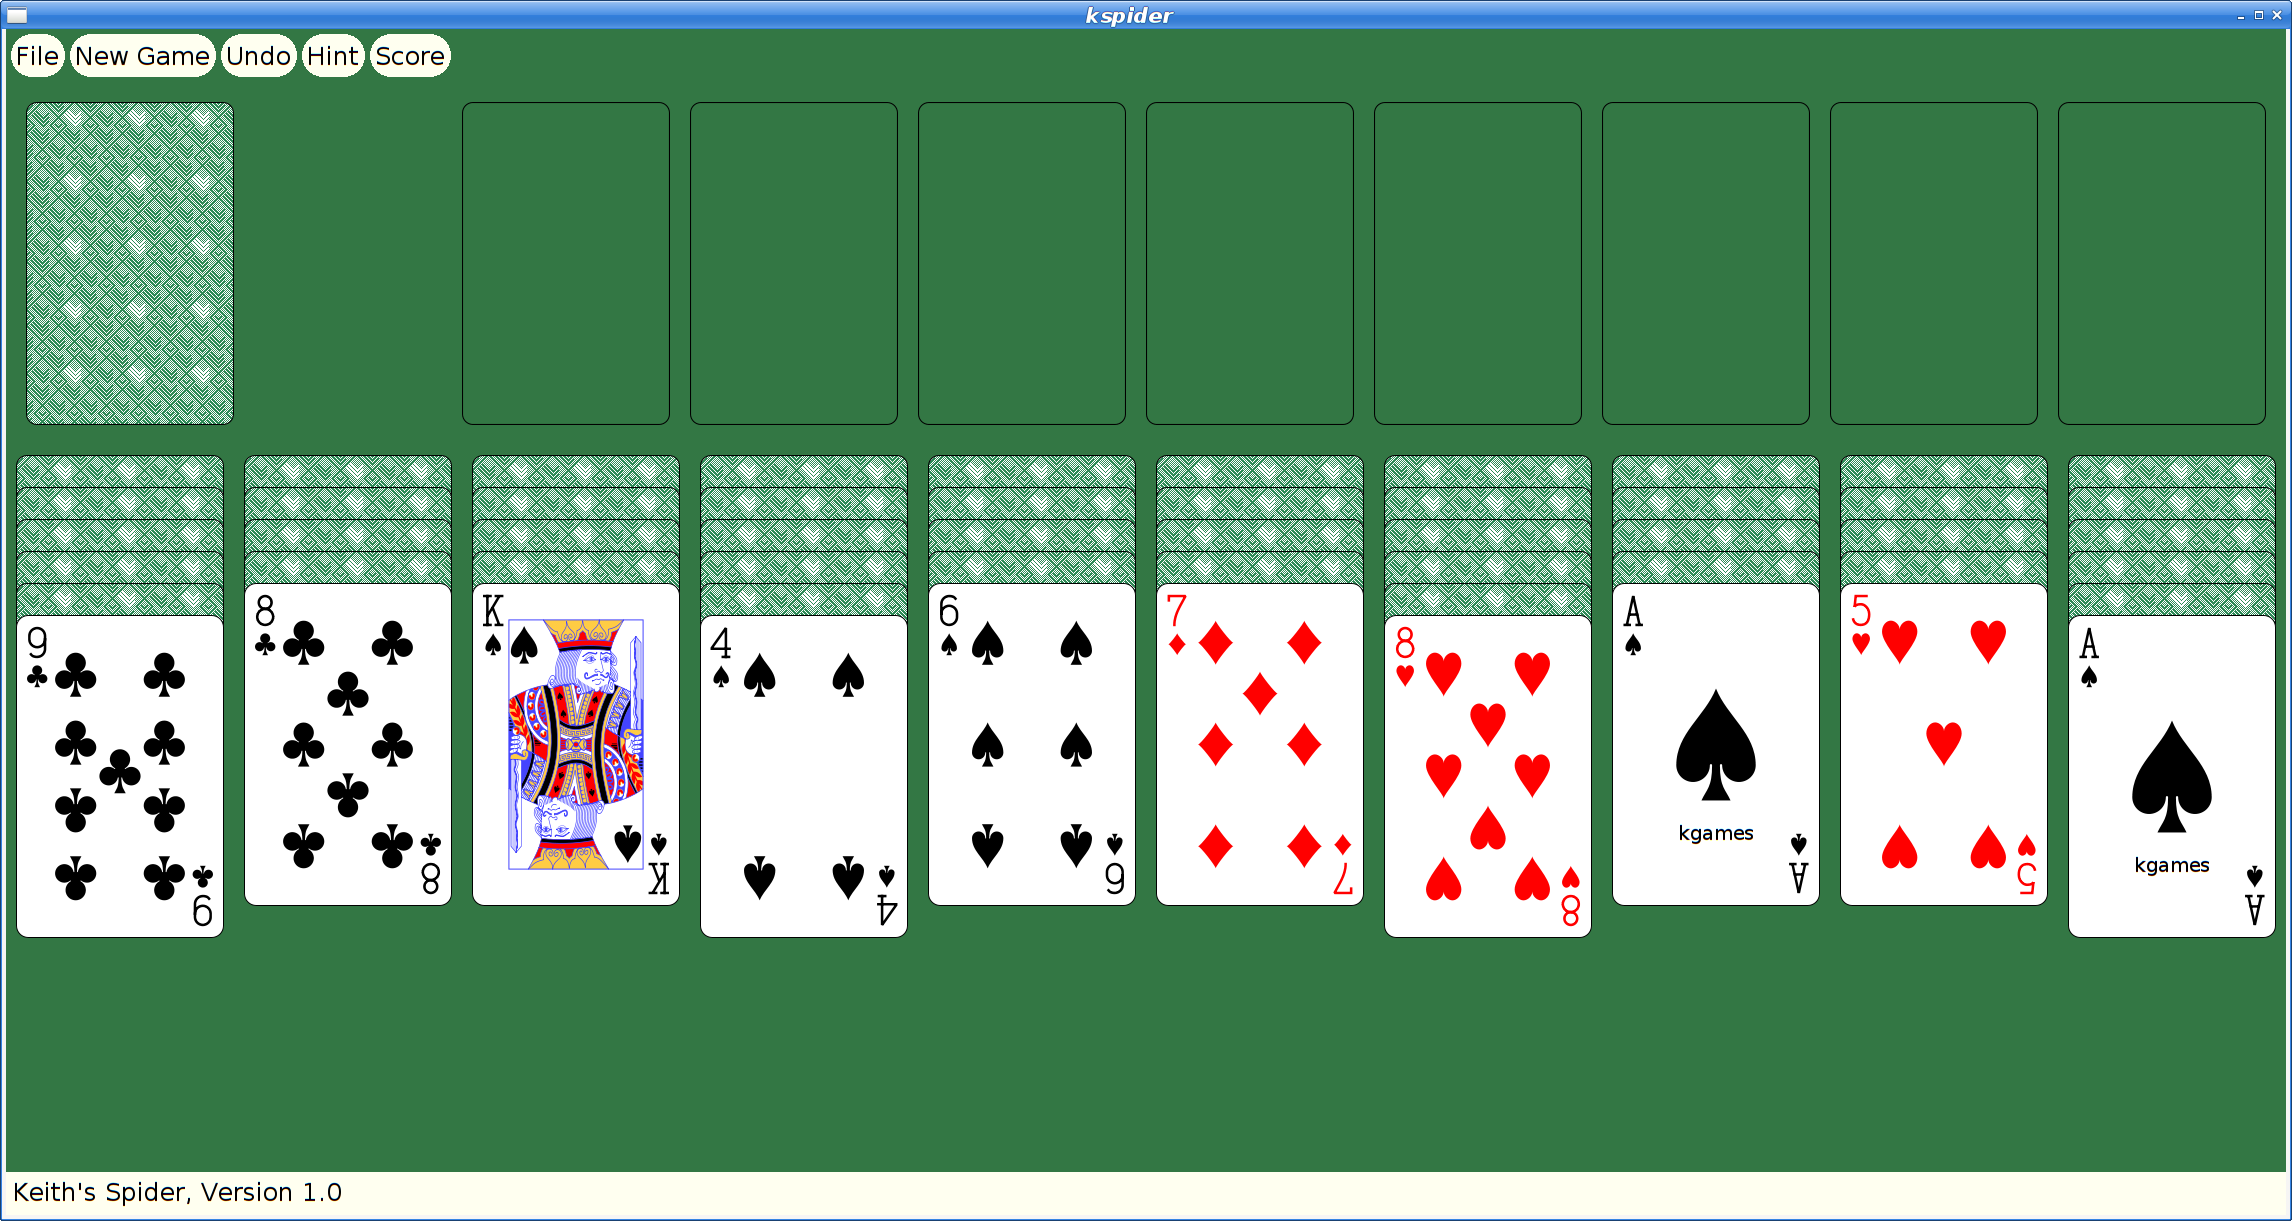
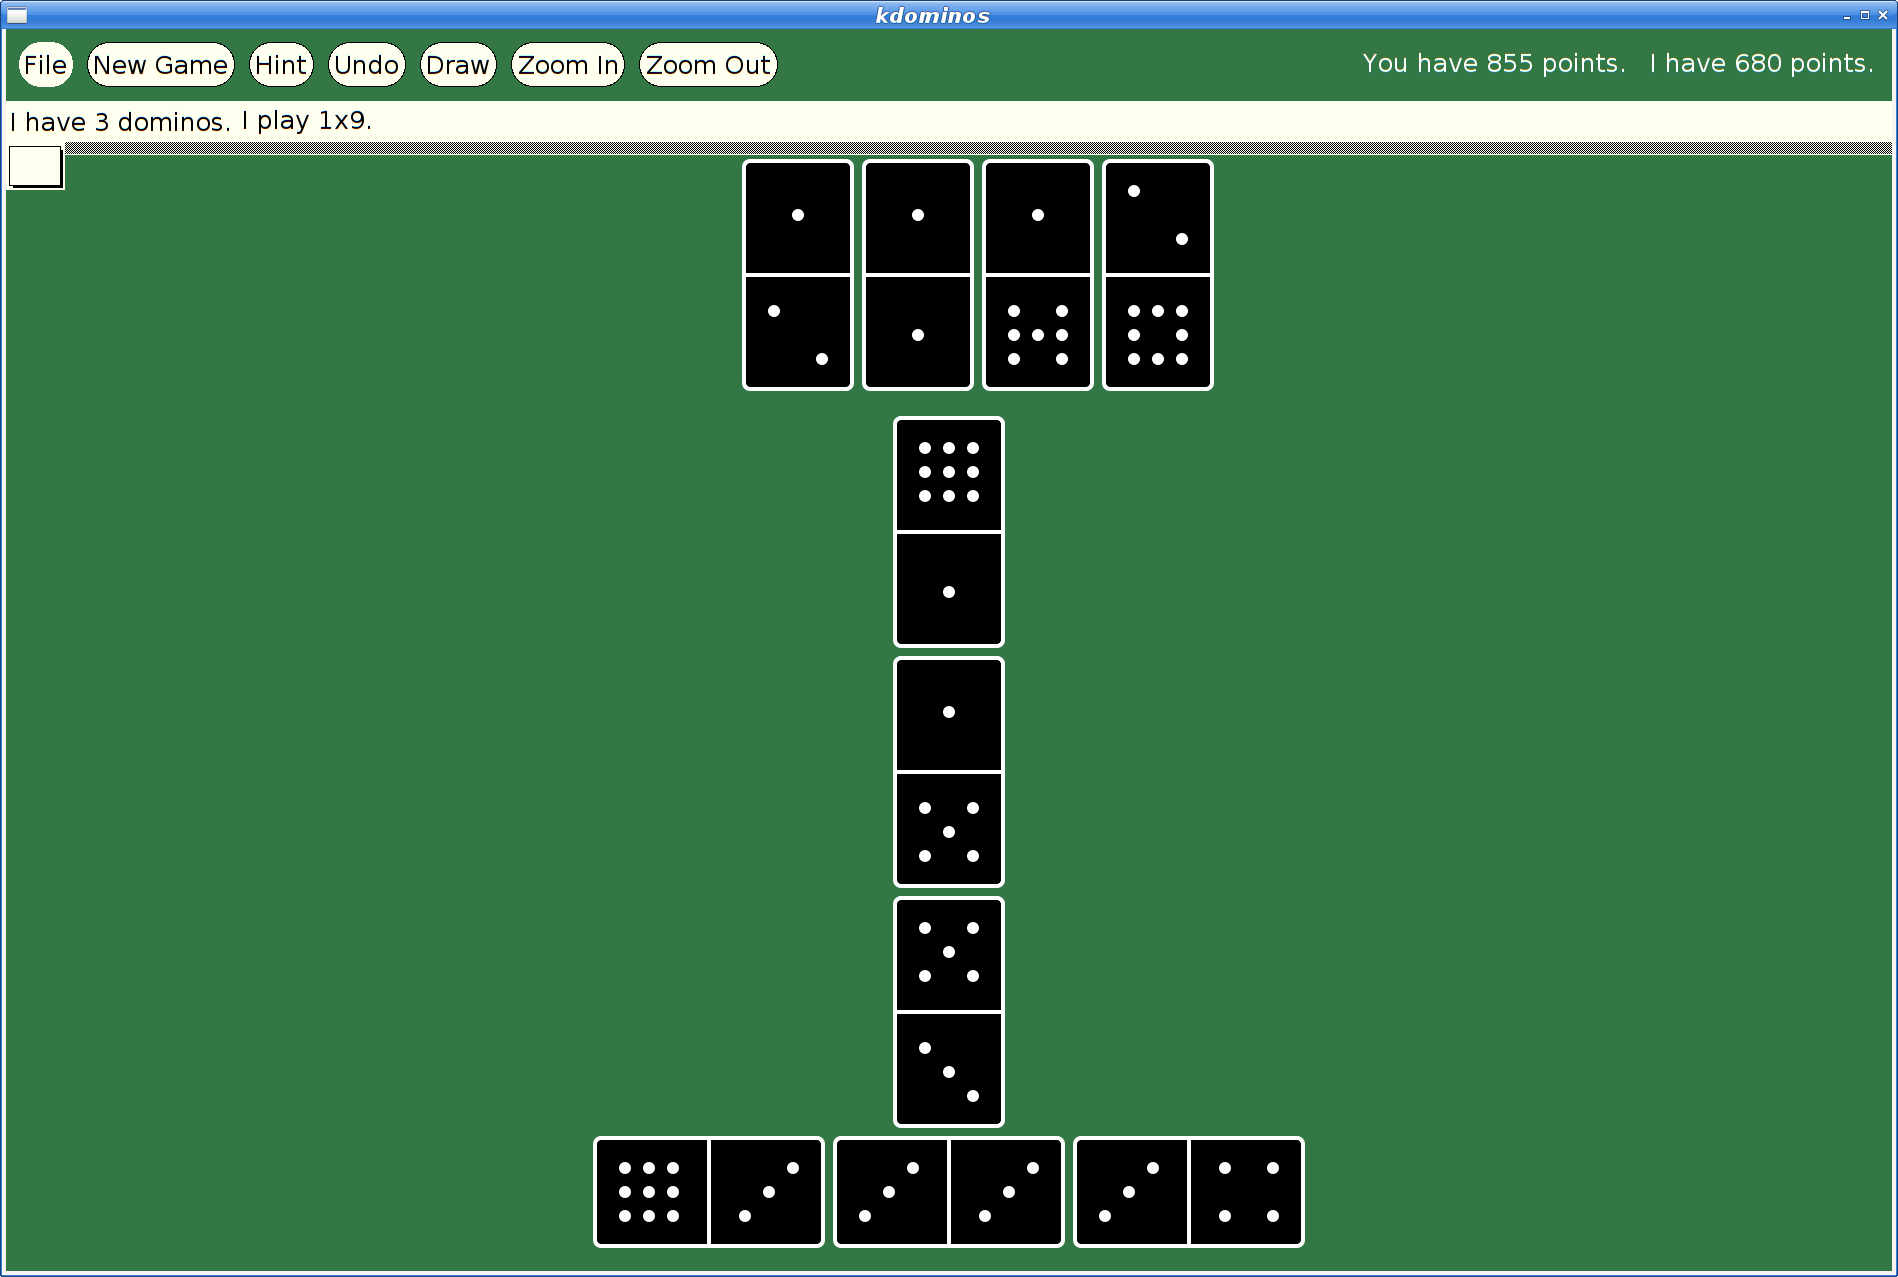
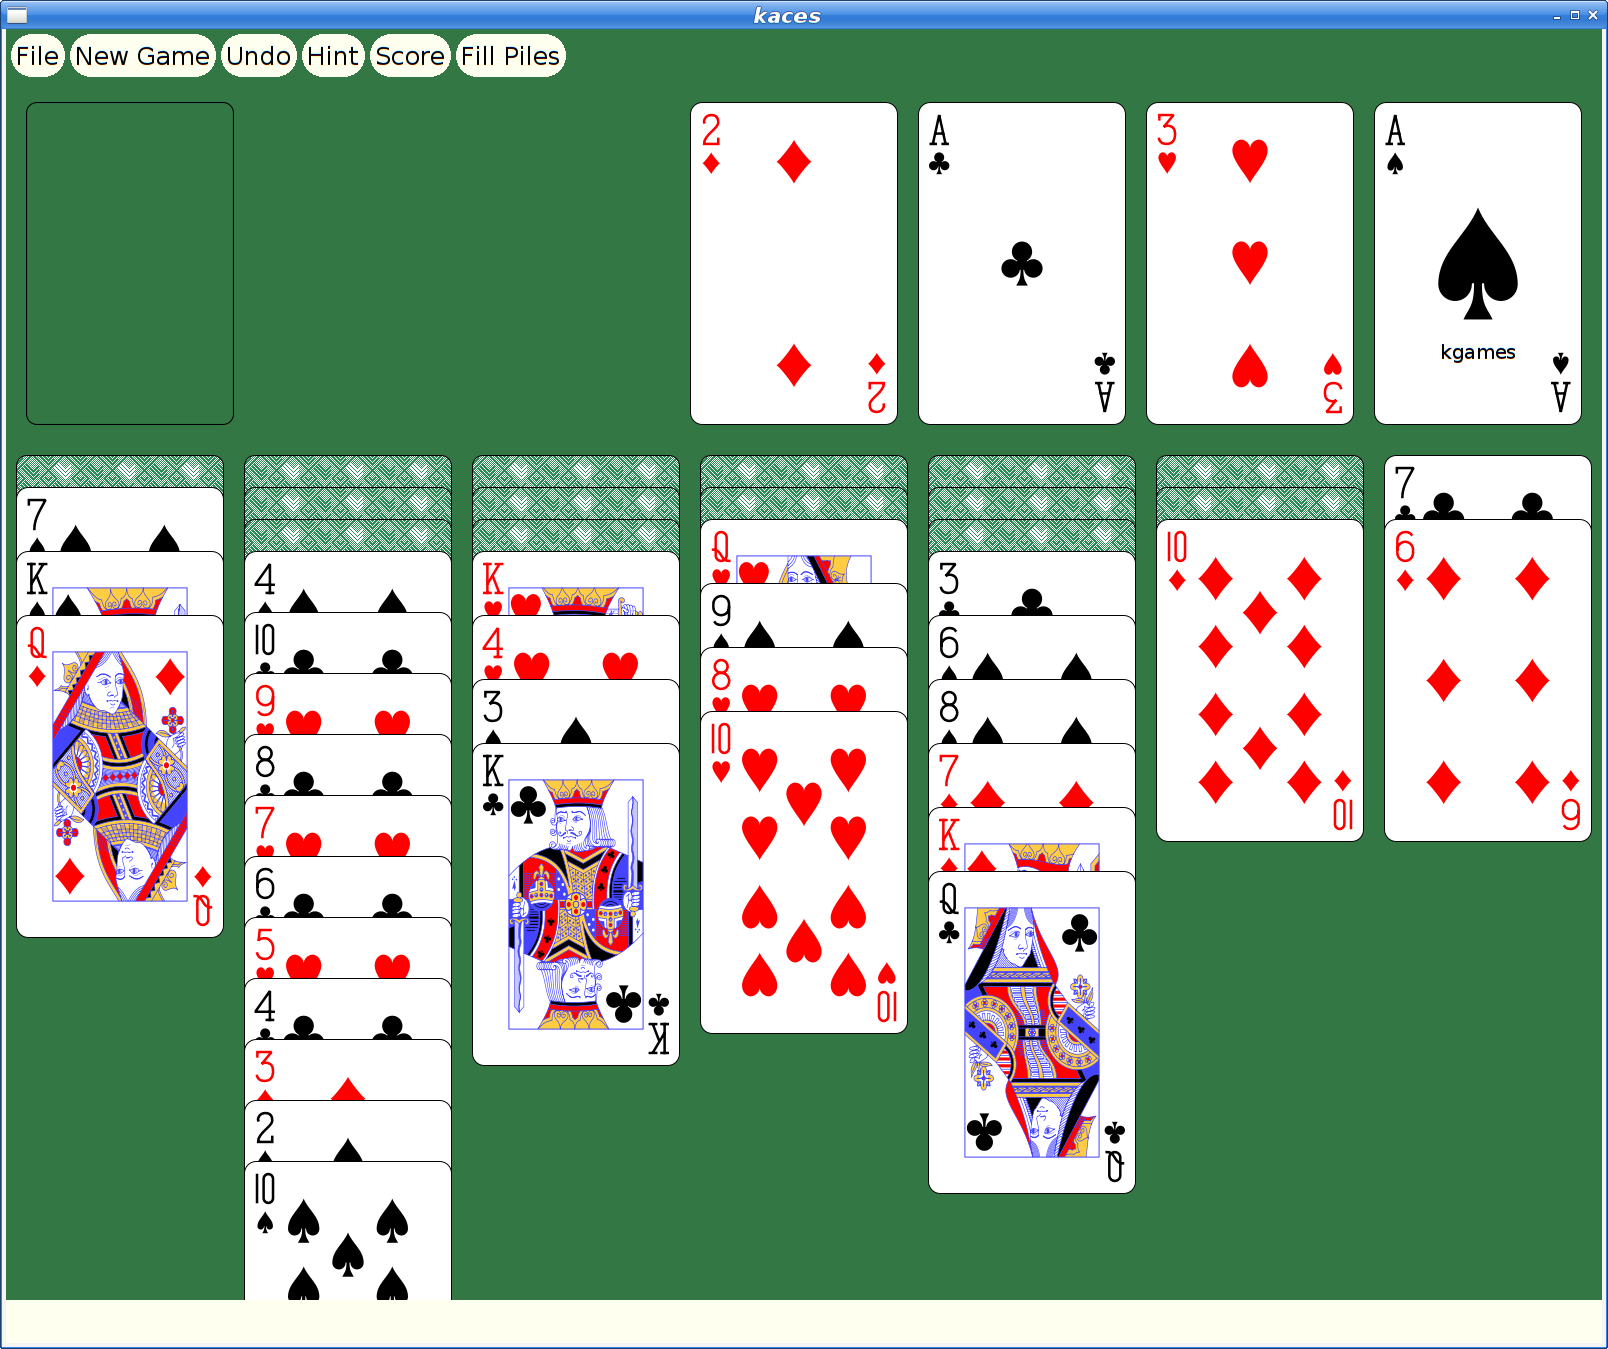
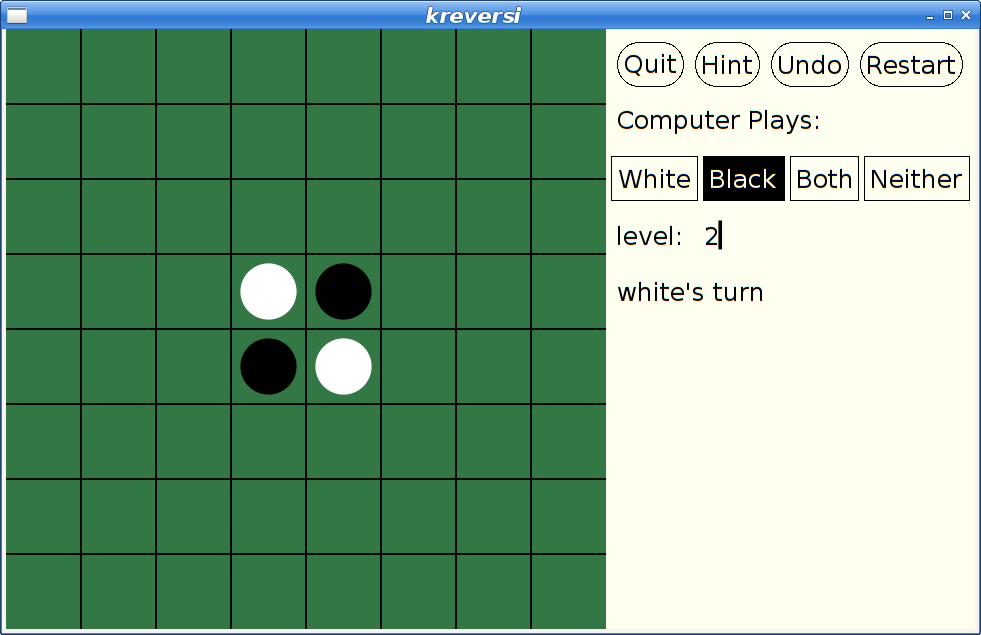
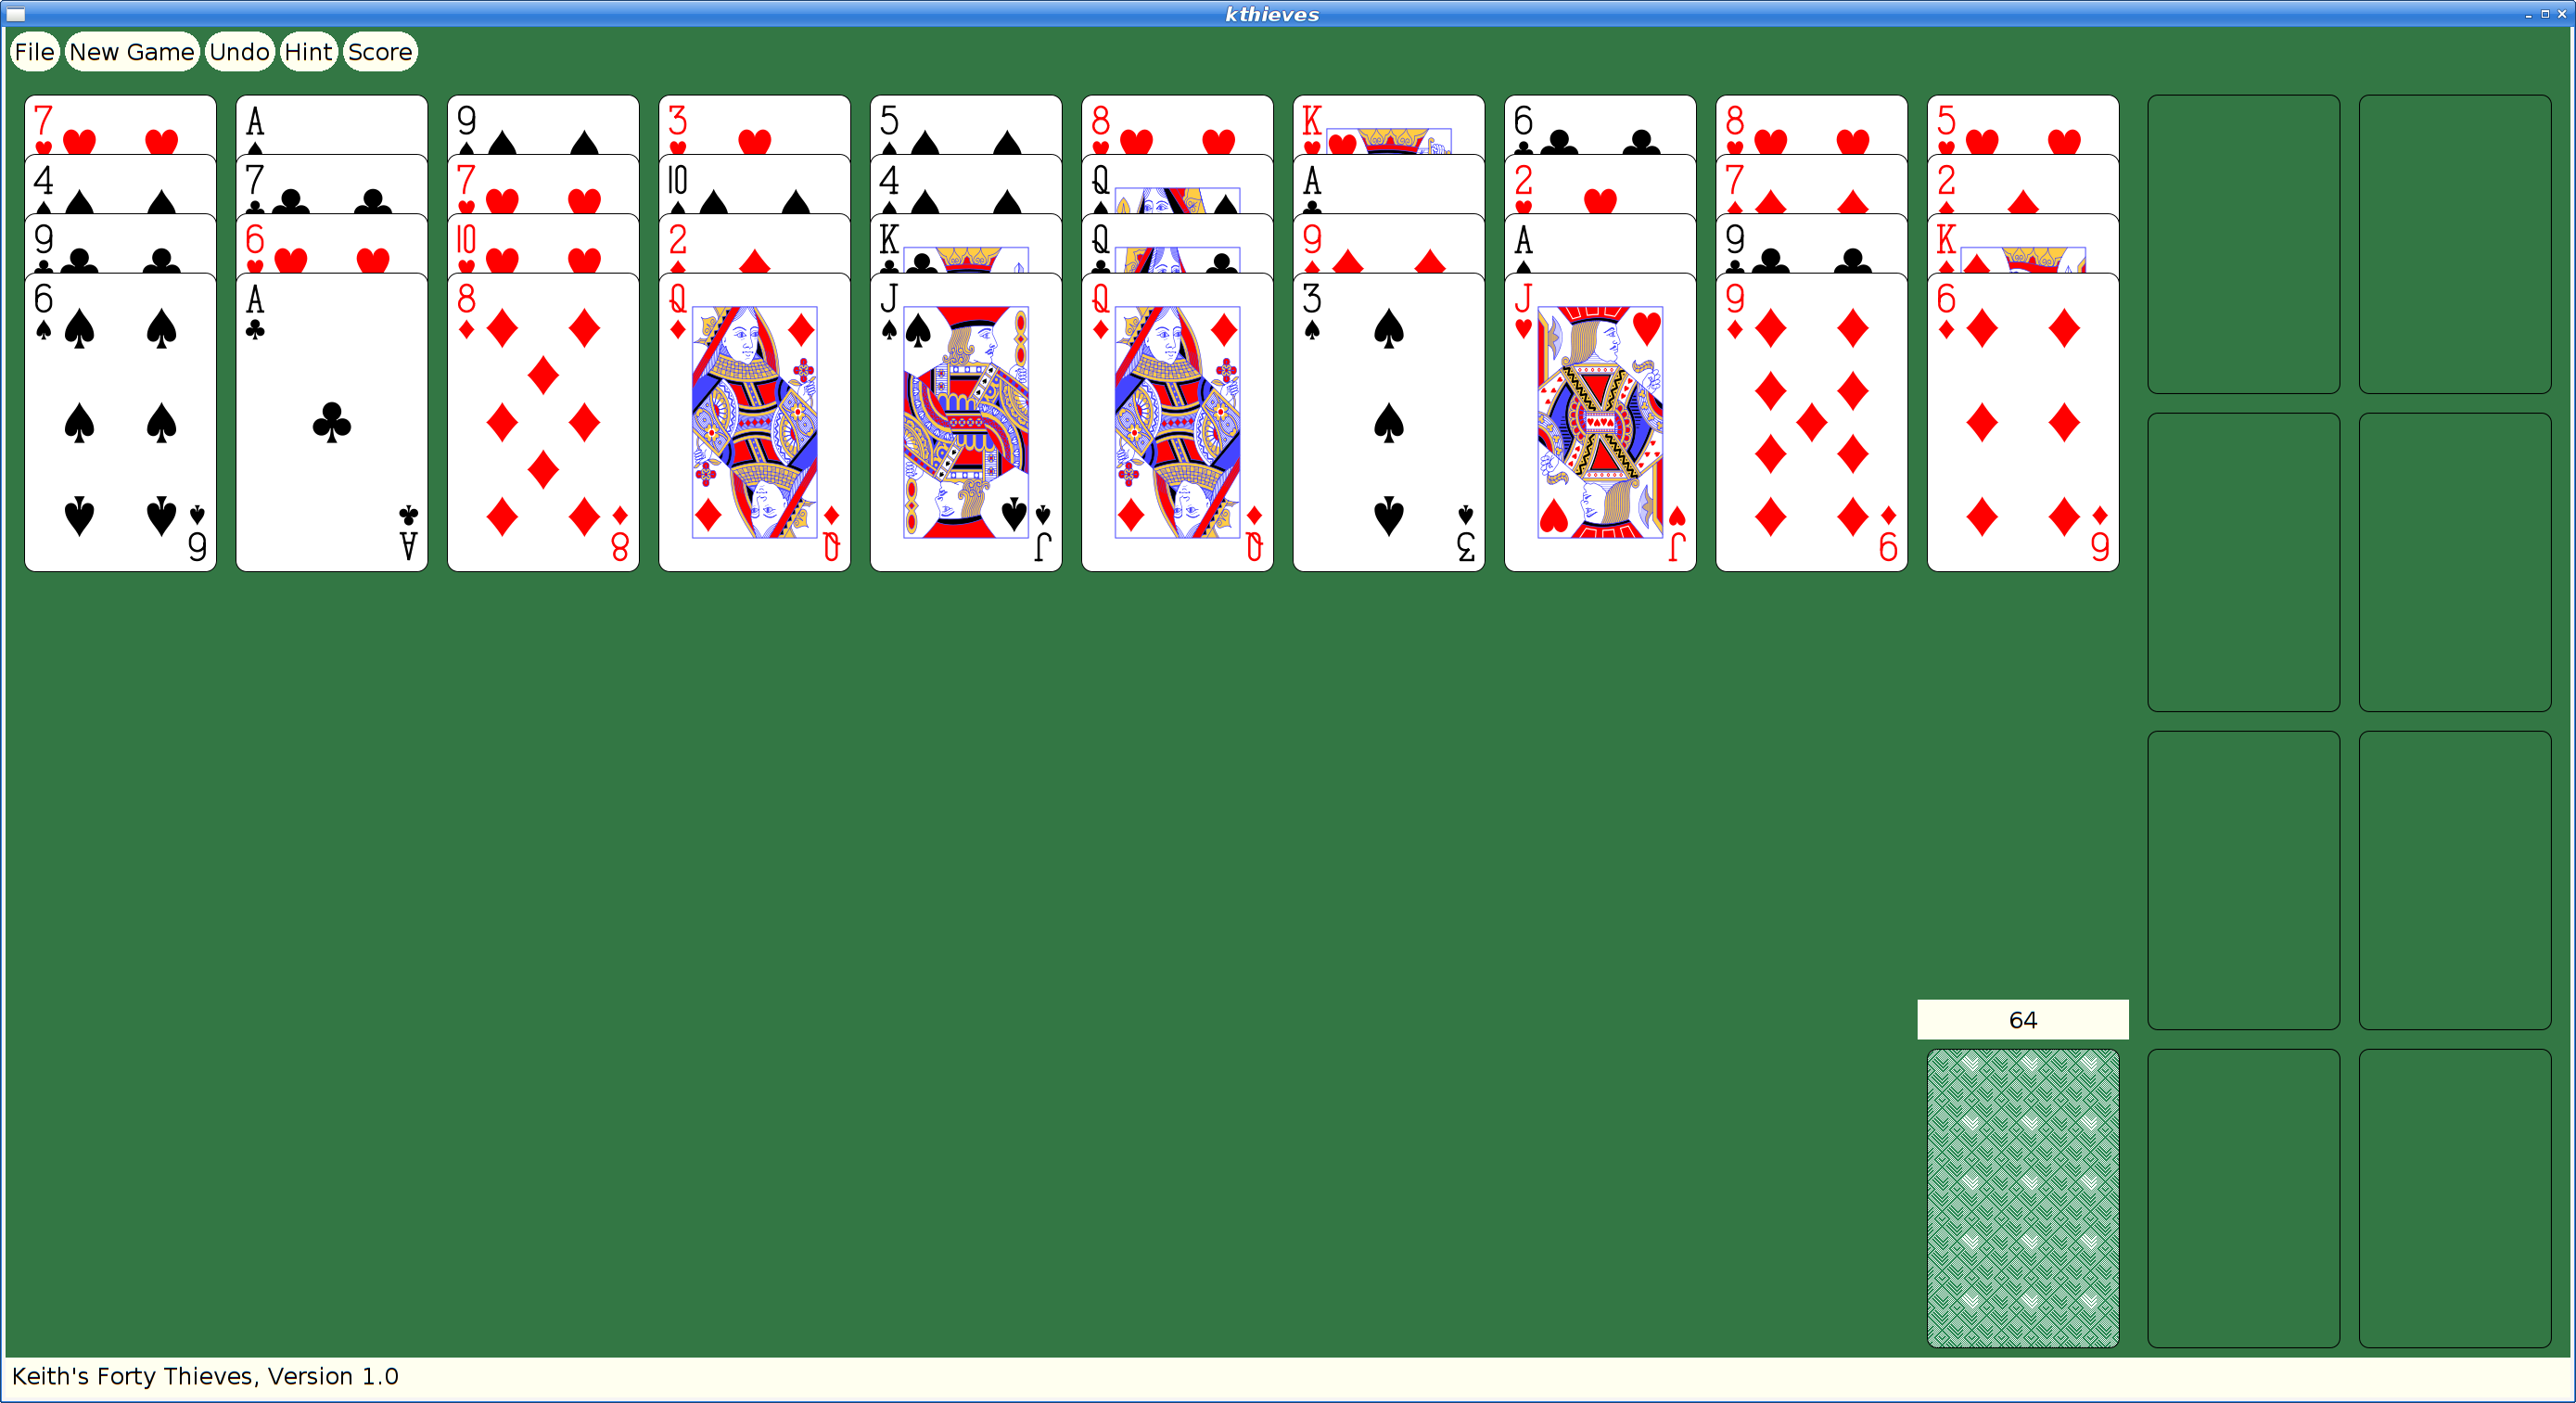
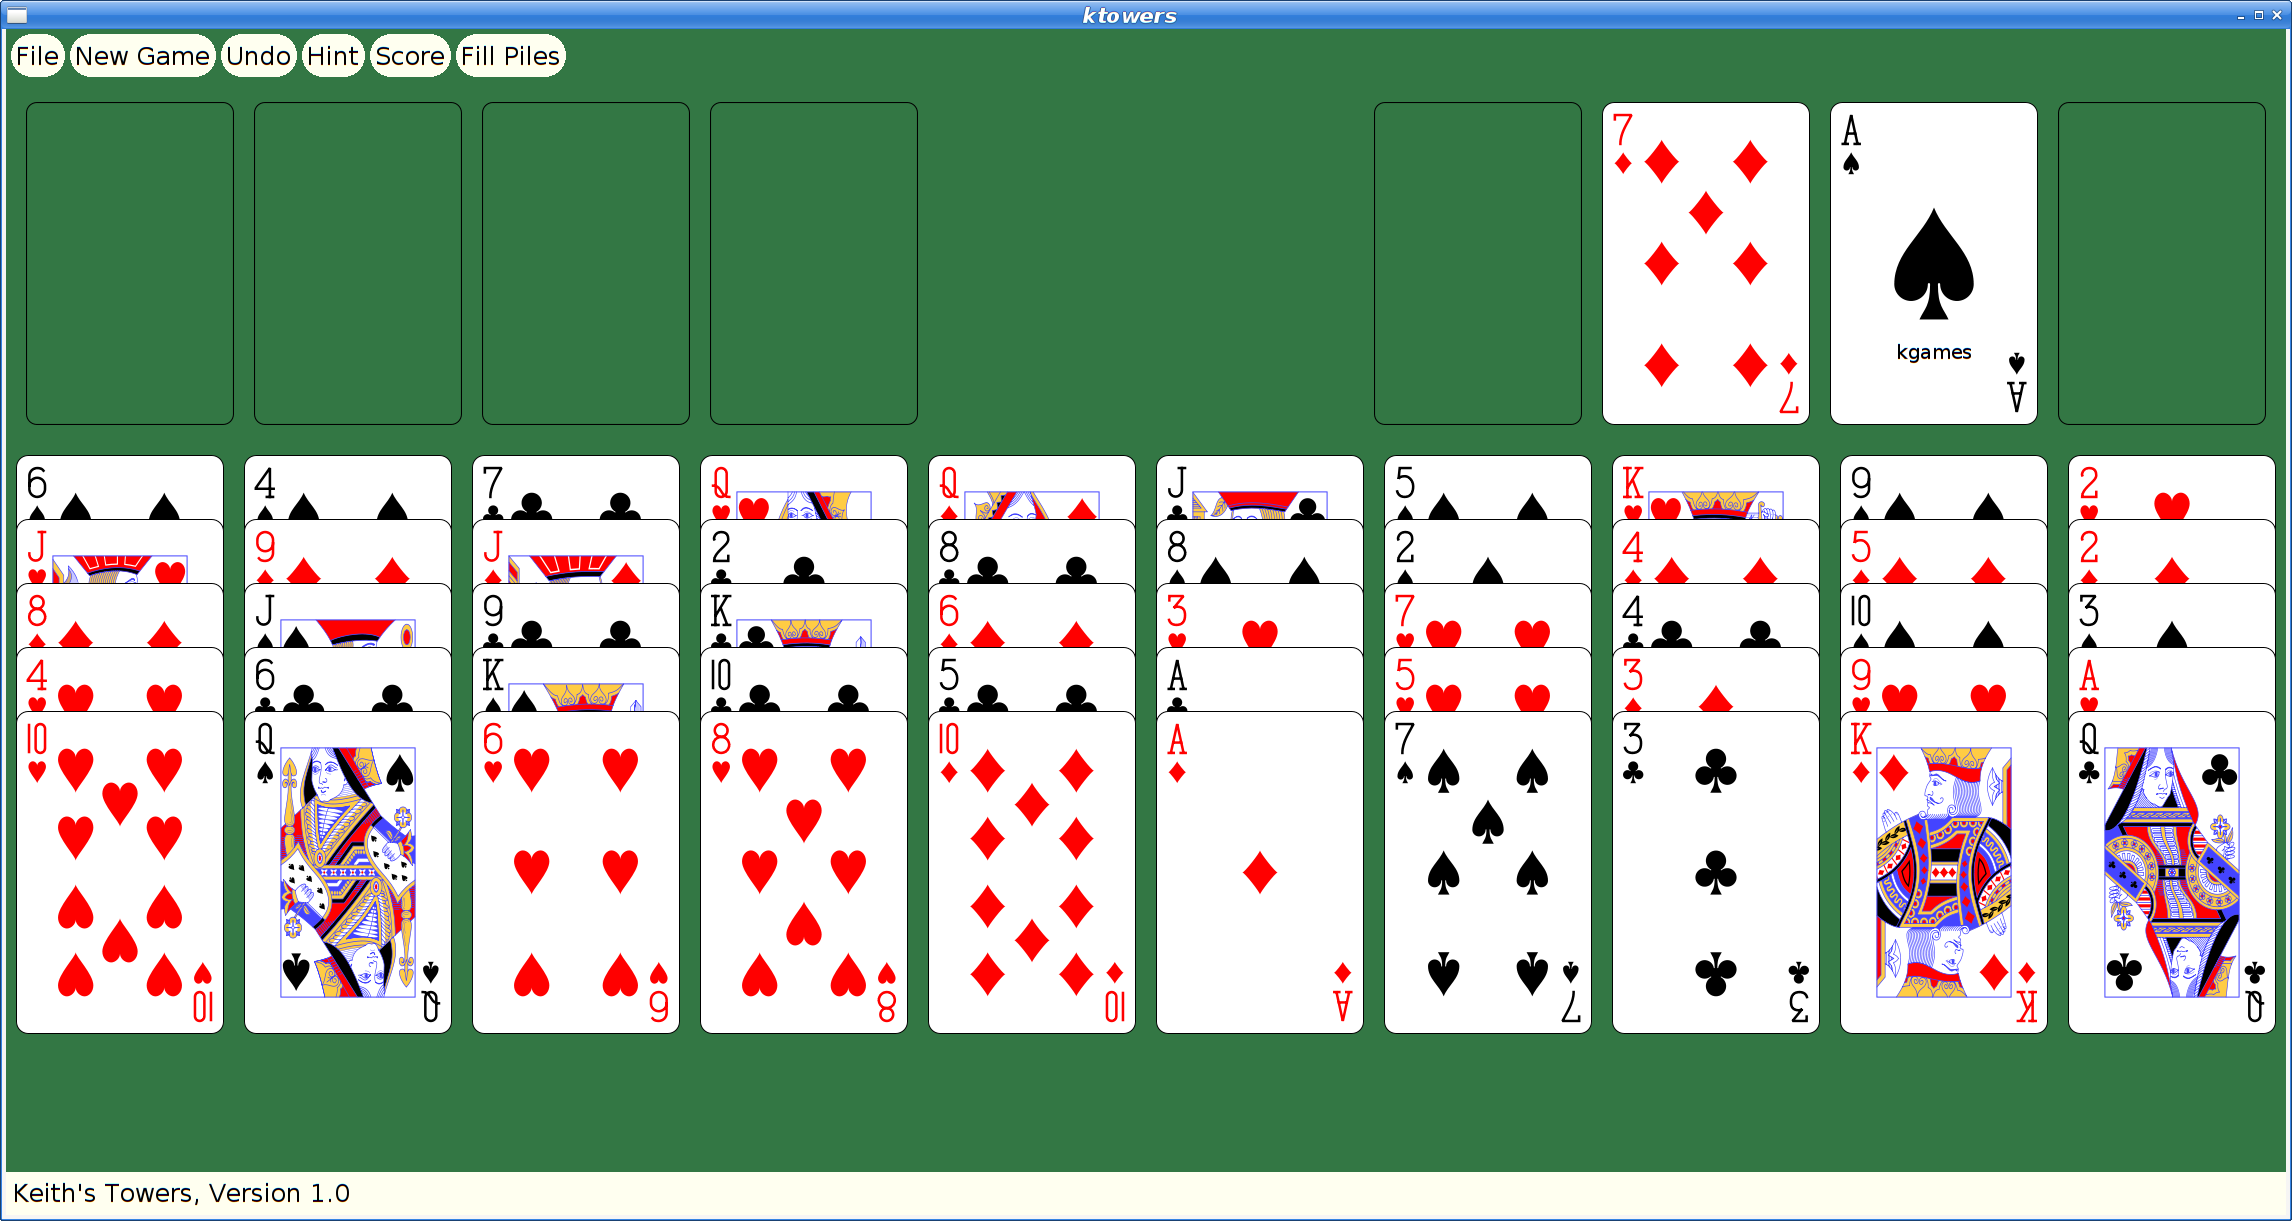
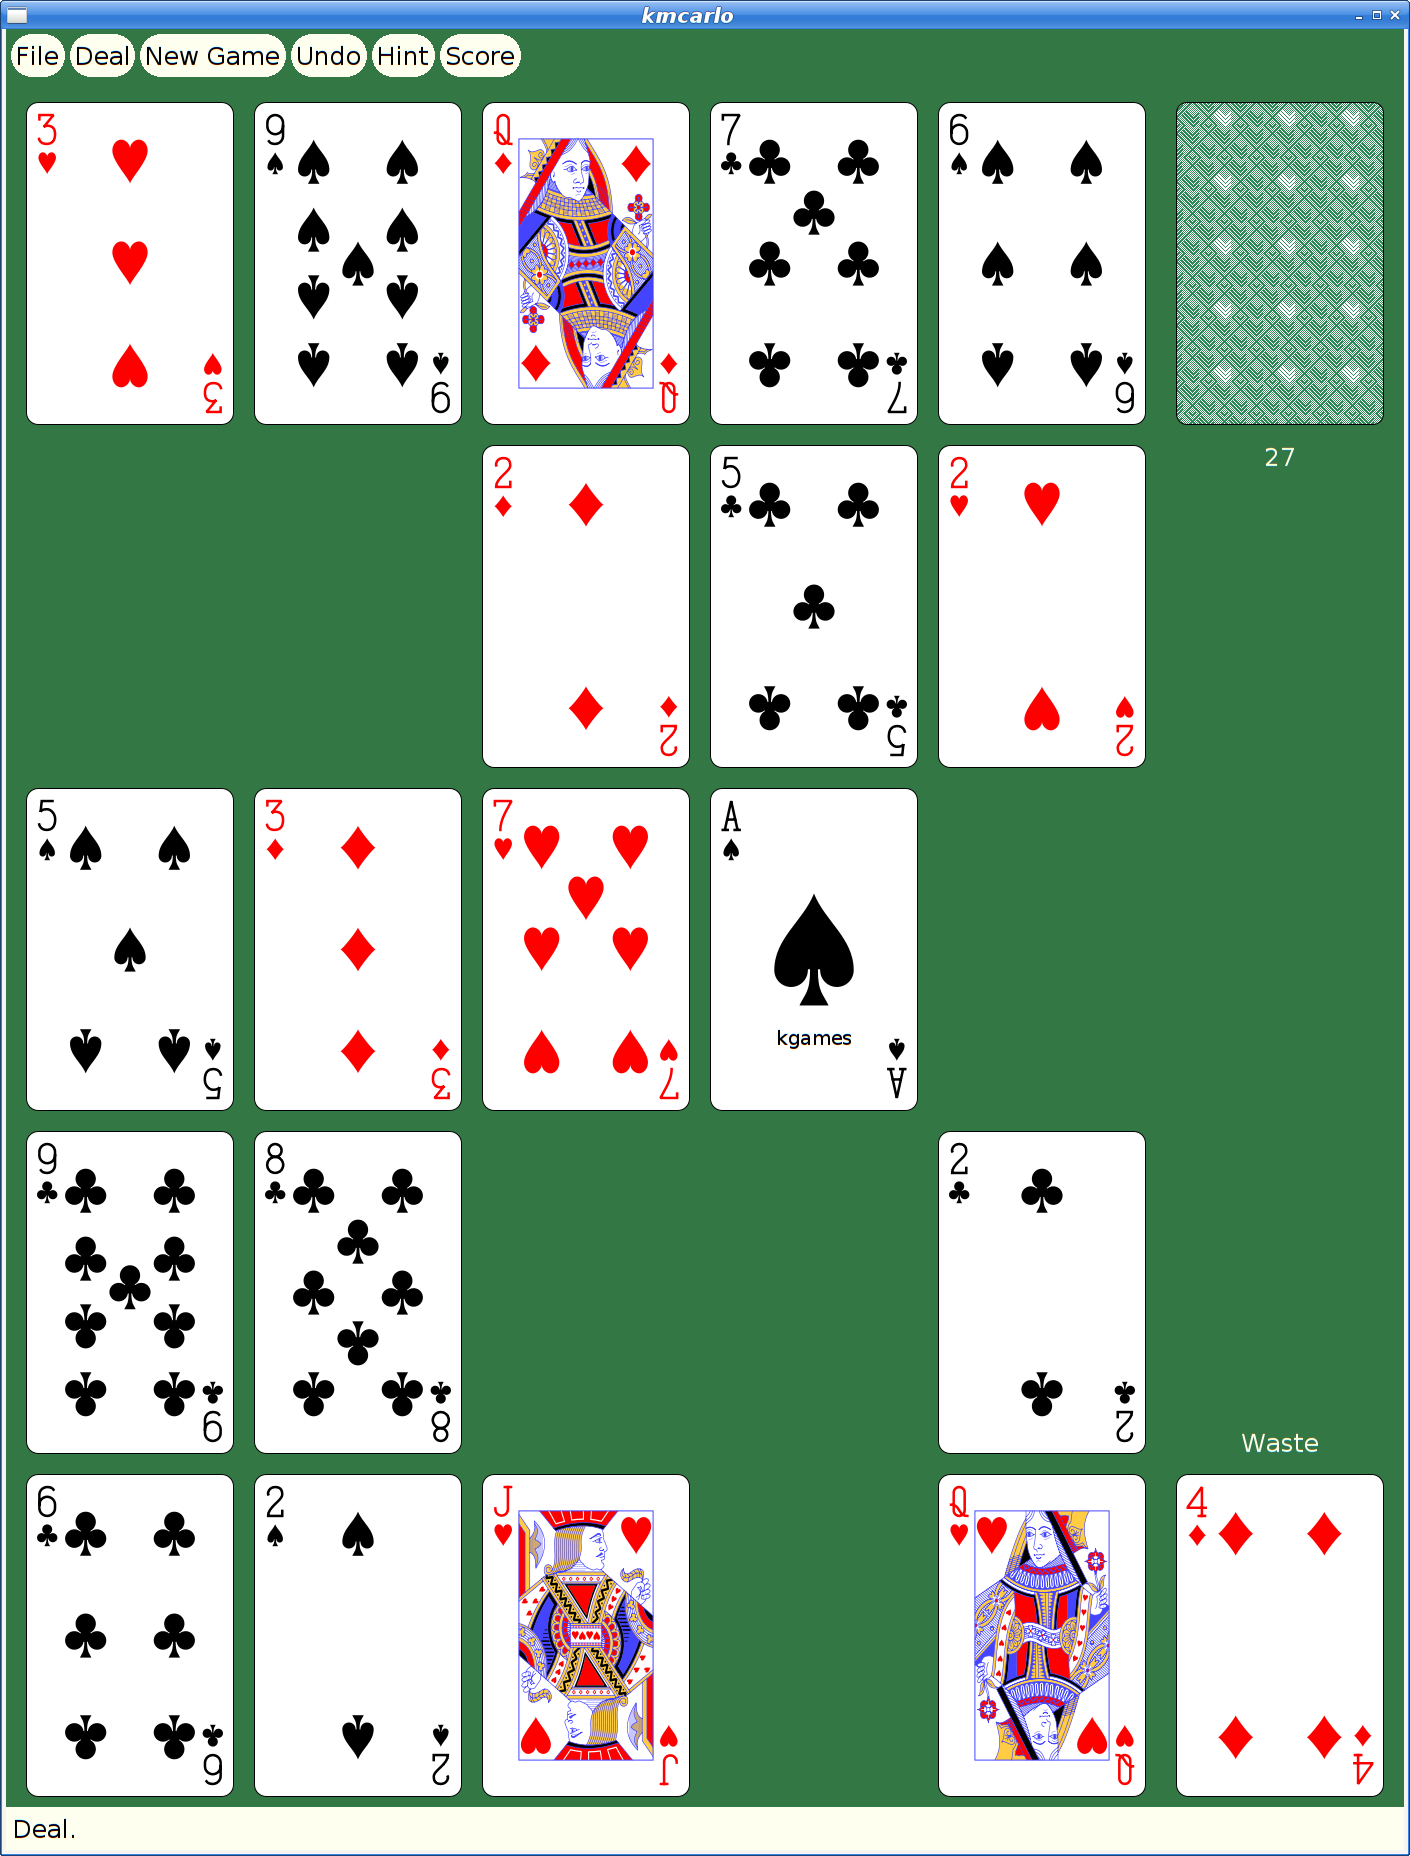
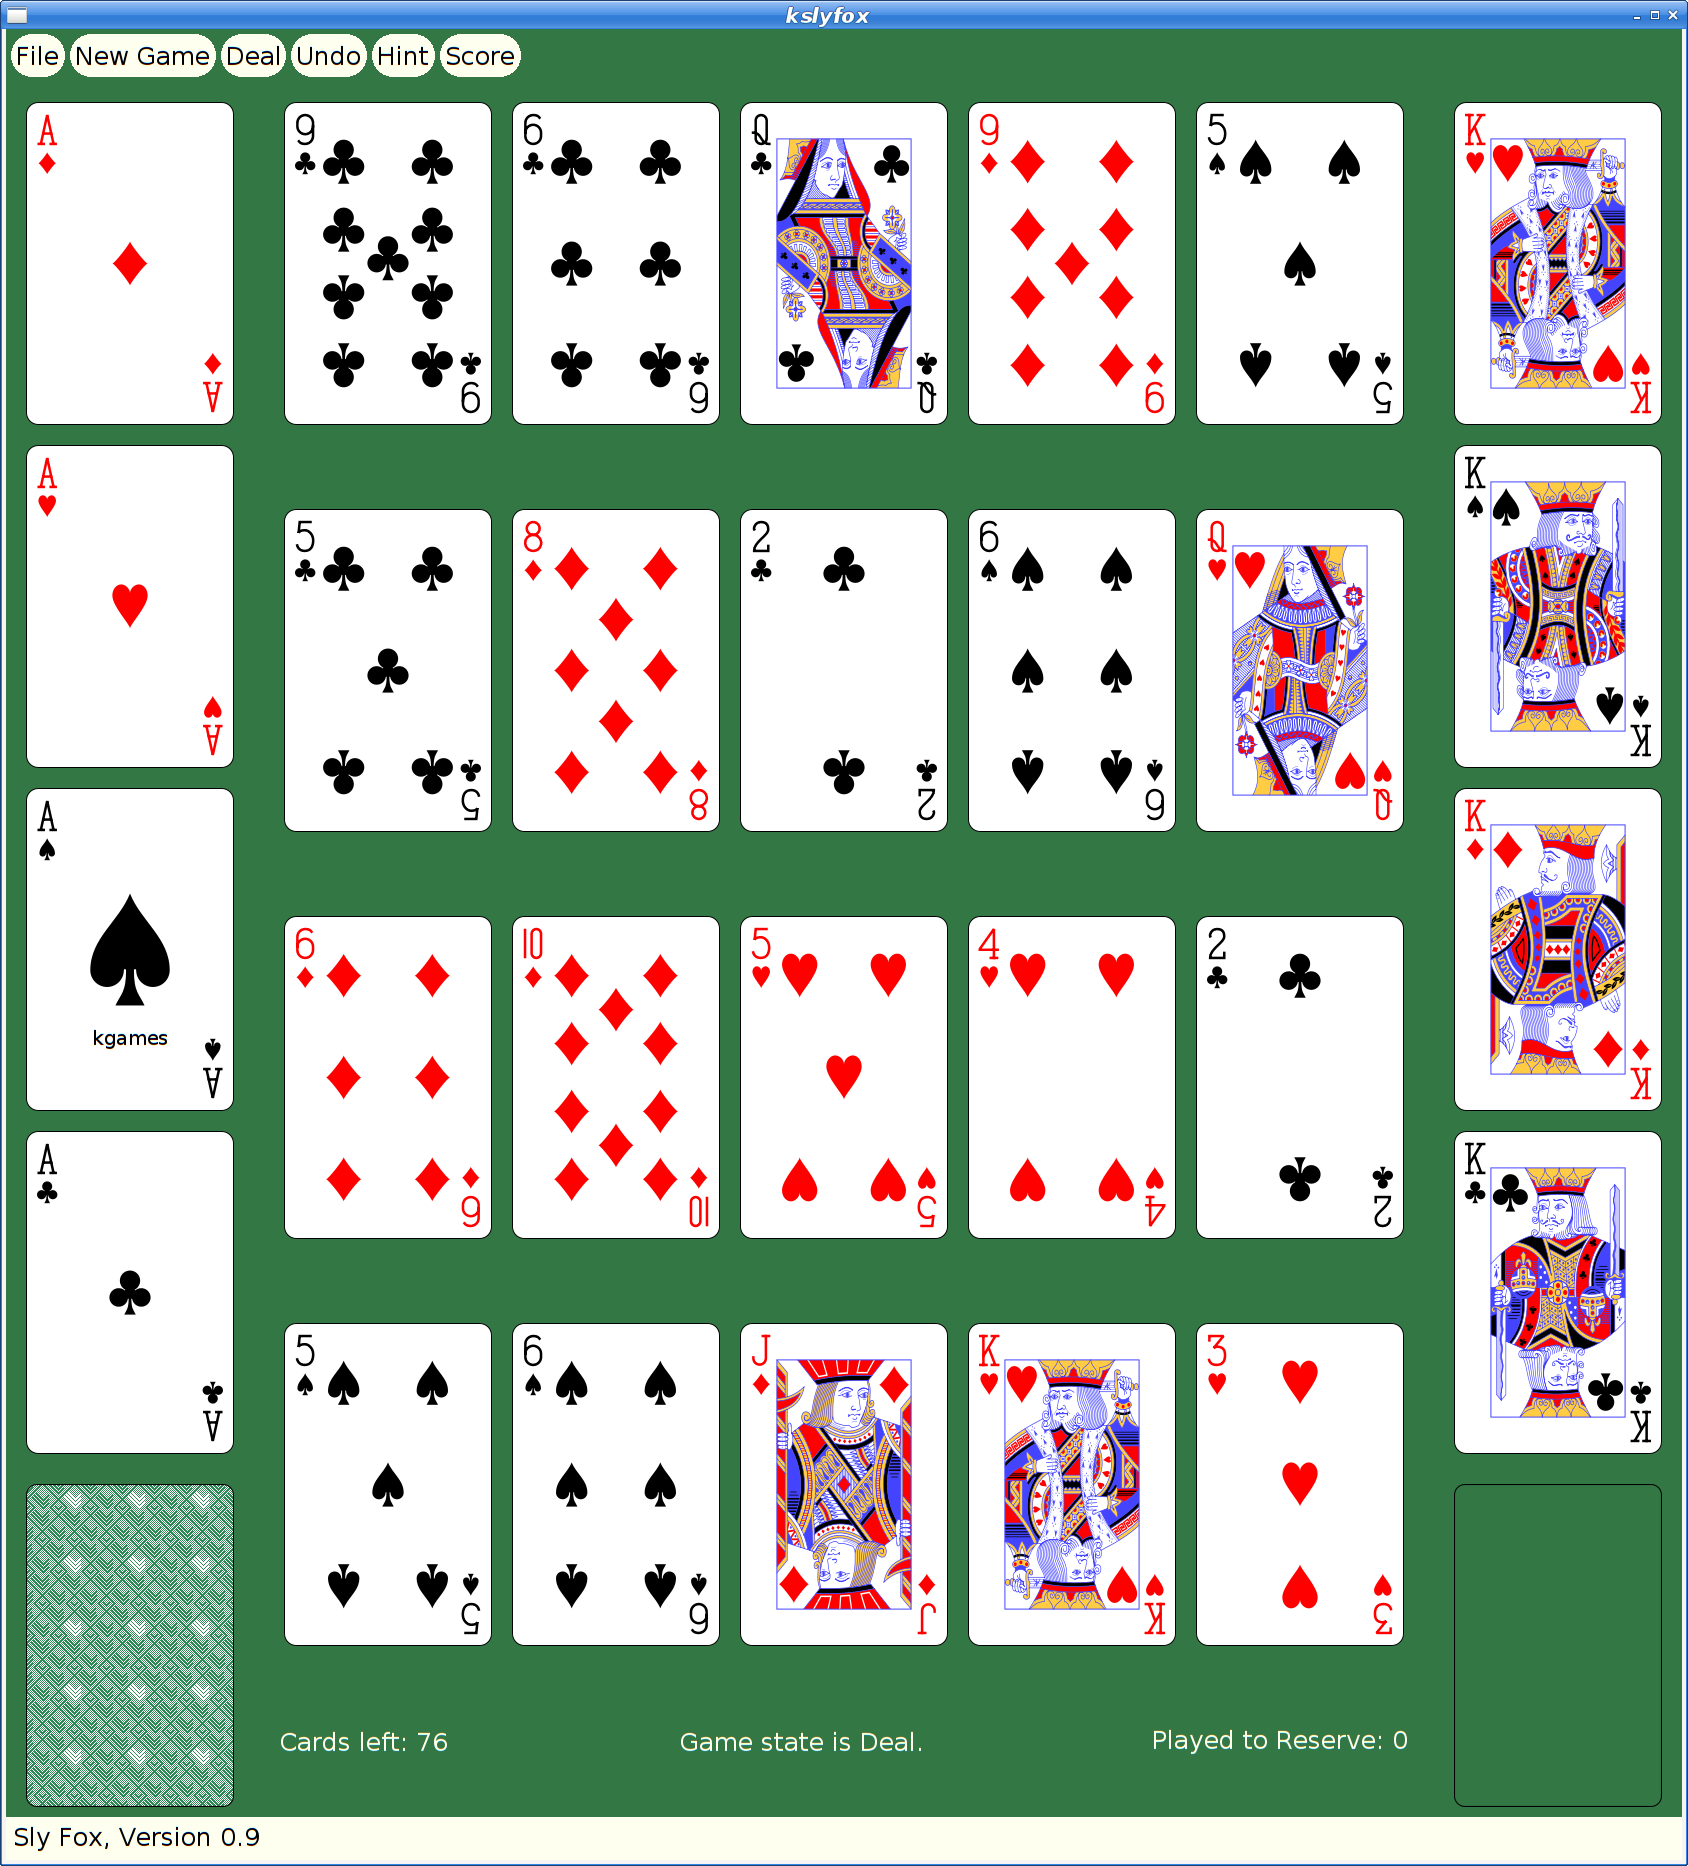
 Here is my monthly update covering what I have been doing in the free software world during December 2020 (
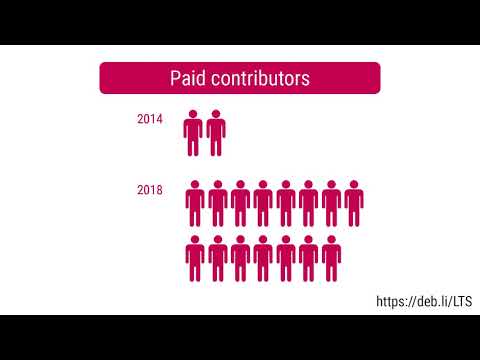

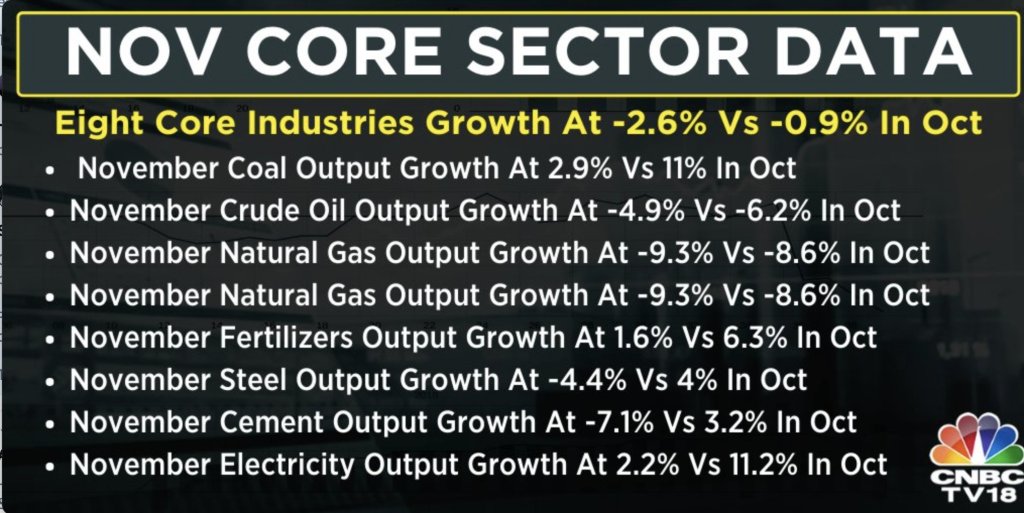

 On doing 540 no-source-change source-only uploads in two weeks
So I've been doing 540 no-source-change source-only uploads in the last two weeks
and am planning to do 3000 more in January 2021. We'll see how that goes
 Let me explain what I have been doing and why.
So,

 Creating Beautiful Github Streaks
Github streaks are a pretty fun and harmless way of visualizing your
contributions on github or gitlab. Some people use them to brag a little, some
companies use them to check out potential candidates. It s all good as long as
everyone is aware how easily you can manipulate them.
In order to fake a commit date in the past, you have to set the
 I know, I m for sure not the first one to discover this kind of thing, but it
was a fun afternoon project anyways!
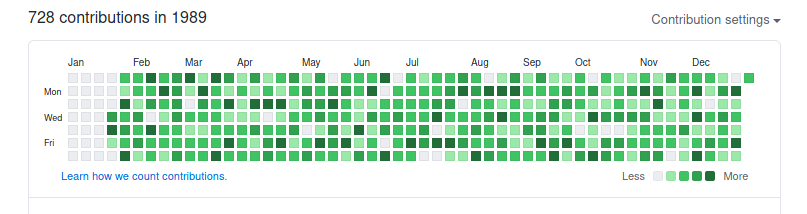 I know, I m for sure not the first one to discover this kind of thing, but it
was a fun afternoon project anyways!
 I am no longer maintaining
 <



 The blue boxes are the very same found on GNOME desktop sessions
while the white ones are currently only found on
phones.
 The virtual version of the annual CCC Congress is underway and feels like a huge playground. Things are bumpy but the participants are still having fun. Of course, we have IRC as a save heaven. That always works.
The virtual world (which is the only thing the sold out tickets are needed for) is really fun. It feels like debugging a DOS game in the 80/90s. Not much works but it is engaging enough to keep poking at things.
 The data formats are 2020 though, the main