Search Results: "xam"

4 June 2010

Russell Coker: Securely Killing Processes

Joey Hess wrote on Debian-devel about the problem of init scripts not doing adequate checks before using the data from a PID file under /var/run to determine which process to kill [1]. Unfortunately that still doesn t quite solve the problem, there is still the issue of a race condition causing a process to die while you are doing the checks and then be replaced by another process. Below I have included the source code to a little program that will repeatedly fork() until it finds a particular PID and then have it s child call sleep(). So you can run a command such as kill -9 1234 ; ./a.out 1234 and then have this program take over the PID 1234. From testing with this it seems that when you have a shell with it s current working directory as /proc/1234 then once process 1234 is killed the current directory is empty, ls -l returns 0 entries. This isn t surprising, it s the standard Unix behavior when the working directory is removed. So if a program (or even a shell script) changes directory to /proc/1234 it can then verify all attributes of the process (it s CWD, it s root directory, the executable used to run it, it s UID, GID, supplemental groups, it s SE Linux context, and lots of other things all atomically. The only possibility for confusion is that a process might execute a SETUID or SETGID program or a program that has a label which triggers a SE Linux domain transition. It might also change some attributes without executing a new process, for example by using the setuid(), setgid(), setgroups(), or other similar system calls. For the purposes of killing a process I don t think that the possibility of it changing it s own attributes or executing a new program are serious problems, if you want to kill a process then you probably want to kill it after it has called setuid() etc. It seems to me that it would be useful to have a file named /proc/PID/signal (or something similar) to which you could write a number and then have the kernel send the signal in question to that process. So the commands kill -9 1234 and echo 9 > /proc/1234/signal would give the same result. But you could run the command cd /proc/1234 and then some time later you could run echo 9 > signal and know that you would kill the original process 1234 if it was still running and not some other process that replaced it. What do you think? Is this worthy of adding a new feature to the proc filesystem? The Source Run the following program with a single parameter which is the PID that you want it to take. It will keep looping through the PID space until it gets the one you specify, if the one you specify isn t available (EG you give it 1 as a parameter) then it will run forever. It will take some time to get a result on a slower system. On my P3-900MHz test system it took up to 72 seconds to get a result. #include <stdio.h>
#include <unistd.h>
#include <stdlib.h>
#include <sys/types.h>
#include <sys/wait.h> int main(int argc, char **argv)

if(argc != 2)

printf("Specify the desired PID on the command-line\n");
return 1;

pid_t wanted = (pid_t)atoi(argv[1]);
int rc;
int status;
while((rc = fork()) != wanted && rc != 0)

if(rc == -1)

printf("fork error\n");
return 1;

if(wait(&status) == -1)
printf("wait error\n");

if(rc == 0)

if(getpid() == wanted)

printf("Got pid %d, sleeping\n", wanted);
sleep(200);

return 0;

wait(&status);
return 0;

Christine Spang: Christine Spang: Django form fields with the same name as Python keywords

For work recently I've been doing some Django-related tasks that involve talking to an external API with POSTed forms. Django forms objects are declared by creating a class that inherits from django.forms.Form, with the fields of the form declared by declaring attributes of that class. Which works well and is clean and easy to remember unless the API you're working with requires a field with the same name as a Python keyword, such as return. You can't declare a field like this as an attribute; it will trigger a syntax error. I spent some time scratching my head over this, and came up with this as a workaround after source-diving to find out how Form objects actually work:
from django import forms
class ExampleForm(forms.Form):
    def __init__(self, data=None, files=None, auto_id='id_%s', prefix=None,
            initial=None, errorclass=ErrorList, label_suffix=':', empty_permitted=False, return_url=None):
        forms.Form.__init__(self, data, files, auto_id, prefix, initial,
            errorclass, label_suffix, empty_permitted)
        if return_url is not None:
            self.fields['return'] = forms.CharField(widget=forms.HiddenInput, initial=return_url)
It turns out that the attribute declaration is just syntactic sugar for creating a dictionary of key/value pairs, which is then stored in the fields attribute. So we can monkeypatch in extra values after the translation. Which is somewhat more awkward and ugly, but works in a pinch. Note that I haven't extensively tested what interactions this may cause with other forms code, so use with some caution.

3 June 2010

Petter Reinholdtsen: Sitesummary tip: Listing computer hardware models used at site

When using sitesummary at a site to track machines, it is possible to get a list of the machine types in use thanks to the DMI information extracted from each machine. The script to do so is included in the sitesummary package, and here is example output from the Skolelinux build servers:
maintainer:~# /usr/lib/sitesummary/hardware-model-summary
  vendor                    count
  Dell Computer Corporation     1
    PowerEdge 1750              1
  IBM                           1
    eserver xSeries 345 -[8670M1X]-     1
  Intel                         2
  [no-dmi-info]                 3
maintainer:~#
The quality of the report depend on the quality of the DMI tables provided in each machine. Here there are Intel machines without model information listed with Intel as vendor and mo model, and virtual Xen machines listed as [no-dmi-info]. One can add -l as a command line option to list the individual machines. A larger list is available from the the city of Narvik, which uses Skolelinux on all their shools and also provide the basic sitesummary report publicly. In their report there are ~1400 machines. I know they use both Ubuntu and Skolelinux on their machines, and as sitesummary is available in both distributions, it is trivial to get all of them to report to the same central collector.

1 June 2010

Steve Langasek: bzr-git case study

Robert Collins did a very nice writeup not so long ago of creating a Debian package with bzr-builddeb, but he starts from the assumption that upstream also uses bzr. As we all know, there are many projects that have their upstream sources in a VCS, but don't use bzr. Can we still get reasonable results from bzr-builddeb, including the ability to merge new upstream releases direct from the VCS, if, say, upstream is using git? Yes, we can! Of course, if you're happy with using git as the VCS for your Debian packaging already, there's probably no compelling reason for you to switch to bzr. But if you prefer to use bzr and have been frustrated at having to choose between being able to use the VCS client of your choice for your packages and being able to use your VCS client to access upstream revision history, read on. Thanks to the fine work of Jelmer Vernooij and friends, bzr-git has been usable for a while if you just want to track the default git branch. But what if you care about tracking multiple upstream branches? Enter bzr git-import, which we'll use to set up a bzr repo from scratch for our cifs-utils package, with a full import of all the branches of upstream's git tree. First we do some work to set up a shared bzr repository. As long as we're going to the effort of mirroring all the git branches, we probably want to publish them for other people to use, so we make sure our bzr repository is reasonably configured for sharing data between branches:
$ bzr init-repo --no-trees cifs-utils.server
Shared repository (format: 2a)
Location:
  shared repository: cifs-utils.server
$ cd cifs-utils.server
Then we use bzr git-import, provided by the bzr-git plugin, to do a full import of the upstream branches into a cleverly named subdirectory:
$ bzr git-import git://git.samba.org/cifs-utils.git upstream
[/                   ] Counting objects: 181, done.
Now we create our own local 'trunk' for the package, by branching from the upstream tag matching the release version we're going to package.
$ bzr branch -r tag:cifs-utils-4.0rc1 upstream/HEAD trunk
Branched 42 revision(s).
Do a little more prep work for future branches...
$ mkdir branches
And that's it. Now we have a bzr repo locally that we can push out to our hosting server of choice (N.B.: we could do this all directly on the server, but alioth doesn't currently have bzr-git installed):
$ rsync -az . alioth.debian.org:/bzr/pkg-samba/cifs-utils/
$
Now that we have a bzr repository, it's time to get ourselves a working directory and do some packaging. We're probably going to work with multiple branches locally as well, so we create another shared repository for local use, and get a copy of the trunk branch we created before.
$ bzr init-repo cifs-utils
Shared repository with trees (format: 2a)
Location:
  shared repository: cifs-utils
$ cd cifs-utils
$ bzr co bzr+ssh://bzr.debian.org/bzr/pkg-samba/cifs-utils/trunk
Now we grab the upstream tarball, and whip up some quick packaging with (what else?) debhelper 7:
$ wget ftp://ftp.samba.org/pub/samba/cifs-utils/cifs-utils-4.0rc1.tar.bz2
$ ln -s cifs-utils-4.0rc1.tar.bz2 cifs-utils_4.0~rc1.orig.tar.bz2
$ cd trunk
$ mkdir -p debian/source
$ echo '3.0 (quilt)' > debian/source/format
$ echo 7 > debian/compat
$ cp /usr/share/doc/debhelper/examples/rules.tiny debian/rules
$ dch --package cifs-utils --versio 4.0~rc1-1 --create 'Initial package'
Create debian/control by hand, generate an initial source package, and import it into bzr with bzr-builddeb.
$ debuild -uc -us -S -i
$ rm -r debian
$ bzr import-dsc ../*.dsc
$
Since we want to continue tracking upstream development, we need to periodically sync our bzr import of the git tree.
$ bzr git-import git://git.samba.org/cifs-utils.git bzr+ssh://bzr.debian.org/bzr/pkg-samba/cifs-utils/upstream
$
And when we find a new upstream version in that import that we want to package, bzr-builddeb makes this a snap, too.
$ cd cifs-utils
$ wget ftp://ftp.samba.org/pub/samba/cifs-utils/cifs-utils-$version.tar.bz2
$ cd trunk
$ bzr merge-upstream --v3 --version $version_with_epoch \
    ../cifs-utils-$version.tar.bz2 -r tag:cifs-utils-$version \
    bzr+ssh://bzr.debian.org/bzr/pkg-samba/cifs-utils/upstream/HEAD
No distribution specified, and no changelog, assuming 'debian'
Committing to: /tmp/tmpbzOVMs/upstream/
Committed revision 2.
All changes applied successfully.
The new upstream version has been imported.
You should now review the changes and then commit.
$ bzr diff
<review changes>
$ bzr commit -m "merge upstream $version"
Committing to: bzr+ssh://bzr.debian.org/bzr/pkg-samba/cifs-utils/trunk
modified debian/changelog
Committed revision 50.
$
And that's it! It's exciting to see signs of real interoperability between DVCSes at last. Thanks to everyone who's helped make it possible!

Russell Coker: Can SE Linux Implement Traditional Unix Users and Groups?

I was asked by email whether SE Linux could implement traditional Unix users and groups. The Strictly Literal Answer to that Question The core of the SE Linux access control is the domain-type model where every process has a domain and every object that a process can access (including other processes) has a type. Domains are not strongly differentiated from types. It would be possible to create a SE Linux policy that created a domain for every combination of UID and GID that is valid for a user shell given that such combinations are chosen by the sysadmin who could limit them to some degree. There are about 2^32 possible UIDs and about 2^32 possible GIDs, as every domain is listed in kernel memory we obviously can t have 2^64 domains, but we could have enough to map a typical system that s in use. Of course the possible combinations of supplemental groups probably makes this impossible for even relatively small systems, but we can use a simpler model that doesn t emulate supplemental groups. For files there are more possible combinations because anyone who is a member of a group can create a SETGID directory and let other users create files in it. But in a typical system the number of groups is not much greater than the number of users the maximum number of groups is typically the number of users plus about 60. So if we had 100 users then the number of combinations of UID and GID would be something like 100*(100+60)=16,000 it should be possible to have that many domains in a SE Linux policy (but not desirable). Then all that would be needed is rules specifying that each domain (which is based on a combination of UID and GID) can have certain types of access to certain other types based on them having either the same UID or the same GID. Such a policy would be large, it would waste a lot of kernel memory, it would need to be regenerated whenever a user is added, and it s generally something you don t want to use. No-one has considered implementing such a policy, I merely describe it to illustrate why certain configuration options are not desirable. The rest of this post is about realistic things that you can do with SE Linux policy and how it will be implemented in Debian/Squeeze. My previous post titled Is SE Linux Unixish? addresses this issue at a more conceptual level and also considers MAC vs DAC [1]. The History of mapping Unix Accounts to SE Linux Access Control In the early releases of SE Linux (long before it was included in Fedora) every user who could login to a system needed to have their user-name compiled into the policy. The policy specified which roles the user could access, the roles specified which domains could be accessed, and therefore what the user could do. The identity of files on disk was used for two purposes, one was logging (you could see who created a file) and the other was a permission check for the SE Linux patched version of Vixie cron which would not execute any command on behalf of a user unless the identity on the crontab file in the cron spool matched the identity used to run it this is an analogy of the checks that Vixie cron makes on the Unix UID of the crontab file (some other cron daemons do fewer checks). Having to recompile policy source every time you added a user was annoying. So a later development was to allow arbitrary mappings between Unix account names and SE Linux Identities (which included a default identity) and another later development was to have a utility program semanage to map particular Unix account and group names to SE Linux identities. This was all done years ago. Fedora Core 5 which was released in 2006 had the modular policy which included these features (apart from mapping Unix groups to SE Linux identities which was more recent). Fedora Core 5 also introduced MCS which was comprised of a set of categories that a security context may have. The sysadmin would configure the set of categories that each account would have. A recent development has been a concept named UBAC (User Based Access Control) which basically means that a process running directly on behalf of a regular user (IE with a SE Linux identity that s not system_u) can only access files that have an identity of system_u or which have the same identity as the process. This means that you can only access your own files or system files not files of other users which may have inappropriate Unix permissions. So for example if a user with a SE Linux identity of john gives their home directory the Unix permission mode of 0777 then a user with a SE Linux identity of jane can t access their files. Of course this means that if you have a group of people working together on a project then they probably need to all have the same Identity and in practice you would probably end up with everyone having the same identity. I ve given up on the idea of using UBAC in Debian. The Current Plan for Users and SE Linux Access Control in Debian My plan is to have things work in Squeeze in much the same way as in Lenny. You have a SE Linux identity assigned to a login session and everything related to it (including cron jobs) based on the Unix account name or possibly the Unix group name (if there are login entries for both the user-name and the group-name then the user-name entry has precedence). The mapping between Unix accounts and SE Linux identities is configured by the sysadmin and SE Linux identities don t matter much for the Targeted configuration (which is what most people use). The identity determines which roles may be used and also has a limit on the MCS categories. The MCS categories are also specified in the login configuration which has to be a sub-set of the categories used by the identity record. So for example the following is the output of a couple of commands run on a Debian/Unstable system. They show that the test Unix account is assigned a SE Linux identity of staff_u and an MCS range of s0-s0:c1 (this means it creates files by default at level s0 and can also write to other files at that level, but can also have read/write access to files at the level s0:c1 ). The staff_u identity (as shown in the output of semanage user -l can be used with all categories in the set s0:c0.c1023 where the dot means the set of categories from c0 to c1023 inclusive) but in the case of the test user only one category will be used. The test group however (as expressed with %test ) is given the identity user_u and is not permitted to use any categories.
# semanage login -l
Login Name    SELinux User    MLS/MCS Range           
%test         user_u          s0                     
__default__   unconfined_u    s0-s0:c0.c1023         
root          unconfined_u    s0-s0:c0.c1023         
system_u      system_u        s0-s0:c0.c1023         
test          staff_u         s0-s0:c1               
# semanage user -l
             Labeling   MLS/       MLS/                         
SELinux User Prefix     MCS Level  MCS Range         SELinux Roles
root         sysadm     s0         s0-s0:c0.c1023    staff_r sysadm_r system_r
staff_u      staff      s0         s0-s0:c0.c1023    staff_r sysadm_r
sysadm_u     sysadm     s0         s0-s0:c0.c1023    sysadm_r
system_u     user       s0         s0-s0:c0.c1023    system_r
unconfined_u unconfined s0         s0-s0:c0.c1023    system_r unconfined_r
user_u       user       s0         s0                user_r
I hope to get the policy written to support multiple user roles in time for the release of Squeeze. If I don t make it then I will put such a policy on my own web site and try to get it included in an update. The policy currently basically works for a Targeted configuration where the users are not confined (apart from MCS). How MMCS Basically Works The vast majority of SE Linux users run with the MCS policy rather than the MLS policy. For Debian I have written a modified version of MCS that I call MMCS. MMCS is mandatory (you can t relabel files to escape it) and it prevents write-down. If a process has the range s0-s0:c1,c3 then it has full access to files labelled as s0, s0:c1, s0:c3, and s0:c1,c3 and any files it creates will be labeled as s0. If a process has the range s0:c1-s0:c1,c3 then it has read-only access to files labelled as s0 and s0:c3 and read-write access to files labelled as s0:c1 and s0:c1,c3. This means that any secret data it accesses that was labelled with category c1 can t be leaked down to a file that is not labelled with that category. Now MCS currently has no network access controls, so there s nothing stopping a user from using scp or other network utilities to transfer files. But that s the way with most usable systems. I don t think that this is necessarily a problem, the almost total lack of network access controls in a traditional Unix model doesn t seem to concern most people. Now to REALLY Answer that Question SE Linux is a Mandatory Access Control (MAC) system, this makes it inherently different to a Discretionary Access Control (DAC) system such as traditional Unix access controls. Unix permissions are based on each file having a UID, a GID, and a set of permissions and each process having a UID, a GID, and a set of supplementary GIDs. If a user runs a setuid or setgid program then the process will have extra privileges. It also has a lot of stuff that most people aren t aware of such as real vs effective UIDs, the tag bit, setgid directories, and lots more including some quite arbitrary things like making ports <1024 special. SE Linux is based on every object (process, file, socket, etc) having a single security label which includes an identity, a role, a type, and a sensitivity label (MCS categories or an MLS range). There is no support for an object to have more than one label. The SE Linux equivalent to setuid/setgid files is a label for a file which triggers a domain transition when it s executed. This differs from setuid files in that the domain transition is complete (the old privileges can t be restored) and the transition is generally not to a strict super-set of the access (usually a different sub-set of possible access and sometimes to lesser access). These differences are quite fundamental. So really SE Linux can t implement traditional Unix access control. What SE Linux is designed to do is to provide a second layer of defense and to also provide access controls that have different aims than that of Unix permissions such as being mandatory and implementing features such as MLS.

Julien Danjou: Thoughts and rambling on the X protocol

Two years ago, while working on awesome, I joined the Freedesktop initiative to work on XCB. I had to learn the arcane of the X11 protocol and all the mysterious and old world that goes with it. Now that I've swum all this months in this mud, I just feel like I need to share my thoughts about what become a mess over the decades. When I was unborn

the Toto band were releasing their song "Africa" and some smart guys were working on a windowing system: the X Window System (this is its full name) which therefore has a (too) long history. The latest version of its protocol, the 11th one, has been designed in the 80's. You can learn more about the history in the Wikipedia article about X. In 2010, we still listen disco music and we still use various protocols designed in the 80's and even before X. Music have evolved, protocols have evolved, and so did X11. The problem is that X11 did not evolve that well. The guys at MIT-and-some other-places-with-very-smart-people-in-it created X version 1 in 1984, and updated it until X version 11 (the one we're still using) in 1987. Eleven version in 3 years, that was following the "release early, release often" model. But I don't know why, it just stopped to happen for the last 23 years1. I don't know what changes have been made in the first 11 major versions of the X protocol, but I'm rather sure we should have deserve a couple of major version updates this last 2 decades. In my humble opinion, X11 was not designed to live 23 years. But hey, I'm not blaming anyone here: I was 4 years old and playing Lego when they released this latest version of the X protocol, so there is little chance I'd have done something better.

1. That's not totally true: they added (and then deprecated) many extensions. We won't fix. We'll work-around.

That is probably one of the guideline of the X protocol for the last years. And don't misread me: I'm not bashing anyone thereafter. Since the X11 protocol was aging, the X guys started to add extensions. They added tons of them over the years. This, in application of one of the early principles of X:

It is as important to decide what a system is not as to decide what it is. Do not serve all the world's needs; rather, make the system extensible so that additional needs can be met in an upwardly compatible fashion.

All of them with no exception were added because, bad luck, the X11 protocol did not anticipated the things that happened in the last 23 years, like video, OpenGL, multiple monitors, or the pleasure to draw oval windows. Some of this extensions are still in use, while some of them have been dropped. While this is not a bad thing to extends the protocol, it seems like a bad thing to try to fix the protocol with for example the XFixes extension, even with all the good intentions Keith Packard might have in his greatness. Actually it's even worst than you think

The X11 protocol (without extensions) defines about 120 types of requests: create a window, move a window, etc. Nowadays, there's at least 25 % of them which are useless: usage of server-side font, or the drawing of squares and polygon, are unused by any modern application or toolkit. All of this is superseded by requests from extensions, like the XRender one. The handling of multiple monitors displays has totally been screwed up. X11 has been designed to work in Zaphod mode (independent monitors). But Xinerama, and nowadays XRandR have replaced it up: recent X servers (released after ~2007) does not support Zaphod mode anymore, even if it's a core piece of the X11 protocol. Worst: on many requests, there's limitation or design flaws, like described in this document: Why X Is Not Our Ideal Window System by DEC researchers. We'll add more broken standard on top of that

Following its early principle, X does not define policies but only mechanisms, which seems like a good thing, Consequently, people started writing specifications to determine a number of stuff and dogmas: ICCCM. That was 22 years ago in 1988. It's useless to add that many things in this specification are now obsolete, useless, or that it misses many modern stuff. I was not the only one to think that. The people from what will be the major desktop environments, KDE and GNOME, saw that too in the 90's while I was learning to count. So they wrote EWMH, another standard that comes on top of ICCCM and extends it with nifty features like maximization, full screen mode, etc. The problem is that this standard has also been written by narrow-minded people who at that time, were working on GNOME or KDE (and maybe others). This desktop environments were having and still have some strong concepts of how should work a desktop: "it should have work-spaces", "a window is only on one workspace", "we only see a workspace at a time", "you do not have multiple screens", etc. Dude, we don't care: we have toolkits!

This vision of how the desktop should work have now been written in marble in all applications and libraries implementing EWMH, like GTK+ or Qt. Nowadays, everybody forgot about all of this standards. Toolkits have implemented this, circumvented the X11 protocol limitation and flaws, and nobody wants to look back. Like all standards, obviously some people implemented them badly. This had some side effects, like OpenOffice acting like a pager. We don't look back? Worst, we forgot where we came from!

With all these layers of bad designed standards, the desktop continued to evolve for more than a decade. They continued to add more standard, the more recent ones being based on D-Bus like the Desktop Notification Specification or the latest Status Notifier Specification developed by KDE. The Status Notifier is a new implementation of the good old system tray based on XEmbed, using D-Bus instead of the X11 mechanisms, and adding the possibility to show the system tray with something else than icons. This specification draft saw an important issue and design flaw raised by Wolfgang Draxinger in this thread on the XDG mailing-list. What Wolfgang points out, is that X is network-oriented, and D-Bus is not. Therefore, making the Status Notifier specification to use D-Bus to pass system tray messages around is a bad idea, since running a X application from host A on host B will draw the system tray on the wrong host! Apparently, reading the thread, this does not fear some of the KDE people:

of course this is a bizarre corner case not worth much thought. at least that's what you'll think until you actually run into it yourself (be it because you are testing something or because you are setting up some weird kiosk environment).

What Oswald describes as a corner case is an actual common use case for many of us. Of course, YMMV. From my point of view, this is a step back in the wrong direction. But we can conclude that the network part of X is now worthless, to at least KDE. I used to believe in XCB

When I joined Freedesktop, it was to work on XCB, the X C Binding. XCB is a nice, clean, 21st century technology based API to play with the X11 protocol. Its code is auto generated based on XML file describing the protocol. In comparison, Xlib is 80's obfuscated code with almost no comments and hard-coded things. Only a few people can understand some of its corner like its i18n or XKB implementations. And all its code is synchronous. For people not knowing it yet, X is a network protocol where you send request (like a GET in HTTP) and then get a response. Xlib forces the application to wait for the reply to its request, so the application is blocked until the X server sends the reply to the request. XCB on the other hand does not block and allows the application to send a batch of requests, do some other stuff in the mean time, and then gets the replies. It's like your Web browser would send one request at a time to a Web server, and would wait until you downloaded all the images one by one to display the page. In cases where X and all its clients are on the same host, the latency is small and not really visible, therefore the gain for XCB to be asynchronous is small. On slow network however, the gain can be huge, as proved in the rewrite of xlsclients with XCB by Peter Harris. One of the long standing goal of the XCB folks is to kick-out Xlib, to increase speed and hides latency in X11 applications. That requires to port many libraries, because almost none of them (Cairo being an exception) supports XCB. From where I stand, I don't really see if the work is worth it now. The desktop world is trusted by GNOME and KDE, meaning GTK+ and Qt. It seems none of this toolkits are interested to work on XCB, neither on the X protocol. They probably put hard effort in bypassing X limitation and flaws, and they now sit on top of crap of workarounds and broken-by-design-standard implementation. It seems to me they don't want to go back in the layers and improves things. They're too high to go back down and they don't see what the gain would be. Enlightenment with its EFL was the first toolkit to have an XCB back-end with the work of Vincent Torri. Unfortunately, the back-end is not maintained and nobody cares about it. Last time I tried it, it did not compile at all. X12 ?

There's a page called X12 on the Freedesktop wiki, listing all the things that should be fixed some days. Unfortunately, the list continues to grow up an no one talks about working on X12. On the other hand, there's a handset of people trying to work when they will have time on XKB2, the second version of the "let's-try-to-fix-up-the keyboard-part-of-the-protocol-we-wrote-23-years-ago-a-second-time" extension. To me, it does not seem X12 will happen in the next decade neither. Alternative ?

Do we got alternative to X ? There's Wayland, but it's far from being usable. There's DirectFB, but that's not very portable. None seems candidate to replace X some days to me. Anyhow, none of the main toolkits around support this alternative. GTK+ once supported DirectFB, but as far as I know, it is not supported nor works nowadays, as stated by Josselin Mouette. This is why recent versions of the Debian installer have migrated to X for the graphic part, thanks to Cyril Brulebois work. Conclusion

XCB has been around for more than half-a-decade, and very few people showed interested in it. As far as I can see, nobody is interested to use the X protocol and everybody tries to encapsulate it in some higher-level API as soon as possible to stop seeing it. This leads to poorly written application and toolkits, with a lot of ugly hack. All of that also means that starting to write applications and graphical toolkits based on XCB would be a very interesting project, but that would lead to spend too much time learning to circumvent the X protocol flaws, things that have been done in years by predecessors like Qt and GTK+. Major toolkits implementations have almost nothing to win in going back in the dark water of X. I guess most of their folks prefer to work on shiny 3D effects based on your GPS location, rather than redefining better basis for everyone. The manpower available in the X world is very small. Debian lacking of X maintainers is just the summit of that. There is very smart and very competent and skilled guys in the X world, as you can see by simply reading blog posts on Planet Freedesktop for example (me excluded). Unfortunately, there's not enough of them to cover all the things involved in X: input devices, graphics devices, new protocol extension specification and so on. The X server is really late, and it seems most of the developers prefers to work on the server itself than on the protocol behalf. Which is understandable. I'm curious to see where all of that will lead in the upcoming years. I've been walking in the X world hallways for about 3 years now, and I feel desktop alternatives to KDE and GNOME will all die sooner or later. The time were you could choose between a dozen "modern" window managers has passed away. After all, maybe that is simply Darwinism applied to computer software.

31 May 2010

Piotr Galiszewski: The end of the first mockups iteration

Last week was very busy for me. Unfortunately, I spent most of my time no my study duties. An exam session is fast approaching, so in next 3 weeks the situation will not be better. But as I promised, during second part of week, I am working full time on my project.

So, here are missing mockups of future Aptitude Qt GUI:

Changes Preview tab:

Only one "Preview Tab" can be opened at the same time. Changes will be live updated here.

Resolver:

Perform Changes tab:


This time I am not too innovative. I think that current Aptitude GTK design for this tabs is quite intuitive and good-looking, so I have added only minor tweaks.

To sum up mockups topic, below are links to all presented mockups (with some comments which raises during my recent private discussions). Now, I am open for any suggestions and comments about current design. At the end of next week, second iteration will be presented. Depending of the level of required changes there could be third iteration, before sending mockups to Piotr "Patpi" Pe zowski, who is the person behind Kadu Usability Project. I am glad that he agreed to spend his spare time and help me with this task :)

Packages tab:

This tab in second iteration will have only small changes. I was told that will be nice to select multiple categories at the same time. I agree, so categories list will support multi selection. There will be also an option in configuration window (There is no mockup now. Currently, I do not know what option will be configurable and it is not the most important thing at this stage. The window will be patterned upon KDE configuration windows) to move this list on the right side of this tab.

It will be possible to have multiple "Packages tabs" opened at the same time. It will not be allowed to close first "Package Tab". Ctrl + T shortcut, action in main menu and toolbar (I have forgotten about toolbar in this iteration - maybe it is not necessary?) will open new tab. There will be also an option that each text search will do this. I will try to add shortcuts wherever is it possible to allow using the GUI without mouse.

"Show changes" button will be change to "Resolve dependencies" when necessary.

Updates widget:

Most of the comments from "Packages tab" apply here too. In the table showing updates will be also "Current Version" column.


Package Informations tab:

Only one clarification: multiple "Packages Informations" tabs for the same package will not be allowed.

I am looking forward to read any comments regarding presented design. Please leave comment below this post or contact me directly (see About Me page).

On Monday/Tuesday I will write first weekly report.

Cheers.

Piotr Galiszewski: Short project update

Hello all.

Last week I was very busy, due to my university duties. On Tuesday I had my first exam in this semester (in Numerical Analysis), which took me more time than I had thought it would be.
From this reason my project is slightly behind schedule, but now I will do my best to catch the plan.

On the other hand, there are also some good news for me. Some time ago, Daniel Burrows migrated aptitude repository from mercurial to GIT. I am git user for nearly year, so I strongly support this move ;) .

Here are some basic thoughts which functionalities good package manager must have (and which approach (from aptitude-gtk, synaptic and adept) I like the most):
All of this will be elaborated in mockups. Am I forgetting something important?

The most important questions is: "What is the most common use case for package manager? Installing packages or upgrading packages?". I am not sure if this two actions require different views, or there should be only new category in install package view.

This is all now. More updates (and mockups) will be available today's midnight (or tomorrow morning). So please stay tuned :)

Piotr Galiszewski: Hello Word

Hello Planet Debian readers!

I've never thought that such a thing can ever happen, but I've started blogging ;) So now it is time to introduce myself.

My name is Piotr Galiszewski and I am second year student of computer science at AGH - University of Science and Technology in Krakow (Poland). I have been GNU/Linux user for about 5 years (mostly Debian based distributions).

Thanks for Debian and Google, this summer I will be working on creating Qt-based user interface for aptitude as my Google Summer of Code project. I hope that my mentors Sune Vuorela and Daniel Barrows will be patient with me ;) I am sure I will learn a lot from them. Please look at abstract of my project made by Debian GSoC administrator Obey Arthur Liu:
Qt GUI for aptitude. Currently, KDE users need to use Aptitude via the console interface, or install the newly developed GTK frontend, which does not fit well into KDE desktop. Making Qt frontend to Aptitude would solve this problem and bring an advanced and fully Debian-compliant graphical package manager to KDE.
As I wrote in my proposal I will split my work into three main parts:
  1. writing low level classes which will abstract aptitude signals and slots (which uses sigc++) into Qt slots and signals.
  2. creating and evaluating GUI mockups
  3. implementing GUI on top of classes from the first point
Point 1 and 2 will be made simultaneously and will take all May and half of June. Low level classes should implement all necessary functions for further use in GUI. This classes allow me to avoid direct usage of none Qt code in GUI classes and also give much more time to prepare completed and usability-wise mockups. Every mockups version will be presented and discussed on this blog. First version should be ready in next few days and updates will appear each week (or to weeks).
After finishing this two steps I will start coding GUI. With mockups and finished low level classes this should not be complicated (Yeah, I know that this is only my dream).

Full text of my proposal (including more precise time-line) can be found at Debian wiki.

Currently, project is slightly behind the schedule . It is caused by changes in my studies plan. The Juwanalia students' festival took place earlier, and yesterday it finished. But my first exam will take place one week later on 18 May, so I will have more time to catch up with time-line.

This project is my first direct contribution to Debian, but not first involvement in free software movement. I've been Kadu Instant Messenger developer for more then two year. In last two years I have been second most active developer with more than 700 commits in master branch. During GSoC period my Kadu activities will be limited. If time allows me to do this, I will be still contributing to Kadu. I still can be found at Kadu forum or #kadu channel on irc.freenode.net. I will also continue reviewing patches and fixing low time-consuming bugs.

My plans for the next few days:
If you have any thoughts about this project, please add comment to this post or contact me directly. I will be glad to read all yours opinions

Cheers

PS. As you can see English is not my mother tongue, so please forgive me my mistakes

30 May 2010

Erich Schubert: Wikipedia contributors are one of a kind

The last weeks, I've occasionally been contributing to Wikipedia. I must say, Wikipedia is a really odd world of its own. Another thing I found quite surprising is the difference between the English and the German Wikipedia.Some things I noticed: So on overall: keep away from Wikipedia contributors, they're all maniacs. And often, don't bother to read a Wikipedia article if you can get an appropriate textbook. The Wikipedia article will just try to sell you a dozen textbooks anyway; you'll also have to read them to check the validity.It is a pity, that despite its size and "eyeballs", Wikipedia so far seems to have not attracted much attention by actual "domain experts", but it seems that it is largely filled by bureocrats, zealots and promoters. (That don't have any real work to do?)There are many things wrong here, that have been pointed out by many others, too. I'm not going to rescue the Wikipedia world, either. And yes, I am aware that you can discuss in Wikipedia, too. I fear that Wikipedia will go the DMOZ road. There was a time that DMOZ was doing quite well. Nowadays, large parts of DMOZ are dead. For two main reasons: it's hard to get in, and the backlog is way too large. If you get into DMOZ for a larger category, you'll be faced with thousands of pending link submissions, where for a large part you don't feel qualified to judge on appropriateness or rewrite their description in a neural manner. I have the impression that the same is happening for Wikipedia: on one hand, users that join are often kicked badly for many of their first contributions and will just leave again. At the same time, many of the old articles are in desparate need for attention, but nobody of the established users is willing to spend the days of cleanup/rewriting needed to get the article into a useful shape again. And a new user will never dare to discard most of the existing article; they usually just add or modify single paragraphs to see what happens. So Wikipedia might be hitting some kind of barrier.Still, I have to admit that I frequently use Wikipedia to look up things. Usually because it just comes up first in Google. I then often follow links to better resources, such as MathWorld. And I wish, Google would have taken me there right away ...And don't assume I'd know how to run things better. I'd sure propose to spend more time at fixing existing articles instead of attacking new contributions that much (you'll lose contributors this way). But I also see the need for fighting spam (although you should also remove old spam ...). But I don't know if there is a solution that will actually attract domain experts to re-write all the badly written and inaccurate articles that don't have their personal zealot to patrol them.P.S. Sorry, no comments on my blog. This isn't Facebook. Instead of commenting on my blog, how about working on Wikipedias backlog instead?P.S. Another example is the German Wikipedia story surrounding Fefe's blog. Many here at the open source communities will know fefe for his work on Dietlibc, libowfat and similar highly respected open source projects. His blog has been famous for being high-quality in security, privacy topics, politics and media critics. Some of his fans (likely) started a Wikipedia page on his blog. There have been at least two huge discussions about deleting the Wikipedia page. "sock puppets" and all such things have been brought up, while Fefe himself was amused. The discussions around deleting the blogs page on Wikipedia made it all the way to the print newspapers. As I said, I'm not actually bringing up new critique on Wikipedia. It's an ongoing problem for years now.[Insert random Deletionism rant against Wikipedia]

David Paleino: GoogleCode redirector

I recently saw a couple of bugreports all complaining about debian/watch files failing with GoogleCode. Since I'm myself maintaining some packages whose upstream authors use Google as their hoster, I felt it was a good idea to offer a service for uscan(1) and DEHS. You can reach the service at http://googlecode.debian.net. To use it in your debian/watch, just use:

http://googlecode.debian.net/p/<project>/<regex>
For example:
http://googlecode.debian.net/p/pyproj/pyproj-(\d+.*).tar.gz
The source code is available at debian-it.it (you should give this url to git clone). This service is currently in beta testing; suggestions and patches are more than welcome! Also, feel free to report any issue you might encounter!

29 May 2010

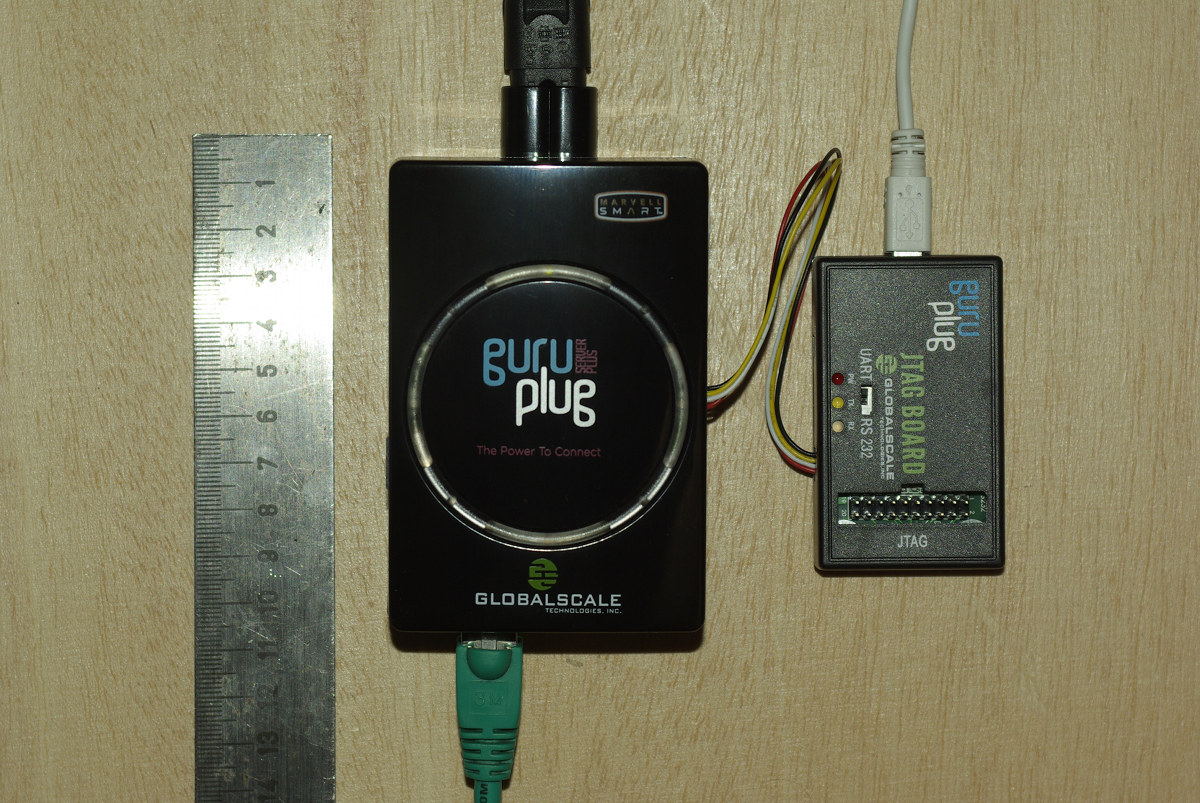
Bernd Zeimetz: installing debian on the guruplug server plus

Yesterday finally my GuruPlug Server Plus arrived. Took longer than expected, but as it seems Globalscale had some issues with the power supplies and they were replaced before shipping the GuruPlugs. GuruPlug Server Plus and JTAG Board

The GuruPlug Basically the GuruPlugs are an enhanced version of the well known SheevaPlugs, the biggest difference is probably the need for an external JTAG/UART<>RS232 board to access the serial console. Good thing is that the board comes with a normal JTAG connector and an additional RS232 connector and 2.5V DC power outlet, so it will be useful for other devices, too. Globalscale could have chosen different connectors with less wiggly cables, though. As I was not able to find a useful howto about installing Debian on the Guruplug, I've written down what I did to install Debian unstable on a micro SD card using the Debian installer for the GuruPlug. I did not have a look who modified the Debian installer to work on the plug, but thanks for that! The instructions below are based on Martin Michlmayer's awesome SheevaPlug documentation, the hints from oinkzwurgl.org/guruplug and various forum posts in the plugforum.

Preparations Please note that I'm not resposible for whatever you're doing with your plug. If you follow this tutorial and end up with a brick, it is your fault, not mine. To install the GuruPlug you need the JTAG Board. Connect the UART port to the GuruPlug and the JTAG board to your computer, it should show up as FTDI (thanks for using good chips!) USB<>Serial converter. Serial port settings are 115200, 8-N-1, no hw/sw flow control. The other thing you should prepare is a working tftpd, I'm using aftpd.
apt-get install aftpd
Recent versions share files from /srv/tftp/, in case you're running Lenny /var/lib/tftpboot/ should be the place to drop your files. When everything is connected properly the boot process should show up in minicom, make sure to press some key to enter uBoot. The first thing you should do is to save the original uBoot environment in case you want to restore the factory settings later. Run
printenv
and save the output somewhere.

Upgrading uBoot Unfortunately the uBoot version on the GuruPlug is pretty old and seems to have some issues in booting from USB devices, so the first thing you should do is to upgrade it. You might want to investigate if there is even a better, more recent uBoot version available somewhere, or build one on your own, but I didn't bother and took the uBoot.guruplug.bin from here. The main issue with that is that booting from USB still seems to be buggy (even for FAT partitions) and that ext2load is still not supported. Otherwise it works well :-). I'm mainly following Martin Michlmayer's tutorial again. Download the uBoot.guruplug.bin and drop it into the tftpd directory. Make sure you always set the plug's IP address (ipaddr) and your server's IP address (serverip) properly. I'll use 192.168.121.253 for the plug and 192.168.121.2 for the server in all examples, make sure to change that for your own needs. Stop if something goes wrong, especially when the tftp download failed.
setenv ipaddr 192.168.121.253
setenv serverip 192.168.121.2
tftp 0x6400000 uBoot.guruplug.bin
nand erase 0x00000000 0x0100000
nand write 0x6400000 0x0000000 0x80000
reset
Enter uBoot again after the reset.

Preparing the installer Download uImage and uInitrd to your tftpd directory. Although I've heard that setting mainlineLinux/arcNumber in the uBoot environment is not necessary anymore for very recent kernel, lets set them to make sure the Debian kernel works:
setenv mainlineLinux yes
setenv arcNumber 2097
saveenv
reset
Again, enter uBoot after the reset.

Running the installer Run the following in the uBoot console:
setenv ipaddr 192.168.121.253
setenv serverip 192.168.121.2
tftpboot 0x01100000 uInitrd
tftpboot 0x00800000 uImage
setenv bootargs console=ttyS0,115200n8 base-installer/initramfs-tools/driver-policy=most
bootm 0x00800000 0x01100000
You should see the installer starting now. You might want to follow the following hints:
  • Before configuring the network, go back and set the debconf priority to low, Then continue. While chosing the Debian mirror, chose sid as the Debian version to install. If you don't have sid as choice, use a different mirror. The kernel in testing does not boot on the GuruPlug, you need 2.6.32-13 from sid.
  • You might want to load the 'network console' installer component and continue via ssh. Makes things fater and colourful.
  • Suggested partitioning: I've installed Debian to an 8GB micro SDcard. The SDcard reader is connected via USB and shows up as /dev/sdb (/dev/sda should be the internal NAND and not shown by the installer). I've used 150MB ext2 for /boot and the rest of the space for /, using ext4. You might want to use the noatime option on both filesystems to avoid unnecessary write access to the SDcard. You might choose to add a swap partition, but SDcards are so slow, so I've skipped that.
When you continue the installation, you will hit the following problem:
  • The installer might fail on 'Make the system bootable' (not sure if it does for you, it did so with the kernel from testing).
  • The uBoot is not able to boot from your /boot anyway. USB support is buggy and ext2load missing.
We'll work around these issues by writing the kernel and initrd into the plug's NAND. To do so, enter a shell in the installer and chroot into the install target. We'll then create the necessary uImage.bin and uInitrd and scp them to our tftpd directory:
chroot /target /bin/bash
cd /boot
mkimage -n vmlinuz -A arm -O linux -T kernel -C none -a 0x00008000 -e 0x00008000 -d /boot/vmlinuz uImage.bin
mkimage -n 'vmlinuz initrd' -A arm -O linux -T ramdisk -C gzip -d /boot/initrd.img uInitrd
scp uI* root@192.168.121.2:/srv/tftp
Now leave the shell, finish the installation and reboot, enter uBoot again.

Make the plug bootable To write kernel and initrd to the NAND memory, we have to transfer it via tftp first, then erase the NAND area we want to write to and then write it to the NAND. The values I've chosen here should be fine for the current Debian kernel, but you might need to change the necessary size for the initrd. To do so have a look at the output while transferring the initrd - the transferred bytes are displayed. They have to fit into the amount of bytes you write (the last option to nand write.e).
setenv ipaddr 192.168.121.253
setenv serverip 192.168.121.2
tftp 0x6400000 uImage.bin
nand erase 0x100000 0x400000
nand write.e 0x6400000 0x100000 0x400000
tftp 0x6400000 uInitrd
nand erase 0x500000 0x1fb00000
nand write.e 0x6400000 0x500000 0x600000
Now we need to set the necessary boot options. Make sure to change the root device if you've chosen a different layout from that I've suggested above, or if you're not using a SDcard.
setenv bootargs_debian 'console=ttyS0,115200 root=/dev/sdb2'
setenv bootcmd_nand 'nand start; nand read.e 0x00800000 0x100000 0x400000; nand read.e 0x01100000 0x500000 0x600000'
setenv bootcmd 'setenv bootargs $(bootargs_debian); run bootcmd_nand; bootm 0x00800000 0x01100000'
saveenv
run bootcmd

Finish Your GuruPlug should boot your new Debian installation now. Have fun! I'll try to keep the howto updated for changes in uBoot and the installer, but I might not have the time to so quickly. Patches and comments are welcome!.
root@guruplug:~# uname -a
Linux guruplug 2.6.32-5-kirkwood #1 Fri May 21 05:44:29 UTC 2010 armv5tel GNU/Linux
root@guruplug:~# cat /proc/cpuinfo 
Processor   : Feroceon 88FR131 rev 1 (v5l)
BogoMIPS    : 1192.75
Features    : swp half thumb fastmult edsp 
CPU implementer : 0x56
CPU architecture: 5TE
CPU variant : 0x2
CPU part    : 0x131
CPU revision    : 1
Hardware    : Marvell GuruPlug Reference Board
Revision    : 0000
Serial      : 0000000000000000
root@guruplug:~# 

Russell Coker: Logging in as Root

Martin Meredith wrote a blog post about logging in as root and the people who so strongly advocate against it [1]. The question is whether you should ssh directly to the root account on a remote server or whether you should ssh to a non-root account and use sudo or su to gain administrative privileges. Does sudo/su make your system more secure? Some years ago the administrator of a SE Linux Play Machine used the same home directory for play users to login as for administrative logins as for his own logins he used newrole to gain administrative access (like su or sudo but for SE Linux). His machine was owned by one of his friends who created a shell function named newrole in one of his login scripts that used netcat to send the administrative password out over the net. He didn t immediately realise that this was a problem until his friend changed the password and locked him out! This is one example of a system being 0wned due to having the double-authentication of course if he had logged in directly with administrative privs while using the same home directory that the attacker could write to then he would still have lost but the attacker would have had to do a little more work. When you login you have lots of shell scripts run on your behalf which have the ability to totally control your environment, if someone has taken over those scripts then they can control everything you see, when you think you run sudo or something they can get the password. When you ssh in to a server your security relies on the security of the client end-point, the encryption of the ssh protocol (including keeping all keys secure to prevent MITM attacks), and the integrity of all the programs that are executed before you have control of the remote system. One benefit for using sshd to spawn a session without full privileges is in the case where you fear an exploit against sshd and are running SE Linux or some other security system that goes way beyond Unix permissions. It is possible to configure SE Linux in the strict configuration to deny administrative rights to any shell that is launched directly by the sshd. Therefore someone who cracks sshd could only wait until an administrator logs in and runs newrole and they wouldn t be able to immediately take over the system. If the sysadmin suspected that a sshd compromise is possible then a sysadmin could login through some other method (maybe visit the server and login at the console) to upgrade the sshd. This is however a very unusual scenario and I suspect that most people who advocate using sudo exclusively don t use a SE Linux strict configuration. Does su/sudo improve auditing? If you have multiple people with root access to one system it can be difficult to determine who did what. If you force everyone to use su or sudo then you will have a record of which Unix account was used to start the root session. Of course if multiple people start root shells via su and leave them running then it can be difficult to determine which of the people who had such shells running made the mistake but at least that reduces the list of suspects. If you put PermitUserEnvironment yes in /etc/ssh/sshd_config then you have the option of setting environment variables by ssh authorized_keys entries, so you could have an entry such as the following: environment= ORIG_USER=john@example.com ssh-rsa AAAAB3Nz[...]/w== john@example.com Then you could have the .bashrc file (or a similar file for your favorite shell) have code such as the following to log the relevant data to syslogd:
if [ "$SSH_TTY" = "" ]; then
logger -p auth.info "user $ORIG_USER ran command \"$BASH_EXECUTION_STRING\" as root"
else
logger -p auth.info "user $ORIG_USER logged in as root on tty $(tty)"
fi I think that forcing the use of su or sudo might improve the ability to track other sysadmins if the system is not well configured. But it seems obvious that the same level of tracking can be implemented in other ways with a small amount of effort. It took me about 30 minutes to devise the above shell code and configuration options, it should take people who read this blog post about 5 minutes to implement it (or maybe 10 minutes if they use a different shell or have some other combination of Bash configuration that results in non-obvious use of initialisation scripts (EG if you have a .bash_profile file then .bashrc may not be executed). Once you have the above infrastructure for logging root login sessions it wouldn t be difficult to run a little script that asks the sysadmin what is the purpose for your root login and logs what they type. If several sysadmins are logged in at the same time and one of them describes the purpose of their login as to reconfigure LDAP then you know who to talk to if your LDAP server stops working! Should you run commands with minimum privilege? It s generally regarded that running each command with the minimum privilege is a good idea. But if the only reason you login to a server is to do root tasks (restarting daemons, writing to files that are owned by root, etc) then there really isn t a lot of potential for achieving anything by doing so. If you need to use a client for a particular service (EG a web browser to test the functionality of a web server or proxy server) then you can login to a different account for that purpose the typical sysadmin desktop has a dozen xterms open at once, using one for root access to do the work and another for non-root access to do the testing is probably a good option. Can root be used for local access? Linux Journal has an article about the distribution that used to be known as Lindows (later Linspire) which used root as the default login for desktop use [2]. It suggests using a non-root account because If someone can trick you into running a program or if a virus somehow runs while you are logged in, that program then has the ability to do anything at all of course someone could trick you into running a program or virus that attempts to run sudo (to see if you enabled it without password checks) and if that doesn t work waits until you run sudo and sniffs the password (using pty interception or X event sniffing). The article does correctly note that you can easily accidentally damage your system as root. Given that the skills of typical Linux desktop users are significantly less than those of typical system administrators it seems reasonable to assume that certain risks of mistake which are significant for desktop users aren t a big deal with skilled sysadmins. I think that it was a bad decision by the Lindows people to use root for everything due to the risk of errors. If you make a mistake on a desktop system as non-root then if your home directory was backed up recently and you use IMAP or caching IMAP for email access then you probably won t lose much of note. But if you make a serious mistake as root then the minimum damage is being forced to do a complete reinstall, which is time consuming and annoying even if you have the installation media handy and your Internet connection has enough quota for the month to complete the process. Finally there are some services that seek out people who use the root account for desktop use. Debian has some support channels on IRC [3] and I decided to use the root account from my SE Linux Play Machine [4] to see how they go. #debian has banned strings matching root. #linpeople didn t like me because Deopped you on channel #linpeople because it is registered with channel services . #linuxhelp and #help let me in, but nothing seemed to be happening in those channels. Last time I tried this experiment I had a minor debate with someone who repeated a mantra about not using root and didn t show any interest in reading my explanation of why root:user_r:user_t is safe for IRC. I can t imagine that good the #debian people expect to gain from denying people the ability to access that channel with an IRC client that reports itself to be running as root. Doing so precludes the possibility of educating them if you think that they are doing something wrong (such as running a distribution like Lindows/Linspire). Conclusion I routinely ssh directly to servers as root. I ve been doing so for as long as ssh has been around and I used to telnet to systems as root before that. Logging in to a server as root without encryption is in most cases a really bad idea, but before ssh was invented it was the only option that was available. For the vast majority of server deployments I think that there is no good reason to avoid sshing directly as root.

26 May 2010

Nico Golde: fail2ban + dns = fail

fail2ban is used by many people to prevent certain types of DoS attacks. I use it myself to reduce trackback spam a little bit.

While this tool becomes quite handy in such situations it is also not generally recommend because you can shoot yourself in the foot. If one of the used filters has a bug and results in incorrect parsing your fail2ban installation might end up banning arbitrary IP addresses or even your own IP range (not even mentioning IP spoofing).
There existed at least two bugs of this kind to my knowledge and since regex might not always be easy I'm sure there will be more in the future.

Since I didn't want to look for a specific regex bug in one of the filters I thought about IP spoofing again and looked at fail2bans filters. What I needed was a filter processing log entries of a service listening on a UDP socket as TCP/IP spoofing over the internet doesn't really work well these days. Finding such a filter would mean an instant win situation. To my surprise there is such a filter: config/filter.d/named.conf

This filter is used to parse log entries consisting of denied DNS queries produced by bind. Interestingly there is even an article at debian-administration describing how to setup fail2ban to mitigate a DNS DDoS attack. This is of course a bad idea and I have no idea why this filter is shipped in a default fail2ban installation. DoSing abritary IP addresses with this filter in use becomes as easy as firing up scapy and querying the server with a forged source IP:

>>> send(IP(dst="81.169.172.197",src="xx.46.63.71")/UDP()/DNS(rd=1,qd=DNSQR(qname="foao.modprobe.de")))
.
Sent 1 packets.

This ends up as:
May 26 22:32:22 modprobe named[30245]: client xx.46.63.71#53: query 'foao.modprobe.de/A/IN' denied

in the bind logs which in turn results in:
2010-05-26 22:32:05,551 fail2ban.actions: WARNING [named-refused] Ban xx.46.63.71

In this example the spoofed IP was xx.46.63.71 which is not under my control.

Mission statement: don't use fail2ban unless you really want to shoot yourself in the foot or know pretty well what you're doing :-)

Russell Coker: UBAC and SE Linux in Debian

A recent development in SE Linux policy is the concept of UBAC (User Based Access Control) which prevents SE Linux users (identitied) from accessing each other s files. SE Linux user identities may map 1:1 to Unix users (as was required in the early versions of SE Linux), you might have unique identities for special users and a default identity for all the other users, or you might have an identity per group or use some other method of assigning identities to groups. The UBAC constraints in the upstream reference policy prevent a process with a SE Linux identity other than system_u from accessing any files with an identity other than system_u. So basically any regular user can access files from the system but not other users and system processes (daemons) can access files from all users. Of course this is just one layer of protection, so while the UBAC constraint doesn t prevent a user from accessing any system files the domain-type access controls may do so. If you used a unique SE Linux identity for each Unix account then UBAC would prevent any user from accessing a file created by another user. For my current policy that I am considering uploading to Debian/Unstable I have allowed the identity unconfined_u to access files owned by all identities. This means that unconfined_u is an identity for administrators, if I proceed on this path then I will grant the same rights to sysadm_u. UBAC was not enabled in Fedora last time I checked, so I m wondering whether there is any point in including it I don t feel obliged to copy everything that Fedora does, but there is some benefit in maintaining compatibility across distributions. For protecting users from each other it seems that MCS (which is Mandatory in the Debian policy) is adequate. MCS allows a much better level of access control. For example I could assign categories c0 to c10 to a set of different projects and allow the person who manages all the projects to be assigned all those categories when they login. That user could then use the command runcon -l s0:c1 bash to start a shell for the purpose of managing files from project 1 and any file or process created by that command would have the category c1 and be prevented from writing to a file with a different category. Of course the down-side to removing UBAC is that since RBAC was removed there is no other way of separating SE Linux users, while MCS is good for what it does it wasn t designed for the purpose of isolating different types of user. So I ll really want to get RBAC reinstalled before Squeeze is released if I remove UBAC. Regardless of this I will need to get RBAC working on Squeeze eventually anyway. I ve had a SE Linux Play Machine running with every release of SE Linux for the last 8 years and I don t plan to stop now.

25 May 2010

Aurelien Jarno: EGLIBC and PowerPCSPE port

This has been roughly one year since Debian switched from GLIBC to EGLIBC, so it s probably the time to make a small report about this change. First of all, on the GLIBC upstream side, things has improved a bit since we now have regular stable release, thanks to Petr Baudis aka Pasky. The good point is that the stable releases are imported into the EGLIBC stable repositories. On the EGLIBC side the switch has helped to reduce the number of patches in the Debian package (for example, resolv.conf is automatically reloaded if needed), and has brought some bug fixes and improvements, especially for the arm, mips and powerpc targets. It should be noted that the newly created PowerPCSPE port for PowerPC e500 series CPU also benefits from EGLIBC, as it is not natively supported by GLIBC.

Matt Zimmerman: The behavioral economics of free software

People who use and promote free software cite various reasons for their choice, but do those reasons tell the whole story? If, as a community, we want free software to continue to grow in popularity, especially in the mainstream, we should understand better the true reasons for choosing it especially our own. Some believe that it offers higher quality, that the availability of source code results in a better product with higher reliability. Although it s difficult to do an apples-to-apples comparison of software, there are certainly instances where free software components have been judged superior to their proprietary counterparts. I m not aware of any comprehensive analysis of the general case, though, and there is plenty of anecdotal evidence on both sides of the debate. Others prefer it for humanitarian reasons, because it s better for society or brings us closer to the world we want to live in. These are more difficult to analyze objectively, as they are closely linked to the individual, their circumstances and their belief system. For developers, a popular reason is the possibility of modifying the software to suit their needs, as enshrined in the Free Software Foundation s freedom 1. This is reasonable enough, though the practical value of this opportunity will vary greatly depending on the software and circumstances. The list goes on: cost savings, educational benefits, universal availability, social rewards, etc. The wealth of evidence of cognitive bias indicates that we should not take these preferences at face value. Not only are human choices seldom rational, they are rarely well understood even by the human themselves. When asked to explain our preferences, we often have a ready answer indeed, we may never run out of reasons but they may not withstand analysis. We have many different ways of fooling ourselves with regard to our own past decisions and held beliefs, as well as those of others. Behavioral economics explores the way in which our irrational behavior affects economies, and the results are curious and subtle. For example, the riddle of experience versus memory (TED video), or the several examples in The Marketplace of Perception (Harvard Magazine article). I think it would be illuminating to examine free software through this lens, and consider that the vagaries of human perception may have a very strong influence on our choices. Some questions for thought: If you re aware of any studies along these lines, I would be interested to read about them.

Russell Coker: Links May 2010

AdRevenge is an interesting concept to pay for Google Adsense adverts about how companies suck [1]. If a suitably large group of people pay to warn you about a company then it s a good signal that the company is actually doing the wrong thing. A guest post by Mili on Charles Stross blog has an interesting analysis of the economcs of Intellectual Property and concludes that content is a public good [2]. New Age Terrorists Develop Homeopathic Bomb [3], an amusing satire of medical fraud and security theatre. The sit has a lot of other good satire too. Mark Shuttleworth wrote an interesting post about new window management changes that will soon go into Ubuntu [4]. He points out that the bottom status bar in applications is a throw-back to Windows 3.1 and notes that a large part of the incentive for removing it (and using the title-bar for the status) is the work on the Netbook version of Ubuntu. This is really ironic given that the resolution of current Netbooks is quite similar to that of desktop systems that were current when Windows 3.1 came out. Omar Ahmad gave an insightful TED talk about the benefit of using a pen and paper to send a letter to a politician [5]. Sebastian Wernicke gave an amusing and informative TED talk about how to give a good TED talk [6]. His talk gives some useful ideas for public speaking that are worth considering. Catherine Mohr gave a brief and interesting TED talk about how to build an energy efficient house with low embodied energy [7]. Her blog at www.301monroe.com has the details. Stephen Wolfram (of Mathematica fame) gave an interesting TED talk [8]. He covers a lot of interesting things that can be done with computers, primarily based on the Wolfram Alpha [9] platform which allows natural language queries of a large data set. He also talks about the search for a Theory of Everything. Esther Duflo gave an interesting TED talk about using social experiments to fight poverty [10]. She describes how scientific tests have been used to determine the effectiveness of various ways of preventing disease and encouraging education in developing countries. One example of the effectiveness of such research is the DeWormTheWorld.org project which was founded after it was discovered that treating intestinal worms was the most cost effective way of getting African children to spend longer at school. David L. Rosenhan wrote an interesting research paper On Being Sane In Insane Places about pseudo-patients admitted to psychiatric hospitals [11]. It seems that psychiatric staff were totally unable to recognise a sane person who was admitted even though other patients could do so. It also documents how psychiatric patients were treated as sub-human. One would hope that things had improved since 1973, but it seems likely that many modern psychiatric hospitals are as bad as was typical in 1973. It s also worth considering the issue of the treatment in society of people who have been diagnosed with a mental illness, it seems likely that the way people are treated in the community would have similar bad results to that which was documented for treatment in psychiatric hospitals even the sanest people will act strangely if treated in an insane manner! Also it seems to me that there could be potential for using a panel of patients assembled via the Delphi Method as part of the psychiatric assessment process as it has been demonstrated that patients can sometimes assess other patients more accurately than psychiatrists! Simon Sinek gave an inspiring TED talk about how great leaders inspire action [12]. Of course the ideas he describes don t just apply to great leaders, they should apply to ordinary people who just want to convince others to adopt their ideas. Stephen Collins write a good article summarising the main reasons why the proposed great firewall of Australia is a bad idea [13]. Lenore Skenazy who is famous for letting her 9yo son catch the metro alone during broad daylight on a pre-planned route home has created a web site about Free Range Kids [14]. She seems to be starting a movement to oppose Helicopter Parenting and has already written a book about her ideas for parenting. The incidence of crime has been steadily increasing, as has the ability of the police to apprehend criminals and recover abducted children. There s no reason for children to be prevented from doing most of the things that children did when I was young!

24 May 2010

Axel Beckert: Perfect Team: autossh and GNU Screen

SSH is definitely one of my most often used tools, not only for system administration at work but also on the road with my netbook, an EeePC 701 running Debian Sid. On the road, it often happens that I have a flaky WLAN or UMTS connection, so I often have to kill (via <Enter>~.) and reconnect my SSH session due to a changed IP address or so. First step against problems arising from using SSH over unreliable network connections is of course GNU Screen. Second step is use SSH keys and ssh-agent to not needing to type the password on every reconnect. But it s still very annoying to kill the SSH connection and call ssh again manually. For luck there is autossh, a wrapper around SSH which regularily checks via two tunnels connect to each other on the remote side if the connection is still alive, and if not, it kills the ssh and starts a new one with the same parameters (i.e. tunnels, port forwardings, commands to call, etc.). It s quite obvious that this is perfect to be combined with screen s -R and -d options (Reattach if a detached screen is around, else start a new screen; detach a currently attached screen), so I found myself very often typing (or fetching it from the commandline history :-):
autossh -t sym.noone.org 'screen -Rd'
-t is necessary to allocate a terminal device on the remote machine which is not done by default if you directly call a command via ssh. In comparision to OpenSSH, autossh needs the single quotes, because otherwise it would parse -Rd as options to parse to ssh and bail out. That s not a real problem, but when you re used to just type ssh -t sym.noone.org screen -Rd without any quotes, you ll run into this then and when. Update, 25-May-2010, 14:55: As Carsten Hey points out, autossh also supports the -- option to declare that all following options and parameters must be passed to ssh itself. (End of Update) Typing that often and mistyping it then and when cries for an shell alias or an shell function. So I came up with the following shell function:
asc()  
    autossh -x -a -t "$@" 'screen -RdU'
 
I used a function instead of an alias in case of autossh will in future regard all parameters given after the command as part of the command as ssh does. The additional options -x and -a disable X and SSH Agent forwarding which both don t work if you reattach to an already running screen. And if you re using Zsh as I do, you can even add some more format string magic to set the window title more or less to the expanded alias, eh, function:
function asc()  
    # Set the title to something more obvious, e.g. the expanded
    # alias, eh, function
    print -Pn "\e]0;%n@%m: autossh -t $* 'screen -RdU'\a";
    autossh -x -a -t "$@" 'screen -RdU'
 
compdef asc=ssh
Update, 25-May-2010, 14:59: As Hauke points out in a comment, Zsh users should also declare that asc should have the same tab completion as ssh itself. The example above has been updated accordingly. (End of Update) In the meanwhile on the EeePC I use asc on the commandline more often than ssh itself. And I nearly no more type autossh. (The most common exception here is autossh hostname tail -F /path/to/some/logfile.) Using that function you can also add common ssh options for tunneling, etc. I use it most often like this:
asc -D 1080 sym.noone.org
This opens a SOCKS proxy on localhost, port 1080 and that way I can surf via the host I m connecting to by SSH. There s one small drawback though: You didn t expect that I can just invent some new three letter command without a namespace clash, did you? There is a free game called Advanced Strategic Command whose binary (and Debian package) is named asc, too. If you have that game installed, you can always call it using its full path, e.g. /usr/games/asc on Debian. P.S.: My whole grml based .zshrc is also available via git at git.noone.org as well as on github.

23 May 2010

Roland Mas: FusionForge news, May 2010

The usual semi-regular bits of news from the FusionForge project. We continue being quite active, with several hundred commits each month. The momentum doesn't seem to stop even after the 5.0 release last month. A large part of the activity stems from the Coclico project, which has several work-packages related to convergence of code across forges (mostly between FusionForge and Codendi). This convergence comes in three flavours: All in all, a fairly busy period for FusionForge. The current trunk is evolving rather fast, with some long-overdue rewrites being underway. Interesting times.

Next.

Previous.