Search Results: "spa"

16 May 2013

Vincent Sanders: True art selects and paraphrases, but seldom gives a verbatim translation

In my professional life I am sometimes required to provide technical support to one of our salesmen. I find this an interesting change in pace though sometimes challenging.

Occasionally I fail to clearly convey the solution we are trying to sell because of my tendency to focus on detail the customer probably does not need to understand but I think is the interesting part of the problem.

Conversely sometimes the sales people gloss over important technology choices which have a deeper impact on the overall solution. I was recently in such a situation where as part of a larger project the subject of internationalisation (you can see why it gets abbreviated to i18n) was raised.

I had little direct personal experience with handling this within a project workflow so could not give any guidance but the salesman recommended the Transifex service as he had seen it used before, indicated integration was simple and we moved onto the next topic.

Unfortunately previous experience tells me that sometime in the near future someone is going to ask me hard technical questions about i18n and possibly how to integrate Transifex into their workflow (or at least give a good estimate on the work required).
LearningBeing an engineer I have few coping strategies available for situations when I do not know how something works. The approach I best know how to employ is to give myself a practical crash course and write up what I learned...so I did.

I proceeded to do all the usual things you do when approaching something unfamiliar (wikipedia, google, colleagues etc.) and got a basic understanding of internationalisation and localisation and how they fit together.

This enabled me to understand that the Transifex workflow proposed only covered the translation part of the problem and that, as Aldrich observed in my title quote, there is an awful lot more to translation than I suspected.
PlatformsMy research indicated that there are numerous translation platforms available for both open source and commercial projects and Transifex is one of many solutions.

Although the specific platform used was Transifex most of these observations apply to all these other platforms. The main lesson though is that all platforms are special snowflakes and once a project invests effort and time into one platform it will result in the dreaded lock in. The effort to move to another platform afterwards is at least as great as the initial implementation.

It became apparent to me that all of these services, regardless of their type, boil down to a very simple data structure. They appear to be a trivial table of Key:Language:Value wrapped in a selection of tools to perform format conversions and interfaces to manipulate the data.

There may be facilities to attach additional metadata to the table such as groupings for specific sets of keys (often referred to as resources) or translator hints to provide context but the fundamental operation is common.

The pseudo workflow is:
The first three steps are almost always performed together by the uploading of a resource file containing an initial set of translations in the "default" language and due to the world being the way it is this is almost always english (some services are so poorly tested with other defaults they fail if this is not the case!)

The platforms I looked at generally follow this pattern with a greater or lesser degree of freedom in what the keys are, how the groupings into resources are made and the languages that can be used. The most common issue with these platforms (especially open source ones) is that the input convertors will only accept a very limited number of formats and often restricted to just GNU gettext PO files. This means that to use those platforms a project would have to be able to convert any internal resources into gettext translatable format.

The prevalence of the PO format pushes assumptions into almost every platform I examined, mainly that a resource is for a single language translation and that the Key (msgid in gettext terms) is the untranslated default language string in the C locale.

The Transifex service does at least allow for the Key values to be arbitrary although the resources are separated by language.

Even assuming a project uses gettext PO files and UTF-8 character encoding (and please can we kill every other character encoding and move the whole world to UTF-8) the tools to integrate the import/export into the project must be written.

A project must decide some pretty important policies, including:
These are project policy decisions and, as I discovered, just as difficult to answer as the technical challenges.

Armed with my basic understanding it was time to move on and see how the transifex platform could be integrated into a real project workflow.
ImplementingProof of conceptMy first exercise was to take a trivial command line tool, use xgettext to generate a PO file and add the relevant libintl calls to produce gettext internationalised tool.

A transifex project was created and the english po file uploaded as the initial resource. A french language was added and the online editor used to provide translations for some strings. The PO resource file for french was exported and the tool executed with LANGUAGE=fr and the french translation seen.

This proved the trivial workflow was straightforward to implement. It also provided insight into the need to automate the process as the manual website operation would soon become exceptionally tedious and error prone.
Something more usefulTo get a better understanding of a real world workflow I needed a project that:
I selected the NetSurf web browser as it best fit this list.

Internally NetSurf keeps all the translated messages in a simple associative array this is serialised to an equally straightforward file named FatMessages. The file is UTF-8 encoded with keys separated from values by a colon. The Key is constrained to be ASCII characters with no colons and is structured as language.toolkit.identifier and is unique on identifier part alone.

This file is processed at build time into a simple identifier:value dictionary for each language and toolkit.

Transifex can import several resource formats similar to this, after experimenting with YAML and Android Resource format I immediately discovered a problem, the services import and export routines were somewhat buggy.

These routines coped ok with simple use cases but having more complex characters such as angle brackets and quotation marks in the translated strings would completely defeat the escaping mechanisms employed by both these formats (through entity escaping in android resource format XML is problematic anyway)

Finally the Java property file format was used (with UTF-8 encoding) which while having bugs in the import and export escaping these could at least be worked around. The existing tool that was used to process the FatMessages file was rewritten to cope with generating different output formats and a second tool to merge the java property format resources.

To create these two tools I enlisted the assistance of my colleague Vivek Dasmohapatra as his Perl language skills exceeded my own. He eventually managed to overcome the format translation issues and produce correct input and output.
I used the Transifex platforms free open source product, created a new project and configured it for free machine translation from the Microsoft service, all of which is pretty clearly documented by Transifex.

Once this was done the messages file was split up tinto resources for the supported languages and uploaded to the transifex system.

I manually marked all the uploaded translations as "verified" and then added a few machine translations to a couple of languages. I also created spanish as a new language and machine translated most of the keys.

The resources for each language were then downloaded and merged and the resulting FatMessages file checked for differences and verified only the changes I expected appeared.

I quickly determined that manually downloading the language resources every time was not going to work with any form of automation, so I wrote a perl script to retrieve the resources automatically (might be useful for other projects too).

Once these tools were written and integrated into the build system I could finally make an evaluation as to how successful this exercise had been.
ConclusionsThe main things I learned from this investigation were:

Overall I think the final observation has to be that integrating translation services is not a straightforward operation and each project has unique challenges and requirements which reduce the existing platforms to compromise solutions.

Russ Allbery: Review: Asimov's, July 2011

Review: Asimov's Science Fiction, July 2011
Editor: Sheila Williams
Issue: Volume 35, No. 7
ISSN: 1065-2698
Pages: 112
Williams's editorial is a mildly interesting piece about story titles. Silverberg's column is a more interesting (and rather convincing) rebuttal of the joke that fiction authors are "professional liars," combined with an examination of a fake and fantastic 14th travelogue that (at least in Silverberg's telling) was widely believed at the time. The precis of Silverberg's argument is that lying requires an intent to deceive, which is a property of deceptive memoir writers but not of fiction authors. Di Filippo's review column, as usual, is devoted almost entirely to esoterica, although I was moderately interested to hear of Stableford's continued work on translating early French SF. None of it seems compelling enough to go buy, but good translations of early works seem like a good thing to have in the world. "Day 29" by Chris Beckett: The conceit of this novelette is an interstellar travel system akin to a transporter that allows near-instantaneous travel between worlds. The drawback is that all memories from somewhere between 40 and 29 days before transit up until transit are wiped. The progatonist is a data analyst who is about to travel, and therefore by agency rule is required to stop doing work on day 40 before transmission since he can't be held legally liable for anything he has no recollection of doing. (I would like to say that I find this implausible, since one could always keep records, but it's exactly the sort of ass-covering regulation that a human resources department would come up with.) The premise is quite interesting: what do you do during that period that you're going to forget? Beckett wisely mixes Stephen's current waiting period on the colony world with his diary of his original waiting period on Earth the first time he went through the transmission process, and the latter adds greatly to the reader's appreciation of the weirdness of the forgotten interval. Unfortunately, this is a story more about psychological exploration than about plot, and Stephen just isn't very interesting. The telepathic but possibly nonsentient aliens add weirdness but not much else, and the ending of the story provided little sense of closure or conclusion for me. A good idea, but not the execution I wanted. (5) "Pug" by Theodora Goss: Since I grew up with a pug, I have a soft spot for a story featuring one; sadly, though, this story has insufficient pug in it. This is a quiet fantasy (Asimov's calls it SF, presumably on the basis of parallel worlds and a hypothesized scientific explanation, but it reads like fantasy to me) featuring Victorian girls, including one with a bad heart. They discover a hidden door to other versions of their world and do some minor exploration. There's little or nothing in the way of plot; the story is more of an attempt to capture a mood. It's mildly diverting, but I wish it had gone somewhere more substantial. (5) "Dunyon" by Kristine Kathryn Rusch: A Rusch story is often the highlight of an issue, and this is no exception. The protagonist is the owner of a bar in a space station that's become a combination of a refugee camp and a slum. War and chaos have created desperate people, most of whom are attempting to find some way to resources and get out of the bottom of society. The story is about a rumor: a mythical system named Dunyon that's safe and far away. And it's about how people react to that rumor. There's nothing particularly surprising about the direction the story goes (it's fairly short), but Rusch is always a good storyteller. (7) "The Music of the Sphere" by Norman Spinrad: I've had mixed feelings about Spinrad's fiction (and some of his essays), but I liked this story, despite its implausibility. It's set in the near future, featuring an expert in cetaceans and dolphin perception and a composer obsessed with both loud music and classical musical style. Just from that description, you can probably predict much of the story, but I thought it had some neat ideas about dolphins, whales, and alternate perception and aesthetics. (Note: neat, not necessarily biologically plausible.) Enjoyable. (6) "Bring on the Rain" by Josh Roseman: In a change of pace from the rest of the issue, this is a post-apocalyptic story of caravans of wheeled ships traversing a scorched and ruined landscape in search of weather systems and rain. The feel is of an inverted Waterworld, but with more emphasis on military tactics and cooperating fleets. The transposition of fleet maneuvers to huge ground vehicles adds some extra fun. The plot has little to do with the background and is a fairly stock military adventure scenario, but it's reasonably well-told. The story feels like an excerpt from a larger military-SF-inspired adventure, but the length keeps the quantity of tactics and maneuvering below the threshold where I would get bored. (6) "Twelvers" by Leah Cypess: This is a sharp and occasionally mean story of adolescent cruelty and alienation. Darla is a "twelver," a child who was carried an extra three months in the womb using newly-invented medical technology because of a belief in the advantages this would bring in later life. Unfortunately for all those who used this technique, what it also brought was a preternatural calm and an unusual reaction to emotions. Darla finds it almost impossible to get upset at anything, and that, of course, prompts the cruelty and abuse of other children. Most of the story is a description of that abuse, leading up to Darla stumbling into a nasty solution to her immediate problem. It's all very believable (well, apart from the motivating biology), but I didn't enjoy reading about it, and I'm certainly not convinced that the ending will lead to anything good. (5) "The Messenger" by Bruce McAllister: This is a very short time travel story, where time travel is used to try to unwind old family pain. This world follows the unalterable history model: no changes to the past are possible, and anything you do in the past has already happened. The mechanics are mostly avoided. Instead, McAllister concentrates on his mother, his father, and their complex relationship. I would have needed a bit more background on the characters to care enough about them for the story to be fully effective, but while the heartstring-pulling is kind of obvious, it's still a solid story. (6) "The Copenhagen Interpretation" by Paul Cornell: This is the most ingenious of the stories in this issue. It's set in a future world that extends what seemed to me to be pre-World-War-I great power politics, although there may be a hint of the Cold War. Great nations have reached a careful balance of power, and spies and secret services work to sustain that balance. The progatonist is one of those agents, making use of advanced technology like space folds in the service of a cause that he doesn't entirely believe in. Cornell mixes in mental conditioning, artificial people, space travel, and even aliens (maybe) in a taut thriller plot that, for me, gained a great deal from the unexplained strangeness of its background. If you like diving into the deep end and following a fast-moving plot against a background of strangeness, this is the sort of SF you'll enjoy. (7) Rating: 6 out of 10

13 May 2013

Hideki Yamane: 100th Tokyo Debian meeting & "Wheezy" release party

We are please to report that we held "100th, Tokyo Area Debian Meeting"... yes, 100th!!! (since 2005), 11th May in Shibuya, Tokyo


Discussed about "stable" releasing,


lectured "cdn.debian.net" by Yasuhiro Araki
and "modern packaging" by Osamu Aoki.


Also, Ubuntu folks showed "Ubuntu phone" and it looks good and interesting (however, it's on the development stage, yet).
Then, party!!! :-) happy to release "Wheezy"


I hope we'll hold "Jessie" in early 2015.

11 May 2013

Russell Coker: Geographic Sorting Lessons to Learn from Ingress

I ve recently been spending a bit of my spare time playing Ingress (see the Wikipedia page if you haven t heard of it). A quick summary is that Ingress is an Android phone game that involves geo-location of portals that you aim to control and most operations on a portal can only be performed when you are within 40 meters so you do a lot of travelling to get to portals at various locations. One reasonably common operation that can be performed remotely is recharging a portal by using it s key, after playing for a while you end up with a collection of keys which can be difficult to manage. Until recently the set of portal keys was ordered alphabetically. This isn t particularly useful given the fact that portal names are made up by random people who photograph things that they consider to be landmarks. If people tried to use a consistent geographic naming system (which was short enough to fit in large print on a phone display) then it would be really difficult to make it usable. But as joke names are accepted there s just no benefit in having a sort by name. A recent update to the Ingress client (the program which runs on the Android phone and is used for all game operations) changed the sort order to be by distance. This makes it really easy to see the portals which are near you (which is really useful) but also means that the order changes whenever you move which isn t such a good idea for use on a mobile phone. It s quite common for Ingress players to recharge portals while on public transport. But with the new Ingress client the list order will change as you move so anyone who does recharging on a train will find the order of the list changing during the process and it s really difficult to find items in a list which is in a different order each time you look at it. This problem of ordering by location has a much greater scope than Ingress. One example is collections of GPS tagged photographs, it wouldn t make any sense to mix the pictures of two different sets of holiday pictures because they were both taken in countries that are the same distance from my current location (as the current Ingress algorithm would do). It seems to me that the best way of sorting geo-tagged items (Ingress portals, photos, etc) is to base it on the distance from a fixed point which the user can select. It could default to the user s current location but in that case the order of the list should remain unchanged at least until the user returns to the main menu and I think it would be ideal for the order to remain unchanged until the user requests it. I think that most Ingress players would agree with me that fixing annoying mis-features of the Ingress client such as this one would be better for the game than adding new features. While most computer games have some degree of make-work (in almost every case a computer could do things better than a person) I don t think that finding things in a changing list should be part of the make-work. Also it would be nice if Google released some code for doing this properly to reduce the incidence of other developers implementing the same mistakes as the Ingress developers in this regard.

9 May 2013

Gunnar Wolf: Still more e-voting related rants

Some weeks ago, I contacted Rosa Mart nez, a tech journalist with some questions regarding what I regarded as a trick interview with an e-voting salesman. Well, not only she offered me to publish an answer to that interview, but she also offered me to write another article on a second site she also works with. So, I accepted. Being quite time-deprived, although I managed to send her the first answer quickly, by April 22, I only sent the second article yesterday night. Anyway, the links. The texts are published in Spanish:

Hideki Yamane: 48GB mem machine for $600

DELL Power Edge T320 is sold for $250 and 8GB memory is $50, then 250 + 50 *6 = $550-600, 48GB memory. wow.

8 May 2013

Lior Kaplan: Debian in space

One more step at being the universal operating system: getting Debian to space:
Specifically, the International Space Station astronauts will be using computers running Debian 6.

Filed under: Debian GNU/Linux

Joey Hess: faster dh

With wheezy released, the floodgates are opened on a lot of debhelper changes that have been piling up. Most of these should be pretty minor, but I released one yesterday that will affect all users of dh. Hopefully in a good way. I made dh smarter about selecting which debhelper commands it runs. It can tell when a package does not use the stuff done by a particular command, and skips running the command entirely. So the debian/rules binary of a package using dh will now often look like this:

dh binary
   dh_testroot
   dh_prep
   dh_auto_install
   dh_installdocs
   dh_installchangelogs
   dh_perl
   dh_link
   dh_compress
   dh_fixperms
   dh_installdeb
   dh_gencontrol
   dh_md5sums
   dh_builddeb
Which is pretty close to the optimal hand-crafted debian/rules file (and just about as fast, too). But with the benefit that if you later add, say, cron job files, dh_installcron will automatically start being run too. Hopefully this will not result in any behavior changes, other than packages building faster and with less noise. If there is a bug it'll probably be something missing in the specification of when a command needs to be run. Beyond speed, I hope that this will help to lower the bar to adding new commands to debhelper, and to the default dh sequences. Before, every such new command slowed things down and was annoying. Now more special-purpose commands won't get in the way of packages that don't need them.
The way this works is that debhelper commands can include a "PROMISE" directive. An example from dh_installexamples
# PROMISE: DH NOOP WITHOUT examples
Mostly this specifies the files in debian/ that are used by the command, and whose presence triggers the command to run. There is also a syntax to specify items that can be present in the package build directory to trigger the command to run. (Unfortunatly, dh_perl can't use this. There's no good way to specify when dh_perl needs to run, short of doing nearly as much work as dh_perl would do when run. Oh well.) Note that third-party dh_ commands can include these directives too, if that makes sense.
I'm happy how this turned out, but I could be happier about the implementation. The PROMISE directives need to be maintained along with the code of the command. If another config file is added, they obviously must be updated. Other changes to a command can invalidate the PROMISE directive, and cause unexpected bugs. What would be ideal is to not repeat the inputs of the command in these directives, but instead write the command such that its inputs can be automatically extracted. I played around with some code like this:
$behavior = main_behavior("docs tmp(usr/share/doc/)", sub  
       my $package=shift;
       my $docs=shift;
       my $docdir=shift;
       install($docs, $docdir);
 );
$behavior->($package);
But refactoring all debhelper commands to be written in this style would be a big job. And I was not happy enough with the flexability and expressiveness of this to continue with it. I can however, dream about what this would look like if debhelper were written in Haskell. Then I would have a Debhelper a monad, within which each command executes.
main = runDebhelperIO installDocs
installDocs :: Monad a => Debhelper a
installDocs = do
    docs <- configFile "docs"
    docdir <- tmpDir "usr/share/doc"
    lift $ install docs docdir
To run the command, runDebhelperIO would loop over all the packages and run the action, in the Debhelper IO monad. But, this also allows making an examineDebhelper that takes an action like installDocs, and runs it in a Debhelper Writer monad. That would accumulate a list of all the inputs used by the action, and return it, without performing any side effecting IO actions. It's been 15 years since I last changed the language debhelper was written in. I did that for less gains than this, really. (The issue back then was that shell getopt sucked.) IIRC it was not very hard, and only took a few days. Still, I don't really anticipate reimplementing debhelper in Haskell any time soon. For one thing, individual Haskell binaries are quite large, statically linking all Haskell libraries they use, and so the installed size of debhelper would go up quite a bit. I hope that forthcoming changes will move things toward dynamically linked haskell libraries, and make it more appealing for projects that involve a lot of small commands. So, just a thought experiment for now..

7 May 2013

Matthew Garrett: A short introduction to TPMs

I've been working on TPMs lately. It turns out that they're moderately awful, but what's significantly more awful is basically all the existing documentation. So here's some of what I've learned, presented in the hope that it saves someone else some amount of misery.

What is a TPM?TPMs are devices that adhere to the Trusted Computing Group's Trusted Platform Module specification. They're typically microcontrollers[1] with a small amount of flash, and attached via either i2c (on embedded devices) or LPC[2] (on PCs). While designed for performing cryptographic tasks, TPMs are not cryptographic accelerators - in almost all situations, carrying out any TPM operations on the CPU instead would be massively faster[3]. So why use a TPM at all?
Keeping secrets with a TPMTPMs can encrypt and decrypt things. They're not terribly fast at doing so, but they have one significant benefit over doing it on the CPU - they can do it with keys that are tied to the TPM. All TPMs have something called a Storage Root Key (or SRK) that's generated when the TPM is initially configured. You can ask the TPM to generate a new keypair, and it'll do so, encrypt them with the SRK (or another key descended from the SRK) and hand it back to you. Other than the SRK (and another key called the Endorsement Key, which we'll get back to later), these keys aren't actually kept on the TPM - the running OS stores them on disk. If the OS wants to encrypt or decrypt something, it loads the key into the TPM and asks it to perform the desired operation. The TPM decrypts the key and then goes to work on the data. For small quantities of data, the secret can even be stored in the TPM's nvram rather than on disk.

All of this means that the keys are tied to a system, which is great for security. An attacker can't obtain the decrypted keys, even if they have a keylogger and full access to your filesystem. If I encrypt my laptop's drive and then encrypt the decryption key with the TPM, stealing my drive won't help even if you have my passphrase - any other TPM simply doesn't have the keys necessary to give you access.

That's fine for keys which are system specific, but what about keys that I might want to use on multiple systems, or keys that I want to carry on using when I need to replace my hardware? Keys can optionally be flagged as migratable, which makes it possible to export them from the TPM and import them to another TPM. This seems like it defeats most of the benefits, but there's a couple of features that improve security here. The first is that you need the TPM ownership password, which is something that's set during initial TPM setup and then not usually used afterwards. An attacker would need to obtain this somehow. The other is that you can set limits on migration when you initially import the key. In this scenario the TPM will only be willing to export the key by encrypting it with a pre-configured public key. If the private half is kept offline, an attacker is still unable to obtain a decrypted copy of the key.
So I just replace the OS with one that steals the secret, right?Say my root filesystem is encrypted with a secret that's stored on the TPM. An attacker can replace my kernel with one that grabs that secret once the TPM's released it. How can I avoid that?

TPMs have a series of Platform Configuration Registers (PCRs) that are used to record system state. These all start off programmed to zero, but applications can extend them at runtime by writing a sha1 hash into them. The new hash is concatenated to the existing PCR value and another sha1 calculated, and then this value is stored in the PCR. The firmware hashes itself and various option ROMs and adds those values to some PCRs, and then grabs the bootloader and hashes that. The bootloader then hashes its configuration and the files it reads before executing them.

This chain of trust means that you can verify that no prior system component has been modified. If an attacker modifies the bootloader then the firmware will calculate a different hash value, and there's no way for the attacker to force that back to the original value. Changing the kernel or the initrd will result in the same problem. Other than replacing the very low level firmware code that controls the root of trust, there's no way an attacker can replace any fundamental system components without changing the hash values.

TPMs support using these hash values to decide whether or not to perform a decryption operation. If an attacker replaces the initrd, the PCRs won't match and the TPM will simply refuse to hand over the secret. You can actually see this in use on Windows devices using Bitlocker - if you do anything that would change the PCR state (like booting into recovery mode), the TPM won't hand over the key and Bitlocker has to prompt for a recovery key. Choosing which PCRs to care about is something of a balancing act. Firmware configuration is typically hashed into PCR 1, so changing any firmware configuration options will change it. If PCR 1 is listed as one of the values that must match in order to release the secret, changing any firmware options will prevent the secret from being released. That's probably overkill. On the other hand, PCR 0 will normally contain the firmware hash itself. Including this means that the user will need to recover after updating their firmware, but failing to include it means that an attacker can subvert the system by replacing the firmware.
What about using TPMs for DRM?In theory you could populate TPMs with DRM keys for media playback, and seal them such that the hardware wouldn't hand them over. In practice this is probably too easily subverted or too user-hostile - changing default boot order in your firmware would result in validation failing, and permitting that would allow fairly straightforward subverted boot processes. You really need a finer grained policy management approach, and that's something that the TPM itself can't support.

This is where Remote Attestation comes in. Rather than keep any secrets on the local TPM, the TPM can assert to a remote site that the system is in a specific state. The remote site can then make a policy determination based on multiple factors and decide whether or not to hand over session decryption keys. The idea here is fairly straightforward. The remote site sends a nonce and a list of PCRs. The TPM generates a blob with the requested PCR values, sticks the nonce on, encrypts it and sends it back to the remote site. The remote site verifies that the reply was encrypted with an actual TPM key, makes sure that the nonce matches and then makes a policy determination based on the PCR state.

But hold on. How does the remote site know that the reply was encrypted with an actual TPM? When TPMs are built, they have something called an Endorsement Key (EK) flashed into them. The idea is that the only way to have a valid EK is to have a TPM, and that the TPM will never release this key to anything else. There's a couple of problems here. The first is that proving you have a valid EK to a remote site involves having a chain of trust between the EK and some globally trusted third party. Most TPMs don't have this - the only ones I know of that do are recent Infineon and STMicro parts. The second is that TPMs only have a single EK, and so any site performing remote attestation can cross-correlate you with any other site. That's a pretty significant privacy concern.

There's a theoretical solution to the privacy issue. TPMs never actually sign PCR quotes with the EK. Instead, TPMs can generate something called an Attestation Identity Key (AIK) and sign it with the EK. The OS can then provide this to a site called a PrivacyCA, which verifies that the AIK is signed by a real EK (and hence a real TPM). When a third party site requests remote attestation, the TPM signs the PCRs with the AIK and the third party site asks the PrivacyCA whether the AIK is real. You can have as many AIKs as you want, so you can provide each service with a different AIK.

As long as the PrivacyCA only keeps track of whether an AIK is valid and not which EK it was signed with, this avoids the privacy concerns - nobody would be able to tell that multiple AIKs came from the same TPM. On the other hand, it makes any PrivacyCA a pretty attractive target. Compromising one would not only allow you to fake up any remote attestation requests, it would let you violate user privacy expectations by seeing that (say) the TPM being used to attest to HolyScriptureVideos.com was also being used to attest to DegradingPornographyInvolvingAnimals.com.

Perhaps unsurprisingly (given the associated liability concerns), there's no public and trusted PrivacyCAs yet, and even if they were (a) many computers are still being sold without TPMs and (b) even those with TPMs often don't have the EK certificate that would be required to make remote attestation possible. So while remote attestation could theoretically be used to impose DRM in a way that would require you to be running a specific OS, practical concerns make it pretty difficult for anyone to deploy that at any point in the near future.
Is this just limited to early OS components?Nope. The Linux kernel has support for measuring each binary run or each module loaded and extending PCRs accordingly. This makes it possible to ensure that the running binaries haven't been modified on disk. There's not a lot of distribution infrastructure for setting this up, but in theory a distribution could deploy an entirely signed userspace and allow the user to opt into only executing correctly signed binaries. Things get more interesting when you add interpreted scripts to the mix, so there's still plenty of work to do there.
So what can I actually use a TPM for?Drive encryption is probably the best example (Bitlocker does it on Windows, and there's a LUKS-based implementation for Linux here) - while in theory you could do things like use your TPM as a factor in two-factor authentication or tie your GPG key to it, there's not a lot of existing infrastructure for handling all of that. For the majority of people, the most useful feature of the TPM is probably the random number generator. rngd has support for pulling numbers out of it and stashing them in /dev/random, and it's probably worth doing that unless you have an Ivy Bridge or other CPU with an RNG.

Things get more interesting in more niche cases. Corporations can bind VPN keys to corporate machines, making it possible to impose varying security policies. Intel use the TPM as part of their anti-theft technology on education-oriented devices like the Classmate. And in the cloud, projects like Trusted Computing Pools use remote attestation to verify that compute nodes are in a known good state before scheduling jobs on them.
Is there a threat to freedom?At the moment, probably not. The lack of any workable general purpose remote attestation makes it difficult for anyone to impose TPM-based restrictions on users, and any local code is obviously under the user's control - got a program that wants to read the PCR state before letting you do something? LD_PRELOAD something that gives it the desired response, or hack it so it ignores failure. It's just far too easy to circumvent.
Summary?TPMs are useful for some very domain-specific applications, drive encryption and random number generation. The current state of technology doesn't make them useful for practical limitations of end-user freedom.

[1] Ranging from 8-bit things that are better suited to driving washing machines, up to full ARM cores
[2] "Low Pin Count", basically ISA without the slots.
[3] Loading a key and decrypting a 5 byte payload takes 1.5 seconds on my laptop's TPM.

comment count unavailable comments

Gunnar Wolf: Talking about Debian while Debian was getting released

Last Saturday, I was invited to talk about Debian to Hackerspace DF, a group that is starting to work at a very nice place together with other collectives, in a quite centric place (Colonia Obrera). I know several of the people in the group (visited them a couple of times in the space's previous incarnation), and wish them great luck in this new hackerspace! Anyway I was invited to give an informal talk about Debian. And of course, I was there. And so was Alfredo, who recorded (most of) it. So, in case you want to see me talking about how Debian works, mostly on a social organization level (but also regarding some technical details). Of course, given the talk was completely informal (it started by me standing there, asking, "OK, any questions?"), I managed to mix up some names and stuff... But I hope that, in the end, the participants understood better what Debian means than when we started. Oh, and by the end of the talk, we were all much happier. Not only because I was about to shut up, but because during my talk, we got notice that Debian 7.0 "Wheezy" was released. Anyway If you want to see me talking for ~1hr, you can download the video or watch it on YouTube.

Timo Jyrinki: Qt 5 in Debian and Ubuntu, patches upstreaming

PackagesI quite like the current status of Qt 5 in Debian and Ubuntu (the links are to the qtbase packages, there are ca. 15 other modules as well). Despite Qt 5 being bleeding edge and Ubuntu having had the need to use it before even the first stable release came out in December, the co-operation with Debian has gone well. Debian is now having the first Qt 5 uploads done to experimental and later on to unstable. My work contributed to pkg-kde git on the modules has been welcomed, and even though more work has been done there by others, there haven't been drastic changes that would cause too big transition problems on the Ubuntu side. It has of course helped to ask others what they want, like the whole usage of qtchooser. Now with Qt 5.0.2 I've been able to mostly re-sync all newer changes / fixes to my packaging from Debian to Ubuntu and vice versa.

There will remain some delta, as pkg-kde plans to ask for a complete transition to qtchooser so that all Qt using packages would declare the Qt version either by QT_SELECT environment variable (preferable) or a package dependency (qt5-default or qt4-default). As a temporary change related to that, Debian will have a debhelper modification that defaults QT_SELECT to qt4 for the duration of the transition. Meanwhile, Ubuntu already shipped the 13.04 release with Qt 5, and a shortcut was taken there instead to prevent any Qt 4 package breakage. However, after the transition period in Debian is over, that small delta can again be removed.

I will also need to continue pushing any useful packaging I do to Debian. I pushed qtimageformats and qtdoc last week, but I know I'm still behind with some "possibly interesting" git snapshot modules like qtsensors and qtpim.

PatchesMore delta exists in the form of multiple patches related to the recent Ubuntu Touch efforts. I do not think they are of immediate interest to Debian let's start packaging Qt 5 apps to Debian first. However, about all of those patches have already been upstreamed to be part of Qt 5.1 or Qt 5.2, or will be later on. Some already were for 5.0.2.

A couple of months ago Ubuntu did have some patches hanging around with no clear author information. This was a result of the heated preparation for the Ubuntu Touch launches, and the fact that patches flew (too) quickly in place into various PPA:s. I started hunting down the authors, and the situation turned out to be better than I thought. About half of the patches were already upstreamed, and work on properly upstreaming the other ones was swiftly started after my initial contact. Proper DEP3 fields do help understanding the overall situation. There are now 10 Canonical individuals in the upstream group of contributors, and in the last week's sprint it turned out more people will be joining them to upstream their future patches.

Nowadays about all the requests I get for including patches from developers are stuff that was already upstreamed, like the XEmbed support in qtbase. This is how it should be.

One big patch still being Ubuntu only is the Unity appmenu support. There was a temporary solution for 13.04 that forward-ported the Qt 4 way of doing it. This will be however removed from the first 13.10 ('saucy') upload, as it's not upstreamable (the old way of supporting Unity appmenus was deliberately dropped from Qt 5). A re-implementation via QPA plugin support is on its way, but it may be that the development version users will be without appmenu support for some duration. Another big patch is related to qtwebkit's device pixel ratio, which will need to be fixed. Apart from these two areas of work that need to be followed through, patches situation is quite nice as mentioned.
ConclusionFree software will do world domination, and I'm happy to be part of it.

6 May 2013

Junichi Uekawa: Got a new 27 inch monitor.

Got a new 27 inch monitor. Thanks to my friend. Connecting with displayPort cable was a breeze. xrandr tells me it is capable of 2560x1440, which is a lot of space compared to 1366x768 on MacBook Air.

Michal &#268;iha&#345;: phpMyAdmin in GSoC 2013

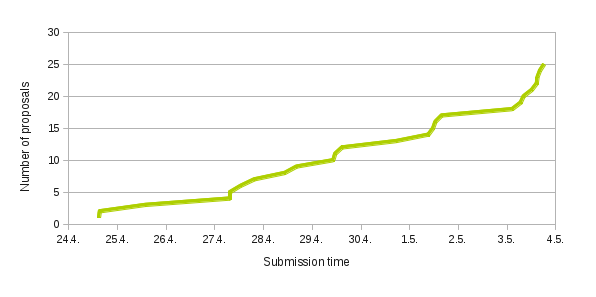
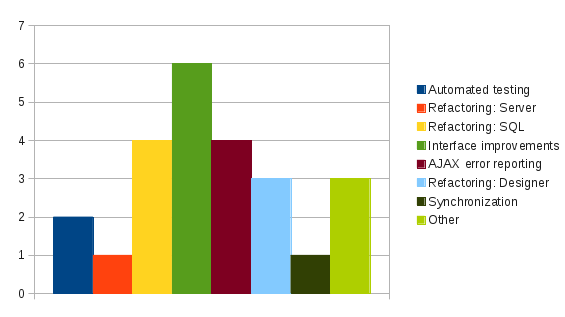
As student application period of Google Summer of Code 2013 is over, it's time to look at proposals we got for phpMyAdmin. First of all we got slightly less proposals than in past years. This is probably related to the fact that we still heavily focus on code cleanup this year and this is definitely not that interesting topic as adding new features. I think quality has also slightly improved and this time we received no bogus or spam proposals. Also as usual, people tend to leave submission for very last date (though not that much as in past years): Number of applications over time Quite unsurprisingly the most interesting topic seemed to be interface improvements, though it is quite wide. You can see how other topics were frequent in following chart: Number of applications for various types Please note that the numbers are not 100% accurate as some proposals really did not fit into above categories. Anyway we're just working on evaluation and will finalize it in upcoming days. Of course you will know the results from Google on May 27th.
Filed under: English Phpmyadmin 0 comments Flattr this!

Sylvestre Ledru: Follow up on Debian & Clang

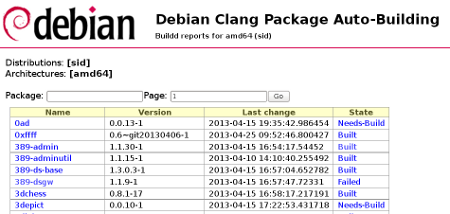
A week after the Euro LLVM conference, I am glad to share the results I presented and discussed during the event. 1) Parallel building infrastructure using clang instead of gcc Based on the work that Alexander Pashaliyski and I did during the GSoC 2012, we are now able to automatically rebuild each package uploaded in Unstable transparently. Results are published here:
http://buildd-clang.debian.net/
This provides a quick and easy way to any Debian contributors or upstream packaged in Debian to check how the package behaves with clang.
For Debian Developer and maintainer, a per maintainer view is also provided. This will list all packages maintained by a Debian packager. My page as example Here is an example of the list of package:
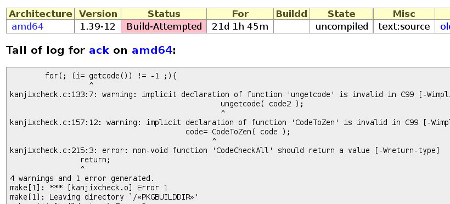
And an example of package failing:
At time of writing, most of the packages in unstable have been rebuilt (16 % are remaining). However, due to resource constraints, only amd64 packages are built. Contact me if you have resources to share for other architectures. Thanks to Paul Wise, the PTS (Debian package tracking system) proposes a link to the clang build logs (failing or not). A repository will be automatically updated with the results of these builds (once I find the time to get into buildd). 2) clang-built repository

Thanks to the Amazon Cloud, with our new DPL (Debian Project Leader), Lucas Nussbaum, we rebuilt unstable last April and published it at the following address:
deb http://clang.debian.net/repository-2013-04-07/ unstable-clang main
This allows some cool stuff like:
$ echo "deb http://clang.debian.net/repository-2013-04-07/ unstable-clang main">>/etc/apt/sources.list
$ apt-get update
$ apt-get install coreutils/unstable-clang
$ ls
$ awk
Note that this repository was only one-shoot and does not get updated. Quality of the binary produced (performance and size) can be tested thanks to this repository. Feedbacks are welcome!

Sylvestre Ledru: Follow up on Debian & Clang

A week after the Euro LLVM conference, I am glad to share the results I presented and discussed during the event. 1) Parallel building infrastructure using clang instead of gcc Based on the work that Alexander Pashaliyski and I did during the GSoC 2012, we are now able to automatically rebuild each package uploaded in Unstable transparently. Results are published here:
http://buildd-clang.debian.net/
This provides a quick and easy way to any Debian contributors or upstream packaged in Debian to check how the package behaves with clang.
For Debian Developer and maintainer, a per maintainer view is also provided. This will list all packages maintained by a Debian packager. My page as example Here is an example of the list of package:
And an example of package failing:
At time of writing, most of the packages in unstable have been rebuilt (16 % are remaining). However, due to resource constraints, only amd64 packages are built. Contact me if you have resources to share for other architectures. Thanks to Paul Wise, the PTS (Debian package tracking system) proposes a link to the clang build logs (failing or not). A repository will be automatically updated with the results of these builds (once I find the time to get into buildd). 2) clang-built repository
Thanks to the Amazon Cloud, with our new DPL (Debian Project Leader), Lucas Nussbaum, we rebuilt unstable last April and published it at the following address:
deb http://clang.debian.net/repository-2013-04-07/ unstable-clang main
This allows some cool stuff like:
$ echo "deb http://clang.debian.net/repository-2013-04-07/ unstable-clang main">>/etc/apt/sources.list
$ apt-get update
$ apt-get install coreutils/unstable-clang
$ ls
$ awk
Note that this repository was only one-shoot and does not get updated. Quality of the binary produced (performance and size) can be tested thanks to this repository. Feedbacks are welcome!

Sylvestre Ledru: Follow up on Debian & Clang

A week after the Euro LLVM conference, I am glad to share the results I presented and discussed during the event. 1) Parallel building infrastructure using clang instead of gcc Based on the work that Alexander Pashaliyski and I did during the GSoC 2012, we are now able to automatically rebuild each package uploaded in Unstable transparently. Results are published here:
http://buildd-clang.debian.net/
This provides a quick and easy way to any Debian contributors or upstream packaged in Debian to check how the package behaves with clang.
For Debian Developer and maintainer, a per maintainer view is also provided. This will list all packages maintained by a Debian packager. My page as example Here is an example of the list of package:
And an example of package failing:
At time of writing, most of the packages in unstable have been rebuilt (16 % are remaining). However, due to resource constraints, only amd64 packages are built. Contact me if you have resources to share for other architectures. Thanks to Paul Wise, the PTS (Debian package tracking system) proposes a link to the clang build logs (failing or not). A repository will be automatically updated with the results of these builds (once I find the time to get into buildd). 2) clang-built repository
Thanks to the Amazon Cloud, with our new DPL (Debian Project Leader), Lucas Nussbaum, we rebuilt unstable last April and published it at the following address:
deb http://clang.debian.net/repository-2013-04-07/ unstable-clang main
This allows some cool stuff like:
$ echo "deb http://clang.debian.net/repository-2013-04-07/ unstable-clang main">>/etc/apt/sources.list
$ apt-get update
$ apt-get install coreutils/unstable-clang
$ ls
$ awk
Note that this repository was only one-shoot and does not get updated. Quality of the binary produced (performance and size) can be tested thanks to this repository. Feedbacks are welcome!

5 May 2013

Vasudev Kamath: CDBS Packaging: package relationship management

(It took me a while to come up with new CDBS packaging series post not because I stopped using CDBS just because I was procrastinating myself as busy) This is the second post in the CDBS packaging series. In this series I'm going to talk about package relationship management. The better example where this feature is useful is packages where build-depends and run-time dependencies overlap. Most of the Perl modules which have test suites have build-depend and run-time dependency intersection. So let me take example of a Perl module. First lets see control file of a Perl package which is not using CDBS and then let me explain how CDBS can help you improve the situation. I choose libxml-libxml-perl lets see part of control file which includes Build-Depends Depends Suggests Recommends.
Source: libxml-libxml-perl
Maintainer: Debian Perl Group <pkg-perl-maintainers@lists.alioth.debian.org>
Uploaders: Jonathan Yu <jawnsy@cpan.org>,
 gregor herrmann <gregoa@debian.org>,
 Chris Butler <chrisb@debian.org>
Section: perl
Priority: optional
Build-Depends: perl (>= 5.12),
 debhelper (>= 9.20120312),
 libtest-pod-perl,
 libxml2-dev,
 libxml-namespacesupport-perl,
 libxml-sax-perl,
 zlib1g-dev
Standards-Version: 3.9.4
Vcs-Browser: http://anonscm.debian.org/gitweb/?p=pkg-perl/packages/libxml-libxml-perl.git
Vcs-Git: git://anonscm.debian.org/pkg-perl/packages/libxml-libxml-perl.git
Homepage: https://metacpan.org/release/XML-LibXML/
Package: libxml-libxml-perl
Architecture: any
Depends: $ shlibs:Depends , $ misc:Depends , $ perl:Depends ,
 libxml-namespacesupport-perl,
 libxml-sax-perl
Breaks: libxml-libxml-common-perl
Replaces: libxml-libxml-common-perl
Description: Perl interface to the libxml2 library
 XML::LibXML is a Perl interface to the GNOME libxml2 library, which provides
 interfaces for parsing and manipulating XML files. This module allows Perl
 programmers to make use of the highly capable validating XML parser and the
 high performance Document Object Model (DOM) implementation. Additionally, it
 supports using the XML Path Language (XPath) to find and extract information.
So 2 packages are both in Build-Depends and Depends field
  1. libsax-xml-perl
  2. libxml-namespacesupport-perl
So in this situation there is a possibility that we miss to add one or both of these packages into Depends field, I'm not saying we will surely miss but we might after all we are all human beings. So how can we improve the situation using CDBS? Let me go through step by step on what we need to do.
  1. Create a file called control.in with same above contents but slight modification in Build-Depends and Depends section. I will display the diff below to avoid re-pasting entire file again and again.
--- debian/control      2013-04-28 23:08:11.930082600 +0530
+++ debian/control.in   2013-05-04 20:51:18.849680419 +0530
@@ -5,13 +5,7 @@
  Chris Butler <chrisb@debian.org>
 Section: perl
 Priority: optional
-Build-Depends: perl (>= 5.12),
- debhelper (>= 9.20120312),
- libtest-pod-perl,
- libxml2-dev,
- libxml-namespacesupport-perl,
- libxml-sax-perl,
- zlib1g-dev
+Build-Depends: @cdbs@
 Standards-Version: 3.9.4
 Vcs-Browser: http://anonscm.debian.org/gitweb/?p=pkg-perl/packages/libxml-libxml-perl.git
 Vcs-Git: git://anonscm.debian.org/pkg-perl/packages/libxml-libxml-perl.git
@@ -20,8 +14,7 @@
 Package: libxml-libxml-perl
 Architecture: any
 Depends: $ shlibs:Depends , $ misc:Depends , $ perl:Depends ,
- libxml-namespacesupport-perl,
- libxml-sax-perl
+ $ cdbs:Depends 
 Breaks: libxml-libxml-common-perl
 Replaces: libxml-libxml-common-perl
 Description: Perl interface to the libxml2 library
@@ -30,4 +23,3 @@
  programmers to make use of the highly capable validating XML parser and the
  high performance Document Object Model (DOM) implementation. Additionally, it
  supports using the XML Path Language (XPath) to find and extract information.
-
  1. Next we need to have something like below in the rule files
#!/usr/bin/make -f
include /usr/share/cdbs/1/rules/debhelper.mk
include /usr/share/cdbs/1/rules/utils.mk
include /usr/share/cdbs/1/rules/upstream-tarball.mk
include /usr/share/cdbs/1/class/perl-makemaker.mk
pkg = $(DEB_SOURCE_PACKAGE)
deps = libxml-libxml-perl libxml-sax-perl
deps-test = libtest-pod-perl
CDBS_BUILD_DEPENDS +=, $(deps), $(deps-test)
CDBS_BUILD_DEPENDS +=, zlib1g-dev, libxml2-dev, perl (>= 5.12)
CDBS_DEPENDS_$(pkg) = , $(deps)
So basically we moved all Build-Depends and Depends to rules file. The common ones are placed in deps variable and assigned to both Build-Depends and Depends. CDBS uses following variables for package relationship management.
  1. CDBS_BUILD_DEPENDS: This variable helps you manage Build-Depends field and all you need to do is in your control.in files Build-Depends field put place holder @cdbs@
  2. CDBS_DEPENDS: This field can be used to manage Depends field of binary package for each binary package you need to have one CDBS_DEPENDS_pkgname variable with depends assigned to it. And in your control.in append $ cdbs:Depends to Depends field.
  3. CDBS_PROVIDES, CDBS_BREAKS, CDBS_RECOMMENDS, CDBS_PREDEPENDS, CDBS_SUGGESTS, CDBS_REPLACES: all these does the job what you think it does :-).
Other than CDBS_BUILD_DEPENDS all other variables work using substvars i.e. CDBS will put the respective substitutions in pkgname.substvars file which will be used during deb creation to replace things in control file. So to make CDBS generate new control file run the below command
DEB_MAINTAINER_MODE=1 fakeroot debian/rules debian/control
Basically this command needs to be executed before starting build process if you miss your changes will not be reflected into debian/control. Additionally this feature is Maintainer Mode helper tool because Debian policy prohibits change of debian/control during normal package build. So what is the benefit of using this feature of CDBS? I've listed some of them which I felt are obvious.
  1. When there is intersection in Build-Depends and Depends this feature from CDBS is helpful. As I shown above put all intersecting dependencies in common variable and appropriately assign them wherever it is required. Thus we can avoid possible missing of some of run-time dependencies due to human error.
  2. It is also possible that newer version of package requires specific version of some package (mostly libraries) and we updated build dependencies but we might forget to do the same in Depends, by using this feature we can make sure we will not miss such minute details.
One last thing I want to point out is if you are NMUing a CDBS package
NMUs need not (but are encouraged to) make special use of these tools. In particular, the debian/control.in file can be completely ignored.
Before closing down the post, If you find some mistake in the post please let me know either through comments or through the email. Soon I will be back with new CDBS recipes till then cya.

4 May 2013

Joerg Jaspert: Wheezy release

There was Lenny, there was Squeeze, now there is Wheezy. Another major release of Debian where I had the pleasure to do the ftpmaster work for the release. Like the last times, Mark joined to help with the work. But 2 FTPMasters aren t enough for one Wheezy, or so, so Ansgar had his first run aside from point releases. With the whole load of work the release team did in the past to prepare this, combined with all the changes in dak we had since Squeeze, it turned out to be rather easy for us. Again, a few moments and not a detailed log (times in CEST): Right now (that is, 21:08 CEST) I am mostly waiting for the CD build to finish. Current schedule seems to have that in some two and a half hours, after which we can push the mirrors and our press people announce it. Except if Murphy wants to show up, but lets hope that not. Thanks go out to everyone involved in preparing this release, be it in the past by fixing bugs, uploading packages, doing whatever was needed, as well as doing the work today.

Russ Allbery: Review: Democracy at Work

Review: Democracy at Work, by Richard Wolff
Publisher: Haymarket
Copyright: 2012
ISBN: 1-60846-247-1
Format: Kindle
Pages: 220
I've been reading (mostly on-line) and thinking quite a bit lately about workplace governance models, economic structure, and why the current organization of the US workplace bothers me so intensely, partly triggered by reading John Kenneth Galbraith's The Affluent Society. The economic monoculture has made that process particularly frustrating. It's rare to find a discussion, even in the context of organizational strategies that are considered radical, that avoids the standard frame of productivity and business value. Most discussion is long on tactics and short on strategy and examination of goals. Wolff's appearance on Moyers & Company was a rare breath of fresh air, enough so that I grabbed his book shortly afterwards. Wolff is a Marxian economist (meaning that he makes use of Marxist analysis of economics and capitalism while separating them from Marxist politics and Marx's advocacy of revolutionary socialism), which for me was part of the interest. Marxist thought of any branch is not common in the United States; we're regularly deprived of several sides in the international conversation on economic models. I was taught Marxist theory in elementary and high school (in retrospect, surprisingly even-handedly and well, despite the biases of my schooling), but none of the later developments of Marxist thought. I think that's a typical experience here; in the United States, Marxism culminated in Mao and Stalin, and no further development of the underlying theories is ever mentioned. Democracy at Work is subtitled A Cure for Capitalism and does indeed advocate a concrete alternative to capitalist business structures. But this is only the last third of the book (and in some ways the least useful, as I'll discuss in a moment). The first two-thirds of the book is basically a remedial education in modern, as opposed to historic, Marxian economics for US readers like myself who have never heard it before, cast in the context of the current financial crisis. This may well be old hat for Europeans, but if you've been wondering what (at least some) modern-day Marxists actually believe, or are saying to yourself "there are modern-day Marxists after the collapse of the Soviet Union?", I recommend this book to your attention. It's an excellent summary, which I read with the delightful feeling of an expanding viewpoint and the discovery of new directions from which to look at a problem. There's quite a bit in this section that's worth thinking about, including another take on the nature of the recent economic collapse and how that fits into a Marxian analysis of capitalist crises. But there was one point in Wolff's explanation that I found particularly helpful. He completely restructured my understanding of the Marxian analysis of worker exploitation and profit allocation. There are two angles of Marxist economic thought and socialist economics that get a great deal of attention, at least in the United States, in history and economics classes: the role (or lack thereof) of markets in price setting, and the ownership of the means of production. Defenders of capitalism like to focus on the former, since it's quite easy to identify the advantages of theoretical free markets in finding ideal prices and balancing supply and demand, whereas central planning of prices and production has resulted in some catastrophic and deadly failures. (Although I will note, with passing interest, that those failures predate large-scale computing, and there are now large corporations that manage budgets larger than some countries via centralized command-and-control economic practices.) Defenders of socialism are more likely to focus on the ownership of the means of production, since it's easy to show prima facie unfairness in owners of capital extracting vast profits without having to do any work themselves, only be lucky enough to start with large quantities of money. Wolff, however, argues that both of these focuses misses a core critique by Marx of the workplace structure in capitalism, and that, by ignoring that critique, supposedly Marxist countries did not create anything that was actually Marxist in implementation. The Soviet Union was just as much a capitalist country as the United States is. It was state capitalism rather than private capitalism, but the core capitalist structure was intact. Wolff arrives at this conclusion, which may be well-trodden ground in parts of the world that include active Marxist thought but which was quite startling to this American, by treating the ownership of capital as a partial distraction. He focuses on a more direct question and practical question: who determines what a worker does on a day-to-day basis and how that product is used? Who determines what profits are collected and how they are spent? In private capitalism, this is done by the owners of the capital: large shareholders, major investors, and the managerial class that they hire. In Soviet state capitalism, this is done by national politicians, bureaucrats, and the managerial class that they hire. In neither model is it done by the workers themselves. The Soviet model gives theoretical ownership of the capital to the workers, but that ownership is diffused, centralized, and politicized, redirected through the mechanisms of the state, and therefore is effectively ignored. Ownership and control is entirely captured by the political class. Both of these systems are capitalist in Wolff's view of Marx: there is a class of owners and managers, who control the terms and nature of work and who allocate the profits, and a class of workers, who have to do what they're told, are not paid full value for their labor, and don't have a say in how the profits their work generates are spent. At the most important level of day-to-day autonomy and empowerment, they are functionally identical. They are both equally hierarchical and exploitative; the only difference is in whether the system is controlled by rich individuals or by well-connected politicians. (And, as any study of modern politics quickly reveals, the distinction between those two groups in most countries is murky at best.) Wolff convincingly recasts modern economic history as a constant pendulum swing between private capitalism and state capitalism. Crises in one system push countries towards the other system; subsequent crises push the country back towards the first system. Regulation grows and shrinks, companies are nationalized and then privatized, but both systems are united in excluding the worker from any meaningful control over their work life. The first two-thirds of the book was full of insights like this for me. I didn't agree with all of it, but all of it was worthwhile and thought-provoking. But I was a bit leery of Wolff's proposed solution. My past experience with critics of capitalism is that the critique is often quite compelling, but the proposed solution is much less believable. And, sadly, that concern was warranted here as well. The core of Wolff's proposal is predictable but possibly sound: a restructuring of the workplace to be radically democratic. The business would be owned entirely and exclusively by the people who work for it, equally regardless of the job of the worker, and the workers would decide democratically or via elected repesentatives from among the workers how to allocate the profits of the business, what standards and business practices should be followed, and how the work is to be done. I was particularly interested to hear that this model (workers' self-directed enterprises) has apparently been successful in Spain in the form of the Mondragon Cooperative. Given all the tricky, small details that have to be resolved in an actual workplace, an existence proof is worth more than pounds of theory. Unfortunately, like a lot of proposed alternatives, Wolff's description of WSDEs is quite fuzzy and involves a lot of hand-waving. I was never able to build, from this book, a coherent and complete mental model of how such a workplace would function. Wolff tends to surround every specific in a halo of contingencies, possibilities, and alternative models, and is maddeningly nonspecific on such practical matters as how line management would work, how such a business would do financial planning or project approval, how competing interests in different parts of the organization would be balanced, and other practical governance matters that fill my work life. Maybe the answer to all of that is just "democracy," but I'm dubious. Democracy has a number of well-known flaws that I thought weren't adequately addressed. For example, democracies are often quite happy to further and reinforce existing prejudice (such as sexism or racism), and are prone to yielding control to the most charismatic. Democracies also have an informed voter problem, which seems like it would be particularly acute if democracy is going to make detailed business decisions. And, for larger organizations, control by pre-existing money could re-enter the equation via propaganda and campaigning around votes. Some of this gap in the book could be addressed via a more in-depth look at how Mondragon and any other real-life examples work, but that is sadly missing here. (I am interested enough now, though, that I'd read a good popular treatment of the history and methodology of Mondragon, although I don't think I'm up to working through an academic study.) The hierarchical, dictatorial management structure imposed by capitalism is so awful that WSDEs don't have a particularly high bar to meet to be fairer and more empowering than what we have today. The question, rather, is would they function sufficiently well that the business would be able to make effective decisions, and that's unclear to me from this book. This is, as Wolff spends some time discussing, particularly difficult when in direct competition with capitalist enterprises. This sort of endeavor will probably trade some degree of economic efficiency and raw marketplace power for improvements to fairness and empowerment, but that means it's going to require support from the surrounding society, which is a huge obstacle. I doubt there's a free lunch here: true fairness and equity also leading to improved economic efficiency in a capitalist context is a nice dream, but not horribly practical. Wolff also seems to suffer from something else I associate with Marxist thought: a preferential focus on a very narrowly-defined type of productive worker, apparently left over from Marx's original critique in the context of industrialization. Wolff inserts a very odd and quite awkward distinction in his WSDE model between workers who directly produce the product that's sold, and who in his model therefore produce the profits of the business, and all other workers in the business. He then gives special privileges to the former group to decide how much profit to return in worker compensation and how much to use for other purposes, thus making the supporting workers second-class citizens within this supposedly equal workplace. Speaking as someone who works in IT, and hence would be classified by Wolff into the supporting rather than directly productive category, I do not find this division at all convincing, and Wolff never provides a coherent explanation for why he introduced it. He only says that it's necessary for the governance of the business to not be exploitative, which seems to assume that there is a special economic role played by the workers who work directly on a saleable product. Maybe there is some analysis that could convince me of this, but, if so, it's not present in this book. It struck me as a recipe for continuing the exploitation of the most invisible and powerless workers in capitalism: janitors, groundskeepers, and other low-paid service jobs. I wish the whole book were as insightful and pointed as the first two-thirds, but alas I found the WSDE discussion to be somewhat muddled and utopian. "How do we get there from here" is always the hardest part of this type of discussion, and Wolff has no special skill in that department. But, despite that, I got a lot of fascinating ideas and new conceptual frameworks out of this book, and I'm tempted to read it again. I suspect some of this, similar to my discovery of promises and infinite streams in programming, is filling in of odd gaps in my personal education rather than a discovery of unusual, new ideas. But if you too have gotten your political education within the US capitalism ber alles bubble, this book may fill in similar gaps in your knowledge. If so, it's a very rewarding experience. If you're curious about a preview of Wolff's perspective without paying for the book, I recommend watching the first episode of Moyers & Company in which he appeared. Wolff is a clear and engaging speaker, and his interview provides a good feel for his discussion style and his general perspective. Rating: 8 out of 10

2 May 2013

Joey Hess: the #newinwheezy game: STM

Debian wheezy includes a bunch of excellent new Haskell libraries. I'm going to highlight one that should be interesting to non-Haskell developers, who may have struggled with writing non-buggy threaded programs in other languages: libghc-stm-dev I had given up on most threaded programs before learning about Software Transactional Memory. Writing a correct threaded program, when multiple threads needed to modify the same state, needed careful uses of locking. In my experience, locking is almost never gotten right the first time. A real life example I encountered is an app that displays a queue of files to be downloaded, and a list of files currently downloading. Starting a new download would go something like this:
startDownload = do
    file <- getQueuedFile
    startDownloadThread file
    push file currentDownLoads
But there's a point in time in which another thread, that refreshes the display, could then see an inconsistent state, where the file is in neither place. To fix this, you'd need to add lock checking around all accesses to the download queue and current downloads list, and lock them both here. (And be sure to always take the locks in the same order!) But, it's worse than that, because how is getQueuedFile implemented? If the queue is empty, it needs to wait on a file being added. But how can a file be added the queue if we've locked it in order to perform this larger startDownload operation? What should be really simple code has become really complex juggling of locks. STM deals with this in a much nicer way:
startDownload = atomically $ do
    file <- getQueuedFile
    startDownloadThread file
    push file currentDownLoads
Now the two operations are performed as one atomic transaction. It's not possible for any other thread to see an inconsistent state. No explicit locking is needed. And, getQueuedFile can do whatever waiting it needs to, also using STM. This becomes part of the same larger transaction, in a way that cannot deadlock. It might be implemented like this:
getQueuedFile = atomically $
    if empty downloadQueue
        then retry
        else pop downloadQueue
When the queue is empty and this calls "retry", STM automatically waits for the queue to change before restarting the transaction. So this blocks until a file becomes available. It does it without any locking, and without you needing to explicitly tell STM what you're waiting on. I find this beautiful, and am happier with it the more I use it in my code. Functions like getQueuedFile that run entirely in STM are building blocks that can be snapped together without worries to build more and more complex things. For non-Haskell developers, STM is also available in Clojure, and work is underway to add it to gcc. There is also Hardware Transactional Memory coming, to speed it up. Although in my experience it's quite acceptably fast already. However, as far as I know, all these other implementations of STM leave developers with a problem nearly as thorny as the original problem with locking. STM inherently works by detecting when a change is made that conflicts with another transaction, throwing away the change, and retrying. This means that code inside a STM transaction may run more than once. Wait a second.. Doesn't that mean this code has a problem?
startDownload = atomically $ do
    file <- getQueuedFile
    startDownloadThread file
    push file currentDownLoads
Yes, this code is buggy! If the download thread is started, but then STM restarts the transaction, the same file will be downloaded repeatedly. The C, Clojure, etc, STM implementations all let you write this buggy code. Haskell, however, does not. The buggy code I showed won't even compile. The way it prevents this involves, well, monads. But essentially, it is able to use type checking to automatically determine that startDownloadThread is not safe to put in the middle of a STM transaction. You're left with no choice but to change things so the thread is only spawned once the transaction succeeds:
startDownload = do
    file <- atomically $ do
        f <- getQueuedFile
        push f currentDownLoads
        return f
    startDownloadThread file
If you appreciate that, you may want to check out some other #newinwheezy stuff like libghc-yesod-dev, a web framework that uses type checking to avoid broken urls and XSS attacks, and also makes heavy use of threading, so is a great fit for using with STM. And libghc-quickcheck2-dev, which leverages the type system to automatically test properties about your program.

Next.

Previous.