Search Results: "reg"

24 March 2025

Arnaud Rebillout: Buid container images with buildah/podman in GitLab CI

Oh no, it broke again! Today, this .gitlab-ci.yml file no longer works in GitLab CI:
build-container-image:
  stage: build
  image: debian:testing
  before_script:
    - apt-get update
    - apt-get install -y buildah ca-certificates
  script:
    - buildah build -t $CI_REGISTRY_IMAGE .
The command buildah build ... fails with this error message:
STEP 2/3: RUN  apt-get update
internal:0:0-0: Error: Could not process rule: No such file or directory
error running container: did not get container start message from parent: EOF
Error: building at STEP "RUN apt-get update": setup network: netavark: nftables error: nft did not return successfully while applying ruleset
After some investigation, it's caused by the recent upload of netavark 1.14.0-2. In this version, netavark switched from iptables to nftables as the default firewall driver. That doesn't really fly on GitLab Saas shared runners. For the complete background, refer to https://discussion.fedoraproject.org/t/125528. Note that the issue with GitLab was reported back in November, but at this point the conversation had died out. Fortunately, it's easy to workaround, we can tell netavark to keep using iptables via the environment variables NETAVARK_FW. The .gitlab-ci.yml file above becomes:
build-container-image:
  stage: build
  image: debian:testing
  variables:
    # Cf. https://discussion.fedoraproject.org/t/125528/7
    NETAVARK_FW: iptables
  before_script:
    - apt-get update
    - apt-get install -y buildah ca-certificates
  script:
    - buildah build -t $CI_REGISTRY_IMAGE .
And everything works again! If you're interested in this issue, feel free to fork https://gitlab.com/arnaudr/gitlab-build-container-image and try it by yourself.

22 March 2025

Luke Faraone: I'm running for the OSI board... maybe

The Open Source Initiative has two classes of board seats: Affiliate seats, and Individual Member seats. In the upcoming election, each affiliate can nominate a candidate, and each affiliate can cast a vote for the Affiliate candidates, but there's only 1 Affiliate seat available. I initially expressed interest in being nominated as an Affiliate candidate via Debian. But since Bradley Kuhn is also running for an Affiliate seat with a similar platform to me, especially with regards to the OSAID, I decided to run as part of an aligned "ticket" as an Individual Member to avoid contention for the 1 Affiliate seat.Bradley and I discussed running on a similar ticket around 8/9pm Pacific, and I submitted my candidacy around 9pm PT on 17 February. I was dismayed when I received the following mail from Nick Vidal:
Dear Luke,

Thank you for your interest in the OSI Board of Directors election. Unfortunately, we are unable to accept your application as it was submitted after the official deadline of Monday Feb 17 at 11:59 pm UTC. To ensure a fair process, we must adhere to the deadline for all candidates.

We appreciate your enthusiasm and encourage you to stay engaged with OSI s mission. We hope you ll consider applying in the future or contributing in other meaningful ways.

Best regards,
OSI Election Teams
Nowhere on the "OSI s board of directors in 2025: details about the elections" page do they list a timezone for closure of nominations; they simply list Monday 17 February. The OSI's contact address is in California, so it seems arbitrary and capricious to retroactively define all of these processes as being governed by UTC.I was not able to participate in the "potential board director" info sessions accordingly, but people who attended heard that the importance of accommodating differing TZ's was discussed during the info session, and that OSI representatives mentioned they try to accommodate TZ's of everyone. This seems in sharp contrast with the above policy. I urge the OSI to reconsider this policy and allow me to stand for an Individual seat in the current cycle. Upd, N.B.: to people writing about this, I use they/them pronouns

Antoine Beaupr : Losing the war for the free internet

Warning: this is a long ramble I wrote after an outage of my home internet. You'll get your regular scheduled programming shortly. I didn't realize this until relatively recently, but we're at war. Fascists and capitalists are trying to take over the world, and it's bringing utter chaos. We're more numerous than them, of course: this is only a handful of people screwing everyone else over, but they've accumulated so much wealth and media control that it's getting really, really hard to move around. Everything is surveilled: people are carrying tracking and recording devices in their pockets at all time, or they drive around in surveillance machines. Payments are all turning digital. There's cameras everywhere, including in cars. Personal data leaks are so common people kind of assume their personal address, email address, and other personal information has already been leaked. The internet itself is collapsing: most people are using the network only as a channel to reach a "small" set of "hyperscalers": mind-boggingly large datacenters that don't really operate like the old internet. Once you reach the local endpoint, you're not on the internet anymore. Netflix, Google, Facebook (Instagram, Whatsapp, Messenger), Apple, Amazon, Microsoft (Outlook, Hotmail, etc), all those things are not really the internet anymore. Those companies operate over the "internet" (as in the TCP/IP network), but they are not an "interconnected network" as much as their own, gigantic silos so much bigger than everything else that they essentially dictate how the network operates, regardless of standards. You access it over "the web" (as in "HTTP") but the fabric is not made of interconnected links that cross sites: all those sites are trying really hard to keep you captive on their platforms. Besides, you think you're writing an email to the state department, for example, but you're really writing to Microsoft Outlook. That app your university or border agency tells you to install, the backend is not hosted by those institutions, it's on Amazon. Heck, even Netflix is on Amazon. Meanwhile I've been operating my own mail server first under my bed (yes, really) and then in a cupboard or the basement for almost three decades now. And what for? So I can tell people I can? Maybe! I guess the reason I'm doing this is the same reason people are suddenly asking me about the (dead) mesh again. People are worried and scared that the world has been taken over, and they're right: we have gotten seriously screwed. It's the same reason I keep doing radio, minimally know how to grow food, ride a bike, build a shed, paddle a canoe, archive and document things, talk with people, host an assembly. Because, when push comes to shove, there's no one else who's going to do it for you, at least not the way that benefits the people. The Internet is one of humanity's greatest accomplishments. Obviously, oligarchs and fascists are trying to destroy it. I just didn't expect the tech bros to be flipping to that side so easily. I thought we were friends, but I guess we are, after all, enemies. That said, that old internet is still around. It's getting harder to host your own stuff at home, but it's not impossible. Mail is tricky because of reputation, but it's also tricky in the cloud (don't get fooled!), so it's not that much easier (or cheaper) there. So there's things you can do, if you're into tech. Share your wifi with your neighbours. Build a LAN. Throw a wire over to your neighbour too, it works better than wireless. Use Tor. Run a relay, a snowflake, a webtunnel. Host a web server. Build a site with a static site generator and throw it in the wind. Download and share torrents, and why not a tracker. Run an IRC server (or Matrix, if you want to federate and lose high availability). At least use Signal, not Whatsapp or Messenger. And yes, why not, run a mail server, join a mesh. Don't write new software, there's plenty of that around already. (Just kidding, you can write code, cypherpunk.) You can do many of those things just by setting up a FreedomBox. That is, after all, the internet: people doing their own thing for their own people. Otherwise, it's just like sitting in front of the television and watching the ads. Opium of the people, like the good old time. Let a billion droplets build the biggest multitude of clouds that will storm over this world and rip apart this fascist conspiracy. Disobey. Revolt. Build. We are more than them.

21 March 2025

Jamie McClelland: AI's Actual Impact

Two years after OpenAI launched ChatGPT 3.5, humanity is not on the cusp of extinction and Elon Musk seems more responsible for job loss than any AI agent. However, ask any web administrator and you will learn that large language models are having a significant impact on the world wide web (or, for a less technical account, see Forbes articles on bots). At May First, a membership organization that has been supporting thousands of web site for over 20 years, we have never seen anything like this before.

Now what? So, no, unfortunately, your web site is not suddenly getting really popular. And, you are blessed with a whole new set of strategic decisions. Fortunately, May First has undergone a major infrastructure transition, resulting in centralized logging of all web sites and a fleet of web proxy servers that intercept all web traffic. Centralized logging means we can analyze traffic and identify bots more easily, and a web proxy fleet allows us to more easily implement rules across all web sites. However, even with all of our latest changes and hours upon hours of work to keep out the bots, our members are facing some hard decisions about maintaining an open web. One member of May First provides Google translations of their web site to every language available. But wow, that is now a disaster because instead of having every bot under the sun scrapping all 843 (a made up number) pieces of unique content on their site, the same bots are scraping 843 * (number of available languages) pieces of content on their site. Should they stop providing this translation service in order to ensure people can access their site in the site s primary language? Should web sites turn off their search features that include drop down options of categories to prevent bots from systematically refreshing the search page with every possible combination of search terms? Do we need to alter our calendar software to avoid providing endless links into the future (ok, that is an easy one)?

What s next? Something has to change.
  • Lock down web 2.0. Web 2.0 brought us wonderful dynamic web sites, which Drupal and WordPress and many other pieces of amazing software have supported for over a decade. This is the software that is getting bogged down by bots. Maybe we need to figure out a way to lock down the dynamic aspects of this software to logged in users and provide static content for everyone else?
  • Paywalls and accounts everywhere. There s always been an amazing non-financial reward to providing a web site with high quality movement oriented content for free. It populates the search engines, provides links to inspiring and useful content in moments of crises, and can galvanize movements. But these moments of triumph happen between long periods of hard labor that now seems to mostly feed capitalist AI scumbags. If we add a new set of expenses and labor to keep the sites running for this purpose, how sustainable is that? Will our treasure of free movement content have to move behind paywalls or logins? If we provide logins, will that keep the bots out or just create a small hurdle for them to automate the account creation process? What happens when we can t search for this kind of content via search engines?
  • Cutting deals. What if our movement content providers are forced to cut deals with the AI entrepreneurs to allow the paying scumbags to fund the content creation. Eww. Enough said.
  • Bot detection. Maybe we just need to get better at bot detection? This will surely be an arms race, but would have some good benefits. Bots have also been filling out our forms and populating our databases with spam, testing credit cards against our donation pages, conducting denial of service attacks and all kinds of other irritating acts of vandalism. If we were better at stopping bots automatically it would have a lot of benefits. But what impact would it have on our web sites and the experience of using them? What about good bots (RSS feed readers, payment processors, web hooks, uptime detectors)? Will we cut the legs off any developer trying to automate something?
I m not really sure where this is going, but it seems that the world wide web is about to head in a new direction.

19 March 2025

Mark Brown: Seoul Trail revamp

I regularly visit Seoul, and for the last couple of years I&aposve been doing segments from the Seoul Trail, a series of walks that add up to a 150km circuit around the outskirts of Seoul. If you like hiking I recommend it, it&aposs mostly through the hills and wooded areas surrounding the city or parks within the city and the bits I&aposve done thus far have mostly been very enjoyable. Everything is generally well signposted and easy to follow, with varying degrees of difficulty from completely flat paved roads to very hilly trails.The trail had been divided into eight segments but just after I last visited the trail was reorganised into 21 smaller ones. This was very sensible, the original segments mostly being about 10-20km and taking 3-6 hours (with the notable exception of section 8, which was 36km) which can be a bit much (especially that section 8, or section 1 which had about 1km of ascent in it overall). It does complicate matters if you&aposre trying to keep track of what you&aposve done already though so I&aposve put together a quick table:
OriginalRevised
11-3
24-5
36-8
49-10
511-12
613-14
715-16
817-21
This is all straightforward, the original segments had all been arranged to start and stop at metro stations (which I think explains the length of 8, the metro network is thin around Bukhansan what with it being an actual mountain) and the new segments are all straight subdivisions, but it&aposs handy to have it written down and I figured other people might find it useful.

17 March 2025

Sergio Talens-Oliag: Configuring forgejo actions

Last week I decided I wanted to try out forgejo actions to build this blog instead of using webhooks, so I looked the documentation and started playing with it until I had it working as I wanted. This post is to describe how I ve installed and configured a forgejo runner, how I ve added an oci organization to my instance to build, publish and mirror container images and added a couple of additional organizations (actions and docker for now) to mirror interesting actions. The changes made to build the site using actions will be documented on a separate post, as I ll be using this entry to test the new setup on the blog project.

Installing the runnerThe first thing I ve done is to install a runner on my server, I decided to use the OCI image installation method, as it seemed to be the easiest and fastest one. The commands I ve used to setup the runner are the following:
$ cd /srv
$ git clone https://forgejo.mixinet.net/blogops/forgejo-runner.git
$ cd forgejo-runner
$ sh ./bin/setup-runner.sh
The setup-runner.sh script does multiple things:
  • create a forgejo-runner user and group
  • create the necessary directories for the runner
  • create a .runner file with a predefined secret and the docker label
The setup-runner.sh code is available here. After running the script the runner has to be registered with the forgejo server, it can be done using the following command:
$ forgejo forgejo-cli actions register --name "$RUNNER_NAME" \
    --secret "$FORGEJO_SECRET"
The RUNNER_NAME variable is defined on the setup-runner.sh script and the FORGEJO_SECRET must match the value used on the .runner file.

Starting it with docker-composeTo launch the runner I m going to use a docker-compose.yml file that starts two containers, a docker in docker service to run the containers used by the workflow jobs and another one that runs the forgejo-runner itself. The initial version used a TCP port to communicate with the dockerd server from the runner, but when I tried to build images from a workflow I noticed that the containers launched by the runner were not going to be able to execute another dockerd inside the dind one and, even if they were, it was going to be expensive computationally. To avoid the issue I modified the dind service to use a unix socket on a shared volume that can be used by the runner service to communicate with the daemon and also re-shared with the job containers so the dockerd server can be used from them to build images.
Warning: The use of the same docker server that runs the jobs from them has security implications, but this instance is for a home server where I am the only user, so I am not worried about it and this way I can save some resources (in fact, I could use the host docker server directly instead of using a dind service, but just in case I want to run other containers on the host I prefer to keep the one used for the runner isolated from it). For those concerned about sharing the same server an alternative would be to launch a second dockerd only for the jobs (i.e. actions-dind) using the same approach (the volume with its socket will have to be shared with the runner service so it can be re-shared, but the runner does not need to use it).
The final docker-compose.yaml file is as follows:
services:
  dind:
    image: docker:dind
    container_name: 'dind'
    privileged: 'true'
    command: ['dockerd', '-H', 'unix:///dind/docker.sock', '-G', '$RUNNER_GID']
    restart: 'unless-stopped'
    volumes:
      - ./dind:/dind
  runner:
    image: 'data.forgejo.org/forgejo/runner:6.2.2'
    links:
      - dind
    depends_on:
      dind:
        condition: service_started
    container_name: 'runner'
    environment:
      DOCKER_HOST: 'unix:///dind/docker.sock'
    user: $RUNNER_UID:$RUNNER_GID
    volumes:
      - ./config.yaml:/config.yaml
      - ./data:/data
      - ./dind:/dind
    restart: 'unless-stopped'
    command: '/bin/sh -c "sleep 5; forgejo-runner daemon -c /config.yaml"'
There are multiple things to comment about this file:
  1. The dockerd server is started with the -H unix:///dind/docker.sock flag to use the unix socket to communicate with the daemon instead of using a TCP port (as said, it is faster and allows us to share the socket with the containers started by the runner).
  2. We are running the dockerd daemon with the RUNNER_GID group so the runner can communicate with it (the socket gets that group which is the same used by the runner).
  3. The runner container mounts three volumes: the data directory, the dind folder where docker creates the unix socket and a config.yaml file used by us to change the default runner configuration.
The config.yaml file was originally created using the forgejo-runner:
$ docker run --rm data.forgejo.org/forgejo/runner:6.2.2 \
    forgejo-runner generate-config > config.yaml
The changes to it are minimal, the runner capacity has been increased to 2 (that allows it to run two jobs at the same time) and the /dind/docker.sock value has been added to the valid_volumes key to allow the containers launched by the runner to mount it when needed; the diff against the default version is as follows:
@@ -13,7 +13,8 @@
   # Where to store the registration result.
   file: .runner
   # Execute how many tasks concurrently at the same time.
-  capacity: 1
+  # STO: Allow 2 concurrent tasks
+  capacity: 2
   # Extra environment variables to run jobs.
   envs:
     A_TEST_ENV_NAME_1: a_test_env_value_1
@@ -87,7 +88,9 @@
   # If you want to allow any volume, please use the following configuration:
   # valid_volumes:
   #   - '**'
-  valid_volumes: []
+  # STO: Allow to mount the /dind/docker.sock on the containers
+  valid_volumes:
+    - /dind/docker.sock
   # overrides the docker client host with the specified one.
   # If "-" or "", an available docker host will automatically be found.
   # If "automount", an available docker host will automatically be found and ...
To start the runner we export the RUNNER_UID and RUNNER_GID variables and call docker-compose up to start the containers on the background:
$ RUNNER_UID="$(id -u forgejo-runner)" RUNNER_GID="$(id -g forgejo-runner)" \
    docker compose up -d
If the server was configured right we are now able to start using actions with this runner.

Preparing the system to run things locallyTo avoid unnecessary network traffic we are going to create a multiple organizations in our forgejo instance to maintain our own actions and container images and mirror remote ones. The rationale behind the mirror use is that we reduce a lot the need to connect to remote servers to download the actions and images, which is good for performance and security reasons. In fact, we are going to build our own images for some things to install the tools we want without needing to do it over and over again on the workflow jobs.

Mirrored actionsThe actions we are mirroring are on the actions and docker organizations, we have created the following ones for now (the mirrors were created using the forgejo web interface and we have disabled manually all the forgejo modules except the code one for them):
To use our actions by default (i.e., without needing to add the server URL on the uses keyword) we have added the following section to the app.ini file of our forgejo server:
[actions]
ENABLED = true
DEFAULT_ACTIONS_URL = https://forgejo.mixinet.net

Setting up credentials to push imagesTo be able to push images to the oci organization I ve created a token with package:write permission for my own user because I m a member of the organization and I m authorized to publish packages on it (a different user could be created, but as I said this is for personal use, so there is no need to complicate things for now). To allow the use of those credentials on the actions I have added a secret (REGISTRY_PASS) and a variable (REGISTRY_USER) to the oci organization to allow the actions to use them. I ve also logged myself on my local docker client to be able to push images to the oci group by hand, as I it is needed for bootstrapping the system (as I m using local images on the worflows I need to push them to the server before running the ones that are used to build the images).

Local and mirrored imagesOur images will be stored on the packages section of a new organization called oci, inside it we have created two projects that use forgejo actions to keep things in shape:
  • images: contains the source files used to generate our own images and the actions to build, tag and push them to the oci organization group.
  • mirrors: contains a configuration file for the regsync tool to mirror containers and an action to run it.
On the next sections we are going to describe the actions and images we have created and mirrored from those projects.

The oci/images projectThe images project is a monorepo that contains the source files for the images we are going to build and a couple of actions. The image sources are on sub directories of the repository, to be considered an image the folder has to contain a Dockerfile that will be used to build the image. The repository has two workflows:
  • build-image-from-tag: Workflow to build, tag and push an image to the oci organization
  • multi-semantic-release: Workflow to create tags for the images using the multi-semantic-release tool.
As the workflows are already configured to use some of our images we pushed some of them from a checkout of the repository using the following commands:
registry="forgejo.mixinet.net/oci"
for img in alpine-mixinet node-mixinet multi-semantic-release; do
  docker build -t $registry/$img:1.0.0 $img
  docker tag $registry/$img:1.0.0 $registry/$img:latest
  docker push $registry/$img:1.0.0
  docker push $registry/$img:latest
done
On the next sub sections we will describe what the workflows do and will show their source code.

build-image-from-tag workflowThis workflow uses a docker client to build an image from a tag on the repository with the format image-name-v[0-9].[0-9].[0-9]+. As the runner is executed on a container (instead of using lxc) it seemed unreasonable to run another dind container from that one, that is why, after some tests, I decided to share the dind service server socket with the runner container and enabled the option to mount it also on the containers launched by the runner when needed (I only do it on the build-image-from-tag action for now). The action was configured to run using a trigger or when new tags with the right format were created, but when the tag is created by multi-semantic-release the trigger does not work for some reason, so now it only runs the job on triggers and checks if it is launched for a tag with the right format on the job itself. The source code of the action is as follows:
name: build-image-from-tag
on:
  workflow_dispatch:
jobs:
  build:
    # Don't build the image if the registry credentials are not set, the ref is not a tag or it doesn't contain '-v'
    if: $  vars.REGISTRY_USER != '' && secrets.REGISTRY_PASS != '' && startsWith(github.ref, 'refs/tags/') && contains(github.ref, '-v')  
    runs-on: docker
    container:
      image: forgejo.mixinet.net/oci/node-mixinet:latest
      # Mount the dind socket on the container at the default location
      options: -v /dind/docker.sock:/var/run/docker.sock
    steps:
      - name: Extract image name and tag from git and get registry name from env
        id: job_data
        run:  
          echo "::set-output name=img_name::$ GITHUB_REF_NAME%%-v* "
          echo "::set-output name=img_tag::$ GITHUB_REF_NAME##*-v "
          echo "::set-output name=registry::$(
            echo "$  github.server_url  "   sed -e 's%https://%%'
          )"
          echo "::set-output name=oci_registry_prefix::$(
            echo "$  github.server_url  /oci"   sed -e 's%https://%%'
          )"
      - name: Checkout the repo
        uses: actions/checkout@v4
      - name: Export build dir and Dockerfile
        id: build_data
        run:  
          img="$  steps.job_data.outputs.img_name  "
          build_dir="$(pwd)/$ img "
          dockerfile="$ build_dir /Dockerfile"
          if [ -f "$dockerfile" ]; then
            echo "::set-output name=build_dir::$build_dir"
            echo "::set-output name=dockerfile::$dockerfile"
          else
            echo "Couldn't find the Dockerfile for the '$img' image"
            exit 1
          fi
      - name: Login to the Container Registry
        uses: docker/login-action@v3
        with:
          registry: $  steps.job_data.outputs.registry  
          username: $  vars.REGISTRY_USER  
          password: $  secrets.REGISTRY_PASS  
      - name: Set up Docker Buildx
        uses: docker/setup-buildx-action@v3
      - name: Build and Push
        uses: docker/build-push-action@v6
        with:
          push: true
          tags:  
            $  steps.job_data.outputs.oci_registry_prefix  /$  steps.job_data.outputs.img_name  :$  steps.job_data.outputs.img_tag  
            $  steps.job_data.outputs.oci_registry_prefix  /$  steps.job_data.outputs.img_name  :latest
          context: $  steps.build_data.outputs.build_dir  
          file: $  steps.build_data.outputs.dockerfile  
          build-args:  
            OCI_REGISTRY_PREFIX=$  steps.job_data.outputs.oci_registry_prefix  /
Some notes about this code:
  1. The if condition of the build job is not perfect, but it is good enough to avoid wrong uses as long as nobody uses manual tags with the wrong format and expects things to work (it checks if the REGISTRY_USER and REGISTRY_PASS variables are set, if the ref is a tag and if it contains the -v string).
  2. To be able to access the dind socket we mount it on the container using the options key on the container section of the job (this only works if supported by the runner configuration as explained before).
  3. We use the job_data step to get information about the image from the tag and the registry URL from the environment variables, it is executed first because all the information is available without checking out the repository.
  4. We use the job_data step to get the build dir and Dockerfile paths from the repository (right now we are assuming fixed paths and checking if the Dockerfile exists, but in the future we could use a configuration file to get them, if needed).
  5. As we are using a docker daemon that is already running there is no need to use the docker/setup-docker-action to install it.
  6. On the build and push step we pass the OCI_REGISTRY_PREFIX build argument to the Dockerfile to be able to use it on the FROM instruction (we are using it in our images).

multi-semantic-release workflowThis workflow is used to run the multi-semantic-release tool on pushes to the main branch. It is configured to create the configuration files on the fly (it prepares things to tag the folders that contain a Dockerfile using a couple of template files available on the repository s .forgejo directory) and run the multi-semantic-release tool to create tags and push them to the repository if new versions are to be built. Initially we assumed that the tag creation pushed by multi-semantic-release would be enough to run the build-tagged-image-task action, but as it didn t work we removed the rule to run the action on tag creation and added code to trigger the action using an api call for the newly created tags (we get them from the output of the multi-semantic-release execution). The source code of the action is as follows:
name: multi-semantic-release
on:
  push:
    branches:
      - 'main'
jobs:
  multi-semantic-release:
    runs-on: docker
    container:
      image: forgejo.mixinet.net/oci/multi-semantic-release:latest
    steps:
      - name: Checkout the repo
        uses: actions/checkout@v4
      - name: Generate multi-semantic-release configuration
        shell: sh
        run:  
          # Get the list of images to work with (the folders that have a Dockerfile)
          images="$(for img in */Dockerfile; do dirname "$img"; done)"
          # Generate a values.yaml file for the main packages.json file
          package_json_values_yaml=".package.json-values.yaml"
          echo "images:" >"$package_json_values_yaml"
          for img in $images; do
            echo " - $img" >>"$package_json_values_yaml"
          done
          echo "::group::Generated values.yaml for the project"
          cat "$package_json_values_yaml"
          echo "::endgroup::"
          # Generate the package.json file validating that is a good json file with jq
          tmpl -f "$package_json_values_yaml" ".forgejo/package.json.tmpl"   jq . > "package.json"
          echo "::group::Generated package.json for the project"
          cat "package.json"
          echo "::endgroup::"
          # Remove the temporary values file
          rm -f "$package_json_values_yaml"
          # Generate the package.json file for each image
          for img in $images; do
            tmpl -v "img_name=$img" -v "img_path=$img" ".forgejo/ws-package.json.tmpl"   jq . > "$img/package.json"
            echo "::group::Generated package.json for the '$img' image"
            cat "$img/package.json"
            echo "::endgroup::"
          done
      - name: Run multi-semantic-release
        shell: sh
        run:  
          multi-semantic-release   tee .multi-semantic-release.log
      - name: Trigger builds
        shell: sh
        run:  
          # Get the list of tags published on the previous steps
          tags="$(
            sed -n -e 's/^\[.*\] \[\(.*\)\] .* Published release \([0-9]\+\.[0-9]\+\.[0-9]\+\) on .*$/\1-v\2/p' \
              .multi-semantic-release.log
          )"
          rm -f .multi-semantic-release.log
          if [ "$tags" ]; then
            # Prepare the url for building the images
            workflow="build-image-from-tag.yaml"
            dispatch_url="$  github.api_url  /repos/$  github.repository  /actions/workflows/$workflow/dispatches"
            echo "$tags"   while read -r tag; do
              echo "Triggering build for tag '$tag'"
              curl \
                -H "Content-Type:application/json" \
                -H "Authorization: token $  secrets.GITHUB_TOKEN  " \
                -d " \"ref\":\"$tag\" " "$dispatch_url"
            done
          fi
Notes about this code:
  1. The use of the tmpl tool to process the multi-semantic-release configuration templates comes from previous uses, but on this case we could use a different approach (i.e. envsubst could be used) but we left it because it keeps things simple and can be useful in the future if we want to do more complex things with the template files.
  2. We use tee to show and dump to a file the output of the multi-semantic-release execution.
  3. We get the list of pushed tags using sed against the output of the multi-semantic-release execution and for each one found we use curl to call the forgejo API to trigger the build job; as the call is against the same project we can use the GITHUB_TOKEN generated for the workflow to do it, without creating a user token that has to be shared as a secret.
The .forgejo/package.json.tmpl file is the following one:
 
  "name": "multi-semantic-release",
  "version": "0.0.0-semantically-released",
  "private": true,
  "multi-release":  
    "tagFormat": "$ name -v$ version "
   ,
  "workspaces":   .images   toJson  
 
As can be seen it only needs a list of paths to the images as argument (the file we generate contains the names and paths, but it could be simplified). And the .forgejo/ws-package.json.tmpl file is the following one:
 
  "name": "  .img_name  ",
  "license": "UNLICENSED",
  "release":  
    "plugins": [
      [
        "@semantic-release/commit-analyzer",
         
          "preset": "conventionalcommits",
          "releaseRules": [
              "breaking": true, "release": "major"  ,
              "revert": true, "release": "patch"  ,
              "type": "feat", "release": "minor"  ,
              "type": "fix", "release": "patch"  ,
              "type": "perf", "release": "patch"  
          ]
         
      ],
      [
        "semantic-release-replace-plugin",
         
          "replacements": [
             
              "files": [ "  .img_path  /msr.yaml" ],
              "from": "^version:.*$",
              "to": "version: $ nextRelease.version ",
              "allowEmptyPaths": true
             
          ]
         
      ],
      [
        "@semantic-release/git",
         
          "assets": [ "msr.yaml" ],
          "message": "ci(release):   .img_name  -v$ nextRelease.version \n\n$ nextRelease.notes "
         
      ]
    ],
    "branches": [ "main" ]


The oci/mirrors projectThe repository contains a template for the configuration file we are going to use with regsync (regsync.envsubst.yml) to mirror images from remote registries using a workflow that generates a configuration file from the template and runs the tool. The initial version of the regsync.envsubst.yml file is prepared to mirror alpine containers from version 3.21 to 3.29 (we explicitly remove version 3.20) and needs the forgejo.mixinet.net/oci/node-mixinet:latest image to run (as explained before it was pushed manually to the server):
version: 1
creds:
  - registry: "$REGISTRY"
    user: "$REGISTRY_USER"
    pass: "$REGISTRY_PASS"
sync:
  - source: alpine
    target: $REGISTRY/oci/alpine
    type: repository
    tags:
      allow:
        - "latest"
        - "3\\.2\\d+"
        - "3\\.2\\d+.\\d+"
      deny:
        - "3\\.20"
        - "3\\.20.\\d+"

mirror workflowThe mirror workflow creates a configuration file replacing the value of the REGISTRY environment variable (computed by removing the protocol from the server_url), the REGISTRY_USER organization value and the REGISTRY_PASS secret using the envsubst command and running the regsync tool to mirror the images using the configuration file. The action is configured to run daily, on push events when the regsync.envsubst.yml file is modified on the main branch and can also be triggered manually. The source code of the action is as follows:
.forgejo/workflows/mirror.yaml
name: mirror
on:
  schedule:
    - cron: '@daily'
  push:
    branches:
      - main
    paths:
      - 'regsync.envsubst.yml'
  workflow_dispatch:
jobs:
  mirror:
    if: $  vars.REGISTRY_USER != '' && secrets.REGISTRY_PASS != ''  
    runs-on: docker
    container:
      image: forgejo.mixinet.net/oci/node-mixinet:latest
    steps:
      - name: Checkout
        uses: actions/checkout@v4
      - name: Sync images
        run:  
          REGISTRY="$(echo "$  github.server_url  "   sed -e 's%https://%%')" \
          REGISTRY_USER="$  vars.REGISTRY_USER  " \
          REGISTRY_PASS="$  secrets.REGISTRY_PASS  " \
            envsubst <regsync.envsubst.yml >.regsync.yml
          regsync --config .regsync.yml once
          rm -f .regsync.yml

ConclusionWe have installed a forgejo-runner and configured it to run actions for our own server and things are working fine. This approach allows us to have a powerful CI/CD system on a modest home server, something very useful for maintaining personal projects and playing with things without needing SaaS platforms like github or gitlab.

James Valleroy: What s New for FreedomBox in Debian 13 trixie

FreedomBox is a Debian blend that makes it easier to run your own server. Approximately every two years, there is a new stable release of Debian. This year s release will be called Debian 13 "trixie". This post will provide an overview of changes between FreedomBox 23.6 (the version that shipped in Debian 12 "bookworm") and 25.5 (the latest release). Note: Debian 13 "trixie" is not yet released, so things may still change, be added or removed, before the official release. General Diagnostics Name Services Networks Privacy Users and Groups Deluge Ejabberd Feather Wiki GitWeb GNOME ikiwiki Kiwix Matrix Synapse MediaWiki MiniDLNA Miniflux Nextcloud OpenVPN Postfix/Dovecot Shadowsocks Server SOGo TiddlyWiki Tor Proxy Transmission Conclusion Over the past two years, FreedomBox has been increasing the number of features and applications available to its users. We have also focused on improving the reliability of the system, detecting unexpected situations, and providing means to return to a known good state. With these improvements, FreedomBox has become a good solution for people with limited time or energy to set up and start running a personal server, at home or in the cloud. Looking forward, we would like to focus on making more powerful hardware available with FreedomBox pre-installed and ready to be used. This hardware would also support larger storage devices, making it suitable as a NAS or media server. We are also very interested in exploring new features such as atomic updates, which will further enhance the reliability of the system.

16 March 2025

Russell Coker: Article Recommendations via FOSS

Google tracking everything we read is bad, particularly since Google abandoned the don t be evil plan and are presumably open to being somewhat evil. The article recommendations on Chrome on Android are useful and I d like to be able to get the same quality of recommendations without Google knowing about everything I read. Ideally without anything other than the device I use knowing what interests me. A ML system to map between sources of news that are of interest should be easy to develop and run on end user devices. The model could be published and when given inputs of articles you like give an output of sites that contain other articles you like. Then an agent on the end user system could spider the sites in question and run a local model to determine which articles to present to the user. Mapping for hate following is possible for such a system (Google doesn t do that), the user could have 2 separate model runs for regular reading and hate-following and determine how much of each content to recommend. It could also give negative weight to entries that match the hate criteria. Some sites with articles (like Medium) give an estimate of reading time. An article recommendation system should have a fixed limit of articles (both in articles and in reading time) to support the I spend half an hour reading during lunch model not doom scrolling. For getting news using only FOSS it seems that the best option at the moment is to use the Lemmy FOSS social network which is like Reddit [1] to recommend articles etc. The Lemoa client for Lemmy uses GTK [2] but it s no longer maintained. The Lemonade client for Lemmy is written in Rust [3]. It would be good if one of those was packaged for Debian, preferably one that s maintained.

14 March 2025

Ravi Dwivedi: Libreoffice Conference 2024 in Luxembourg

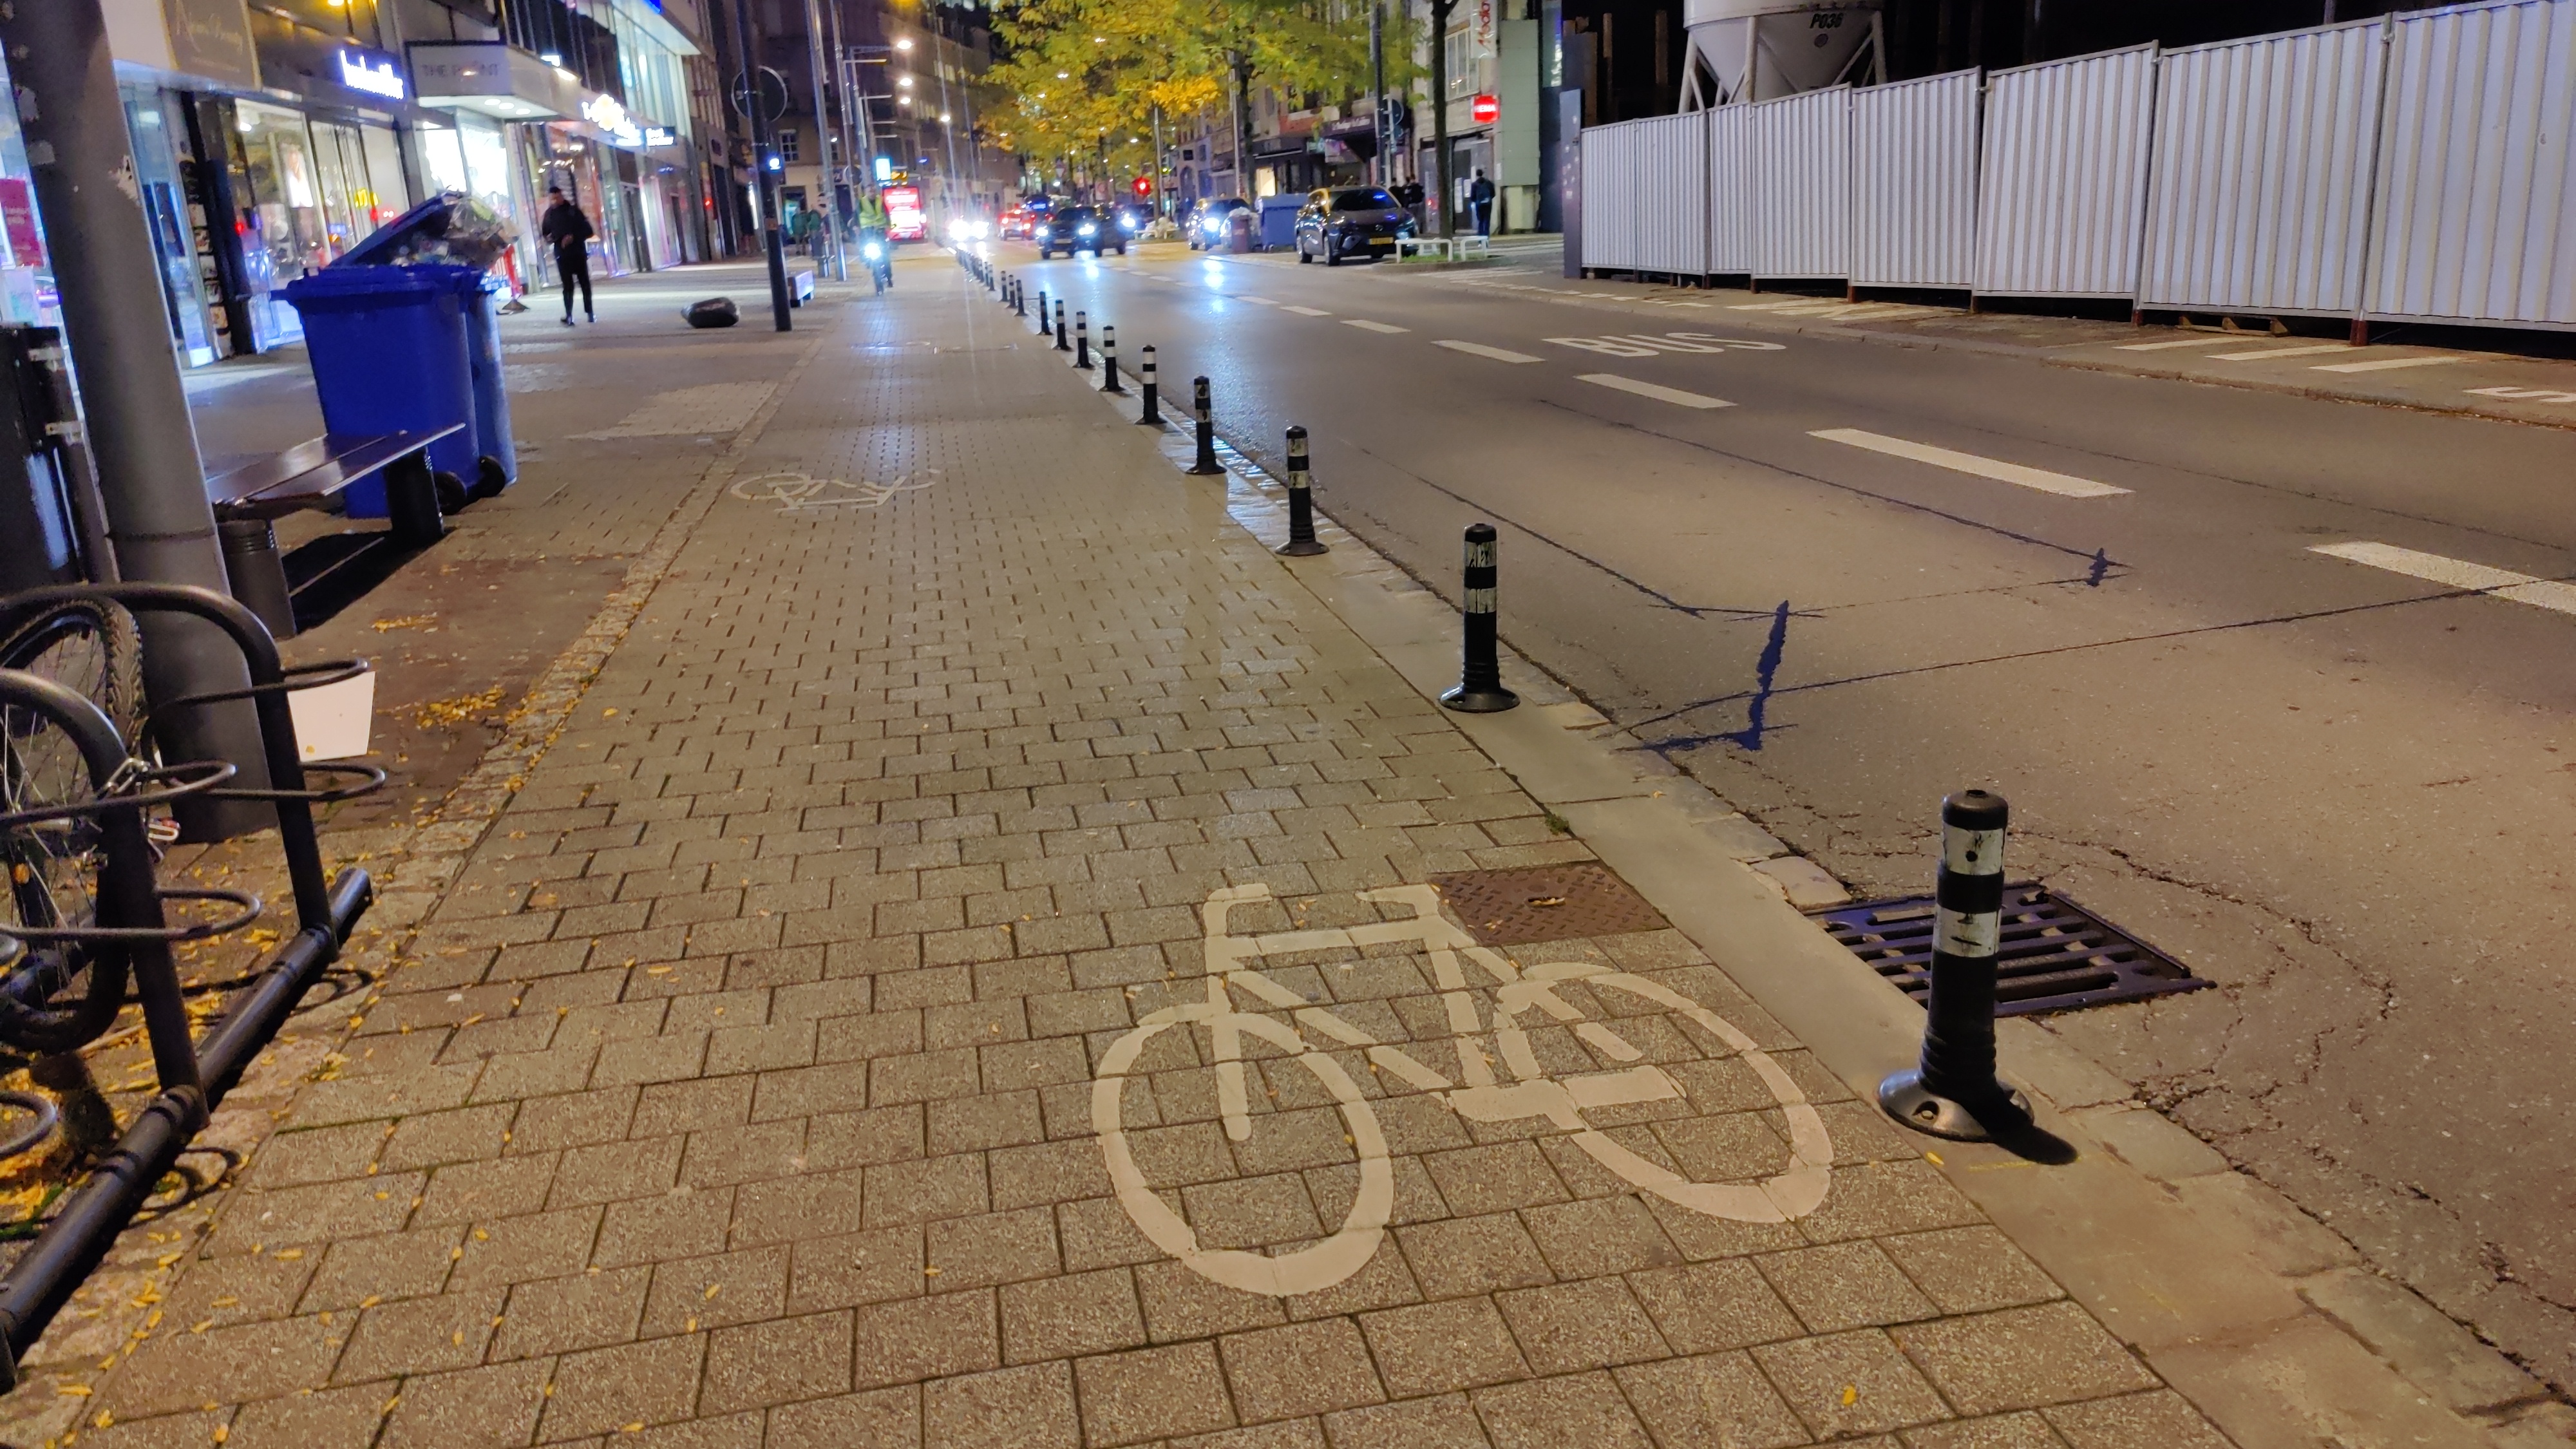
Last year, I attended the annual LibreOffice Conference in Luxembourg with the help of a generous travel grant by The Document Foundation (TDF). It was a three-day event from the 10th to the 12th of October 2024, with an additional day for community meetup on the 9th. Luxembourg is a small (twice as big as Delhi) country in Western Europe. After going through an arduous visa process, I reached Luxembourg on the 8th of October. Upon arriving in Luxembourg, I took a bus to the city center, where my hotel Park Inn was located. All the public transport in Luxembourg was free of cost. It was as if I stepped in another world. There were separate tracks for cycling and a separate lane for buses, along with good pedestrian infrastructure. In addition, the streets were pretty neat and clean.
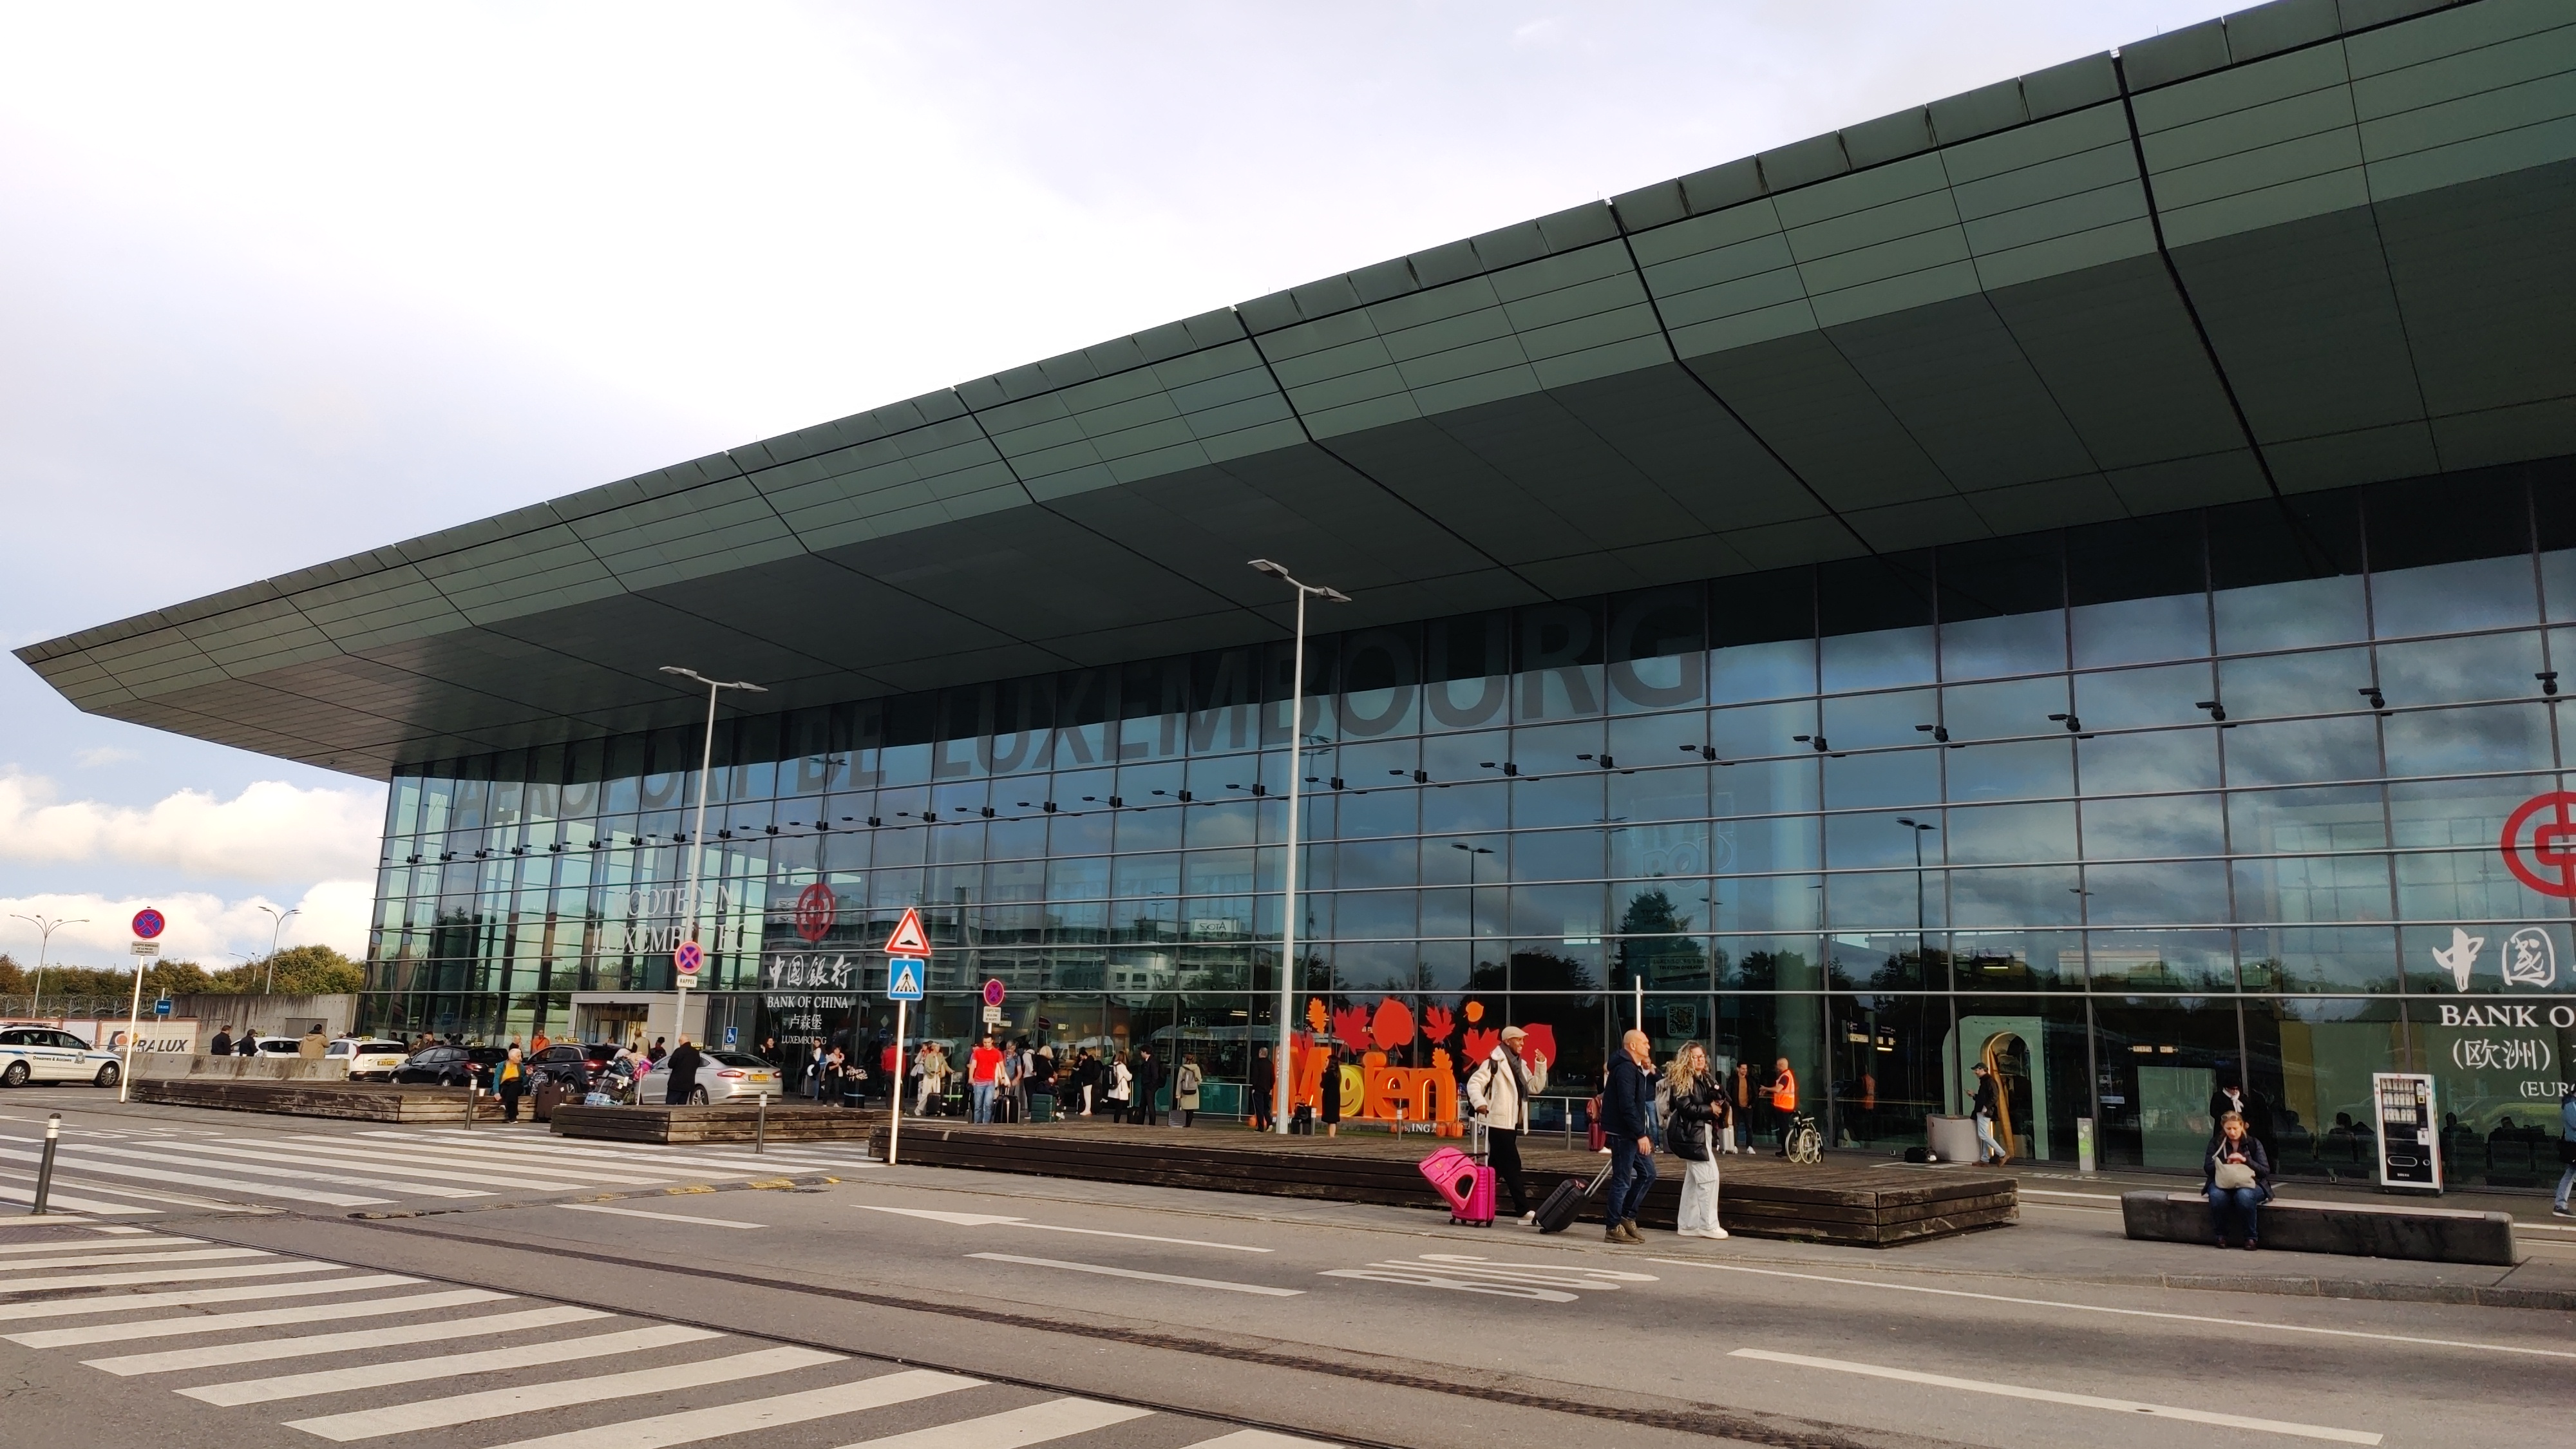
Luxembourg's Findel Airport
Separate cycling tracks in Luxembourg
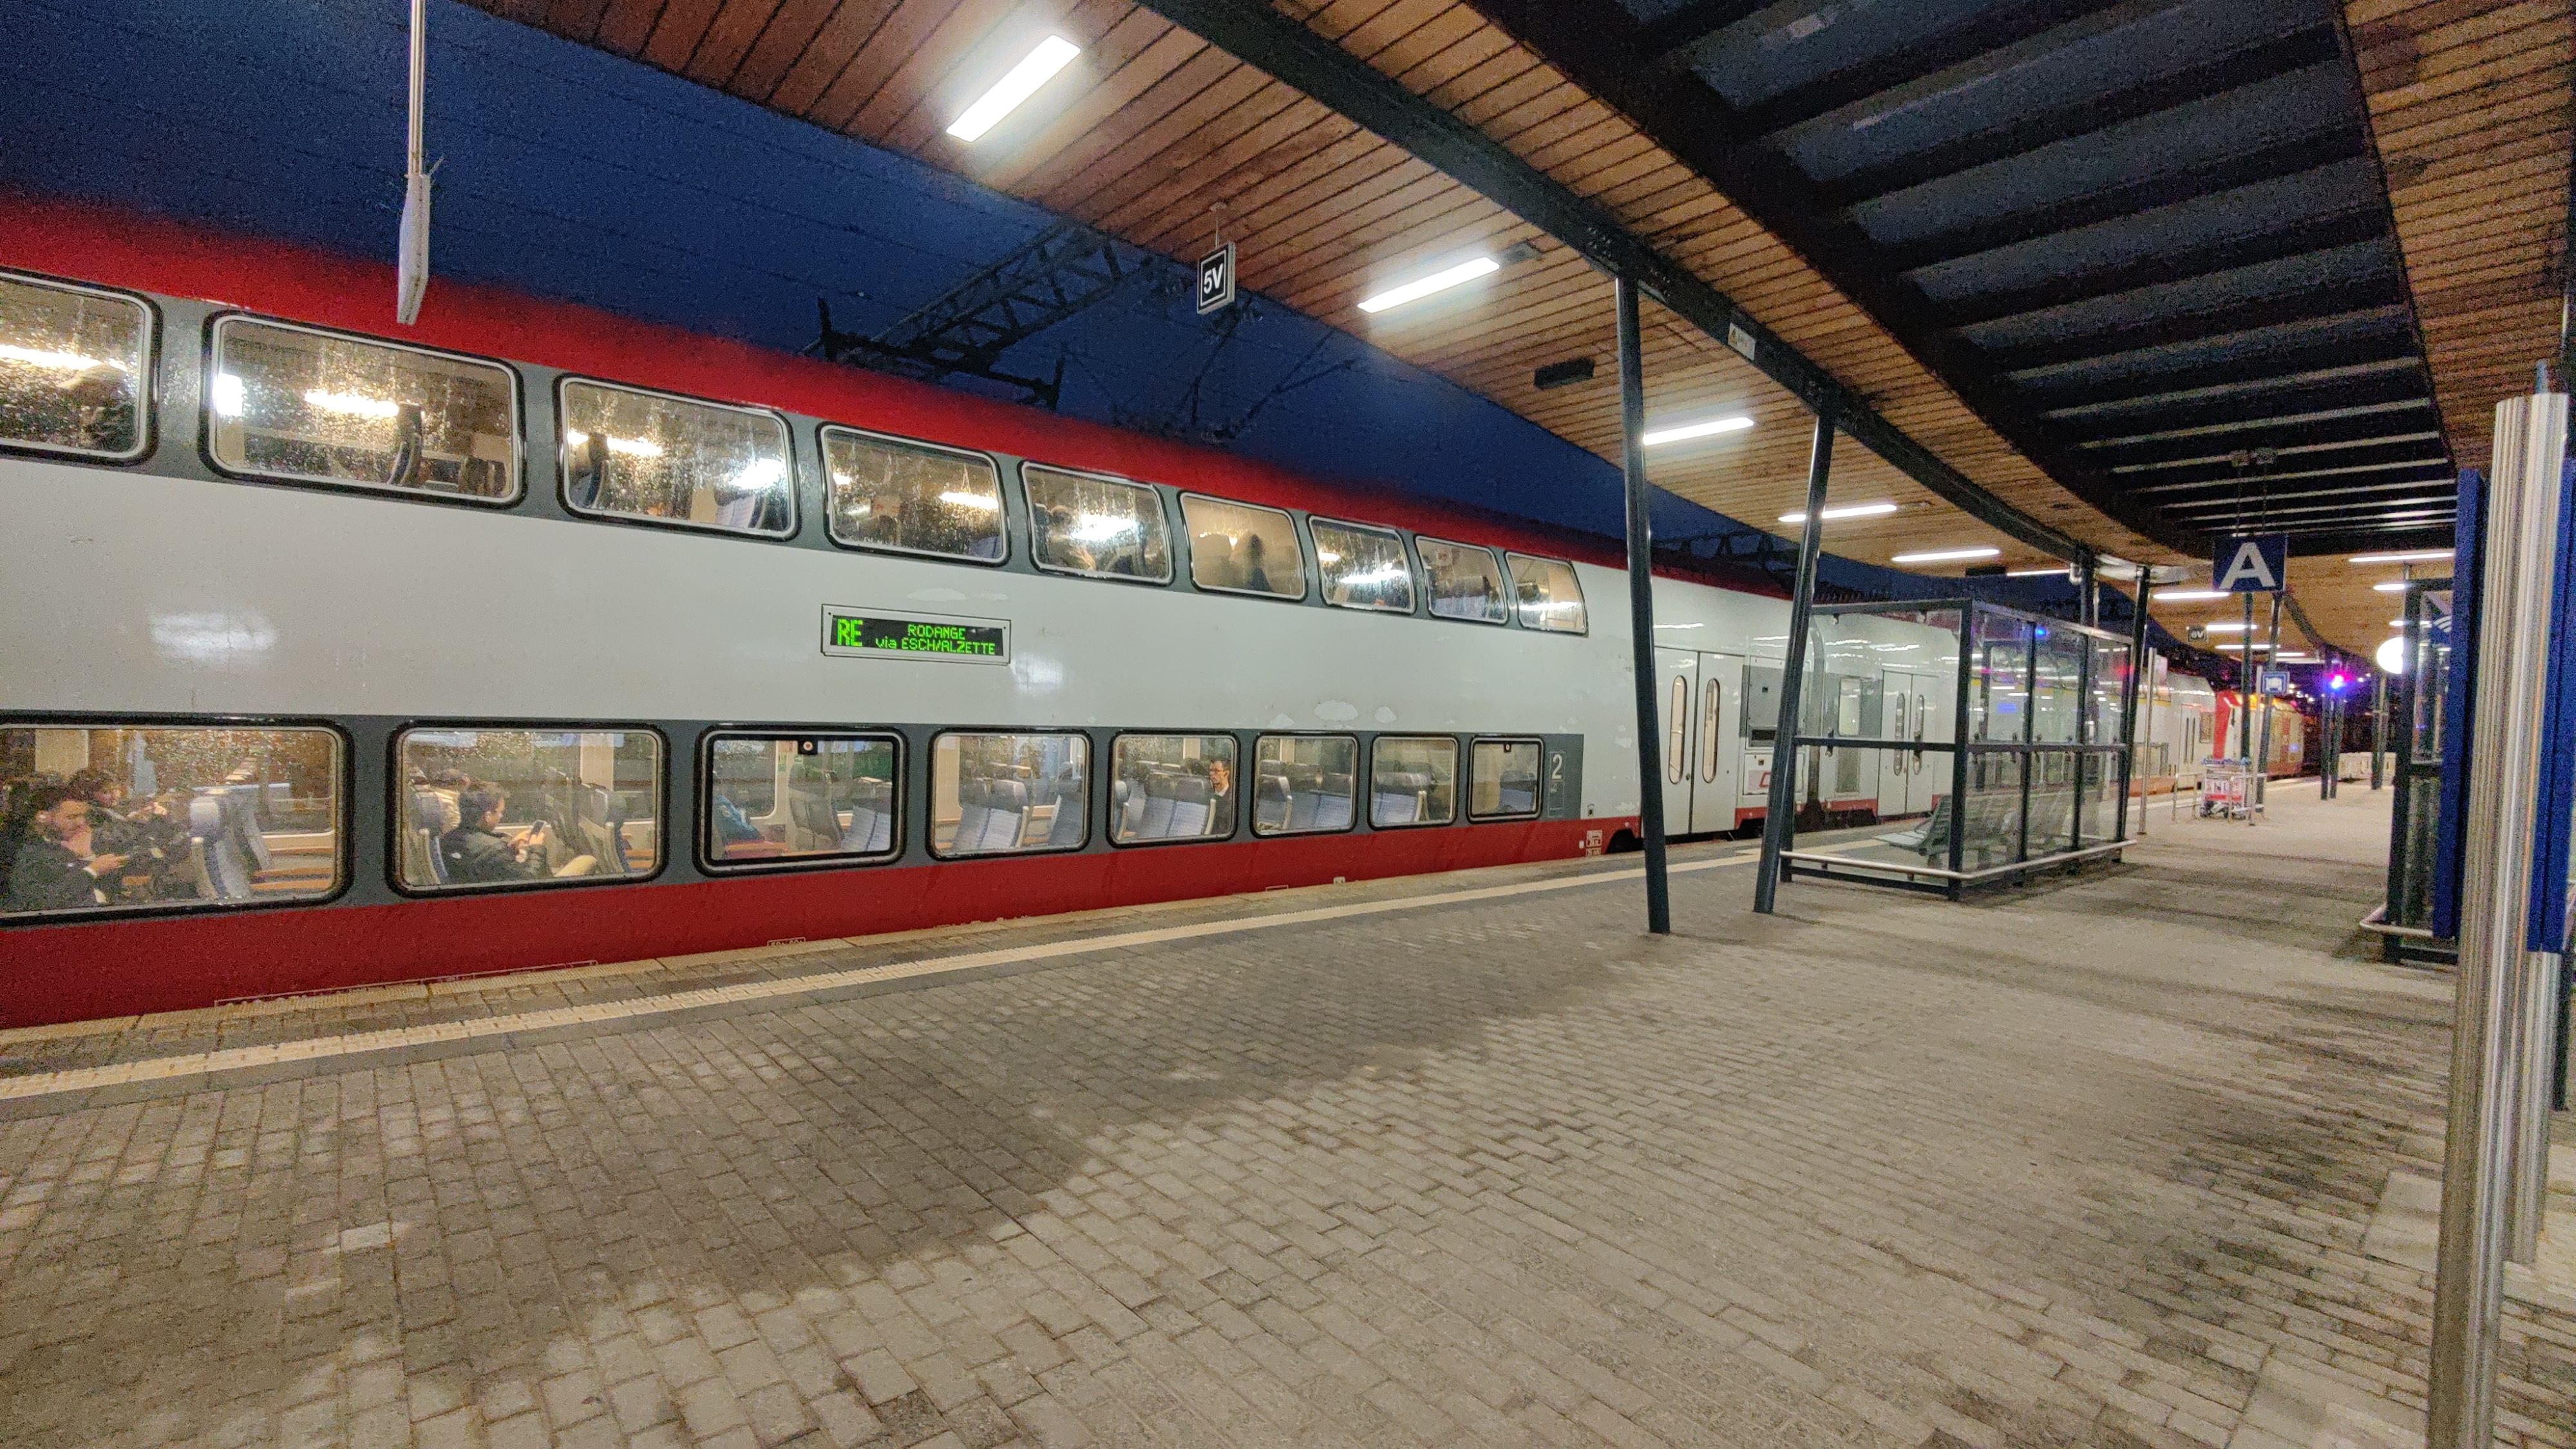
My hotel was 20 km from the conference venue in Belval. However, the commute was convenient due to a free of cost train connection, which were comfortable, smooth, and scenic, covering the distance in half an hour. The hotel included a breakfast buffet, recharging us before the conference.
This is what trains look like in Luxembourg
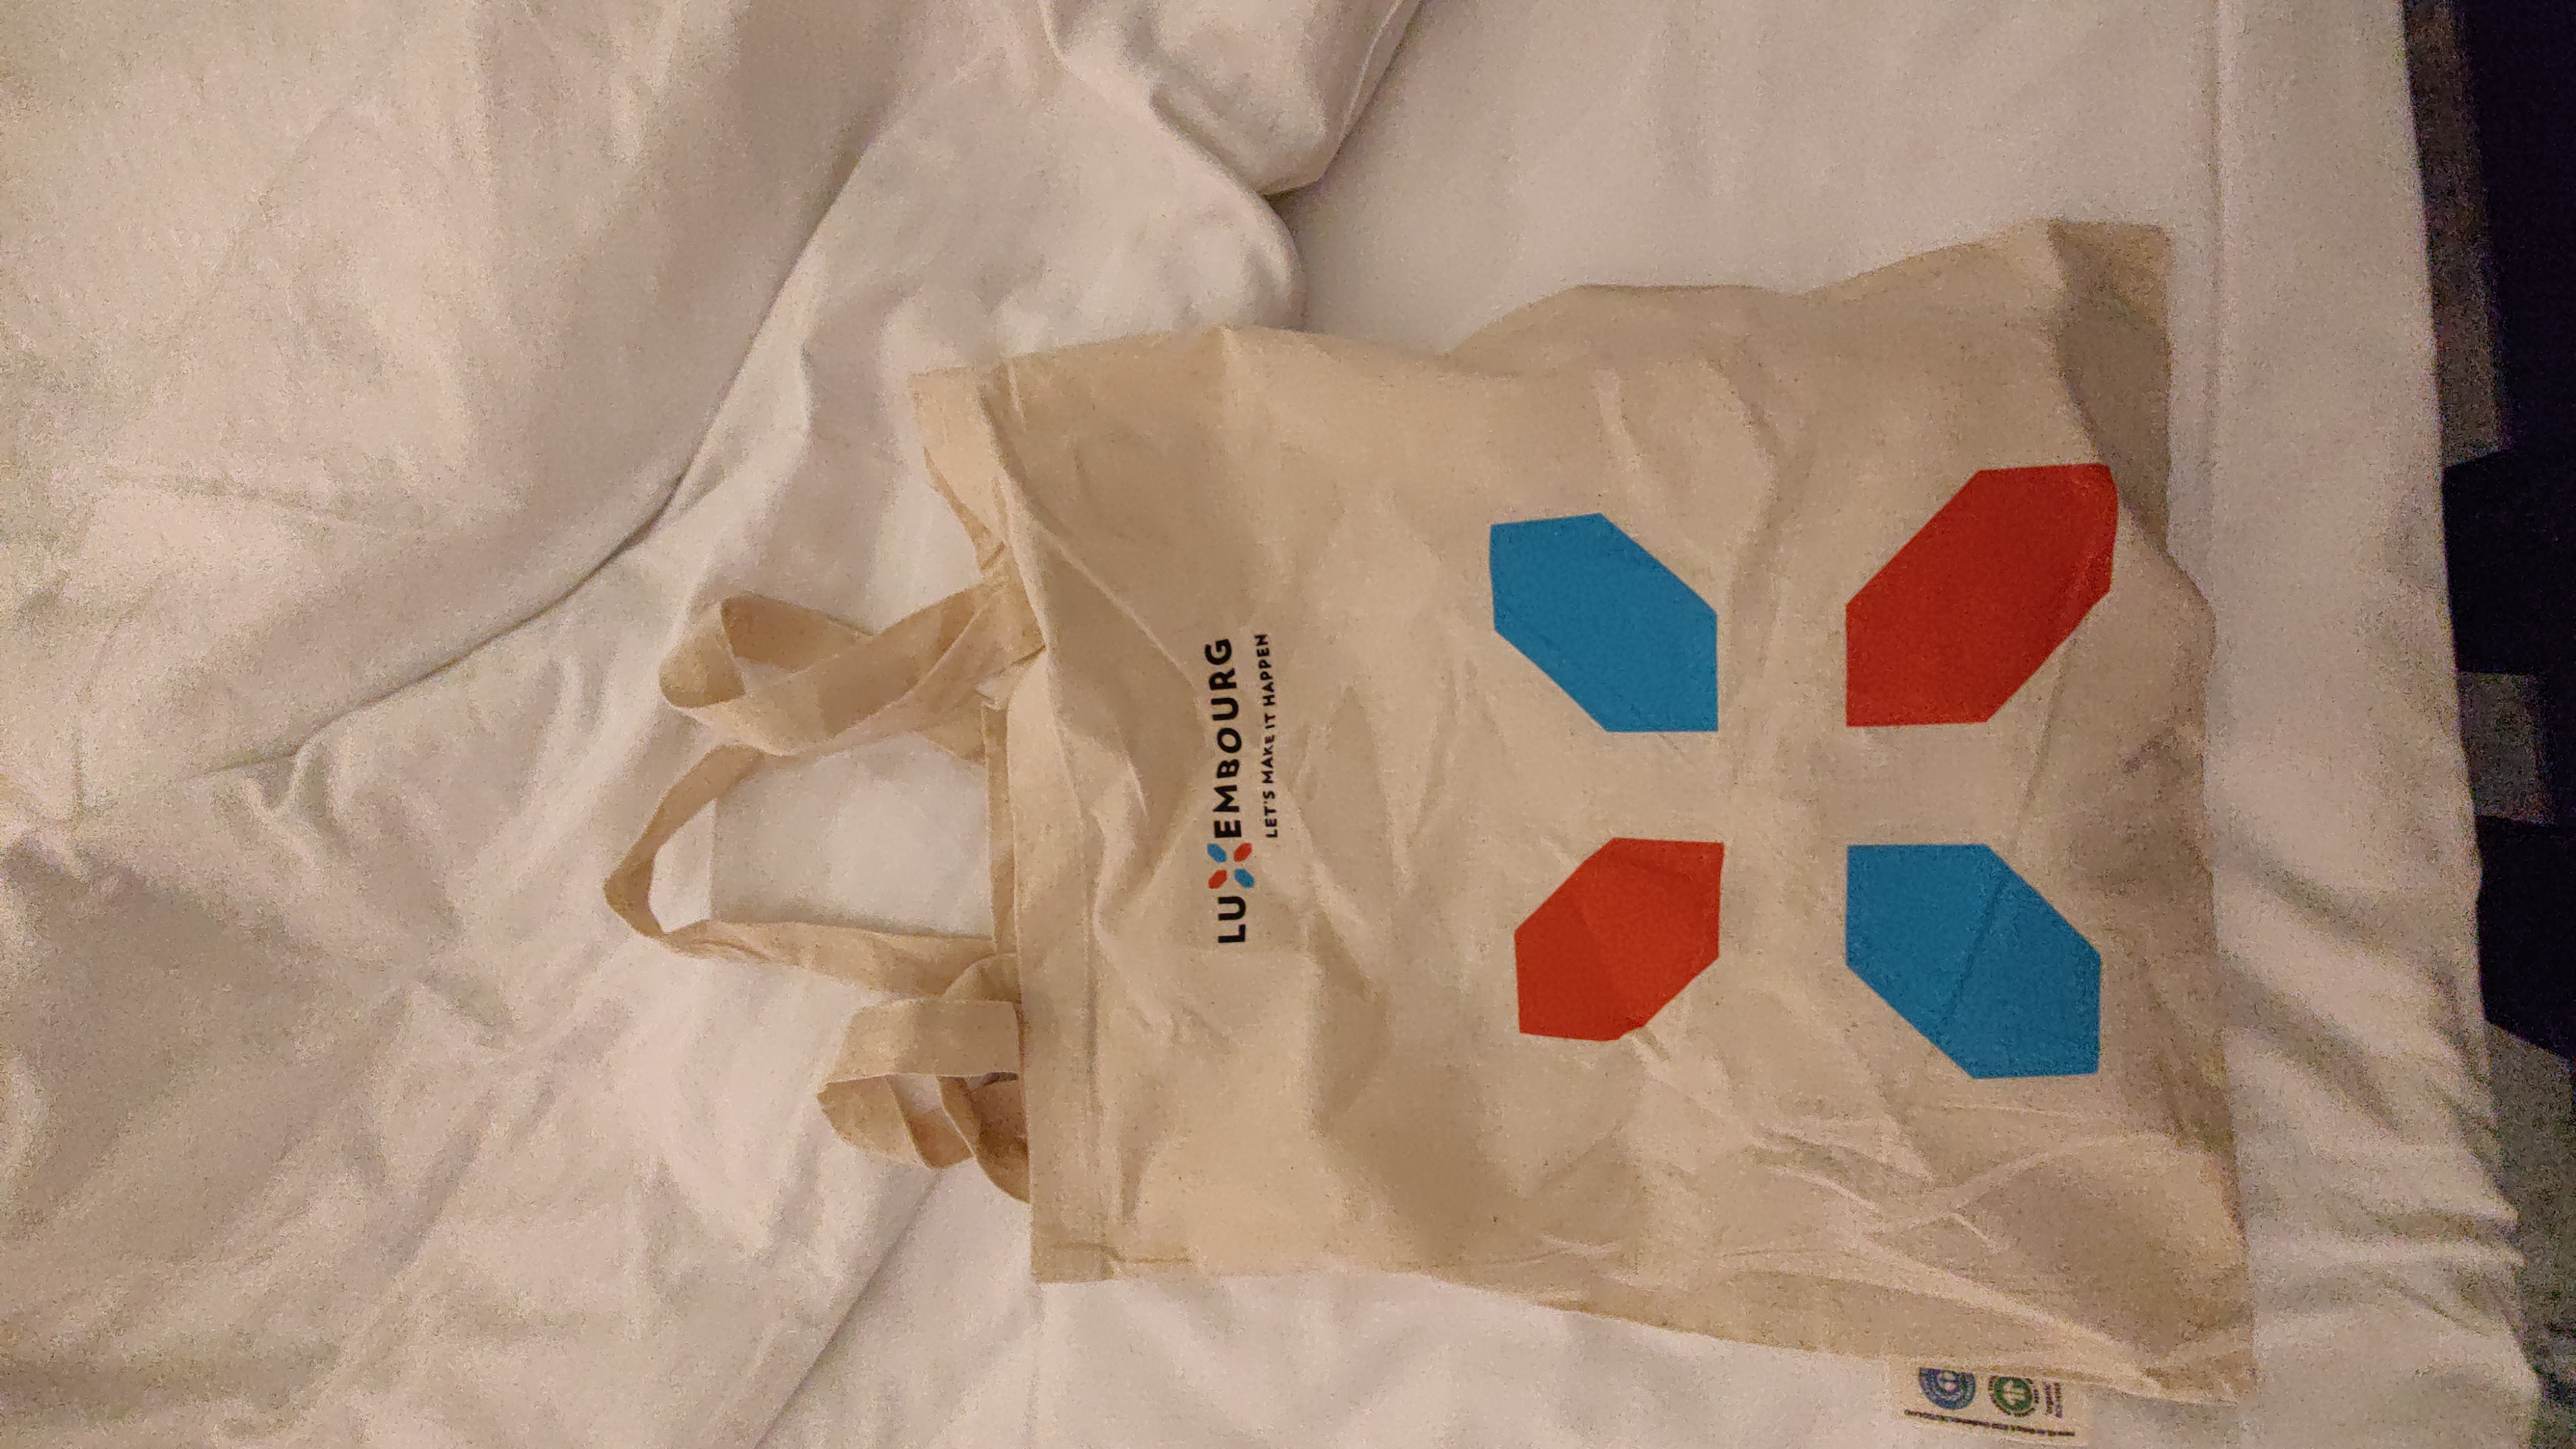
Pre-conference, a day was reserved for the community meetup on the 9th of October. On that day, the community members introduced themselves and their contributions to the LibreOffice project. It acted as a brainstorming session. I got a lovely conference bag, which contained a T-Shirt, a pen and a few stickers. I also met my long time collaborators Mike, Sophie and Italo from the TDF, whom I had interacted only remotely till then. Likewise, I also met TDF s sysadmin Guilhem, who I interacted before regarding setting up my LibreOffice mirror.
Conference bag
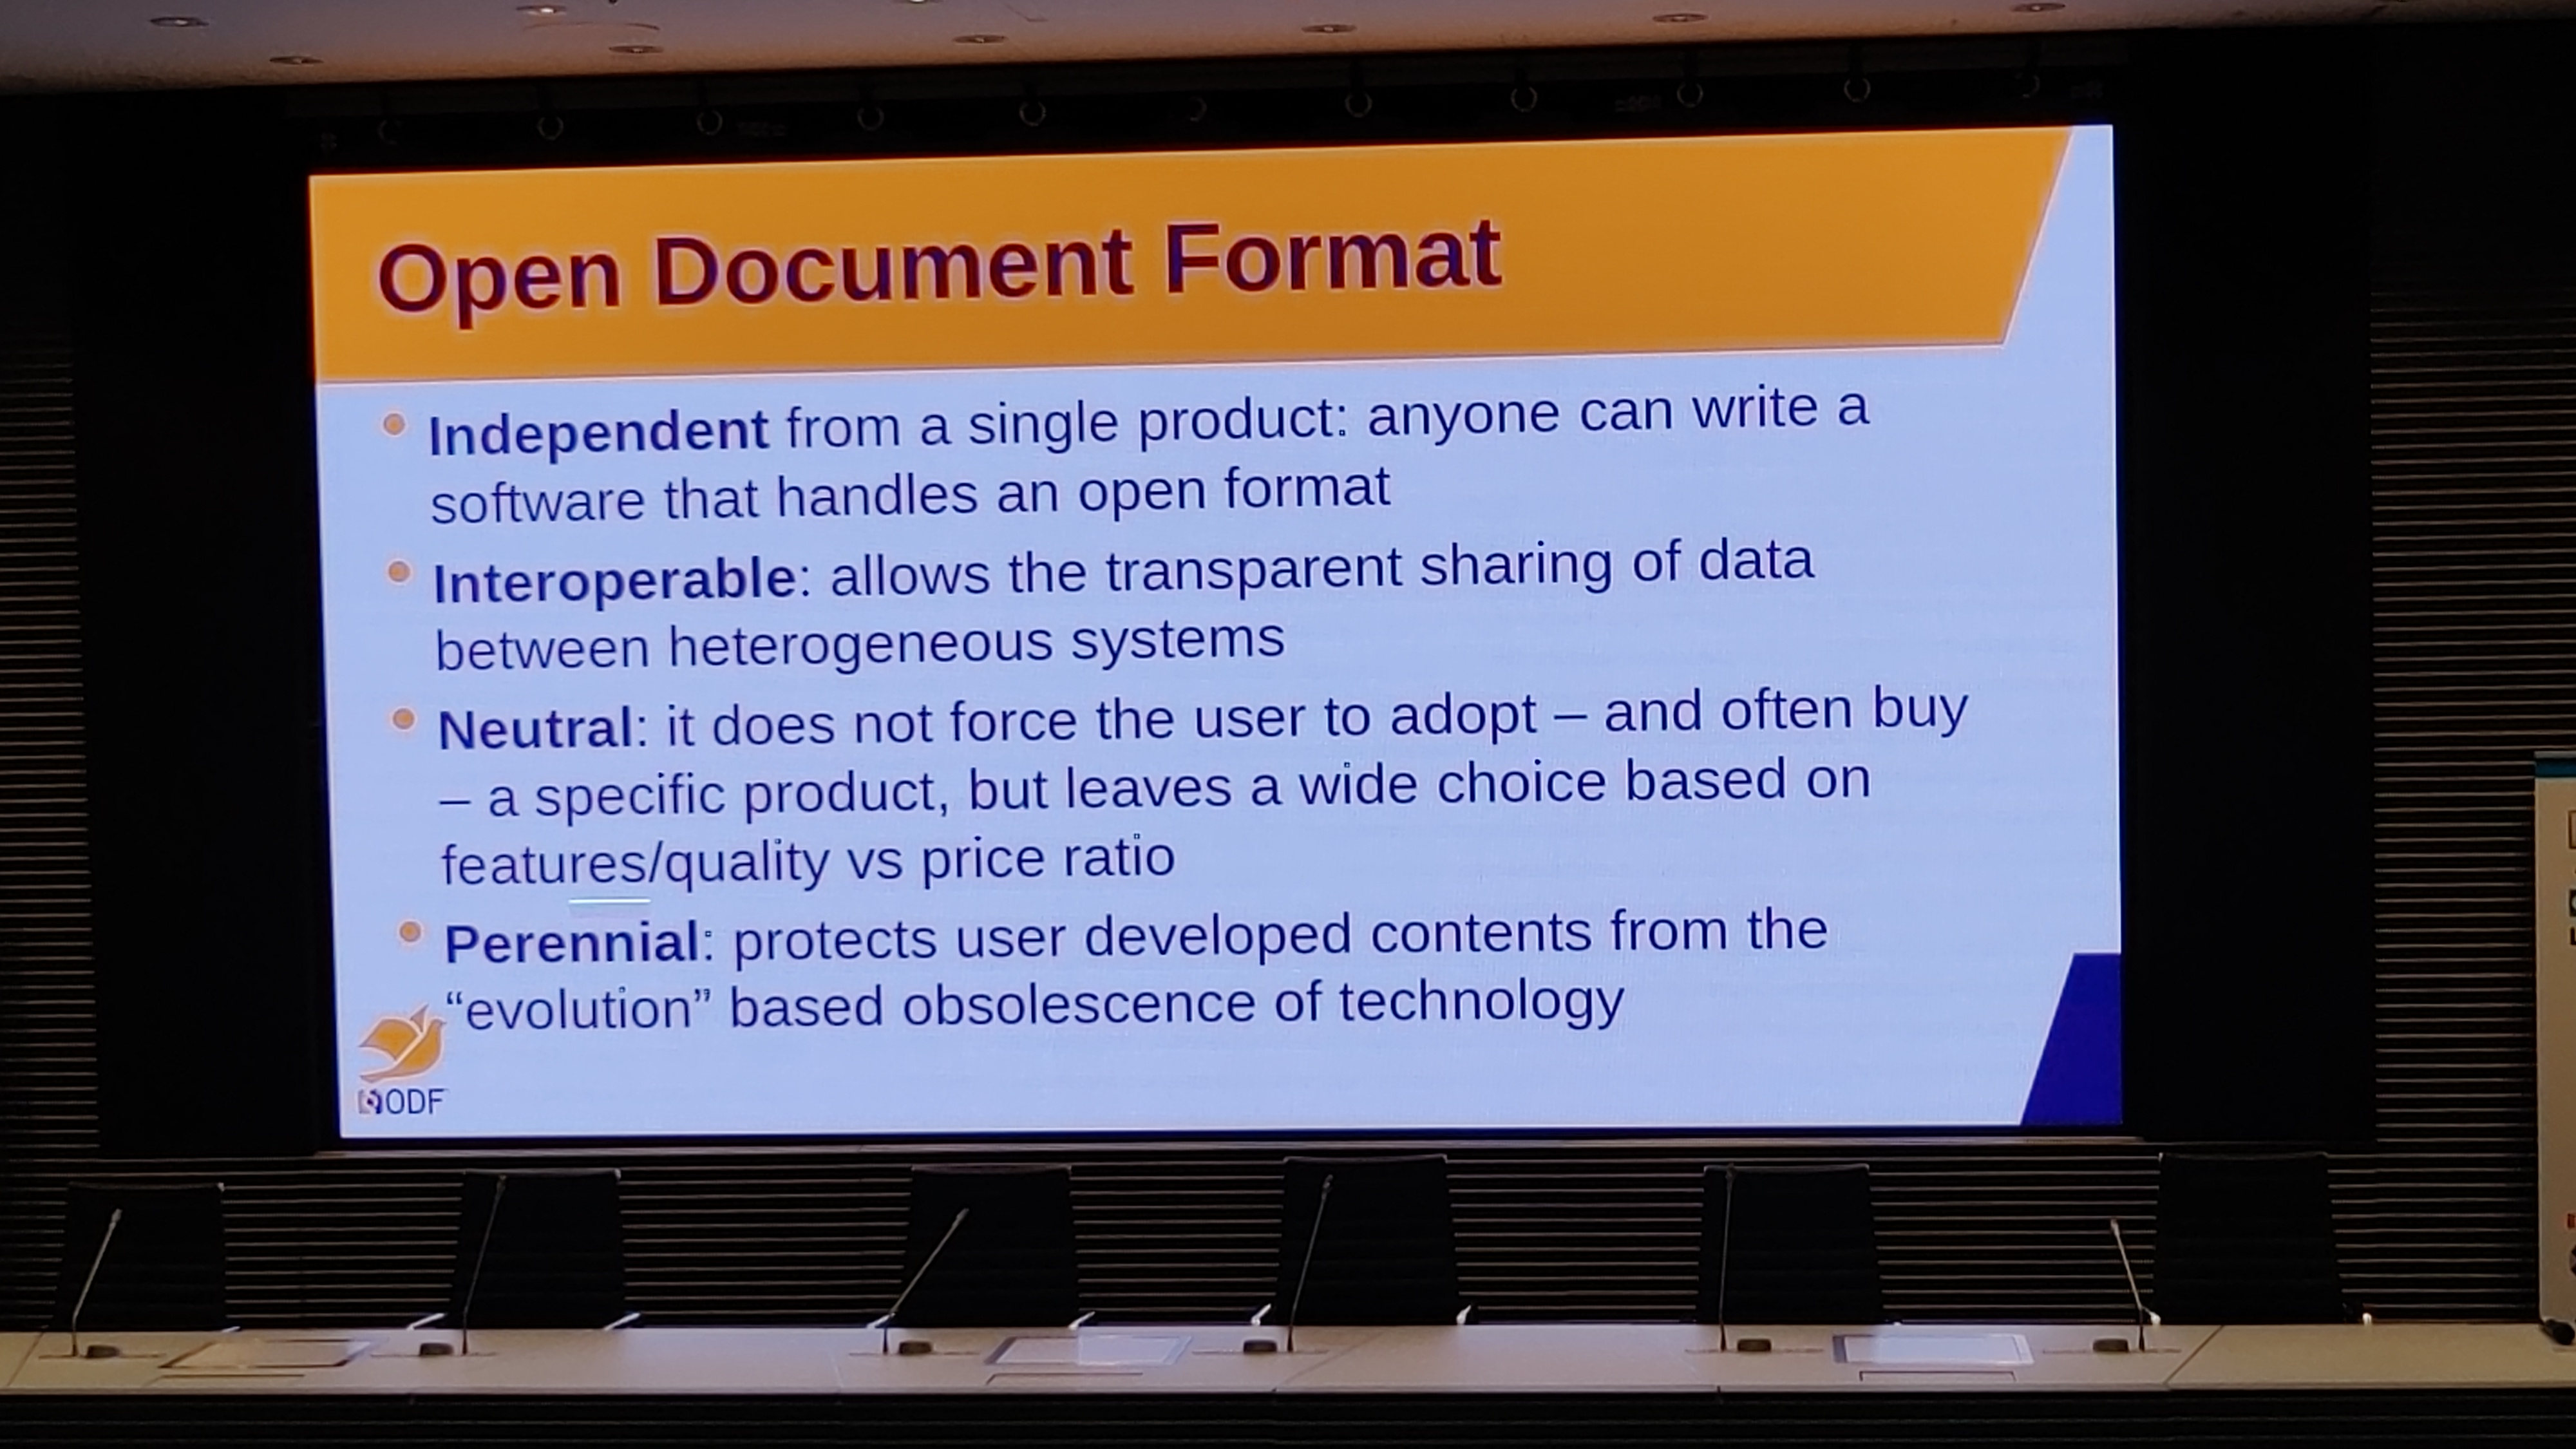
The conference started on the 10th. There were 5 attendees from India, including me, while most of the attendees were from Europe. The talks were in English. One of the talks that stood out for me was about Luxchat a chat service run by the Luxembourg government based on the Matrix protocol for the citizens of Luxembourg. I also liked Italo s talk on why document formats must be freedom-respecting. On the first night, the conference took us to a nice dinner in a restaurant. It offered one more way to socialize with other attendees and explore food at the same time.
One of the slides of Italo's talk
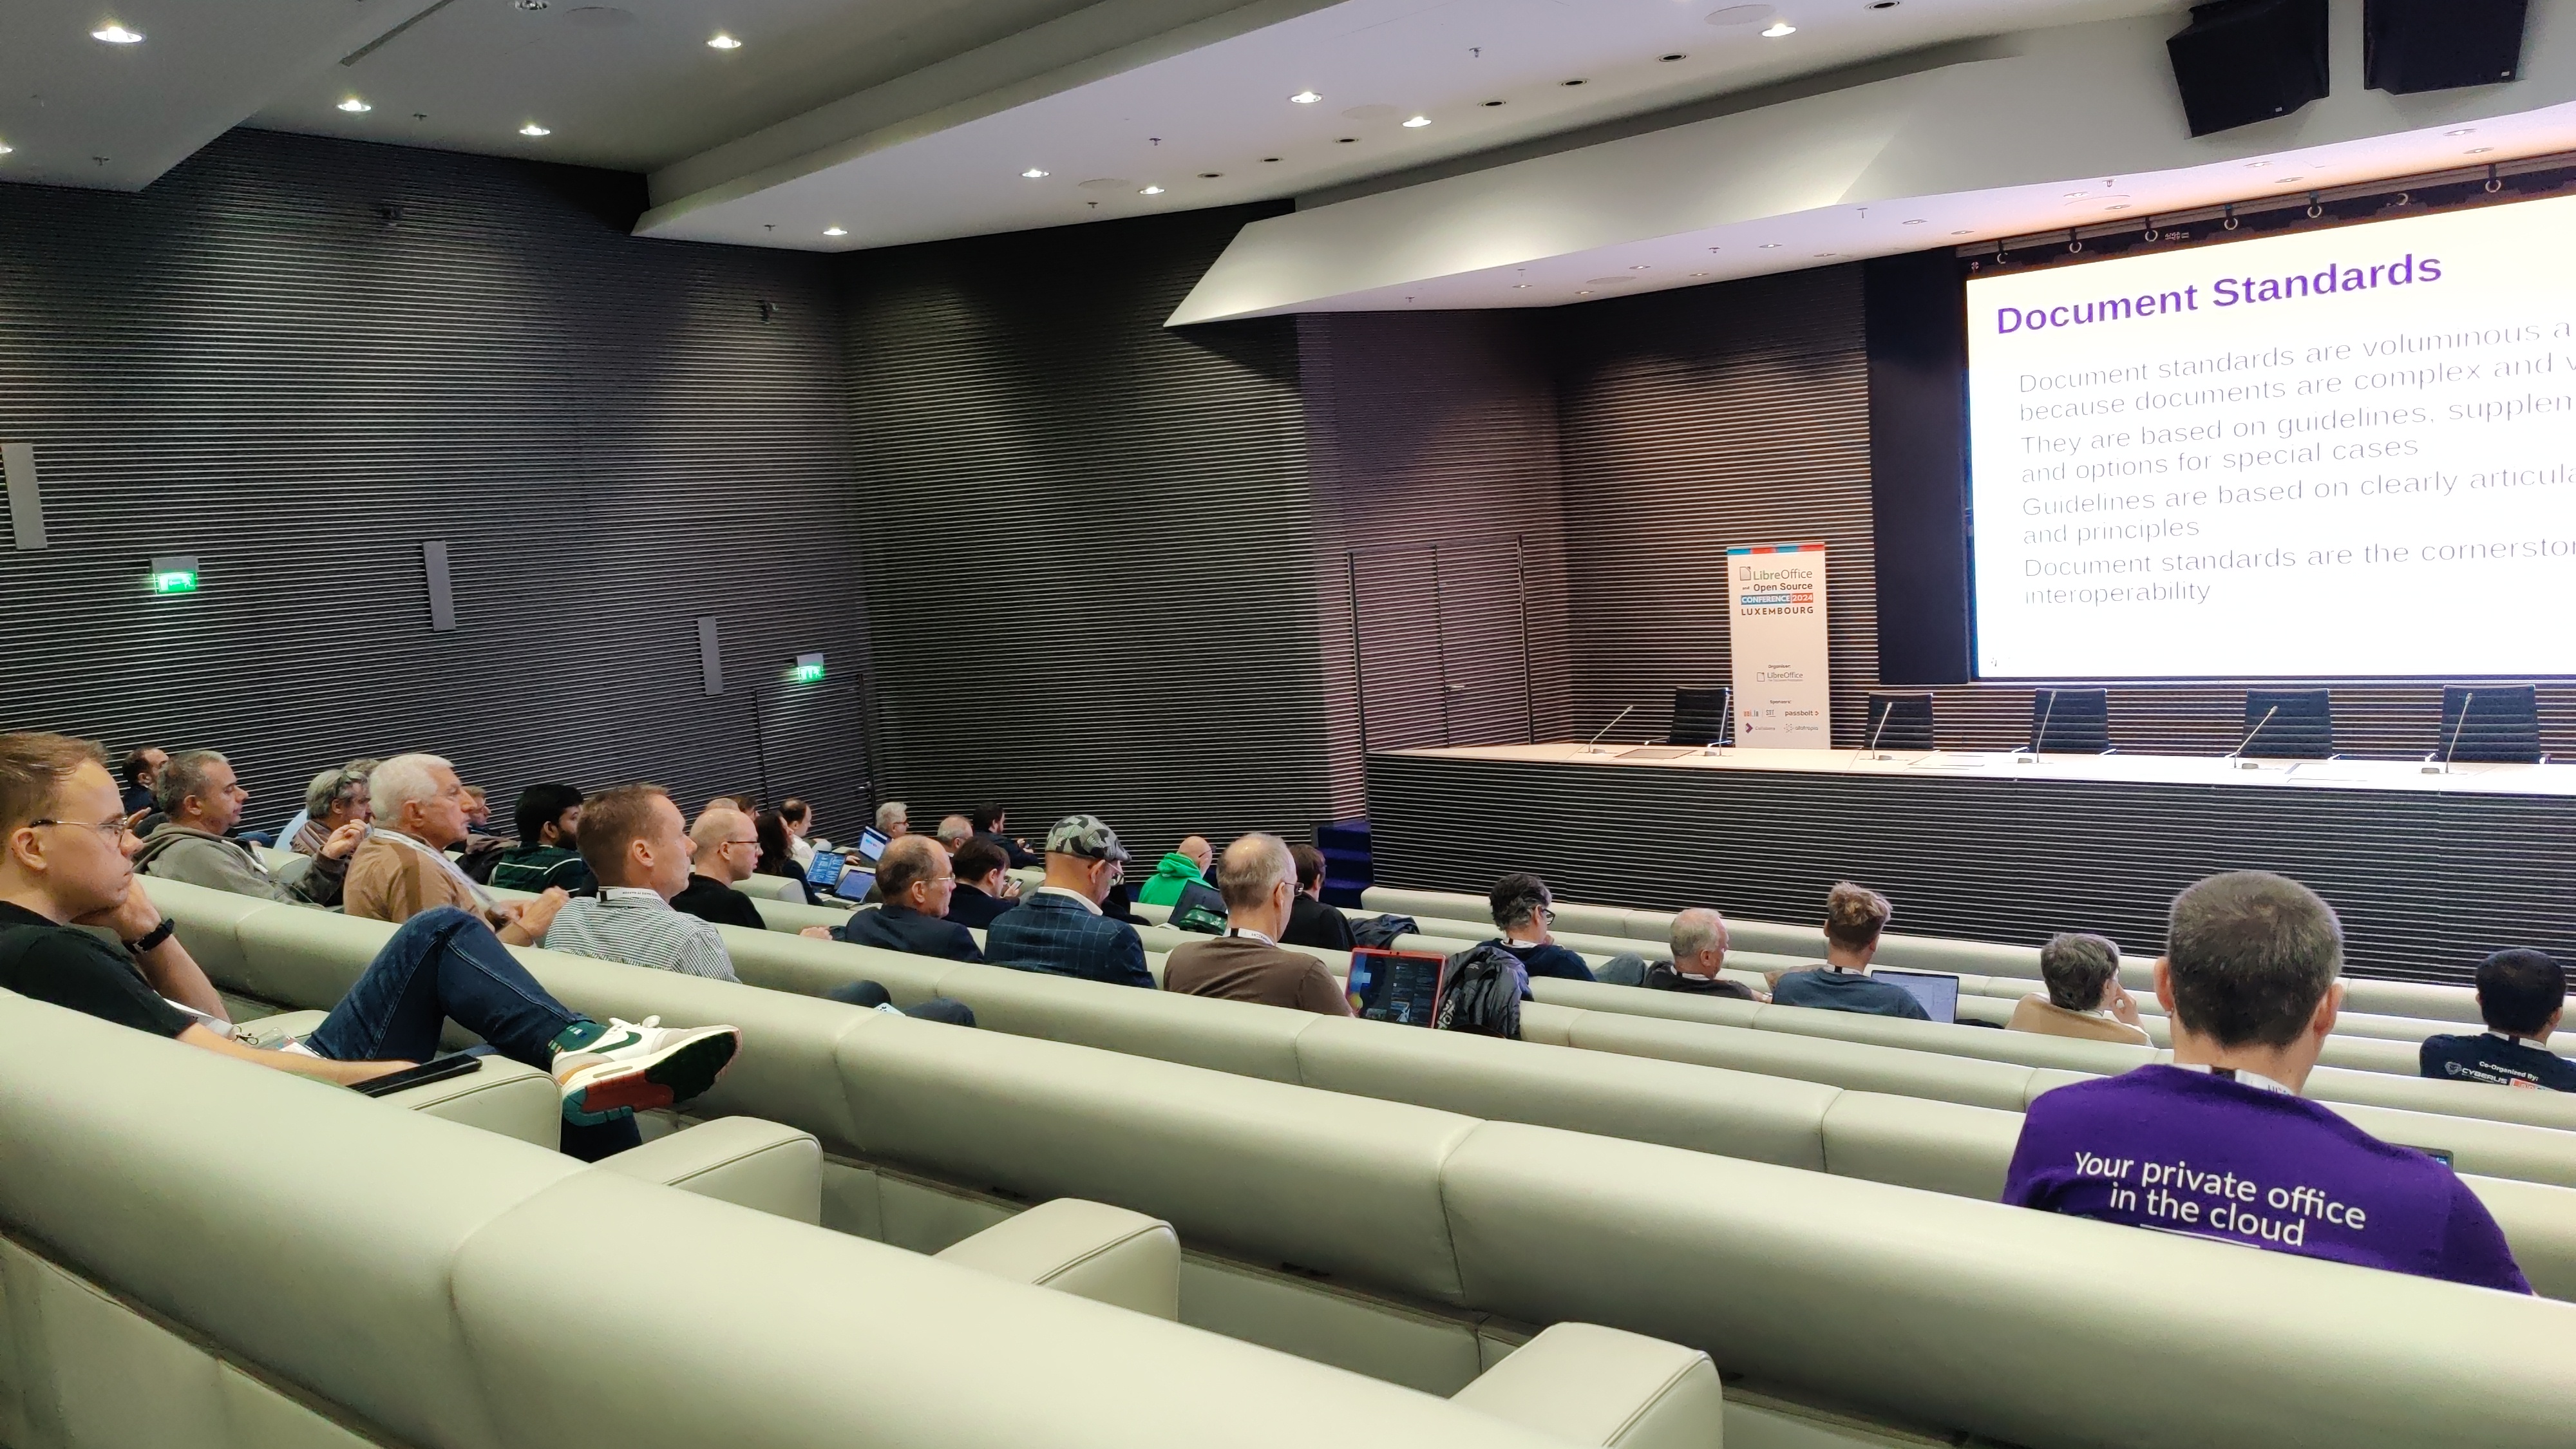
Picture of the hall in which talks were held
On the 11th of October, I went for a walk in the morning with Biswadeep for some sightseeing around our hotel area. As a consequence, I missed the group photo of the conference, which I wanted to be in. Anyway, we enjoyed roaming around the picturesque Luxembourg city. We also sampled a tram ride to return to our hotel.
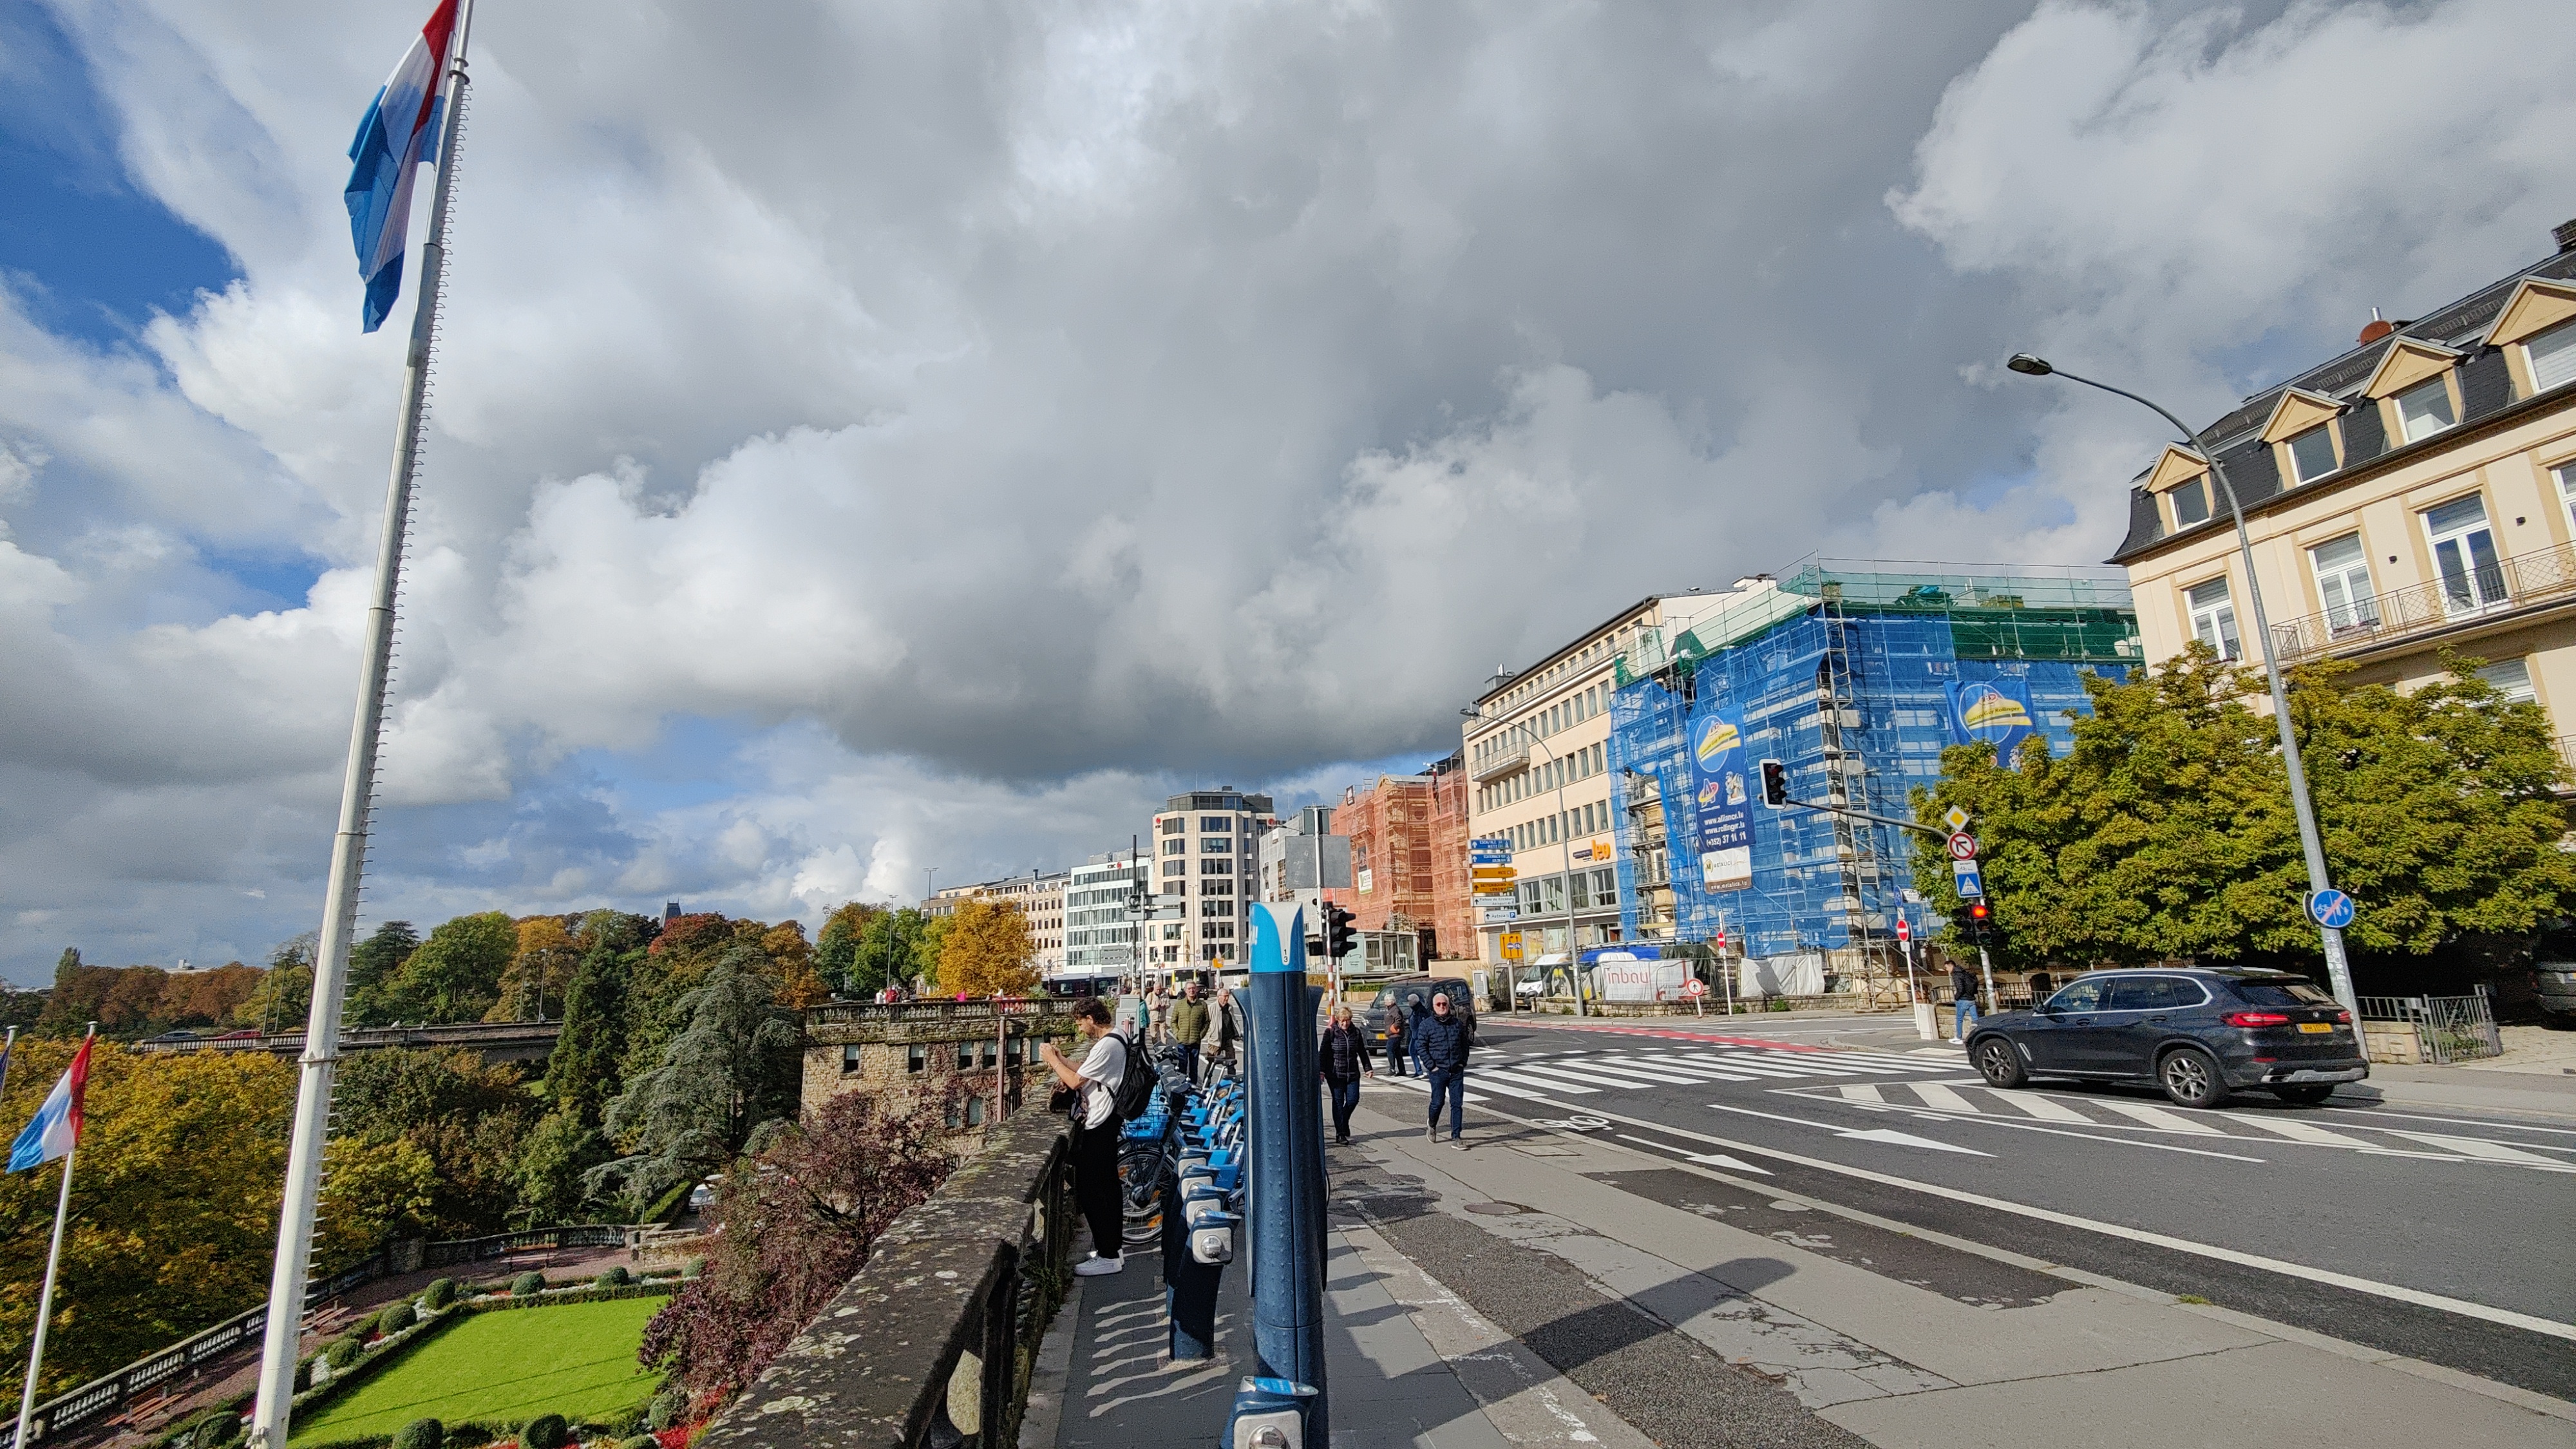
We encountered such scenic views during our walk
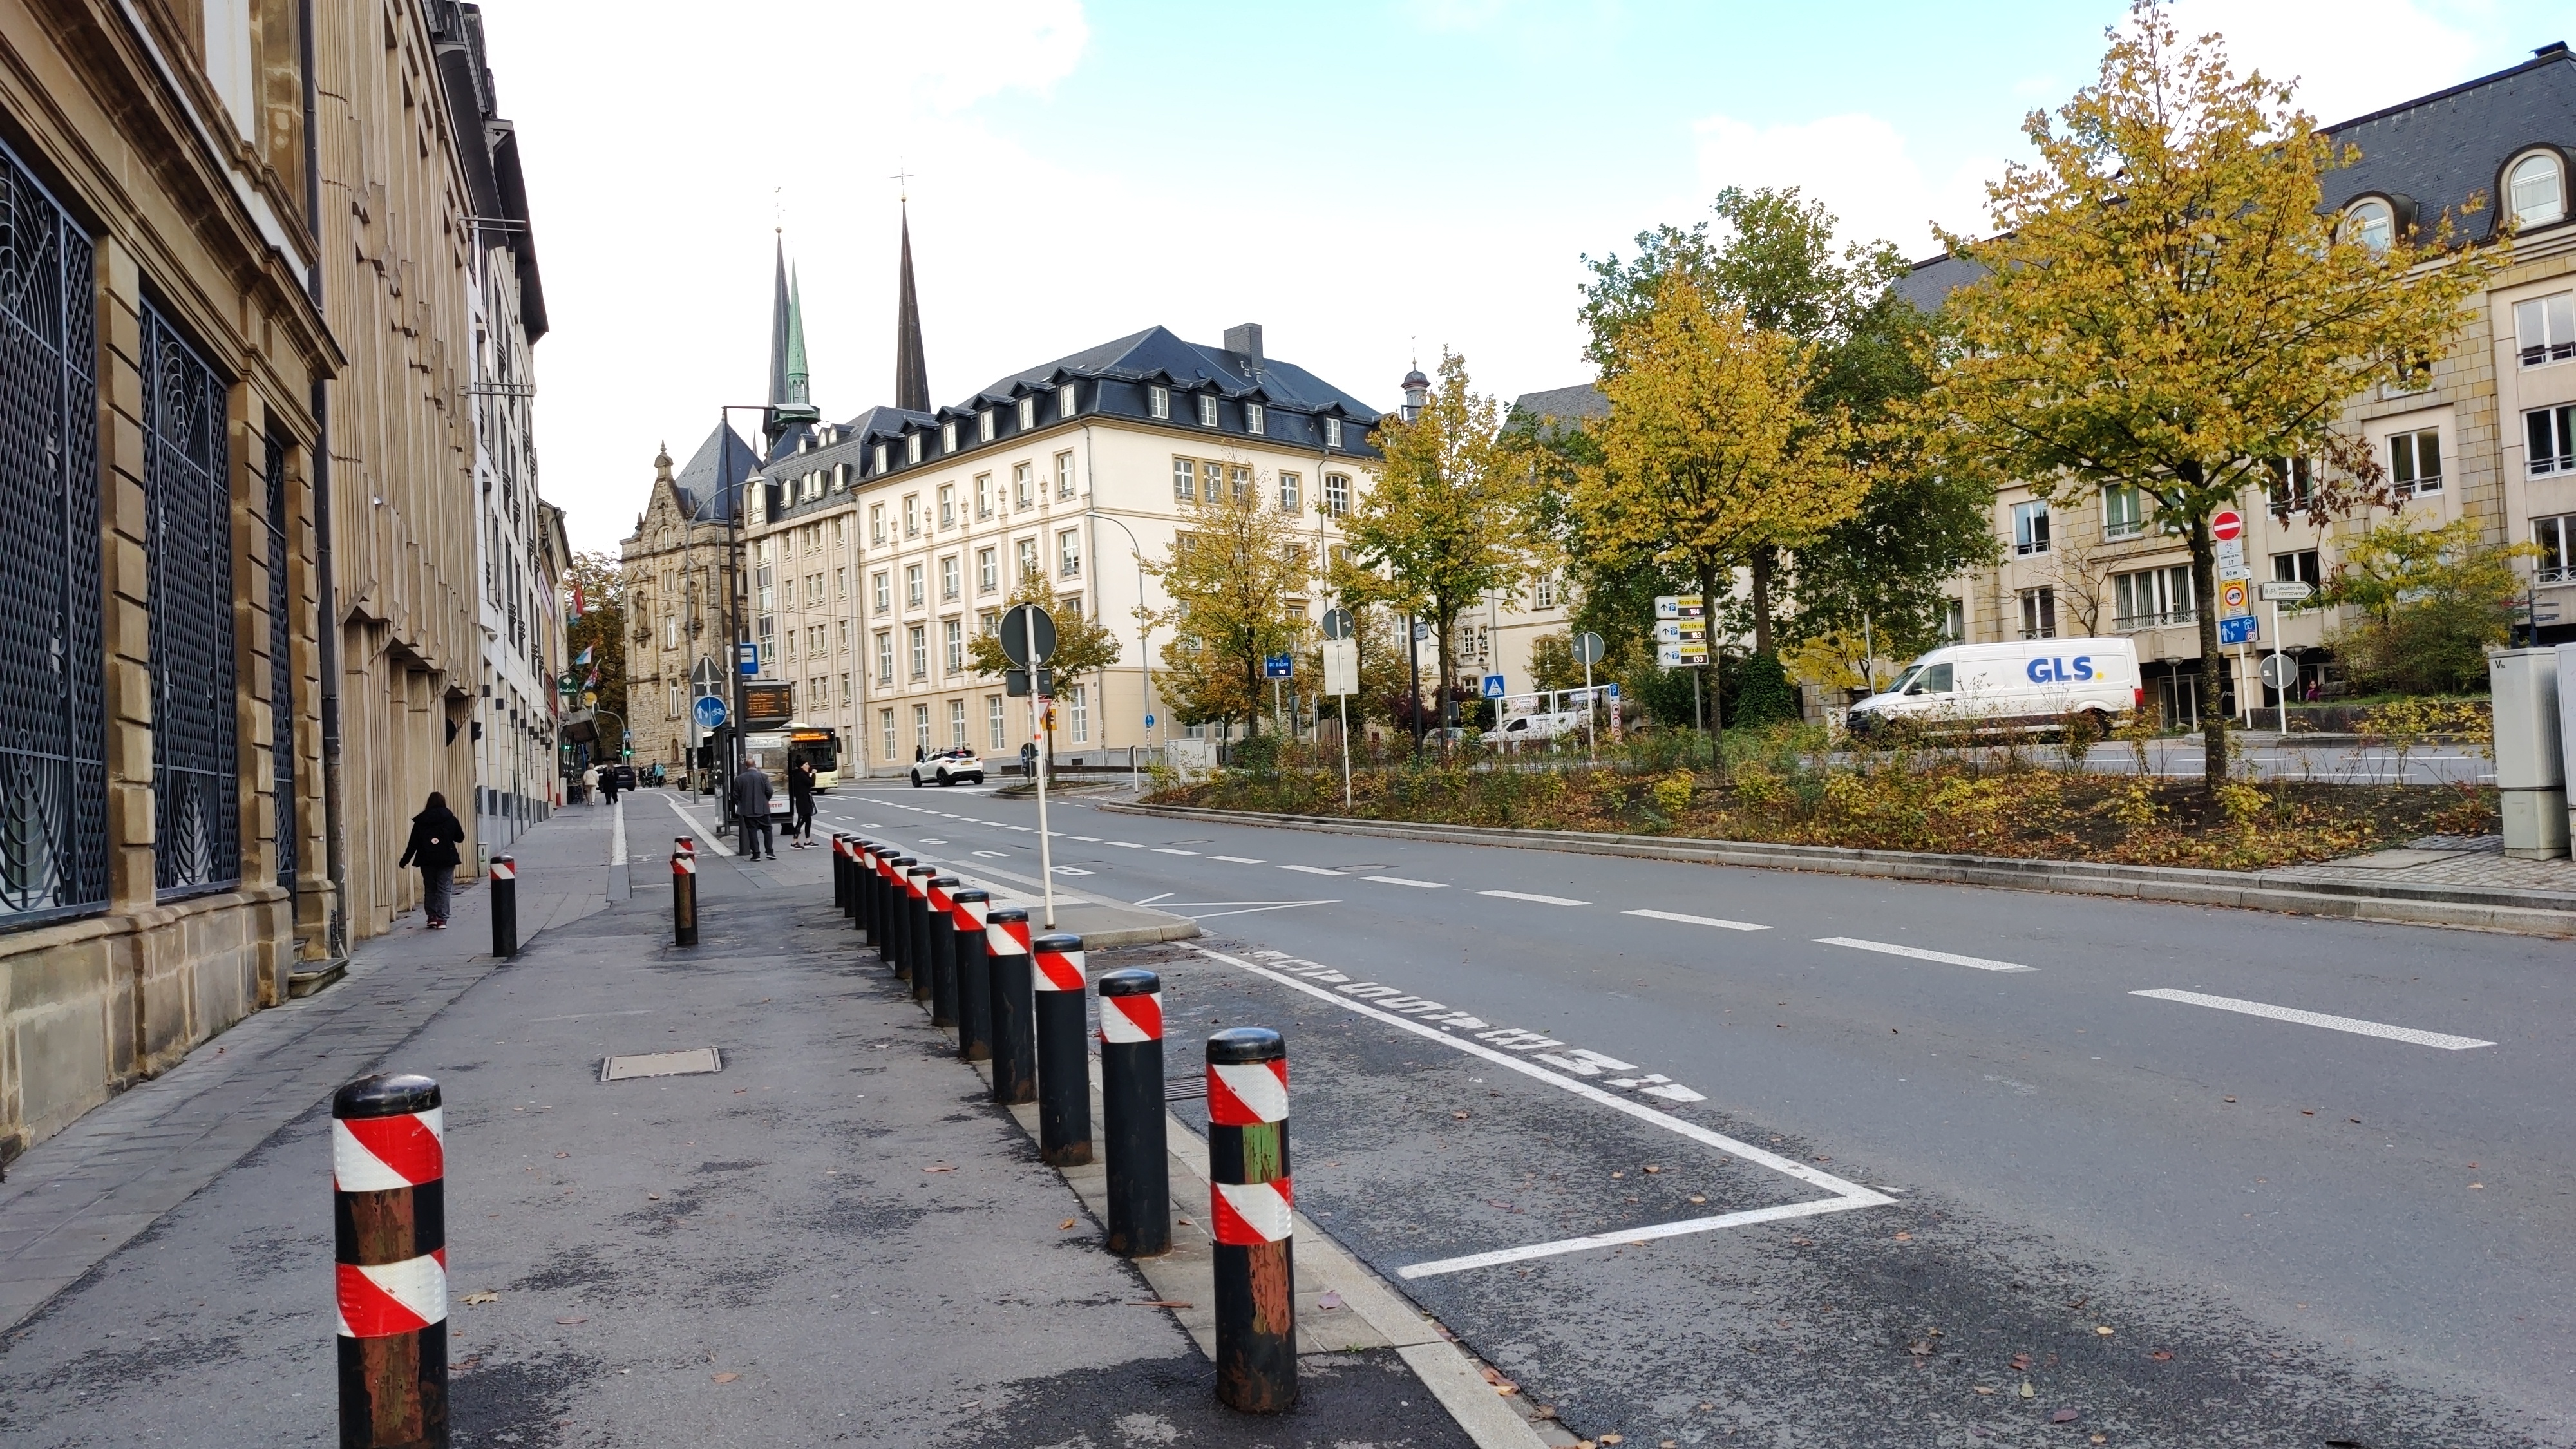
Another view of Luxembourg city area
The conference ended on the 12th with a couple of talks. This conference gave me an opportunity to meet the global LibreOffice community, connect and share ideas. It also gave me a peek into the country of Luxembourg and its people, where I had good experience. English was widely known, and I had no issues getting by. Thanks to all the organizers and sponsors of the conference!

Dima Kogan: Getting precise timings out of RS-232 output

For uninteresting reasons I need very regular 58Hz pulses coming out of an RS-232 Tx line: the time between each pulse should be as close to 1/58s as possible. I produce each pulse by writing an \xFF byte to the device. The start bit is the only active-voltage bit being sent, and that produces my pulse. I wrote this obvious C program:
#include <stdio.h>
#include <stdlib.h>
#include <stdbool.h>
#include <sys/ioctl.h>
#include <unistd.h>
#include <fcntl.h>
#include <termios.h>
#include <stdint.h>
#include <sys/time.h>
static uint64_t gettimeofday_uint64()
 
    struct timeval tv;
    gettimeofday(&tv, NULL);
    return (uint64_t) tv.tv_sec * 1000000ULL + (uint64_t) tv.tv_usec;
 
int main(int argc, char* argv[])
 
    // open the serial device, and make it as raw as possible
    const char* device = "/dev/ttyS0";
    const speed_t baud = B9600;
    int fd = open(device, O_WRONLY O_NOCTTY);
    tcflush(fd, TCIOFLUSH);
    struct termios options =  .c_iflag = IGNBRK,
                              .c_cflag = CS8   CREAD   CLOCAL ;
    cfsetspeed(&options, baud);
    tcsetattr(fd, TCSANOW, &options);
    const uint64_t T_us = (uint64_t)(1e6 / 58.);
    const uint64_t t0 = gettimeofday_uint64();
    for(int i=0; ; i++)
     
        const uint64_t t_target = t0 + T_us*i;
        const uint64_t t1       = gettimeofday_uint64();
        if(t_target > t1)
            usleep(t_target - t1);
        write(fd, &((char) '\xff' ), 1);
     
    return 0;
 
This tries to make sure that each write() call happens at 58Hz. I need these pulses to be regular, so I need to also make sure that the time between each userspace write() and when the edge actually hits the line is as short as possible or, at least, stable. Potential reasons for timing errors:
  1. The usleep() doesn't wake up exactly when it should. This is subject to the Linux scheduler waking up the trigger process
  2. The write() almost certainly ends up scheduling a helper task to actually write the \xFF to the hardware. This helper task is also subject to the Linux scheduler waking it up.
  3. Whatever the hardware does. RS-232 doesn't give you any guarantees about byte-byte timings, so this could be an unfixable source of errors
The scheduler-related questions are observable without any extra hardware, so let's do that first. I run the ./trigger program, and look at diagnostics while that's running. I look at some device details:
# ls -lh /dev/ttyS0
crw-rw---- 1 root dialout 4, 64 Mar  6 18:11 /dev/ttyS0
# ls -lh /sys/dev/char/4:64/
total 0
-r--r--r-- 1 root root 4.0K Mar  6 16:51 close_delay
-r--r--r-- 1 root root 4.0K Mar  6 16:51 closing_wait
-rw-r--r-- 1 root root 4.0K Mar  6 16:51 console
-r--r--r-- 1 root root 4.0K Mar  6 16:51 custom_divisor
-r--r--r-- 1 root root 4.0K Mar  6 16:51 dev
lrwxrwxrwx 1 root root    0 Mar  6 16:51 device -> ../../../0000:00:16.3:0.0
-r--r--r-- 1 root root 4.0K Mar  6 16:51 flags
-r--r--r-- 1 root root 4.0K Mar  6 16:51 iomem_base
-r--r--r-- 1 root root 4.0K Mar  6 16:51 iomem_reg_shift
-r--r--r-- 1 root root 4.0K Mar  6 16:51 io_type
-r--r--r-- 1 root root 4.0K Mar  6 16:51 irq
-r--r--r-- 1 root root 4.0K Mar  6 16:51 line
-r--r--r-- 1 root root 4.0K Mar  6 16:51 port
drwxr-xr-x 2 root root    0 Mar  6 16:51 power
-rw-r--r-- 1 root root 4.0K Mar  6 16:51 rx_trig_bytes
lrwxrwxrwx 1 root root    0 Mar  6 16:51 subsystem -> ../../../../../../../class/tty
-r--r--r-- 1 root root 4.0K Mar  6 16:51 type
-r--r--r-- 1 root root 4.0K Mar  6 16:51 uartclk
-rw-r--r-- 1 root root 4.0K Mar  6 16:51 uevent
-r--r--r-- 1 root root 4.0K Mar  6 16:51 xmit_fifo_size
Unsurprisingly, this is a part of the tty subsystem. I don't want to spend the time to really figure out how this works, so let me look at all the tty kernel calls and also at all the kernel tasks scheduled by the trigger process, since I suspect that the actual hardware poke is happening in a helper task. I see this:
# bpftrace -e 'k:*tty* /comm=="trigger"/
                 printf("%d %d %s\n",pid,tid,probe);  
               t:sched:sched_wakeup /comm=="trigger"/
                 printf("switching to %s(%d); current backtrace:", args.comm, args.pid); print(kstack());   '
...
3397345 3397345 kprobe:tty_ioctl
3397345 3397345 kprobe:tty_check_change
3397345 3397345 kprobe:__tty_check_change
3397345 3397345 kprobe:tty_wait_until_sent
3397345 3397345 kprobe:tty_write
3397345 3397345 kprobe:file_tty_write.isra.0
3397345 3397345 kprobe:tty_ldisc_ref_wait
3397345 3397345 kprobe:n_tty_write
3397345 3397345 kprobe:tty_hung_up_p
switching to kworker/0:1(3400169); current backtrace:
        ttwu_do_activate+268
        ttwu_do_activate+268
        try_to_wake_up+605
        kick_pool+92
        __queue_work.part.0+582
        queue_work_on+101
        rpm_resume+1398
        __pm_runtime_resume+75
        __uart_start+85
        uart_write+150
        n_tty_write+1012
        file_tty_write.isra.0+373
        vfs_write+656
        ksys_write+109
        do_syscall_64+130
        entry_SYSCALL_64_after_hwframe+118
3397345 3397345 kprobe:tty_update_time
3397345 3397345 kprobe:tty_ldisc_deref
... repeated with each pulse ...
Looking at the sources I see that uart_write() calls __uart_start(), which schedules a task to call serial_port_runtime_resume() which eventually calls serial8250_tx_chars(), which calls some low-level functions to actually send the bits. I look at the time between two of those calls to quantify the scheduler latency:
pulserate=58
sudo zsh -c \
  '( echo "# dt_write_ns dt_task_latency_ns";
     bpftrace -q -e "k:vfs_write /comm==\"trigger\" && arg2==1/
                      \$t=nsecs(); if(@t0)   @dt_write = \$t-@t0;   @t0=\$t; 
                     k:serial8250_tx_chars /@dt_write/
                      \$t=nsecs(); printf(\"%d %d\\n\", @dt_write, \$t-@t0); "
   )' \
  vnl-filter                  \
    --stream -p dt_write_ms="dt_write_ns/1e6 - 1e3/$pulserate",dt_task_latency_ms=dt_task_latency_ns/1e6 \
  feedgnuplot  \
    --stream   \
    --lines    \
    --points   \
    --xlen 200 \
    --vnl      \
    --autolegend \
    --xlabel 'Pulse index' \
    --ylabel 'Latency (ms)'
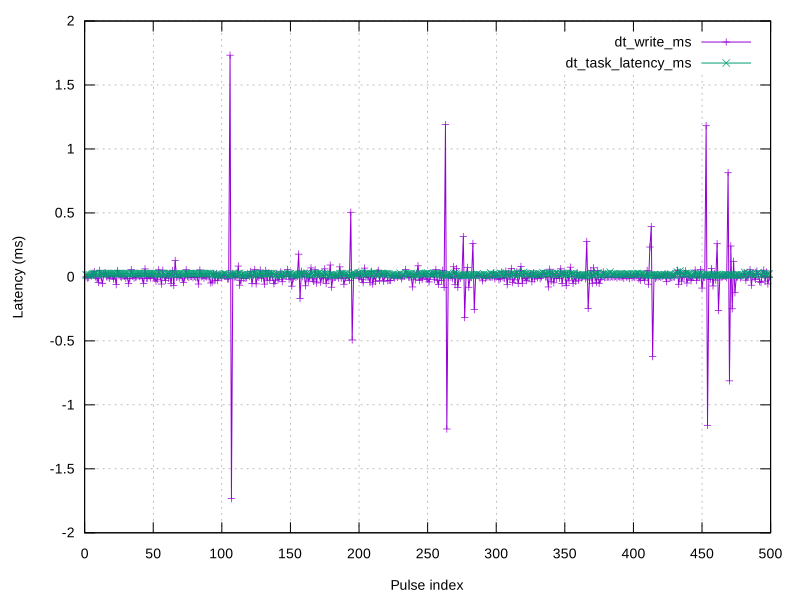
Here I'm making a realtime plot showing The raw data as I tweak things lives here. Initially I see big latency spikes:
timings.scheduler.1.noise.svg
These can be fixed by adjusting the priority of the trigger task. This tells the scheduler to wake that task up first, even if something else is currently using the CPU. I do this:
sudo chrt -p 90  pidof trigger 
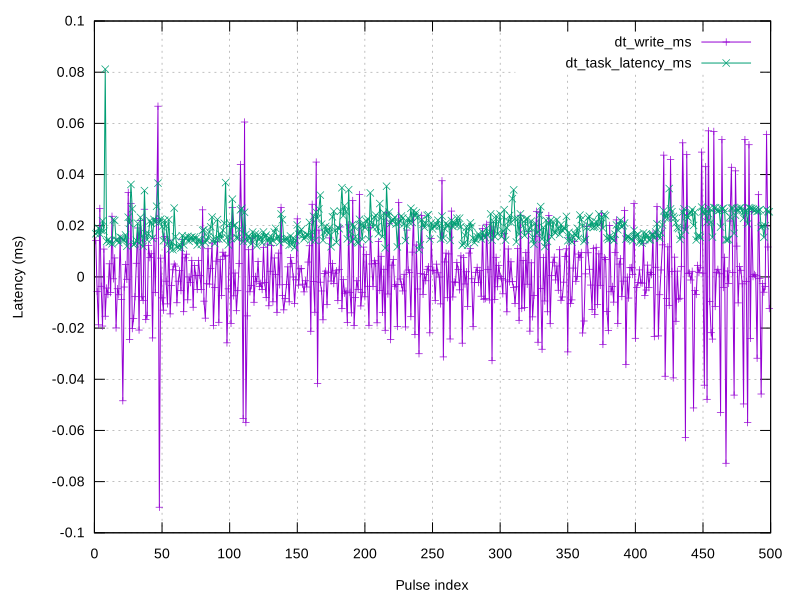
And I get better-looking latencies:
timings.scheduler.2.clean.svg
During some experiments (not in this dataset) I would see high helper-task timing instabilities as well. These could be fixed by prioritizing the helper task. In this kernel (6.12) the helper task is called kworker/N where N is the CPU index. I tie the trigger process to cpu 0, and priorities all the relevant helpers:
taskset -c 0 ./trigger 58
pgrep -f kworker/0   while   read pid     sudo chrt -p 90 $pid  
This fixes the helper-task latency spikes. OK, so it looks like on the software side we're good to within 0.1ms of the true period. This is in the ballpark of the precision I need; even this might be too high. It's possible to try to push the software to do better: one could look at the kernel sources a bit more, to do smarter things with priorities or to try an -rt kernel. But all this doesn't matter if the serial hardware adds unacceptable delays. Let's look. Let's look at it with a logic analyzer. I use a saleae logic analyzer with sigrok. The tool spits out the samples as it gets them, and an awk script finds the edges and reports the timings to give me a realtime plot.
samplerate=500000;
pulserate=58.;
sigrok-cli -c samplerate=$samplerate -O csv --continuous -C D1 \
  mawk -Winteractive  \
    "prev_logic==0 && \$0==1 \
       
       iedge = NR;
       if(prev_iedge)
        
         di = iedge -prev_iedge;
         dt = di/$samplerate;
         print(dt*1000);
        
       prev_iedge = iedge;
      
      
       prev_logic=\$0;
       "   feedgnuplot --stream --ylabel 'Period (ms)' --equation "1000./$pulserate title \"True $ pulserate Hz period\""
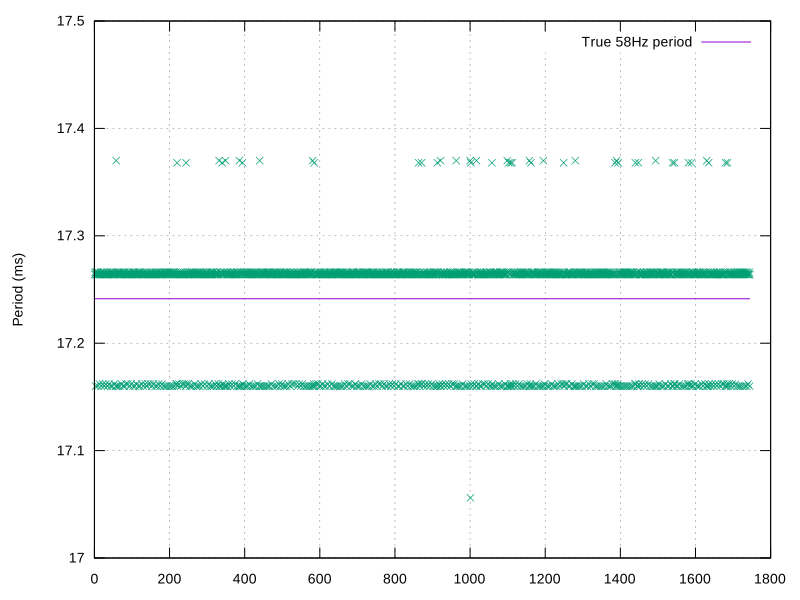
On the server I was using (physical RS-232 port, ancient 3.something kernel):
timings.hw.serial-server.svg
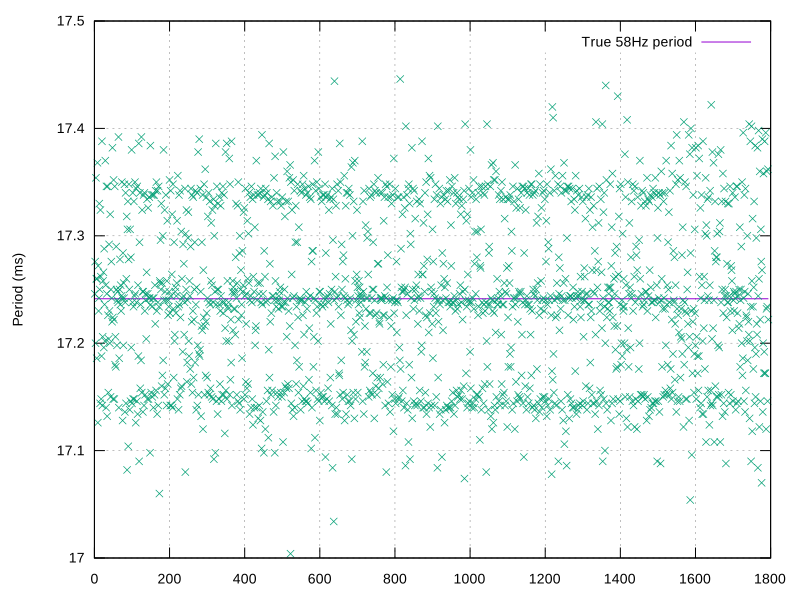
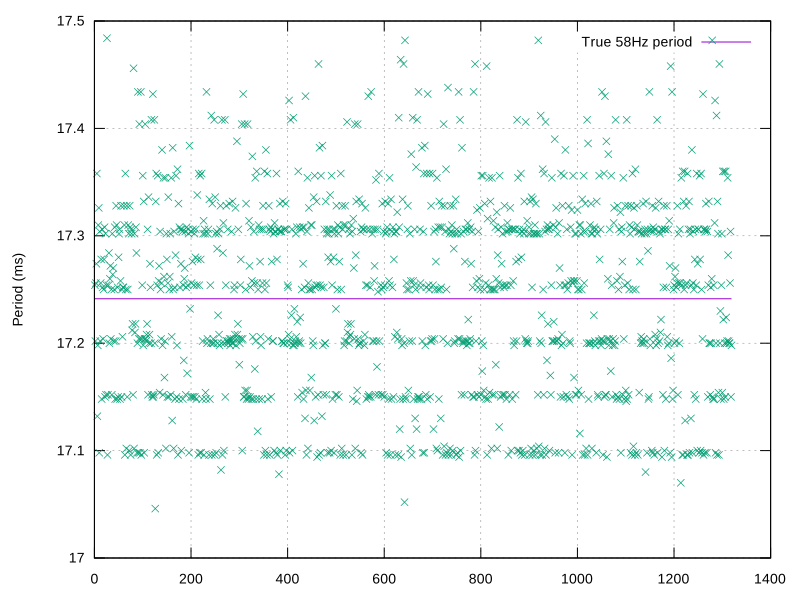
OK This is very discrete for some reason, and generally worse than 0.1ms. What about my laptop (physical RS-232 port, recent 6.12 kernel)?
timings.hw.serial-laptop.svg
Not discrete anymore, but not really any more precise. What about using a usb-serial converter? I expect this to be worse.
timings.hw.usbserial.svg
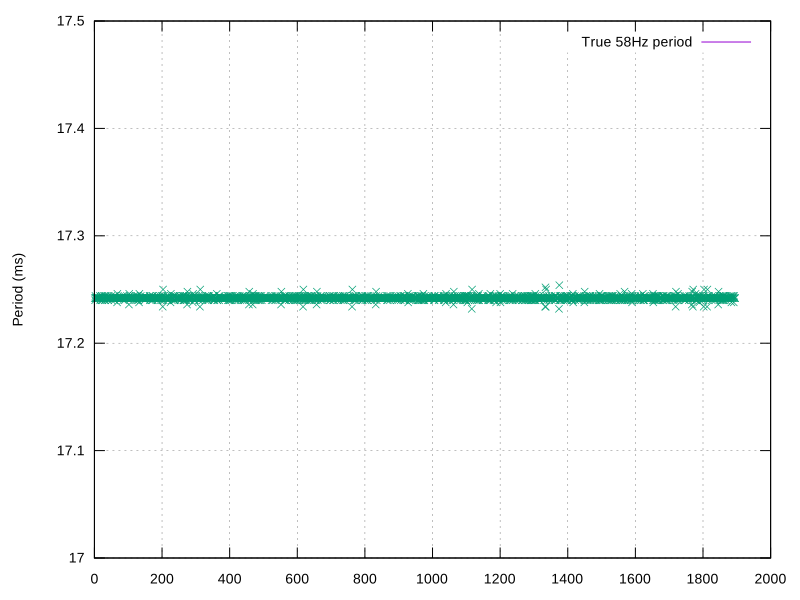
Yeah, looks worse. For my purposes, an accuracy of 0.1ms is marginal, and the hardware adds non-negligible errors. So I cut my losses, and use an external signal generator:
timings.hw.generator.svg
Yeah. That's better, so that's what I use.

11 March 2025

Freexian Collaborators: Debian Contributions: Debian.Social administration, DebConf 25 preparations, Fixing Time-based test failure in Python requests package and more! (by Anupa Ann Joseph)

Debian Contributions: 2025-02 Contributing to Debian is part of Freexian s mission. This article covers the latest achievements of Freexian and their collaborators. All of this is made possible by organizations subscribing to our Long Term Support contracts and consulting services.

Debian.Social administration, by Stefano Rivera Over the last year, the Debian.social services outgrew the infrastructure that was supporting them. The matrix bridge in particular was hosted on a cloud instance backed by a large expensive storage volume. Debian.CH rented a new large physical server to host all these instances, earlier this year. Stefano set up Incus on the new physical machine and migrated all the old debian.social LXC Containers, libvirt VMs, and cloud instances into Incus-managed LXC containers. Stefano set up Prometheus monitoring and alerts for the new infrastructure and a Grafana dashboard. The current stack of debian.social services seem to comfortably fit on the new machine, with good room to grow.

DebConf 25, by Santiago Ruano Rinc n and Stefano Rivera DebConf 25 preparations continue. The team is currently finalizing a budget. Stefano helped to review the current budget proposals and suggest approaches for balancing it. Stefano installed a Zammad instance to organize queries from attendees, for the registration and visa teams. Santiago continued discussions with possible caterers so we can have options for the different diet requirements and that could fit into the DebConf budget. Also, in collaboration with Anupa, Santiago pushed the first draft changes to document the venue information in the DebConf 25 website and how to get to Brest.

Time-based test failure in requests, by Colin Watson Colin fixed a fun bug in the Python requests package. Santiago Vila has been running tests of what happens when Debian packages are built on a system in which time has been artificially set to somewhere around the end of the support period for the next Debian release, in order to make it easier to do things like issuing security updates for the lifetime of that release. In this case, the failure indicated an expired test certificate, and since the repository already helpfully included scripts to regenerate those certificates, it seemed natural to try regenerating them just before running tests. However, this failed for more obscure reasons and Colin spent some time investigating. This turned out to be because the test CA was missing the CA constraint and so recent versions of OpenSSL reject it; Colin sent a pull request to fix this.

Priority list for outdated packages, by Santiago Ruano Rinc n Santiago started a discussion on debian-devel about packages that have a history of security issues and that are outdated regarding new upstream releases. The goal of the mentioned effort is to have a prioritized list of packages needing some work, from a security point of view. Moreover, the aim of publicly sharing the list of packages with the Debian Developers community is to make it easier to look at the packages maintained by teams, or even other maintainers where help could be welcome. Santiago is planning to take into account the feedback provided in debian-devel and to propose a tooling that could help to regularly bring collective awareness of these packages.

Miscellaneous contributions
  • Carles worked on English to Catalan po-debconf translations: reviewed translations, created merge requests and followed up with developers for more than 30 packages using po-debconf-manager.
  • Carles helped users, fixed bugs and implemented downloading updated templates on po-debconf-manager.
  • Carles packaged a new upstream version of python-pyaarlo.
  • Carles improved reproducibility of qnetload (now reported as reproducible) and simplemonitor (followed up with upstream and pending update of Debian package).
  • Carles collaborated with debian-history package: fixed FTBFS from master branch, enabled salsa-ci and investigated reproducibility.
  • Emilio improved support for automatically marking CVEs as NOT-FOR-US in the security-tracker, closing #1073012.
  • Emilio updated xorg-server and xwayland in unstable, fixing the last round of security vulnerabilities.
  • Stefano prepared a few PyPy and cPython uploads, and started the python3.13-only transition.
  • Helmut Grohne sent patches for 24 cross build failures.
  • Helmut fixed two problems in the Debian /usr-merge analysis tool. In one instance, it would overmatch Debian bugs to issues and in another it would fail to recognize Pre-Depends as a conflict mechanism.
  • Helmut attempted making rebootstrap work for gcc-15 with limited success as very many packages FTBFS with gcc-15 due to using function declarations without arguments.
  • Helmut provided a change to the security-tracker that would pre-compute /data/json during database updates rather than on demand resulting in a reduced response time.
  • Colin uploaded OpenSSH security updates for testing/unstable, bookworm, bullseye, buster, and stretch.
  • Colin fixed upstream monitoring for 26 Python packages, and upgraded 54 packages (mostly Python-related, but also PuTTY) to new upstream versions.
  • Colin updated python-django in bookworm-backports to 4.2.18 (issuing BSA-121), and added new backports of python-django-dynamic-fixture and python-django-pgtrigger, all of which are dependencies of debusine.
  • Thorsten Alteholz finally managed to upload hplip to fix two release critical and some normal bugs. The next step in March would be to upload the latest version of hplip.
  • Faidon updated crun in unstable & trixie, resolving a long-standing request of enabling criu support and thus enabling podman with checkpoint/restore functionality (With gratitude to Salvatore Bonaccorso and Reinhard Tartler for the cooperation and collaboration).
  • Faidon uploaded a number of packages (librdkafka, libmaxminddb, python-maxminddb, lowdown, tox, tox-uv, pyproject-api, xiccd and gdnsd) bringing them up to date with new upstream releases, resolving various bugs.
  • Lucas Kanashiro uploaded some ruby packages involved in the Rails 7 transition with new upstream releases.
  • Lucas triaged a ruby3.1 bug (#1092595)) and prepared a fix for the next stable release update.
  • Lucas set up the needed wiki pages and updated the Debian Project status in the Outreachy portal, in order to send out a call for projects and mentors for the next round of Outreachy.
  • Anupa joined Santiago to prepare a list of companies to contact via LinkedIn for DebConf 25 sponsorship.
  • Anupa printed Debian stickers and sponsorship brochures, flyers for DebConf 25 to be distributed at FOSS ASIA summit 2025.
  • Anupa participated in the Debian publicity team meeting and discussed the upcoming events and tasks.
  • Rapha l packaged zim 0.76.1 and integrated an upstream patch for another regression that he reported.
  • Rapha l worked with the Debian System Administrators for tracker.debian.org to better cope with gmail s requirement for mails to be authenticated.

10 March 2025

Thorsten Alteholz: My Debian Activities in February 2025

Debian LTS This was my hundred-twenty-eighth month that I did some work for the Debian LTS initiative, started by Raphael Hertzog at Freexian. During my allocated time I uploaded or worked on: Last but not least I did some days of FD this month and attended the monthly LTS/ELTS meeting. Debian ELTS This month was the seventy-ninth ELTS month. During my allocated time I uploaded or worked on: Last but not least I did some days of FD this month and attended the monthly LTS/ELTS meeting. Debian Printing This month I uploaded new packages or new upstream or bugfix versions of: This work is generously funded by Freexian! Debian Matomo This month I uploaded new packages or new upstream or bugfix versions of: Finally matomo was uploaded. Thanks a lot to Utkarsh Gupta and William Desportes for doing most of the work to make this happen. This work is generously funded by Freexian! Debian Astro Unfortunately I didn t found any time to upload packages.Have you ever heard of poliastro? It was a package to do calculations related to astrodynamics and orbital mechanics? It was archived by upstream end of 2023. I am now trying to revive it under the new name boinor and hope to get it back into Debian over the next months. This is almost the last month that Patrick, our Outreachy intern for the Debian Astro project, is handling his tasks. He is working on automatic updates of the indi 3rd-party driver. Debian IoT Unfortunately I didn t found any time to work on this topic. Debian Mobcom This month I uploaded new packages or new upstream or bugfix versions of: misc Unfortunately I didn t found any time to work on this topic. FTP master This month I accepted 437 and rejected 64 packages. The overall number of packages that got accepted was 445.

9 March 2025

Dirk Eddelbuettel: RcppNLoptExample 0.0.2: Minor Updates

An update to our package RcppNLoptExample arrived on CRAN earlier today marking the first update since the intial release more than four year ago. The nloptr package, created by Jelmer Ypma, has long been providing an excellent R interface to NLopt, a very comprehensive library for nonlinear optimization. In particular, Jelmer carefully exposed the API entry points such that other R packages can rely on NLopt without having to explicitly link to it (as one can rely on R providing sufficient function calling and registration to make this possible by referring back to nloptr which naturally has the linking information and resolution). This package demonstrates this in a simple-to-use Rcpp example package that can serve as a stanza. More recent NLopt versions appear to have changed behaviour a little so that an example we relied upon in simple unit test now converges to a marginally different numerical value, so we adjusted a convergence treshold. Other than that we did a number of the usual small updates to package metadata, to the README.md file, and to continuous integration. The (very short) NEWS entry follows:

Changes in version 0.0.2 (2025-03-09)
  • Updated tolerance in simple test as newer upstream nlopt change behaviour ever so slightly leading to an other spurious failure
  • Numerous small and standard updates to DESCRIPTION, README.md, badges, and continuous integration setup

Courtesy of my CRANberries, there is also a diffstat report for this release. For questions, suggestions, or issues please use the issue tracker at the GitHub repo.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. If you like this or other open-source work I do, you can now sponsor me at GitHub.

Niels Thykier: Improving Debian packaging in Kate

The other day, I noted that the emacs integration with debputy stopped working. After debugging for a while, I realized that emacs no longer sent the didOpen notification that is expected of it, which confused debputy. At this point, I was already several hours into the debugging and I noted there was some discussions on debian-devel about emacs and byte compilation not working. So I figured I would shelve the emacs problem for now. But I needed an LSP capable editor and with my vi skills leaving much to be desired, I skipped out on vim-youcompleteme. Instead, I pulled out kate, which I had not been using for years. It had LSP support, so it would fine, right? Well, no. Turns out that debputy LSP support had some assumptions that worked for emacs but not kate. Plus once you start down the rabbit hole, you stumble on things you missed previously.
Getting started First order of business was to tell kate about debputy. Conveniently, kate has a configuration tab for adding language servers in a JSON format right next to the tab where you can see its configuration for built-in LSP (also in JSON format9. So a quick bit of copy-paste magic and that was done. Yesterday, I opened an MR against upstream to have the configuration added (https://invent.kde.org/utilities/kate/-/merge_requests/1748) and they already merged it. Today, I then filed a wishlist against kate in Debian to have the Debian maintainers cherry-pick it, so it works out of the box for Trixie (https://bugs.debian.org/1099876). So far so good.
Inlay hint woes Since July (2024), debputy has support for Inlay hints. They are basically small bits of text that the LSP server can ask the editor to inject into the text to provide hints to the reader. Typically, you see them used to provide typing hints, where the editor or the underlying LSP server has figured out the type of a variable or expression that you did not explicitly type. Another common use case is to inject the parameter name for positional arguments when calling a function, so the user do not have to count the position to figure out which value is passed as which parameter. In debputy, I have been using the Inlay hints to show inherited fields in debian/control. As an example, if you have a definition like:
Source: foo-src
Section: devel
Priority: optional
Package: foo-bin
Architecture: any
Then foo-bin inherits the Section and Priority field since it does not supply its own. Previously, debputy would that by injecting the fields themselves and their value just below the Package field as if you had typed them out directly. The editor always renders Inlay hints distinctly from regular text, so there was no risk of confusion and it made the text look like a valid debian/control file end to end. The result looked something like:
Source: foo-src
Section: devel
Priority: optional
Package: foo-bin
Section: devel
Priority: optional
Architecture: any
With the second instances of Section and Priority being rendered differently than its surrendering (usually faded or colorlessly). Unfortunately, kate did not like injecting Inlay hints with a newline in them, which was needed for this trick. Reading into the LSP specs, it says nothing about multi-line Inlay hints being a thing and I figured I would see this problem again with other editors if I left it be. I ended up changing the Inlay hints to be placed at the end of the Package field and then included surrounding () for better visuals. So now, it looks like:
Source: foo-src
Section: devel
Priority: optional
Package: foo-bin  (Section: devel)  (Priority: optional)
Architecture: any
Unfortunately, it is no longer 1:1 with the underlying syntax which I liked about the previous one. But it works in more editors and is still explicit. I also removed the Inlay hint for the Homepage field. It takes too much space and I have yet to meet someone missing it in the binary stanza. If you have any better ideas for how to render it, feel free to reach out to me.
Spurious completion and hover As I was debugging the Inlay hints, I wanted to do a quick restart of debputy after each fix. Then I would trigger a small change to the document to ensure kate would request an update from debputy to render the Inlay hints with the new code. The full outgoing payloads are sent via the logs to the client, so it was really about minimizing which LSP requests are sent to debputy. Notably, two cases would flood the log:
  • Completion requests. These are triggered by typing anything at all and since I wanted to a change, I could not avoid this. So here it was about making sure there would be nothing to complete, so the result was a small as possible.
  • Hover doc requests. These are triggered by mouse hovering over field, so this was mostly about ensuring my mouse movement did not linger over any field on the way between restarting the LSP server and scrolling the log in kate.
In my infinite wisdom, I chose to make a comment line where I would do the change. I figured it would neuter the completion requests completely and it should not matter if my cursor landed on the comment as there would be no hover docs for comments either. Unfortunately for me, debputy would ignore the fact that it was on a comment line. Instead, it would find the next field after the comment line and try to complete based on that. Normally you do not see this, because the editor correctly identifies that none of the completion suggestions start with a \#, so they are all discarded. But it was pretty annoying for the debugging, so now debputy has been told to explicitly stop these requests early on comment lines.
Hover docs for packages I added a feature in debputy where you can hover over package names in your relationship fields (such as Depends) and debputy will render a small snippet about it based on data from your local APT cache. This doc is then handed to the editor and tagged as markdown provided the editor supports markdown rendering. Both emacs and kate support markdown. However, not all markdown renderings are equal. Notably, emacs's rendering does not reformat the text into paragraphs. In a sense, emacs rendering works a bit like <pre>...</pre> except it does a bit of fancy rendering inside the <pre>...</pre>. On the other hand, kate seems to convert the markdown to HTML and then throw the result into an HTML render engine. Here it is important to remember that not all newlines are equal in markdown. A Foo<newline>Bar is treated as one "paragraph" (<p>...</p>) and the HTML render happily renders this as single line Foo Bar provided there is sufficient width to do so. A couple of extra newlines made wonders for the kate rendering, but I have a feeling this is not going to be the last time the hover docs will need some tweaking for prettification. Feel free to reach out if you spot a weirdly rendered hover doc somewhere.
Making quickfixes available in kate Quickfixes are treated as generic code actions in the LSP specs. Each code action has a "type" (kind in the LSP lingo), which enables the editor to group the actions accordingly or filter by certain types of code actions. The design in the specs leads to the following flow:
  1. The LSP server provides the editor with diagnostics (there are multiple ways to trigger this, so we will keep this part simple).
  2. The editor renders them to the user and the user chooses to interact with one of them.
  3. The interaction makes the editor asks the LSP server, which code actions are available at that location (optionally with filter to only see quickfixes).
  4. The LSP server looks at the provided range and is expected to return the relevant quickfixes here.
This flow is really annoying from a LSP server writer point of view. When you do the diagnostics (in step 1), you tend to already know what the possible quickfixes would be. The LSP spec authors realized this at some point, so there are two features the editor provides to simplify this.
  1. In the editor request for code actions, the editor is expected to provide the diagnostics that they received from the server. Side note: I cannot quite tell if this is optional or required from the spec.
  2. The editor can provide support for remembering a data member in each diagnostic. The server can then store arbitrary information in that member, which they will see again in the code actions request. Again, provided that the editor supports this optional feature.
All the quickfix logic in debputy so far has hinged on both of these two features. As life would have it, kate provides neither of them. Which meant I had to teach debputy to keep track of its diagnostics on its own. The plus side is that makes it easier to support "pull diagnostics" down the line, since it requires a similar feature. Additionally, it also means that quickfixes are now available in more editors. For consistency, debputy logic is now always used rather than relying on the editor support when present. The downside is that I had to spend hours coming up with and debugging a way to find the diagnostics that overlap with the range provided by the editor. The most difficult part was keeping the logic straight and getting the runes correct for it.
Making the quickfixes actually work With all of that, kate would show the quickfixes for diagnostics from debputy and you could use them too. However, they would always apply twice with suboptimal outcome as a result. The LSP spec has multiple ways of defining what need to be changed in response to activating a code action. In debputy, all edits are currently done via the WorkspaceEdit type. It has two ways of defining the changes. Either via changes or documentChanges with documentChanges being the preferred one if both parties support this. I originally read that as I was allowed to provide both and the editor would pick the one it preferred. However, after seeing kate blindly use both when they are present, I reviewed the spec and it does say "The edit should either provide changes or documentChanges", so I think that one is on me. None of the changes in debputy currently require documentChanges, so I went with just using changes for now despite it not being preferred. I cannot figure out the logic of whether an editor supports documentChanges. As I read the notes for this part of the spec, my understanding is that kate does not announce its support for documentChanges but it clearly uses them when present. Therefore, I decided to keep it simple for now until I have time to dig deeper.
Remaining limitations with kate There is one remaining limitation with kate that I have not yet solved. The kate program uses KSyntaxHighlighting for its language detection, which in turn is the basis for which LSP server is assigned to a given document. This engine does not seem to support as complex detection logic as I hoped from it. Concretely, it either works on matching on an extension / a basename (same field for both cases) or mime type. This combined with our habit in Debian to use extension less files like debian/control vs. debian/tests/control or debian/rules or debian/upstream/metadata makes things awkward a best. Concretely, the syntax engine cannot tell debian/control from debian/tests/control as they use the same basename. Fortunately, the syntax is close enough to work for both and debputy is set to use filename based lookups, so this case works well enough. However, for debian/rules and debian/upstream/metadata, my understanding is that if I assign these in the syntax engine as Debian files, these rules will also trigger for any file named foo.rules or bar.metadata. That seems a bit too broad for me, so I have opted out of that for now. The down side is that these files will not work out of the box with kate for now. The current LSP configuration in kate does not recognize makefiles or YAML either. Ideally, we would assign custom languages for the affected Debian files, so we do not steal the ID from other language servers. Notably, kate has a built-in language server for YAML and debputy does nothing for a generic YAML document. However, adding YAML as a supported language for debputy would cause conflict and regressions for users that are already happy with their generic YAML language server from kate. So there are certainly still work to be done. If you are good with KSyntaxHighlighting and know how to solve some of this, I hope you will help me out.
Changes unrelated to kate While I was working on debputy, I also added some other features that I want to mention.
  1. The debputy lint command will now show related context to diagnostic in its terminal report when such information is available and is from the same file as the diagnostic itself (cross file cases are rendered without related information). The related information is typically used to highlight a source of a conflict. As an example, if you use the same field twice in a stanza of debian/control, then debputy will add a diagnostic to the second occurrence. The related information for that diagnostic would provide the position of the first occurrence. This should make it easier to find the source of the conflict in the cases where debputy provides it. Let me know if you are missing it for certain diagnostics.

  2. The diagnostics analysis of debian/control will now identify and flag simple duplicated relations (complex ones like OR relations are ignored for now). Thanks to Matthias Geiger for suggesting the feature and Otto Kek l inen for reporting a false positive that is now fixed.

Closing I am glad I tested with kate to weed out most of these issues in time before the freeze. The Debian freeze will start within a week from now. Since debputy is a part of the toolchain packages it will be frozen from there except for important bug fixes.

8 March 2025

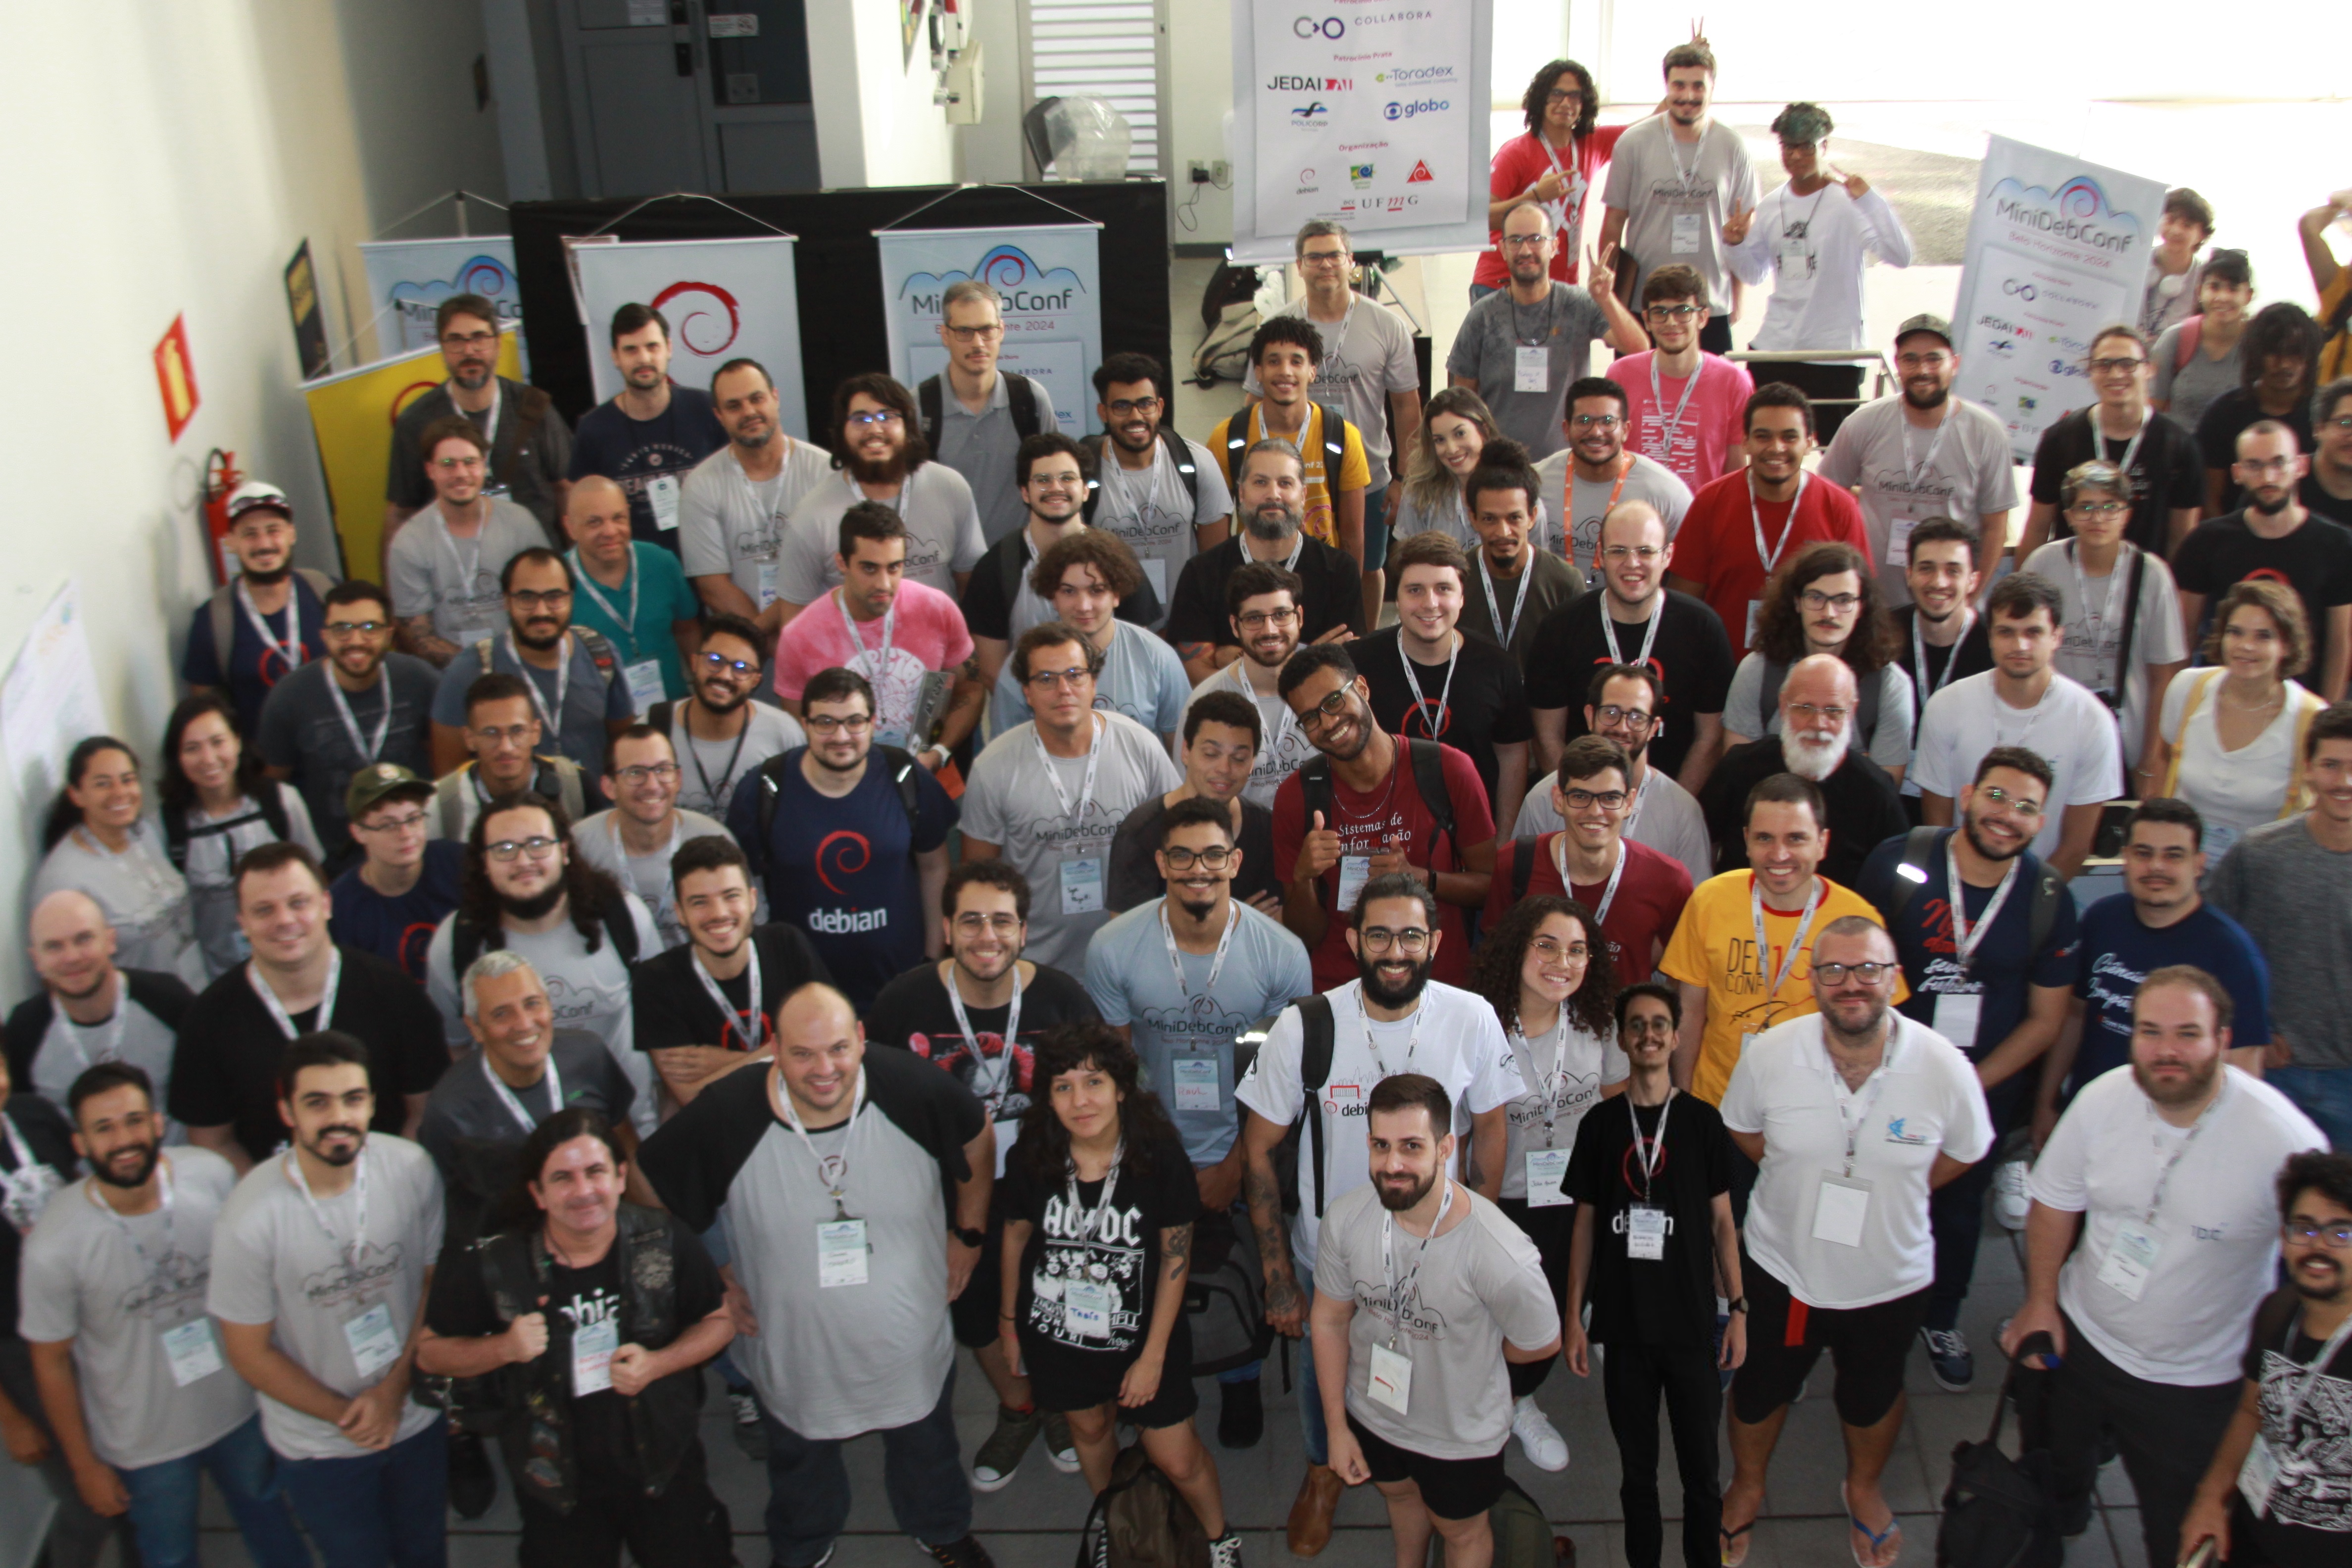
Debian Brasil: MiniDebConf Belo Horizonte 2024 - a brief report

From April 27th to 30th, 2024, MiniDebConf Belo Horizonte 2024 was held at the Pampulha Campus of UFMG - Federal University of Minas Gerais, in Belo Horizonte city. MiniDebConf BH 2024 banners This was the fifth time that a MiniDebConf (as an exclusive in-person event about Debian) took place in Brazil. Previous editions were in Curitiba (2016, 2017, and 2018), and in Bras lia 2023. We had other MiniDebConfs editions held within Free Software events such as FISL and Latinoware, and other online events. See our event history. Parallel to MiniDebConf, on 27th (Saturday) FLISOL - Latin American Free Software Installation Festival took place. It's the largest event in Latin America to promote Free Software, and It has been held since 2005 simultaneously in several cities. MiniDebConf Belo Horizonte 2024 was a success (as were previous editions) thanks to the participation of everyone, regardless of their level of knowledge about Debian. We value the presence of both beginner users who are familiarizing themselves with the system and the official project developers. The spirit of welcome and collaboration was present during all the event. MiniDebConf BH 2024 flisol 2024 edition numbers During the four days of the event, several activities took place for all levels of users and collaborators of the Debian project. The official schedule was composed of: MiniDebConf BH 2024 palestra The final numbers for MiniDebConf Belo Horizonte 2024 show that we had a record number of participants. Of the 224 participants, 15 were official Brazilian contributors, 10 being DDs (Debian Developers) and 05 (Debian Maintainers), in addition to several unofficial contributors. The organization was carried out by 14 people who started working at the end of 2023, including Prof. Lo c Cerf from the Computing Department who made the event possible at UFMG, and 37 volunteers who helped during the event. As MiniDebConf was held at UFMG facilities, we had the help of more than 10 University employees. See the list with the names of people who helped in some way in organizing MiniDebConf Belo Horizonte 2024. The difference between the number of people registered and the number of attendees in the event is probably explained by the fact that there is no registration fee, so if the person decides not to go to the event, they will not suffer financial losses. The 2024 edition of MiniDebconf Belo Horizonte was truly grand and shows the result of the constant efforts made over the last few years to attract more contributors to the Debian community in Brazil. With each edition the numbers only increase, with more attendees, more activities, more rooms, and more sponsors/supporters. MiniDebConf BH 2024 grupo
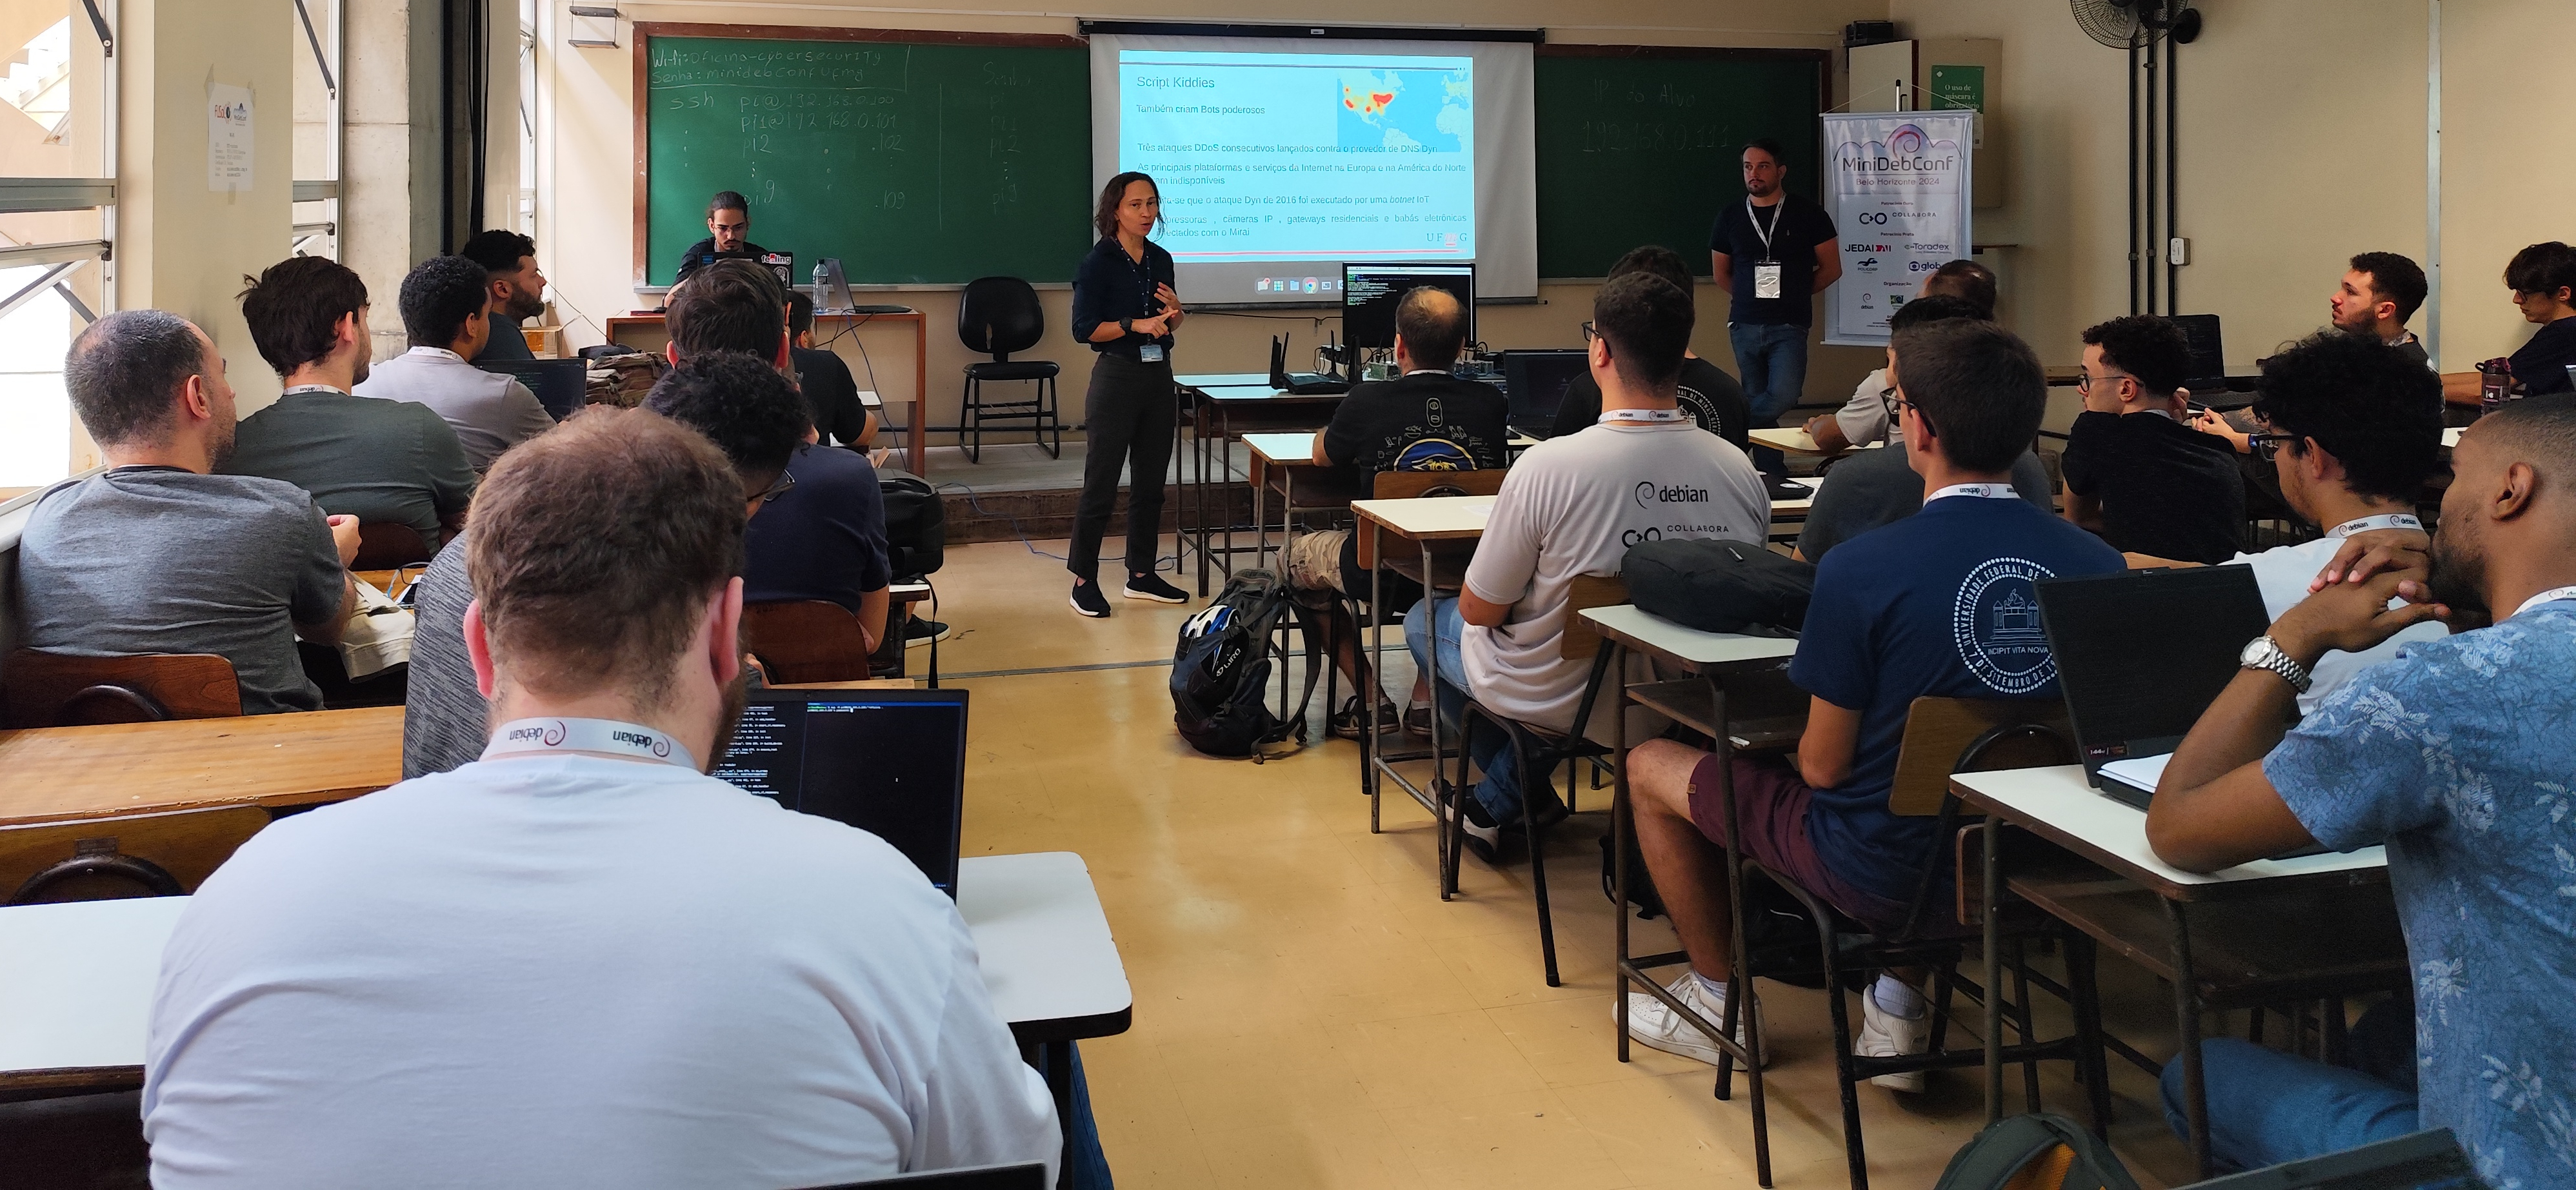
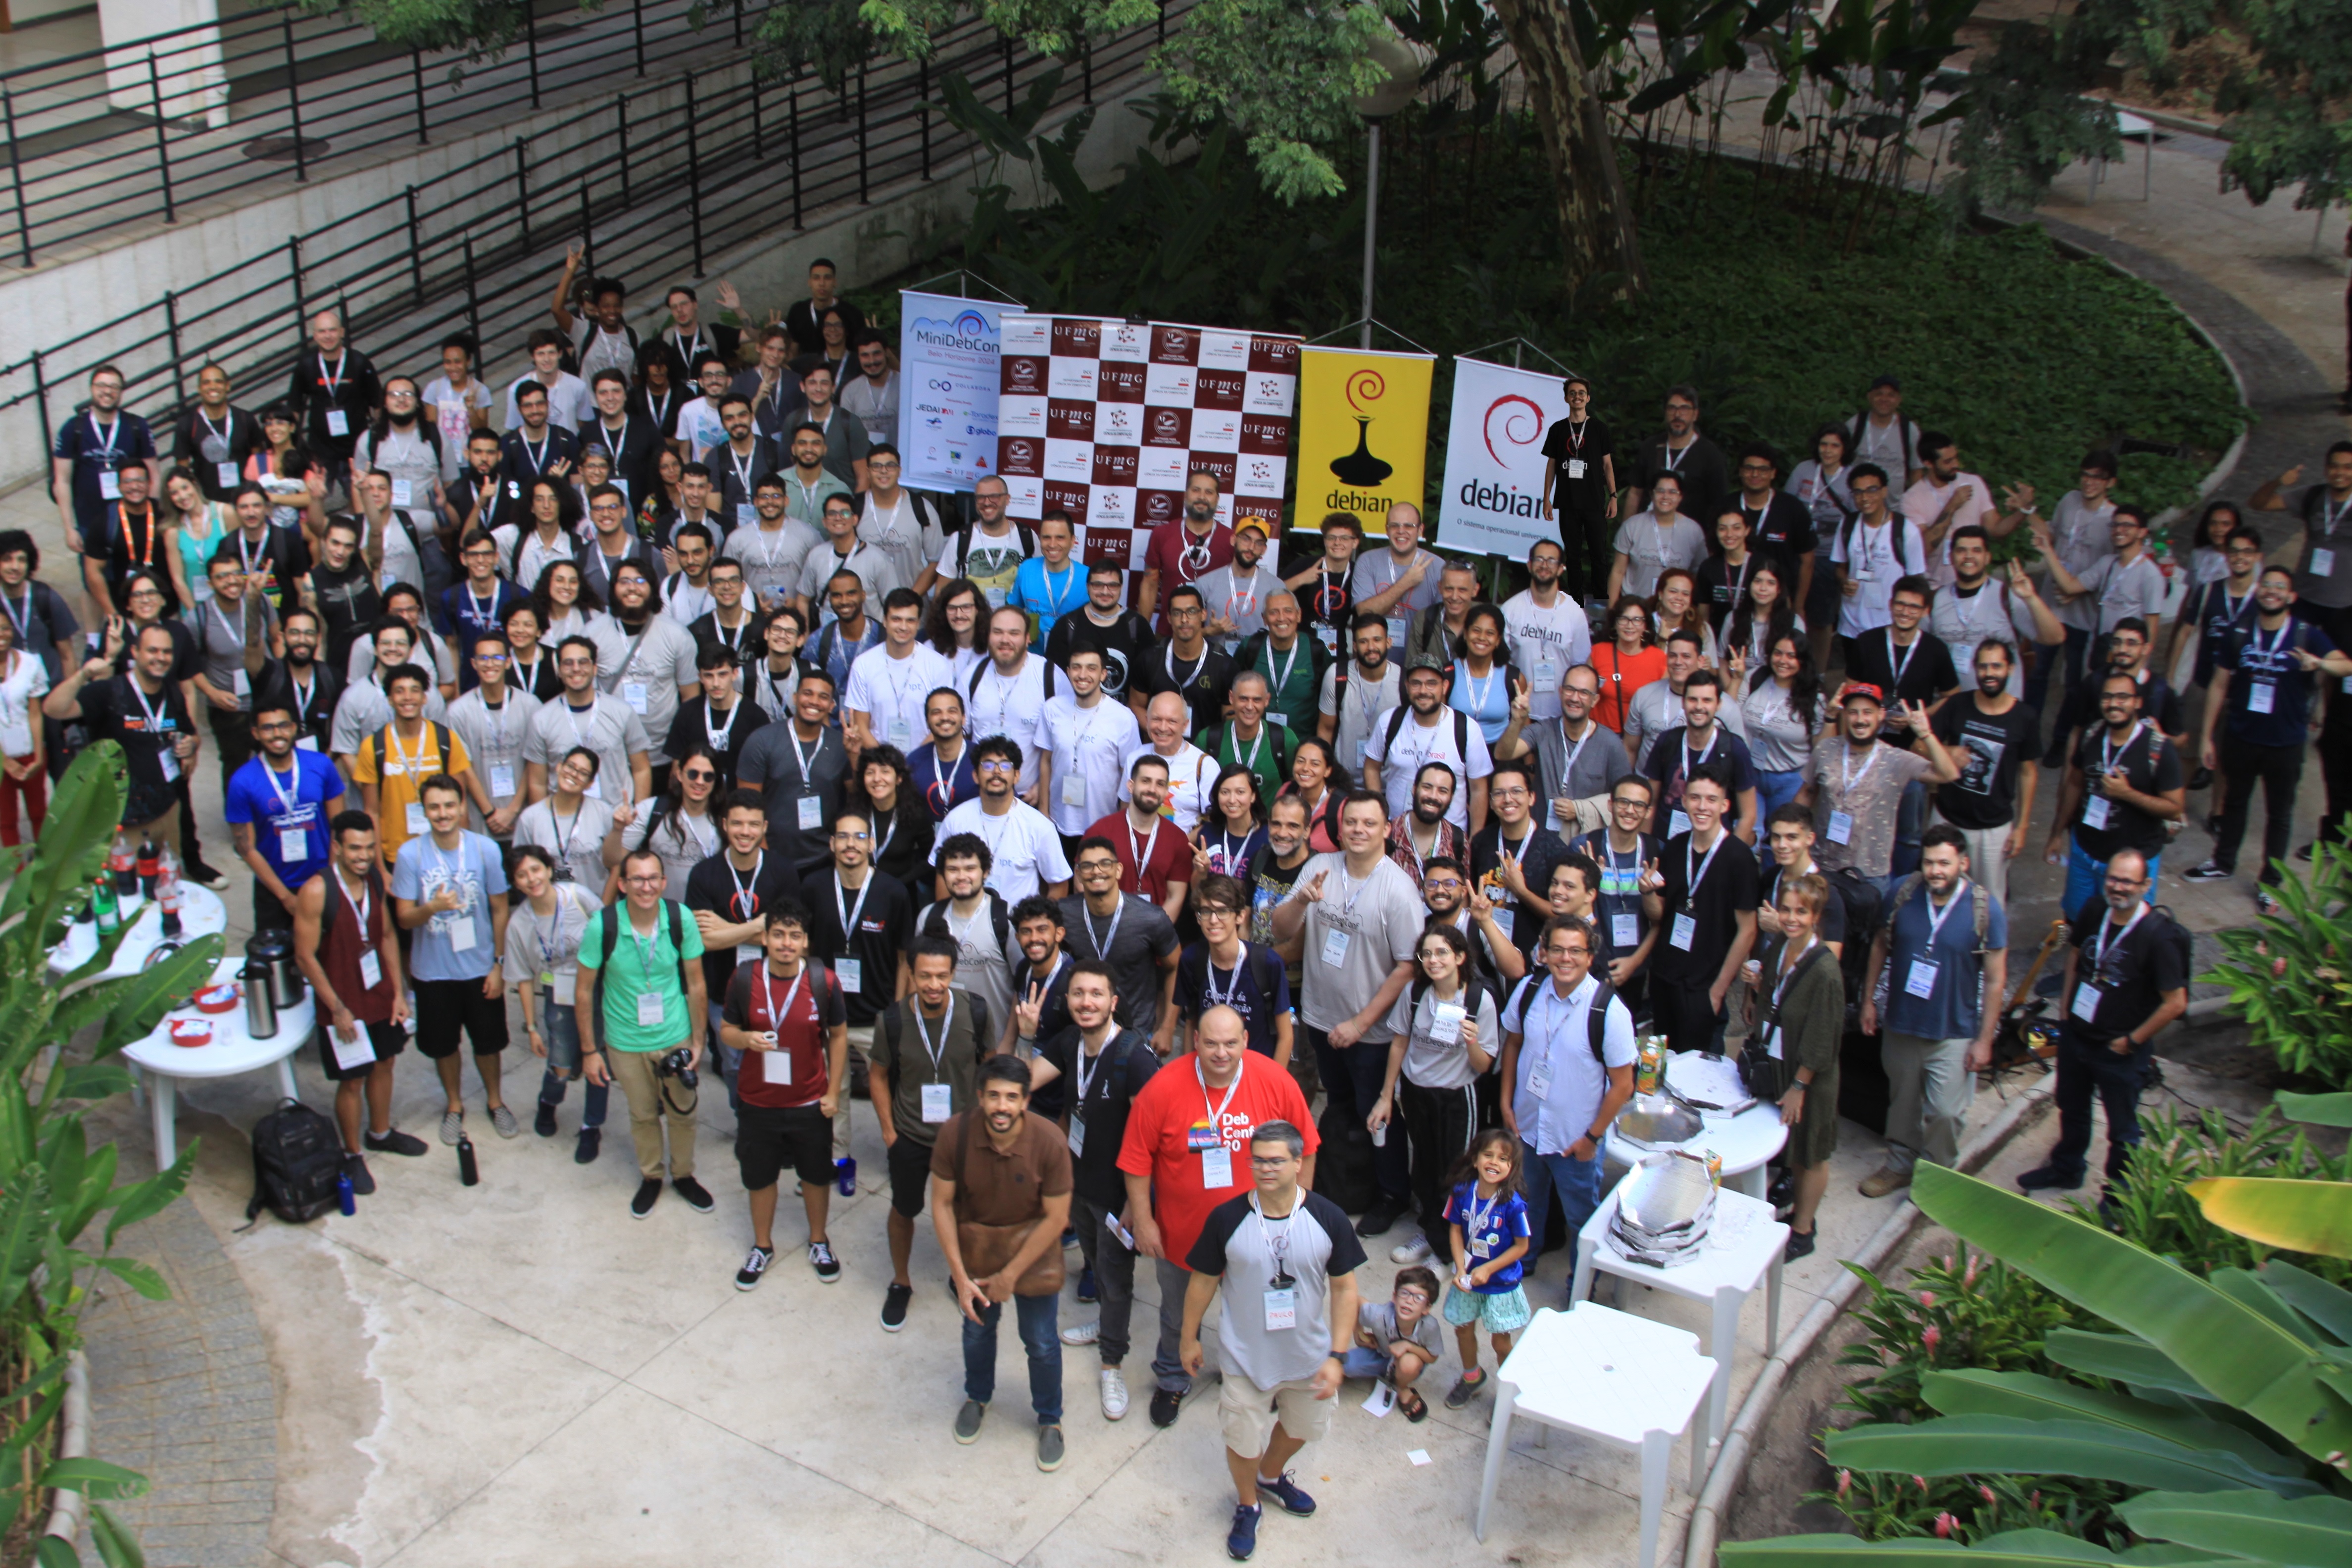
MiniDebConf BH 2024 grupo Activities The MiniDebConf schedule was intense and diverse. On the 27th, 29th and 30th (Saturday, Monday and Tuesday) we had talks, discussions, workshops and many practical activities. MiniDebConf BH 2024 palestra On the 28th (Sunday), the Day Trip took place, a day dedicated to sightseeing around the city. In the morning we left the hotel and went, on a chartered bus, to the Belo Horizonte Central Market. People took the opportunity to buy various things such as cheeses, sweets, cacha as and souvenirs, as well as tasting some local foods. MiniDebConf BH 2024 mercado After a 2-hour tour of the Market, we got back on the bus and hit the road for lunch at a typical Minas Gerais food restaurant. MiniDebConf BH 2024 palestra With everyone well fed, we returned to Belo Horizonte to visit the city's main tourist attraction: Lagoa da Pampulha and Capela S o Francisco de Assis, better known as Igrejinha da Pampulha. MiniDebConf BH 2024 palestra We went back to the hotel and the day ended in the hacker space that we set up in the events room for people to chat, packaging, and eat pizzas. MiniDebConf BH 2024 palestra Crowdfunding For the third time we ran a crowdfunding campaign and it was incredible how people contributed! The initial goal was to raise the amount equivalent to a gold tier of R$ 3,000.00. When we reached this goal, we defined a new one, equivalent to one gold tier + one silver tier (R$ 5,000.00). And again we achieved this goal. So we proposed as a final goal the value of a gold + silver + bronze tiers, which would be equivalent to R$ 6,000.00. The result was that we raised R$7,239.65 (~ USD 1,400) with the help of more than 100 people! Thank you very much to the people who contributed any amount. As a thank you, we list the names of the people who donated. MiniDebConf BH 2024 doadores Food, accommodation and/or travel grants for participants Each edition of MiniDebConf brought some innovation, or some different benefit for the attendees. In this year's edition in Belo Horizonte, as with DebConfs, we offered bursaries for food, accommodation and/or travel to help those people who would like to come to the event but who would need some kind of help. In the registration form, we included the option for the person to request a food, accommodation and/or travel bursary, but to do so, they would have to identify themselves as a contributor (official or unofficial) to Debian and write a justification for the request. Number of people benefited: The food bursary provided lunch and dinner every day. The lunches included attendees who live in Belo Horizonte and the region. Dinners were paid for attendees who also received accommodation and/or travel. The accommodation was held at the BH Jaragu Hotel. And the travels included airplane or bus tickets, or fuel (for those who came by car or motorbike). Much of the money to fund the bursaries came from the Debian Project, mainly for travels. We sent a budget request to the former Debian leader Jonathan Carter, and He promptly approved our request. In addition to this event budget, the leader also approved individual requests sent by some DDs who preferred to request directly from him. The experience of offering the bursaries was really good because it allowed several people to come from other cities. MiniDebConf BH 2024 grupo Photos and videos You can watch recordings of the talks at the links below: Thanks We would like to thank all the attendees, organizers, volunteers, sponsors and supporters who contributed to the success of MiniDebConf Belo Horizonte 2024. MiniDebConf BH 2024 grupo Sponsors Gold: Silver: Bronze: Organizers
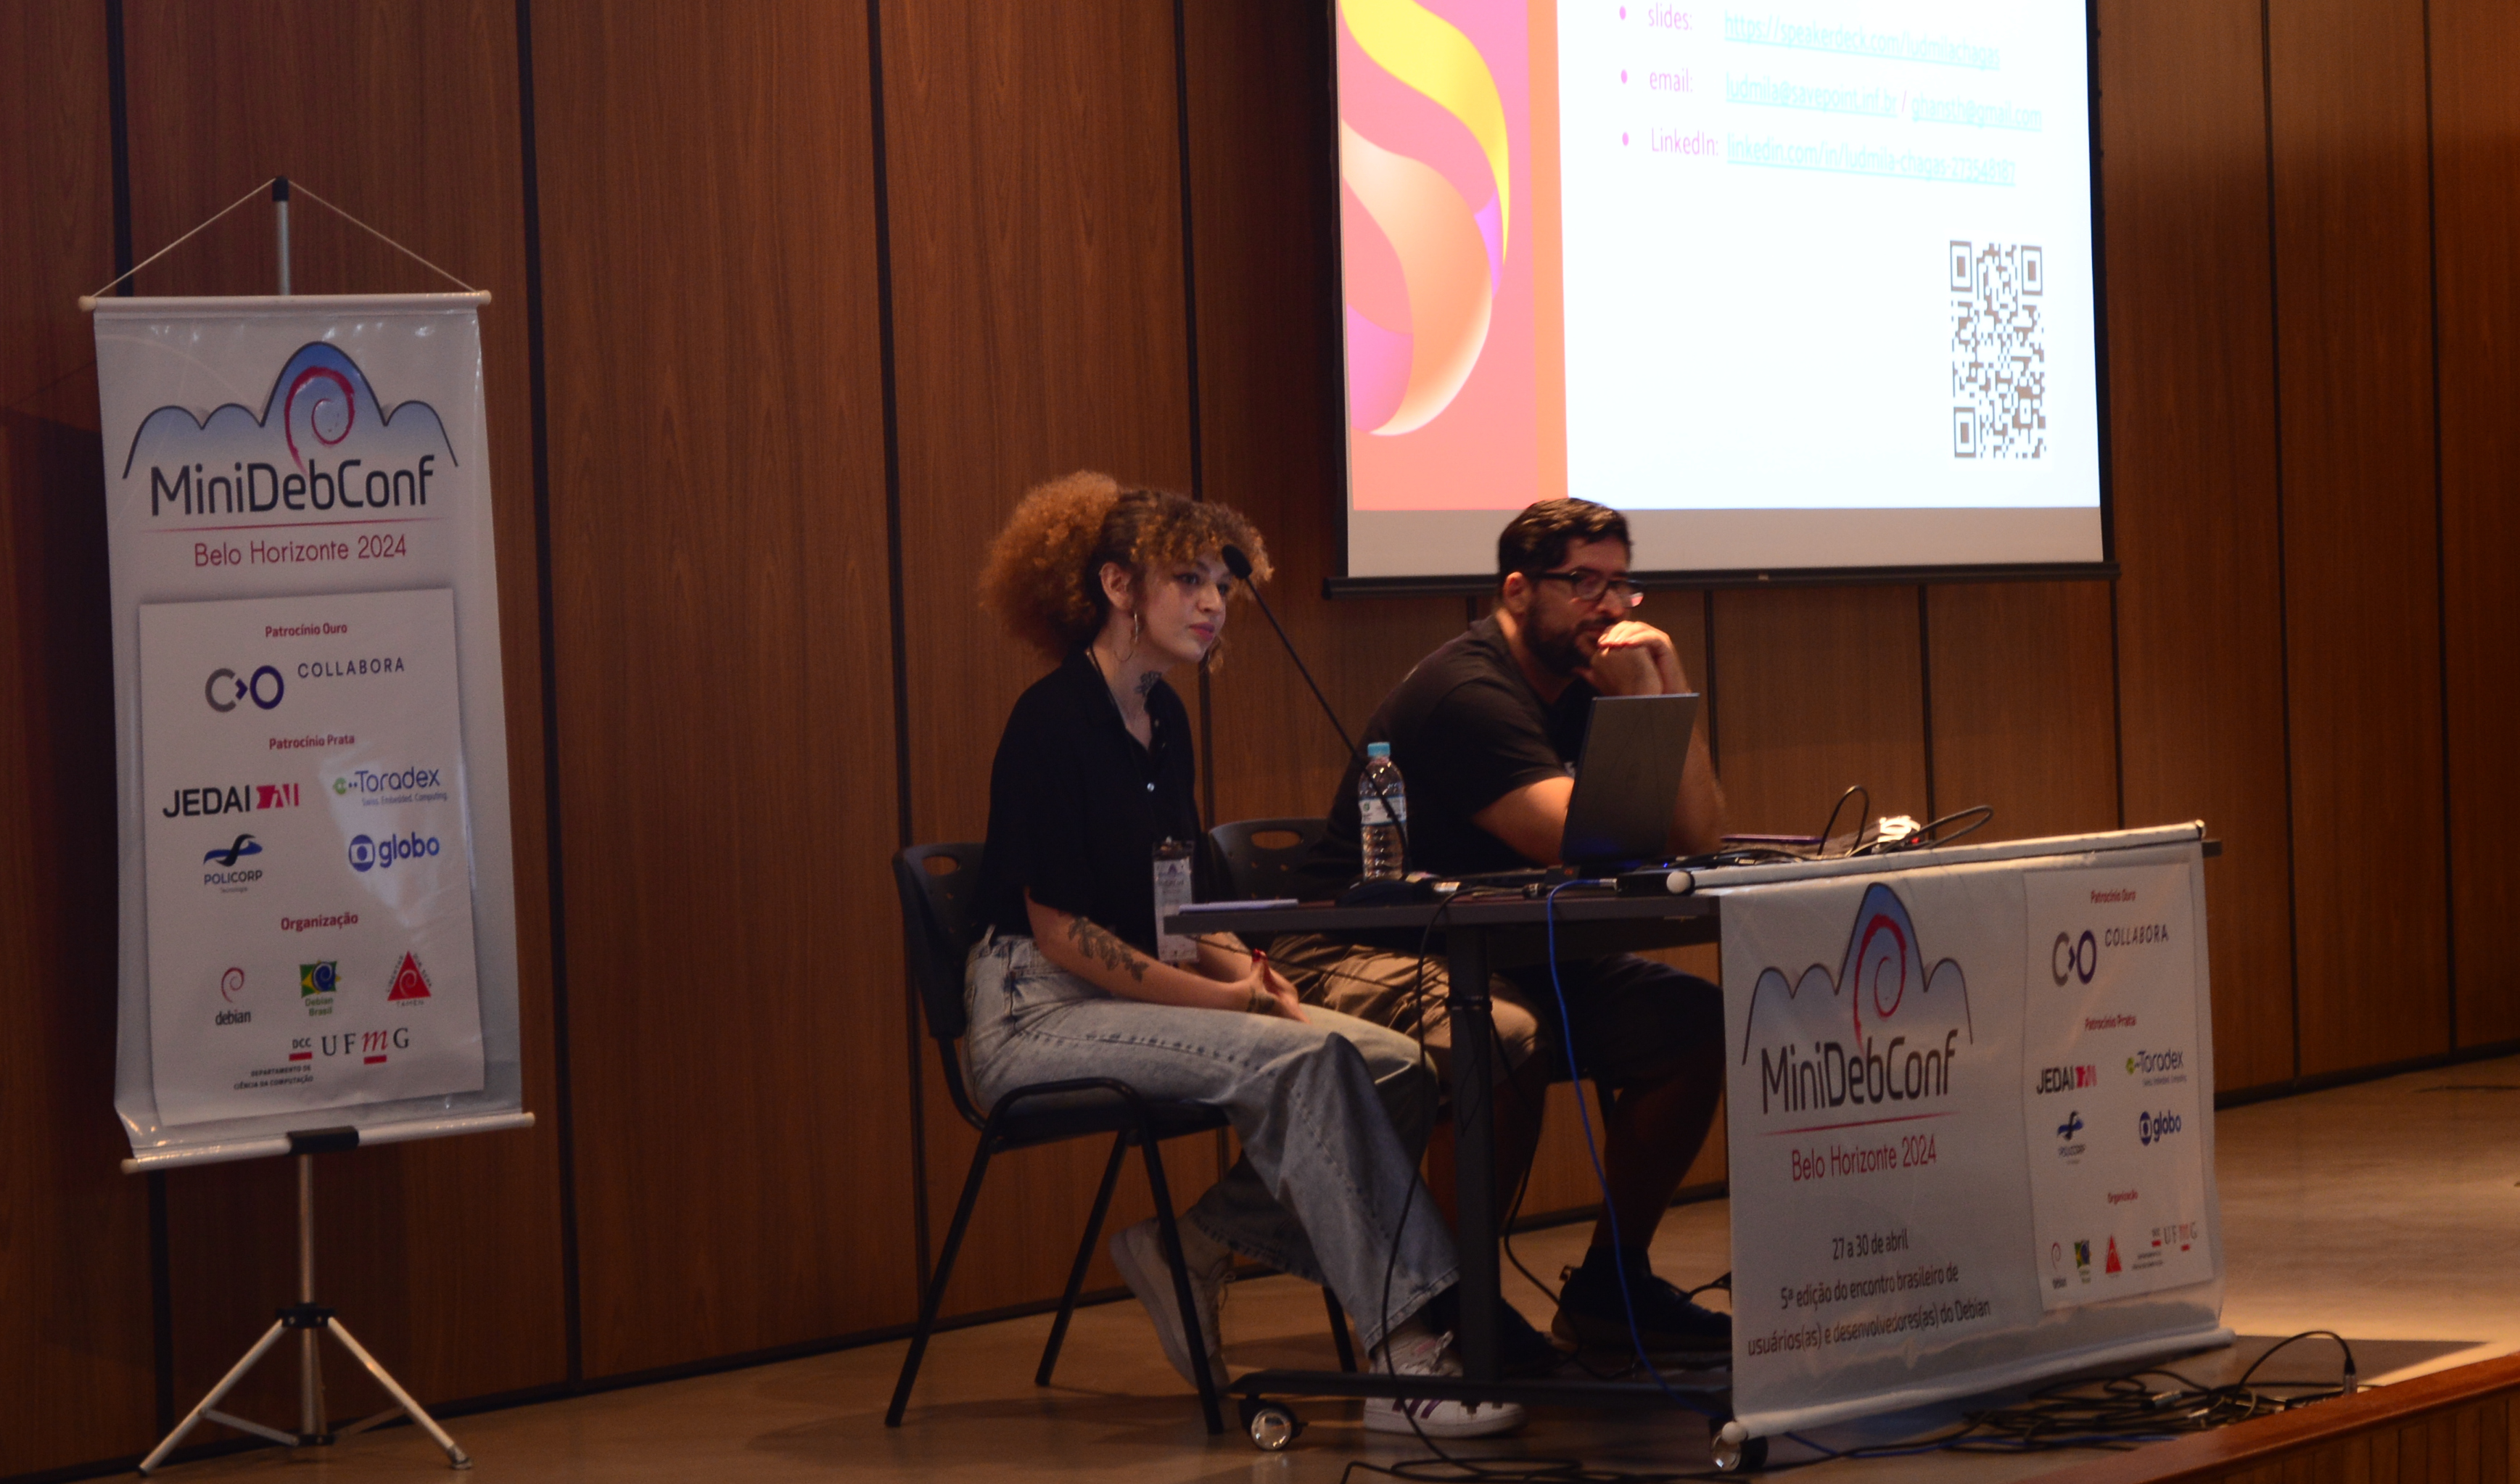
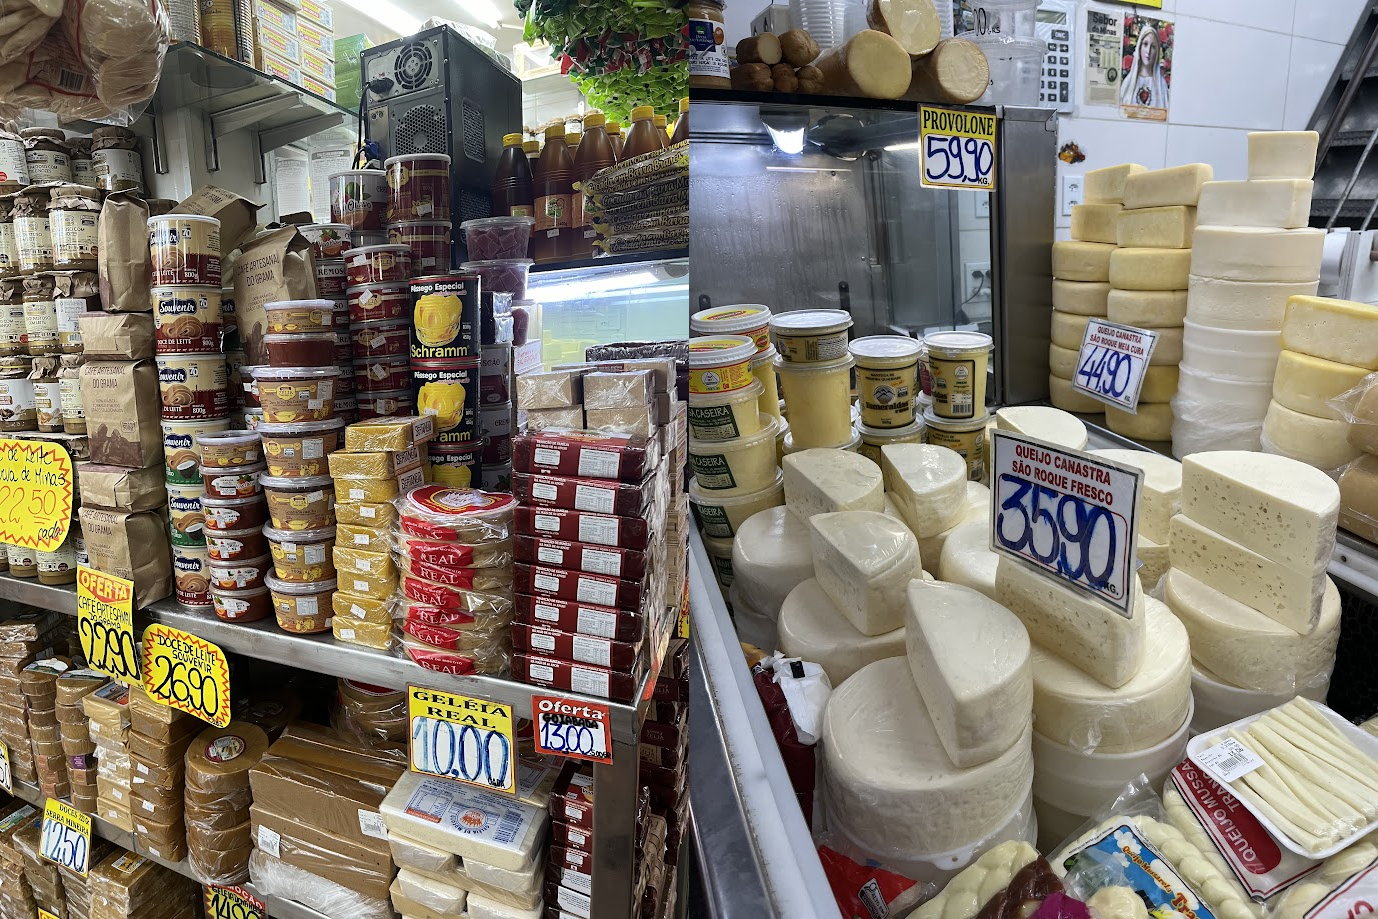
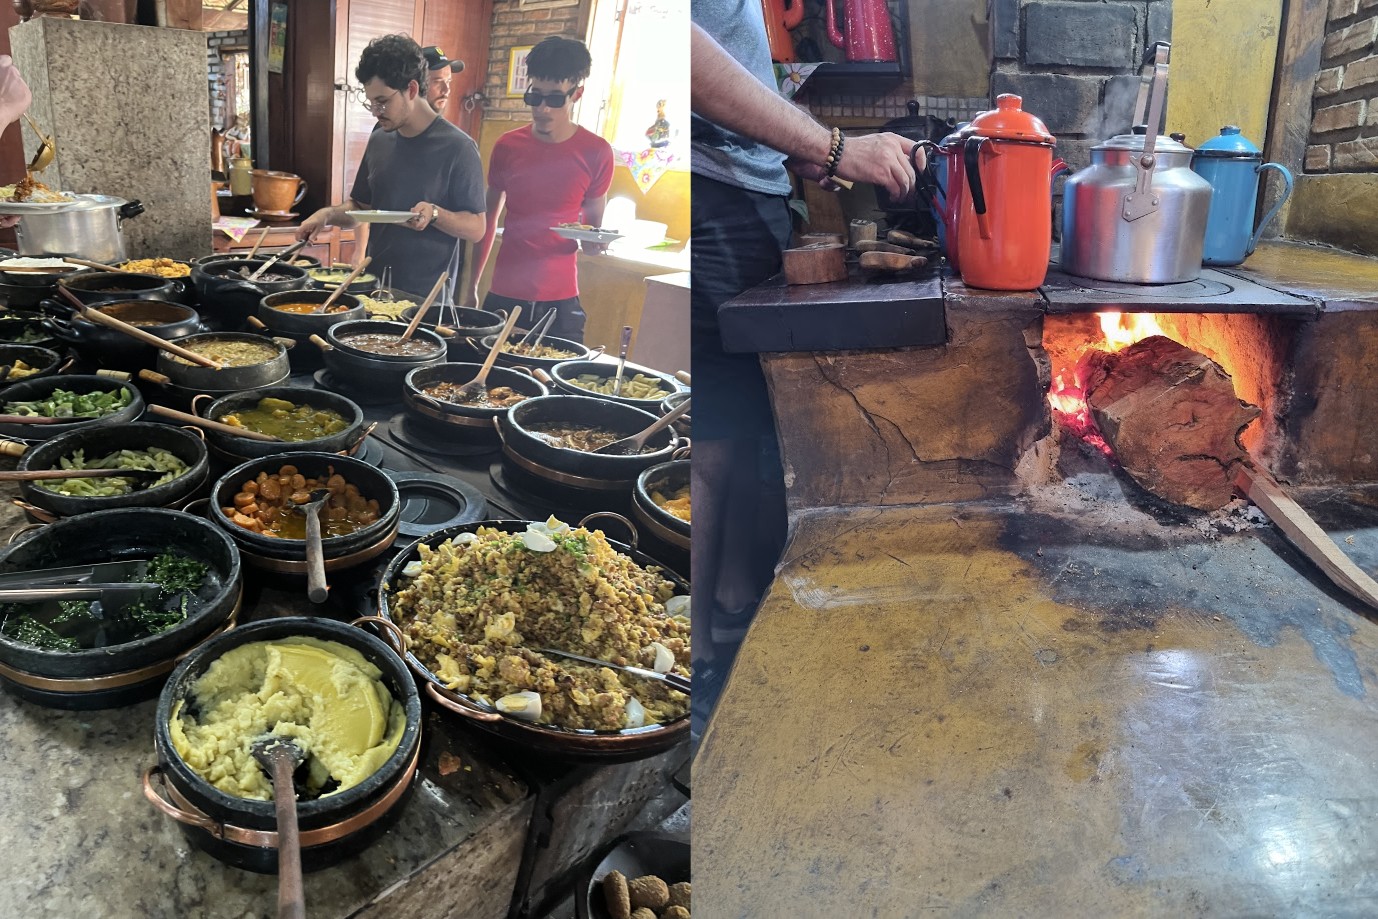
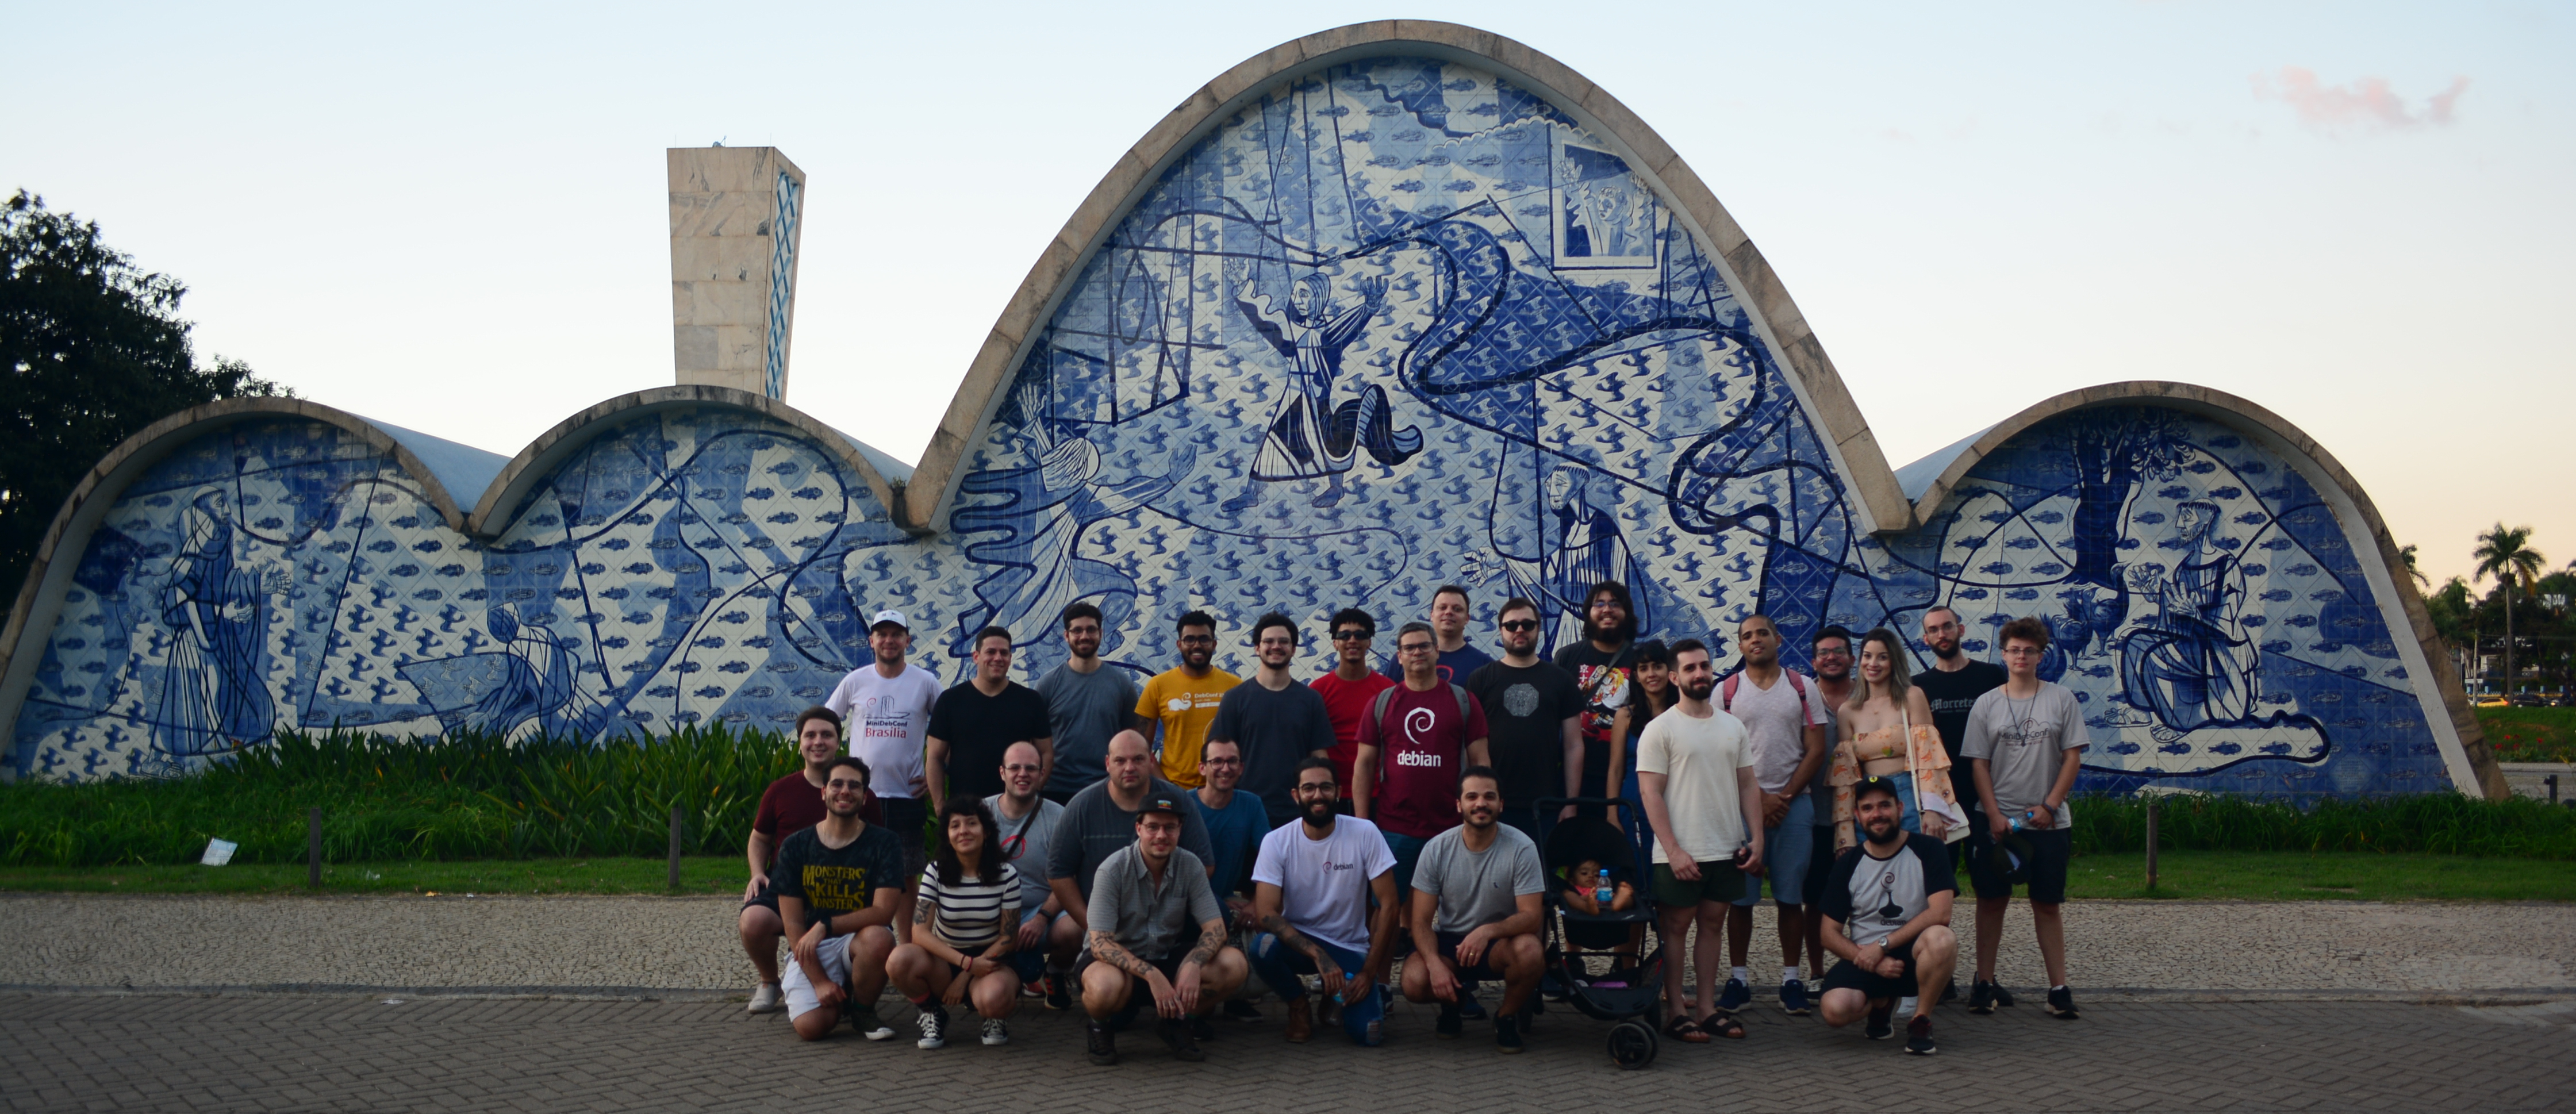
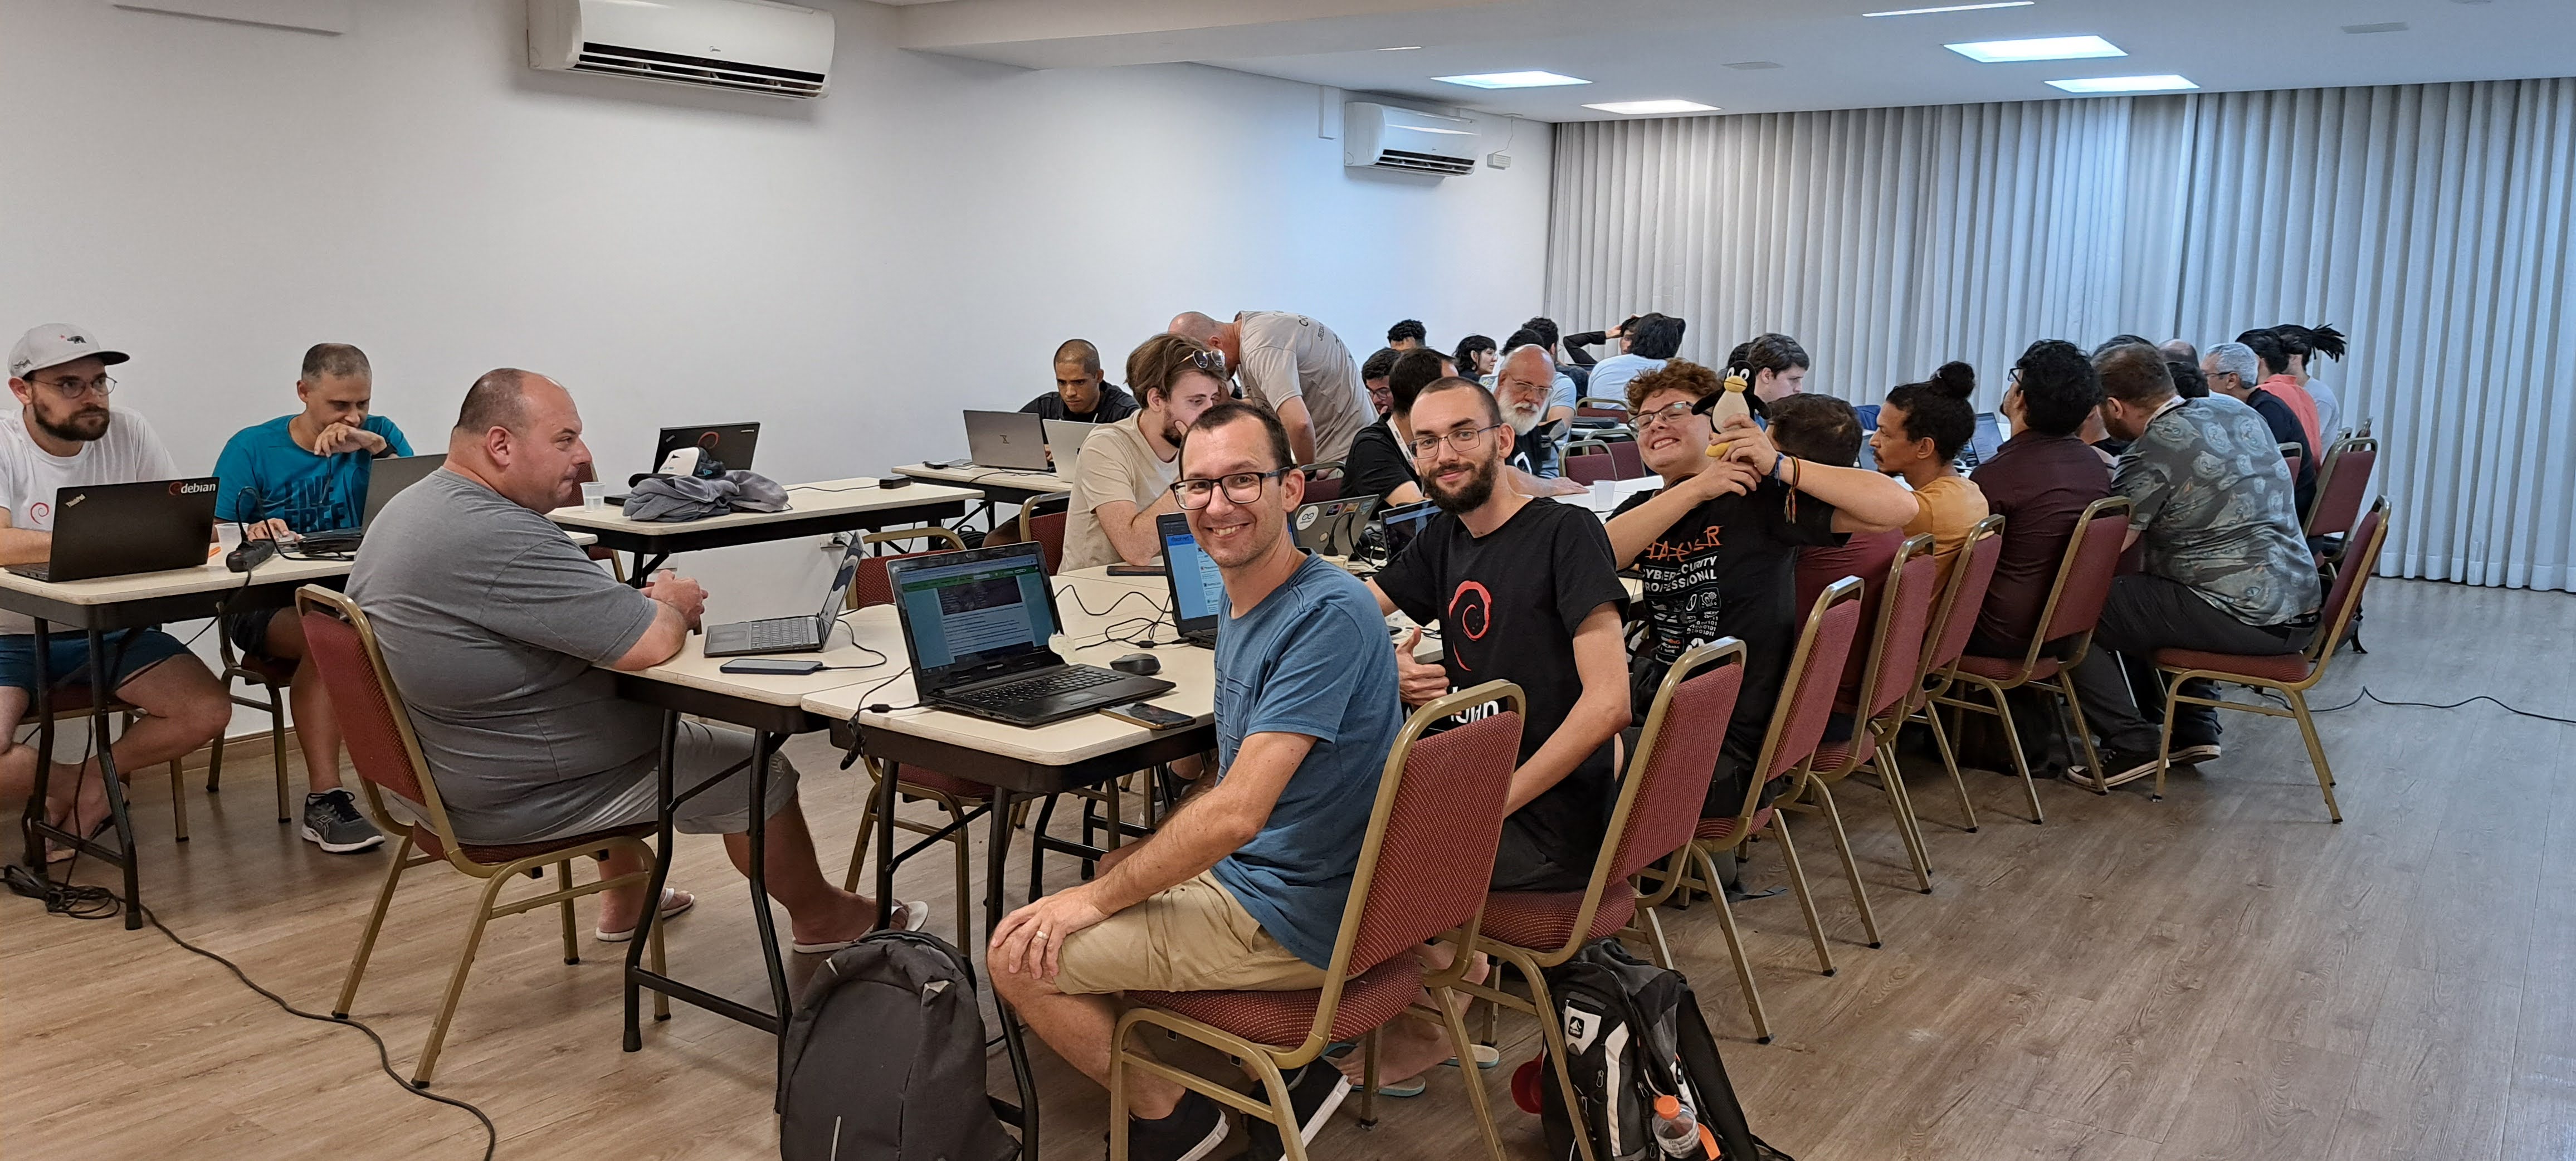
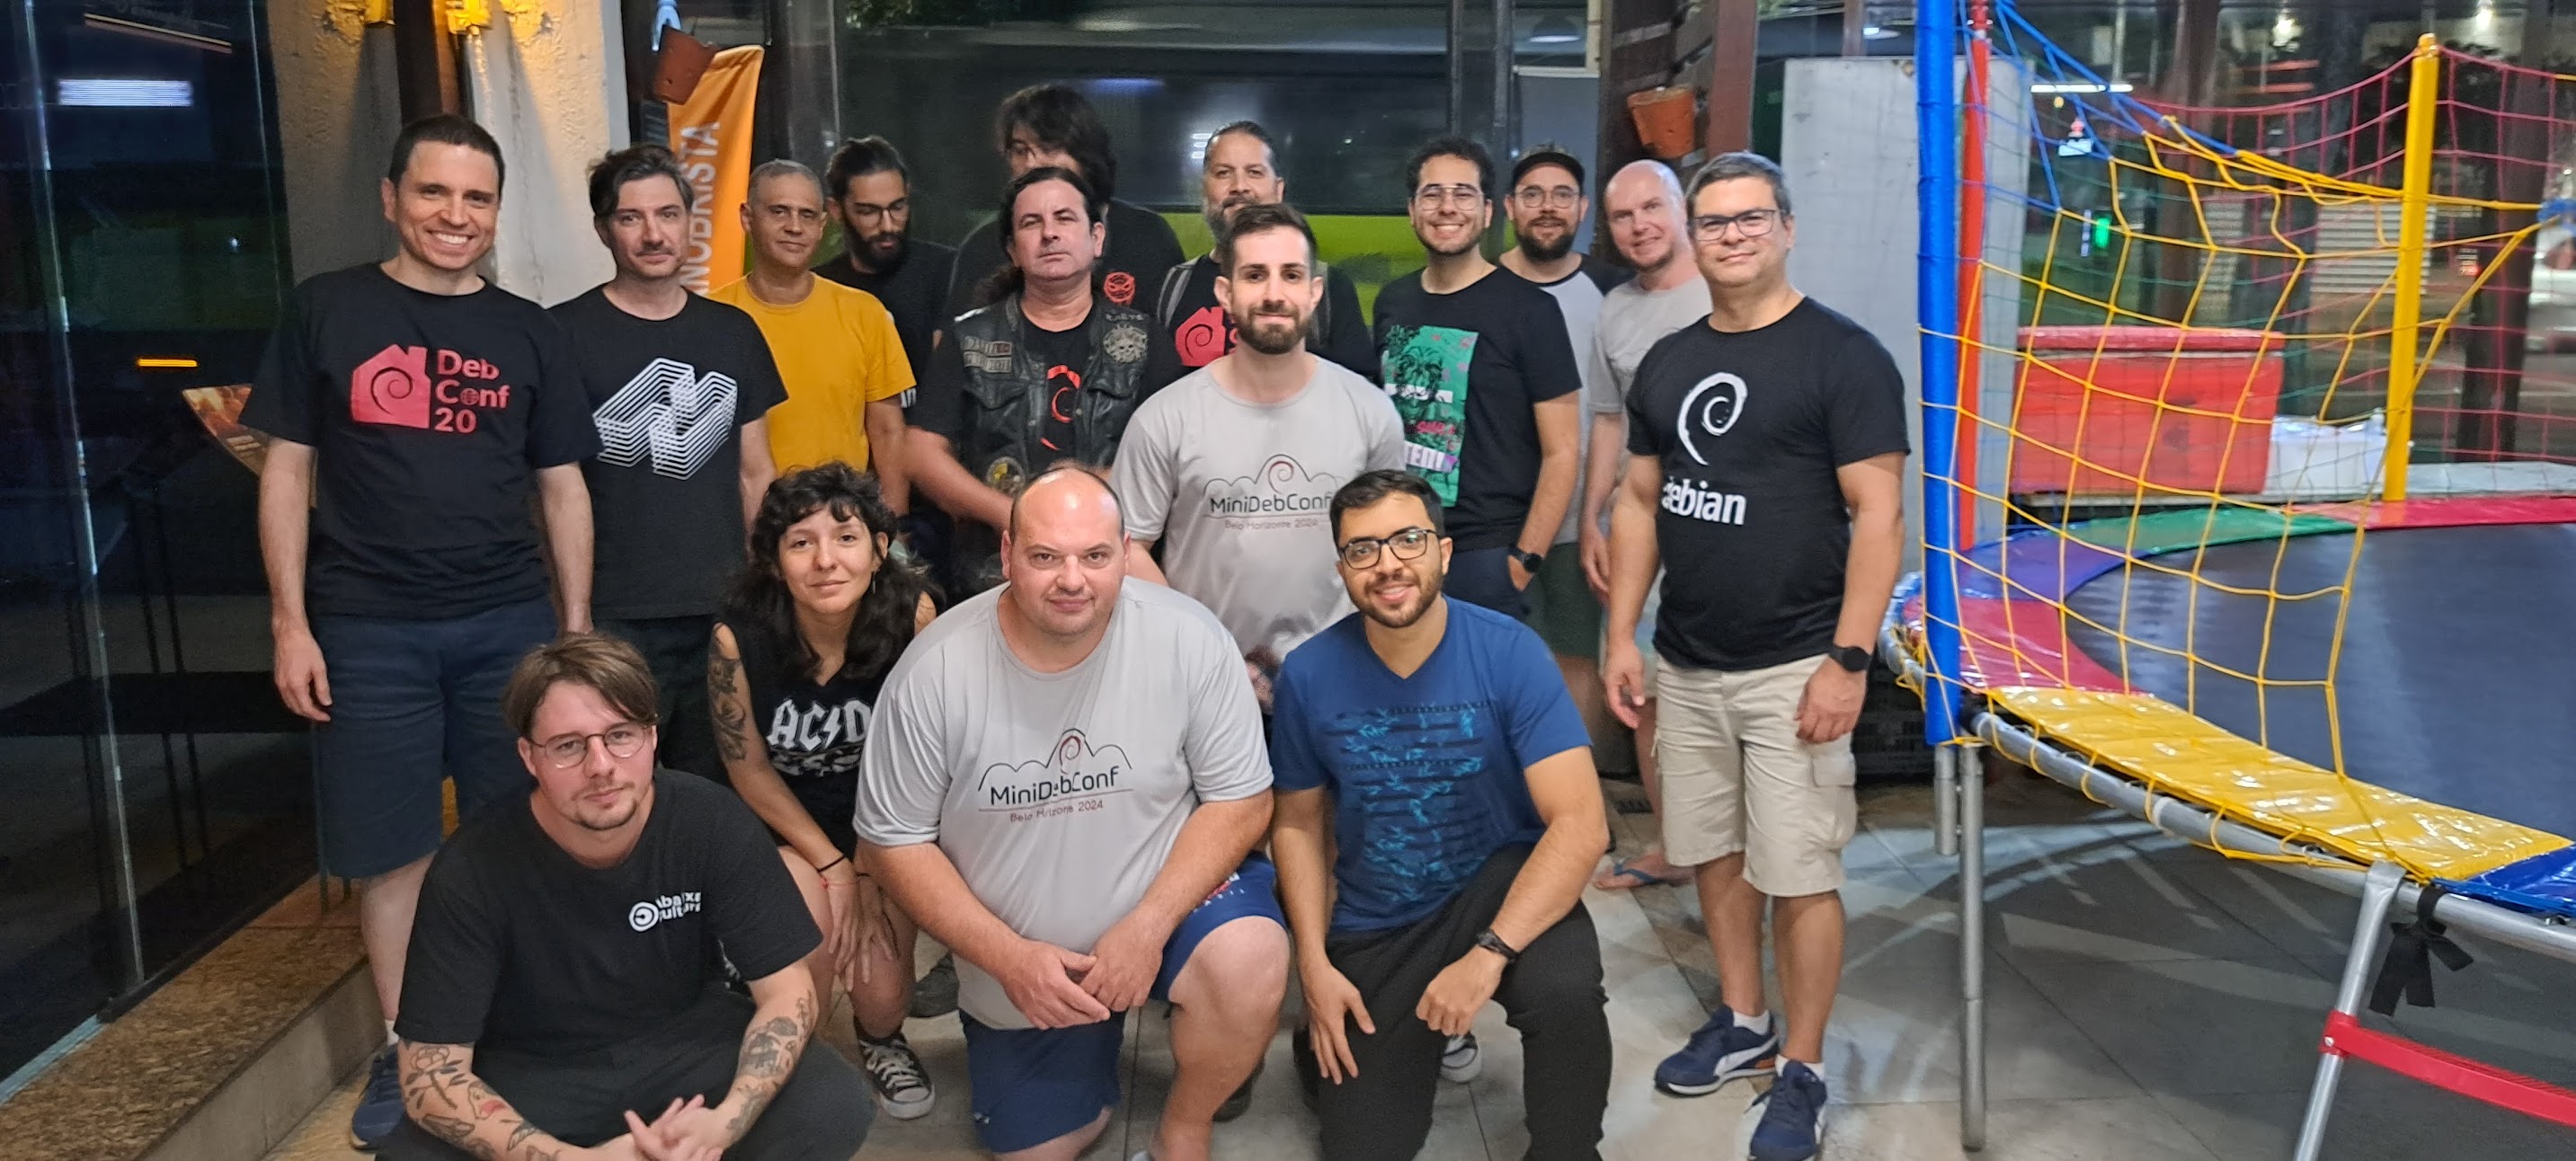
Vincent Bernat: Auto-expanding aliases in Zsh

To avoid needless typing, the fish shell features command abbreviations to expand some words after pressing space. We can emulate such a feature with Zsh:
# Definition of abbrev-alias for auto-expanding aliases
typeset -ga _vbe_abbrevations
abbrev-alias()  
    alias $1
    _vbe_abbrevations+=($ 1%%\=* )
 
_vbe_zle-autoexpand()  
    local -a words; words=($ (z)LBUFFER )
    if (( $  #_vbe_abbrevations[(r)$ words[-1] ]  )); then
        zle _expand_alias
    fi
    zle magic-space
 
zle -N _vbe_zle-autoexpand
bindkey -M emacs " " _vbe_zle-autoexpand
bindkey -M isearch " " magic-space
# Correct common typos
(( $+commands[git] )) && abbrev-alias gti=git
(( $+commands[grep] )) && abbrev-alias grpe=grep
(( $+commands[sudo] )) && abbrev-alias suod=sudo
(( $+commands[ssh] )) && abbrev-alias shs=ssh
# Save a few keystrokes
(( $+commands[git] )) && abbrev-alias gls="git ls-files"
(( $+commands[ip] )) &&  
  abbrev-alias ip6='ip -6'
  abbrev-alias ipb='ip -brief'
 
# Hard to remember options
(( $+commands[mtr] )) && abbrev-alias mtrr='mtr -wzbe'
Here is a demo where gls is expanded to git ls-files after pressing space:
Auto-expanding gls to git ls-files
I don t auto-expand all aliases. I keep using regular aliases when slightly modifying the behavior of a command or for well-known abbreviations:
alias df='df -h'
alias du='du -h'
alias rm='rm -i'
alias mv='mv -i'
alias ll='ls -ltrhA'

6 March 2025

Russell Coker: 8k Video Cards

I previously blogged about getting an 8K TV [1]. Now I m working on getting 8K video out for a computer that talks to it. I borrowed an NVidia RTX A2000 card which according to it s specs can do 8K [2] with a mini-DisplayPort to HDMI cable rated at 8K but on both Windows and Linux the two highest resolutions on offer are 3840*2160 (regular 4K) and 4096*2160 which is strange and not useful. The various documents on the A2000 differ on whether it has DisplayPort version 1.4 or 1.4a. According to the DisplayPort Wikipedia page [3] both versions 1.4 and 1.4a have a maximum of HBR3 speed and the difference is what version of DSC (Display Stream Compression [4]) is in use. DSC apparently causes no noticeable loss of quality for movies or games but apparently can be bad for text. According to the DisplayPort Wikipedia page version 1.4 can do 8K uncompressed at 30Hz or 24Hz with high dynamic range. So this should be able to work. My theories as to why it doesn t work are: To get some more input on this issue I posted on Lemmy, here is the Lemmy post [5]. I signed up to lemmy.ml because it was the first one I found that seemed reasonable and was giving away free accounts, I haven t tried any others and can t review it but it seems to work well enough and it s free. It s described as A community of privacy and FOSS enthusiasts, run by Lemmy s developers which is positive, I recommend that everyone who s into FOSS create an account there or some other Lemmy server. My Lemmy post was about what video cards to buy. I was looking at the Gigabyte RX 6400 Eagle 4G as a cheap card from a local store that does 8K, it also does DisplayPort 1.4 so might have the same issues, also apparently FOSS drivers don t support 8K on HDMI because the people who manage HDMI specs are jerks. It s a $200 card at MSY and a bit less on ebay so it s an amount I can afford to risk on a product that might not do what I want, but it seems to have a high probability of getting the same result. The NVidia cards have the option of proprietary drivers which allow using HDMI and there are cards with DisplayPort 1.4 (which can do 8K@30Hz) and HDMI 2.1 (which can do 8K@50Hz). So HDMI is a better option for some cards just based on card output and has the additional benefit of not needing DisplayPort to HDMI conversion. The best option apparently is the Intel cards which do DisplayPort internally and convert to HDMI in hardware which avoids the issue of FOSS drivers for HDMI at 8K. The Intel Arc B580 has nice specs [6], HDMI 2.1a and DisplayPort 2.1 output, 12G of RAM, and being faster than the low end cards like the RX 6400. But the local computer store price is $470 and the ebay price is a bit over $400. If it turns out to not do what I need it still will be a long way from the worst way I ve wasted money on computer gear. But I m still hesitating about this. Any suggestions?

5 March 2025

Reproducible Builds: Reproducible Builds in February 2025

Welcome to the second report in 2025 from the Reproducible Builds project. Our monthly reports outline what we ve been up to over the past month, and highlight items of news from elsewhere in the increasingly-important area of software supply-chain security. As usual, however, if you are interested in contributing to the Reproducible Builds project, please visit our Contribute page on our website. Table of contents:
  1. Reproducible Builds at FOSDEM 2025
  2. Reproducible Builds at PyCascades 2025
  3. Does Functional Package Management Enable Reproducible Builds at Scale?
  4. reproduce.debian.net updates
  5. Upstream patches
  6. Distribution work
  7. diffoscope & strip-nondeterminism
  8. Website updates
  9. Reproducibility testing framework

Reproducible Builds at FOSDEM 2025 Similar to last year s event, there was considerable activity regarding Reproducible Builds at FOSDEM 2025, held on on 1st and 2nd February this year in Brussels, Belgium. We count at least four talks related to reproducible builds. (You can also read our news report from last year s event in which Holger Levsen presented in the main track.)
Jelle van der Waa, Holger Levsen and kpcyrd presented in the Distributions track on A Tale of several distros joining forces for a common goal. In this talk, three developers from two different Linux distributions (Arch Linux and Debian), discuss this goal which is, of course, reproducible builds. The presenters discuss both what is shared and different between the two efforts, touching on the history and future challenges alike. The slides of this talk are available to view, as is the full video (30m02s). The talk was also discussed on Hacker News.
Zbigniew J drzejewski-Szmek presented in the ever-popular Python track a on Rewriting .pyc files for fun and reproducibility, i.e. the bytecode files generated by Python in order to speed up module imports: It s been known for a while that those are not reproducible: on different architectures, the bytecode for exactly the same sources ends up slightly different. The slides of this talk are available, as is the full video (28m32s).
In the Nix and NixOS track, Julien Malka presented on the Saturday asking How reproducible is NixOS: We know that the NixOS ISO image is very close to be perfectly reproducible thanks to reproducible.nixos.org, but there doesn t exist any monitoring of Nixpkgs as a whole. In this talk I ll present the findings of a project that evaluated the reproducibility of Nixpkgs as a whole by mass rebuilding packages from revisions between 2017 and 2023 and comparing the results with the NixOS cache. Unfortunately, no video of the talk is available, but there is a blog and article on the results.
Lastly, Simon Tournier presented in the Open Research track on the confluence of GNU Guix and Software Heritage: Source Code Archiving to the Rescue of Reproducible Deployment. Simon s talk describes design and implementation we came up and reports on the archival coverage for package source code with data collected over five years. It opens to some remaining challenges toward a better open and reproducible research. The slides for the talk are available, as is the full video (23m17s).

Reproducible Builds at PyCascades 2025 Vagrant Cascadian presented at this year s PyCascades conference which was held on February 8th and 9th February in Portland, OR, USA. PyCascades is a regional instance of PyCon held in the Pacific Northwest. Vagrant s talk, entitled Re-Py-Ducible Builds caught the audience s attention with the following abstract:
Crank your Python best practices up to 11 with Reproducible Builds! This talk will explore Reproducible Builds by highlighting issues identified in Python projects, from the simple to the seemingly inscrutable. Reproducible Builds is basically the crazy idea that when you build something, and you build it again, you get the exact same thing or even more important, if someone else builds it, they get the exact same thing too.
More info is available on the talk s page.

Does Functional Package Management Enable Reproducible Builds at Scale? On our mailing list last month, Julien Malka, Stefano Zacchiroli and Th o Zimmermann of T l com Paris in-house research laboratory, the Information Processing and Communications Laboratory (LTCI) announced that they had published an article asking the question: Does Functional Package Management Enable Reproducible Builds at Scale? (PDF). This month, however, Ludovic Court s followed up to the original announcement on our mailing list mentioning, amongst other things, the Guix Data Service and how that it shows the reproducibility of GNU Guix over time, as described in a GNU Guix blog back in March 2024.

reproduce.debian.net updates The last few months have seen the introduction of reproduce.debian.net. Announced first at the recent Debian MiniDebConf in Toulouse, reproduce.debian.net is an instance of rebuilderd operated by the Reproducible Builds project. Powering this work is rebuilderd, our server which monitors the official package repositories of Linux distributions and attempt to reproduce the observed results there. This month, however, Holger Levsen:
  • Split packages that are not specific to any architecture away from amd64.reproducible.debian.net service into a new all.reproducible.debian.net page.
  • Increased the number of riscv64 nodes to a total of 4, and added a new amd64 node added thanks to our (now 10-year sponsor), IONOS.
  • Discovered an issue in the Debian build service where some new incoming build-dependencies do not end up historically archived.
  • Uploaded the devscripts package, incorporating changes from Jochen Sprickerhof to the debrebuild script specifically to fix the handling the Rules-Requires-Root header in Debian source packages.
  • Uploaded a number of Rust dependencies of rebuilderd (rust-libbz2-rs-sys, rust-actix-web, rust-actix-server, rust-actix-http, rust-actix-server, rust-actix-http, rust-actix-web-codegen and rust-time-tz) after they were prepared by kpcyrd :
Jochen Sprickerhof also updated the sbuild package to:
  • Obey requests from the user/developer for a different temporary directory.
  • Use the root/superuser for some values of Rules-Requires-Root.
  • Don t pass --root-owner-group to old versions of dpkg.
and additionally requested that many Debian packages are rebuilt by the build servers in order to work around bugs found on reproduce.debian.net. [ ][[ ][ ]
Lastly, kpcyrd has also worked towards getting rebuilderd packaged in NixOS, and Jelle van der Waa picked up the existing pull request for Fedora support within in rebuilderd and made it work with the existing Koji rebuilderd script. The server is being packaged for Fedora in an unofficial copr repository and in the official repositories after all the dependencies are packaged.

Upstream patches The Reproducible Builds project detects, dissects and attempts to fix as many currently-unreproducible packages as possible. We endeavour to send all of our patches upstream where appropriate. This month, we wrote a large number of such patches, including:

Distribution work There as been the usual work in various distributions this month, such as: In Debian, 17 reviews of Debian packages were added, 6 were updated and 8 were removed this month adding to our knowledge about identified issues.
Fedora developers Davide Cavalca and Zbigniew J drzejewski-Szmek gave a talk on Reproducible Builds in Fedora (PDF), touching on SRPM-specific issues as well as the current status and future plans.
Thanks to an investment from the Sovereign Tech Agency, the FreeBSD project s work on unprivileged and reproducible builds continued this month. Notable fixes include:
The Yocto Project has been struggling to upgrade to the latest Go and Rust releases due to reproducibility problems in the newer versions. Hongxu Jia tracked down the issue with Go which meant that the project could upgrade from the 1.22 series to 1.24, with the fix being submitted upstream for review (see above). For Rust, however, the project was significantly behind, but has made recent progress after finally identifying the blocking reproducibility issues. At time of writing, the project is at Rust version 1.82, with patches under review for 1.83 and 1.84 and fixes being discussed with the Rust developers. The project hopes to improve the tests for reproducibility in the Rust project itself in order to try and avoid future regressions. Yocto continues to maintain its ability to binary reproduce all of the recipes in OpenEmbedded-Core, regardless of the build host distribution or the current build path.
Finally, Douglas DeMaio published an article on the openSUSE blog on announcing that the Reproducible-openSUSE (RBOS) Project Hits [Significant] Milestone. In particular:
The Reproducible-openSUSE (RBOS) project, which is a proof-of-concept fork of openSUSE, has reached a significant milestone after demonstrating a usable Linux distribution can be built with 100% bit-identical packages.
This news was also announced on our mailing list by Bernhard M. Wiedemann, who also published another report for openSUSE as well.

diffoscope & strip-nondeterminism diffoscope is our in-depth and content-aware diff utility that can locate and diagnose reproducibility issues. This month, Chris Lamb made the following changes, including preparing and uploading versions 288 and 289 to Debian:
  • Add asar to DIFFOSCOPE_FAIL_TESTS_ON_MISSING_TOOLS in order to address Debian bug #1095057) [ ]
  • Catch a CalledProcessError when calling html2text. [ ]
  • Update the minimal Black version. [ ]
Additionally, Vagrant Cascadian updated diffoscope in GNU Guix to version 287 [ ][ ] and 288 [ ][ ] as well as submitted a patch to update to 289 [ ]. Vagrant also fixed an issue that was breaking reprotest on Guix [ ][ ]. strip-nondeterminism is our sister tool to remove specific non-deterministic results from a completed build. This month version 1.14.1-2 was uploaded to Debian unstable by Holger Levsen.

Website updates There were a large number of improvements made to our website this month, including:

Reproducibility testing framework The Reproducible Builds project operates a comprehensive testing framework running primarily at tests.reproducible-builds.org in order to check packages and other artifacts for reproducibility. In January, a number of changes were made by Holger Levsen, including:
  • reproduce.debian.net-related:
    • Add a helper script to manually schedule packages. [ ][ ][ ][ ][ ]
    • Fix a link in the website footer. [ ]
    • Strip the emojis from package names on the manual rebuilder in order to ease copy-and-paste. [ ]
    • On the various statistics pages, provide the number of affected source packages [ ][ ] as well as provide various totals [ ][ ].
    • Fix graph labels for the various architectures [ ][ ] and make them clickable too [ ][ ][ ].
    • Break the displayed HTML in blocks of 256 packages in order to address rendering issues. [ ][ ]
    • Add monitoring jobs for riscv64 archicture nodes and integrate them elsewhere in our infrastructure. [ ][ ]
    • Add riscv64 architecture nodes. [ ][ ][ ][ ][ ]
    • Update much of the documentation. [ ][ ][ ]
    • Make a number of improvements to the layout and style. [ ][ ][ ][ ][ ][ ][ ]
    • Remove direct links to JSON and database backups. [ ]
    • Drop a Blues Brothers reference from frontpage. [ ]
  • Debian-related:
    • Deal with /boot/vmlinuz* being called vmlinux* on the riscv64 architecture. [ ]
    • Add a new ionos17 node. [ ][ ][ ][ ][ ]
    • Install debian-repro-status on all Debian trixie and unstable jobs. [ ]
  • FreeBSD-related:
    • Switch to run latest branch of FreeBSD. [ ]
  • Misc:
    • Fix /etc/cron.d and /etc/logrotate.d permissions for Jenkins nodes. [ ]
    • Add support for riscv64 architecture nodes. [ ][ ]
    • Grant Jochen Sprickerhof access to the o4 node. [ ]
    • Disable the janitor-setup-worker. [ ][ ]
In addition:
  • kpcyrd fixed the /all/api/ API endpoints on reproduce.debian.net by altering the nginx configuration. [ ]
  • James Addison updated reproduce.debian.net to display the so-called bad reasons hyperlink inline [ ] and merged the Categorized issues links into the Reproduced builds column [ ].
  • Jochen Sprickerhof also made some reproduce.debian.net-related changes, adding support for detecting a bug in the mmdebstrap package [ ] as well as updating some documentation [ ].
  • Roland Clobus continued their work on reproducible live images for Debian, making changes related to new clustering of jobs in openQA. [ ]
And finally, both Holger Levsen [ ][ ][ ] and Vagrant Cascadian performed significant node maintenance. [ ][ ][ ][ ][ ]
If you are interested in contributing to the Reproducible Builds project, please visit our Contribute page on our website. However, you can get in touch with us via:

Otto Kek l inen: Will decentralized social media soon go mainstream?

Featured image of post Will decentralized social media soon go mainstream?In today s digital landscape, social media is more than just a communication tool it is the primary medium for global discourse. Heads of state, corporate leaders and cultural influencers now broadcast their statements directly to the world, shaping public opinion in real time. However, the dominance of a few centralized platforms X/Twitter, Facebook and YouTube raises critical concerns about control, censorship and the monopolization of information. Those who control these networks effectively wield significant power over public discourse. In response, a new wave of distributed social media platforms has emerged, each built on different decentralized protocols designed to provide greater autonomy, censorship resistance and user control. While Wikipedia maintains a comprehensive list of distributed social networking software and protocols, it does not cover recent blockchain-based systems, nor does it highlight which have the most potential for mainstream adoption. This post explores the leading decentralized social media platforms and the protocols they are based on: Mastodon (ActivityPub), Bluesky (AT Protocol), Warpcast (Farcaster), Hey (Lens) and Primal (Nostr).
Comparison of architecture and mainstream adoption potential
Protocol Identity System Example Storage model Cost for end users Potential
Mastodon Tied to server domain @ottok@mastodon.social Federated instances Free (some instances charge) High
Bluesky Portable (DID) ottoke.bsky.social Federated instances Free Moderate
Farcaster ENS (Ethereum) @ottok Blockchain + off-chain Small gas fees Moderate
Lens NFT-based (Polygon) @ottok Blockchain + off-chain Small gas fees Niche
Nostr Cryptographic Keys npub16lc6uhqpg6dnqajylkhwuh3j7ynhcnje508tt4v6703w9kjlv9vqzz4z7f Federated instances Free (some instances charge) Niche

1. Mastodon (ActivityPub) Screenshot of Mastodon Mastodon was created in 2016 by Eugen Rochko, a German software developer who sought to provide a decentralized and user-controlled alternative to Twitter. It was built on the ActivityPub protocol, now standardized by W3C Social Web Working Group, to allow users to join independent servers while still communicating across the broader Mastodon network. Mastodon operates on a federated model, where multiple independently run servers communicate via ActivityPub. Each server sets its own moderation policies, leading to a decentralized but fragmented experience. The servers can alternatively be called instances, relays or nodes, depending on what vocabulary a protocol has standardized on.
  • Identity: User identity is tied to the instance where they registered, represented as @username@instance.tld.
  • Storage: Data is stored on individual instances, which federate messages to other instances based on their configurations.
  • Cost: Free to use, but relies on instance operators willing to run the servers.
The protocol defines multiple activities such as:
  • Creating a post
  • Liking
  • Sharing
  • Following
  • Commenting

Example Message in ActivityPub (JSON-LD Format)
json
 
 "@context": "https://www.w3.org/ns/activitystreams",
 "type": "Create",
 "actor": "https://mastodon.social/users/ottok",
 "object":  
 "type": "Note",
 "content": "Hello from #Mastodon!",
 "published": "2025-03-03T12:00:00Z",
 "to": ["https://www.w3.org/ns/activitystreams#Public"]
  
 
Servers communicate across different platforms by publishing activities to their followers or forwarding activities between servers. Standard HTTPS is used between servers for communication, and the messages use JSON-LD for data representation. The WebFinger protocol is used for user discovery. There is however no neat way for home server discovery yet. This means that if you are browsing e.g. Fosstodon and want to follow a user and press Follow, a dialog will pop up asking you to enter your own home server (e.g. mastodon.social) to redirect you there for actually executing the Follow action on with your account. Mastodon is open source under the AGPL at github.com/mastodon/mastodon. Anyone can operate their own instance. It just requires to run your own server and some skills to maintain a Ruby on Rails app with a PostgreSQL database backend, and basic understanding of the protocol to configure federation with other ActivityPub instances.

Popularity: Already established, but will it grow more? Mastodon has seen steady growth, especially after Twitter s acquisition in 2022, with some estimates stating it peaked at 10 million users across thousands of instances. However, its fragmented user experience and the complexity of choosing instances have hindered mainstream adoption. Still, it remains the most established decentralized alternative to Twitter. Note that Donald Trump s Truth Social is based on the Mastodon software but does not federate with the ActivityPub network. The ActivityPub protocol is the most widely used of its kind. One of the other most popular services is the Lemmy link sharing service, similar to Reddit. The larger ecosystem of ActivityPub is called Fediverse, and estimates put the total active user count around 6 million.

2. Bluesky (AT Protocol) Screenshot of Bluesky Interestingly, Bluesky was conceived within Twitter in 2019 by Twitter founder Jack Dorsey. After being incubated as a Twitter-funded project, it spun off as an independent Public Benefit LLC in February 2022 and launched its public beta in February 2023. Bluesky runs on top of the Authenticated Transfer (AT) Protocol published at https://github.com/bluesky-social/atproto. The protocol enables portable identities and data ownership, meaning users can migrate between platforms while keeping their identity and content intact. In practice, however, there is only one popular server at the moment, which is Bluesky itself.
  • Identity: Usernames are domain-based (e.g., @user.bsky.social).
  • Storage: Content is theoretically federated among various servers.
  • Cost: Free to use, but relies on instance operators willing to run the servers.

Example Message in AT Protocol (JSON Format)
json
 
 "repo": "did:plc:ottoke.bsky.social",
 "collection": "app.bsky.feed.post",
 "record":  
 "$type": "app.bsky.feed.post",
 "text": "Hello from Bluesky!",
 "createdAt": "2025-03-03T12:00:00Z",
 "langs": ["en"]


Popularity: Hybrid approach may have business benefits? Bluesky reported over 3 million users by 2024, probably getting traction due to its Twitter-like interface and Jack Dorsey s involvement. Its hybrid approach decentralized identity with centralized components could make it a strong candidate for mainstream adoption, assuming it can scale effectively.

3. Warpcast (Farcaster Network) Farcaster was launched in 2021 by Dan Romero and Varun Srinivasan, both former crypto exchange Coinbase executives, to create a decentralized but user-friendly social network. Built on the Ethereum blockchain, it could potentially offer a very attack-resistant communication medium. However, in my own testing, Farcaster does not seem to fully leverage what Ethereum could offer. First of all, there is no diversity in programs implementing the protocol as at the moment there is only Warpcast. In Warpcast the signup requires an initial 5 USD fee that is not payable in ETH, and users need to create a new wallet address on the Ethereum layer 2 network Base instead of simply reusing their existing Ethereum wallet address or ENS name. Despite this, I can understand why Farcaster may have decided to start out like this. Having a single client program may be the best strategy initially. One of the decentralized chat protocol Matrix founders, Matthew Hodgson, shared in his FOSDEM 2025 talk that he slightly regrets focusing too much on developing the protocol instead of making sure the app to use it is attractive to end users. So it may be sensible to ensure Warpcast gets popular first, before attempting to make the Farcaster protocol widely used. As a protocol Farcaster s hybrid approach makes it more scalable than fully on-chain networks, giving it a higher chance of mainstream adoption if it integrates seamlessly with broader Web3 ecosystems.
  • Identity: ENS (Ethereum Name Service) domains are used as usernames.
  • Storage: Messages are stored in off-chain hubs, while identity is on-chain.
  • Cost: Users must pay gas fees for some operations but reading and posting messages is mostly free.

Example Message in Farcaster (JSON Format)
json
 
 "fid": 766579,
 "username": "ottok",
 "custodyAddress": "0x127853e48be3870172baa4215d63b6d815d18f21",
 "connectedWallet": "0x3ebe43aa3ae5b891ca1577d9c49563c0cee8da88",
 "text": "Hello from Farcaster!",
 "publishedAt": 1709424000,
 "replyTo": null,
 "embeds": []
 

Popularity: Decentralized social media + decentralized payments a winning combo? Ethereum founder Vitalik Buterin (warpcast.com/vbuterin) and many core developers are active on the platform. Warpcast, the main client for Farcaster, has seen increasing adoption, especially among Ethereum developers and Web3 enthusiasts. I too have an profile at warpcast.com/ottok. However, the numbers are still very low and far from reaching network effects to really take off. Blockchain-based social media networks, particularly those built on Ethereum, are compelling because they leverage existing user wallets and persistent identities while enabling native payment functionality. When combined with decentralized content funding through micropayments, these blockchain-backed social networks could offer unique advantages that centralized platforms may find difficult to replicate, being decentralized both as a technical network and in a funding mechanism.

4. Hey.xyz (Lens Network) The Lens Protocol was developed by decentralized finance (DeFi) team Aave and launched in May 2022 to provide a user-owned social media network. While initially built on Polygon, it has since launched its own Layer 2 network called the Lens Network in February 2024. Lens is currently the main competitor to Farcaster. Lens stores profile ownership and references on-chain, while content is stored on IPFS/Arweave, enabling composability with DeFi and NFTs.
  • Identity: Profile ownership is tied to NFTs on the Polygon blockchain.
  • Storage: Content is on-chain and integrates with IPFS/Arweave (like NFTs).
  • Cost: Users must pay gas fees for some operations but reading and posting messages is mostly free.

Example Message in Lens (JSON Format)
json
 
 "profileId": "@ottok",
 "contentURI": "ar://QmExampleHash",
 "collectModule": "0x23b9467334bEb345aAa6fd1545538F3d54436e96",
 "referenceModule": "0x0000000000000000000000000000000000000000",
 "timestamp": 1709558400
 

Popularity: Probably not as social media site, but maybe as protocol? The social media side of Lens is mainly the Hey.xyz website, which seems to have fewer users than Warpcast, and is even further away from reaching critical mass for network effects. The Lens protocol however has a lot of advanced features and it may gain adoption as the building block for many Web3 apps.

5. Primal.net (Nostr Network) Nostr (Notes and Other Stuff Transmitted by Relays) was conceptualized in 2020 by an anonymous developer known as fiatjaf. One of the primary design tenets was to be a censorship-resistant protocol and it is popular among Bitcoin enthusiasts, with Jack Dorsey being one of the public supporters. Unlike the Farcaster and Lens protocols, Nostr is not blockchain-based but just a network of relay servers for message distribution. If does however use public key cryptography for identities, similar to how wallets work in crypto.
  • Identity: Public-private key pairs define identity (with prefix npub...).
  • Storage: Content is federated among multiple servers, which in Nostr vocabulary are called relays.
  • Cost: No gas fees, but relies on relay operators willing to run the servers.

Example Message in Nostr (JSON Format)
json
 
 "id": "note1xyz...",
 "pubkey": "npub1...",
 "kind": 1,
 "content": "Hello from Nostr!",
 "created_at": 1709558400,
 "tags": [],
 "sig": "sig1..."
 

Popularity: If Jack Dorsey and Bitcoiners promote it enough? Primal.net as a web app is pretty solid, but it does not stand out much. While Jack Dorsey has shown support by donating $1.5 million to the protocol development in December 2021, its success likely depends on broader adoption by the Bitcoin community.

Will any of these replace X/Twitter? As usage patterns vary, the statistics are not fully comparable, but this overview of the situation in March 2025 gives a decent overview.
Platform Total Accounts Active Users Growth Trend
Mastodon ~10 million ~1 million Steady
Bluesky ~33 million ~1 million Steady
Nostr ~41 million ~20 thousand Steady
Farcaster ~850 thousand ~50 thousand Flat
Lens ~140 thousand ~20 thousand Flat
Mastodon and Bluesky have already reached millions of users, while Lens and Farcaster are growing within crypto communities. It is however clear that none of these are anywhere close to how popular X/Twitter is. In particular, Mastodon had a huge influx of users in the fall of 2022 when Twitter was acquired, but to challenge the incumbents the growth would need to significantly accelerate. We can all accelerate this development by embracing decentralized social media now alongside existing dominant platforms. Who knows, given the right circumstances maybe X.com leadership decides to change the operating model and start federating contents to break out from a walled garden model. The likelyhood of such development would increase if decentralized networks get popular, and the encumbents feel they need to participate to not lose out.

Past and future The idea of decentralized social media is not new. One early pioneer identi.ca launched in 2008, only two years after Twitter, using the OStatus protocol to promote decentralization. A few years later it evolved into pump.io with the ActivityPump protocol, and also forked into GNU Social that continued with OStatus. I remember when these happened, and that in 2010 also Diaspora launched with fairly large publicity. Surprisingly both of these still operate (I can still post both on identi.ca and diasp.org), but the activity fizzled out years ago. The protocol however survived partially and evolved into ActivityPub, which is now the backbone of the Fediverse. The evolution of decentralized social media over the next decade will likely parallel developments in democracy, freedom of speech and public discourse. While the early 2010s emphasized maximum independence and freedom, the late 2010s saw growing support for content moderation to combat misinformation. The AI era introduces new challenges, potentially requiring proof-of-humanity verification for content authenticity. Key factors that will determine success:
  • User experience and ease of onboarding
  • Network effects and critical mass of users
  • Integration with existing web3 infrastructure
  • Balance between decentralization and usability
  • Sustainable economic models for infrastructure
This is clearly an area of development worth monitoring closely, as the next few years may determine which protocol becomes the de facto standard for decentralized social communication.

3 March 2025

Bits from Debian: Bits from the DPL

Dear Debian community, this is bits from DPL for February. Ftpmaster team is seeking for new team members In December, Scott Kitterman announced his retirement from the project. I personally regret this, as I vividly remember his invaluable support during the Debian Med sprint at the start of the COVID-19 pandemic. He even took time off to ensure new packages cleared the queue in under 24 hours. I want to take this opportunity to personally thank Scott for his contributions during that sprint and for all his work in Debian. With one fewer FTP assistant, I am concerned about the increased workload on the remaining team. I encourage anyone in the Debian community who is interested to consider reaching out to the FTP masters about joining their team. If you're wondering about the role of the FTP masters, I'd like to share a fellow developer's perspective:
"My read on the FTP masters is:
  • In truth, they are the heart of the project.
  • They know it.
  • They do a fantastic job."
I fully agree and see it as part of my role as DPL to ensure this remains true for Debian's future. If you're looking for a way to support Debian in a critical role where many developers will deeply appreciate your work, consider reaching out to the team. It's a great opportunity for any Debian Developer to contribute to a key part of the project. Project Status: Six Months of Bug of the Day In my Bits from the DPL talk at DebConf24, I announced the Tiny Tasks effort, which I intended to start with a Bug of the Day project. Another idea was an Autopkgtest of the Day, but this has been postponed due to limited time resources-I cannot run both projects in parallel. The original goal was to provide small, time-bound examples for newcomers. To put it bluntly: in terms of attracting new contributors, it has been a failure so far. My offer to explain individual bug-fixing commits in detail, if needed, received no response, and despite my efforts to encourage questions, none were asked. However, the project has several positive aspects: experienced developers actively exchange ideas, collaborate on fixing bugs, assess whether packages are worth fixing or should be removed, and work together to find technical solutions for non-trivial problems. So far, the project has been engaging and rewarding every day, bringing new discoveries and challenges-not just technical, but also social. Fortunately, in the vast majority of cases, I receive positive responses and appreciation from maintainers. Even in the few instances where help was declined, it was encouraging to see that in two cases, maintainers used the ping as motivation to work on their packages themselves. This reflects the dedication and high standards of maintainers, whose work is essential to the project's success. I once used the metaphor that this project is like wandering through a dark basement with a lone flashlight-exploring aimlessly and discovering a wide variety of things that have accumulated over the years. Among them are true marvels with popcon >10,000, ingenious tools, and delightful games that I only recently learned about. There are also some packages whose time may have come to an end-but each of them reflects the dedication and effort of those who maintained them, and that deserves the utmost respect. Leaving aside the challenge of attracting newcomers, what have we achieved since August 1st last year? With some goodwill, you can see a slight impact on the trends.debian.net graphs (thank you Lucas for the graphs), but I would never claim that this project alone is responsible for the progress. What I have also observed is the steady stream of daily uploads to the delayed queue, demonstrating the continuous efforts of many contributors. This ongoing work often remains unseen by most-including myself, if not for my regular check-ins on this list. I would like to extend my sincere thanks to everyone pushing fixes there, contributing to the overall quality and progress of Debian's QA efforts. If you examine the graphs for "Version Control System" and "VCS Hosting" with the goodwill mentioned above, you might notice a positive trend since mid-last year. The "Package Smells" category has also seen reductions in several areas: "no git", "no DEP5 copyright", "compat <9", and "not salsa". I'd also like to acknowledge the NMUers who have been working hard to address the "format != 3.0" issue. Thanks to all their efforts, this specific issue never surfaced in the Bug of the Day effort, but their contributions deserve recognition here. The experience I gathered in this project taught me a lot and inspired me to some followup we should discuss at a Sprint at DebCamp this year. Finally, if any newcomer finds this information interesting, I'd be happy to slow down and patiently explain individual steps as needed. All it takes is asking questions on the Matrix channel to turn this into a "teaching by example" session. By the way, for newcomers who are interested, I used quite a few abbreviations-all of which are explained in the Debian Glossary. Sneak Peek at Upcoming Conferences I will join two conferences in March-feel free to talk to me if you spot me there.
  1. FOSSASIA Summit 2025 (March 13-15, Bangkok, Thailand) Schedule: https://eventyay.com/e/4c0e0c27/schedule
  2. Chemnitzer Linux-Tage (March 22-23, Chemnitz, Germany) Schedule: https://chemnitzer.linux-tage.de/2025/de/programm/vortraege
Both events will have a Debian booth-come say hi! Kind regards Andreas.

Next.

Previous.