Search Results: "ag"

22 January 2021

Enrico Zini: Polishing nspawn-runner

This post is part of a series about trying to setup a gitlab runner based on systemd-nspawn. I published the polished result as nspawn-runner on GitHub. gitlab-runner supports adding extra arguments to the custom scripts, and I can take advantage of that to pack all the various scripts that I prototyped so far into an all-in-one nspawn-runner command:
usage: nspawn-runner [-h] [-v] [--debug]
                      chroot-create,chroot-login,prepare,run,cleanup,gitlab-config,toml 
                     ...
Manage systemd-nspawn machines for CI runs.
positional arguments:
   chroot-create,chroot-login,prepare,run,cleanup,gitlab-config,toml 
                        sub-command help
    chroot-create       create a chroot that serves as a base for ephemeral
                        machines
    chroot-login        enter the chroot to perform maintenance
    prepare             start an ephemeral system for a CI run
    run                 run a command inside a CI machine
    cleanup             cleanup a CI machine after it's run
    gitlab-config       configuration step for gitlab-runner
    toml                output the toml configuration for the custom runner
optional arguments:
  -h, --help            show this help message and exit
  -v, --verbose         verbose output
  --debug               verbose output
chroot maintenance chroot-create and chroot-login are similar to what pbuilder, cowbuilder, schroot, debspawn and similar tools do. They only take a chroot name, and default the rest of paths to where nspawn-runner expects things to be under /var/lib/nspawn-runner. gitlab-runner setup nspawn-runner toml <chroot-name> outputs a snippet to add to /etc/gitlab-runner/config.toml to configure the CI. For example:
$ ./nspawn-runner toml buster
[[runners]]
  name="buster"
  url="TODO"
  token="TODO"
  executor = "custom"
  builds_dir = "/var/lib/nspawn-runner/.build"
  cache_dir = "/var/lib/nspawn-runner/.cache"
  [runners.custom_build_dir]
  [runners.cache]
    [runners.cache.s3]
    [runners.cache.gcs]
    [runners.cache.azure]
  [runners.custom]
    config_exec = "/home/enrico/ /nspawn-runner/nspawn-runner"
    config_args = ["gitlab-config"]
    config_exec_timeout = 200
    prepare_exec = "/home/enrico/ /nspawn-runner/nspawn-runner"
    prepare_args = ["prepare", "buster"]
    prepare_exec_timeout = 200
    run_exec = "/home/enrico/dev/nspawn-runner/nspawn-runner"
    run_args = ["run"]
    cleanup_exec = "/home/enrico/ /nspawn-runner/nspawn-runner"
    cleanup_args = ["cleanup"]
    cleanup_exec_timeout = 200
    graceful_kill_timeout = 200
    force_kill_timeout = 200
One needs to remember to set url and token, and the runner is configured. The end, for now This is it, it works! Time will tell what issues or ideas will come up: for now, it's a pretty decent first version. The various prepare, run, cleanup steps are generic enough that they can be used outside of gitlab-runner: feel free to build on them, and drop me a note if you find this useful! Updated: Issues noticed so far, that could go into a new version:

Enrico Zini: Assembling the custom runner

This post is part of a series about trying to setup a gitlab runner based on systemd-nspawn. I published the polished result as nspawn-runner on GitHub. The plan Back to custom runners, here's my plan: The scripts Here are the scripts based on Federico's work: base.sh with definitions sourced by all scripts:
MACHINE="run-$CUSTOM_ENV_CI_JOB_ID"
ROOTFS="/var/lib/gitlab-runner-custom-chroots/buster"
OVERLAY="/var/lib/gitlab-runner-custom-chroots/$MACHINE"
config.sh doing nothing:
#!/bin/sh
exit 0
prepare.sh starting the machine:
#!/bin/bash
source $(dirname "$0")/base.sh
set -eo pipefail
# trap errors as a CI system failure
trap "exit $SYSTEM_FAILURE_EXIT_CODE" ERR
logger "gitlab CI: preparing $MACHINE"
mkdir -p $OVERLAY
systemd-run \
  -p 'KillMode=mixed' \
  -p 'Type=notify' \
  -p 'RestartForceExitStatus=133' \
  -p 'SuccessExitStatus=133' \
  -p 'Slice=machine.slice' \
  -p 'Delegate=yes' \
  -p 'TasksMax=16384' \
  -p 'WatchdogSec=3min' \
  systemd-nspawn --quiet -D $ROOTFS \
    --overlay="$ROOTFS:$OVERLAY:/"
    --machine="$MACHINE" --boot --notify-ready=yes
run.sh running the provided scripts in the machine:
#!/bin/bash
logger "gitlab CI: running $@"
source $(dirname "$0")/base.sh
set -eo pipefail
trap "exit $SYSTEM_FAILURE_EXIT_CODE" ERR
systemd-run --quiet --pipe --wait --machine="$MACHINE" /bin/bash < "$1"
cleanup.sh stopping the machine and removing the writable overlay directory:
#!/bin/bash
logger "gitlab CI: cleanup $@"
source $(dirname "$0")/base.sh
machinectl stop "$MACHINE"
rm -rf $OVERLAY
Trying out the plan I tried a manual invocation of gitlab-runner, and it worked perfectly:
# mkdir /var/lib/gitlab-runner-custom-chroots/build/
# mkdir /var/lib/gitlab-runner-custom-chroots/cache/
# gitlab-runner exec custom \
    --builds-dir /var/lib/gitlab-runner-custom-chroots/build/ \
    --cache-dir /var/lib/gitlab-runner-custom-chroots/cache/ \
    --custom-config-exec /var/lib/gitlab-runner-custom-chroots/config.sh \
    --custom-prepare-exec /var/lib/gitlab-runner-custom-chroots/prepare.sh \
    --custom-run-exec /var/lib/gitlab-runner-custom-chroots/run.sh \
    --custom-cleanup-exec /var/lib/gitlab-runner-custom-chroots/cleanup.sh \
    tests
Runtime platform                                    arch=amd64 os=linux pid=18662 revision=775dd39d version=13.8.0
Running with gitlab-runner 13.8.0 (775dd39d)
Preparing the "custom" executor
Using Custom executor...
Running as unit: run-r1be98e274224456184cbdefc0690bc71.service
executor not supported                              job=1 project=0 referee=metrics
Preparing environment
Getting source from Git repository
Executing "step_script" stage of the job script
WARNING: Starting with version 14.0 the 'build_script' stage will be replaced with 'step_script': https://gitlab.com/gitlab-org/gitlab-runner/-/issues/26426
Job succeeded
Deploy The remaining step is to deploy all this in /etc/gitlab-runner/config.toml:
concurrent = 1
check_interval = 0
[session_server]
  session_timeout = 1800
[[runners]]
  name = "nspawn runner"
  url = "http://gitlab.siweb.local/"
  token = " "
  executor = "custom"
  builds_dir = "/var/lib/gitlab-runner-custom-chroots/build/"
  cache_dir = "/var/lib/gitlab-runner-custom-chroots/cache/"
  [runners.custom_build_dir]
  [runners.cache]
    [runners.cache.s3]
    [runners.cache.gcs]
    [runners.cache.azure]
  [runners.custom]
    config_exec = "/var/lib/gitlab-runner-custom-chroots/config.sh"
    config_exec_timeout = 200
    prepare_exec = "/var/lib/gitlab-runner-custom-chroots/prepare.sh"
    prepare_exec_timeout = 200
    run_exec = "/var/lib/gitlab-runner-custom-chroots/run.sh"
    cleanup_exec = "/var/lib/gitlab-runner-custom-chroots/cleanup.sh"
    cleanup_exec_timeout = 200
    graceful_kill_timeout = 200
    force_kill_timeout = 200
Next steps My next step will be polishing all this in a way that makes deploying and maintaining a runner configuration easy.

Enrico Zini: Exploring nspawn for CIs

This post is part of a series about trying to setup a gitlab runner based on systemd-nspawn. I published the polished result as nspawn-runner on GitHub. Here I try to figure out possible ways of invoking nspawn for the prepare, run, and cleanup steps of gitlab custom runners. The results might be useful invocations beyond Gitlab's scope of application. I begin with a chroot which will be the base for our build environments:
debootstrap --variant=minbase --include=git,build-essential buster workdir
Fully ephemeral nspawn This would be fantastic: set up a reusable chroot, mount readonly, run the CI in a working directory mounted on tmpfs. It sets up quickly, it cleans up after itself, and it would make prepare and cleanup noops:
mkdir workdir/var/lib/gitlab-runner
systemd-nspawn --read-only --directory workdir --tmpfs /var/lib/gitlab-runner "$@"
However, run gets run multiple times, so I need the side effects of run to persist inside the chroot between runs. Also, if the CI uses a large amount of disk space, tmpfs may get into trouble. nspawn with overlay Federico used --overlay to keep the base chroot readonly while allowing persistent writes on a temporary directory on the filesystem. Note that using --overlay requires systemd and systemd-container from buster-backports because of systemd bug #3847. Example:
mkdir -p tmp-overlay
systemd-nspawn --quiet -D workdir \
  --overlay=" pwd /workdir: pwd /tmp-overlay:/"
I can run this twice, and changes in the file system will persist between systemd-nspawn executions. Great! However, any process will be killed at the end of each execution. machinectl I can give a name to systemd-nspawn invocations using --machine, and it allows me to run multiple commands during the machine lifespan using machinectl and systemd-run. In theory machinectl can also fully manage chroots and disk images in /var/lib/machines, but I haven't found a way with machinectl to start multiple machines sharing the same underlying chroot. It's ok, though: I managed to do that with systemd-nspawn invocations. I can use the --machine=name argument to systemd-nspawn to make it visible to machinectl. I can use the --boot argument to systemd-nspawn to start enough infrastructure inside the container to allow machinectl to interact with it. This gives me any number of persistent and named running systems, that share the same underlying chroot, and can cleanup after themselves. I can run commands in any of those systems as I like, and their side effects persist until a system is stopped. The chroot needs systemd and dbus for machinectl to be able to interact with it:
debootstrap --variant=minbase --include=git,systemd,systemd,build-essential buster workdir
Let's boot the machine:
mkdir -p overlay
systemd-nspawn --quiet -D workdir \
    --overlay=" pwd /workdir: pwd /overlay:/"
    --machine=test --boot
Let's try machinectl:
# machinectl list
MACHINE CLASS     SERVICE        OS     VERSION ADDRESSES
test    container systemd-nspawn debian 10      -
1 machines listed.
# machinectl shell --quiet test /bin/ls -la /
total 60
[ ]
To run commands, rather than machinectl shell, I need to use systemd-run --wait --pipe --machine=name, otherwise machined won't forward the exit code. The result however is pretty good, with working stdin/stdout/stderr redirection and forwarded exit code. Good, I'm getting somewhere. The terminal where I ran systemd-nspawn is currently showing a nice getty for the booted system, which is cute, and not what I want for the setup process of a CI. Spawning machines without needing a terminal machinectl uses /lib/systemd/system/systemd-nspawn@.service to start machines. I suppose there's limited magic in there: start systemd-nspawn as a service, use --machine to give it a name, and machinectl manages it as if it started it itself. What if, instead of installing a unit file for each CI run, I try to do the same thing with systemd-run?
systemd-run \
  -p 'KillMode=mixed' \
  -p 'Type=notify' \
  -p 'RestartForceExitStatus=133' \
  -p 'SuccessExitStatus=133' \
  -p 'Slice=machine.slice' \
  -p 'Delegate=yes' \
  -p 'TasksMax=16384' \
  -p 'WatchdogSec=3min' \
  systemd-nspawn --quiet -D  pwd /workdir \
    --overlay=" pwd /workdir: pwd /overlay:/"
    --machine=test --boot
It works! I can interact with it using machinectl, and fine tune DevicePolicy as needed to lock CI machines down. This setup has a race condition where if I try to run a command inside the machine in the short time window before the machine has finished booting, it fails:
# systemd-run [ ] systemd-nspawn [ ] ; machinectl --quiet shell test /bin/ls -la /
Failed to get shell PTY: Protocol error
# machinectl shell test /bin/ls -la /
Connected to machine test. Press ^] three times within 1s to exit session.
total 60
[ ]
systemd-nspawn has the option --notify-ready=yes that solves exactly this problem:
# systemd-run [ ] systemd-nspawn [ ] --notify-ready=yes ; machinectl --quiet shell test /bin/ls -la /
Running as unit: run-r5a405754f3b740158b3d9dd5e14ff611.service
total 60
[ ]
On nspawn's side, I should now have all I need. Next steps My next step will be wrapping it all together in a gitlab runner.

Enrico Zini: Gitlab runners with nspawn

This is a first post in a series about trying to setup a gitlab runner based on systemd-nspawn. I published the polished result as nspawn-runner on GitHub. The goal I need to setup gitlab runners, and I try to not involve docker in my professional infrastructure if I can avoid it. Let's try systemd-nspawn. It's widely available and reasonably reliable. I'm not the first to have this idea: Federico Ceratto made a setup based on custom runners and Josef Kufner one based on ssh runners. I'd like to skip the complication of ssh, and to expand Federico's version to persist not just filesystem changes but also any other side effect of CI commands. For example, one CI command may bring up a server and the next CI command may want to test interfacing with it. Understanding gitlab-runner First step: figuring out gitlab-runner. Test runs of gitlab-runner I found that I can run gitlab-runner manually without needing to go through a push to Gitlab. It needs a local git repository with a .gitlab-ci.yml file:
mkdir test
cd test
git init
cat > .gitlab-ci.yml << EOF
tests:
 script:
  - env   sort
  - pwd
  - ls -la
EOF
git add .gitlab-ci.yml
git commit -am "Created a test repo for gitlab-runner"
Then I can go in the repo and test gitlab-runner:
gitlab-runner exec shell tests
It doesn't seem to use /etc/gitlab-runner/config.toml and it needs all the arguments passed to its command line: I used the shell runner for a simple initial test. Later I'll try to brew a gitlab-runner exec custom invocation that uses nspawn. Basics of custom runners A custom runner runs a few scripts to manage the run: run gets at least one argument which is a path to the script to run. The other scripts get no arguments by default. The runner configuration controls the paths of the scripts to run, and optionally extra arguments to pass to them Next steps My next step will be to figure out possible ways of invoking nspawn for the prepare, run, and cleanup scripts.

21 January 2021

Russell Coker: Links January 2021

Krebs on Security has an informative article about web notifications and how they are being used for spamming and promoting malware [1]. He also includes links for how to permanently disable them. If nothing else clicking no on each new site that wants to send notifications is annoying. Michael Stapelberg wrote an insightful posts about inefficiencies in the Debian development processes [2]. While I agree with most of his assessment of Debian issues I am not going to decrease my involvement in Debian. Of the issues he mentions the 2 that seem to have the best effort to reward ratio are improvements to mailing list archives (to ideally make it practical to post to lists without subscribing and read responses in the archives) and the issues of forgetting all the complexities of the development process which can be alleviated by better Wiki pages. In my Debian work I ve contributed more to the Wiki in recent times but not nearly as much as I should. Jacobin has an insightful article Ending Poverty in the United States Would Actually Be Pretty Easy [3]. Mark Brown wrote an interesting blog post about the Rust programming language [4]. He links to a couple of longer blog posts about it. Rust has some great features and I ve been meaning to learn it. Scientific America has an informative article about research on the spread of fake news and memes [5]. Something to consider when using social media. Bruce Schneier wrote an insightful blog post on whether there should be limits on persuasive technology [6]. Jonathan Dowland wrote an interesting blog post about git rebasing and lab books [7]. I think it s an interesting thought experiment to compare the process of developing code worthy of being committed to a master branch of a VCS to the process of developing a Ph.D thesis. CBS has a disturbing article about the effect of Covid19 on people s lungs [8]. Apparently it usually does more lung damage than long-term smoking and even 70%+ of people who don t have symptoms of the disease get significant lung damage. People who live in heavily affected countries like the US now have to worry that they might have had the disease and got lung damage without knowing it. Russ Allbery wrote an interesting review of the book Because Internet about modern linguistics [9]. The topic is interesting and I might read that book at some future time (I have many good books I want to read). Jonathan Carter wrote an interesting blog post about CentOS Streams and why using a totally free OS like Debian is going to be a better option for most users [10]. Linus has slammed Intel for using ECC support as a way of segmenting the market between server and desktop to maximise profits [11]. It would be nice if a company made a line of Ryzen systems with ECC RAM support, but most manufacturers seem to be in on the market segmentation scam. Russ Allbery wrote an interesting review of the book Can t Even about millenials as the burnout generation and the blame that the corporate culture deserves for this [12].

20 January 2021

Molly de Blanc: Inauguration Pie

How can I put four years into a pie? I m thinking of Inauguration Day 2017 through to today, Inauguration Day 2021. In truth things started back in 2015, when Donald Trump announced his run for the United States presidency, and I don t know how long things will continue past the moment when President-Elect Joe Biden becomes President Joe Biden. For the United States, it s been a hell of a time. For the world, it d been even worse. Every generation thinks that they lived through more than anyone else, that they had it worse. I had a Boomer tell me that the existential stress of COVID is nothing compared to the Vietnam War. I m sure when we are living through a global water crisis, I ll tell the kids that we had it bad too. Everyday I listen to the radio and read Twitter, aware that the current state of endless wars wars against terrorism and drugs, organized crime and famine, climate change and racism is global, and not limited to just what s happening to and around me. That makes it feel worse and bigger and I wonder if earlier generations can really grasp how big that is. The last four years brought me in closer working relationships with people in India and Nigeria. I would call these people my friends in that if they were in town I would want to see them and show them around. Most of them I would offer a space in my small apartment, in case they needed somewhere to sleep and wanted to save the money. We chat, though we only have the internet as opposed to elevator rides in tall office buildings and slow walks down to the shops during lunch breaks. From these relationships I have learned very little about life in India or Nigeria, and I only visited India separately from any of my colleagues there. (I went for a wedding. My visa to Nigeria was denied on account of a medical issue.) But, I follow these people on social media and see what they share, the same political and social utterances that could be the same here or virtually any other place, as long as we replace the right keywords. Exchange the name of one leader, conservative party, or government unit for another. When I first saw the #EndSARS hashtag show up, I thought the images were from Black Lives Matter protests. Stop police brutality. And that was only in the last few months. I ve had three jobs since Trump first announced his candidacy in three very different places. In the first I felt like I wasn t able to talk about the sexism and discrimination I was dealing with in the office, and how much more so my views on an organizational partnership with a government whose policies I strongly disagreed with. In the second I was able to talk about these things, but there was nothing to do about them. I ve been in love and had my heart broken three times in three very different ways that all came down to someone valuing someone else more than they valued me. Can I bake heartbreak into a pie? Is it even fair to distract from the political world with my own loss? What about COVID-19? There s bitterness and anger and tears and pain emotional and physical. There is desperation and desolation and loneliness. Covid has colored everything during the past year. It is a burden our new political leaders will take on. Biden and Harris, all of the new people in Congress, and everyone else who has taken on an elected position now must content with Covid with new levels of responsibility. Not only do their decisions affect the people they come into contact with, they now affect everyone their policies touch and perhaps even more than that. The government hired people to build walls. Our government approved it and people willingly took on the job of building those walls. Families were separated. Children were placed in inhumane conditions; children were tortured. Remember when the guards at border detention facilities were raping children? Remember when children had guards? Women were forcefully operated upon and had their bodies permanently changed without their permission, against their desires. People were executed by the state. There were so many things I ve lost track of them all. I remember bits and pieces as I write this, coming back to me like singing a song I haven t thought about in years. With each line, I remember another one. Being worried about coming home from Cuba, when the visitation rules were changed in the middle of my trip. Climate change, again and again. Pollution and microplastics and watching the country being broken into pieces and sold off in the name of economy and progress. People losing their access to healthcare, through clinics closing down and loss of insurance. What do you bake into a pie that tastes like sedition? What are the flavors of loss and racism and hate? How to you balance the sourness with subtle hints of hope, which feels to tender and fragile? Do we pair equal parts of the palatable with the unpalatable, in the name of our neatly divided senate? I have hope, of course I have hope, and I have always had hope, but now it feels thinner than ever, like a ganache or a caramel after your hand slips and you pour too much cream in. A custard or compote or curd that that refuses to thicken no matter how long you cook it. I see that things could be better, but better does not mean good and better does not mean enough. So I will put my hope into this pie. I put my pain and anger into the dough. I will put my tears and helplessness and bitterness into the filling. I will cover it sweetness and the delicate hope I ve spun out of sugar. Soon I will bake it and share it with the three other people I see because the most important thing about surviving these past years, these past months and weeks and days, is that we did it together. We will commiserate on what we ve overcome, and we will share our hope and the sweetness of the moment, as the spun sugar dissolves on our tongues. There is so much we have left to do, so much we must do. We will be angry in the future, we may be angry later today, but until then, we have pie.

Rapha&#235;l Hertzog: Freexian s report about Debian Long Term Support, December 2020

A Debian LTS logo Like each month, have a look at the work funded by Freexian s Debian LTS offering. Debian project funding In December, we put aside 2100 EUR to fund Debian projects. The first project proposal (a tracker.debian.org improvement for the security team) was received and quickly approved by the paid contributors, then we opened a request for bids and the bid winner was announced today (it was easy, we had only one candidate). Hopefully this first project will be completed until our next report. We re looking forward to receive more projects from various Debian teams! Learn more about the rationale behind this initiative in this article. Debian LTS contributors In December, 12 contributors have been paid to work on Debian LTS, their reports are available: Evolution of the situation December was a quiet month as we didn t have a team meeting nor any other unusual activity and we released 43 DLAs. The security tracker currently lists 30 packages with a known CVE and the dla-needed.txt file has 25 packages needing an update. This month we are pleased to welcome Deveryware as new sponsor! Thanks to our sponsors Sponsors that joined recently are in bold.

19 January 2021

John Goerzen: Roundup of Secure Messengers with Off-The-Grid Capabilities (Distributed/Mesh Messengers)

Amid all the conversation about Signal, and the debate over decentralization, one thing has often not been raised: all of these things require an Internet connection. Of course, you might say. Internet is everywhere these days. Well, not so much, and it turns out there are some very good reasons that people might want messengers that work offline. Here are some examples: How do they work? These all use some form of local radio signal. Some, such as Briar, may use short-range Bluetooth and Wifi, while others use radios such as LoRa that can reach several miles with low power. I ve written quite a bit about LoRa before, and its unique low-speed but extreme-distance radio capabilities even on low power. One common thread through these is that most of them are Android-only, though many are compatible with F-Droid and privacy-enhanced Android distributions. Every item on this list uses full end-to-end encryption (E2EE). Let s dive on in. Briar Of all the options mentioned here, Briar is the one that bridges the traditional Internet-based approach with alternative options the best. It offers three ways for distributing data: As far as I can tell, there is no centralized server in Briar at all. Your account , such as it is, lives entirely within your device; if you wipe your device, you will have to make a new account and re-establish contacts. The use of Tor is also neat to see; it ensures that an adversary can t tell, just from that, that you re using Briar at all, though of course timing analysis may still be possible (and Bluetooth and Wifi uses may reval some of who is communicating). Briar features several types of messages (detailed in the manual), which really are just different spins on communication, which they liken to metaphors people are familiar with: By default, Briar raises an audible notification for incoming messages of all types. This is configurable for each type. Blogs have a way to reblog (even a built-in RSS reader to facilitate that), but framed a different way, they are broadcast messages. They could, for instance, be useful for a send help message to everyone (assuming that people haven t all shut off notifications of blogs due to others using them different ways). Briar s how it works page has an illustration specifically of how blogs are distributed. I m unclear on some of the details, and to what extent this applies to other kinds of messages, but one thing that you can notice from this is that a person A could write a broadcast message without Internet access, person B could receive it via Bluetooth or whatever, and then when person B gets Internet access again, the post could be distributed more widely. However, it doesn t appear that Briar is really a full mesh, since only known contacts in the distribution path for the message would repeat it. There are some downsides to Briar. One is that, since an account is fully localized to a device, one must have a separate account for each device. That can lead to contacts having to pick a specific device to send a message to. There is an online indicator, which may help, but it s definitely not the kind of seamless experience you get from Internet-only messengers. Also, it doesn t support migrating to a new phone, live voice/video calls, or attachments, but attachments are in the works. All in all, a solid communicator, and is the only one on this list that works 100% with the hardware everyone already has. While Bluetooth and Wifi have far more limited range than the other entries, there is undeniably convenience in not needing any additional hardware, and it may be particularly helpful when extra bags/pockets aren t available. Also, Briar is fully Open Source. Meshtastic Meshtastic is a radio-first LoRa mesh project. What do I mean by radio-first? Well, basically cell phones are how you interact with Meshtastic, but they are optional. The hardware costs about $30 and the batteries last about 8 days. Range between nodes is a few miles in typical conditions (up to 11km / 7mi in ideal conditions), but nodes act as repeaters, so it is quite conceivable to just drop a node in the middle if you and contacts will be far apart. The project estimates that around 2000 nodes are in operation, and the network is stronger the more nodes are around. The getting started site describes how to build one. Most Meshtastic device builds have a screen and some buttons. They can be used independently from the Android app to display received messages, distance and bearing to other devices (assuming both have a GPS enabled), etc. This video is an introduction showing it off, this one goes over the hardware buttons. So even if your phone is dead, you can at least know where your friends are. Incidentally, the phone links up to the radio board using Bluetooth, and can provide a location source if you didn t include one in your build. There are ideas about solar power for Meshtastic devices, too. Meshtastic doesn t, as far as I know, have an option for routing communication over the Internet, but the devices appear to be very thoughtfully-engineered and easy enough to put together. This one is definitely on my list to try. Ripple-based devices This is based on the LoRa Mesh Radio Instructables project, and is similar in concept to Meshtastic. It uses similar hardware, a similar app, but also has an option with a QWERTY hardware keyboard available, for those that want completely phone-free operation while still being able to send messages. There are a number of related projects posted at Instructables: a GPS tracker, some sensors, etc. These are variations on the same basic concept. These use the Ripple firmware, which is not open source, so I haven t pursued it further. GoTenna For people that want less of a DIY model, and don t mind proprietary solutions, there are two I ll mention. The first is GoTenna Mesh, which is LoRa-based and sells units for $90 each. However, there are significant community concerns about the longevity of the project, as GoTenna has re-focused on government and corporate work. The Android app hasn t been updated in 6 monnths despite a number of reviews citing issues, and the iOS app is also crusty. Beartooth Even more expensive at $125 each is the Beartooth. Also a proprietary option, I haven t looked into it more, but they are specifically targetting backwoods types of markets. Do not use: Bridgefy Bridgefy was briefly prominent since it was used during the Hong Kong protests. However, numerous vulnerabilities have been demonstrated, and the developers have said they are re-working the app to address them. I wouldn t recommend it for now. Alternatives: GMRS handhelds In the USA, GMRS voice handhelds are widely available. Although a license is required, it is simple (no exam) and cheap ($35) and extends to a whole family. GMRS radios also interoperate with FRS radios, which require no license and share some frequencies, but are limited to lower power (though are often sufficient). Handheld GMRS radios that use up to 5W of power are readily available. A voice signal is a lot harder to carry for a long distance than a very low-bandwidth digital one, so even with much more power you will probably not get the same kind of range you will with something like Meshtastic, and they don t come with any kind of security or encryption at all. However, for basic communication, they are often a useful tool.

Russ Allbery: Review: The Secret Barrister

Review: The Secret Barrister, by The Secret Barrister
Publisher: Picador
Copyright: 2018
Printing: 2019
ISBN: 1-5098-4115-6
Format: Kindle
Pages: 344
The Secret Barrister is a survey and critique of the criminal legal system of England and Wales. The author is an anonymous barrister who writes a legal blog of the same name (which I have not read). A brief and simplified primer for those who, like me, are familiar with the US legal system but not the English one: A barrister is a lawyer who argues cases in court, as distinct from a solicitor who does all the other legal work (and may make limited court appearances). If you need criminal legal help in England and Wales, you hire a solicitor, and they are your primary source of legal advise. If your case goes to court, your solicitor will generally (not always) refer the work of arguing your case before a judge and jury to a barrister and "instruct" them in the details of your argument. The job of the barrister is then to handle the courtroom trial, offer trial-specific legal advice, and translate your defense (or the crown's prosecution) into persuasive courtroom arguments. Unlike the United States, with its extremely sharp distinction between prosecutors and criminal defense attorneys, criminal barristers in England and Wales argue both prosecutions and defenses depending on who hires them. (That said, the impression I got from this book is that the creation of the Crown Prosecution Service is moving England closer to the US model and more prosecutions are now handled by barristers employed directly by the CPS, whom I assume do not take defense cases.) Barristers follow the cab-rank rule, which means that, like a taxicab, they are professionally obligated to represent people on a first-come, first-serve basis and are not allowed to pick and choose clients. (Throughout, I'm referencing the legal system of England and Wales because the author restricts his comments to it. Presumably this is because the Scottish and Northern Irish? legal systems are different yet again in ways I do not know.) If details like this sound surprising, you can see the appeal of this book to me. It's easy, in the US, to have a vast ignorance about the legal systems of other countries or even the possibility of different systems, which makes it hard to see how our system could be improved. I had a superficial assumption that since US law started as English common law, the US and English legal systems would be substantially similar. And they are to an extent; they're both adversarial rather than inquisitorial, for example (more on that in a moment). But the current system of criminal prosecution evolved long after US independence and thus evolved differently despite similar legal foundations. Those differences are helpful for this American to ponder the road not taken and the impact of our respective choices. That said, explaining the criminal legal system to Americans isn't the author's purpose. The first fifty pages are that beginner's overview, since apparently even folks who live in England are confused by the ubiquity of US legal dramas (not that those are very accurate representations of the US legal system either). The rest of the book, and its primary purpose, is an examination of the system's failings, starting with the magistrates' courts (which often use lay judges and try what in the US would be called misdemeanors, although as discussed in this book their scope is expanding). Other topics include problems with bail, how prosecution is structured, how victims and witnesses are handled, legal aid, sentencing, and the absurd inadequacy of compensation for erroneous convictions. The most useful part of this book for me, apart from the legal system introduction, was the two chapters the author spends arguing first for and then against replacing an adversarial system with an inquisitorial system (the French criminal justice system, for example). When one is as depressed about the state of one's justice system as both I and the author are, something radically different sounds appealing. The author first makes a solid case for the inquisitorial system and then tries to demolish it, still favoring the adversarial system, and I liked that argument construction. The argument in favor of an adversarial system is solid and convincing, but it's also depressing. It's the argument of someone who has seen the corruption, sloppiness, and political motivations in an adversarial system and fears what would happen if they were able to run rampant under a fig leaf of disinterested objectivity. I can't disagree, particularly when starting from an adversarial system, but this argument feels profoundly cynical. It reminds me of the libertarian argument for capitalism: humans are irredeemably awful, greed and self-interest are the only reliable or universal human motives, and therefore the only economic system that can work is one based on and built to harness greed, because expecting any positive characteristics from humans collectively is hopelessly naive. The author of this book is not quite that negative in their argument for an adversarial system, but it's essentially the same reasoning: the only way a system can be vaguely honest is if it's constantly questioned and attacked. It can never be trusted to be objective on its own terms. I wish the author had spent more time on the obvious counter-argument: when the system is designed for adversarial combat, it normalizes and even valorizes every dirty tactic that might result in a victory. The system reinforces our worst impulses, not to mention grinding up and destroying people who cannot afford their own dirty tricks. The author proposes several explanations for the problems they see in the criminal legal system, including "tough on crime" nonsense from politicians that sounds familiar to this American reader. Most problems, though, they trace back to lack of funding: of the police, of the courts, of the prosecutors, and of legal aid. I don't know enough about English politics to have an independent opinion on this argument, but the stories of outsourcing to the lowest bidder, overworked civil servants, ridiculously low compensation rates, flawed metrics like conviction rates, and headline-driven political posturing that doesn't extend to investing in necessary infrastructure like better case-tracking systems sounds depressingly familiar. This is one of those books where I appreciated the content but not the writing. It's not horrible, but the sentences are ponderous and strained and the author is a bit too fond of two-dollar words. They also have a dramatic and self-deprecating way of describing their own work that I suspect they thought was funny but that I found grating. By the end of this book, I was irritated enough that I can't recommend it. But the content was interesting, even the critique of a political system that isn't mine, and it prompted some new thoughts on the difficulties of creating a fair justice system. If you can deal with the author's writing style, you may also enjoy it. Rating: 6 out of 10

18 January 2021

Evgeni Golov: building a simple KVM switch for 30

Prompted by tweets from Lesley and Dave, I thought about KVM switches again and came up with a rather cheap solution to my individual situation (YMMY, as usual). As I've written last year, my desk has one monitor, keyboard and mouse and two computers. Since writing that post I got a new (bigger) monitor, but also an USB switch again (a DIGITUS USB 3.0 Sharing Switch) - this time one that doesn't freak out my dock \o/ However, having to switch the used computer in two places (USB and monitor) is rather inconvenient, but also getting an KVM switch that can do 4K@60Hz was out of question. Luckily, hackers gonna hack, everything, and not only receipt printers ( ). There is a tool called ddcutil that can talk to your monitor and change various settings. And udev can execute commands when (USB) devices connect You see where this is going? After installing the package (available both in Debian and Fedora), we can inspect our system with ddcutil detect. You might have to load the i2c_dev module (thanks Philip!) before this works -- it seems to be loaded automatically on my Fedora, but you never know .
$ sudo ddcutil detect
Invalid display
   I2C bus:             /dev/i2c-4
   EDID synopsis:
      Mfg id:           BOE
      Model:
      Serial number:
      Manufacture year: 2017
      EDID version:     1.4
   DDC communication failed
   This is an eDP laptop display. Laptop displays do not support DDC/CI.
Invalid display
   I2C bus:             /dev/i2c-5
   EDID synopsis:
      Mfg id:           AOC
      Model:            U2790B
      Serial number:
      Manufacture year: 2020
      EDID version:     1.4
   DDC communication failed
Display 1
   I2C bus:             /dev/i2c-7
   EDID synopsis:
      Mfg id:           AOC
      Model:            U2790B
      Serial number:
      Manufacture year: 2020
      EDID version:     1.4
   VCP version:         2.2
The first detected display is the built-in one in my laptop, and those don't support DDC anyways. The second one is a ghost (see ddcutil#160) which we can ignore. But the third one is the one we can (and will control). As this is the only valid display ddcutil found, we don't need to specify which display to talk to in the following commands. Otherwise we'd have to add something like --display 1 to them. A ddcutil capabilities will show us what the monitor is capable of (or what it thinks, I've heard some give rather buggy output here) -- we're mostly interested in the "Input Source" feature (Virtual Control Panel (VCP) code 0x60):
$ sudo ddcutil capabilities
 
   Feature: 60 (Input Source)
      Values:
         0f: DisplayPort-1
         11: HDMI-1
         12: HDMI-2
 
Seems mine supports it, and I should be able to switch the inputs by jumping between 0x0f, 0x11 and 0x12. You can see other values defined by the spec in ddcutil vcpinfo 60 --verbose, some monitors are using wrong values for their inputs . Let's see if ddcutil getvcp agrees that I'm using DisplayPort now:
$ sudo ddcutil getvcp 0x60
VCP code 0x60 (Input Source                  ): DisplayPort-1 (sl=0x0f)
And try switching to HDMI-1 using ddcutil setvcp:
$ sudo ddcutil setvcp 0x60 0x11
Cool, cool. So now we just need a way to trigger input source switching based on some event There are three devices connected to my USB switch: my keyboard, my mouse and my Yubikey. I do use the mouse and the Yubikey while the laptop is not docked too, so these are not good indicators that the switch has been turned to the laptop. But the keyboard is! Let's see what vendor and product IDs it has, so we can write an udev rule for it:
$ lsusb
 
Bus 005 Device 006: ID 17ef:6047 Lenovo ThinkPad Compact Keyboard with TrackPoint
 
Okay, so let's call ddcutil setvcp 0x60 0x0f when the USB device 0x17ef:0x6047 is added to the system:
ACTION=="add", SUBSYSTEM=="usb", ATTR idVendor =="17ef", ATTR idProduct =="6047", RUN+="/usr/bin/ddcutil setvcp 0x60 0x0f"
$ sudo vim /etc/udev/rules.d/99-ddcutil.rules
$ sudo udevadm control --reload
And done! Whenever I connect my keyboard now, it will force my screen to use DisplayPort-1. On my workstation, I deployed the same rule, but with ddcutil setvcp 0x60 0x11 to switch to HDMI-1 and my cheap not-really-KVM-but-in-the-end-KVM-USB-switch is done, for the price of one USB switch (~30 ). Note: if you want to use ddcutil with a Lenovo Thunderbolt 3 Dock (or any other dock using Displayport Multi-Stream Transport (MST)), you'll need kernel 5.10 or newer, which fixes a bug that prevents ddcutil from talking to the monitor using I C.

Craig Small: Percent CPU for processes

The ps program gives a snapshot of the processes running on your Unix-like system. On most Linux installations, this will be the ps program from the procps project. While you can get a lot of information from the tool, a lot of the fields need further explanation or can give wrong or confusing information; or putting it another way, they provide the right information that looks wrong. One of these confusing fields is the %CPU or pcpu field. You can see this as the third field with the ps aux command. You only really need the u option to see it, but ps aux is a pretty common invokation. More than 100%? This post was inspired by procps issue 186 where the submitter said that the sum of the processes cannot be more than the number of CPUs times 100%. If you have 1 CPU then the sum of %CPU for all processes should be 100% or less, have 16 CPUs then 1600% is your maximum number. Some people reason for the oddity of over 100% CPU as some rounding thing gone wrong and at first I did think that; except I know we get a lot of reports about comparing the top header CPU load vs process load not lining up and its because they re different . The trick here, is ps is reporting a percentage of what? Or, perhaps to give a better clue, a percentage of when? PCPU Calculations So to get to the bottom of this, let s look at the relevant code. In ps/output.c we have a function pr_pcpu that prints the percent CPU. The relevant lines are:
  total_time = pp->utime + pp->stime;
  if(include_dead_children) total_time += (pp->cutime + pp->cstime);
  seconds = cook_etime(pp);
  if(seconds) pcpu = (total_time * 1000ULL / Hertz) / seconds;
OK, ignoring the include _dead_time line (you get this from the S option and means you include the time this process waited for its children processes) and the scaling (process times are in Jiffies, we have the CPU as 0 to 999 for reasons) you can reduce this down to. %CPU = ( Tutime + Tstime ) / Tetime
So we find the amount of time the CPU(s) have been busy either in userland or the system, add them together, then divide the sum by the total time. The utime and stime increment like a car s odometer. So if a process uses one Jiffy of CPU time in userland, that counter goes to 1. If it does it again a few seconds later, then that counter goes to 2. To give an example, if a process has run for ten seconds and within those ten seconds the CPU has been busy in userland for that process, then we get 10/10 = 100% which makes sense. Not all Start times are the same Let s take another example, a process still consumes ten seconds CPU time but been running for twenty seconds, the answer is 10/20 or 50%. With our single CPU example system both of these cannot be running at the same time otherwise we have 150% CPU utilisation which is not possible. However, let s adjust this slightly. We have assumed uniform utilisation. But take the following scenario: The output for ps -o times,etimes,pcpu,comm would look something like:
    TIME ELAPSED %CPU COMMAND
      10      20   50 P1
      10      10  100 P2
What we will see is P1 has 10/20 or 50% CPU and P2 has 10/10 or 100% CPU. Add those up, and you have 150% CPU, magic! The key here is the ELAPSED column. P1 has given you the CPU utilisation across 20 seconds of system time and P2 the CPU utilisation across only 10 seconds. You directly add them together you get the wrong answer. What s the point of %CPU? Probably the %CPU column gives results that a lot of people are not expecting, so what s the point of it? Don t use it to see why the CPU is running hot; you can see above those two processes were working the CPU hard at different times. What it is useful for is to see how busy a process is, but be warned its an average. It s helpful for something that starts busy but if the process idles or hardly uses CPU for a week then goes bananas you won t see it. The top program, because a lot of its statistics are deltas from the last refresh, is a much better program for this sort of information about what is happening right now.

17 January 2021

Enrico Zini: OpenStreetMap maps links

Some interesting renderings of OpenStreetMap data: If you want to print out local maps, MyOSMatic is a service to generate maps of cities using OpenStreetMap data. The generated maps are available in PNG, PDF and SVG formats and are ready to be printed. On a terminal? Sure: MapSCII is a Braille & ASCII world map renderer for the console: telnet mapscii.me and explore the map with the mouse, keyboard arrows, and a and z to zoom, c to switch to block character mode, q to quit. Alternatively you can fly over it, and you might have to dodge the rare map editing bug, or have fun landing on it: A typo created a 212-story monolith in Microsoft Flight Simulator

Wouter Verhelst: SReview 0.6

... isn't ready yet, but it's getting there. I had planned to release a new version of SReview, my online video review and transcoding system that I wrote originally for FOSDEM but is being used for DebConf, too, after it was set up and running properly for FOSDEM 2020. However, things got a bit busy (both in my personal life and in the world at large), so it fell a bit by the wayside. I've now also been working on things a bit more, in preparation for an improved administrator's interface, and have started implementing a REST API to deal with talks etc through HTTP calls. This seems to be coming along nicely, thanks to OpenAPI and the Mojolicious plugin for parsing that. I can now design the API nicely, and autogenerate client side libraries to call them. While at it, because libmojolicious-plugin-openapi-perl isn't available in Debian 10 "buster", I moved the docker containers over from stable to testing. This revealed that both bs1770gain and inkscape changed their command line incompatibly, resulting in me having to work around those incompatibilities. The good news is that I managed to do so in a way that keeps running SReview on Debian 10 viable, provided one installs Mojolicious::Plugin::OpenAPI from CPAN rather than from a Debian package. Or installs a backport of that package, of course. Or, heck, uses the Docker containers in a kubernetes environment or some such -- I'd love to see someone use that in production. Anyway, I'm still finishing the API, and the implementation of that API and the test suite that ensures the API works correctly, but progress is happening; and as soon as things seem to be working properly, I'll do a release of SReview 0.6, and will upload that to Debian. Hopefully that'll be soon.
Wouter Verhelst: Dear Google

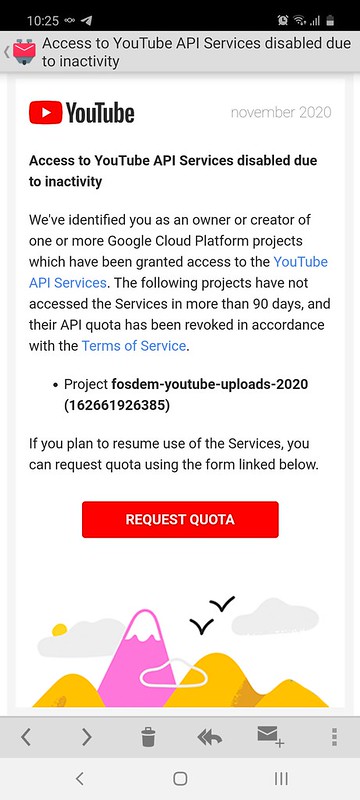
... Why do you have to be so effing difficult about a YouTube API project that is used for a single event per year? FOSDEM creates 600+ videos on a yearly basis. There is no way I am going to manually upload 600+ videos through your webinterface, so we use the API you provide, using a script written by Stefano Rivera. This script grabs video filenames and metadata from a YAML file, and then uses your APIs to upload said videos with said metadata. It works quite well. I run it from cron, and it uploads files until the quota is exhausted, then waits until the next time the cron job runs. It runs so well, that the first time we used it, we could upload 50+ videos on a daily basis, and so the uploads were done as soon as all the videos were created, which was a few months after the event. Cool! The second time we used the script, it did not work at all. We asked one of our key note speakers who happened to be some hotshot at your company, to help us out. He contacted the YouTube people, and whatever had been broken was quickly fixed, so yay, uploads worked again. I found out later that this is actually a normal thing if you don't use your API quota for 90 days or more. Because it's happened to us every bloody year. For the 2020 event, rather than going through back channels (which happened to be unavailable this edition), I tried to use your normal ways of unblocking the API project. This involves creating a screencast of a bloody command line script and describing various things that don't apply to FOSDEM and ghaah shoot me now so meh, I created a new API project instead, and had the uploads go through that. Doing so gives me a limited quota that only allows about 5 or 6 videos per day, but that's fine, it gives people subscribed to our channel the time to actually watch all the videos while they're being uploaded, rather than being presented with a boatload of videos that they can never watch in a day. Also it doesn't overload subscribers, so yay. About three months ago, I started uploading videos. Since then, every day, the "fosdemtalks" channel on YouTube has published five or six videos. Given that, imagine my surprise when I found this in my mailbox this morning... Google lies, claiming that my YouTube API project isn't being used for 90 days and informing me that it will be disabled This is an outright lie, Google. The project has been created 90 days ago, yes, that's correct. It has been used every day since then to upload videos. I guess that means I'll have to deal with your broken automatic content filters to try and get stuff unblocked... ... or I could just give up and not do this anymore. After all, all the FOSDEM content is available on our public video host, too.

Wouter Verhelst: Software available through Extrepo

Just over 7 months ago, I blogged about extrepo, my answer to the "how do you safely install software on Debian without downloading random scripts off the Internet and running them as root" question. I also held a talk during the recent "MiniDebConf Online" that was held, well, online. The most important part of extrepo is "what can you install through it". If the number of available repositories is too low, there's really no reason to use it. So, I thought, let's look what we have after 7 months... To cut to the chase, there's a bunch of interesting content there, although not all of it has a "main" policy. Each of these can be enabled by installing extrepo, and then running extrepo enable <reponame>, where <reponame> is the name of the repository. Note that the list is not exhaustive, but I intend to show that even though we're nowhere near complete, extrepo is already quite useful in its current state:

Free software
  • The debian_official, debian_backports, and debian_experimental repositories contain Debian's official, backports, and experimental repositories, respectively. These shouldn't have to be managed through extrepo, but then again it might be useful for someone, so I decided to just add them anyway. The config here uses the deb.debian.org alias for CDN-backed package mirrors.
  • The belgium_eid repository contains the Belgian eID software. Obviously this is added, since I'm upstream for eID, and as such it was a large motivating factor for me to actually write extrepo in the first place.
  • elastic: the elasticsearch software.
  • Some repositories, such as dovecot, winehq and bareos contain upstream versions of their respective software. These two repositories contain software that is available in Debian, too; but their upstreams package their most recent release independently, and some people might prefer to run those instead.
  • The sury, fai, and postgresql repositories, as well as a number of repositories such as openstack_rocky, openstack_train, haproxy-1.5 and haproxy-2.0 (there are more) contain more recent versions of software packaged in Debian already by the same maintainer of that package repository. For the sury repository, that is PHP; for the others, the name should give it away. The difference between these repositories and the ones above is that it is the official Debian maintainer for the same software who maintains the repository, which is not the case for the others.
  • The vscodium repository contains the unencumbered version of Microsoft's Visual Studio Code; i.e., the codium version of Visual Studio Code is to code as the chromium browser is to chrome: it is a build of the same softare, but without the non-free bits that make code not entirely Free Software.
  • While Debian ships with at least two browsers (Firefox and Chromium), additional browsers are available through extrepo, too. The iridiumbrowser repository contains a Chromium-based browser that focuses on privacy.
  • Speaking of privacy, perhaps you might want to try out the torproject repository.
  • For those who want to do Cloud Computing on Debian in ways that isn't covered by Openstack, there is a kubernetes repository that contains the Kubernetes stack, the as well as the google_cloud one containing the Google Cloud SDK.

Non-free software While these are available to be installed through extrepo, please note that non-free and contrib repositories are disabled by default. In order to enable these repositories, you must first enable them; this can be accomplished through /etc/extrepo/config.yaml.
  • In case you don't care about freedom and want the official build of Visual Studio Code, the vscode repository contains it.
  • While we're on the subject of Microsoft, there's also Microsoft Teams available in the msteams repository. And, hey, skype.
  • For those who are not satisfied with the free browsers in Debian or any of the free repositories, there's opera and google_chrome.
  • The docker-ce repository contains the official build of Docker CE. While this is the free "community edition" that should have free licenses, I could not find a licensing statement anywhere, and therefore I'm not 100% sure whether this repository is actually free software. For that reason, it is currently marked as a non-free one. Merge Requests for rectifying that from someone with more information on the actual licensing situation of Docker CE would be welcome...
  • For gamers, there's Valve's steam repository.
Again, the above lists are not meant to be exhaustive. Special thanks go out to Russ Allbery, Kim Alvefur, Vincent Bernat, Nick Black, Arnaud Ferraris, Thorsten Glaser, Thomas Goirand, Juri Grabowski, Paolo Greppi, and Josh Triplett, for helping me build the current list of repositories. Is your favourite repository not listed? Create a configuration based on template.yaml, and file a merge request!

Wouter Verhelst: On Statements, Facts, Hypotheses, Science, Religion, and Opinions

The other day, we went to a designer's fashion shop whose owner was rather adamant that he was never ever going to wear a face mask, and that he didn't believe the COVID-19 thing was real. When I argued for the opposing position, he pretty much dismissed what I said out of hand, claiming that "the hospitals are empty dude" and "it's all a lie". When I told him that this really isn't true, he went like "well, that's just your opinion". Well, no -- certain things are facts, not opinions. Even if you don't believe that this disease kills people, the idea that this is a matter of opinion is missing the ball by so much that I was pretty much stunned by the level of ignorance. His whole demeanor pissed me off rather quickly. While I disagree with the position that it should be your decision whether or not to wear a mask, it's certainly possible to have that opinion. However, whether or not people need to go to hospitals is not an opinion -- it's something else entirely. After calming down, the encounter got me thinking, and made me focus on something I'd been thinking about before but hadn't fully forumlated: the fact that some people in this world seem to misunderstand the nature of what it is to do science, and end up, under the claim of being "sceptical", with various nonsense things -- see scientology, flat earth societies, conspiracy theories, and whathaveyou. So, here's something that might (but probably won't) help some people figuring out stuff. Even if it doesn't, it's been bothering me and I want to write it down so it won't bother me again. If you know all this stuff, it might be boring and you might want to skip this post. Otherwise, take a deep breath and read on... Statements are things people say. They can be true or false; "the sun is blue" is an example of a statement that is trivially false. "The sun produces light" is another one that is trivially true. "The sun produces light through a process that includes hydrogen fusion" is another statement, one that is a bit more difficult to prove true or false. Another example is "Wouter Verhelst does not have a favourite color". That happens to be a true statement, but it's fairly difficult for anyone that isn't me (or any one of the other Wouters Verhelst out there) to validate as true. While statements can be true or false, combining statements without more context is not always possible. As an example, the statement "Wouter Verhelst is a Debian Developer" is a true statement, as is the statement "Wouter Verhelst is a professional Volleybal player"; but the statement "Wouter Verhelst is a professional Volleybal player and a Debian Developer" is not, because while I am a Debian Developer, I am not a professional Volleybal player -- I just happen to share a name with someone who is. A statement is never a fact, but it can describe a fact. When a statement is a true statement, either because we trivially know what it states to be true or because we have performed an experiment that proved beyond any possible doubt that the statement is true, then what the statement describes is a fact. For example, "Red is a color" is a statement that describes a fact (because, yes, red is definitely a color, that is a fact). Such statements are called statements of fact. There are other possible statements. "Grass is purple" is a statement, but it is not a statement of fact; because as everyone knows, grass is (usually) green. A statement can also describe an opinion. "The Porsche 911 is a nice car" is a statement of opinion. It is one I happen to agree with, but it is certainly valid for someone else to make a statement that conflicts with this position, and there is nothing wrong with that. As the saying goes, "opinions are like assholes: everyone has one". Statements describing opinions are known as statements of opinion. The differentiating factor between facts and opinions is that facts are universally true, whereas opinions only hold for the people who state the opinion and anyone who agrees with them. Sometimes it's difficult or even impossible to determine whether a statement is true or not. The statement "The numbers that win the South African Powerball lottery on the 31st of July 2020 are 2, 3, 5, 19, 35, and powerball 14" is not a statement of fact, because at the time of writing, the 31st of July 2020 is in the future, which at this point gives it a 1 in 24,435,180 chance to be true). However, that does not make it a statement of opinion; it is not my opinion that the above numbers will win the South African powerball; instead, it is my guess that those numbers will be correct. Another word for "guess" is hypothesis: a hypothesis is a statement that may be universally true or universally false, but for which the truth -- or its lack thereof -- cannot currently be proven beyond doubt. On Saturday, August 1st, 2020 the above statement about the South African Powerball may become a statement of fact; most likely however, it will instead become a false statement. An unproven hypothesis may be expressed as a matter of belief. The statement "There is a God who rules the heavens and the Earth" cannot currently (or ever) be proven beyond doubt to be either true or false, which by definition makes it a hypothesis; however, for matters of religion this is entirely unimportant, as for believers the belief that the statement is correct is all that matters, whereas for nonbelievers the truth of that statement is not at all relevant. A belief is not an opinion; an opinion is not a belief. Scientists do not deal with unproven hypotheses, except insofar that they attempt to prove, through direct observation of nature (either out in the field or in a controlled laboratory setting) that the hypothesis is, in fact, a statement of fact. This makes unprovable hypotheses unscientific -- but that does not mean that they are false, or even that they are uninteresting statements. Unscientific statements are merely statements that science cannot either prove or disprove, and that therefore lie outside of the realm of what science deals with. Given that background, I have always found the so-called "conflict" between science and religion to be a non-sequitur. Religion deals in one type of statements; science deals in another. The do not overlap, since a statement can either be proven or it cannot, and religious statements by their very nature focus on unprovable belief rather than universal truth. Sure, the range of things that science has figured out the facts about has grown over time, which implies that religious statements have sometimes been proven false; but is it heresy to say that "animals exist that can run 120 kph" if that is the truth, even if such animals don't exist in, say, Rome? Something very similar can be said about conspiracy theories. Yes, it is possible to hypothesize that NASA did not send men to the moon, and that all the proof contrary to that statement was somehow fabricated. However, by its very nature such a hypothesis cannot be proven or disproven (because the statement states that all proof was fabricated), which therefore implies that it is an unscientific statement. It is good to be sceptical about what is being said to you. People can have various ideas about how the world works, but only one of those ideas -- one of the possible hypotheses -- can be true. As long as a hypothesis remains unproven, scientists love to be sceptical themselves. In fact, if you can somehow prove beyond doubt that a scientific hypothesis is false, scientists will love you -- it means they now know something more about the world and that they'll have to come up with something else, which is a lot of fun. When a scientific experiment or observation proves that a certain hypothesis is true, then this probably turns the hypothesis into a statement of fact. That is, it is of course possible that there's a flaw in the proof, or that the experiment failed (but that the failure was somehow missed), or that no observance of a particular event happened when a scientist tried to observe something, but that this was only because the scientist missed it. If you can show that any of those possibilities hold for a scientific proof, then you'll have turned a statement of fact back into a hypothesis, or even (depending on the exact nature of the flaw) into a false statement. There's more. It's human nature to want to be rich and famous, sometimes no matter what the cost. As such, there have been scientists who have falsified experimental results, or who have claimed to have observed something when this was not the case. For that reason, a scientific paper that gets written after an experiment turned a hypothesis into fact describes not only the results of the experiment and the observed behavior, but also the methodology: the way in which the experiment was run, with enough details so that anyone can retry the experiment. Sometimes that may mean spending a large amount of money just to be able to run the experiment (most people don't have an LHC in their backyard, say), and in some cases some of the required materials won't be available (the latter is expecially true for, e.g., certain chemical experiments that involve highly explosive things); but the information is always there, and if you spend enough time and money reading through the available papers, you will be able to independently prove the hypothesis yourself. Scientists tend to do just that; when the results of a new experiment are published, they will try to rerun the experiment, partially because they want to see things with their own eyes; but partially also because if they can find fault in the experiment or the observed behavior, they'll have reason to write a paper of their own, which will make them a bit more rich and famous. I guess you could say that there's three types of people who deal with statements: scientists, who deal with provable hypotheses and statements of fact (but who have no use for unprovable hypotheses and statements of opinion); religious people and conspiracy theorists, who deal with unprovable hypotheses (where the religious people deal with these to serve a large cause, while conspiracy theorists only care about the unprovable hypotheses); and politicians, who should care about proven statements of fact and produce statements of opinion, but who usually attempt the reverse of those two these days :-/ Anyway... [[!img Error: Image::Magick is not installed]]

Junichi Uekawa: Yesterday was our monthly Debian meeting.

Yesterday was our monthly Debian meeting. We do one every month for Tokyo and Kansai combined, because it's online and no reason to split for now. I presented what I learnt about nodejs packaging in Debian. This time, I started using Emacs for presentation, presenting PDF file. This week I switched most of my login shells to emacsclient, and experimenting. It's interesting how much things break, and how much I depended on .bashrc and .profile being loaded. But most things work and I don't need most things outside of emacs...
16 January 2021

Christian Kastner: Keeping your Workstation Silent

I require moderately powerful boxes for my work. Moderately powerful boxes generate a non-negligible amount of heat, and therefore require appropriate cooling. Most cooling solutions involve a certain degree of noise, which I dislike. Water-cooling is supposed to be the most effective solution for noise reduction, but it always felt like too much of a hassle to try to me. Considering the various solutions I've tried in the past years, two observations I've made really stick out:
  1. Noctua's reputation for CPU cooling is well-earned.
  2. A "silent" (meaning sound-proofed) case, isn't. At least, not anymore.
I've tried numerous coolers in the past, some of monstrous proportions (always thinking that more mass must be better, and reputable brands are equally good), but I was never really satisfied; hence, I was doubtful that trying yet another cooler would make a difference. I'm glad I tried the Noctua NH-D15 anyway. With some tweaking to the fan profile in the BIOS, it's totally inaudible at normal to medium workloads, and just a very gentle hum at full load subtle enough to disappear in the background. For the past decade, I've also regularly purchased sound-proofed cases, but this habit appears anachronistic now. Years ago, sound-proofed cases helped contain the noise of a few HDDs. However, all of my boxes now contain NVMe drives (which, to me, are the biggest improvement to computing since CPUs going multi-core). On the other hand, some of my boxes now contain powerful GPUs used for GPGPU computing, and with the recent higher-end Nvidia and AMD cards all pulling in over 300W, there is a lot of heat to manage. The best way to quickly dump heat is with good airflow. Sound-proofing works against that. Its insulation restricts airflow, which ultimately causes even more noise, as the GPU's fans need to spin at very high RPMs. This is, of course, totally obvious in hindsight. I removed the front cover from a new GPU box, and the noise went down from almost-hair-dryer to acceptable-whoosh levels. I'm wondering whether a completely open box might not be even more effective.

Abhijith PA: Transition from Thunderbird to Mutt

I was going OK with Thunderbird and enigmail(though it have many problems). Normally I go through changelogs before updating packages and rarely do a complete upgrage of my machine. Couple of days ago I did a complete upgrade of system which updated my Thunderbird to latest version and throwing of enigmail plugin for using their native openPGP support. There is a blog from Mozilla which I should ve read earlier. Thunderbird s builtin openPGP functionality is still in experimental, atleast not ready for my workflow. I could ve downgrade to version 68. But I chose to move to my secondary MUA, mutt. I was using mutt for emails and newsletters that I check twice in a year a so. So I started configuring mutt to handle my big mailboxes. It took three evenings to configure mutt to my workflow. Though the basic setup can be done in less than an hour it is the small nitpicks consumed much of my time. Currently I have isync to pull and keep mails offline. Mutt to read, msmtp to send, abook as the email address book and urlview to see the links in mail. I am still learning notmuch and virtual mailbox ways to filter. Mutt There are ton of articles out there to configure mutt and all related things to it. But I find certain configs very hard to get. So I will write down those. So far, everything going okay.

Cons
  • some times mbsync throws EOF and secret key not found error.
  • searching is still a pain in mutt
  • nano s spell checker also check things which I am replying to.

More to come Well for now I moved mail from part of the Thunderbird. But Thunderbird was more than a MUA to me. It was my RSS reader, calendar and to-do list manager. I will write more about those once I make a complete transition.

15 January 2021

Dirk Eddelbuettel: Rcpp 1.0.6: Some Updates

rcpp logo The Rcpp team is proud to announce release 1.0.6 of Rcpp which arrived at CRAN earlier today, and has been uploaded to Debian too. Windows and macOS builds should appear at CRAN in the next few days. This marks the first release on the new six-months cycle announced with release 1.0.5 in July. As reminder, interim dev or rc releases will often be available in the Rcpp drat repo; this cycle there were four. Rcpp has become the most popular way of enhancing R with C or C++ code. As of today, 2174 packages on CRAN depend on Rcpp for making analytical code go faster and further (which is an 8.5% increase just since the last release), along with 207 in BioConductor. This release features six different pull requests from five different contributors, mostly fixing fairly small corner cases, plus some minor polish on documentation and continuous integration. Before releasing we once again made numerous reverse dependency checks none of which revealed any issues. So the passage at CRAN was pretty quick despite the large dependency footprint, and we are once again grateful for all the work the CRAN maintainers do.

Changes in Rcpp patch release version 1.0.6 (2021-01-14)
  • Changes in Rcpp API:
    • Replace remaining few uses of EXTPTR_PTR with R_ExternalPtrAddr (Kevin in #1098 fixing #1097).
    • Add push_back and push_front for DataFrame (Walter Somerville in #1099 fixing #1094).
    • Remove a misleading-to-wrong comment (Mattias Ellert in #1109 cleaning up after #1049).
    • Address a sanitizer report by initializing two private bool variables (Benjamin Christoffersen in #1113).
    • External pointer finalizer toggle default values were corrected to true (Dirk in #1115).
  • Changes in Rcpp Documentation:
    • Several URLs were updated to https and/or new addresses (Dirk).
  • Changes in Rcpp Deployment:
    • Added GitHub Actions CI using the same container-based setup used previously, and also carried code coverage over (Dirk in #1128).
  • Changes in Rcpp support functions:
    • Rcpp.package.skeleton() avoids warning from R. (Dirk)

Thanks to my CRANberries, you can also look at a diff to the previous release. Questions, comments etc should go to the rcpp-devel mailing list off the R-Forge page. Bugs reports are welcome at the GitHub issue tracker as well (where one can also search among open or closed issues); questions are also welcome under rcpp tag at StackOverflow which also allows searching among the (currently) 2616 previous questions. If you like this or other open-source work I do, you can sponsor me at GitHub. My sincere thanks to my current sponsors for me keeping me caffeinated.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

Next.

Previous.

