Search Results: "tar"

1 April 2016

Francois Marier: How Safe Browsing works in Firefox

Firefox has had support for Google's Safe Browsing since 2005 when it started as a stand-alone Firefox extension. At first it was only available in the USA, but it was opened up to the rest of the world in 2006 and moved to the Google Toolbar. It then got integrated directly into Firefox 2.0 before the public launch of the service in 2007. Many people seem confused by this phishing and malware protection system and while there is a pretty good explanation of how it works on our support site, it doesn't go into technical details. This will hopefully be of interest to those who have more questions about it.

Browsing Protection The main part of the Safe Browsing system is the one that watches for bad URLs as you're browsing. Browsing protection currently protects users from: If a Firefox user attempts to visit one of these sites, a warning page will show up instead, which you can see for yourself here: The first two warnings can be toggled using the browser.safebrowsing.malware.enabled preference (in about:config) whereas the last one is controlled by browser.safebrowsing.enabled.

List updates It would be too slow (and privacy-invasive) to contact a trusted server every time the browser wants to establish a connection with a web server. Instead, Firefox downloads a list of bad URLs every 30 minutes from the server (browser.safebrowsing.provider.google.updateURL) and does a lookup against its local database before displaying a page to the user. Downloading the entire list of sites flagged by Safe Browsing would be impractical due to its size so the following transformations are applied:
  1. each URL on the list is canonicalized,
  2. then hashed,
  3. of which only the first 32 bits of the hash are kept.
The lists that are requested from the Safe Browsing server and used to flag pages as malware/unwanted or phishing can be found in urlclassifier.malwareTable and urlclassifier.phishTable respectively. If you want to see some debugging information in your terminal while Firefox is downloading updated lists, turn on browser.safebrowsing.debug. Once downloaded, the lists can be found in the cache directory:
  • ~/.cache/mozilla/firefox/XXXX/safebrowsing/ on Linux
  • ~/Library/Caches/Firefox/Profiles/XXXX/safebrowsing/ on Mac
  • C:\Users\XXXX\AppData\Local\mozilla\firefox\profiles\XXXX\safebrowsing\ on Windows

Resolving partial hash conflicts Because the Safe Browsing database only contains partial hashes, it is possible for a safe page to share the same 32-bit hash prefix as a bad page. Therefore when a URL matches the local list, the browser needs to know whether or not the rest of the hash matches the entry on the Safe Browsing list. In order resolve such conflicts, Firefox requests from the Safe Browsing server (browser.safebrowsing.provider.mozilla.gethashURL) all of the hashes that start with the affected 32-bit prefix and adds these full-length hashes to its local database. Turn on browser.safebrowsing.debug to see some debugging information on the terminal while these "completion" requests are made. If the current URL doesn't match any of these full hashes, the load proceeds as normal. If it does match one of them, a warning interstitial page is shown and the load is canceled.

Download Protection The second part of the Safe Browsing system protects users against malicious downloads. It was launched in 2011, implemented in Firefox 31 on Windows and enabled in Firefox 39 on Mac and Linux. It roughly works like this:
  1. Download the file.
  2. Check the main URL, referrer and redirect chain against a local blocklist (urlclassifier.downloadBlockTable) and block the download in case of a match.
  3. On Windows, if the binary is signed, check the signature against a local whitelist (urlclassifier.downloadAllowTable) of known good publishers and release the download if a match is found.
  4. If the file is not a binary file then release the download.
  5. Otherwise, send the binary file's metadata to the remote application reputation server (browser.safebrowsing.downloads.remote.url) and block the download if the server indicates that the file isn't safe.
Blocked downloads can be unblocked by right-clicking on them in the download manager and selecting "Unblock". While the download protection feature is automatically disabled when malware protection (browser.safebrowsing.malware.enabled) is turned off, it can also be disabled independently via the browser.safebrowsing.downloads.enabled preference. Note that Step 5 is the only point at which any information about the download is shared with Google. That remote lookup can be suppressed via the browser.safebrowsing.downloads.remote.enabled preference for those users concerned about sending that metadata to a third party.

Types of malware The original application reputation service would protect users against "dangerous" downloads, but it has recently been expanded to also warn users about unwanted software as well as software that's not commonly downloaded. These various warnings can be turned on and off in Firefox through the following preferences:
  • browser.safebrowsing.downloads.remote.block_dangerous
  • browser.safebrowsing.downloads.remote.block_dangerous_host
  • browser.safebrowsing.downloads.remote.block_potentially_unwanted
  • browser.safebrowsing.downloads.remote.block_uncommon
and tested using Google's test page. If you want to see how often each "verdict" is returned by the server, you can have a look at the telemetry results for Firefox Beta.

Privacy One of the most persistent misunderstandings about Safe Browsing is the idea that the browser needs to send all visited URLs to Google in order to verify whether or not they are safe. While this was an option in version 1 of the Safe Browsing protocol (as disclosed in their privacy policy at the time), support for this "enhanced mode" was removed in Firefox 3 and the version 1 server was decommissioned in late 2011 in favor of version 2 of the Safe Browsing API which doesn't offer this type of real-time lookup. Google explicitly states that the information collected as part of operating the Safe Browsing service "is only used to flag malicious activity and is never used anywhere else at Google" and that "Safe Browsing requests won't be associated with your Google Account". In addition, Firefox adds a few privacy protections:
  • Query string parameters are stripped from URLs we check as part of the download protection feature.
  • Cookies set by the Safe Browsing servers to protect the service from abuse are stored in a separate cookie jar so that they are not mixed with regular browsing/session cookies.
  • When requesting complete hashes for a 32-bit prefix, Firefox throws in a number of extra "noise" entries to obfuscate the original URL further.
On balance, we believe that most users will want to keep Safe Browsing enabled, but we also make it easy for users with particular needs to turn it off.

Learn More If you want to learn more about how Safe Browsing works in Firefox, you can find all of the technical details on the Safe Browsing and Application Reputation pages of the Mozilla wiki or you can ask questions on our mailing list. Google provides some interesting statistics about what their systems detect in their transparency report and offers a tool to find out why a particular page has been blocked. Some information on how phishing sites are detected is also available on the Google Security blog, but for more detailed information about all parts of the Safe Browsing system, see the following papers:

Bits from Debian: Debian announces partnership to sub-contract publicity and press to an outside marketing agency

Last year we started to push more of Debian news and information away the single news source of the DPN into other media services. Debian has been more active than ever on our many IRC channels, free software based social networks, and unofficial Twitter and Facebook feeds. Today we have decided to announce the next stage in keeping Debian at the forefront of media by sub-contracting publicity and press to an outside marketing agency. The marketing agency (name will be disclosed soon) has provided an AI system (running entirely with free software) which will be fed with all the content of Debian mailing lists and sources.debian.net to understand the character of the Debian community and then better customize future articles, interviews, and event news. However, some bits of personal information are also needed. Please install the "publicity" package and you'll be presented a form to fill in your data: name, surname, phone, snail mail address, place of birth, names of family members, employers or employees. Each person providing their data to the agency will receive coupon for a 20% discount in the download (purchase) of next Debian release (valid only for downloads from the official site www.debian.org). We kindly ask every Debian community member to sign up in, at least, one of theses services: Twitter, Whatsapp, Slack or Facebook (IRC, mailing lists, and free software based RTC are allegedly not so 'cool'). Users need not be concerned with losing the features that the IRC bots provide (so long KGB!) as they will be replaced by Tay-like AI systems. The most visible change will be that MeetBot will no longer log the meetings anymore, but we have bribed an NSA employee so they pass the relevant messages to us. "If this 'centralization, outsourcing and pay-and-forget' approach goes well with publicity, I'm considering running for DPL in 2017 to extend this model to other areas of Debian" said Laura Arjona Reina, (now) former publicity delegate. A new logo and mascot has been designed too, as a symbol of this new era embracing the standards of branding and corporate messaging. Please consider voting in favor of it, in the General Resolution that will be proposed soon: Mascot and Logo

31 March 2016

Antoine Beaupr : My free software activities, march 2016

Debian Long Term Support (LTS) This is my 4th month working on Debian LTS, started by Raphael Hertzog at Freexian. I spent half of the month away on a vacation so little work was done, especially since I tried to tackle rather large uploads like NSS and Xen. I also worked on the frontdesk shift last week.

Frontdesk That work mainly consisted of figuring out how to best help the security team with the last uploads to the Wheezy release. For those who don't know, Debian 7 Wheezy, or "oldstable", is going to be unsupported by the security team starting end of april, and the Debian 6 Squeeze (the previous LTS) is now unsupported. The PGP signatures on the archived release have started yielding expiration errors which can be ignored but that are really a strong reminder that it is really time to upgrade. So the LTS team is now working towards backporting a few security issues from squeeze to wheezy, and this is what I focused on during triage work. I have identified the following high priority packages I will work on after I complete my work on the Xen and NSS packages (detailed below):
  • libidn
  • icu
  • phpmyadmin
  • tomcat6
  • optipng
  • srtp
  • dhcpcd
  • python-tornado

Updates to NSS and Xen I have spent a lot of time testing and building packages for NSS and Xen. To be fair, Brian May did most of the work on the Xen packages, and I merely did some work to test the packages on Koumbit's infrastructure, something which I will continue doing in the next month. For NSS, wheezy and jessie are in this weird state where patches were provided to the security team all the way back in November yet were never tested. Since then, yet more issues came up and I worked hard to review and port patches for those new security issues to wheezy. I'll followup on both packages in the following month.

Other free software work

Android TL;DR: there's an even longer version of this with the step-by-step procedures and that I will update as time goes on in my wiki. I somehow inherited an Android phone recently, on a loan from a friend because the phone broke one too many times and she got a new one from her provider. This phone is a HTC One S "Ville", which is fairly old, but good enough to play with and give me a mobile computing platform to listen to podcasts, play music, access maps and create GPS traces. I was previously doing this with my N900, but that device is really showing its age: very little development is happening on it, the SDK is closed source and the device itself is fairly big, compared to the "Ville". Plus, the SIM card actually works on the Ville so, even though I do not have an actual contract with a cell phone provider (too expensive, too invasive on my privacy), I can still make emergency phone calls (911)! Plus, since there is good wifi on the machine, I can use it to connect to the phone system with the built-in SIP client, send text messages through SMS (thanks to VoIP.ms SMS support) or Jabber. I have also played around with LibreSignal, the free software replacement for Signal, which uses proprietary google services. Yes, the VoIP.ms SMS app also uses GCM, but hopefully that can be fixed. (While I was writing this, another Debian Developer wrote a good review of Signal so I am happy to skip that step. Go read that.)
See also my apps list for a more complete list of the apps I have installed on the phone. I welcome recommendations on cool free software apps I should use!
I have replaced the stock firmware on the phone with Cyanogenmod 12.1, which was a fairly painful experience, partly because of the difficult ambiance on the #cyanogenmod channel on Freenode, where I had extreme experiences: a brave soul helped me through the first flashing process for around 2 hours, nicely holding my hand at every step. Other times, I have seen flames and obtuse comments from people being vulgar, brutal, obnoxious, if not sometimes downright homophobic and sexist from other users. It is clearly a community that needs to fix their attitude. I have documented everything I could in details in this wiki page, in case others want to resuscitate their old phones, but also because I ended up reinstalling the freaking phone about 4 times, and was getting tired of forgetting how to do it every time. I am somewhat fascinated by Android: here is the Linux-based device that should save us all from the proprietary Apple nightmares of fenced in gardens and censorship. Yet, public Android downloads are hidden behind license agreements, even though the code itself is free, which has led fellow Debian developers to work on making libre rebuilds of Androids to workaround this insanity. But worse: all phones are basically proprietary devices down to the core. You need custom firmware to be loaded on the machine for it to boot at all, from the bootloader all the way down to the GSM baseband and Wifi drivers. It is a minefield of closed source software, and trying to run free software on there is a bit of a delusion, especially since the baseband has so much power over the phone. Still, I think it is really interesting to run free software on those machines, and help people that are stuck with cell phones get familiar with software freedom. It seems especially important to me to make Android developers aware of software freedom considering how many apps are available for free yet on which it is not possible to contribute significantly because the source code is not published at all, or published only on the Google Store, instead of the more open and public F-Droid repository which publishes only free software. So I did contribute. This month, I am happy to announce that I contributed to the following free software projects on Android: I have also reviewed the literature surrounding Telegram, a popular messaging app rival to Signal and Whatsapp. Oddly enough, my contributions to Wikipedia on that subject were promptly reverted which made me bring up the subject on the page's Talk page. This lead to an interesting response from the article's main editors which at least added that the "its security features have been contested by security researchers and cryptography experts". Considering the history of Telegram, I would keep people away from it and direct people to use Signal instead, even though Signal has similar metadata issues, mostly because Telegram's lack of response to the security issues that were outlined by fellow security researchers. Both systems suffer from a lack of federation as well, which is a shame in this era of increasing centralization. I am not sure I will put much more work in developing for Android for now. It seems like a fairly hostile platform to work on, and unless I have specific pain points I want to fix, it feels so much better to work on my own stuff in Debian. Which brings me to my usual plethora of free software projects I got stuck in this month.

IRC projects irssi-plugin-otr had a bunch of idiotic bugs lying around, and I had a patch that I hadn't submitted upstream from the Debian package, which needed a rebuild because the irssi version changed, which is a major annoyance. The version in sid is now a snapshot because upstream needs to make a new release but at least it should fix things for my friends running unstable and testing. Hopefully those silly uploads won't be necessary in the future. That's for the client side. On the server side, I have worked on updating the Atheme-services package to the latest version, which actually failed because the upstream libmowgli is missing release tags, which means the Debian package for it is not up-to-date either. Still, it is nice to have a somewhat newer version, even though it is not the latest and some bugs were fixed. I have also looked at making atheme reproducible but was surprised at the hostility of the upstream. In the end, it looks like they are still interested in patches, but they will be a little harder to deploy than for Charybdis, so this could take some time. Hopefully I will find time in the coming weeks to test the new atheme services daemon on the IRC network I operate.

Syncthing I have also re-discovered Syncthing, a file synchronization software. Amazingly, I was having trouble transferring a single file between two phones. I couldn't use Bluetooth (not sure why), the "Wifi sharing" app was available only on one phone (and is proprietary, and has a limit of 4MB files), and everything else requires an account, the cloud, or cabling. So. Just heading to f-droid, install syncthing, flash a few qr-codes around and voil : files are copied over! Pretty amazing: the files were actually copied over the local network, using IPv6 link-local addresses, encryption and the DHT. Which is a real geeky way of saying it's completely fast, secure and fast. Now, I found a few usability issues, so much that I wrote a whole usability story for the developers, which were really appreciative of my review. Some of the issues were already fixed, others were pretty minor. Syncthing has a great community, and it seems like a great project I encourage everyone to get familiar with.

Battery stats The battery-status project I mentionned previously has been merged with the battery-stats project (yes, the names are almost the same, which is confusing) and so I had to do some work to fix my Python graph script, which was accepted upstream and will be part of Debian officially from now on, which is cool. The previous package was unofficial. I have also noticed that my battery has a significantly than when I wrote the script. Whereas it was basically full back then, it seems now it has lost almost 15% of its capacity in about 6 months. According to the calculations of the script:
this battery will reach end of life (5%) in 935 days, 19:07:58.336480, on 2018-10-23 12:06:07.270290
Which is, to be fair, a good life: it will somewhat work for about three more years.

Playlist, git-annex and MPD in Python On top of my previously mentioned photos-import script, I have worked on two more small programs. One is called get-playlist and is an extension to git-annex to easily copy to the local git-annex repository all files present in a given M3U playlist. This is useful for me because my phone cannot possibly fit my whole MP3 collection, and I use playlists in GMPC to tag certain files, particularly the Favorites list which is populated by the "star" button in the UI. I had a lot of fun writing this script. I started using elpy as an IDE in Emacs. (Notice how Emacs got a new webpage, which is a huge improvement was had been basically unchanged since the original version, now almost 20 years old, and probably written by RMS himself.) I wonder how I managed to stay away from Elpy for so long, as it glues together key components of Emacs in an elegant and functional bundle:
  • Company: the "vim-like" completion mode i had been waiting for forever
  • Jedi: context-sensitive autocompletion for Python
  • Flymake: to outline style and syntax errors (unfortunately not the more modern Flycheck)
  • inline documentation...
In short, it's amazing and makes everything so much easier to work with that I wrote another script. The first program wouldn't work very well because some songs in the playlists had been moved, so I made another program, this time to repair playlists which refer to missing files. The script is simply called fix-playlists, and can operate transparently on multiple playlists. It has a bunch of heuristics to find files and uses a MPD server as a directory to search into. It can edit files in place or just act as a filter.

Useful snippets Writing so many scripts, so often, I figured I needed to stop wasting time always writing the same boilerplate stuff on top of every file, so I started publishing Yasnippet-compatible file snippets, in my snippets repository. For example, this report is based on the humble lts snippet. I also have a base license snippet which slaps the AGPLv3 license on top of a Python file. But the most interesting snippet, for me, is this simple script snippet which is a basic scaffolding for a commandline script that includes argument processing, logging and filtering of files, something which I was always copy-pasting around.

Other projects And finally, a list of interesting issues en vrac:
  • there's a new Bootstrap 4 theme for Ikiwiki. It was delivering content over CDNs, which is bad for privacy issues, so I filed an issue which was almost immediately fixed by the author!
  • I found out about BitHub, a tool to make payments with Bitcoins for patches submitted on OWS projects. It wasn't clear to me where to find the demo, but when I did, I quickly filed a PR to fix the documentation. Given the number of open PRs there and the lack of activity, I wonder if the model is working at all...
  • a fellow Debian Developer shared his photos workflow, which was interesting to me because I have my own peculiar script, which I never mentionned here, but which I ended up sharing with the author

Chris Lamb: Free software activities in March 2016

Here is my monthly update covering a large part of what I have been doing in the free software world (previously):
Debian
  • Presented Reproducible Builds - fulfilling the original promise of free software at FOSSASIA '16.
  • Uploaded libfiu (0.94-4), adding a patch from Logan Rose to fix a FTBFS with ld --as-needed.
My work in the Reproducible Builds project was also covered in more depth in Lunar's weekly reports (#44, #45, #46, #47).
LTS

This month I have been paid to work 7 hours on Debian Long Term Support (LTS). Whilst the LTS team will take over support from the Security Team on April 26, 2016, in the meantime I did the following:
  • Archived the squeeze distribution (via the FTPteam).
  • Assisted in preparing updates for python-django.
  • Helping end-users migrate to wheezy now that squeeze LTS has reached end-of-life.


FTP Team

As a Debian FTP assistant I ACCEPTed 143 packages: acme-tiny, berkshelf-api, circlator, cloud-utils, corsix-th, cronic, diaspora-installer, dub, dumb-init, firehol, firetools, flask-bcrypt, flask-oldsessions, flycheck, ganeti, geany-plugins, git-build-recipe, git-phab, gnome-shell-extension-caffeine, gnome-shell-extension-mediaplayer, golang-github-cheggaaa-pb, golang-github-coreos-ioprogress, golang-github-cyberdelia-go-metrics-graphite, golang-github-cznic-ql, golang-github-elazarl-goproxy, golang-github-hashicorp-hil, golang-github-mitchellh-go-wordwrap, golang-github-mvdan-xurls, golang-github-paulrosania-go-charset, golang-github-xeipuuv-gojsonreference, golang-github-xeipuuv-gojsonschema, grilo-plugins, gtk3-nocsd, herisvm, identity4c, lemonldap-ng, libisal, libmath-gsl-perl, libmemcached-libmemcached-perl, libplack-middleware-logany-perl, libplack-middleware-logwarn-perl, libpng1.6, libqmi, librdf-generator-http-perl, libtime-moment-perl, libvirt-php, libxml-compile-soap-perl, libxml-compile-wsdl11-perl, linux, linux-tools, mdk-doc, mesa, mpdecimal, msi-keyboard, nauty, node-addressparser, node-ansi-regex, node-argparse, node-array-find-index, node-base62, node-co, node-component-consoler, node-crypto-cacerts, node-decamelize, node-delve, node-for-in, node-function-bind, node-generator-supported, node-invert-kv, node-json-localizer, node-normalize-git-url, node-nth-check, node-obj-util, node-read-file, node-require-dir, node-require-main-filename, node-seq, node-starttls, node-through, node-uid-number, node-uri-path, node-url-join, node-xmlhttprequest-ssl, ocrmypdf, octave-netcdf, open-infrastructure-container-tools, osmose-emulator, pdal, pep8, pg-backup-ctl, php-guzzle, printrun, pydocstyle, pysynphot, python-antlr3, python-biom-format, python-brainstorm, python-django-adminsortable, python-feather-format, python-gevent, python-lxc, python-mongoengine, python-nameparser, python-pdal, python-pefile, python-phabricator, python-pika-pool, python-pynlpl, python-qtawesome, python-requests-unixsocket, python-saharaclient, python-stringtemplate3, r-cran-adegraphics, r-cran-assertthat, r-cran-bold, r-cran-curl, r-cran-data.table, r-cran-htmltools, r-cran-httr, r-cran-lazyeval, r-cran-mcmc, r-cran-openssl, r-cran-pbdzmq, r-cran-rncl, r-cran-uuid, rawtran, reel, ruby-certificate-authority, ruby-rspec-pending-for, ruby-ruby-engine, ruby-ruby-version, scribus-ng, specutils, symfony, tandem-mass, tdb, thrift, udfclient, vala, why3, wmaker, xdg-app & xiccd.

Lars Wirzenius: New job: QvarnLabs

Today was my last day at Suomen Tilaajavastuu, where I worked on Qvarn. Tomorrow is my first day at my new job. The new job is for a new company, tentatively named QvarnLabs (registration is in process), to further develop and support Qvarn. The new company starts operation tomorrow, so you'll have to excuse me that there isn't a website yet. Qvarn provides a secure, RESTful JSON HTTP API for storing and retrieving data, with detailed access control (and I can provide more buzzwords if necessary). If you operate in the EU, and store information about people, you might want to read up about the General Data Protection Regulation, and Qvarn may be a possible part of a solution you want to look into, once we have the website up.

30 March 2016

Julien Danjou: The OpenStack Schizophrenia

When I started contributing to OpenStack, almost five years ago, it was a small ecosystem. There were no foundation, a handful of projects and you could understand the code base in a few days. Fast forward 2016, and it is a totally different beast. The project grew to no less than 54 teams, each team providing one or more deliverable. For example, the Nova and Swift team each one produces one service and its client, whereas the Telemetry team produces 3 services and 3 different clients. In 5 years, OpenStack went to a few IaaS projects, to 54 different teams tackling different areas related to cloud computing. Once upon a time, OpenStack was all about starting some virtual machines on a network, backed by images and volumes. Nowadays, it's also about orchestrating your network deployment over containers, while managing your application life-cycle using a database service, everything being metered and billed for. This exponential growth has been made possible with the decision of the OpenStack Technical Committee to open the gates with the project structure reform voted at the end of 2014. This amendment suppresses the old OpenStack model of "integrated projects" (i.e. Nova, Glance, Swift ). The big tent, as it's called, allowed OpenStack to land new projects every month, growing from the 20 project teams of December 2014 to the 54 we have today multiplying the number of projects by 2.7 in a little more than a year. Amazing growth, right? And this was clearly a good change. I sat at the Technical Committee in 2013, when projects were trying to apply to be "integrated", after Ceilometer and Heat were. It was painful to see how the Technical Committee was trying to assess whether new projects should be brought in or not. But what I notice these days, is how OpenStack is still stuck between its old and new models. On one side, it accepted a lot of new teams, but on the other side, many are considered as second-class citizens. Efforts are made to continue to build an OpenStack project that does not exist anymore. For example, there is a team trying to define what's OpenStack core, named DefCore. That is looking to define which projects are, somehow, actually OpenStack. This leads to weird situations, such as having non-DefCore projects seeing their doc rejected from installation guides. Again, I reiterated my proposal to publish documentation as part of each project code to solve that dishonest situation and put everything on a level playing field Some cross-projects specs are also pushed without implication of all OpenStack projects. For example, The deprecate-cli spec which proposes to deprecate command-line interface tools proposed by each project had a lot of sense in the old OpenStack sense, where the goal was to build a unified and ubiquitous cloud platform. But when you now have tens of projects with largely different scopes, this start making less sense. Still, this spec was merged by the OpenStack Technical Committee this cycle. Keystone is the first project to proudly force users to rely on openstack-client, removing its old keystone command line tool. I find it odd to push that specs when it's pretty clear that some projects (e.g. Swift, Gnocchi ) have no intention to go down that path. Unfortunately, most specs pushed by the Technical Committee are in the realm of wishful thinking. It somehow makes sense, since only a few of the members are actively contributing to OpenStack projects, and they can't by themselves implement all of that magically. But OpenStack is no exception in the free software world and remains a do-ocracy. There is good cross-project content in OpenStack, such as the API working group. While the work done should probably not be OpenStack specific, there's a lot that teams have learned by building various HTTP REST API with different frameworks. Compiling this knowledge and offering it as a guidance to various teams is a great help. My fellow developer Chris Dent wrote a post about what he would do on the Technical Committee. In this article, he points to a lot of the shortcomings I described here, and his confusion between OpenStack being a product or being a kit is quite understandable. Indeed, the message broadcasted by OpenStack is still very confusing after the big tent openness. There's no enough user experience improvement being done. The OpenStack Technical Committee election is opened for April 2016, and from what I read so far, many candidates are proposing to now clean up the big tent, kicking out projects that do not match certain criteria anymore. This is probably a good idea, there is some inactive project laying around. But I don't think that will be enough to solve the identity crisis that OpenStack is experiencing. So this is why, once again this cycle, I will throw my hat in the ring and submit my candidacy for OpenStack Technical Committee.

Colin Watson: Re-signing PPAs

Julian has written about their efforts to strengthen security in APT, and shortly before that notified us that Launchpad s signatures on PPAs use weak SHA-1 digests. Unfortunately we hadn t noticed that before; GnuPG s defaults tend to result in weak digests unless carefully tweaked, which is a shame. I started on the necessary fixes for this immediately we heard of the problem, but it s taken a little while to get everything in place, and I thought I d explain why since some of the problems uncovered are interesting in their own right. Firstly, there was the relatively trivial matter of using SHA-512 digests on new signatures. This was mostly a matter of adjusting our configuration, although writing the test was a bit tricky since PyGPGME isn t as helpful as it could be. (Simpler repository implementations that call gpg from the command line should probably just add the --digest-algo SHA512 option instead of imitating this.) After getting that in place, any change to a suite in a PPA will result in it being re-signed with SHA-512, which is good as far as it goes, but we also want to re-sign PPAs that haven t been modified. Launchpad hosts more than 50000 active PPAs, though, a significant percentage of which include packages for sufficiently recent Ubuntu releases that we d want to re-sign them for this. We can t expect everyone to push new uploads, and we need to run this through at least some part of our usual publication machinery rather than just writing a hacky shell script to do the job (which would have no idea which keys to sign with, to start with); but forcing full reprocessing of all those PPAs would take a prohibitively long time, and at the moment we need to interrupt normal PPA publication to do this kind of work. I therefore had to spend some quality time working out how to make things go fast enough. The first couple of changes (1, 2) were to add options to our publisher script to let us run just the one step we need in careful mode: that is, forcibly re-run the Release file processing step even if it thinks nothing has changed, and entirely disable the other steps such as generating Packages and Sources files. Then last week I finally got around to timing things on one of our staging systems so that we could estimate how long a full run would take. It was taking a little over two seconds per archive, which meant that if we were to re-sign all published PPAs then that would take more than 33 hours! Obviously this wasn t viable; even just re-signing xenial would be prohibitively slow. The next question was where all that time was going. I thought perhaps that the actual signing might be slow for some reason, but it was taking about half a second per archive: not great, but not enough to account for most of the slowness. The main part of the delay was in fact when we committed the database transaction after processing each archive, but not in the actual PostgreSQL commit, rather in the ORM invalidate method called to prepare for a commit. Launchpad uses the excellent Storm for all of its database interactions. One property of this ORM (and possibly of others; I ll cheerfully admit to not having spent much time with other ORMs) is that it uses a WeakValueDictionary to keep track of the objects it s populated with database results. Before it commits a transaction, it iterates over all those alive objects to note that if they re used in future then information needs to be reloaded from the database first. Usually this is a very good thing: it saves us from having to think too hard about data consistency at the application layer. But in this case, one of the things we did at the start of the publisher script was:
def getPPAs(self, distribution):
    """Find private package archives for the selected distribution."""
    if (self.isCareful(self.options.careful_publishing) or
            self.options.include_non_pending):
        return distribution.getAllPPAs()
    else:
        return distribution.getPendingPublicationPPAs()
def getTargetArchives(self, distribution):
    """Find the archive(s) selected by the script's options."""
    if self.options.partner:
        return [distribution.getArchiveByComponent('partner')]
    elif self.options.ppa:
        return filter(is_ppa_public, self.getPPAs(distribution))
    elif self.options.private_ppa:
        return filter(is_ppa_private, self.getPPAs(distribution))
    elif self.options.copy_archive:
        return self.getCopyArchives(distribution)
    else:
        return [distribution.main_archive]
That innocuous-looking filter means that we do all the public/private filtering of PPAs up-front and return a list of all the PPAs we intend to operate on. This means that all those objects are alive as far as Storm is concerned and need to be considered for invalidation on every commit, and the time required for that stacks up when many thousands of objects are involved: this is essentially accidentally quadratic behaviour, because all archives are considered when committing changes to each archive in turn. Normally this isn t too bad because only a few hundred PPAs need to be processed in any given run; but if we re running in a mode where we re processing all PPAs rather than just ones that are pending publication, then suddenly this balloons to the point where it takes a couple of seconds. The fix is very simple, using an iterator instead so that we don t need to keep all the objects alive:
from itertools import ifilter
def getTargetArchives(self, distribution):
    """Find the archive(s) selected by the script's options."""
    if self.options.partner:
        return [distribution.getArchiveByComponent('partner')]
    elif self.options.ppa:
        return ifilter(is_ppa_public, self.getPPAs(distribution))
    elif self.options.private_ppa:
        return ifilter(is_ppa_private, self.getPPAs(distribution))
    elif self.options.copy_archive:
        return self.getCopyArchives(distribution)
    else:
        return [distribution.main_archive]
After that, I turned to that half a second for signing. A good chunk of that was accounted for by the signContent method taking a fingerprint rather than a key, despite the fact that we normally already had the key in hand; this caused us to have to ask GPGME to reload the key, which requires two subprocess calls. Converting this to take a key rather than a fingerprint gets the per-archive time down to about a quarter of a second on our staging system, about eight times faster than where we started. Using this, we ve now re-signed all xenial Release files in PPAs using SHA-512 digests. On production, this took about 80 minutes to iterate over around 70000 archives, of which 1761 were modified. Most of the time appears to have been spent skipping over unmodified archives; even a few hundredths of a second per archive adds up quickly there. The remaining time comes out to around 0.4 seconds per modified archive. There s certainly still room for speeding this up a bit. We wouldn t want to do this procedure every day, but it s acceptable for occasional tasks like this. I expect that we ll similarly re-sign wily, vivid, and trusty Release files soon in the same way.

NOKUBI Takatsugu: GAME-ON the historical videogame exhibition

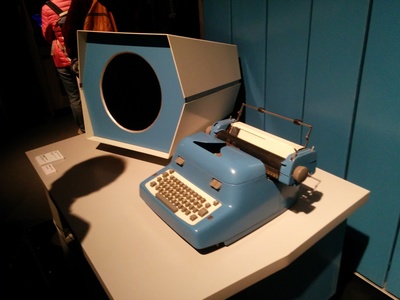
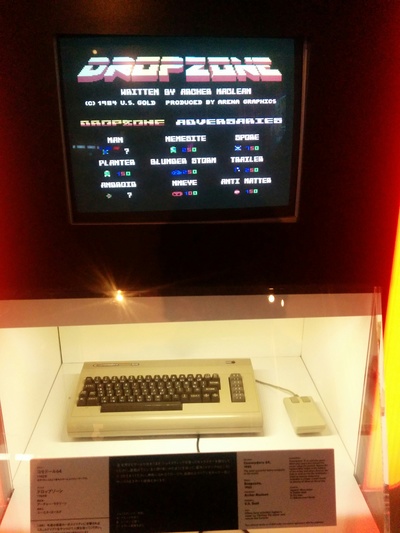
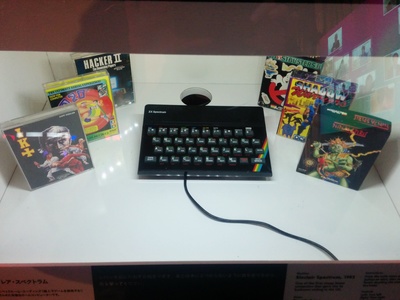
I attended GAME-ON last weedkend at Miraikan, The National Museum of Emerging Science and Innovation in Tokyo. There are many historical videogame hardware and software, and the bland-new PSVR exibition. DEC PDP-1 DisplayI can see the real DEC PDP-1 hardware. Unfortunately it is only haredware, not worked. And also PONG is exibited.
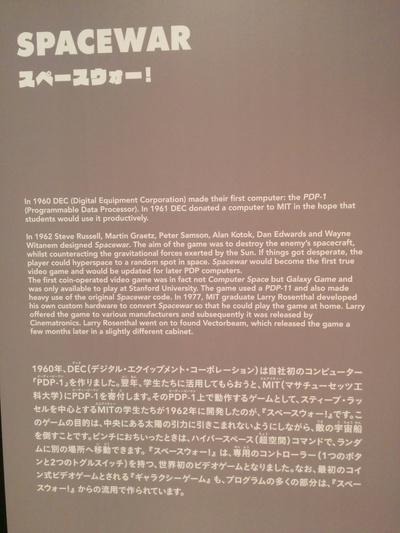
SPACEWAR description

SPACEWAR description

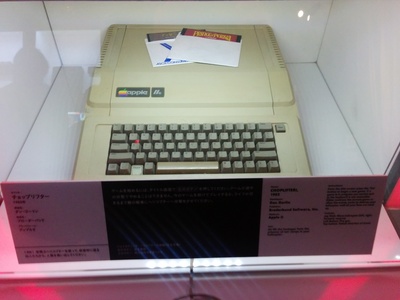
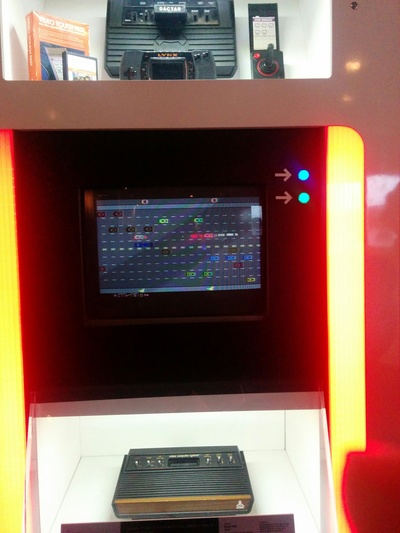
There are many old hardware Atari 2600, Commodore 64, Spectrum, and so on. Apple IIe Atari 2600/VCS Commodore 64 Spectrum Almost exhibition with English description, and officials can talk English, if you feel interested, go Miraikan until 30th May.

29 March 2016

Rog rio Brito: Partially switching to Chromium

In the interest of being as brief as possible (just ask for details if you want to know more or if you think that it would help), I have started, against my preferences, to start using chromium from Debian instead of Firefox (aka, Iceweasel). The reason? I have a slow computer (a Core 2 Duo T7250). My main computer. My workhorse. There are some sites that even with an empty profile and a vanilla Firefox build right from Mozilla Foundation cause Firefox to generate a very heavy CPU load. I briefly reported this via Twitter to one (but not the only!) of the sites in question and to Firefox Site Compatibility. What do I see? Many CSS and redraw events (thanks to Firefox's profiling tools). In fact, as many events that Firefox alone is able to completely take over 1 (of the 2) cores that I have, with just that single tab open. I don't see those problems with Chromium, unfortunately (or, at least, they are not that perceptible to my computer's CPU). So, before I go on and formally file a bug report, I would love to confirm if other people see the same problems that I am seeing. Do you also see something similar? Your input is highly welcome!

28 March 2016

Rhonda D'Vine: Ich bin was ich bin

As my readers probably are well aware, I wrote my transgender coming out poem Mermaids over 10 years ago, to make it clear to people how I define, what I am and how I would hope they could accept me. I did put it publicly into my blog so I could point people to it. And I still do so regularly. It still comes from the bottom of my heart. And I am very happy that I got the chance to present it in a Poetry Slam last year, it was even recorded and uploaded to YouTube. There is just one thing that I was also told over the time every now and then by some people that I would have liked to understand what's going on: Why is it in English, my English isn't that good. My usual response was along the lines of that the events that triggered me writing it were in an international context and I wanted to make sure that they understood what I wrote. At that time I didn't realize that I am cutting out a different group of people from being able to understand what's going on inside me. So this year there was a similar event: the Flawless Poetry Slam which touched the topics of Feminist? Queer? Gender? Rolemodels? - Let's talk about it. I took that as motivation to finally write another text on the topic, and this time in German. Unfortunately though I wasn't able to present it that evening, I wasn't drawn for the lineup. But, I was told that there was another slam going on just last wednesday, so I went there ... and made it onto the stage! And this is the text that I presented there. I am uncertain how well online translators work for you, but I hope you get the core points if you don't understand German:
Ich bin was ich bin
F nf Worte mit wahrem Sinn:
Ich bin was ich bin Du denkst: "Mann im Rock?
Das ist ja wohl l cherlich,
der ist sicher schwul." "Fingernagellack?
Na da schau ich nicht mehr hin,
wer will das schon seh'n." Jedoch liegst du falsch,
Mit all deinen Punkten, denn:
Ich bin was ich bin. Ich bin Transgender
Und erlebe mich selber,
ich bin eine Frau. "Haha, eine Frau?
Wem willst du das weismachen?
Heb mal den Rock hoch!" Und wie ist's bei dir?
Was ist zwischen den Beinen?
Geht mich das nichts an? Warum fragst du mich?
Da ist's dann in Ordnung?
Oder vielleicht nicht? Ich bin was ich bin
F nf Worte mit ernstem Sinn:
Ich bin was ich bin Ich steh weiblich hier
Und das hier ist mein K rper
Mein Geschlecht ist's auch Oberfl chlichkeit
Das ist mein gr tes Problem
Schl gt mir entgegen Wenn ich mich ffne
Verst ndnis fast berall
Es wird akzeptiert Doch gelegentlich
und das schmerzt mich am meisten
sagt doch mal wer "er" Von Fremden? Egal
Doch hab ich mich ge ffnet
Ist es eine Qual "Ich seh dich als Mann"
Da ist, was es transportiert
Akzeptanz? Dahin Meine Pronomen
Wenn ihr ber mich redet
sind sie, ihr, ihres Ich leb was ich leb
F nf Worte mit tiefem Sinn:
Ich bin was ich bin "Doch, wie der erst spricht!
Ich meinte, wie sie denn spricht!
Das ist nicht normal." Ich schreib hier Haikus:
Japanische Gedichtsform
Mit fixem Versmars Sind f nf, sieben, f nf
Silben in jeder Zeile
Haikus sind simpel Probier es mal aus
Transportier eine Message
Es macht auch viel Spa Wortwahl ist wichtig
Ein guter Thesaurus hilft
Sei kurz und pr gnant Ich sag was ich sag
F nf Worte mit klugem Sinn:
Ich bin was ich bin Doch ich schweife ab
Verst ndnis fast berall?
Wird es akzeptiert? Erstaunlicherweise
Doch ich bin auch was and'res
Und hier geht's bergab Eine Sache gibt's
Die erw h'n ich besser nicht
f r die steck ich ein "Deshalb bin ich hier"
So der Titel eines Lieds
verfasst von Thomas D "Wenn ich erkl re
warum ich mich wie ern hr"
So weit komm ich nicht Man erw hnt Vegan
Die Intoleranz ist da
Man ist unten durch "Mangelerscheinung!"
"Das Essen meines Essens!"
Akzeptanz ade Hab 'ne Theorie:
Vegan sein: 'ne Entscheidung
Transgender sein nicht Mensch f hlt sich dann schlecht
dass bei sich selbst die Kraft fehlt
und greift damit an "Ich k nnte das nicht"
Ich verurteile dich nicht
Iss doch was du willst Ich zwing es nicht auf
Aber R cksicht w r schon fein
Statt nur Hohn und Schm h Ich ess was ich ess
F nf Worte zum nachdenken:
Ich bin was ich bin
Hope you get the idea. The audience definitely liked it, the jury wasn't so much on board but that's fine, it's five random people and it's mostly for fun anyway. Later that night though some things happened that didn't make me feel so comfortable anymore. I went to the loo, waiting in line with the other ladies, a bit later the waitress came along telling me "the men's room is over there". I told her that I'm aware of that and thanked her, which got her confused and said something along the lines of "so you are both, or what?" but went away after that. Her tone and response wasn't really giving me much comfort, though none of the other ladies in the line did look strangely.
But the most disturbing event after that was to find out about North Carolina signed the bathroom bill making it illegal for trans people to use the bathroom for their gender and insisting on using the one for the gender they were assigned at birth. So men like James Sheffield are now forced to go to the lady's restroom, or face getting arrested. Brave new world. :/ So, enjoy the text and don't get too wound up by stupid laws and hope for time to fix people's discriminatory minds for fixing issues that already are regulated: Assaults are assaults and are already banned. Arguing with people might get assaulted and thus discriminating trans people is totally missing the point, by miles.

/personal permanent link Comments: 2 Flattr this

Lucy Wayland: Stuffed Butternut Squash

This is a fusion recipe from a rather bland just stuff it with ricotta recipe I saw, David Scott s The Peniless Vegetarian , and my own mutations on those themes. I can t give you exact quantities, just make a little more than you will make the hollowed mound (grin), and the rest will make an excellent pasta sauce. Ingredients For an average sized butternut squash, you will need:
1 onion (I prefer red)
3 cloves of garlic
1 capsicum pepper (I prefer green, my ex- preferred red)
Some red lentils
Optional green or brown lentils for texture and flavour. I used some puy
The lentil quantity is hard to estimate, but I ratio 4 red to 1 optional.
Roughly one handful of chopped mushrooms i.e. when chopped, it is one handful
1 tin tinned tomatoes
Some tomato puree
A generous amout of garam masala garam masala is what brings out the flavout in lentils
Some paprike
Optional chilli if using chilli, I recommend fresh of course.
Optional Balsamic vinegar
Optional Marmite Preperation of the Squash
1. Cut the butternut squash in half, length ways. This is very hard, you will need a good large knife, and may require you jumping up and down into the air. This is the second most hard of the procedure. 2. For each half, scoop out the seeds, and pare back the bowl till it is no longer overly fibrous. Discard this, or find a use for the seeds. 3. For each half, scoop a channel of the softer flesh up from the baisin up near the top. This has to be done by feel, is hard and thankless work. Also experimentation required. Reserve this flesh. Preperation of the Filling This is just basically a nice lentil sauce that can be used with pasta, rice, toast etc. Important: this is not a stir fry, but a largish, heavy bottom pan is recommended. 1. Finely peel then chopp the onions and the garlic. Chopp the chillis if used (I am a chilli gal). Please observe Chilli Protocol[0] 2. Wash and chop the pepper and mushrooms. Not finely diced, but not crudite-sized slices. Remember that peppers shrivel down a little, mushrooms a lot. 3. Start frying the onions for a while in some oil (I prefer olive, but others are acceptible), until they just about to go translucent. Then add the garlic and optional chillis until the garlic is just cooking nicely. 4. Add the spices, turn over until all the containts of the pan are covered, and cook for another 30 seconds or so. Then add the tinned tomato, and then add half a can of cold water water which rinsed the tin out with. Stir this around, and make sure it is now at just at a simmer or pre-simmer. 5. Add the lentils. You want 0.5-1 cm of water above the lentils when you have added and stirred. Let these cook and expand for about 5 mins, stirring all the while, all the lentils will stick to the bottom. 6. Add the pepper, mushroom, reserved squash flesh, and optional dash of balsamic vinegar, and half a tea spoon of marmite. Cook and stir until the pepper goes soft. This is the hard part. Add boiling water if really too thick, or some tomato puree if too thin. There is no hard science to this, you want at the end of 10 minutes or so something resembling the thickness in texture of a stiff bolognaise sauce. Assembly
1. Have a baking tray. Whether you prefer to grease, line with foil, or line with baking parchment is up to you. I prefer baking parchment. 2. Stuff those two halves of butternut squash with that sauce you made. It should make a mound of about 1cm about the level. If you feel extravagent, and are not vegan, sprinkle a little grated cheese on top. 3. Place in a pre-heated oven of 200oC. Cooking time should be about 20 mins, but larger ones take longer. The acid test is to briefly take them out, and prod the lower side with a fork. It should go through the skin with little resistance. When ready, serve. It s really a dish in itself, but some people might like a bit of salad, or maybe a light green risotto.

Andreas Metzler: exim4 stable update - testing requested

I have prepared an update for exim4, targeted at stable and would appreciate some testing / second eyes. https://people.debian.org/~ametzler/exim-dsa/
git repo on alioth Changes: Please send your feedback to ametzler(at)debian.org or exim4(at)packages.debian.org.

Lars Wirzenius: Obnam user survey, 2016

In January and February of 2016 I ran an Obnam user survey. I'm not a statistician, but here is my analysis of the results. Executive summary: Obnam is slow, buggy, and the name is bad. But they'd like to buy stickers and t-shirts. Method I wrote up a long list of questions about things I felt were of interest to me. I used Google Forms to collect responses, and exported them as a CSV file, and analysed based on that. I used Google Forms, even though it is not free software, as it was the easiest service I got to work that also seemed it'd be nice for people to use. I could have run the survey using Ikiwiki, but it wouldn't have been nearly as nice. I could have found and hosted some free software for this, but that would have been much more work. Most questions had free form text responses, and this was both good and bad. It was good, because many of the responses included things I could never have expected. It was bad, because it took me a lot more time and effort to process those. I think next time I'll keep the number of free text responses down. For some of the questions, I hand-processed the responses to a more or less systematic form, in order to count things with a bit of code. For others, I did not, and show the full list of responses (I'm lazy, we don't need a survey to determine that). The responses See http://code.liw.fi/obnam/survey-2016.html for the responses, after hand-processing. For the questions for which it makes sense, a script has tabulated the various responses and calculated percentages. I haven't produced graphs, as I don't know how to do that easily. (Maybe next time I'll enlist the help of statisticians.) Conclusions

Joey Hess: type safe multi-OS Propellor

Propellor was recently ported to FreeBSD, by Evan Cofsky. This new feature led me down a two week long rabbit hole to make it type safe. In particular, Propellor needed to be taught that some properties work on Debian, others on FreeBSD, and others on both. The user shouldn't need to worry about making a mistake like this; the type checker should tell them they're asking for something that can't fly.

-- Is this a Debian or a FreeBSD host? I can't remember, let's use both package managers!
host "example.com" $ props
    & aptUpgraded
    & pkgUpgraded
As of propellor 3.0.0 (in git now; to be released soon), the type checker will catch such mistakes. Also, it's really easy to combine two OS-specific properties into a property that supports both OS's:
upgraded = aptUpgraded  pickOS  pkgUpgraded
type level lists and functions The magick making this work is type-level lists. A property has a metatypes list as part of its type. (So called because it's additional types describing the type, and I couldn't find a better name.) This list can contain one or more OS's targeted by the property:
aptUpgraded :: Property (MetaTypes '[ 'Targeting 'OSDebian, 'Targeting 'OSBuntish ])
pkgUpgraded :: Property (MetaTypes '[ 'Targeting 'OSFreeBSD ])
In Haskell type-level lists and other DataKinds are indicated by the ' if you have not seen that before. There are some convenience aliases and type operators, which let the same types be expressed more cleanly:
aptUpgraded :: Property (Debian + Buntish)
pkgUpgraded :: Property FreeBSD
Whenever two properties are combined, their metatypes are combined using a type-level function. Combining aptUpgraded and pkgUpgraded will yield a metatypes that targets no OS's, since they have none in common. So will fail to type check. My implementation of the metatypes lists is hundreds of lines of code, consisting entirely of types and type families. It includes a basic implementation of singletons, and is portable back to ghc 7.6 to support Debian stable. While it takes some contortions to support such an old version of ghc, it's pretty awesome that the ghc in Debian stable supports this stuff. extending beyond targeted OS's Before this change, Propellor's Property type had already been slightly refined, tagging them with HasInfo or NoInfo, as described in making propellor safer with GADTs and type families. I needed to keep that HasInfo in the type of properties. But, it seemed unnecessary verbose to have types like Property NoInfo Debian. Especially if I want to add even more information to Property types later. Property NoInfo Debian NoPortsOpen would be a real mouthful to need to write for every property. Luckily I now have this handy type-level list. So, I can shove more types into it, so Property (HasInfo + Debian) is used where necessary, and Property Debian can be used everywhere else. Since I can add more types to the type-level list, without affecting other properties, I expect to be able to implement type-level port conflict detection next. Should be fairly easy to do without changing the API except for properties that use ports. singletons As shown here, pickOS makes a property that decides which of two properties to use based on the host's OS.
aptUpgraded :: Property DebianLike
aptUpgraded = property "apt upgraded" (apt "upgrade"  requires  apt "update")
pkgUpgraded :: Property FreeBSD
pkgUpgraded = property "pkg upgraded" (pkg "upgrade")
    
upgraded :: Property UnixLike
upgraded = (aptUpgraded  pickOS  pkgUpgraded)
     describe  "OS upgraded"
Any number of OS's can be chained this way, to build a property that is super-portable out of simple little non-portable properties. This is a sweet combinator! Singletons are types that are inhabited by a single value. This lets the value be inferred from the type, which came in handy in building the pickOS property combinator. Its implementation needs to be able to look at each of the properties at runtime, to compare the OS's they target with the actial OS of the host. That's done by stashing a target list value inside a property. The target list value is inferred from the type of the property, thanks to singletons, and so does not need to be passed in to property. That saves keyboard time and avoids mistakes. is it worth it? It's important to consider whether more complicated types are a net benefit. Of course, opinions vary widely on that question in general! But let's consider it in light of my main goals for Propellor:
  1. Help save the user from pushing a broken configuration to their machines at a time when they're down in the trenches dealing with some urgent problem at 3 am.
  2. Advance the state of the art in configuration management by taking advantage of the state of the art in strongly typed haskell.
This change definitely meets both criteria. But there is a tradeoff; it got a little bit harder to write new propellor properties. Not only do new properties need to have their type set to target appropriate systems, but the more polymorphic code is, the more likely the type checker can't figure out all the types without some help. A simple example of this problem is as follows.
foo :: Property UnixLike
foo = p  requires  bar
  where
    p = property "foo" $ do
        ...
The type checker will complain that "The type variable metatypes1 is ambiguous". Problem is that it can't infer the type of p because many different types could be combined with the bar property and all would yield a Property UnixLike. The solution is simply to add a type signature like p :: Property UnixLike Since this only affects creating new properties, and not combining existing properties (which have known types), it seems like a reasonable tradeoff. things to improve later There are a few warts that I'm willing to live with for now... Currently, Property (HasInfo + Debian) is different than Property (Debian + HasInfo), but they should really be considered to be the same type. That is, I need type-level sets, not lists. While there's a type level sets library for hackage, it still seems to require a specific order of the set items when writing down a type signature. Also, using ensureProperty, which runs one property inside the action of another property, got complicated by the need to pass it a type witness.
foo = Property Debian
foo = property' $ \witness -> do
    ensureProperty witness (aptInstall "foo")
That witness is used to type check that the inner property targets every OS that the outer property targets. I think it might be possible to store the witness in the monad, and have ensureProperty read it, but it might complicate the type of the monad too much, since it would have to be parameterized on the type of the witness. Oh no, I mentioned monads. While type level lists and type functions and generally bending the type checker to my will is all well and good, I know most readers stop reading at "monad". So, I'll stop writing. ;) thanks Thanks to David Miani who answered my first tentative question with a big hunk of example code that got me on the right track. Also to many other people who answered increasingly esoteric Haskell type system questions. Also thanks to the Shuttleworth foundation, which funded this work by way of a Flash Grant.

27 March 2016

Lunar: Reproducible builds: week 48 in Stretch cycle

What happened in the reproducible builds effort between March 20th and March 26th:

Toolchain fixes
  • Sebastian Ramacher uploaded breathe/4.2.0-1 which makes its output deterministic. Original patch by Chris Lamb, merged uptream.
  • Rafael Laboissiere uploaded octave/4.0.1-1 which allows packages to be built in place and avoid unreproducible builds due to temporary build directories appearing in the .oct files.
Daniel Kahn Gillmor worked on removing build path from build symbols submitting a patch adding -fdebug-prefix-map to clang to match GCC, another patch against gcc-5 to backport the removal of -fdebug-prefix-map from DW_AT_producer, and finally by proposing the addition of a normalizedebugpath to the reproducible feature set of dpkg-buildflags that would use -fdebug-prefix-map to replace the current directory with . using -fdebug-prefix-map. As succesful result of lobbying at LibrePlanet 2016, the --clamp-mtime option will be featured in the next Tar release. This option is likely to be used by dpkg-deb to implement deterministic mtimes for packaged files.

Packages fixed The following packages have become reproducible due to changes in their build dependencies: augeas, gmtkbabel, ktikz, octave-control, octave-general, octave-image, octave-ltfat, octave-miscellaneous, octave-mpi, octave-nurbs, octave-octcdf, octave-sockets, octave-strings, openlayers, python-structlog, signond. The following packages became reproducible after getting fixed: Some uploads fixed some reproducibility issues, but not all of them: Patches submitted which have not made their way to the archive yet:
  • #818742 on milkytracker by Reiner Herrmann: sorts the list of source files.
  • #818752 on tcl8.4 by Reiner Herrmann: sort source files using C locale.
  • #818753 on tk8.6 by Reiner Herrmann: sort source files using C locale.
  • #818754 on tk8.5 by Reiner Herrmann: sort source files using C locale.
  • #818755 on tk8.4 by Reiner Herrmann: sort source files using C locale.
  • #818952 on marionnet by ceridwen: dummy out build date and uname to make build reproducible.
  • #819334 on avahi by Reiner Herrmann: ship upstream changelog instead of the one generated by gettextize (although duplicate of #804141 by Santiago Vila).

tests.reproducible-builds.org i386 build nodes have been setup by converting 2 of the 4 amd64 nodes to i386. (h01ger)

Package reviews 92 reviews have been removed, 66 added and 31 updated in the previous week. New issues: timestamps_generated_by_xbean_spring, timestamps_generated_by_mangosdk_spiprocessor. Chris Lamb filed 7 FTBFS bugs.

Misc. On March 20th, Chris Lamb gave a talk at FOSSASIA 2016 in Singapore. The very same day, but a few timezones apart, h01ger did a presentation at LibrePlanet 2016 in Cambridge, Massachusetts. Seven GSoC/Outreachy applications were made by potential interns to work on various aspects of the reproducible builds effort. On top of interacting with several applicants, prospective mentors gathered to review the applications. Huge thanks to Linda Naeun Lee for the new hackergotchi visible on Planet Debian.

Bits from Debian: Debian Project Leader elections 2016

It's that time of year again for the Debian Project: the elections of its Project Leader! Neil McGovern who has held the office for the last year will not be seeking reelection. Debian Developers will have to choose between voting for the only candidate running Mehdi Dogguy or None Of The Above. If None Of The Above wins the election then the election procedure is repeated, many times if necessary. Mehdi Dogguy was a candidate for the DPL position last year, finishing second with a close amount of votes to the winner Neil McGovern. We are in the middle of the campaigning period that will last until April 2nd. The candidate and Debian contributors are expected to engage in debates and discussions on the debian-vote mailing list. The voting period starts on April 3rd, and during the following two weeks, Debian Developers will vote to choose the person who will guide the project for one year. The results will be published on April 17th with the term for new the project leader starting immediately that same day.

26 March 2016

Jonathan McDowell: Dr Stoll: Or how I learned to stop worrying and love the GPL

[I wrote this as part of BelFOSS but I think it s worth posting here.] My Free Software journey starts with The Cuckoo s Egg. Back in the early 90s a family friend suggested I might enjoy reading it. He was right; I was fascinated by the world of interconnected machines it introduced me to. That helped start my involvement in FidoNet, but it also got me interested in Unix. So when I saw a Linux book at the Queen s University bookshop (sadly no longer with us) with a Slackware CD in the back I had to have it. The motivation at this point was to have a low cost version of Unix I could run on the PC hardware I already owned. I had no knowledge of the GNU Project before this point, and as I wasn t a C programmer I had no interest in looking at the source code. I spent some time futzing around with it and that partition (I was dual booting with DOS 6.22) fell into disuse. It wasn t until I d learnt some C and turned up to university, which provided me with an internet connection and others who were either already using Linux or interested in doing so, that I started running a Linux box full time. Once I was doing that I became a lot more interested in the Open Source side of the equation. Rather than running a closed operating system that even the API for wasn t properly specified (or I wouldn t have needed my copy of Undocumented DOS) I had the complete source to both the underlying OS and all the utilities that it was using. For someone doing a computer science degree this was invaluable. Minix may have been the OS discussed in the OS Design module I studied, but Linux was a much more feature complete option that I was running on my desktop and could also peer under the hood of. In my professional career I ve always welcomed the opportunities to work with Open Source. A long time ago I experienced a particularly annoying issue when writing a device driver under QNX. The documentation didn t seem to match the observed behaviour of the subsystem I was interfacing with. However due to licensing issues only a small number of people in the organisation were able to actually look at the QNX source. So I ended up wasting a much more senior engineer s time with queries like I think it s actually doing x, y and z instead of a, b and c; can you confirm? . Instances where I can look directly at the source code myself make me much more productive. Commercial development also started to make me more understanding of the Free Software nature of the code I was running. It wasn t just the ability to look at the code which was useful, but also the fact there was no need to reinvent the wheel. Need a base OS to build an appliance on? Debian ensures that the main component is Free for all usage. No need to worry about rolling your own compilers, base libraries etc. From a commercial perspective that allows you to concentrate on the actual product. And when you hit problems, the source is available and you can potentially fix it yourself or at least more easily find out if there s been a fix for that issue released (being able to see code development in version control systems rather than getting a new upstream release with a whole heap on unrelated fixes in it really helps with that). I had thus progressed from using FLOSS because it was free-as-in-beer, to appreciating the benefits of Open Source in my own learning and employment experiences, to a deeper understanding of the free-as-in-speech benefits that could be gained. However at this point I was still thinking very much from a developer mindset. Even my thoughts about how users can benefit from Free Software were in the context of businesses being able to easily switch suppliers or continue to maintain legacy software because they had the source to their systems available. One of the major factors that has helped me to see beyond this is the expansion of the Internet of Things (IoT). With desktop or server software there is by and large a choice about what to use. This is not the case with appliances. While manufacturers will often produce a few revisions of software for their devices, usually eventually there is a newer and shiny model and the old one is abandoned. This is problematic for many reasons. For example, historically TVs have been long lived devices (I had one I bought second hand that happily lasted me 7+ years). However the smart capabilities of the TV I purchased in 2012 are already of limited usefulness, and LG have moved on to their current models. I have no intention of replacing the device any time soon, so have had to accept it is largely acting as a dumb display. More serious is the lack of security updates. For a TV that doesn t require a network connection to function this is not as important, but the IoT is a trickier proposition. For example Matthew Garrett had an awful experience with some intelligent light bulbs, which effectively circumvented any home network security you might have set up. The manufacturer s defence? No longer manufactured or supported. It s cases like these that have slowly led me to a more complete understanding of the freedom that Free Software truly offers to users. It s not just about cost free/low cost software. It s not just about being able to learn from looking at the source to the programs you are running. It s not even about the freedom to be able to modify the programs that we use. It s about giving users true Freedom to use and modify their devices as they see fit. From this viewpoint it is much easier to understand the protections against Tivoization that were introduced with GPLv3, and better appreciate the argument sometimes made that the GPL offers more freedom than BSD style licenses.

Gunnar Wolf: Yes! I can confirm that...

I am very very (very very very!) happy to confirm that... This year, and after many years of not being able to, I will cross the Atlantic. To do this, I will take my favorite excuse: Attending DebConf! So, yes, this image I am pasting here is as far as you can imagine from official promotional material. But, having bought my plane tickets, I have to start bragging about it ;-) In case it is of use to others (at least, to people from my general geographic roundabouts), I searched for plane tickets straight from Mexico. I was accepting my lack of luck, facing an over-36-hour trip(!!) and at very high prices. Most routes were Mexico- central_europe -Arab Emirates-South Africa... Great for collecting frequent-flier miles, but terrible for anything else. Of course, requesting a more logical route (say, via Sao Paulo in Brazil) resulted in a price hike to over US$3500. Not good. I found out that Mexico-Argentina tickets for that season were quite agreeable at US$800, so I booked our family vacation to visit the relatives, and will fly from there at US$1400. So, yes, in a 48-hr timespan I will do MEX-GRU-ROS, then (by land) Rosario to Buenos Aires, then AEP-GRU-JNB-CPT. But while I am at DebConf, Regina and the kids will be at home with the grandparents and family and friends. In the end, win-win with just an extra bit of jetlag for me ;-) I *really* expect flights to be saner for USians, Europeans, and those coming from further far away. But we have grown to have many Latin Americans, and I hope we can all meet in CPT for the most intense weeks of the year! See you all in South Africa!

24 March 2016

Michal Čihař: stardicter 0.9

For quite some time I maintain set of scripts to convert some freely available dictionaries to StarDict format. I think it's time to make it easily available to others as well, so it has seen first release on PyPI after the code is almost 10 years old. The project originally started for English - Czech dictionary, but over the time support for more sources have been introduced and you can generate StarDict dictionaries from many other sources. So we now have German - Czech dictionary as well. There is also support for dicts.info which provides many bilingual dictionaries, unfortunately it's license doesn't allow to distribute them.

Filed under: English StarDict 0 comments

23 March 2016

Petter Reinholdtsen: Full battery stats collector is now available in Debian

Since this morning, the battery-stats package in Debian include an extended collector that will collect the complete battery history for later processing and graphing. The original collector store the battery level as percentage of last full level, while the new collector also record battery vendor, model, serial number, design full level, last full level and current battery level. This make it possible to predict the lifetime of the battery as well as visualise the energy flow when the battery is charging or discharging. The new tools are available in /usr/share/battery-stats/ in the version 0.5.1 package in unstable. Get the new battery level graph and lifetime prediction by running:
/usr/share/battery-stats/battery-stats-graph /var/log/battery-stats.csv
Or select the 'Battery Level Graph' from your application menu. The flow in/out of the battery can be seen by running (no menu entry yet):
/usr/share/battery-stats/battery-stats-graph-flow
I'm not quite happy with the way the data is visualised, at least when there are few data points. The graphs look a bit better with a few years of data. A while back one important feature I use in the battery stats collector broke in Debian. The scripts in /usr/lib/pm-utils/power.d/ were no longer executed. I suspect it happened when Jessie started using systemd, but I do not know. The issue is reported as bug #818649 against pm-utils. I managed to work around it by adding an udev rule to call the collector script every time the power connector is connected and disconnected. With this fix in place it was finally time to make a new release of the package, and get it into Debian. If you are interested in how your laptop battery is doing, please check out the battery-stats in Debian unstable, or rebuild it on Jessie to get it working on Debian stable. :) The upstream source is available from github. As always, patches are very welcome.

Next.

Previous.