Search Results: "spa"

9 August 2013

Gunnar Wolf: Not in Switzerland But still, cheering for Debian's 20th anniversary!

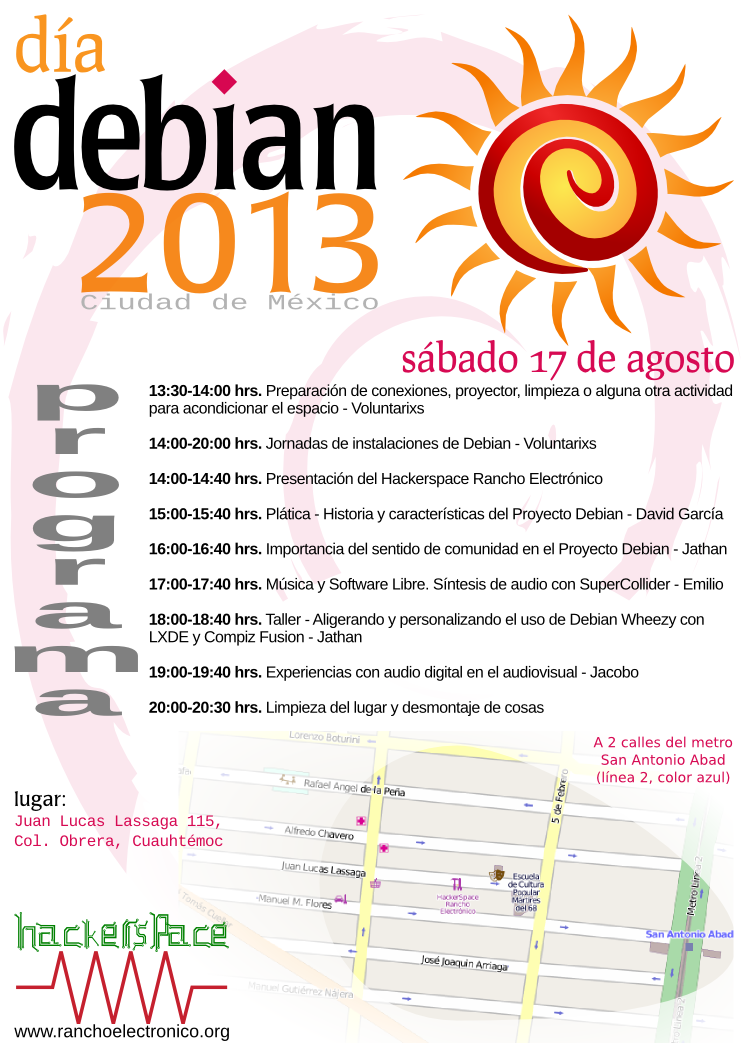
So... Well, contrary to the popular sentiment in Planet Debian, this year I'm very sorry to inform that... -( This is the first DebConf I miss in ten years, so... Yes, it's a big bummer for me. I'm not attending because this year, DebC(amp onf) coincide with the two first weeks of classes at my university And as a new teacher, I cannot afford to miss it! Anyway, but that should not stand in the way to attend a nice Debian 20th anniversary party! Parties will be held around the world. (Didn't find your city? Plan something and add it *now!*). In Mexico City, the nice guys at the very interesting Rancho Electr nico hackerspace took the lead, and organized the following activities: Debian Day 2013 Mexico City program Don't you yet know the hackerspace? You should go there! It's in a very centric location, just two blocks West from Metro San Antonio Abad (Juan Lucas Lassaga 114, col. Obrera). And the only two times I have been there, it has been good fun. Surely this Saturday we can have a nice party as well! The planned activities are from 13:30 to 20:30. See you there!

6 August 2013

Ian Wienand: Running cloud images locally

Fedora and Ubuntu both provide compact cloud images that are useful for spinning up small VM's quickly (much quicker than installing from a huge ISO or even net-install). Both these pages have single-click buttons to simply launch the VM's at Amazon, which is very cool. However, you may have reason to use them "offline" with a local KVM (outside of EC2 or OpenStack) for testing, or on a plane, etc. I didn't find a lot of information on this (although it is all available once you know what you're looking for). So here's my quick guide for the complete newbie. Firstly, download your image of choice and put it in /var/lib/libvirt/images. Open up virt-manager and you can create your new VM via "import existing image". You can try booting it, but the problem you'll hit is the images have no default password or way to log-in because, very sensibly, you're expected to inject that. Booting you'll see cloud-init attempting to contact 169.254.169.254 to collect the meta-data to initalize the VM; eventually it will time out and you're left at a login prompt you can't log in at. cloud-init does many things and is very flexible with lots of different plugins to initialise images in various ways. The particular one we're interested in is the No cloud plugin. This will look for data from a locally attached CD drive, which works very easily for this scenario. Now that you know that's what you're looking for, the instructions are fairly clear; I'll repeat them just for clarity. Firstly you want to create a minimal meta-data file that has a host-name and an instance-id:
$ cat meta-data
instance-id: iid-local01;
local-hostname: myhost;
Modifying the instance-id will signal to cloud-init that it should run again because something changed. This is also where you can put static IP address data; see the documentation. Secondly, create a user-data file that has the commands to enable password login; set a password, and inject your ssh public key so you can easily log-in:
$ cat user-data
#cloud-config
password: mypassword
ssh_pwauth: True
chpasswd:   expire: False  
ssh_authorized_keys:
  - ssh-rsa ... foo@foo.com (insert ~/.ssh/id_rsa.pub here)
Note for new players: that #cloud-config isn't an optional comment, it's a directive. If you leave it out, you'll probably see a little something about Unhandled non-multipart userdata starting... and your changes won't apply. Insert those two into files into an iso:
$ genisoimage -output init.iso -volid cidata -joliet -rock user-data meta-data
Then copy init.iso into /var/lib/libvirtd/images as well, and connect that as a virtual-cd drive to your virtual-machine created from the image. When you boot you should see some output as it injects your key. It should get an address via DHCP and then you should be able to log-in with fedora or ubuntu users. Then you can start getting more complicated with things like static addresses, package installations, running commands, etc by reading the documentation.

5 August 2013

Ian Wienand: Skipping bash history for command-lines starting with space

I was recently reading about a case where part of the evidence appears to be a deleted bash history-file. From what I gather, the accused says that the removal was a clean-up job to remove inadvertently stored passwords rather than an attempt to hide nefarious activity. What had managed to pass me by in 15 or so years of using bash but not reading man bash properly is the HISTCONTROL variable. If it is set to ignorespace then commands entered with a leading-space will not be stored in the history. Like all the best discoveries I found this only by accident on a machine where it was turned on. It's been quite useful in keeping my history pruned. However, not usually for security reasons around hiding passwords passwords on the command-line have other problems and I'm sure any security person would tell you not to use them just from a defense-in-depth perspective. That said, from a "keeping ctrl-r reversi-search useful" point-of-view it's often helpful; for example I've mostly trained my fingers to <space>rm -rf because I'm sure I'm not the only one who has deleted the wrong thing via a history-recall-combined-with-typing-to-fast scenario. So, HISTCONTROL=ignoreboth (which also ignores duplicates) is certainly a useful one to slip into your .bashrc. At least it would be one-less thing to explain to the FBI!

Daniel Pocock: Effectively supporting virtual domains with Mailman

When I first decided to run my own list server, I was well aware of the popularity of Mailman but I was deterred from using it by the complexity of setting up virtual hosts. In particular, 99% of the software I use for servers is packaged. Whenever I choose a new piece of software, using something that is packaged and supported is high on my list of priorities. Mailman's distribution tarball and the packages built from it only have limited support for virtual hosting. My own objective is to host lists for open source projects. As some of these projects don't have dedicated budgets, it is particularly important to find lightweight, low-maintenance solutions. Furthermore, it is important that those solutions don't detract from the time I want to invest in the projects themselves. I've developed some scripts to solve the problem: to start using them quickly, please see the README file. Here I provide a more detailed overview of the logic behind this approach. Mailman's limitations and workarounds For me, the biggest limitation of Mailman is that the site list is always linked to a single domain, which has to be chosen arbitrarily from the list of domains being hosted. Although it is not emphasized in the documentation, there is also the inconvenience of having all the lists from potentially unrelated projects appearing together on Mailman's main index page. Another limitation is that each list name must be globally unique across all domains. Some existing workarounds exist but they have limitations too. There is a virtual domain patch, but it is not clear how this handles the site list or the site index page. There is also the postfix-to-mailman script distributed by Debian and Ubuntu: using a transport-based solution looks elegant at first, but when you realise that you need to whitelist the addresses (to ensure messages are rejected at ingress rather than bounced), it becomes just as much work to maintain as the alternatives it aims to avoid: Mailman's authors do not endorse this approach. Experimenting with Sympa Deterred by Mailman's limitations, I initially went with Sympa and that seemed to run quite well for a number of years. In particular, it supports full virtual hosting out-of-the-box and all this is standard in the convenient Debian packages. From time-to-time, users have complained about the use of JavaScript in the web UI, but that was not something I could immediately resolve. However, when I upgraded to Debian 7 (wheezy), more serious problems appeared. Initially, the web UI (used for subscribing or browsing the archives) was completely broken. Anybody accessing the site would be given a download of the wws binary rather than the page that was supposed to be generated by the binary. I discovered errors about this in Apache's error.log and tried installing libapache2-mod-fcgid. The problem was resolved, but from then on, my whole web server became unstable and at least once every day I would have to restart the Apache process or it would become inaccessible. I put the details into a bug report and after not getting any feedback, decided to go and have another look at Mailman. A closer look at Mailman Looking at Mailman again, it appeared that the only way to achieve a relatively "pure" virtual hosting solution would be to run multiple installations of Mailman in different directory trees. Initially, I hoped this could be done by sharing copies of the binaries and just creating replicas of the structure under /var/lib/mailman. Looking under the hood, I discovered that the paths were compiled into the binaries and could not be easily overriden. It appears that this limitation could be overcome with some trivial patches to read directory names from the environment. The main aims of using shared binaries are disk space efficiency and also being able to benefit from security updates for the binary packages. However, if I had to patch the binaries, then I wouldn't be able to benefit from the security update packages anyway. So, it became inevitable that I would have to build binaries from source one way or another: either with a patch or by building multiple copies of each binary, each hardcoded with a different path. Putting it into practice Looking over the Mailman architecture, there are four things to be replicated for each installation:
  • init script to start a standalone qrunner per domain
  • cron jobs
  • CGI configuration from Apache (easily isolated by using a different ScriptAlias inside each Apache <VirtualHost>
  • Invocation of the Mailman binary from the mailer's aliases file
The init scripts and crontabs can be easily generated from a template (I used Debian's copies of these files as a base for that). Some of the Apache configuration can be handled by putting wildcards in the <Directory> specifications and the rest can be easily cut-and-pasted into <VirtualHost> definitions. Based on all of the above, all I had to do was run Mailman's configure script and make once for each virtual domain. I've scripted the whole process - my script is available here Managing the aliases file One particular limitation of my mailer (Postfix) is that the Mailman message processor can't be invoked directly from a rule in the virtual alias map. Scripts like this can only be invoked from the normal /etc/aliases file. This problem is not unique to Mailman: for Sympa, I also had to deal with this. The most common solution is to use the virtual file to translate all the virtual list addresses into very verbose usernames within the local domain:
Address Mapped to
widget-users@lists.example.org lists.example.org-widget-users@my-local-domain
The local part, lists.example.org-widget-users can then be used in the regular /etc/aliases file. This approach is described in the Sympa documentation and also in one of the virtual domain patches for Mailman. I've included a script for generating these alias mappings in the repository with my other scripts for building virtual Mailman installations. It would also be possible to patch Mailman itself to generate such files dynamically when new lists are created. Conclusion and next steps Using the techniques described and these small scripts, I successfully built independent virtual hosts for two of my domains, lists.lumicall.org and lists.dynalogin.org on a single mail host. Notice how each of them has the appearance of a clean, standalone Mailman installation? Going forward, I believe it would not be hard for the 2.x branch of Mailman to support this approach to virtual hosting with three changes:
  • Allowing the binaries to take their directory tree name from an environment variable or command line option or by inspecting argv[0] to discover their own location,
  • Generating the aliases file in the more verbose format and
  • Providing some convenient init script and crontab that iterates over all the domains

4 August 2013

Dirk Eddelbuettel: RcppArmadillo 0.3.900.7

A bug-fix release 3.900.7 of Armadillo was provided by Conrad a few days ago. It has been rolled into a new RcppArmadillo release 0.3.900.7 which, after a brief delay, is now on CRAN and in Debian. The main bug fix is a change in the in-place version of reshape(). This in turn caused the CRAN package Amelia to fail, but some diligent debugging by Conrad (which was much appreciated) revealed that the error was in fact in RcppArmadillo where we did not set the matrix flag properly in the constructor. The corresponding one-character fix had been made in this release. Another package exhibiting an issue is unmarked. It needs to make the target variable of reshape a matrix object in a handful of places. I sent the authors a small patch addressing this but have not yet heard back. The complete list of changes is below. In the meantime, I have also done some work on a new as() and wrap() converters for sparse matrices; a first implementation is in SVN.
Changes in RcppArmadillo version 0.3.900.7 (2013-08-02)
  • Upgraded to Armadillo release Version 3.900.7 (Bavarian Sunflower)
    • minor fix for inplace reshape()
    • minor corrections for compilation issues under GCC 4.8+ and MSVC
  • Corrected setting of vec_stats in intialization of row, vector and matrix objects
  • The inline package is no longer used in the examples and unit tests which have all been converted to using Rcpp attributes
Courtesy of CRANberries, there is also a diffstat report for the most recent release As always, more detailed information is on the RcppArmadillo page. Questions, comments etc should go to the rcpp-devel mailing list off the R-Forge page.

Steve Kemp: TAB completion is hard

I've spent the past few days overhauling the TAB-completion which is included in lumail. Completing a single token is easy, if there is only one match, and you limit yourself to completing at the start of a line. But doing real completion is hard. Consider the case where you want to complete something like this:
unread_message_colour("re[TAB]
Clearly completing the first part "unread_[TAB]" is simple. But to complete "re" to "red" you need to split up your input line into tokens so that you can recognize a quote as a valid completion point. Similarly you need to split on "(" to allow:
-- show the path to the editor
msg(edit[TAB]
To allow this to be changed/controlled by the user I defined completion_chars() which contains: SPACE, QUOTE, "(", etc. I'm pleased with the user-callback for offering completion suggestions, my own is pretty basic and just includes all user-defined functions as well as an address book. The latter allows steve.org.uk[TAB] to complete to: "Steve Kemp" <steve@steve.org.uk> - because we allow matches anywhere in the completion string, rather than just prefix-matching. I struggled with resolving ambiguities, but now that is handled correctly too. Press "TAB" when there are multiple choices available and you can graphically TAB-through the available choices, or press Esc to cancel. In conclusion I've spent a few days fighting with user-interface stuff and now the mail-client is better, but I've still to tackle RFC 2047 header decoding because that is really hard!

3 August 2013

Steve Langasek: Network services and Upstart

So Debian bug #710747 led to an interesting discussion the other night on IRC which made me realize there are a lot of people who have yet to understand why sysvinit needs replacing. I can't speak to whether upstart solves this bug in particular. The tftpd-hpa package in Ubuntu (and in Debian experimental) does have an upstart job, and I have used tftpd-hpa on systems whose network interfaces are managed entirely with NetworkManager, and I have not seen this bug; but I can't say that this is more than coincidence. However, I can speak to how upstart provides facilities that address the general problem of starting services that require a working network connection to be present before they start up. Traditionally on Linux systems, init scripts could assume that the network connection is up before starting any services for the target runlevel. With LSB dependencies, you could also express this as
Required-Start:    $network
The trouble with both of these approaches is that they assume that there is a single point in time, early in the boot of the system, when the "network" is up. This was an ok assumption 15 years ago, when the Linux kernel initialized all devices serially and all our network configuration was static. But nowadays, you simply cannot rely on systems booting in such a way that the network is fully up shortly after boot - or in a way that you can block the system boot waiting for the network to be up. If all of our services would cope gracefully with being started without the network, this would be a non-issue. Unfortunately, not all network services are written in such a way as to work without a network; nor do they all cope with dynamic changes to interfaces or addresses. While it would be better if these services were written more robustly, since there's no shortage of daemons written this way, it's convenient that upstart provides tools for coping with this behavior in the meantime. Here's a real (simplified) example of an upstart job for a service that needs to wait for a non-loopback interface before it starts:
start on (local-filesystems and net-device-up IFACE!=lo)
stop on runlevel [!2345]
expect fork
respawn
exec nmbd -D
Now, you might also have a service that you only want to start up when a particular network device comes up. This is easily expressed in upstart, and might look like this hypothetical job:
start on net-device-up IFACE=wlan0
stop on net-device-down IFACE=wlan0
expect daemon
respawn
exec mydaemon
If you need to restart a daemon whenever the set of active network connections changes, that's less straightforward. Upstart doesn't have the notion of a 'restart' rule, so you would need two jobs to handle this - one for the daemon itself that starts on the first network connection, and a second job to trigger a restart of the daemon when the network status changes. For the tftpd-hpa case in the abovementioned bug, this might look like:
$ cat /etc/init/tftpd-hpa.conf
start on runlevel [2345]
stop on runlevel [!2345]
expect fork
respawn
script
        if [ -f $ DEFAULTS  ]; then
                . $ DEFAULTS 
        fi
        exec /usr/sbin/in.tftpd --listen  --user $ TFTP_USERNAME  --address $ TFTP_ADDRESS  $ TFTP_OPTIONS  $ TFTP_DIRECTORY 
end script
$ cat /etc/init/tftpd-hpa-restart.conf
start on net-device-up
task
instance $IFACE
script
        status tftpd-hpa   grep -q start/   stop
        restart tftpd-hpa
end script
For this case, upstart doesn't provide quite so great an advantage. It's nice to be able to use upstart natively for both pieces, but you can do the same thing with an init script plus an if-up.d script for ifupdown, which is what maintainers do today. I think adding a restart on stanza to upstart in the future to address this would be a good idea. Though in any event, this is far simpler to do with upstart than with any if-up.d script I've ever seen for managing an initscript-based service. Between the more friendly declarative syntax, and the enhanced semantics for expressing when to run (or restart) a job, upstart offers clear advantages over other init systems.

R&#233;mi Vanicat: Xorg and special keys

Xorg and special keys: one solution for keycode>255 An historic I've buy an IR receiver, and an universal controller to control my multimedia computer, my TV, my ADSL box and my 2.1 Home cinema. I've been pleased to see that my universal controller do now more control than the remote that was sold with my IR receiver. But a lot of those control didn't work with Xorg, so I had to find someway to use them. At first, my logs where spamed with line like:
imon 4-4:1.0: imon_incoming_packet: unknown keypress, code 0x100000e
(imon is the real builder of the IR receiver). I looked for this on the internet and found So I waited, and Linux 3.10 was released, and the Debian Kernel Team did include it in debian sid, so I could easily use it. But some command was still unrecognized as key by Xorg, so I had to find how to let X know them. Reading documentation on internet, and trying some command lead nowhere: the kernel did in fact understood very well the command, but X did ignore them. After two day of trying to understood XKB, I found this bug: those key was unavailable to X and XKB because their keycode was bigger than 255. The first solution to this problem is this patch, but I prefer to use standard tool. I finally found that udev can remap key, hence my solution: The Solution To use key that have keycode bigger than 255, you need to have keycode smaller than 255. keycode are determined by a map in the kernel, that udev can set when the receiver is plugged. You need a keymap. input-kbd from the input-utils package will list the available scancode, and their current keycode (to know the number of your input device, use lsinput):
% sudo input-kbd 6
0x100007f = 106  # KEY_RIGHT
0x1000080 = 105  # KEY_LEFT
0x1007f00 = 108  # KEY_DOWN
0x1008000 = 103  # KEY_UP
0x1010000 = 272  # BTN_LEFT
0x1010080 = 272  # BTN_LEFT
0x1020000 = 273  # BTN_RIGHT
0x1020080 = 273  # BTN_RIGHT
0x200001e = 513  # KEY_NUMERIC_1
0x200001f = 514  # KEY_NUMERIC_2
(There is more, I just cut it there). Putting this in some file (say keymap), editing it, and running sudo input-kbd -f keymap 6 should change the kernel mapping. But it don't. It's not a problem, because the best solution is to use udev. Wrote a keyboard mapping in say /etc/udev/imon:
0x200001e  KP1
0x200001f  KP2
0x2000020  KP3
0x2000021  KP4
0x2000022  KP5
0x2000023  KP6
0x2000024  KP7
0x2000025  KP8
0x2000026  KP9
0x2000027  KP0
0x2800000  MENU
0x288795b7 PAGEDOWN
0x289395b7 PAGEUP
You then need to tell udev to load this mapping, with /etc/udev/rules.d/96-local-keymap.rules:
ACTION=="remove", GOTO="mykeyboard_end"
KERNEL!="event*", GOTO="mykeyboard_end"
ENV ID_INPUT_KEY =="", GOTO="mykeyboard_end"
SUBSYSTEMS=="bluetooth", GOTO="mykeyboard_end"
SUBSYSTEMS=="usb", IMPORT builtin ="usb_id"
ENV ID_VENDOR =="15c2", ENV ID_MODEL_ID =="0042", RUN+="keymap $name /etc/udev/imon"
LABEL="mykeyboard_end"
You will need to adapt 15c2 and 0042 to you own remote. I've found those using lsusb
Bus 004 Device 014: ID 15c2:0042 SoundGraph Inc.
I could now use xkb to further refine the way those key are used by xorg...

Russell Coker: Religious Conversion

Today I was in the center of Melbourne and I saw two stands run by Muslims advocating their faith. They had a selection of DVDs and brochures to give away and seemed friendly enough for anyone who wanted a chat. I think that this is a good thing, if the majority of the Australian population would think of the Muslim minority as people who give away DVDs rather than as potential suicide bombers then it would be a great benefit for society. Then I saw a Christian stand which had placards indicating that Jesus loves Muslims, which is fine. One of the workers on that stand then gleefully told me that there had been a Muslim stand in that area but the Muslims departed when they arrived. It would be good if advocates for the various religions could work together to promote positive things that they all agree on (generally related to being nice to other people). When they seem to be essentially bullying other religious groups into leaving the area they aren t making a good case for a kind and caring god. The Christian who was so happy about the Muslims departing then tried to convert me. He started by talking about a mobile phone not being able to appear from nothing which was the start of an utterly stupid argument about creationism. That was stupid firstly because it s obvious that evolution doesn t apply to consumer electronics, if I leave a phone lying on top of another phone overnight I m not going to get some little phones appearing as a result. But the bigger stupidity is in even promoting creationism in the first place. Advocating creationism is essentially claiming that god is so incapable that ze can t manage an evolutionary process. An all-seeing all-knowing god of infinite intelligence could just create a plasma cloud that will form into a solar system and evolve life. People who argue for creationism don t believe in a capable god, they believe in a being that resembles a god in the way a magician resembles someone who can actually perform magic. Arguing for creationism is arguing for a limited being which probably isn t worthy of worship (why worship space aliens who are probably only a few thousand years ahead of us). Regardless of the scientific evidence (which is strongly in favor of evolution) just logically thinking about the issue in regard to what a being with infinite powers might actually do suggests that ze could just as easily create or evolve all life and probably wouldn t care about what we believe. Genesis should be taken as metaphor because it s obvious that nothing that s taught in a year 7 science class could be taught to your typical stone age goat-herd, but even if it was taken literally it s not specified as a required belief (as opposed to a belief in a single god, repenting sins, and other beliefs which are required). The greatest stupidity however is the fact that even if it made any sense to promote creationism it wouldn t make sense to do so immediately. Any time you want to convert someone to a set of beliefs it s a good strategy to start with the ones which will seem least wacky. I can have have a conversation with Christians about positive things which we generally agree on such as donating to charity and trying to do good things in various ways. But when they start with the stupid stuff I walk away. When the weather is better I plan to interview representatives of the various religious groups who are trying to convert people on the street and rate them according to how wacky they are. I ll be a little limited in my ability to review them by the total lack of any right to free speech in Australia (our laws are much the same as those in the UK). But I should still be able to give them a reasonable review.

Paul Tagliamonte: Hy: The survival guide

One of my new favorite languages is a peppy little lisp called hy. I like it a lot since it's a result of a hilarious idea I had while talking with some coworkers over mexican food. Since I'm the most experienced Hypster on the planet, I figured I should write a survival guide. This will go a lot easier if you already know Lisp, but you can get away with quite a bit of Python. The Tao of Hy We don't have many rules (yet), but we do have quite a bit of philosophy. The collective Hyve Mind has spent quite a bit of time working out Hy's internals, and we do spend a bit of time looking at how the language feels . The following is a brief list of some of the design decisions we've picked out.
  1. Look like a lisp, DTRT with it (e.g. dashes turn to underscores, earmuffs turn to all-caps.)
  2. We're still Python. Most of the internals translate 1:1 to Python internals.
  3. Use unicode everywhere.
  4. Tests or it doesn't exist.
  5. Fix the bad decisions in Python 2 when we can (see true_division)
  6. When in doubt, defer to Python.
  7. If you're still unsure, defer to Clojure
  8. If you're even more unsure, you're fucked (see also: defer to Common Lisp)
Naturally, this doesn't cover everything, but if you can drop into that mindset, things start to make quite a bit of sense. The Style of Hy Although I am perhaps the least qualified person to do so (I still don't write idiomatic Lisp all the time), I'm going to set up a few ground-rules when it comes to idiomatic Hy code. We borrow quite a bit of syntax from Common Lisp and Clojure, so again, feel free to defer to either if you're not working on Hy internals. I prefer the Clojure Style Guidelines myself. As such, these are what we will defer to in the case that the Hy style is undefined. Clojure-isms Hy has quite a few Clojure-isms that I rather prefer, such as the threading macro, and dot-notation (for accessing methods on an Object), which I would rather see used throught the hylands.
;; good:
(with [fd (open "/etc/passwd")]
    (print (.readlines fd)))
;; bad:
(with [fd (open "/etc/passwd")]
    (print (fd.readlines)))
Some other hy devs very much disagree, and there's nothing syntactically invalid about the latter, and it will continue to be supported (in fact, it makes some things easier!), but it will not be considered for Hy internal code. We also very much encourage use of the threading macro throughout code where it makes sense.
;; good:
(import [sh [cat grep]])
(-> (cat "/usr/share/dict/words") (grep "-E" "tag$"))
;; bad:
(import [sh [cat grep]])
(grep (cat "/usr/share/dict/words") "-E" "tag$")
However, do use it when it helps aid in clarity, like all things, there are cases where it makes a mess out of something that ought to not be futzed with. Python-isms In addition to stealing quite a bit of syntax from Clojure, I'm going to take a few Python rules from PEP8 that apply to Hy as well. These are taken because PEP8 is a really great set of rules, and Hy code ends up pretty, well, Pythonic. The following are a collection of Pythonic rules that explicitly apply to Hy code. Trailing spaces is a huge one. Never ever ever shall it be OK to have trailing spaces on internal Hy code. For they suck. As with Python, you shall always double-space module-level definitions if seperated with a newline. All public functions must always contain docstrings. Inline comments shall be two spaces from the end of the code, if they are inline comments. They must always have a space between the comment character and the start of the comment. Hy-isms Indentation shall be two spaces, except where matching the indentation of the previous line.
;; good (and prefered):
(defn fib [n]
  (if (<= n 2)
      n
      (+ (fib (- n 1)) (fib (- n 2)))))
;; still OK:
(defn fib [n]
  (if (<= n 2) n (+ (fib (- n 1)) (fib (- n 2)))))
;; still OK:
(defn fib [n]
  (if (<= n 2)
    n
    (+ (fib (- n 1)) (fib (- n 2)))))
;; Stupid as hell
(defn fib [n]
    (if (<= n 2)
            n
      (+ (fib (- n 1)) (fib (- n 2)))))
Parens must never be alone, sad, all by their lonesome on their own line.
;; good (and prefered):
(defn fib [n]
  (if (<= n 2)
      n
      (+ (fib (- n 1)) (fib (- n 2)))))
;; Stupid as hell
(defn fib [n] 
    (if (<= n 2)
      n
      (+ (fib (- n 1)) (fib (- n 2)))
    )
)  ; GAH, BURN IT WITH FIRE
Don't use S-Expression syntax where vector syntax is really required. For instance, the fact that:
;; bad (and evil)
(defn foo (x) (print x))
(foo 1)
works is just because the compiler isn't overly strict. In reality, the correct syntax in places such as this is:
;; good (and prefered):
(defn foo [x] (print x))
(foo 1)
Notice This guide is, above all, a guide. This is also only truely binding for working on Hy code internally. This post is also super subject to change in the future, whenever I can be bothered to ensure that we have more of the de facto rules written down.

2 August 2013

Justus Winter: There is no spoon...

This is the Hurd shutting down:
root@debian:~# init 0
INIT: Switching to runlevel: 0
INIT: Sending processes the TERM signal
INIT: Sending processes the KILL signal
Using makefile-style concurrent boot in runlevel 0.
Stopping deferred execution scheduler: atd.
Asking all remaining processes to terminate...done.
All processes ended within 1 seconds...done.
Stopping enhanced syslogd: rsyslogd.
Deconfiguring network interfaces...ifdown: failed to open pid file /run/network/ifdown-/dev/eth0.pid: No such file or directory
Internet Systems Consortium DHCP Client 4.2.2
Copyright 2004-2011 Internet Systems Consortium.
All rights reserved.
For info, please visit https://www.isc.org/software/dhcp/
can't create /var/lib/dhcp/dhclient./dev/eth0.leases: No such file or directory
Listening on Socket//dev/eth0
Sending on   Socket//dev/eth0
/bin/sh: 1: ifconfig: not found
done.
Deactivating swap...swapoff: /dev/hd0s5: 177152k swap space
done.
mount: cannot remount /: Device or resource busy
Will now halt.
INIT: no more processes left in this runlevel
The important line is the one saying Asking all remaining processes to terminate...done.. What happens there is that /sbin/killall5 is run, actually does its job and the system survives that. What was needed to fix killall5 is to mark some processes (all translators being started as root as well as any essential processes) as important and to exempt them from being frozen and killed by killall5. Furthermore it was necessary to fill in the correct values for the start_code and end_code fields of the /proc/*/stat records (this used to be an issue for Debian/kFreeBSD as well). I am still in the process of cleaning up the patch series, I will finish that first thing Monday morning. I also spent my time polishing my mtab translator, the patch series is in its fourth revision and I consider it ready for inclusion: http://lists.gnu.org/archive/html/bug-hurd/2013-07/msg00259.html I also had this moment of clarity and enlightenment. For the first time I thought I finally understood what the Hurd really was. It is just a bunch of Mach programs that talk to each other in this really strange language and as a result they behave very much like the equivalent programs would on a different POSIX-like system. This is of course hidden away from the application programmer in our libc. This language is a mere convention, Richard calls this system personality. On some other level I have known this for a long time, but I never grasped the profound implications for users and developers, and for composability and the security of the system as a whole. I will try to show some of the cool stuff that can be done with such a system, stuff that is hard to do on monolithic kernels. And I had to patch the exec server. You know what they say, once you looked into /hurd/exec, there is no going back. I am very happy to report that I addressed all three major issues I identified in my second week. Next week I will clean up my initscripts patch series and submit it for inclusion. I will also rebuild the hurd, sysvinit and libc packages with all my patches included for broader testing. And if I ever run out of stuff to do first, I will have to look at the network related issues.

1 August 2013

Julien Danjou: The definitive guide on how to use static, class or abstract methods in Python

Doing code reviews is a great way to discover things that people might struggle to comprehend. While proof-reading OpenStack patches recently, I spotted that people were not using correctly the various decorators Python provides for methods. So here's my attempt at providing me a link to send them to in my next code reviews. :-) How methods work in Python A method is a function that is stored as a class attribute. You can declare and access such a function this way:
>>> class Pizza(object):
... def __init__(self, size):
... self.size = size
... def get_size(self):
... return self.size
...
>>> Pizza.get_size
<unbound method Pizza.get_size>

What Python tells you here, is that the attribute get_size of the class Pizza is a method that is unbound. What does this mean? We'll know as soon as we'll try to call it:
>>> Pizza.get_size()
Traceback (most recent call last):
File "<stdin>", line 1, in <module>
TypeError: unbound method get_size() must be called with Pizza instance as first argument (got nothing instead)

We can't call it because it's not bound to any instance of Pizza. And a method wants an instance as its first argument (in Python 2 it must be an instance of that class; in Python 3 it could be anything). Let's try to do that then:
>>> Pizza.get_size(Pizza(42))
42

It worked! We called the method with an instance as its first argument, so everything's fine. But you will agree with me if I say this is not a very handy way to call methods; we have to refer to the class each time we want to call a method. And if we don't know what class is our object, this is not going to work for very long. So what Python does for us, is that it binds all the methods from the class Pizza to any instance of this class. This means that the attribute get_size of an instance of Pizza is a bound method: a method for which the first argument will be the instance itself.
>>> Pizza(42).get_size
<bound method Pizza.get_size of <__main__.Pizza object at 0x7f3138827910>>
>>> Pizza(42).get_size()
42

As expected, we don't have to provide any argument to get_size, since it's bound, its self argument is automatically set to our Pizza instance. Here's a even better proof of that:
>>> m = Pizza(42).get_size
>>> m()
42

Indeed, you don't even have to keep a reference to your Pizza object. Its method is bound to the object, so the method is sufficient to itself. But what if you wanted to know which object this bound method is bound to? Here's a little trick:
>>> m = Pizza(42).get_size
>>> m.__self__
<__main__.Pizza object at 0x7f3138827910>
>>> # You could guess, look at this:
...
>>> m == m.__self__.get_size
True

Obviously, we still have a reference to our object, and we can find it back if we want. In Python 3, the functions attached to a class are not considered as unbound method anymore, but as simple functions, that are bound to an object if required. So the principle stays the same, the model is just simplified.
>>> class Pizza(object):
... def __init__(self, size):
... self.size = size
... def get_size(self):
... return self.size
...
>>> Pizza.get_size
<function Pizza.get_size at 0x7f307f984dd0>

Static methods Static methods are a special case of methods. Sometimes, you'll write code that belongs to a class, but that doesn't use the object itself at all. For example:
class Pizza(object):
@staticmethod
def mix_ingredients(x, y):
return x + y

def cook(self):
return self.mix_ingredients(self.cheese, self.vegetables)

In such a case, writing mix_ingredients as a non-static method would work too, but it would provide it a self argument that would not be used. Here, the decorator @staticmethod buys us several things:
>>> Pizza().cook is Pizza().cook
False
>>> Pizza().mix_ingredients is Pizza.mix_ingredients
True
>>> Pizza().mix_ingredients is Pizza().mix_ingredients
True

Class methods Having said that, what are class methods? Class methods are methods that are not bound to an object, but to a class!
>>> class Pizza(object):
... radius = 42
... @classmethod
... def get_radius(cls):
... return cls.radius
...
>>>
>>> Pizza.get_radius
<bound method type.get_radius of <class '__main__.Pizza'>>
>>> Pizza().get_radius
<bound method type.get_radius of <class '__main__.Pizza'>>
>>> Pizza.get_radius is Pizza().get_radius
True
>>> Pizza.get_radius()
42

Whatever the way you use to access this method, it will be always bound to the class it is attached too, and its first argument will be the class itself (remember that classes are objects too). When to use this kind of methods? Well class methods are mostly useful for two types of methods:
class Pizza(object):
def __init__(self, ingredients):
self.ingredients = ingredients

@classmethod
def from_fridge(cls, fridge):
return cls(fridge.get_cheese() + fridge.get_vegetables())

class Pizza(object):
def __init__(self, radius, height):
self.radius = radius
self.height = height

@staticmethod
def compute_circumference(radius):
return math.pi * (radius ** 2)

@classmethod
def compute_volume(cls, height, radius):
return height * cls.compute_circumference(radius)

def get_volume(self):
return self.compute_volume(self.height, self.radius)

Abstract methods An abstract method is a method defined in a base class, but that may not provide any implementation. In Java, it would describe the methods of an interface. So the simplest way to write an abstract method in Python is:
class Pizza(object):
def get_radius(self):
raise NotImplementedError

Any class inheriting from Pizza should implement and override the get_radius method, otherwise an exception would be raised. This particular way of implementing abstract method has a drawback. If you write a class that inherits from Pizza and forget to implement get_radius, the error will only be raised when you'll try to use that method.
>>> Pizza()
<__main__.Pizza object at 0x7fb747353d90>
>>> Pizza().get_radius()
Traceback (most recent call last):
File "<stdin>", line 1, in <module>
File "<stdin>", line 3, in get_radius
NotImplementedError

There's a way to triggers this way earlier, when the object is being instantiated, using the abc module that's provided with Python.
import abc

class BasePizza(object):
__metaclass__ = abc.ABCMeta

@abc.abstractmethod
def get_radius(self):
"""Method that should do something."""

Using abc and its special class, as soon as you'll try to instantiate BasePizza or any class inheriting from it, you'll get a TypeError.
>>> BasePizza()
Traceback (most recent call last):
File "<stdin>", line 1, in <module>
TypeError: Can't instantiate abstract class BasePizza with abstract methods get_radius

Mixing static, class and abstract methods When building classes and inheritances, the time will come where you will have to mix all these methods decorators. So here's some tips about it. Keep in mind that declaring a class as being abstract, doesn't freeze the prototype of that method. That means that it must be implemented, but i can be implemented with any argument list.
import abc

class BasePizza(object):
__metaclass__ = abc.ABCMeta

@abc.abstractmethod
def get_ingredients(self):
"""Returns the ingredient list."""

class Calzone(BasePizza):
def get_ingredients(self, with_egg=False):
egg = Egg() if with_egg else None
return self.ingredients + egg

This is valid, since Calzone fulfil the interface requirement we defined for BasePizza objects. That means that we could also implement it as being a class or a static method, for example:
import abc

class BasePizza(object):
__metaclass__ = abc.ABCMeta

@abc.abstractmethod
def get_ingredients(self):
"""Returns the ingredient list."""

class DietPizza(BasePizza):
@staticmethod
def get_ingredients():
return None

This is also correct and fulfil the contract we have with our abstract BasePizza class. The fact that the get_ingredients method don't need to know about the object to return result is an implementation detail, not a criteria to have our contract fulfilled. Therefore, you can't force an implementation of your abstract method to be a regular, class or static method, and arguably you shouldn't. Starting with Python 3 (this won't work as you would expect in Python 2, see issue5867), it's now possible to use the @staticmethod and @classmethod decorators on top of @abstractmethod:
import abc

class BasePizza(object):
__metaclass__ = abc.ABCMeta

ingredient = ['cheese']

@classmethod
@abc.abstractmethod
def get_ingredients(cls):
"""Returns the ingredient list."""
return cls.ingredients

Don't misread this: if you think this going to force your subclasses to implement get_ingredients as a class method, you are wrong. This simply implies that your implementation of get_ingredients in the BasePizza class is a class method. An implementation in an abstract method? Yes! In Python, contrary to methods in Java interfaces, you can have code in your abstract methods and call it via super():
import abc

class BasePizza(object):
__metaclass__ = abc.ABCMeta

default_ingredients = ['cheese']

@classmethod
@abc.abstractmethod
def get_ingredients(cls):
"""Returns the ingredient list."""
return cls.default_ingredients

class DietPizza(BasePizza):
def get_ingredients(self):
return ['egg'] + super(DietPizza, self).get_ingredients()

In such a case, every pizza you will build by inheriting from BasePizza will have to override the get_ingredients method, but will be able to use the default mechanism to get the ingredient list by using super().

Matthew Garrett: Don't ship 32-bit UEFI firmware on x86

Shipping a UEFI-bootable Linux distribution is a touch awkward[1], with the main sticking point being the necessity to produce boot media with multiple El-Torito images. An El-Torito image is either an image of a floppy disk or a small hard drive, embedded into the ISO. This allows BIOS systems to look for an El Torito image, hook some interrupts and then boot without the BIOS having to care about the fact that the image is embedded in an ISO-9660 filesystem. UEFI systems will look for an El-Torito image with a special tag - if they find it they'll mount it as a FAT filesystem and look for a bootloader, and if not they'll fall back to BIOS compatibility.
So, if you want a CD that'll boot on both BIOS and UEFI systems, you need two El-Torito images - one for BIOS, one for UEFI. Unfortunately, various BIOSes deal exceptionally badly with CD images that contain more than one El-Torito image. The most common failure case is to print a menu asking you to choose an option without labelling the options, but some will just fail outright. Thankfully, this is pretty much exclusively limited to 32-bit systems.

Things get irritatingly more complicated due to a quirk of UEFI. UEFI is based on executing code in native mode. That means that 32-bit UEFI systems can't execute 64-bit code in firmware, even if the CPU is capable of it. A 64-bit OS can only boot on 32-bit UEFI if it has very ugly compatibility hacks, including having to rewrite structures and register state every time it makes a UEFI call. The only OS I'm aware of that implements this is MacOS X. Having looked into what it'd take to implement it in Linux, I decided that hammering rusty nails through my feet would be a preferable use of time. Thankfully, I went drinking instead.

So distributions have a choice. They can either produce UEFI-bootable CD images for 32-bit x86 and risk failures on actual 32-bit systems, or they can ignore UEFI entirely on 32-bit and succeed in booting on all the hardware that people actually own[2]. Unsurprisingly, they tend to choose the second option.

So, if you're building an x86 hardware platform, don't ship with 32-bit UEFI. If you're stuck with a 32-bit CPU then just ship BIOS. If you have a 64-bit CPU then ship a 64-bit UEFI. If you ship with 32-bit UEFI, no significant existing Linux distribution will support you, and you'll face an uphill battle to convince them to do so.

32-bit UEFI. Just say what on earth were you thinking, please, no, can't you find a solution that doesn't involve me getting tetanus jabs.

(If you're worried about the extra memory consumption of 64-bit OSes, just encourage 32-bit userspace on a 64-bit kernel. Or just boot via BIOS)

[1] See the number that still don't manage it despite having had several years to adapt
[2] Until recently, the only vendor to ship 32-bit UEFI firmware on volume hardware was Apple. This was fine on their 32-bit systems, but on their 64-bit systems with 32-bit UEFI booting a 64-bit version of Windows would result in boot failure. Apple rectified this by stating that 64-bit Windows wasn't supported on platforms with 32-bit UEFI, which is a neat trick if you can manage it. 32-bit Windows (and Linux) was fine because it didn't include a UEFI boot image and so didn't trigger the bug.

comment count unavailable comments

30 July 2013

Daniel Pocock: Switzerland's scariest railway (video)

Although promoted as a funicular railway, the Gelmerbahn funicular has the appearance of a giant roller coaster and all of the fun too. For all those still having nightmares about recent rail tragedies in the age of non-stop surveillance and on-line replays, the 108 degree ascent (or descent) may not be your thing. On the other hand, for those who experience the London Underground each morning, "mind the gap" takes on a whole new meaning as you see your feet hanging out the bottom of the train and the tracks descending vertically into the valley below. <video controls="" height="340" poster="http://danielpocock.com/sites/danielpocock.com/files/gbahn-preview.jpg" width="560">

<source src="http://video.danielpocock.com/Gelmerbahn.webm" type="video/webm"></source>
Click to access video on original page
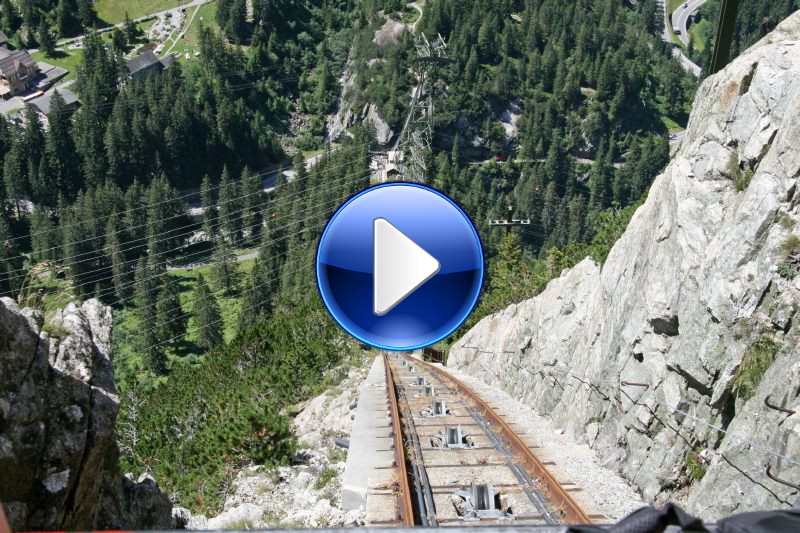
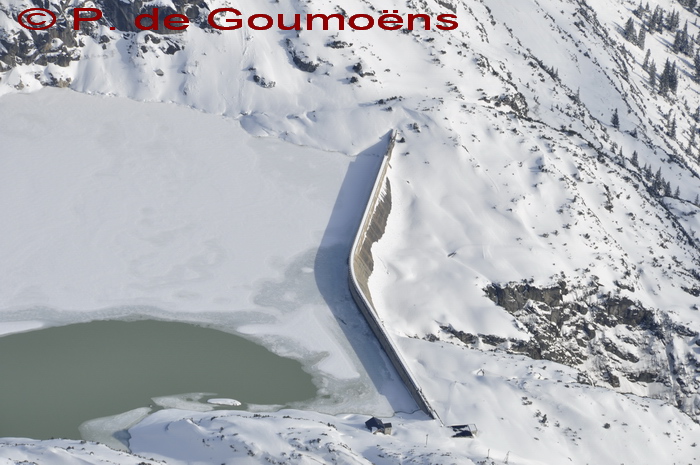
</video> and here are download links for those who prefer to download now and watch later (about 160MB): At the top At the top, there is a scenic two hour walk around Lake Gelmer, the path takes you across the top of a dam built for hydro-electric power generation. Lake Gelmer - hydro-electric dam Getting there from DebConf13 and the Debian 20th birthday For those coming to Switzerland for DebConf13 next month, the Gelmerbahn is probably a little bit too far for a day trip but makes an excellent place to stop during a 2 or 3 day tour around Switzerland. It is accessible using the all-day bus pass for the tour of 3 or 4 mountain passes or by train to Innertkirchen and then a short ride on the bus. The busses are irregular, use sbb.ch to plan the journey. Walking down the mountain from the lake to the bus stop takes about 90 minutes and for those who choose this option, the ticket is cheaper. More Swiss travel blogs Please click here to access some of my previous blogs about Swiss travel with videos and useful ideas for day trips.

29 July 2013

Gergely Nagy: HOWTO: JSON processing with syslog-ng

Continuing my HOWTO series, in this article, I will explore how to set up syslog-ng to process JSON in various scenarios. We will touch the subject of interoperability, and have a look at multiple scenarios, in the hope that readers will find something similar to their own needs. There are many different ways in which one can plug JSON into their logging system, and it is very likely that I will not be able to cover it all within this HOWTO. However, I will explain the basics, and how to plug the pieces together, which should at least be a useful foundation to build even more complex systems onto.In essence, we will look at the following scenarios: raw JSON transport, JSON over syslog, JSON and syslog payload in the same stream. The documentation will cover both syslog-ng 3.4 and 3.5, where the 3.5 parts will be clearly marked as such. The 3.3 series do not have a JSON parser, and as such, is insufficient for most needs explored in this guide.In the default setting, the JSON parser will parse the MESSAGE part of an incoming log event, and place every key into a macro of the same name. If the incoming JSON is structured, it the keys will be converted to dot notation format:
"deeper": "level": "very much so"
In this case, one can access the value as $ deeper.level within a syslog-ng template.The parsed keys can be prefixed using the prefix() option of the json-parser. One can also change what the parser will receive as input by using the template() option.See the documentation for more information on these.Transporting raw JSONThe simplest scenario is to take a transport like TCP, and simply push raw JSON structures through, one each line, and have syslog-ng parse that to its internal representation. One can do all kinds of things with the data then: transport it further as JSON, store it in files, in a database - the possibilities are endless, but we will explore two scenarios.JSON on TCP, using syslog field namesThe first one is receiving JSON on TCP, using syslog field names, store the parsed stuff in a file (using the conventional format), and in mongodb.
source s_tcp_json   tcp(port(10514) flags(no-parse));  ;
parser p_json   json-parser();  ;
destination d_file   file("/var/log/remote.log");  ;
destination d_mongodb   mongodb(collection("remote_log"));  ;
log  
 source(s_tcp_json);
 parser(p_json);
 destination(d_file);
 destination(d_mongodb);
 ;
This needs a bit of an explanation: we use the no-parse flag on the source, because by default, the tcp() source expects a message that conforms to the old syslog protocol. We have raw JSON, and we need to tell the source that. The other elements should be self explanatory, I believe, with the exception of json-parser(): we give it no parameters, so it will not modify the keys in the JSON it receives, keeping them intact, as-is.For this reason, incoming messages need to have the same keys as syslog-ng normally would use internally: DATE, HOST, MESSAGE, and so on, like in the following example:
"PROGRAM":"prg00000","PRIORITY":"info","PID":"1234","MESSAGE":"seq: 0000000000, thread: 0000, runid: 1374490607, stamp: 2013-07-22T12:56:47 MESSAGE...","HOST":"localhost","FACILITY":"auth","DATE":"Jul 22 12:56:47"
JSON on TCP, custom field namesA more likely scenario is when we receive JSON, but not in a layout syslog-ng uses internally. In this case, we need to rewrite the message a little, and possibly use templates, depending on what kind of output we wish to use.Lets assume the incoming JSON has these fields:
"app":"prg00000","prio":"info","id":"1234","msg":"seq: 0000000000, thread: 0000, runid: 1374490607, stamp: 2013-07-22T12:56:47 MESSAGE...","source":"localhost","timestamp":"Jul 22 12:56:47"
As you can see, this has similar fields, but not quite, and FACILITY is missing too.In this case, we'll use a different configuration:
source s_tcp_json   tcp(port(10514) flags(no-parse));  ;
parser p_json   json-parser(prefix(".json."));  ;
destination d_file   file("/var/log/remote.log"
                          template("$ .json.timestamp  $ .json.source  $ .json.app [$ .json.id ]: $ .json.msg \n"));  ;
destination d_mongodb   mongodb(collection("remote_log")
                                value-pairs(
                                  pair("PROGRAM" "$ .json.app ")
                                  pair("HOST" "$ .json.source ")
                                  pair("PID" "$ .json.id ")
                                  pair("MESSAGE" "$ .json.msg ")
                                  pair("DATE" "$ .json.timestamp ")
                                  pair("PRIORITY" "$ .json.prio ")
                                  pair("FACILITY" "auth")
                                ));  ;
log  
 source(s_tcp_json);
 parser(p_json);
 destination(d_file);
 destination(d_mongodb);
 ;
We use the prefix() option of json-parser(), to avoid collisions with the default syslog-ng namespace. Then, we use a template for the file destination, and value-pairs() for the MongoDB one. Doing all this, we get similar results as we did in the first scenario.JSON over syslogAn even likelier scenario is when we have JSON payload in the message part of a normal syslog message. This is useful because the logs themselves remain syslog compatible, and can be transported through devices that know no better.Thankfully, if we do not tell syslog-ng that we do not want any parsing on the input, the json-parser will receive the MESSAGE part of the log, so if we have JSON payload there, things will just work:
source s_tcp_json_payload   tcp();  ;
parser p_json   json-parser();  ;
destination d_file   file("/var/log/remote.log");  ;
destination d_mongodb   mongodb(collection("remote_log"));  ;
log  
 source(s_tcp_json_payload);
 parser(p_json);
 destination(d_file);
 destination(d_mongodb);
 ;
Again, this assumes that the JSON payloads uses field names compatible with syslog-ng's defaults. Adapting it to use templates or value-pairs can of course be made, as shown in an example above.As an example, here's how a syslog message with JSON payload would look like:
<38>2013-07-22T13:45:54 localhost prg00000[1234]:  "MESSAGE": "foo", "PROGRAM": "bar" 
This would, of course, override the MESSAGE and PROGRAM fields, but the rest would be kept intact.Mixed JSON and syslog streamIn order to parse JSON that is intermingled with normal syslog streams, we can use a new feature of syslog-ng 3.4: junctions. These allow us to create branches, and tell syslog-ng something along these lines:
If there's an incoming message, that begins with @json:, parse it as JSON, otherwise treat it as a normal syslog message.
We can, of course, skip the part that mandates an in-stream marker, and things will just work, but in that case, for each JSON message, an error will get logged too, which is undesirable. Therefore, if one wants to intermingle JSON and syslog traffic on the same wire, it's best to do so with the JSON having a marker prefix. The marker, however, is not going to be part of the string the json parser receives, so setting it to an opening curly bracket will not work, unless the template is modified accordingly.The config to do this looks like this:
block parser mixed-json-parser()  
 channel  
  junction  
   channel  
    parser   json-parser(marker("@json:"));  ;
    rewrite   set-tag(".json");  ;
    flags(final);
    ;
   channel  
    flags(final);
    ;
   ;
  ;
 ;
source s_mixed  
 tcp();
 parser   mixed-json-parser();  ;
 ;
A more elaborate example can be found in a post by Bazsi.Closing thoughtsThat covers most of the use cases I saw for the JSON parser, if there are cases uncovered, or questions unanswered, I can be reached via twitter, email and a whole host of other ways, and I will happily expand this tutorial if there's enough demand for more.

28 July 2013

Francois Marier: FISL for foreigners HOWTO

FISL (pronounced FIZZ lay by the locals) is a large Free and Open Source software gathering in Porto Alegre, Brazil. While the primary audience of that conference is the Latin America "libre software" community, a number of overseas speakers also participate in that conference. This is my contribution to them: a short guide for international guests visiting the F rum Internacional do Software Livre.

Planning Before you fly out, make sure you look up the visa requirements for your country of citizenship. Many western countries will require a visa and you will need to visit the local Brazillian embassy ahead of time to get one. Next, have a look at the list of recommended immunizations. As with most destinations, it is recommended that your routine immunizations be up to date, but there are also other specialized ones such as Yellow Fever that are recommended by the Brazillian government. You should therefore visit a travel clinic a few weeks ahead of time. Other than that, I suggest reading up on the country and keeping an eye on the various travel advisories.

Arrival You will be flying at the Porto Alegre airport. If you need to exchange overseas money for Brazilian Reals, you can do that there. You'll probably also want to pick up a power adapter at the airport if you intend to charge your laptop while you're in the country :) Brazil has both 127V and 220V outlets using Type N sockets. Privacy note: using the free airport wifi will require giving your Passport details as part of the registration process.

Language If you don't speak Portuguese, expect a few challenges since most of the people you'll meet (including taxi drivers, many airport workers, some hotel staff) won't speak English. I highly recommend getting a phrase book before you leave and printing paper maps of where you are planning to go (to show to taxi drivers when you get lost). Native Spanish speakers seem to get by speaking Spanish to Portuguese speakers and understanding enough Portuguese to hold a conversation. I wouldn't count on it unless your Spanish is quite good though. Also, the official conference blog posts get eventually translated to English, but there is a delay, so you may want to subscribe to the Portuguese feed and use Google Translate to keep up with FISL news before you get there.

The conference FISL is a large conference and it has a very "decentralized" feel to it. From the outside, it looks like it's organized by an army of volunteers where everyone is taking care of some portion of it without a whole lot of top-down direction. It seems to work quite well! What this means for you as a foreign speaker however is that you're unlikely to be provided with a lot of information or help finding your way around the conference (i.e. no "speaker liaison"). There is a separate registration desk for speakers but that's about all of the attention you'll receive before you deliver your talk. So make sure you know where to go and show up in your assigned room early to speak with the person introducing you. If your talk is in English, it will be live-transated by an interpreter. It's therefore a good idea to speak a bit more slowly and to pause a bit more. Other than that, the organizers make an effort to schedule an English talk in each timeslot so non-Portuguese speakers should still be able to get a lot out of the conference. FISL was a lot of fun for me and I hope that some of these tips will help you enjoy the biggest FLOSS gathering in the southern hemisphere!

27 July 2013

Julien Danjou: OpenStack Ceilometer Havana-2 milestone released

Last week, the second milestone of the Havana developement branch of Ceilometer has been released and is now available for testing and download. This means the first half of the OpenStack Havana development has passed! New features Ten blueprints have been implemented as you can see on the release page. I'm going to talk through some of them here, that are the most interesting for users.
The Ceilometer API now returns all the samples sorted by timestamp. This blueprint is the first one implemented by Terri Yu, our OPW intern! In the same spirit, I've added the ability to limit the number of samples returned. On the alarming front, things evolved a lot. I've implemented the notifier system that will be used to run actions when alarms are triggered. To trigger these alarms, Eoghan Glynn (RedHat) worked on the alarm evaluation system that will use the Ceilometer API to check for alarm states. I've reworked the publisher system so it now uses URL formatted target for publication. That now allows to publish different meters to different target using the same publishing protocol (e.g. via UDP toward different hosts). Sandy Walsh (RackSpace) have been working on the StackTach like functionality and added the ability for the collector to optionally store the notification events received. Finally, Mehdi Abaakouk (eNovance) implemented a TTL system for the database, so you're now able to expire your data whenever you like. Bug fixes Thirty-five bugs were fixed, though most of them might not interest you so I won't elaborate too much on that. Go read the list if you are curious. Toward Havana 3 We now have 30 blueprints targeting the Ceilometer's third Havana milestone, with some of them are already started.I'll try to make sure we'll get there without too much trouble for the 6th September 2013. Stay tuned!

Christian Perrier: Developers per country (July 2013)

This is time again for my annual report about the number of developers per country. This is now the fifth edition of this report, after the 2012, 2011, 2010 and 2009 editions. So, here we are with the July 2013 version, sorted by the ratio of *active* developers per million population for each country.
Act: number of active developers
Dev: total number of developers
A/M: number of active devels per million pop.
D/M: number of devels per million pop.
2009: rank in 2009
2010: rank in 2010
2011: rank in 2011 (June)
2011: rank in 2012 (June)
2013: rank now
Code Name Population Act Dev Dev Act/Million Dev/Million 2009 2010 June 2011 June 2012 July 2013
fi Finland 5259250 19 31 3,61 5,89 1 1 1 1 1
ie Ireland 4670976 12 15 2,57 3,21 13 9 6 2 2
ch Switzerland 7870134 20 27 2,54 3,43 2 2 2 3 3
mq Martinique 396404 1 1 2,52 2,52

3 4 4
se Sweden 9088728 22 37 2,42 4,07 3 6 7 5 5
no Norway 4973029 12 15 2,41 3,02 5 4 4 6 6
nz New Zealand 4331600 10 15 2,31 3,46 4 3 5 7 7
de Germany 81471834 165 235 2,03 2,88 7 7 9 9 8 *
lu Luxemburg 503302 1 1 1,99 1,99 8 5 8 8 9 *
at Austria 8217280 16 26 1,95 3,16 6 8 10 10 10
fr France 65350000 100 130 1,53 1,99 12 12 11 11 11
au Australia 22607571 31 59 1,37 2,61 9 10 12 12 12
be Belgium 11071483 14 17 1,26 1,54 10 11 13 13 13
uk United-Kingdom 62698362 73 114 1,16 1,82 14 14 14 14 14
nl Netherlands 16728091 19 40 1,14 2,39 11 13 15 15 15
ca Canada 33476688 32 61 0,96 1,82 15 15 17 16 16
dk Denmark 5529888 5 10 0,9 1,81 17 17 16 17 17
es Spain 46754784 35 56 0,75 1,2 16 16 19 18 18
it Italy 59464644 36 51 0,61 0,86 23 22 22 19 19
cz Czech Rep 10190213 6 6 0,59 0,59 21 20 21 21 20 *
lt Lithuania 3535547 2 2 0,57 0,57 28 19 20 22 21 *
us USA 313232044 173 378 0,55 1,21 19 21 25 24 22 *
il Israel 7740900 4 6 0,52 0,78 24 24 24 25 23 *
hu Hungary 10076062 5 10 0,5 0,99 18 25 26 20 24 *
hr Croatia 4290612 2 2 0,47 0,47 20 18 18 26 25 *
lv Latvia 2204708 1 1 0,45 0,45 26 26 27 27 26 *
bg Bulgaria 7364570 3 3 0,41 0,41 25 23 23 23 27 *
uy Uruguay 3477778 1 2 0,29 0,58 22 27 28 28 28
jp Japan 127078679 35 50 0,28 0,39 30 28 29 29 29
pl Poland 38441588 10 14 0,26 0,36 29 29 30 30 30
cr Costa Rica 4301712 1 1 0,23 0,23 31 30 31 31 31
by Belarus 9577552 2 2 0,21 0,21 35 36 39 39 32 *
sg Singapore 5183700 1 1 0,19 0,19


33 33
pt Portugal 10561614 2 4 0,19 0,38 27 32 32 34 34
gr Greece 10787690 2 3 0,19 0,28 33 38 34 35 35
sk Slovakia 5477038 1 1 0,18 0,18 32 31 33 36 36
ar Argentina 40677348 6 8 0,15 0,2 34 33 35 32 37 *
rs Serbia 7186862 1 1 0,14 0,14


38 *
tw Taiwan 23040040 3 3 0,13 0,13 37 34 37 37 39 *
br Brazil 192376496 21 23 0,11 0,12 36 35 38 38 40 *
cu Cuba 11241161 1 1 0,09 0,09
38 41 41 41
kr South Korea 48754657 4 6 0,08 0,12 39 39 42 42 42
gt Guatemala 13824463 1 1 0,07 0,07


43 *
ve Venezuela 28047938 2 2 0,07 0,07 40 45 50 49 44 *
ec Ecuador 15007343 1 1 0,07 0,07
40 43 43 45 *
co Colombia 45566856 3 4 0,07 0,09 41 44 46 47 46 *
cl Chile 16746491 1 2 0,06 0,12 42 41 44 44 47 *
za South Africa 50590000 3 10 0,06 0,2 38 48 48 48 48
ru Russia 143030106 7 8 0,05 0,06 43 42 47 45 49 *
mg Madagascar 21281844 1 1 0,05 0,05 44 37 40 40 50 *
ro Romania 21904551 1 2 0,05 0,09 45 43 45 46 51 *
my Malaysia 28250000 1 1 0,04 0,04

49 50 52 *
pe Peru 29907003 1 1 0,03 0,03 46 46 51 51 53 *
tr Turkey 74724269 2 2 0,03 0,03 47 47 52 52 54 *
ua Ukraine 45134707 1 1 0,02 0,02 48 53 58 59 55 *
th Thailand 66720153 1 2 0,01 0,03 50 50 54 54 56 *
eg Egypt 80081093 1 3 0,01 0,04 51 51 55 55 57 *
mx Mexico 112336538 1 1 0,01 0,01 49 49 53 53 58 *
cn China 1344413526 10 14 0,01 0,01 53 53 57 56 59 *
in India 1210193422 9 9 0,01 0,01 52 52 56 57 60 *
sv El Salvador 7066403 0 1 0 0,14

36 58 61 *


957 1535 62,35%


A few interesting facts:

25 July 2013

John Goerzen: Development Freedom in New Platforms

I started writing code when I was somewhere around 1st grade, hacking some rudimentary BASIC on a TRS-80. Since then, I ve used more programming languages than I can count; everything from C to Prolog, Python to Haskell, and probably a dozen others. I enjoy diversity in programming languages and tools. I ve had an interest in both web and mobile development for some time, but have done little with either. Reflecting on that lately, I realize that both platforms severely restrict my freedom to use the tools I choose. Even on an old x86 with 640K of RAM, I had choices; BASIC, Pascal, and C would work under DOS. (Plus assembler, but I had yet to learn that at the time.) On Android, my choices are Java or Java. (OK, or something that compiles to Java, but those selections are still limited.) Plus it seems like I d have to use Eclipse, which seems to have taken the kitchen sync crown from Emacs long ago, and not in a good way. On iOS, the choices are Objective C. And on the web, it s JavaScript. The problem with all this is that there s little room for language innovation on those platforms. If predictions about the decline of development on the PC pan out, how will the next advance in programming languages gain traction if the hot spots for development are locked down to three main languages? Will we find ourselves only willing to consider languages that can compile to Java/Dalvik bytecode? And won t that put limits on the possible space for innovation to occur within? Yes, I know about things like Mono and the Android Scripting Environment, which offer some potential for hope, but I think it s still safe to say that these platforms are pretty closed to development in unofficial languages. I don t know of major apps in the Android market written in Python, for instance. I know of efforts such as Ubuntu s, but even they simply lock down development to a different toolkit. There is no choice there of GTK vs. Qt, or such things. Sadly, I don t think it has to be this way. My phone has way more power than my computer did just a few years ago, and that computer was capable of not just executing, but even compiling, code written in all sorts of different languages. But I don t know if there s much we can do to change things. Even with native code on Android, plenty still has to go through Dalvik (at least that s my understanding). If you wanted to write a Python app with a full graphical touch interface on Android, I don t think this would be all that easy of a task.

24 July 2013

Daniel Leidert: Moving from (software) RAID 1 to RAID 5 and testing performance

Finally I finished migrating my new N54L from a 2-disk software RAID 1 (2x2TB WD20EFRX) to 3-disk RAID 5 (3x2TB WD20EFRX) using mdadm. I got an excellent mini HOWTO I followed. Resyncing and reshaping the RAID took several days ... top speed was 110.000K/s ... but left my data untouched. Finally growing the RAID now I have two partitions; one with 0.5GB (md0) and the other with 3.4GB (md1) which both host an EXT4 file system, whereas the first one is encrypted via LUKS and the second one is not. RAID device and file system configuration Below is a summary of the setup and the values I found working well for my system.
3-disk RAID 5 devicefile system
devicechunkstripe_cache_sizeread_ahead_kbtypeencryptionstridestripe-width
/dev/md064409632768ext4luks1632
/dev/md15121638432768ext4no128256
I've played around with the system a bit. Changing the chunk size on the fly however took a long time. /dev/md0 will contain some backups, so there probably will be a mixture of small and large files. So I've chosen to only test the values 64K, 128K and 512K (default) for this device. I left the other untouched as it will mainly contain large files. Performance measurement Below are the results using hdparm to measure performance. First lets take a look at the drives ...

$ hdparm -tT /dev/sd[bcd]
/dev/sdb:
Timing cached reads: 3268 MB in 2.00 seconds = 1634.54 MB/sec
Timing buffered disk reads: 438 MB in 3.00 seconds = 145.87 MB/sec

/dev/sdc:
Timing cached reads: 3292 MB in 2.00 seconds = 1646.32 MB/sec
Timing buffered disk reads: 392 MB in 3.01 seconds = 130.22 MB/sec

/dev/sdd:
Timing cached reads: 3306 MB in 2.00 seconds = 1653.18 MB/sec
Timing buffered disk reads: 436 MB in 3.00 seconds = 145.26 MB/sec

$ hdparm --direct -tT /dev/sd[bcd]
/dev/sdb:
Timing O_DIRECT cached reads: 468 MB in 2.01 seconds = 233.17 MB/sec
Timing O_DIRECT disk reads: 442 MB in 3.00 seconds = 147.15 MB/sec

/dev/sdc:
Timing O_DIRECT cached reads: 468 MB in 2.00 seconds = 233.69 MB/sec
Timing O_DIRECT disk reads: 392 MB in 3.01 seconds = 130.36 MB/sec

/dev/sdd:
Timing O_DIRECT cached reads: 468 MB in 2.00 seconds = 233.94 MB/sec
Timing O_DIRECT disk reads: 442 MB in 3.01 seconds = 146.93 MB/sec
... and now at the RAID devices ...

$ hdparm -tT /dev/md?
/dev/md0:
Timing cached reads: 3320 MB in 2.00 seconds = 1660.37 MB/sec
Timing buffered disk reads: 770 MB in 3.01 seconds = 256.05 MB/sec

/dev/md1:
Timing cached reads: 3336 MB in 2.00 seconds = 1668.07 MB/sec
Timing buffered disk reads: 742 MB in 3.01 seconds = 246.89 MB/sec

$ hdparm --direct -tT /dev/md?
/dev/md0:
Timing O_DIRECT cached reads: 974 MB in 2.00 seconds = 487.08 MB/sec
Timing O_DIRECT disk reads: 770 MB in 3.01 seconds = 256.17 MB/sec

/dev/md1:
Timing O_DIRECT cached reads: 784 MB in 2.00 seconds = 391.18 MB/sec
Timing O_DIRECT disk reads: 742 MB in 3.01 seconds = 246.42 MB/sec
... and now lets see, which actual speed we reach using dd. First lets check the encrypted device:

RAID-5 /dev/md0 (LUKS encrypted EXT4): chunk=64K, stripe_cache_size=4096,
readahead(blockdev)=65536, stride=16, stripe-width=32 ...

$ dd if=/dev/zero of=/mnt/md0/10g.img bs=1k count=10000000
10000000+0 Datens tze ein
10000000+0 Datens tze aus
10240000000 Bytes (10 GB) kopiert, 64,1227 s, 160 MB/s

$ dd if=/mnt/md0/10g.img of=/dev/null bs=1k count=10000000
10000000+0 Datens tze ein
10000000+0 Datens tze aus
10240000000 Bytes (10 GB) kopiert, 85,768 s, 119 MB/s
Well, read speed is consistently lower than write speed for the encrypted file system. Lets take a look at the non-encrypted device:

RAID-5 /dev/md1 (EXT4): chunk=512K, stripe_cache_size=16384,
readahead(blockdev)=65536, stride=128, stripe-width=256 ...

$ dd if=/dev/zero of=/mnt/md1/10g.img bs=1k count=10000000
10000000+0 Datens tze ein
10000000+0 Datens tze aus
10240000000 Bytes (10 GB) kopiert, 37,0016 s, 277 MB/s

$ dd if=/mnt/md1/10g.img of=/dev/null bs=1k count=10000000
10000000+0 Datens tze ein
10000000+0 Datens tze aus
10240000000 Bytes (10 GB) kopiert, 33,5901 s, 305 MB/s
Looks nice to me. How to set these values I use a mixture of udev, util-linux and e2fsprogs to set the values. First I checked, which values for stripe_cache_size and read_ahead_kb are working best for me. For the LUKS encrypted EXT4 I got varying results showing best performances with values of 4096, 8192 and 16384 for stripe_cache_size. I decided for the first value, because it appeared more often with the best performance than the others.

$ less /etc/udev/rules.d/90-local-n54l.rules grep stripe_cache
SUBSYSTEM=="block", KERNEL=="md0", ACTION=="add", TEST=="md/stripe_cache_size", TEST=="queue/read_ahead_kb", ATTR md/stripe_cache_size ="4096", ATTR queue/read_ahead_kb ="32768", ATTR bdi/read_ahead_kb ="32768"
SUBSYSTEM=="block", KERNEL=="md1", ACTION=="add", TEST=="md/stripe_cache_size", TEST=="queue/read_ahead_kb", ATTR md/stripe_cache_size ="16384", ATTR queue/read_ahead_kb ="32768", ATTR bdi/read_ahead_kb ="32768"
The read_ahead_kb value can also be set using blockdev. Note that this command expects a value of 512-byte sectors whereas read_ahead_kb is the size in kbyte. Therefor the difference in values:

$ blockdev --setra 65536 /dev/md[01]
Tuning the EXT4 file system performance with calculated values using tune2fs:

$ tune2fs -E stride=16,stripe-width=32 -O dir_index /dev/mapper/_dev_md0
$ tune2fs -E stride=128,stripe-width=256 -O dir_index /dev/md1
Disabling NCQ reduced the speed a lot for me, so I left the values as is and did not struggle with it:

$ cat /sys/block/sd[bcd]/device/queue_depth
31
31
31

Next.

Previous.