Search Results: "tar"

30 April 2016

Chris Lamb: Free software activities in April 2016

Here is my monthly update covering a large part of what I have been doing in the free software world (previously):
Debian My work in the Reproducible Builds project was covered in our weekly reports. (#48, #49, #50, #51 & #52)
Uploads
  • redis (2:3.0.7-3) Adding, amongst some other changes, systemd LimitNOFILE support to allow a higher number of open file descriptors.


FTP Team

As a Debian FTP assistant I ACCEPTed 135 packages: aptitude, asm, beagle, blends, btrfs-progs, camitk, cegui-mk2, cmor-tables, containerd, debian-science, debops, debops-playbooks, designate-dashboard, efitools, facedetect, flask-testing, fstl, ganeti-os-noop, gnupg, golang-fsnotify, golang-github-appc-goaci, golang-github-benbjohnson-tmpl, golang-github-dchest-safefile, golang-github-docker-go, golang-github-dylanmei-winrmtest, golang-github-hawkular-hawkular-client-go, golang-github-hlandau-degoutils, golang-github-hpcloud-tail, golang-github-klauspost-pgzip, golang-github-kyokomi-emoji, golang-github-masterminds-semver-dev, golang-github-masterminds-vcs-dev, golang-github-masterzen-xmlpath, golang-github-mitchellh-ioprogress, golang-github-smartystreets-assertions, golang-gopkg-hlandau-configurable.v1, golang-gopkg-hlandau-easyconfig.v1, golang-gopkg-hlandau-service.v2, golang-objx, golang-pty, golang-text, gpaste, gradle-plugin-protobuf, grip, haskell-brick, haskell-hledger-ui, haskell-lambdabot-haskell-plugins, haskell-text-zipper, haskell-werewolf, hkgerman, howdoi, jupyter-client, jupyter-core, letsencrypt.sh, libbpp-phyl, libbpp-raa, libbpp-seq, libbpp-seq-omics, libcbor-xs-perl, libdancer-plugin-email-perl, libdata-page-pageset-perl, libevt, libevtx, libgit-version-compare-perl, libgovirt, libmsiecf, libnet-ldap-server-test-perl, libpgobject-type-datetime-perl, libpgobject-type-json-perl, libpng1.6, librest-client-perl, libsecp256k1, libsmali-java, libtemplates-parser, libtest-requires-git-perl, libtext-xslate-perl, linux, linux-signed, mandelbulber2, netlib-java, nginx, node-rc, node-utml, nvidia-cuda-toolkit, openfst, openjdk-9, openssl, php-cache-integration-tests, pulseaudio, pyfr, pygccxml, pytest-runner, python-adventure, python-arrayfire, python-django-feincms, python-fastimport, python-fitsio, python-imagesize, python-lib389, python-libtrace, python-neovim-gui, python3-proselint, pythonpy, pyzo, r-cran-ca, r-cran-fitbitscraper, r-cran-goftest, r-cran-rnexml, r-cran-rprotobuf, rrdtool, ruby-proxifier, ruby-seamless-database-pool, ruby-syslog-logger, rustc, s5, sahara-dashboard, salt-formula-ceilometer, salt-formula-cinder, salt-formula-glance, salt-formula-heat, salt-formula-horizon, salt-formula-keystone, salt-formula-neutron, salt-formula-nova, seer, simplejson, smrtanalysis, tiles-autotag, tqdm, tran, trove-dashboard, vim, vulkan, xapian-bindings & xapian-core.

Daniel Stender: What I've worked on for Debian this month

This month I've worked on the following things for Debian: To begin with that, I've set up a Debhelper sequencer script for dh-buildinfo1, this add-on now can be used with dh $@ --with buildinfo in deb/rules instead of having to explicitly call it somewhere in an override. Debops I've set up initial Debian packages of Debops2, a collection of fine crafted Ansible roles and playbooks especially for Debian servers, shipped with a couple of convenience and wrapper scripts in Python3. There are two binary packages, one for the toolset (debops), and the other for the playbooks and roles of the project (debops-playbooks). The application is easy to use, just initialize a new project with debops-init foo and add your server(s) to foo/ansible/inventory/hosts belonging to groups representing services and things you want to employ on them. Like the group [debops_gitlab] automatically installs a complete running Gitlab setup on one or a multitude of servers in the same run with the debops command4. Use other groups like [debops_mariadb_server] accordingly in the same host inventory. Ansible runs agent less, so you don't have to prepare freshly setup servers with nothing special to use that tool randomly (like on localhost). The list of things you could deploy with Debops is quite amazing and you've got dozens of services at your hand. The new packages are currently in experimental because they need some more fine tuning, like there are a couple of minor error messages which recently occur using it, but it works well. The (early staged) documentation unfortunately couldn't be packaged because of the scattered resp. collective nature of the project (all parts have their own Github repositories)5, and also how to generate the upstream tarball remains a bit of a challenge (currently, it's the outcome of debops-init)6. I'll have this package in unstable soon. More info on Debops is coming up, then. Hashicorp's Packer I'm very glad to announce that Packer7 is ready being available in unstable, and the two year old RFP bug could be finally closed8. It's another great and much convenient devops tool which does a lot of different things in an automated fashion using only a single "one-argument" CLI tool in combination with a couple of lines in a configuration script (thanks to Yaroslav Halchenko for the tip). Packer helps creating machine images for different platforms. This is like when you use e.g. Debian installations in a Qemu box for testing or development purposes. Instead of setting up a new virtual machine manually like installing Debian on another computer this process could be automated with Packer, like I've written about in this blog entry here9. You just need a template containing instructions for the included Qemu-builder and a preseeding script for the Debian installer, and there you go drinking your coffee while Packer does all the work for you: downloading the installation ISO image, creating the new virtual harddrive, booting the emulator, running the whole installation process automatically like answering questions, selecting things, rebooting without ISO image to complete the installation etc. A couple of minutes and you have a new pre-baked virtual machine image like from a vendoring machine, a fresh one everytime you need it. Packer10 supports a number of builders for different target platforms (desktop virtualization solutions as much as public cloud providers and private cloud software), can build in parallel, and also the full range of common provisioners can be employed in the process to equip the newly installed OSs. Vagrant boxes could be generated by one of the included postprocessors. I'll write more on Packer here on this blog, soon. There were more then two dozens of packages missing to complete Packer11, which is the achievement of combined forces within the pkg-go group. Much thanks esp. to Alexandre Viau who have worked on the most of the needed new packages. Thanks also to the FTP-masters which were always very quick in reviewing the Go packages, so that it could be proceeded to build and package the sub dependent new ones always consecutively. Squirrel3 I've didn't had the most work with it and just sponsored this for Fabian Wolff, but want to highlight here that there's a new package of Squirrel12 now available in Debian13. Squirrel is a lightweight scripting language, somewhat comparable to Lua. It's fully object-oriented and highly embeddable, it's used in a lot of commerical computer games under the hood for implementing intelligence for bots next to other things14, but also for the Internet of Things (it's embedded in hardware from Electric Imp). Squirrel functions could be called from C++15. I've filed an ITP bug for Squirrel already in 2011 (#651195), but always something else got in the way, and it ended up being an RFP. I'm really glad that it got picked up and completed. misc There were a couple of uploads on updated upstream tarballs and for fixing bugs, namely afl/2.10b-1 and 2.11b-1, python-afl/0.5.3-1, pyutilib/5.3.2-1, pyomo/4.3.11327-1, libvigraimpex/1.10.0+git20160211.167be93dfsg-2 (fix of #820429, thanks for Tobias Frost), and gamera/3.4.2+svn1454-1. For the pkg-go group, I've set up a new package of github-mitchellh-ioprogress (which is needed by the official DigitalOcean CLI tool doctl, now RFP #807956 instead of ITP due to the lack of time - again facing a lot of missing packages), and provided a little patch for dh-make-golang updating some standards16. For Packer I've also updated azure-go-autorest and azure-sdk as team upload (#821938, #821832), but it came out that the project which is currently under heavy development towards a new official release broke a lot in the past weeks (and no Git branching have been used), so that Packer as a matter of fact needed a vendored snapshot, although there have been only a couple of commits in between. Docker-registry hat the same problem with the new package of azure-sdk/2.1.1~beta1, so that it needed to be fixed, too (#822146). By the way, the tool ratt17 comes very handy for automatically test building down all reverse dependencies, not only for Go packages (thanks to Tianon Gravi for the tip). Finally, I've posted the needed reverse depencies as RFP bugs for Terraform18 (again quite a lot), Vuls19, and cve-dictionary20, which is needed for Vuls. I'll let them rest a while waiting to get picked up before working anything down.

Daniel Stender: My work for Debian in April

This month I've worked on the these things for Debian: To begin with that, I've set up a Debhelper sequencer script for dh-buildinfo1, this add-on now can be used with dh $@ --with buildinfo in deb/rules instead of having to explicitly call it somewhere in an override. Debops I've set up initial Debian packages of Debops2, a collection of fine crafted Ansible roles and playbooks especially for Debian servers (servers which run on Debian), which are shipped with a couple of helper and wrapper scripts in Python3. There are two binary packages, one for the toolset (debops), and the other for the playbooks and roles of the project (debops-playbooks). The application is easy to use, just initialize a new project with debops-init foo and add your server(s) to foo/ansible/inventory/hosts belonging to groups representing services and things you want to employ on them. For example, the group [debops_gitlab] automatically installs a complete running Gitlab setup on one or a multitude of servers in the same run with the debops command4. Other groups like [debops_mariadb_server] could be used accordingly in the same host inventory. Ansible works without agent, so you don't have to prepare freshly setup servers with nothing special to use that tool randomly (like on localhost). The list of things you could deploy with Debops is quite amazing and dozens of services are at hand. The new Debian packages are currently in experimental because they need some more fine tuning, e.g. there are a couple of minor error messages which recently occur using it, but it works well. The (early staged) documentation unfortunately couldn't be packaged because of the scattered resp. collective nature of the project (all parts have their own Github repositories)5, and also how to generate the upstream tarball remains a bit of a challenge (currently, it's the outcome of debops-init)6. I'll have this package in unstable soon. More info on Debops is coming up, then. HashiCorp's Packer I'm very glad to announce that Packer7 is ready being available in unstable, and the RFP bug could be finally closed after I've taken it over8. It's another great and much convenient devops tool which does a lot of different things in an automated fashion using only a single "one-argument" CLI tool in combination with a couple of lines in a configuration script (thanks to Yaroslav Halchenko for the tip). Packer helps creating machine images for different platforms. This is like when you use e.g. Debian installations in a Qemu box for testing or development purposes. Instead of setting up a new virtual machine manually the same way as installing Debian on another computer this process can be completely automated with Packer, like I've written about in this blog entry here9. You just need a template which contains instructions for the included Qemu builder and a preseeding script for the Debian installer, and there you go drinking your coffee while Packer does all the work: download the ISO image for installation, create the new virtual harddrive, boot the emulator, run the whole installation process automatically like with answering questions, selecting things, reboot without ISO image to complete the installation etc. A couple of minutes and you have a new pre-baked virtual machine image like from a vendoring machine, another fresh one could be created anytime. Packer10 supports a number of builders for different target platforms (desktop virtualization solutions as much as public cloud providers and private cloud software), can build in parallel, and also the full range of common provisioners can be employed in the process to equip the newly installed OSs with services and programs. Vagrant boxes could be generated by one of the included postprocessors. I'll write more on Packer here on this blog, soon. There were more then two dozens of packages missing to complete Packer11, which is the achievement of combined forces within the pkg-go group. Much thanks esp. to Alexandre Viau who have worked on the most of the needed new packages. Thanks also to the FTP masters which were always very quick in reviewing the Go packages, so that it could be proceeded to build and package the sub dependent new ones always consecutively. Squirrel3 I've didn't had the major work of that and just sponsored this for Fabian Wolff, but want to highlight here that there's a new package of Squirrel12 now available in Debian13. Squirrel is a lightweight scripting language, somewhat comparable to Lua. It's fully object-oriented and highly embeddable, it's used in a lot of commerical computer games under the hood for implementing intelligence for bots next to other things14, but also for the Internet of Things (it's embedded in hardware from Electric Imp). Squirrel functions could be called from C++15. I've filed an ITP bug for Squirrel already in 2011 (#651195), but always something else had a higher priority, and it ended up being an RFP. I'm really glad that it got picked up and completed quickly afterwards. misc There were a couple of uploads on updated upstream tarballs and for fixing bugs, namely afl/2.10b-1 and 2.11b-1, python-afl/0.5.3-1, pyutilib/5.3.2-1, pyomo/4.3.11327-1, libvigraimpex/1.10.0+git20160211.167be93dfsg-2 (fix of #820429, thanks to Tobias Frost), and gamera/3.4.2+svn1454-1. For the pkg-go group, I've set up a new package of github-mitchellh-ioprogress (which is needed by the official DigitalOcean CLI tool doctl, now RFP #807956 instead of ITP due to the lack of time, again a lot of missing packages are missing for that), and provided a little patch for dh-make-golang updating some standards16. For Packer I've also updated azure-go-autorest and azure-sdk as team upload (#821938, #821832), but it came out that the project which is currently under heavy development towards a new official release broke a lot in the past weeks (no Git branching have been used), so that Packer as a matter of fact needed a vendored snapshot, although there have been only a couple of commits in between. Docker-registry has the same problem with the new package of azure-sdk/2.1.1~beta1, so that it needed to be fixed, too (#822146). By the way, the tool ratt17 comes very handy for automatically test building down all reverse dependencies, not only for Go packages (thanks to Tianon Gravi for the tip). Finally, I've posted the needed reverse depencies as RFP bugs for Terraform18 (again quite a lot), Vuls19, and cve-dictionary20, which is needed for Vuls. I'll let them rest a while waiting to get picked up before working anything down.

Stein Magnus Jodal: March and April contributions

The following is a short summary of my open source work in March and April, almost like in previous months, except that I haven t spent as much time as previously on Open Source the last two months.

Debian

Mopidy
  • Bugfixes for the upcoming Mopidy 2.0.1 (which should have been released a long time ago): merged PR #1455, created PR #1493.
  • Started on, but didn t finish, fixing the Travis CI setup for Mopidy-GMusic.
  • Upgraded the Mopidy project server from Ubuntu 14.04 LTS to 16.04 LTS. Rebuilt the discuss.mopidy.com Discourse/Docker instance.
  • Accepted Lars Kruse as the new maintainer of Mopidy-Beets. Thanks!
  • The extensions still in need of a new maintainer are: If you re a user of any of these and want to contribute, please step up. Instructions can be found in the README of any of these projects.

29 April 2016

Iain R. Learmonth: MiniDebCamp Vienna 2016

I'm currently in Vienna for MiniDebCamp and MiniDebConf at FH Technikum Wien, hosted as a part of Linuxwochen Wien. Today and yesterday have been spent hacking on Debian, and I've produced a few package updates and closed a few bugs.

Scapy The last update to Scapy in Debian was in August 2011. Bug #773554 was filed in 2014 to request a new upstream version be packaged and in a few days this bug should be closed. As this package is maintained by someone else and I'm performing a non-maintainer upload, the upload will sit in the delayed queue for 3 days. There has also been a Python 3 port of Scapy developed, and I've also packaged this (bug #822096). You will be able to install this version as python3-scapy and run it as /usr/bin/scapy3, which means it can fully co-exist with an installation of the original Python 2 version on the same system.

Hamradio Blend
  • Carles Fernandez had produced an updated package for gnss-sdr and this has now been uploaded to unstable.
  • Ana Custura produced an updated package for chirp and this has now been uploaded to unstable.
  • I've made a couple of updates to the hamradio-maintguide and released version 0.2 of that documentation. This was simple changes for secure URIs for the Vcs-* fields and options for updating existing packages to new upstream versions using uscan, by tarball URL or by local tarball.

qtile qtile is a "full-featured, hackable tiling window manager written and configured in Python". I've been a big fan of tiling window managers for a few years now, starting with XMonad in 2013, moving to i3 and now I plan to move to qtile as I think its customisability and complete removal of window decorations will work well for me. I have now packaged qtile (bug #762637), and updated one of its dependencies (xcffib), and it will appear in unstable after passing ftp-master scrutiny.

28 April 2016

Holger Levsen: Voctomix available in Debian sid

Yesterday evening CarlFK prodded me to package Voctomix, which is a live video mixer written by the Chaos Communication Congress' Video Operation Crew. It's written in Python using GStreamer and was started when they realised dvswitch was not suitable anymore for them. The DebConf16 video team plans to test it in Cape Town (for covering the BoF room), so I figured I'd help now with packaging the software. Less than 24h after I started, voctomix made it through NEW and is now available in sid and hopefully will be available in stretch soon too! And by DebConf16 it should also finally be available in jessie-backports. Wheeehooo! Thanks to Stefano Rivera who helped me with some dh_python3 detail and the Debian ftpmasters for letting it though NEW so quickly (and btw, for their general awesome work on NEW processing in the last years too!) - may the winkekatze be with you! ;-)

Dirk Eddelbuettel: RcppRedis 0.1.7

A new release of RcppRedis arrived on CRAN today. And just like for the previous release, Russell Pierce contributed a lot of changes via several pull requests which make for more robust operations. In addition, we have started to add support for MessagePack by relying on our recently-announced RcppMsgPack package.
Changes in version 0.1.7 (2016-04-27)
  • Added support for timeout constructor argument (PR #14 by Russell Pierce)
  • Added new commands exists, ltrim, expire and pexpire along with unit tests (PR #16 by Russell Pierce)
  • Return NULL for empty keys in serialized get for consistency with lpop and rpop (also PR #16 by Russell Pierce)
  • Minor corrections to get code and hget and hset documentation (also PR #16 by Russell Pierce)
  • Error conditions are now properly forwarded as R errors (PR #22 by Russell Pierce)
  • Results from Redis commands are now checked for NULL (PR #23 by Russell Pierce)
  • MessagePack encoding can now be used which requires MessagePackage headers of version 1.0 or later; the (optional) RcppMsgPack package can be used.
Courtesy of CRANberries, there is also a diffstat report for the most recent release. More information is on the RcppRedis page.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

26 April 2016

Jonathan McDowell: Notes on Kodi + IR remotes

This post is largely to remind myself of the details next time I hit something similar; I found bits of relevant information all over the place, but not in one single location. I love Kodi. These days the Debian packages give me a nice out of the box experience that is easy to use. The problem comes in dealing with remote controls and making best use of the available buttons. In particular I want to upgrade the VDR setup my parents have to a more modern machine that s capable of running Kodi. In this instance an AMD E350 nettop, which isn t recent but does have sufficient hardware acceleration of video decoding to do the job. Plus it has a built in fintek CIR setup. First step was finding a decent remote. The fintek is a proper IR receiver supported by the in-kernel decoding options, so I had a lot of flexibility. As it happened I ended up with a surplus to requirements Virgin V Box HD remote (URC174000-04R01). This has the advantage of looking exactly like a STB remote, because it is one. Pointed it at the box, saw that the fintek_cir module was already installed and fired up irrecord. Failed to get it to actually record properly. Googled lots. Found ir-keytable. Fired up ir-keytable -t and managed to get sensible output with the RC-5 decoder. Used irrecord -l to get a list of valid button names and proceed to construct a vboxhd file which I dropped in /etc/rc_keymaps/. I then added a
fintek-cir * vboxhd
line to /etc/rc_maps.cfg to force my new keymap to be loaded on boot. That got my remote working, but then came the issue of dealing with the fact that some keys worked fine in Kodi and others didn t. This seems to be an issue with scancodes above 0xff. I could have remapped the remote not to use any of these, but instead I went down the inputlirc approach (which is already in use on the existing VDR box). For this I needed a stable device file to point it at; the /dev/input/eventN file wasn t stable and as a platform device it didn t end up with a useful entry in /dev/input/by-id. A quick
udevadm info -a -p $(udevadm info -q path -n /dev/input/eventN)
provided me with the PNP id (FIT0002) allowing me to create /etc/udev/rules.d/70-remote-control.rules containing
KERNEL=="event*",ATTRS id =="FIT0002",SYMLINK="input/remote"
Bingo, a /dev/input/remote symlink. /etc/defaults/inputlirc ended up containing:
EVENTS="/dev/input/remote"
OPTIONS="-g -m 0"
The options tell it to grab the device for its own exclusive use, and to take all scancodes rather than letting the keyboard ones through to the normal keyboard layer. I didn t want anything other than things specifically configured to use the remote to get the key presses. At this point Kodi refused to actually do anything with the key presses. Looking at ~kodi/.kodi/temp/kodi.log I could see them getting seen, but not understood. Further searching led me to construct an Lircmap.xml - in particular the piece I needed was the <remote device="/dev/input/remote"> bit. The existing /usr/share/kodi/system/Lircmap.xml provided a good starting point for what I wanted and I dropped my generated file in ~kodi/.kodi/userdata/. (Sadly it turns out I got lucky with the remote; it seems to be using the RC-5x variant which was broken in 3.17; works fine with the 3.16 kernel in Debian 8 (jessie) but nothing later. I ve narrowed down the offending commit and raised #117221.) Helpful pages included:

Niels Thykier: Putting Debian packages in labelled boxes

Lintian 2.5.44 was released the other day and (to most) the most significant bug fix was probably that Lintian learned about Policy 3.9.8. I would like to thank Axel Beckert for doing that. Notably it also made me update the test suite so to make future policy releases less painful. For others, it might be the fact that Lintian now accepts (valid) versioned provides (which seemed prudent now that Britney accepts them as well). Newcomers might appreciate that we are giving a much more sensible warning when they have extra spaces in their changelog sign off line (rather than pretending it is an improper NMU). But I digress What I am here to talk about is that Lintian 2.5.44 started classifying packages based on various facts or properties , we can determine. Therefore: Here are some of the labelled boxes your packages will be put into[0]: The tags themselves are (as mentioned) mere classifications and their primary purpose is to classify or measure certain properties. With them any body can download the data set and come with some bold statement about Debian packages (hopefully without relying too much on lies, damned lies and statistics ). Lets try that immediately! In the next release, we will also add tracking of auto-generated snippets from dh_*-tools. Currently unversioned, but I hope to add versioning to that so we can find and rebuild packages that have been built with buggy autoscripts (like #788098) If you want to see the classification tags for your package, please run lintian with like this:
# Add classification tags
$ lintian -L +classification <pkg-or-changes>
# Or if you want only classification tags$ lintian -L =classification <pkg-or-changes>
Please keep in mind that classification tags ( C ) are not issues in themselves. Lintian is simply attempting to add a visible indicator about a given fact or property in the package nothing more, nothing less. Future work help (read: patches) welcome: [0] Mind you, the reporting framework s handling of these tags could certainly be improved. [1] Please note how it distinguishes 1.0 into native and non-native based on whether the package has a diff.gz. Presumably that can be exploited somehow [2] Disclaimer: At the time of writing, only ~80% of the archive have been processed. This is computed as: NS / (NS + WS), where NS and WS are the number of unique packages with the tags no-ctrl-scripts and ctrl-script respectively. [3] or maybe not, but we got two packages classified as using both CDBS and the dh-sequencer. I have not looked at it in detail. For the curious: libmecab-java and ctioga2.
Filed under: Debian, Lintian

Matthias Klumpp: Why are AppStream metainfo files XML data?

This is a question raised quite quite often, the last time in a blogpost by Thomas, so I thought it is a good idea to give a slightly longer explanation (and also create an article to link to ). There are basically three reasons for using XML as the default format for metainfo files: 1. XML is easily forward/backward compatible, while YAML is not This is a matter of extending the AppStream metainfo files with new entries, or adapt existing entries to new needs. Take this example XML line for defining an icon for an application:
<icon type="cached">foobar.png</icon>
and now the equivalent YAML:
Icons:
  cached: foobar.png
Now consider we want to add a width and height property to the icons, because we started to allow more than one icon size. Easy for the XML:
<icon type="cached" width="128" height="128">foobar.png</icon>
This line of XML can be read correctly by both old parsers, which will just see the icon as before without reading the size information, and new parsers, which can make use of the additional information if they want. The change is both forward and backward compatible. This looks differently with the YAML file. The foobar.png is a string-type, and parsers will expect a string as value for the cached key, while we would need a dictionary there to include the additional width/height information:
Icons:
  cached: name: foobar.png
          width: 128
          height: 128
The change shown above will break existing parsers though. Of course, we could add a cached2 key, but that would require people to write two entries, to keep compatibility with older parsers:
Icons:
  cached: foobar.png
  cached2: name: foobar.png
          width: 128
          height: 128
Less than ideal. While there are ways to break compatibility in XML documents too, as well as ways to design YAML documents in a way which minimizes the risk of breaking compatibility later, keeping the format future-proof is far easier with XML compared to YAML (and sometimes simply not possible with YAML documents). This makes XML a good choice for this usecase, since we can not do transitions with thousands of independent upstream projects easily, and need to care about backwards compatibility. 2. Translating YAML is not much fun A property of AppStream metainfo files is that they can be easily translated into multiple languages. For that, tools like intltool and itstool exist to aid with translating XML using Gettext files. This can be done at project build-time, keeping a clean, minimal XML file, or before, storing the translated strings directly in the XML document. Generally, YAML files can be translated too. Take the following example (shamelessly copied from Dolphin):
<summary>File Manager</summary>
<summary xml:lang="bs">Upravitelj datoteka</summary>
<summary xml:lang="cs">Spr vce soubor </summary>
<summary xml:lang="da">Filh ndtering</summary>
This would become something like this in YAML:
Summary:
  C: File Manager
  bs: Upravitelj datoteka
  cs: Spr vce soubor 
  da: Filh ndtering
Looks manageable, right? Now, AppStream also covers long descriptions, where individual paragraphs can be translated by the translators. This looks like this in XML:
<description>
  <p>Dolphin is a lightweight file manager. It has been designed with ease of use and simplicity in mind, while still allowing flexibility and customisation. This means that you can do your file management exactly the way you want to do it.</p>
  <p xml:lang="de">Dolphin ist ein schlankes Programm zur Dateiverwaltung. Es wurde mit dem Ziel entwickelt, einfach in der Anwendung, dabei aber auch flexibel und anpassungsf hig zu sein. Sie k nnen daher Ihre Dateiverwaltungsaufgaben genau nach Ihren Bed rfnissen ausf hren.</p>
  <p>Features:</p>
  <p xml:lang="de">Funktionen:</p>
  <p xml:lang="es">Caracter sticas:</p>
  <ul>
  <li>Navigation (or breadcrumb) bar for URLs, allowing you to quickly navigate through the hierarchy of files and folders.</li>
  <li xml:lang="de">Navigationsleiste f r Adressen (auch editierbar), mit der Sie schnell durch die Hierarchie der Dateien und Ordner navigieren k nnen.</li>
  <li xml:lang="es">barra de navegaci n (o de ruta completa) para URL que permite navegar r pidamente a trav s de la jerarqu a de archivos y carpetas.</li>
  <li>Supports several different kinds of view styles and properties and allows you to configure the view exactly how you want it.</li>
  ....
  </ul>
</description>
Now, how would you represent this in YAML? Since we need to preserve the paragraph and enumeration markup somehow, and creating a large chain of YAML dictionaries is not really a sane option, the only choices would be: In both cases, we would loose the ability to translate individual paragraphs, which also means that as soon as the developer changes the original text in YAML, translators would need to translate the whole bunch again, which is inconvenient. On top of that, there are no tools to translate YAML properly that I am aware of, so we would need to write those too. 3. Allowing XML and YAML makes a confusing story and adds complexity While adding YAML as a format would not be too hard, given that we already support it for DEP-11 distro metadata (Debian uses this), it would make the business of creating metainfo files more confusing. At time, we have a clear story: Write the XML, store it in /usr/share/metainfo, use standard tools to translate the translatable entries. Adding YAML to the mix adds an additional choice that needs to be supported for eternity and also has the problems mentioned above. I wanted to add YAML as format for AppStream, and we discussed this at the hackfest as well, but in the end I think it isn t worth the pain of supporting it for upstream projects (remember, someone needs to maintain the parsers and specification too and keep XML and YAML in sync and updated). Don t get me wrong, I love YAML, but for translated metadata which needs a guarantee on format stability it is not the ideal choice. So yeah, XML isn t fun to write by hand. But for this case, XML is a good choice.

Michal &#268;iha&#345;: Weekly phpMyAdmin contributions 2016-W16

Last week was again focused on bug fixing due to increased amount of received bug reports on 4.6.0 release. Fortunately most of the annoying bugs are already fixed in git and will be soon released as 4.6.1. Another bigger task which was started last week was wiki migration. So far we've been using own wiki running MediaWiki and we're migrating it to GitHub wiki. The wiki on GitHub is way simpler, but it seems as better choice for us. During the migration all user documentation will be merged into our documentation, so that it's all in one place and wiki will be targeted on developers. Handled issues:

Filed under: English phpMyAdmin 2 comments

Rhonda D'Vine: Prince

Last week we lost another great musician, song writer, artist. It's painful to realise that more and more of the people you grew up with aren't there anymore. We lost Prince, TAFKAP, Symbol, Prince. He wrote a lot of great music, even some you wouldn't attribute to him, like Sinead O'Connor's Nothing Compares To You, Bangles' Manic Monday or Chaka Khan's I Feel For You. But I actually would like to share some songs that are also performed by himself, so without further ado here are the songs: Rest in peace, Prince. And you, enjoy.

/music permanent link Comments: 0 Flattr this

Steinar H. Gunderson: Full stack

As I'm nearing the point where Nageru, my live video mixer, can produce a stream directly that is actually suitable to streaming directly to clients (without a transcoding layer in the chain), it struck me the other day how much of the chain I've actually had to touch: In my test setup, the signal comes into a Blackmagic Intensity Shuttle. At some point, I found what I believe is a bug in the card's firmware; I couldn't fix it, but a workaround was applied in the Linux kernel. (I also have some of their PCI cards, in which I haven't found any bugs, but I have found bugs in their drivers.) From there, it goes into bmusb, a driver I wrote myself. bmusb uses libusb-1.0 to drive the USB card from userspace but for performance and stability reasons, I patched libusb to use the new usbfs zerocopy support in the Linux kernel. (The patch is still pending review.) Said zerocopy support wasn't written by me, but I did the work to clean up the support and push it upstream (it's in the 4.6-rc* series). Once safely through bmusb, it goes of course into Nageru, which I wrote myself. Nageru uses Movit for pixel processing, which I also wrote myself. Movit in turn uses OpenGL; I've found bugs in all three major driver implementations, and fixed a Nageru-related one in Mesa (and in the process of debugging that, found bugs in apitrace, a most useful OpenGL debugger). Sound goes through zita-resampler to stretch it ever so gently (in case audio and video clocks are out of sync), which I didn't wrote, but patched to get SSE support (patch pending upstream). So now Nageru chews a bit on it, and then encodes the video using x264 (that's the new part in 1.3.0 of course, you need a fast CPU to do that as opposed to using Quick Sync). I didn't write x264, but I had to redo parts of the speedcontrol patch (not part of upstream; awaiting review semi-upstream) because of bugs and outdated timings, but I also found a bug in x264 proper (fixed by upstream, pending inclusion). Muxing is done through ffmpeg, where I actually found multiple bugs in the muxer (some of which are still pending fixes). Once the stream is safely encoded and hopefully reasonably standards-conforming (that took me quite a while), it goes to Cubemap, which I wrote, for reflection to clients. For low-bitrate clients, it takes a detour through VLC to get a re-encode on a faster machine to lower bitrate I've found multiple bugs in VLC's streaming support in the past (and also fixed some of them, plus written the code that interacts with Cubemap). From there it goes to any of several clients, usually a browser. I didn't write any browsers (thank goodness!), but I wrote the client-side JavaScript that picks the closest relay, and the code for sending it to a Chromecast. I also found a bug in Chrome for Android (will be fixed in version 50 or 51, although the fix was just about turning on something that was already in the works), and one in Firefox for Linux (fixed by patching GStreamer's MP4 demuxer, although they've since switched away from that to something less crappy). IE/Edge also broke at some point, but unfortunately I don't have a way to report bugs to Microsoft. There's also at least one VLC bug involved on the client side (it starts decoding frames too late if they come with certain irregular timestamps, which causes them to drop), but I want to verify that they still persist even after the muxer is fixed before I go deep on that. Moral of the story: If anyone wants to write a multimedia application and says I'll just use <framework, language or library XYZ>, and I'll get everything for free; I just need to click things together! , they simply don't know what they're talking about and are in for a rude awakening. Multimedia is hard, an amazing amount of things can go wrong, complex systems have subtle bugs, and there is no silver bullet.

Matthias Klumpp: A GNOME Software Hackfest report

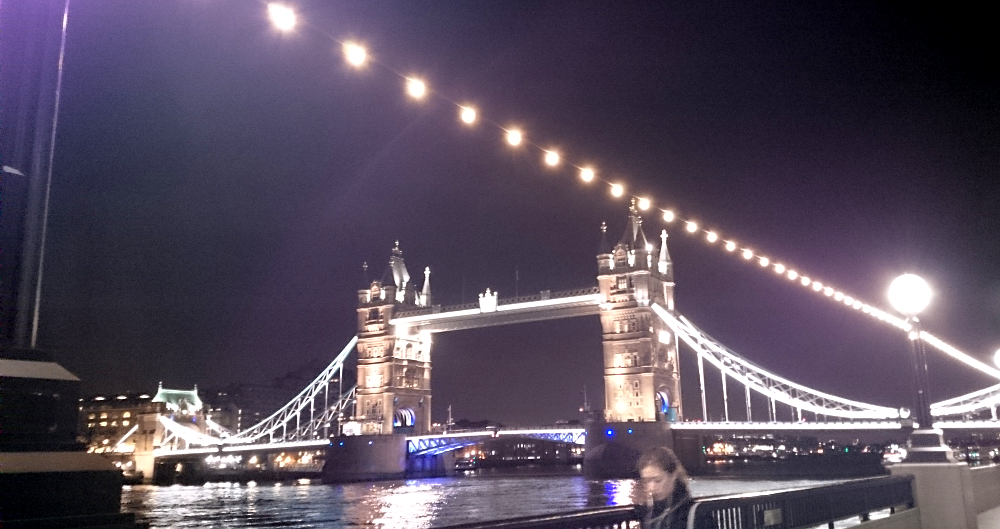
Two weeks ago was the GNOME Software hackfest in London, and I ve been there! And I just now found the time to blog about it, but better do it late than never  . Arriving in London and finding the Red Hat offices After being stuck in trains for the weekend, but fortunately arriving at the airport in time, I finally made it to London with quite some delay due to the slow bus transfer from Stansted Airport. After finding the hotel, the next issue was to get food and a place which accepted my credit card, which was surprisingly hard in defence of London I must say though, that it was a Sunday, 7 p.m. and my card is somewhat special (in Canada, it managed to crash some card readers, so they needed a hard-reset). While searching for food, I also found the Red Hat offices where the hackfest was starting the next day by accident. My hotel, the office and the tower bridge were really close, which was awesome! I have been to London in 2008 the last time, and only for a day, so being that close to the city center was great. The hackfest didn t leave any time to visit the city much, but by being close to the center, one could hardly avoid the London experience  . Cool people working on great stuff towerbridge2016That s basically the summary for the hackfest  . It was awesome to meet with Richard Hughes again, since we haven t seen each other in person since 2011, but work on lots of stuff together. This was especially important, since we managed to solve quite some disagreements we had over stuff Richard even almost managed to make me give in to adding <kudos/> to the AppStream spec, something which I was pretty against supporting (it didn t make it yet, but I am no longer against the idea of having that the remaining issues are solvable). Meeting Iain Lane again (after FOSDEM) was also very nice, and also seeing other people I ve only worked with over IRC or bug reports (e.g. William, Kalev, ) was great. Also lots of new people were there, like guys from Endless, who build their low-budget computer for developing/emerging countries on top of GNOME and Linux technologies. It s pretty cool stuff they do, you should check out their website! (they also build their distribution on top of Debian, which is even more awesome, and something I didn t know before (because many Endless people I met before were associated with GNOME or Fedora, I kind of implicitly assumed the system was based on Fedora  )). The incarnation of GNOME Software used by endless looks pretty different from what the normal GNOME user sees, since it s adjusted for a different audience and input method. But it looks great, and is a good example for how versatile GS already is! And for upstream GNOME, we ve seen some pretty great mockups done by Endless too I hope those will make it into production somehow.
Ironically, a "snapstore" was close to the office ;-)

Ironically, a snapstore was close to the office ;-)

XdgApp and sandboxing of apps was also a big topic, aside from Ubuntu and Endless integration. Fortunately, Alexander Larsson was also there to answer all the sandboxing and XdgApp-questions. I used the time to follow up on a conversation with Alexander we started at FOSDEM this year, about the Limba vs. XdgApp bundling issue. While we are in-line on the sandboxing approach, the way how software is distributed is implemented differently in Limba and XdgApp, and it is bad to have too many bundling systems around (doesn t make for a good story where we can just tell developers ship as this bundling format, and it will be supported everywhere ). Talking with Alex about this was very nice, and I think there is a way out of the too-many-solutions dilemma, at least for Limba and XdgApp I will blog about that separately soon. On the Ubuntu side, a lot of bugs and issues were squashed and changes upstreamed to GNOME, and people were generally doing their best to reduce Richard s bus-factor on the project a little  . I mainly worked on AppStream issues, finishing up the last pieces of appstream-generator and running it against some sample package sets (and later that week against the whole Debian archive). I also started to implement support for showing AppStream issues in the Debian PTS (this work is not finished yet). I also managed to solve a few bugs in the old DEP-11 generator and prepare another release for Ubuntu. We also enjoyed some good Japanese food, and some incredibly great, but also suddenly very expensive Indian food (but that s a different story  ). The most important thing for me though was to get together with people actually using AppStream metadata in software centers and also more specialized places. This yielded some useful findings, e.g. that localized screenshots are not something weird, but actually a wanted feature of Endless for their curated AppStore. So localized screenshots will be part of the next AppStream spec. Also, there seems to be a general need to ship curation information for software centers somehow (which apps are featured? how are they styled? added special banners for some featured apps, app of the day features, etc.). This problem hasn t been solved, since it s highly implementation-specific, and AppStream should be distro-agnostic. But it is something we might be able to address in a generic way sooner or later (I need to talk to people at KDE and Elementary about it). In summary It was a great event! Going to conferences and hackfests always makes me feel like it moves projects leaps ahead, even if you do little coding. Sorting out issues together with people you see in person (rather than communicating with them via text messages or video chat), is IMHO always the most productive way to move forward (yeah, unless you do this every week, but I think you get my point  ). For me, being the only (and youngest ^^) developer at the hackfest who was not employed by any company in the FLOSS business, the hackfest was also motivating to continue to invest spare time into working on these projects. So, the only thing left to do is a huge shout out of THANK YOU to the Ubuntu Community Fund and therefore the Ubuntu community for sponsoring me! You rock! Also huge thanks to Canonical for organizing the sponsoring really quickly, so I didn t get into trouble with paying my flights.
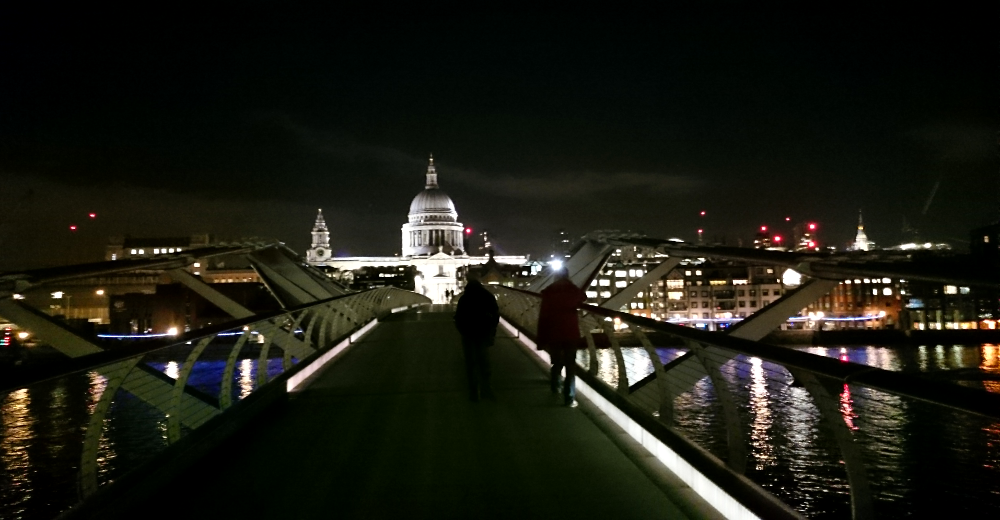
Laney and attente walking on the Millennium Bridge after we walked the distance between Red Hat and Canonical's offices.

Laney and attente on the Millennium Bridge after we walked the distance between Red Hat and Canonical s offices.

To worried KDE people: No, I didn t leave the blue side I just generally work on cross-desktop stuff, and would like all desktops to work as well as possible

Francois Marier: Using DNSSEC and DNSCrypt in Debian

While there is real progress being made towards eliminating insecure HTTP traffic, DNS is a fundamental Internet service that still usually relies on unauthenticated cleartext. There are however a few efforts to try and fix this problem. Here is the setup I use on my Debian laptop to make use of both DNSSEC and DNSCrypt.

DNSCrypt DNSCrypt was created to enable end-users to encrypt the traffic between themselves and their chosen DNS resolver. To switch away from your ISP's default DNS resolver to a DNSCrypt resolver, simply install the dnscrypt-proxy package and then set it as the default resolver either in /etc/resolv.conf:
nameserver 127.0.2.1
if you are using a static network configuration or in /etc/dhcp/dhclient.conf:
supersede domain-name-servers 127.0.2.1;
if you rely on dynamic network configuration via DHCP. There are two things you might want to keep in mind when choosing your DNSCrypt resolver:
  • whether or not they keep any logs of the DNS traffic
  • whether or not they support DNSSEC
I have personally selected a resolver located in Iceland by setting the following in /etc/default/dnscrypt-proxy:
DNSCRYPT_PROXY_RESOLVER_NAME=ns0.dnscrypt.is

DNSSEC While DNSCrypt protects the confidentiality of our DNS queries, it doesn't give us any assurance that the results of such queries are the right ones. In order to authenticate results in that way and prevent DNS poisoning, a hierarchical cryptographic system was created: DNSSEC. In order to enable it, I have setup a local unbound DNSSEC resolver on my machine and pointed /etc/resolv.conf (or /etc/dhcp/dhclient.conf) to my unbound installation at 127.0.0.1. Then I put the following in /etc/unbound/unbound.conf.d/dnscrypt.conf:
server:
    # Remove localhost from the donotquery list
    do-not-query-localhost: no
forward-zone:
    name: "."
    forward-addr: 127.0.2.1@53
to stop unbound from resolving DNS directly and to instead go through the encrypted DNSCrypt proxy.

Reliability In my experience, unbound and dnscrypt-proxy are fairly reliable but they eventually get confused (presumably) by network changes and start returning errors. The ugly but dependable work-around I have found is to create a cronjob at /etc/cron.d/restart-dns.conf that restarts both services once a day:
0 3 * * *    root    /usr/sbin/service dnscrypt-proxy restart
1 3 * * *    root    /usr/sbin/service unbound restart

Captive portals The one remaining problem I need to solve has to do with captive portals. This can be quite annoying when travelling because it requires me to use the portal's DNS resolver in order to connect to the splash screen that unlocks the wifi connection. The dnssec-trigger package looked promising but when I tried it on my jessie laptop, it wasn't particularly reliable. My temporary work-around is to comment out this line in /etc/dhcp/dhclient.conf whenever I need to connect to such annoying wifi networks:
#supersede domain-name-servers 127.0.0.1;
If you've found a better solution to this problem, please leave a comment!

25 April 2016

Antoine Beaupr : My free software activities, April 2016

Debian Long Term Support (LTS) This is my 5th month working on Debian LTS, started by Raphael Hertzog at Freexian. This is my largest month so far, in which I worked on completing the Xen and NSS packages updates from last month, but also spent a significant amount of time working on phpMyAdmin and libidn.

Updates to NSS and Xen completed This basically consisted on following up on the reviews from other security people. I basically continued building up on Brian's work and tested the package on a test server at Koumbit, which seems to have survived well the upgrade. The details are in this post to the debian-lts mailing list. As for NSS, the package was mostly complete, but I forgot to ship the tests for some reason, so I added them back. I also wrote the release team to see if it was possible to update NSS to the same version in all suites. Unfortunately, this issue is still pending, but I still hope we can find better ways of managing that package in the long term.

IDN and phpMyAdmin Most of my time this month was spent working on IDN and phpMyAdmin. Unfortunately, it turns out that someone else had worked on the libidn package. This is partly my fault: I forgot to check in the dsa-needed.txt file for assignment before working on the package. But considering how in flux the workflow currently is with the switch between the main security team and the LTS team for the wheezy maintenance, I don't feel too bad. Still, I prepared a package which was a bit more painful than it should have been because of GNUlib. I didn't even know about GNUlib before, oddly enough, and after that experience, I feel that it should just not exist at all anymore. I have filed a bug to remove that dependency at the very least, but I do not clearly see how such a tool is necessary on Debian at this point in time. But phpMyAdmin, no one had worked on that. And I understand why: even though it's a very popular package, there were quite a few outstanding issues (8!) in Wheezy, with 10-15 patches to be ported. Plus, it's ... well, PHP. And old PHP at that, with parts of it with modern autoloader classes, and other with mixed HTML and PHP content, require (and not require_once) and all sorts of nasty things you still find in the PHP universe. I nevertheless managed to produce a new Debian package for wheezy and test it on Koumbit's test servers. Hopefully, that can land into Wheezy soon.

Long term software support I am a little worried that we are, both in Jessie and Wheezy sitting in between stable releases for phpMyAdmin, something that is a recurring issue for a lot of packages in Debian stable or LTS. Sometimes, it just happens that the version that happens to be in Debian testing when it is released as stable is just not a supported release upstream. It's the case for phpMyAdmin in Jessie (4.3, whereas 4.0 and 4.4 are supported) and Wheezy (3.4, although it's unclear how long that was supported upstream). But even if the next Debian stable (Stretch), would pick a stable release upstream, there is actually no phpMyAdmin release that has a support window as long as Debian stable (roughly 3 years), let alone as long as Debian LTS (5 years). This is a similar problem with NSS: upstream is simply not supporting their product in the long term, or at least not in the terms we are used to in the Debian community (ie. only security fixes or regressions). This is, in my opinion, a real concern for the reliability and sustainability of the computing infrastructure we are creating. While some developers are of the opinion that software older than 18 months is too old, here we are shipping hardware and software in space or we have Solaris, which is supported for 16 years! Now that is a serious commitment and something we can rely on. 18 months is really, really, a tiny short time in the history of our civilization. I know computer programmers and engineers like to think of themselves in elitist terms, that they are changing the world every other year. But the truth is that things have not changed much in the last 4 decades where computing has existed, both in terms of security or functionality. Two quotes from my little quotes collection come to mind here:
Software gets slower faster than hardware gets faster. - Wirth's law The future is already here it's just not very evenly distributed. - William Gibson
Because of course, the response to my claims that computing is not really advancing is "but look! we have supercomputers in our pockets now!" Yes, of course, we do have those fancy phones and they are super-connected, but they are a threat to our fundamental rights and freedom. And those glittering advances always pale in comparison to what could be done if we wouldn't be wasting our time rewriting the same software over and over again on different, often proprietary, platforms, simply because of the megalomaniac fantasies of egoistic programmers. It would be great to build something that lasts, for a while. Software that does not need to be updated every 16 months. You'd think that something as basic as a screensaver release could survive what is basically the range of human infancy. Yet it seems we like to run mindlessly in the minefield of software development, one generation following the other without questioning the underlying assumption of infinite growth that permeates our dying civilization. I have talked about this before of course, but working with the LTS project just unnerves me so bad that I just needed to let out another rant. (For the record, I really have a lot of respect for JWZ and all the work he has done in the free software world. I frequently refer to his "no-bullshit" backup guide and use Xscreensaver daily. But I do think he was wrong in this case: asking Debian to remove Xscreensaver is just too much. The response from the maintainer was exemplary of how to handle such issues in the future. I restarted Xscreensaver after the stable update, and the message is gone, and things are still all fine. Thanks JWZ and Tormod for keeping things rolling.)

Other free software work With that in mind, I obviously didn't stop doing other computing work this month. In fact, I did a lot of work to try to generally fix the internet, that endless and not-quite-gratifying hobby so many of us are destroying our bodies to accomplish.

Build tools I have experimented a bit more with different build tools. I got worried because at some point cowbuilder got orphaned and I figured I could refresh the way I build packages for LTS. I looked into sbuild, but that ended up not bringing much improvements over my current cowbuilder setup (which I really need to document better). I was asked by the new maintainer to open a bug report to make such setups easier by guessing the basepath better, so we'll see how that goes. I did enjoy the simplicity of gitpkg and discovered cowpoke which made it about 2 times faster to build packages because I could use another server to build larger packages. I also found that gitpkg doesn't use -n by default when calling gzip, which makes it harder to reproduce tarballs when they are themselves built reproducibly, which is the case for Github tarballs (really nice of them). So I filed bug #820842 about that. It would be pretty awesome if such buildds would be available for Debian Developers to do their daily tasks. It could simply be a machine that would spin up a chroot with cowbuilder or it could even be a full, temporary VM although that would take way more resources than a simple VM with a cowbuilder setup. In the meantime, I should probably look at whalebuilder as an alternative to cowbuilder. It is a tool that supports building packages within a Docker chroot, which means that packages are built from a clean environment like pbuilder, and using COW optimisations but also without privileges or network access, which is a huge plus especially when you build untrusted packages.

Ikiwiki admonitions I have done some work to implement Moinmoin-like admonitions in Ikiwiki, something I am quite happy about since it's something I was really missing about Moinmoin. Admonitions bring a really nice way to outline certain blocks with varying severity levels and distinct styles. For example:
Admonitions are great!
This was done with a macro, but basically, since Markdown allows more or less arbitrary HTML, this can also be done with the <div> tag. I like that we don't have a new weird markup here. Yet, I still liked the sub-parser feature of MoinMoin, something that can be implemented in Ikiwiki, but it's a little more clunky. Normally, you'd probably do this with the inline macro and subpages, but it's certainly less intuitive that directly inlined content.

Ereader I got a new e-reader! I was hesitant between the Kobo Aura H20 and the Kobo Glo HD, which were the ones available at Bestbuy. So I bought both and figured I would return the other. That was a painful decision! In the end, both machines are pretty nice:
  • Aura H2O
    • Pros:
      • waterproof
      • larger screen (makes it easier to see web pages and better for the eyes)
      • naturally drawn to it
    • Cons:
      • heavier
      • larger (fits in outside pocket though)
      • port cover finicky
      • more expensive (180$) - prices may go down in future
  • Aura Glo HD
    • Pros
      • smaller (fits in inside pocket of both coats)
      • better resolution in theory (can't notice in practice)
      • cheaper (100$)
      • may be less common on the future (larger models more common? just a guess)
    • Cons
      • no SD card
      • smaller screen
      • power button in the middle
... but in the end, I ended up settling down on the Glo, mostly for the price. Heck, I saved around 100$, so for that amount, I could have gotten two machines so that if one breaks I would still have the other. I have ordered a cover for it on Deal Extreme about two weeks ago, and it still hasn't arrived. I suspect it's going to take a few more months to get there, by which point I may have changed e-reader again. Note that both e-readers needed an update to calibre, so I started working on a calibre backport (#818309) which I will complete soon. So anyways, I looked into better ways of transferring articles from the web to the e-reader, something which I do quite a bit to avoid spending too much time on the computer. Since the bookmark manager I use (Bookie) is pretty much dead, I started looking at other alternatives. And partly inspired by Framasoft's choice of Wallabag for their bookmarking service (Framabag), I started to look into that software, especially since my friend who currently runs the Bookie instance is thinking of switching to Wallabag as well. It seems the simplest way to browse articles remotely through a standard protocol is by implementing OPDS support in Wallabag. OPDS is a standard developed in part by the Internet Archive and it allows for browsing book collections and downloading them. Articles and bookmarks would then be presented as individual books that would be accessible from any OPDS-compatible device. Unfortunately, the Kobo e-readers don't support OPDS out of the box: you need to setup some OPDS-compatible reader like Koreader. And that I found nearly impossible to do: I was able to setup KSM (the "start menu", not to be confused with that KSM), but not Koreader in KSM. Besides, I do not want a separate OS running here on the tablet: I just want to start Koreader every once in a while. KSM just starts another system when you reboot the e-reader, something which is not really convenient on the Kobo. Basically, I just want to add Koreader as a tile in the home screen on the e-reader. I found the documentation on that topic to be sparse and hard to follow. It is often dispersed across multiple forum threads and involves uploading random binaries, often proprietary, to the e-reader. It had been a long time since I was asked to "register my software" frenetically, and I hadn't missed that one bit. So I decided to stay away from this until that solution and its documentation matures a bit.

Streaming re-established I have worked a bit on my home radio stream. I simply turned the Liquidsoap stream back online, and did a few tweaks to the documentation that I had built back then. All that experimenting led me to do two NMUs. One was for gmpc-plugins to fix a FTBFS (bug #807735) and to properly kill the shout streamer when completing the playback (bug #820908). The other was to fix the ezstream manpage (bug #573928), a patch that had been sitting there for 5 years! This was to try to find an easy way to stream random audio (say from a microphone) to the Icecast server, something which is surprisingly difficult, consider how basic that functionality is. I was surprised to see that Darkice just completely fails to start (bug #821040) and I had to fallback to the simplest ices2 software to stream the audio. I am still having issues with Liquidsoap: it's really unstable! As a server, I would expect it to keep running for days if not years. Unfortunately, there's always something that makes it crash. I had assertion failed (bug #821112) and I keep seeing it crash after 2-3 days fairly reliably, a bug I reported 3 years ago and that is still not fixed (bug #727307). Switching back the stream to Vorbis (because I was having problems with the commandline mp3 players and ogg123 is much more lightweight) created another set of problems too, this time with the phone. It seems that Android cannot stream Vorbis at all, something that is even worse in Cyanogenmod... I also had to tweak my MPD config to make the Android client be able to load the larger playlists (see dmix buffer is full).

Android apps So I have also done quite a bit of work again on my phone. I finally was told how to access from Termux from adb shell which is pretty cool because now I can start a screen on my phone and then, when I'm tired of tapping to type, I can just reconnect to it when I plug in a USB cable on my laptop. I sent a pull request to fix the documentation regarding that. I also tried to see how my SMS and Signal situation could be improved. Right now, I have two different apps to do SMS on my phone: I use both Signal and the VoIP.ms SMS client, because I do not have a contract or SIM card in my phone. Both work well independently, but it's somewhat annoying to have to switch between the two. (In fact, I feel that Signal itself has an issue with how it depends on the network to send encrypted messages: I often have to "ping" people in clear text (and therefore in the other app) so that they connect to their data plan to fetch my "secure" signal messages...) Anyways, I figured it would be nice if at least there would be a SMS fallback in Signal that would allow me to send regular text messages from signal through Voip.MS. That was dismissed really fast. Moxie even closed the conversation completely, something I had never experienced before, and doesn't feel exactly pleasant. The Voip.MS side was of course not impressed and basically shrugged it off because Signal was not receptive. I also tried to clear up the Libresignal confusion: there are 3 different projects named "Libresignal", and I am not sure I figured out the right thing, even though the issue is now closed and there's a FAQ that is supposed to make all that clear. Nevertheless, I opened two distinct feature requests to try to steer the conversation into a more productive direction: GCM-less calls and GCM support. But I'm not sure neither will go anywhere. In the meantime, I am using the official signal client, which I downloaded using gplaycli and which I keep up to date with Aptoide. Even though the reliability of that site is definitely questionable, it seems that once you have a trusted version, it is safe to upgrade, regardless of the source because there is a trust path between you and the developer. I also filed a few issues with varying levels of success/response from the community:

Random background radiation And then there's of course the monthly background noise of all the projects I happened to not only stumble on, but also file bugs or patches against:

Gunnar Wolf: Passover / Pesaj, a secular viewpoint, a different viewpoint... And slowly becoming history!

As many of you know (where "you" is "people reading this who actually know who I am), I come from a secular Jewish family. Although we have some religious (even very religious) relatives, neither my parents nor my grandparents were religious ever. Not that spirituality wasn't important to them My grandparents both went deep into understanding by and for themselves the different spiritual issues that came to their mind, and that's one of the traits I most remember about them while I was growing up. But formal, organized religion was never much welcome in the family; again, each of us had their own ways to concile our needs and fears with what we thought, read and understood. This week is the Jewish celebration of Passover, or Pesaj as we call it (for which Passover is a direct translation, as Pesaj refers to the act of the angel of death passing over the houses of the sons of Israel during the tenth plague in Egypt; in Spanish, the name would be Pascua, which rather refers to the ritual sacrifice of a lamb that was done in the days of the great temple)... Anyway, I like giving context to what I write, but it always takes me off the main topic I want to share. Back to my family. I am a third-generation member of the Hashomer Hatzair zionist socialist youth movement; my grandmother was among the early Hashomer Hatzair members in Poland in the 1920s, both my parents were active in the Mexico ken in the 1950s-1960s (in fact, they met and first interacted there), and I was a member from 1984 until 1996. It was also thanks to Hashomer that my wife and I met, and if my children get to have any kind of Jewish contact in their lifes, I hope it will be through Hashomer as well. Hashomer is a secular, nationalist movement. A youth movement with over a century of history might seem like a contradiction. Over the years, of course, it has changed many details, but as far as I know, the essence is still there, and I hope it will continue to be so for good: Helping shape integral people, with identification with Judaism as a nation and not as a religion; keeping our cultural traits, but interpreting them liberally, and aligned with a view towards the common good Socialism, no matter how the concept seems pass nowadays. Colectivism. Inclusion. Peaceful coexistence with our neighbours. Acceptance of the different. I could write pages on how I learnt about each of them during my years in Hashomer, how such concepts striked me as completely different as what the broader Jewish community I grew up in understood and related to them... But again, I am steering off the topic I want to pursue. Every year, we used to have a third Seder (that is, a third Passover ceremony) at Hashomer. A third one, because as tradition mandates two ceremonies to be held outside Israel, and a movement comprised of people aged between 7 and 21, having a seder competing with the familiar one would not be too successful, we held a celebration on a following day. But it would never be the same as the "formal" Pesaj: For the Seder, the Jewish tradition mandates following the Hagada The Seder always follows a predetermined order (literally, Seder means order), and the Hagad (which means both legend and a story that is spoken; you can find full Hagadot online if you want to see what rites are followed; I found a seemingly well done, modern, Hebrew and English version, a more traditional one, in Hebrew and Spanish, and Wikipedia has a description including its parts and rites) is, quite understandably, full with religious words, praises for God, and... Well, many things that are not in line with Hashomer's values. How could we be a secular movement and have a big celebration full with praises for God? How could we yearn for life in the kibbutz distance from the true agricultural meaning of the celebration? The members of Hashomer Hatzair repeatedly took on the task (or, as many would see it, the heresy) of adapting the Hagada to follow their worldview, updated it for the twentieth century, had it more palatable for our peculiarities. Yesterday, when we had our Seder, I saw my father still has together with the other, more traditional Hagadot we use two copies of the Hagad he used at Hashomer Hatzair's third Seder. And they are not only beautiful works showing what they, as very young activists thought and made solemn, but over time, they are becoming historic items by themselves (one when my parents were still young janijim, in 1956, and one when they were starting to have responsabilities and were non-formal teachers or path-showers, madrijim, in 1959). He also had a copy of the Hagad we used in the 1980s when I was at Hashomer; this last one was (sadly?) not done by us as members of Hashomer, but prepared by a larger group between Hashomer Hatzair and the Mexican friends of Israeli's associated left wing party, Mapam. This last one, I don't know which year it was prepared and published on, but I remember following it in our ceremony. So, I asked him to borrow me the three little books, almost leaflets, and scanned them to be put online. Of course, there is no formal licensing information in them, much less explicit authorship information, but they are meant to be shared So I took the liberty of uploading them to the Internet Archive, tagging them as CC-0 licensed. And if you are interested in them, flowing over and back between Spanish and Hebrew, with many beautiful texts adapted for them from various sources, illustrated by our own with the usual heroic, socialist-inspired style, and lovingly hand-reproduced using the adequate technology for their day... Here they are: I really enjoyed the time I took scanning and forming them, reading some passages, imagining ourselves and my parents as youngsters, remembering the beautiful work we did at such a great organization. I hope this brings this joy to others like it did to me. , . Once shomer, always shomer.
24 April 2016

Bits from Debian: Debian welcomes its 2016 summer interns

GSoC 2016 logo Outreachy logo We're excited to announce that Debian has selected 29 interns to work with us this summer: 4 in Outreachy, and 25 in the Google Summer of Code. Here is the list of projects and the interns who will work on them: Android SDK tools in Debian: APT - dpkg communications rework: Continuous Integration for Debian-Med packages: Extending the Debian Developer Horizon: Improving and extending AppRecommender: Improving the debsources frontend: Improving voice, video and chat communication with Free Software: MIPS and MIPSEL ports improvements: Reproducible Builds for Debian and Free Software: Support for KLEE in Debile: The Google Summer of Code and Outreachy programs are possible in Debian thanks to the effort of Debian developers and contributors that dedicate part of their free time to mentor students and outreach tasks. Join us and help extend Debian! You can follow the students weekly reports on the debian-outreach mailing-list, chat with us on our IRC channel or on each project's team mailing lists. Congratulations to all of them!

Dominique Dumont: Automount usb devices with systemd

Hello Ever since udisk-glue was obsoleted with udisk (the first generation), I ve been struggling to find a solution to automatically mount a usb drive when such a device is connected to a kodi based home cinema PC. I wanted to avoid writing dedicated scripts or udev rules. Systemd is quite powerful and I thought that a simple solution should be possible using systemd configuration. Actually, auto-mount notion covers 2 scenario :
  1. A device is mounted after being plugged in
  2. An already available device is mounted when a process accesses its mount point
The first case is the one that is needed with Kodi. The second may be usefull so is also documented in this post. For the first case, add a line like the following in /etc/fstab:
/dev/sr0 /mnt/br auto defaults,noatime,auto,nofail 0 2
and reload systemd configuration:
sudo systemctl daemon-reload
The important parameters are auto and nofail : with auto , systemd mounts the filesystem as soon as the device is available. This behavior is different from sysvinit where auto is taken into account only when mount -a is run by init scripts. nofail ensures that boot does not fail when the device is not available. The second case is handled by a line like the following one (even if the line is split here to improve readability):
/dev/sr0 /mnt/br auto defaults,x-systemd.automount,\
   x-systemd.device-timeout=5,noatime,noauto 0 2
With the line above in /etc/fstab, the file system is mounted when user does (for instance) ls /mnt/br (actually, the first ls fails and triggers the mount. A second ls gives the expected result. There s probably a way to improve this behavior, but I ve not found it ) x-systemd.* parameters are documented in systemd.mount(5). Last but not least, using a plain device file (like /dev/sr0) works fine to automount optical devices. But it is difficult to predict the name of a device file created for a usb drive, so a LABEL or a UUID should be used in /etc/fstab instead of a plain device file. I.e. something like:
LABEL=my_usb_drive /mnt/my-drive auto defaults,auto,nofail 0 2
All the best
Tagged: kodi, systemd

Norbert Preining: Armenia and Turkey Erdo an did it again

It is 101 years to the day that Turkey started the first genocide of the 20th century, the Armenian Genocide. And Recep Tayyip Erdo an, the populistic and seemingly maniac president of Turkey, does not drop any chance to continue the shame of Turkey. armenien-genocide After having sued a German comedian of making fun of him followed promptly by an as shameful cowtow of Merkel by allowing the jurisdiction to start prosecuting Jan B hmermann, heis continuing suing other journalists, and above all putting pressure on the European Community to not support a concert tour of the Dresdner Sinfoniker in memoriam of the genocide. European Values have disappeared, and politicians pay stupid tribute to a dictator-like Erdo an who is destroying free speech and free media, not only in his country but all around the world. Must be a good friend of Abe, both are installing anti-freedom laws. Shame on Europe for this. And Turkey, either vote Erdo an out of office, or you should not (and hopefully will never) be allowed into the EC, because you don t belong there.

Next.

Previous.