Search Results: "cas"

7 May 2013

Gunnar Wolf: Talking about Debian while Debian was getting released

Last Saturday, I was invited to talk about Debian to Hackerspace DF, a group that is starting to work at a very nice place together with other collectives, in a quite centric place (Colonia Obrera). I know several of the people in the group (visited them a couple of times in the space's previous incarnation), and wish them great luck in this new hackerspace! Anyway I was invited to give an informal talk about Debian. And of course, I was there. And so was Alfredo, who recorded (most of) it. So, in case you want to see me talking about how Debian works, mostly on a social organization level (but also regarding some technical details). Of course, given the talk was completely informal (it started by me standing there, asking, "OK, any questions?"), I managed to mix up some names and stuff... But I hope that, in the end, the participants understood better what Debian means than when we started. Oh, and by the end of the talk, we were all much happier. Not only because I was about to shut up, but because during my talk, we got notice that Debian 7.0 "Wheezy" was released. Anyway If you want to see me talking for ~1hr, you can download the video or watch it on YouTube.

6 May 2013

Sylvestre Ledru: Follow up on Debian & Clang

A week after the Euro LLVM conference, I am glad to share the results I presented and discussed during the event. 1) Parallel building infrastructure using clang instead of gcc Based on the work that Alexander Pashaliyski and I did during the GSoC 2012, we are now able to automatically rebuild each package uploaded in Unstable transparently. Results are published here:
http://buildd-clang.debian.net/
This provides a quick and easy way to any Debian contributors or upstream packaged in Debian to check how the package behaves with clang.
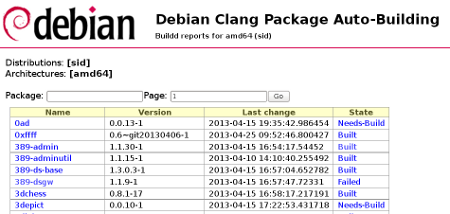
For Debian Developer and maintainer, a per maintainer view is also provided. This will list all packages maintained by a Debian packager. My page as example Here is an example of the list of package:
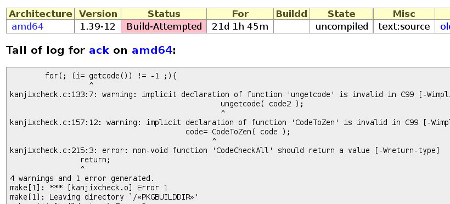
And an example of package failing:
At time of writing, most of the packages in unstable have been rebuilt (16 % are remaining). However, due to resource constraints, only amd64 packages are built. Contact me if you have resources to share for other architectures. Thanks to Paul Wise, the PTS (Debian package tracking system) proposes a link to the clang build logs (failing or not). A repository will be automatically updated with the results of these builds (once I find the time to get into buildd). 2) clang-built repository
Thanks to the Amazon Cloud, with our new DPL (Debian Project Leader), Lucas Nussbaum, we rebuilt unstable last April and published it at the following address:
deb http://clang.debian.net/repository-2013-04-07/ unstable-clang main
This allows some cool stuff like:
$ echo "deb http://clang.debian.net/repository-2013-04-07/ unstable-clang main">>/etc/apt/sources.list
$ apt-get update
$ apt-get install coreutils/unstable-clang
$ ls
$ awk
Note that this repository was only one-shoot and does not get updated. Quality of the binary produced (performance and size) can be tested thanks to this repository. Feedbacks are welcome!

4 May 2013

Russ Allbery: Review: Democracy at Work

Review: Democracy at Work, by Richard Wolff
Publisher: Haymarket
Copyright: 2012
ISBN: 1-60846-247-1
Format: Kindle
Pages: 220
I've been reading (mostly on-line) and thinking quite a bit lately about workplace governance models, economic structure, and why the current organization of the US workplace bothers me so intensely, partly triggered by reading John Kenneth Galbraith's The Affluent Society. The economic monoculture has made that process particularly frustrating. It's rare to find a discussion, even in the context of organizational strategies that are considered radical, that avoids the standard frame of productivity and business value. Most discussion is long on tactics and short on strategy and examination of goals. Wolff's appearance on Moyers & Company was a rare breath of fresh air, enough so that I grabbed his book shortly afterwards. Wolff is a Marxian economist (meaning that he makes use of Marxist analysis of economics and capitalism while separating them from Marxist politics and Marx's advocacy of revolutionary socialism), which for me was part of the interest. Marxist thought of any branch is not common in the United States; we're regularly deprived of several sides in the international conversation on economic models. I was taught Marxist theory in elementary and high school (in retrospect, surprisingly even-handedly and well, despite the biases of my schooling), but none of the later developments of Marxist thought. I think that's a typical experience here; in the United States, Marxism culminated in Mao and Stalin, and no further development of the underlying theories is ever mentioned. Democracy at Work is subtitled A Cure for Capitalism and does indeed advocate a concrete alternative to capitalist business structures. But this is only the last third of the book (and in some ways the least useful, as I'll discuss in a moment). The first two-thirds of the book is basically a remedial education in modern, as opposed to historic, Marxian economics for US readers like myself who have never heard it before, cast in the context of the current financial crisis. This may well be old hat for Europeans, but if you've been wondering what (at least some) modern-day Marxists actually believe, or are saying to yourself "there are modern-day Marxists after the collapse of the Soviet Union?", I recommend this book to your attention. It's an excellent summary, which I read with the delightful feeling of an expanding viewpoint and the discovery of new directions from which to look at a problem. There's quite a bit in this section that's worth thinking about, including another take on the nature of the recent economic collapse and how that fits into a Marxian analysis of capitalist crises. But there was one point in Wolff's explanation that I found particularly helpful. He completely restructured my understanding of the Marxian analysis of worker exploitation and profit allocation. There are two angles of Marxist economic thought and socialist economics that get a great deal of attention, at least in the United States, in history and economics classes: the role (or lack thereof) of markets in price setting, and the ownership of the means of production. Defenders of capitalism like to focus on the former, since it's quite easy to identify the advantages of theoretical free markets in finding ideal prices and balancing supply and demand, whereas central planning of prices and production has resulted in some catastrophic and deadly failures. (Although I will note, with passing interest, that those failures predate large-scale computing, and there are now large corporations that manage budgets larger than some countries via centralized command-and-control economic practices.) Defenders of socialism are more likely to focus on the ownership of the means of production, since it's easy to show prima facie unfairness in owners of capital extracting vast profits without having to do any work themselves, only be lucky enough to start with large quantities of money. Wolff, however, argues that both of these focuses misses a core critique by Marx of the workplace structure in capitalism, and that, by ignoring that critique, supposedly Marxist countries did not create anything that was actually Marxist in implementation. The Soviet Union was just as much a capitalist country as the United States is. It was state capitalism rather than private capitalism, but the core capitalist structure was intact. Wolff arrives at this conclusion, which may be well-trodden ground in parts of the world that include active Marxist thought but which was quite startling to this American, by treating the ownership of capital as a partial distraction. He focuses on a more direct question and practical question: who determines what a worker does on a day-to-day basis and how that product is used? Who determines what profits are collected and how they are spent? In private capitalism, this is done by the owners of the capital: large shareholders, major investors, and the managerial class that they hire. In Soviet state capitalism, this is done by national politicians, bureaucrats, and the managerial class that they hire. In neither model is it done by the workers themselves. The Soviet model gives theoretical ownership of the capital to the workers, but that ownership is diffused, centralized, and politicized, redirected through the mechanisms of the state, and therefore is effectively ignored. Ownership and control is entirely captured by the political class. Both of these systems are capitalist in Wolff's view of Marx: there is a class of owners and managers, who control the terms and nature of work and who allocate the profits, and a class of workers, who have to do what they're told, are not paid full value for their labor, and don't have a say in how the profits their work generates are spent. At the most important level of day-to-day autonomy and empowerment, they are functionally identical. They are both equally hierarchical and exploitative; the only difference is in whether the system is controlled by rich individuals or by well-connected politicians. (And, as any study of modern politics quickly reveals, the distinction between those two groups in most countries is murky at best.) Wolff convincingly recasts modern economic history as a constant pendulum swing between private capitalism and state capitalism. Crises in one system push countries towards the other system; subsequent crises push the country back towards the first system. Regulation grows and shrinks, companies are nationalized and then privatized, but both systems are united in excluding the worker from any meaningful control over their work life. The first two-thirds of the book was full of insights like this for me. I didn't agree with all of it, but all of it was worthwhile and thought-provoking. But I was a bit leery of Wolff's proposed solution. My past experience with critics of capitalism is that the critique is often quite compelling, but the proposed solution is much less believable. And, sadly, that concern was warranted here as well. The core of Wolff's proposal is predictable but possibly sound: a restructuring of the workplace to be radically democratic. The business would be owned entirely and exclusively by the people who work for it, equally regardless of the job of the worker, and the workers would decide democratically or via elected repesentatives from among the workers how to allocate the profits of the business, what standards and business practices should be followed, and how the work is to be done. I was particularly interested to hear that this model (workers' self-directed enterprises) has apparently been successful in Spain in the form of the Mondragon Cooperative. Given all the tricky, small details that have to be resolved in an actual workplace, an existence proof is worth more than pounds of theory. Unfortunately, like a lot of proposed alternatives, Wolff's description of WSDEs is quite fuzzy and involves a lot of hand-waving. I was never able to build, from this book, a coherent and complete mental model of how such a workplace would function. Wolff tends to surround every specific in a halo of contingencies, possibilities, and alternative models, and is maddeningly nonspecific on such practical matters as how line management would work, how such a business would do financial planning or project approval, how competing interests in different parts of the organization would be balanced, and other practical governance matters that fill my work life. Maybe the answer to all of that is just "democracy," but I'm dubious. Democracy has a number of well-known flaws that I thought weren't adequately addressed. For example, democracies are often quite happy to further and reinforce existing prejudice (such as sexism or racism), and are prone to yielding control to the most charismatic. Democracies also have an informed voter problem, which seems like it would be particularly acute if democracy is going to make detailed business decisions. And, for larger organizations, control by pre-existing money could re-enter the equation via propaganda and campaigning around votes. Some of this gap in the book could be addressed via a more in-depth look at how Mondragon and any other real-life examples work, but that is sadly missing here. (I am interested enough now, though, that I'd read a good popular treatment of the history and methodology of Mondragon, although I don't think I'm up to working through an academic study.) The hierarchical, dictatorial management structure imposed by capitalism is so awful that WSDEs don't have a particularly high bar to meet to be fairer and more empowering than what we have today. The question, rather, is would they function sufficiently well that the business would be able to make effective decisions, and that's unclear to me from this book. This is, as Wolff spends some time discussing, particularly difficult when in direct competition with capitalist enterprises. This sort of endeavor will probably trade some degree of economic efficiency and raw marketplace power for improvements to fairness and empowerment, but that means it's going to require support from the surrounding society, which is a huge obstacle. I doubt there's a free lunch here: true fairness and equity also leading to improved economic efficiency in a capitalist context is a nice dream, but not horribly practical. Wolff also seems to suffer from something else I associate with Marxist thought: a preferential focus on a very narrowly-defined type of productive worker, apparently left over from Marx's original critique in the context of industrialization. Wolff inserts a very odd and quite awkward distinction in his WSDE model between workers who directly produce the product that's sold, and who in his model therefore produce the profits of the business, and all other workers in the business. He then gives special privileges to the former group to decide how much profit to return in worker compensation and how much to use for other purposes, thus making the supporting workers second-class citizens within this supposedly equal workplace. Speaking as someone who works in IT, and hence would be classified by Wolff into the supporting rather than directly productive category, I do not find this division at all convincing, and Wolff never provides a coherent explanation for why he introduced it. He only says that it's necessary for the governance of the business to not be exploitative, which seems to assume that there is a special economic role played by the workers who work directly on a saleable product. Maybe there is some analysis that could convince me of this, but, if so, it's not present in this book. It struck me as a recipe for continuing the exploitation of the most invisible and powerless workers in capitalism: janitors, groundskeepers, and other low-paid service jobs. I wish the whole book were as insightful and pointed as the first two-thirds, but alas I found the WSDE discussion to be somewhat muddled and utopian. "How do we get there from here" is always the hardest part of this type of discussion, and Wolff has no special skill in that department. But, despite that, I got a lot of fascinating ideas and new conceptual frameworks out of this book, and I'm tempted to read it again. I suspect some of this, similar to my discovery of promises and infinite streams in programming, is filling in of odd gaps in my personal education rather than a discovery of unusual, new ideas. But if you too have gotten your political education within the US capitalism ber alles bubble, this book may fill in similar gaps in your knowledge. If so, it's a very rewarding experience. If you're curious about a preview of Wolff's perspective without paying for the book, I recommend watching the first episode of Moyers & Company in which he appeared. Wolff is a clear and engaging speaker, and his interview provides a good feel for his discussion style and his general perspective. Rating: 8 out of 10

3 May 2013

DebConf team: The DebConf13 matching fund completes, raising 2500 USD, twice (Posted by Didier Raboud)

The DebConf13 matching fund announced previously is now complete. The matching sponsor, Brandorr Group will match the collected amount of 2513 USD, resulting in 5026 USD of sponsoring money for DebConf13, for the benefit of all attendees. Despite raising only slightly more than half of the expected money, this first experience of raising funds through this matching fund mechanism can be considered successful.
DebConf is very important to the health of Debian, and Debian is very important to our team, so we re doing what we can to help. In this case we really wanted to see if we could provide an incentive for individual users of Debian to donate to the project. It seems like it worked well, and we d love to do something like this again in the future.
Brian Gupta, Brandorr Group
DebConf13 continues to welcome donations from individuals and is also seeking further sponsors. Registration opening Registration for DebConf13 will be opening shortly: stay tuned! We look forward to welcoming you to Vaumarcus!

2 May 2013

Axel Beckert: New web browsers in Wheezy

Since there is so much nice new stuff in Debian Wheezy, I have to split up my contributions to Mika s #newinwheezy game on Planet Debian. Here s the next bunch, this time web browsers:
Dillo Screenshot
dillo
The FLTK-based lightweight GUI web browser Dillo comes with its own rendering engine (no JavaScript, incomplete CSS support) was already in Debian before, but was removed before the release of Debian Squeeze, because Dillo 2 relied on FLTK 2.x which had an unclear license situation back then and never made it into Debian. In the meanwhile Dillo 3 relies on FLTK 1.3 as FLTK upstream abandoned the 2.0 branch and continued development on the 1.3 branch. So I brought Dillo back into Debian with its 3.0.x release.

Netsurf Screenshot
netsurf
The RiscOS-originating lightweight GUI web browser Netsurf was already in Debian, too, but didn t make it into Debian Squeeze as it needed the Lemon parser generator (part of the SQLite source) to build back then and a change in Lemon caused Netsurf to no more build properly in the wrong moment. Netsurf supports CSS 2.1, but has no JavaScript support either. I d consider its rendering engine more complete than Dillo s.

XXXTerm Screenshot
surf and xxxterm
Surf and XXXTerm are both simple and minimalistic webkit-based browsers. Surf is easy to embed in other applications and XXXTerm features vi-like keybindings for heavy keyboard users.
To be continued ;-)

Axel Beckert: New SSH-related stuff in Wheezy

Mika had the nice idea of doing a #newinwheezy game on Planet Debian, so let s join: There are (at least) two new SSH related tools new in Debian Wheezy:
mosh
is the mobile shell , an UDP based remote shell terminal which works better than SSH in case of lag, packet loss or other forms of bad connection. I wrote about mosh in more detail about a year ago. mosh is also available for Debian Squeeze via squeeze-backports.
sshuttle
is somewhere between port-forwarding and VPN. It allows forward arbitrary TCP connections over an SSH connection without the need to configure individual port forwardings. It does not need root access on the server-side either. I wrote about sshuttle in more detail about a year ago.
To be continued ;-)

Russ Allbery: Review: The System of the World

Review: The System of the World, by Neal Stephenson
Series: The Baroque Cycle #3
Publisher: William Morrow
Copyright: 2004
ISBN: 0-06-052387-5
Format: Hardcover
Pages: 892
This is the third book of the three-volume Baroque Cycle. I think you could, if you really wanted, read it without reading the previous volumes; Stephenson is certainly long-winded enough that you can pick up most of what's going on while you read. It's been a year since I read the second volume, and I only resorted to Wikipedia a couple of times to remember plot elements (and mostly from the first book). However, I wouldn't recommended starting here. Many of the character relationships, and most of the underpinning of the plot, is established in the previous volumes and given more significance by them. You would also miss The Confusion, which is the best book of the series, although none of this series rises to the level at which I'd recommend it except under specific circumstances. Quicksilver establishes the characters of Daniel Waterhouse, a fictional Puritan whose family was close to Cromwell and who became a friend to Isaac Newton in the days following the Restoration; Jack Shaftoe, a vagabond who wanders Europe in a sequence of improbable adventures; and Eliza, who becomes a friend to Leibniz and a spy for William of Orange. The Waterhouse sections are prominent in Quicksilver: full of the early history of the Royal Society, alchemy, and a small amount of politics. Of those three characters, Eliza is by far the most interesting, which meant that I was delighted when The Confusion dropped Waterhouse almost entirely and mixed Eliza's further story with more improbable but entertaining sea adventures of Jack Shaftoe. You will immediately sense my root problem with The System of the World when you hear that it is almost entirely about Daniel Waterhouse. While Eliza and Jack both appear, they play supporting roles at best, and Eliza's wonderful sharp intelligence and pragmatic survival skills are left out almost entirely. Instead, this is a novel about Waterhouse's return to England after spending quite a bit of time in the American colonies working on calculating machines. He is almost immediately entangled in dangerous politics from multiple directions: the precarious national politics in England near the end of the reign of Queen Anne, Isaac Newton's attempts to maintain the currency of England as Master of the Mint, and a bombing attempt that may have been aimed at him, may have been aimed at Newton, and may have been aimed at someone else entirely. Much of the book consists of an extended investigation of this bombing plot, skullduggery involving counterfeiters, and attempts to use the currency and the Mint as part of the political conflict between Whigs and Tories, mixed in with attempts to construct a very early computer (this is Stephenson, after all). Leibniz and Eliza come into this only as confidants of the Hanoverians. All this may sound exciting, and there are parts of it that hold the attention. But this book sprawls as badly as Quicksilver did. There's just too much detail without either enough plot or enough clarity. Stephenson tries to make you feel, smell, and hear the streets of London and the concerns of an idiosyncratic group of semi-nobles during one of the more interesting junctures of British history, but he does that by nearly drowning you in it, and without providing enough high-level guidance. For most of the book, I felt like I was being given a tour of a house on my hands and knees with a magnifying glass. It's a bad sign when the reader of a historical novel is regularly resorting to Wikipedia, not to follow interesting tangents of supporting material, but to try to get a basic sense of the players and the politics involved because the author never explains them clearly. If you're more familiar with the details of British history than I am, and can more easily follow the casual intermixing of two or three forms of address for the same historical figure, you may not have that problem. But I think other structural issues remain, and one of the largest is Waterhouse himself. Jack Shaftoe, and particularly Eliza, are more interesting characters because they're characters. They're not always particularly believable, but they attack the world with panache and are constantly squirming into the center of things. Stephenson's portrayals of Newton, Leibniz, the Duke of Marlborough, Sophia of Hanover, Peter the Great, and the other historical figures who show up here are interesting for different reasons: Stephenson has history to draw on and elaborate, and it's fascinating to meet those people from a different angle than dry lists of accomplishments. History has a way of providing random details that are too bizarre to make up; Isaac Newton, for example, actually did disguise himself to infiltrate London criminal society in pursuit of counterfeiters while he was Master of the Mint! Waterhouse, for me, has none of these advantages. He is an invented character in whom I have no pre-existing interest. He drifts through events largely through personal connections, all of which seem to be almost accidental. He's welcome in the councils of the Royal Society because he's apparently a scientist, but the amount of actual science we see him doing is quite limited. His nonconformist background allies him squarely with the Whigs, but his actual position on religious matters seems much less set than the others around him. What he seems to want, more than anything else, is to help Leibniz in the development of a computer and to reconcile Newton and Leibniz. And he's not particularly effective at either. In short, he has little in the way of memorable character or dynamism, despite being the primary viewpoint character, and seems to exist mostly to know everyone and be everywhere that's important to the story. He feels like an authorial insertion more than a character. It's quite easy to believe that Stephenson himself would have loved to be in exactly the role and situation that Waterhouse finds himself in throughout the book, in the middle of the councils of the wise and powerful, in just the right position to watch the events of history. I can sympathize, but it doesn't make for engrossing reading. Novels live and die by the strength of their characters, particularly their protagonists; I want more than just a neutral viewpoint. The third major structural problem that I had with this book is that I think Stephenson buries his lede. After finishing it, I think this is a book with a point, a central premise around which all the events of the story turn, and which is the philosophical culmination of The Baroque Cycle as a whole. But Stephenson seems oddly unwilling to state that premise outright until the very end of the book. For the first half, one could be forgiven in thinking this is a story about alchemy and the oddly heavy gold that's been a part of the story since The Confusion, or perhaps about foundational but forgotten work on computation that preceded Babbage by a century. But those all turn out to be side stories, sometimes even without a proper conclusion. I appreciate honoring the intelligence of the reader, and I presume that Stephenson would like to guide the reader through the same process of realization that the characters go through, but I think he takes this much too far and fails to make the realization clear. I'll therefore state what I believe is the premise outright, since I think it's a stronger book with this idea in mind: The System of the World is a continuation of the transformational economics shown in The Confusion into the realm of politics. Specifically, it's about the replacement of people with systems, about the journey towards Parliamentary supremacy, central banking, and the persistent state, and about the application of scientific principles of consistency and reproducibility to politics and economics (however fitfully and arbitrarily). Quicksilver was about the rise of science; The Confusion was, in retrospect, about the rise of economics; and The System of the World tries to be about the rise of technocratic modern politics, barely perceptible among the squabbles between Tories and Whigs. I think that's a fascinating premise, and I would have loved to read a book that tackles it head-on. That's a concept that is much more familiar from the late 19th and early 20th centuries in the context of Marxism, early socialism, technological utopianism, and similar attempted applications of scientific analysis to political and human behavior for the betterment of human civilization. Shifting that 200 years earlier and looking at a similar question from the perspective of the giants of the Enlightenment feels full of of potential. There are moments when I think Stephenson captures the sense of a seismic shift in how economies are run, knowledge is established, and civilizations are knit together. But, most of the time, it just isn't clear. There's so much other stuff in this book, and in the whole series: so many false starts, digressions, abandoned plots, discarded characters, and awkward attempts at romance (as much as I like the characters, Stephenson's portrayal of the relationship between Eliza and Jack is simply ridiculous and not particularly funny) that the whole weight of the edifice crushes what I think is the core concept. Stephenson is never going to be sparse. When you start a Stephenson novel, you know it's going to be full of chunks of partly digested encyclopedia and random research findings that may have nothing to do with the plot. But his best books (Snow Crash, The Diamond Age, even Cryptonomicon) have an underlying structure off of which all of those digressions are hung. You can see the bones beneath the flesh, and the creature they create is one you want to get to know. I'm not sure there are any bones here, and that may be the peril, for Stephenson, of writing historical fiction. I wonder if he felt that the structure of history would provide enough structure by itself that he could wrap a few plots around the outside of it and call it good. If so, it didn't work, at least for me. A lot of things happen. Some of them are even exciting and tense. A lot of people meet, interact, and show off their views of the world. A great deal of history, research, and sense of place is described in painstaking detail. But at the end of the book, I felt like I had to reach for some sort of point and try to retrofit it to the story. Lots happened, but there wasn't a novel. And that makes it quite hard to get enthused by the book. If you adored Quicksilver, I suspect you will also like this. I think they're the most similar. If, like I did, you thought The Confusion was a significant step up in enjoyment in the series and were hoping the trend will continue, I'm sad to report that it didn't. If you were considering whether to read the whole series and were waiting to see what I thought of the end, my advice is to give The Baroque Cycle a pass unless you absolutely love Stephenson's digressions, don't care if they're about history instead of current technology, and cannot live without 3,000 pages of them. It's not that they're bad books, but they're very long books, they take a significant investment of time and attention, and I think that, for most readers, there are other books that would repay a similar investment with more enjoyment. Rating: 5 out of 10

1 May 2013

Russ Allbery: WebAuth 4.5.1

Unfortunately, as always seems to happen with large releases, one of the features that we added in WebAuth 4.5.0 wasn't adequately tested and had some lingering issues. In this case, it was a last minute change: from a UI perspective, we decided it was better to present the user with a checkbox (checked by default) saying "remember my login on this computer" instead of a checkbox (off by default) saying "this is a public computer; don't remember me." People are much more familiar with the former than the latter. Unfortunately, due to how HTML checkboxes work, this required changing the default in the code, and that turned out to break single sign-on completely. We were assuming we should not maintain single sign-on credentials by default, so all the WebLogin interactions that never passed through the forms so that the form could establish a default would delete the cookies. This should be all sorted out in this release, along with a few other edge cases that became apparent when I thought harder about this. The documentation also makes clearer the required template changes when upgrading from versions prior to 4.5.0. We also snuck in one new feature: the user information service can pass a message to the user through to the confirmation page. You can get the latest release from the official WebAuth distribution site or from my WebAuth distribution pages.

Russ Allbery: Review: Questions for a Soldier

Review: Questions for a Soldier, by John Scalzi
Publisher: Subterranean
Copyright: 2005
Printing: 2012
ISBN: 1-59606-468-4
Format: Kindle
Pages: 28
Yet another short story from the Subterranean Scalzi Super Bundle collection, which is padding out my numbers this year since I don't seem to be writing as many reviews. Unlike some of the others, this one is fairly hard to come by if you didn't buy the original chapbook or the issue of Subterranean Magazine that included it. But don't worry, you're not really missing anything. Questions for a Soldier is really a short story, and slight even for that. It's a pendant to Old Man's War, a close-up of one stop in a good will tour that John Perry, the protagonist of that novel, does during it. In universe, it's basically a propaganda piece for the Colonial Defense Force that fleshes out some more of the background, mainly from the CDF side, of Scalzi's future universe. What Scalzi is doing here is mildly interesting: he's trying to capture the style of this sort of public affairs, feel-good speaking engagement but balance that against his portrayal of Perry as an honest straight shooter. Perry does a lot of the careful presentation of both sides that one would expect from someone who knows he's standing up to represent one side of an issue but doesn't want to make the propaganda too obvious. As a portrayal of a political speech of the subgenre "trying not to act like a politician," I think Scalzi successfully captures the tone. That's probably also why I found it vaguely annoying, since I think such speeches are a classic form of manipulation. Take someone (who may even honestly be a person of good will), put them up in front of a crowd, don't tell them what they have to say but make sure they're representing something that they're at least somewhat proud of, and let social pressure and expectations take care of the rest. The person will come across as honest and open (since they consider themselves to be), they don't actually know anything damaging, and they'll want to present their side in a good light. Humans are wonderful at rationalizations. The audience comes away feeling like the people they may be politically opposed to are human, and good people, and they can't be doing anything that upsetting since that fellow was a nice, upstanding person who told some great war stories and was clearly putting themselves in danger to protect the rest of us. It blunts political outrage and anger, justified or not, with a bit of "we're all on the same side and we're all good people" emotional camaraderie without any danger of any real revelations, uncomfortable information, or dangerous theories being expressed. Scalzi does a good job holding up a mirror here, and he also gives Perry the opportunity to make the solid (if quite predictable and dangerously incomplete) case for a professional military (and a completely cliched case for world, or galactic, peace). It all sounds quite believable because Perry obviously believes it. (That does not mean that Scalzi believes it; he's writing a character in a time, place, and role when the character believed those things.) But, at the end, it's a bit of political fluff that isn't really a story (no plot) and adds little to the larger series in which it was embedded. The later novels in the Old Man's War series raise the questions asked here in a much more forceful and direct way, in ways that produce at least a few answers. The general style is the sort of speech that you could find almost anywhere in US politics. If you have the collection anyway, it's mildly interesting to take apart what Scalzi is portraying here and think about it a bit, but it's completely missable. Rating: 5 out of 10

29 April 2013

Thomas Goirand: Jenkins: building debian packages after a git push (my 2cents of a howto)

The below is written in the hope it will be helpful for my fellow DDs. Why using build after push ? Simple answer: to save time, to always use a clean build environment, to automate more tests. Real answer: because you are lazy, and tired of always having to type these build commands, and that watching the IRC channel is more fun than watching the build process. Other less important answers: building takes some CPU time, and makes your computer run slower for other tasks. It is really nice that building doesn t consume CPU cycles on your workstation/laptop, and that a server does the work, not disturbing you while you are working. It is also super nice that it can maintain a Debian repository for you after a successful build, available for everyone to use and test, which would be harder to achieve on your work machine (which may be behind a router doing NAT, or even sometimes turned off, etc.). It s also kind of fun to have an IRC robot telling everyone when a build is successful, so that you don t have to tell them, they can see it and start testing your work. Install a SID box that can build with cowbuilder

Install Jenkins WARNING: Probably, before really installing, you should read what s bellow (eg: Securing Jenkins). Simply apt-get install jenkins from experimental (the SID version has some security issues, and has been removed from Wheezy, on a request of the maintainer). Normally, after installing jenkins, you can access it through:
http://<ip-of-your-server>:8080/
There is no auth by default, so anyone will be able to access your jenkins web GUI and start any script under the jenkins user (sic!). Jenkins auth
Before doing anything else, you have to enable Jenkins auth, otherwise, you have everything accessible from the outside, meaning that more or less, anyone browsing your jenkins server could be allowed to run any command. It might sound simple, but in fact, Jenkins auth is tricky to activate, and it is very easy to get yourself locked out, with no working web access. So here s the steps: 1. Click on Manage Jenkins then on Configure system 2. Check the enable security checkbox 3. Under security realm select Jenkins s own user database and leave allow users to sign up . Important: leave Anyone can do anything for the moment (otherwise, you will lock yourself out). 5. At the bottom of the screen, click on the SAVE button. 6. On the top right, click to login / create an account. Create yourself an account, and stay logged in. 7. Once logged-in, go back again in the Manage Jenkins -> Configure system , under security. 8. Switch to Project based matrix authentication strategy . Under User/group to add , enter the new login you ve just created, and click on Add . 9. Select absolutely all checkboxes for that user, so that you make yourself an administrator. 10. For the Anonymous user, for Job, check Read, Build and Workspace. For Overall select Read. 11. At the bottom of the screen, hit save again. Now, anonymous (eg: not logged-in) users should be able to see all projects, and be able to click on the build now button. Note that if you lock yourself out, the way to fix is to turn off Jenkins, edit config.xml, remove the useSecurity thing, and all what is in authorizationStragegy and securityRealm , then restart Jenkins. I had to do that multiple times until I had it right (as it isn t really obvious you got to leave Jenkins completely insecure when creating a new user). Securing Jenkins: Proxy Jenkins through apache to use it over SSL
When doing a quick $search-engine search, you will see lots of tutorials to use apache as a proxy, which seems to be the standard way to run Jenkins. Add the following to /etc/apache2/sites-available/default-ssl:
ProxyPass / http://localhost:8080/
ProxyPassReverse / http://localhost:8080/
ProxyRequests Off
Then perform the following commands on the shell:
htpasswd -c /etc/apache2/jenkins_htpasswd <your-jenkins-username>
a2enmod proxy
a2enmod proxy_http
a2enmod ssl
a2ensite default-ssl
a2dissite default
apache2ctl restart
Then disable access to the port 8080 of jenkins from outside:
iptables -I INPUT -d <ip-of-your-server> -p tcp --dport 8080 -j REJECT
Of course, this doesn t mean you shouldn t take the steps to activate Jenkins own authentication, which is disabled by default (sic!). Build a script to build packages in a cowbuilder I thought it was hard. In fact it was not. All together, this was kind of fun to hack. Yes hack. What I did yet another kind of 10km ugly shell script. The way to use it is simply: build-openstack-pkg <package-name>. On my build server, I have put that script in /usr/bin, so that it is accessible from the default path.Ugly, but it does the job! Jenkins build script for openstack At the end of the script, scan_repo() generates the necessary files for a Debian repository to work under /home/ftp. I use pure-ftpd to serve it. /home/ftp must be owned by jenkins:jenkins so that the build script can copy packages in it. This build script is by no mean state of the art, and in fact, it s quite hack-ish (so I m not particularly proud of it, but it does its job ). If I am showing it in this blog post, it is just to show an example of what can be done. It is left as an exercise to the reader to create another build script adapted to its own needs, and write something cleaner and more modular. Dependency building Let s say that you are using the Built-Using: field, and that package B needs to be built if package A changes. Well, Jenkins can be configured to do that. Simply edit the configuration of project B (you will find it, it s easy ). My use case: In my case, for building Glance, Heat, Keystone, Nova, Quantum, Cinder and Ceilometer, which are all components of Openstack, I have written a small (about 500 lines) library of shell functions, and an also small (90 lines) Makefile, which are packaged in openstack-pkg-tools (so Nova, Glance, etc. all build-depends on openstack-pkg-tools). The shell functions are included in each maintainer scripts (debian/*.config and debian/*.postinst mainly) to avoid having some pre-depends that would break debconf flow. The Makefile of openstack-pkg-tools is included in debian/rules of each packages. In such a case, trying to manage the build process by hand is boring and time consuming (spending your time watching the build process of package A, so that you can manually start the build of package B, then wait again ). But it is also error prone: it is easy to do a mistakes in the build order, you can forget to dpkg -i the new version of package A, etc. But that s not it. Probably at some point, you will want Jenkins to rebuild everything. Well, that s easy to do. Simply create a dummy project, and have other project to build after that one. The build steps could simply be: echo Dummy project as a shell script (I m not even sure that s needed ). Configuring git to start a build on each push In Jenkins, pass your mouse over the Build now URL. Well, we just need to wget that URL in your Alioth repository. A small drawing is better than long explanation:
for i in  ls /git/openstack  ; do
    echo "wget -q --no-check-certificate \
    https://<ip-of-your-server>/job/$ PROJ_NAME /build?delay=0sec \
    -O /dev/null" >/git/openstack/$ i /hooks/post-receive \
        && chmod 0770 /git/openstack/$ i /hooks/post-receive;
done
The chmod 0770 is necessary if you don t want every Alioth users to have access to your Jenkins server web interface and see an eventual htpassword protection that you can add to your jenkins box (I m not covering that, but it is fairly easy to add such protection). Note that all of the members of your Alioth group will then have access to this post-receive hook, containing the password of your htaccess, so you must trust everyone in your Alioth group to not do nasty things with your Jenkins. Bonus point: IRC robot If you would like to see the result of your build published on IRC, Jenkins can do that. Click on Manage Jenkins , then on Manage Plugins . Then click on available and check the box in front of IRC plugin . Go at the bottom of the screen and click on Add . Then check the box to restart Jenkins automatically. Once it is restarted, go again under Manage jenkins then Configure system . Select the IRC Notification and configure it to join the network and the channel you want. Click on Advanced to select the IRC nick name of your bot, and make sure you change the port (by default jenkins has 194, when IRC normally uses 6667). Be patient when waiting for the IRC robot to connect / disconnect, this can take some time. Now, for each jenkins Job, you can tick the IRC Notification option. Doing piuparts after build One nice thing with automated builds, is that most of the time, you don t need to wait starring at them. So you can add as many tests as you want, the Jenkins IRC robot will anyway let you know sooner or later the result of your build. So adding piuparts tests in the build script seems the correct thing to do. Though that is still on my todo, so maybe that will be for my next blog post.

28 April 2013

Mart&iacute;n Ferrari: Moving my stuff away from home

TL;DR version: I want to get rid of the small server running at home, I tell you here about the service I've chosen, and why I like it. In following posts, I'll explain how did I set it up remotely. Disclaimer: I am in now way affiliated with the companies I mention here (except for Picasa, as I am a Google employee), and don't get any bonuses for this post. I am only sharing this because I think it might be useful information for other people.
Being a frequent migrant means possessions are a burden. In my previous place of residence (in France), I originally intended to only stay for 6 months, and so I arrived with just a couple of suitcases, and in the end that was enough for me to live for almost 2 years. The last time, on the other hand, I was removing my stuff completely from Argentina. I emptied my house, gave away some stuff, send some boxes to my parents' place, and carried the rest with me. That was a lot of stuff, but since the company was paying for the relocation, it was not much of a problem. Later I realised my mistake, and knowing that my time in Ireland is limited, I started to try and get rid of stuff I don't need. I know I will just sell or give away much of my stuff when I finally leave, but there are some things that are not so easy to part with. The main one being my home server, which hosts this website, my VCS repositories, pictures, and many other things I need to have on the net. This all used to be located in a home-made PC tucked in a data centre, co-located by a friendly company. But that computer died almost 2 years ago, and so canterville became abhean, and my stuff started being hosted with my aDSL connection. It worked well for some time, but now I realised I had to revert that change. With this in mind I set off to find a cheap place to host my stuff. I had a few requirements: I don't have that many photos, nor they are too big, but these requirements made it clear that most VPS offerings were not going to work for me. For some reason I fail to understand, local storage in VPS offerings is usually prohibitively expensive. This is OK for most use cases, but not for mine. A friend of mine, with a similar use case, is a happy VPS customer. He told me his trick: he only hosts in the server low-quality versions of the pictures, and keeps the originals (and back-ups) at home. This was a great idea, but with two fatal flaws: I want to only carry around a laptop and one or two external hard drives; and I want to have back-ups that are not physically with me. I was starting to think about hosting my files in Amazon s3 or something like that, since most dedicated servers are way too expensive. But then I heard about two French companies offering dirt-cheap servers: OVH and Online.net. Both of them offered small servers for about 12 a month, cheaper than most VPS offerings! Online seems to mainly cater to the French market, and for some silly reason, they charge a 50 set-up fee to customers outside of France. OVH, on the other hand, has many local branches, including an Irish one, so I went with them. The offering is a low-cost line called Kimsufi, and the smallest one is still very decent for a personal server: Once I had paid the fee for one month, it took a while for it to be activated (their payment system is pretty bad), but it finally was enabled about 24h later. Then the real fun started. On one hand, I was happy to see a wide selections of operating systems to choose from, including Debian stable and testing, and a web console with many functionalities, including some basic monitoring; but on the other hand, I realised that the installed image was not pristine, the online docs are not very good, and the web application is a bit buggy and really awkward to navigate. Having sub-par docs is not something I would usually care much about, but it made it a bit more difficult to me to understand some of the very cool functionalities their system offers (more on that in a bit), and more importantly, it made it clear to me that I won't trust their image: the procedures detailed there were not exactly best-practices, and they allow themselves to log-in as root into my server. I want to describe here what I think are their most interesting features, that made it possible to me to do risky operations, like encrypting the root partition, and setting up a firewall; and being able to fix problems that would usually require physical access. These are found in their web console: a hardware reset, and configurable netboot support with many offered images, including a rescue image based on Ubuntu and one that serves as a virtual KVM. (It is surprising that these servers don't have a serial console, but at least the kernel does not detect any). With these in hand, I didn't have to fear being locked out of my server for ever. Just set up a netboot image and hard-reboot the machine! Also, it made it very simple to install my system from scratch with debootstrap. The virtual KVM is a very interesting trick. It is a netboot image that runs some tests, and fires up a web browser. You get an email with the URL and a password to access it, and then you open a page that offers you what is basically a Qemu connected to a VNC server which will boot from your real hard drive. It is super slow, but that allows you to get console access to your server, which can be very handy to debug booting problems, unless it is some issue with the real hardware. It also offers the possibility of downloading an ISO image off the network and booting that, so it can be used to run a stock installer CD too. In another post I'll describe how I reinstalled my server remotely, and some of the pitfalls that I've encountered in the process.

Vagrant Cascadian: intro

For many years, I've been meaning to write about various things in some sort of online journal. I'd like to tie together various parts of my life, such as my technical work in Debian, LTSP and other Free Software, Software Libre, and Open Source Software projects, but also my passion for Aikido, and other ideas that inspire me, such as pleaching. As with many new things, I struggled to name this journal. I even struggled with calling it a journal as opposed to a Blog, though blog always sounded a bit... brief and kind of blunt for my liking. So journal it is. But I still didn't even really have a name for it. Recently introduced to the concept of pleaching, essentially weaving living, growing branches togther, I was drawn to the concept, but admittedly, the sound of "pleach" or "pleaching" also carried some hint of harshness in it. Looking into synonyms, weaving, plait, braid... braid, yes, I typically wear my hair in a pair of braids... It has enough meaning to get by on... But that's too plain... so I borrowed from Spanish to come up with "trenza". So, thankfully to all involved, most of these posts will probably not be about picking names for things. I have a bit of backlog about some technical projects I've worked on that I'd like to write about, so I'll start with a few of those...

26 April 2013

Keith Packard: Shared Memory Fences

Shared Memory Fences In our last adventure, dri3k first steps, one of the future work items was to deal with synchronization between the direct rendering application and the X server. DRI2 handles this by performing a round trip each time the application starts using a buffer that was being used by the X server. As DRI3 manages buffer allocation within the application, there s really no reason to talk to the server, so this implicit serialization point just isn t available to us. As I mentioned last time, James Jones and Aaron Plattner added an explicit GPU serialization system to the Sync extension. These SyncFences serializing rendering between two X clients, but within the server there are hooks provided for the driver to use hardware-specific serialization primitives. The existing Linux DRM interfaces queue rendering to the GPU in the order requests are made to the kernel, so we don t need the ability to serialize within the GPU, we just need to serialize requests to the kernel. Simple CPU-based serialization gating access to the GPU will suffice here, at least for the current set of drivers. GPU access which is not mediated by the kernel will presumably require serialization that involves the GPU itself. We ll leave that for a future adventure though; the goal today is to build something that works with the current Linux DRM interfaces. SyncFence Semantics The semantics required by SyncFences is for multiple clients to block on a fence which a single client then triggers. All of the blocked clients start executing requests immediately after the trigger fires. There are four basic operations on SyncFences: SyncFences are the same as Events as provided by Python and other systems. Of course all of the names have been changed to keep things interesting. I ll call them Fences here, to be consistent with the current X usage. Using Pthread Primitives One fact about pthreads that I recently learned is that the synchronization primitives (mutexes, barriers and semaphores) are actually supposed to work across process boundaries, if those objects are in shared memory mapped by each process. That seemed like a great simplification for this project; allocate a page of shared memory, map into the X server and direct rendering application and use the existing pthreads APIs. Alas, the pthread objects are architecture specific. I m pretty sure that when that spec was written, no-one ever thought of running multiple architectures within the same memory space. I went and looked at the code to check, and found that each of these objects has a different size and structure on x86 and x86_64 architectures. That makes it pretty hard to use this API within X as we often have both 32- and 64- bit applications talking to the same (presumably 64-bit) X server. As a last resort, I read through a bunch of articles on using futexes directly within applications and decided that it was probably possible to implement what I needed in an architecture-independent fashion. Futexes Linux Futexes live in this strange limbo of being a not-quite-public kernel interface. Glibc uses them internally to implement locking primitives, but it doesn t export any direct interface to the system call. Certainly they re easy to use incorrectly, but it s unusual in the Linux space to have our fundamental tools locked away for our own safety . Fortunately, we can still get at futexes by creating our own syscall wrappers.
static inline long sys_futex(void *addr1, int op, int val1,
                 struct timespec *timeout, void *addr2, int val3)
 
    return syscall(SYS_futex, addr1, op, val1, timeout, addr2, val3);
 
For this little exercise, I created two simple wrappers, one to block on a futex:
static inline int futex_wait(int32_t *addr, int32_t value)  
    return sys_futex(addr, FUTEX_WAIT, value, NULL, NULL, 0);
 
and one to wake up all futex waiters:
static inline int futex_wake(int32_t *addr)  
    return sys_futex(addr, FUTEX_WAKE, MAXINT, NULL, NULL, 0);
 
Atomic Memory Operations I need atomic memory operations to keep separate cores from seeing different values of the fence value, GCC defines a few such primitives and I picked _syncboolcompareandswap and _syncvalcompareandswap. I also need fetch and store operations that the compiler won t shuffle around:
#define barrier() __asm__ __volatile__("": : :"memory")
static inline void atomic_store(int32_t *f, int32_t v)
 
    barrier();
    *f = v;
    barrier();
 
static inline int32_t atomic_fetch(int32_t *a)
 
    int32_t v;
    barrier();
    v = *a;
    barrier();
    return v;
 
If your machine doesn t make these two operations atomic, then you would redefine these as needed. Futex-based Fences These wake-all semantics of Fences greatly simplify reasoning about the operation as there s no need to ensure that only a single thread runs past Await, the only requirement is that no threads pass the Await operation until the fence is triggered. A Fence is defined by a single 32-bit integer which can take one of three values: With those, I built the fence operations as follows. Here s Await:
int fence_await(int32_t *f)
 
    while (__sync_val_compare_and_swap(f, 0, -1) != 1)  
        if (futex_wait(f, -1))  
            if (errno != EWOULDBLOCK)
                return -1;
         
     
    return 0;
 
The basic requirement that the thread not run until the fence is triggered is met by fetching the current value of the fence and comparing it with 1. Until it is signaled, that comparison will return false. The compareandswap operation makes sure the fence is -1 before the thread calls futex_wait, either it was already -1 in the case where there were other waiters, or it was 0 before and is now -1 in the case where there were no waiters before. This needs to be an atomic operation so that the fence value will be seen as -1 by the trigger operation if there are any threads in the syscall. The futex_wait call will return once the value is no longer -1, it also ensures that the thread won t block if the trigger occurs between the swap and the syscall. Here s the Trigger function:
int fence_trigger(int32_t *f)
 
    if (__sync_val_compare_and_swap(f, 0, 1) == -1)  
        atomic_store(f, 1);
        if (futex_wake(f) < 0)
            return -1;
     
    return 0;
 
The atomic compareandswap operation will make sure that no Await thread swaps the 0 for a -1 while the trigger is changing the value from 0 to 1; either the Await switches from 0 to -1 or the Trigger switches from 0 to 1. If the value before the compareandswap was -1, then there may be threads waiting on the Fence. An atomic store, constructed with two memory barriers and a regular store operation, to mark the Fence triggered is followed by the futex_wake call to unblock all Awaiting threads. The Query function is just an atomic fetch:
int fence_query(int32_t *f)
 
    return atomic_fetch(f) == 1;
 
Reset requires a compareandswap so that it doesn t disturb things if the fence has already been reset and there are threads waiting on it:
void fence_reset(int32_t *f)
 
    __sync_bool_compare_and_swap(f, 1, 0);
 
A Request for Review Ok, so we ve all tried to create synchronization primitives only to find that our obvious implementations were full of holes. I d love to hear from you if you ve identified any problems in the above code, or if you can figure out how to use the existing glibc primitives for this operation.

Vincent Sanders: When you make something, cleaning it out of structural debris is one of the most vital things you do.

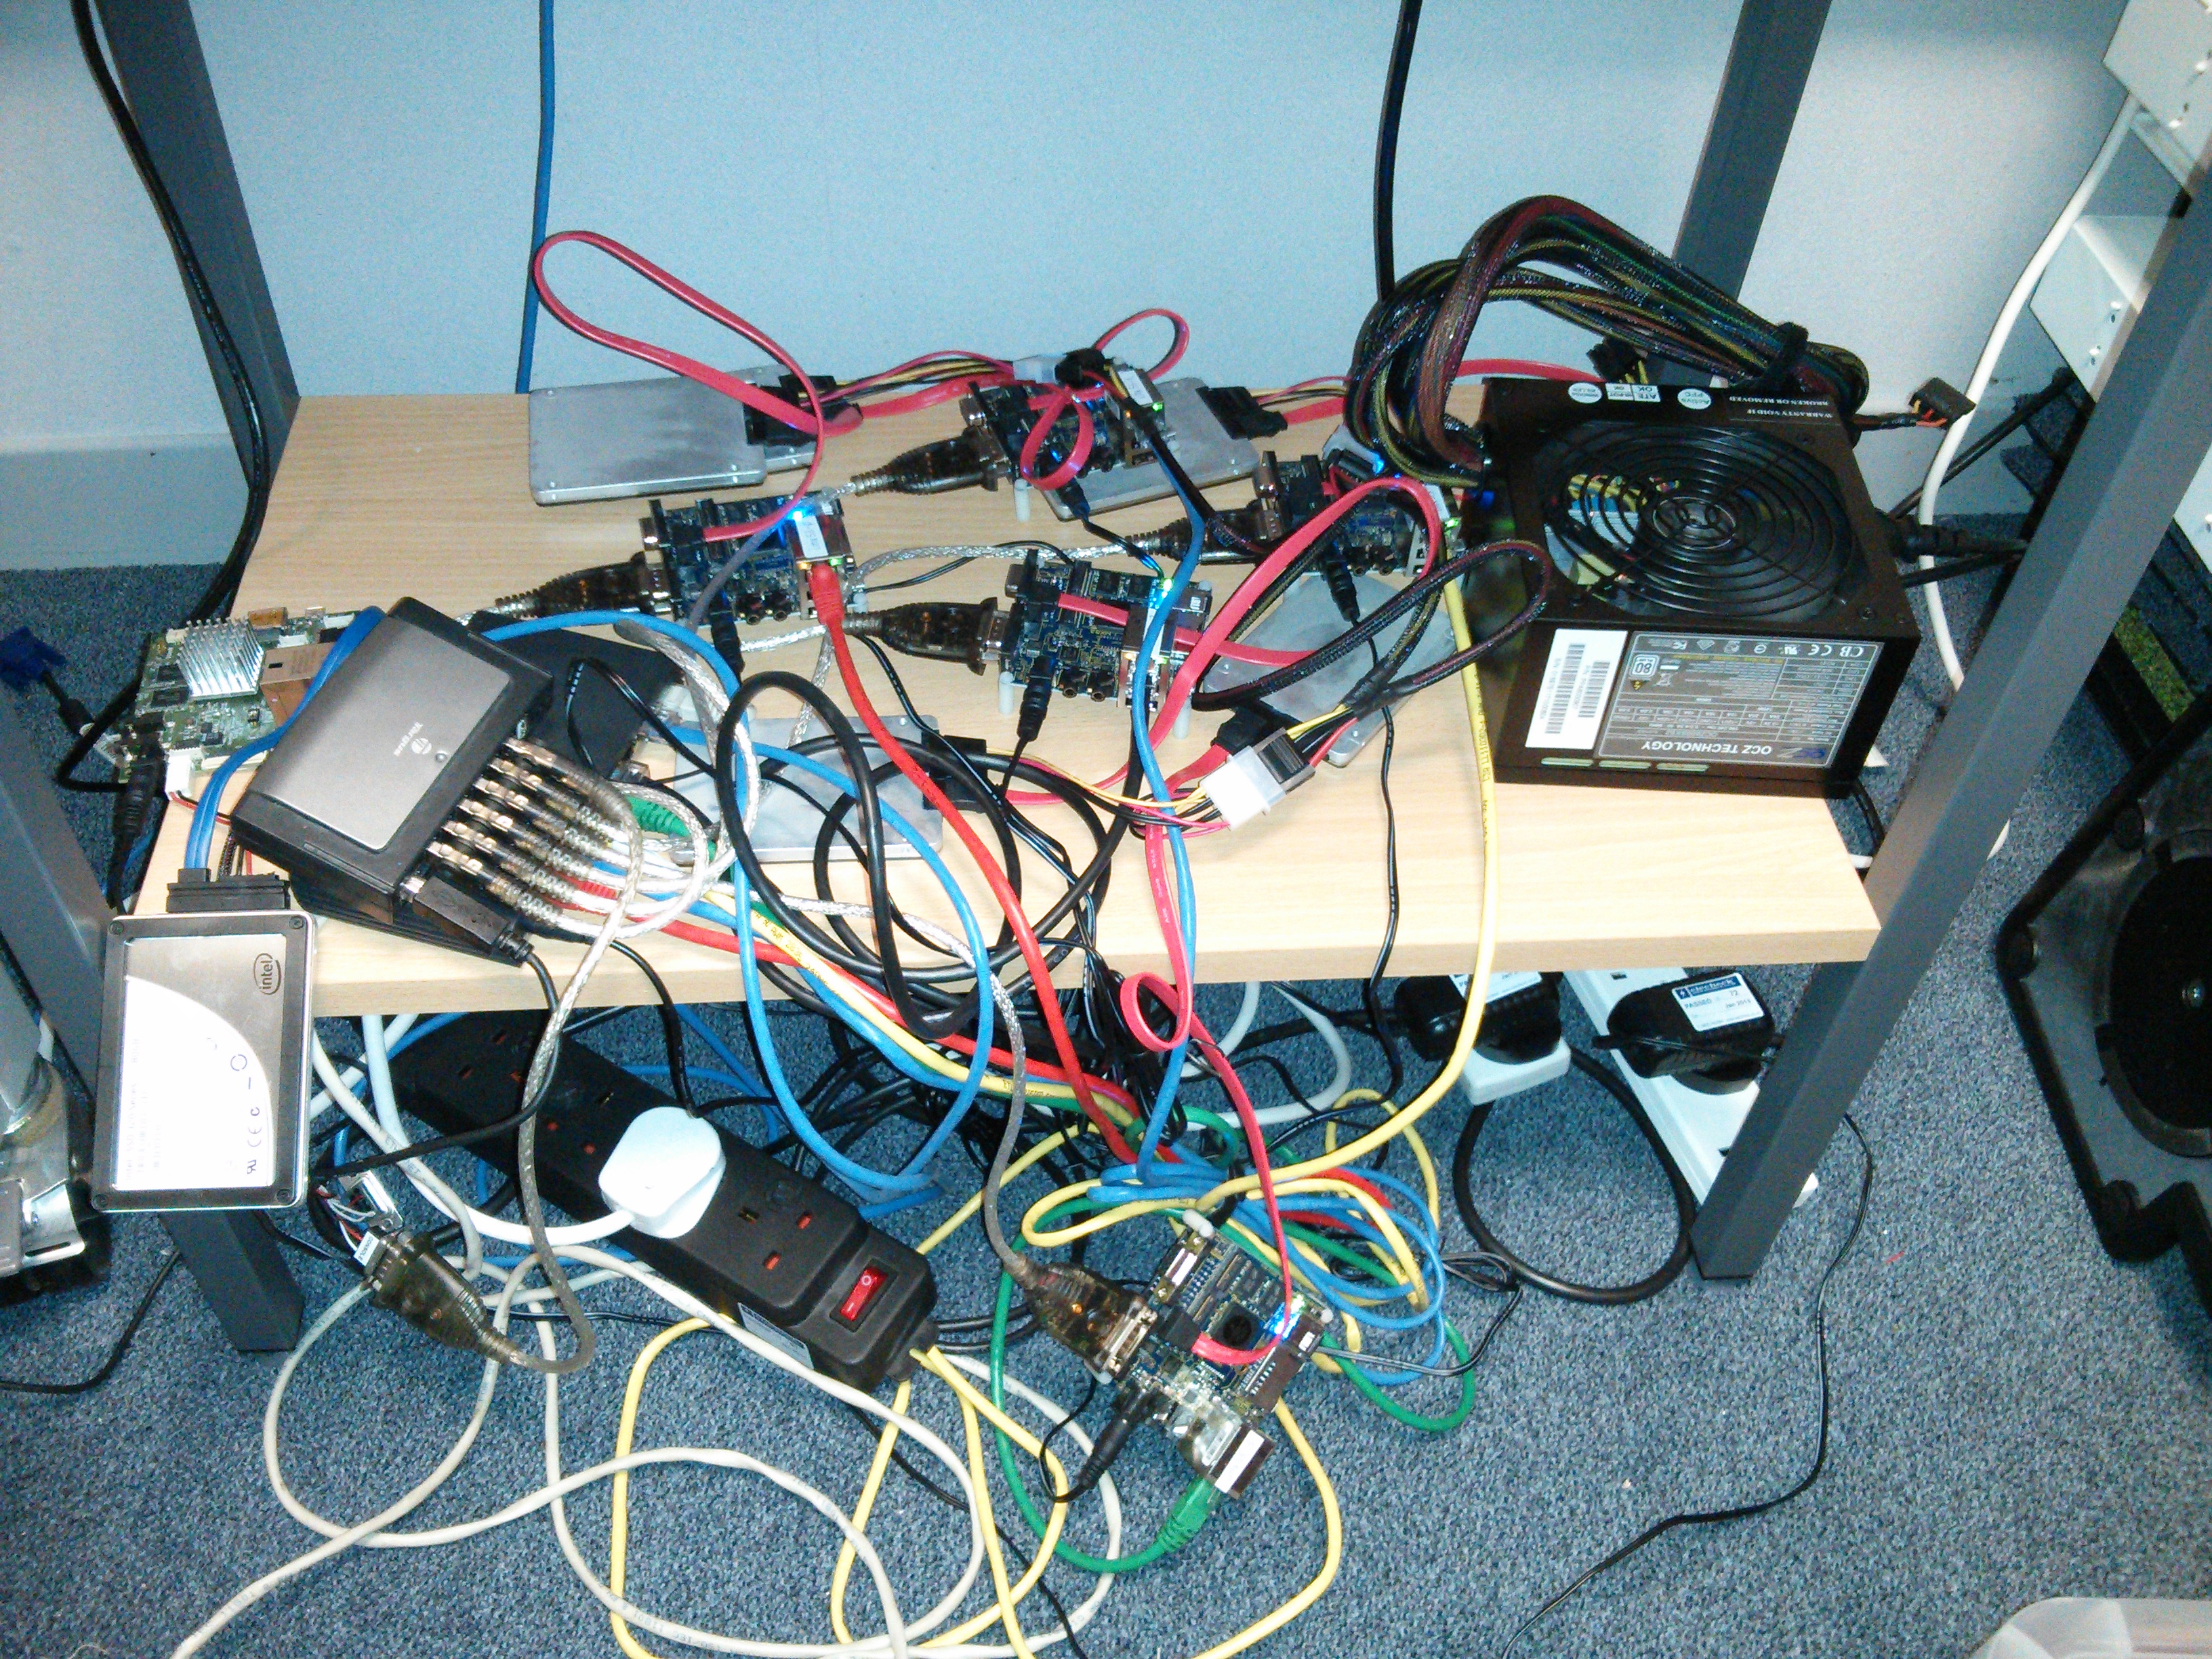
Collabora recently had a problem with a project's ARM build farm. In a nice change of pace it was not that the kernel was crashing, nor indeed any of the software or hardware.
The ProblemInstead our problem was our build farm could best be described as "a pile of stuff" and we wanted to add more systems to it and have switched power control for automated testing.

Which is kinda where the Christopher Alexander quote comes into this. I suggested that I might be able to come up with a better, or at least cleaner, solution.
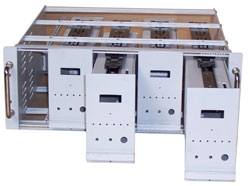
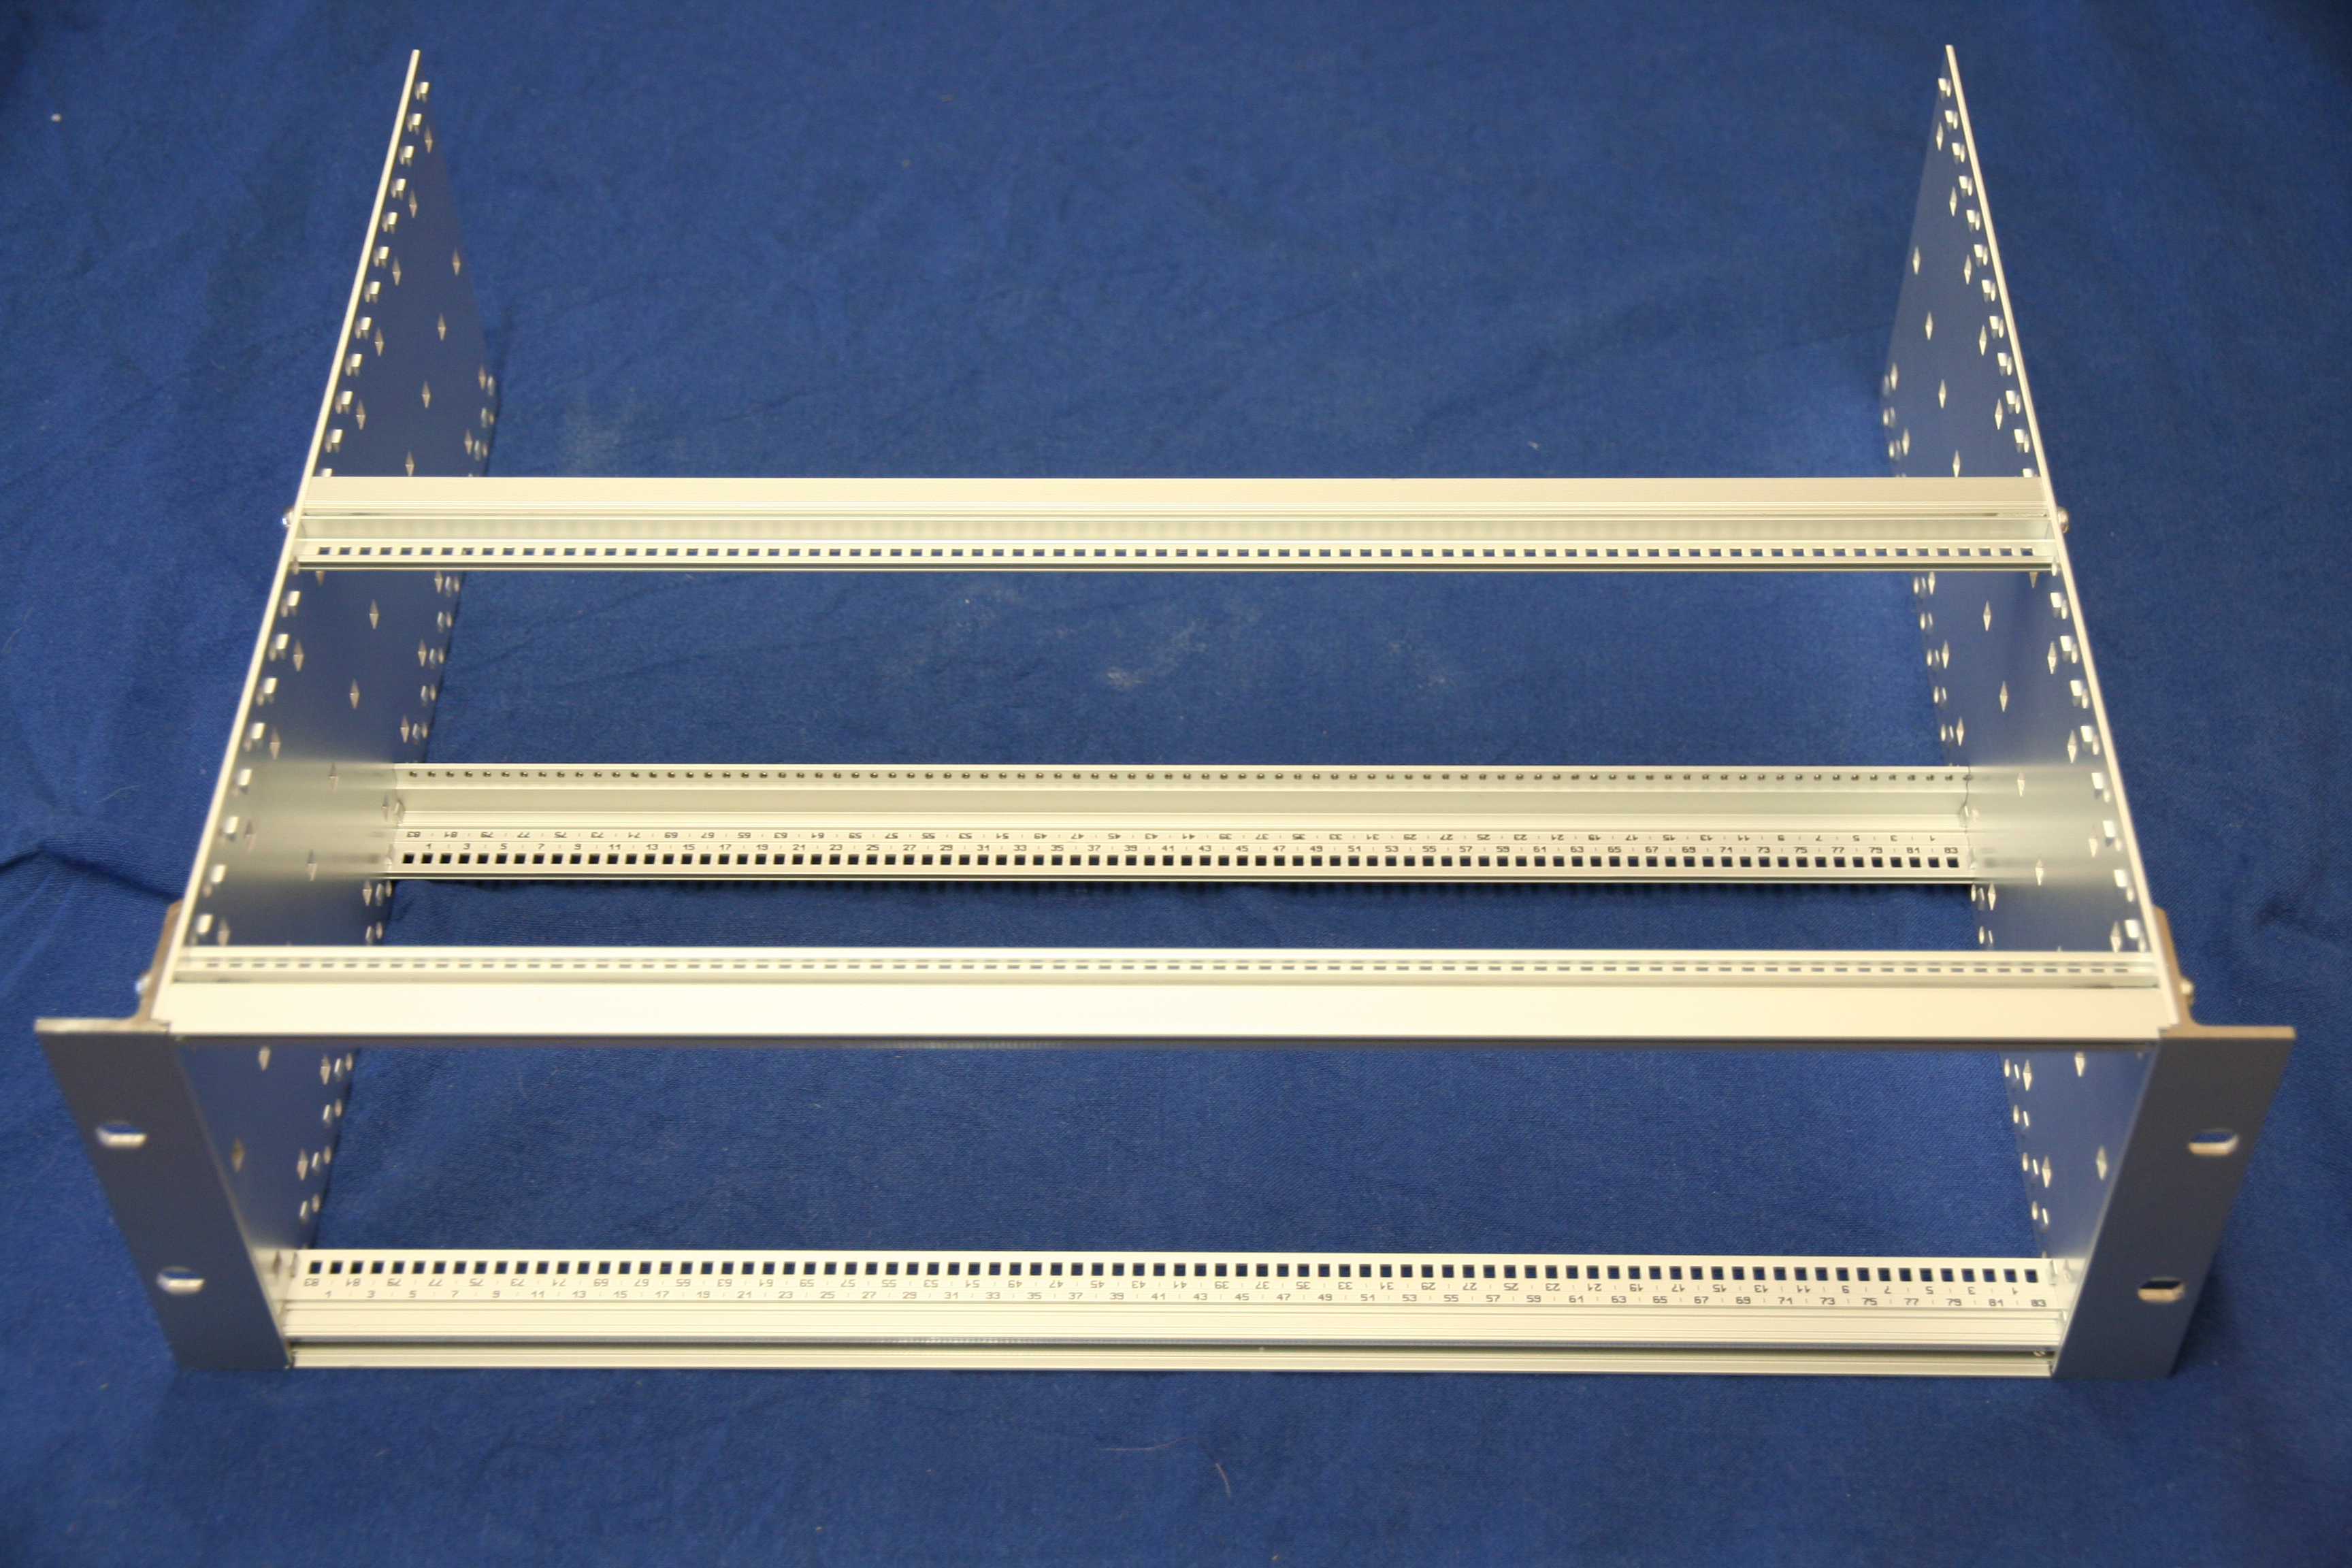
The IdeaA subrack with sub modulesPrevious experience had exposed me to the idea of using 19 inch subracks for mounting circuits inside submodules.

I originally envisaged the dev boards individually mounted inside these boxes. However preliminary investigation revealed that the enclosures were both expensive and used a lot of space which would greatly increase the rack space required to house these systems.

imx53 QSB eurocard carrier
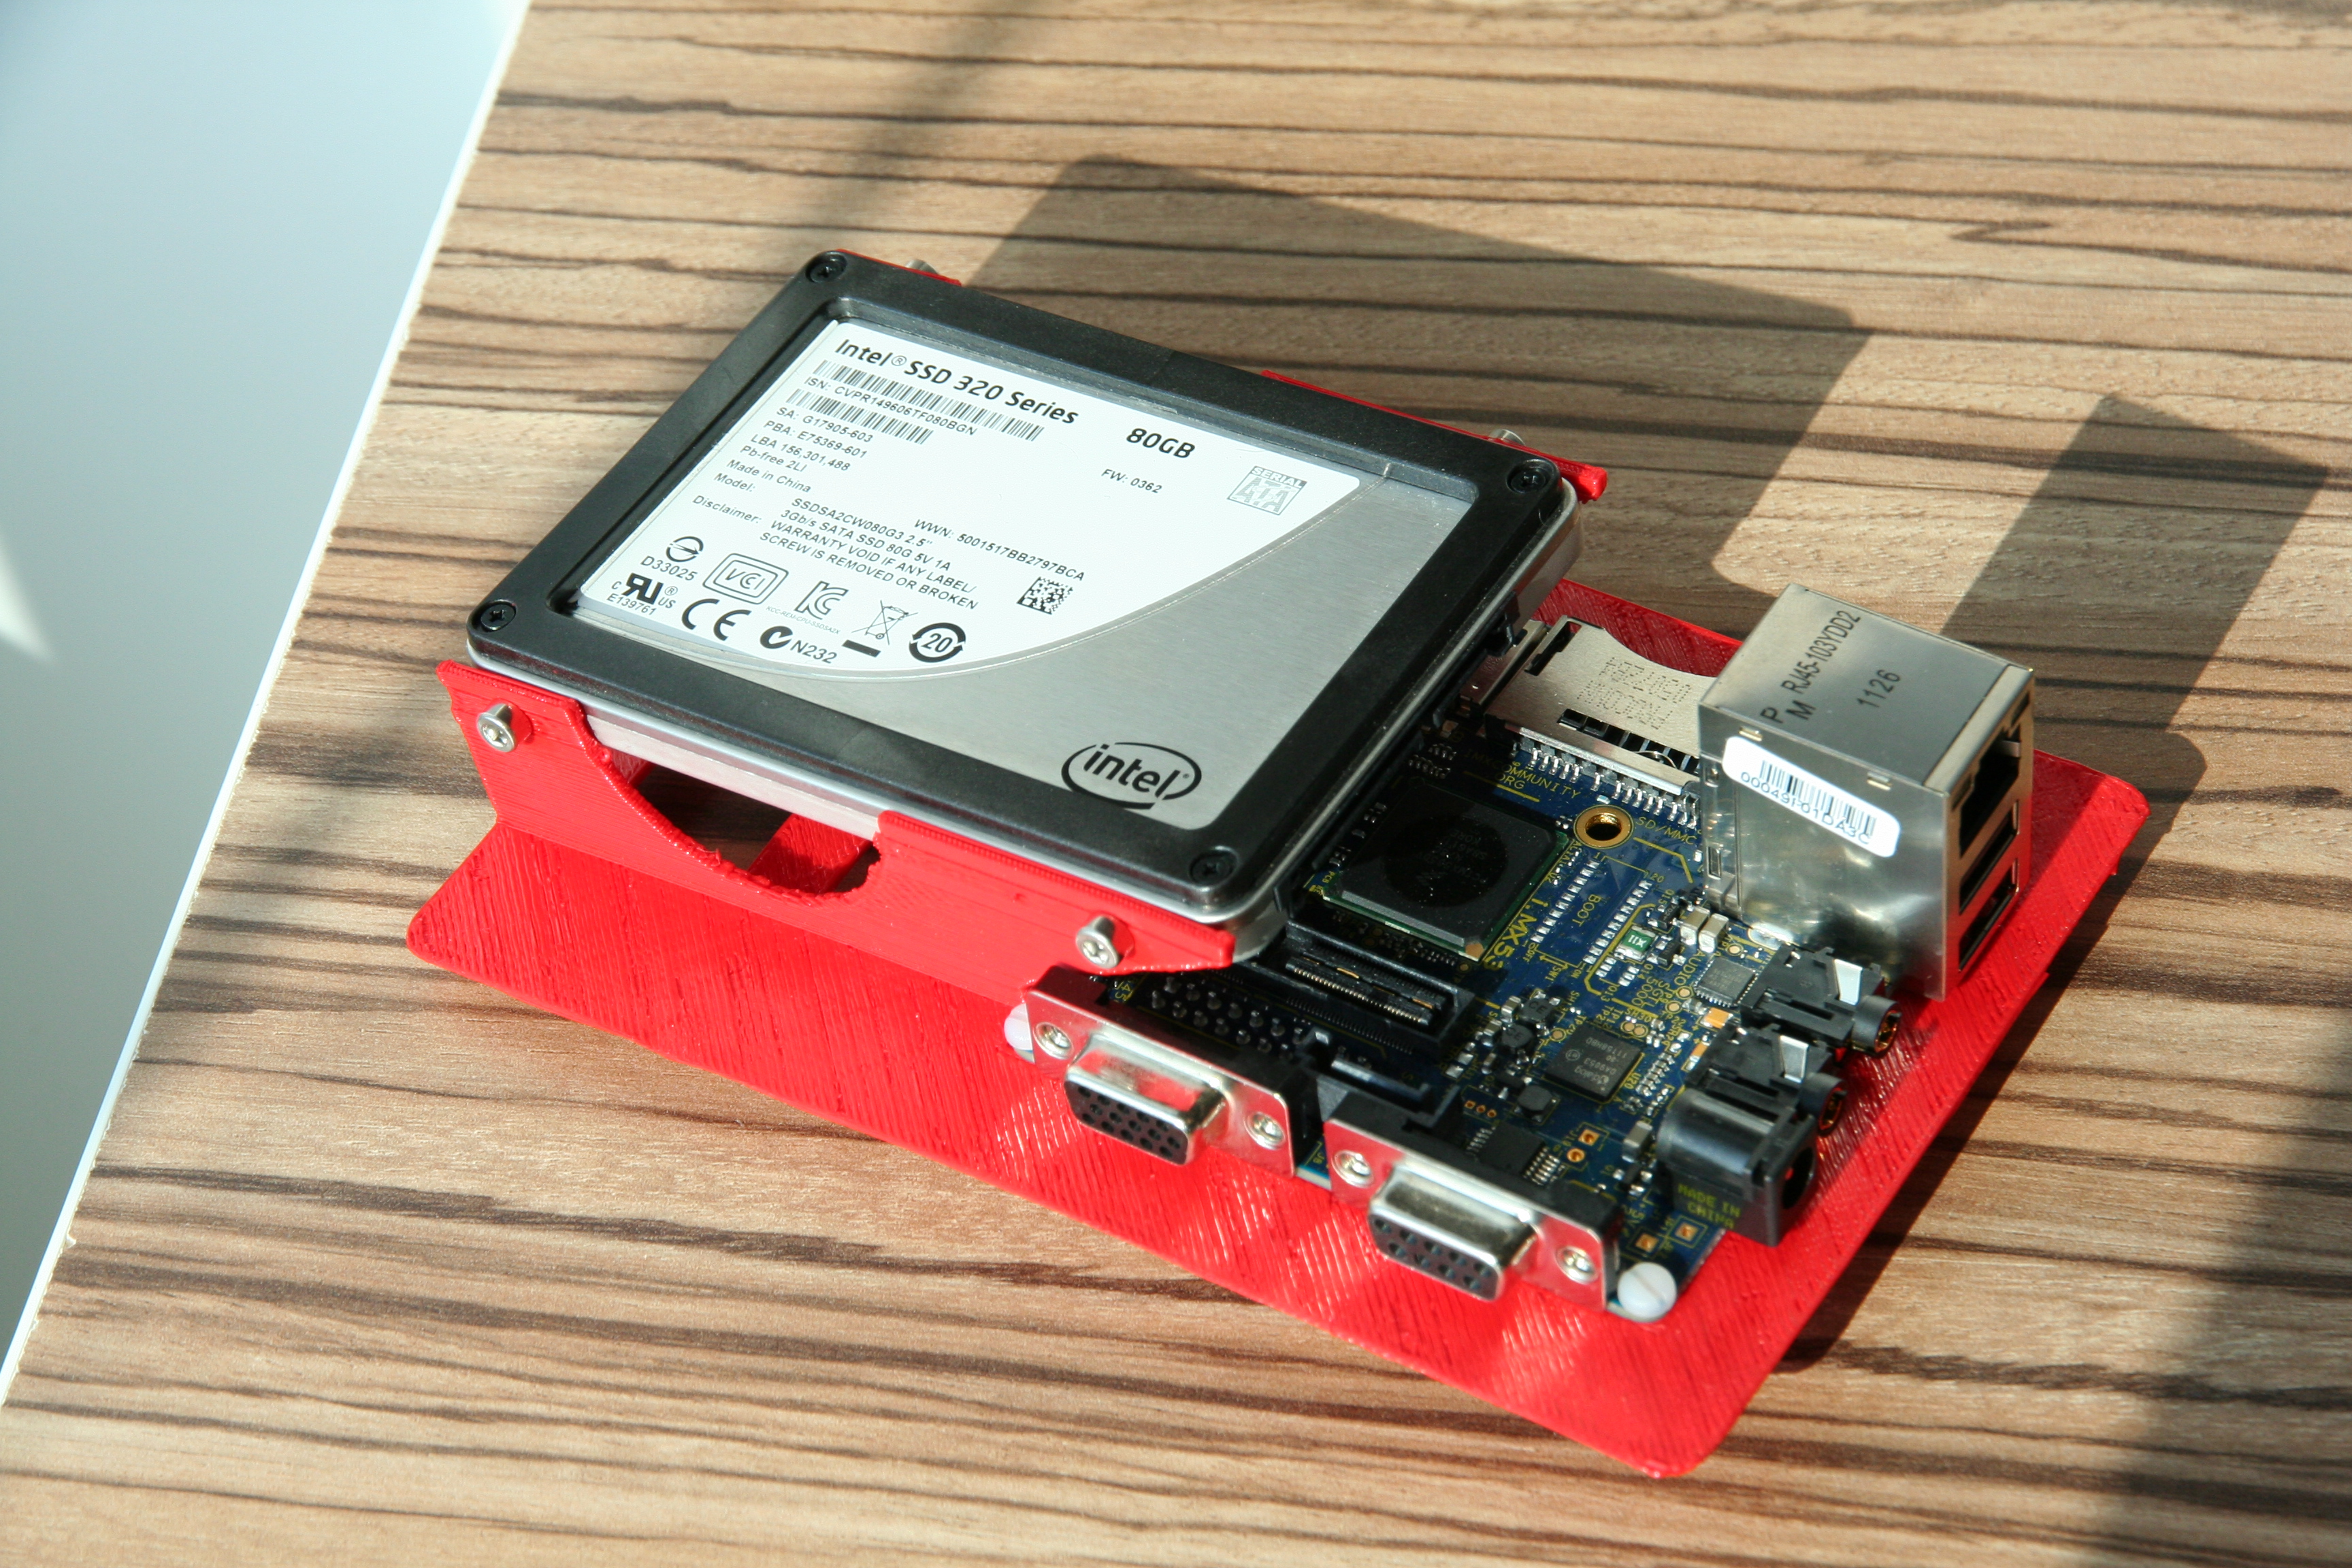
I decided to instead look at eurocard type subracks with carriers for the systems. Using my 3D printer I came up with a carrier design for the imx53 QSB and printed it. I used the basic eurocard size of 100mm x 160mm which would allow the cards to be used within a 3U subrack.

Once assembled it became apparent that each carrier would be able to share resources like power supply, ethernet port and serial console via USB just as the existing setup did and that these would need to be housed within the subrack.
The Prototype
The carrier prototype was enough to get enough interest to allow me to move on to the next phase of the project. I purchased a Schroff 24563-194 subrack kit and three packs of guide rails from Farnell and assembled it.

Initially I had envisaged acquiring additional horizontal rails from Schroff which would enable constructing an area suitable for mounting the shared components behind the card area.

Rear profile for Schroff subrackUnfortunately Schroff have no suitable horizontal profiles in their catalog and are another of those companies who seem to not want to actually sell products to end users but rather deal with wholesalers who do not have their entire product range!

Printed rear profile for Schroff subrack
Undaunted by this I created my own horizontal rail profile and 3D printed some lengths. The profile is designed to allow a 3mm thick rear cover sheet attached with M2.5 mounting bolts and fit rack sides in the same way the other profiles do.

At this point I should introduce some information on how these subracks are dimensioned. A standard 19 inch rack (as defined in IEC 60297) has a width of 17.75 inches(450.85mm) between the vertical posts. The height is measured in U (1.75 inches)

A subrack must obviously fit in the horizontal gap while providing as much internal space as possible. A subrack is generally either 3 or 6 U high. The width within a subrack is defined in units called HP (Horizontal Pitch) which are 0.2 inches(5.08 mm) and subracks like the Schroff generally list 84 usable HP.

However we must be careful (or actually just learn from me stuffing this up ;-) as the usable HP is not the same thing as the actual length of the horizontal rails! The enclosures actually leave and additional 0.1 inch at either end giving a total internal width of 85HP (17 inches, 431.8 mm) which leaves 0.75 inches for the subrack sides and some clearance.

The Schroff subrack allows eurocards to be slotted into rails where the card centre line is on HP boundaries, hence we describe the width of a card in the slot in terms of HP

I cannot manufacture aluminium extrusions (I know it is a personal failing) nor produce more than 100 mm long length of the plastic profile on my printer.

Even if full lengths are purchased from a commercial service (120 euros for a pair including tax and shipping) the plastic does not have sufficient mechanical strength.

The solution I came up with was somewhat innovative, as an alternative a M5 bolt into a thread in the aluminium extrusion I used a 444mm long length of 4mm threaded rod with nuts at either end. This arrangement puts the extrusion under compression and gives it a great deal of additional mechanical strength as the steel threaded rod is very strong.

Additionally to avoid having to print enough extrusion for the entire length I used some 6mm aluminium tube as a spacer between 6HP(30.48mm) wide sections of the printed extrusion.

It was intended to use a standard modular PC power supply which is 150mm wide which is pretty close to 30HP (6 inches) so it was decided to have a 6HP section of rail at that point to allow a rear mounting plate for the PSU to be attached.

This gives 6HP of profile, 21HP(106.68mm) of tube spacer, 6HP of profile, 46HP(233.68 mm) of tube spacer and a final 6HP profile summing to our total of 85HP. Of course this would be unnecessary if a full continuous 85HP rail had been purchased, but 6 of 6 HP long profile is only 51 euro a saving of 70 euro.

To provide a flat area on which to mount the power switching, Ethernet switch and USB hubs I ordered a 170 x 431 mm sheet of 3mm thick aluminium from inspiredsteel who, while being an ebay company, were fast, cheap and the cutting was accurate.

Do be sure to mention you would prefer it if any error made the sheet smaller rather than larger or it might not fit, for me though they were accurate to the tenth of a mm! If you would prefer the rear section of the rack to be enclosed when you are finished, buy a second sheet for the top. For my prototype I only purchased a 170 x 280mm sheet as I was unsure if I wanted a surface under the PSU (you do, buy the longer sheet)

PC power supply mounted to back plateMounting the PSU was a simple case of constructing a 3 mm thick plate with the correct cutouts and mounting holes for an ATX supply. Although the images show the PSU mounted on the left hand side of the rack this was later reversed to improve cable management.

The subrack needed to provide Ethernet switch ports to all the systems. A TP-Link TL-SF1016DS 16-Port 10/100Mbps Switch was acquired and the switch board removed from its enclosure. The switch selected has an easily removed board and is powered by a single 3.3V input which is readily available from the ATX PSU.

Attention now returned to the eurocard carriers for the systems, the boards to be housed were iMX53 QSB and iMX6 SABRE Lite and a Raspberry Pi control system to act as USB serial console etc.

The carriers for both main boards needed to be 8HP wide, comprised of:
Although only 38 mm this is 7.5HP and fractions of an HP are not possible with the selected subrack.

With 8HP wide modules this would allow for ten slots, within the 84 usable HP, and an eleventh 4HP wide in which the Raspberry Pi system fits.

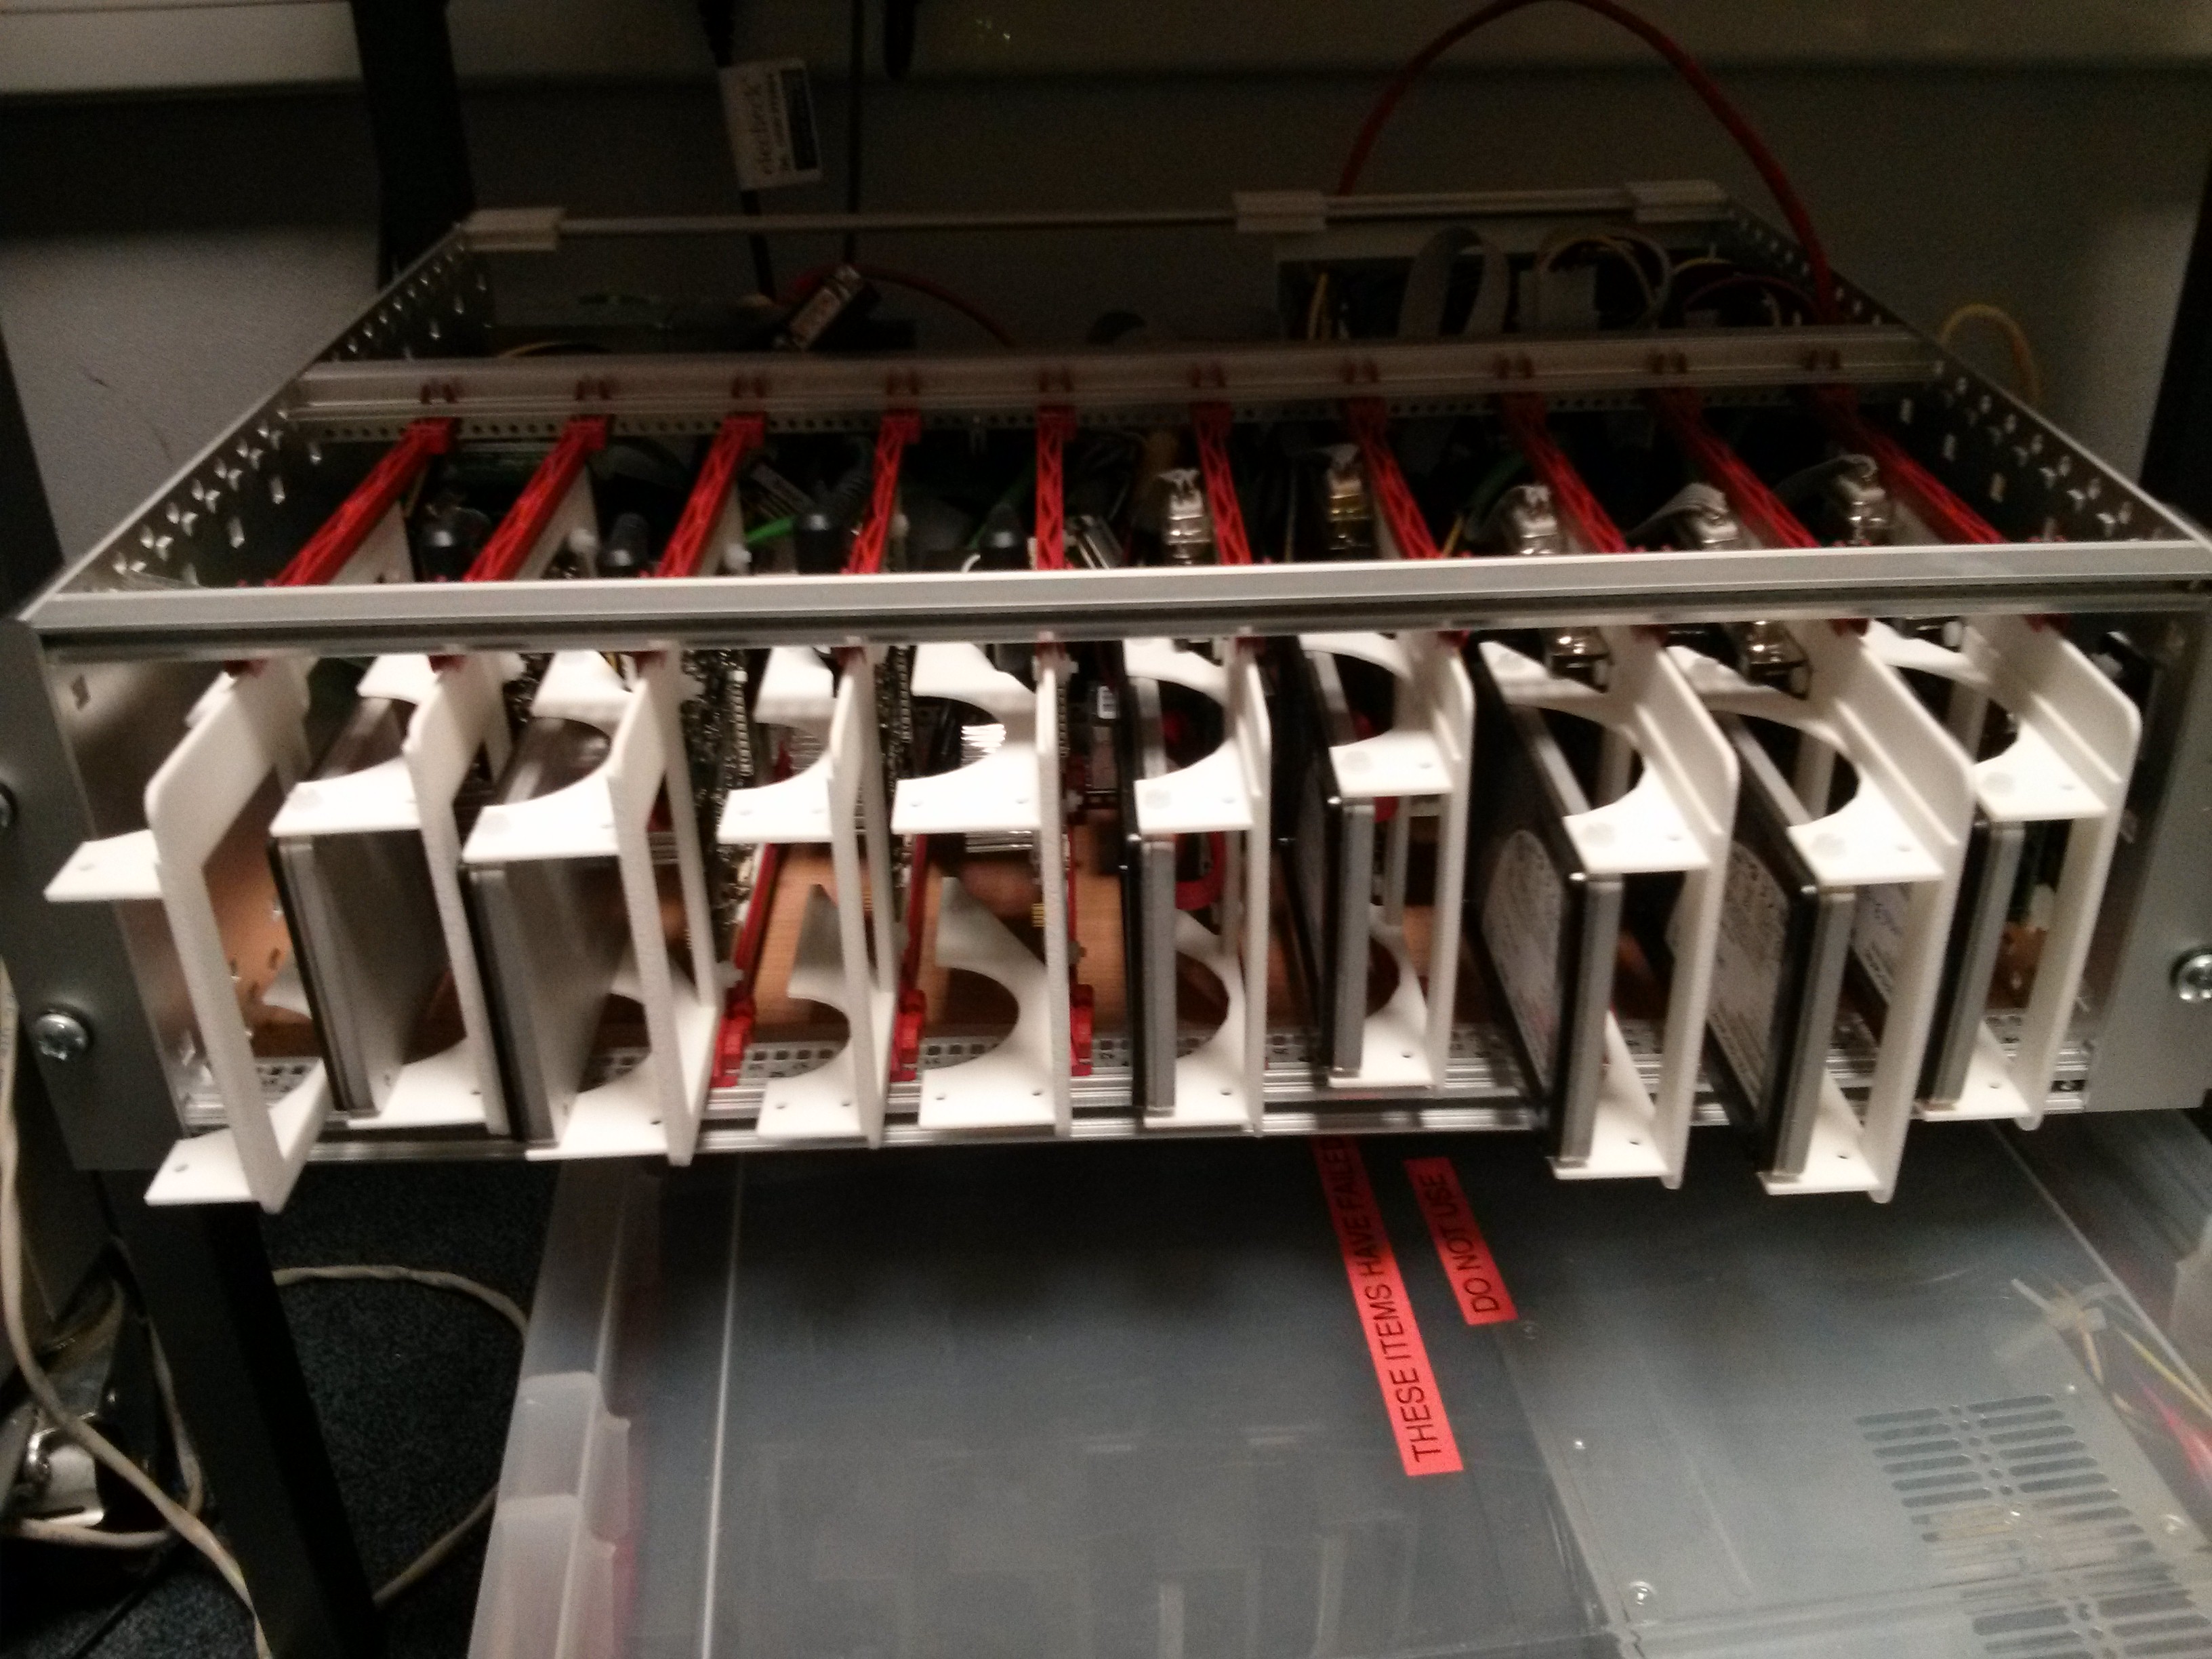
iMX6 SABRE Lite eurocard carrierCarrier designs for both the i.MX53 QSB and the i.MX6 SABRE Lite boards were created and fabricated at a professional 3D print shop which gave a high quality finish product and removed the perceived risk of relying on a personal 3D printer for a quantity of parts.

This resulted in changes in the design to remove as much material as possible as commercial 3D services charge by the cubic cm. This Design For Manufacture (DFM) step removed almost 50% from the price of the initial design.

i.MX53 QSB carriers with wiring loom
The i.MX6 design underwent a second iteration to allow for the heatsink to be mounted and not mechanically interfere with the hard drive (although the prototype carrier has been used successfully for a system that does not require a hard drive). The lesson learned here is to be aware that an design iteration or two is likely and that it is not without cost.

The initial installation was to have six i.MX53 and two i.MX6 this later changed to a five/four split, however the carrier solution allows for almost any combination, the only caveat (discovered later) is the imx53 carriers should be to the right hand side with the small 4HP gap at that end as they have a JTAG connector underneath the board which otherwise foul the hard drive of the next carrier.

Racked cards showing unwanted cable tails
A wiring loom was constructed for each board giving them a connector tail long enough to allow them to be removed. This was the wrong approach! if you implement this design (or when I do it again) the connector tails on the wiring loom should present all the connections to the rear at the same depth as the Ethernet connection.

The rack cables themselves should be long enough to allow the slides to be removed but importantly it is not desirable to have the trailing cable on the cards. I guess the original eurocard designers figured this out as they designed the cards around the standard fixed DIN connectors at the back of the card slots.

USB relay board with wiring loom attached
We will now briefly examine a misjudgement that caused the initially deployed solution to be reimplemented. As the design was going to use USB serial converters to access the serial console a USB connected relay board was selected to switch the power to each slot. I had previously used serial controlled relay boards with a USB serial convertor however these were no longer available.

Initial deployment with USB controlled relay board
All the available USB relay boards were HID controlled, this did not initially seem to be an issue and Linux software was written to provide a reasonable interface. However it soon became apparent that the firmware on the purchased board was very buggy and crashed the host computer's USB stack multiple times.

Deployed solutionOnce it became apparent that the USB controlled power board was not viable a new design was conceived. As the Ethernet switch had ports available Ethernet controlled relay boards were acquired.

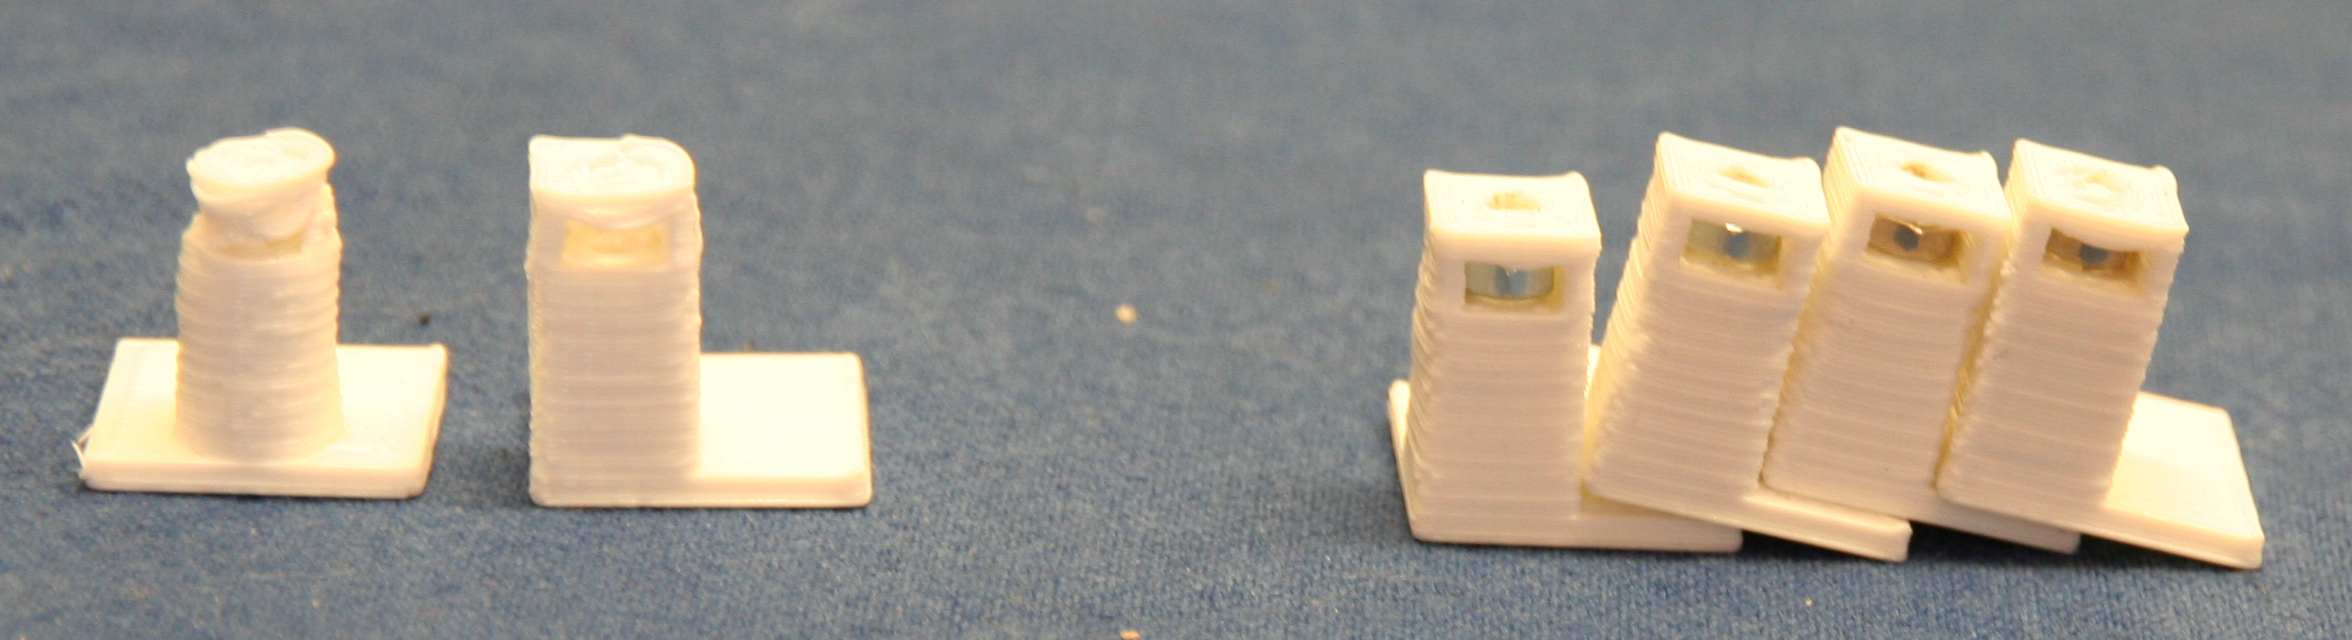
Evolution of 3mm PCB pillars
It did prove necessary to design and print some PCB support posts with M3 nut traps to allow the relay boards to be easily mounted using double sided adhesive pads.

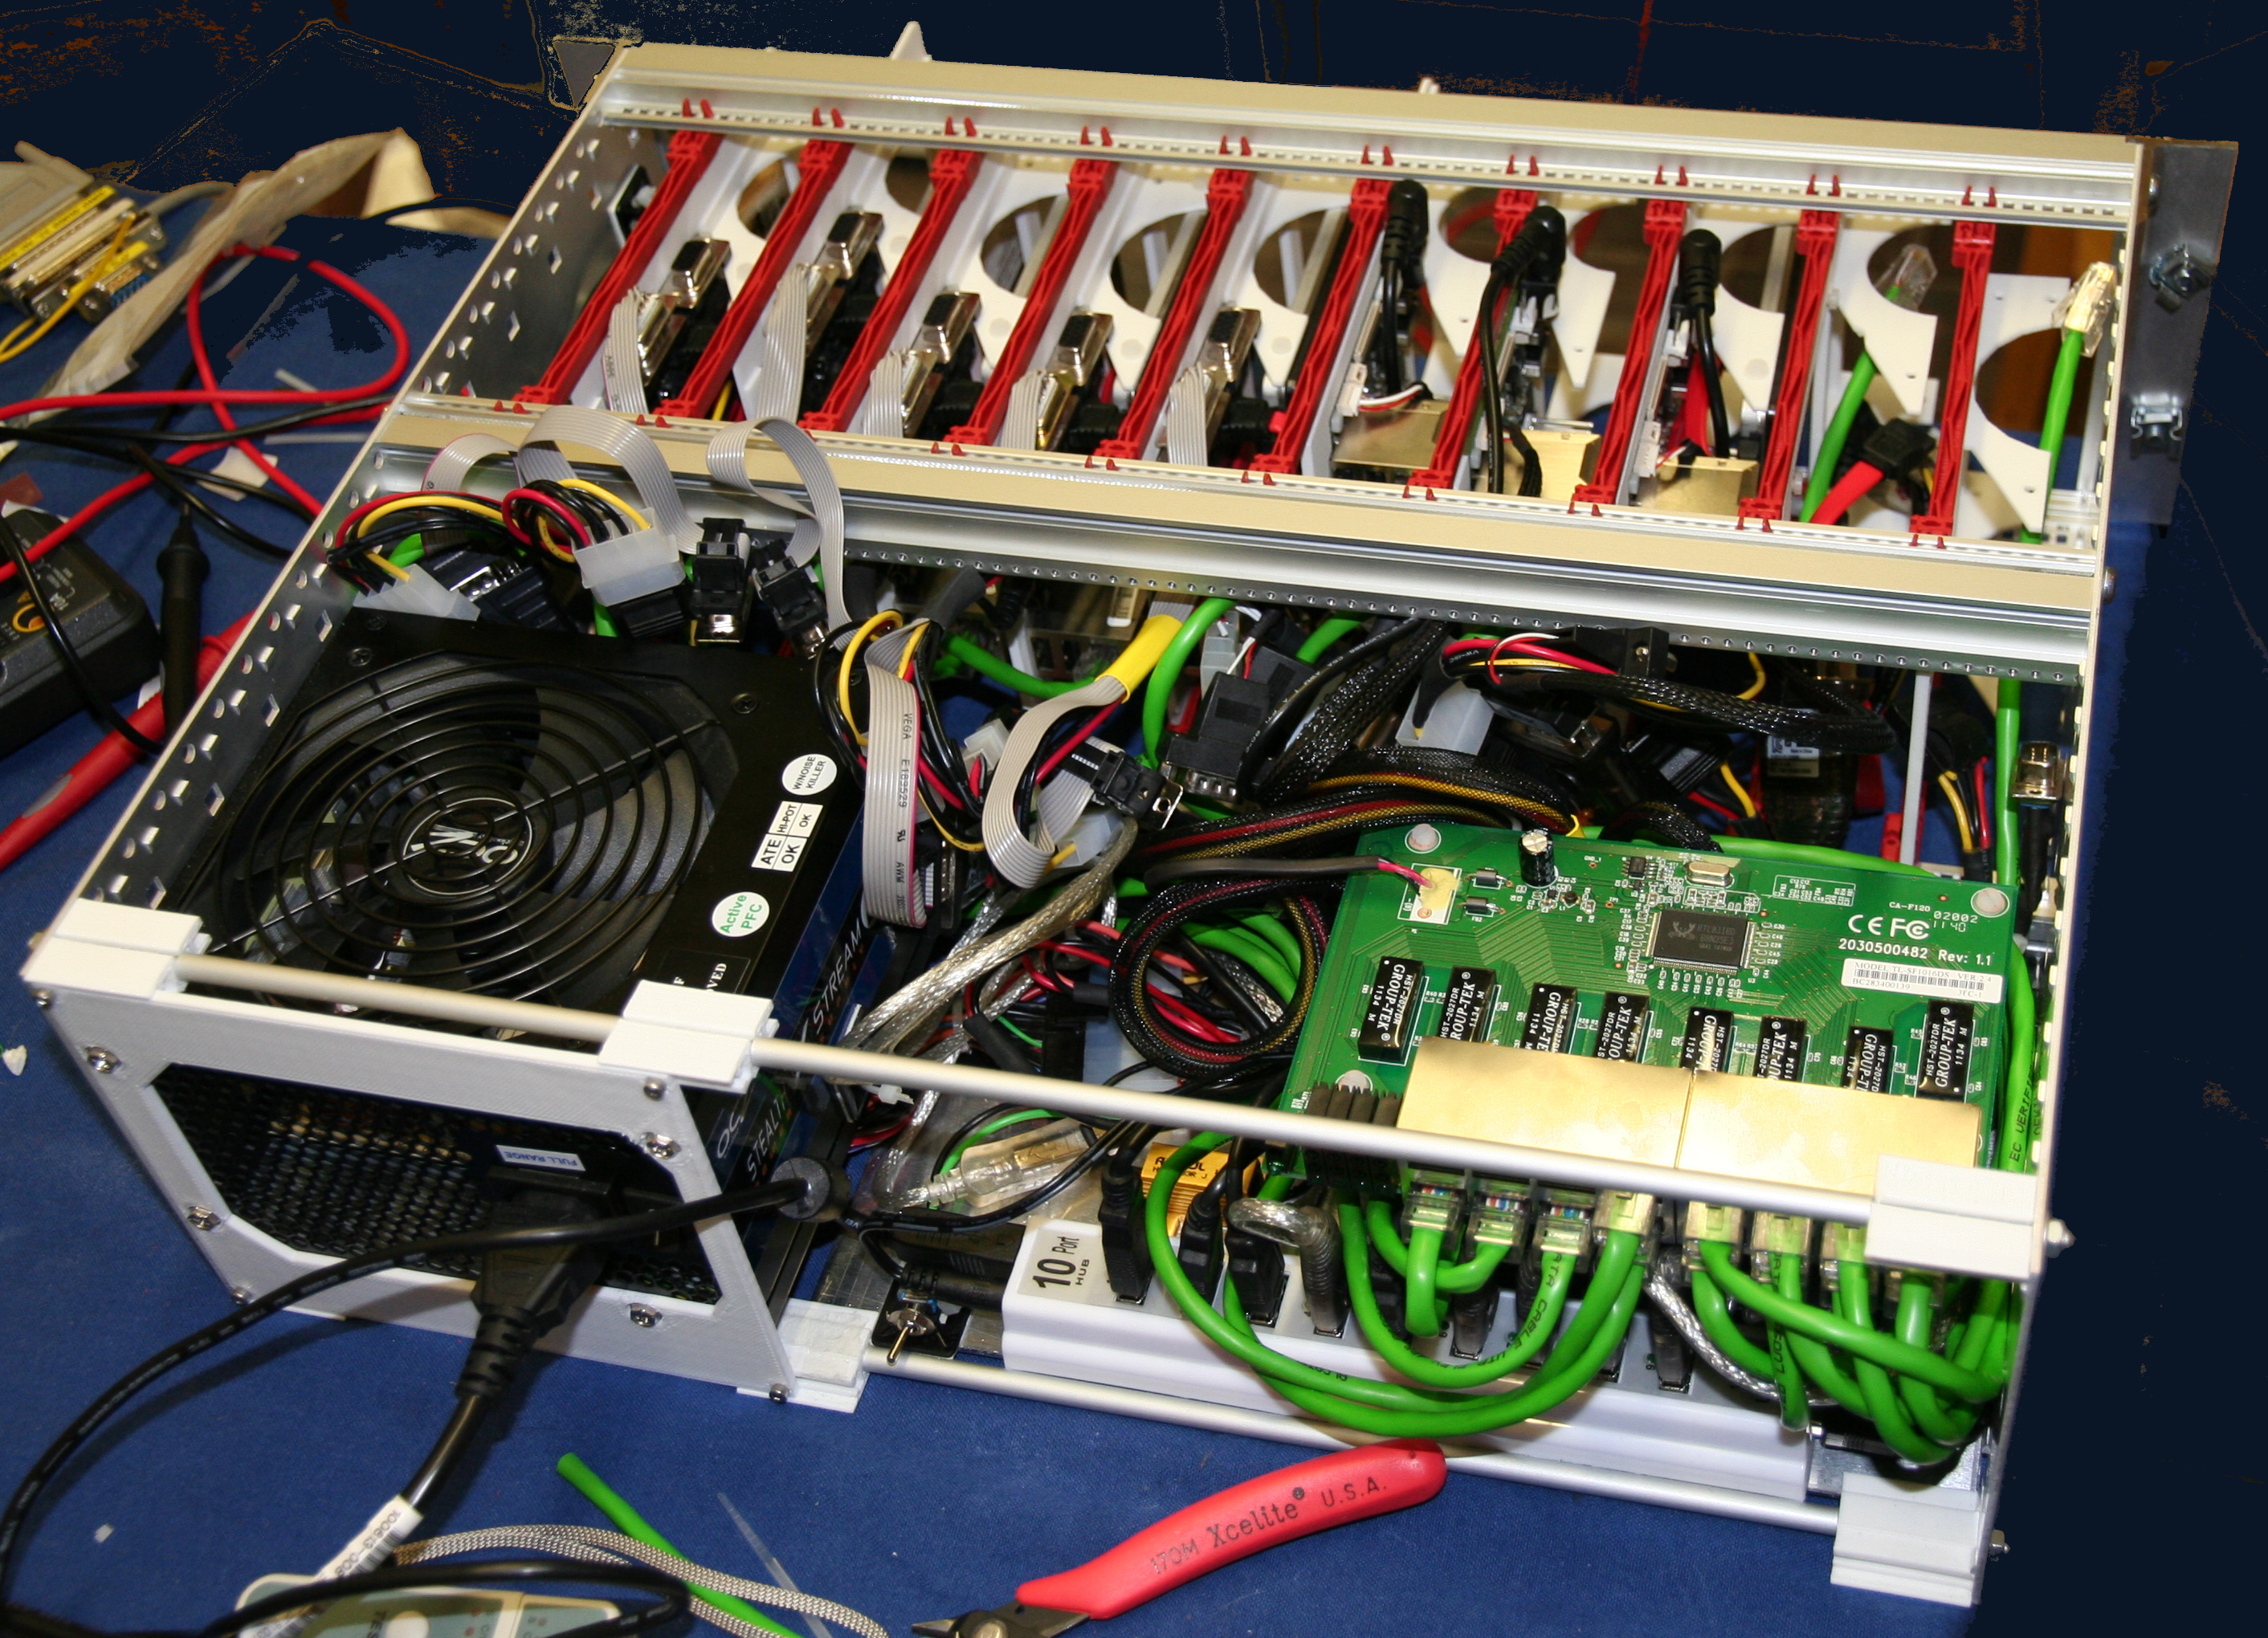
By stacking the relay boards face to face and the Ethernet switch on top separated using nylon spacers it was possible to reduce the cable clutter and provide adequate cable routing space.

A busbar for Ground (black) and unswitched 12V (yellow) was constructed from two lengths of 5A chock block.

An issue with power supply stability was noted so a load resistor was added to the 12V supply and an adhesive thermal pad used to attach it to the aluminium base plate.

Completed redesign
It was most fortunate that the ethernet switch mounting holes lined up very well with the relay board mounting holes allowing for a neat stack.

This second edition is the one currently in use, it has proved reliable in operation and has been successfully updated with additional carriers.

The outstanding issues are mainly centered around the Raspberry Pi control board:
  • Needs its carrier fitting. It is currently just stuck to the subrack end plate.
  • Needs its Ethernet cable replacing. The existing one has developed a fault post installation.
  • Needs the USB hub supply separating from the device cable. The current arrangement lets the hub power the Pi which means you cannot power cycle it.
  • Connect its switched supply separately to the USB hub/devices.
Shopping listThe final bill of materials (excluding labour and workshop costs) which might be useful to anyone hoping to build their own version.

Prices are in GBP currency converted where appropriate and include tax at 20% and delivery to Cambridge UK and were correct as of April 2013.

The purchasing was not optimised and for example around 20GBP could be saved just by ordering all the shapeways parts in one order.
Base subrack
ItemSupplierQuantityLine Price
Schroff 24563-194 subrack kitFarnell141.28
Schroff 24560-351 guide railsFarnell313.65
Schroff rack rear horizontal railShapeways2100.00
1000mm length of 4mm threaded rodB and Q11.48
170mm x 431mm x 3mm Aluminium sheetinspired steel240.00
PSU mounting plateShapeways135.42
PCB standoffShapeways422.30
160mm Deep Modular PC supplyCCL155.76
TP-Link TL-SF1016DS 16-Port 10/100Mbps-SwitchCCL123.77
8 Channel 16A Relay Board Controlled Via EthernetRapid2126.00
Raspberry PiFarnell126.48
USB Serial convertersCCL1037.40
10 port strip style USB HUBEbay17.00
Parts for custom Ethernet cablesRS1326.00
Parts for custom molex power cables (salvaged from scrap ATX PSU)Workshop1111.00
33R 10W wirewound resistor for dummy loadRS11.26
24pin ATX female connector pre-wiredMaplin12.99
Akasa double sided thermal padMaplin15.00
Small cable tie basesMaplin16.49
Miscellaneous cable, connectors, nylon standoffs, solder, heatshrink, zip ties, nuts, washers etc. Workshop120.00
Total for subrack603.28

The carriers are similarly not optimally priced as over five GBP each can be saved by combining shipping on orders alone. Also the SSD drive selection was made some time ago and a newer model may be more suitable.
i.MX53 QSB carrier
ItemSupplierQuantityLine Price
i.MX53 QSBFarnell1105.52
Intel 320 SSD 80GCCL1111.83
Carrier boardShapeways130.00
combined sata data and power (15 to 20cm version)EBay15.00
Low profile right angle 5.5mm x 2.1mm barrel jackEBay10.25
Parts for 9pin serial cable extensionRS15.00
Miscellaneous solder, heatshrink, nylon nuts, bolts and washersWorkshop15.00
Total for carrier262.60

i.MX6 SABRE Lite carrier
ItemSupplierQuantityLine Price
i.MX6 SABRE LiteFarnell1128.06
Intel 320 SSD 80GCCL1111.83
Carrier boardShapeways135.00
combined sata data and power (15 to 20cm version)EBay15.00
Low profile right angle 5.5mm x 2.1mm barrel jackEBay10.25
Parts for 9pin serial cable modificationRS12.00
Miscellaneous solder, heatshrink, nylon nuts, bolts and washersWorkshop15.00
Total for carrier287.14
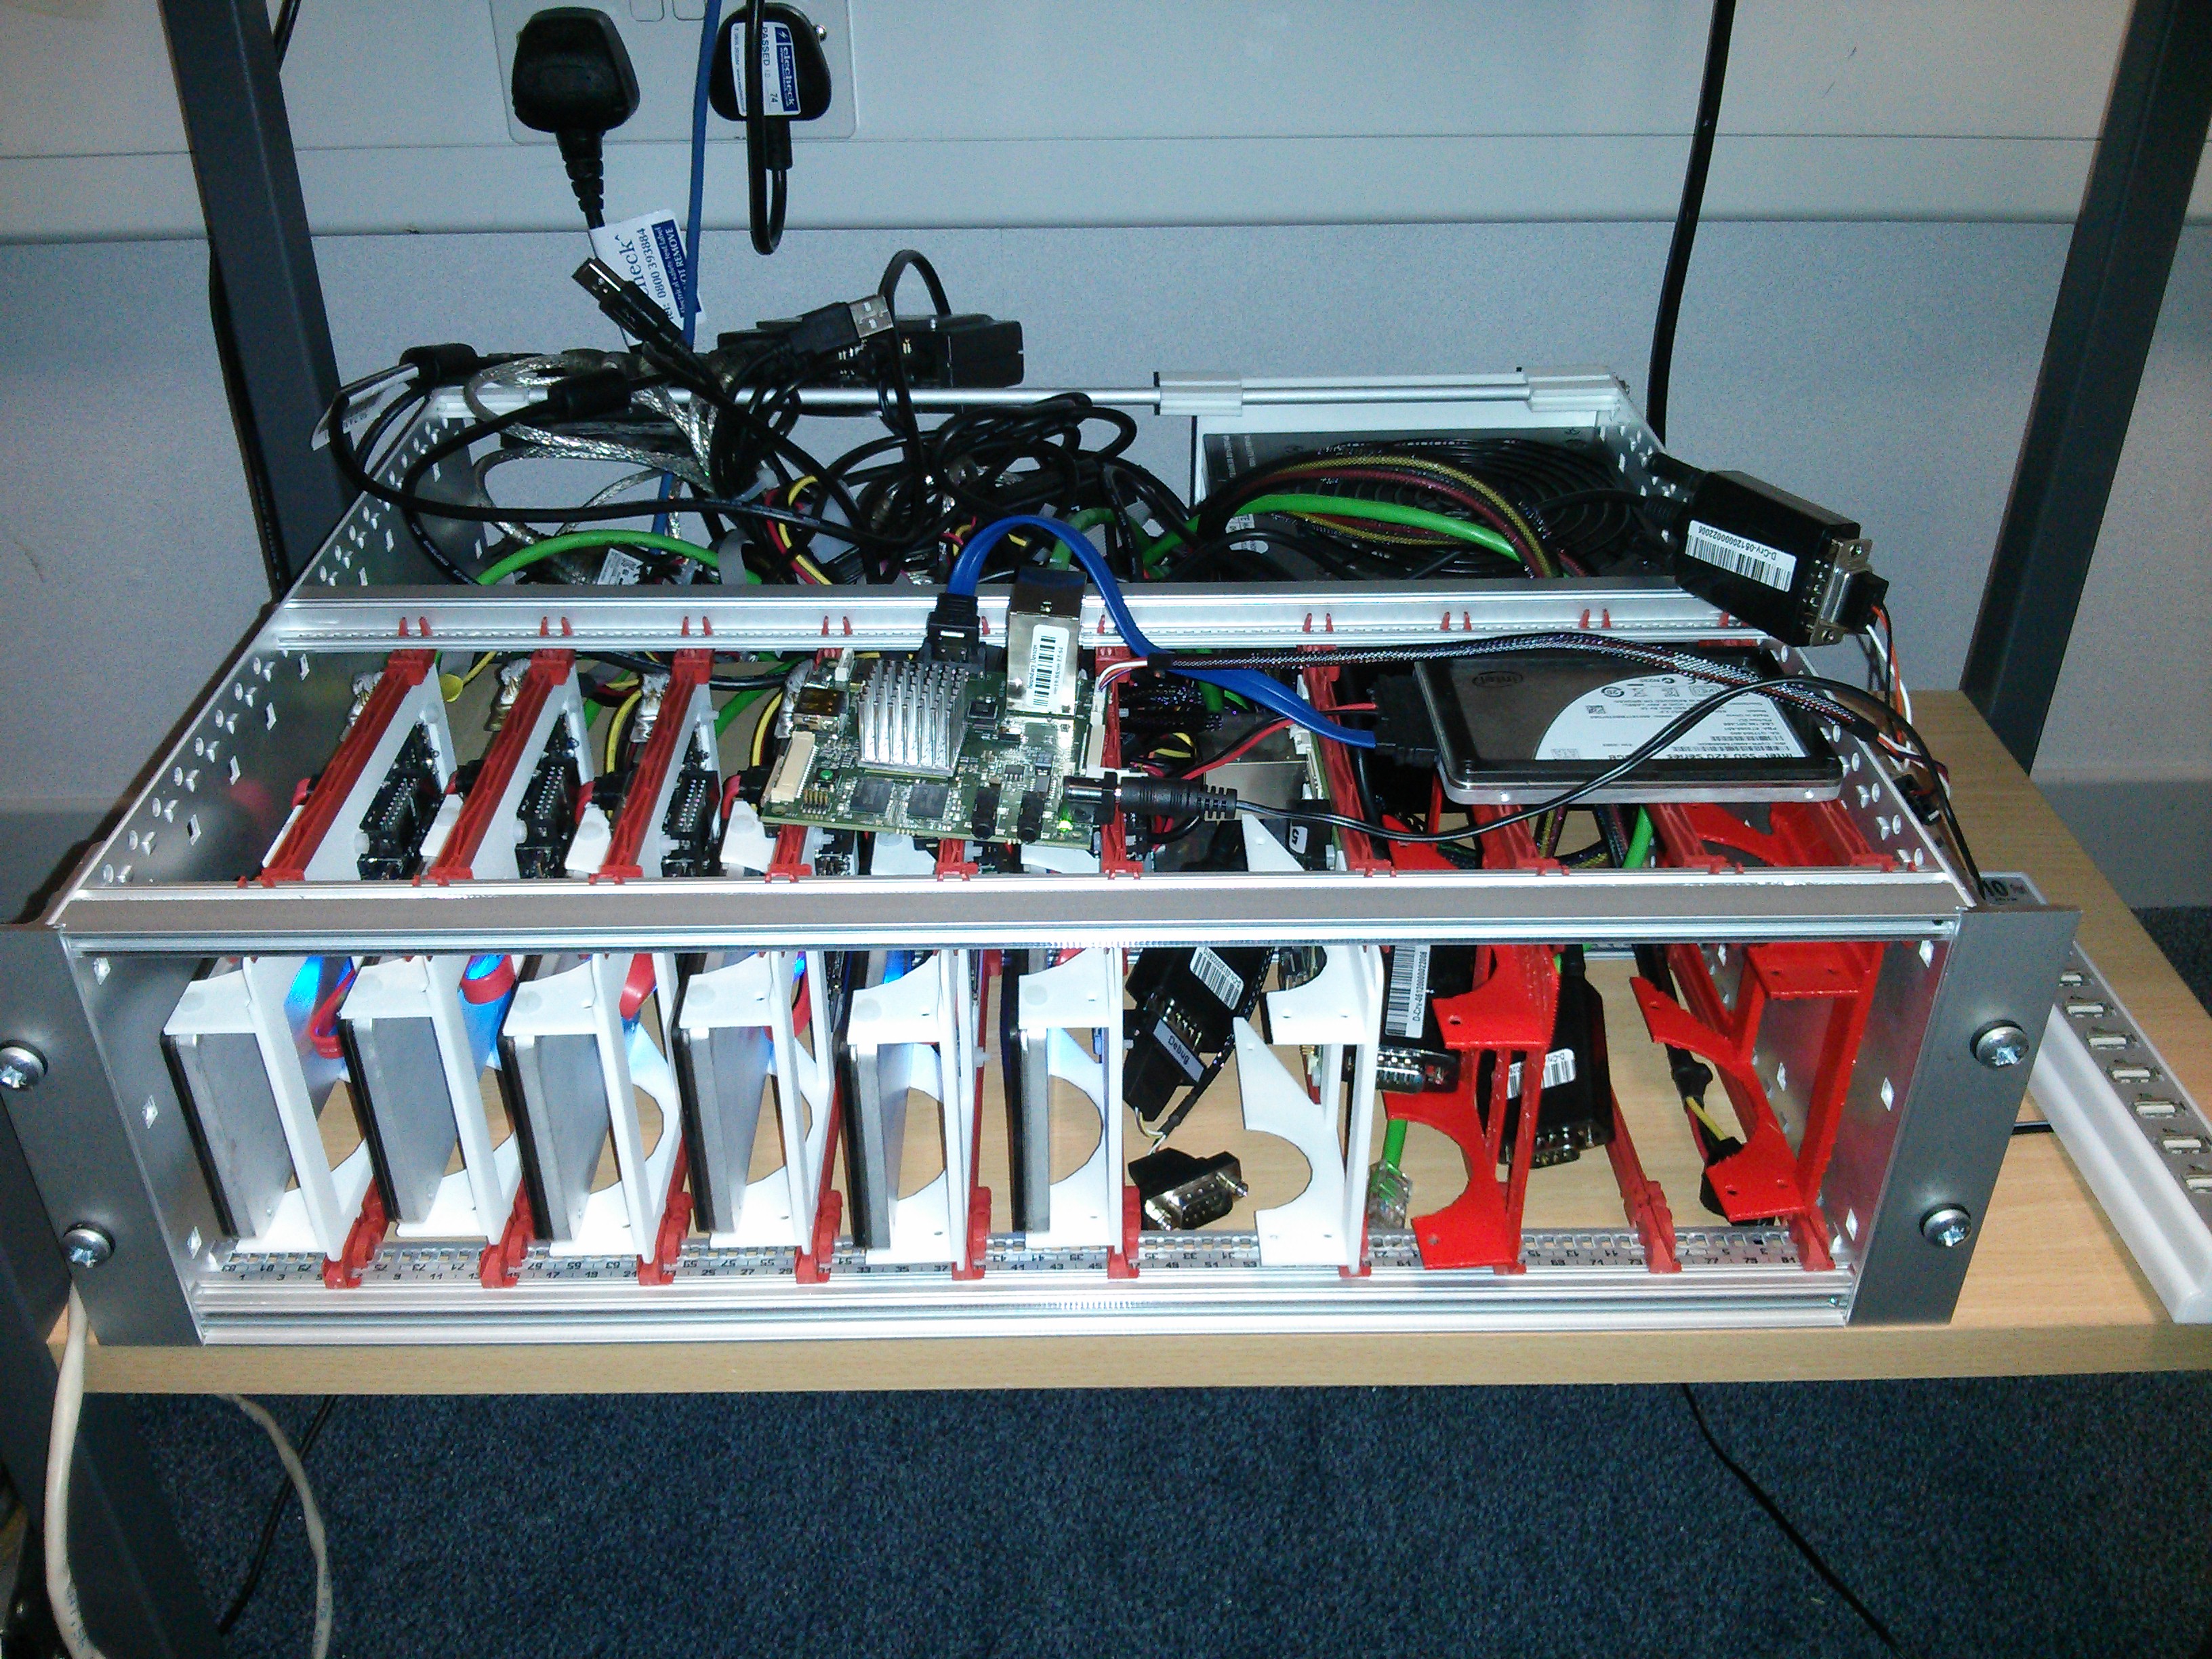
ConclusionThe solution works and in a 3U high 355mm deep subrack ten ARM development boards can be racked complete with local ethernet switching, power control and serial consoles.

Deployed system in situ configured as a build and test farm
The solution is neat and provides flexibility, density and reproducibility the "pile of stuff" solution failed to do.

For current prototype with nine filled slots the total cost was around 3000GBP or around 330GBP per slot which indicates a 100GBP per slot overhead over the "pile of stuff" solution. These figures omit the costs of the engineer and workshop time, which are estimated at an additional 1500GBP. Therefore a completed rack, fully filled with i.MX6 carriers costs around 5000GBP

Density could be increased if boards with lower height requirements were used however above twelve units there issues with Ethernet switch, power switch and USB port availability become a factor. For Example the 16 port Ethernet switch requires a port for uplink, one for each relay board and one for the console server which leaves only 12 ports for systems.

Addressing the outstanding issues would result in a much more user friendly solution. As the existing unit is in full time use and downtime is not easily scheduled for all ten systems, the issues are not likely to be fixed on the prototype and would have to be solved on a new build.

The solution is probably not suitable for turning into a product but that was not really the original aim. A commercial ARM blade server using this format would almost certainly use standard DIN connectors and a custom PCB design rather than adapting existing boards.

Ian Campbell: Generating Random MAC Addresses

Working with virtualisation I find myself occasionally needing to generate a random MAC address for use with a virtual machine. I have a stupid little local script which spits one out, which is all fine and dandy for my purposes. However this week one of my colleagues was writing a wiki page and needed to include instructions on how to set the MAC address on the Arndale board. He wanted to include a shell snippet to generate one and I suggested that there must be websites which will generate you a suitable address. But when I came to look we found that not a single one of the half a dozen site which I looked at handled the locally administered or multicast bits correctly, meaning that they would randomly generate either multicast addresses or addresses using assigned OUI (or both). Using a random OUI may not cause too much trouble in practice but using a multicast address is sure to lead to strange behaviour, and in any case it's kind of lame. So last night I sat down and wrote a quick hack cgi script to generate random addresses and tonight I deployed it at: http://www.hellion.org.uk/cgi-bin/randmac.pl. This is where the world and his dog leaves a comment pointing me to the existing service my searches missed...

Francesca Ciceri: And the winner is...

I totally forgot it, but as the DPL elections are now done, we have a winner for the #DPL game. Of the (more or less) fifteen persons who participated to the game (thank you!), only four received points for having at least one of their Fantastic Four running for DPL: As Lucas is now the new DPL, our one and only winner of the DPL game is... ... Mehdi Dogguy! Congrats!

Lior Kaplan: The commit police: learning for recent reference mistakes

Continuing the previous post about commits and bugs, I d like to review some mistakes I saw recently. Mistakes do happen, but mentioning them here is meant to teach others and hopefully to reduce similar ones in the future. This post isn t about shaming the authors/commiters. Also, the points I highlight are what I consider as a mistakes or problems, other people might think differently.
  1. Mentioning two bugs in one commit message, which our system doesn t support right now. So the second bug doesn t get the commit notification, and that should be done manually (example: commit 2933935 and fdo#53278).
  2. Referencing gerrit changes as part of the commit message (example: commit 87f185d). Giving references as part of the commit is great and helpful, but I would prefer to see the reference to the actual commit and not to its review process. This is meaningful when you search the log. If the followup change is suggested when the first change is still in review it should be combined, otherwise it already have a commit to reference.
  3. Following up a commit, and not mentioning the bug it references (example: commit 87f185d). In this specific case, the we re talking about a meta bug for translating comments from German to English (fdo#39468), so no harm done. But this important when you want to cherry pick a fix for a bug to other branches and might forget the follow up commits. It s also relevant to more technical meta bugs (example: fdo#62096).
  4. Referencing a mailing list which reference a commit and a bug instead of referencing them directly (commit 21fea27, fdo#60534). This bug shows very well why correct referencing is important, a commit was made to fix the bug, a follow up commit was done without proper reference, and than the first commit was reverted. No one involved in trying to fix that specific bug knew about the follow up commit as it wasn t documented anywhere.
  5. Referencing bugs though full bug URL instead of the right format (example: commit e1f6dac). Also the bug is referenced in the commit in the body of the message instead of the first line (header) which is more visible.
  6. Referencing non existing bugs (example: commit 3a4534b). Which got a manual notification in the bug by the comitter (fdo#33091).
  7. Using shortening services URL as part of commit messages (example: commit 86f8fba). There s no way to know to what the reference is without using the service, which in this case was leading to a post on one of the projects mailing list. There isn t any problem giving the direct URL to the list s archive. It s interesting whether we should link to our URL and is it OK to use other external services who also archive our mailing lists (example: commit e83990a).
To conclude, having references in commit message is really helpful, but please reference the right resource to help people find it easily and to let our automated services parse it.
Filed under: LibreOffice

25 April 2013

David Bremner: Exporting Debian packaging patches from git, (redux)*

(Debian) packaging and Git. The big picture is as follows. In my view, the most natural way to work on a packaging project in version control [1] is to have an upstream branch which either tracks upstream Git/Hg/Svn, or imports of tarballs (or some combination thereof, and a Debian branch where both modifications to upstream source and commits to stuff in ./debian are added [2]. Deviations from this are mainly motivated by a desire to export source packages, a version control neutral interchange format that still preserves the distinction between upstream source and distro modifications. Of course, if you're happy with the distro modifications as one big diff, then you can stop reading now gitpkg $debian_branch $upstream_branch and you're done. The other easy case is if your changes don't touch upstream; then 3.0 (quilt) packages work nicely with ./debian in a separate tarball. So the tension is between my preferred integration style, and making source packages with changes to upstream source organized in some nice way, preferably in logical patches like, uh, commits in a version control system. At some point we may be able use some form of version control repo as a source package, but the issues with that are for another blog post. At the moment then we are stuck with trying bridge the gap between a git repository and a 3.0 (quilt) source package. If you don't know the details of Debian packaging, just imagine a patch series like you would generate with git format-patch or apply with (surprise) quilt. From Git to Quilt. The most obvious (and the most common) way to bridge the gap between git and quilt is to export patches manually (or using a helper like gbp-pq) and commit them to the packaging repository. This has the advantage of not forcing anyone to use git or specialized helpers to collaborate on the package. On the other hand it's quite far from the vision of using git (or your favourite VCS) to do the integration that I started with. The next level of sophistication is to maintain a branch of upstream-modifying commits. Roughly speaking, this is the approach taken by git-dpm, by gitpkg, and with some additional friction from manually importing and exporting the patches, by gbp-pq. There are some issues with rebasing a branch of patches, mainly it seems to rely on one person at a time working on the patch branch, and it forces the use of specialized tools or workflows. Nonetheless, both git-dpm and gitpkg support this mode of working reasonably well [3]. Lately I've been working on exporting patches from (an immutable) git history. My initial experiments with marking commits with git notes more or less worked [4]. I put this on the back-burner for two reasons, first sharing git notes is still not very well supported by git itself [5], and second Gitpkg maintainer Ron Lee convinced me to automagically pick out what patches to export. Ron's motivation (as I understand it) is to have tools which work on any git repository without extra metadata in the form of notes. Linearizing History on the fly. After a few iterations, I arrived at the following specification. Condition (4) suggests we want something roughly like git format-patch upstream..head, removing those patches which are only about Debian packaging. Because of (3), we have to be a bit careful about commits that touch upstream and ./debian. We also want to avoid outputting patches that have been applied (or worse partially applied) upstream. git patch-id can help identify cherry-picked patches, but not partial application. Eventually I arrived at the following strategy.
  1. Use git-filter-branch to construct a copy of the history upstream..head with ./debian (and for technical reasons .pc) excised.
  2. Filter these commits to remove e.g. those that are present exactly upstream, or those that introduces no changes, or changes unrepresentable in a patch.
  3. Try to revert the remaining commits, in reverse order. The idea here is twofold. First, a patch that occurs twice in history because of merging will only revert the most recent one, allowing earlier copies to be skipped. Second, the state of the temporary branch after all successful reverts represents the difference from upstream not accounted for by any patch.
  4. Generate a "fixup patch" accounting for any remaining differences, to be applied before any if the "nice" patches.
  5. Cherry-pick each "nice" patch on top of the fixup patch, to ensure we have a linear history that can be exported to quilt. If any of these cherry-picks fail, abort the export.
Yep, it seems over-complicated to me too. TL;DR: Show me the code. You can clone my current version from
git://pivot.cs.unb.ca/gitpkg.git
This provides a script "git-debcherry" which does the history linearization discussed above. In order to test out how/if this works in your repository, you could run
git-debcherry --stat $UPSTREAM
For actual use, you probably want to use something like
git-debcherry -o debian/patches
There is a hook in hooks/debcherry-deb-export-hook that does this at source package export time. I'm aware this is not that fast; it does several expensive operations. On the other hand, you know what Don Knuth says about premature optimization, so I'm more interested in reports of when it does and doesn't work. In addition to crashing, generating multi-megabyte "fixup patch" probably counts as failure. Notes
  1. This first part doesn't seem too Debian or git specific to me, but I don't know much concrete about other packaging workflows or other version control systems.
  2. Another variation is to have a patched upstream branch and merge that into the Debian packaging branch. The trade-off here that you can simplify the patch export process a bit, but the repo needs to have taken this disciplined approach from the beginning.
  3. git-dpm merges the patched upstream into the Debian branch. This makes the history a bit messier, but seems to be more robust. I've been thinking about trying this out (semi-manually) for gitpkg.
  4. See e.g. exporting. Although I did not then know the many surprising and horrible things people do in packaging histories, so it probably didn't work as well as I thought it did.
  5. It's doable, but one ends up spending about a bunch lines of code on duplicating basic git functionality; e.g. there is no real support for tags of notes.
  6. Since as far as I know quilt has no way of deleting files except to list the content, this means in particular exporting upstream should yield a DFSG Free source tree.

Next.

Previous.