Search Results: "xam"

12 November 2024

Paul Tagliamonte: Complex for Whom?

In basically every engineering organization I ve ever regarded as particularly high functioning, I ve sat through one specific recurring conversation which is not a conversation about complexity . Things are good or bad because they are or aren t complex, architectures needs to be redone because it s too complex some refactor of whatever it is won t work because it s too complex. You may have even been a part of some of these conversations or even been the one advocating for simple light-weight solutions. I ve done it. Many times. Rarely, if ever, do we talk about complexity within its rightful context complexity for whom. Is a solution complex because it s complex for the end user? Is it complex if it s complex for an API consumer? Is it complex if it s complex for the person maintaining the API service? Is it complex if it s complex for someone outside the team maintaining it to understand? Complexity within a problem domain I ve come to believe, is fairly zero-sum there s a fixed amount of complexity in the problem to be solved, and you can choose to either solve it, or leave it for those downstream of you to solve that problem on their own. That being said, while I believe there is a lower bound in complexity to contend with for a problem, I do not believe there is an upper bound to the complexity of solutions possible. It is always possible, and in fact, very likely that teams create problems for themselves while trying to solve a problem. The rest of this post is talking to the lower bound. When getting feedback on an early draft of this blog post, I ve been informed that Fred Brooks coined a term for what I call lower bound complexity Essential Complexity , in the paper No Silver Bullet Essence and Accident in Software Engineering , which is a better term and can be used interchangeably.

Complexity Culture In a large enough organization, where the team is high functioning enough to have and maintain trust amongst peers, members of the team will specialize. People will begin to engage with subsets of the work to be done, and begin to have their efficacy measured against that part of the organization s problems. Incentives shift, and over time it becomes increasingly likely that two engineers may have two very different priorities when working on the same system together. Someone accountable for uptime and tasked with responding to outages will begin to resist changes. Someone accountable for rapidly delivering features will resist gates between them and their users. Companies (either wittingly or unwittingly) will deal with this by tasking engineers with both production (feature development) and operational tasks (maintenance), so the difference in incentives isn t usually as bad as it could be. When we get a bunch of folks from far-flung corners of an organization in a room, fire up a slide deck and throw up some aspirational to-be architecture diagram in order to get a sign-off to solve some problem (be it someone needs a credible promotion packet, new feature needs to get delivered, or the system has begun to fail and needs fixing), the initial reaction will, more often than I d like, start to devolve into a discussion of how this is going to introduce a bunch of complexity, going to be hard to maintain, why can t you make it less complex? Right around here is when I start to try and contextualize the conversation happening around me understand what complexity is that being discussed, and understand who is taking on that burden. Think about who should be owning that problem, and work through the tradeoffs involved. Is it best solved here, or left to consumers (be them other systems, developers, or users). Should something become an API call s optional param, taking on all the edge-cases and on, or should users have to implement the logic using the data you return (leaving everyone else to take on all the edge-cases and maintenance)? Should you process the data, or require the user to preprocess it for you? Frequently it s right to make an active and explicit decision to simplify and leave problems to be solved downstream, since they may not actually need to be solved or perhaps you expect consumers will want to own the specifics of how the problem is solved, in which case you leave lots of documentation and examples. Many other times, especially when it s something downstream consumers are likely to hit, it s best solved internal to the system, since the only thing that can come of leaving it unsolved are bugs, frustration and half-correct solutions. This is a grey-space of tradeoffs, not a clear decision tree. No one wants the software manifestation of a katamari ball or a junk drawer, nor does anyone want a half-baked service unable to handle the simplest use-case.

Head-in-sand as a Service Popoffs about how complex something is, are, to a first approximation, best understood as meaning complicated for the person making comments . A lot of the #thoughtleadership believe that an AWS hosted EKS k8s cluster running images built by CI talking to an AWS hosted PostgreSQL RDS is not complex. They re right. Mostly right. This is less complex less complex for them. It s not, however, without complexity and its own tradeoffs it s just complexity that they do not have to deal with. Now they don t have to maintain machines that have pesky operating systems or hard drive failures. They don t have to deal with updating the version of k8s, nor ensuring the backups work. No one has to push some artifact to prod manually. Deployments happen unattended. You click a button and get a cluster. On the other hand, developers outside the ops function need to deal with troubleshooting CI, debugging access control rules encoded in turing complete YAML, permissions issues inside the cluster due to whatever the fuck a service mesh is, everyone needs to learn how to use some k8s tools they only actually use during a bad day, likely while doing some x.509 troubleshooting to connect to the cluster (an internal only endpoint; just port forward it) not to mention all sorts of rules to route packets to their project (a single repo s binary being run in 3 containers on a single vm host). Beyond that, there s the invisible complexity complexity on the interior of a service you depend on. I think about the dozens of teams maintaining the EKS service (which is either run on EC2 instances, or alternately, EC2 instances in a trench coat, moustache and even more shell scripts), the RDS service (also EC2 and shell scripts, but this time accounting for redundancy, backups, availability zones), scores of hypervisors pulled off the shelf (xen, kvm) smashed together with the ones built in-house (firecracker, nitro, etc) running on hardware that has to be refreshed and maintained continuously. Every request processed by network ACL rules, AWS IAM rules, security group rules, using IP space announced to the internet wired through IXPs directly into ISPs. I don t even want to begin to think about the complexity inherent in how those switches are designed. Shitloads of complexity to solve problems you may or may not have, or even know you had. What s more complex? An app running in an in-house 4u server racked in the office s telco closet in the back running off the office Verizon line, or an app running four hypervisors deep in an AWS datacenter? Which is more complex to you? What about to your organization? In total? Which is more prone to failure? Which is more secure? Is the complexity good or bad? What type of Complexity can you manage effectively? Which threaten the system? Which threaten your users?

COMPLEXIVIBES This extends beyond Engineering. Decisions regarding what tools are we able to use be them existing contracts with cloud providers, CIO mandated SaaS products, a list of the only permissible open source projects will incur costs in terms of expressed complexity . Pinning open source projects to a fixed set makes SBOM production less complex . Using only one SaaS provider s product suite (even if its terrible, because it has all the types of tools you need) makes accreditation less complex . If all you have is a contract with Pauly T s lowest price technically acceptable artisinal cloudary and haberdashery, the way you pay for your compute is less complex for the CIO shop, though you will find yourself building your own hosted database template, mechanism to spin up a k8s cluster, and all the operational and technical burden that comes with it. Or you won t and make it everyone else s problem in the organization. Nothing you can do will solve for the fact that you must now deal with this problem somewhere because it was less complicated for the business to put the workloads on the existing contract with a cut-rate vendor. Suddenly, the decision to reduce complexity because of an existing contract vehicle has resulted in a huge amount of technical risk and maintenance burden being onboarded. Complexity you would otherwise externalize has now been taken on internally. With a large enough organizations (specifically, in this case, i m talking about you, bureaucracies), this is largely ignored or accepted as normal since the personnel cost is understood to be free to everyone involved. Doing it this way is more expensive, more work, less reliable and less maintainable, and yet, somehow, is, in a lot of ways, less complex to the organization. It s particularly bad with bureaucracies, since screwing up a contract will get you into much more trouble than delivering a broken product, leaving basically no reason for anyone to care to fix this. I can t shake the feeling that for every story of technical mandates gone awry, somewhere just out of sight there s a decisionmaker optimizing for what they believe to be the least amount of complexity least hassle, fewest unique cases, most consistency as they can. They freely offload complexity from their accreditation and risk acceptance functions through mandates. They will never have to deal with it. That does not change the fact that someone does.

TC;DR (TOO COMPLEX; DIDN T REVIEW) We wish to rid ourselves of systemic Complexity after all, complexity is bad, simplicity is good. Removing upper-bound own-goal complexity ( accidental complexity in Brooks s terms) is important, but once you hit the lower bound complexity, the tradeoffs become zero-sum. Removing complexity from one part of the system means that somewhere else maybe outside your organization or in a non-engineering function must grow it back. Sometimes, the opposite is the case, such as when a previously manual business processes is automated. Maybe that s a good idea. Maybe it s not. All I know is that what doesn t help the situation is conflating complexity with everything we don t like legacy code, maintenance burden or toil, cost, delivery velocity.
  • Complexity is not the same as proclivity to failure. The most reliable systems I ve interacted with are unimaginably complex, with layers of internal protection to prevent complete failure. This has its own set of costs which other people have written about extensively.
  • Complexity is not cost. Sometimes the cost of taking all the complexity in-house is less, for whatever value of cost you choose to use.
  • Complexity is not absolute. Something simple from one perspective may be wildly complex from another. The impulse to burn down complex sections of code is helpful to have generally, but sometimes things are complicated for a reason, even if that reason exists outside your codebase or organization.
  • Complexity is not something you can remove without introducing complexity elsewhere. Just as not making a decision is a decision itself; choosing to require someone else to deal with a problem rather than dealing with it internally is a choice that needs to be considered in its full context.
Next time you re sitting through a discussion and someone starts to talk about all the complexity about to be introduced, I want to pop up in the back of your head, politely asking what does complex mean in this context? Is it lower bound complexity? Is this complexity desirable? Is what they re saying mean something along the lines of I don t understand the problems being solved, or does it mean something along the lines of this problem should be solved elsewhere? Do they believe this will result in more work for them in a way that you don t see? Should this not solved at all by changing the bounds of what we should accept or redefine the understood limits of this system? Is the perceived complexity a result of a decision elsewhere? Who s taking this complexity on, or more to the point, is failing to address complexity required by the problem leaving it to others? Does it impact others? How specifically? What are you not seeing? What can change? What should change?

11 November 2024

Vincent Bernat: Customize Caddy's plugins with Nix

Caddy is an open-source web server written in Go. It handles TLS certificates automatically and comes with a simple configuration syntax. Users can extend its functionality through plugins1 to add features like rate limiting, caching, and Docker integration. While Caddy is available in Nixpkgs, adding extra plugins is not simple.2 The compilation process needs Internet access, which Nix denies during build to ensure reproducibility. When trying to build the following derivation using xcaddy, a tool for building Caddy with plugins, it fails with this error: dial tcp: lookup proxy.golang.org on [::1]:53: connection refused.
  pkgs  :
pkgs.stdenv.mkDerivation  
  name = "caddy-with-xcaddy";
  nativeBuildInputs = with pkgs; [ go xcaddy cacert ];
  unpackPhase = "true";
  buildPhase =
    ''
      xcaddy build --with github.com/caddy-dns/powerdns@v1.0.1
    '';
  installPhase = ''
    mkdir -p $out/bin
    cp caddy $out/bin
  '';
 
Fixed-output derivations are an exception to this rule and get network access during build. They need to specify their output hash. For example, the fetchurl function produces a fixed-output derivation:
  stdenv, fetchurl  :
stdenv.mkDerivation rec  
  pname = "hello";
  version = "2.12.1";
  src = fetchurl  
    url = "mirror://gnu/hello/hello-$ version .tar.gz";
    hash = "sha256-jZkUKv2SV28wsM18tCqNxoCZmLxdYH2Idh9RLibH2yA=";
   ;
 
To create a fixed-output derivation, you need to set the outputHash attribute. The example below shows how to output Caddy s source code, with some plugin enabled, as a fixed-output derivation using xcaddy and go mod vendor.
pkgs.stdenvNoCC.mkDerivation rec  
  pname = "caddy-src-with-xcaddy";
  version = "2.8.4";
  nativeBuildInputs = with pkgs; [ go xcaddy cacert ];
  unpackPhase = "true";
  buildPhase =
    ''
      export GOCACHE=$TMPDIR/go-cache
      export GOPATH="$TMPDIR/go"
      XCADDY_SKIP_BUILD=1 TMPDIR="$PWD" \
        xcaddy build v$ version  --with github.com/caddy-dns/powerdns@v1.0.1
      (cd buildenv* && go mod vendor)
    '';
  installPhase = ''
    mv buildenv* $out
  '';
  outputHash = "sha256-F/jqR4iEsklJFycTjSaW8B/V3iTGqqGOzwYBUXxRKrc=";
  outputHashAlgo = "sha256";
  outputHashMode = "recursive";
 
With a fixed-output derivation, it is up to us to ensure the output is always the same: You can use this derivation to override the src attribute in pkgs.caddy:
pkgs.caddy.overrideAttrs (prev:  
  src = pkgs.stdenvNoCC.mkDerivation   /* ... */  ;
  vendorHash = null;
  subPackages = [ "." ];
 );
Check out the complete example in the GitHub repository. To integrate into a Flake, add github:vincentbernat/caddy-nix as an overlay:
 
  inputs =  
    nixpkgs.url = "nixpkgs";
    flake-utils.url = "github:numtide/flake-utils";
    caddy.url = "github:vincentbernat/caddy-nix";
   ;
  outputs =   self, nixpkgs, flake-utils, caddy  :
    flake-utils.lib.eachDefaultSystem (system:
      let
        pkgs = import nixpkgs  
          inherit system;
          overlays = [ caddy.overlays.default ];
         ;
      in
       
        packages =  
          default = pkgs.caddy.withPlugins  
            plugins = [ "github.com/caddy-dns/powerdns@v1.0.1" ];
            hash = "sha256-F/jqR4iEsklJFycTjSaW8B/V3iTGqqGOzwYBUXxRKrc=";
           ;
         ;
       );
 

Update (2024-11) This flake won t work with Nixpkgs 24.05 or older because it relies on this commit to properly override the vendorHash attribute.


  1. This article uses the term plugins, though Caddy documentation also refers to them as modules since they are implemented as Go modules.
  2. This is a feature request since quite some time. A proposed solution has been rejected. The one described in this article is a bit different and I have proposed it in another pull request.
  3. This is not perfect: if the source code produced by xcaddy changes, the hash would change and the build would fail.

10 November 2024

Dirk Eddelbuettel: inline 0.3.20: Mostly Maintenance

A new release of the inline package got to CRAN today marking the first release in three and half years. inline facilitates writing code in-line in simple string expressions or short files. The package was used quite extensively by Rcpp in the very early days before Rcpp Attributes arrived on the scene providing an even better alternative for its use cases. inline is still used by rstan and a number of other packages. This release was tickled by changing in r-devel just this week, and the corresponding please fix or else email I received this morning. R_NO_REMAP is now the default in r-devel, and while we had already converted most (old-style) calls into the API to using the now mandatory Rf_ prefix, the package contained few remaining cases in examples as well as one in code generation. The release also contains a helpful contributed PR making an error message a little clearer, plus several small and common maintenance changed around continuous integration, package layout and the repository. The NEWS extract follows and details the changes some more.

Changes in inline version 0.3.20 (2024-11-10)
  • Error message formatting is improved for compileCode (Alexis Derumigny in #25)
  • Switch to using Authors@R, other general packaging maintenance for continuous integration and repository
  • Use Rf_ in a handful of cases as R-devel now mandates it

Thanks to my CRANberries, you can also look at a diff to the previous release Questions, comments etc should go to the rcpp-devel mailing list off the R-Forge page. Bugs reports are welcome at the GitHub issue tracker as well (where one can also search among open or closed issues). If you like this or other open-source work I do, you can sponsor me at GitHub.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

Reproducible Builds: Reproducible Builds in October 2024

Welcome to the October 2024 report from the Reproducible Builds project. Our reports attempt to outline what we ve been up to over the past month, highlighting news items from elsewhere in tech where they are related. As ever, if you are interested in contributing to the project, please visit our Contribute page on our website. Table of contents:
  1. Beyond bitwise equality for Reproducible Builds?
  2. Two Ways to Trustworthy at SeaGL 2024
  3. Number of cores affected Android compiler output
  4. On our mailing list
  5. diffoscope
  6. IzzyOnDroid passed 25% reproducible apps
  7. Distribution work
  8. Website updates
  9. Reproducibility testing framework
  10. Supply-chain security at Open Source Summit EU
  11. Upstream patches

Beyond bitwise equality for Reproducible Builds? Jens Dietrich, Tim White, of Victoria University of Wellington, New Zealand along with Behnaz Hassanshahi and Paddy Krishnan of Oracle Labs Australia published a paper entitled Levels of Binary Equivalence for the Comparison of Binaries from Alternative Builds :
The availability of multiple binaries built from the same sources creates new challenges and opportunities, and raises questions such as: Does build A confirm the integrity of build B? or Can build A reveal a compromised build B? . To answer such questions requires a notion of equivalence between binaries. We demonstrate that the obvious approach based on bitwise equality has significant shortcomings in practice, and that there is value in opting for alternative notions. We conceptualise this by introducing levels of equivalence, inspired by clone detection types.
A PDF of the paper is freely available.

Two Ways to Trustworthy at SeaGL 2024 On Friday 8th November, Vagrant Cascadian will present a talk entitled Two Ways to Trustworthy at SeaGL in Seattle, WA. Founded in 2013, SeaGL is a free, grassroots technical summit dedicated to spreading awareness and knowledge about free source software, hardware and culture. Vagrant s talk:
[ ] delves into how two project[s] approaches fundamental security features through Reproducible Builds, Bootstrappable Builds, code auditability, etc. to improve trustworthiness, allowing independent verification; trustworthy projects require little to no trust. Exploring the challenges that each project faces due to very different technical architectures, but also contextually relevant social structure, adoption patterns, and organizational history should provide a good backdrop to understand how different approaches to security might evolve, with real-world merits and downsides.

Number of cores affected Android compiler output Fay Stegerman wrote that the cause of the Android toolchain bug from September s report that she reported to the Android issue tracker has been found and the bug has been fixed.
the D8 Java to DEX compiler (part of the Android toolchain) eliminated a redundant field load if running the class s static initialiser was known to be free of side effects, which ended up accidentally depending on the sharding of the input, which is dependent on the number of CPU cores used during the build.
To make it easier to understand the bug and the patch, Fay also made a small example to illustrate when and why the optimisation involved is valid.

On our mailing list On our mailing list this month:

diffoscope diffoscope is our in-depth and content-aware diff utility that can locate and diagnose reproducibility issues. This month, Chris Lamb made the following changes, including preparing and uploading versions 279, 280, 281 and 282 to Debian:
  • Ignore errors when listing .ar archives (#1085257). [ ]
  • Don t try and test with systemd-ukify in the Debian stable distribution. [ ]
  • Drop Depends on the deprecated python3-pkg-resources (#1083362). [ ]
In addition, Jelle van der Waa added support for Unified Kernel Image (UKI) files. [ ][ ][ ] Furthermore, Vagrant Cascadian updated diffoscope in GNU Guix to version 282. [ ][ ]

IzzyOnDroid passed 25% reproducible apps The IzzyOnDroid project has reached a good milestone by reaching over 25% of the ~1,200 Android apps provided by their repository (of official APKs built by the original application developers) having been confirmed to be reproducible by a rebuilder.

Distribution work In Debian this month:
  • Holger Levsen uploaded devscripts version 2.24.2, including many changes to the debootsnap, debrebuild and reproducible-check scripts. This is the first time that debrebuild actually works (using sbuild s unshare backend). As part of this, Holger also fixed an issue in the reproducible-check script where a typo in the code led to incorrect results [ ]
  • Recently, a news entry was added to snapshot.debian.org s homepage, describing the recent changes that made the system stable again:
    The new server has no problems keeping up with importing the full archives on every update, as each run finishes comfortably in time before it s time to run again. [While] the new server is the one doing all the importing of updated archives, the HTTP interface is being served by both the new server and one of the VM s at LeaseWeb.
    The entry list a number of specific updates surrounding the API endpoints and rate limiting.
  • Lastly, 12 reviews of Debian packages were added, 3 were updated and 18 were removed this month adding to our knowledge about identified issues.
Elsewhere in distribution news, Zbigniew J drzejewski-Szmek performed another rebuild of Fedora 42 packages, with the headline result being that 91% of the packages are reproducible. Zbigniew also reported a reproducibility problem with QImage. Finally, in openSUSE, Bernhard M. Wiedemann published another report for that distribution.

Website updates There were an enormous number of improvements made to our website this month, including:
  • Alba Herrerias:
    • Improve consistency across distribution-specific guides. [ ]
    • Fix a number of links on the Contribute page. [ ]
  • Chris Lamb:
  • hulkoba
  • James Addison:
    • Huge and significant work on a (as-yet-merged) quickstart guide to be linked from the homepage [ ][ ][ ][ ][ ]
    • On the homepage, link directly to the Projects subpage. [ ]
    • Relocate dependency-drift notes to the Volatile inputs page. [ ]
  • Ninette Adhikari:
    • Add a brand new Success stories page that highlights the success stories of Reproducible Builds, showcasing real-world examples of projects shipping with verifiable, reproducible builds . [ ][ ][ ][ ][ ][ ]
  • Pol Dellaiera:
    • Update the website s README page for building the website under NixOS. [ ][ ][ ][ ][ ]
    • Add a new academic paper citation. [ ]
Lastly, Holger Levsen filed an extensive issue detailing a request to create an overview of recommendations and standards in relation to reproducible builds.

Reproducibility testing framework The Reproducible Builds project operates a comprehensive testing framework running primarily at tests.reproducible-builds.org in order to check packages and other artifacts for reproducibility. In October, a number of changes were made by Holger Levsen, including:
  • Add a basic index.html for rebuilderd. [ ]
  • Update the nginx.conf configuration file for rebuilderd. [ ]
  • Document how to use a rescue system for Infomaniak s OpenStack cloud. [ ]
  • Update usage info for two particular nodes. [ ]
  • Fix up a version skew check to fix the name of the riscv64 architecture. [ ]
  • Update the rebuilderd-related TODO. [ ]
In addition, Mattia Rizzolo added a new IP address for the inos5 node [ ] and Vagrant Cascadian brought 4 virt nodes back online [ ].

Supply-chain security at Open Source Summit EU The Open Source Summit EU took place recently, and covered plenty of topics related to supply-chain security, including:

Upstream patches The Reproducible Builds project detects, dissects and attempts to fix as many currently-unreproducible packages as possible. We endeavour to send all of our patches upstream where appropriate. This month, we wrote a large number of such patches, including:

Finally, If you are interested in contributing to the Reproducible Builds project, please visit our Contribute page on our website. However, you can get in touch with us via:

9 November 2024

Jonathan Dowland: Progressively enhancing CGI apps with htmx

I was interested in learning about htmx, so I used it to improve the experience of posting comments on my blog. It seems much of modern web development is structured around having a JavaScript program on the front-end (browser) which exchanges data encoded in JSON asynchronously with the back-end servers. htmx uses a novel (or throwback) approach: it asynchronously fetches snippets of HTML from the back-end, and splices the results into the live page. For example, a htmx-powered button may request a URI on the server, receive HTML in response, and then the button itself would be replaced by the resulting HTML, within the page. I experimented with incorporating it into an existing, old-school CGI web app: IkiWiki, which I became a co-maintainer of this year, and powers my blog. Throughout this project I referred to the excellent book Server-Driven Web Apps with htmx. Comment posting workflow I really value blog comments, but the UX for posting them on my blog was a bit clunky. It went like this:
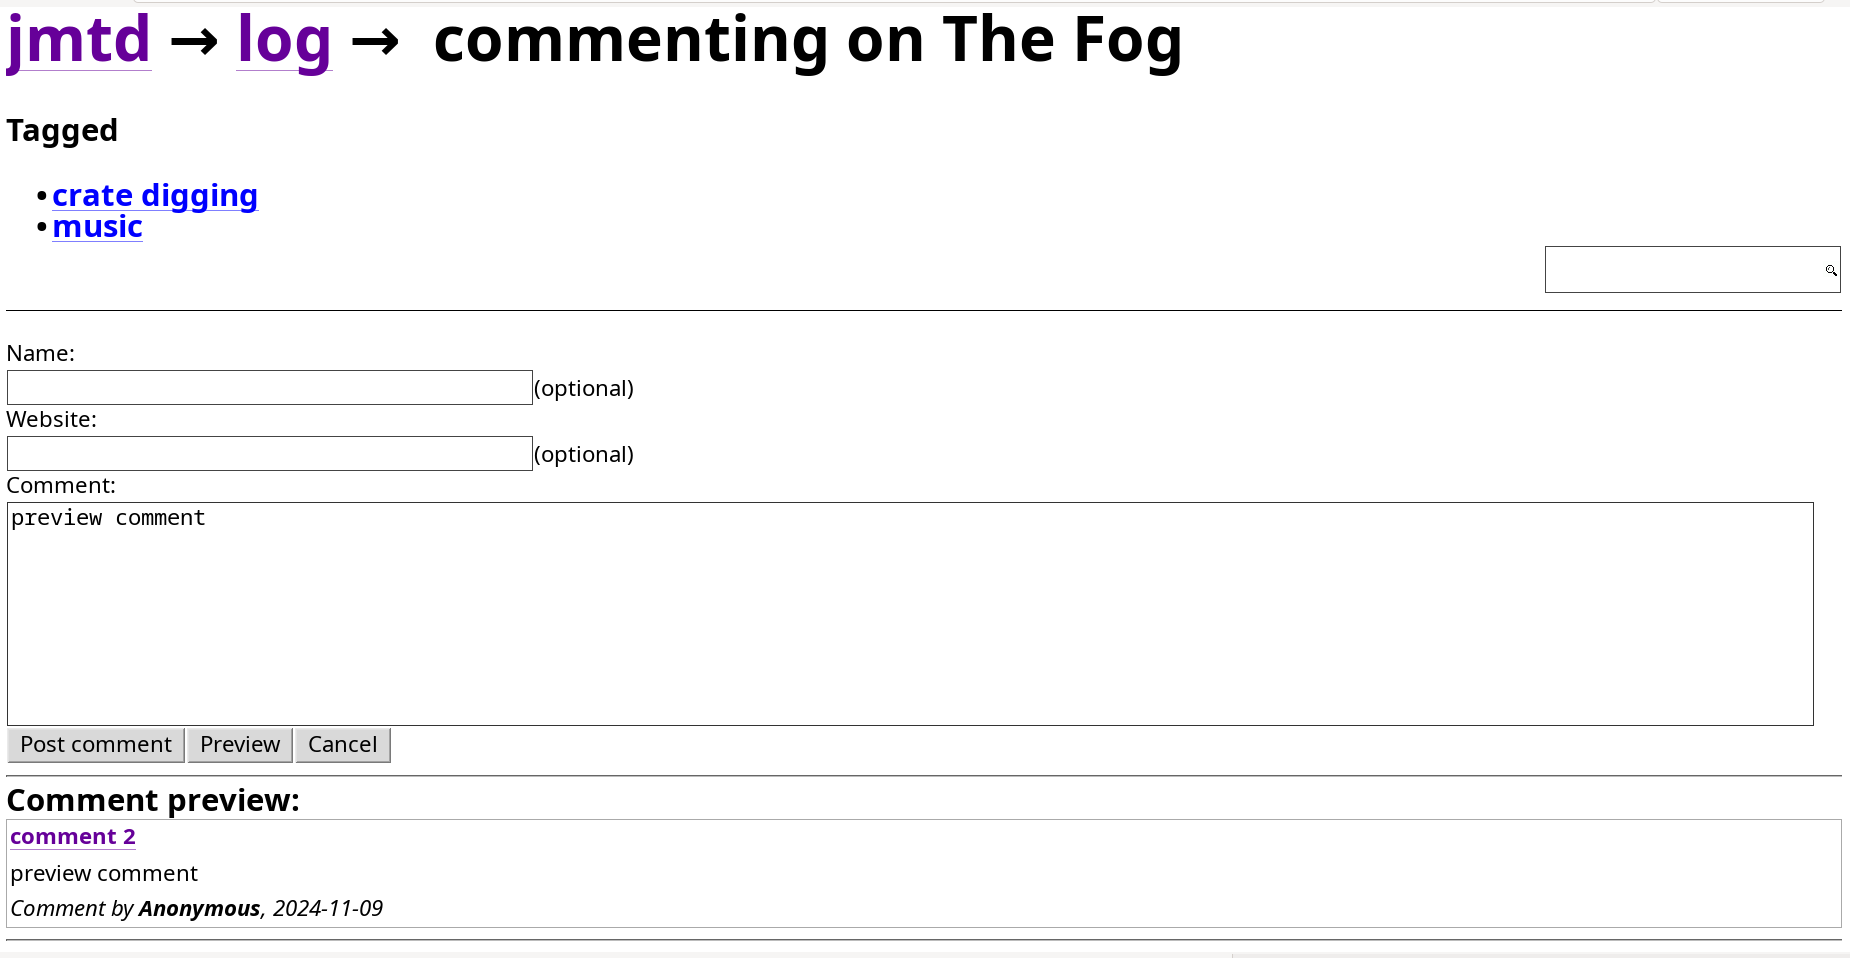
  1. you load a given page (such as this blog post), which is a static HTML document. There's a link to add a comment to the page.
  2. The link loads a new page which is generated dynamically and served back to you via CGI. This contains a HTML form for you to write your comment.
  3. The form submits to the server via HTTP POST. IkiWiki validates the form content. Various static pages (in particular the one you started on, in Step 1) are regenerated.
  4. the server response to the request in (3) is a HTTP 302 redirect, instructing the browser to go back to the page in Step 1.
First step: fetching a comment form First, I wanted the "add a comment" link to present the edit box in the current page. This step was easiest: add four attributes to the "comment on this page" anchor tag:
hx-get="<CGI ENDPOINT GOES HERE>"
suppresses the normal behaviour of the tag, so clicking on it doesn't load a new page.
issues an asynchronous HTTP GET to the CGI end-point, which returns the full HTML document for the comment edit form
hx-select=".editcomment form"
extract the edit-comment form from within that document
hx-swap=beforeend and hx-target=".addcomment"
append (courtesy of beforeend) the form into the source page after the "add comment" anchor tag (.addcomment)
Now, clicking "comment on this page" loads in the edit-comment box below it without moving you away from the source page. All that without writing any new code! Second step: handling previews
The old Preview Comment page The old Preview Comment page
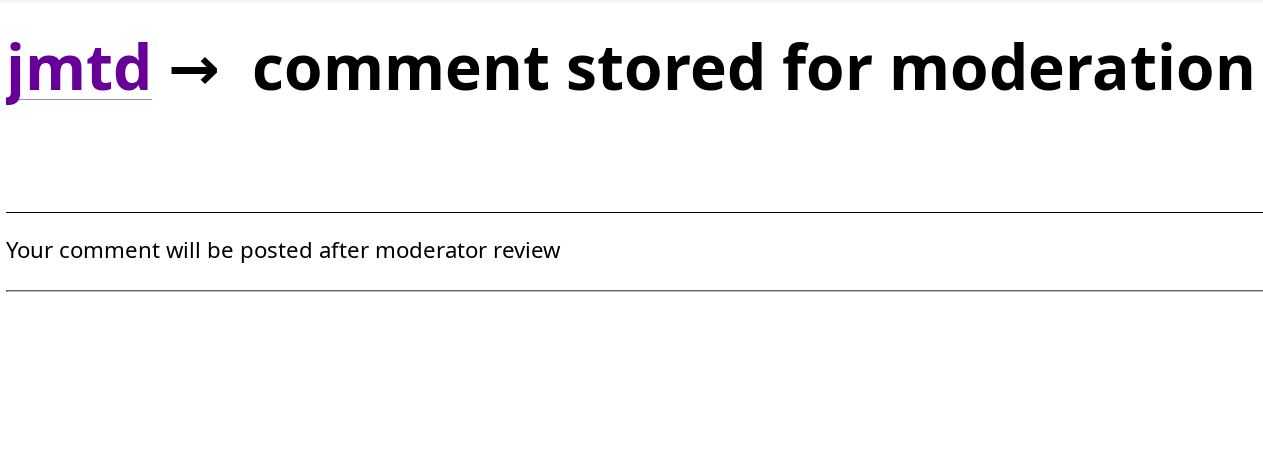
In the traditional workflow, clicking on "Preview" loaded a new page containing the edit form (but not the original page or any existing comments) with a rendering of the comment-in-progress below it. I wasn't originally interested in supporting the "Preview" feature, but I needed to for reasons I'll explain later. Rather than load new pages, I wanted "Preview" to insert a rendering of the comment-in-progress being inserted into the current page's list of comments, marked up to indicate that it's a preview. IkiWiki provides some templates which you can override to customise your site. I've long overridden page.tmpl, the template used for all pages. I needed to add a new empty div tag in order to have a "hook" to target with the previewed comment. The rest of this was achieved with htmx attributes on the "Preview" button, similar to in the last step: hx-post to define a target URI when you click the button (and specify HTTP POST); hx-select to filter the resulting HTML and extract the comment; hx-target to specify where to insert it. Now, clicking "Preview" does not leave the current page, but fetches a rendering of your comment-in-progress, and splices it into the comment list, appropriately marked up to be clear it's a preview. Third step: handling submitted comments IkiWiki is highly configurable, and many different things could happen once you post a comment. On my personal blog, all comments are held for moderation before they are published. The page you were served after submitting a comment was rather bare-bones, a status message "Your comment will be posted after moderator review", without the original page content or comments. I wanted your comment to appear in the page immediately, albeit marked up to indicate it was awaiting review. Since the traditional workflow didn't render or present your comment to you, I had to cheat. handling moderated comments
Moderation message upon submitting a comment Moderation message upon submitting a comment
One of my goals with this project was not to modify IkiWiki itself. I had to break this rule for moderated comments. When returning the "comment is moderated" page, IkiWiki uses HTTP status code 200, the same as for other scenarios. I wrote a tiny patch to return HTTP 202 (Accepted, but not processed) instead. I now have to write some actual JavaScript. htmx emits the htmx:beforeSwap event after an AJAX call returns, but before the corresponding swap is performed. I wrote a function that is triggered on this event, filters for HTTP 202 responses, triggers the "Preview" button, and then alters the result to indicate a moderated, rather than previewed, comment. (That's why I bothered to implement previews). You can read the full function here: jon.js. Summary I've done barely any front-end web development for years and I found working with htmx to be an enjoyable experience. You can leave a comment on this very blog post if you want to see it in action. I couldn't resist adding an easter egg: Brownie points if you can figure out what it is. Adding htmx to an existing CGI-based website let me improve one of the workflows in a gracefully-degrading way (without JavaScript, the old method will continue to work fine) without modifying the existing application itself (well, almost) and without having to write very much code of my own at all: nearly all of the configuration was declarative.

8 November 2024

Freexian Collaborators: Debian Contributions: October s report (by Anupa Ann Joseph)

Debian Contributions: 2024-10 Contributing to Debian is part of Freexian s mission. This article covers the latest achievements of Freexian and their collaborators. All of this is made possible by organizations subscribing to our Long Term Support contracts and consulting services.

rebootstrap, by Helmut Grohne After significant changes earlier this year, the state of architecture cross bootstrap is normalizing again. More and more architectures manage to complete rebootstrap testing successfully again. Here are two examples of what kind of issues the bootstrap testing identifies. At some point, libpng1.6 would fail to cross build on musl architectures whereas it would succeed on other ones failing to locate zlib. Adding --debug-find to the cmake invocation eventually revealed that it would fail to search in /usr/lib/<triplet>, which is the default library path. This turned out to be a bug in cmake assuming that all linux systems use glibc. libpng1.6 also gained a baseline violation for powerpc and ppc64 by enabling the use of AltiVec there. The newt package would fail to cross build for many 32-bit architectures whereas it would succeed for armel and armhf due to -Wincompatible-pointer-types. It turns out that this flag was turned into -Werror and it was compiling with a warning earlier. The actual problem is a difference in signedness between wchar_t and FriBidChar (aka uint32_t) and actually affects native building on i386.

Miscellaneous contributions
  • Helmut sent 35 patches for cross build failures.
  • Stefano Rivera uploaded the Python 3.13.0 final release.
  • Stefano continued to rebuild Python packages with C extensions using Python 3.13, to catch compatibility issues before the 3.13-add transition starts.
  • Stefano uploaded new versions of a handful of Python packages, including: dh-python, objgraph, python-mitogen, python-truststore, and python-virtualenv.
  • Stefano packaged a new release of mkdocs-macros-plugin, which required packaging a new Python package for Debian, python-super-collections (now in NEW review).
  • Stefano helped the mini-DebConf Online Brazil get video infrastructure up and running for the event. Unfortunately, Debian s online-DebConf setup has bitrotted over the last couple of years, and it eventually required new temporary Jitsi and Jibri instances.
  • Colin Watson fixed a number of autopkgtest failures to get ansible back into testing.
  • Colin fixed an ssh client failure in certain cases when using GSS-API key exchange, and added an integration test to ensure this doesn t regress in future.
  • Colin worked on the Python 3.13 transition, fixing problems related to it in 15 packages. This included upstream work in a number of packages (postgresfixture, python-asyncssh, python-wadllib).
  • Colin upgraded 41 Python packages to new upstream versions.
  • Carles improved po-debconf-manager: now it can create merge requests to Salsa automatically (created 17, new batch coming this month), imported almost all the packages with debconf translation templates whose VCS is Salsa (currently 449 imported), added statistics per package and language, improved command line interface options. Performed user support fixing different issues. Also prepared an abstract for the talk at MiniDebConf Toulouse.
  • Santiago Ruano Rinc n continued the organization work for the DebConf 25 conference, to be held in Brest, France. Part of the work relates to the initial edits of the sponsoring brochure. Thanks to Benjamin Somers who finalized the French and English versions.
  • Rapha l forwarded a couple of zim and hamster bugs to the upstream developers, and tried to diagnose a delayed startup of gdm on his laptop (cf #1085633).
  • On behalf of the Debian Publicity Team, Anupa interviewed 7 women from the Debian community, old and new contributors. The interview was published in Bits from Debian.

6 November 2024

Bits from Debian: Bits from the DPL

Dear Debian community, this is Bits from DPL for October. In addition to a summary of my recent activities, I aim to include newsworthy developments within Debian that might be of interest to the broader community. I believe this provides valuable insights and foster a sense of connection across our diverse projects. Also, I welcome your feedback on the format and focus of these Bits, as community input helps shape their value. Ada Lovelace Day 2024 As outlined in my platform, I'm committed to increasing the diversity of Debian developers. I hope the recent article celebrating Ada Lovelace Day 2024 featuring interviews with women in Debian will serve as an inspiring motivation for more women to join our community. MiniDebConf Cambridge This was my first time attending the MiniDebConf in Cambridge, hosted at the ARM building. I thoroughly enjoyed the welcoming atmosphere of both MiniDebCamp and MiniDebConf. It was wonderful to reconnect with people who hadn't made it to the last two DebConfs, and, as always, there was plenty of hacking, insightful discussions, and valuable learning. If you missed the recent MiniDebConf, there's a great opportunity to attend the next one in Toulouse. It was recently decided to include a MiniDebCamp beforehand as well. FTPmaster accepts MRs for DAK At the recent MiniDebConf in Cambridge, I discussed potential enhancements for DAK to make life easier for both FTP Team members and developers. For those interested, the document "Hacking on DAK" provides guidance on setting up a local DAK instance and developing patches, which can be submitted as MRs. As a perfectly random example of such improvements some older MR, "Add commands to accept/reject updates from a policy queue" might give you some inspiration. At MiniDebConf, we compiled an initial list of features that could benefit both the FTP Team and the developer community. While I had preliminary discussions with the FTP Team about these items, not all ideas had consensus. I aim to open a detailed, public discussion to gather broader feedback and reach a consensus on which features to prioritize. Sometimes, packages are rejected not because of DFSG-incompatible licenses but due to other issues that could be resolved within an existing package (as discussed in my DebConf23 BoF, "Chatting with ftpmasters"[1]). During the "Meet the ftpteam" BoF (Log/transcription of the BoF can be found here), for the moment until the MR gets accepted, a new option was proposed for FTP Team members reviewing packages in NEW:

Accept + Bug Report This option would allow a package to enter Debian (in unstable or experimental) with an automatically filed RC bug report. The RC bug would prevent the package from migrating to testing until the issues are addressed. To ensure compatibility with the BTS, which only accepts bug reports for existing packages, a delayed job (24 hours post-acceptance) would file the bug.

When binary package names change, currently the package must go through the NEW queue, which can delay the availability of updated libraries. Allowing such packages to bypass the queue could expedite this process. A configuration option to enable this bypass specifically for uploads to experimental may be useful, as it avoids requiring additional technical review for experimental uploads. Previously, I believed the requirement for binary name changes to pass through NEW was due to a missing feature in DAK, possibly addressable via an MR. However, in discussions with the FTP Team, I learned this is a matter of team policy rather than technical limitation. I haven't found this policy documented, so it may be worth having a community discussion to clarify and reach consensus on how we want to handle binary name changes to get the MR sensibly designed. When a developer requests the removal of a package whether entirely or for specific architectures RM bugs must be filed for the package itself as well as for each package depending on it. It would be beneficial if the dependency tree could be automatically resolved, allowing either:
a) the DAK removal tooling to remove the entire dependency tree
   after prompting the bug report author for confirmation, or
b) the system to auto-generate corresponding bug reports for all
   packages in the dependency tree.
The latter option might be better suited for implementation in an MR for reportbug. However, given the possibility of large-scale removals (for example, targeting specific architectures), having appropriate tooling for this would be very beneficial. In my opinion the proposed DAK enhancements aim to support both FTP Team members and uploading developers. I'd be very pleased if these ideas spark constructive discussion and inspire volunteers to start working on them--possibly even preparing to join the FTP Team. On the topic of ftpmasters: an ongoing discussion with SPI lawyers is currently reviewing the non-US agreement established 22 years ago. Ideally, this review will lead to a streamlined workflow for ftpmasters, removing certain hurdles that were originally put in place due to legal requirements, which were updated in 2021. Contacting teams My outreach efforts to Debian teams have slowed somewhat recently. However, I want to emphasize that anyone from a packaging team is more than welcome to reach out to me directly. My outreach emails aren't following any specific orders--just my own somewhat na ve view of Debian, which I'm eager to make more informed. Recently, I received two very informative responses: one from the Qt/KDE Team, which thoughtfully compiled input from several team members into a shared document. The other was from the Rust Team, where I received three quick, helpful replies one of which included an invitation to their upcoming team meeting. Interesting readings on our mailing lists I consider the following threads on our mailing list some interesting reading and would like to add some comments. Sensible languages for younger contributors Though the discussion on debian-devel about programming languages took place in September, I recently caught up with it. I strongly believe Debian must continue evolving to stay relevant for the future. "Everything must change, so that everything can stay the same." -- Giuseppe Tomasi di Lampedusa, The Leopard I encourage constructive discussions on integrating programming languages in our toolchain that support this evolution. Concerns regarding the "Open Source AI Definition" A recent thread on the debian-project list discussed the "Open Source AI Definition". This topic will impact Debian in the future, and we need to reach an informed decision. I'd be glad to see more perspectives in the discussions particularly on finding a sensible consensus, understanding how FTP Team members view their delegated role, and considering whether their delegation might need adjustments for clarity on this issue. Kind regards Andreas.

4 November 2024

Sven Hoexter: Google CloudDNS HTTPS Records with ipv6hint

I naively provisioned an HTTPS record at Google CloudDNS like this via terraform:
resource "google_dns_record_set" "testv6"  
    name         = "testv6.some-domain.example."
    managed_zone = "some-domain-example"
    type         = "HTTPS"
    ttl          = 3600
    rrdatas      = ["1 . alpn=\"h2\" ipv4hint=\"198.51.100.1\" ipv6hint=\"2001:DB8::1\""]
 
This results in a permanent diff because the Google CloudDNS API seems to parse the record content, and stores the ipv6hint expanded (removing the :: notation) and in all lowercase as 2001:db8:0:0:0:0:0:1. Thus to fix the permanent diff we've to use it like this:
resource "google_dns_record_set" "testv6"  
    name = "testv6.some-domain.example."
    managed_zone = "some-domain-example"
    type = "HTTPS"
    ttl = 3600
    rrdatas = ["1 . alpn=\"h2\" ipv4hint=\"198.51.100.1\" ipv6hint=\"2001:db8:0:0:0:0:0:1\""]
 
Guess I should be glad that they already support HTTPS records natively, and not bicker too much about the implementation details.

1 November 2024

Taavi V n nen: Custom domains on the Wikimedia Cloud VPS web proxy

The shared web proxy used on Wikimedia Cloud VPS now has technical support for using arbitrary domains (and not just wmcloud.org subdomains) in proxy names. I think this is a good example of how software slowly evolves over time as new requirements emerge, with each new addition building on top of the previous ones. According to the edit history on Wikitech, the web proxy service has its origins in 2012, although the current idea where you create a proxy and map it to a specific instance and port was only introduced a year later. (Before that, it just directly mapped the subdomain to the VPS instance with the same name). There were some smaller changes in the coming years like the migration to acme-chief for TLS certificate management, but the overall logic stayed very similar until 2020 when the wmcloud.org domain was introduced. That was implemented by adding a config option listing all possible domains, so future domain additions would be as simple as adding the new domain to that list in the configuration. Then the changes start becoming more frequent:

26 October 2024

Russell Coker: The CUPS Vulnerability

The Announcement Late last month there was an announcement of a severity 9.9 vulnerability allowing remote code execution that affects all GNU/Linux systems (plus others) [1]. For something to affect all Linux systems that would have to be either a kernel issue or a sshd issue. The announcement included complaints about the lack of response of vendors and And YES: I LOVE hyping the sh1t out of this stuff because apparently sensationalism is the only language that forces these people to fix . He seems to have a different experience to me of reporting bugs, I have had plenty of success getting bugs fixed without hyping them. I just report the bug, wait a while, and it gets fixed. I have reported potential security bugs without even bothering to try and prove that they were exploitable (any situation where you can make a program crash is potentially exploitable), I just report it and it gets fixed. I was very dubious about his ability to determine how serious a bug is and to accurately report it so this wasn t a situation where I was waiting for it to be disclosed to discover if it affected me. I was quite confident that my systems wouldn t be at any risk. Analysis Not All Linux Systems Run CUPS When it was published my opinion was proven to be correct, it turned out to be a series of CUPS bugs [2]. To describe that as all GNU/Linux systems (plus others) seems like a vast overstatement, maybe a good thing to say if you want to be a TikTok influencer but not if you want to be known for computer security work. For the Debian distribution the cups-browsed package (which seems to be the main exploitable one) is recommended by cups-daemon, as I have my Debian systems configured to not install recommended packages by default that means that it wasn t installed on any of my systems. Also the vast majority of my systems don t do printing and therefore don t have any part of CUPS installed. CUPS vs NAT The next issue is that in Australia most home ISPs don t have IPv6 enabled and CUPS doesn t do the things needed to allow receiving connections from the outside world via NAT with IPv4. If inbound port 631 is blocked on both TCP and USP as is the default on Australian home Internet or if there is a correctly configured firewall in place then the network is safe from attack. There is a feature called uPnP port forwarding [3] to allow server programs to ask a router to send inbound connections to them, this is apparently usually turned off by default in router configuration. If it is enabled then there are Debian packages of software to manage this, the miniupnpc package has the client (which can request NAT changes on the router) [4]. That package is not installed on any of my systems and for my home network I don t use a router that runs uPnP. The only program I knowingly run that uses uPnP is Warzone2100 and as I don t play network games that doesn t happen. Also as an aside in version 4.4.2-1 of warzone2100 in Debian and Ubuntu I made it use Bubblewrap to run the game in a container. So a Remote Code Execution bug in Warzone 2100 won t be an immediate win for an attacker (exploits via X11 or Wayland are another issue). MAC Systems Debian has had AppArmor enabled by default since Buster was released in 2019 [5]. There are claims that AppArmor will stop this exploit from doing anything bad. To check SE Linux access I first use the semanage fcontext command to check the context of the binary, cupsd_exec_t means that the daemon runs as cupsd_t. Then I checked what file access is granted with the sesearch program, mostly just access to temporary files, cupsd config files, the faillog, the Kerberos cache files (not used on the Kerberos client systems I run), Samba run files (might be a possibility of exploiting something there), and the security_t used for interfacing with kernel security infrastructure. I then checked the access to the security class and found that it is permitted to check contexts and access-vectors not access that can be harmful. The next test was to use sesearch to discover what capabilities are granted, which unfortunately includes the sys_admin capability, that is a capability that allows many sysadmin tasks that could be harmful (I just checked the Fedora source and Fedora 42 has the same access). Whether the sys_admin capability can be used to do bad things with the limited access cupsd_t has to device nodes etc is not clear. But this access is undesirable. So the SE Linux policy in Debian and Fedora will stop cupsd_t from writing SETUID programs that can be used by random users for root access and stop it from writing to /etc/shadow etc. But the sys_admin capability might allow it to do hostile things and I have already uploaded a changed policy to Debian/Unstable to remove that. The sys_rawio capability also looked concerning but it s apparently needed to probe for USB printers and as the domain has no access to block devices it is otherwise harmless. Below are the commands I used to discover what the policy allows and the output from them.
# semanage fcontext -l grep bin/cups-browsed
/usr/bin/cups-browsed                              regular file       system_u:object_r:cupsd_exec_t:s0 
# sesearch -A -s cupsd_t -c file -p write
allow cupsd_t cupsd_interface_t:file   append create execute execute_no_trans getattr ioctl link lock map open read rename setattr unlink write  ;
allow cupsd_t cupsd_lock_t:file   append create getattr ioctl link lock open read rename setattr unlink write  ;
allow cupsd_t cupsd_log_t:file   append create getattr ioctl link lock open read rename setattr unlink write  ;
allow cupsd_t cupsd_runtime_t:file   append create getattr ioctl link lock open read rename setattr unlink write  ;
allow cupsd_t cupsd_rw_etc_t:file   append create getattr ioctl link lock open read rename setattr unlink write  ;
allow cupsd_t cupsd_t:file   append create getattr ioctl link lock open read rename setattr unlink write  ;
allow cupsd_t cupsd_tmp_t:file   append create getattr ioctl link lock open read rename setattr unlink write  ;
allow cupsd_t faillog_t:file   append getattr ioctl lock open read write  ;
allow cupsd_t init_tmpfs_t:file   append getattr ioctl lock read write  ;
allow cupsd_t krb5_host_rcache_t:file   append create getattr ioctl link lock open read rename setattr unlink write  ; [ allow_kerberos ]:True
allow cupsd_t print_spool_t:file   append create getattr ioctl link lock open read relabelfrom relabelto rename setattr unlink write  ;
allow cupsd_t samba_var_t:file   append getattr ioctl lock open read write  ;
allow cupsd_t security_t:file   append getattr ioctl lock open read write  ;
allow cupsd_t security_t:file   append getattr ioctl lock open read write  ; [ allow_kerberos ]:True
allow cupsd_t usbfs_t:file   append getattr ioctl lock open read write  ;
# sesearch -A -s cupsd_t -c security
allow cupsd_t security_t:security check_context; [ allow_kerberos ]:True
allow cupsd_t security_t:security   check_context compute_av  ;
# sesearch -A -s cupsd_t -c capability
allow cupsd_t cupsd_t:capability net_bind_service; [ allow_ypbind ]:True
allow cupsd_t cupsd_t:capability   audit_write chown dac_override dac_read_search fowner fsetid ipc_lock kill net_bind_service setgid setuid sys_admin sys_rawio sys_resource sys_tty_config  ;
# sesearch -A -s cupsd_t -c capability2
allow cupsd_t cupsd_t:capability2   block_suspend wake_alarm  ;
# sesearch -A -s cupsd_t -c blk_file
Conclusion This is an example of how not to handle security issues. Some degree of promotion is acceptable but this is very excessive and will result in people not taking security announcements seriously in future. I wonder if this is even a good career move by the researcher in question, will enough people believe that they actually did something good in this that it outweighs the number of people who think it s misleading at best?

21 October 2024

Russ Allbery: California general election

As usual with these every-two-year posts, probably of direct interest only to California residents. Maybe the more obscure things we're voting on will be a minor curiosity to people elsewhere. I'm a bit late this year, although not as late as last year, so a lot of people may have already voted, but I've been doing this for a while and wanted to keep it up. This post will only be about the ballot propositions. I don't have anything useful to say about the candidates that isn't hyper-local. I doubt anyone who has read my posts will be surprised by which candidates I'm voting for. As always with Calfornia ballot propositions, it's worth paying close attention to which propositions were put on the ballot by the legislature, usually because there's some state law requirement (often that I disagree with) that they be voted on by the public, and propositions that were put on the ballot by voter petition. The latter are often poorly written and have hidden problems. As a general rule of thumb, I tend to default to voting against propositions added by petition. This year, one can conveniently distinguish by number: the single-digit propositions were added by the legislature, and the two-digit ones were added by petition. Proposition 2: YES. Issue $10 billion in bonds for public school infrastructure improvements. I generally vote in favor of spending measures like this unless they have some obvious problem. The opposition argument is a deranged rant against immigrants and government debt and fails to point out actual problems. The opposition argument also claims this will result in higher property taxes and, seriously, if only that were true. That would make me even more strongly in favor of it. Proposition 3: YES. Enshrines the right to marriage without regard to sex or race into the California state constitution. This is already the law given US Supreme Court decisions, but fixing California state law is a long-overdue and obvious cleanup step. One of the quixotic things I would do if I were ever in government, which I will never be, would be to try to clean up the laws to make them match reality, repealing all of the dead clauses that were overturned by court decisions or are never enforced. I am in favor of all measures in this direction even when I don't agree with the direction of the change; here, as a bonus, I also strongly agree with the change. Proposition 4: YES. Issue $10 billion in bonds for infrastructure improvements to mitigate climate risk. This is basically the same argument as Proposition 2. The one drawback of this measure is that it's kind of a mixed grab bag of stuff and probably some of it should be supported out of the general budget rather than bonds, but I consider this a minor problem. We definitely need to ramp up climate risk mitigation efforts. Proposition 5: YES. Reduces the required super-majority to pass local bond measures for affordable housing from 67% to 55%. The fact that this requires a supermajority at all is absurd, California desperately needs to build more housing of any kind however we can, and publicly funded housing is an excellent idea. Proposition 6: YES. Eliminates "involuntary servitude" (in other words, "temporary" slavery) as a legally permissible punishment for crimes in the state of California. I'm one of the people who think the 13th Amendment to the US Constitution shouldn't have an exception for punishment for crimes, so obviously I'm in favor of this. This is one very, very tiny step towards improving the absolutely atrocious prison conditions in the state. Proposition 32: YES. Raises the minimum wage to $18 per hour from the current $16 per hour, over two years, and ties it to inflation. This is one of the rare petition-based propositions that I will vote in favor of because it's very straightforward, we clearly should be raising the minimum wage, and living in California is absurdly expensive because we refuse to build more housing (see Propositions 5 and 33). The opposition argument is the standard lie that a higher minimum wage will increase unemployment, which we know from numerous other natural experiments is simply not true. Proposition 33: NO. Repeals Costa-Hawkins, which prohibits local municipalities from enacting rent control on properties built after 1995. This one is going to split the progressive vote rather badly, I suspect. California has a housing crisis caused by not enough housing supply. It is not due to vacant housing, as much as some people would like you to believe that; the numbers just don't add up. There are way more people living here and wanting to live here than there is housing, so we need to build more housing. Rent control serves a valuable social function of providing stability to people who already have housing, but it doesn't help, and can hurt, the project of meeting actual housing demand. Rent control alone creates a two-tier system where people who have housing are protected but people who don't have housing have an even harder time getting housing than they do today. It's therefore quite consistent with the general NIMBY playbook of trying to protect the people who already have housing by making life harder for the people who do not, while keeping the housing supply essentially static. I am in favor of rent control in conjunction with real measures to increase the housing supply. I am therefore opposed to this proposition, which allows rent control without any effort to increase housing supply. I am quite certain that, if this passes, some municipalities will use it to make constructing new high-density housing incredibly difficult by requiring it all be rent-controlled low-income housing, thus cutting off the supply of multi-tenant market-rate housing entirely. This is already a common political goal in the part of California where I live. Local neighborhood groups advocate for exactly this routinely in local political fights. Give me a mandate for new construction that breaks local zoning obstructionism, including new market-rate housing to maintain a healthy lifecycle of housing aging into affordable housing as wealthy people move into new market-rate housing, and I will gladly support rent control measures as part of that package. But rent control on its own just allocates winners and losers without addressing the underlying problem. Proposition 34: NO. This is an excellent example of why I vote against petition propositions by default. This is a law designed to affect exactly one organization in the state of California: the AIDS Healthcare Foundation. The reason for this targeting is disputed; one side claims it's because of the AHF support for Proposition 33, and another side claims it's because AHF is a slumlord abusing California state funding. I have no idea which side of this is true. I also don't care, because I am fundamentally opposed to writing laws this way. Laws should establish general, fair principles that are broadly applicable, not be written with bizarrely specific conditions (health care providers that operate multifamily housing) that will only be met by a single organization. This kind of nonsense creates bad legal codes and the legal equivalent of technical debt. Just don't do this. Proposition 35: YES. I am, reluctantly, voting in favor of this even though it is a petition proposition because it looks like a useful simplification and cleanup of state health care funding, makes an expiring tax permanent, and is supported by a very wide range of organizations that I generally trust to know what they're talking about. No opposition argument was filed, which I think is telling. Proposition 36: NO. I am resigned to voting down attempts to start new "war on drugs" nonsense for the rest of my life because the people who believe in this crap will never, ever, ever stop. This one has bonus shoplifting fear-mongering attached, something that touches on nasty local politics that have included large retail chains manipulating crime report statistics to give the impression that shoplifting is up dramatically. It's yet another round of the truly horrific California "three strikes" criminal penalty obsession, which completely misunderstands both the causes of crime and the (almost nonexistent) effectiveness of harsh punishment as deterrence.

15 October 2024

Andrew Cater: Mini-DebConf Cambridge 20241013 1300

LATE NEWS I haven't blogged until now: I should have done from Thursday onwards.

It's a joy to be here in Cambridge at ARM HQ. Lots of people I recognise from last year here: lots *not* here because this mini-conference is a month before the next one in Toulouse and many people can't attend both.

Two days worth of chatting, working on bits and pieces, chatting and informal meetings was a very good and useful way to build relationships and let teams find some space for themselves.

Lots of quiet hacking going on - a few loud conversations. A new ARM machine in mini-ITX format - see Steve McIntyre's blog on planet.debian.org about Rock 5 ITX.

Two days worth of talks for Saturday and Sunday. For some people, this is a first time. Lightning talks are particularly good to break down barriers - three slides and five minutes (and the chance for a bit of gamesmanship to break the rules creatively).

Longer talks: a couple from Steve Capper of ARM were particularly helpful to those interested in upcoming development. A couple of the talks in the schedule are traditional: if the release team are here, they tell us what they are doing, for example.

ARM are main sponsors and have been very generous in giving us conference and facilities space. Fast network, coffee and interested people - what's not to like :)[EDIT/UPDATE - And my talk is finished and went fairly well: slides have now been uploaded and the talk is linked from the Mini-DebConf pages]

Dirk Eddelbuettel: qlcal 0.0.13 on CRAN: Small Calendar Update

The thirteenth release of the qlcal package arrivied at CRAN today. qlcal delivers the calendaring parts of QuantLib. It is provided (for the R package) as a set of included files, so the package is self-contained and does not depend on an external QuantLib library (which can be demanding to build). qlcal covers over sixty country / market calendars and can compute holiday lists, its complement (i.e. business day lists) and much more. Examples are in the README at the repository, the package page, and course at the CRAN package page. This releases synchronizes qlcal with the QuantLib release 1.36 (made this week) and contains some minor updates to two calendars.

Changes in version 0.0.13 (2024-10-15)
  • Synchronized with QuantLib 1.36 released yesterday
  • Calendar updates for South Korea and Poland

Courtesy of my CRANberries, there is a diffstat report for this release. See the project page and package documentation for more details, and more examples. If you like this or other open-source work I do, you can sponsor me at GitHub.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

14 October 2024

Philipp Kern: Touch Notifications for YubiKeys

When setting up your YubiKey you have the option to require the user to touch the device to authorize an operation (be it signing, decrypting, or authenticating). While web browsers often provide clear prompts for this, other applications like SSH or GPG will not. Instead the operation will just hang without any visual indication that user input is required. The YubiKey itself will blink, but depending on where it is plugged in that is not very visible.
yubikey-touch-detector (fresh in unstable) solves this issue by providing a way for your desktop environment to signal the user that the device is waiting for a touch. It provides an event feed on a socket that other components can consume. It comes with libnotify support and there are some custom integrations for other environments.For GNOME and KDE libnotify support should be sufficient, however you still need to turn it on:
$ mkdir -p ~/.config/yubikey-touch-detector
$ sed -e 's/^YUBIKEY_TOUCH_DETECTOR_LIBNOTIFY=.*/YUBIKEY_TOUCH_DETECTOR_LIBNOTIFY=true/' \
  < /usr/share/doc/yubikey-touch-detector/examples/service.conf.example \
  > ~/.config/yubikey-touch-detector/service.conf
$ systemctl --user restart yubikey-touch-detector
I would still have preferred a more visible, more modal prompt. I guess that would be an exercise for another time, listening to the socket and presenting a window. But for now, desktop notifications will do for me.PS: I have not managed to get SSH's no-touch-required to work with YubiKey 4, while it works just fine with a YubiKey 5.

12 October 2024

Jonathan Dowland: Code formatting in documents

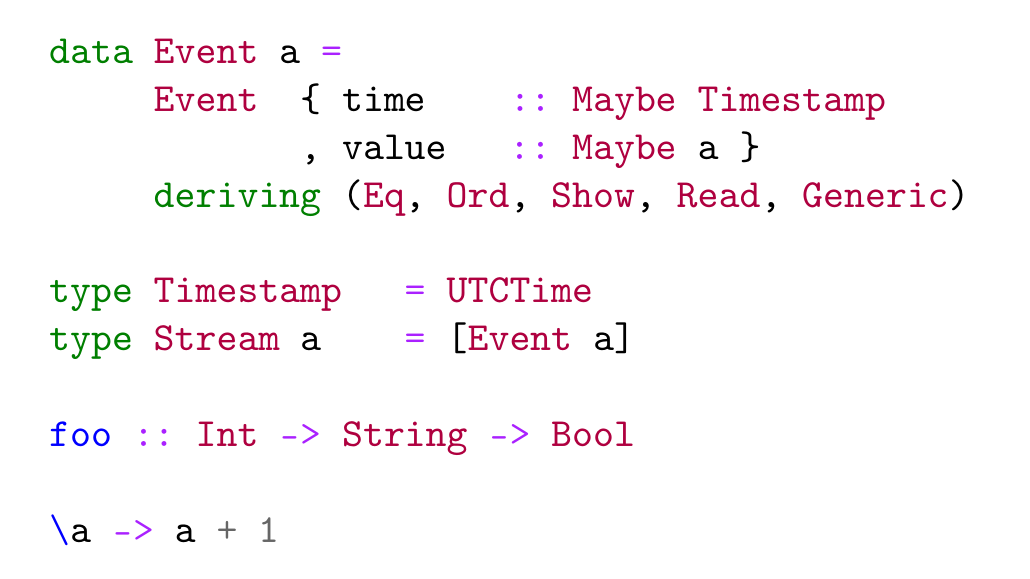
I've been exploring typesetting and formatting code within text documents such as papers, or my thesis. Up until now, I've been using the listings package without thinking much about it. By default, some sample Haskell code processed by listings looks like this (click any of the images to see larger, non-blurry versions):
default output of listings on a Haskell code sample
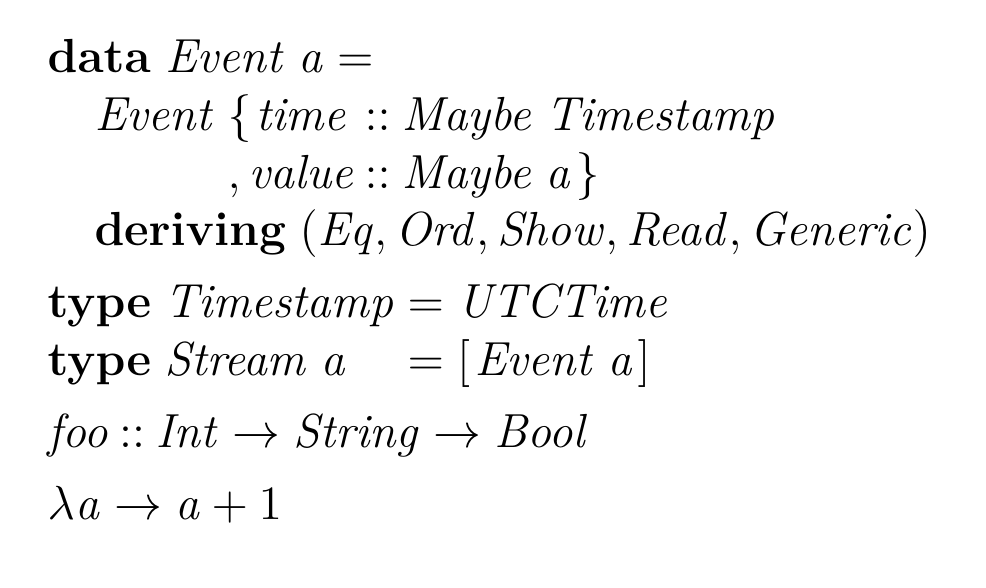
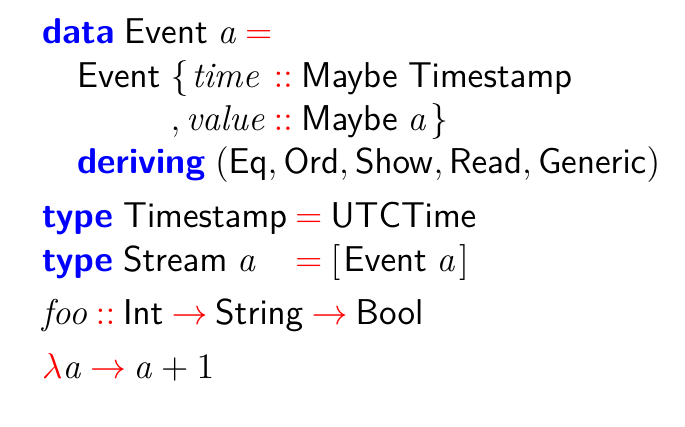
It's formatted with a monospaced font, with some keywords highlighted, but not syntactic symbols. There are several other options for typesetting and formatting code in LaTeX documents. For Haskell in particular, there is the preprocessor lhs2tex, The default output of which looks like this:
default output of lhs2tex on a Haskell code sample
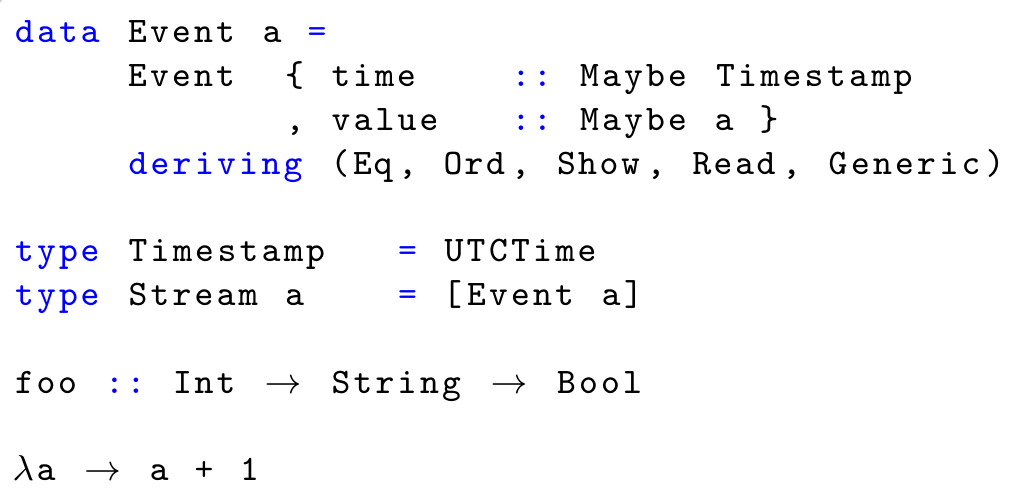
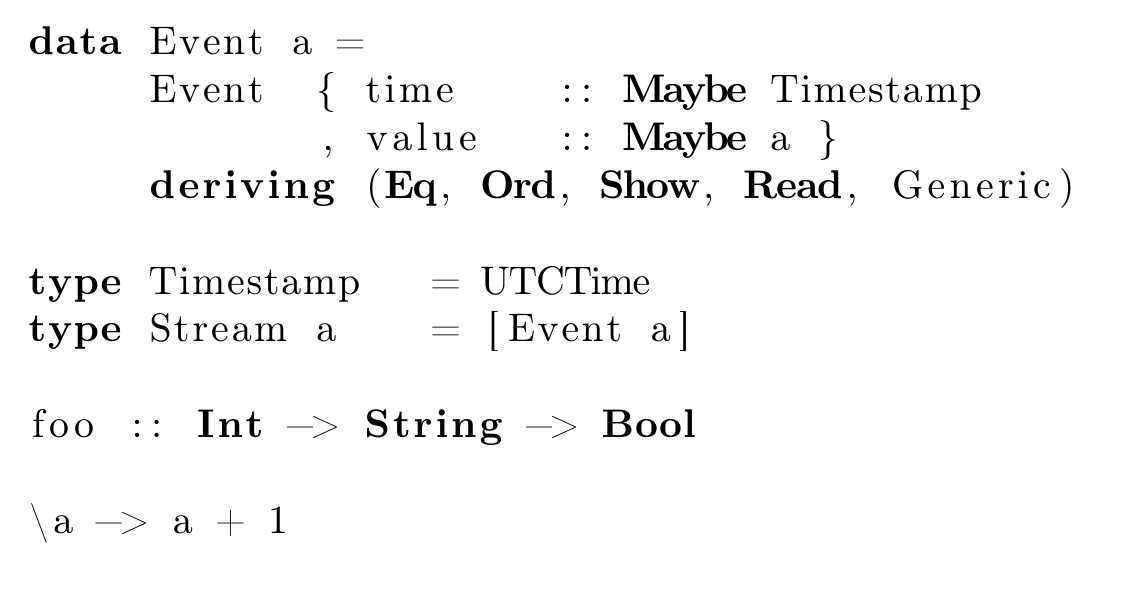
A proportional font, but it's taken pains to preserve vertical alignment, which is syntactically significant for Haskell. It looks a little cluttered to me, and I'm not a fan of nearly everything being italic. Again, symbols aren't differentiated, but it has substituted them for more typographically pleasing alternatives: -> has become , and \ is now . Another option is perhaps the newest, the LaTeX package minted, which leverages the Python Pygments program. Here's the same code again. It defaults to monospace (the choice of font seems a lot clearer to me than the default for listings), no symbolic substitution, and liberal use of colour:
default output of minted on a Haskell code sample
An informal survey of the samples so far showed that the minted output was the most popular. All of these packages can be configured to varying degrees. Here are some examples of what I've achieved with a bit of tweaking
_listings_ adjusted with colour and some symbols substituted (but sadly not the two together) listings adjusted with colour and some symbols substituted (but sadly not the two together)
_lhs2tex_ adjusted to be less italic, sans-serif and use some colour lhs2tex adjusted to be less italic, sans-serif and use some colour
All of this has got me wondering whether there are straightforward empirical answers to some of these questions of style. Firstly, I'm pretty convinced that symbolic substitution is valuable. When writing Haskell, we write ->, \, /= etc. not because it's most legible, but because it's most practical to type those symbols on the most widely available keyboards and popular keyboard layouts.1 Of the three options listed here, symbolic substitution is possible with listings and lhs2tex, but I haven't figured out if minted can do it (which is really the question: can pygments do it?) I'm unsure about proportional versus monospaced fonts. We typically use monospaced fonts for editing computer code, but that's at least partly for historical reasons. Vertical alignment is often very important in source code, and it can be easily achieved with monospaced text; it's also sometimes important to have individual characters (., etc.) not be de-emphasised by being smaller than any other character. lhs2tex, at least, addresses vertical alignment whilst using proportional fonts. I guess the importance of identifying individual significant characters is just as true in a code sample within a larger document as it is within plain source code. From a (brief) scan of research on this topic, it seems that proportional fonts result in marginally quicker reading times for regular prose. It's not clear whether those results carry over into reading computer code in particular, and the margin is slim in any case. The drawbacks of monospaced text mostly apply when the volume of text is large, which is not the case for the short code snippets I am working with. I still have a few open questions:

  1. The Haskell package Data.List.Unicode lets the programmer use a range of unicode symbols in place of ASCII approximations, such as instead of elem, instead of /=. Sadly, it's not possible to replace the denotation for an anonymous function, \, with this way.

10 October 2024

Gunnar Wolf: Started a guide to writing FUSE filesystems in Python

As DebConf22 was coming to an end, in Kosovo, talking with Eeveelweezel they invited me to prepare a talk to give for the Chicago Python User Group. I replied that I m not really that much of a Python guy But would think about a topic. Two years passed. I meet Eeveelweezel again for DebConf24 in Busan, South Korea. And the topic came up again. I had thought of some ideas, but none really pleased me. Again, I do write some Python when needed, and I teach using Python, as it s the language I find my students can best cope with. But delivering a talk to ChiPy? On the other hand, I have long used a very simplistic and limited filesystem I ve designed as an implementation project at class: FIUnamFS (for Facultad de Ingenier a, Universidad Nacional Aut noma de M xico : the Engineering Faculty for Mexico s National University, where I teach. Sorry, the link is in Spanish but you will find several implementations of it from the students ). It is a toy filesystem, with as many bad characteristics you can think of, but easy to specify and implement. It is based on contiguous file allocation, has no support for sub-directories, and is often limited to the size of a 1.44MB floppy disk. As I give this filesystem as a project to my students (and not as a mere homework), I always ask them to try and provide a good, polished, professional interface, not just the simplistic menu I often get. And I tell them the best possible interface would be if they provide support for FIUnamFS transparently, usable by the user without thinking too much about it. With high probability, that would mean: Use FUSE. Python FUSE But, in the six semesters I ve used this project (with 30-40 students per semester group), only one student has bitten the bullet and presented a FUSE implementation. Maybe this is because it s not easy to understand how to build a FUSE-based filesystem from a high-level language such as Python? Yes, I ve seen several implementation examples and even nice web pages (i.e. the examples shipped with thepython-fuse module Stavros passthrough filesystem, Dave Filesystem based upon, and further explaining, Stavros , and several others) explaining how to provide basic functionality. I found a particularly useful presentation by Matteo Bertozzi presented ~15 years ago at PyCon4 But none of those is IMO followable enough by itself. Also, most of them are very old (maybe the world is telling me something that I refuse to understand?). And of course, there isn t a single interface to work from. In Python only, we can find python-fuse, Pyfuse, Fusepy Where to start from? So I setup to try and help. Over the past couple of weeks, I have been slowly working on my own version, and presenting it as a progressive set of tasks, adding filesystem calls, and being careful to thoroughly document what I write (but maybe my documentation ends up obfuscating the intent? I hope not and, read on, I ve provided some remediation). I registered a GitLab project for a hand-holding guide to writing FUSE-based filesystems in Python. This is a project where I present several working FUSE filesystem implementations, some of them RAM-based, some passthrough-based, and I intend to add to this also filesystems backed on pseudo-block-devices (for implementations such as my FIUnamFS). So far, I have added five stepwise pieces, starting from the barest possible empty filesystem, and adding system calls (and functionality) until (so far) either a read-write filesystem in RAM with basicstat() support or a read-only passthrough filesystem. I think providing fun or useful examples is also a good way to get students to use what I m teaching, so I ve added some ideas I ve had: DNS Filesystem, on-the-fly markdown compiling filesystem, unzip filesystem and uncomment filesystem. They all provide something that could be seen as useful, in a way that s easy to teach, in just some tens of lines. And, in case my comments/documentation are too long to read, uncommentfs will happily strip all comments and whitespace automatically! So I will be delivering my talk tomorrow (2024.10.10, 18:30 GMT-6) at ChiPy (virtually). I am also presenting this talk virtually at Jornadas Regionales de Software Libre in Santa Fe, Argentina, next week (virtually as well). And also in November, in person, at nerdear.la, that will be held in Mexico City for the first time. Of course, I will also share this project with my students in the next couple of weeks And hope it manages to lure them into implementing FUSE in Python. At some point, I shall report! Update: After delivering my ChiPy talk, I have uploaded it to YouTube: A hand-holding guide to writing FUSE-based filesystems in Python, and after presenting at Jornadas Regionales, I present you the video in Spanish here: Aprendiendo y ense ando a escribir sistemas de archivo en espacio de usuario con FUSE y Python.
7 October 2024

Reproducible Builds: Reproducible Builds in September 2024

Welcome to the September 2024 report from the Reproducible Builds project! Our reports attempt to outline what we ve been up to over the past month, highlighting news items from elsewhere in tech where they are related. As ever, if you are interested in contributing to the project, please visit our Contribute page on our website. Table of contents:
  1. New binsider tool to analyse ELF binaries
  2. Unreproducibility of GHC Haskell compiler 95% fixed
  3. Mailing list summary
  4. Towards a 100% bit-for-bit reproducible OS
  5. Two new reproducibility-related academic papers
  6. Distribution work
  7. diffoscope
  8. Other software development
  9. Android toolchain core count issue reported
  10. New Gradle plugin for reproducibility
  11. Website updates
  12. Upstream patches
  13. Reproducibility testing framework

New binsider tool to analyse ELF binaries Reproducible Builds developer Orhun Parmaks z has announced a fantastic new tool to analyse the contents of ELF binaries. According to the project s README page:
Binsider can perform static and dynamic analysis, inspect strings, examine linked libraries, and perform hexdumps, all within a user-friendly terminal user interface!
More information about Binsider s features and how it works can be found within Binsider s documentation pages.

Unreproducibility of GHC Haskell compiler 95% fixed A seven-year-old bug about the nondeterminism of object code generated by the Glasgow Haskell Compiler (GHC) received a recent update, consisting of Rodrigo Mesquita noting that the issue is:
95% fixed by [merge request] !12680 when -fobject-determinism is enabled. [ ]
The linked merge request has since been merged, and Rodrigo goes on to say that:
After that patch is merged, there are some rarer bugs in both interface file determinism (eg. #25170) and in object determinism (eg. #25269) that need to be taken care of, but the great majority of the work needed to get there should have been merged already. When merged, I think we should close this one in favour of the more specific determinism issues like the two linked above.

Mailing list summary On our mailing list this month:
  • Fay Stegerman let everyone know that she started a thread on the Fediverse about the problems caused by unreproducible zlib/deflate compression in .zip and .apk files and later followed up with the results of her subsequent investigation.
  • Long-time developer kpcyrd wrote that there has been a recent public discussion on the Arch Linux GitLab [instance] about the challenges and possible opportunities for making the Linux kernel package reproducible , all relating to the CONFIG_MODULE_SIG flag. [ ]
  • Bernhard M. Wiedemann followed-up to an in-person conversation at our recent Hamburg 2024 summit on the potential presence for Reproducible Builds in recognised standards. [ ]
  • Fay Stegerman also wrote about her worry about the possible repercussions for RB tooling of Debian migrating from zlib to zlib-ng as reproducibility requires identical compressed data streams. [ ]
  • Martin Monperrus wrote the list announcing the latest release of maven-lockfile that is designed aid building Maven projects with integrity . [ ]
  • Lastly, Bernhard M. Wiedemann wrote about potential role of reproducible builds in combatting silent data corruption, as detailed in a recent Tweet and scholarly paper on faulty CPU cores. [ ]

Towards a 100% bit-for-bit reproducible OS Bernhard M. Wiedemann began writing on journey towards a 100% bit-for-bit reproducible operating system on the openSUSE wiki:
This is a report of Part 1 of my journey: building 100% bit-reproducible packages for every package that makes up [openSUSE s] minimalVM image. This target was chosen as the smallest useful result/artifact. The larger package-sets get, the more disk-space and build-power is required to build/verify all of them.
This work was sponsored by NLnet s NGI Zero fund.

Distribution work In Debian this month, 14 reviews of Debian packages were added, 12 were updated and 20 were removed, all adding to our knowledge about identified issues. A number of issue types were updated as well. [ ][ ] In addition, Holger opened 4 bugs against the debrebuild component of the devscripts suite of tools. In particular:
  • #1081047: Fails to download .dsc file.
  • #1081048: Does not work with a proxy.
  • #1081050: Fails to create a debrebuild.tar.
  • #1081839: Fails with E: mmdebstrap failed to run error.
Last month, an issue was filed to update the Salsa CI pipeline (used by 1,000s of Debian packages) to no longer test for reproducibility with reprotest s build_path variation. Holger Levsen provided a rationale for this change in the issue, which has already been made to the tests being performed by tests.reproducible-builds.org. This month, this issue was closed by Santiago R. R., nicely explaining that build path variation is no longer the default, and, if desired, how developers may enable it again. In openSUSE news, Bernhard M. Wiedemann published another report for that distribution.

diffoscope diffoscope is our in-depth and content-aware diff utility that can locate and diagnose reproducibility issues. This month, Chris Lamb made the following changes, including preparing and uploading version 278 to Debian:
  • New features:
    • Add a helpful contextual message to the output if comparing Debian .orig tarballs within .dsc files without the ability to fuzzy-match away the leading directory. [ ]
  • Bug fixes:
    • Drop removal of calculated os.path.basename from GNU readelf output. [ ]
    • Correctly invert X% similar value and do not emit 100% similar . [ ]
  • Misc:
    • Temporarily remove procyon-decompiler from Build-Depends as it was removed from testing (via #1057532). (#1082636)
    • Update copyright years. [ ]
For trydiffoscope, the command-line client for the web-based version of diffoscope, Chris Lamb also:
  • Added an explicit python3-setuptools dependency. (#1080825)
  • Bumped the Standards-Version to 4.7.0. [ ]

Other software development disorderfs is our FUSE-based filesystem that deliberately introduces non-determinism into system calls to reliably flush out reproducibility issues. This month, version 0.5.11-4 was uploaded to Debian unstable by Holger Levsen making the following changes:
  • Replace build-dependency on the obsolete pkg-config package with one on pkgconf, following a Lintian check. [ ]
  • Bump Standards-Version field to 4.7.0, with no related changes needed. [ ]

In addition, reprotest is our tool for building the same source code twice in different environments and then checking the binaries produced by each build for any differences. This month, version 0.7.28 was uploaded to Debian unstable by Holger Levsen including a change by Jelle van der Waa to move away from the pipes Python module to shlex, as the former will be removed in Python version 3.13 [ ].

Android toolchain core count issue reported Fay Stegerman reported an issue with the Android toolchain where a part of the build system generates a different classes.dex file (and thus a different .apk) depending on the number of cores available during the build, thereby breaking Reproducible Builds:
We ve rebuilt [tag v3.6.1] multiple times (each time in a fresh container): with 2, 4, 6, 8, and 16 cores available, respectively:
  • With 2 and 4 cores we always get an unsigned APK with SHA-256 14763d682c9286ef .
  • With 6, 8, and 16 cores we get an unsigned APK with SHA-256 35324ba4c492760 instead.

New Gradle plugin for reproducibility A new plugin for the Gradle build tool for Java has been released. This easily-enabled plugin results in:
reproducibility settings [being] applied to some of Gradle s built-in tasks that should really be the default. Compatible with Java 8 and Gradle 8.3 or later.

Website updates There were a rather substantial number of improvements made to our website this month, including:

Upstream patches The Reproducible Builds project detects, dissects and attempts to fix as many currently-unreproducible packages as possible. We endeavour to send all of our patches upstream where appropriate. This month, we wrote a large number of such patches, including:

Reproducibility testing framework The Reproducible Builds project operates a comprehensive testing framework running primarily at tests.reproducible-builds.org in order to check packages and other artifacts for reproducibility. In September, a number of changes were made by Holger Levsen, including:
  • Debian-related changes:
    • Upgrade the osuosl4 node to Debian trixie in anticipation of running debrebuild and rebuilderd there. [ ][ ][ ]
    • Temporarily mark the osuosl4 node as offline due to ongoing xfs_repair filesystem maintenance. [ ][ ]
    • Do not warn about (very old) broken nodes. [ ]
    • Add the risc64 architecture to the multiarch version skew tests for Debian trixie and sid. [ ][ ][ ]
    • Mark the virt 32,64 b nodes as down. [ ]
  • Misc changes:
    • Add support for powercycling OpenStack instances. [ ]
    • Update the fail2ban to ban hosts for 4 weeks in total [ ][ ] and take care to never ban our own Jenkins instance. [ ]
In addition, Vagrant Cascadian recorded a disk failure for the virt32b and virt64b nodes [ ], performed some maintenance of the cbxi4a node [ ][ ] and marked most armhf architecture systems as being back online.

Finally, If you are interested in contributing to the Reproducible Builds project, please visit our Contribute page on our website. However, you can get in touch with us via:

6 October 2024

Bits from Debian: Bits from the DPL

Dear Debian community, this are my bits from DPL for September. New lintian maintainer I'm pleased to welcome Louis-Philippe V ronneau as a new Lintian maintainer. He humorously acknowledged his new role, stating, "Apparently I'm a Lintian maintainer now". I remain confident that we can, and should, continue modernizing our policy checker, and I see this as one important step toward that goal. SPDX name / license tools There was a discussion about deprecating the unique names for DEP-5 and migrating to fully compliant SPDX names. Simon McVittie wrote: "Perhaps our Debian-specific names are better, but the relevant question is whether they are sufficiently better to outweigh the benefit of sharing effort and specifications with the rest of the world (and I don't think they are)." Also Charles Plessy sees the value of deprecating the Debian ones and align on SPDX. The thread on debian-devel list contains several practical hints for writing debian/copyright files. proposal: Hybrid network stack for Trixie There was a very long discussion on debian-devel list about the network stack on Trixie that started in July and was continued in end of August / beginning of September. The discussion was also covered on LWN. It continued in a "proposal: Hybrid network stack for Trixie" by Lukas M rdian. Contacting teams I continued reaching out to teams in September. One common pattern I've noticed is that most teams lack a clear strategy for attracting new contributors. Here's an example snippet from one of my outreach emails, which is representative of the typical approach: Q: Do you have some strategy to gather new contributors for your team? A: No. Q: Can I do anything for you? A: Everything that can help to have more than 3 guys :-D Well, only the first answer, "No," is typical. To help the JavaScript team, I'd like to invite anyone with JavaScript experience to join the team's mailing list and offer to learn and contribute. While I've only built a JavaScript package once, I know this team has developed excellent tools that are widely adopted by others. It's an active and efficient team, making it a great starting point for those looking to get involved in Debian. You might also want to check out the "Little tutorial for JS-Team beginners". Given the lack of a strategy to actively recruit new contributors--a common theme in the responses I've received--I recommend reviewing my talk from DebConf23 about teams. The Debian Med team would have struggled significantly in my absence (I've paused almost all work with the team since becoming DPL) if I hadn't consistently focused on bringing in new members. I'm genuinely proud of how the team has managed to keep up with the workload (thank you, Debian Med team!). Of course, onboarding newcomers takes time, and there's no guarantee of long-term success, but if you don't make the effort, you'll never find out. OS underpaid The Register, in its article titled "Open Source Maintainers Underpaid, Swamped by Security, Going Gray", summarizes the 2024 State of the Open Source Maintainer Report. I find this to be an interesting read, both in general and in connection with the challenges mentioned in the previous paragraph about finding new team members. Kind regards Andreas.

4 October 2024

Jonathan Dowland: synths

Although I've never written about them, I've been interested in music synthesisers for ages. My colleagues know this. Whilst I've been off sick, they had a whip-round and bought me a voucher for Andertons, a UK-based music store, to cheer me up. I'm absolutely floored by this generosity. And so, I'm now on a quest to buy a synthesizer! Although, not my first one.
Alesis Micron on my desk, taunting me Alesis Micron on my desk, taunting me
I bought my first synth, an Alesis Micron, from a colleague at $oldjob, 16 years ago. For various reasons, I've struggled to engage with it, and it's mostly been gathering dust on my desk in all that time. (I might write more about the Micron in a later blog post). "Bad Gear" sums it up better than I could:
So, I'm not truly buying my "first" synth, but for all intents and purposes I'm on a similar journey to if I was, and I thought it might be fun to write about it. Goals I want something which has as many of its parameters presented physically, as knobs or sliders etc., as possible. One reason I've failed to engage with the Micron (so far) is it's at the other end of this spectrum, with hundreds of tunable parameters but a small handful of knobs. To change parameters you have to go diving into menus presented on a really old-fashioned, small LCD display. If you know what you are looking for, you can probably find it; but if you just want to experiment and play around, it's off-putting. Secondly, I want something I can use away from a computer, as much as possible. Computers are my day-job, largely dominate my existing hobbies, and are unavoidable even in some of the others (like 3d printing). Most of the computers I interact with run Linux. And for all its strengths, audio management is not one of them. If I'm going to carve out some of my extremely limited leisure time to explore this stuff, I don't to spend any of it (at least now) fighting Pulseaudio/ALSA/Pipewire/JACK/OSS/whatever, or any of the other foibles that might crop up1. Thirdly, I'd like something which, in its soul, is an instrument. You can get some amazing little synth boxes with a huge number of features in them. Something with a limited number of features but which really feels well put together would suit me better. So next time, I'll write about the 2-3 top candidates on my list. Can you guess what they might be?

  1. To give another example. The other day I sat down to try and use the Micron, which had its audio out wired into an external audio interface, in turn plugged into my laptop's Thunderbolt dock. For a while I couldn't figure out why I couldn't hear anything, until I realised the Thunderbolt dock was having "a moment" and not presenting its USB devices to the laptop. Hobby time window gone!

3 October 2024

Mike Gabriel: Creating (a) new frontend(s) for Polis

After (quite) a summer break, here comes the 4th article of the 5-episode blog post series on Polis, written by Guido Berh rster, member of staff at my company Fre(i)e Software GmbH. Have fun with the read on Guido's work on Polis,
Mike
Table of Contents of the Blog Post Series
  1. Introduction
  2. Initial evaluation and adaptation
  3. Issues extending Polis and adjusting our goals
  4. Creating (a) new frontend(s) for Polis (this article)
  5. Current status and roadmap
4. Creating (a) new frontend(s) for Polis Why a new frontend was needed... Our initial experiences of working with Polis, the effort required to implement more invasive changes and the desire of iterating changes more rapidly ultimately lead to the decision to create a new foundation for frontend development that would be independent of but compatible with the upstream project. Our primary objective was thus not to develop another frontend but rather to make frontend development more flexible and to facilitate experimentation and rapid prototyping of different frontends by providing abstraction layers and building blocks. This also implied developing a corresponding backend since the Polis backend is tightly coupled to the frontend and is neither intended to be used by third-party projects nor supporting cross-domain requests due to the expectation of being embedded as an iframe on third-party websites. The long-term plan for achieving our objectives is to provide three abstraction layers for building frontends: The Particiapp Project Under the umbrella of the Particiapp project we have so far developed two new components: Both the participation frontend and backend are fully compatible and require an existing Polis installation and can be run alongside the upstream frontend. More specifically, the administration frontend and common backend are required to administrate conversations and send out notifications and the statistics processing server is required for processing the voting results. Particiapi server For the backend the Python language and the Flask framework were chosen as a technological basis mainly due to developer mindshare, a large community and ecosystem and the smaller dependency chain and maintenance overhead compared to Node.js/npm. Instead of integrating specific identity providers we adopted the OpenID Connect standard as an abstraction layer for authentication which allows delegating authentication either to a self-hosted identity provider or a large number of existing external identity providers. Particiapp Example Frontend The experimental example frontend serves both as a test bed for the client library and as a tool for better understanding the needs of frontend designers. It also features a completely redesigned user interface and results visualization in line with our goals. Branded variants are currently used for evaluation and testing by the stakeholders. In order to simplify evaluation, development, testing and deployment a Docker Compose configuration is made available which contains all necessary components for running Polis with our experimental example frontend. In addition, a development environment is provided which includes a preconfigured OpenID Connect identity provider (KeyCloak), SMTP-Server with web interface (MailDev), and a database frontend (PgAdmin). The new frontend can also be tested using our public demo server.

Next.

Previous.