I ve decided it s time to tag a v0.1.0 release on my roguelike game project, Stagger. It s more of a small demo than a full game at this point. It is turn-based, and has purely text-based graphics , like the original Rogue.
Here s a screenshot :
This post will be updated in the next weeks with the test results as
they become available.
Note
Most of the images in this post have no real alt-text: they are all
scans of the test sheet at various stages through the test, and the
results visible on them are described in detail at the end of the
post.
Most of the time, what people write by hand will either end up inside a
notebook in a drawer or cupboard where it s well protected, or thrown in
the recycling where it doesn t matter.
There are times, however, when things will be exposed to light: it
doesn t matter whether it s a work of artistic calligraphy that you want
to frame or a passive-aggressive notice left in the atrium of a
building; it is useful to know whether the work will remain legible or
it will fade into nothing in a short time.
A few inks are tested by the producers for lightfastness according to
some established standard, a few others are declared lightfast in a
generic way, but a lot come with no indication at all.
Proper testing according to the standard scales requires significant
equipment to precisely control the exposure, but it s significantly
easier and fun to do a simple test to divide the inks into three
categories:
suitable for framed calligraphy, i.e. it looks the same after 3 months
of direct sun exposure;
suitable for complaining about the way your neighbours deal with the
trash, i.e. still readable after 3 months of exposure;
not suitable for either, i.e. has faded significantly in the same time.
In the past I ve done some such tests by taping some sheets to a
south-east facing window, and I ve noticed that most of the results were
already apparent after a month, and there was basically no difference
between two and three months of exposure, but spring equinox to summer
solstice is a nice timeframe to use for such a test (and it leaves time
for a second test of different materials from summer solstice to autumn
equinox), so this is what I ve chosen to do this year.
Rather than a window, now I have access to a south-facing covered
balcony that is protected from rain but receives quite a bit of direct
sun, so instead of taping sheets to the windows1 I ve prepared a
sturdy cardboard panel that I can leave on a table on the balcony,
hopefully safe from the rain, but well exposed to the sun.
And then made a quick test, and realized that without the window glass
in front, the black strip used to cover the unexposed half of the sample
doesn t lay flat and lets some sun in, so I used an old cheap2
glass frame instead of the panel.
The next step, already in January, was mentioning in a fountain-pen
enthusiasts forum that I planned such a test, and asking if people were
interested in having me buy a few samples of more inks when I was
buying my next pen.
The word enthusiasts is probably a hint of the reason why soon
afterwards I received a package with the pen I had planned to buy, its
converter, and a couple dozens ink samples.
And then a couple envelopes with additional samples of inks that weren t
available on the shops, from said enthusiasts.
Added to the inks I already had acquired since the last lightfastness
test, it meant that they couldn t all fit in one single page, and thus I
had some room to add some inks I had already tested: some were requests,
and for others I tried to select ones that felt relevant.
Since I m changing the test setup, I ve decided I should probably keep
doing this until I ve tested again all of the inks I still have
available.
For the paper, I ve used A4 sheets of Clairefontaine Dessin Croquis
160 g/m ,
one of my staples that I m sure I will have available in the next years,
printed with a dot pattern with a laser printer, using this pdf.
And as for the pen I ve used a fresh Brause n 361 nib: loading a fountain pen
with all of these inks wouldn t be a reasonable effort, and the 361 is
one of the writing implements I use most anyway. I also used a glass pen
to fill a couple of squares on the paper with more ink.
One side of each sheet was then covered with a strip of 300 g/m black
paper (also from Clairefontaine), kept in place with three dots of
non-permanent two sided tape, put in the frame and set out in the sun on
the morning of 2026-03-20, the day of the spring equinox.
While I was filling the sheet for the lightfastness tests, I decided to
also prepare a second set of sheet, for a liquid resistance drop test.
On each line, beside the name of the ink, I added five sets of crossing
parallel lines, and let everything dry for a few days.
Then I used a syringe to put a drop of a liquid on each set of lines,
waited for it to be absorbed into the paper and to dry, at least
overnight, but sometimes also for a day or two (life happened), and then
looked at the results and did the next test.
The first liquid was water, with the usual wild difference between
washable and permanent inks, and all of the intermediate possibilities.
The second liquid was isopropyl alcohol, and I was surprised to see
that, with very few exceptions, most inks didn t change at all. I
wonder whether that s related to the fact that instead of forming a drop
it was absorbed almost immediately into the paper, and dried in a very
short time.
The third liquid was hydrogen peroxide: beside the individual results I
noticed that its column yellowed visibly; I wonder whether that means
that the paper I used has optical brighteners, and it will also yellow
under the sun: that wouldn t be ideal, but it would also be a surprise,
for paper that is acid free and sold for arts.
The fourth liquid was citric acid, by mixing a bit less than a teaspoon
of citric acid granules in just enough very warm water (heated to 70 C,
i.e. the lowest temperature available on my kettle) to dissolve most of
the acid. I forgot that I had some old PH strips until one hour after
I ve put the drop on the paper, and I don t know whether something had
changed, but when I did remember about them it showed a deep red between
1 and 2. I don t think I can trust those strips too much, however.
This backfired badly: the drop of citric acid never dried out, but
formed a sticky paste that prevented me from scanning the results,
and I m not sure whether I ll do the last test, which was supposed to be
household bleach.
Luckily I had scanned the partial results, and they are shown here.
After one full day with plenty of sun, nothing really had changed,
except possibly for a vague hint that the Herbin Bleu Myosotis may have
have been a bit lighter than it started, but it may also have been a
suggestion.
After three days, however, some results started to show, with the most
fugitive inks starting to be visibly changed, becoming either paler or
in some case duller.
And the full week showed more of that, with a few more inks starting to
show visible change.
After two weeks the paper had significantly yellowed, something I did
not expect from drawing paper (and which means that I will probably use
a different paper when making similar tests in the future).
As for the inks, there were a couple more inks with visible changes, but
mostly it was more of the same as seen in the previous week.
Three weeks started to show changes in the black and most irongall inks, and of course more changes in the even less resistant inks.
Week four saw a bit more clouds and rain than the first few weeks, and
there weren t big changes, but mostly more of what had already started
to happen earlier.
A month didn t change much compared to the four weeks, but I did the
scans for completeness, and from now on I m going to update monthly.
These are the inks I ve tested, and here I ll add notes on the results,
as soon as they will be available, keeping this section updated.
When nothing is mentioned, it means that there were no changes, either
under the light or under the various liquids.
Lamy Sepia
Not resistant to water, the drop becomes an uniform colour spot.
After one week it started to be just slightly paler, more so after
three weeks.
Sheaffer Skrip Red
Not resistant to water, the drop becomes an uniform colour spot.
After one week it started to be just slightly paler, more so after
three weeks.
Waterman Audacious Red
Not resistant to water, the drop becomes an uniform colour spot.
After three days it started to be just slightly paler, after a week
visibly so. After four weeks it was very pale.
Waterman Harmonious Green
Not resistant to water, the drop becomes an uniform colour spot; the
hydrogen peroxide drop looks a bit lighter than the one with just
water.
After one week it started to be just slightly paler, more so after
three weeks. After four weeks it was very pale.
Waterman Mysterious Blue
Not resistant to water, the drop becomes an uniform colour spot; the
hydrogen peroxide drop is significantly lighter and tends towards
green.
After two weeks it started to be just slightly paler, after three
weeks it was more gray. After four weeks it was very pale.
Waterman Serenity Blue
Not resistant to water, the drop becomes an uniform colour spot; the
hydrogen peroxide drop is almost completely bleached to a light yellow.
After one week it started to be a bit duller. After four weeks it was
paler and duller.
Visconti Blue
Not resistant to water, the drop becomes an uniform colour spot.
After one week it was visibly duller, looking darker than the
original. After three weeks it was duller, and lighter. After a month
it was just a pale gray.
Montblanc Royal Blue
Not resistant to water, the drop becomes an uniform colour spot; the
hydrogen peroxide drop is almost completely bleached to a light
yellow.
After one week it started to be just slightly duller, more so after
two weeks. After three weeks it was also paler. After a month it was
just a pale gray.
Montblanc Mystery Black
Not resistant to water, the drop becomes an uniform colour spot.
After three weeks it started to be a bit paler.
Aurora Nero
Not resistant to water, the drop becomes an uniform colour spot.
After three weeks it started to be a bit more brown.
Online Duft Blueberry
Not resistant to water, the drop looks very washed out, although a
hint of the original shape can be guessed; the hydrogen peroxide drop
is almost completely bleached to a light yellow.
After one week it was visibly paler and duller. After three weeks
significantly so. After a month it was a pale grey.
Diamine Forever Ink - Smoky Mauve
After a month it looked a bit more purple.
Diamine Forever Ink - Honey Pot
.
Diamine Forever Ink - Coral Blaze
.
Diamine Forever Ink - Red Ochre
.
Diamine Graphite
Not resistant to water, the drop becomes an uniform colour spot.
Diamine Rustic Brown
Not resistant to water, the drop becomes an uniform colour spot.
After three weeks it started to be very slightely paler.
Diamine China Blue
Not resistant to water, the drop becomes an uniform colour spot; the
hydrogen peroxide drop is almost completely bleached to a light
yellow.
After three weeks it started to be paler and duller.
Diamine Inkvent Purple Edition - Glacier
Not resistant to water, there is a drop of uniform colour, but it
maintains a somewhat recognisable shade of the original shape.
After three weeks it started to be lighter.
Fountainfeder STEVE
Not resistant to water, there is a drop of uniform colour, but it
maintains a somewhat recognisable shade of the original shape.
After two weeks the base colour had changed to a pink rather than
purple.
Pilot Iroshizuku Syo Ro
Not resistant to water, there is a drop of uniform colour, but it
maintains a somewhat recognisable shade of the original shape.
After four weeks it was very slightely paler.
Pilot Iroshizuku Shin-Kai
Not resistant to water, there is a drop of uniform colour, but it
maintains a somewhat recognisable shade of the original shape.
After two weeks it had become lighter and more purple. After four
weeks it was a purple gray.
Rohrer & Klingner IG Ebony
Not resistant to water, there is a drop of uniform colour, but it
maintains a recognisable shade of the original shape; under
hydrogen peroxide the shade is significantly lighter.
After four weeks it was a bit lighter
KWZ IG Orange
Not resistant to water, the drop becomes an uniform colour spot; the
hydrogen peroxide drop is significantly bleached to a light orange.
Kallipos.de Schwarze Eisengallus-Tinte
Water stains the paper, leaving however the original shape quite
visible; is it almost completely bleached by hydrogen peroxide.
After three weeks it started to be very slightely lighter.
Kallipos.de Blaue Eisengallus-Tinte
Water stains the paper, leaving however the original shape quite
visible; is it almost completely bleached by hydrogen peroxide.
After two weeks it had started to become lighter and more gray.
Rohrer & Klingner IG Salix
Water stains the paper, leaving however the original shape quite
visible; is it almost completely bleached by hydrogen peroxide.
After two weeks it had become lighter and significantly more gray.
After a month it was a yellowish gray.
Rohrer & Klingner IG Scabiosa
Water stains the paper with a significant purple spot, leaving
however the original shape quite visible; is is a bit bleached by
hydrogen peroxide, but still quite readable.
Pelikan Edelstein Tanzanite
Not resistant to water, the drop becomes an uniform colour spot, but
there is a visible trace of the original shape.
After three weeks it started to be slightly paler.
Montblanc Burgundy Red
Not resistant to water, the drop becomes an uniform colour spot, with
just a hint of the original shape; slightly bleached by hydrogen
peroxide.
After three weeks it started to be paler.
Cifra inchiostro finissimo verde alla lavanda
Not resistant to water, the drop becomes an uniform colour spot;
quite bleached to a light yellowish green by hydrogen peroxide.
After one week it was visibly paler. After a month it was a still
readable pale trace.
Sennelier Abstract acrylic ink 917 purple
.
The Feather Pen Ink
.
Eloquentia Inchiostro nero
.
DeAtramentis Document Blue
.
DeAtramentis Document BlueGrey
.
DeAtramentis Document Brown
.
DeAtramentis Document Fuchsia
.
DeAtramentis Document Grau
.
DeAtramentis Document Green Grey
.
DeAtramentis Document Light Grey
.
DeAtramentis Document Moosgr n
.
DeAtramentis Document Orange
.
DeAtramentis Document Purpurviolett
.
DeAtramentis Document Urban Sienna
.
KWZ Sheen Machine
Not resistant to water, the drop becomes an uniform colour spot; the
hydrogen peroxide bleached away the red sheen. This was one of the
only two inks to react to isopropyl alcohol, which caused a pale cyan
halo around the lines.
After three days it was still perfectly readable, but had visibly
lost some red sheen, after one week the red had completely gone and
it looked very dark blue (but still shiny)
KWZ Walk over Vistula
Not resistant to water, the drop becomes an uniform colour spot.
After four weeks it looked a bit darker and duller.
KWZ Warsaw Dreaming
Not resistant to water, the drop becomes an uniform colour spot.
After a month it started to be a bit lighter.
Octopus Neon Violett
Water very lightly stains the paper, leaving however the original
shape quite visible. The other ink that reacted to isopropyl alcohol,
with a pale purple halo around the lines.
After two weeks it was paler, more pink.
Octopus Write & Draw Elephant Black
.
Platinum blue black
Water stains the paper, leaving however the original shape quite
visible; it is significantly bleached by hydrogen peroxide.
After three weeks it started to become gray.
Pelikan 4001 Brillant-Schwarz
Not resistant to water, the drop becomes an uniform colour spot.
After three weeks it was a bit more brown than black, after a month
noticeably so.
Pelikan 4001 Blau-Schwarz
Water stains the paper, leaving however the original shape quite
visible; it is significantly bleached by hydrogen peroxide.
After three weeks it started to become gray.
Pelikan 4001 K nigsblau
Not resistant to water, the drop becomes an uniform colour spot, with
just a hint of the original shape; significantly bleached by hydrogen
peroxide.
After three days it had started to be slightly paler.
After three weeks it was significantly desaturated.
Herbin Bleu Myosotis
Not resistant to water, the drop becomes an uniform pink spot,
significantly bleached by hydrogen peroxide.
After three days it was already visibly paler, after one week it was
a pale grey. After a month it was still somehow readable, but as a
trace.
Faber Castell Royal Blue
Not resistant to water, the drop becomes an uniform colour spot, with
just a hint of the original shape; significantly bleached by hydrogen
peroxide.
After three days it was slightly duller, after two weeks definitely
so. After a month it was also quite paler.
Koh-I-Noor Fountain pen ink blue
Not resistant to water, the drop becomes an uniform colour spot, with
just a hint of the original shape; significantly bleached by hydrogen
peroxide.
After three days it had started to be slightly paler, more so after
one week when it had also turned grey. After four weeks it was very
pale.
Koh-I-Noor Document Ink Blue
.
Koh-I-Noor Document Ink Black
Water leaves a very light stain, but the original shape doesn t look
changed.
DeAtramentis Document Black
.
Waterman Intense Black
Not resistant to water, the drop becomes an uniform colour spot, with
a trace of the original shape still visible; very lightly bleached by
hydrogen peroxide.
After three weeks it started to look a bit more brown, noticeably so
after a month.
Herbin Perle Noir
Not resistant to water, the drop becomes an uniform colour spot, with
a trace of the original shape still visible.
After three weeks it started to look a bit more brown, noticeably so
after a month.
Parker Quink black
Not resistant to water, the drop becomes an uniform colour spot.
Platinum Carbon black
.
Rohrer & Klingner Documentus Black
.
Sailor Pigment Kiwaguro
.
Platinum Dyestuff Red
Not resistant to water, the drop becomes an uniform colour spot; very
lightly bleached by hydrogen peroxide.
After three weeks it was a bit paler.
Noodler s Eternal Polar Blue
.
which would be spend the day covered by mostly closed
shutters anyway, because they receive quite a bit of direct sun, and
we don t want that to enter the house during the summer.
I was reading a post on Alex Chan's
website1 that referenced the concept of
digital gardens,
a concept/analogy for organising information which dates back to the 90s.
This old concept is getting new traction today by contrasting the approach
with "endless stream" as used and abused by social media, but also how blogs
are typically presented.
This site, my homepage, has a blog, and that's the bit that most people who
interact with the site will experience. Partly, because it's the bit that gets
syndicated out: via feeds; on Planet
Debian and downstream from it; once upon a time on
Twitter; nowadays on the Fediverse.
However there's more to my homepage than that. The rest of it may be of little
interest to anyone beside me, but it's useful to me, at least. So I may switch
focus a little bit from mainly writing blog posts, and tend to the rest of the
garden a bit more.
Some recent seeding and pruning:
Recently my guest status at Newcastle University came up for renewal, so I
wrote down my goals in the Historic Computing Committee for the next year or
so, and put them here: nuhcc. I've also been pondering what I'm up to in
Debian at the moment, so took some time to add my current projects to
that page.
I'm reminded that I should really publish a "blog roll" of cool
blogs I'm following at the moment, of which Alex Chan's is one.
Interested in future updates? Follow me on mastodon at
@paul@soylent.green. Posts about
hz.tools will be tagged
#hztools.
It s well known and universally agreed that radios are cool. Among the
contested field of coolest radios, Software Defined Radios (SDRs) are
definitely the most interesting to me. Out of all of my (entirely too many)
SDRs I own, the rtlsdr is still my #1. It s just good. It s a great price,
extremely capable, reliable, well-supported, and compact. Why bother with
anything else? Sure, it can t transmit, uses a (fairly weird) 8 bit unsigned
integer IQ representation,
limited sampling rate, limited frequency range but even with all that, it s
still the radio I will pack first. Don t get me wrong, I love my Ettus radios,
PlutoSDRs, HackRFs, my AirspyHF+ - they re great! I just always find myself
falling back to an rtl-sdr, every time.
Perhaps the best reason to use an rtlsdr is the absolutely mind-boggling
amount of cool stuff people have written for it. The rtlsdr API is super easy
to use, widely supported if you re building on top of existing radio processing
frameworks it s still a shock to me when something omits rtlsdr support.
sparky
Over the last 7 years, I ve been learning about radios I got my ham radio
license (de K3XEC), hackedonsomecoolstuff where I ve
learned how radios work by doing , and even was lucky enough to give my first
rf-centric talk at districtcon.
Embarrassingly, I still haven t gotten around to learning how the fancy stuff
like GNU Radio works. I m sure I m going to love
it when I do.
As part of this, I ve also cooked up some very unprofessional formats and
protocols I use for convenience. Locally, all my on-disk captures are stored in
rfcap or more recently arf,
while direct SDR access at my house is almost entirely a mix of
the widely used rtl-tcp protocol, and my
riq protocol (post on this coming soon). Both rtl-tcp and riq operate
over the network, so I don t have to bother with plugging things into USB ports,
and I can share my radios with my friends.
All of that work sits in my current generation of radio processing code,
sparky (a reference to
spark-gap transmitters),
which is a heap of Rust, supporting everything from no_std for embedded
experiments, conditional support for interfacing with all the radios I
own, and tokio-based async support in addition to blocking i/o
for highly concurrent daemons. This quickly advanced beyond my old Go-based
code (hz.tools/go-sdr), which I archived
so I can focus on learning. I still think Go is a great language to write RF
code in but I can t focus on that tech tree anymore.
Of course, this now poses a new problem no one supports my format(s) or
radio protocol(s), since, well, I m the only one using them. I ve committed a
fair amount of my hardware to this setup, and yanking it from the rack to try
something out does pose a bit of a pickle. This isn t a huge deal for learning,
but it does make it tedious to try out something from the internets.
librtlsdr.so
Thankfully, Rust has robust support for
wrap[ping itself] in a grotesque simulacra of C s skin and mak[ing its] flesh undulate,
which is an attractive nuisance if i ve ever seen one. Naturally, my ability
to restrain myself from engaging in ill-advised rf adventures is basically
zero, so it s time to do the thing any similarly situated person would do
reimplement the API and ABI of librtlsdr.so, backed with sparky instead.
Since enumeration of devices is going to be annoying (specifically, they re
over the network), I decided early-on to rely on an explicit list of
devices via a configuration file. I d rather only load that once so programs
don t get confused, so I opted to use a
CTOR
to run a stub when the ELF is linked at runtime.
Next, it s time to start with the basics. Opening and closing a handle using
rtlsdr_open and rtlsdr_close. Given we don t control the runtime, and the
rtl-sdr device handle is opaque (for good reason!), I opted to smuggle a rust
Box<Device> non-FFI safe heap-allocated struct through the device handle
pointer, and let C take ownership of the Box. No one should be looking in
there anyway.
With that in place, we can chip away at the API surface, translating calls
as best as we can. I won t bother listing it all, since it s not very
interesting but here s an example implementation of rtlsdr_set_sample_rate
and rtlsdr_get_sample_rate. These calls are translating from an rtl-sdr
frequency (which is a u32 containing the value as Hz) into a sparky Frequency
type, and invoking get_sample_rate or set_sample_rate on the device s
rust handle. Since each device implements the sparky Sdr trait, the actual
underlying device doesn t matter much here.
After repeating this process for the rest of the stubs I could (and otherwise
setting error conditions if the functionality is not supported), I was ready to
try it out. Within sparky, I patched my MockSDR (basically a Sdr traited
Mock type) to implement the same testmode IQ protocol that the RTL-SDR has, and
decided to see if rtl_test from apt without any changes could be fooled.
$ rtl_test
No supported devices found.
Great, cool. No devices plugged in. Looks great. Let s try it with my
librtlsdr.soLD_PRELOAD-ed into the binary first:
$ LD_PRELOAD=target/release/librtlsdr.so rtl_test
Found 1 device(s):
 0: hz.tools, mock sdr, SN: totally legit no tricks

Using device 0: sparky mock sdr
Supported gain values (0):
Sampling at 2048000 S/s.

Info: This tool will continuously read from the device, and report if
samples get lost. If you observe no further output, everything is fine.

Reading samples in async mode...
^CSignal caught, exiting!

User cancel, exiting...
Samples per million lost (minimum): 0
$
Outstanding. Even more outstandingly, if I change my testmode implementation to
skip samples, rtl_test correctly reports the errors I think it s showing
promise! On to try the real endgame here let s have our new librtlsdr.so
connect to an rtl-tcp endpoint and see if rtl_fm works:
LD_PRELOAD=target/release/librtlsdr.so \
 rtl_fm -d 1 -s 120k -E deemp -M fm -f 90.9M   \
 ffplay -f s16le -ar 120k -i -
Found 2 device(s):
 0: hz.tools, mock sdr, SN: totally legit no tricks
 1: hz.tools, rtl-tcp, SN: node2.rf.lan:1202

Using device 1: sparky rtltcp node2
Tuner gain set to automatic.
Tuned to 91170000 Hz.
Oversampling input by: 9x.
Oversampling output by: 1x.
Buffer size: 7.59ms
Sampling at 1080000 S/s.
Output at 120000 Hz.
And there it was! Not the best audio quality (mostly due to my inability to
correctly read the rtl_fm manpage to tune the filter and
downsample/oversampling rates to audio), but it s definitely passable.
I figured I d try something that was a bit more interesting next gqrx,
since it s super handy, I use it a ton, and will definitely amuse me to no
end. To my surprise and delight, LD_PRELOAD=target/release/librtlsdr.so gqrx
wound up running, and I saw my devices pop right up in the setting menu:
Huge. Huge. Amazing. It did crash as soon as I tried to actually use the
radio, but after fixing a few dangling bugs in the API surface (and some
assumptions I think some underlying gnuradio driver may be making that I need
to double check in the code), I was able to get a super solid stream of
broadcast fm radio, with gqrx being none the wiser. It thought it was
just talking to the device it knows as rtl=1.
Nice. I can t wait to try this with the rest of the rtl-sdr based tools I like
having around using my riq protocol next. I don t think that ll be worth a
post, but hopefully I ll get around to publishing details on that stack next.
epilogue
Well. That s it. End of story. A bit anti-climatic, sure. While this new shim
will provide me endless minutes of mild amusement, I could see using this to
expose my sparky testing utilities via librtlsdr.so my mock sdr driver
allows for replaying captures off disk, which could be interesting to make sure
that signals are still properly decoded after changes, or instrument
performance changes (via SNR, BER, packets observed, etc) on reference samples
I have on my NAS. Maybe that ll come in handy one day!
Truth be told, I m not sure I actually want to encourage anyone to do this for
real (although I think I ll definitely be using it on my LAN to see what
happens). I also don t have a repo to share I don t particularly feel with
dealing with the secondary effects of publishing sparky (and sparky-rtlsdr)
yet, since i m still getting my feet under me on the radio aspect of all this.
I ll be sure to post updates if anything changes with this here (tagged
sparky) and at
@paul@soylent.green.
I can t wait to post more about some of the odd sidequests (like this one!)
i ve completed over the last few years I ve been waiting to feel
confident that my work has matured and was withstood the new problems i ve
thrown at it, and it largely has.
It s my hope that these projects (and this project in particular) has provided
a glimpse into the world of software defined radio for my systems friends, and
a bit about systems for my radio friends. It s not all magic, and I hope
someone out there feels inclined to have some fun with radios themselves!
A few months ago, in June 2025, I joined Chainguard, a company focused on software supply chain security.
This post is a reflection on how I got here, what I ve been doing, and why this role feels like a natural
fit for my interests in Linux and open source technology.
The company and its mission
Chainguard s mission is to make the software supply chain secure by default. The company is built around
the idea that the software we all depend on from operating system packages to container base images carries
hidden risk in the form of vulnerabilities, unverified provenance, and untrusted build processes.
The company is perhaps best known for Chainguard Images: a catalog of minimal, hardened container
base images that are continuously rebuilt and kept free of known CVEs. Each image is accompanied by a signed
SBOM (Software Bill of Materials) and a verifiable provenance attestation, making it possible
to cryptographically verify what went into a given image and how it was built.
Chainguard has an extensive catalog of software, and maintaining it up-to-date and CVE-free is a significant
engineering challenge.
What I do
I joined the Chainguard Sustaining Engineering team as a Senior Software Engineer. We are responsible
for maintaining packages and images in the software catalog up-to-date and CVE-free. The core of the business, basically.
We focus on the horizontal dimension of the catalog (pretty much all packages and images).
With +30,000 packages and +2,000 images, this is indeed an interesting task.
My role as Debian Developer, and my experiencie in the Debian LTS project was extremely valuable when joning this
new team.
Looking ahead
Software supply chain is truly a deep topic, gaining more and more relevance every day, especially as new technologies emerge
and get adopted everywhere.
Since early in my career, I saw a recurrent problem of how companies, enterprises, or even governments, relate to and consume
open source software, in a reliable, secure way. I believe Chainguard is doing the right things in the ecosystem,
and I m happy to be participating in the effort.
tl;dr
This is an experimental feature that, for the first time, brings full ECH
support to curl on Debian using OpenSSL.
Starting with curl 8.19.0-3+exp2 (Debian Experimental), you can now use
ECH, with HTTPS-RR and DoH for maximum privacy.
curl 8.19.0-3+exp2 is quite fresh at the time of writing, bear in mind that your
repository might not have synced the package yet, all mirrors should have it by
March 27th 14:00 UTC.
# defo.ie is a test server that confirms whether ECH was successfully usedcurl -v --ech hard https://defo.ie/ech-check.php# For Encrypted Client Hello (ECH) + DNS over HTTPS (DoH)curl -v --ech hard --doh-url https://1.1.1.1/dns-query https://defo.ie/ech-check.php
"--ech hard" tells curl to refuse the connection entirely if ECH cannot be negotiated.
Or, if you would like to try it out in a container:
podman run debian:experimental /bin/bash -c 'apt install --update -t experimental -y curl && curl -v --ech hard --doh-url https://1.1.1.1/dns-query https://defo.ie/ech-check.php'
(in case you haven't noticed, apt now has the --update option for the
upgrade and install commands)
For Privacy
CloudFlare calls it "the last puzzle piece to privacy" in their must-read
announcement: https://blog.cloudflare.com/announcing-encrypted-client-hello/.
Encrypted Client Hello (rfc9849) encrypts the
"which website are you connecting to?" part of the TLS handshake that was
previously visible in plaintext.
HTTPS-RR (rfc9460) is a DNS record type that
publishes connection parameters for a service, including the public key clients
need to perform ECH.
DNS Over HTTPS (rfc8484) encrypts DNS queries
by tunneling them over HTTPS, hiding what domains you're looking up from
network observers.
When all three operate together over a CDN with shared IP space, the target
domain name is hidden from passive observers; the HTTPS-RR record is queried
over DoH in order to retrieve the ECH key
(rfc9848) for the TLS handshake.
Seems like quite an important feature, and in fact the major browsers have it
enabled for some time now, the trick is that they do not use OpenSSL (Chrome
uses BoringSSL and Firefox uses NSS).
For everyone else, the only option is to patch OpenSSL or wait until 4.0.0 is
released, and so part of the reason Debian is the first distro to enable it
(curl + OpenSSL + ECH) is that the OpenSSL maintainer (Sebastian Andrzej
Siewior) packaged the alpha release just 3 days after it was published.
Do not forget that ECH support is experimental and currently relies on the
alpha release of OpenSSL.
wcurl Gets It Too
Considering wcurl is just a wrapper on curl, it gets
the feature for free:
wcurl --curl-options="--ech hard --doh-url https://1.1.1.1/dns-query" $URL
If you're using wcurl, you don't want to have to set parameters, this is just
to show that the feature is there and if you have a .curlrc file, it can
enable the feature seamlessly.
Other Debian Releases
Given the ECH feature requires OpenSSL >= 4, it will not make it to Debian 13,
having a small chance of going to Debian 13 Backports (emphasis on small).
It should get to Debian Unstable and Debian Testing within the next couple of
months as the OpenSSL GA release happens and gets packaged, but you should be
able to install the package from Experimental in your Unstable and Testing
systems without issues. It will also be in Debian 14 once it becomes the new Stable.
Shoulders of Giants
Stephen Farrell's presentation from OpenSSL Conference 2025 has a lot of
background on the work involved:
Encrypted Client Hello Lessons learned from trying to do something that was
probably too complicated
They have been working on implementing ECH in open-source projects for years,
something as big as this doesn't happen without lots of people dedicating both
their paid and free times over it.
I ended up being the person who enabled it on Debian, which was pretty much the
least amount of work between everyone involved, but hey it's fun flipping the
switch and telling you about it.
Background
Since 2025, the curl developers started organizing an yearly meeting with all
maintainers of curl in Operating Systems. The 2026 edition happened in March
26th:
https://github.com/curl/curl/wiki/curl-distro-discussion-2026.
Attendance was really good, and as you can imagine one of the topics of
discussion was ECH, in which it was pointed out that having OpenSSL 4 was
the main requirement but besides it nothing unusual was needed.
In Debian Experimental, we have been enabling HTTPS-RR since March 2025, and
OpenSSL 4.0.0 alpha was packaged just recently (2026-03-13) by Sebastian
Andrzej Siewior, it's time for the next step.
The curl distro meeting was just the motivation I needed to go ahead and
enable it in Debian Experimental, so as part of our Debian Brasil Weekly
Meetings I've prepared and uploaded the changes, while Carlos Henrique Lima
Melara worked on addressing a recent test regression for Debian Unstable.
Unfortunately sergiodj couldn't join and I'm sure he's jealous of the hacking
session now.
Appendix
While writing this, I've noticed one of the authors of the CloudFlare blogpost
is the previous curl maintainer on Debian; Alessandro Ghedini let me take over
the maintenance back in 2021 and today curl is maintained by a team of 4
people, it's nice to see Alessandro's involvement.
The LinuxCNC project continues
to thrive. I believe this great software system for numerical control
of machines such as milling machines, lathes, plasma cutters, routers,
cutting machines, robots, and hexapods would benefit even more from
in-person developer gatherings. Therefore, we plan to organise another
gathering this summer as well.
We invite you to a small LinuxCNC and free software fabrication
workshop/gathering in Norway this summer, over the weekend starting
June 26th, 2026. As last year, we maintain a slightly broader scope
and welcome people outside the LinuxCNC community. As before, we
suggest to organise it as an
unconference,
where participants create the program upon arrival.
The location is a metal workshop 15 minutes' drive from Gardermoen
airport (OSL), with plenty of space and a hotel just 5 minutes away by
car. We plan to fire up the barbecue in the evenings. Please let us
know if you would like to join. We track the list of participants on
a simple pad.
Please add yourself there if you are interested in joining.
Our friends over at the
TS Robotics
team at the University of Oslo have offered to handle any money
involved with this gathering, that is, holding sponsor funds and
paying the bills. We hope to secure enough sponsors to cover food, lodging,
and travel. So far, Debian has offered to sponsor part of the
expenses, which should cover food and a bit more. Please get in touch
if you would like to help sponsor the gathering.
As usual, if you use Bitcoin and wish to show your support of my
activities, please send Bitcoin donations to my address
15oWEoG9dUPovwmUL9KWAnYRtNJEkP1u1b.
At the end of last year I uninstalled the Twitter app on my phone.
In the past Twitter used to be very useful for providing feedback to large organisations. I had responses from supermarkets, chain restaurants, online stores, major computer companies, and even the IT department of a court. In recent times I have had less responses from corporations which significantly reduces the value of Twitter to me and to many other users. It seems that Elon s management style has discouraged not only advertising but also all forms of corporate interaction. Messing up the check mark on accounts to make it harder to work out which is a real corporate
Since Elon bought it Twitter has been increasingly pushing conservative Tweets and has done little to stop bot accounts. The incidence of useful discussions has steadily decreased. I know people who have quit Twitter entirely due to opposition to Elon, I am not doing that. I finally decided to stop using Twitter in any serious way when the notifications on my phone about popular Tweets started only being about Tweets from conservative influencers and Elon. This was obviously not any algorithm based on Tweets I was liking, it was based on political decisions. I didn t uninstall the app due to political disagreement, I uninstalled it because it was through deliberate design promoting material that any algorithm would know was something I wouldn t either like or like .
I still announce new blog posts on Twitter for my 198 followers at the same time as announcing them on Mastodon and Facebook. I get the most reactions to such announcements on Mastodon, the second most on Facebook, and hardly any on Twitter. I m wondering how long it will be worth announcing blog posts on Twitter or whether I should stop now.
I am sure that many other people are making similar decisions and this is going to affect Twitter overall.
The web site www.russellcoker.com has information on all the ways of following me.
AI sure is a hot topic right now, and I see a lot of people arguing about it. To a lot of people around here, I m the computer person they know and I get asked a lot about AI.
I m going to suggest a lot of things can be true at once. For instance:
LLMs are changing how we work and will continue to do so.
LLMs are vastly over-hyped by vested interests, and may be in a bubble.
Or how about:
Huge investment in GenAI is having many negative consequences, ranging from environmental to causing affordability problems in many industries that use hardware (ie, everywhere)
Useful results can be had from models that run on local hardware, even battery-powered hardware, which may have negligible harm or even some benefit
And:
GenAI is further concentrating wealth and power in megacorps, with the effect of squeezing out the smaller players even more.
GenAI is lowering the cost of entry for people without a lot of resources already.
I have sympathy for the naysayers; those that say it s nothing but a stochastic parrot. But I don t have a lot of sympathy for the naysayers that deny ever using it; you can t form a credible argument against something without having an understanding of it informed by experience.
I also have sympathy for the cheerleaders. I have seen some impressive things from AI; for instance, a story from an engineer who has a child with a rare disease without a credible cure. The engineer did a lot of research on it, started feeding research papers into AI to analyze, and the AI started finding correlations between different areas of research that humans hadn t yet found leading to a positive result for the child.
To be fair, I have rarely seen an AI deliver a 100% correct answer on anything with any real level of complexity. I have seen it both waste more time than it saves, and save a ton of time.
My point here is: It is neither always fantastic nor always terrible.
Let me talk you through an example.
I am a fan of inbox zero for email. That is, the inbox should be empty. Unfortunately, mine has 8000 messages in it. According to the oldest messages in my inbox, I last had inbox zero 8 years ago. But really, only a handful are older than 2020. I guess something must have happened that year
I ve been chipping away at this for quite some time now. The problem is, there are certain emails in there that really do still need some action maybe it s photos to save off into our photo collection, for instance. But when looking at things sorted by date or thread, there are old shipping confirmations next to phishing attempts and family photos. One can t just scan down the list.
I ve tried all the usual tricks, most of which involve selecting groups of message that are easy to bulk erase, or at least easy to scan visually for the occasional thing worth saving. Sort by sender or subject line, for instance. Then I can, for instance, delete all the old messages from the shopping sites I commonly use all at once. But then they start using different senders and different subject lines and that doesn t get all of them. I ve tried keyword searches for this sort of thing too. Still, that got me down to about 8000 messages.
So I thought: why not see if an LLM could help me classify these? Maybe it could categorize them, and then I could look at emails grouped by category.
I have one machine with a discrete GPU, an Nvidia RTX 4070. It s a desktop machine I don t use all that often. But I set up Ollama on it, running in a Docker container. Ollama runs models locally.
I should also mention at this point that we are solar-powered, and this time of year is a time of peak production of excess solar, because it is sunny and not much heat or AC is required. So that machine is solar-powered and isn t causing environmental harm. In any case, charging the EV uses much more power than that GPU.
I figured I would do this in two passes. First, ask the LLM to classify each message (or a sampling of them would probably work too), letting it pick its own categories for each. Then, look at the patterns that emerge and give it a single, much smaller, set of broad categories to use and rerun it over that.
Then I can easily select messages from my Maildirs by category and process them in bulk.
I used open-interpreter pointing to that GPU on my network to help me write the scripts for this. It didn t get things right on its own; for instance, it didn t call the Ollama API correctly, and insisted on appending /cur to the path to the Maildir (which was not going to fly with Python s maildir module). It took roughly an hour to classify those 8000 messages (or, as I had it do, the first 2000 characters of them), and then the same to do it a second time. I had it output lines in the form of filename\tcategory and hand-wrote the shell script that processed those.
In the end, was it useful? Yes, quite. Its classifications weren t perfect (and it didn t even follow my prompt perfectly; sometimes it would give me a long discussion on why it picked a certain category rather than just that category, and occasionally it picked categories not on the list). But then, neither were my manual keyword searches. So far I ve gotten rid of nearly 1000 more messages. Several categories were a visual scan for sanity and then delete all sort of thing.
My emails never left my network. I didn t rely on a cloud AI to process them. I didn t contribute to global warming (this may have even been a case of saving energy, since it no doubt will offset quite a bit of manual time that would keep screens and room lights energized and so forth). I used about as much energy as watching a movie on a TV.
Did it complete the task for me entirely autonomously? Also no. AI isn t a mind reader and it can t possibly evaluate exactly what my thought process would be for a given task. But it can do a decent enough job to save me some time.
Still, this didn t require hyperscaler datacenters. AI even runs on-phone (Google Translate being one of the most useful AI-driven apps I ve ever seen, and it can run on-device).
A Shadow in Summer is a high fantasy novel, the first of (as the
name implies) a completed four-book series. Daniel Abraham is perhaps
better known as half of the writing pair behind James S.A. Corey, author
of the Expanse series. This was his first
novel.
Otah was the sixth son of a Khai, sent like many of the unwanted later
children of the powerful to learn the secrets of the andat and be trained
as a poet. He learned his lessons well enough to reject the school and its
teachings and walk away.
Amat Kyaan has worked her way up from nothing to become the senior
overseer of the foreign Galtic House Wilsin in the sun-drenched port city
of Saraykeht. Liat is her apprentice, distracted by young love. Maati is a
new apprentice poet, having endured his training and sent to learn from
Heshai how to eventually hold the andat Removing-The-Part-That-Continues,
better known as Seedless. None of them know they will find themselves
entangled in a plot to destroy the poet of Saraykeht and, through him, the
city's most potent economic tool.
A poet in this world is not what we would think of a poet. They are, in
essence, magical slave-drivers who capture the essence of an andat, a
spirit embodying an idea that is coerced into the prison of volition and
obedience by the poet. The andat Seedless, the embodiment of the concept
of removing the spark of life, is central to the economic wealth of
Saraykeht in a way that is startling in its simplicity: Seedless can
remove the seeds from a warehouse full of cotton at a thought. This gives
Saraykeht a massive productivity advantage in the cotton trade.
Seedless is also a powerful potential weapon. What he can do to cotton, he
could as easily do to any other crop, or to people. The Galts are not fond
of the independence and power of Saraykeht, but as long as the city
controls a powerful andat, they do not dare to attack it directly.
Indirectly, though... that's another matter.
This is one of those fantasy novels with meticulous and thoughtful
world-building, careful and evocative prose, and a complex ensemble cast
of interesting characters that the novel then attempts to make utterly
miserable and complicit in their own misery. There should be a name for
this style of writing. It's not tragedy because the ending is not tragic,
precisely. It's not magic realism; the andats are openly magical, which
makes this clearly high fantasy. But Abraham approaches the story from the
type of realist frame that considers the pain and desperation of the
characters to be more interesting than their ability to overcome
challenges.
Amat starts the story as an admirable, sharp-witted expert manager, so her
life is destroyed and she's subjected to sexual violence. Heshai loathes
himself and veers between a tragic figure and a wastrel as the story
systematically undermines opportunities for redemption. Maati is young and
idealistic, so of course every character in the book sets out to crush his
idealism under the weight of unforeseen consequences. There is a sad and
depressing love triangle, because this is exactly the sort of book that
has a sad and depressing love triangle. At the end of the novel, everyone
who survives is older and wiser in the sense that some stories seem to
think wisdom comes from the accumulation of trauma.
I find books like this so immensely frustrating because their merits are
so clear. The world-building is careful and detailed in a way that
includes economic systems, unlike so much fantasy. It is full of small,
intriguing touches, such as the use of posture and gesture to communicate
the emotional valence of one's words. Abraham understands the moral
implications of poets and andats and the story tackles them head-on. The
writing flows beautifully and gave me a strong sense of the city. I wanted
to like this book for the obvious skill that went into it, and sometimes I
even managed.
And yet, it's taken me three months to finish A Shadow in Summer
because I simply do not want to spend this much time around miserable
people. I would get through one or two chapters in a night and then wanted
to read something happy or defiant or heroic, rather than watching
slow-motion train wrecks intermixed with desperate attempts to navigate
stifling layers of immoral systems. It's not that the story lacks a moral
compass. The characters are sincerely trying to make the world a better
place, with some success. It even delivers a happy ending of sorts. But so
much of the journey was watching the lives of the characters fall apart.
I am completely unsurprised that some people loved this book. I'm still
intrigued enough by the world-building that I'm half-tempted to try to
read the sequel even after having to drag myself through this one. I had a
similar reaction to Abraham's The
Dragon's Path, though, so I think Abraham is just not for me. I may get
back to the Expanse at some point, but having to drag myself through both
of his solo novels I've tried, in two different series, probably indicates
an incompatibility between author and reader. That's a shame, given the
quality of the writing.
Followed by A Betrayal in Winter.
Content notes: Sexual and reproductive violence as significant plot
elements.
Rating: 6 out of 10
This needs to be clear: systemd is under attack by a trolling campaign orchestrated by fascist elements. Nobody is forced to like or use systemd, but anybody who wants to pick a side should know the facts.
Recently, the free software Nazi bar crowd styling themselves as "concerned citizens" has tried to start a moral panic by saying that systemd is implementing age verification checks or that somehow it will require providing personally identifiable information.
This is a lie: the facts are simply that the systemd users database has gained an optional "date of birth" field, which the desktop environments may use or not as they deem appropriate. Of course there is no "identity verification" or requirements to provide any data, which in any case would not be shared beyond authorized local applications.
While the multiple recent bills proposing that general purpose operating systems implement age verification mechanisms are often concerning, both from a social and technical point of view, this is not the topic being discussed here. They are often suboptimal, but for a long time I have been opposing attempts to implement parental control at the network level and argued that it should be managed locally, by parents on their own machines: I cannot see why I should outright reject an attempt to implement the infrastructure to do that.
If we want to keep age-appropriate controls out of the hands of centralized authorities, the alternative is giving families the means to manage it themselves: this is what this field enables. Whether desktop environments use it for parental controls, for birthday reminders, or for nothing at all, is their users' decision.
By the way, the original UNIX users database has allowed storing PII in the GECOS field since it was invented in the '70s. Similar fields are also specified by many popular LDAP schemes: adding such an optional field is consistent with the UNIX tradition.
And while we are at it, let's also refute the other smear campaign started by the same people: the systemd project is not accepting "AI slop". What happened is that a documentation file for the benefit of coding agents was added to the repository. To be clear: agents still cannot submit merge requests. The file itself remarks that all contributions must be reviewed in detail by humans, and this is basically the same policy used by the Linux kernel.
Note: I have not published blog posts about my academic papers over the past few years. To ensure that my blog contains a more comprehensive record of my published papers and to surface them for folks who missed them, I will periodically (re) publish blog posts about some older published projects. This post draws material from a previously published post by Kaylea Champion on the Community Data Science Blog.
Taboo subjects such as sexuality and mental health are as important to discuss as they are difficult to raise in conversation. Although many people turn to online resources for information on taboo subjects, censorship and low-quality information are common in search results. In two papers I recently published at CSCW both led by Kaylea Champion we presented a series of analyses showing how taboo shapes the process of collaborative knowledge building on English Wikipedia.
The first study is a quantitative analysis showing that articles on taboo subjects are much more popular and are the subject of more vandalism than articles on non-taboo topics. In surprising news, we also found that they were edited more often and were of higher quality!
Short video of Kaylea s presentation of the work given at Wikimania in August 2023.
The first challenge we faced in conducting this work was identifying taboo articles. Kaylea had a brilliant idea for a new computational approach to doing so without relying on our individual intuitions about what qualifies as taboo (something we understood would be highly specific to our own culture, class, etc). Her approach was to make use of an insight from linguistics: people develop euphemisms as ways to talk about taboos (i.e., think about all the euphemisms we ve devised for death, or sex, or menstruation, or mental health).
We used this insight to build a new machine-learning classifier based on English Wiktionary definitions. If a sense of a word was tagged as euphemistic, we treated the words in the definition as indicators of taboo. The end result was a series of words and phrases that most powerfully differentiate taboo from non-taboo. We then did a simple match between those words and phrases and the titles of Wikipedia articles. The topics were taboo enough that we were a little uncomfortable discussing them in our meetings! We built a comparison sample of articles whose titles are words that, like our taboo articles, appear in Wiktionary definitions.
In the first paper, we used this new dataset to test a series of hypotheses about how taboo shapes collaborative production in Wikipedia. Our initial hypotheses were based on the idea that taboo information is often in high demand but that Wikipedians might be reluctant to associate their names (or usernames) with taboo topics. The result, we argued, would be articles that were in high demand but of low quality.
We found that taboo articles are thriving on Wikipedia! In summary, we found that in comparison to non-taboo articles:
Taboo articles are more popular (as expected).
Taboo articles receive more contributions (contrary to expectations).
Taboo articles receive more low-quality contributions (as expected).
Taboo articles are higher quality (contrary to expectations).
Taboo article contributors are more likely to contribute without an account (as expected), and have less experience (as expected), but that accountholders are more likely to make themselves more identifiable by having a user page, disclosing their gender, and making themselves emailable (all three of these are contrary to expectation!).
Image of the estimated qualiy of articles of the four articles in the second mixed-methods paper. Extreme dips reflect periods of frequent vandalism.
Kaylea attempted to understand these somewhat confusing results by designing a fantastic mixed-methods analysis that sought to unpack some of the nuance missing in the quantitative analysis by delving deep into the life histories of four articles on English Wikipedia: two on taboo topics related to women s anatomy (Clitoris and Menstration) and two nontaboo articles chosen for comparison (Cell membrance and Philip Pullman).
Although the findings from the analysis can be difficult to summarize succinctly (as with many qualitative studies), we showed how the taboo example articles success was hard-won amid real challenges and attacks. The paper describes how challenges were overcome through resilient leadership, often provided by a single dedicated individual. The paper provides a template for how taboo can be and frequently is overcome by dedicated Wikipedians in ways that provide useful knowledge resources in real demand.
For more details, visualizations, statistics, and more, we hope you ll take a look at our papers, both linked below.
The full citation for the papers are: (1) Champion, Kaylea, and Benjamin Mako Hill. 2023. Taboo and Collaborative Knowledge Production: Evidence from Wikipedia. Proceedings of the ACM on Human-Computer Interaction 7 (CSCW2): 299:1-299:25. https://doi.org/10.1145/3610090. (2) Champion, Kaylea, and Benjamin Mako Hill. 2024. Life Histories of Taboo Knowledge Artifacts. Proceedings of the ACM: Human-Computer Interaction 8 (CSCW2): 505:1-505:32. https://doi.org/10.1145/3687044.
Dark Class is the fifth novel (not counting the
skippable novella) in Michelle Diener's Class 5
romantic science fiction series. As with the previous novels, this follows
romance series conventions: There are new protagonists, but characters
from the previous books make an appearance. It's helpful but not that
necessary to remember the details of the previous books; the necessary
background is explained enough to follow the story.
By now, series readers know the formula. Yet another Earth woman was
secretly abducted by the Tecran, encounters a Class 5 ship, and finds a
way to be surprisingly dangerous and politically destabilizing. This time,
Ellie has been mostly unconscious since her abduction and awakes in a
secret Tecran base after the Tecran have all been murdered. There is a
Class 5 AI involved, but not a full ship; instead, Dark Class picks
up (or, arguably, manufactures) a loose end from Dark Minds. Other than that break from the formula, you know what
to expected by now: a hunky Grih, a tricky political standoff, a
protective Class 5, a slow-burn romance, and a surprisingly capable
protagonist who upends politics through plucky grit and refusal to
tolerate poor treatment. Oh, and a new selection of salvaged clothing and
weapons to make Ellie beautiful and surprisingly dangerous.
If you are this far into the series, you probably like the formula. That's
my position. I don't care about the romance, but something about the
prisoner to threat evolution of the kidnapped protagonists and the growing
friendship with an AI makes me happy. This is not great literature, but it
is reliably entertaining with a guaranteed victorious protagonist and
happy ending, making it a comfortable break from more difficult books with
emotionally wrenching scenes.
Dark Class is one of the better executions of the formula because
it has long stretches of my favorite parts of these books: exploration of
mostly-abandoned surroundings for neat gadgets while the AI and the
protagonist slowly build a relationship of mutual respect. This book has
bonus drones with minds of their own and an enigmatic alien spaceship that
provides a fun mid-novel twist. The Tecran and the Grih repeatedly
underestimate Ellie and are caught by surprise at dramatically satisfying
moments. It's just fun to read, and I save this series for when I need
that type of book.
As with the other books of the series, Diener's writing is serviceable but
not great. She repeats herself, uses way too many paragraph breaks for
emphasis, and is not going to win any literary awards for prose quality.
The series is in the upper half of self-published works, and I've
certainly read worse, but either the formula will click with you or it
won't. If it doesn't, the prose is not going to salvage the book.
There is some development of the series plot, but it's mostly predictable
fallout from Dark Matters. This book is
mostly tactical and smaller in scale. I am a little curious where Diener
is going with political developments, since the accumulated Earth women
and Class 5 ships are in some danger of becoming a sort of shadow
government through sheer military power, but I'm dubious this series will
have enough political sophistication to dig into the implications. It's
best enjoyed as small-scale episodic wish fulfillment for female
protagonists, and that's good enough for me.
If you've read this far in the series, recommended; this is one of the
stronger entries.
Followed by Collision Course, which breaks the title convention for
the series.
Rating: 7 out of 10
I often need a quick calculation or a unit conversion. Rather than reaching for
a separate tool, a few lines of Zsh configuration turn = into a calculator.
Typing = 660km / (2/3)c * 2 -> ms gives me 6.60457 ms1 without
leaving my terminal, thanks to the Zsh line editor.
The equal alias
The main idea looks simple: define = as an alias to a calculator command. I
prefer Numbat, a scientific calculator that supports unit conversions.
Qalculate is a close second.2 If neither is available, we fall back to
Zsh s built-in zcalc module.
As the alias built-in uses = as a separator for name and value, we need to
alter the aliases associative array:
With this in place, = 847/11 becomes numbat -e 847/11.
The quoting problem
The first problem surfaces quickly. Typing = 5 * 3 fails: Zsh expands the *
character as a glob pattern before passing it to the calculator. The same issue
applies to other characters that Zsh treats specially, such as > or . You
must quote the expression:
$ ='5 * 3'15
We fix this by hooking into the Zsh line editor to quote the expression
before executing it.
Automatic quoting with ZLE
Zsh calls the line-finish widget before submitting a command. We hook a
function that detects the = prefix and quotes the expression:
_vbe_calc_quote()case$BUFFERin"="*)typeset-g_vbe_calc_expr=$BUFFER# not used yetBUFFER="= $ (q-)$ $ BUFFER#=# ";;esac
add-zle-hook-widgetline-finish_vbe_calc_quote
When you type = 5 * 3 and press , _vbe_calc_quote strips the =
prefix, quotes the remainder with the (q-) parameter expansion flag,
and rewrites the buffer to = '5 * 3' before Zsh submits the command. As a
bonus, you can save a few keystrokes with =5*3!
You can now compute math expressions and convert units directly from your shell.
Zsh automatically quotes your expressions:
The metric system is the tool of the devil! My car gets forty rods to the hogshead, and that's the way I like it! Grampa Simpson, A Star Is Burns
Storing unquoted history
As is, Zsh records the quoted expression in history. You must unquote it
before submitting it again. Otherwise, the ZLE widget quotes it a second time.
Bart Schaefer provided a solution to store the
original version:
The zshaddhistory hook returns 1 if we are evaluating an expression, telling
Zsh not to record the command. The preexec hook then adds the original,
unquoted command with print -s.
The complete code is available in my zshrc. A common alternative is the
noglob precommand modifier. If you stick with to instead of ->
for unit conversion, it covers 90% of use cases. For a related Zsh line editor
trick, see how I use auto-expanding aliases to fix common typos.
This is the fastest a packet can travel back and forth between
Paris and Marseille over optical fiber.
Qalculate is less understanding with units. For example, it parses
Mbps as megabarn per picosecond:
I saw Ladytron perform in Digital, Newcastle last night. The
last time I saw them was, I think, at the same venue, 18 years ago. Time flies!
Back in the day (perhaps their heyday, perhaps not!) Ladytron ploughed a
particular sonic furrow and did it very well. Going into the gig I had set my
expectations that, should they play just these hits, I'd have a good time.
The gig exceeded my expectations. The setlist very much did not lean into
their best-known period: the more recent few albums were very well represented
and to me this felt very confident. The lead singer, Helen Marnie, demonstrated
some excellent range, particularly on some of the new songs. Daniel Hunt did a
lot of backing vocals and they were really complementary to Helen's: underscoring
but not overpowering. I enjoyed nerding out watching Mira Ayoro's excellent
wrangling of her Korg MS-20. One highlight was an encore performance of
Light & Magic, which was arguably the "alternate version" as available on the
expanded versions of that album or the Remixed and Rare companion.
I thought I'd try to put together a 5-track playlist for a friend who attended
the gig but isn't super familiar with them. As usual this is hard. I'm going
to avoid the obvious hits, try to represent their whole career and try to
ensure the current trio each get a vocal turn in the selection.
They actually released their latest album, Paradises, yesterday as well. One
track from it is in the list below.
I'm Not Scared by LadytronKingdom Undersea by LadytronBlue Jeans by LadytronHe took her to a movie by LadytronTransparent Days by Ladytron
(If you can't see anything, the bandcamp embeds have been stripped out by
whatever you are viewing this with)
When you re looking at source code it can be helpful to have some evidence
indicating who wrote it. Author tags give a surface level indication, but
it turns out you can just
lie
and if someone isn t paying attention when merging stuff there s certainly a
risk that a commit could be merged with an author field that doesn t
represent reality. Account compromise can make this even worse - a PR being
opened by a compromised user is going to be hard to distinguish from the
authentic user. In a world where supply chain security is an increasing
concern, it s easy to understand why people would want more evidence that
code was actually written by the person it s attributed to.
git has support for cryptographically signing
commits and tags. Because git is about choice even if Linux isn t, you can
do this signing with OpenPGP keys, X.509 certificates, or SSH keys. You re
probably going to be unsurprised about my feelings around OpenPGP and the
web of trust, and X.509 certificates are an absolute nightmare. That leaves
SSH keys, but bare cryptographic keys aren t terribly helpful in isolation -
you need some way to make a determination about which keys you trust. If
you re using someting like GitHub you can extract that
information from the set of keys associated with a user account1, but
that means that a compromised GitHub account is now also a way to alter the
set of trusted keys and also when was the last time you audited your keys
and how certain are you that every trusted key there is still 100% under
your control? Surely there s a better way.
SSH Certificates
And, thankfully, there is. OpenSSH supports
certificates, an SSH public key that s been signed by some trusted party and
so now you can assert that it s trustworthy in some form. SSH Certificates
also contain metadata in the form of Principals, a list of identities that
the trusted party included in the certificate. These might simply be
usernames, but they might also provide information about group
membership. There s also, unsurprisingly, native support in SSH for
forwarding them (using the agent forwarding protocol), so you can keep your
keys on your local system, ssh into your actual dev system, and have access
to them without any additional complexity.
And, wonderfully, you can use them in git! Let s find out how.
Local config
There s two main parameters you need to set. First,
1
git config set gpg.format ssh
because unfortunately for historical reasons all the git signing config is
under the gpg namespace even if you re not using OpenPGP. Yes, this makes
me sad. But you re also going to need something else. Either
user.signingkey needs to be set to the path of your certificate, or you
need to set gpg.ssh.defaultKeyCommand to a command that will talk to an
SSH agent and find the certificate for you (this can be helpful if it s
stored on a smartcard or something rather than on disk). Thankfully for you,
I ve written one. It will
talk to an SSH agent (either whatever s pointed at by the SSH_AUTH_SOCK
environment variable or with the -agent argument), find a certificate
signed with the key provided with the -ca argument, and then pass that
back to git. Now you can simply pass -S to git commit and various other
commands, and you ll have a signature.
Validating signatures
This is a bit more annoying. Using native git tooling ends up calling out to
ssh-keygen2, which validates signatures against a file in a format
that looks somewhat like authorized-keys. This lets you add something like:
1
* cert-authority ssh-rsa AAAA
which will match all principals (the wildcard) and succeed if the signature
is made with a certificate that s signed by the key following
cert-authority. I recommend you don t read the code that does this in
git
because I made that mistake myself, but it does work. Unfortunately it
doesn t provide a lot of granularity around things like Does the
certificate need to be valid at this specific time and Should the user
only be able to modify specific files and that kind of thing, but also if
you re using GitHub or GitLab you wouldn t need to do this at all because
they ll just do this magically and put a verified tag against anything
with a valid signature, right?
Haha. No.
Unfortunately while both GitHub and GitLab support using SSH certificates
for authentication (so a user can t push to a repo unless they have a
certificate signed by the configured CA), there s currently no way to say
Trust all commits with an SSH certificate signed by this CA . I am unclear
on why. So, I wrote my
own. It takes a range of
commits, and verifies that each one is signed with either a certificate
signed by the key in CA_PUB_KEY or (optionally) an OpenPGP key provided in
ALLOWED_PGP_KEYS. Why OpenPGP? Because even if you sign all of your own
commits with an SSH certificate, anyone using the API or web interface will
end up with their commits signed by an OpenPGP key, and if you want to have
those commits validate you ll need to handle that.
In any case, this should be easy enough to integrate into whatever CI
pipeline you have. This is currently very much a proof of concept and I
wouldn t recommend deploying it anywhere, but I am interested in merging
support for additional policy around things like expiry dates or group
membership.
Doing it in hardware
Of course, certificates don t buy you any additional security if an attacker
is able to steal your private key material - they can steal the certificate
at the same time. This can be avoided on almost all modern hardware by
storing the private key in a separate cryptographic coprocessor - a Trusted
Platform Module on
PCs, or the Secure
Enclave
on Macs. If you re on a Mac then Secretive has
been around for some time, but things are a little harder on Windows and
Linux - there s various things you can do with
PKCS#11 but you ll hate yourself
even more than you ll hate me for suggesting it in the first place, and
there s ssh-tpm-agent except
it s Linux only and quite tied to Linux.
So, obviously, I wrote my
own. This makes use of the
go-attestation library my team
at Google wrote, and is able to generate TPM-backed keys and export them
over the SSH agent protocol. It s also able to proxy requests back to an
existing agent, so you can just have it take care of your TPM-backed keys
and continue using your existing agent for everything else. In theory it
should also work on Windows3 but this is all in preparation for a
talk I only found out I was giving about two weeks
beforehand, so I haven t actually had time to test anything other than that
it builds.
And, delightfully, because the agent protocol doesn t care about where the
keys are actually stored, this still works just fine with forwarding - you
can ssh into a remote system and sign something using a private key that s
stored in your local TPM or Secure Enclave. Remote use can be as transparent
as local use.
Wait, attestation?
Ah yes you may be wondering why I m using go-attestation and why the term
attestation is in my agent s name. It s because when I m generating the
key I m also generating all the artifacts required to prove that the key was
generated on a particular TPM. I haven t actually implemented the other end
of that yet, but if implemented this would allow you to verify that a key
was generated in hardware before you issue it with an SSH certificate - and
in an age of agentic bots accidentally exfiltrating whatever they find on
disk, that gives you a lot more confidence that a commit was signed on
hardware you own.
Conclusion
Using SSH certificates for git commit signing is great - the tooling is a
bit rough but otherwise they re basically better than every other
alternative, and also if you already have infrastructure for issuing SSH
certificates then you can just reuse it4 and everyone wins.
Did you know you can just download people s SSH pubkeys from github from https://github.com/<username>.keys? Now you do
Yes it is somewhat confusing that the keygen command does things
other than generate keys
Before reaching Vietnam
Continuing from the last post, Badri and I took a flight from the Brunei International Airport to Kuala Lumpur on the 12th of December 2024. We reached Kuala Lumpur in the evening.
After arriving at the airport, we went through immigration. In a previous post, I mentioned that we had put our stuff in lockers at the TBS bus terminal in Kuala Lumpur. Therefore, we had to go there.
The locker was automated and required us to enter the PIN we had set. Upon entering the PIN, the locker wasn t getting unlocked. After trying this for 10-15 minutes without any luck, we tried getting some help as there the lockers weren t under supervision.
So, I roamed around and found a staff member, reporting that our lockers weren t getting unlocked. They called the person who was in-charge of the lockers. He came to us in a few minutes and used their admin access to open the locker. We were supposed to pay for using the lockers by putting the banknotes inside through a slot. However, as the machine wasn t working, we gave the amount for the use of our locker service to that person instead.
We soon went back to the KL airport to catch our morning flight to Ho Chi Minh City in Vietnam. At the flight counter, we were afraid we would have to pay extra as our luggage surpassed the allowed weight limit. This one was also a budget airline AirAsia and our tickets didn t include a check-in bag.
Generally, passengers from countries requiring a visa to visit Vietnam (such as India) require going to the airline and showing their visa to get the boarding pass. However, when we went to the AirAsia counter at the Kuala Lumpur airport, they didn t weigh our bags and asked us to get our boarding passes from an automated kiosk. So, we got our boarding passes printed and proceeded to the airport security.
While clearing the airport security, a lotion I bought from Singapore was confiscated because it was 200 mL, exceeding the limit of 100 mL per bottle. Had that 200 mL liquid been in two different bottles of 100 mL each, I would have been allowed to take it in my carry-on bag, but a single 200 mL bottle wasn t! I was allowed to keep it in the check-in bag, but I didn t have it included in my ticket. Huh, airports and their weird rules :( The lotion was an expensive one, so having it thrown away did ruin my mood.
Overview
We started our Vietnam trip from Ho Chi Minh City in the south on the 13th of December 2024 and finished it in Hanoi in the north on the 20th of December. We traveled from Ho Chi Minh City to Hanoi mostly by train, except for a hundred or so kilometers by bus, in chunks. On the way, we visited Nha Trang, Hoi An, and Hue. The distance between Ho Chi Minh City and Hanoi is 1700 km.
For your reference, here are those places labeled on Vietnam s map.
A map of Vietnam with points of places we went to labeled. CARTO MAPTILER OPENSTREETMAP
Ho Chi Minh City
We landed in Ho Chi Minh City early morning on the 13th of December 2024. I was tired and sleepy as I hadn t gotten a good night s sleep. After going through immigration, we went to a currency exchange counter to get Vietnamese Dong. Unlike other countries on this trip, money exchange counters in Vietnam didn t accept Indian rupees. Therefore, we exchanged euros to get Vietnamese dong at the airport.
After getting out of the airport, we took a bus to the city center. It was 15,000 dongs approximately 50 Indian rupees. Our plan was to meet Badri s friend and stay the night at his apartment.
So we went to a caf nearby and bought a coffee for each of us for 75,000 dongs. We went upstairs and sat for a while. The Wi-Fi password was mentioned on our bill. During the trip, I found out about the caf culture of Vietnam. They have their own coffee brands (such as Highlands Coffee), and you can sit down at any of the caf s for work or wait for the rain to stop. It rained a lot while we were there, so we did use these caf s for that purpose.
Badri s friend met us there, and we roamed around the area a bit, which included roaming inside a beautiful park. Then Badri s friend took us to a restaurant. Because I do not eat meat, he took us to a vegan restaurant. Having been to four Southeast Asian countries at this point (excluding Vietnam), I was under the impression that there wouldn t be a lot of things for my diet in Vietnam.
A picture of the park we roamed around in Ho Chi Minh City. Photo by Ravi Dwivedi, released under CC-BY-SA 4.0.
However, I was pleasantly surprised at the restaurant. I found all the dishes to be tasty, especially their signature noodles called Pho. I liked another dish so much that I tracked down the restaurant again with Badri using the geotagged image of the bill I had taken earler to have it again. As a tip for vegans coming to Vietnam, the places having the letters Chay (without any accented letters) in their name are vegan only.
This is the restaurant Badri s friend took us to. Photo by Ravi Dwivedi, released under CC-BY-SA 4.0.
One of the dishes we had in the restaurant. This one was especially tasty. Photo by Ravi Dwivedi, released under CC-BY-SA 4.0.
One of the dishes we had in the restaurant. Photo by Ravi Dwivedi, released under CC-BY-SA 4.0.
These noodles are called Pho and are very popular in Vietnam. Photo by Ravi Dwivedi, released under CC-BY-SA 4.0.
In the night, we went to a supermarket where I got myself some oranges and guavas. Then, we went to a Japanese restaurant where I didn t have anything, as there was no vegetarian option available for me. Then we took a free bus to the place to Badri s friend s apartment. The construction company that built the apartment also runs this free bus service from their residential area to different parts of the city as a way of promoting their apartments. Anyone can take the bus, not just residents.
The next day, we took the free bus back to the city center and checked in to a hostel for a night. We took two beds in dormitories, which were 88,000 dongs (270 rupees) for each bed for a night. In Vietnam, if you can spend around 300 rupees per night, you can get a bed in a decent hostel.
Train from Ho Chi Minh City to Nha Trang
On the night of the 15th of December 2024, we boarded a train from Ho Chi Minh City to Nha Trang. The ticket for each of us was 519,000 dongs (1600 Indian rupees). The train name was SNT2. When we reached the Ho Chi Minh City train station, we noticed that the station was rather small by Indian standards.
After entering the train station, we went inside to the first platform, where the tickets were checked by a staff member. Ho Chi Minh City was the originating station for our train, so our train was already standing at the station. We had to cross the railway tracks on foot to reach the platform our train was on. Then we located our coach, where a ticket inspector was standing at the gate. He let us in after checking our tickets. In all these instances, we just had to show our digital boarding pass which we had received by email.
Unlike Indian trains, the train didn t have side berths. Additionally, I liked the fact that it had a dedicated space to put our bags in, which was very convenient. The train departed from Ho Chi Minh City at 21:05 and arrived in Nha Trang at 05:30 in the morning.
Interior of our train coach. Trains in Vietnam don t have side berths, unlike India. Photo by Ravi Dwivedi, released under CC-BY-SA 4.0.
A picture of the berths from our coach. It had three tiers, similar to a 3 AC coach in Indian trains. Photo by Ravi Dwivedi, released under CC-BY-SA 4.0.
The train had a cabin to put the bags in. Photo by Ravi Dwivedi, released under CC-BY-SA 4.0.
Nha Trang train station. Photo by Ravi Dwivedi, released under CC-BY-SA 4.0.
Nha Trang
Nha Trang is a coastal place, and we planned to go to a beach. We figured out that the bus to the airport goes can drop us near the beach. Therefore, we went to the bus station to get to the airport bus. The bus station was walking distance from the railway station. So, we decided to walk.
On the way, we stopped at a small shop for a coffee. The shop also gave a complimentary cup of green tea along with the coffee. I found out later that it is common for local shops to give a cup of complimentary green tea in Vietnam.
I got a complimentary cup of green tea along with coffee in Nha Trang. In this trip, Badri and I found out that this is customary at local places in Vietnam. Photo by Ravi Dwivedi, released under CC-BY-SA 4.0.
Soon we reached the bus station and took a bus to the beach. It was 65,000 dongs ( 200). After getting down from the bus, I had coconut water and some eggs at a small local place.
Eggs being cooked on a pan for my order. Photo by Ravi Dwivedi, released under CC-BY-SA 4.0.
Then we went to the beach, but nobody else was there. We spent some time there and went back to the place where the bus dropped us as it started raining. We couldn t find a bus for some time. A taxi driver approached us and agreed to take us to the city center for 200,000 dongs ( 650). For reference, the place where he dropped us was 35 km from the place we took the taxi. Taxi fares in Vietnam were also cheap!
The beach we went to in Nha Trang. Photo by Ravi Dwivedi, released under CC-BY-SA 4.0.
Nha Trang was a beautiful place, and so we roamed around for a while. Then we stopped at a Highlands Coffee branch for a while. Since Christmas was coming up, the caf had a Christmas tree, and I liked the Christmas vibes. They were playing Mariah Carey s All I Want for Christmas Is You.
This one was shot in the city center. In this trip, Badri and I found out that this is customary at local places in Vietnam. Photo by Ravi Dwivedi, released under CC-BY-SA 4.0.
Inside a Highlands Coffee cafe in Nha Trang. Photo by Ravi Dwivedi, released under CC-BY-SA 4.0.
A coffee I got from Highlands Coffee in Nha Trang. Photo by Ravi Dwivedi, released under CC-BY-SA 4.0.
During the evening, we went to a local place to eat. The place mentioned Chay in its name, and you know what it means it was a vegan place. There was a man there and no other customers. I don t remember the names of the dishes we ordered, but it was a bowl of soupy noodles and a bowl of dry noodles. They were very tasty. To top that off, the meal was a total of 55,000 dongs ( 180) for both of us.
The host was welcoming and friendly. We had a nice conversation with the host. In Vietnam, restaurants give chopsticks to eat noodles. While Badri was good at using them, I wasn t. So, the host of this restaurant helped me in using chopsticks. Although my technique was not perfect and I take a bit of time, I could now eat solely with chopsticks.
The restaurant we went to in Nha Trang. The word Chay in the name means it was a vegan restaurant. Photo by Ravi Dwivedi, released under CC-BY-SA 4.0.
Soupy noodles we got at that restaurant. Photo by Ravi Dwivedi, released under CC-BY-SA 4.0.
Dry noodles we got at that restaurant. Photo by Ravi Dwivedi, released under CC-BY-SA 4.0.
Our plan was to take a night bus to Hoi An, and we were hoping to find a bus stand. However, we couldn t find one. Asking around about the pickup location of the Hoi An bus led us to many different locations. Finally, we ended up at a bus booking agency s office where we found out that there were no tickets available for Hoi An.
At this point, we gave up on booking the bus and searched for trains instead. As we didn t have a local SIM, we asked the agency to let us connect to their Wi-Fi so that we could look for trains. They were kind enough to let us do that. It also seemed like they were going to close the office in like 10 minutes.
Unfortunately, all the sleeper berths were booked from Nha Trang till Hoi An on the next train with only seating berths being available. It takes around 10 hours, so I wasn t comfortable traveling on seating berths.
Here I came up with the idea to look for sleeper berths from an intermediate stop. Fortunately, there were sleeper berths available from the next stop, Ninh H a. Therefore, we booked a seating berth from Nha Trang to Ninh H a and a sleeper berth from Ninh H a to Tr Ki u (the nearest railway station from Hoi An). The train name was SE6, and it was a total of 500,000 dongs per person ( 1600 per person).
So, we went to the Nha Trang railway station and boarded the train. We had to spend 40 minutes seated for the train to reach the next stop before we could go to our sleeper berths. Badri had some friendly co-passengers on that trip who gave him Saigon beer and some crispy papad-like thing. They offered me as well, but I thought it was non-veg, so I declined it.
Hoi An
On the morning of 17th December 2024, we got down at the Tr Ki u station at around 09:30. Our hostel was in Hoi An, which was around 22 km from the station. There was no public transport to get there.
Instead, there was a taxi driver at the train platform. We told him the name of our hostel, and he quoted 270,000 dongs (around 850). We said it was too expensive for us, so he agreed to bargain at 250,000 dongs. At this point, we told him that we could give him no more than 200,000 dongs, but he didn t agree.
Badri tried a trick. He asked the driver to show us prices in the Grab app (a popular taxi booking app in Southeast Asia). Unfortunately, the Grab app showed 258,000 dongs, which was more than the fare the driver agreed to.
So we walked away as if we had so many options (we didn t!) to reach the hostel. We got out of the station and stopped at a small shop outside to have some coffee. As is customary in Vietnam, we got a complimentary green tea here as well.
This was the place we had our coffee in Tra Kieu. Photo by Ravi Dwivedi, released under CC-BY-SA 4.0.
That taxi driver also joined us and sat in that shop. He started talking with the locals in the shop in the local language. The taxi driver was insistent on taking us to Hoi An for 250,000 dongs. At this point, Badri told the taxi driver (by the use of translation software) that we usually use public transport during our trips, and we aren t used to paying high prices to get around. So, he can drop us somewhere in Hoi An for 200,000 dongs as we don t mind walking a bit to reach our hotel.
After reading this, the taxi driver agreed to take us to our hostel for 200,000 dongs ( 660). He also had me take a picture with Badri after this. I think such a bargain tactic would not work in India.
Photo of Badri with taxi driver. Photo by Ravi Dwivedi, released under CC-BY-SA 4.0.
The nice thing we noticed in Vietnam is, once bargaining is done and the deal is settled, people don t try to bargain more or keep on talking about the subject. Before the deal, the driver was being somewhat insistent and argumentative, but after the deal was done, it was as if no argument had happened at all.
A picture of Tra Kieu area near the train station we got down at. Photo by Ravi Dwivedi, released under CC-BY-SA 4.0.
We were treated to some beautiful scenery on the way to our hostel. Soon we reached our place and completed all the formalities for checking-in. During the time our room was being prepared for check-in, we had an egg sandwich with coffee in the hotel. I found the egg sandwich very tasty. The bread looked like the French baguette. The hostel was 240 per night for each of us.
The name of the hostel was Bana Spa. We liked staying here and we can recommend it if you find yourself there. It is operated by a family.
Our breakfast in Hoi An. Photo by Ravi Dwivedi, released under CC-BY-SA 4.0.
A photo of the hostel we stayed in Hoi An. Photo by Ravi Dwivedi, released under CC-BY-SA 4.0.
We also rented a bicycle for each of us 25,000 dongs per day ( 80) and explored the old town during the evening. Hoi An is popular for Vietnamese silk. Tourists come here to buy fabric and get it done by the tailor. The buildings here looked old, and they were painted in yellow with a gabled roof.
Typical yellow house with gabled roof in Hoi An old town. Photo by Ravi Dwivedi, released under CC-BY-SA 4.0.
Here, I also had egg coffee for the first time, and I liked it. Egg coffee is a delicacy of Hanoi, but you can get it in other parts of Vietnam. If you find yourself in Vietnam, then I recommend you try egg coffee. We also bought some cool T-shirts and other souvenirs, such as a Vietnamese hat, from here.
Egg coffee I had in Hoi An. Photo by Ravi Dwivedi, released under CC-BY-SA 4.0.
Hue
The next day the 18th of December 2024 we went to Hue by bus. As we could not take a bus on our own in Nha Trang, we asked the hostel to book it for us this time. We booked it a day before, and they told us to be ready by 07:00 in the morning. At 07:00, a minibus arrived, which took us to a bus agency s office. There we waited for a few minutes and got into the bus to Hue.
The bus had sleeper seats, so I took the opportunity to catch some sleep. The ride was comfortable, so I am assuming the roads were good. In a couple of hours, we reached Hue. Again, we went to Highlands Coffee to have some coffee, charge our phones, and use the internet, not to mention using the bathrooms.
During the afternoon, we went to a local restaurant named Qu n Chay Thanh Li u. It was a vegan restaurant (remember the thing I mentioned earlier about Chay being in the name?). On the way, we had a steamed dumpling shaped like a momo called banh bao from a street vendor. It wasn t very good, but I found it worthwhile.
Bahn Bao in Hue. Photo by Ravi Dwivedi, released under CC-BY-SA 4.0.
At the restaurant, we ordered a hot pot. First, they brought noodles and a gas stove. Then came the stock and our gas stove was turned on. The stock was kept simmering on the stove. Then, we had it bit by bit with the noodles. A big hot pot at this place costs 50,000 dongs ( 170). Then we had b nh cu n. These were steamed rolls made of rice flour for 10,000 dongs ( 33).
Hot Pot. Photo by Ravi Dwivedi, released under CC-BY-SA 4.0.
Added soup to the noodles. Photo by Ravi Dwivedi, released under CC-BY-SA 4.0.
Steamed rolls made of rice flour. Photo by Ravi Dwivedi, released under CC-BY-SA 4.0.
Restaurants in Vietnam usually add photos of the meals in their menu or write a description in English. So, even though the dish names were Vietnamese, we had no problems in ordering food there. In addition, all the places we went to provided free Wi-Fi. They either mention the Wi-Fi password on the bill, on the menu or paste it on the wall. This made our trip smoother without getting a local SIM.
Menu from a restaurant in Ho Chi Minh City with detailed description of the food. Photo by Ravi Dwivedi, released under CC-BY-SA 4.0.
Then we slowly walked towards the railway station, as we had a night train to Hanoi. We had egg coffee in a cafe. Near the railway station, we had a b nh m (egg sandwich). As for sightseeing, we had plans to visit a couple of places in Hue, but we ended up spending all our time inside sheltered spaces due to heavy rain.
We had booked the train SE20 for Hanoi, which had a departure time of 20:41 from Hue. This one was 948,000 dongs ( 3100) for myself and 870,000 dongs ( 2900) for Badri. My ticket was pricier than Badri s because I got a lower berth. Our train was late by half an hour, so we waited in the common area of the station. After the train arrived, we got inside and took our seats.
The cabin had four berths two upper and two lower, similar to India s First AC class. The ticket inspector came to us and offered us the whole cabin (two additional berths) for 300,000 dongs ( 1,000), which we declined. However, this hinted at the other two seats not being reserved. Eventually, we had the whole cabin to ourselves, as nobody else showed up for the other two berths. It was a 14-hour journey, and I got a good sleep.
Our berths in the train. Photo by Ravi Dwivedi, released under CC-BY-SA 4.0.
Hanoi
On the morning of the 19th of December 2024, we reached Vietnam s capital, Hanoi. We had booked a private hotel room for 800. It was 1 km from the Hanoi Airport. However, it was pretty far from the railway station. So, we roamed around in the city and went to the hotel in the evening.
First, we walked to a place and had egg coffee with egg sandwiches. Then we went to Hanoi Train Street, which was walking distance from the train station. After clicking some pictures at the train street, we went to a museum nearby. Upon reaching there, we found out that it was closed.
Egg coffee in Hanoi. Photo by Ravi Dwivedi, released under CC-BY-SA 4.0.
Hanoi train street is a tourist attraction in Hanoi. Photo by Ravi Dwivedi, released under CC-BY-SA 4.0.
Then we went shopping for jackets, as Hanoi was cold compared to other parts of Vietnam we had been to, and since many of them are manufactured in Vietnam, we thought they would be cheaper. I liked some jackets, but they were not my size. Eventually, we didn t buy anything at the clothes shop.
In the evening, I bought a Vietnamese-styled phin coffee filter and coffee powder from Highlands Coffee. We spent a lot of time in their cafes, so it made sense to buy some souvenirs from there. Badri bought a few coffee filters for his family at Trung Nguyen, where I also bought another filter.
We had dinner at a local place where we had pho and banh it. Bahn it was served packed in banana leaves and it was made of sticky rice.
A picture of pho we had in Hanoi. Photo by Ravi Dwivedi, released under CC-BY-SA 4.0.
Bahn it is served packed in banana leaves. Photo by Ravi Dwivedi, released under CC-BY-SA 4.0.
Bahn it. Photo by Ravi Dwivedi, released under CC-BY-SA 4.0.
Next, we went to Hanoi railway station to catch a bus to the airport since our hotel was 1 km from the airport. The locals there helped us take the bus. It took like an hour to get to the airport. We saw on OpenStreetMap that we can take a bus from there to the hotel, but we could not find it. So we walked to our hotel instead.
It was a decent hotel room for 800 for a night. We went outside to explore the area and had egg sandwiches and egg coffee at a local place. Again, we were given a complimentary green tea. We went to this place like three times. We had practically become regulars by the time we left.
The next day 20th of December 2024 we took a bus to the airport and boarded our flight to Delhi.
Credits: Thanks Badri, Kishy and Richard for proofreading.
The
WWW::Mechanize::Chrome Saga: A Comprehensive Narrative of PR #104
This document synthesizes the extensive work performed from March
13th to March 20th, 2026, to harden, stabilize, and refactor the WWW::Mechanize::Chrome library and its test suite. This
effort involved deep dives into asynchronous programming,
platform-specific bug hunting, and strategic architectural
decisions.
Part I:
The Quest for Cross-Platform Stability (March 13 16)
The initial phase of work focused on achieving a green test suite
across a variety of Linux distributions and preparing for a new release.
This involved significant hardening of the library to account for
different browser versions, OS-level security restrictions, and
filesystem differences.
Key Milestones &
Engineering Decisions:
Fedora & RHEL-family Success: A major effort
was undertaken to achieve a 100% pass rate on modern Fedora 43 and
CentOS Stream 10. This required several key engineering decisions to
handle modern browser behavior:
Decision: Implement Asynchronous DOM Serialization
Fallback. Synchronous fallbacks in an async context are
dangerous. To prevent Resource was not cached errors during saveResources, we implemented a fully asynchronous fallback
in _saveResourceTree. By chaining _cached_document with DOM.getOuterHTML
messages, we can reconstruct document content without blocking the event
loop, even if Chromium has evicted the resource from its cache. This
also proved resilient against Fedora s security policies, which often
block file:// access.
Decision: Truncate Filenames for Cross-Platform
Safety. To avoid File name too long errors,
especially on Windows where the MAX_PATH limit is 260
characters, filenameFromUrl was hardened. The filename
truncation was reduced to a more conservative 150
characters, leaving ample headroom for deeply nested CI
temporary directories. Logic was also added to preserve file extensions
during truncation and to sanitize backslashes from URI paths.
Decision: Expand Browser Discovery Paths. To
support RHEL-based systems out-of-the-box, the default_executable_names was expanded to include headless_shell and search paths were updated to include /usr/lib64/chromium-browser/.
Decision: Mitigate Race Conditions with Stabilization Waits
and Resilient Fetching. On fast systems, DOM.documentUpdated events could invalidate nodeIds immediately after navigation, causing XPath queries
to fail with Could not find node with given id . A small stabilization sleep(0.25s) was added after page loads to ensure the DOM
is settled. Furthermore, the asynchronous DOM fetching loop was hardened
to gracefully handle these errors by catching protocol errors and
returning an empty string for any node that was invalidated during
serialization, ensuring the overall process could complete.
Windows Hardening:
Decision: Adopt Platform-Aware Watchdogs. The test
suite s reliance on ualarm was a blocker for Windows, where
it is not implemented. The t::helper::set_watchdog function
was refactored to use standard alarm() (seconds) on Windows
and ualarm (microseconds) on Unix-like systems, enabling
consistent test-level timeout enforcement.
Version 0.77 Release:
Decision: Adopt SOP for Version Synchronization.
The project maintains duplicate version strings across 24+ files. A
Standard Operating Procedure was adopted to use a batch-replacement tool
to update all sub-modules in lib/ and to always run make clean and perl Makefile.PL to ensure META.json and META.yml reflect the new
version. After achieving stability on Linux, the project version was
bumped to 0.77.
Infrastructure & Strategic Work:
The ad2 Windows Server 2025 instance was restored and
optimized, with Active Directory demoted and disk I/O performance
improved.
A strategic proposal for the Heterogeneous Directory
Replication Protocol (HDRP) was drafted and published.
Part II: The
Great Async Refactor (March 17 18)
Despite success on Linux, tests on the slow ad2 Windows
host were still plagued by intermittent, indefinite hangs. This
triggered a fundamental architectural shift to move the library s core
from a mix of synchronous and asynchronous code to a fully non-blocking
internal API.
Key Milestones &
Engineering Decisions:
Decision: Expose a _future API.
Instead of hardcoding timeouts in the library, the core strategy was to
refactor all blocking methods (xpath, field, get, etc.) into thin wrappers around new non-blocking ..._future counterparts. This moved timeout management to
the test harness, allowing for flexible and explicit handling of
stalls.
# Example library implementationsub xpath($self, $query, %options) return$self->xpath_future($query, %options)->get;sub xpath_future($self, $query, %options) # Async implementation using $self->target->send_message(...)
Decision: Centralize Test Hardening in a Helper.
A dedicated test library, t/lib/t/helper.pm, was created to
contain all stabilization logic. Safe wrappers (safe_get, safe_xpath) were implemented there, using Future->wait_any to race asynchronous operations against
a timeout, preventing tests from hanging.
Decision: Refactor Node Attribute Cache.
Investigations into flaky checkbox tests (t/50-tick.t)
revealed that WWW::Mechanize::Chrome::Node was storing
attributes as a flat list ([key, val, key, val]), which was
inefficient for lookups and individual updates. The cache was refactored
to definitively use a HashRef, providing O(1) lookups
and enabling atomic dual-updates where both the browser property (via
JS) and the internal library attribute are synchronized
simultaneously.
Decision: Implement Self-Cancelling Socket
Watchdog. On Windows, traditional watchdog processes often
failed to detect parent termination, leading to 60-second hangs after
successful tests. We implemented a new socket-based watchdog in t::helper that listens on an ephemeral port; the background
process terminates immediately when the parent socket closes,
eliminating these cumulative delays.
Decision: Deep Recursive Refactoring & Form
Selection. To make the API truly non-blocking, the entire
internal call stack had to be refactored. For example, making get_set_value_future non-blocking required first making its
dependency, _field_by_name, asynchronous. This culminated
in refactoring the entire form selection API (form_name, form_id, etc.) to use the new asynchronous _future lookups, which was a key step in mitigating the
Windows deadlocks.
Evaluation Normalization: Implemented a _process_eval_result helper to centralize the parsing of
results from Runtime.evaluate. This ensures consistent
handling of return values and exceptions between synchronous
(eval_in_page) and asynchronous (eval_future)
calls.
Memory Cycle Mitigation: A significant memory
leak was discovered where closures attached to CDP event futures (like
for asynchronous body retrieval) would capture strong references to $self and the $response object, creating a
circular reference. The established rule is to now always use Scalar::Util::weaken on both $self and any
other relevant objects before they are used inside a ->then block that is stored on an object.
Context Propagation (wantarray): A
major regression was discovered where Perl s wantarray
context, which distinguishes between scalar and list context, was lost
inside asynchronous Future->then blocks. This caused
methods like xpath to return incorrect results (e.g., a
count instead of a list of nodes). The solution was to adopt the Async
Context Pattern : capture wantarray in the synchronous
wrapper, pass it as an option to the _future method, and
then use that captured value inside the future s final resolution
block.
Asynchronous Body Retrieval & Robust Content
Fallbacks: Fixed a bug where decoded_content()
would return empty strings by ensuring it awaited a __body_future. This was implemented by storing the
retrieval future directly on the response object
($response-> __body_future ). To make this more robust,
a tiered strategy was implemented: first try to get the content from the
network response, but if that fails (e.g., for about:blank
or due to cache eviction), fall back to a JavaScript XMLSerializer to get the live DOM content.
Signature Hardening: Fixed Too few arguments
errors when using modern Perl signatures with Future->then. Callbacks were updated to use optional
parameters (sub($result = undef) ... ) to gracefully
handle futures that resolve with no value.
XHTML Split-Brain Bug: Resolved a
long-standing Chromium bug (40130141) where content provided via setDocumentContent is parsed differently than content
loaded from a URL. A workaround was implemented: for XHTML documents,
WMC now uses a JavaScript-based XPath evaluation
(document.evaluate) against the live DOM, bypassing the
broken CDP search mechanism.
Derived Architectural Rules
& SOPs:
Rule: Always provide _future variants.
Every library method that interacts with the browser via CDP must have a
non-blocking asynchronous counterpart.
Rule: Centralize stabilization in the test layer.
All timeout and retry logic should reside in the test harness
(t/lib/t/helper.pm), not in the core library.
Rule: Explicitly propagate wantarray
context. Synchronous wrappers must capture the caller s context
and pass it down the Future chain to ensure correct
scalar/list behavior.
Rule: The entire call chain must be asynchronous.
To enable non-blocking timeouts, even a single hidden blocking call in
an otherwise asynchronous method will cause a stall.
SOP: Reduce Library Noise. Diagnostic messages
(warn, note, diag) should be
removed from library code before commits. All such messages should be
converted to use the internal $self->log('debug', ...)
mechanism, ensuring a clean TAP output for CI systems.
Part III: The MutationObserver Saga (March 19)
With most of the library refactored to be asynchronous, one stubborn
test, t/65-is_visible.t, continued to fail with timeouts.
This led to an ambitious, but ultimately unsuccessful, attempt to
replace the wait_until_visible polling logic with a more
modern MutationObserver.
Key Milestones & Challenges:
The Theory: The goal was to replace an inefficient repeat sleep loop with an event-driven MutationObserver in JavaScript that would notify Perl
immediately when an element s visibility changed.
Implementation & Cascade Failure: The
implementation proved incredibly difficult and introduced a series of
new, hard-to-diagnose bugs:
An incorrect function signature for callFunctionOn_future.
A critical unit mismatch, passing seconds from Perl to JavaScript s setTimeout, which expected milliseconds.
A fundamental hang where the MutationObserver s
JavaScript Promise would never resolve, even after the
underlying DOM element changed.
Debugging Maze: Multiple attempts to fix the checkVisibility JavaScript logic inside the observer
callback, including making it more robust by adding DOM tree traversal
and extensive console.log tracing, failed to resolve the
hang. This highlighted the opacity and difficulty of debugging complex,
cross-language asynchronous interactions, especially when dealing with
low-level browser APIs.
Procedural Learning:
Granular Edits
The effort was plagued by procedural missteps in using automated
file-editing tools. Initial attempts to replace large code blocks in a
single operation led to accidental code loss and match failures.
Decision: Adopt Delete, then Add Workflow.
Following forceful user correction, a new SOP was established for all
future modifications:
Isolate: Break the file into small, manageable
chunks (e.g., 250 lines).
Delete: Perform a delete operation by replacing
the old code block with an empty string.
Add: Perform an add operation by inserting the
new code into the empty space.
Verify: Verifying each atomic step before
proceeding. This granular process, while slower, ensured surgical
precision and regained technical control over the large Chrome.pm module.
The consistent failure of the MutationObserver approach
eventually led to the decision to abandon it in favor of stabilizing the
original, more transparent implementation.
Part IV:
Reversion and Final Stabilization (March 20)
After exhausting all reasonable attempts to fix the MutationObserver, a strategic decision was made to revert
to the simpler, more transparent polling implementation and fix it
correctly. This proved to be the correct path to a stable solution.
Key Milestones &
Engineering Decisions:
Decision: Perform Strategic Reversion. The MutationObserver implementation, when integrated via callFunctionOn_future with awaitPromise,
proved fundamentally unstable. Its JavaScript promise would consistently
fail to resolve, causing indefinite hangs. A decision was made to
revert all MutationObserver code from WWW::Mechanize::Chrome.pm and restore the original repeat sleep polling mechanism. A stable,
understandable solution was prioritized over an elegant but broken
one.
Decision: Correct Timeout Delegation in the
Harness. The root cause of the original timeout failure was
identified as a race condition in the t/lib/t/helper.pm
test harness. The safe_wait_until_* wrappers were
implementing their own timeout (via wait_any and sleep_future) that raced against the underlying polling
function s internal timeout. This led to intermittent failures on slow
machines. The helpers were refactored to delegate all timeout
management to the library s polling functions, ensuring a
single, authoritative timer controlled the operation.
Decision: Optimize Polling Performance. At the
user s request, the polling interval was reduced from 300ms to
150ms. This modest performance improvement reduced the
test suite s wallclock execution time by over a second while maintaining
stability.
Decision: Tune Test Watchdogs. The global watchdog
timeout was adjusted to 12 seconds, specifically calculated as 1.5x the
observed real execution time of the optimized test. This provides a
data-driven safety margin for CI.
Part
V: The Last Bug A Platform-Specific Memory Leak (March 20)
With all other tests passing, a single memory leak failure in t/78-memleak.t persisted, but only on the Windows ad2 environment. This required a different approach than
the timeout fixes.
Key Milestones:
The Bug: A strong reference cycle involving the on_dialog event listener was not being broken on Windows,
despite multiple attempts to fix it. Fixes that worked on Linux (such as
calling on_dialog(undef) in DESTROY) were not
sufficient on the Windows host.
The Diagnosis: The issue was determined to be a
deep, platform-specific interaction between Perl s garbage collector,
the IO::Async event loop implementation on Windows, and the Test::Memory::Cycle module. The cycle report was identical
on both platforms, but the cleanup behavior was different.
Failed Attempts: A series of increasingly
aggressive fixes were attempted to break the cycle, including:
Moving the on_dialog(undef) call from close() to DESTROY().
Explicitly deleteing the listener and callback
properties from the object hash in DESTROY.
Swapping between $self->remove_listener and $self->target->unlisten in a mistaken attempt to find
the correct un-registration method.
Pragmatic Solution: After exhausting all reasonable
code-level fixes without a resolution on Windows, the user opted to mark
the failing test as a known issue for that specific platform.
Final Fix: The single failing test in t/78-memleak.t was wrapped in a conditional TODO block that only executes on Windows
(if ($^O =~ /MSWin32/i)), formally acknowledging the bug
without blocking the build. This allows the test suite to pass in CI
environments while flagging the issue for future, deeper
investigation.
Part VI: CI Hardening (March
20)
A final failure in the GitHub Actions CI environment revealed one
last configuration flaw.
Key Milestones:
The Bug: The CI was running prove --nocount --jobs 3 -I local/ -bl xt t directly. This
command was missing the crucial -It/lib include path, which
is necessary for test files to locate the t::helper module.
This resulted in nearly all tests failing with Can't locate t/helper.pm in @INC.
The Investigation: An analysis of Makefile.PL revealed a custom MY::test block
specifically designed to inject the -It/lib flag into the make test command. This confirmed that make test is the correct, canonical way to run the test
suite for this project.
The Fix: The .github/workflows/linux.yml file was modified to replace
the direct prove call with make test in the Run Tests step. This ensures the CI environment runs the
tests in the exact same way as a local developer, with all necessary
include paths correctly configured by the project s build system.
Final Outcome
After this long and arduous journey, the WWW::Mechanize::Chrome test suite is now stable and
passing on all targeted platforms, with known
platform-specific issues clearly documented in the code. The project is
in a vastly more robust and reliable state.
Version 0.0.28 of RcppSpdlog arrived
on CRAN today, has been
uploaded to Debian and built for r2u. The (nice) documentation site
has been refreshed too. RcppSpdlog
bundles spdlog, a
wonderful header-only C++ logging library with all the bells and
whistles you would want that was written by Gabi Melman, and also includes fmt by Victor Zverovich. You can learn
more at the nice package
documention site.
This release contains a rebuild RcppExports.cpp to aid
Rcpp in the transition towards
Rcpp::stop() and away from Rf_error() in its
user packages. No othe
The NEWS entry for this release follows.
Changes in
RcppSpdlog version 0.0.28 (2026-03-19)
Regenerate RcppExports.cpp to switch to
(Rf_error) aiding in Rcpp
transition to Rcpp::stop()
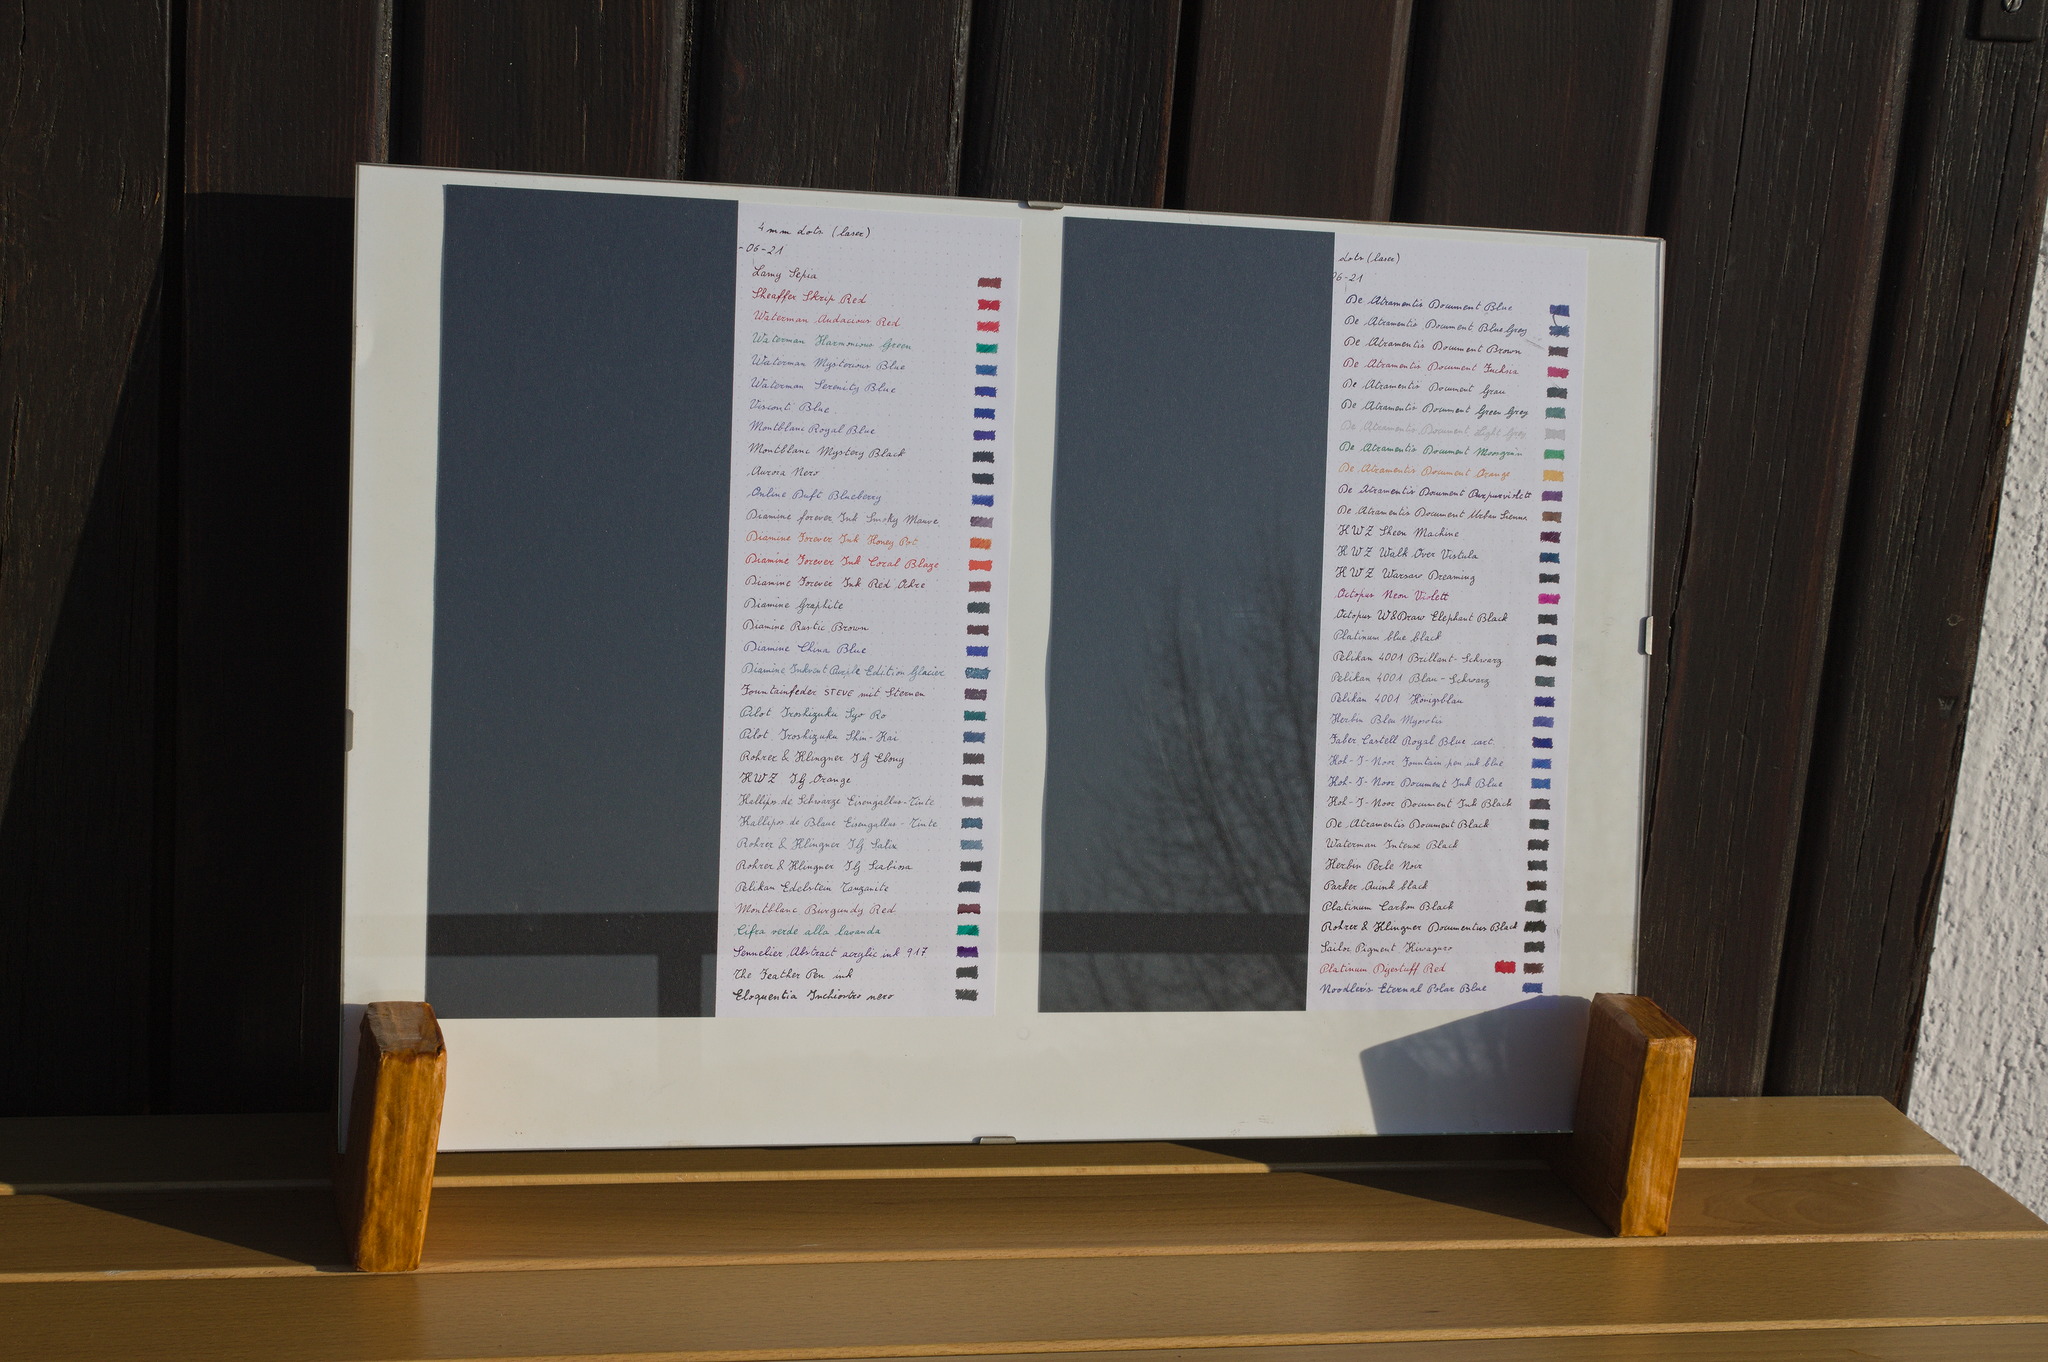
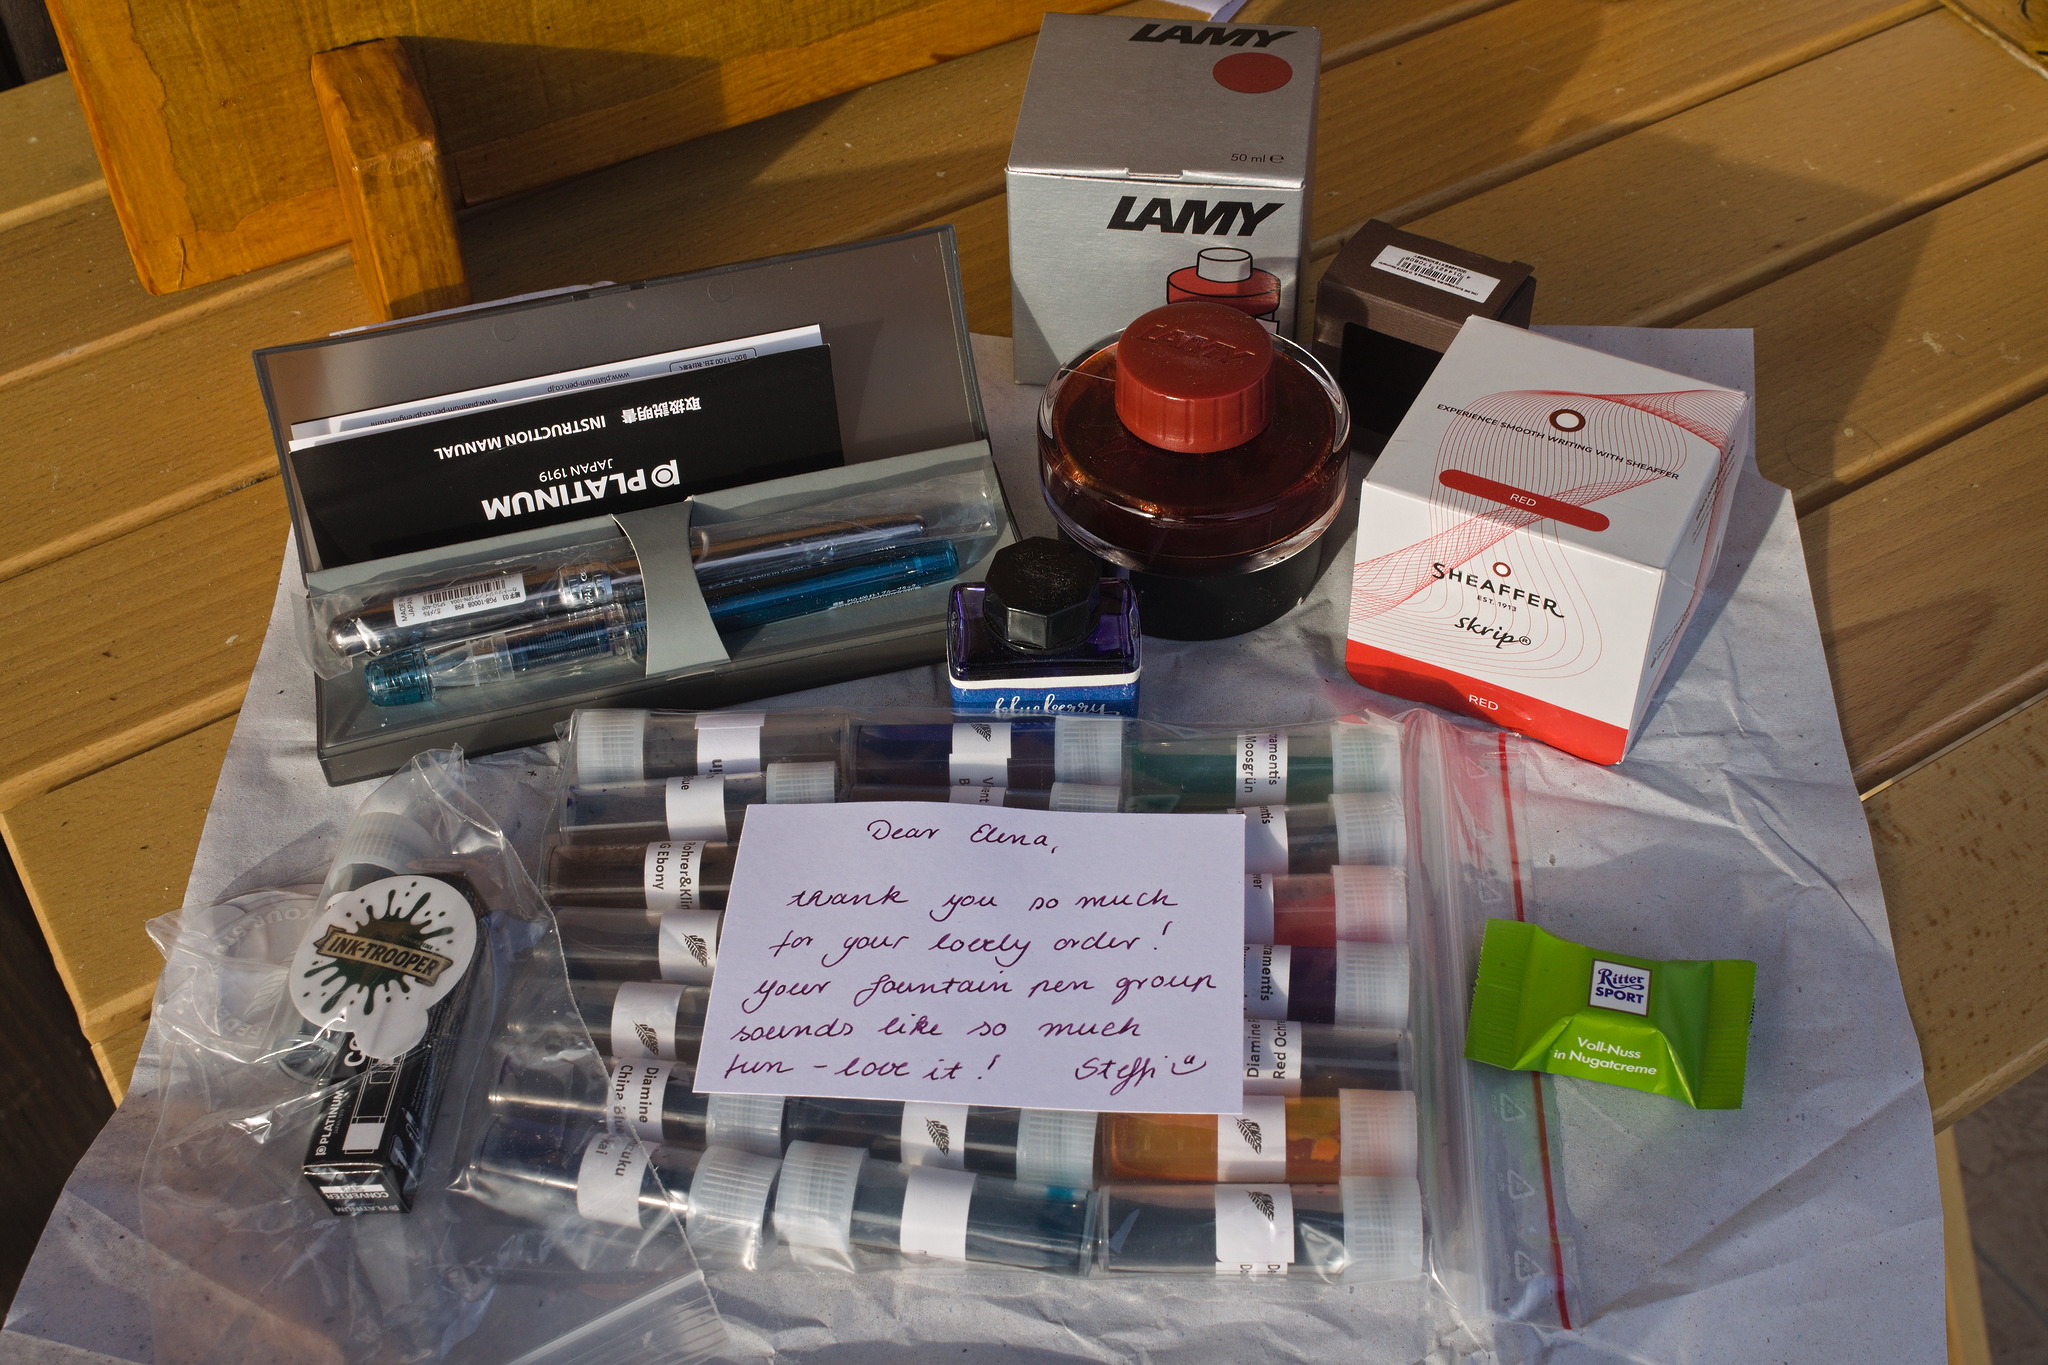 The next step, already in January, was mentioning in a fountain-pen
enthusiasts forum that I planned such a test, and asking if people were
interested in having me buy a few samples of more inks when I was
buying my next pen.
The word enthusiasts is probably a hint of the reason why soon
afterwards I received a package with the pen I had planned to buy, its
converter, and a couple dozens ink samples.
And then a couple envelopes with additional samples of inks that weren t
available on the shops, from said enthusiasts.
Added to the inks I already had acquired since the last lightfastness
test, it meant that they couldn t all fit in one single page, and thus I
had some room to add some inks I had already tested: some were requests,
and for others I tried to select ones that felt relevant.
Since I m changing the test setup, I ve decided I should probably keep
doing this until I ve tested again all of the inks I still have
available.
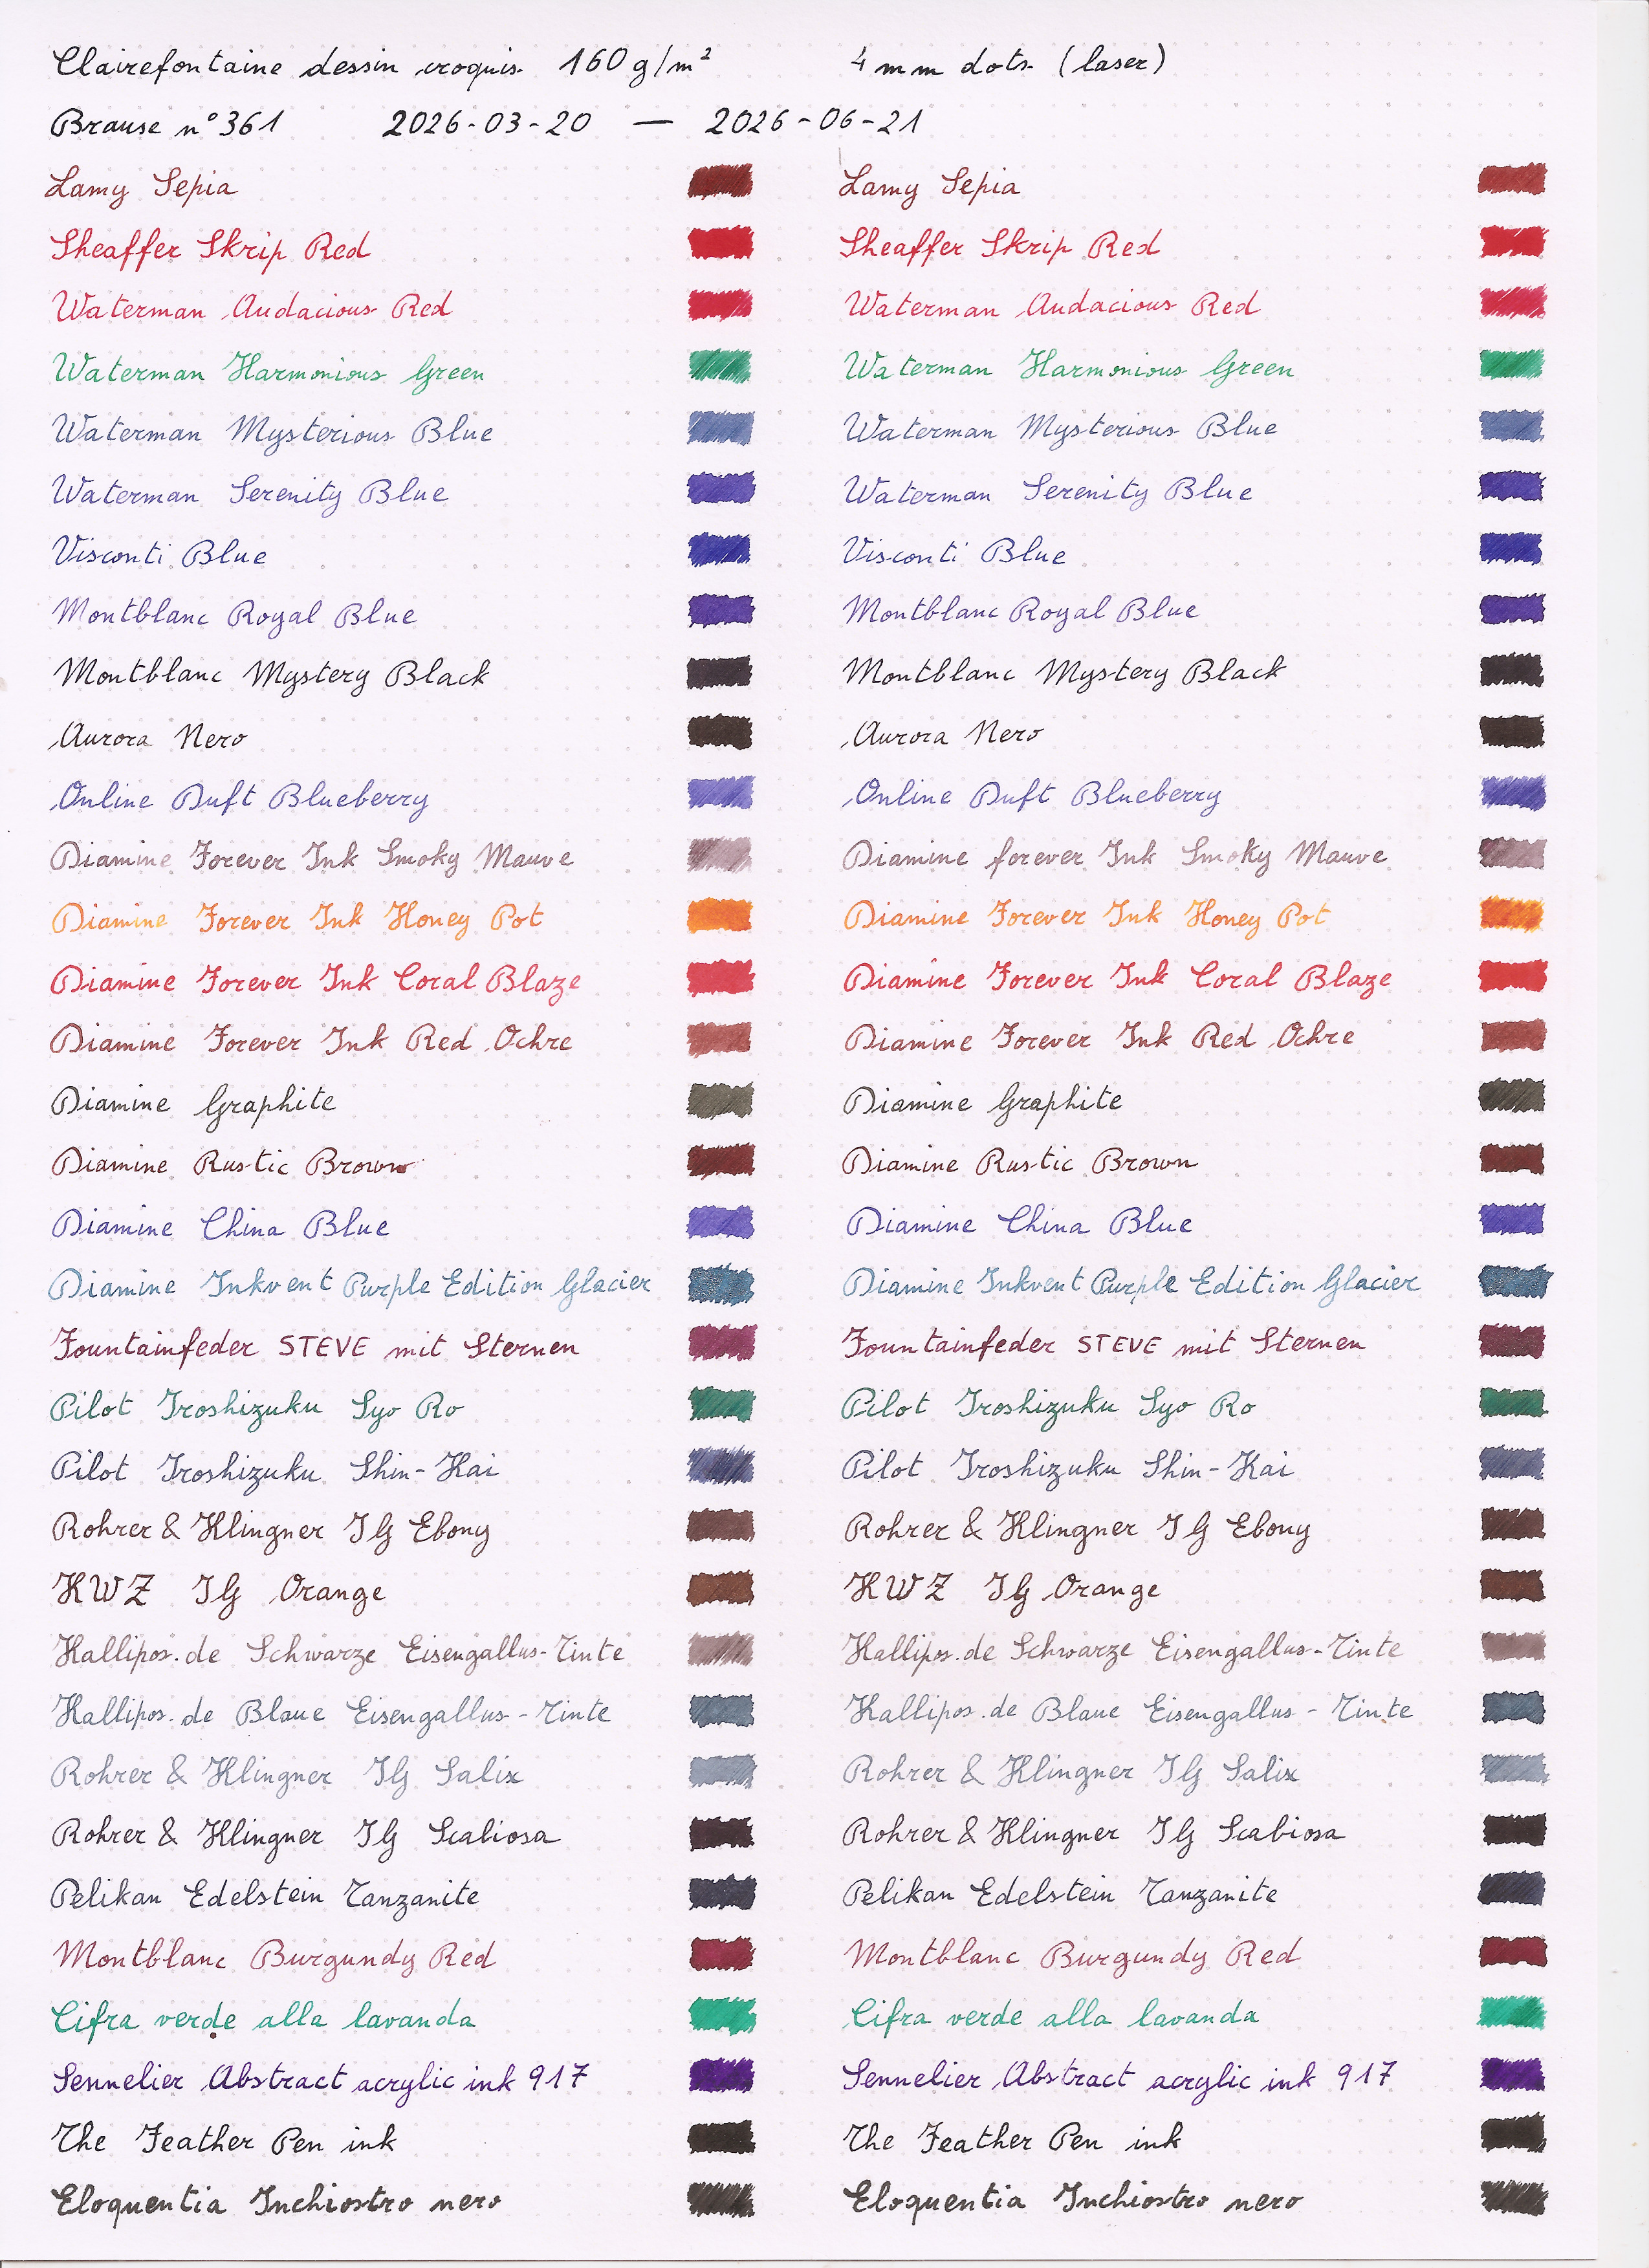
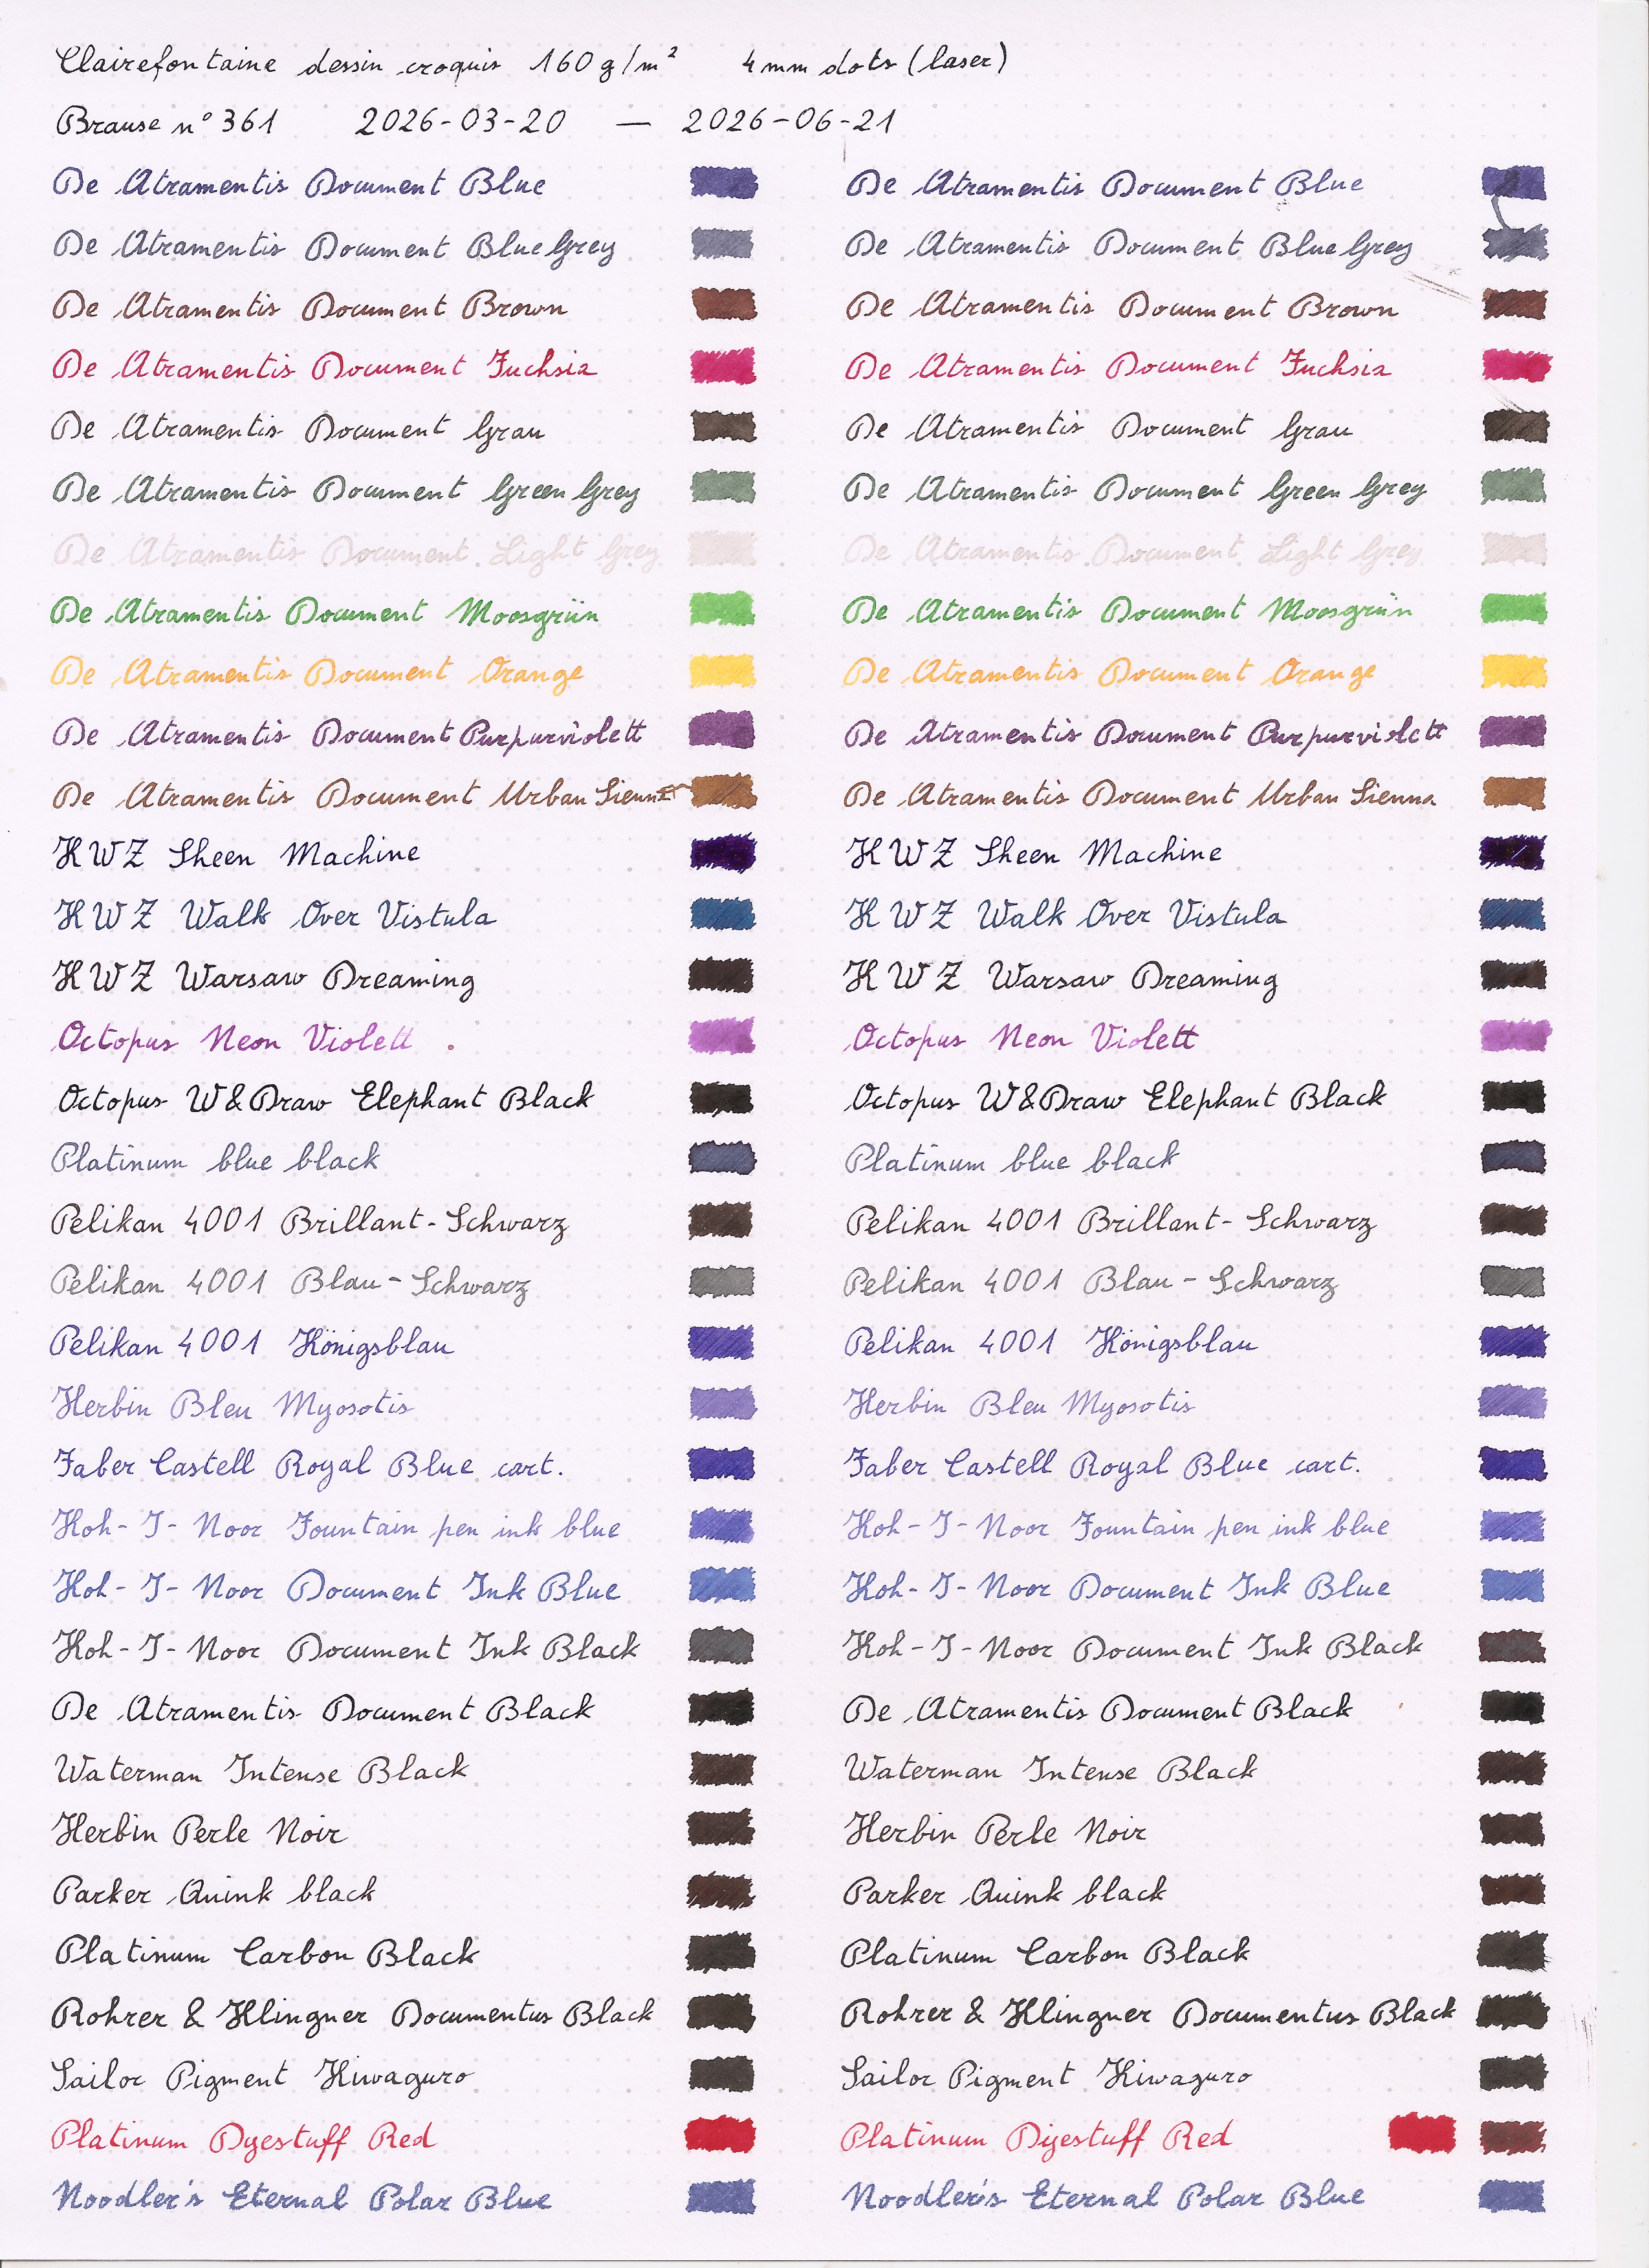 For the paper, I ve used A4 sheets of
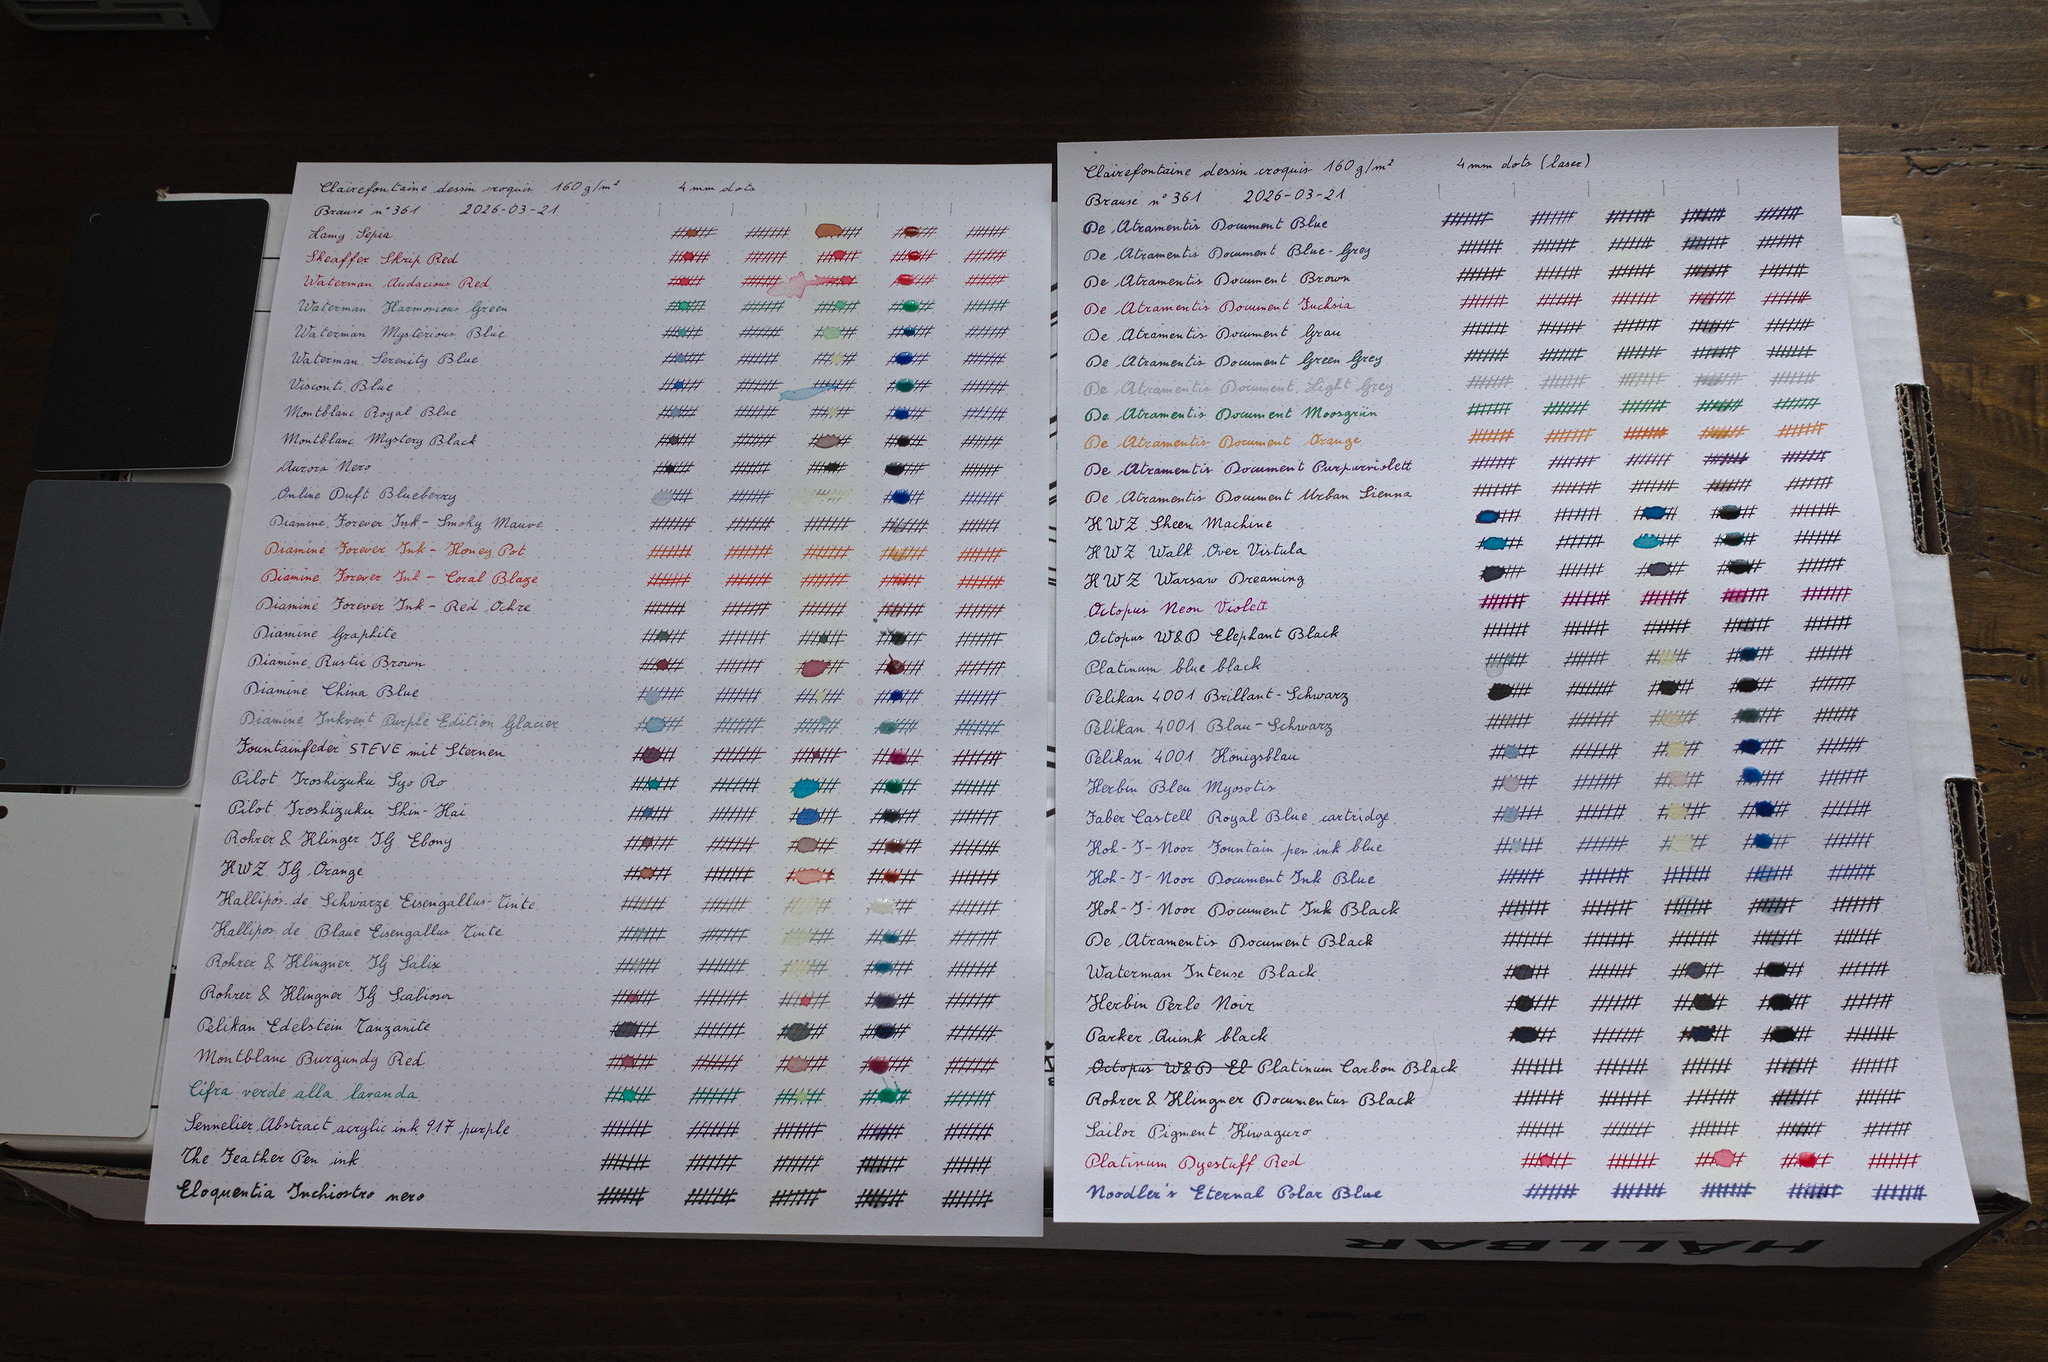 While I was filling the sheet for the lightfastness tests, I decided to
also prepare a second set of sheet, for a liquid resistance drop test.
On each line, beside the name of the ink, I added five sets of crossing
parallel lines, and let everything dry for a few days.
Then I used a syringe to put a drop of a liquid on each set of lines,
waited for it to be absorbed into the paper and to dry, at least
overnight, but sometimes also for a day or two (life happened), and then
looked at the results and did the next test.
The first liquid was water, with the usual wild difference between
washable and permanent inks, and all of the intermediate possibilities.
The second liquid was isopropyl alcohol, and I was surprised to see
that, with very few exceptions, most inks didn t change at all. I
wonder whether that s related to the fact that instead of forming a drop
it was absorbed almost immediately into the paper, and dried in a very
short time.
The third liquid was hydrogen peroxide: beside the individual results I
noticed that its column yellowed visibly; I wonder whether that means
that the paper I used has optical brighteners, and it will also yellow
under the sun: that wouldn t be ideal, but it would also be a surprise,
for paper that is acid free and sold for arts.
The fourth liquid was citric acid, by mixing a bit less than a teaspoon
of citric acid granules in just enough very warm water (heated to 70 C,
i.e. the lowest temperature available on my kettle) to dissolve most of
the acid. I forgot that I had some old PH strips until one hour after
I ve put the drop on the paper, and I don t know whether something had
changed, but when I did remember about them it showed a deep red between
1 and 2. I don t think I can trust those strips too much, however.
This backfired badly: the drop of citric acid never dried out, but
formed a sticky paste that prevented me from scanning the results,
and I m not sure whether I ll do the last test, which was supposed to be
household bleach.
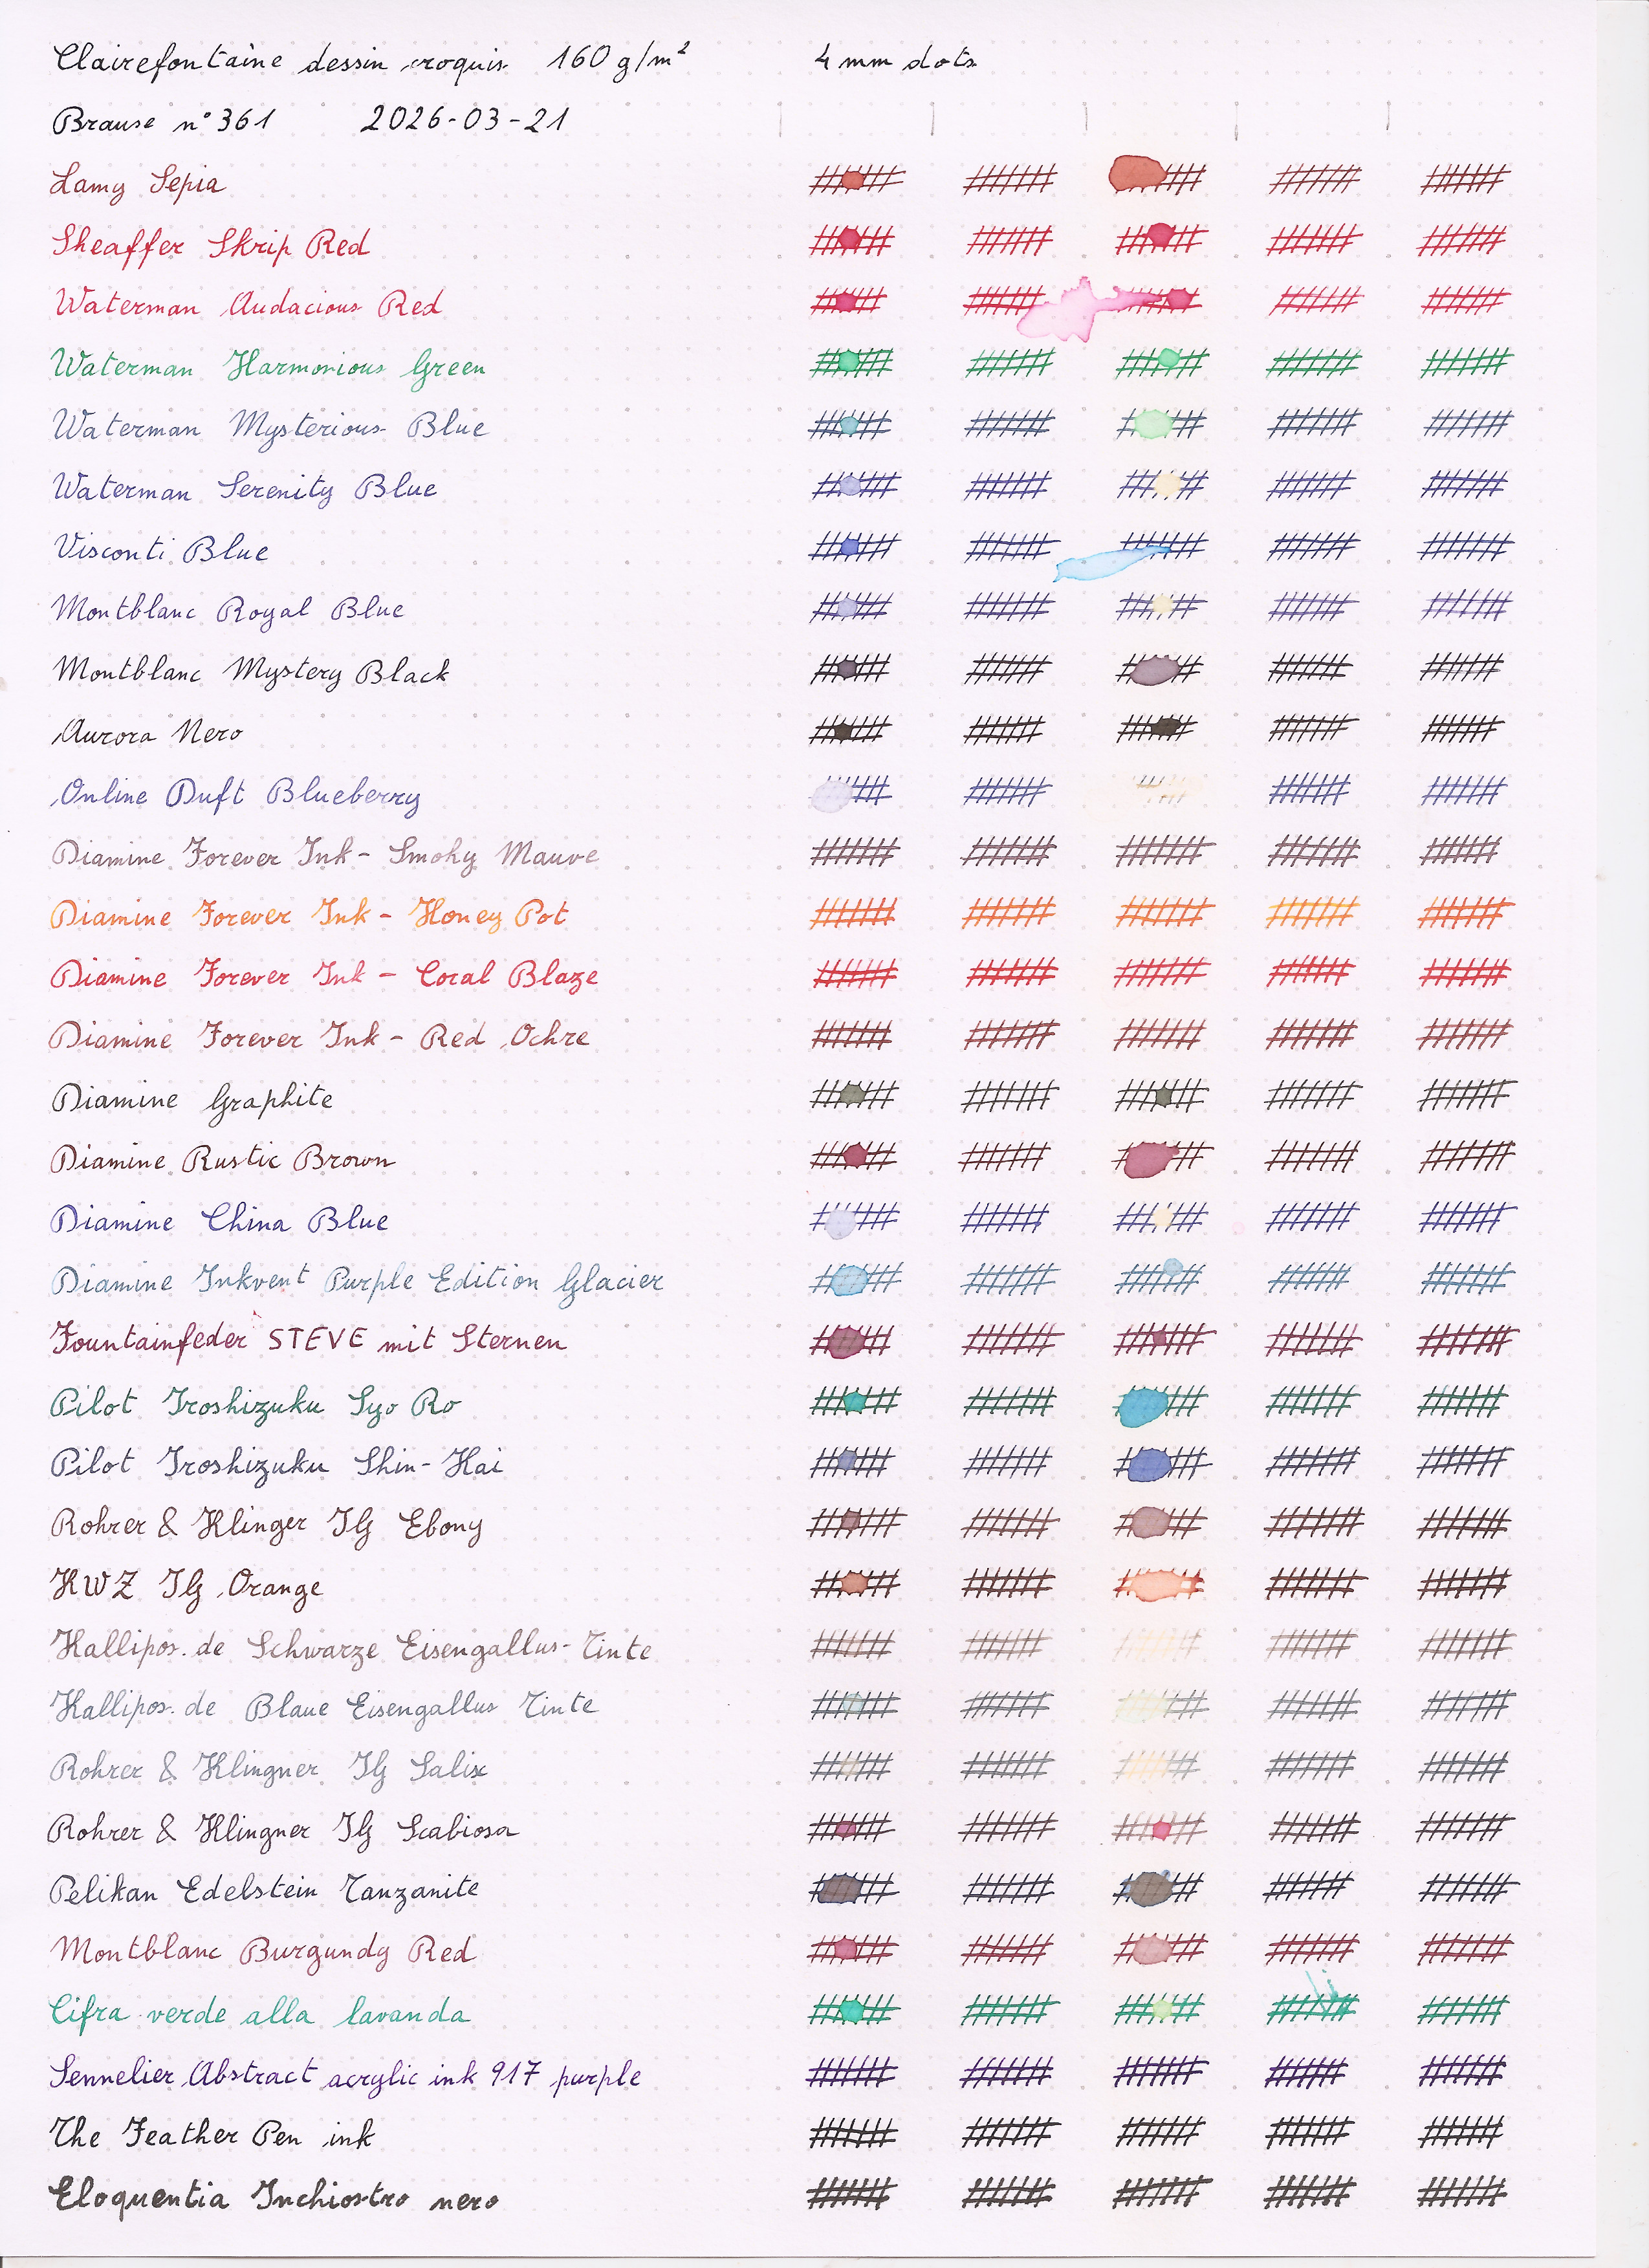
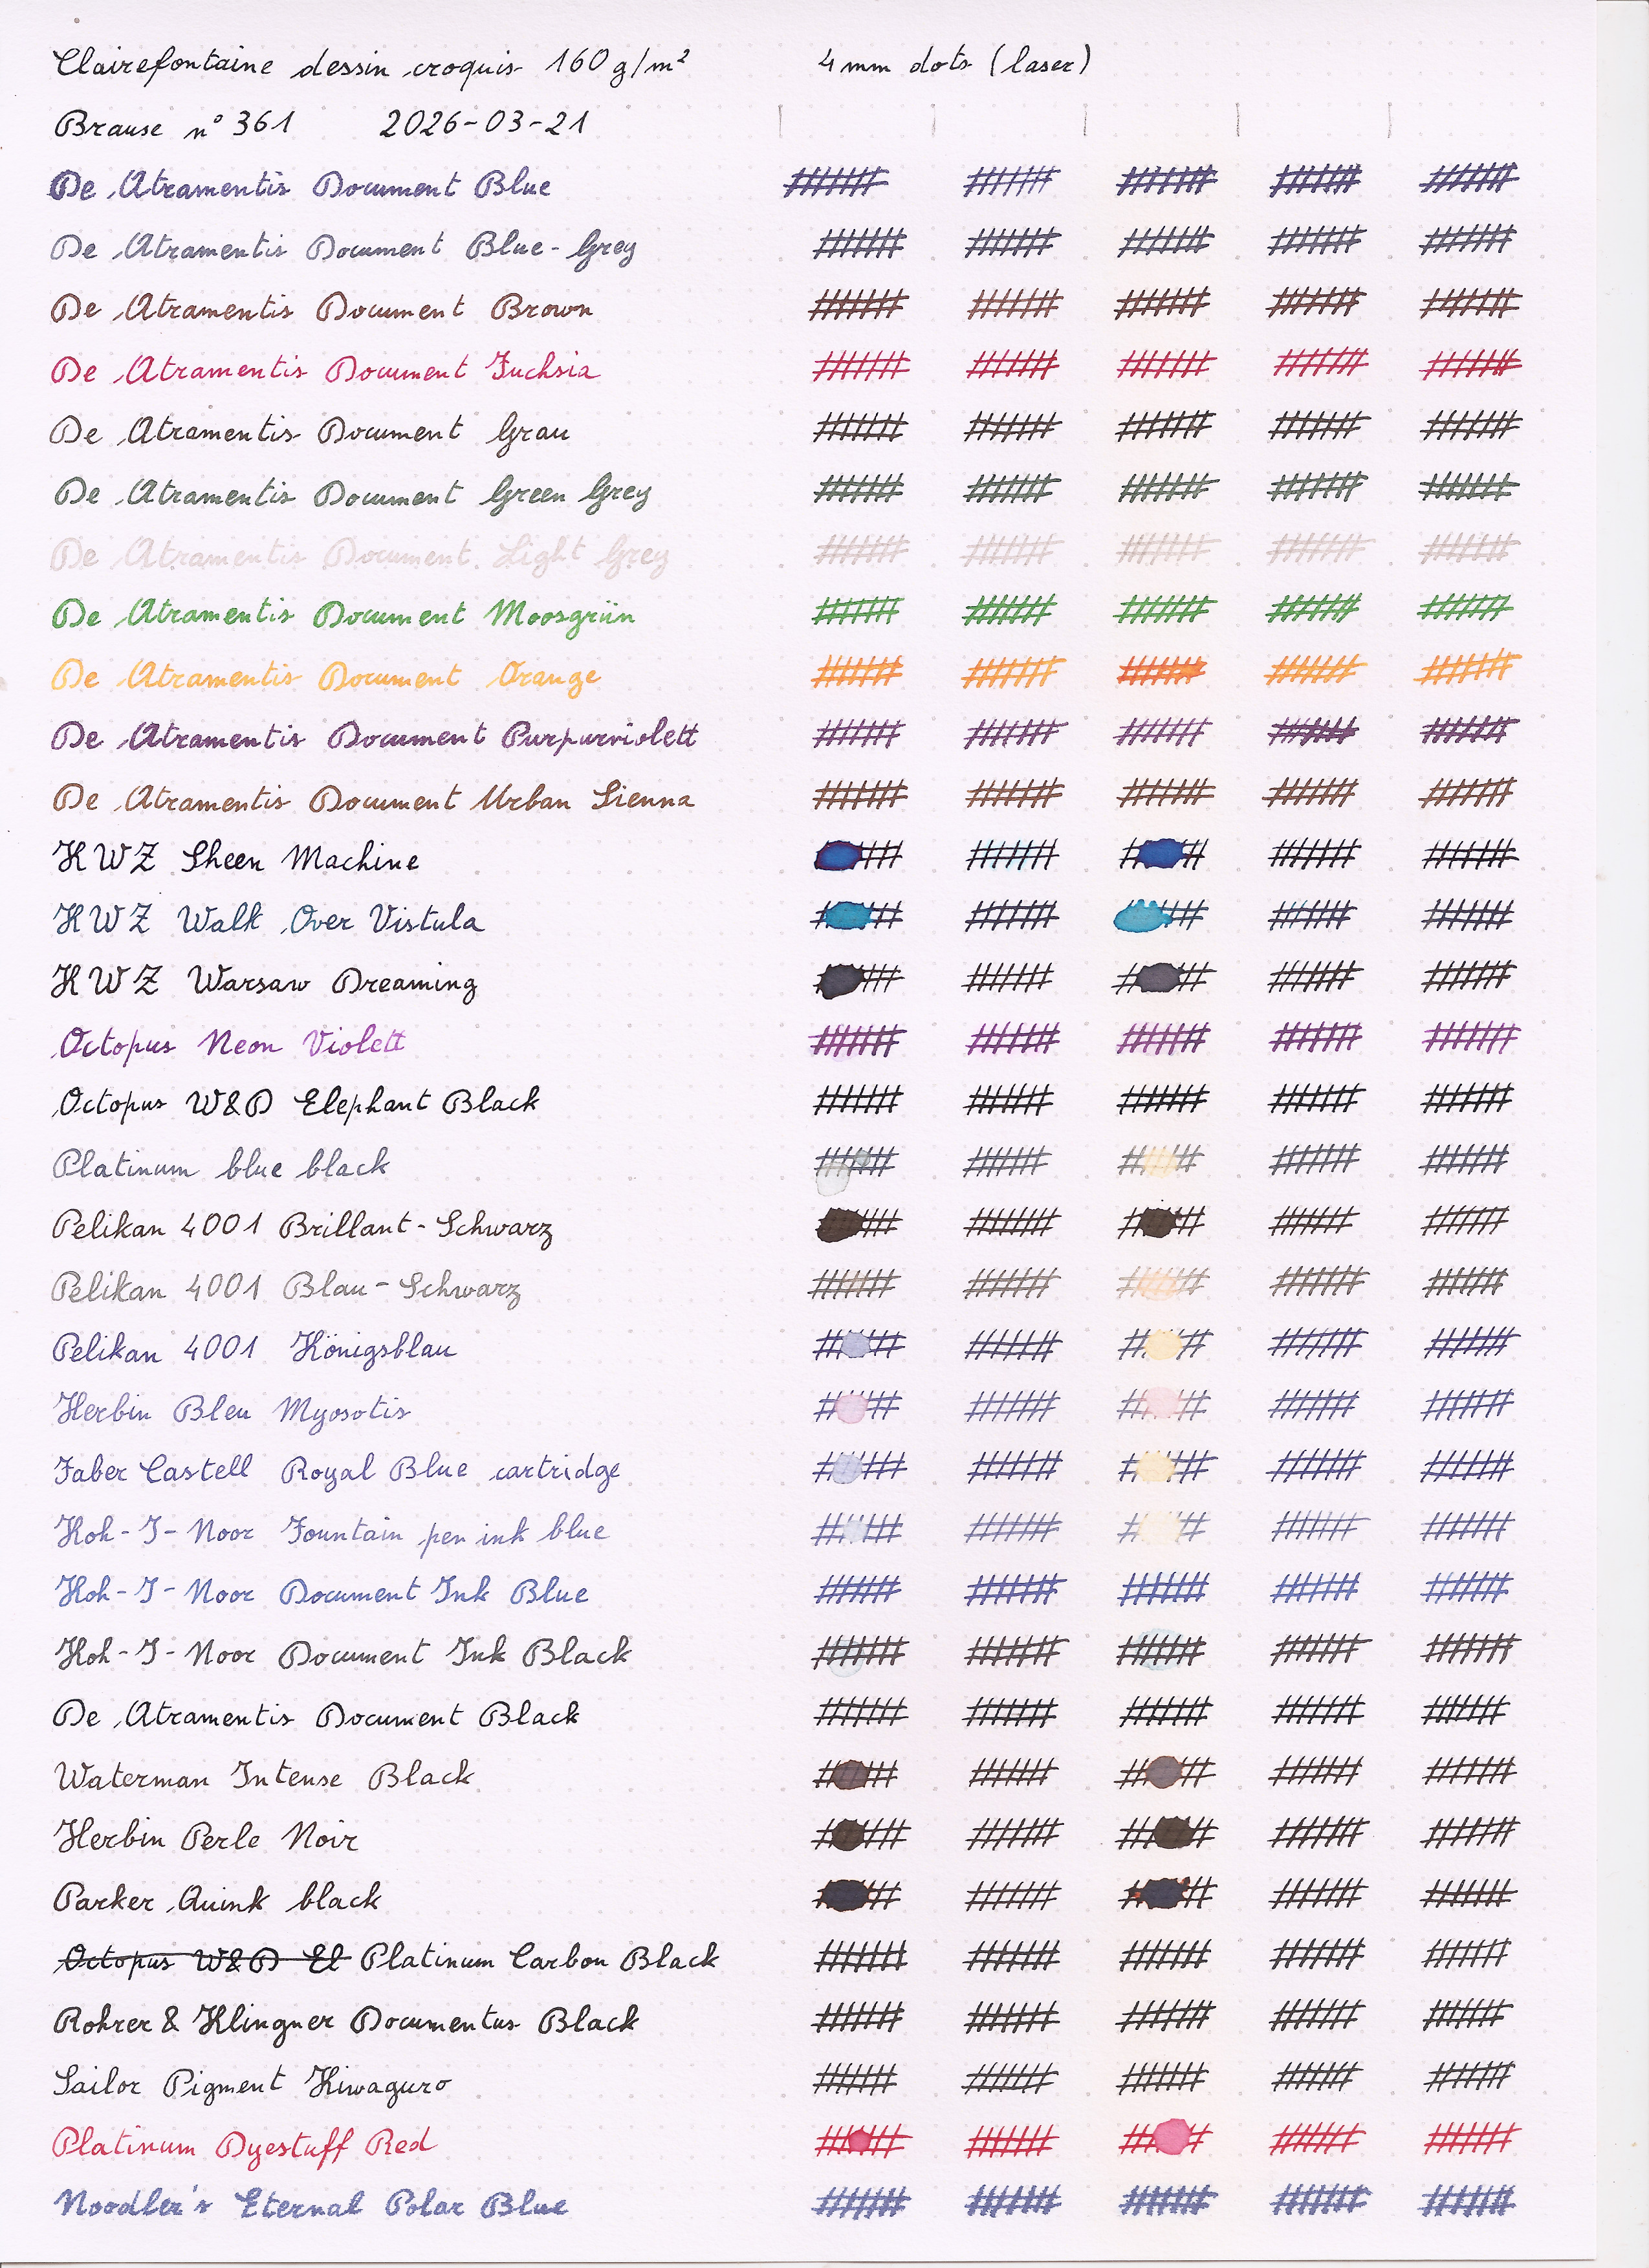 Luckily I had scanned the partial results, and they are shown here.
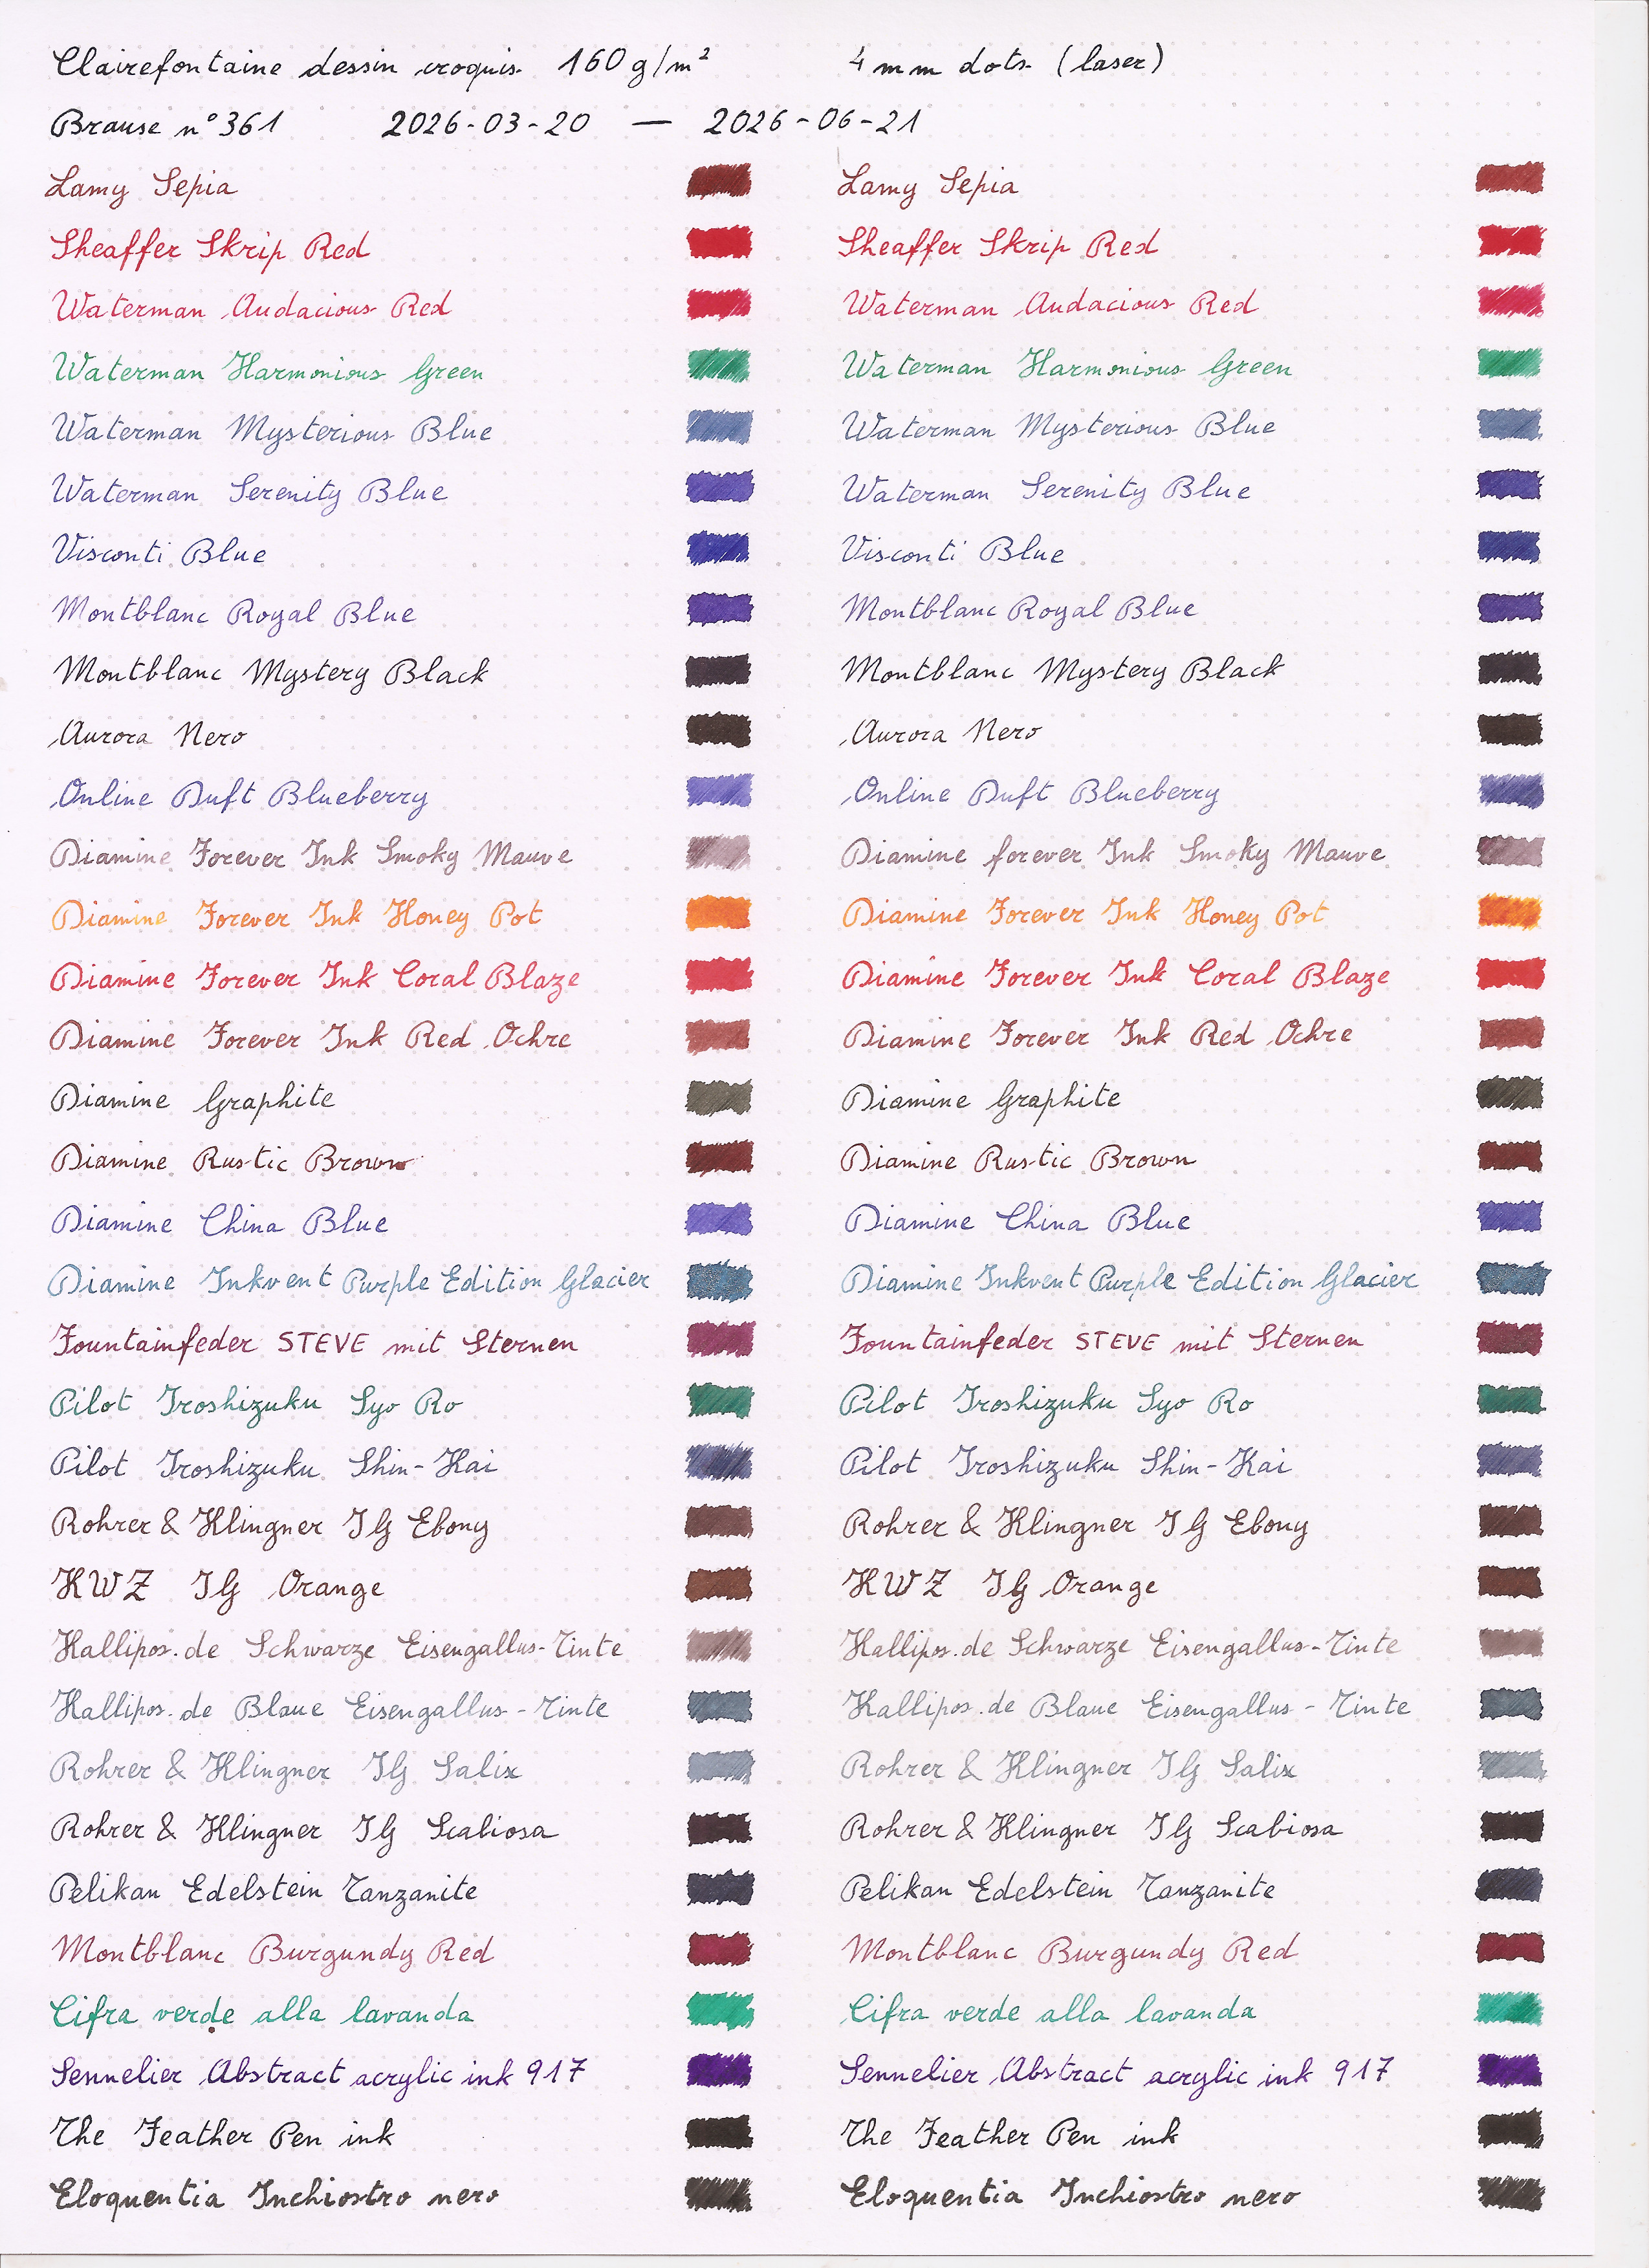
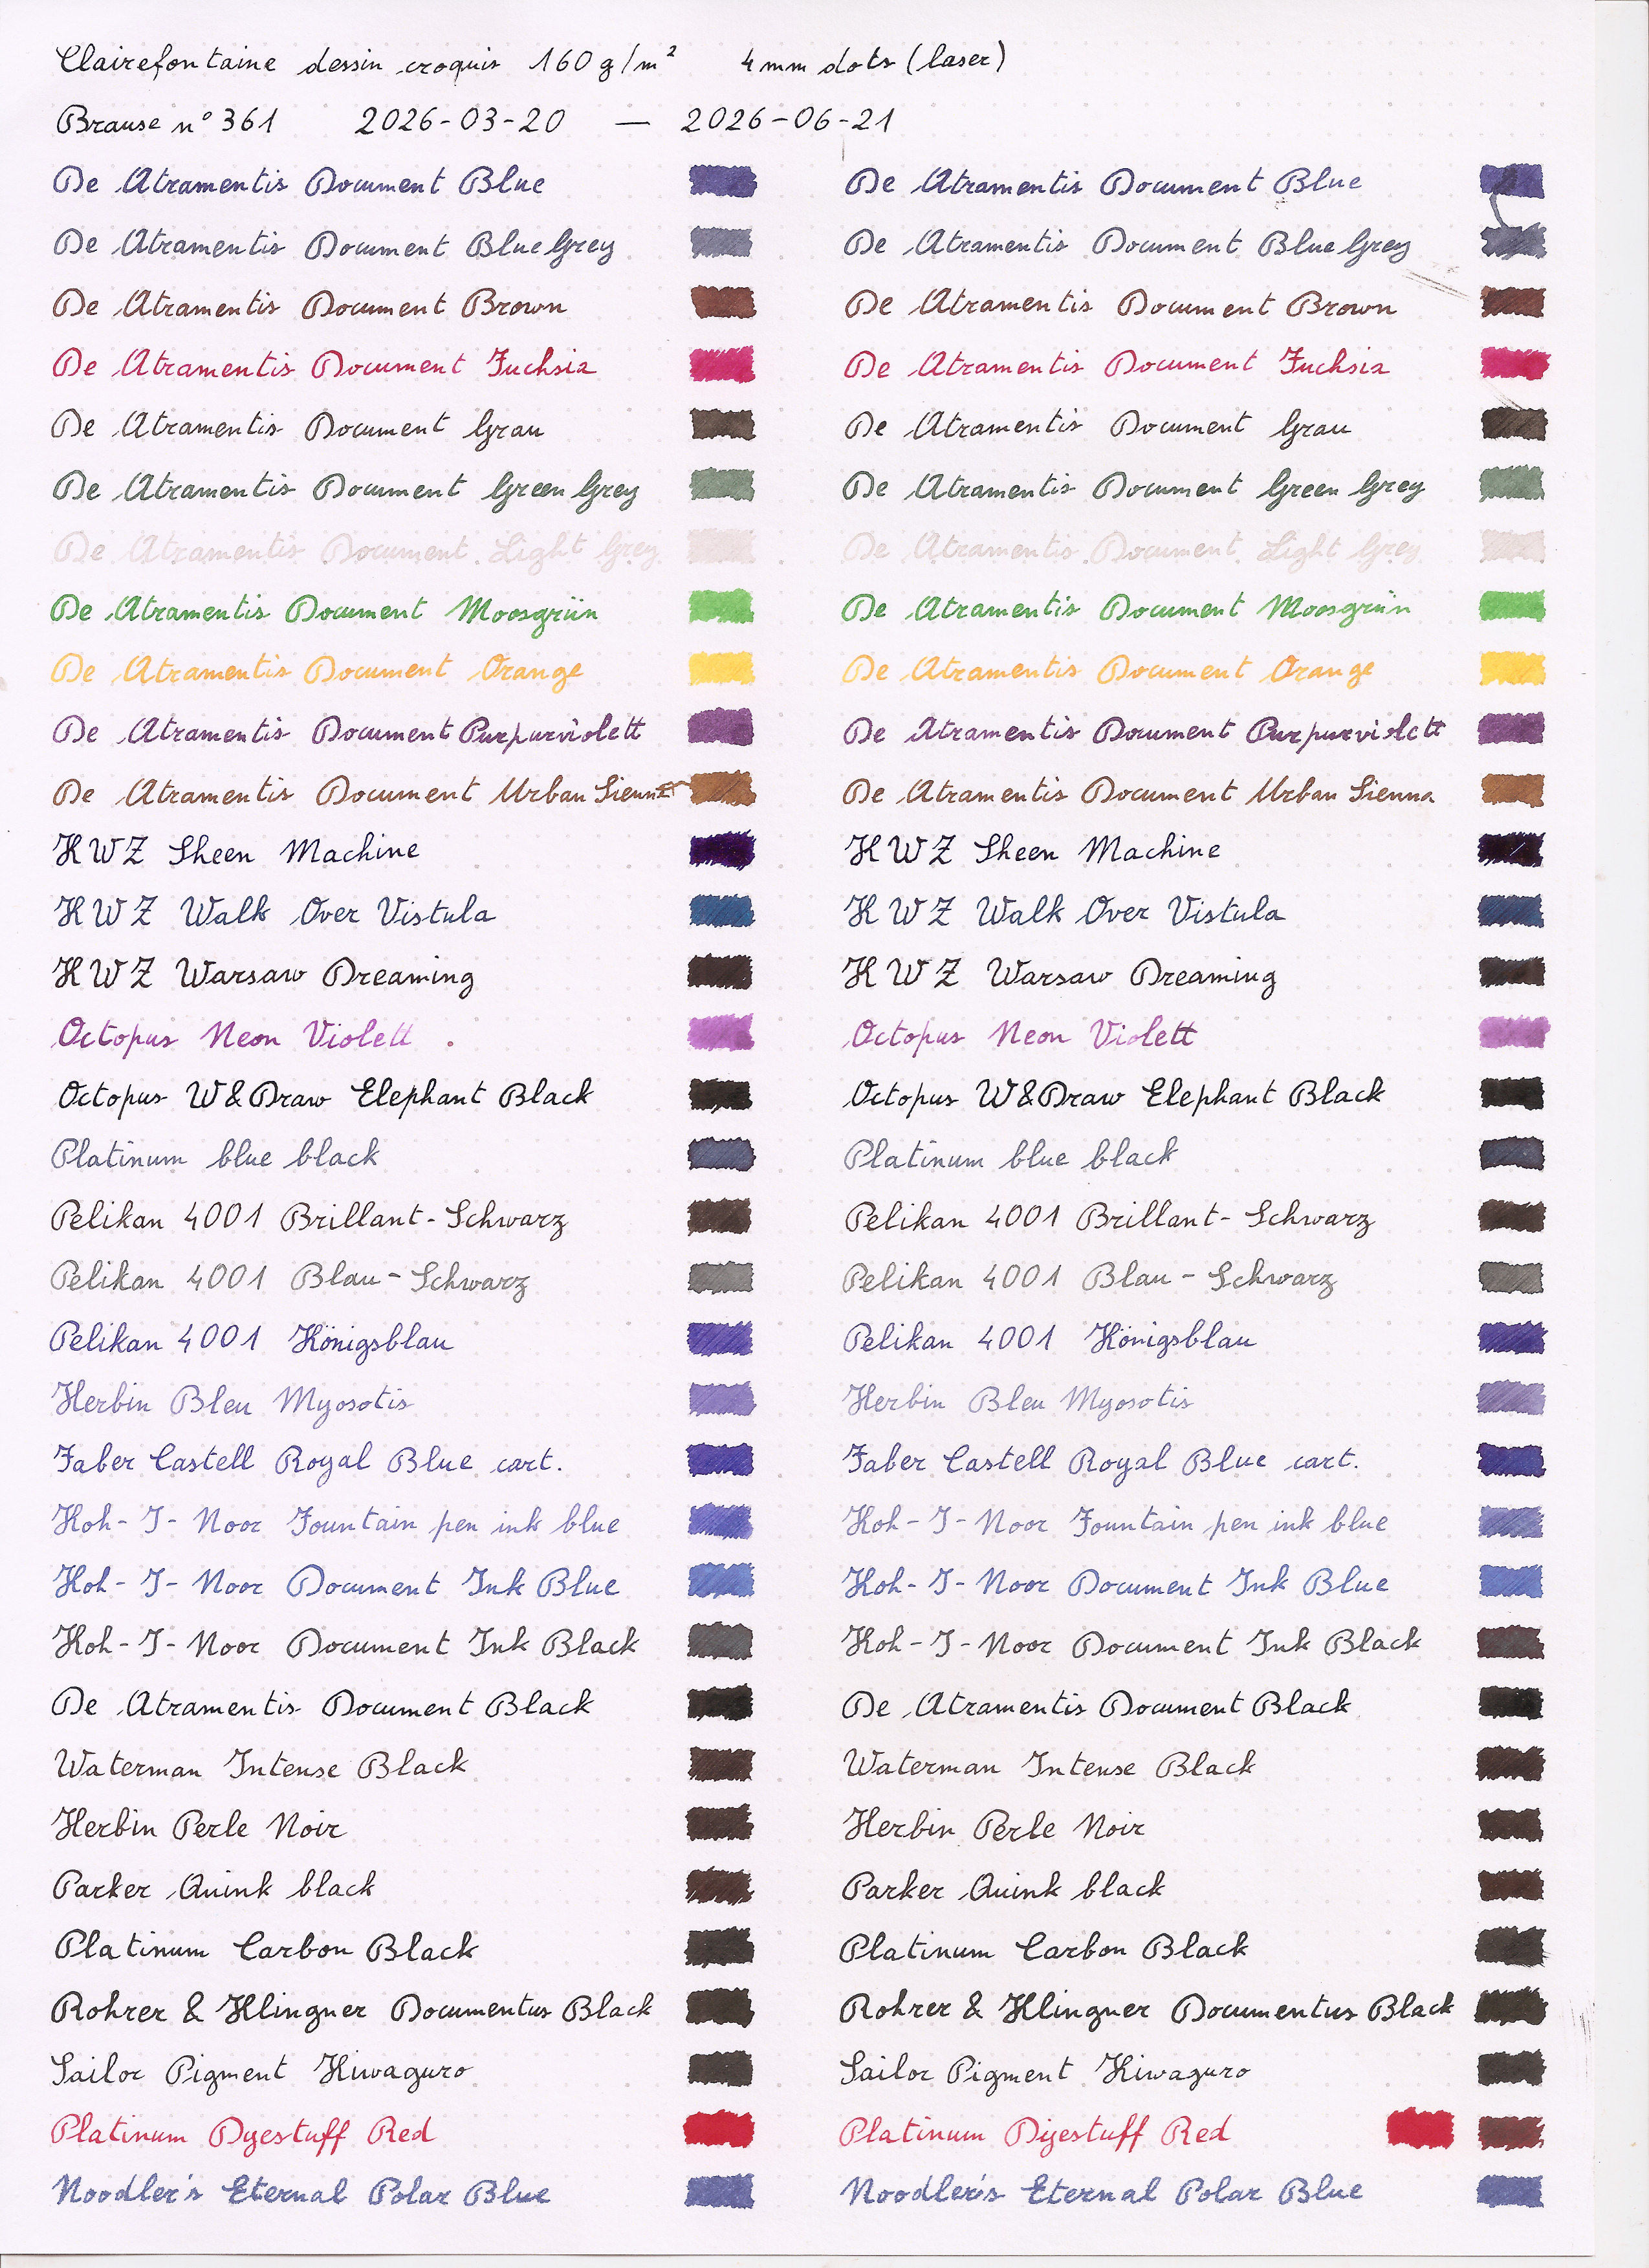 After one full day with plenty of sun, nothing really had changed,
except possibly for a vague hint that the Herbin Bleu Myosotis may have
have been a bit lighter than it started, but it may also have been a
suggestion.
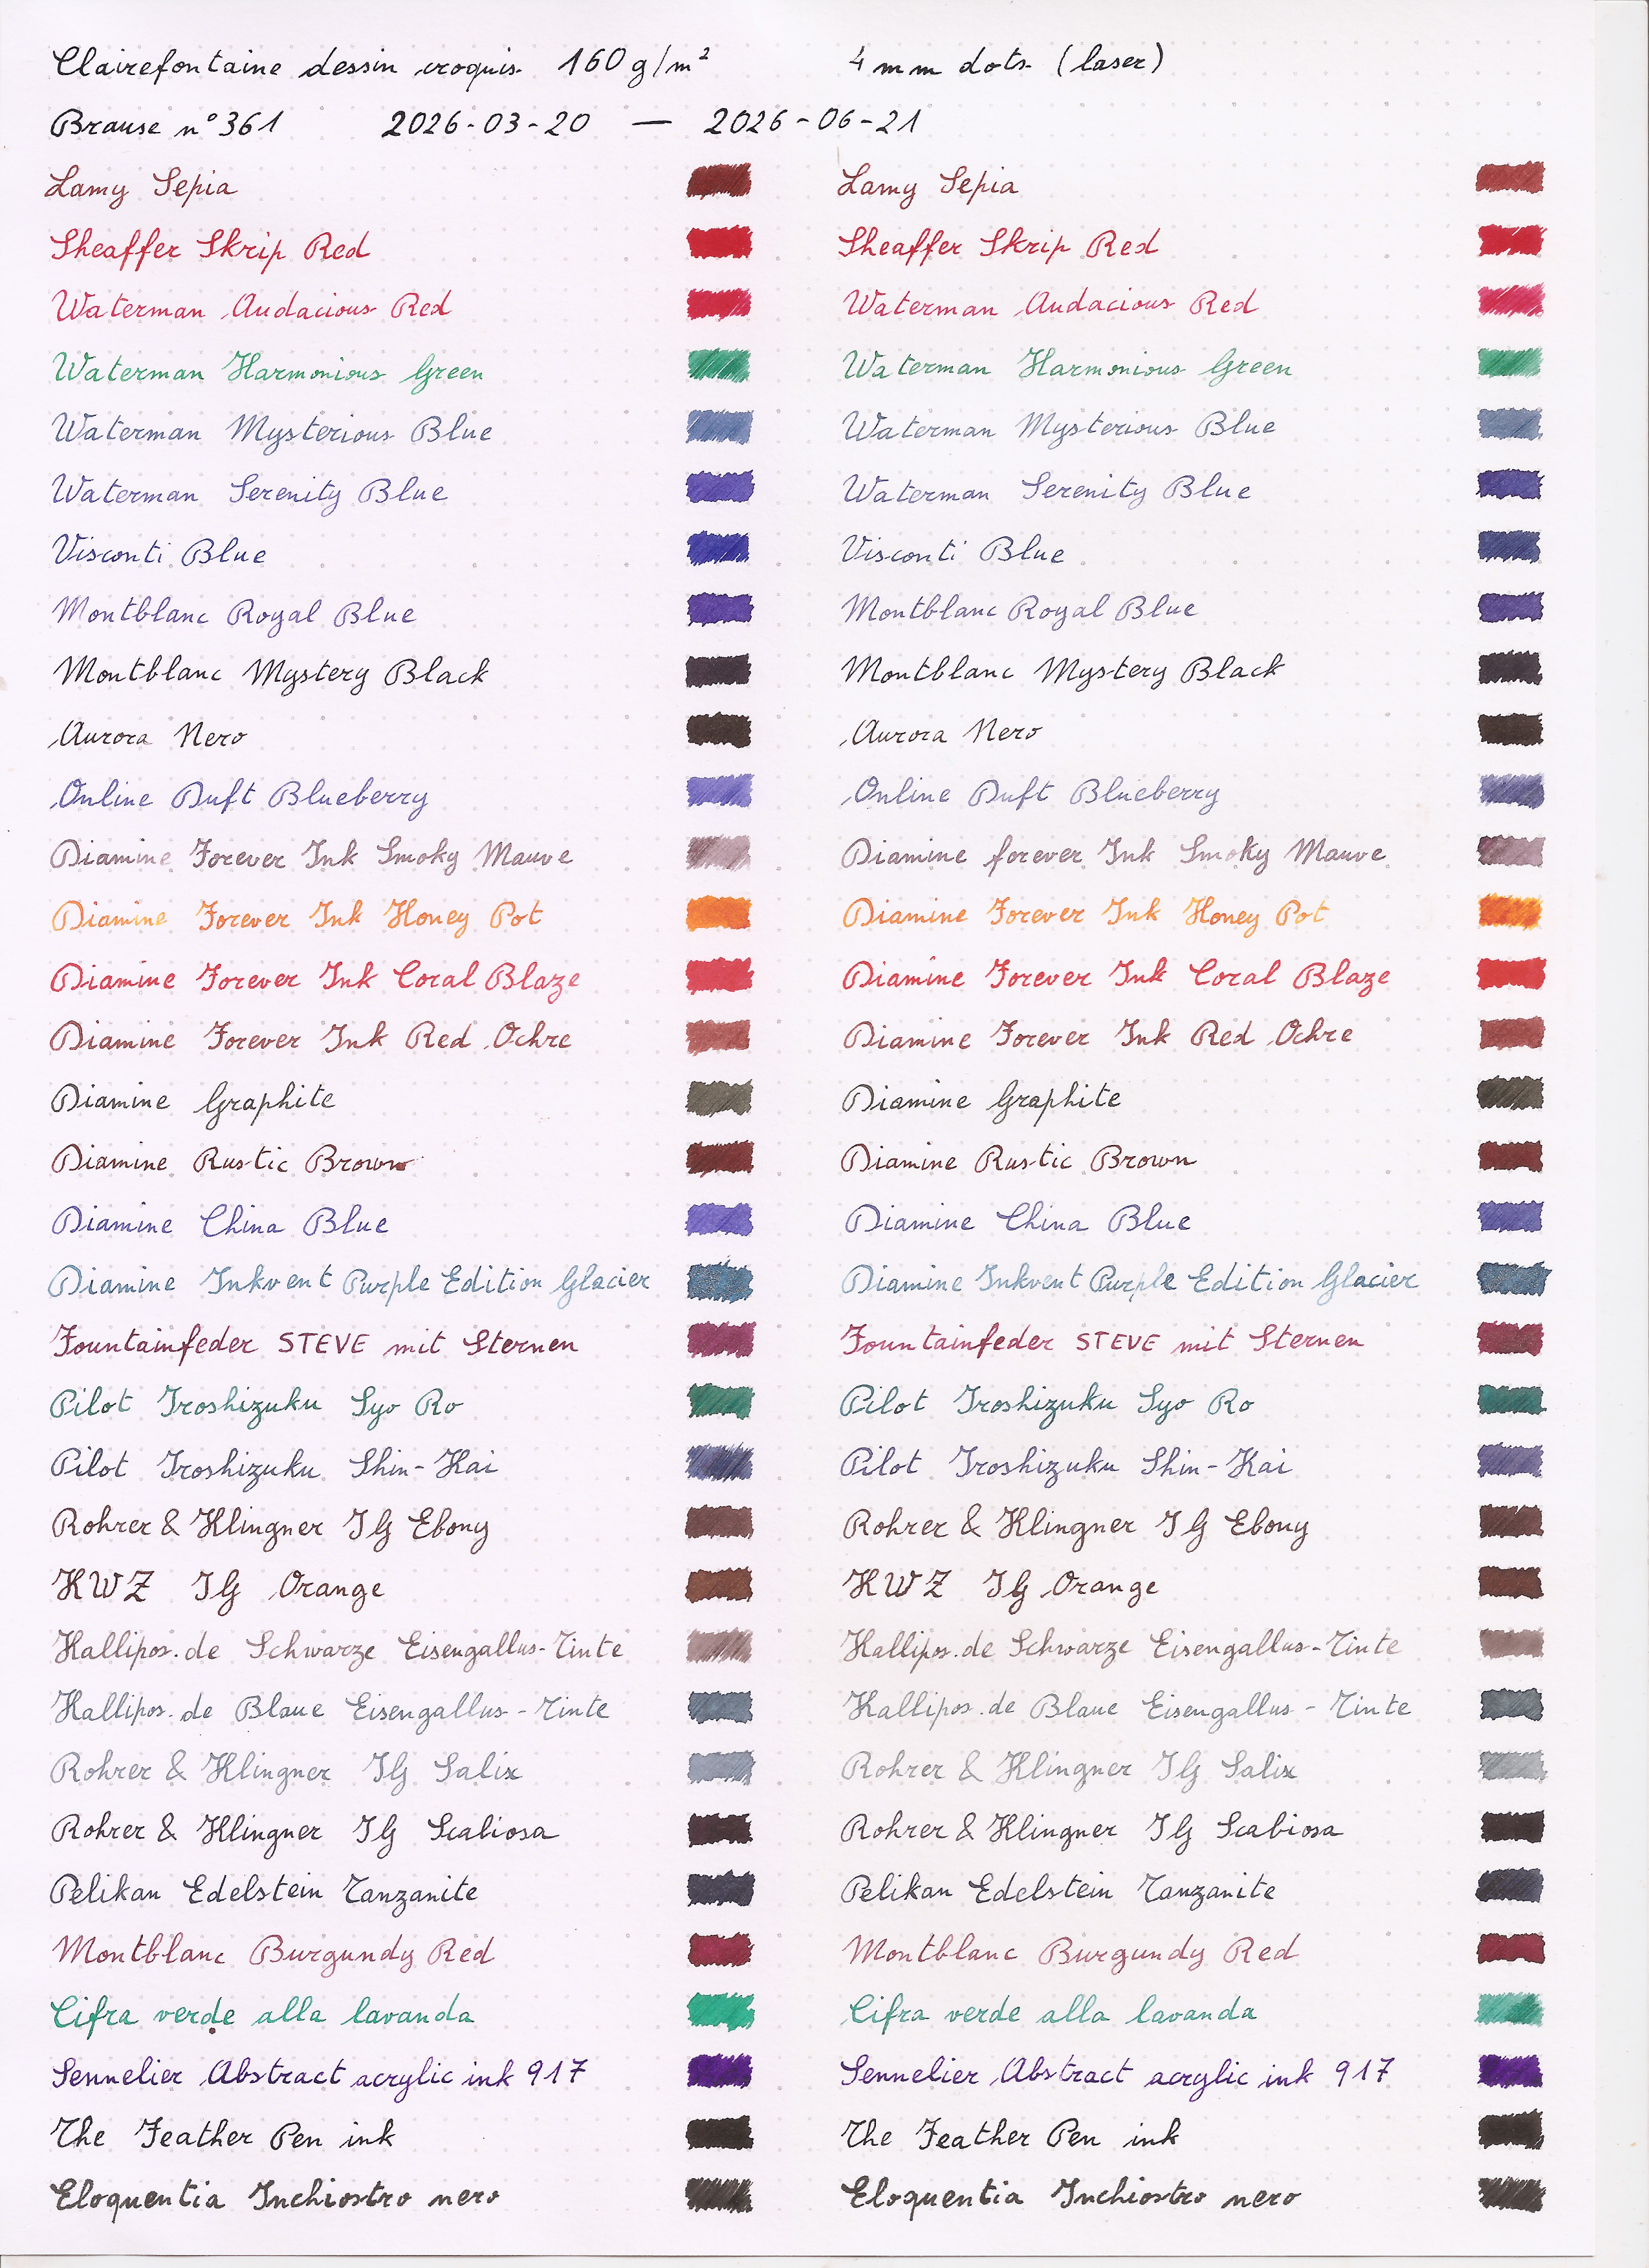
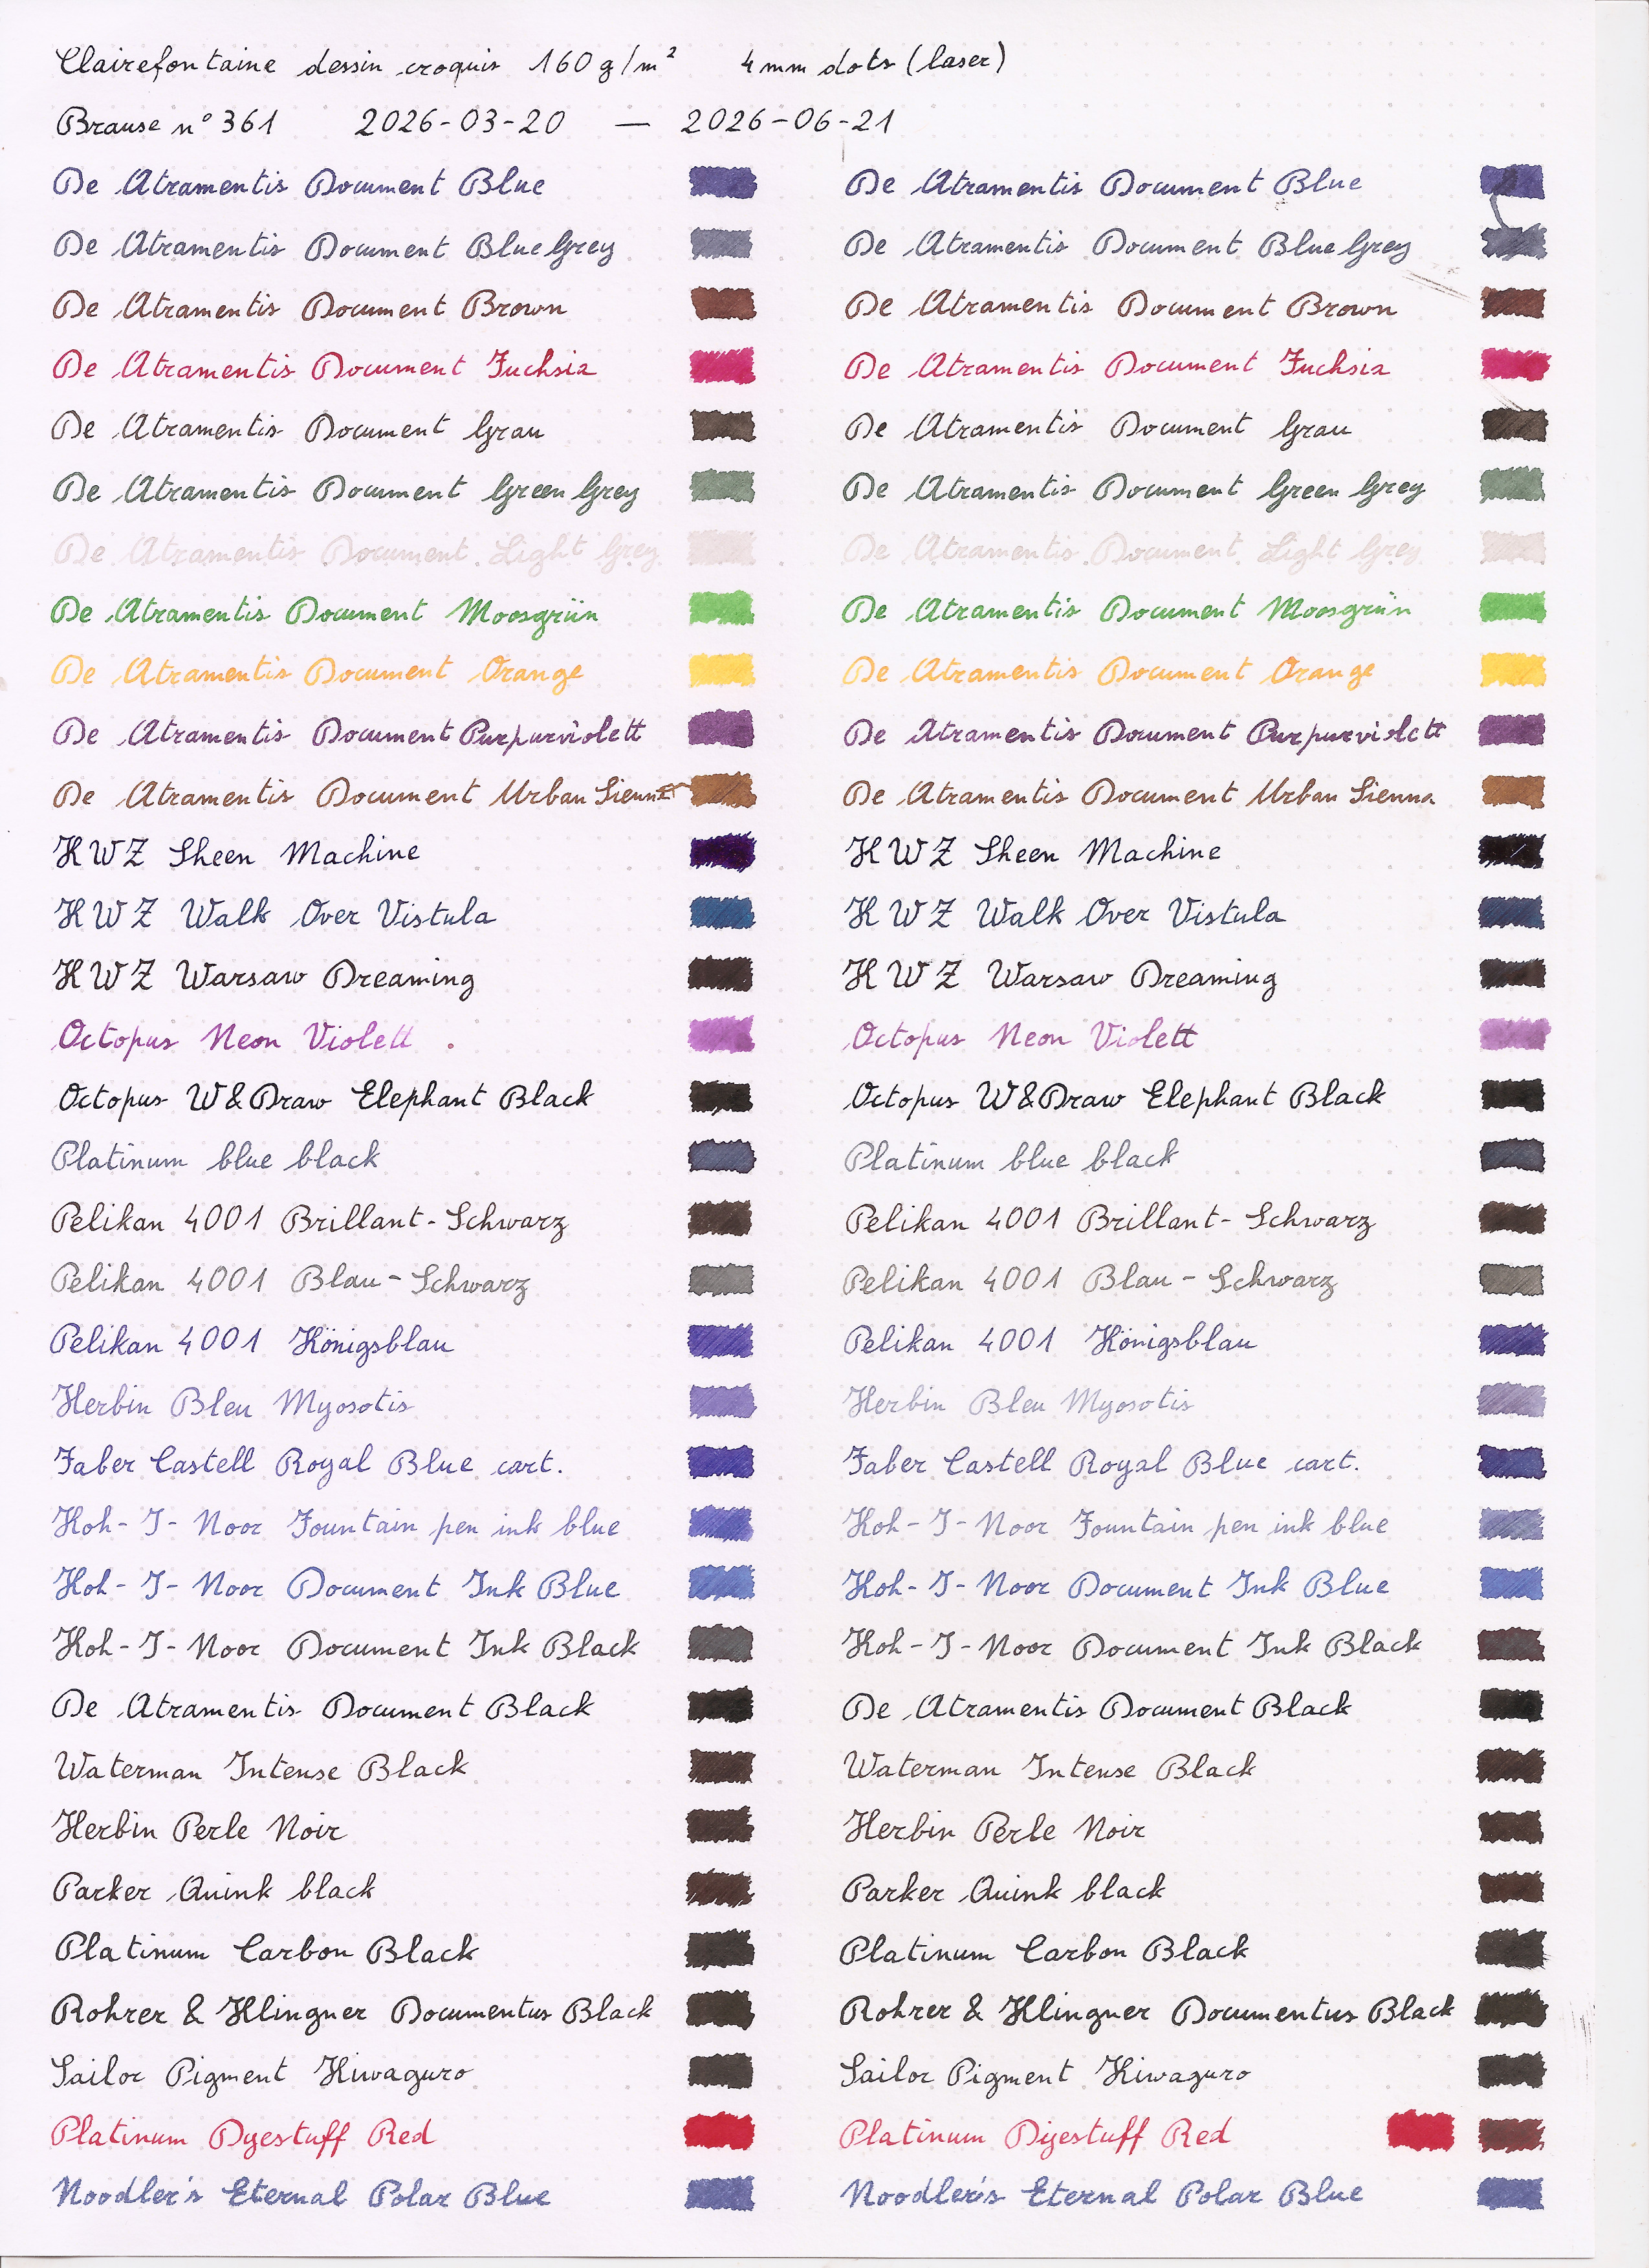 After three days, however, some results started to show, with the most
fugitive inks starting to be visibly changed, becoming either paler or
in some case duller.
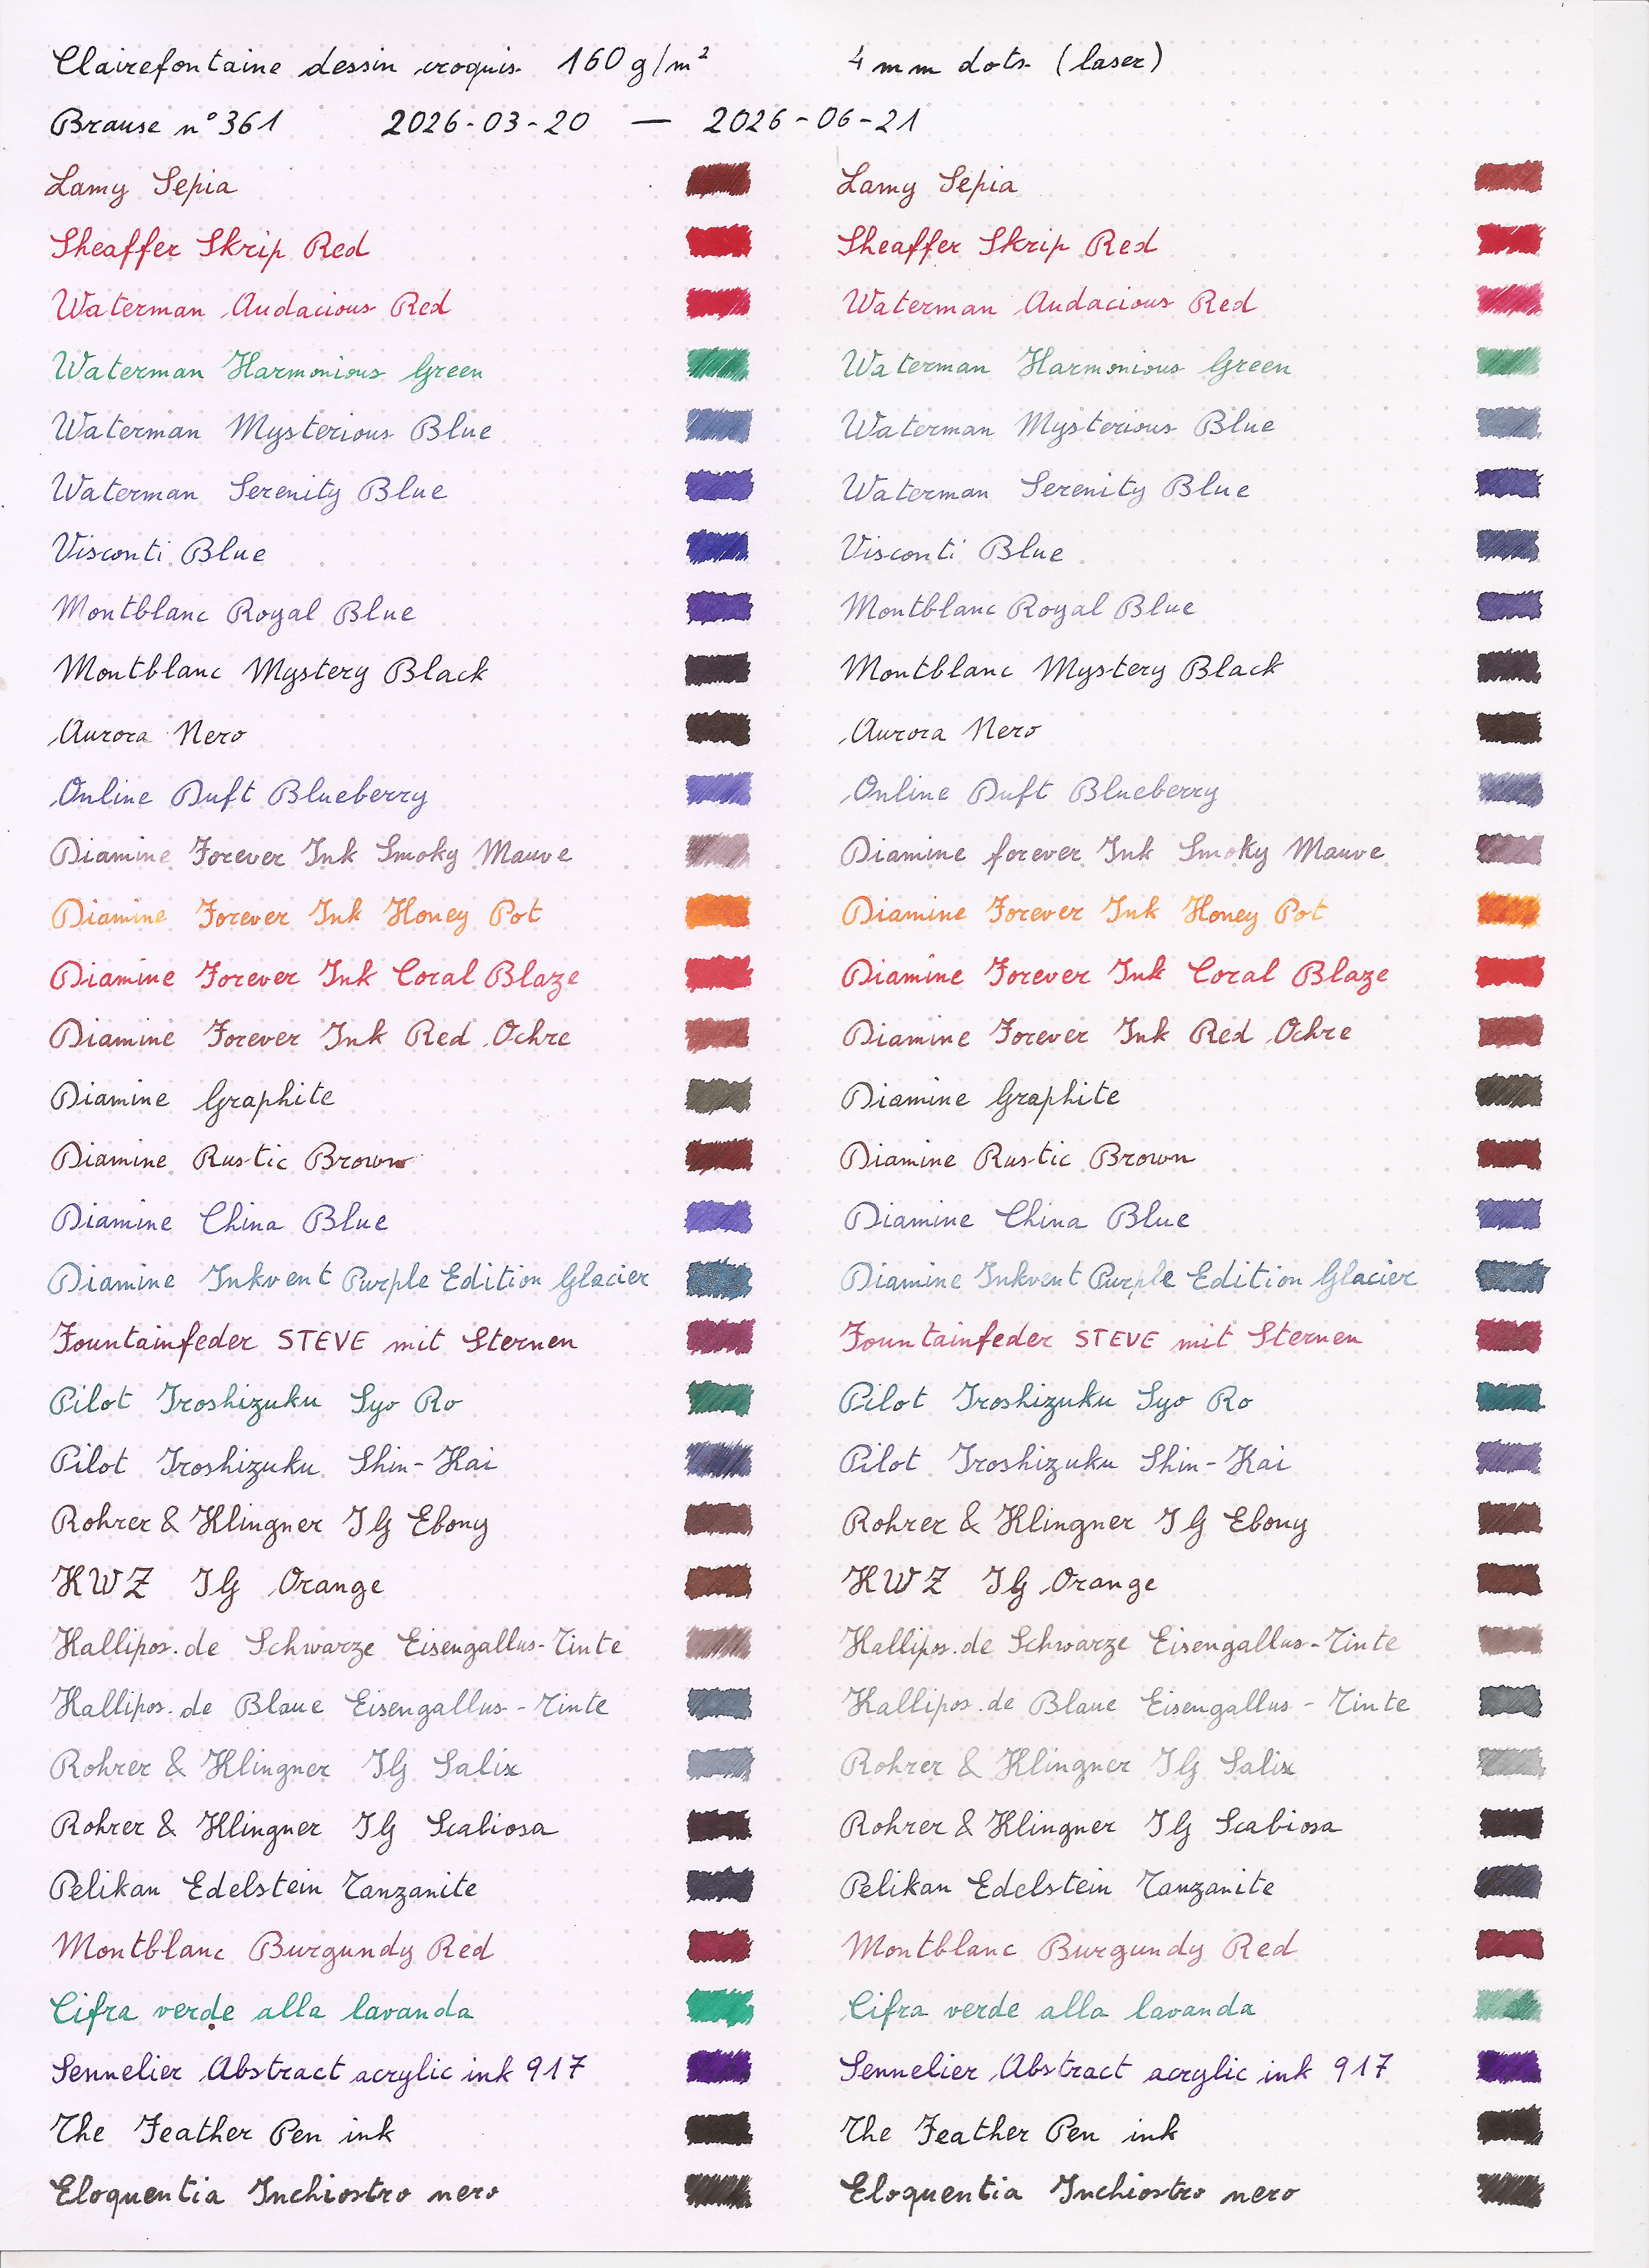
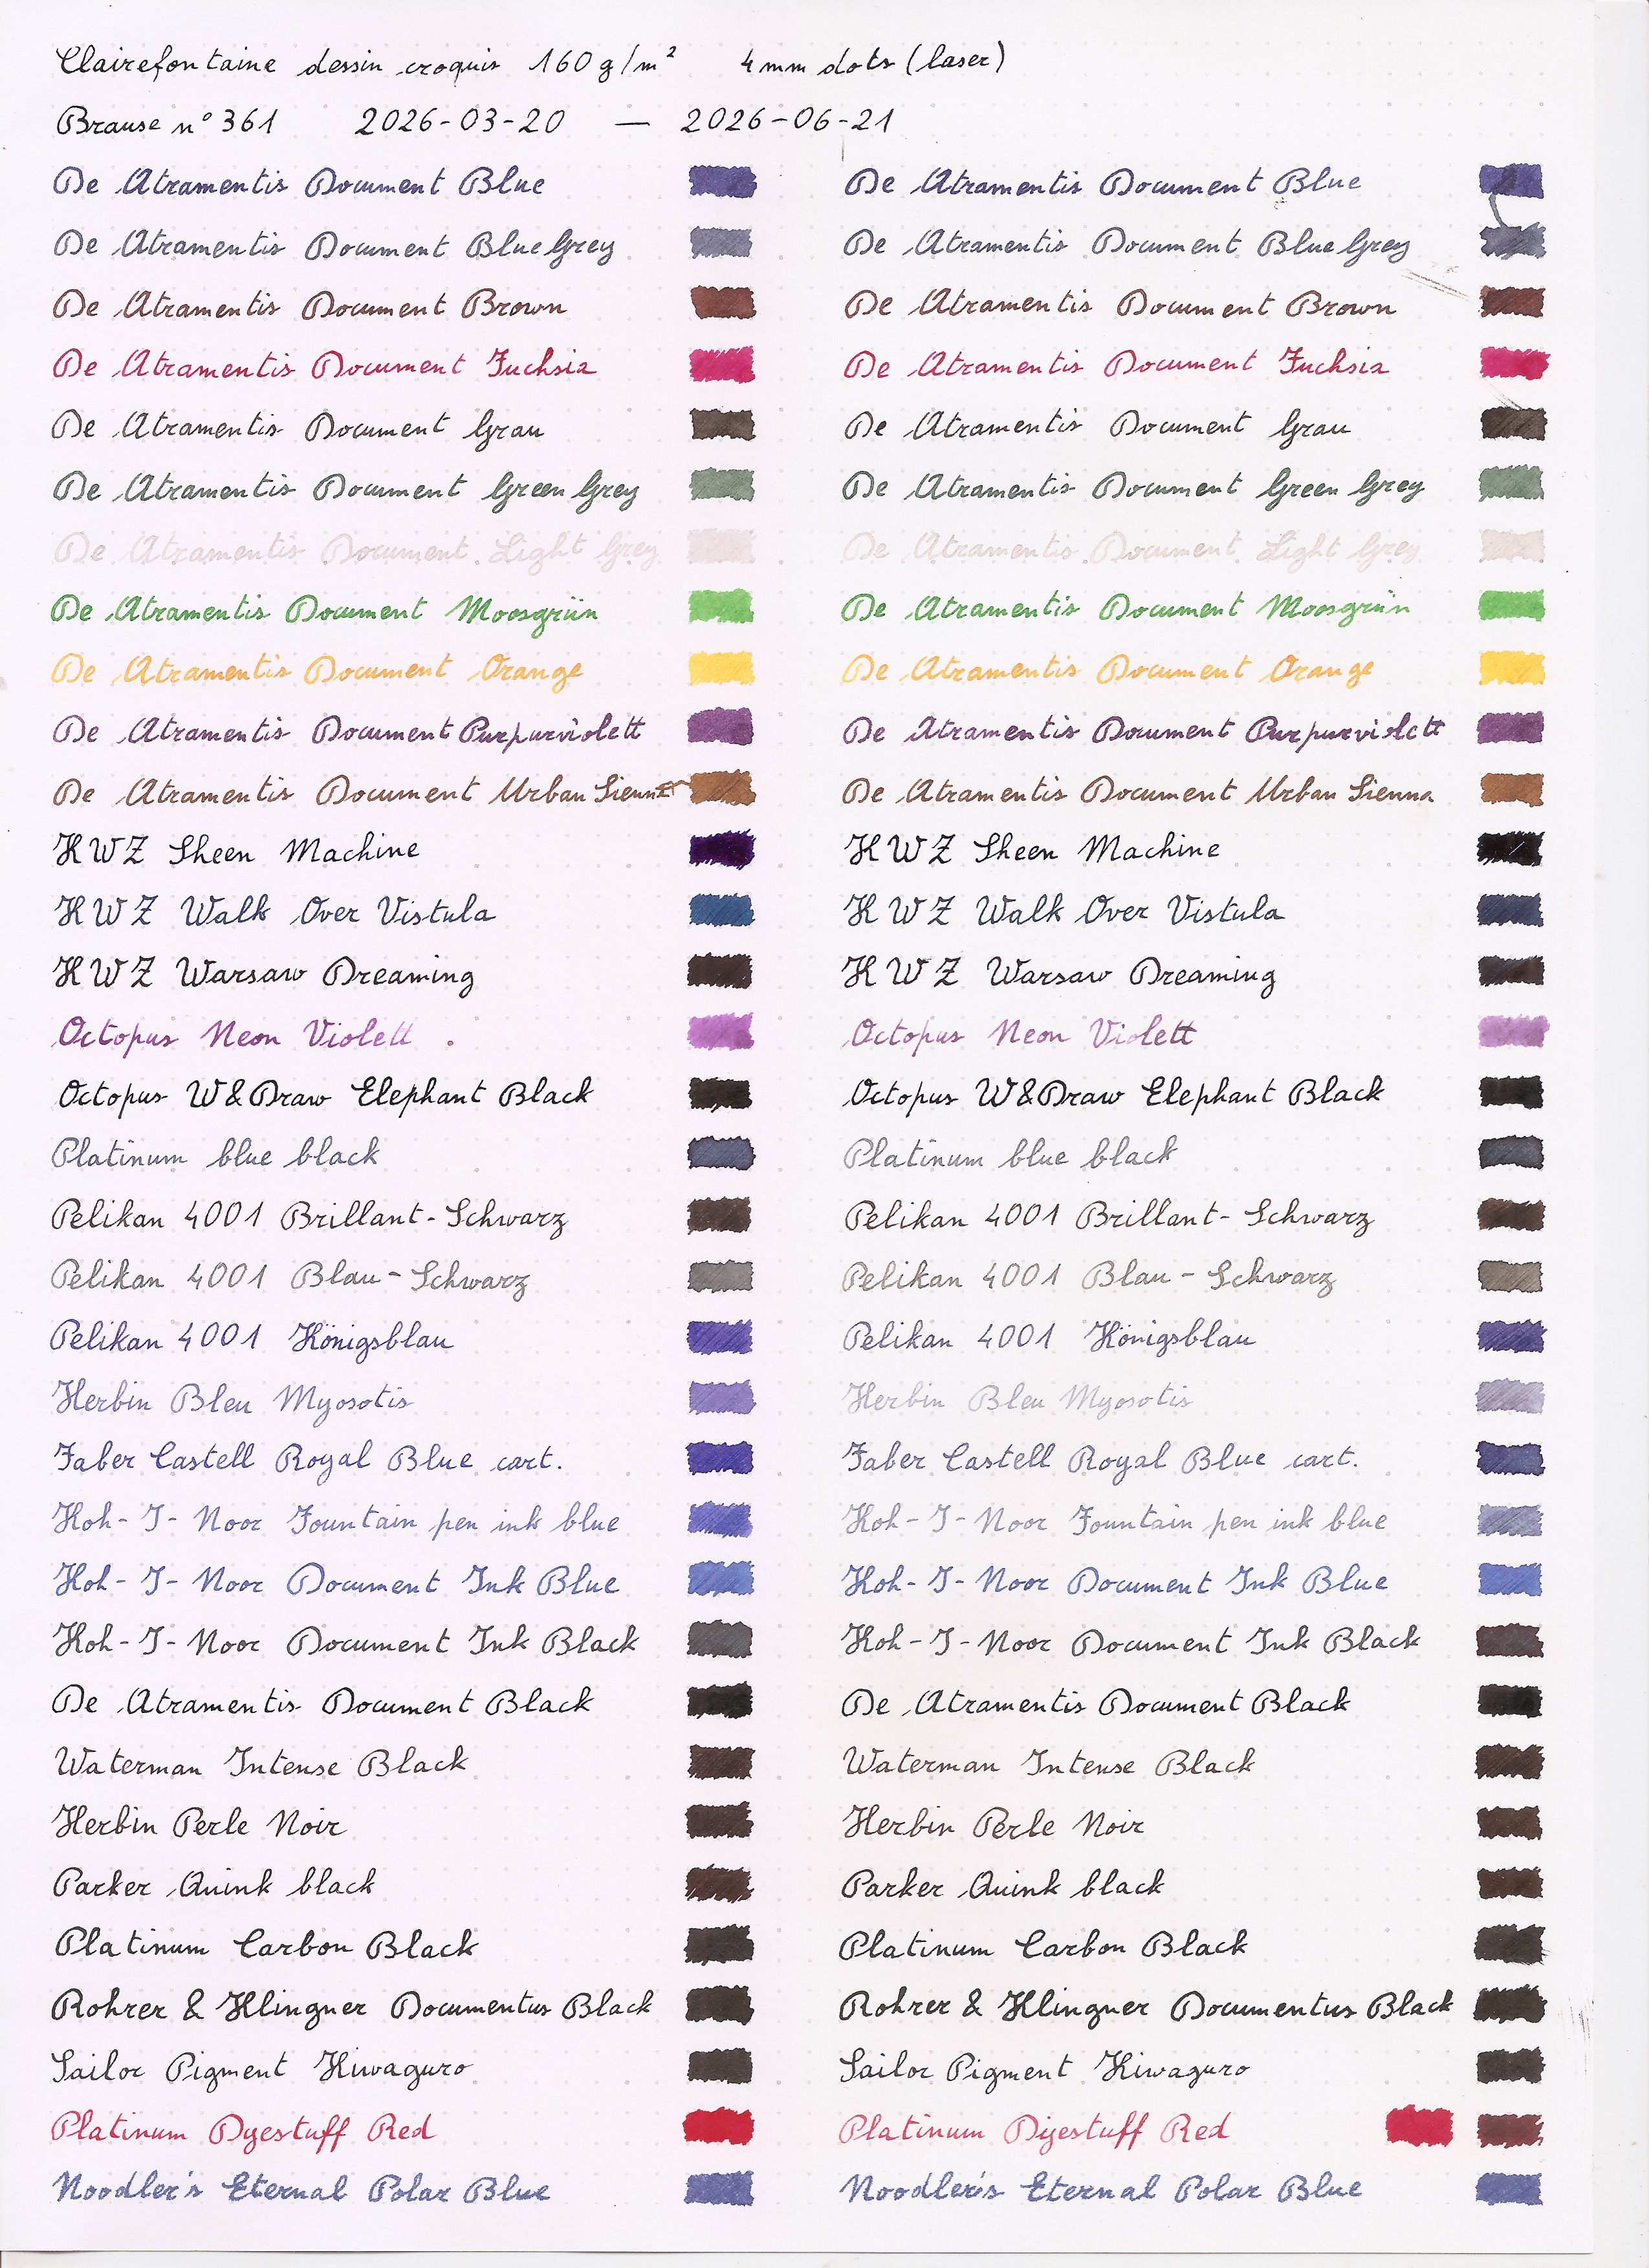 And the full week showed more of that, with a few more inks starting to
show visible change.

 After two weeks the paper had significantly yellowed, something I did
not expect from drawing paper (and which means that I will probably use
a different paper when making similar tests in the future).
As for the inks, there were a couple more inks with visible changes, but
mostly it was more of the same as seen in the previous week.
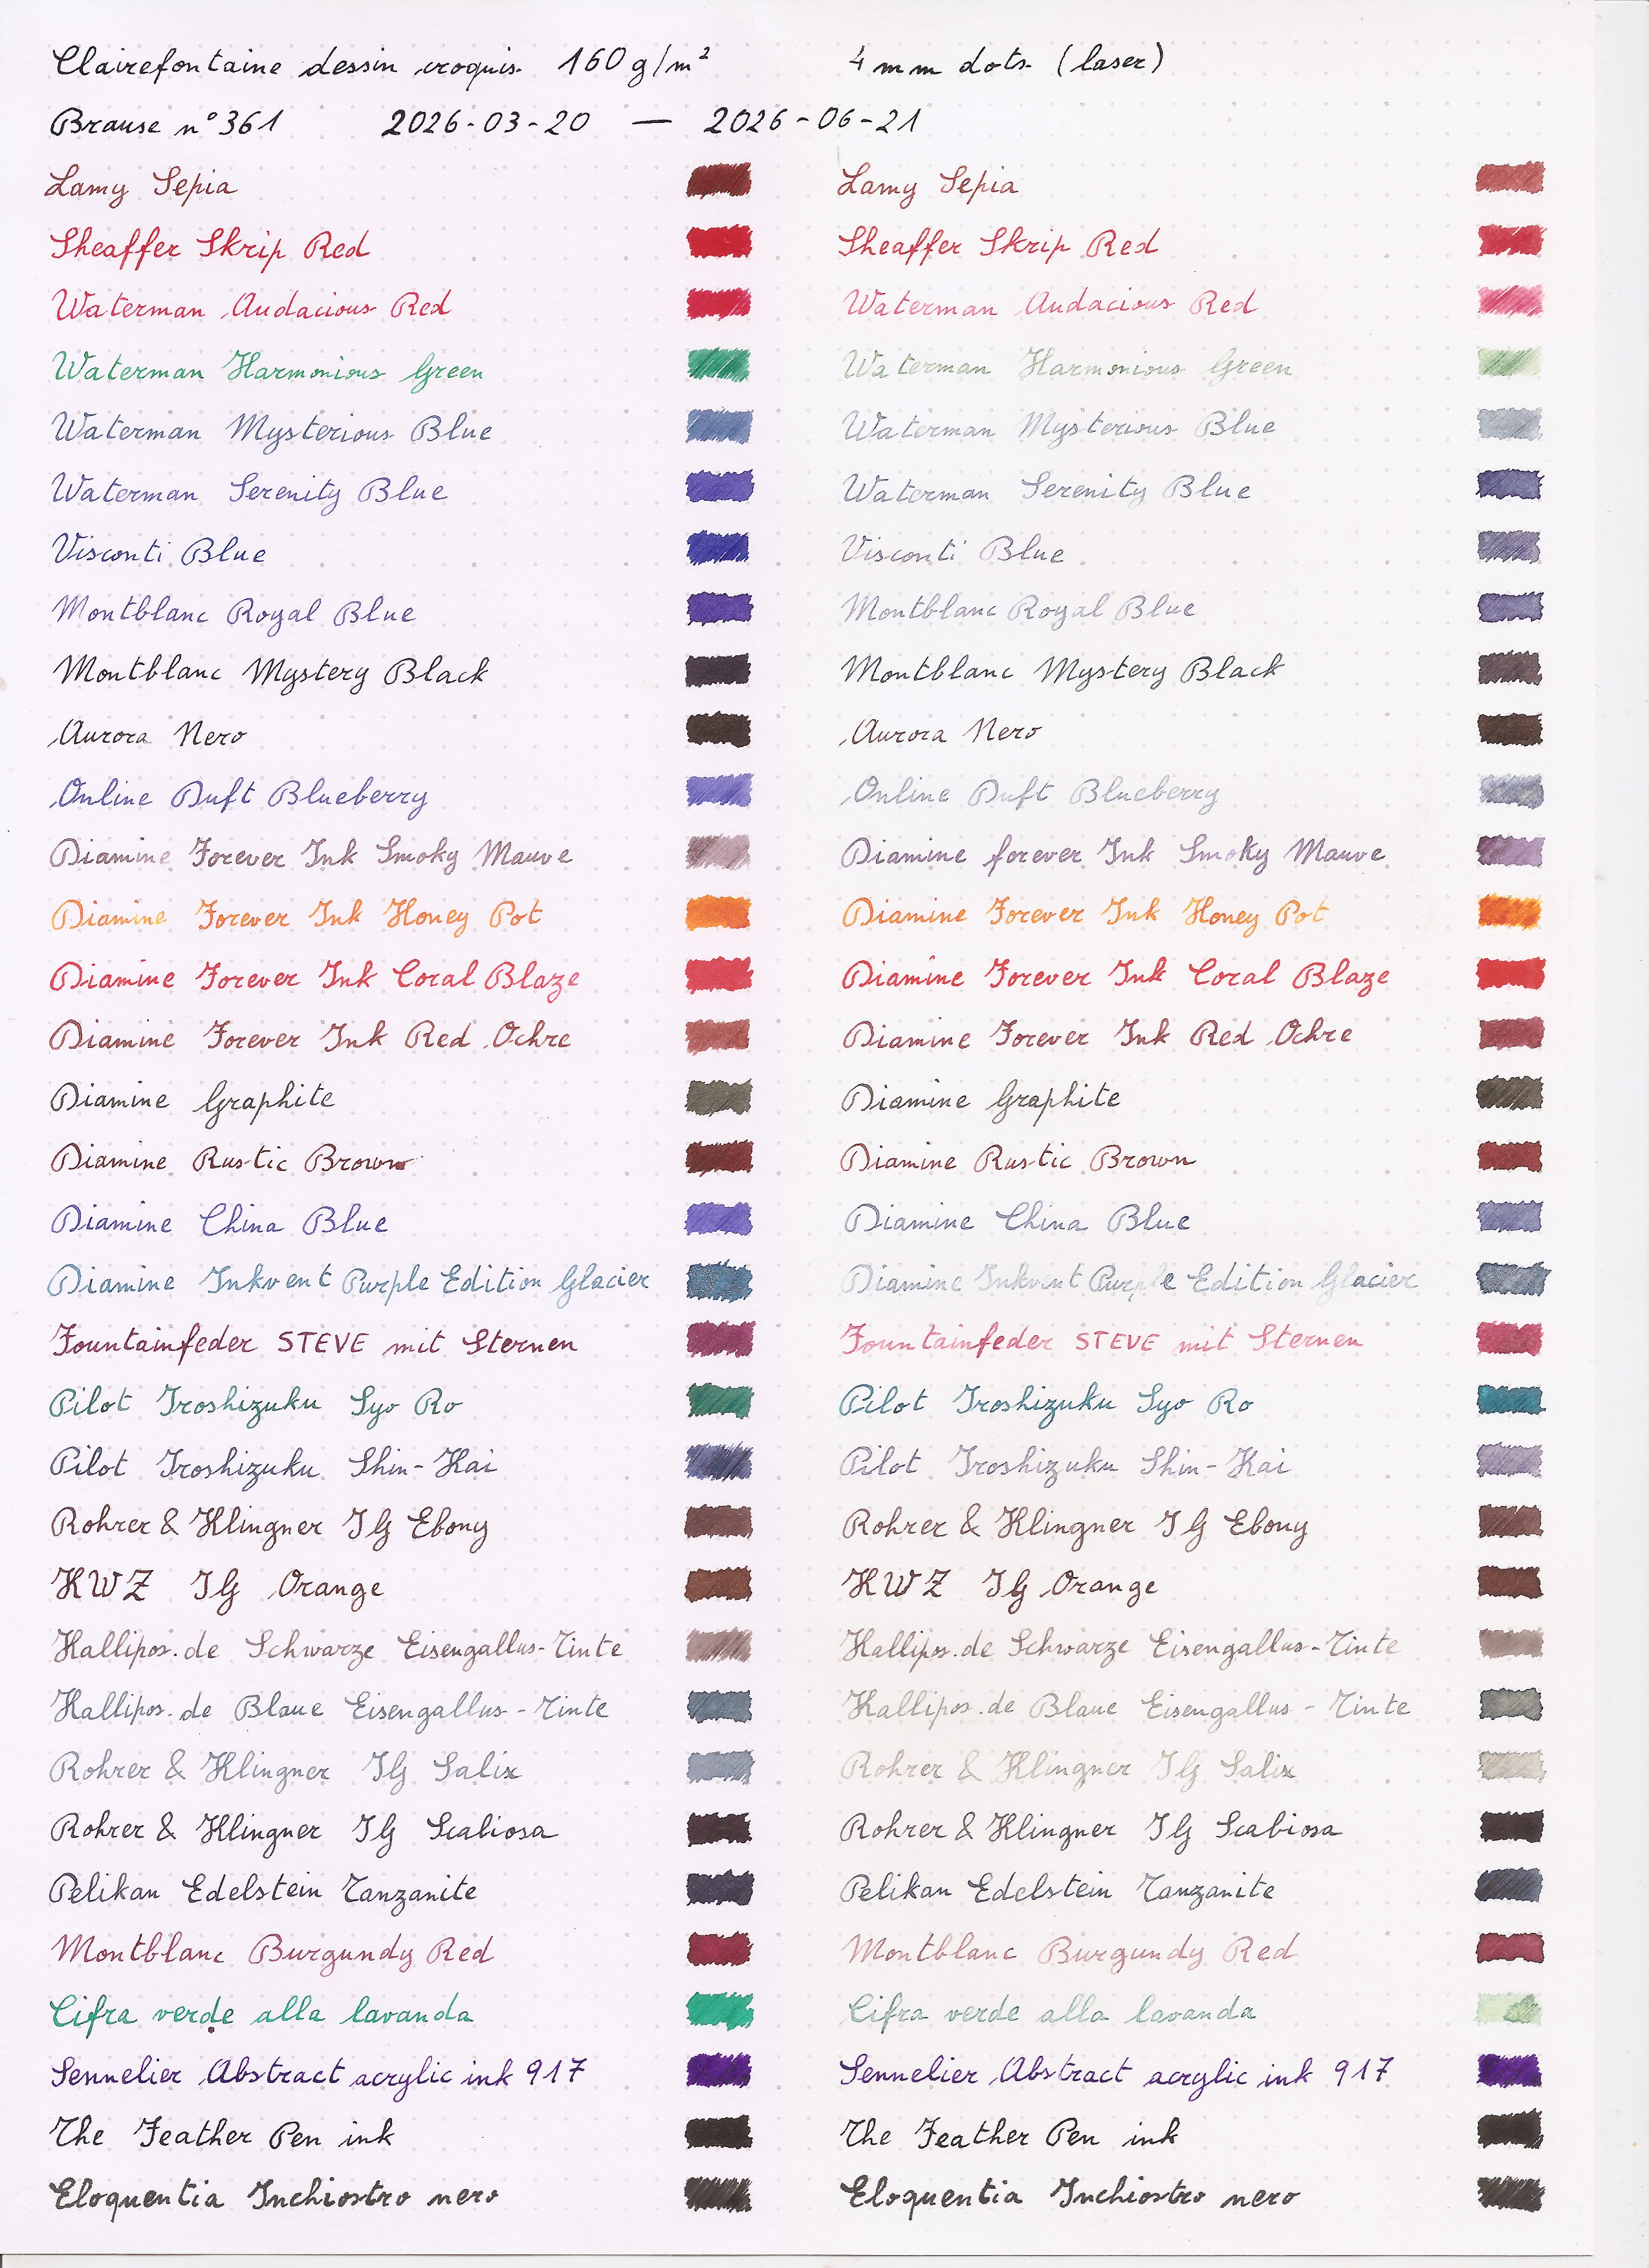
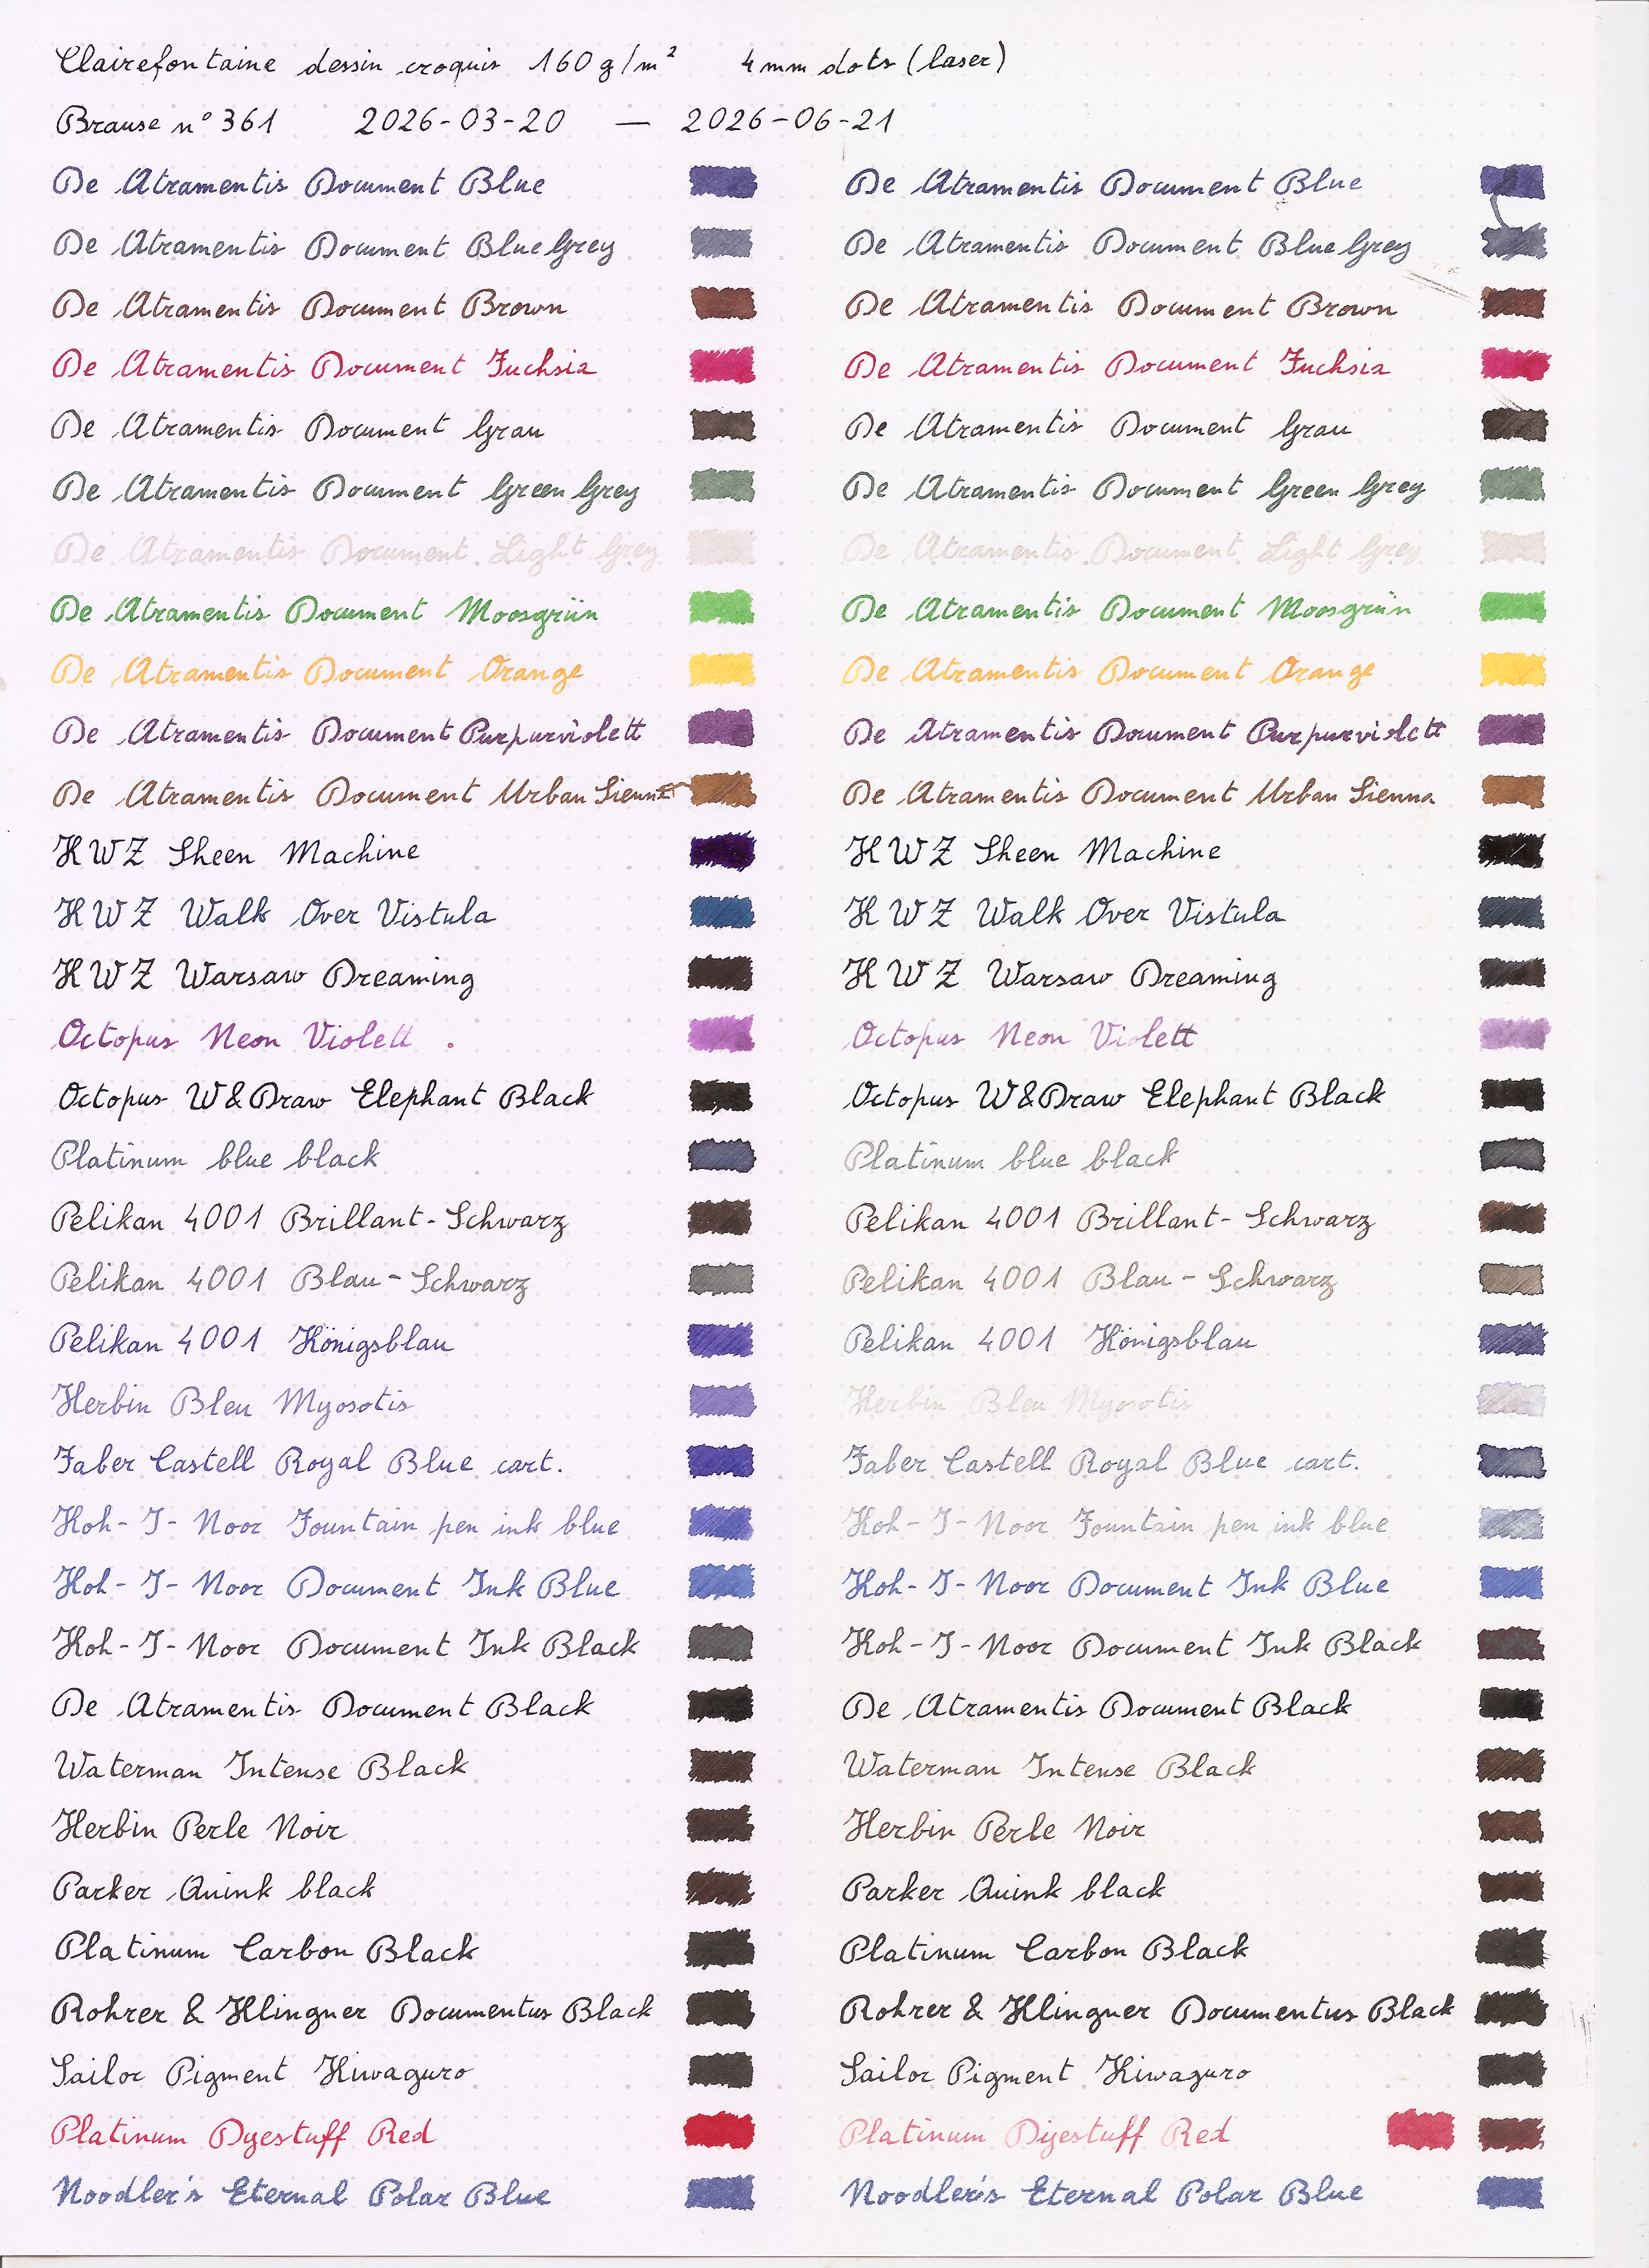 Three weeks started to show changes in the black and most irongall inks, and of course more changes in the even less resistant inks.
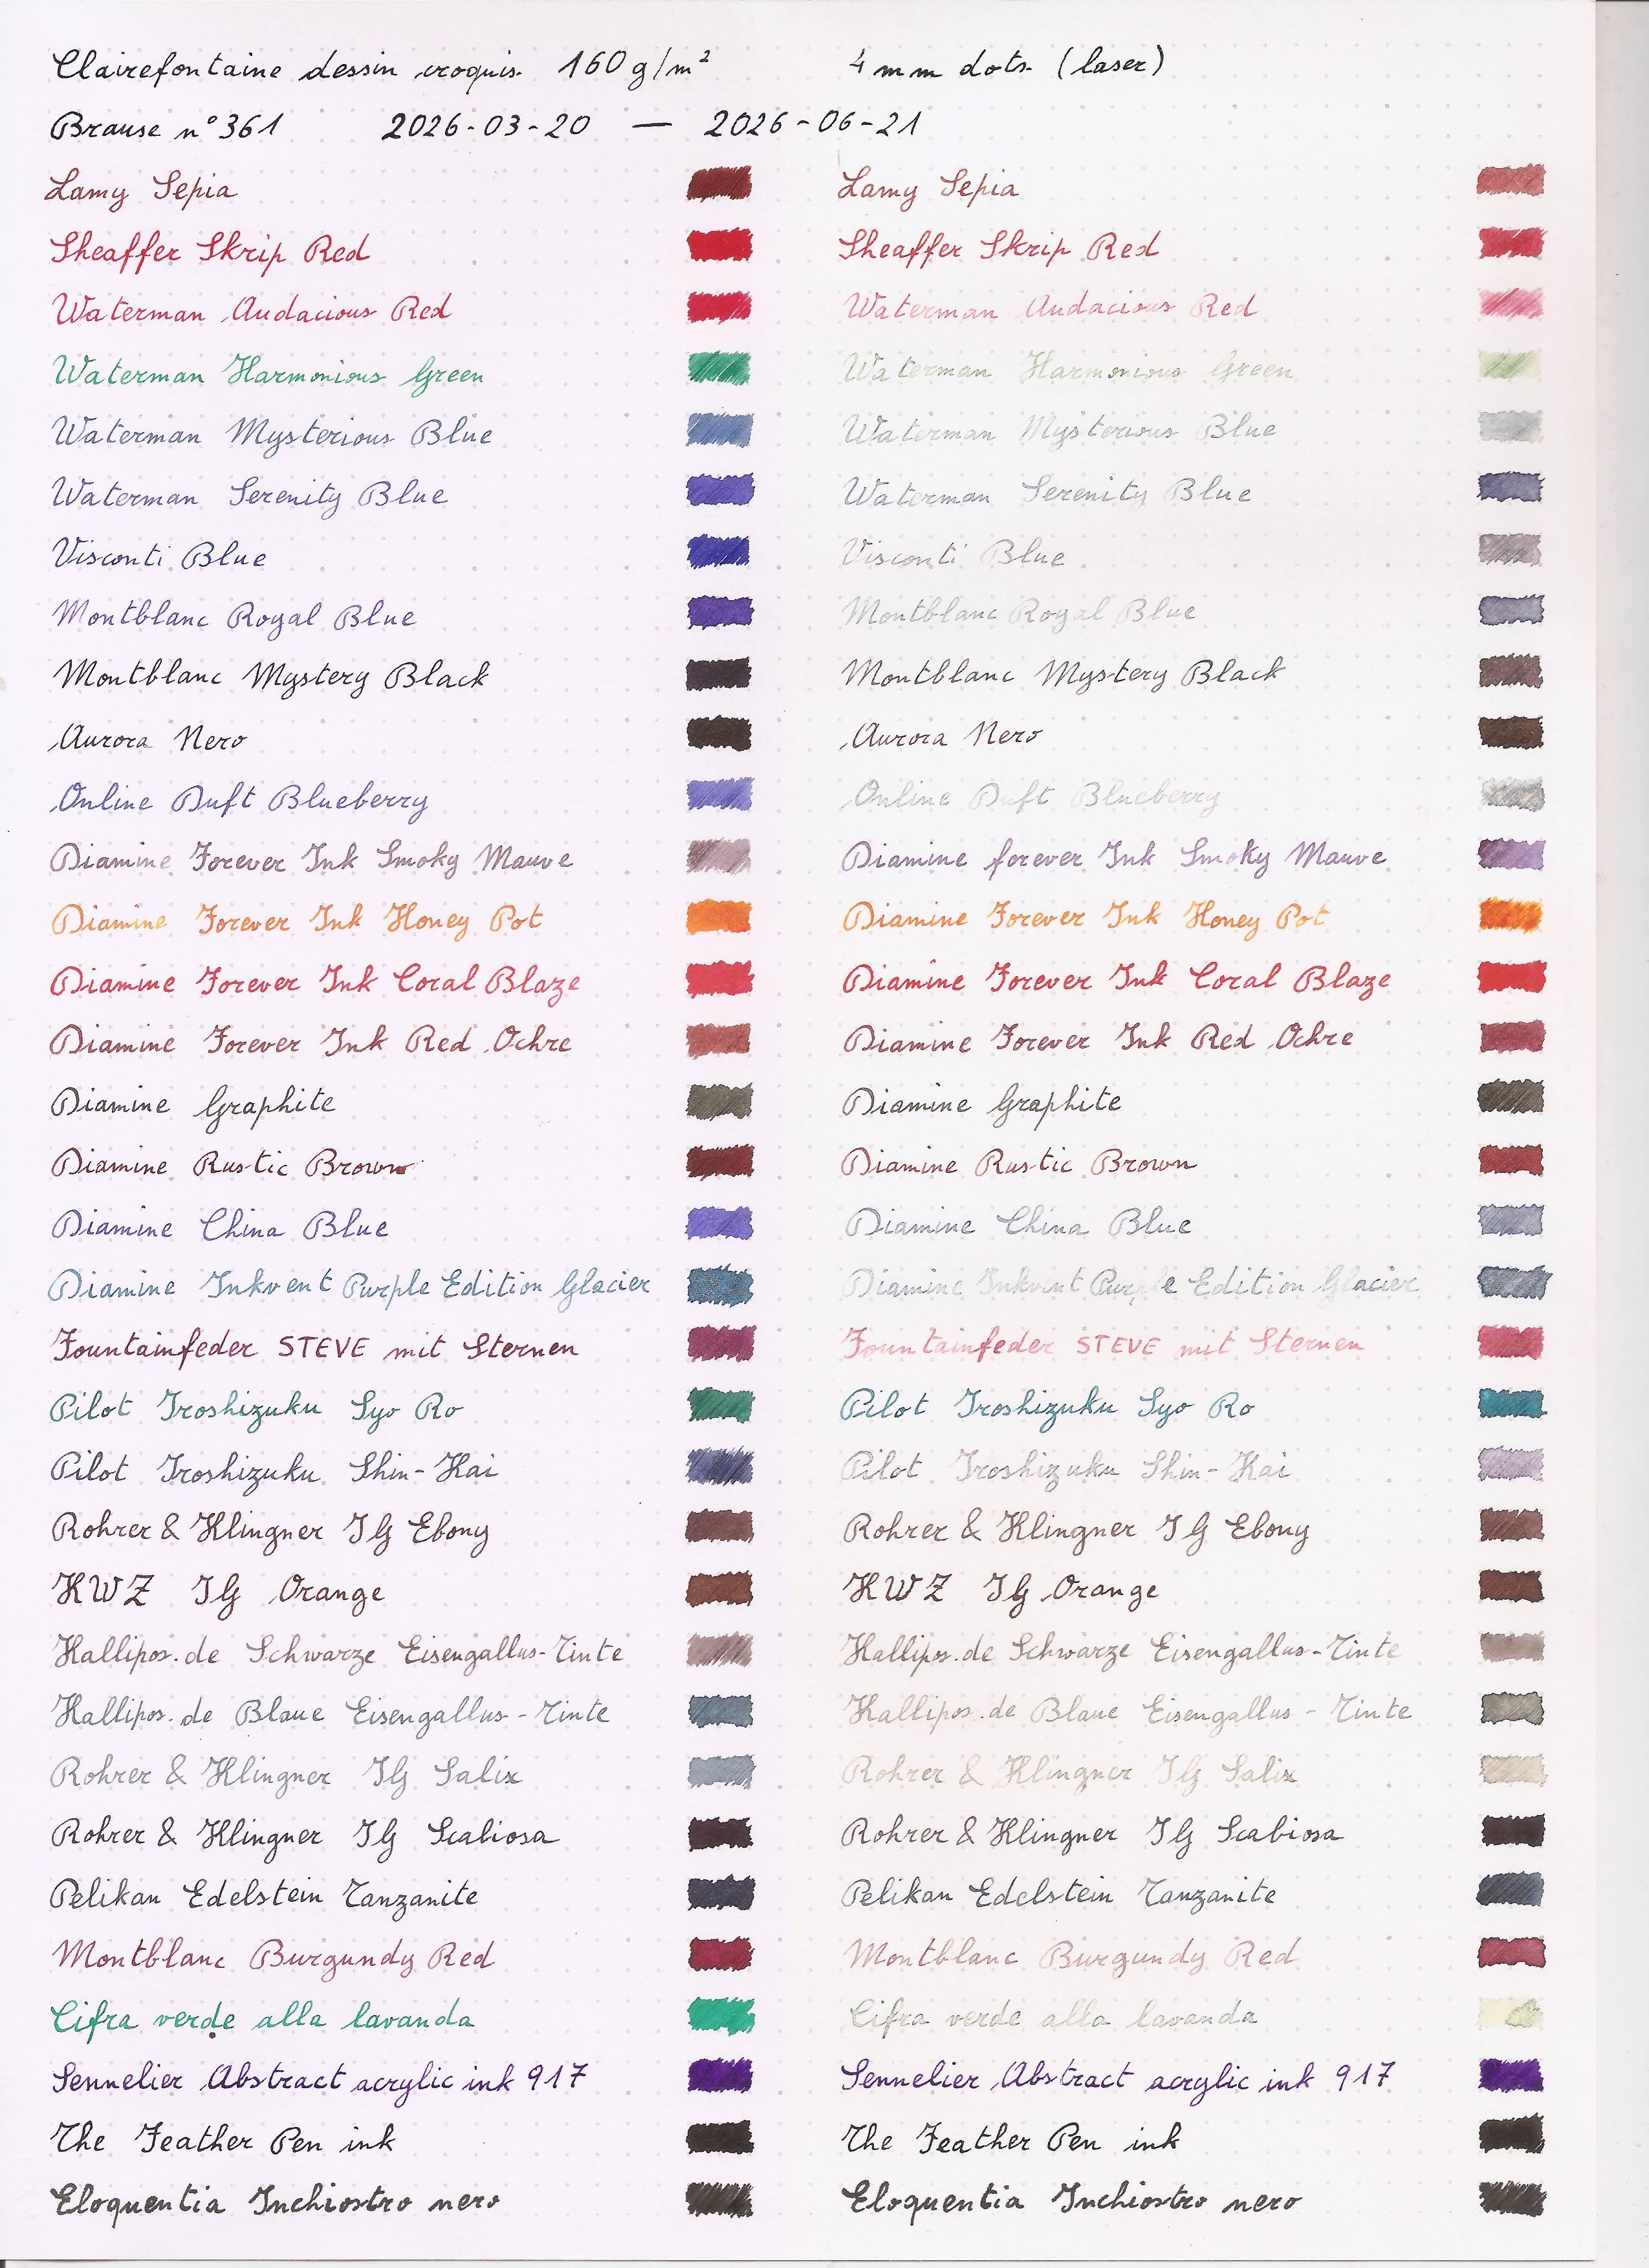
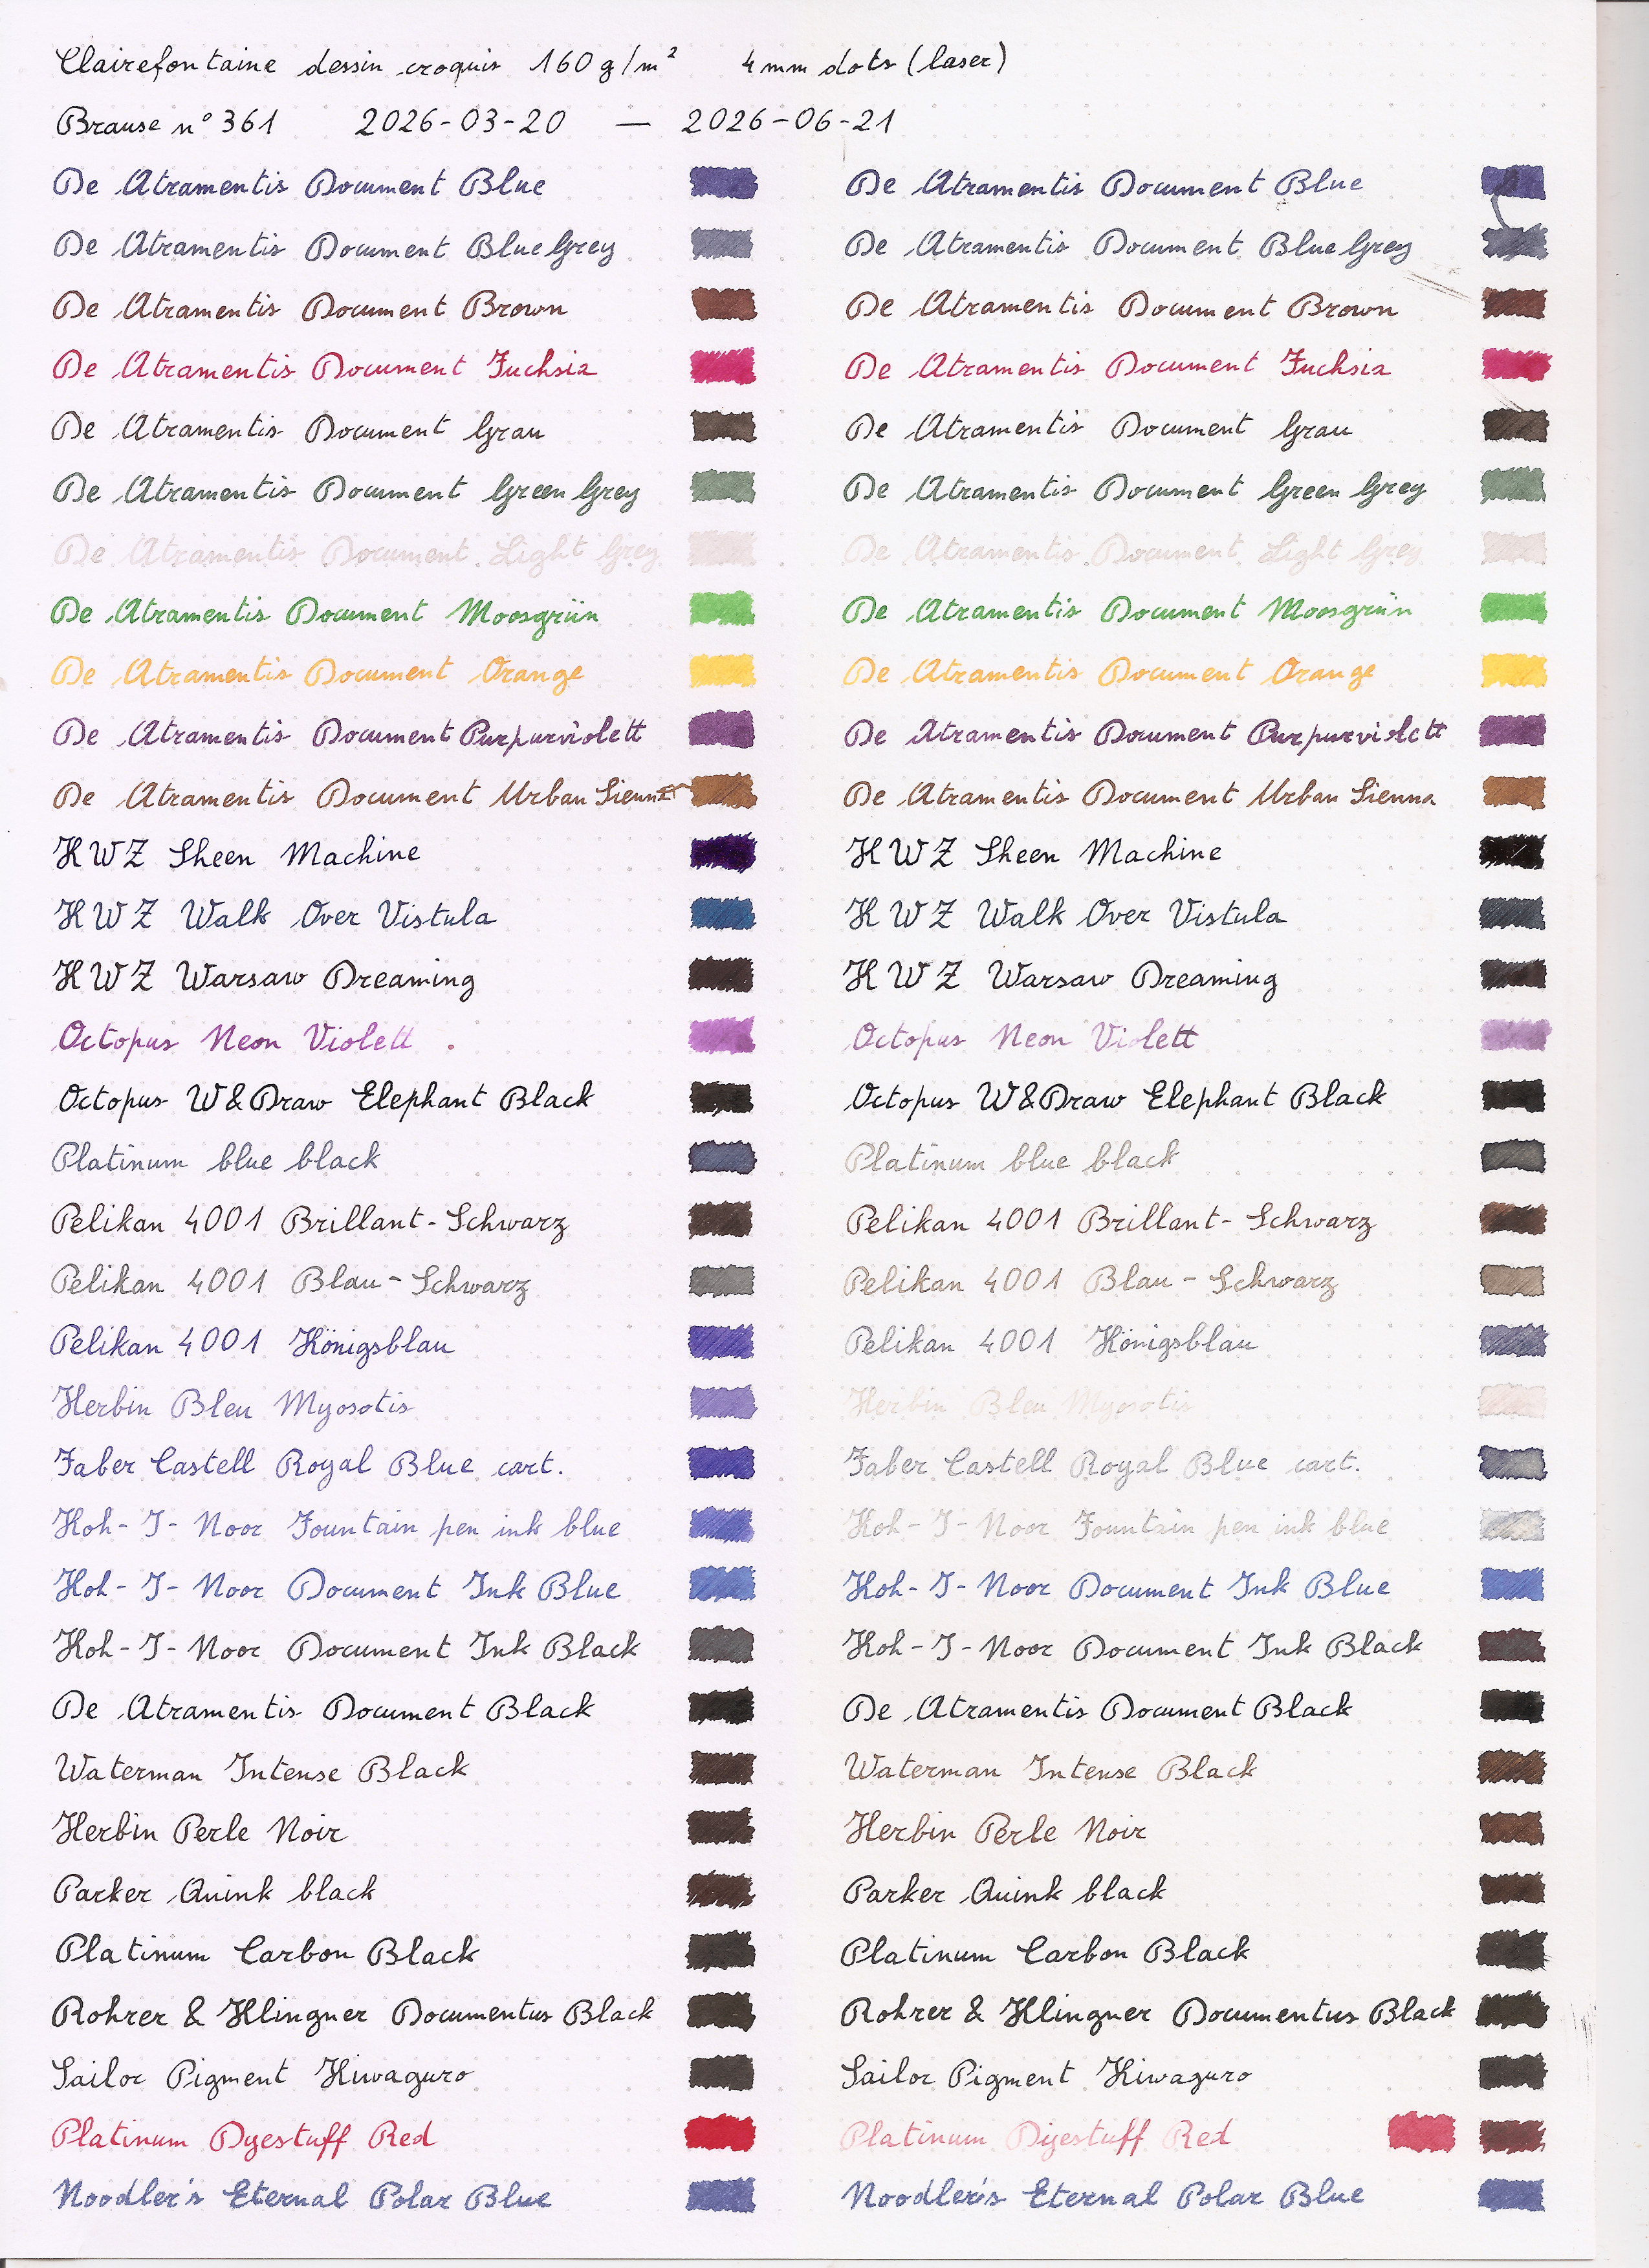 Week four saw a bit more clouds and rain than the first few weeks, and
there weren t big changes, but mostly more of what had already started
to happen earlier.
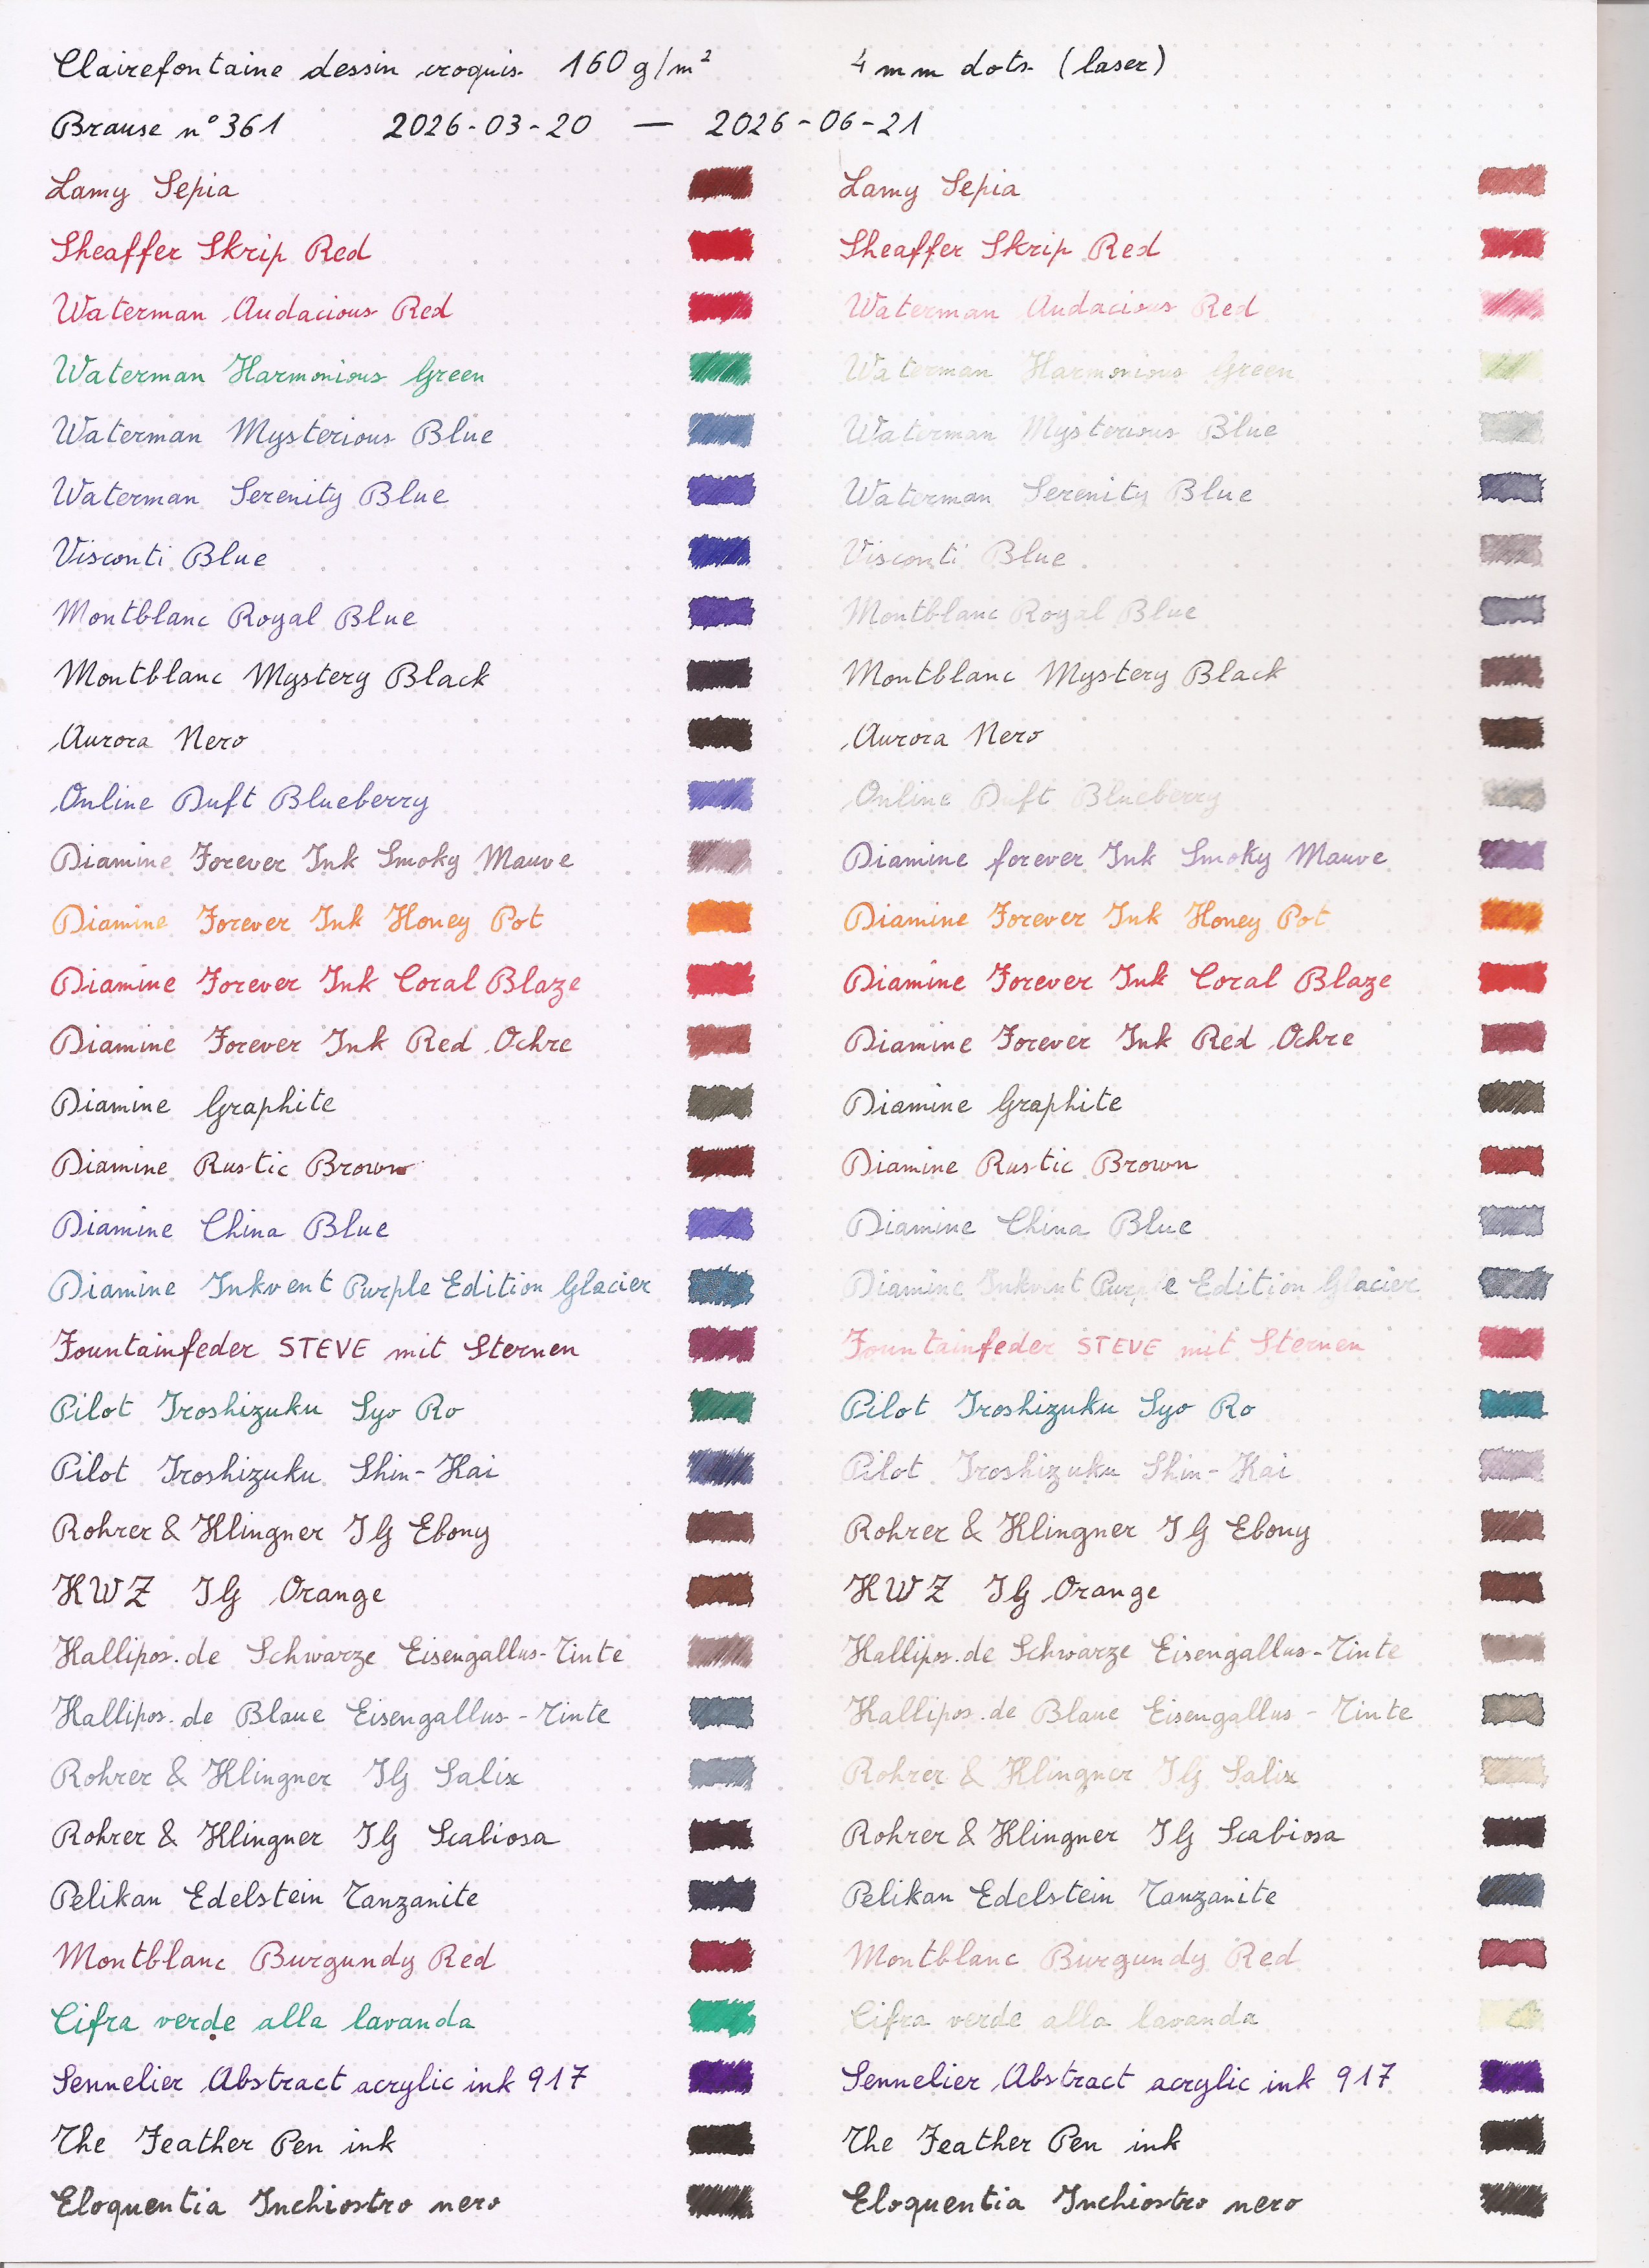
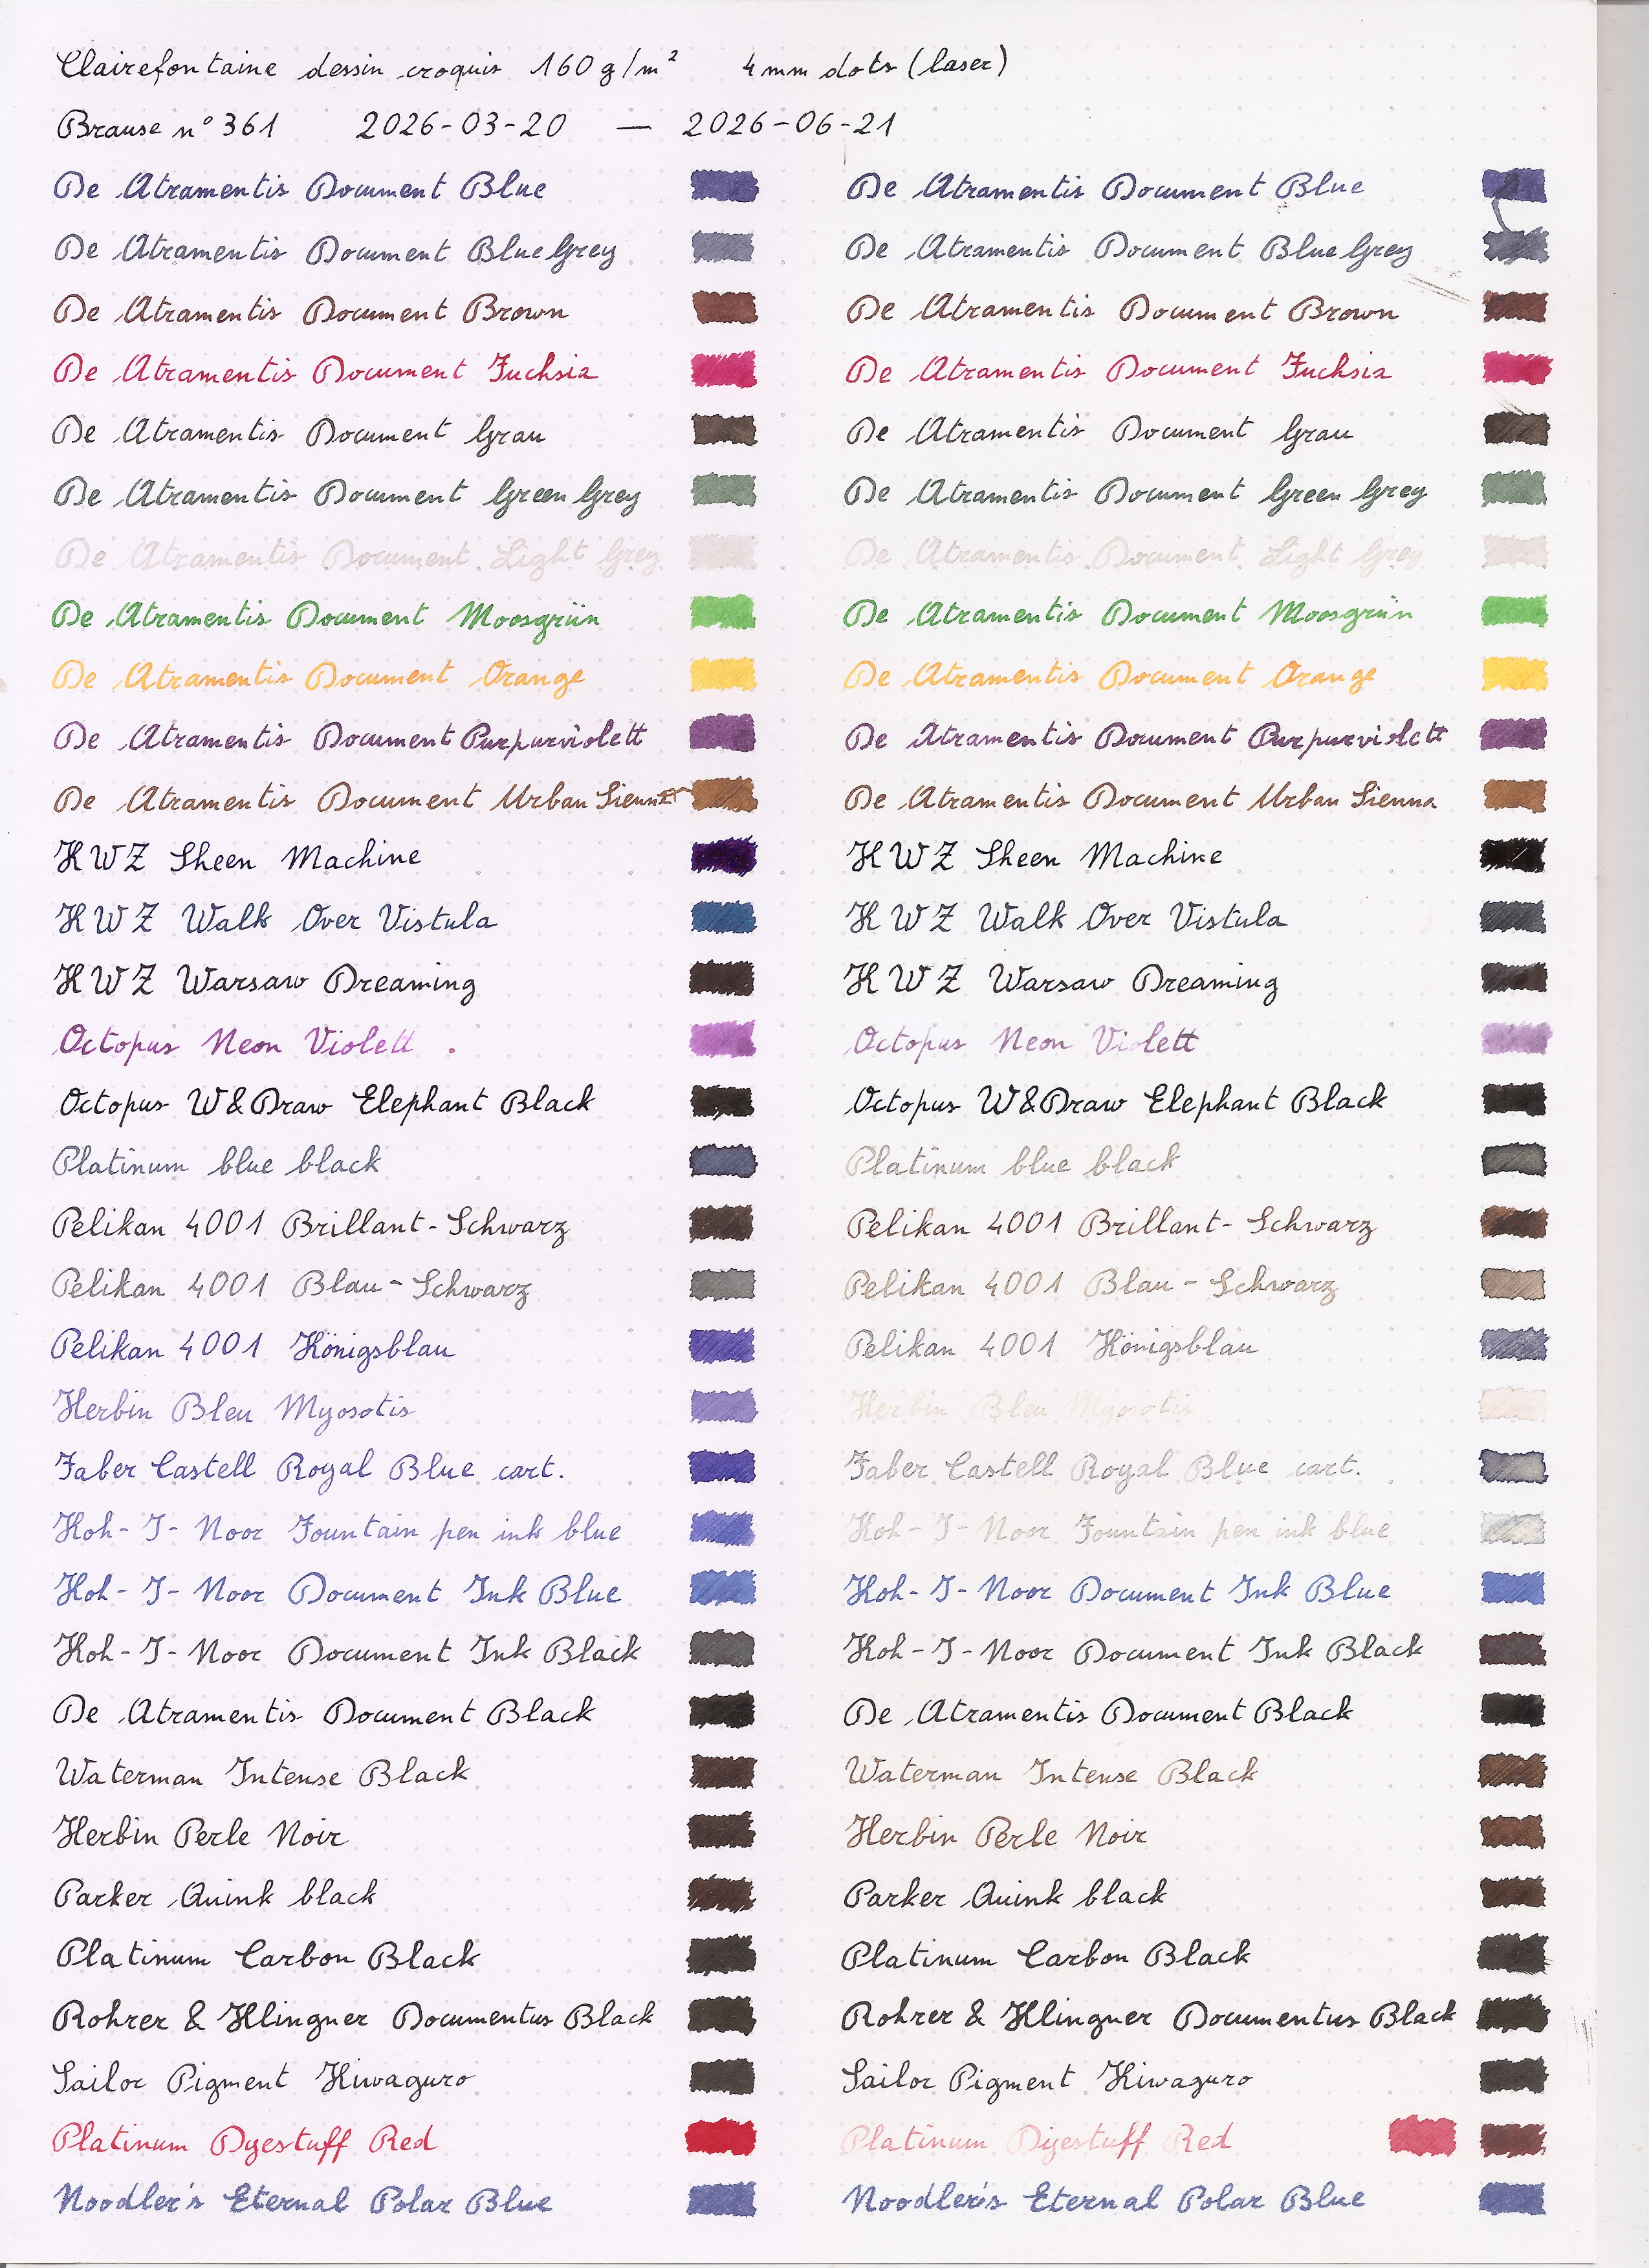 A month didn t change much compared to the four weeks, but I did the
scans for completeness, and from now on I m going to update monthly.
 I was reading
 The following contributors got their Debian Developer accounts in the last two
months:

 Huge. Huge. Amazing. It did crash as soon as I tried to actually use the
radio, but after fixing a few dangling bugs in the API surface (and some
assumptions I think some underlying gnuradio driver may be making that I need
to double check in the code), I was able to get a super solid stream of
broadcast fm radio, with gqrx being none the wiser. It thought it was
just talking to the device it knows as
 Nice. I can t wait to try this with the rest of the rtl-sdr based tools I like
having around using my
 A few months ago, in June 2025, I joined
 This needs to be clear: systemd is under attack by a trolling campaign orchestrated by fascist elements. Nobody is forced to like or use systemd, but anybody who wants to pick a side should know the facts.
Recently, the free software

 Image of the estimated qualiy of articles of the four articles in the second mixed-methods paper. Extreme dips reflect periods of frequent vandalism.

 When you re looking at source code it can be helpful to have some evidence
indicating who wrote it. Author tags give a surface level indication,
 A map of Vietnam with points of places we went to labeled. CARTO MAPTILER OPENSTREETMAP
 A picture of the park we roamed around in Ho Chi Minh City. Photo by Ravi Dwivedi, released under CC-BY-SA 4.0.
 This is the restaurant Badri s friend took us to. Photo by Ravi Dwivedi, released under CC-BY-SA 4.0.
 One of the dishes we had in the restaurant. This one was especially tasty. Photo by Ravi Dwivedi, released under CC-BY-SA 4.0.
 One of the dishes we had in the restaurant. Photo by Ravi Dwivedi, released under CC-BY-SA 4.0.
 These noodles are called Pho and are very popular in Vietnam. Photo by Ravi Dwivedi, released under CC-BY-SA 4.0.
 Interior of our train coach. Trains in Vietnam don t have side berths, unlike India. Photo by Ravi Dwivedi, released under CC-BY-SA 4.0.
 A picture of the berths from our coach. It had three tiers, similar to a 3 AC coach in Indian trains. Photo by Ravi Dwivedi, released under CC-BY-SA 4.0.
 The train had a cabin to put the bags in. Photo by Ravi Dwivedi, released under CC-BY-SA 4.0.
 Nha Trang train station. Photo by Ravi Dwivedi, released under CC-BY-SA 4.0.
 I got a complimentary cup of green tea along with coffee in Nha Trang. In this trip, Badri and I found out that this is customary at local places in Vietnam. Photo by Ravi Dwivedi, released under CC-BY-SA 4.0.
 Eggs being cooked on a pan for my order. Photo by Ravi Dwivedi, released under CC-BY-SA 4.0.
 The beach we went to in Nha Trang. Photo by Ravi Dwivedi, released under CC-BY-SA 4.0.
 This one was shot in the city center. In this trip, Badri and I found out that this is customary at local places in Vietnam. Photo by Ravi Dwivedi, released under CC-BY-SA 4.0.
 Inside a Highlands Coffee cafe in Nha Trang. Photo by Ravi Dwivedi, released under CC-BY-SA 4.0.
 A coffee I got from Highlands Coffee in Nha Trang. Photo by Ravi Dwivedi, released under CC-BY-SA 4.0.
 The restaurant we went to in Nha Trang. The word Chay in the name means it was a vegan restaurant. Photo by Ravi Dwivedi, released under CC-BY-SA 4.0.
 Soupy noodles we got at that restaurant. Photo by Ravi Dwivedi, released under CC-BY-SA 4.0.
 Dry noodles we got at that restaurant. Photo by Ravi Dwivedi, released under CC-BY-SA 4.0.
 This was the place we had our coffee in Tra Kieu. Photo by Ravi Dwivedi, released under CC-BY-SA 4.0.
 Photo of Badri with taxi driver. Photo by Ravi Dwivedi, released under CC-BY-SA 4.0.
 A picture of Tra Kieu area near the train station we got down at. Photo by Ravi Dwivedi, released under CC-BY-SA 4.0.
 Our breakfast in Hoi An. Photo by Ravi Dwivedi, released under CC-BY-SA 4.0.
 A photo of the hostel we stayed in Hoi An. Photo by Ravi Dwivedi, released under CC-BY-SA 4.0.
 Typical yellow house with gabled roof in Hoi An old town. Photo by Ravi Dwivedi, released under CC-BY-SA 4.0.
 Egg coffee I had in Hoi An. Photo by Ravi Dwivedi, released under CC-BY-SA 4.0.
 Bahn Bao in Hue. Photo by Ravi Dwivedi, released under CC-BY-SA 4.0.
 Hot Pot. Photo by Ravi Dwivedi, released under CC-BY-SA 4.0.
 Added soup to the noodles. Photo by Ravi Dwivedi, released under CC-BY-SA 4.0.
 Steamed rolls made of rice flour. Photo by Ravi Dwivedi, released under CC-BY-SA 4.0.
 Menu from a restaurant in Ho Chi Minh City with detailed description of the food. Photo by Ravi Dwivedi, released under CC-BY-SA 4.0.
 Our berths in the train. Photo by Ravi Dwivedi, released under CC-BY-SA 4.0.
 Egg coffee in Hanoi. Photo by Ravi Dwivedi, released under CC-BY-SA 4.0.
 Hanoi train street is a tourist attraction in Hanoi. Photo by Ravi Dwivedi, released under CC-BY-SA 4.0.
 A picture of pho we had in Hanoi. Photo by Ravi Dwivedi, released under CC-BY-SA 4.0.
 Bahn it is served packed in banana leaves. Photo by Ravi Dwivedi, released under CC-BY-SA 4.0.
 Bahn it. Photo by Ravi Dwivedi, released under CC-BY-SA 4.0.

 Version 0.0.28 of