Search Results: "ana"

31 May 2025

Russell Coker: Links May 2025

Christopher Biggs gave an informative Evrything Open lecture about voice recognition [1]. We need this on Debian phones. Guido wrote an informative blog post about booting a custom Android kernel on a Pixel 3a [2]. Good work in writing this up, but a pity that Google made the process so difficult. Interesting to read about an expert being a victim of a phishing attack [3]. It can happen to anyone, everyone has moments when they aren t concentrating. Interesting advice on how to leak to a journalist [4]. Brian Krebs wrote an informative article about the ways that Trump is deliberately reducing the cyber security of the US government [5]. Brian Krebs wrote an interesting article about the main smishng groups from China [6]. Louis Rossmann (who is known for high quality YouTube videos about computer repair) made an informative video about a scammy Australian company run by a child sex offender [7]. The Helmover was one of the wildest engineering projects of WW2, an over the horizon guided torpedo that could one-shot a battleship [8]. Interesting blog post about DDoSecrets and the utter failure of the company Telemessages which was used by the US government [9]. Jonathan McDowell wrote an interesting blog post about developing a free software competitor to Alexa etc, the listening hardware costs $13US per node [10]. Noema Magazine published an insightful article about Rewilding the Internet, it has some great ideas [11].

Antoine Beaupr : Traffic meter per ASN without logs

Have you ever found yourself in the situation where you had no or anonymized logs and still wanted to figure out where your traffic was coming from? Or you have multiple upstreams and are looking to see if you can save fees by getting into peering agreements with some other party? Or your site is getting heavy load but you can't pinpoint it on a single IP and you suspect some amoral corporation is training their degenerate AI on your content with a bot army? (You might be getting onto something there.) If that rings a bell, read on.

TL;DR: ... or just skip the cruft and install asncounter:
pip install asncounter
Also available in Debian 14 or later, or possibly in Debian 13 backports (soon to be released) if people are interested:
apt install asncounter
Then count whoever is hitting your network with:
awk ' print $2 ' /var/log/apache2/*access*.log   asncounter
or:
tail -F /var/log/apache2/*access*.log   awk ' print $2 '   asncounter
or:
tcpdump -q -n   asncounter --input-format=tcpdump --repl
or:
tcpdump -q -i eth0 -n -Q in "tcp and tcp[tcpflags] & tcp-syn != 0 and (port 80 or port 443)"   asncounter --input-format=tcpdump --repl
Read on for why this matters, and why I wrote yet another weird tool (almost) from scratch.

Background and manual work This is a tool I've been dreaming of for a long, long time. Back in 2006, at Koumbit a colleague had setup TAS ("Traffic Accounting System", " " in Russian, apparently), a collection of Perl script that would do per-IP accounting. It was pretty cool: it would count bytes per IP addresses and, from that, you could do analysis. But the project died, and it was kind of bespoke. Fast forward twenty years, and I find myself fighting off bots at the Tor Project (the irony...), with our GitLab suffering pretty bad slowdowns (see issue tpo/tpa/team#41677 for the latest public issue, the juicier one is confidential, unfortunately). (We did have some issues caused by overloads in CI, as we host, after all, a fork of Firefox, which is a massive repository, but the applications team did sustained, awesome work to fix issues on that side, again and again (see tpo/applications/tor-browser#43121 for the latest, and tpo/applications/tor-browser#43121 for some pretty impressive correlation work, I work with really skilled people). But those issues, I believe were fixed.) So I had the feeling it was our turn to get hammered by the AI bots. But how do we tell? I could tell something was hammering at the costly /commit/ and (especially costly) /blame/ endpoint. So at first, I pulled out the trusted awk, sort uniq -c sort -n tail pipeline I am sure others have worked out before:
awk ' print $1 ' /var/log/nginx/*.log   sort   uniq -c   sort -n   tail -10
For people new to this, that pulls the first field out of web server log files, sort the list, counts the number of unique entries, and sorts that so that the most common entries (or IPs) show up first, then show the top 10. That, other words, answers the question of "which IP address visits this web server the most?" Based on this, I found a couple of IP addresses that looked like Alibaba. I had already addressed an abuse complaint to them (tpo/tpa/team#42152) but never got a response, so I just blocked their entire network blocks, rather violently:
for cidr in 47.240.0.0/14 47.246.0.0/16 47.244.0.0/15 47.235.0.0/16 47.236.0.0/14; do 
  iptables-legacy -I INPUT -s $cidr -j REJECT
done
That made Ali Baba and his forty thieves (specifically their AL-3 network go away, but our load was still high, and I was still seeing various IPs crawling the costly endpoints. And this time, it was hard to tell who they were: you'll notice all the Alibaba IPs are inside the same 47.0.0.0/8 prefix. Although it's not a /8 itself, it's all inside the same prefix, so it's visually easy to pick it apart, especially for a brain like mine who's stared too long at logs flowing by too fast for their own mental health. What I had then was different, and I was tired of doing the stupid thing I had been doing for decades at this point. I had recently stumbled upon pyasn recently (in January, according to my notes) and somehow found it again, and thought "I bet I could write a quick script that loops over IPs and counts IPs per ASN". (Obviously, there are lots of other tools out there for that kind of monitoring. Argos, for example, presumably does this, but it's a kind of a huge stack. You can also get into netflows, but there's serious privacy implications with those. There are also lots of per-IP counters like promacct, but that doesn't scale. Or maybe someone already had solved this problem and I just wasted a week of my life, who knows. Someone will let me know, I hope, either way.)

ASNs and networks A quick aside, for people not familiar with how the internet works. People that know about ASNs, BGP announcements and so on can skip. The internet is the network of networks. It's made of multiple networks that talk to each other. The way this works is there is a Border Gateway Protocol (BGP), a relatively simple TCP-based protocol, that the edge routers of those networks used to announce each other what network they manage. Each of those network is called an Autonomous System (AS) and has an AS number (ASN) to uniquely identify it. Just like IP addresses, ASNs are allocated by IANA and local registries, they're pretty cheap and useful if you like running your own routers, get one. When you have an ASN, you'll use it to, say, announce to your BGP neighbors "I have 198.51.100.0/24" over here and the others might say "okay, and I have 216.90.108.31/19 over here, and I know of this other ASN over there that has 192.0.2.1/24 too! And gradually, those announcements flood the entire network, and you end up with each BGP having a routing table of the global internet, with a map of which network block, or "prefix" is announced by which ASN. It's how the internet works, and it's a useful thing to know, because it's what, ultimately, makes an organisation responsible for an IP address. There are "looking glass" tools like the one provided by routeviews.org which allow you to effectively run "trace routes" (but not the same as traceroute, which actively sends probes from your location), type an IP address in that form to fiddle with it. You will end up with an "AS path", the way to get from the looking glass to the announced network. But I digress, and that's kind of out of scope. Point is, internet is made of networks, networks are autonomous systems (AS) and they have numbers (ASNs), and they announced IP prefixes (or "network blocks") that ultimately tells you who is responsible for traffic on the internet.

Introducing asncounter So my goal was to get from "lots of IP addresses" to "list of ASNs", possibly also the list of prefixes (because why not). Turns out pyasn makes that really easy. I managed to build a prototype in probably less than an hour, just look at the first version, it's 44 lines (sloccount) of Python, and it works, provided you have already downloaded the required datafiles from routeviews.org. (Obviously, the latest version is longer at close to 1000 lines, but it downloads the data files automatically, and has many more features). The way the first prototype (and later versions too, mostly) worked is that you feed it a list of IP addresses on standard input, it looks up the ASN and prefix associated with the IP, and increments a counter for those, then print the result. That showed me something like this:
root@gitlab-02:~/anarcat-scripts# tcpdump -q -i eth0 -n -Q in "(udp or tcp)"   ./asncounter.py --tcpdump                                                                                                                                                                          
tcpdump: verbose output suppressed, use -v[v]... for full protocol decode                                                                
listening on eth0, link-type EN10MB (Ethernet), snapshot length 262144 bytes                                                             
INFO: collecting IPs from stdin, using datfile ipasn_20250523.1600.dat.gz                                                                
INFO: loading datfile /root/.cache/pyasn/ipasn_20250523.1600.dat.gz...                                                                   
INFO: loading /root/.cache/pyasn/asnames.json                       
ASN     count   AS               
136907  7811    HWCLOUDS-AS-AP HUAWEI CLOUDS, HK                                                                                         
[----]  359     [REDACTED]
[----]  313     [REDACTED]
8075    254     MICROSOFT-CORP-MSN-AS-BLOCK, US
[---]   164     [REDACTED]
[----]  136     [REDACTED]
24940   114     HETZNER-AS, DE  
[----]  98      [REDACTED]
14618   82      AMAZON-AES, US                                                                                                           
[----]  79      [REDACTED]
prefix  count                                         
166.108.192.0/20        1294                                                                                                             
188.239.32.0/20 1056                                          
166.108.224.0/20        970                    
111.119.192.0/20        951              
124.243.128.0/18        667                                         
94.74.80.0/20   651                                                 
111.119.224.0/20        622                                         
111.119.240.0/20        566           
111.119.208.0/20        538                                         
[REDACTED]  313           
Even without ratios and a total count (which will come later), it was quite clear that Huawei was doing something big on the server. At that point, it was responsible for a quarter to half of the traffic on our GitLab server or about 5-10 queries per second. But just looking at the logs, or per IP hit counts, it was really hard to tell. That traffic is really well distributed. If you look more closely at the output above, you'll notice I redacted a couple of entries except major providers, for privacy reasons. But you'll also notice almost nothing is redacted in the prefix list, why? Because all of those networks are Huawei! Their announcements are kind of bonkers: they have hundreds of such prefixes. Now, clever people in the know will say "of course they do, it's an hyperscaler; just ASN14618 (AMAZON-AES) there is way more announcements, they have 1416 prefixes!" Yes, of course, but they are not generating half of my traffic (at least, not yet). But even then: this also applies to Amazon! This way of counting traffic is way more useful for large scale operations like this, because you group by organisation instead of by server or individual endpoint. And, ultimately, this is why asncounter matters: it allows you to group your traffic by organisation, the place you can actually negotiate with. Now, of course, that assumes those are entities you can talk with. I have written to both Alibaba and Huawei, and have yet to receive a response. I assume I never will. In their defence, I wrote in English, perhaps I should have made the effort of translating my message in Chinese, but then again English is the Lingua Franca of the Internet, and I doubt that's actually the issue.

The Huawei and Facebook blocks Another aside, because this is my blog and I am not looking for a Pullitzer here. So I blocked Huawei from our GitLab server (and before you tear your shirt open: only our GitLab server, everything else is still accessible to them, including our email server to respond to my complaint). I did so 24h after emailing them, and after examining their user agent (UA) headers. Boy that was fun. In a sample of 268 requests I analyzed, they churned out 246 different UAs. At first glance, they looked legit, like:
Mozilla/5.0 (Macintosh; Intel Mac OS X 10_15_7) AppleWebKit/537.36 (KHTML, like Gecko) Chrome/131.0.0.0 Safari/537.36
Safari on a Mac, so far so good. But when you start digging, you notice some strange things, like here's Safari running on Linux:
Mozilla/5.0 (X11; U; Linux i686; en-US) AppleWebKit/534.3 (KHTML, like Gecko) Chrome/6.0.457.0 Safari/534.3
Was Safari ported to Linux? I guess that's.. possible? But here is Safari running on a 15 year old Ubuntu release (10.10):
Mozilla/5.0 (X11; Linux i686) AppleWebKit/534.24 (KHTML, like Gecko) Ubuntu/10.10 Chromium/12.0.702.0 Chrome/12.0.702.0 Safari/534.24
Speaking of old, here's Safari again, but this time running on Windows NT 5.1, AKA Windows XP, released 2001, EOL since 2019:
Mozilla/5.0 (Windows; U; Windows NT 5.1; en-CA) AppleWebKit/534.13 (KHTML like Gecko) Chrome/9.0.597.98 Safari/534.13
Really? Here's Firefox 3.6, released 14 years ago, there were quite a lot of those:
Mozilla/5.0 (Windows; U; Windows NT 6.1; lt; rv:1.9.2) Gecko/20100115 Firefox/3.6
I remember running those old Firefox releases, those were the days. But to me, those look like entirely fake UAs, deliberately rotated to make it look like legitimate traffic. In comparison, Facebook seemed a bit more legit, in the sense that they don't fake it. most hits are from:
meta-externalagent/1.1 (+https://developers.facebook.com/docs/sharing/webmasters/crawler)
which, according their documentation:
crawls the web for use cases such as training AI models or improving products by indexing content directly
From what I could tell, it was even respecting our rather liberal robots.txt rules, in that it wasn't crawling the sprawling /blame/ or /commit/ endpoints, explicitly forbidden by robots.txt. So I've blocked the Facebook bot in robots.txt and, amazingly, it just went away. Good job Facebook, as much as I think you've given the empire to neo-nazis, cause depression and genocide, you know how to run a crawler, thanks. Huawei was blocked at the web server level, with a friendly 429 status code telling people to contact us (over email) if they need help. And they don't care: they're still hammering the server, from what I can tell, but then again, I didn't block the entire ASN just yet, just the blocks I found crawling the server over a couple hours.

A full asncounter run So what does a day in asncounter look like? Well, you start with a problem, say you're getting too much traffic and want to see where it's from. First you need to sample it. Typically, you'd do that with tcpdump or tailing a log file:
tail -F /var/log/apache2/*access*.log   awk ' print $2 '   asncounter
If you have lots of traffic or care about your users' privacy, you're not going to log IP addresses, so tcpdump is likely a good option instead:
tcpdump -q -n   asncounter --input-format=tcpdump --repl
If you really get a lot of traffic, you might want to get a subset of that to avoid overwhelming asncounter, it's not fast enough to do multiple gigabit/second, I bet, so here's only incoming SYN IPv4 packets:
tcpdump -q -n -Q in "tcp and tcp[tcpflags] & tcp-syn != 0 and (port 80 or port 443)"   asncounter --input-format=tcpdump --repl
In any case, at this point you're staring at a process, just sitting there. If you passed the --repl or --manhole arguments, you're lucky: you have a Python shell inside the program. Otherwise, send SIGHUP to the thing to have it dump the nice tables out:
pkill -HUP asncounter
Here's an example run:
> awk ' print $2 ' /var/log/apache2/*access*.log   asncounter
INFO: using datfile ipasn_20250527.1600.dat.gz
INFO: collecting addresses from <stdin>
INFO: loading datfile /home/anarcat/.cache/pyasn/ipasn_20250527.1600.dat.gz...
INFO: finished reading data
INFO: loading /home/anarcat/.cache/pyasn/asnames.json
count   percent ASN AS
12779   69.33   66496   SAMPLE, CA
3361    18.23   None    None
366 1.99    66497   EXAMPLE, FR
337 1.83    16276   OVH, FR
321 1.74    8075    MICROSOFT-CORP-MSN-AS-BLOCK, US
309 1.68    14061   DIGITALOCEAN-ASN, US
128 0.69    16509   AMAZON-02, US
77  0.42    48090   DMZHOST, GB
56  0.3 136907  HWCLOUDS-AS-AP HUAWEI CLOUDS, HK
53  0.29    17621   CNCGROUP-SH China Unicom Shanghai network, CN
total: 18433
count   percent prefix  ASN AS
12779   69.33   192.0.2.0/24    66496   SAMPLE, CA
3361    18.23   None        
298 1.62    178.128.208.0/20    14061   DIGITALOCEAN-ASN, US
289 1.57    51.222.0.0/16   16276   OVH, FR
272 1.48    2001:DB8::/48   66497   EXAMPLE, FR
235 1.27    172.160.0.0/11  8075    MICROSOFT-CORP-MSN-AS-BLOCK, US
94  0.51    2001:DB8:1::/48 66497   EXAMPLE, FR
72  0.39    47.128.0.0/14   16509   AMAZON-02, US
69  0.37    93.123.109.0/24 48090   DMZHOST, GB
53  0.29    27.115.124.0/24 17621   CNCGROUP-SH China Unicom Shanghai network, CN
Those numbers are actually from my home network, not GitLab. Over there, the battle still rages on, but at least the vampire bots are banging their heads against the solid Nginx wall instead of eating the fragile heart of GitLab. We had a significant improvement in latency thanks to the Facebook and Huawei blocks... Here are the "workhorse request duration stats" for various time ranges, 20h after the block:
range mean max stdev
20h 449ms 958ms 39ms
7d 1.78s 5m 14.9s
30d 2.08s 3.86m 8.86s
6m 901ms 27.3s 2.43s
We went from two seconds mean to 500ms! And look at that standard deviation! 39ms! It was ten seconds before! I doubt we'll keep it that way very long but for now, it feels like I won a battle, and I didn't even have to setup anubis or go-away, although I suspect that will unfortunately come. Note that asncounter also supports exporting Prometheus metrics, but you should be careful with this, as it can lead to cardinal explosion, especially if you track by prefix (which can be disabled with --no-prefixes . Folks interested in more details should read the fine manual for more examples, usage, and discussion. It shows, among other things, how to effectively block lots of networks from Nginx, aggregate multiple prefixes, block entire ASNs, and more! So there you have it: I now have the tool I wish I had 20 years ago. Hopefully it will stay useful for another 20 years, although I'm not sure we'll have still have internet in 20 years. I welcome constructive feedback, "oh no you rewrote X", Grafana dashboards, bug reports, pull requests, and "hell yeah" comments. Hacker News, let it rip, I know you can give me another juicy quote for my blog. This work was done as part of my paid work for the Tor Project, currently in a fundraising drive, give us money if you like what you read.

30 May 2025

Russell Coker: Service Setup Difficulties

Marco wrote a blog post opposing hyperscale systems which included We want to use an hyperscaler cloud because our developers do not want to operate a scalable and redundant database just means that you need to hire competent developers and/or system administrators. [1]. I previously wrote a blog post Why Clusters Usually Don t Work [2] and I believe that all the points there are valid today and possibly exacerbated by clusters getting less direct use as clustering is increasingly being done by hyperscale providers. Take a basic need, a MySQL or PostgreSQL database for example. You want it to run and basically do the job and to have good recovery options. You could set it up locally, run backups, test the backups, have a recovery plan for failures, maybe have a hot-spare server if it s really important, have tests for backups and hot-spare server, etc. Then you could have documentation for this so if the person who set it up isn t available when there s a problem they will be able to find out what to do. But the hyperscale option is to just select a database in your provider and have all this just work. If the person who set it up isn t available for recovery in the event of failure the company can just put out a job advert for person with experience on cloud company X and have them just immediately go to work on it. I don t like hyperscale providers as they are all monopolistic companies that do anti-competitive actions. Google should be broken up, Android development and the Play Store should be separated from Gmail etc which should be separated from search and adverts, and all of them should be separated from the GCP cloud service. Amazon should be broken up, running the Amazon store should be separated from selling items on the store, which should be separated from running a video on demand platform, and all of them should be separated from the AWS cloud. Microsoft should be broken up, OS development should be separated from application development all of that should be separated from cloud services (Teams and Office 365), and everything else should be separate from the Azure cloud system. But the cloud providers offer real benefits at small scale. Running a MySQL or PostgreSQL database for local services is easy, it s a simple apt command to install it and then it basically works. Doing backup and recovery isn t so easy. One could say just hire competent people but if you do hire competent people do you want them running MySQL databases etc or have them just click on the create mysql database option on a cloud control panel and then move on to more important things? The FreedomBox project is a great project for installing and managing home/personal services [3]. But it s not about running things like database servers, it s for a high level running mail servers and other things for the user not for the developer. The Debian packaging of Open Stack looks interesting [4], it s a complete setup for running your own hyper scale cloud service. For medium and large organisations running Open Stack could be a good approach. But for small organisations it s cheaper and easier to just use a cloud service to run things. The issue of when to run things in-house and when to put them in the cloud is very complex. I think that if the organisation is going to spend less money on cloud services than on the salary of one sysadmin then it s probably best to have things in the cloud. When cloud costs start to exceed the salary of one person who manages systems then having them spend the extra time and effort to run things locally starts making more sense. There is also an opportunity cost in having a good sysadmin work on the backups for all the different systems instead of letting the cloud provider just do it. Another possibility of course is to run things in-house on low end hardware and just deal with the occasional downtime to save money. Knowingly choosing less reliability to save money can be quite reasonable as long as you have considered the options and all the responsible people are involved in the discussion. The one situation that I strongly oppose is having hyper scale services setup by people who don t understand them. Running a database server on a cloud service because you don t want to spend the time managing it is a reasonable choice in many situations. Running a database server on a cloud service because you don t understand how to setup a database server is never a good choice. While the cloud services are quite resilient there are still ways of breaking the overall system if you don t understand it. Also while it is quite possible for someone to know how to develop for databases including avoiding SQL injection etc but be unable to setup a database server that s probably not going to be common, probably if someone can t set it up (a generally easy task) then they can t do the hard tasks of making it secure.

29 May 2025

Arthur Diniz: Bringing Kubernetes Back to Debian

I ve been part of the Debian Project since 2019, when I attended DebConf held in Curitiba, Brazil. That event sparked my interest in the community, packaging, and how Debian works as a distribution. In the early years of my involvement, I contributed to various teams such as the Python, Golang and Cloud teams, packaging dependencies and maintaining various tools. However, I soon felt the need to focus on packaging software I truly enjoyed, tools I was passionate about using and maintaining. That s when I turned my attention to Kubernetes within Debian.

A Broken Ecosystem The Kubernetes packaging situation in Debian had been problematic for some time. Given its large codebase and complex dependency tree, the initial packaging approach involved vendorizing all dependencies. While this allowed a somewhat functional package to be published, it introduced several long-term issues, especially security concerns. Vendorized packages bundle third-party dependencies directly into the source tarball. When vulnerabilities arise in those dependencies, it becomes difficult for Debian s security team to patch and rebuild affected packages system-wide. This approach broke Debian s best practices, and it eventually led to the abandonment of the Kubernetes source package, which had stalled at version 1.20.5. Due to this abandonment, critical bugs emerged and the package was removed from Debian s testing channel, as we can see in the package tracker.

New Debian Kubernetes Team Around this time, I became a Debian Maintainer (DM), with permissions to upload certain packages. I saw an opportunity to both contribute more deeply to Debian and to fix Kubernetes packaging. In early 2024, just before DebConf Busan in South Korea, I founded the Debian Kubernetes Team. The mission of the team was to repackage Kubernetes in a maintainable, security-conscious, and Debian-compliant way. At DebConf, I shared our progress with the broader community and received great feedback and more visibility, along with people interested in contributing to the team. Our first tasks was to migrate existing Kubernetes-related tools such as kubectx, kubernetes-split-yaml and kubetail into a dedicated namespace on Salsa, Debian s GitLab instance. Many of these tools were stored across different teams (like the Go team), and consolidating them helped us organize development and focus our efforts.

De-vendorizing Kubernetes Our main goal was to un-vendorize Kubernetes and bring it up-to-date with upstream releases. This meant:
  • Removing the vendor directory and all embedded third-party code.
  • Trimming the build scope to focus solely on building kubectl, Kubernetes CLI.
  • Using Files-Excluded in debian/copyright to cleanly drop unneeded files during source imports.
  • Rebuilding the dependency tree, ensuring all Go modules were separately packaged in Debian.
We used uscan, a standard Debian packaging tool that fetches upstream tarballs and prepares them accordingly. The Files-Excluded directive in our debian/copyright file instructed uscan to automatically remove unnecessary files during the repackaging process:
$ uscan
Newest version of kubernetes on remote site is 1.32.3, specified download version is 1.32.3
Successfully repacked ../v1.32.3 as ../kubernetes_1.32.3+ds.orig.tar.gz, deleting 30616 files from it.
The results were dramatic. By comparing the original upstream tarball with our repackaged version, we can see that our approach reduced the tarball size by over 75%:
$ du -h upstream-v1.32.3.tar.gz kubernetes_1.32.3+ds.orig.tar.gz
14M	upstream-v1.32.3.tar.gz
3.2M	kubernetes_1.32.3+ds.orig.tar.gz
This significant reduction wasn t just about saving space. By removing over 30,000 files, we simplified the package, making it more maintainable. Each dependency could now be properly tracked, updated, and patched independently, resolving the security concerns that had plagued the previous packaging approach.

Dependency Graph To give you an idea of the complexity involved in packaging Kubernetes for Debian, the image below is a dependency graph generated with debtree, visualizing all the Go modules and other dependencies required to build the kubectl binary. kubectl-depgraph This web of nodes and edges represents every module and its relationship during the compilation process of kubectl. Each box is a Debian package, and the lines connecting them show how deeply intertwined the ecosystem is. What might look like a mess of blue spaghetti is actually a clear demonstration of the vast and interconnected upstream world that tools like kubectl rely on. But more importantly, this graph is a testament to the effort that went into making kubectl build entirely using Debian-packaged dependencies only, no vendoring, no downloading from the internet, no proprietary blobs.

Upstream Version 1.32.3 and Beyond After nearly two years of work, we successfully uploaded version 1.32.3+ds of kubectl to Debian unstable. kubernetes/-/merge_requests/1 The new package also includes:
  • Zsh, Fish, and Bash completions installed automatically
  • Man pages and metadata for improved discoverability
  • Full integration with kind and docker for testing purposes

Integration Testing with Autopkgtest To ensure the reliability of kubectl in real-world scenarios, we developed a new autopkgtest suite that runs integration tests using real Kubernetes clusters created via Kind. Autopkgtest is a Debian tool used to run automated tests on binary packages. These tests are executed after the package is built but before it s accepted into the Debian archive, helping catch regressions and integration issues early in the packaging pipeline. Our test workflow validates kubectl by performing the following steps:
  • Installing Kind and Docker as test dependencies.
  • Spinning up two local Kubernetes clusters.
  • Switching between cluster contexts to ensure multi-cluster support.
  • Deploying and scaling a sample nginx application using kubectl.
  • Cleaning up the entire test environment to avoid side effects.
  • debian/tests/kubectl.sh

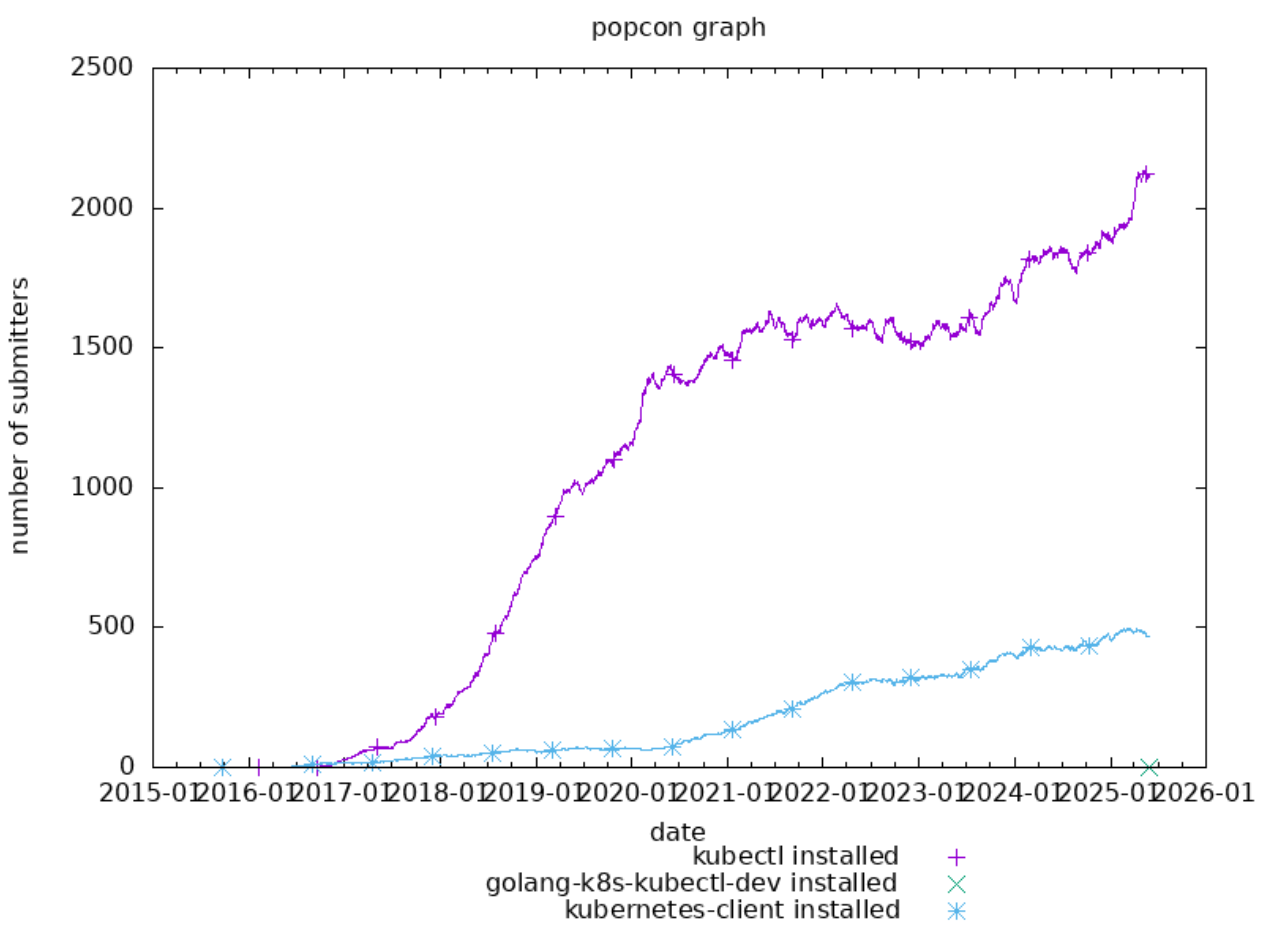
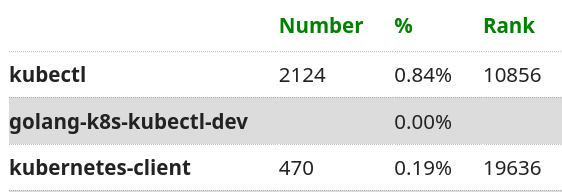
Popcon: Measuring Adoption To measure real-world usage, we rely on data from Debian s popularity contest (popcon), which gives insight into how many users have each binary installed. popcon-graph popcon-table Here s what the data tells us:
  • kubectl (new binary): Already installed on 2,124 systems.
  • golang-k8s-kubectl-dev: This is the Go development package (a library), useful for other packages and developers who want to interact with Kubernetes programmatically.
  • kubernetes-client: The legacy package that kubectl is replacing. We expect this number to decrease in future releases as more systems transition to the new package.
Although the popcon data shows activity for kubectl before the official Debian upload date, it s important to note that those numbers represent users who had it installed from upstream source-lists, not from the Debian repositories. This distinction underscores a demand that existed even before the package was available in Debian proper, and it validates the importance of bringing it into the archive.
Also worth mentioning: this number is not the real total number of installations, since users can choose not to participate in the popularity contest. So the actual adoption is likely higher than what popcon reflects.

Community and Documentation The team also maintains a dedicated wiki page which documents:
  • Maintained tools and packages
  • Contribution guidelines
  • Our roadmap for the upcoming Debian releases
https://debian-kubernetes.org

Looking Ahead to Debian 13 (Trixie) The next stable release of Debian will ship with kubectl version 1.32.3, built from a clean, de-vendorized source. This version includes nearly all the latest upstream features, and will be the first time in years that Debian users can rely on an up-to-date, policy-compliant kubectl directly from the archive. By comparing with upstream, our Debian package even delivers more out of the box, including shell completions, which the upstream still requires users to generate manually. In 2025, the Debian Kubernetes team will continue expanding our packaging efforts for the Kubernetes ecosystem. Our roadmap includes:
  • kubelet: The primary node agent that runs on each node. This will enable Debian users to create fully functional Kubernetes nodes without relying on external packages.
  • kubeadm: A tool for creating Kubernetes clusters. With kubeadm in Debian, users will then be able to bootstrap minimum viable clusters directly from the official repositories.
  • helm: The package manager for Kubernetes that helps manage applications through Kubernetes YAML files defined as charts.
  • kompose: A conversion tool that helps users familiar with docker-compose move to Kubernetes by translating Docker Compose files into Kubernetes resources.

Final Thoughts This journey was only possible thanks to the amazing support of the debian-devel-br community and the collective effort of contributors who stepped up to package missing dependencies, fix bugs, and test new versions. Special thanks to:
  • Carlos Henrique Melara (@charles)
  • Guilherme Puida (@puida)
  • Jo o Pedro Nobrega (@jnpf)
  • Lucas Kanashiro (@kanashiro)
  • Matheus Polkorny (@polkorny)
  • Samuel Henrique (@samueloph)
  • Sergio Cipriano (@cipriano)
  • Sergio Durigan Junior (@sergiodj)
I look forward to continuing this work, bringing more Kubernetes tools into Debian and improving the developer experience for everyone.

Debian XMPP Team: XMPP/Jabber Debian 13 Trixie News

Debian 13 "Trixie" full freeze has started 2025-05-17, so this is a good time to take a look at some of the features, that this release will bring. Here we will focus on packages related to XMPP, a.k.a. Jabber. XMPP is a universal communication protocol for instant messaging, push notifications, IoT, WebRTC, and social applications. It has existed since 1999, originally called "Jabber", it has a diverse and active developers community. Clients Servers Libraries Gateways/Transports Not in Trixie

28 May 2025

Clint Adams: Potted meat is viewed differently by different cultures

I've been working on a multi-label email classification model. It's been a frustrating slog, fraught with challenges, including a lack of training data. Labeling emails is labor-intensive and error-prone. Also, I habitually delete certain classes of email immediately after its usefulness has been reduced. I use a CRM-114-based spam filtering system (actually I use two different isntances of the same mailreaver config, but that's another story), which is differently frustrating, but I delete spam when it's detected or when it's trained. Fortunately, there's no shortage of incoming spam, so I can collect enough, but for other, arguably more important labels, they arrive infrequently. So, those labels need to be excluded, or the small sample sizes wreck the training feedback loop. Currently, I have ten active labels, and even though the point of this is not to be a spam filter, spam is one of the labels. Out of curiosity, I decided to compare the performance of my three different models, and to do so on a neutral corpus (in other words, emails that none of them had ever been trained on). I grabbed the full TREC 2007 corpus and ran inference. The results were unexpected in many ways. For example, the Pearson correlation coefficient between my older CRM-114 model and my newer CRM-114 was only about 0.78. I was even more surprised by how poorly all three performed. Were they overfit to my email? So, I decided to look at the TREC corpus for the first time, and lo and behold, the first spam-labeled email I checked was something I would definitely train all three models with as non-spam, but ham for CRM-114 and an entirely different label for my experimental model.
Posted on 2025-05-28
Tags:

Bits from Debian: Debian welcomes the 2025 GSOC contributors/students

GSoC logo We are very excited to announce that Debian has selected nine contributors to work under mentorship on a variety of projects with us during the Google Summer of Code. Here is a list of the projects and students, along with details of the tasks to be performed.
Project: Quality assurance and continuous integration for biological and medical applications inside Debian Deliverables of the project: Continuous integration tests for Debian Med applications lacking a test, Quality Assurance review and bug fixing if issues might be uncovered.
Project: Device-specific Tweaks Management Deliverables of the project: Analysis and discussion of the current state of device tweaks management in Debian and Mobian. Proposal for a unified, run-time approach. Packaging of this service and tweaks data/configuration for at least one device.
Project: Enhancing Debian packages with ROCm GPU acceleration Deliverables of the project: New Debian packages with GPU support. Enhanced GPU support within existing Debian packages. More autopackagetests running on the Debian ROCm CI.
Project: Make Debian for Raspberry Pi Build Again Deliverables of the project: Refreshing the set of daily-built images. Having the set of daily-built images become automatic again that is, go back to the promise of having it daily-built. Write an Ansible playbook/Chef recipe/Puppet whatsitsname to define a virtual serve and have it build daily. Do the (very basic!) hardware testing on several Raspberry computers. Do note, naturally, this will require having access to the relevant hardware.
Project: Package LLM Inference Libraries Deliverables of the project: Eventually I hope we can make vLLM into Debian archive, based on which we can deliver something for LLM inference out-of-the-box. If the amount of work eventually turns to be beyond my expectation, I'm still happy to see how far we can go towards this goal. If the amount of work required for vLLM is less than I expected, we can also look at something else like SGLang, another open source LLM inference library.
Project: Autopkgtests for the rsync package Deliverables of the project: Autopkgtests for the rsync package.
Project: Enhancing Salsa CI in Debian Deliverables of the project: More features, robustness, speed.
Congratulations and welcome to all the contributors! The Google Summer of Code program is possible in Debian thanks to the efforts of Debian Developers and Debian Contributors that dedicate part of their free time to mentor contributors and outreach tasks. Join us and help extend Debian! You can follow the contributors' weekly reports on the debian-outreach mailing-list, chat with us on our IRC channel or reach out to the individual projects' team mailing lists.

26 May 2025

Otto Kek l inen: Creating Debian packages from upstream Git

Featured image of post Creating Debian packages from upstream GitIn this post, I demonstrate the optimal workflow for creating new Debian packages in 2025, preserving the upstream git history. The motivation for this is to lower the barrier for sharing improvements to and from upstream, and to improve software provenance and supply-chain security by making it easy to inspect every change at any level using standard git tooling. Key elements of this workflow include: To make the instructions so concrete that anyone can repeat all the steps themselves on a real package, I demonstrate the steps by packaging the command-line tool Entr. It is written in C, has very few dependencies, and its final Debian source package structure is simple, yet exemplifies all the important parts that go into a complete Debian package:
  1. Creating a new packaging repository and publishing it under your personal namespace on salsa.debian.org.
  2. Using dh_make to create the initial Debian packaging.
  3. Posting the first draft of the Debian packaging as a Merge Request (MR) and using Salsa CI to verify Debian packaging quality.
  4. Running local builds efficiently and iterating on the packaging process.

Create new Debian packaging repository from the existing upstream project git repository First, create a new empty directory, then clone the upstream Git repository inside it:
shell
mkdir debian-entr
cd debian-entr
git clone --origin upstreamvcs --branch master \
 --single-branch https://github.com/eradman/entr.git
Using a clean directory makes it easier to inspect the build artifacts of a Debian package, which will be output in the parent directory of the Debian source directory. The extra parameters given to git clone lay the foundation for the Debian packaging git repository structure where the upstream git remote name is upstreamvcs. Only the upstream main branch is tracked to avoid cluttering git history with upstream development branches that are irrelevant for packaging in Debian. Next, enter the git repository directory and list the git tags. Pick the latest upstream release tag as the commit to start the branch upstream/latest. This latest refers to the upstream release, not the upstream development branch. Immediately after, branch off the debian/latest branch, which will have the actual Debian packaging files in the debian/ subdirectory.
shell
cd entr
git tag # shows the latest upstream release tag was '5.6'
git checkout -b upstream/latest 5.6
git checkout -b debian/latest
%% init:   'gitGraph':   'mainBranchName': 'master'      %%
gitGraph:
checkout master
commit id: "Upstream 5.6 release" tag: "5.6"
branch upstream/latest
checkout upstream/latest
commit id: "New upstream version 5.6" tag: "upstream/5.6"
branch debian/latest
checkout debian/latest
commit id: "Initial Debian packaging"
commit id: "Additional change 1"
commit id: "Additional change 2"
commit id: "Additional change 3"
At this point, the repository is structured according to DEP-14 conventions, ensuring a clear separation between upstream and Debian packaging changes, but there are no Debian changes yet. Next, add the Salsa repository as a new remote which called origin, the same as the default remote name in git.
shell
git remote add origin git@salsa.debian.org:otto/entr-demo.git
git push --set-upstream origin debian/latest
This is an important preparation step to later be able to create a Merge Request on Salsa that targets the debian/latest branch, which does not yet have any debian/ directory.

Launch a Debian Sid (unstable) container to run builds in To ensure that all packaging tools are of the latest versions, run everything inside a fresh Sid container. This has two benefits: you are guaranteed to have the most up-to-date toolchain, and your host system stays clean without getting polluted by various extra packages. Additionally, this approach works even if your host system is not Debian/Ubuntu.
shell
cd ..
podman run --interactive --tty --rm --shm-size=1G --cap-add SYS_PTRACE \
 --env='DEB*' --volume=$PWD:/tmp/test --workdir=/tmp/test debian:sid bash
Note that the container should be started from the parent directory of the git repository, not inside it. The --volume parameter will loop-mount the current directory inside the container. Thus all files created and modified are on the host system, and will persist after the container shuts down. Once inside the container, install the basic dependencies:
shell
apt update -q && apt install -q --yes git-buildpackage dpkg-dev dh-make

Automate creating the debian/ files with dh-make To create the files needed for the actual Debian packaging, use dh_make:
shell
# dh_make --packagename entr_5.6 --single --createorig
Maintainer Name : Otto Kek l inen
Email-Address : otto@debian.org
Date : Sat, 15 Feb 2025 01:17:51 +0000
Package Name : entr
Version : 5.6
License : blank
Package Type : single
Are the details correct? [Y/n/q]

Done. Please edit the files in the debian/ subdirectory now.
Due to how dh_make works, the package name and version need to be written as a single underscore separated string. In this case, you should choose --single to specify that the package type is a single binary package. Other options would be --library for library packages (see libgda5 sources as an example) or --indep (see dns-root-data sources as an example). The --createorig will create a mock upstream release tarball (entr_5.6.orig.tar.xz) from the current release directory, which is necessary due to historical reasons and how dh_make worked before git repositories became common and Debian source packages were based off upstream release tarballs (e.g. *.tar.gz). At this stage, a debian/ directory has been created with template files, and you can start modifying the files and iterating towards actual working packaging.
shell
git add debian/
git commit -a -m "Initial Debian packaging"

Review the files The full list of files after the above steps with dh_make would be:
 -- entr
   -- LICENSE
   -- Makefile.bsd
   -- Makefile.linux
   -- Makefile.linux-compat
   -- Makefile.macos
   -- NEWS
   -- README.md
   -- configure
   -- data.h
   -- debian
     -- README.Debian
     -- README.source
     -- changelog
     -- control
     -- copyright
     -- gbp.conf
     -- entr-docs.docs
     -- entr.cron.d.ex
     -- entr.doc-base.ex
     -- manpage.1.ex
     -- manpage.md.ex
     -- manpage.sgml.ex
     -- manpage.xml.ex
     -- postinst.ex
     -- postrm.ex
     -- preinst.ex
     -- prerm.ex
     -- rules
     -- salsa-ci.yml.ex
     -- source
       -- format
     -- upstream
       -- metadata.ex
     -- watch.ex
   -- entr.1
   -- entr.c
   -- missing
     -- compat.h
     -- kqueue_inotify.c
     -- strlcpy.c
     -- sys
     -- event.h
   -- status.c
   -- status.h
   -- system_test.sh
 -- entr_5.6.orig.tar.xz
You can browse these files in the demo repository. The mandatory files in the debian/ directory are:
  • changelog,
  • control,
  • copyright,
  • and rules.
All the other files have been created for convenience so the packager has template files to work from. The files with the suffix .ex are example files that won t have any effect until their content is adjusted and the suffix removed. For detailed explanations of the purpose of each file in the debian/ subdirectory, see the following resources:
  • The Debian Policy Manual: Describes the structure of the operating system, the package archive and requirements for packages to be included in the Debian archive.
  • The Developer s Reference: A collection of best practices and process descriptions Debian packagers are expected to follow while interacting with one another.
  • Debhelper man pages: Detailed information of how the Debian package build system works, and how the contents of the various files in debian/ affect the end result.
As Entr, the package used in this example, is a real package that already exists in the Debian archive, you may want to browse the actual Debian packaging source at https://salsa.debian.org/debian/entr/-/tree/debian/latest/debian for reference. Most of these files have standardized formatting conventions to make collaboration easier. To automatically format the files following the most popular conventions, simply run wrap-and-sort -vast or debputy reformat --style=black.

Identify build dependencies The most common reason for builds to fail is missing dependencies. The easiest way to identify which Debian package ships the required dependency is using apt-file. If, for example, a build fails complaining that pcre2posix.h cannot be found or that libcre2-posix.so is missing, you can use these commands:
shell
$ apt install -q --yes apt-file && apt-file update
$ apt-file search pcre2posix.h
libpcre2-dev: /usr/include/pcre2posix.h
$ apt-file search libpcre2-posix.so
libpcre2-dev: /usr/lib/x86_64-linux-gnu/libpcre2-posix.so
libpcre2-posix3: /usr/lib/x86_64-linux-gnu/libpcre2-posix.so.3
libpcre2-posix3: /usr/lib/x86_64-linux-gnu/libpcre2-posix.so.3.0.6
The output above implies that the debian/control should be extended to define a Build-Depends: libpcre2-dev relationship. There is also dpkg-depcheck that uses strace to trace the files the build process tries to access, and lists what Debian packages those files belong to. Example usage:
shell
dpkg-depcheck -b debian/rules build

Build the Debian sources to generate the .deb package After the first pass of refining the contents of the files in debian/, test the build by running dpkg-buildpackage inside the container:
shell
dpkg-buildpackage -uc -us -b
The options -uc -us will skip signing the resulting Debian source package and other build artifacts. The -b option will skip creating a source package and only build the (binary) *.deb packages. The output is very verbose and gives a large amount of context about what is happening during the build to make debugging build failures easier. In the build log of entr you will see for example the line dh binary --buildsystem=makefile. This and other dh commands can also be run manually if there is a need to quickly repeat only a part of the build while debugging build failures. To see what files were generated or modified by the build simply run git status --ignored:
shell
$ git status --ignored
On branch debian/latest

Untracked files:
 (use "git add <file>..." to include in what will be committed)
 debian/debhelper-build-stamp
 debian/entr.debhelper.log
 debian/entr.substvars
 debian/files

Ignored files:
 (use "git add -f <file>..." to include in what will be committed)
 Makefile
 compat.c
 compat.o
 debian/.debhelper/
 debian/entr/
 entr
 entr.o
 status.o
Re-running dpkg-buildpackage will include running the command dh clean, which assuming it is configured correctly in the debian/rules file will reset the source directory to the original pristine state. The same can of course also be done with regular git commands git reset --hard; git clean -fdx. To avoid accidentally committing unnecessary build artifacts in git, a debian/.gitignore can be useful and it would typically include all four files listed as untracked above. After a successful build you would have the following files:
shell
 -- entr
   -- LICENSE
   -- Makefile -> Makefile.linux
   -- Makefile.bsd
   -- Makefile.linux
   -- Makefile.linux-compat
   -- Makefile.macos
   -- NEWS
   -- README.md
   -- compat.c
   -- compat.o
   -- configure
   -- data.h
   -- debian
     -- README.source.md
     -- changelog
     -- control
     -- copyright
     -- debhelper-build-stamp
     -- docs
     -- entr
       -- DEBIAN
         -- control
         -- md5sums
       -- usr
       -- bin
         -- entr
       -- share
       -- doc
         -- entr
         -- NEWS.gz
         -- README.md
         -- changelog.Debian.gz
         -- copyright
       -- man
       -- man1
       -- entr.1.gz
     -- entr.debhelper.log
     -- entr.substvars
     -- files
     -- gbp.conf
     -- patches
       -- PR149-expand-aliases-in-system-test-script.patch
       -- series
       -- system-test-skip-no-tty.patch
       -- system-test-with-system-binary.patch
     -- rules
     -- salsa-ci.yml
     -- source
       -- format
     -- tests
       -- control
     -- upstream
       -- metadata
       -- signing-key.asc
     -- watch
   -- entr
   -- entr.1
   -- entr.c
   -- entr.o
   -- missing
     -- compat.h
     -- kqueue_inotify.c
     -- strlcpy.c
     -- sys
     -- event.h
   -- status.c
   -- status.h
   -- status.o
   -- system_test.sh
 -- entr-dbgsym_5.6-1_amd64.deb
 -- entr_5.6-1.debian.tar.xz
 -- entr_5.6-1.dsc
 -- entr_5.6-1_amd64.buildinfo
 -- entr_5.6-1_amd64.changes
 -- entr_5.6-1_amd64.deb
 -- entr_5.6.orig.tar.xz
The contents of debian/entr are essentially what goes into the resulting entr_5.6-1_amd64.deb package. Familiarizing yourself with the majority of the files in the original upstream source as well as all the resulting build artifacts is time consuming, but it is a necessary investment to get high-quality Debian packages. There are also tools such as Debcraft that automate generating the build artifacts in separate output directories for each build, thus making it easy to compare the changes to correlate what change in the Debian packaging led to what change in the resulting build artifacts.

Re-run the initial import with git-buildpackage When upstreams publish releases as tarballs, they should also be imported for optimal software supply-chain security, in particular if upstream also publishes cryptographic signatures that can be used to verify the authenticity of the tarballs. To achieve this, the files debian/watch, debian/upstream/signing-key.asc, and debian/gbp.conf need to be present with the correct options. In the gbp.conf file, ensure you have the correct options based on:
  1. Does upstream release tarballs? If so, enforce pristine-tar = True.
  2. Does upstream sign the tarballs? If so, configure explicit signature checking with upstream-signatures = on.
  3. Does upstream have a git repository, and does it have release git tags? If so, configure the release git tag format, e.g. upstream-vcs-tag = %(version%~%.)s.
To validate that the above files are working correctly, run gbp import-orig with the current version explicitly defined:
shell
$ gbp import-orig --uscan --upstream-version 5.6
gbp:info: Launching uscan...
gpgv: Signature made 7. Aug 2024 07.43.27 PDT
gpgv: using RSA key 519151D83E83D40A232B4D615C418B8631BC7C26
gpgv: Good signature from "Eric Radman <ericshane@eradman.com>"
gbp:info: Using uscan downloaded tarball ../entr_5.6.orig.tar.gz
gbp:info: Importing '../entr_5.6.orig.tar.gz' to branch 'upstream/latest'...
gbp:info: Source package is entr
gbp:info: Upstream version is 5.6
gbp:info: Replacing upstream source on 'debian/latest'
gbp:info: Running Postimport hook
gbp:info: Successfully imported version 5.6 of ../entr_5.6.orig.tar.gz
As the original packaging was done based on the upstream release git tag, the above command will fetch the tarball release, create the pristine-tar branch, and store the tarball delta on it. This command will also attempt to create the tag upstream/5.6 on the upstream/latest branch.

Import new upstream versions in the future Forking the upstream git repository, creating the initial packaging, and creating the DEP-14 branch structure are all one-off work needed only when creating the initial packaging. Going forward, to import new upstream releases, one would simply run git fetch upstreamvcs; gbp import-orig --uscan, which fetches the upstream git tags, checks for new upstream tarballs, and automatically downloads, verifies, and imports the new version. See the galera-4-demo example in the Debian source packages in git explained post as a demo you can try running yourself and examine in detail. You can also try running gbp import-orig --uscan without specifying a version. It would fetch it, as it will notice there is now Entr version 5.7 available, and import it.

Build using git-buildpackage From this stage onwards you should build the package using gbp buildpackage, which will do a more comprehensive build.
shell
gbp buildpackage -uc -us
The git-buildpackage build also includes running Lintian to find potential Debian policy violations in the sources or in the resulting .deb binary packages. Many Debian Developers run lintian -EviIL +pedantic after every build to check that there are no new nags, and to validate that changes intended to previous Lintian nags were correct.

Open a Merge Request on Salsa for Debian packaging review Getting everything perfectly right takes a lot of effort, and may require reaching out to an experienced Debian Developers for review and guidance. Thus, you should aim to publish your initial packaging work on Salsa, Debian s GitLab instance, for review and feedback as early as possible. For somebody to be able to easily see what you have done, you should rename your debian/latest branch to another name, for example next/debian/latest, and open a Merge Request that targets the debian/latest branch on your Salsa fork, which still has only the unmodified upstream files. If you have followed the workflow in this post so far, you can simply run:
  1. git checkout -b next/debian/latest
  2. git push --set-upstream origin next/debian/latest
  3. Open in a browser the URL visible in the git remote response
  4. Write the Merge Request description in case the default text from your commit is not enough
  5. Mark the MR as Draft using the checkbox
  6. Publish the MR and request feedback
Once a Merge Request exists, discussion regarding what additional changes are needed can be conducted as MR comments. With an MR, you can easily iterate on the contents of next/debian/latest, rebase, force push, and request re-review as many times as you want. While at it, make sure the Settings > CI/CD page has under CI/CD configuration file the value debian/salsa-ci.yml so that the CI can run and give you immediate automated feedback. For an example of an initial packaging Merge Request, see https://salsa.debian.org/otto/entr-demo/-/merge_requests/1.

Open a Merge Request / Pull Request to fix upstream code Due to the high quality requirements in Debian, it is fairly common that while doing the initial Debian packaging of an open source project, issues are found that stem from the upstream source code. While it is possible to carry extra patches in Debian, it is not good practice to deviate too much from upstream code with custom Debian patches. Instead, the Debian packager should try to get the fixes applied directly upstream. Using git-buildpackage patch queues is the most convenient way to make modifications to the upstream source code so that they automatically convert into Debian patches (stored at debian/patches), and can also easily be submitted upstream as any regular git commit (and rebased and resubmitted many times over). First, decide if you want to work out of the upstream development branch and later cherry-pick to the Debian packaging branch, or work out of the Debian packaging branch and cherry-pick to an upstream branch. The example below starts from the upstream development branch and then cherry-picks the commit into the git-buildpackage patch queue:
shell
git checkout -b bugfix-branch master
nano entr.c
make
./entr # verify change works as expected
git commit -a -m "Commit title" -m "Commit body"
git push # submit upstream
gbp pq import --force --time-machine=10
git cherry-pick <commit id>
git commit --amend # extend commit message with DEP-3 metadata
gbp buildpackage -uc -us -b
./entr # verify change works as expected
gbp pq export --drop --commit
git commit --amend # Write commit message along lines "Add patch to .."
The example below starts by making the fix on a git-buildpackage patch queue branch, and then cherry-picking it onto the upstream development branch:
shell
gbp pq import --force --time-machine=10
nano entr.c
git commit -a -m "Commit title" -m "Commit body"
gbp buildpackage -uc -us -b
./entr # verify change works as expected
gbp pq export --drop --commit
git commit --amend # Write commit message along lines "Add patch to .."
git checkout -b bugfix-branch master
git cherry-pick <commit id>
git commit --amend # prepare commit message for upstream submission
git push # submit upstream
The key git-buildpackage commands to enter and exit the patch-queue mode are:
shell
gbp pq import --force --time-machine=10
gbp pq export --drop --commit
%% init:   'gitGraph':   'mainBranchName': 'debian/latest'      %%
gitGraph
checkout debian/latest
commit id: "Initial packaging"
branch patch-queue/debian/latest
checkout patch-queue/debian/latest
commit id: "Delete debian/patches/..."
commit id: "Patch 1 title"
commit id: "Patch 2 title"
commit id: "Patch 3 title"
These can be run at any time, regardless if any debian/patches existed prior, or if existing patches applied cleanly or not, or if there were old patch queue branches around. Note that the extra -b in gbp buildpackage -uc -us -b instructs to build only binary packages, avoiding any nags from dpkg-source that there are modifications in the upstream sources while building in the patches-applied mode.

Programming-language specific dh-make alternatives As each programming language has its specific way of building the source code, and many other conventions regarding the file layout and more, Debian has multiple custom tools to create new Debian source packages for specific programming languages. Notably, Python does not have its own tool, but there is an dh_make --python option for Python support directly in dh_make itself. The list is not complete and many more tools exist. For some languages, there are even competing options, such as for Go there is in addition to dh-make-golang also Gophian. When learning Debian packaging, there is no need to learn these tools upfront. Being aware that they exist is enough, and one can learn them only if and when one starts to package a project in a new programming language.

The difference between source git repository vs source packages vs binary packages As seen in earlier example, running gbp buildpackage on the Entr packaging repository above will result in several files:
entr_5.6-1_amd64.changes
entr_5.6-1_amd64.deb
entr_5.6-1.debian.tar.xz
entr_5.6-1.dsc
entr_5.6.orig.tar.gz
entr_5.6.orig.tar.gz.asc
The entr_5.6-1_amd64.deb is the binary package, which can be installed on a Debian/Ubuntu system. The rest of the files constitute the source package. To do a source-only build, run gbp buildpackage -S and note the files produced:
entr_5.6-1_source.changes
entr_5.6-1.debian.tar.xz
entr_5.6-1.dsc
entr_5.6.orig.tar.gz
entr_5.6.orig.tar.gz.asc
The source package files can be used to build the binary .deb for amd64, or any architecture that the package supports. It is important to grasp that the Debian source package is the preferred form to be able to build the binary packages on various Debian build systems, and the Debian source package is not the same thing as the Debian packaging git repository contents.
flowchart LR
git[Git repository<br>branch debian/latest] --> gbp buildpackage -S  src[Source Package<br>.dsc + .tar.xz]
src --> dpkg-buildpackage  bin[Binary Packages<br>.deb]
If the package is large and complex, the build could result in multiple binary packages. One set of package definition files in debian/ will however only ever result in a single source package.

Option to repackage source packages with Files-Excluded lists in the debian/copyright file Some upstream projects may include binary files in their release, or other undesirable content that needs to be omitted from the source package in Debian. The easiest way to filter them out is by adding to the debian/copyright file a Files-Excluded field listing the undesired files. The debian/copyright file is read by uscan, which will repackage the upstream sources on-the-fly when importing new upstream releases. For a real-life example, see the debian/copyright files in the Godot package that lists:
debian
Files-Excluded: platform/android/java/gradle/wrapper/gradle-wrapper.jar
The resulting repackaged upstream source tarball, as well as the upstream version component, will have an extra +ds to signify that it is not the true original upstream source but has been modified by Debian:
godot_4.3+ds.orig.tar.xz
godot_4.3+ds-1_amd64.deb

Creating one Debian source package from multiple upstream source packages also possible In some rare cases the upstream project may be split across multiple git repositories or the upstream release may consist of multiple components each in their own separate tarball. Usually these are very large projects that get some benefits from releasing components separately. If in Debian these are deemed to go into a single source package, it is technically possible using the component system in git-buildpackage and uscan. For an example see the gbp.conf and watch files in the node-cacache package. Using this type of structure should be a last resort, as it creates complexity and inter-dependencies that are bound to cause issues later on. It is usually better to work with upstream and champion universal best practices with clear releases and version schemes.

When not to start the Debian packaging repository as a fork of the upstream one Not all upstreams use Git for version control. It is by far the most popular, but there are still some that use e.g. Subversion or Mercurial. Who knows maybe in the future some new version control systems will start to compete with Git. There are also projects that use Git in massive monorepos and with complex submodule setups that invalidate the basic assumptions required to map an upstream Git repository into a Debian packaging repository. In those cases one can t use a debian/latest branch on a clone of the upstream git repository as the starting point for the Debian packaging, but one must revert the traditional way of starting from an upstream release tarball with gbp import-orig package-1.0.tar.gz.

Conclusion Created in August 1993, Debian is one of the oldest Linux distributions. In the 32 years since inception, the .deb packaging format and the tooling to work with it have evolved several generations. In the past 10 years, more and more Debian Developers have converged on certain core practices evidenced by https://trends.debian.net/, but there is still a lot of variance in workflows even for identical tasks. Hopefully, you find this post useful in giving practical guidance on how exactly to do the most common things when packaging software for Debian. Happy packaging!

25 May 2025

Iustin Pop: Corydalis v2025.21.0 - new features!

I just released yesterday a new version of Corydalis (https://demo.corydalis.io, https://github.com/iustin/corydalis). To me personally, it s a major improvement, since the native (my own) image viewer finally gets zooming, panning, gesture handling, etc. This is table-stakes for an image viewer, but oh well, it took me a long time to implement it, because of multiple things: lack of time, the JS library I was using for gestures was pretty old and unmaintained and it caused more trouble than was helping, etc. The feature is not perfect, and on the demo site there s already a bug since all images are smaller than the screen, and this I didn t test , so double-click to zoom doesn t work: says Already at minimum zoom , but zooming otherwise (+/- on the keyboard, mouse wheel, gesture) works. End-to-end, the major development for this release was done over around two weeks, which is pretty short: I extensively used Claude Sonnet and Grok to unblock myself. Not to write code per se - although there is code written 1:1 by LLMs, but most of the code is weirdly wrong, and I have to either correct it or just use it as a starter and rewrite most of it. But to discuss and unblock, and learn about new things, the current LLMs are very good at. And yet, sometimes even what they re good at, fails hard. I asked for ideas to simplify a piece of code, and it went nowhere, even if there were significant rewrite possibilities. I spent the brain cycles on it, reverse engineered my own code, then simplified. I ll have to write a separate blog post on this In any case, this (zooming) was the last major feature I was missing. There are image viewer libraries, but most of them slow, compared to the bare-bones (well, now not so much anymore) viewer that I use as main viewer. From now on, it will me minor incremental features, mostly around Exif management/handling, etc. Or, well, internal cleanups: extend test coverage, remove use of JQuery in the frontend, etc., there are tons of things to do. Fun fact: I managed to discover a Safari iOS bug. Or at least I think it s a bug, so reported it and curious what ll come out of it. Finally, I still couldn t fix the GitHub actions bug where the git describe doesn t see the just pushed tag, sigh, so the demo site still lists Corydalis v2024.12.0-133-g00edf63 as the version .

Otto Kek l inen: New Debian package creation from upstream git repository

Featured image of post New Debian package creation from upstream git repositoryIn this post, I demonstrate the optimal workflow for creating new Debian packages in 2025, preserving the upstream git history. The motivation for this is to lower the barrier for sharing improvements to and from upstream, and to improve software provenance and supply-chain security by making it easy to inspect every change at any level using standard git tooling. Key elements of this workflow include: To make the instructions so concrete that anyone can repeat all the steps themselves on a real package, I demonstrate the steps by packaging the command-line tool Entr. It is written in C, has very few dependencies, and its final Debian source package structure is simple, yet exemplifies all the important parts that go into a complete Debian package:
  1. Creating a new packaging repository and publishing it under your personal namespace on salsa.debian.org.
  2. Using dh_make to create the initial Debian packaging.
  3. Posting the first draft of the Debian packaging as a Merge Request (MR) and using Salsa CI to verify Debian packaging quality.
  4. Running local builds efficiently and iterating on the packaging process.

Create new Debian packaging repository from the existing upstream project git repository First, create a new empty directory, then clone the upstream Git repository inside it:
shell
mkdir debian-entr
cd debian-entr
git clone --origin upstreamvcs --branch master \
 --single-branch https://github.com/eradman/entr.git
Using a clean directory makes it easier to inspect the build artifacts of a Debian package, which will be output in the parent directory of the Debian source directory. The extra parameters given to git clone lay the foundation for the Debian packaging git repository structure where the upstream git remote name is upstreamvcs. Only the upstream main branch is tracked to avoid cluttering git history with upstream development branches that are irrelevant for packaging in Debian. Next, enter the git repository directory and list the git tags. Pick the latest upstream release tag as the commit to start the branch upstream/latest. This latest refers to the upstream release, not the upstream development branch. Immediately after, branch off the debian/latest branch, which will have the actual Debian packaging files in the debian/ subdirectory.
shell
cd entr
git tag # shows the latest upstream release tag was '5.6'
git checkout -b upstream/latest 5.6
git checkout -b debian/latest
%% init:   'gitGraph':   'mainBranchName': 'master'      %%
gitGraph:
checkout master
commit id: "Upstream 5.6 release" tag: "5.6"
branch upstream/latest
checkout upstream/latest
commit id: "New upstream version 5.6" tag: "upstream/5.6"
branch debian/latest
checkout debian/latest
commit id: "Initial Debian packaging"
commit id: "Additional change 1"
commit id: "Additional change 2"
commit id: "Additional change 3"
At this point, the repository is structured according to DEP-14 conventions, ensuring a clear separation between upstream and Debian packaging changes, but there are no Debian changes yet. Next, add the Salsa repository as a new remote which called origin, the same as the default remote name in git.
shell
git remote add origin git@salsa.debian.org:otto/entr-demo.git
git push --set-upstream origin debian/latest
This is an important preparation step to later be able to create a Merge Request on Salsa that targets the debian/latest branch, which does not yet have any debian/ directory.

Launch a Debian Sid (unstable) container to run builds in To ensure that all packaging tools are of the latest versions, run everything inside a fresh Sid container. This has two benefits: you are guaranteed to have the most up-to-date toolchain, and your host system stays clean without getting polluted by various extra packages. Additionally, this approach works even if your host system is not Debian/Ubuntu.
shell
cd ..
podman run --interactive --tty --rm --shm-size=1G --cap-add SYS_PTRACE \
 --env='DEB*' --volume=$PWD:/tmp/test --workdir=/tmp/test debian:sid bash
Note that the container should be started from the parent directory of the git repository, not inside it. The --volume parameter will loop-mount the current directory inside the container. Thus all files created and modified are on the host system, and will persist after the container shuts down. Once inside the container, install the basic dependencies:
shell
apt update -q && apt install -q --yes git-buildpackage dpkg-dev dh-make

Automate creating the debian/ files with dh-make To create the files needed for the actual Debian packaging, use dh_make:
shell
# dh_make --packagename entr_5.6 --single --createorig
Maintainer Name : Otto Kek l inen
Email-Address : otto@debian.org
Date : Sat, 15 Feb 2025 01:17:51 +0000
Package Name : entr
Version : 5.6
License : blank
Package Type : single
Are the details correct? [Y/n/q]

Done. Please edit the files in the debian/ subdirectory now.
Due to how dh_make works, the package name and version need to be written as a single underscore separated string. In this case, you should choose --single to specify that the package type is a single binary package. Other options would be --library for library packages (see libgda5 sources as an example) or --indep (see dns-root-data sources as an example). The --createorig will create a mock upstream release tarball (entr_5.6.orig.tar.xz) from the current release directory, which is necessary due to historical reasons and how dh_make worked before git repositories became common and Debian source packages were based off upstream release tarballs (e.g. *.tar.gz). At this stage, a debian/ directory has been created with template files, and you can start modifying the files and iterating towards actual working packaging.
shell
git add debian/
git commit -a -m "Initial Debian packaging"

Review the files The full list of files after the above steps with dh_make would be:
 -- entr
   -- LICENSE
   -- Makefile.bsd
   -- Makefile.linux
   -- Makefile.linux-compat
   -- Makefile.macos
   -- NEWS
   -- README.md
   -- configure
   -- data.h
   -- debian
     -- README.Debian
     -- README.source
     -- changelog
     -- control
     -- copyright
     -- gbp.conf
     -- entr-docs.docs
     -- entr.cron.d.ex
     -- entr.doc-base.ex
     -- manpage.1.ex
     -- manpage.md.ex
     -- manpage.sgml.ex
     -- manpage.xml.ex
     -- postinst.ex
     -- postrm.ex
     -- preinst.ex
     -- prerm.ex
     -- rules
     -- salsa-ci.yml.ex
     -- source
       -- format
     -- upstream
       -- metadata.ex
     -- watch.ex
   -- entr.1
   -- entr.c
   -- missing
     -- compat.h
     -- kqueue_inotify.c
     -- strlcpy.c
     -- sys
     -- event.h
   -- status.c
   -- status.h
   -- system_test.sh
 -- entr_5.6.orig.tar.xz
You can browse these files in the demo repository. The mandatory files in the debian/ directory are:
  • changelog,
  • control,
  • copyright,
  • and rules.
All the other files have been created for convenience so the packager has template files to work from. The files with the suffix .ex are example files that won t have any effect until their content is adjusted and the suffix removed. For detailed explanations of the purpose of each file in the debian/ subdirectory, see the following resources:
  • The Debian Policy Manual: Describes the structure of the operating system, the package archive and requirements for packages to be included in the Debian archive.
  • The Developer s Reference: A collection of best practices and process descriptions Debian packagers are expected to follow while interacting with one another.
  • Debhelper man pages: Detailed information of how the Debian package build system works, and how the contents of the various files in debian/ affect the end result.
As Entr, the package used in this example, is a real package that already exists in the Debian archive, you may want to browse the actual Debian packaging source at https://salsa.debian.org/debian/entr/-/tree/debian/latest/debian for reference. Most of these files have standardized formatting conventions to make collaboration easier. To automatically format the files following the most popular conventions, simply run wrap-and-sort -vast or debputy reformat --style=black.

Identify build dependencies The most common reason for builds to fail is missing dependencies. The easiest way to identify which Debian package ships the required dependency is using apt-file. If, for example, a build fails complaining that pcre2posix.h cannot be found or that libcre2-posix.so is missing, you can use these commands:
shell
$ apt install -q --yes apt-file && apt-file update
$ apt-file search pcre2posix.h
libpcre2-dev: /usr/include/pcre2posix.h
$ apt-file search libpcre2-posix.so
libpcre2-dev: /usr/lib/x86_64-linux-gnu/libpcre2-posix.so
libpcre2-posix3: /usr/lib/x86_64-linux-gnu/libpcre2-posix.so.3
libpcre2-posix3: /usr/lib/x86_64-linux-gnu/libpcre2-posix.so.3.0.6
The output above implies that the debian/control should be extended to define a Build-Depends: libpcre2-dev relationship. There is also dpkg-depcheck that uses strace to trace the files the build process tries to access, and lists what Debian packages those files belong to. Example usage:
shell
dpkg-depcheck -b debian/rules build

Build the Debian sources to generate the .deb package After the first pass of refining the contents of the files in debian/, test the build by running dpkg-buildpackage inside the container:
shell
dpkg-buildpackage -uc -us -b
The options -uc -us will skip signing the resulting Debian source package and other build artifacts. The -b option will skip creating a source package and only build the (binary) *.deb packages. The output is very verbose and gives a large amount of context about what is happening during the build to make debugging build failures easier. In the build log of entr you will see for example the line dh binary --buildsystem=makefile. This and other dh commands can also be run manually if there is a need to quickly repeat only a part of the build while debugging build failures. To see what files were generated or modified by the build simply run git status --ignored:
shell
$ git status --ignored
On branch debian/latest

Untracked files:
 (use "git add <file>..." to include in what will be committed)
 debian/debhelper-build-stamp
 debian/entr.debhelper.log
 debian/entr.substvars
 debian/files

Ignored files:
 (use "git add -f <file>..." to include in what will be committed)
 Makefile
 compat.c
 compat.o
 debian/.debhelper/
 debian/entr/
 entr
 entr.o
 status.o
Re-running dpkg-buildpackage will include running the command dh clean, which assuming it is configured correctly in the debian/rules file will reset the source directory to the original pristine state. The same can of course also be done with regular git commands git reset --hard; git clean -fdx. To avoid accidentally committing unnecessary build artifacts in git, a debian/.gitignore can be useful and it would typically include all four files listed as untracked above. After a successful build you would have the following files:
shell
 -- entr
   -- LICENSE
   -- Makefile -> Makefile.linux
   -- Makefile.bsd
   -- Makefile.linux
   -- Makefile.linux-compat
   -- Makefile.macos
   -- NEWS
   -- README.md
   -- compat.c
   -- compat.o
   -- configure
   -- data.h
   -- debian
     -- README.source.md
     -- changelog
     -- control
     -- copyright
     -- debhelper-build-stamp
     -- docs
     -- entr
       -- DEBIAN
         -- control
         -- md5sums
       -- usr
       -- bin
         -- entr
       -- share
       -- doc
         -- entr
         -- NEWS.gz
         -- README.md
         -- changelog.Debian.gz
         -- copyright
       -- man
       -- man1
       -- entr.1.gz
     -- entr.debhelper.log
     -- entr.substvars
     -- files
     -- gbp.conf
     -- patches
       -- PR149-expand-aliases-in-system-test-script.patch
       -- series
       -- system-test-skip-no-tty.patch
       -- system-test-with-system-binary.patch
     -- rules
     -- salsa-ci.yml
     -- source
       -- format
     -- tests
       -- control
     -- upstream
       -- metadata
       -- signing-key.asc
     -- watch
   -- entr
   -- entr.1
   -- entr.c
   -- entr.o
   -- missing
     -- compat.h
     -- kqueue_inotify.c
     -- strlcpy.c
     -- sys
     -- event.h
   -- status.c
   -- status.h
   -- status.o
   -- system_test.sh
 -- entr-dbgsym_5.6-1_amd64.deb
 -- entr_5.6-1.debian.tar.xz
 -- entr_5.6-1.dsc
 -- entr_5.6-1_amd64.buildinfo
 -- entr_5.6-1_amd64.changes
 -- entr_5.6-1_amd64.deb
 -- entr_5.6.orig.tar.xz
The contents of debian/entr are essentially what goes into the resulting entr_5.6-1_amd64.deb package. Familiarizing yourself with the majority of the files in the original upstream source as well as all the resulting build artifacts is time consuming, but it is a necessary investment to get high-quality Debian packages. There are also tools such as Debcraft that automate generating the build artifacts in separate output directories for each build, thus making it easy to compare the changes to correlate what change in the Debian packaging led to what change in the resulting build artifacts.

Re-run the initial import with git-buildpackage When upstreams publish releases as tarballs, they should also be imported for optimal software supply-chain security, in particular if upstream also publishes cryptographic signatures that can be used to verify the authenticity of the tarballs. To achieve this, the files debian/watch, debian/upstream/signing-key.asc, and debian/gbp.conf need to be present with the correct options. In the gbp.conf file, ensure you have the correct options based on:
  1. Does upstream release tarballs? If so, enforce pristine-tar = True.
  2. Does upstream sign the tarballs? If so, configure explicit signature checking with upstream-signatures = on.
  3. Does upstream have a git repository, and does it have release git tags? If so, configure the release git tag format, e.g. upstream-vcs-tag = %(version%~%.)s.
To validate that the above files are working correctly, run gbp import-orig with the current version explicitly defined:
shell
$ gbp import-orig --uscan --upstream-version 5.6
gbp:info: Launching uscan...
gpgv: Signature made 7. Aug 2024 07.43.27 PDT
gpgv: using RSA key 519151D83E83D40A232B4D615C418B8631BC7C26
gpgv: Good signature from "Eric Radman <ericshane@eradman.com>"
gbp:info: Using uscan downloaded tarball ../entr_5.6.orig.tar.gz
gbp:info: Importing '../entr_5.6.orig.tar.gz' to branch 'upstream/latest'...
gbp:info: Source package is entr
gbp:info: Upstream version is 5.6
gbp:info: Replacing upstream source on 'debian/latest'
gbp:info: Running Postimport hook
gbp:info: Successfully imported version 5.6 of ../entr_5.6.orig.tar.gz
As the original packaging was done based on the upstream release git tag, the above command will fetch the tarball release, create the pristine-tar branch, and store the tarball delta on it. This command will also attempt to create the tag upstream/5.6 on the upstream/latest branch.

Import new upstream versions in the future Forking the upstream git repository, creating the initial packaging, and creating the DEP-14 branch structure are all one-off work needed only when creating the initial packaging. Going forward, to import new upstream releases, one would simply run git fetch upstreamvcs; gbp import-orig --uscan, which fetches the upstream git tags, checks for new upstream tarballs, and automatically downloads, verifies, and imports the new version. See the galera-4-demo example in the Debian source packages in git explained post as a demo you can try running yourself and examine in detail. You can also try running gbp import-orig --uscan without specifying a version. It would fetch it, as it will notice there is now Entr version 5.7 available, and import it.

Build using git-buildpackage From this stage onwards you should build the package using gbp buildpackage, which will do a more comprehensive build.
shell
gbp buildpackage -uc -us
The git-buildpackage build also includes running Lintian to find potential Debian policy violations in the sources or in the resulting .deb binary packages. Many Debian Developers run lintian -EviIL +pedantic after every build to check that there are no new nags, and to validate that changes intended to previous Lintian nags were correct.

Open a Merge Request on Salsa for Debian packaging review Getting everything perfectly right takes a lot of effort, and may require reaching out to an experienced Debian Developers for review and guidance. Thus, you should aim to publish your initial packaging work on Salsa, Debian s GitLab instance, for review and feedback as early as possible. For somebody to be able to easily see what you have done, you should rename your debian/latest branch to another name, for example next/debian/latest, and open a Merge Request that targets the debian/latest branch on your Salsa fork, which still has only the unmodified upstream files. If you have followed the workflow in this post so far, you can simply run:
  1. git checkout -b next/debian/latest
  2. git push --set-upstream origin next/debian/latest
  3. Open in a browser the URL visible in the git remote response
  4. Write the Merge Request description in case the default text from your commit is not enough
  5. Mark the MR as Draft using the checkbox
  6. Publish the MR and request feedback
Once a Merge Request exists, discussion regarding what additional changes are needed can be conducted as MR comments. With an MR, you can easily iterate on the contents of next/debian/latest, rebase, force push, and request re-review as many times as you want. While at it, make sure the Settings > CI/CD page has under CI/CD configuration file the value debian/salsa-ci.yml so that the CI can run and give you immediate automated feedback. For an example of an initial packaging Merge Request, see https://salsa.debian.org/otto/entr-demo/-/merge_requests/1.

Open a Merge Request / Pull Request to fix upstream code Due to the high quality requirements in Debian, it is fairly common that while doing the initial Debian packaging of an open source project, issues are found that stem from the upstream source code. While it is possible to carry extra patches in Debian, it is not good practice to deviate too much from upstream code with custom Debian patches. Instead, the Debian packager should try to get the fixes applied directly upstream. Using git-buildpackage patch queues is the most convenient way to make modifications to the upstream source code so that they automatically convert into Debian patches (stored at debian/patches), and can also easily be submitted upstream as any regular git commit (and rebased and resubmitted many times over). First, decide if you want to work out of the upstream development branch and later cherry-pick to the Debian packaging branch, or work out of the Debian packaging branch and cherry-pick to an upstream branch. The example below starts from the upstream development branch and then cherry-picks the commit into the git-buildpackage patch queue:
shell
git checkout -b bugfix-branch master
nano entr.c
make
./entr # verify change works as expected
git commit -a -m "Commit title" -m "Commit body"
git push # submit upstream
gbp pq import --force --time-machine=10
git cherry-pick <commit id>
git commit --amend # extend commit message with DEP-3 metadata
gbp buildpackage -uc -us -b
./entr # verify change works as expected
gbp pq export --drop --commit
git commit --amend # Write commit message along lines "Add patch to .."
The example below starts by making the fix on a git-buildpackage patch queue branch, and then cherry-picking it onto the upstream development branch:
shell
gbp pq import --force --time-machine=10
nano entr.c
git commit -a -m "Commit title" -m "Commit body"
gbp buildpackage -uc -us -b
./entr # verify change works as expected
gbp pq export --drop --commit
git commit --amend # Write commit message along lines "Add patch to .."
git checkout -b bugfix-branch master
git cherry-pick <commit id>
git commit --amend # prepare commit message for upstream submission
git push # submit upstream
The key git-buildpackage commands to enter and exit the patch-queue mode are:
shell
gbp pq import --force --time-machine=10
gbp pq export --drop --commit
%% init:   'gitGraph':   'mainBranchName': 'debian/latest'      %%
gitGraph
checkout debian/latest
commit id: "Initial packaging"
branch patch-queue/debian/latest
checkout patch-queue/debian/latest
commit id: "Delete debian/patches/..."
commit id: "Patch 1 title"
commit id: "Patch 2 title"
commit id: "Patch 3 title"
These can be run at any time, regardless if any debian/patches existed prior, or if existing patches applied cleanly or not, or if there were old patch queue branches around. Note that the extra -b in gbp buildpackage -uc -us -b instructs to build only binary packages, avoiding any nags from dpkg-source that there are modifications in the upstream sources while building in the patches-applied mode.

Programming-language specific dh-make alternatives As each programming language has its specific way of building the source code, and many other conventions regarding the file layout and more, Debian has multiple custom tools to create new Debian source packages for specific programming languages. Notably, Python does not have its own tool, but there is an dh_make --python option for Python support directly in dh_make itself. The list is not complete and many more tools exist. For some languages, there are even competing options, such as for Go there is in addition to dh-make-golang also Gophian. When learning Debian packaging, there is no need to learn these tools upfront. Being aware that they exist is enough, and one can learn them only if and when one starts to package a project in a new programming language.

The difference between source git repository vs source packages vs binary packages As seen in earlier example, running gbp buildpackage on the Entr packaging repository above will result in several files:
entr_5.6-1_amd64.changes
entr_5.6-1_amd64.deb
entr_5.6-1.debian.tar.xz
entr_5.6-1.dsc
entr_5.6.orig.tar.gz
entr_5.6.orig.tar.gz.asc
The entr_5.6-1_amd64.deb is the binary package, which can be installed on a Debian/Ubuntu system. The rest of the files constitute the source package. To do a source-only build, run gbp buildpackage -S and note the files produced:
entr_5.6-1_source.changes
entr_5.6-1.debian.tar.xz
entr_5.6-1.dsc
entr_5.6.orig.tar.gz
entr_5.6.orig.tar.gz.asc
The source package files can be used to build the binary .deb for amd64, or any architecture that the package supports. It is important to grasp that the Debian source package is the preferred form to be able to build the binary packages on various Debian build systems, and the Debian source package is not the same thing as the Debian packaging git repository contents.
flowchart LR
git[Git repository<br>branch debian/latest] --> gbp buildpackage -S  src[Source Package<br>.dsc + .tar.xz]
src --> dpkg-buildpackage  bin[Binary Packages<br>.deb]
If the package is large and complex, the build could result in multiple binary packages. One set of package definition files in debian/ will however only ever result in a single source package.

Option to repackage source packages with Files-Excluded lists in the debian/copyright file Some upstream projects may include binary files in their release, or other undesirable content that needs to be omitted from the source package in Debian. The easiest way to filter them out is by adding to the debian/copyright file a Files-Excluded field listing the undesired files. The debian/copyright file is read by uscan, which will repackage the upstream sources on-the-fly when importing new upstream releases. For a real-life example, see the debian/copyright files in the Godot package that lists:
debian
Files-Excluded: platform/android/java/gradle/wrapper/gradle-wrapper.jar
The resulting repackaged upstream source tarball, as well as the upstream version component, will have an extra +ds to signify that it is not the true original upstream source but has been modified by Debian:
godot_4.3+ds.orig.tar.xz
godot_4.3+ds-1_amd64.deb

Creating one Debian source package from multiple upstream source packages also possible In some rare cases the upstream project may be split across multiple git repositories or the upstream release may consist of multiple components each in their own separate tarball. Usually these are very large projects that get some benefits from releasing components separately. If in Debian these are deemed to go into a single source package, it is technically possible using the component system in git-buildpackage and uscan. For an example see the gbp.conf and watch files in the node-cacache package. Using this type of structure should be a last resort, as it creates complexity and inter-dependencies that are bound to cause issues later on. It is usually better to work with upstream and champion universal best practices with clear releases and version schemes.

When not to start the Debian packaging repository as a fork of the upstream one Not all upstreams use Git for version control. It is by far the most popular, but there are still some that use e.g. Subversion or Mercurial. Who knows maybe in the future some new version control systems will start to compete with Git. There are also projects that use Git in massive monorepos and with complex submodule setups that invalidate the basic assumptions required to map an upstream Git repository into a Debian packaging repository. In those cases one can t use a debian/latest branch on a clone of the upstream git repository as the starting point for the Debian packaging, but one must revert the traditional way of starting from an upstream release tarball with gbp import-orig package-1.0.tar.gz.

Conclusion Created in August 1993, Debian is one of the oldest Linux distributions. In the 32 years since inception, the .deb packaging format and the tooling to work with it have evolved several generations. In the past 10 years, more and more Debian Developers have converged on certain core practices evidenced by https://trends.debian.net/, but there is still a lot of variance in workflows even for identical tasks. Hopefully, you find this post useful in giving practical guidance on how exactly to do the most common things when packaging software for Debian. Happy packaging!

24 May 2025

Julian Andres Klode: A SomewhatMaxSAT Solver

As you may recall from previous posts and elsewhere I have been busy writing a new solver for APT. Today I want to share some of the latest changes in how to approach solving. The idea for the solver was that manually installed packages are always protected from removals in terms of SAT solving, they are facts. Automatically installed packages become optional unit clauses. Optional clauses are solved after manual ones, they don t partake in normal unit propagation. This worked fine, say you had
A                                   # install request for A
B                                   # manually installed, keep it
A depends on: conflicts-B   C
Installing A on a system with B installed installed C, as it was not allowed to install the conflicts-B package since B is installed. However, I also introduced a mode to allow removing manually installed packages, and that s where it broke down, now instead of B being a fact, our clauses looked like:
A                               # install request for A
A depends on: conflicts-B   C
Optional: B                     # try to keep B installed
As a result, we installed conflicts-B and removed B; the steps the solver takes are:
  1. A is a fact, mark it
  2. A depends on: conflicts-B C is the strongest clause, try to install conflicts-B
  3. We unit propagate that conflicts-B conflicts with B, so we mark not B
  4. Optional: B is reached, but not satisfiable, ignore it because it s optional.
This isn t correct: Just because we allow removing manually installed packages doesn t mean that we should remove manually installed packages if we don t need to. Fixing this turns out to be surprisingly easy. In addition to adding our optional (soft) clauses, let s first assume all of them! But to explain how this works, we first need to explain some terminology:
  1. The solver operates on a stack of decisions
  2. enqueue means a fact is being added at the current decision level, and enqueued for propagation
  3. assume bumps the decision level, and then enqueues the assumed variable
  4. propagate looks at all the facts and sees if any clause becomes unit, and then enqueues it
  5. unit is when a clause has a single literal left to assign
To illustrate this in pseudo Python code:
  1. We introduce all our facts, and if they conflict, we are unsat:
    for fact in facts:
        enqueue(fact)
    if not propagate():
        return False
    
  2. For each optional literal, we register a soft clause and assume it. If the assumption fails, we ignore it. If it succeeds, but propagation fails, we undo the assumption.
    for optionalLiteral in optionalLiterals:
        registerClause(SoftClause([optionalLiteral]))
        if assume(optionalLiteral) and not propagate():
            undo()
    
  3. Finally we enter the main solver loop:
    while True:
        if not propagate():
            if not backtrack():
                return False
        elif <all clauses are satisfied>:
            return True
        elif it := find("best unassigned literal satisfying a hard clause"):
            assume(it)
        elif it := find("best literal satisfying a soft clause"):
            assume(it)
    
The key point to note is that the main loop will undo the assumptions in order; so if you assume A,B,C and B is not possible, we will have also undone C. But since C is also enqueued as a soft clause, we will then later find it again:
  1. Assume A: State=[Assume(A)], Clauses=[SoftClause([A])]
  2. Assume B: State=[Assume(A),Assume(B)], Clauses=[SoftClause([A]),SoftClause([B])]
  3. Assume C: State=[Assume(A),Assume(B),Assume(C)], Clauses=[SoftClause([A]),SoftClause([B]),SoftClause([C])]
  4. Solve finds a conflict, backtracks, and sets not C: State=[Assume(A),Assume(B),not(C)]
  5. Solve finds a conflict, backtracks, and sets not B: State=[Assume(A),not(B)] C is no longer assumed either
  6. Solve, assume C as it satisfies SoftClause([C]) as next best literal: State=[Assume(A),not(B),Assume(C)]
  7. All clauses are satisfied, solution is A, not B, and C.
This is not (correct) MaxSAT, because we actually do not guarantee that we satisfy as many soft clauses as possible. Consider you have the following clauses:
Optional: A
Optional: B
Optional: C
B Conflicts with A
C Conflicts with A
There are two possible results here:
  1. A If we assume A first, we are unable to satisfy B or C.
  2. B,C If we assume either B or C first, A is unsat.
The question to ponder though is whether we actually need a global maximum or whether a local maximum is satisfactory in practice for a dependency solver If you look at it, a naive MaxSAT solver needs to run the SAT solver 2**n times for n soft clauses, whereas our heuristic only needs n runs. For dependency solving, it seems we do not seem have a strong need for a global maximum: There are various other preferences between our literals, say priorities; and empirically, from evaluating hundreds of regressions without the initial assumptions, I can say that the assumptions do fix those cases and the result is correct. Further improvements exist, though, and we can look into them if they are needed, such as:

22 May 2025

Dirk Eddelbuettel: RcppArmadillo 14.4.3-1 on CRAN: Small Upstream Bug Fix

armadillo image Armadillo is a powerful and expressive C++ template library for linear algebra and scientific computing. It aims towards a good balance between speed and ease of use, has a syntax deliberately close to Matlab, and is useful for algorithm development directly in C++, or quick conversion of research code into production environments. RcppArmadillo integrates this library with the R environment and language and is widely used by (currently) 1251 other packages on CRAN, downloaded 39.8 million times (per the partial logs from the cloud mirrors of CRAN), and the CSDA paper (preprint / vignette) by Conrad and myself has been cited 628 times according to Google Scholar. Conrad released a minor bugfix version yesterday which addresses corner cases with non-finite values in sparse matrices. And despite conference traveling, I managed to wrap this up and ship it to CRAN where it appeared yesterday. The changes since the last CRAN release are summarised below.

Changes in RcppArmadillo version 14.4.3-1 (2025-05-21)
  • Upgraded to Armadillo release 14.4.3 (Filtered Espresso)
    • Fix for several corner cases involving handling of non-finite elements by sparse matrices

Courtesy of my CRANberries, there is a diffstat report relative to previous release. More detailed information is on the RcppArmadillo page. Questions, comments etc should go to the rcpp-devel mailing list off the Rcpp R-Forge page.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. If you like this or other open-source work I do, you can sponsor me at GitHub.

21 May 2025

Simon Quigley: Fences and Values

Don t knock the fence down before you know why it s up. I repeat this phrase over and over again, yet the (metaphorical) Homeowner s Association still decides my fence is the wrong color.Well, now you get to know why the fence is up. If anyone s actually willing to challenge me on this level, I d welcome it.The four ideas I d like to discuss are this: quantum physics, Lutheranism, mental resilience, and psychology. I ve been studying these topics intensely for the past decade as a passion project. I m just going to let my thoughts flow, but I d like to hear other opinions on this.Can the mysteries of the mind, the subatomic world, and faith converge to reveal deeper truths?When it comes to self-taught knowledge on analysis, I m mostly learned on Freud, with some hints of Jung and Peterson. I ve read much of the original source material, and watched countless presentations on it. This all being said, I m both learned on Rothbard and Marx, so if there is a major flaw in the way of Freud is frowned upon, I d genuinely like to know so I can update my research and juxtapose the two schools of thought.Alongside this, although probably not directly relevant, I m learned on John Locke and transcendentalism. What I d like to focus on here is this the Id.The Id is the pleasure-seeking, instinctual part of the psyche. Jung further extends this into the idea of the shadow self, and Peterson maps the meanings of these texts into a combined work (at least in my rudimentary understanding).In my research, the Id represents the part of your psyche that deals with religious values. As an example, if you re an impulsive person, turning to a spiritual or religious outlet can be highly beneficial. I ve been using references from the foundational text of the Judaeo-Christian value system this entire time, feel free to re-read my other blog posts (instead of claiming they don t exist).Let s tie this into quantum physics. This is the part where I ll struggle most. I ve watched several movies about this, read several books, and even learned about it academically, but quantum physics is likely to be my weak spot here.I did some research, and here are the elements I m looking for: uncertainty principle, wave-particle duality, quantum entanglement, and the observer effect.I already know about the cat in the box. And the Cat in the Hat, for that matter. I know about wave-particle duality from an incredibly intelligent high school physics teacher of mine. I know about the uncertainty principle purely in a colloquial sense. The remaining element I need to wrap my head around is quantum entanglement, but it feels like I m almost there.These concepts do actually challenge the idea of pure free will. It s almost like we re coming full circle. Some theologians (including myself, if you can call me a self-taught one) do believe the idea of quantum indeterminacy can be a space where divine action may take place. You could also liken the unpredictable nature of the Id to quantum indeterminacy as well. These are ones to think about, because in all reality, they re subjective opinions. I do believe they re interconnected.In terms of Lutheranism, I ll be short on this one. Please do go read the full history behind Martin Luther and his turbulent relationship with Catholicism. I m not a Bible thumper, and I actually think this is the first time I ve mentioned religion publicly at all. This being said, now I m actually ready to defend the points on an academic level.The Id represents hidden psychological forces, quantum physics reveals subatomic mysteries, and Lutheranism emphasizes faith in the unseen God. Okay, so we have the baseline. Now, time for some mental resilience. When I think of mental resilience, the first people I think of are David Goggins and Jocko Willink. I ve also enjoyed Dr. Andrew Huberman s podcast.The idea there is simple if you understand exactly how to learn, you know your fundamentals well enough to draw them and explain them vividly on a whiteboard, and you can make it a habit, at that point you re ready to work on your mental resilience. Little by little, gradually, how far can you push the bar towards the ceiling?There s obviously limits. People sometimes get scared when I mention mental resilience, but obviously that s a bit of a catch 22. There are plenty of satirical videos out there, and of course, I don t believe in Goggins or Jocko wholeheartedly. They re just tools in the toolbox when times get tough.I wish you all well, and I hope this gets you thinking about those people who just insist there is no God or higher being, and think you re stupid for believing there is one. Those people obviously haven t read analysis, in my own opinion.Have a great night!

Simon Quigley: AI and what it actually means

A popular topic of public conversation in 2025 is balance. How do we balance budgets, how do we balance entities, and how do we balance perspectives? How do we balance the right of free expression with our ability to effectively convey a message?Here s another popular topic of conversation AI. What is it? What does it do?I m going to give you some resources, as someone who first learned the inner workings of AI about ten years ago.I ll start with the presentation I gave in middle school. Our objective was to give a presentation on a topic of our choice, and we would be graded on our ability to give a presentation. Instead of talking about specific things or events, I talked about the broader idea of fully establishing an artificial form of intelligence.This is the video I used as a basis for that presentation:https://medium.com/media/21d2427a502b7c7cb669220e2e3478c8/hrefNot only did I explain exactly how this specific video game worked, it helped me understand machine learning and genetic algorithms. If I m recalling correctly, the actual title of my presentation had to do with genetic algorithms specifically.In the presentation, I specifically tied in Darwin s readings on evolution (of course, I had to keep it secular ), directly relating the information I learned about evolution in science class into a presentation about what would become AI. But Simon, the title of that video says Machine Learning. Do you have your glasses on?!? Yes, yes I do. It took me a few years to watch this space evolve, as I focused on other portions of the open source world. This changed when I attended SCaLE 21x. At that conference, the product manager for AI at Canonical (apologies if I m misquoting your exact title) gave a presentation on how she sees this space evolving. It s a must watch, in my opinion:https://medium.com/media/a13b2e46fc8acaa3bebf01a7f7bdeebb/hrefThis comprehensive presentation really covers the entire space, and does an excellent job at giving the whole picture.The short of it is this calling everything AI is inaccurate. Using AI for everything under the sun also isn t accurate. Speaking of the sun, it will get us if we don t find a sustainable way to get all that energy we ll need.I also read a paper on this issue, which I believe ties it together nicely. Published in June 2024, it s titled Situational Awareness The Decade Ahead and does an excellent job in predicting how this space will evolve. So far, it s been very accurate.The reason I m explaining this is fairly simple. In 2025, I still don t think many people have taken the time to dig into the content. From many conversations I ve heard, including one I took notes on in an entirely personal capacity, I m finding that not many people have a decent idea for where this space is going.It s been researched! :)If someone can provide a dissent for this view of the artificial intelligence space in the comments, I d be more than happy to hear it. Here s where I think this connects to the average person Many of the open source companies right now, without naming names, are focusing too much on the corporate benefits of AI. Yes, AI will be an incredibly useful tool for large organizations, and it will have a great benefit for how we conduct business over the course of the next decade. But do we have enough balance?Before you go all-in on AI, just do your research, please. Take a look at your options, and choose one that is correctly calibrated with the space as you see it.Lastly, when I talk about AI, I always bring up Orwell. I m a very firm, strong believer in free speech. AI must not be used to censor content, and the people who design your AI stack are very important. Look at which one of the options, as a company, enforces a diversity policy that is consistent with your values. The values of that company will carry over into its product. If you think I m wrong about this point, seriously, go read 1984 by George Orwell a few times over. You ll get the picture on what we re looking to avoid.In short, there s no need to over-complicate AI to those who don t understand it. Use the video game example. It s simple, and it works. Try using that same sentiment in your messaging, too. Appealing to both companies and individual users, together, should be important for open source companies, especially those with a large user base.I wish you all well. If you re getting to the end of this post and you re mad at me, sorry about that. Go re-read 1984 just one more time, please. ;)

20 May 2025

Arturo Borrero Gonz lez: Wikimedia Cloud VPS: IPv6 support

Cape Town (ZA), Sea Point, Nachtansicht Dietmar Rabich, Cape Town (ZA), Sea Point, Nachtansicht 2024 1867-70 2, CC BY-SA 4.0 This post was originally published in the Wikimedia Tech blog, authored by Arturo Borrero Gonzalez. Wikimedia Cloud VPS is a service offered by the Wikimedia Foundation, built using OpenStack and managed by the Wikimedia Cloud Services team. It provides cloud computing resources for projects related to the Wikimedia movement, including virtual machines, databases, storage, Kubernetes, and DNS. A few weeks ago, in April 2025, we were finally able to introduce IPv6 to the cloud virtual network, enhancing the platform s scalability, security, and future-readiness. This is a major milestone, many years in the making, and serves as an excellent point to take a moment to reflect on the road that got us here. There were definitely a number of challenges that needed to be addressed before we could get into IPv6. This post covers the journey to this implementation. The Wikimedia Foundation was an early adopter of the OpenStack technology, and the original OpenStack deployment in the organization dates back to 2011. At that time, IPv6 support was still nascent and had limited implementation across various OpenStack components. In 2012, the Wikimedia cloud users formally requested IPv6 support. When Cloud VPS was originally deployed, we had set up the network following some of the upstream-recommended patterns: In order for us to be able to implement IPv6 in a way that aligned with our architectural goals and operational requirements, pretty much all the elements in this list would need to change. First of all, we needed to migrate from nova-networks into Neutron, a migration effort that started in 2017. Neutron was the more modern component to implement software-defined networks in OpenStack. To facilitate this transition, we made the strategic decision to backport certain functionalities from nova-networks into Neutron, specifically the dmz_cidr mechanism and some egress NAT capabilities. Once in Neutron, we started to think about IPv6. In 2018 there was an initial attempt to decide on the network CIDR allocations that Wikimedia Cloud Services would have. This initiative encountered unforeseen challenges and was subsequently put on hold. We focused on removing the previously backported nova-networks patches from Neutron. Between 2020 and 2021, we initiated another significant network refresh. We were able to introduce the cloudgw project, as part of a larger effort to rework the Cloud VPS edge network. The new edge routers allowed us to drop all the custom backported patches we had in Neutron from the nova-networks era, unblocking further progress. Worth mentioning that the cloudgw router would use nftables as firewalling and NAT engine. A pivotal decision in 2022 was to expose the OpenStack APIs to the internet, which crucially enabled infrastructure management via OpenTofu. This was key in the IPv6 rollout as will be explained later. Before this, management was limited to Horizon the OpenStack graphical interface or the command-line interface accessible only from internal control servers. Later, in 2023, following the OpenStack project s announcement of the deprecation of the neutron-linuxbridge-agent, we began to seriously consider migrating to the neutron-openvswitch-agent. This transition would, in turn, simplify the enablement of tenant networks a feature allowing each OpenStack project to define its own isolated network, rather than all virtual machines sharing a single flat network. Once we replaced neutron-linuxbridge-agent with neutron-openvswitch-agent, we were ready to migrate virtual machines to VXLAN. Demonstrating perseverance, we decided to execute the VXLAN migration in conjunction with the IPv6 rollout. We prepared and tested several things, including the rework of the edge routing to be based on BGP/OSPF instead of static routing. In 2024 we were ready for the initial attempt to deploy IPv6, which failed for unknown reasons. There was a full network outage and we immediately reverted the changes. This quick rollback was feasible due to our adoption of OpenTofu: deploying IPv6 had been reduced to a single code change within our repository. We started an investigation, corrected a few issues, and increased our network functional testing coverage before trying again. One of the problems we discovered was that Neutron would enable the enable_snat configuration flag for our main router when adding the new external IPv6 address. Finally, in April 2025, after many years in the making, IPv6 was successfully deployed. Compared to the network from 2011, we would have: Over time, the WMCS team has skillfully navigated numerous challenges to ensure our service offerings consistently meet high standards of quality and operational efficiency. Often engaging in multi-year planning strategies, we have enabled ourselves to set and achieve significant milestones. The successful IPv6 deployment stands as further testament to the team s dedication and hard work over the years. I believe we can confidently say that the 2025 Cloud VPS represents its most advanced and capable iteration to date. This post was originally published in the Wikimedia Tech blog, authored by Arturo Borrero Gonzalez.

Simon Quigley: Donuts and 5-Star Restaurants

In my home state of Wisconsin, there is an incredibly popular gas station called Kwik Trip. (Not to be confused with Quik Trip.) It is legitimately one of the best gas stations I ve ever been to, and I m a frequent customer.What makes it that great?Well, everything about it. The store is clean, the lights work, the staff are always friendly (and encourage you to come back next time), there s usually bakery on sale (just depends on location etc), and the list goes on.There s even a light-switch in the bathroom of a large amount of locations that you can flip if a janitor needs to attend to things. It actually does set off an alarm in the back room.A dear friend of mine from Wisconsin once told me something along the lines of, it s inaccurate to call Kwik Trip a gas station, because in all reality, it s a five star restaurant. (M , I hope you re well.)In my own opinion, they have an espresso machine. That s what really matters. ;)I mentioned the discount bakery. In reality, it s a pretty great system. To my limited understanding, the bakery that is older than standard but younger than expiry are set to half price and put towards the front of the store. In my personal experience, the vast majority of the time, the quality is still amazing. In fact, even if it isn t, the people working at Kwik Trip seem to genuinely enjoy their job.When you re looking at that discount rack of bakery, what do you choose? A personal favorite of mine is the banana nut bread with frosting on top. (To the non-Americans, yes, it does taste like it s homemade, it doesn t taste like something made in a factory.)Everyone chooses different bakery items. And honestly, there could be different discount items out depending on the time. You take what you can get, but you still have your own preferences. You like a specific type of donut (custard-filled, or maybe jelly-filled). Frosting, sprinkles there are so many ways to make different bakery items.It s not only art, it s kind of a science too.Is there a Kwik Trip that you ve called a gas station instead of a five star restaurant? Do you also want to tell people about your gas station? Do you only pick certain bakery items off the discount rack, or maybe ignore it completely? (And yes, there would be good reason to ignore the bakery in favor of the Hot Spot, I d consider that acceptable in my personal opinion.)Remember, sometimes you just have to like donuts.https://medium.com/media/73f78efd7bd6bb9ce495c2f08428c7d3/hrefHave a sweet day. :)

19 May 2025

Melissa Wen: A Look at the Latest Linux KMS Color API Developments on AMD and Intel

This week, I reviewed the last available version of the Linux KMS Color API. Specifically, I explored the proposed API by Harry Wentland and Alex Hung (AMD), their implementation for the AMD display driver and tracked the parallel efforts of Uma Shankar and Chaitanya Kumar Borah (Intel) in bringing this plane color management to life. With this API in place, compositors will be able to provide better HDR support and advanced color management for Linux users. To get a hands-on feel for the API s potential, I developed a fork of drm_info compatible with the new color properties. This allowed me to visualize the display hardware color management capabilities being exposed. If you re curious and want to peek behind the curtain, you can find my exploratory work on the drm_info/kms_color branch. The README there will guide you through the simple compilation and installation process. Note: You will need to update libdrm to match the proposed API. You can find an updated version in my personal repository here. To avoid potential conflicts with your official libdrm installation, you can compile and install it in a local directory. Then, use the following command: export LD_LIBRARY_PATH="/usr/local/lib/" In this post, I invite you to familiarize yourself with the new API that is about to be released. You can start doing as I did below: just deploy a custom kernel with the necessary patches and visualize the interface with the help of drm_info. Or, better yet, if you are a userspace developer, you can start developing user cases by experimenting with it. The more eyes the better.

KMS Color API on AMD The great news is that AMD s driver implementation for plane color operations is being developed right alongside their Linux KMS Color API proposal, so it s easy to apply to your kernel branch and check it out. You can find details of their progress in the AMD s series. I just needed to compile a custom kernel with this series applied, intentionally leaving out the AMD_PRIVATE_COLOR flag. The AMD_PRIVATE_COLOR flag guards driver-specific color plane properties, which experimentally expose hardware capabilities while we don t have the generic KMS plane color management interface available. If you don t know or don t remember the details of AMD driver specific color properties, you can learn more about this work in my blog posts [1] [2] [3]. As driver-specific color properties and KMS colorops are redundant, the driver only advertises one of them, as you can see in AMD workaround patch 24. So, with the custom kernel image ready, I installed it on a system powered by AMD DCN3 hardware (i.e. my Steam Deck). Using my custom drm_info, I could clearly see the Plane Color Pipeline with eight color operations as below:
 "COLOR_PIPELINE" (atomic): enum  Bypass, Color Pipeline 258  = Bypass
     Bypass
     Color Pipeline 258
         Color Operation 258
             "TYPE" (immutable): enum  1D Curve, 1D LUT, 3x4 Matrix, Multiplier, 3D LUT  = 1D Curve
             "BYPASS" (atomic): range [0, 1] = 1
             "CURVE_1D_TYPE" (atomic): enum  sRGB EOTF, PQ 125 EOTF, BT.2020 Inverse OETF  = sRGB EOTF
         Color Operation 263
             "TYPE" (immutable): enum  1D Curve, 1D LUT, 3x4 Matrix, Multiplier, 3D LUT  = Multiplier
             "BYPASS" (atomic): range [0, 1] = 1
             "MULTIPLIER" (atomic): range [0, UINT64_MAX] = 0
         Color Operation 268
             "TYPE" (immutable): enum  1D Curve, 1D LUT, 3x4 Matrix, Multiplier, 3D LUT  = 3x4 Matrix
             "BYPASS" (atomic): range [0, 1] = 1
             "DATA" (atomic): blob = 0
         Color Operation 273
             "TYPE" (immutable): enum  1D Curve, 1D LUT, 3x4 Matrix, Multiplier, 3D LUT  = 1D Curve
             "BYPASS" (atomic): range [0, 1] = 1
             "CURVE_1D_TYPE" (atomic): enum  sRGB Inverse EOTF, PQ 125 Inverse EOTF, BT.2020 OETF  = sRGB Inverse EOTF
         Color Operation 278
             "TYPE" (immutable): enum  1D Curve, 1D LUT, 3x4 Matrix, Multiplier, 3D LUT  = 1D LUT
             "BYPASS" (atomic): range [0, 1] = 1
             "SIZE" (atomic, immutable): range [0, UINT32_MAX] = 4096
             "LUT1D_INTERPOLATION" (immutable): enum  Linear  = Linear
             "DATA" (atomic): blob = 0
         Color Operation 285
             "TYPE" (immutable): enum  1D Curve, 1D LUT, 3x4 Matrix, Multiplier, 3D LUT  = 3D LUT
             "BYPASS" (atomic): range [0, 1] = 1
             "SIZE" (atomic, immutable): range [0, UINT32_MAX] = 17
             "LUT3D_INTERPOLATION" (immutable): enum  Tetrahedral  = Tetrahedral
             "DATA" (atomic): blob = 0
         Color Operation 292
             "TYPE" (immutable): enum  1D Curve, 1D LUT, 3x4 Matrix, Multiplier, 3D LUT  = 1D Curve
             "BYPASS" (atomic): range [0, 1] = 1
             "CURVE_1D_TYPE" (atomic): enum  sRGB EOTF, PQ 125 EOTF, BT.2020 Inverse OETF  = sRGB EOTF
         Color Operation 297
             "TYPE" (immutable): enum  1D Curve, 1D LUT, 3x4 Matrix, Multiplier, 3D LUT  = 1D LUT
             "BYPASS" (atomic): range [0, 1] = 1
             "SIZE" (atomic, immutable): range [0, UINT32_MAX] = 4096
             "LUT1D_INTERPOLATION" (immutable): enum  Linear  = Linear
             "DATA" (atomic): blob = 0
Note that Gamescope is currently using AMD driver-specific color properties implemented by me, Autumn Ashton and Harry Wentland. It doesn t use this KMS Color API, and therefore COLOR_PIPELINE is set to Bypass. Once the API is accepted upstream, all users of the driver-specific API (including Gamescope) should switch to the KMS generic API, as this will be the official plane color management interface of the Linux kernel.

KMS Color API on Intel On the Intel side, the driver implementation available upstream was built upon an earlier iteration of the API. This meant I had to apply a few tweaks to bring it in line with the latest specifications. You can explore their latest work here. For a more simplified handling, combining the V9 of the Linux Color API, Intel s contributions, and my necessary adjustments, check out my dedicated branch. I then compiled a kernel from this integrated branch and deployed it on a system featuring Intel TigerLake GT2 graphics. Running my custom drm_info revealed a Plane Color Pipeline with three color operations as follows:
 "COLOR_PIPELINE" (atomic): enum  Bypass, Color Pipeline 480  = Bypass
     Bypass
     Color Pipeline 480
         Color Operation 480
             "TYPE" (immutable): enum  1D Curve, 1D LUT, 3x4 Matrix, 1D LUT Mult Seg, 3x3 Matrix, Multiplier, 3D LUT  = 1D LUT Mult Seg
             "BYPASS" (atomic): range [0, 1] = 1
             "HW_CAPS" (atomic, immutable): blob = 484
             "DATA" (atomic): blob = 0
         Color Operation 487
             "TYPE" (immutable): enum  1D Curve, 1D LUT, 3x4 Matrix, 1D LUT Mult Seg, 3x3 Matrix, Multiplier, 3D LUT  = 3x3 Matrix
             "BYPASS" (atomic): range [0, 1] = 1
             "DATA" (atomic): blob = 0
         Color Operation 492
             "TYPE" (immutable): enum  1D Curve, 1D LUT, 3x4 Matrix, 1D LUT Mult Seg, 3x3 Matrix, Multiplier, 3D LUT  = 1D LUT Mult Seg
             "BYPASS" (atomic): range [0, 1] = 1
             "HW_CAPS" (atomic, immutable): blob = 496
             "DATA" (atomic): blob = 0
Observe that Intel s approach introduces additional properties like HW_CAPS at the color operation level, along with two new color operation types: 1D LUT with Multiple Segments and 3x3 Matrix. It s important to remember that this implementation is based on an earlier stage of the KMS Color API and is awaiting review.

A Shout-Out to Those Who Made This Happen I m impressed by the solid implementation and clear direction of the V9 of the KMS Color API. It aligns with the many insightful discussions we ve had over the past years. A huge thank you to Harry Wentland and Alex Hung for their dedication in bringing this to fruition! Beyond their efforts, I deeply appreciate Uma and Chaitanya s commitment to updating Intel s driver implementation to align with the freshest version of the KMS Color API. The collaborative spirit of the AMD and Intel developers in sharing their color pipeline work upstream is invaluable. We re now gaining a much clearer picture of the color capabilities embedded in modern display hardware, all thanks to their hard work, comprehensive documentation, and engaging discussions. Finally, thanks all the userspace developers, color science experts, and kernel developers from various vendors who actively participate in the upstream discussions, meetings, workshops, each iteration of this API and the crucial code review process. I m happy to be part of the final stages of this long kernel journey, but I know that when it comes to colors, one step is completed for new challenges to be unlocked. Looking forward to meeting you in this year Linux Display Next hackfest, organized by AMD in Toronto, to further discuss HDR, advanced color management, and other display trends.

Simon Quigley: Toolboxes and Hammers Be You

Toolboxes and Hammers Be YouEveryone has a story. We all started from somewhere, and we re all going somewhere.Ten years ago this summer, I first heard of Ubuntu. It took me time to learn how to properly pronounce the word, although I m glad I learned that early on. I was less fortunate when it came to the pronunciation of the acronym for the Ubuntu Code of Conduct. I had spent time and time again breaking my computer, and I d wanted to start fresh.I ve actually talked about this in an interview before, which you can find here (skip to 5:02 6:12 for my short explanation, I m in orange):https://medium.com/media/ad59becdbd06d230b875fb1512df1921/hrefI ve also done a few interviews over the years, here are some of the more recent ones:https://medium.com/media/83bda448d5f2a979f848e17f04376aa6/hrefAsk Noah Show 377Lastly, I did a few talks at SCaLE 21x (which the Ubuntu community donation funds helped me attend, thank you for that!):https://medium.com/media/0fbde7ef0ed83c2272a8653a5ea38b67/hrefhttps://medium.com/media/4d18f1770dc7eed6c7a9d711ff6a6e89/hrefMy story is fairly simple to summarize, if you don t have the time to go through all the clips.I started in the Ubuntu project at 13 years old, as a middle school student living in Green Bay, WI. I m now 23 years old, still living in Green Bay, but I became an Ubuntu Core Developer, Lubuntu s Release Manager, and worked up to a very great and comfortable spot.So, Simon, what advice would you give to someone at 13 who wants to do the same thing? Here are a few tips * Don t be afraid to be yourself. If you put on a mask, it hinders your growth, and you ll end up paying for it later anyway.
* Find a mentor. Someone who is okay working with someone your age, and ideally someone who works well with people your age (quick shoutout to Aaron Prisk and Walter Lapchynski for always being awesome to me and other folks starting out at high school.) This is probably the most important part.
* Ask questions. Tons of them. Ask questions until you re blue in the face. Ask questions until you get a headache so bad that your weekend needs to come early. Okay, maybe don t go that far, but at the very least, always stay curious.
* Own up to your mistakes. Even the most experienced people you know have made tons of mistakes. It s not about the mistake itself, it s about how you handle it and grow as a person.Now, after ten years, I ve seen many people come and go in Ubuntu. I was around for the transition from upstart to systemd. I was around for the transition from Unity to GNOME. I watched Kubuntu as a flavor recover from the arguments only a few years before I first started, only to jump in and help years later when the project started to trend downwards again.I have deep love, respect, and admiration for Ubuntu and its community. I also have deep love, respect, and admiration for Canonical as a company. It s all valuable work. That being said, I need to recognize where my own limits are, and it s not what you d think. This isn t some big burnout rant.Some of you may have heard rumors about an argument between me and the Ubuntu Community Council. I refuse to go into the private details of that, but what I ll tell you is this in retrospect, it was in good faith. The entire thing, from both my end and theirs, was to try to either help me as a person, or the entire community. If you think any part of this was bad faith from either side, you re fooling yourself. Plus, tons of great work and stories actually came out of this.The Ubuntu Community Council really does care. And so does Mark Shuttleworth.Now, I won t go into many specifics. If you want specifics, I d direct you to the Ubuntu Community Council who would be more than happy to answer any questions (actually they d probably stay silent. Nevermind.) That being said, I can t really talk about any of this without mentioning how great Mark has become.Remember, I was around for a few different major changes within the project. I ve heard and seen stories about Mark that actually match what Reddit says about him. But in 2025, out of the bottom of my heart, I m here to tell you that you re all wrong now.See, Mark didn t just side with somebody and be done with it. He actually listened, and I could tell, he cares very very deeply. I really enjoyed reading ogra s recent blog post, you should seriously check it out. Of course, I m only 23 years old, but I have to say, my experiences with Mark match that too.Now, as for what happens from here. I m taking a year off from Ubuntu. I talked this over with a wide variety of people, and I think it s the right decision. People who know me personally know that I m not one to make a major decision like this without a very good reason to. Well, I d like to share my reasons with you, because I think they d help.People who contribute time to open source find it to be very rewarding. Sometimes so rewarding, in fact, that no matter how many economics and finance books they read, they still haven t figured out how to balance that with a job that pays money. I m sure everyone deeply involved in this space has had the urge to quit their job at least once or twice to pursue their passions.Here s the other element too I ve had a handful of romantic relationships before, and they ve never really panned out. I found the woman that I truly believe I m going to marry. Is it going to be a rough road ahead of us? Absolutely, and to be totally honest, there is still a (small, at this point) chance it doesn t work out.That being said I remain optimistic. I m not taking a year off because I m in some kind of trouble. I haven t burned any bridge here except for one.You know who you are. You need help. I d be happy to reconnect with you once you realize that it s not okay to do what you did. An apology letter is all I want. I don t want Mutually Assured Destruction, I don t want to sit and battle on this for years on end. Seriously dude, just back off. Please.I hate having to take out the large hammer. But sometimes, you just have to do it. I ve quite enjoyed Louis Rossmann s (very not-safe-for-work) videos on BwE.https://medium.com/media/ab64411c41e65317f271058f56bb2aba/hrefI genuinely enjoy being nice to people. I want to see everyone be successful and happy, in that order (but with both being very important). I m not perfect, I m a 23-year-old who just happened to stumble into this space at the right time.To this specific person only, I tell you, please, let me go take my year off in peace. I don t wish you harm, and I won t make anything public, including your name, if you just back off.Whew. Okay. Time to be happy again.Again, I want to see people succeed. That goes for anyone in Ubuntu, Lubuntu, Kubuntu, Canonical, you name it. I m going to remain detached from Ubuntu for at least a year. If circumstances change, or if I feel the timing just isn t right, I ll wait longer. My point is, I ll be back, the when of it will just never be public before it happens.In the meantime, you re welcome to reach out to me. It ll take me some time to bootstrap things, more than I originally thought, but I m hoping it ll be quick. After all, I ve had practice.I m also going to continue writing. About what? I don t know yet.But, I ll just keep writing. I want to share all of the useful tips I ve learned over the years. If you actually liked this post, or if you ve enjoyed my work in the Ubuntu project, please do subscribe to my personal blog, which will be here on Medium (unless someone can give me an open source alternative with a funding model). This being said, while I d absolutely take any donations people would like to provide, at the end of the day, I don t do this for the money. I do this for the people just like me, out of love.So you, just like me, can make your dreams happen.Don t give up, it ll come. Just be patient with yourself.As for me, I have business to attend to. What business is that, exactly? Read Walden, and you ll find out.I wish you all well, even the person I called out. I sincerely hope you find what you re looking for in life. It takes time. Sometimes you have to listen to some music to pass the time, so I created a conceptual mixtape if you want to listen to some of the same music as me.I ll do another blog post soon, don t worry.Be well. Much, much more to come.
17 May 2025

Daniel Lange: Polkitd (Policy Kit Daemon) in Trixie ... getting rid of "Authentication is required to create a color profile"

On the way to Trixie, polkitd (Policy Kit Daemon) has lost the functionality to evaluate its .pkla (Polkit Local Authority) files.
$ zcat /usr/share/doc/polkitd/NEWS.Debian.gz 
policykit-1 (121+compat0.1-2) experimental; urgency=medium
  This version of polkit changes the syntax used for local policy rules:
  it is now the same JavaScript-based format used by the upstream polkit
  project and by other Linux distributions.
  System administrators can override the default security policy by
  installing local policy overrides into /etc/polkit-1/rules.d/*.rules,
  which can either make the policy more restrictive or more
  permissive. Some sample policy rules can be found in the
  /usr/share/doc/polkitd/examples directory. Please see polkit(8) for
  more details.
  Some Debian packages include security policy overrides, typically to
  allow members of the sudo group to carry out limited administrative
  actions without re-authenticating. These packages should install their
  rules as /usr/share/polkit-1/rules.d/*.rules. Typical examples can be
  found in packages like flatpak, network-manager and systemd.
  Older Debian releases used the "local authority" rules format from
  upstream version 0.105 (.pkla files with an .desktop-like syntax,
  installed into subdirectories of /etc/polkit-1/localauthority
  or /var/lib/polkit-1/localauthority). The polkitd-pkla package
  provides compatibility with these files: if it is installed, they
  will be processed at a higher priority than most .rules files. If the
  polkitd-pkla package is removed, .pkla files will no longer be used.
 -- Simon McVittie   Wed, 14 Sep 2022 21:33:22 +0100
This applies now to the polkitd version 126-2 destined for Trixie. The most prominent issue is that you will get an error message: "Authentication is required to create a color profile" asking for the root(!) password every time you remotely log into a Debian Trixie system via RDP, x2go or the like. This used to be mendable with a .pkla file dropped into /etc/polkit-1/localauthority/50-local.d/ ... but these .pkla files are void now and need to be replace with a Javascript "rules" file. The background to his is quite a fascinating read ... 13 years later:
https://davidz25.blogspot.com/2012/06/authorization-rules-in-polkit.html The solution has been listed in DevAnswers as other distros (Fedora, ArchLinux, OpenSuse) have been faster to depreciate the .pkla files and require .rules files. I amended the solution given there with checking for root to be automatically authenticated, too. So, create a 50-color-manager.rules file in /etc/polkit-1/rules.d/:
polkit.addRule(function(action, subject)
if (action.id.startsWith("org.freedesktop.color-manager.") && (subject.isInGroup("users") (subject.user == "root")))
return polkit.Result.YES;

);
and run systemctl restart polkit. You should be good until polkit is rewritten in Rust.

Next.

Previous.