Search Results: "ema"

5 August 2012

Vasudev Kamath: Rewriting SILPA with Flask microframework

As a introduction on what is SILPA you can read my previous post This application was written by Santhosh about 6-7 years ago in May 2010 2009 ( Correct me if I'm wrong Santhosh ;-) Thanks to Santhosh for correcting me ) in Python without using any web framework. He crafted whole system single handed and with very nice ideas. He wrote all the modules available in it for all possible Indian languages even though he is native Malayalam speaker. I joined him 3 years back and I was providing some or other improvements and he ultimately made me as the Co-Developer of SILPA. Recently I came across the Flask microframework and thought of rewriting SILPA to use Flask. You might ask me why Flask? So here are my reasonings
 1. Why reinvent Python webframework when we can use existing? Besides maintaining a not so well known framework code which is not written by you will be difficult    and time consuming.
 2. All Python modules are useful even outside SILPA project why make them dependent on SILPA code?
 3. Templating system used is very old and can't be ported to new Python version lets use something which is new and portable
 4. If new contributor wanted to add a module he need to understand SILPA framework to write and integrate it. This might be discouraging new
    contributions so lets use pure python module and make integration with SILPA straight forward.
 5. I was overwhelmed by Flask :P
I had previously tried bottle microframework but for some reason I couldn't crack it so choosing of Flask is not because it was better among other available microframework or something like that. I choose it because I could easily understand it and it suited my needs better. So I proposed about this to Santhosh and he asked me for a POC code. I started working on April 8 2012 and today by August 5 I can say I've first stable version of SILPA rewritten using Flask deployable over WSGI on Apache2. It can also be deployed on other servers supporting WSGI interface. It took me quite a bit of time but to be frank in the middle I completely had stopped coding because of some other works. Here is the commit graph and code frequency graphs from Github.

Changes in New Version Here is some major changes in current version.
1. Newly developed framework provides plug and play features for new modules.
2. You need to install the modules which you want to run on it separately using PIP and only minimal code change is required. Only configuration and webbridge.py 
   will be changed. Ofcourse you need to add html file to *templates* folder.
3. This version uses decent routing logic from Flask for page serving.
4. It also provides JSONRPC interface which is compatible with previous version but only with method name changed.
5. This version separates out run time module loading and routing the request to modules.
6. Dynamic module loading now happens only at the beginning of application, so if I want to implement caching for particular services it will be straight forward
   now.
7. Routing requests to proper module is adapted from old version with few modifications
8. All previous pages are now converted to use *Jinja2* template system.
Things Remaining TODO Below is some stuffs still pending before this version can completely replace http://silpa.org.in
1. Separate all modules from original SILPA and get it uploaded to pypi
2. Provide RESTful interface
3. Provide proper LICENSE, AUTHORS file for all modules 
4. Prepare a Nice UI
5. Find a better name than *SILPA*
...
Update
Forgot to provide the github link and demo link for the new version of SILPA. Thanks to Aravinda for pointing
it out. Here it goes
Github: http://github.com/copyninja/Silpa-Flask
Demo: http://flasksilpa-indic.rhcloud.com

4 August 2012

Russell Coker: Love of Technology at First Sight

After seeing the Retina display I ve been thinking about the computer products that I ve immediately desired. Here is the list of the ones I can still remember:
  1. My first computer which was the TEC-1 [1], in 1982 or 1983.
  2. A computer with a full keyboard and a monitor (Microbee), in about 1984. A hex-only keypad is very limiting.
  3. Unix, initially SunOS 4.0 in 1991. Primarily the benefits of this were TCP/IP networking, fast email (no multi-day delay for Fidonet mail), IRC, and file transfer from anywhere in the world. Not inherent benefits to Unix, but at the time only Unix systems did TCP/IP at all well.
  4. OS/2 2.0 in 1992. At the time OS/2 had the best GUI of any system available (IMHO) and clearly the best multitasking of DOS and Windows programs.
  5. Linux in 1992. I started with the TAMU and MCC Interim distributions and then moved to SLS when it was released. The first kernel I compiled was about 0.52. At the time the main use of Linux for almost everyone was to learn about Unix and compile kernels. In 1993 I started running a public access Linux server.
  6. Trinitron monitors in 1996. I first saw an IBM Trinitron monitor when working on an IBM project and had to buy one for home use, at the time a 17 Trinitron monitor beat the hell out of any other display device that one could reasonably afford. A bigger screen allowed me to display more code at once which allowed easier debugging.
  7. Thinkpad laptops from 1998 until now. They just keep working well and seem to be better than other products every time I compare them. I also like the TrackPoint. 1998 was when a Thinkpad dropped to a mere $3,800 for a system that could run with 96M of RAM, enough compute power for the biggest compiles and it cost less than most cars!
  8. The KDE desktop environment in 1998. In 1998 I switched my primary workstation from a PC running OS/2 to a Thinkpad running Linux because of KDE. Prior to KDE nothing on Linux was user-friendly enough.
  9. The iPaQ hand-held PC. I got one in 2002 and ran the Familiar distribution of Linux on it. I had it running SE Linux and used it for writing an article for Linux Journal. Being able to get a computer out on public transport to do some work really saved some time. In some ways the iPaQ hardware and the Familiar OS beat modern Android systems.
  10. The EeePC 701 which I bought in 2008 [2]. In the last 4 years someone has probably released a system that s no larger or heavier and has the same amount of compute power (enough for web browsing, email, and ssh). But most Netbooks that I ve seen don t compete. The EeePC allowed me to take laptops to places where it previously wasn t convenient.
  11. Android, before using Android I never had a smart phone that I used for anything other than taking photos. The other smart phone OSs are either locked down or don t have the app support that Android has. I listed lots of problems with my first phone the Sony Ericsson Xperia X10, but I still really enjoyed using it a lot [3]. Since getting an Android phone I ve read a lot of email while on the go, this means I can respond faster when necessary and use time that might otherwise be wasted. The ssh client means that I don t need to carry a laptop with me when there s a risk that emergency sysadmin work may be required.
  12. Cheap rented servers, Amazon defined cloud computing with EC2, Linode offers great deals for small virtual servers, and Hetzner offers amazing deals on renting entire servers. Getting your own Internet connection or running your own physical server in someone s data-center is a lot of effort and expense. Being able to just rent servers is so much easier and allows so many new projects. I can t remember when I first started using such services, maybe 5 years ago.
  13. The Apple Retina Display [4] a few days ago.
For the period between 1998 and 2008 I can t think of anything that really excited me apart from the iPaQ. Computers became a lot smaller, faster, cheaper, etc. But it was never a big exciting change. The AMD64 architecture wasn t particularly exciting as most systems didn t need more than 4G of RAM and the ones that did could use PAE. What are the most exciting computer products you have seen? Related posts:
  1. Old PDA vs New Mobile Phone for PDA use Since about 2002 I have been using a iPaQ [1]...
  2. CyanogenMod and the Galaxy S Thanks to some advice from Philipp Kern I have now...
  3. Moving from a Laptop to a Cloud Lifestyle My Laptop History In 1998 I bought my first laptop,...

31 July 2012

Russell Coker: The Retina Display

Last night I played with an Apple Macbook Pro with the new Retina Display (Wikipedia link). Wikipedia cites some controversy about whether the display actually has higher resolution than the human eye can perceive. When wearing glasses my vision is considerably better than average (I have average vision without glasses) and while kneeling in front of the Macbook I couldn t easily distinguish pixels. So Apple s marketing claims seem technically correct to me. When I tested the Macbook Pro I found that the quality of the text display was very high, even now the 1680*1050 display on my Thinkpad T61 looks completely crap when compared to the 2880*1800 display on the Macbook. The Macbook was really great for text and for a JPEG that was installed on the system for testing. But unfortunately pictures on web sites didn t look particularly good. Pictures on my blog looked quite poor and pictures returned by a Google search for art didn t look that great either. I wonder if Safari (the Apple web browser) isn t properly optimised for the display or if there is something that we should do when preparing pictures for web sites to make them look better on Safari. The retina display has a 71% greater DPI which means 2.93* the total number of pixels of my Thinkpad. The overall quality of the experience for me (apart from web pictures) seems more like a factor of 2.93 when compared with my Thinkpad than a factor of 1.71. This has to be one of the most desirable products I ve seen from a company that s opposed to freedom for it s users. I m not about to buy one though, $2,300 is a lot of money for a system that can t be upgraded, repaired, or recycled, and doesn t even have an Ethernet port. I m sure that if I bought one I would discover that it some of the hardware features don t work properly with Linux. The new Apple design trend of making it impossible to repair anything works reasonably well for phones and tablets which are cheap enough that they are hardly worth repairing when they have been used for a while. Lots of people can afford to spend about $600 on something that may be discarded after a year or two, but very few people can afford to spend more than $2,000 on such a disposable product. Why is Apple the only company producing systems with such displays? If someone produced regular PCs that have the expected features (including an Ethernet port) with such a display at a lower price then I m sure that there would be a great demand. Related posts:
  1. Modern Laptops Suck One of the reasons why I m moving from a laptop...
  2. A First Digital Camera I ve just been asked for advice on buying a digital...
  3. RPC and SE Linux One ongoing problem with TCP networking is the combination of...

30 July 2012

Johannes Schauer: port bootstrap build-ordering tool report 4

A copy of this post is sent to soc-coordination@lists.alioth.debian.org as well as to debian-bootstrap@lists.mister-muffin.de.

Diary

July 2
  • playing around with syntactic dependency graphs and how to use them to flatten dependencies

July 4
  • make work with dose 3.0.2
  • add linux-amd64 to source architectures
  • remove printing in build_compile_rounds
  • catch Not_found exception and print warning
  • use the whole installation set in crosseverything.ml instead of flattened dependencies
  • detect infinite loop and quit in crosseverything.ml
  • use globbing in _tags file
  • use wildcards and patsubst in makefile

July 5
  • throw a warning if there exist binary packages without source packages
  • add string_of_list and string_of_pkglist and adapt print_pkg_list and print_pkg_list_full to use them
  • fix and extend flatten_deps - now also tested with Debian Sid

July 6
  • do not exclude the crosscompiled packages from being compiled in crosseverything.ml
  • clean up basebuildsystem.ml, remove old code, use BootstrapCommon code
  • clean up basenocycles.ml, remove unused code and commented out code
  • add option to print statistics about the generated dependency graph
  • implement most_needed_fast_wrong as well as most_needed_slow_correct and make both available through the menu

July 7
  • allow to investigate all scc, not only the full graph and the scc containing the investigated package
  • handle Not_found in src_list_from_bin_list with warning message
  • handle the event of the whole archive actually being buildable
  • replace raise Failure with failwith
  • handle incorrectly typed package names
  • add first version of reduced_dist.ml to create a self-contained mini distribution out of a big one

July 8
  • add script to quickly check for binary packages without source package
  • make Debian Sid default in makefile
  • add *.d.byte files to .gitignore
  • README is helpful now
  • more pattern matching and recursiveness everywhere

July 9
  • fix termination condition of reduced_dist.ml
  • have precise as default ubuntu distribution
  • do not allow to investigate an already installable package

July 10
  • milestone: show all cycles in a graph
  • add copyright info (LGPL3+)

July 11
  • advice to use dose tools in README

July 16
  • write apt_pkg based python filter script replacing grep-dctrl

July 17
  • use Depsolver.listcheck more often
  • add dist_graph.ml
  • refactor dependency graph code into its own module

July 18
  • improve package selection for reduced_dist.ml
  • improve performance of cycle enumeration code

July 20
  • implement buildprofile support into dose3

July 22
  • let dist_graph.ml use commandline arguments

July 23
  • allow dose3 to generate source package lists without Build- Depends Conflicts -Indep

July 29
  • implement crosscompile support into dose3

Results

Readme There is not yet a writeup on how everything works and how all the pieces of the code work together but the current README file provides a short introduction on how to use the tools.
  • build and runtime dependencies
  • compile instructions
  • execution examples for each program
  • step by step guide how to analyze the dependency situation
  • explanation of general commandline options
A detailed writeup about the inner workings of everything will be part of a final documentation stage.

License All my code is now released under the terms of the LGPL either version 3, or (at your option) any later version. A special linking exception is made to the license which can be read at the top of the provided COPYING file. The exception is necessary because Ocaml links statically, which means that without that exception, the conditions of distribution would basically equal GPL3+.

reduced_dist.ml Especially the Debian archive is huge and one might want to work on a reduced selection of packages first. Having a smaller selection of the archive would be significantly faster and would also not add thousands of packages that are not important for an extended base system. I call a reduced distribution a set of source packages A and a set of binary packages B which fulfill the following three properties:
  • all source packages A must be buildable with only binary packages B being available
  • all binary packages B except for architecture:all packages must be buildable from source packages A
The set of binary packages B and source packages A can be retrieved using the reduced_dist program. It allows to either build the most minimal reduced distribution or one that includes a certain package selection. To filter out the package control stanzas for a reduced distribution from a full distribution, I originally used a call to grep-dctrl but later replaced that by a custom python script called filter-packages.py. This script uses python-apt to filter Packages and Sources files for a certain package selection.

dist_graph.ml It soon became obvious that there were not many independent dependency cycle situation but just one big scc that would contain 96% of the packages that are involved in build dependency cycles. Therefor it made sense to write a program that does not iteratively build the dependency graph starting from a single package, but which builds a dependency graph for a whole archive.

Cycles I can now enumerate all cycles in the dependency graph. I covered the theoretical part in another blog post and wrote an email about the achievement to the list. Both resources contain more links to the respective sourcecode. The dependency graph generated for Debian Sid has 39486 vertices. It has only one central scc with 1027 vertices and only eight other scc with 2 to 7 vertices. All the other source and binary packages in the dependency graph for the archive are degenerate components of length one. Obtaining the attached result took 4 hours on my machine (Core i5 @ 2.53GHz). 1.5 h of that were needed to build the dependency graph, the other 2.5 hours were needed to run johnson's algorithm on the result. Memory consumption of the program was at about 700 MB. It is to my joy that apparently the runtime of the cycle finding algorithm for a whole Debian Sid repository as well as the memory requirements are within orders of magnitude that are justifiable when being run on off-the-shelf hardware. It must also be noted that nothing is optimized for performance yet. A list of all cycles in Debian Sid up to length 4 can be retrieved from this email. This cycle analysis assumes that only essential packages, build-essential and dependencies and debhelper are available. Debhelper is not an essential or build-essential package but 79% of the archive build-depends on it. The most interesting cycles are probably those of length 2 that need packages that they build themselves. Noticeable examples for these situations are vala, python, mlton, fpc, sbcl and ghc. Languages seem love to need themselves to be built.

Buildprofiles There is a long discussion of how to encode staged build dependency information in source packages. While the initial idea was to use Build-Depends-StageN fields, this solution would duplicate large parts of the Build-Depends field, which leads to bitrot as well as it is inflexible to possible other build "profiles". To remedy the situation it was proposed to use field names like Build-Depends[stage1 embedded] but this would also duplicate information and would break with the rfc822 format of package description files. A document maintained by Guillem Jover gives even more ideas and details. Internally, Patrick and me decided for another idea of Guillem Jover to annotate staged build dependencies. The format reads like:
Build-Depends: huge (>= 1.0) [i386 arm] <!embedded !bootstrap>, tiny
So each build profile would follow a dependency in <> "brackets" an have a similar format as architecture options. Patrick has a patch for dpkg that implements this functionality while I patched dose3.

Dropping Build-Depends-Indep and Build-Conflicts-Indep When representing the dependencies of a source package, dose3 concatenates its Build-Depends and Build-Depends-Indep dependency information. So up to now, a source package could only be compiled, if it manages to compile all of its binary packages including architecture:all packages. But when bootstrapping a new architecture, it should be sufficient to only build the architecture dependent packages and therefor to only build the build-arch target in debian/rules and not the build-indep target. Only considering the Build-Depends field and dismissing the Build-Depends-Indep field, reduced the main scc from 1027 vertices to 979 vertices. The amount of cycles up to length four reduced from 276 to 206. Especially the cycles containing gtk-doc-tools, doxygen, debiandoc-sgml and texlive-latex-base got much less. Patrick managed to add a Build-Depends-Indep field to four packages so far which reduced the scc further by 14 vertices down to 965 vertices. So besides staged build dependencies and cross building there is now a third method that can be applied to break dependency cycles: add Build-Depends-Indep information to them or update existing information. I submitted a list of packages that have a binary-indep and/or a build-indep target in their debian/rules to the list. I also submitted a patch for dose3 to be able to specify to ignore Build-Depends-Indep and Build-Conflicts-Indep information.

Dose3 crossbuilding So far I only looked at dependency situations in the native case. While the native case contains a huge scc of about 1000 packages, the dependency situation will be much nicer when cross building. But dose3 was so far not able to simulate cross building of source packages. I wrote a patch that implements this functionality and will allow me to write programs that help analyze the cross-situation as well.

Debconf Presentation Wookey was giving a talk at debconf12 for which I was supplying him with slides. The slides in their final version can be downloaded here

Future Patrick maintains a list of "weak" build dependencies. Those are dependencies that are very likely to be droppable in either a staged build or using Build-Depends-Indep. I must make use of this list to make it easier to find packages that can easily be removed of their dependencies. I will have to implement support for resolving the main scc using staged build dependencies. Since it is unlikely that Patrick will be fast enough in supplying me with modified packages, I will need to create myself a database of dummy packages. Another open task is to allow to analyze the crossbuilding dependency situation. What I'm currently more or less waiting on is the inclusion of my patches into dose3 as well as a decision on the buildprofile format. More people need to discuss about it until it can be included into tools as well as policy. Every maintainer of a package can help making bootstrapping easier by making sure that as many dependencies as possible are part of the Build-Depends-Indep field.

29 July 2012

Gregor Herrmann: RC bugs 2012/27-30

during the last weeks I was quite busy with other things (like DebCamp, DebConf, & vacations), so this is a report covering 4 weeks. at least I managed to catch up during the last days a bit

Jordi Mallach: GUADEC 2012

I've been in A Coru a for this year's GUADEC since Tuesday night, and it rocked. I did a late registration after my first week at Collabora, which is sponsoring my stay here.
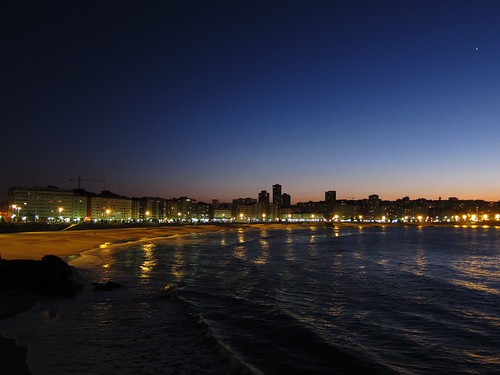
I came one day early to participate, as Debian's representative, at the yearly GNOME Advisory Board meeting, for the first time. It was a positive experience, which helped me get a grasp of the big picture of what the GNOME Foundation does. I also had the pleasure of visiting Igalia's awesome offices in the city, and puting faces to many names during the meeting. I presented an overview of Debian's relation to GNOME, how our packaging team works and what are our goals and biggest problems as a GNOME downstream. We stirred some good debate as some other Advisory Board members share part of our problems. I should be posting a summary of what happened there for debian-project@ldo as soon as I have the time to scribble it. I've met with GNOME Hispano people I hadn't seen since 2004 or 2006 in the best case, and catched up with many of them. I've also met many GPUL members I had know for over a decade via IRC, but never had met in person, and it was about time. And of course, I've got to known a good number of my new workmates at Collabora, and had fun with them around the conference, the beach and the numerous post-conference events. Last, but not least, I ended up participating in the GNOME Olympics, substituting Rodrigo in Team B Core Dumped , along with Stefano, John, Bastien, Chema and Adam. WE WON, not thanks to me, but the statistics shine: I've won all FreeFA World Cups I've played :P so here's a PROtip: if you want to win next year, be sure to be my team mate, and more importantly, be sure Adam is not your rival. :) Unfortunately, I'm only attending the core days so tonight I'll be flying back to Madrid on my way home in Val ncia. See you next year! A Coru a is a city that has impressed me quite a bit, and I'm looking forward to coming back for some more standard vacation at some point. :)

28 July 2012

John Goerzen: How to get started programming?

I have been asked for advice from several people recently on how to get started programming, or how to further develop a nascent interest in coding or software engineering. The people asking the questions range in age from about 10 years old to older than me. These are people that, for various reasons, are not very easily able to take computer science courses right now. One would think that, since I ve been doing this for somewhere around a quarter century (oh I do feel old now), that I d be ready to offer up some great advice. And offer some suggestions I have. But I m not convinced they re good ones. I have two main tensions. The first is that I, like many in the communities I tend to hang out in such as Debian s, have a personality that leads me to take a deep dive into details of anything that holds my interest. Whether it s Linux, Haskell, or amateur radio, I want to do more than skim the surface if I m having fun with it. Many people are not like that. They may have a lot of fun programming in Visual Basic, not really caring that other languages are out there. Or some people are not like this yet. I feel unqualified to provide good advice to people that are different from me in that way. To put it a different way: most people don t want to wait 4 years to be useful, and want to start out right away and get better over time (and I was the same way too.) The second is related. I learned programming at a time when, other than BASIC, interpreted languages were not really available to me. (Yes, they were available, but not to me.) I cut my teeth on BASIC, Pascal, and C. Although I rarely use C anymore, I can still drop into it at a moment s notice and be perfectly comfortable. I feel it was a fundamentally valuable experience, and that it would be very hard to become a great programmer without ever having lived and breathed something like C, where memory and pointers must be managed manually. Having said that, it is probably possible to become a good coder without ever having touched C. Here, then, is an edited version of some rambly advice I sent to someone recently, where learning OOP was particularly mentioned. I would welcome your comments and suggestions. I may point people that ask to this post in the future. For simply learning how to write code, Dive Into Python has long been a decent resource, though it may assume more experience than some have. I haven t read them myself, but I ve also heard good things about the How to Think Like a Computer Scientist series from Green Tea Press. They re all available as free PDF downloads, too! Eric S. Raymond s The Art of Unix Programming is another work I ve heard good things about, despite having never read it myself. A quick glance at the table of contents makes me think that even if people don t wind up working on Unix, the lessons and philosophy should be informative. It seems that many Computer Science programs are using Java for the core of their instruction, or even almost exclusively. Whether that is good or bad, I m not completely sure. It certainly gets people into OOP more deeply, but I m a right tool for the job kind of person. Despite the hype, OO like everything else isn t the right tool for every job. It is fine for people to dive straight into OO and become good programmers/engineers. However, I think it would be difficult to become a great programmer/engineer without ever having a solid understanding of a more low-level language, such as C in particular. I did my CS work when it was mostly based in C, and am glad for it. If someone never has to manage memory or pointers, I suspect they will be at a disadvantage in the long run for not being able to understand or work with the system at a more fundamental level. If a person knows C, plus some concepts of OO and Functional Programming (FP), it should be easy to pick up just about any other language out there. I used to think Python was a great first language, but during the 2.x series they added so much fluff and so many special cases that I m less enthusiastic now, though I don t know how much of that got cleaned up in 3.x. I am not too keen on Java as a first language, because too many things that should be simple aren t. I have a fondness for Haskell, and its close relationship to mathematics could make it a great first language or maybe a poor one, depending on your perspective. One other thing I think it s important for good programmers to have experience with all three major models of programming (procedural, OO, functional.) Even if a person winds up working mostly in one universe, knowledge of and experience with the others is important and informative and, in my experience, leads to better algorithms and architecture all around.

Alberto Garc a: GUADEC 2012

Third day of GUADEC already. And in Coru a! Coru a This is a very special city for me. I came here in 1996 to study Computer Science. Here I discovered UNIX for the first time, and spent hours learning how to use it. It s funny to see now those old UNIX servers being displayed in a small museum in the auditorium where the main track takes place. It was also here where I learnt about free software, installed my first Debian system, helped creating the local LUG and met the awesome people that founded Igalia with me. Then we went international, but our headquarters and many of our people are still here so I guess we can still call this home. So, needless to say, we are very happy to have GUADEC here this time. I hope you all are enjoying the conference as much as we are. I m quite satisfied with how it s been going so far, the local team has done a good job organising everything and taking care of lots of details to make the life of all attendees easier. I especially want to stress all the effort put into the network infrastructure, one of the best that I remember in a GUADEC conference. At Igalia we ve been very busy lately. We re putting lots of effort in making WebKit better, but our work is not limited to that. Our talks this year show some of the things we ve been doing: We are also coordinating 4 BOFs (a11y, GNOME OS, WebKit and Grilo) and hosted a UX hackfest in our offices before the conference. And we have a booth next to the info desk where you can get some merchandising and see our interactivity demos. WebKitGTK+ In case you missed the conference this year, all talks are being recorded and the videos are expected to be published really soon (before the end of the conference). So enjoy the remaining days of GUADEC, and enjoy Coru a! And of course if you re staying after the conference and want to know more about the city or about Galicia, don t hesitate to ask me or anyone from the local team, we ll be glad to help you. Queimada
Martin-&#201;ric Racine: OpenWRT: SLAAC and DHCPv6 on White Russian

As I recently reported, I have been trying to configure my Linksys WRT54GL running the OpenWRT firmware (version 0.9 a.k.a. White Russian) to support SLAAC and DHCPv6 out of the box.Most of the feedback I got involved upgrading the OpenWRT firmware to a more recent release that might not fit the available storage capacity of the device, which felt like too risky of an operation to attempt.The solution I found instead involved adding ipkg sources to OpenWRT's backports repository, which offers a minimalistic DHCPv6 client. Although I haven't been able to find any proper documentation for this client, the content of its configuration file is mostly intelligible. What remains now is to actually configure it to cooperate with the kernel's native SLAAC implementation and, whenever an IPv6 network is found on the ISP side, to propagate the address space, DNS and routing information to my LAN using radvd.Would anyone located within the Helsinki metropolitan area happen to have an IPv6 testing environment that would at least allow me to configure and test my router?

Luke Faraone: Google Cr-48 first impressions

On a lark, I signed up for the pilot program of the Google Cr-48 about a week ago. To my surprise, I found the distinctive box on my doorstep a week later. After initially mistaking it for an overpacked, late-model OLPC XO-1 I would have to repair, I sort of did a double-take as I realized what I had received.
Using Chrome OS


Wow, they weren't kidding about the boot time. Chrome OS responds (to suspend / resume and boot / power-off) very quickly. Responsiveness elsewhere in the OS of course varies on system load and other factors. On the "terms" page, there is a "system security setting" which tells me I have a Trusted Platform Module, and that my TPM has a randomly generated password. The dialog could use some rewording; I'm pretty familiar with the idea of a TPM, but I'm still not sure what I'm to do with that information.

Cloud print is really a problem for me, right now. I use school printers for the majority of my work, which I was previously able to use by adding them by IP address. Unless there's some magic I'm missing here, I can't do that with Chrome OS, and such a feature will not be supported. (except by "connectors" on Windows and Mac computers)
General thoughts
I can't imagine using a system running Chrome OS as a primary computer. The biggest missing feature is PGP (or any sort of encryption) support for email. This is probably not terribly difficult to implement as an extension, but the idea of my cryptographic software being automatically updated is rather unsettling. I think I'll have to agree with Paul Buchheit that ChromeOS will have to merge with Android; there is a utility for local apps, even if they're becoming less and less critical.

25 July 2012

Vincent Sanders: Fowlers Delight?

Fowler published his paper on Continuous Integration (CI) way back in 2000. Personally at the time I was a much more naive developer, I was not really an adherent to the whole XP community and had worked for a series of companies where the idea of a release build was of a month long process and the concept that the whole codebase could be built and tested on every commit was a comical notion at best.

By the time the time the 2006 edition of the paper came out however I was convinced. Ever since then I have tried to make the projects I worked on have as many CI features as possible. It is one reason I ran the ARM Kernel autobuilder for years as an attempt to provide at least build coverage.

I especially like the way these concepts mean that releases are much less "scary" events and release anxiety is reduced to a minimum. When every commit produces something that is of release quality a project really is doing it right.

The reason I mention any of this is I have recently set up the NetSurf projects CI server. The heavy lifting is being done by a Jenkins instance running on a VPS fulfilling the "Every Commit Should Build the Mainline on an Integration Machine" part of the Fowler guidelines.

Setting up Jenkins was much less trouble than many of the previous systems I have used. I have been a little underwhelmed by the support for plain old make based projects which you have to resort to shell scripts for, but leaving that aside the rest was straightforward. The documentation could do with a purge pass for the old hudson name and the error reporting (especially under memory pressure) is not great.

And there lies my one real issue with the tool, memory. The VPS has 512MByte RAM and runs nothing beyond a web server, jenkins and the C compiler to build the project components. One would hope that was plenty of memory, doing the builds by hand it did seem gcc is happy in that space, alas Jenkins is a Java application and guzzles RAM (over 60% of RSS right now) and causes itself out of memory exceptions with distressing frequency.

The project is left with the choices:
It is such a pity too, aside from the RAM issues it is all going well and it has already encouraged us to get the toolchains for the less commonly built targets (ppc amiga and windows for a start) working.

24 July 2012

Gunnar Wolf: Ten theses in favor of free download of cultural goods on the Internet (by Enrique G. Gallegos)

This is one of the days where reading my everyday newspaper was worth more than just getting bitter at the news. I found this text in La Jornada, my usual newspaper. I liked it very much, and decided to translate it for a wider audience. Of course, if you can read Spanish, do yourself a favor and go to the original. It is not that the text is so easy to translate. And, after all, I'm not a native English writer. I'm trying to do a literal translation, even when disagreeing with the author. Ten theses in favor of free download of cultural goods on the Internet Enrique G. Gallegos Poet and philosopher. Currently a researcher in Universidad Aut noma Metropolitana-C
  1. Historical legacy. Criticists who promote the persecution of piracy and free downloads of cultural works from the Internet argue that the patrimonial rights have been wronged; they start off suposing that a cultural work is formed from a historical void, as if there was a "nothing" to begin with, and then a "something" appeared. Nothing more fallacious: All cultural products has its precedents, and thanks to these it generates part of its best forces.
  2. Opening towards the future. Human beings are projected into the future. As the main philosophies of the 20th century have explored, one of the singular characteristics of mankind is the ability to think and imagine the future. Products of culture are the best ways to think and project society, politics, love, hope, needs, failures A song, a poem, an essay, can trigger imaginary worlds with a transformative potential. To deny this to humanity with "patrimonial damage" as an argument is to mutilate man's temporal nature.
  3. Recognition of the present. Cultural works generate moments of reflection, criticism and pleasure; they can trigger actions demanding commitment, solidarity and strong indignation against injustice. If every cultural work is adscribed in some way to a historic tradition, and if cultural products anre necessary to imagine other possible worlds and open our future, it's not less true that they also allow us to recognize our present by making us more sensitive to others' ideas, sensations and emotions. Without culture, there is no present nor others' presence.
  4. Divulgation of the cultural heritage. If culture is "heritage of mankind", it should be also spread by any possible way. But not just spread, but actively sought for the biggest number of people to be able to effectively have access to it. In a potentially interconnected world, Internet is the most adequate world for it (despite its limitations). Therefore, penalizing free downloads means avoiding spreading it and restricting access to those groups who don't have enough economic resources.
  5. Preserving cultural heritage. If we agree that cultural works are heritage of mankind, we need to take every action needed to preserve them. But preserving culture does not only mean keeping the products in museums, galleries or never-polluted drawers; it rather means to keep them in the collective memory and in the flow of constant interpretations and appropiations. Said in other words, the genuine way to preserve culture is to allow universal access to cultural goods. That's why, holding that free copies and downloads of books, music, videos, etc. over the Internet are harmful, is an incompatible argument with the obligation to preserve cultural heritage.
  6. They are not goods. Cultural works are material and spiritual manifestations of mankind, concretions of its historicity; they are, also, expressions of emotions, ideas and projections of other lives and other worlds. That's why they cannot be equated to goods or inserted in patrimonialist logic. The market might want to cheat by giving a certain price to a painting by Orozco or auctioning a Baudelaire manuscript, but it will never be able to aprehend their true meaning as cultural works. And it's not that culture is not faluable, but taht its estimation criteria do not follow the rules of market, but those of the imponderable and unlimited.
  7. Price disproportion. Assuming we accept the possibility that intermediaries charge for the services they perform, the value of a book, record or movie should never exceed the daily wage of a worker or employee. But this ellection would only be one more option within the effective possibility that people opt to download or freely copy the cultural work. The final decision as to which media to go to should be a sovereign resolution of the culture-interested person.
  8. The principle of the most benefit. Even when copies and free downloads over Internet could generate a patrimonial "wrong" to third parties, the cultural benefit obtained by it will always be greater in as much that it carries out intensely the principle to foster, spread and access the cultural heritage of mankind. To think otherwise is to privilege the few over the many.
  9. The real evil is elsewhere. Murder, women- and children-trade, poverty and misery are the real evils that ache mankind. According to the United Nations, in 2010 there were 468 thousand murders in the world; the estimation is that 3500 million people live in poverty; in their 2009 inform, the UN found over 2400 victims of "people trade", kidnapped as sex slaves; in some regions in Africa, close to 30% of children suffer acute malnutrition and six people (between children and adults) die every day from hunger. That's why pretending that free download of cultural works is an evil is clearly a tricky and deceptive speech
  10. Against the intermediary-salesman. Culture does not need intermedieries that reduce cultural works to goods. Culture is too important to leavie it in the hands of salespeople that simplistly equate cultural goods with cakes. An intermediary of this kind will never understand the difference between a work of art and a disposable razor blade. What the world needs is more support from the government from every country to artists, creators and poets, as well as ensuring the conditions for the absolute mobility freedom for cultural works.

Julien Danjou: Emacs configuration published

I've finally published my Emacs configuration. This took me a while, since I had personal information inside (like passwords). Recently, I've been able to move them away and can now publish everything in my Git repository. It's probably not yet usable from scratch, since I didn't include the bootstrap code for el-get. But you can at least lurk and grab some ideas or lines of code. And do not hesitate to ask me anything about it! Note that I'm using Emacs development version (trunk), so it's possible that some things do not work with (old) released Emacs versions.

Wouter Verhelst: DebConf 12 is over :(

As I write this, DebConf12 has actually been over for more than a week. Usually during DebConf, I'm a more proficient blogger than during other times of the year, since I'm not doing as much work that I have to remain quiet about at that time, which simply means I have more to blog about. Unfortunately, however, this year the server on which this blog runs managed to become unavailable on the second day of DebCamp, an issue that I could only fix once I was back in Belgium, which meant I haven't been able to blog as much as I would've wanted to. Anyway, all I can say is that both DebConf and DebCamp have been a huge success for me again, this year. I'd started the second rewrite of ipcfg a few weeks before DebCamp, and spent most of DebCamp whipping the basic framework into shape. It's nowhere near ready yet, but I'm confident it'll get further this time than it did before. During DebConf, I was also responsible for doing the group photo. I'd done that (together with Andrew McMillan) during DebConf8 before (if you look closely, you'll see me pressing the remote which actually triggers that picture), and I still like that picture. This time around, we didn't have a beach nearby (at least not as nearby as during DebConf8), so we had to do things slightly differently. Rather than doing one large picture, I took several pictures and used Hugin to stitch them together. Unfortunately however, some things did go wrong with the group photo. For starters, the weather wasn't very helpful, in that I noticed it was about to rain. As such, the main bunch of pictures were taken slightly before the announced time of 14:30, which meant that some people had missed it. To make matters worse, I had rushed to the group and handed the camera to someone else, so that I could gimp myself onto the picture too; but that meant that some people who were arriving as these pictures were being taken thought they were on the picture, when they really weren't. I've fixed most of these by just gimping them into the picture as well, but I might've missed some of them. If you're one of them, talk to me! Preferably now. If you're not one of them (or even if you are), hold off on doing things like printing it in large format or some such. I'll re-upload improved versions onto the same location once they're ready.

23 July 2012

Michal &#268;iha&#345;: Weblate hacking #1

The first day of Hackweek VIII is about to end for me and it's time to share some of the results. As planned, I've started hacking on Weblate. The most prominent feature from today are email notifications. You can now monitor the translation in various ways - be informed about new strings to translate, new contributor, added suggestion or simply watch all translations. Another bigger change is rearranging of main page, which now provides instant access to per language stats, which were quite hidden before. Rest of time was spent on adding some sort of spam protection (need to deploy this to demo to see how successful it is) and one more promoting widget (88x31 pixels). There are 6 open issues targeted for 1.2 release, so there is still something to do in next days :-).

Filed under: English Suse Weblate 0 comments Flattr this!

22 July 2012

Steve Kemp: Another day, another upgrade

Tonight I upgraded my personal machine to run the recently released 3.5[.0] kernel. On my personal machine(s) I'm usually loathe to change a running kernel, but this one was a good step forward because it allows me to experiment with seccomp filters. I've tested the trivial "no new privileges" pctl and I followed along with the nice seccomp tutorial which gave me simple working code which I married to my javascript interpreter. On top of that I upgraded node.js, which meant I had to clean up a little depreciated code in my node reverse proxy - which is the public face of the websites I run upon my box. (The proxy tunnels to about 10 different thttpd instances, each running upon 127.0.0.1:xx). Happily however my weekend was not full of code, it was brightened by the opportunity to take pictures of Aurora and her long hair - more to come as I've still got about 350 images to wade through.. ObQuote: "Don't you think I make a remarkable queen? " - St. Trinian's (2007)

Mark Brown: regmap updates in 3.5

A surprisingly large series of updates for regmap this time, mostly due to all the work Stephen Warren has done to add support for MMIO buses. This wasn t really the target for the framework but it turns out that there s a reasonable number of cases where it s very helpful to use the register cache support to allow the register map to remain available while the device is suspended.

21 July 2012

Andrew Pollock: [debian] New audit package in experimental

Various security folks at work have been keen on a newer version of audit be in Ubuntu (preferably 12.04), but unfortunately the Debian maintainer has been too busy to package it for Debian, so I finally carved out some time recently to do an upload to experimental, with his permission. It would have been really nice to land it in unstable before Wheezy froze, but as it involved a library transition, and I didn't get a chance to talk to the release team about it until very close to the freeze, they said it was too late. That meant the grand plan of getting it into Ubuntu 12.10 and then trying to get it into precise-backports went up in smoke as well. Oh well. It was a fair bit of work to package. A lot of the patches were no longer relevant, and the remaining ones all needed to be refitted. It was also my first attempt at touching a library package where a SONAME bump was involved. I think I did everything correctly.

Julien Danjou: ERC notifications

Today, I've merged my erc notifications module inside Emacs trunk. This way, it will be available for everybody in Emacs 24.2. erc-notifications example This module allows you to be notified via notifications-notify (the Emacs implementation of the Freedesktop desktop notifications) on private message received on IRC, or when your nickname is mentioned on a channel. To enable it in Emacs > 24.1, you just have to add the following line to your configuration file:
(add-to-list 'erc-modules 'notifications)
If you want to download it and use it stand-alone for a previous Emacs version, you can fetch the latest file revision and load it before adding the previously given line.

17 July 2012

Luciano Bello: there is no cabal.. but, what s a cabal?

In my long trip to Nicaragua I made progress in my reading: Quicksilver, by Neal Stephenson. In the Spanish edition the title is Azogue. But I m assuming that you are not a Spanish speaker. Here is a small fragment (in English) I found there:
You must remember that the planters are short-sighted. They re all desperate to get out of Jamaica they wake up every day expecting to find themselves, or their children, in the grip of some tropical fever. To import female Neegers would cost nearly as much as to import males, but the females cannot produce as much sugar particularly when they are breeding. Daniel had finally recognized this voice as belonging to Sir Richard Apthorp the second A in the CABAL.
It s a bit embarrassing when I discovered myself realizing where the word cabal comes from. And I m posting this as a head-up for everyone who know there is no cabal in Debian; but they don t know which is the origin of the word cabal. Stephenson changed the name of the historic cabal, a group of high councillers of King Charles II of England, Scotland and Ireland, in 1668. In the novel, they are: John Comstock (Earl of Epsom), Louis Anglesey (Duke of Gunfleet), Knott Bolstrood (Count Penistone), Sir Richard Apthorp and Hugh Lewis (Duke of Tweed). In the real world they had been:
Thomas Clifford, 1st Baron Clifford of Chudleigh (1630-1673). Henry Bennet, 1st Earl of Arlington (1618-1685). George Villiers, 2nd Duke of Buckingham (1628-1687). Anthony Ashley Cooper, 1st Baron Ashley of Wimborne St Giles (1621-1683). John Maitland, 1st Duke of Lauderdale (1616-1682).
This group shared the effective power in a royal council rather than the King.

Next.

Previous.