Search Results: "cas"

19 June 2013

Julien Viard de Galbert: Building a custom debian CD

The French version is available on linuxembedded.fr : Cr e un CD d installation d une debian sp cialis e The goal is to build a debian install CD suitable for the distribution of a complete system including the operating system and applications. Debian already has a tool for that purpose: simple-cdd. Simple-cdd is a set of scripts wrapping debian-cd which is the tool used to build official CDs. In our case, we will include some non-free packages (firmwares for instance) and application specific packages in the system. Using simple-cdd Simple-cdd gets some of its configuration from your host computer, so it s recommended to work on a machine similar to your target (in particular the machine should use the same architecture: i386 or amd64). All the following actions should be done in a working directory that will contain the downloads and configurations for our system. We will start by creting a configuration file my-cdd.conf stating the mirror and components to use:
debian_mirror="http://ftp2.fr.debian.org/debian/"
mirror_components="main contrib non-free"
Then we will launch the build-simple-cdd tool once. This will build a local mirror of the needed packages that we will reused later. So be patient this can be a bit long.
build-simple-cdd --conf ./my-cdd.conf
Once done, you should get a CD iso in the images subfolder. Customizing the image To customize our image we will create a profile my-profile that will define which package to install and which extra package to include on the CD (dev packages for instance). Create a profiles folder:
mkdir profiles
Selecting the packages If you ve got an already installed machine (the one you used to test your application) you can ask dpkg to list the installed packages from that machine and use that as a basis.
dpkg --get-selections >package-list
In this file only the names of packages in the install state are needed:
grep -e '\<install$' package-list   awk ' print $1 ;' >profiles/my-profile.downloads
The file my-profile.downloads is a list of packages to include on the CD-ROM. The list of program to install is my-profile.packages . The tool will resolve dependencies, so we don t need to track down all dependencies add add them to these files. Specific packages We want to add some custom packages that we built ourselves to the CD, those packages not present in the debian archive. Let s create a local_pkg folder and fill it with all of our packages. We now can update the configuration to use all those files and make the profile my-profile the default profile.
debian_mirror="http://ftp2.fr.debian.org/debian/"
mirror_components="main contrib non-free"
simple_cdd_dir=$(pwd)
profiles="my-profile"
auto_profiles="my-profile"
local_packages="$simple_cdd_dir/local_pkg/"
If you now run the tool again, you ll get a full custom install CD!
build-simple-cdd --conf ./my-cdd.conf
However you might have missed some specific packages or their dependencies, in that case they will be missing on the CD. To find this out, check the messages for a line like:
WARNING: missing optional packages from profile my-profile: libevent-2.0-5 [...]
In that case libevent from squeeze-backports was missing. Simple-cdd is not able to download packages from backports, so I just added the packages to local_pkg . Customizing the installer Simple-cdd automatically uses a default profile. This profile might not suite your needs. To override it you just have to place modified file in the profiles folder. To do so, first copy the desired file from /usr/share/simple-cdd/profiles/ and update it. For instance the default.pressed file:
cp /usr/share/simple-cdd/profiles/default.pressed profiles
Then update the wanted options in this file. For example the partitioning options. Also as we enabled contrib and non-free you should uncomment the following lines:
d-i apt-setup/non-free  boolean true
d-i apt-setup/contrib boolean true
Adding extra files to the CD Finally we want to add the documentation, sources and other files to the CD. Simple-cdd can add files to the simple-cdd folder but there is no way to add a complete directory structure. However, as we can override the profiles, we can also override some scripts, especially tools/build/debian-cd that builds the CD.
mkdir -p tools/build
cp /usr/share/simple-cdd/tools/build/debian-cd tools/build
Then add the following lines after the $extras_base_dir cleanup:
if [ -d "$cd_extras" ]; then
  mkdir -p "$extras_base_dir"
  cp -a "$cd_extras/." "$extras_base_dir"
fi
Finally let s add the cd_extras variable to our configuration file :
cd_extras="$simple_cdd_dir/local_extras/"
Be careful to not create files conflicting with the CD content, nothing would warn you about that! Conclusion We now have a way of building a debian install CD including any files we might want to deliver with our system: sources and documentation for example.

18 June 2013

Daniel Pocock: RSA Key Sizes: 2048 or 4096 bits?

Many people are taking a fresh look at IT security strategies in the wake of the NSA revelations. One of the issues that comes up is the need for stronger encryption, using public key cryptography instead of just passwords. This is sometimes referred to as certificate authentication, but certificates are just one of many ways to use public key technology. One of the core decisions in this field is the key size. Most people have heard that 1024 bit RSA keys have been cracked and are not used any more for web sites or PGP. The next most fashionable number after 1024 appears to be 2048, but a lot of people have also been skipping that and moving to 4096 bit keys. This has lead to some confusion as people try to make decisions about which smartcards to use, which type of CA certificate to use, etc. The discussion here is exclusively about RSA key pairs, although the concepts are similar for other algorithms (although key lengths are not equivalent) The case for using 2048 bits instead of 4096 bits
  • Some hardware (many smart cards, some card readers, and some other devices such as Polycom phones) don't support anything bigger than 2048 bits.
  • Uses less CPU than a longer key during encryption and authentication
  • Using less CPU means using less battery power (important for mobile devices)
  • Uses less storage space: while not an issue on disk, this can be an issue in small devices like smart cards that measure their RAM in kilobytes rather than gigabytes
So there are some clear benefits of using 2048 bit keys and not just jumping on the 4096 bit key bandwagon The case for using 4096 bits
  • For some types of attack, security is not just double, it is exponential. 4096 is significantly more secure in this scenario. If an attack is found that allows a 2048 bit key to be hacked in 100 hours, that does not imply that a 4096 bit key can be hacked in 200 hours. The hack that breaks a 2048 bit key in 100 hours may still need many years to crack a single 4096 bit key
  • Some types of key (e.g. an OpenPGP primary key which is signed by many other people) are desirable to keep for an extended period of time, perhaps 10 years or more. In this context, the hassle of replacing all those signatures may be quite high and it is more desirable to have a long-term future-proof key length.
The myth of certificate expiration Many types of public key cryptography, such as X.509, offer an expiry feature. This is not just a scheme to force you to go back to the certificate authority and pay more money every 12 months. It provides a kind of weak safety net in the case where somebody is secretly using an unauthorised copy of the key or a certificate that the CA issued to an imposter. However, the expiry doesn't eliminate future algorithmic compromises. If, in the future, an attacker succeeds in finding a shortcut to break 2048 bit keys, then they would presumably crack the root certificate as easily as they crack the server certificates and then, using their shiny new root key, they would be in a position to issue new server certificates with extended expiry dates. Therefore, the expiry feature alone doesn't protect against abuse of the key in the distant future. It does provide some value though: forcing people to renew certificates periodically allows the industry to bring in new minimum key length standards from time to time. In practical terms, content signed with a 2048 bit key today will not be valid indefinitely. Imagine in the year 2040 you want to try out a copy of some code you released with a digital signature in 2013. In 2040, that signature may not be trustworthy: most software in that era would probably see the key and tell you there is no way you can trust it. The NIST speculates that 2048 bit keys will be valid up to about the year 2030, so that implies that any code you sign with a 2048 bit key today will have to be resigned with a longer key in the year 2029. You would do that re-signing in the 2048 bit twilight period while you still trust the old signature. Fortunately, there are likely to be few projects where such old code will be in demand. 4096 in practice One of the reasons I decided to write this blog is the fact that some organisations have made the 4096 bit keys very prominent (although nobody has made them mandatory as far as I am aware). Debian's guide to key creation currently recommends 4096 bit keys (although it doesn't explicitly mandate their use) Fedora's archive keys are all 4096 bit keys. The CACert.org project has developed a 4096 bit root These developments may leave people feeling a little bit naked if they have to use a shorter 2048 bit key for any of the reasons suggested above (e.g. for wider choice of smart cards and compatibility with readers). It has also resulted in some people spending time looking for 4096 bit smart cards and compatible readers when they may be better off just using 2048 bits and investing their time in other security improvements. In fact, the "risk" of using only 2048 rather than 4096 bits in the smartcard may well be far outweighed by the benefits of hardware security (especially if a smartcard reader with pin-pad is used) My own conclusion is that 2048 is not a dead duck and using this key length remains a valid decision and is very likely to remain so for the next 5 years at least. The US NIST makes a similar recommendation and suggests it will be safe until 2030, although it is the minimum key length they have recommended. My feeling is that the Debian preference for 4096 bit PGP keys is not based solely on security, rather, it is also influenced by the fact that Debian is a project run by volunteers. Given this background, there is a perception that if everybody migrates from 1024 to 2048, then there would be another big migration effort to move all users from 2048 to 4096 and that those two migrations could be combined into a single effort going directly from 1024 to 4096, reducing the future workload of the volunteers who maintain the keyrings. This is a completely rational decision for administrative reasons, but it is not a decision that questions the security of using 2048 bit keys today. Therefore, people should not see Debian's preference to use 4096 bit keys as a hint that 2048 bit keys are fundamentally flawed. Unlike the Debian keys (which are user keys), the CACert.org roots and Fedora archive signing keys are centrally managed keys with a long lifetime and none of the benefits of using 2048 bit keys is a compelling factor in those use cases. Practical issues to consider when choosing key-length Therefore, the choice of using 2048 or 4096 is not pre-determined, and it can be balanced with a range of other decisions:

  • Key lifetime: is it a long life key, such as an X.509 root for an in-house CA or an OpenPGP primary key? Or is it just for a HTTPS web server or some other TLS server that can be replaced every two years?
  • Is it for a dedicated application (e.g. a closed user group all using the same software supporting 4096 bit) or is it for a widespread user base where some users need to use 2048 bit due to old software/hardware?
  • Is it necessary to use the key(s) in a wide variety of smartcard readers?
  • Is it a mobile application (where battery must be conserved) or a server that is likely to experience heavy load?

17 June 2013

Michael Stapelberg: Talk about Debian Code Search

At this year s GPN13 I gave a talk about Debian Code Search. It was in German, so I spent a few hours creating english subtitles. You can watch the video at youtube.com/watch?v=n6DtW3zCTvk with english subtitles. In case you prefer to download the file(s), get http://ftp.ccc.de/events/gpn/gpn13/gpn13-debian-code-search.mp4 (84 MiB) and the corresponding subtitle file at http://t.zekjur.net/gpn13-debian-code-search.srt. Drop both files in the same directory, run mplayer gpn13-debian-code-search.mp4 and press v to enable subtitles. I intend to eventually put the (subtitled) video on YouTube and refer to it from codesearch.debian.net, but I wanted to post the video in its current form already. The presentation itself explains the motivation behind Debian Code Search and how it works. You don t need any knowledge of the system in order to understand the talk. Enjoy!

Lars Wirzenius: If it quacks like a duck: what is a backup?

The purpose of a backup is to allow you to recover from a disaster with reasonable cost and effort. If you delete a file you shouldn't have, or make changes that you shouldn't have, backups are meant to save you from having to re-create the file, or undo a large amount of steps. Speaking very broadly, any copy of your live data is a backup, but this is a uselessly broad definition. For example, if you use an automatic synchronisation system such as Dropbox or git-annex, to keep your live data in sync between two computers, you could pretend they're backups of each other. However, unless the synchronisation also allows you to keep a history of file versions, it's not a very good backup. If you delete your precious file on one computer, and it gets then deleted on the other computer as well, automatically, perhaps in seconds, then the backup is not of much use. Another common assumption is that a RAID array works as a backup. RAID is an excellent technology that allows you to combine several hard disks so that they protect you against loss of data in case of disk failure. If one disk fails, the others have enough data to re-create the data on the failed disk, using either full copies (RAID-1) or error correction codes (RAID-5, RAID-6). This is not a backup. It doesn't protect you against accidental file deletions. There is also no backup history. A version control system is very much like a backup. It stores copies of many of the versions of your project. However, in most version control systems it's fairly easy to make changes that lose history. Ask anyone who has used git reset to change the tip of the master branch to undo a wrong commit or merge, and then accidentally force-pushed that to the server. This is arguably a normal, if uncommon use of the version control system. A good backup system will protect you from you own mistakes, when you do the kinds of things you're expected to do. Version control systems also rarely capture all your data. When you were five, and made some stuff on the family computer, and saved it on a floppy, and then drew a cute little picture of yourself on the floppy to make it clear to everyone it was your floppy, and not anyone else's, certainly not your bully of your brother's, and your mother kept the floppy for decades because of the cute picture, then that is also not a backup. You didn't even know your Mom had kept it. A reasonable backup is one from which you can restore a working copy of your data, when you need to, without too much effort or expense, compared to the disaster you're experiencing. If the disaster is that you deleted a one-page draft outline of the book you want to write someday, the disaster is not very severe. The cost of restoring should be low. If the disaster is that your plans to become the supreme emperor of the world, and make all people your slaves, are in a spreadsheet on your laptop, and your minions accidentally drove a car over your laptop, and you had accidentally not used a Thinkpad as your laptop, the disaster is quite severe. Unless you recover the spreadsheet, you'll never be able to tell apart the buttons to launch the Moon rocket, to self-destruct your HQ, and to switch channels on your TV, and all your work will be in vain, and you'll never, ever, ever convince the pretty girl with red hair living in the house opposite that she should be interested in you. Also, you'll never be able to move away from your parent's house. So, quite severe. It will be acceptable to go to quite some effort and expense to recover that spreadsheet. It's better if you don't need to, but you will, if you have to. Your backup should also be reasonably up to date. Backing up every Christmas is a fine family tradition, but if you don't make a backup also on Easter, Midsummer, and Aunt Agatha's birthday sometime in September was it, or maybe October, you'll risk losing a whole year's worth of work. A year is a long time, and you might never be able to re-do all the work. Personally, I backup my personal laptop every day to a file server at home, and less often to an online backup server. My work laptop gets backed up once an hour to the company file server, which gets backed up to two backup servers about once a day. You need to balance the risk of losing data and work, and the expense and effort to back up your data. How much is a day's work worth to you, or your employer? How much does a backup system cost? In the next episode, I'll ponder on how many backups are enough.

Gunnar Wolf: Cultural objects/goods: When a superhero is too famous for his own good

I found the following news item; if you can read Spanish, you will most probably prefer the original version in the Proceso magazine's site. The subject? The federal police (PGR) and army arrest 17 artisans for making money out of Spiderman. The following translation is mine. Done past midnight, and being quite tired, and translated so this news item can reach a broader audience. All errors are mine (except those carried out by the security forces, that is).
June 13, 2013 Cuernavaca, Morelos. Policement from the General Republic Attorney (Procuradur a General de la Rep blica, PGR) and the Army entered and searched the "3 de mayo" neighbourhood, in the municipality of Emiliano Zapata, detaining 17 ceramist artisans that sold candies, dolls and pi atas shaped like Spiderman. This search was done on the evening of last Wednesday, around 16:00. Federal ministerial policement and army soldiers closed a street with several informal stores and detained workers taht were selling this Marvel Comics character, following said company's denounce. As a result for this operation, 17 artisants were detained, although the same day five of them were freed. The policemen also seized 12 bags of candies, pi atas, ceramics and wooden figures of the superhero. PGR closed down 11 stores where ceramics with this same figure was being sold, accusing the detainees of plagiarizing Spiderman's image, protected under the copyright law. The 12 that remained under detention were put at the Federal Justice's disposal, which prompted that this Thursday, around 10AM, hundreds of sellers of "3 de mayo" went out to PGR's building to demand their friends' freedom, who are facing a bail of up to 200,000 pesos (~USD$18,000). Outraged because they said they were treated as if they were part of a drug ring, hundreds of artisans closed intermitently Avenida Cuauhn huac, where the PGR representation in Morelos state is located. The artisans' pressure helped for the amount of the bail to be lowered from MX$200,000 to MX$16,000, and so they were set free. Francisco Fern ndez Flores, president of the Ceramists Association, criticized the operation because, he said, it was as strong as if they were "drug dealers". The artisans explained that they don't even make the Spiderman figures, they are made by the interns of the Centro Estatal de Reinserci n Social de Atlacholoaya (prision), located in the Xochitepec municipality, who offered them to the ceramists so they could be sold. "The Atlacholoaya inmates do them, we buy them to support them, and turns out we are the delinquents now", said Miriam Monroy, sister of one of the detainees. This information was contradicted by Jes s Valencia Valencia, responsible for Morelos' state prision system, who assured that in said prision no ceramics are done. Fern ndez Flores insisted though that from within the prision they are being offered pi atas, candies and "piggy banks" with Spiderman's shape. Jos Luis Pozo, vicepresident of the Ceramists Union, said that to avoid more such federal operations for copyright breaches, they have committed not to produce or commercialize Marvel superhero figures, and any other characters the authority demands. "We do commit to, from now on, those products singled out to us will not be commercialized", he said. Pozo said that the PGR operation caused losses not just to the detained producers and salesmen, but to over 200 ceramists that had to close their stores in solidarity with their friends. Acording to the artisans, the products were a success until the PGR came, seized the products and detained the salesmen.
And yes, the copyright insanity does not stop. Spiderman is by today a clear part of popular culture. Marvel brilliantly succeeded in creating such a popular icon that everybody recognizes, that everybody identifies with And that everybody should be able to recreate. We are not talking about brand protection. Marvel does not, and will never, commercialize pi atas, ceramics or wooden toys. And even if they were plastic-cast While Spiderman is still under the protection of copyright, as the Berne Convention defines it (and of course, as the much stricter Mexican laws agree), that does not mean that any and every product resembling a Spiderman should be protected. Many ceramists and pi ata makers will create unique pieces of art Ok, handicraft. But reading the copyright law more strictly, Spiderman is more treated as a trademark than as a copyright. And it is a trademark that should be declared as having passed on to the public domain.

16 June 2013

Daniel Pocock: Monitoring with Ganglia: an O'Reilly community book project

I recently had the opportunity to contribute to an O'Reilly community book project, developing the book Monitoring with Ganglia in collaboration with other members of the Ganglia team

The project itself, as a community book, pays no royalties back to the contributors, as we have chosen to donate all proceeds to charity. People who contributed to the book include
Robert Alexander, Jeff Buchbinder, Frederiko Costa, Alex Dean, Dave Josephsen, Bernard Li, Matt Massie, Brad Nicholes, Peter Phaal and Vladimir Vuksan and we also had generous assistance from various members of the open source community who assisted in the review process. Ganglia itself started at University of California, Berkeley as an initiative of Matt Massie, for monitoring HPC cloud infrastructure My own contact with Ganglia only began in 2008 when I was offered the opportunity to work full-time on the enterprise-wide monitoring systems for a large investment bank. Ganglia had been chosen for this huge project due to it's small footprint, support for many platforms and it's ability to work on a heterogeneous network as well as providing dedicated features for the bank's HPC grid. This brings me to one important point about Ganglia: it's not just about HPC any more. While it is extremely useful for clusters, grids and clouds, it is also quite suitable for a mixed network of web servers, mail servers, databases and all the other applications you may find in a small business, education or ISP environment. Instantly up and running with packages One of the most compelling features, even for small sites with less than 10 nodes, is the ease of installation: install the packages on Debian, Ubuntu, Fedora, OpenCSW and some other platforms, and it just works. Ganglia nodes will find each other over multicast, instantly, no manual configuration changes necessary. On one of the nodes, the web interface must be installed for viewing the statistics. Dare I say it: it is so easy, you hardly even need the book for a small installation. Where the book is really compelling is if you have hundreds or thousands of nodes, if you want custom charts or custom metrics or anything else beyond just installing the package. If monitoring is more than 10% of your job, the book is probably a must-have. Excellent open source architecture Ganglia's simplicity is largely thanks to the way it leverages other open source projects such as Tobi Oetiker's RRDtool and PHP Anybody familiar with these tools will find Ganglia is particularly easy to work with and customise. Custom metrics: IO service times One of my own contributions to the project has been the creation of ganglia-modules-linux, some plugins for Linux-specific metrics and ganglia-modules-solaris providing some similar metrics for Solaris. These projects on github provide an excellent base for people to fork and implement their own custom metrics in C or C++ The book provides a more detailed account of how to work with the various APIs for Python, C/C++, gmetric (command line/shell scripts) and Java. The new web interface For people who had tried earlier versions of Ganglia (and for those people who installed versions < 3.3.0 and still haven't updated), the new web interface is a major improvement and well worth the effort to install. It is available on the most recent packages (for example, it is in Debian 7 (wheezy) but not in Debian 6.) It was originally promoted as a standalone project (code-named gweb2) but was adopted as the official Ganglia web interface around the release of Ganglia 3.3.0. This web page provides a useful overview of what has changed and here is the original release announcement.

15 June 2013

Daniel Pocock: Girls Around Me and the NSA

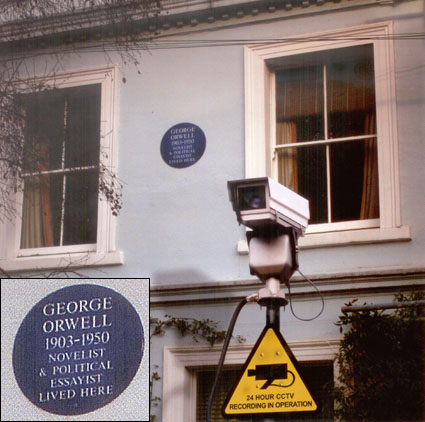
When the Girls Around Me app was released in 2012, it received massive criticism on the basis that it could enable stalking and undermine privacy. Nonetheless, the existence of this app may well be an even bigger problem for the NSA right now than it is for single women. US Government officials in damage control mode over the NSA surveillance leaks have sought to deny that it is even possible to monitor people in the way that The Guardian reported the matter. Leaders of Internet giants such as Google and Facebook have also tried to deny and downplay the possibilities of PRISM. In my view, a company like Google is no more likely to admit hiving off customer data than a bank is likely to admit a liquidity crisis, for fear of starting a self-fulfulling bank run. User trust is as existential with data as it is with bank deposits. So my question is, if the NSA with an $8 billion annual budget can't track people in real-time, how come a small team of app developers could do much the same thing so easily in Girls Around Me? One possibility is that some companies may be accurate in what they have reported: they are not letting data out the back door. The scary thing is, they are letting it out the front door and it is just as possible for third-party commercial operators and foreign powers to harvest a lot of this data in the same way as Girls Around Me In one of the most remarkable cases, the chief of British MI6 (the team that James Bond plays for) may have been compromised by his wife's Facebook posts - if Facebook really is an outsourced NSA operation, then that is a remarkable case of friendly fire Both the scandals around Girls Around Me and the NSA spying leaks only serve to confirm one thing: that people need to think twice every time they fill in some form or submit some data that could be used to identify or track them.
12 June 2013

Daniel Pocock: When conspiracy theories come true

In a blog attempting to join the dots between Australia's intelligence services and the US PRISM program, I speculated that Australia has had extensive access to data harvested by PRISM. My hunch has just been exposed rather dramatically today: Top secret data center under construction to house all our secrets. "There has been no discussion of the project in Senate estimates committee hearings, and the public reports of Parliament's joint committee on intelligence and security make no reference to it." The news story also suggests that the relationship is bi-directional, with data harvested from Australian ISPs cross referenced against US databases from Facebook and Google. From a human rights perspective, the implications of this data sharing are much more dramatic than the NSA just snooping on US citizens within the US. While Australia often tries to portray the image that it is a safe and happy country, it has a dark side. Police are kept busy investigating politicians and Government officials: Prime Minister and her associates connected to a union slush fund, the central bank's banknote printing agency's chief executive and 8 colleagues on conspiracy charges and even a senator on good old fashioned shoplifting and assault charges Exporting PRISM data to a human rights backwater As an Australian, my own rights and those of my family are more heavily protected and respected living in Europe than if I lived in my country of birth. Australia does not have a bill of rights like the US (where PRISM data is harvested) or the European Convention of Human Rights. Once US data is exported to Australia, it can be used to support sinister programs like the indefinite detention of coloured people in sinister desert camps. Just this week, the Government left over 50 bodies of poor refugees for the sharks to eat. For someone with such a lack of a conscience, can you imagine them thinking twice about using PRISM data for unscrupulous purposes? Is US PRISM data at greater risk? Despite the stench of corruption and lip service to human rights, is there any hard evidence that PRISM data will be at greater risk if allowed into the hands of Australians? Death by SMS One former Australian official (having dual-citizenship with Sri Lanka) is accused of facilitating war crimes in the Sri Lankan civil war. At present he is Sri Lanka's ambassador at the UN, giving him the benefit of diplomatic immunity. When he was working for Australia, how much data did he have access to? Isn't it ludicrous that in the name of stopping terrorism, data may have been collected and handed to war criminals on a silver platter? Behind enemy lines Like James Bond in reverse, an Australian official was exposed unofficially engaging in a relationship with a Vietnamese spy colonel. In addition to the $20 million in bribery to win a bank note printing contract, is data being used as a tool to leverage trade negotiations, officially or otherwise? If an Australian official with top-secret clearance ends up under the control of a foreign agent, what is the risk that they would be exploited to obtain PRISM data? Defence minister resignation in Chinese spy scandal In 2009 Australia's defence minister was identified having close links to a Chinese-Australian business woman including all the usual little luxuries: first class flights, apartment rental and joint business deals with family members. He subsequently resigned. Little details were made public. How much PRISM data was directly available to political officials like the defence minister? Disappearing Prime Ministers The disappearance of a serving Prime Minister, Harold Holt, during the cold war remains an unsolved mystery to this day. People continue to ask was he swept out to sea or voluntarily whisked away in a Chinese or Soviet nuclear submarine. While Australia has traditionally had strong ties to Britain and the US, there have been exceptions to the rule. Fortunately this all happened before PRISM and Harold Holt red submarine rumours are no more well-founded than the UFO theories of his abduction. Where did all the data go? As the music industry has found out the hard way, digital data can be copied at will with the originator having no control. The revelations that Britain and Australia are in on the PRISM shenanigans only confirms that this data is seen as a new form of currency for exchange in geo-political posturing. While used weapons take decades to work their way down the chain, data can spread at the speed of light.

Bernhard R. Link: listing your git repositories on git.debian.org

With the new gitweb version available on alioth after the upgrade to wheezy (thanks to the alioth admins for their work on alioth), there is a new feature available I want to advertise a bit here: listing only a subtree of all repositories. Before now one could only either look at a specific repository or get the list of all repositories and the list of all repositories is quite large and slow. With the new feature you can link to all the repositories in your alioth project. For example in reprepro's case that is http://anonscm.debian.org/gitweb/?pf=mirrorer. Much more I missed what is now possible with the link http://anonscm.debian.org/gitweb/?pf=debian-science: getting a list of all debian-science repositories (still slow enough, but much better than the full list).

Marc 'Zugschlus' Haber: How to amd64 an i386 Debian installation with multiarch

Migrating a Debian installation between architectures has always been difficult. The recommended way to crossgrade an i386 Debian to amd64 Debian was to reinstall the system, move over data and configuration. For the more brave, in-place crossgrades usually involved chroots, rescue CDs, a lot of ar p tar xf - data.tar.gz and luck. I have never been brave when it comes to system administration, have done a lot of architecture migrations with reinstallation, and have always taken the opportunity to clear out the contamination that accumulates itself when a system is running for a long time. I would even recommend doing this to most people even now. However, I have a few very ugly systems in place that are still on i386 because I didn t dare going the reinstallation path. Doing in-place crossgrades has become a lot easier since wheezy s release, since once now can have both i386 and amd64 libraries installed in parallel, which allows to replace foo:i386 with foo:amd64 without influencing the other parts of the system. The process is still full of pitfalls: I have only tried this yet with a freshly installed minimal wheezy server system. I do not, however, expect surprises when it comes to using this process with real life systems. I will document other pitfalls I have fallen into here at a later time. My minimal wheezy system was running in a KVM VM with its virtual disk as a LVM LV in the host system. I took a snapshot before beginning and used lvconvert --merge numerous time to return my LV to the original state. Be aware that lvconvert --merge removes the snapshot after merging it, so you ll need to re-create the snapshot before trying again. During the process, I discussed things with Paul Tagliamonte, who has done this before, but on a live system and with a slightly more invasive approach. He has blogged about this. Thank you very much, your hints were very helpful. Here is a commented typescript of what I have done. Be warned: This was a lab setting with a rather minimal system. If you re going to try this with a production system, have a backup, or, if you re on snapshottable infrastructure, take snapshots and be prepared to roll back if anything goes wrong. First let s see what we have and save a list of installed packages.
mh@swivel:~$ ssh wheezyarch.zugschlus.de
$ uname -a
Linux wheezyarch 3.9.4-zgsrv2008064 #2 SMP PREEMPT Wed Jun 5 12:57:51 UTC 2013 x86_64 GNU/Linux
$ dpkg --print-architecture
i386
$ dpkg --print-foreign-architectures
$ dpkg --list   grep i386   wc -l
175
$ dpkg --list   grep amd64   wc -l
0
$ sudo dpkg --get-selections   grep install   awk  print $1    sed  s/:.*//;s/$/:amd64
install/;  > get-selections.pre
So we have an i386 system running an x86_64 kernel. Next, we add amd64 as an additional architecture which allows us to install amd64 packages. We download the amd64 packages files. Note that dpkg still considers this an i386 system with amd64 as a foreign arch.
$ sudo dpkg --add-architecture amd64
$ sudo apt-get update
Get:1 http://security.debian.org wheezy/updates Release.gpg [836 B]
( )
Fetched 6.155 kB in 4s (1.400 kB/s)
Reading package lists... Done
$ dpkg --print-architecture
i386
$ dpkg --print-foreign-architectures
amd64
$ dpkg --list   grep i386   wc -l
175
$ dpkg --list   grep amd64   wc -l
0
Next, download everything that is necessary to migrate dpkg and apt from i386 and amd64. We cannot directly apt things as the remove-install cycle used by apt will leave us without working dpkg. One could work around this by un-aring the dpkg.deb and directly forcing the amd64 files upon the system, but I think this approach is much cleaner. apt-get download will not resolve dependices while apt-get --download install does. After the download, dpkg --install the packages. dpkg is not particularly smart about installation order, so Pre-Depends may fail or not. If they fail, dpkg will give a list of deb files that were affected, which is an easy help to finish their installation. One could also choose the easy way (which I did here) and repeat the dpkg --install *.deb command. Since the Pre-Depends will already be installed, the second install run will succeed.
$ sudo apt-get --download-only install dpkg:amd64 apt:amd64
Reading package lists... Done
Building dependency tree       
Reading state information... Done
The following extra packages will be installed:
  gcc-4.7-base:amd64 libapt-pkg4.12:amd64 libbz2-1.0:amd64 libc6:amd64
  libgcc1:amd64 liblzma5:amd64 libselinux1:amd64 libstdc++6:amd64
  zlib1g:amd64
Suggested packages:
  aptitude:amd64 synaptic:amd64 wajig:amd64 dpkg-dev:amd64 apt-doc:amd64
  python-apt:amd64 glibc-doc:amd64 locales:amd64
The following packages will be REMOVED:
  apt cron-apt dpkg
The following NEW packages will be installed:
  apt:amd64 dpkg:amd64 gcc-4.7-base:amd64 libapt-pkg4.12:amd64
  libbz2-1.0:amd64 libc6:amd64 libgcc1:amd64 liblzma5:amd64 libselinux1:amd64
  libstdc++6:amd64 zlib1g:amd64
0 upgraded, 11 newly installed, 3 to remove and 0 not upgraded.
Need to get 10,0 MB of archives.
After this operation, 14,9 MB of additional disk space will be used.
Do you want to continue [Y/n]? 
Get:1 http://debian.debian.zugschlus.de/debian/ wheezy/main gcc-4.7-base amd64 4.7.2-5 [144 kB]
( )
Fetched 10,0 MB in 2s (3.535 kB/s)
Download complete and in download only mode
$ sudo dpkg --install /var/cache/apt/archives/*.deb
(Reading database ... 16586 files and directories currently installed.)
Preparing to replace apt 0.9.7.8 (using .../archives/apt_0.9.7.8_amd64.deb) ...
Unpacking replacement apt ...
dpkg: regarding .../dpkg_1.16.10_amd64.deb containing dpkg, pre-dependency problem:
 dpkg pre-depends on libbz2-1.0
dpkg: error processing /var/cache/apt/archives/dpkg_1.16.10_amd64.deb (--install):
 pre-dependency problem - not installing dpkg
Selecting previously unselected package gcc-4.7-base:amd64.
( )
Errors were encountered while processing:
 /var/cache/apt/archives/dpkg_1.16.10_amd64.deb
$ sudo dpkg --install /var/cache/apt/archives/*.deb
(Reading database ... 16905 files and directories currently installed.)
Preparing to replace apt 0.9.7.8 (using .../archives/apt_0.9.7.8_amd64.deb) ...
Unpacking replacement apt ...
( )
$
From dpkg s point of view, the system is now already amd64, with i386 being a foreign arch. However, the majory of packages is still i386.
$ dpkg --print-architecture
amd64
$ dpkg --print-foreign-architectures
i386
$ dpkg --list   grep i386   wc -l
173
$ dpkg --list   grep amd64   wc -l
11
$ 
The apt resolver is currently in a very bad broken state since the system is missing most essential packages in its native architecture. This is not easily solved by apt-get -f install, as this would zap most of the existing system . We let apt-get --download-only -f install download the packages that it wants to replace with its amd64 counterparts and their dependencies, and, again, use dpkg --install *.deb to install them.
$ sudo apt-get --download-only -f install
Reading package lists... Done
Building dependency tree       
Reading state information... Done
Correcting dependencies... Done
The following packages were automatically installed and are no longer required:
  cpio gettext-base:i386 klibc-utils libapt-inst1.5 libasprintf0c2:i386
  libcurl3-gnutls:i386 libfreetype6:i386 libfuse2:i386 libklibc
  libreadline5:i386
Use  apt-get autoremove  to remove them.
The following extra packages will be installed:
  acpid aide bsd-mailx cpio cron curl daemon dctrl-tools exim4-base
  exim4-daemon-light initscripts insserv kbd klibc-utils less libbsd0
  libcomerr2 libcurl3 libdb5.1 libexpat1 libgcrypt11 libgdbm3 libgnutls26
  libgpg-error0 libgssapi-krb5-2 libidn11 libk5crypto3 libkeyutils1 libklibc
  libkmod2 libkrb5-3 libkrb5support0 libldap-2.4-2 liblockfile1 libncursesw5
  libnewt0.52 libp11-kit0 libpam-modules libpam0g libpcre3 libpopt0
  libreadline6 librtmp0 libsasl2-2 libslang2 libsqlite3-0 libssh2-1
  libssl1.0.0 libtasn1-3 libterm-readkey-perl libtinfo5 openssl perl
  perl-base python2.7 python2.7-minimal sysvinit-utils whiptail
Suggested packages:
  libarchive1 anacron logrotate checksecurity debtags mail-reader eximon4
  exim4-doc-html exim4-doc-info spf-tools-perl swaks bootchart2 rng-tools
  krb5-doc krb5-user libpam-doc perl-doc make python2.7-doc binutils
  binfmt-support bootlogd sash
Recommended packages:
  exim4 postfix mail-transport-agent psmisc mailx ca-certificates
  krb5-locales libgpm2 libfribidi0 libsasl2-modules libpng12-0
The following packages will be REMOVED:
  acpid:i386 aide:i386 aptitude:i386 bsd-mailx:i386 cpio:i386 cron:i386
  curl:i386 daemon:i386 dctrl-tools:i386 debsecan dmsetup:i386 e2fsprogs:i386
  exim4-base:i386 exim4-daemon-light:i386 git:i386 grub-common:i386
  grub-pc:i386 grub-pc-bin:i386 grub2-common:i386 ifupdown:i386
  initramfs-tools initscripts:i386 insserv:i386 ippl:i386 jed:i386 kbd:i386
  klibc-utils:i386 less:i386 libdevmapper-event1.02.1:i386
  libdevmapper1.02.1:i386 libklibc:i386 libnewt0.52:i386
  libparted0debian1:i386 libterm-readkey-perl:i386 lsof:i386 lvm2:i386
  molly-guard ntp:i386 openssh-server:i386 openssl:i386 parted:i386 perl:i386
  perl-base:i386 procps:i386 python-apt:i386 python2.7:i386
  python2.7-minimal:i386 rsyslog:i386 sysvinit:i386 sysvinit-utils:i386
  udev:i386 util-linux:i386 whiptail:i386
The following NEW packages will be installed:
  acpid aide bsd-mailx cpio cron curl daemon dctrl-tools exim4-base
  exim4-daemon-light initscripts insserv kbd klibc-utils less libbsd0
  libcomerr2 libcurl3 libdb5.1 libexpat1 libgcrypt11 libgdbm3 libgnutls26
  libgpg-error0 libgssapi-krb5-2 libidn11 libk5crypto3 libkeyutils1 libklibc
  libkmod2 libkrb5-3 libkrb5support0 libldap-2.4-2 liblockfile1 libncursesw5
  libnewt0.52 libp11-kit0 libpam-modules libpam0g libpcre3 libpopt0
  libreadline6 librtmp0 libsasl2-2 libslang2 libsqlite3-0 libssh2-1
  libssl1.0.0 libtasn1-3 libterm-readkey-perl libtinfo5 openssl perl
  perl-base python2.7 python2.7-minimal sysvinit-utils whiptail
0 upgraded, 58 newly installed, 53 to remove and 0 not upgraded.
Need to get 23,4 MB of archives.
After this operation, 17,5 MB disk space will be freed.
Do you want to continue [Y/n]? Y
Get:1 http://security.debian.org/debian-security/ wheezy/updates/main libgnutls26 amd64 2.12.20-7 [619 kB]
( )
Fetched 23,4 MB in 11s (2.038 kB/s)                                           
Download complete and in download only mode
$ sudo dpkg --install /var/cache/apt/archives/*.deb
(Reading database ... 16905 files and directories currently installed.)
Preparing to replace acpid 1:2.0.16-1+deb7u1 (using .../acpid_1%3a2.0.16-1+deb7u1_amd64.deb) ...
( )
Selecting previously unselected package libpam-modules:amd64.
dpkg: regarding .../libpam-modules_1.1.3-7.1_amd64.deb containing libpam-modules:amd64, pre-dependency problem:
 libpam-modules pre-depends on libdb5.1
  libdb5.1:amd64 is unpacked, but has never been configured.
dpkg: error processing /var/cache/apt/archives/libpam-modules_1.1.3-7.1_amd64.deb (--install):
 pre-dependency problem - not installing libpam-modules:amd64
Selecting previously unselected package libpcre3:amd64.
Unpacking libpcre3:amd64 (from .../libpcre3_1%3a8.30-5_amd64.deb) ...
( )
Errors were encountered while processing:
 /var/cache/apt/archives/libpam-modules_1.1.3-7.1_amd64.deb
$ sudo dpkg --install /var/cache/apt/archives/libpam-modules_1.1.3-7.1_amd64.deb
(Reading database ... 17007 files and directories currently installed.)
Unpacking libpam-modules:amd64 (from .../libpam-modules_1.1.3-7.1_amd64.deb) ...
Setting up libpam-modules:amd64 (1.1.3-7.1) ...
$ sudo apt-get clean
$ dpkg --print-architecture
amd64
$ dpkg --print-foreign-architectures
i386
$ dpkg --list   grep i386   wc -l
151
$ dpkg --list   grep amd64   wc -l
66
$ 
The concluding apt-get clean prevents packages from being reinstalled again in the next dpkg --install *.deb run. Now, the apt resolver is kind of fixed, but apt will still want to remove most of the system. I haven t found a way to get out of this mess short of allowing apt to de-install those packages and to manually install their amd64 counterparts later. First, we see what apt wants to do, and paste the The following packages will be removed part of apt-get s output into a sed expression which fixes the architecture strings for us so that we can use the resulting file as input for the following installation procedure. After that, we let apt-get do what itself considers a bad thing and requires us to type a consent sentence. The key is that this deinstallation of essential packages breaks the system, but not apt and dpkg, which allows us to un-break the system afterwards.
$ sudo apt-get -f install
Reading package lists... Done
Building dependency tree       
Reading state information... Done
Correcting dependencies... Done
The following packages were automatically installed and are no longer required:
  gettext-base:i386 libapt-inst1.5 libasprintf0c2:i386 libcurl3-gnutls:i386
  libfreetype6:i386 libfuse2:i386 libreadline5:i386
Use  apt-get autoremove  to remove them.
The following extra packages will be installed:
  sysvinit-utils:i386
Suggested packages:
  bootlogd:i386 sash:i386
The following packages will be REMOVED:
  adduser aide-common aptitude:i386 bsd-mailx console-common console-data
  console-log cron curl debian-goodies debsecan dmsetup:i386 e2fsprogs:i386
  exim4-base exim4-config exim4-daemon-light git:i386 grub-common:i386
  grub-pc:i386 grub-pc-bin:i386 grub2-common:i386 ifupdown:i386
  initramfs-tools initscripts ippl:i386 jed:i386 libcurl3
  libdevmapper-event1.02.1:i386 libdevmapper1.02.1:i386 liberror-perl
  libfile-find-rule-perl libnumber-compare-perl libparted0debian1:i386
  libswitch-perl libterm-readkey-perl libterm-readline-perl-perl
  libtext-glob-perl libtimedate-perl locales lsof:i386 lvm2:i386 molly-guard
  ntp:i386 openssh-client:i386 openssh-server:i386 openssl openssl-blacklist
  openssl-blacklist-extra parted:i386 perl perl-modules procps:i386
  python-apt:i386 rsyslog:i386 stow sysv-rc sysvinit:i386 sysvinit-utils
  tzdata ucf udev:i386 util-linux:i386
The following NEW packages will be installed:
  sysvinit-utils:i386
WARNING: The following essential packages will be removed.
This should NOT be done unless you know exactly what you are doing!
  e2fsprogs:i386 util-linux:i386 (due to e2fsprogs:i386) sysvinit:i386
  sysvinit-utils tzdata (due to util-linux:i386)
0 upgraded, 1 newly installed, 62 to remove and 0 not upgraded.
Need to get 97,1 kB of archives.
After this operation, 131 MB disk space will be freed.
You are about to do something potentially harmful.
To continue type in the phrase  Yes, do as I say!  ? (abort with Ctrl-C)
$ sed  s/:i386//g  > removedpkg (paste  The following packages will be REMOVED:  stanza here and
type Ctrl-D afterwards)
  adduser aide-common aptitude:i386 bsd-mailx console-common console-data
  console-log cron curl debian-goodies debsecan dmsetup:i386 e2fsprogs:i386
  exim4-base exim4-config exim4-daemon-light git:i386 grub-common:i386
  grub-pc:i386 grub-pc-bin:i386 grub2-common:i386 ifupdown:i386
  initramfs-tools initscripts ippl:i386 jed:i386 libcurl3
  libdevmapper-event1.02.1:i386 libdevmapper1.02.1:i386 liberror-perl
  libfile-find-rule-perl libnumber-compare-perl libparted0debian1:i386
  libswitch-perl libterm-readkey-perl libterm-readline-perl-perl
  libtext-glob-perl libtimedate-perl locales lsof:i386 lvm2:i386 molly-guard
  ntp:i386 openssh-client:i386 openssh-server:i386 openssl openssl-blacklist
  openssl-blacklist-extra parted:i386 perl perl-modules procps:i386
  python-apt:i386 rsyslog:i386 stow sysv-rc sysvinit:i386 sysvinit-utils
  tzdata ucf udev:i386 util-linux:i386
$ cat removedpkg 
  adduser aide-common aptitude bsd-mailx console-common console-data
  console-log cron curl debian-goodies debsecan dmsetup e2fsprogs
  exim4-base exim4-config exim4-daemon-light git grub-common
  grub-pc grub-pc-bin grub2-common ifupdown
  initramfs-tools initscripts ippl jed libcurl3
  libdevmapper-event1.02.1 libdevmapper1.02.1 liberror-perl
  libfile-find-rule-perl libnumber-compare-perl libparted0debian1
  libswitch-perl libterm-readkey-perl libterm-readline-perl-perl
  libtext-glob-perl libtimedate-perl locales lsof lvm2 molly-guard
  ntp openssh-client openssh-server openssl openssl-blacklist
  openssl-blacklist-extra parted perl perl-modules procps
  python-apt rsyslog stow sysv-rc sysvinit sysvinit-utils
  tzdata ucf udev util-linux
$ sudo apt-get -f install
Reading package lists... Done
Building dependency tree       
Reading state information... Done
Correcting dependencies... Done
The following packages were automatically installed and are no longer required:
  gettext-base:i386 libapt-inst1.5 libasprintf0c2:i386 libcurl3-gnutls:i386
  libfreetype6:i386 libfuse2:i386 libreadline5:i386
Use  apt-get autoremove  to remove them.
The following extra packages will be installed:
  sysvinit-utils:i386
Suggested packages:
  bootlogd:i386 sash:i386
The following packages will be REMOVED:
  adduser aide-common aptitude:i386 bsd-mailx console-common console-data
  console-log cron curl debian-goodies debsecan dmsetup:i386 e2fsprogs:i386
  exim4-base exim4-config exim4-daemon-light git:i386 grub-common:i386
  grub-pc:i386 grub-pc-bin:i386 grub2-common:i386 ifupdown:i386
  initramfs-tools initscripts ippl:i386 jed:i386 libcurl3
  libdevmapper-event1.02.1:i386 libdevmapper1.02.1:i386 liberror-perl
  libfile-find-rule-perl libnumber-compare-perl libparted0debian1:i386
  libswitch-perl libterm-readkey-perl libterm-readline-perl-perl
  libtext-glob-perl libtimedate-perl locales lsof:i386 lvm2:i386 molly-guard
  ntp:i386 openssh-client:i386 openssh-server:i386 openssl openssl-blacklist
  openssl-blacklist-extra parted:i386 perl perl-modules procps:i386
  python-apt:i386 rsyslog:i386 stow sysv-rc sysvinit:i386 sysvinit-utils
  tzdata ucf udev:i386 util-linux:i386
The following NEW packages will be installed:
  sysvinit-utils:i386
WARNING: The following essential packages will be removed.
This should NOT be done unless you know exactly what you are doing!
  e2fsprogs:i386 util-linux:i386 (due to e2fsprogs:i386) sysvinit:i386
  sysvinit-utils tzdata (due to util-linux:i386)
0 upgraded, 1 newly installed, 62 to remove and 0 not upgraded.
Need to get 97,1 kB of archives.
After this operation, 131 MB disk space will be freed.
You are about to do something potentially harmful.
To continue type in the phrase  Yes, do as I say! 
 ?] Yes, do as I say! (actually type this!)
Get:1 http://debian.debian.zugschlus.de/debian/ wheezy/main sysvinit-utils i386 2.88dsf-41 [97,1 kB]
Fetched 97,1 kB in 0s (687 kB/s)    
(Reading database ... 17050 files and directories currently installed.)
Removing aide-common ...
( )
dpkg: warning: overriding problem because --force enabled:
 This is an essential package - it should not be removed.
Removing e2fsprogs ...
Removing sysv-rc ...
dpkg: warning: overriding problem because --force enabled:
 This is an essential package - it should not be removed.
Removing sysvinit ...
dpkg: warning: overriding problem because --force enabled:
 This is an essential package - it should not be removed.
Removing sysvinit-utils ...
dpkg: warning: overriding problem because --force enabled:
 This is an essential package - it should not be removed.
Removing ucf ...
dpkg: warning: overriding problem because --force enabled:
 This is an essential package - it should not be removed.
dpkg: warning: overriding problem because --force enabled:
 This is an essential package - it should not be removed.
dpkg: warning: overriding problem because --force enabled:
 This is an essential package - it should not be removed.
dpkg: warning: overriding problem because --force enabled:
 This is an essential package - it should not be removed.
dpkg: warning: overriding problem because --force enabled:
 This is an essential package - it should not be removed.
Removing libdevmapper1.02.1:i386 ...
Removing libswitch-perl ...
Removing perl ...
dpkg: warning: overriding problem because --force enabled:
 This is an essential package - it should not be removed.
Removing dmsetup ...
Removing perl-modules ...
dpkg: warning: overriding problem because --force enabled:
 This is an essential package - it should not be removed.
Removing util-linux ...
Removing tzdata ...
Processing triggers for mime-support ...
Selecting previously unselected package sysvinit-utils.
(Reading database ... 9802 files and directories currently installed.)
Unpacking sysvinit-utils (from .../sysvinit-utils_2.88dsf-41_i386.deb) ...
Setting up sysvinit-utils (2.88dsf-41) ...
$ sudo apt-get install $(cat removedpkg)
Reading package lists... Done
Building dependency tree       
Reading state information... Done
The following packages were automatically installed and are no longer required:
  libasprintf0c2:i386 libcurl3-gnutls:i386 libfreetype6:i386 libfuse2:i386
  libreadline5:i386
Use  apt-get autoremove  to remove them.
The following extra packages will be installed:
  e2fslibs gettext-base libapt-inst1.5 libasprintf0c2 libattr1 libblkid1
  libboost-iostreams1.49.0 libcap2 libcurl3-gnutls libcwidget3 libedit2
  libept1.4.12 libfreetype6 libfuse2 libgpm2 libncurses5 libopts25 libprocps0
  libreadline5 libsepol1 libsigc++-2.0-0c2a libss2 libudev0 libuuid1 libwrap0
  libxapian22 logrotate
Suggested packages:
  liblocale-gettext-perl tasksel debtags unicode-data anacron checksecurity
  popularity-contest xdg-utils zenity gpart e2fsck-static mail-reader eximon4
  exim4-doc-html exim4-doc-info spf-tools-perl swaks git-daemon-run
  git-daemon-sysvinit git-doc git-el git-arch git-cvs git-svn git-email
  git-gui gitk gitweb multiboot-doc grub-emu xorriso desktop-base
  isc-dhcp-client dhcp-client ppp rdnssd net-tools gpm libcwidget-dev fuse
  libparted0-dev libparted0-i18n xapian-tools ntp-doc ssh-askpass libpam-ssh
  keychain monkeysphere rssh ufw parted-doc perl-doc make libpod-plainer-perl
  python-apt-dbg python-gtk2 python-vte python-apt-doc rsyslog-mysql
  rsyslog-pgsql rsyslog-doc rsyslog-gnutls rsyslog-gssapi rsyslog-relp
  doc-base sysv-rc-conf bum bootlogd sash util-linux-locales dosfstools
Recommended packages:
  aptitude-doc-en aptitude-doc apt-xapian-index libparse-debianchangelog-perl
  exim4 postfix mail-transport-agent psmisc mailx patch rsync ssh-client
  os-prober busybox busybox-initramfs busybox-static ca-certificates
  uuid-runtime xauth ncurses-term iso-codes usbutils
The following packages will be REMOVED:
  gettext-base:i386 libboost-iostreams1.49.0:i386 libcwidget3:i386
  libept1.4.12:i386 libopts25:i386 libxapian22:i386 logrotate:i386
  sysvinit-utils:i386
The following NEW packages will be installed:
  adduser aide-common aptitude bsd-mailx console-common console-data
  console-log cron curl debian-goodies debsecan dmsetup e2fslibs e2fsprogs
  exim4-base exim4-config exim4-daemon-light gettext-base git grub-common
  grub-pc grub-pc-bin grub2-common ifupdown initramfs-tools initscripts ippl
  jed libapt-inst1.5 libasprintf0c2 libattr1 libblkid1
  libboost-iostreams1.49.0 libcap2 libcurl3 libcurl3-gnutls libcwidget3
  libdevmapper-event1.02.1 libdevmapper1.02.1 libedit2 libept1.4.12
  liberror-perl libfile-find-rule-perl libfreetype6 libfuse2 libgpm2
  libncurses5 libnumber-compare-perl libopts25 libparted0debian1 libprocps0
  libreadline5 libsepol1 libsigc++-2.0-0c2a libss2 libswitch-perl
  libterm-readkey-perl libterm-readline-perl-perl libtext-glob-perl
  libtimedate-perl libudev0 libuuid1 libwrap0 libxapian22 locales logrotate
  lsof lvm2 molly-guard ntp openssh-client openssh-server openssl
  openssl-blacklist openssl-blacklist-extra parted perl perl-modules procps
  python-apt rsyslog stow sysv-rc sysvinit sysvinit-utils tzdata ucf udev
  util-linux
WARNING: The following essential packages will be removed.
This should NOT be done unless you know exactly what you are doing!
  sysvinit-utils:i386
0 upgraded, 89 newly installed, 8 to remove and 0 not upgraded.
Need to get 55.3 MB of archives.
After this operation, 134 MB of additional disk space will be used.
You are about to do something potentially harmful.
To continue type in the phrase  Yes, do as I say! 
 ?] Yes, do as I say! (actually type this!)
Get:1 http://debian.debian.zugschlus.de/debian/ wheezy/main e2fslibs amd64 1.42.5-1.1 [197 kB]
( )
Fetched 55.3 MB in 20s (2648 kB/s)                                            
perl: warning: Setting locale failed.
( )
This process may re-ask some debconf questions that you have already answered during initial system setup. I find it comforting to actually see that my answers were preserved, but you can always export DEBIAN_FRONTEND=noninteractive if you want installation to be silent. If you know how this step can be done more elegantly, please comment. We now, finally, have the resolver in a consistent state.
$ sudo apt-get -f install
Reading package lists... Done
Building dependency tree       
Reading state information... Done
The following packages were automatically installed and are no longer required:
  libasprintf0c2:i386 libcurl3-gnutls:i386 libfreetype6:i386 libfuse2:i386
  libreadline5:i386
Use  apt-get autoremove  to remove them.
0 upgraded, 0 newly installed, 0 to remove and 0 not upgraded.
$ dpkg --print-architecture
amd64
$ dpkg --print-foreign-architectures
i386
$ dpkg --list   grep i386   wc -l
121
$ dpkg --list   grep amd64   wc -l
119
$ 
Now we can force-crossgrade all i386 packages that are still left on the system. Again, we use the apt-get --download install, dpkg --install stunt as coreutils gets crossgraded at this step and dpkg is less than happy if it finds itself without /bin/rm. Remember, with --download, nothing is actually removed during this step even if apt-get claims to remove things. Apt will also complain that many of these packages are already installed. Those are libs that were pulled in previously. The first dpkg --install run in this step will complain about gazillions of dependency problems, which will all be resolved in concluding apt-get -f install after the second dpkg --install run, this time a manual one.
$ sudo apt-get --download-only install $(dpkg --list   awk  if( $1 ==  ii  && $4 ==
 i386  )   print $2     sed  s/:i386// )
Reading package lists... Done
Building dependency tree       
Reading state information... Done
( )
The following packages were automatically installed and are no longer required:
  libasprintf0c2:i386 libcurl3-gnutls:i386 libfreetype6:i386 libfuse2:i386
  libreadline5:i386
Use  apt-get autoremove  to remove them.
Suggested packages:
  powermgmt-base bash-doc bzip2-doc diffutils-doc wdiff mlocate locate
  gnupg-doc xloadimage imagemagick eog libpcsclite1 iproute-doc resolvconf
  avahi-autoipd nfs-common ncompress indent
Recommended packages:
  bsdmainutils gnupg-curl libatm1
The following packages will be REMOVED:
  anacron:i386 apt-utils:i386 base-files:i386 base-passwd:i386 bash:i386
( )
The following NEW packages will be installed:
  anacron apt-utils base-files base-passwd bash bsdutils busybox bzip2
( )
0 upgraded, 56 newly installed, 49 to remove and 0 not upgraded.
Need to get 24,1 MB of archives.
After this operation, 2.030 kB of additional disk space will be used.
Do you want to continue [Y/n]? y
Get:1 http://debian.debian.zugschlus.de/debian/ wheezy/main kmod amd64 9-3 [60,5 kB]
( )
Fetched 24,1 MB in 11s (2.120 kB/s)                                           
Download complete and in download only mode
$ sudo dpkg --install /var/cache/apt/archives/*.deb
(Reading database ... 17098 files and directories currently installed.)
Preparing to replace adduser 3.113+nmu3 (using .../adduser_3.113+nmu3_all.deb) ...
Unpacking replacement adduser ...
( )
Errors were encountered while processing:
 /var/cache/apt/archives/bash_4.2+dfsg-0.1_amd64.deb
 /var/cache/apt/archives/coreutils_8.13-3.5_amd64.deb
 initscripts
 lvm2
 procps
 rsyslog
 sysvinit
 sysv-rc
 udev
 util-linux
 aide-common
 dmsetup
 e2fsprogs
 ifupdown
 initramfs-tools
 libdevmapper1.02.1:amd64
 libdevmapper-event1.02.1:amd64
 libparted0debian1:amd64
 molly-guard
 openssh-server
 parted
 grub-common
 grub-pc
 grub-pc-bin
 grub2-common
$ sudo dpkg --install /var/cache/apt/archives/bash_4.2+dfsg-0.1_amd64.deb
/var/cache/apt/archives/coreutils_8.13-3.5_amd64.deb
(Reading database ... 17129 files and directories currently installed.)
Preparing to replace bash 4.2+dfsg-0.1 (using .../bash_4.2+dfsg-0.1_amd64.deb) ...
Unpacking replacement bash ...
Preparing to replace coreutils 8.13-3.5 (using .../coreutils_8.13-3.5_amd64.deb) ...
Unpacking replacement coreutils ...
Setting up bash (4.2+dfsg-0.1) ...
update-alternatives: using /usr/share/man/man7/bash-builtins.7.gz to provide /usr/share/man/man7/builtins.7.gz
(builtins.7.gz) in auto mode
Setting up coreutils (8.13-3.5) ...
$ sudo apt-get -f install
Reading package lists... Done
Building dependency tree       
Reading state information... Done
Correcting dependencies... Done
The following packages were automatically installed and are no longer required:
  libasprintf0c2:i386 libcurl3-gnutls:i386 libfreetype6:i386 libfuse2:i386
  libreadline5:i386
Use  apt-get autoremove  to remove them.
The following extra packages will be installed:
  sysvinit-utils
Suggested packages:
  bootlogd sash
The following packages will be REMOVED:
  libslang2-modules:i386 sysvinit-utils:i386
The following NEW packages will be installed:
  sysvinit-utils
WARNING: The following essential packages will be removed.
This should NOT be done unless you know exactly what you are doing!
  sysvinit-utils:i386
0 upgraded, 1 newly installed, 2 to remove and 0 not upgraded.
23 not fully installed or removed.
Need to get 0 B/99,5 kB of archives.
After this operation, 328 kB disk space will be freed.
You are about to do something potentially harmful.
To continue type in the phrase  Yes, do as I say! 
 ?] Yes, do as I say! (actually type this!)
dpkg: warning: overriding problem because --force enabled:
 This is an essential package - it should not be removed.
(Reading database ... 17129 files and directories currently installed.)
Removing sysvinit-utils ...
Selecting previously unselected package sysvinit-utils.
(Reading database ... 17105 files and directories currently installed.)
Unpacking sysvinit-utils (from .../sysvinit-utils_2.88dsf-41_amd64.deb) ...
Setting up sysvinit-utils (2.88dsf-41) ...
Setting up sysv-rc (2.88dsf-41) ...
Setting up initscripts (2.88dsf-41) ...
Setting up util-linux (2.20.1-5.3) ...
Setting up e2fsprogs (1.42.5-1.1) ...
Setting up sysvinit (2.88dsf-41) ...
sysvinit: restarting... done.
(Reading database ... 17129 files and directories currently installed.)
Removing libslang2-modules:i386 ...
Setting up ifupdown (0.7.8) ...
Setting up procps (1:3.3.3-3) ...
[ ok ] Setting kernel variables ... /etc/sysctl.conf...done.
Setting up udev (175-7.2) ...
[ ok ] Stopping the hotplug events dispatcher: udevd.
[ ok ] Starting the hotplug events dispatcher: udevd.
update-initramfs: deferring update (trigger activated)
Setting up rsyslog (5.8.11-3) ...
[ ok ] Stopping enhanced syslogd: rsyslogd.
[ ok ] Starting enhanced syslogd: rsyslogd.
Setting up aide-common (0.15.1-8) ...
Setting up initramfs-tools (0.109.1) ...
update-initramfs: deferring update (trigger activated)
Setting up openssh-server (1:6.0p1-4) ...
[ ok ] Restarting OpenBSD Secure Shell server: sshd.
Setting up molly-guard (0.4.5-1) ...
Setting up libdevmapper1.02.1:amd64 (2:1.02.74-7) ...
Setting up libdevmapper-event1.02.1:amd64 (2:1.02.74-7) ...
Setting up libparted0debian1:amd64 (2.3-12) ...
Setting up grub-common (1.99-27+deb7u1) ...
Setting up grub2-common (1.99-27+deb7u1) ...
Setting up grub-pc-bin (1.99-27+deb7u1) ...
Setting up grub-pc (1.99-27+deb7u1) ...
Installation finished. No error reported.
Generating grub.cfg ...
Found linux image: /boot/vmlinuz-3.9.4-zgsrv2008064
Found initrd image: /boot/initrd.img-3.9.4-zgsrv2008064
done
Setting up parted (2.3-12) ...
Setting up dmsetup (2:1.02.74-7) ...
update-initramfs: deferring update (trigger activated)
Setting up lvm2 (2.02.95-7) ...
[ ok ] Setting up LVM Volume Groups...done.
update-initramfs: deferring update (trigger activated)
Processing triggers for initramfs-tools ...
update-initramfs: Generating /boot/initrd.img-3.9.4-zgsrv2008064
Found 12 processes using old versions of upgraded files
( )
$ sudo apt-get -f install
Reading package lists... Done
Building dependency tree       
Reading state information... Done
The following packages were automatically installed and are no longer required:
  libasprintf0c2:i386 libcurl3-gnutls:i386 libfreetype6:i386 libfuse2:i386
  libreadline5:i386
Use  apt-get autoremove  to remove them.
0 upgraded, 0 newly installed, 0 to remove and 0 not upgraded.
$ dpkg --print-architecture
amd64
$ dpkg --print-foreign-architectures
i386
$ dpkg --list   grep i386   wc -l
72
$ dpkg --list   grep amd64   wc -l
175
$ 
We have completed the actual crossgrade. All non-multiarch packages are now amd64. The resolver is now fine as well. At this current state, all i386 packages that are still installed should be unneeded libs. We can safely nuke them. Careful minds may inspect the list of packages to be removed for important or non-lib items. After completion of the command, a second call of the same command verifies that we were successful.
$ sudo apt-get remove $(dpkg --list   awk  if( $1 ==  ii  && $4 ==  i386  )   print $2
  )
Reading package lists... Done
Building dependency tree       
Reading state information... Done
The following packages will be REMOVED:
  e2fslibs:i386 gcc-4.7-base:i386 libacl1:i386 libapt-inst1.5:i386
  libapt-pkg4.12:i386 libasprintf0c2:i386 libattr1:i386 libblkid1:i386
  libbsd0:i386 libbz2-1.0:i386 libc6:i386 libcap2:i386 libcomerr2:i386
  libcurl3:i386 libcurl3-gnutls:i386 libdb5.1:i386 libedit2:i386
  libexpat1:i386 libfreetype6:i386 libfuse2:i386 libgcc1:i386
  libgcrypt11:i386 libgdbm3:i386 libgnutls26:i386 libgpg-error0:i386
  libgpm2:i386 libgssapi-krb5-2:i386 libidn11:i386 libk5crypto3:i386
  libkeyutils1:i386 libkmod2:i386 libkrb5-3:i386 libkrb5support0:i386
  libldap-2.4-2:i386 liblockfile1:i386 liblzma5:i386 libmagic1:i386
  libncurses5:i386 libncursesw5:i386 libp11-kit0:i386 libpam-modules:i386
  libpam0g:i386 libpci3:i386 libpcre3:i386 libpng12-0:i386 libpopt0:i386
  libprocps0:i386 libreadline5:i386 libreadline6:i386 librtmp0:i386
  libsasl2-2:i386 libselinux1:i386 libsemanage1:i386 libsepol1:i386
  libsigc++-2.0-0c2a:i386 libslang2:i386 libsqlite3-0:i386 libss2:i386
  libssh2-1:i386 libssl1.0.0:i386 libstdc++6:i386 libtasn1-3:i386
  libtinfo5:i386 libudev0:i386 libusb-0.1-4:i386 libustr-1.0-1:i386
  libuuid1:i386 libwrap0:i386 linux-image-3.9.4-zgsrv2008064:i386 zlib1g:i386
0 upgraded, 0 newly installed, 70 to remove and 0 not upgraded.
After this operation, 67,5 MB disk space will be freed.
Do you want to continue [Y/n]? y
(Reading database ... 17111 files and directories currently installed.)
Removing e2fslibs:i386 ...
( )
$ sudo apt-get remove $(dpkg --list   awk  if( $1 ==  ii  && $4 ==  i386  )   print $2
  )
Reading package lists... Done
Building dependency tree       
Reading state information... Done
0 upgraded, 0 newly installed, 0 to remove and 0 not upgraded.
$ dpkg --print-architecture
amd64
$ dpkg --print-foreign-architectures
i386
$ dpkg --list   grep i386   wc -l
70
$ dpkg --list   grep amd64   wc -l
175
$ 
To finally make the packages really vanish from the system, we purge all packages that dpkg --list still reports in state rc , which means removed, configuration still present . Thankfully, dpkg seems to handle the case where a dpkg-conffile belongs to a transitioned package gracefully.
$ sudo dpkg --purge $(dpkg --list   awk  if ($1 ==  rc )   print $2  )
(Reading database ... 15868 files and directories currently installed.)
Removing e2fslibs:i386 ...
Purging configuration files for e2fslibs:i386 ...
( )
$ dpkg --print-architecture
amd64
$ dpkg --print-foreign-architectures
i386
$ dpkg --list   grep i386   wc -l
0
$ dpkg --list   grep amd64   wc -l
175
$ 
We now verify that all packages we have are either arch all or arch amd64.
$ dpkg --list   grep -v  \(amd64 all\) 
Desired=Unknown/Install/Remove/Purge/Hold
  Status=Not/Inst/Conf-files/Unpacked/halF-conf/Half-inst/trig-aWait/Trig-pend
 / Err?=(none)/Reinst-required (Status,Err: uppercase=bad)
 / Name                            Version                   Architecture Description
+++-===============================-=========================-============-========================================================================
As I found myself suddenly without e2fsprogs during one of my experiments, I check for e2fsprogs being present. If this package is missing, you ll only find out after rebooting.
$ dpkg --list e2fsprogs
Desired=Unknown/Install/Remove/Purge/Hold
  Status=Not/Inst/Conf-files/Unpacked/halF-conf/Half-inst/trig-aWait/Trig-pend
 / Err?=(none)/Reinst-required (Status,Err: uppercase=bad)
 / Name           Version      Architecture Description
+++-==============-============-============-=================================
ii  e2fsprogs      1.42.5-1.1   amd64        ext2/ext3/ext4 file system utilit
My locally built amd64 kernel with 32 bit support was an arch i386 package as well, so it got zapped in the migration process. Replace it with a real amd64 kernel. This step will vary if you use Debian kernels. Do not forget the firmwares.
$ sudo apt-get -t wheezy-zg-experimental install kernel-image-zgserver linux-firmware-image
Reading package lists... Done
Building dependency tree       
Reading state information... Done
The following extra packages will be installed:
  cpio initramfs-tools kernel-image-zgsrv20080 klibc-utils libklibc
  linux-image-3.9.4-zgsrv20080
Suggested packages:
  libarchive1
The following NEW packages will be installed:
  cpio initramfs-tools kernel-image-zgserver kernel-image-zgsrv20080
  klibc-utils libklibc linux-firmware-image linux-image-3.9.4-zgsrv20080
0 upgraded, 8 newly installed, 0 to remove and 0 not upgraded.
Need to get 11,2 MB of archives.
After this operation, 30,5 MB of additional disk space will be used.
Do you want to continue [Y/n]? 
Get:1 http://zg20110.debian.zugschlus.de/ wheezy-zg-experimental/main linux-image-3.9.4-zgsrv20080 amd64
3.9.4.20130605.0 [10,4 MB]
( )
I now make sure that the initrd I have built contains all file system modules and is of the right architecture:
$ cd /tmp
$ < /boot/initrd.img-3.9.4-zgsrv20080 gunzip   cpio -i
32053 blocks
$ find . -name  *ext*.ko 
./lib/modules/3.9.4-zgsrv20080/kernel/fs/ext3/ext3.ko
./lib/modules/3.9.4-zgsrv20080/kernel/fs/ext2/ext2.ko
./lib/modules/3.9.4-zgsrv20080/kernel/fs/ext4/ext4.ko
$ file ./lib/modules/3.9.4-zgsrv20080/kernel/fs/ext4/ext4.ko
./lib/modules/3.9.4-zgsrv20080/kernel/fs/ext4/ext4.ko: ELF 64-bit LSB relocatable, x86-64, version 1 (SYSV),
BuildID[sha1]=0x259a642448805c9597932ee25c62c8e6a00a32ad, not stripped
$ cd
As the last step, remove i386 as an architecture and reboot into the newly migrated system. We verify that the system considers itself amd64 with no foreign architectures.
$ sudo dpkg --remove-architecture i386
$ dpkg --print-architecture
amd64
$ 
$ dpkg --print-foreign-architectures
$ dpkg --list   grep i386   wc -l
0
$ dpkg --list   grep amd64   wc -l
181
$ sudo shutdown -r now
Broadcast message from root@wheezyarch (pts/0) (Wed Jun 12 16:09:24 2013):
The system is going down for reboot NOW!
$ Connection to wheezyarch.zugschlus.de closed by remote host.
Connection to wheezyarch.zugschlus.de closed.
$ ssh wheezyarch.zugschlus.de
Linux wheezyarch 3.9.4-zgsrv20080 #2 SMP PREEMPT Wed Jun 5 13:12:04 UTC 2013 x86_64
$ dpkg --print-architecture
amd64
$
We now check whether we have lost any packages in this process:
$ sudo dpkg --get-selections   grep install   awk  print $1    sed  s/:.*//;s/$/:amd64
install/;  > get-selections.post
$ wc -l get-selections.*
  234 get-selections.post
  226 get-selections.pre
$ diff --unified=0 get-selections.pre get-selections.post 
--- get-selections.pre  2013-06-12 19:47:40.278176000 +0200
+++ get-selections.post 2013-06-12 20:28:51.389874000 +0200
@@ -22,0 +23 @@
+cpio:amd64 install
@@ -58,0 +60 @@
+initramfs-tools:amd64 install
@@ -68,0 +71,3 @@
+kernel-image-zgserver:amd64 install
+kernel-image-zgsrv20080:amd64 install
+klibc-utils:amd64 install
@@ -108,0 +114 @@
+libklibc:amd64 install
@@ -163,0 +170,2 @@
+linux-firmware-image:amd64 install
+linux-image-3.9.4-zgsrv20080:amd64 install
So we have not actually lost things, but we have gained the pure amd64 kernel and the packages that are needed to build a proper initrd. These were missing from the initial install of the i386 test VM. The downside of the process is that we have lost most of the automatically installed markers in aptitude which make sure to remove a library once nothing depends on it any more. If you make a point in having those markers correctly set, as I do, this is tedious work to set it on every package in the aptitude curses interface, making aptitude suggest removing the entire system, and then again remove it from the packages you actually intend to keep. This should not result in anything being removed, otherwise you have goofed previously. All Done! I am now off perfecting my upgrade process so that the i386 lenny and squeeze machines can first be moved to wheezy and then to amd64.

Daniel Pocock: The week that everything changed

Last Wednesday, I felt an urge to carefully write out a list of all the possible characteristics that would make communications technology genuinely free. I felt this was important for a number of reasons: for example, to follow up on my earlier claim that free software does not always provide free communications, it is necessary to be able to measure the shortcomings against a perfect (although possibly unachievable) benchmark. Then something happened Just hours after my blog was live, The Guardian, a leading British newspaper (and contributor to open source) started publishing explosive allegations about the extent of US Government monitoring of communications. They kicked off a dramatic four days of coverage of this topic with the story that one of America's largest phone companies, Verizon, is secretly passing details of all customer phone calls and approximate locations (metadata) to the NSA. I've published further blog entries about this subject in the meantime. One thing I want to make clear: real friends tell each other the truth. There is no need to flatter America with gratitude for inventing the Internet when discussing these fundamental privacy failings. Anybody who has tried to generalise any comments about the NSA scandal as anti-American' is themselves failing to respect America's own principles of free speech. A doctor doesn't make up fairy tales for a patient diagnosed with cancer, he puts the facts on the table as that is the first step in making progress. The winds of change Activity on all my free communications web sites, especially Lumicall and OpenTelecoms.org has doubled. Google Play reports that the rate of Lumicall installations have also doubled - hopefully it is getting closer to the point where Metcalfe's Law kicks in and everybody will have federated SIP on their phone. What next One thing is clear: this situation provides a huge opportunity for anybody promoting free software, not just for communications. As I mentioned, web sites on the subject of free and private communications are attracting significant interest and I hope this rubs off on other projects. While I have contended that free software does not always provide free communications, there is a compelling argument for the case that you can't have free communications without having genuinely free software. Some of the developments that are coming up in the very near future: An upcoming release of DruCall, initially packaged for Debian and leveraging the libraries API packaging scheme, is going to make it much, much easier for the vast majority of web sites to offer a secure calling facility, without any third-party browser plugins required. Other CMS vendors such as xWiki are also working on WebRTC support. DebConf13 is aiming to feature a half-day track on Free real-time communications with a focus on the way free operating systems, particularly Debian (and it's derivatives like Ubuntu) are fundamental to rolling out an alternative to the status quo. Federated VoIP is also a confirmed feature of the upcoming Fedora 19 release and will eventually work it's way into EPEL. This is another great way for people who work in an RPM environment to start getting more active deploying SIP as a standard service in their environment. The real-time communication (RTC) quick-start guide is currently being updated and will include a convenient web-checker to help people test their federated connectivity. Can you help? Not sure where to begin? Come and join us on the Free RTC discussion list that has been sponsored by the FSF Europe or join the discussion list of one of your favourite free RTC applications.

Petter Reinholdtsen: Debian Edu interview: Jonathan Carter

There is a certain cross-over between the Debian Edu / Skolelinux project and the Edubuntu project, and for example the LTSP packages in Debian are a joint effort between the projects. One person with a foot in both camps is Jonathan Carter, which I am now happy to present to you. Who are you, and how do you spend your days? I'm a South-African free software geek who lives in Cape Town. My days vary quite a bit since I'm involved in too many things. As I'm getting older I'm learning how to focus a bit more :) I'm also an Edubuntu contributor and I love when there are opportunities for the Edubuntu and Debian Edu projects to benefit from each other. How did you get in contact with the Skolelinux / Debian Edu project? I've been somewhat familiar with the project before, but I think my first direct exposure to the project was when I met Petter [Reinholdtsen] and Knut [Yrvin] at the Edubuntu summit in 2005 in London. They provided great feedback that helped the bootstrapping of Edubuntu. Back then Edubuntu (and even Ubuntu) was still very new and it was great getting input from people who have been around longer. I was also still very excitable and said yes to everything and to this day I have a big todo list backlog that I'm catching up with. I think over the years the relationship between Edubuntu and Debian-Edu has been gradually improving, although I think there's a lot that we could still improve on in terms of working together on packages. I'm sure we'll get there one day. What do you see as the advantages of Skolelinux / Debian Edu? Debian itself already has so many advantages. I could go on about it for pages, but in essence I love that it's a very honest project that puts its users first with no hidden agendas and also produces very high quality work. I think the advantage of Debian Edu is that it makes many common set-up tasks simpler so that administrators can get up and running with a lot less effort and frustration. At the same time I think it helps to standardise installations in schools so that it's easier for community members and commercial suppliers to support. What do you see as the disadvantages of Skolelinux / Debian Edu? I had to re-type this one a few times because I'm trying to separate "disadvantages" from "areas that need improvement" (which is what I originally rambled on about) The biggest disadvantage I can think of is lack of manpower. The project could do so much more if there were more good contributors. I think some of the problems are external too. Free software and free content in education is a no-brainer but it takes some time to catch on. When you've been working with the same proprietary eco-system for years and have gotten used to it, it can be hard to adjust to some concepts in the free software world. It would be nice if there were more Debian Edu consultants across the world. I'd love to be one myself but I'm already so over-committed that it's just not possible currently. I think the best short-term solution to that large-scale problem is for schools to be pro-active and share their experiences and grow their skills in-house. I'm often saddened to see how much money educational institutions spend on 3rd party solutions that they don't have access to after the service has ended and they could've gotten so much more value otherwise by being more self-sustainable and autonomous. Which free software do you use daily? My main laptop dual-boots between Debian and Windows 7. I was Windows free for years but started dual-booting again last year for some games which help me focus and relax (Starcraft II in particular). Gaming support on Linux is improving in leaps and bounds so I suppose I'll soon be able to regain that disk space :) Besides that I rely on Icedove, Chromium, Terminator, Byobu, irssi, git, Tomboy, KVM, VLC and LibreOffice. Recently I've been torn on which desktop environment I like and I'm taking some refuge in Xfce while I figure that out. I like tools that keep things simple. I enjoy Python and shell scripting. I went to an Arduino workshop recently and it was awesome seeing how easy and simple the IDE software was to get up and running in Debian compared to the users running Windows and OS X. I also use mc which some people frown upon slightly. I got used to using Norton Commander in the early 90's and it stuck (I think the people who sneer at it is just jealous that they don't know how to use it :p) Which strategy do you believe is the right one to use to get schools to use free software? I think trying to force it is unproductive. I also think that in many cases it's appropriate for schools to use non-free systems and I don't think that there's any particular moral or ethical problem with that. I do think though that free software can already solve so so many problems in educational institutions and it's just a shame not taking advantage of that. I also think that some curricula need serious review. For example, some areas of the world rely heavily on very specific versions of MS Office, teaching students to parrot menu items instead of learning the general concepts. I think that's very unproductive because firstly, MS Office's interface changes drastically every few years and on top of that it also locks in a generation to a product that might not be the best solution for them. To answer your question, I believe that the right strategy is to educate and inform, giving someone the information they require to make a decision that would work for them.

11 June 2013

Daniel Pocock: Interrupt-free computing

On debian-devel, there has been a discussion about the security issues of "spontaneously" appearing popups demanding the root password to make immediate security updates. There is a much more general issue related to this: computing without interruptions. Most of us have probably seen some friend or acquaintance with a (usually non-Linux) PC that is constantly beeping and flashing with chat notifications, new email popups, Adobe update this, Java update that, etc. In one recent case I came across somebody who had experienced a dramatic drop in his productivity as a consequence - giving him a laptop with a freshly installed copy of Linux made a dramatic difference to his work. I can already hear people insisting that security trumps everything (which isn't an original argument either) and that popups can't be avoided. A search on the web for "computing without interruptions" reveals users have a particular distaste for these things appearing while watching a video. Websites responding to that complaint fill the search results. With many types of interactive real-time content (video, WebRTC phone/video calls and so on) deployed within browsers, it is even more important for UI designers to contemplate when it is not appropriate to interrupt a user and to do everything possible to avoid interrupting the user. Preparing for disaster On the other hand, just ignoring security updates and not telling the user their disk is filling until 0 bytes remain available could only shift the problem down the road (from constant annoyance to periodic crisis). That said, sometimes you can still fill the disk very suddenly (especially with fast SSDs) and rather than relying on popups to keep users away from the precipice, applications (particularly the core desktop and daemon processes) could be tested more regularly to ensure they remain resilient in full disk situations. Managing information overload Popups are just part of a wider problem of information overload. There are emails too: some applications, such as Drupal, will send daily or weekly emails to a user if their system is not up to date. For many virtual-hosted sites, this starts to resemble a small flood. There is a flaw in this design: applications are competing for attention by sending more and more emails and popups or making them more annoying (e.g. the security updates in Debian 6 were ignorable popups in the top right-hand corner of the screen, Debian 7's Gnome Classic mode displays a big password prompt in the middle of the screen). The solution would be to develop a mechanism for unifying, de-duplicating and then prioritising these information/event flows. Some fault alerting systems already do this for their own events - these are niche solutions that aren't always applicable to the average PC-owner, although the principles are well tested. Some email organisation tools have similar features, but only for email. I'm not currently aware of any solution that synthesizes such an experience for all possible information sources. Setting priorities One well-read work on this subject in the business world is The 7 Habits of Highly Effective People (Stephen R. Covey, 1989). Of particular interest for the problem at hand is the priority matrix (borrowed from the Eisenhower Method): The left column, Urgent items, typically must be executed by a certain date (e.g. buying a gift before a birthday or installing a new SSL certificate before the old one expires). A security update or Acrobat reader update does not have this same characteristic. Under this model:
Urgent Non-urgent
Important Replace SSL certificate
Buy birthday gift
Security update
Run backup job
Not important Register for conference before deadline for free gift Non-security update for Acrobat reader
Covey even released an Outlook plugin, Plan Plus to help people organise their tasks (and their lives) using his methodology. Unfortunately it is closed-source software with a terrible set of ratings on Amazon - this review from a customer stands out: "My take is that Franklin does not consider robust software nor customer support to be either Urgent or Important." Could this be replicated more successfully with an open-source plugin for Mozilla Lightning or a similar productivity tool, and could the concept be extended across the range of data sources, including email, calendar items, system notifications and more to provide a unified approach to both the computing platform and general productivity (real-life) time management? Would this help solve the same problem in a more effective manner? In other words, would such an effort to help users integrate the demands of technology with the other demands of life make them more likely to keep their systems up to date? The wider community experience Going beyond the desktop/user experience, could this model be extended to automatically integrate external tasks, such as handling bug reports, moderating mailing lists and other slightly tedious things that have to be given regular attention to keep the free-software world moving along smoothly? Managing down-time For people who work in computing, there is almost no down-time any more. Even when on holiday, checking in for a flight might involve navigating through a buggy wifi access control system and an annoying set of advertisements from your low-cost airline as you try to print a boarding pass. These things often trigger thoughts about similar issues on client projects. Glancing at your email to find the booking number could awaken thoughts of a whole lot of projects you had tried to put out of your mind for a week. This is another area where excessive popups and emails can only compound the problem. Who really wants to download and install security updates while on holiday using an intermittent wifi connection? Managing all these events through a common mechanism may also finally make it possible to have an "ordinary user" experience with your PC. In practice, this might mean being able to view information/events through a time-of-day filter or "holiday mode" - and only on demand. A worthy design goal? Would any free software operating system make it a design goal to give their users a 100% interrupt-free experience? Of course there would still be things like chat notifications - but those would only be possible when a user has signed-in to a chat application. The distinction for the interrupt-free experience would only need to apply to default system behavior and not to every application.

9 June 2013

Paul Tagliamonte: Automatically lint your packages with debuild.me

Over my time working with Debian packages, I've always been concerned that I have been missing catchable mistakes by not running all the static checking tools I could run. As a result, I've been interested in writing some code that automates this process, a place where I can push a package and come back a few hours later to check on the results. This is great, since it provides a slightly less scary interface to new packagers, and helps avoid thinking they've just been told off by a Developer. I've spent the time to actually write this code, and I've called it debuild.me. The code itself is in its fourth iteration, and is built up from a few core components. The client / server code (lucy and ethel) are quite interconnected, but firehose works great on it's own, and is a single, unified (and sane!) spec that is easy to hack with (or even on!). Hopefully, this means that our wrappers will be usable outside of debuild.me, which is a win for everyone. Backend Design The backend (lucy) was the first part I wanted to design. I made the decision (very early on) that everything was going to be 100% Python 3.3+. This lets me use some of the (frankly, sweet) tools in the stdlib. Since I've written this type of thing before (i've tried to write this tool many, many, many, many times before), so I had a rough sense of how I wanted to design the backend. Past iterations had suffered from and overly complex server half, so I decided to go ultra minimal with the design of debuild.me. <aside class="left"> You can find the code for the server (lucy) on my GitHub </aside> The backend watches a directory (using a simple inotify script) and processes .changes files as they come in. If the package is a source package, a set of jobs are triggered (such as lintian, build and desktop-file-validate), as well as a different set for binary packages (such as lintian, piuparts and adequite). Only people may upload source packages (without any debs) and only builders can upload binary packages (without source). The client and server talk using XML-RPC with BASIC HTTP auth. I'm going to (eventually) SSL secure the transport layer, but for now, this will work as a proof of concept. Since I tend to like to keep my codebase simple and straightforward, I've used MongoDB as Lucy's DB. This lets me move between documents in Mongo to Python objects without any trouble. In addition, I evaluated some of the queue code out there (ZMQ, etc), and they all seemed like overkill for my problem, and had a hard time keeping track of jobs that (must never!) get lost. As a result, I wrote my own (very simple) job queue in Mongo, which has no sense of scheduling (at all), but can do it's job (and do it well). Jobs describe what's to be built with a link to the package document that the job relates to, and it's arch and suite (don't worry about the rest just yet). Jobs get assigned via natural sort on it's UUID based _id, and assigned to the first builder that can process it's arch / suite. Source packages are considered arch:all / suite:unstable (so they always get the most up-to-date linters on any arch that comes along). Lucy also allows for uploads to be given an X-Lucy-Group tag to manage which set of packages they're a part of. This comes in handy for doing partial archive rebuilds, or eventually using it to manage what jobs should be run on which uploads. This will allow me to run much more time-consuming tools for packages I want to review versus rebuilding to ensure packages don't FTBFS or aren't adequite. Client Design The buildd client (ethel) talks with lucy via XML-RPC to get assigned new jobs, release old jobs, close finished jobs, and upload package report data. When the etheld requests a new job, it also passes along what suites it knows of, which arches it can build, as well as what types it can run (stuff like lintian, build or cppcheck.) Lucy then assigns the builder to that job (so that we don't allocate the same job twice), and what time it was assigned at. <aside class="right"> You can find the code for the client (ethel) on my GitHub </aside> Ethel then takes the result of the job (in the form of a firehose.model tree) and transmits it over the line back to the Lucy server as a report (which also contains information on if the build failed or not), at which point lucy hands back a location (on the lucy host) that the daemon can write the log to. If the job was a binary build, the etheld process will dput the package to the server, with a special X-Lucy-Job tag to signal which job that build relates to, so that future lint runs can fetch the deb files that the build produced. Tooling Ethel runs a set of static checkers on the source code, which are basically fancy wrappers around the tools we all know and love (like lintian, desktop-file-validate, or piuparts) which output Firehose in place of home-grown stdout. This allows us to programmatically deal with the output of these tools in a normal and consistent way. <aside class="left"> You can read more about Firehose over in the Firehose README.rst </aside> Some of the more complex runners are made of 3 parts - a runner, wrapper and command. The server invokes the command routine, which invokes the runner (the command just provides a unified interface to all the runners), who's output gets parsed by the wrapper to turn it into a Firehose model tree. The goal here is that tons of very quick-running tools get run over a distributed network, and machine-readable reports get filed in a central location to aid in reviewing packages. Ricky In addition to the actual code to run builds, I've worked on a few tools to aid with using debuild.me for my DD related life. I have some uncommon use-cases that are nice to support. One such use-case is the ability to rebuild packages from the archive (unmodified) to check that they rebuild OK against the target. This is handy for things like arch:all packages that get uploaded (since they never get rebuilt on the buildd machines, and FTBFSs are sadly common) or packages that have had a Build-Dependency change on them. Ricky is able to create a .dsc url to your friendly local mirror, and fetch that exact version of the package. Ricky can then also use the .dsc (in a monumental hack) to forge a package_version_source.changes file, and sign it with an autobuild key and upload it to the debuild.me instance. Since it can also modify the .changes's target distribution, you can also use this to test if a package will build on stable or testing, unmodified. Fred Fred is a wrapper around Ricky, to help with fetching packages that may not exist yet. Fred also contains an email scraper to read off such lists as debian-devel-changes, and add an entry to fetch that upload when it becomes available on the local mirror, pass it to ricky, and allow debuild.me to rebuild new packages that match a set of criteria. I'm currently playing around with the idea of rebuilding all incoming Python packages to ensure they don't FTBFS in a clean chroot. Loofah Loofah is also another wrapper around Ricky, but for use manually. Loofah is able to sync down the apt Sources list, and place it in Mongo for fast queries. This than allows me to manually run rebuilds on any Source package that fits a set of critera (written in the form of a Mongo query), which get pulled and uploaded by Ricky. An example script to rebuild any packages that Build-Depend on python3-all-dev in Debian unstable / main would look like: <aside class="right"> You can find more queries in the Loofah examples </aside>
[
      "version": "unstable", "suite": "main"  ,
      "Build-Depends": "python3-all-dev"  
]
Or, a script to rebuild any package that depends on CDBS:
[
     ,
     "$or": [ "Build-Depends": "cdbs" ,
              "Build-Depends-Indep": "cdbs" ] 
]
You can use anything that exists in the Sources.gz file to query off of ( including Maintainer!) Future Work The future work on debuild.me will be centered around making it easier for buildd nodes to be added to the network, with more and more automation in that process (likely in the form of debs). I also want to add better control over the jobs, so that packages I upload only go to my personal servers. I'd also very much like to get better EC2 / Virtualization support integrated into the network, so that the buildd count grows with the queue size. This is a slightly hard problem that I'm keen to fix. I'm also considering moving the log parsing code out of the workers, so that the parsing code can be fixed without upgrading all the workers. This would also drop the Firehose dep on the client code, which would be nice. Migration from a debuild.me build into a local reprepro repo is something that would be fairly easy to do as well, likely to be done remotely via the XML-RPC interface, which calls a couple of reprepro commands (such as includedsc and includedeb) and publishes it to the user's repo. This is a nice use of the debs that get built, and could also allow debuild.me to be used like a PPA system, but this allows the user to not migrate packages that may contain piuparts issues.

8 June 2013

Michael Stapelberg: Survey answers part 1: systemd has too many dependencies, or it is bloated, or it does too many things, or is too complex

This blog post is the first of a series of posts dealing with the results of the Debian systemd survey. I intend to give a presentation at DebConf 2013, too, so you could either read my posts, or watch the talk, or both :-). The top concern shared by most people is:
systemd has too many dependencies, or it is bloated, or it does too many things, or is too complex
Now this concern actually has a lot of different facets, and I am trying to share my opinion on each of them. systemd has too many dependencies First, let s start with too many dependencies , because that is easy to check and reason about. I have created a document which lists all dependencies of the systemd binary itself (pid 1) and all the binaries which are currently shipped by the systemd Debian package. If you don t want to take my word for granted, please read that document. Have you read the document? Very nice! As you can see, the systemd binary itself has 10 dependencies (excluding libc). Now, the question is, what is bad about dependencies? Why do people list dependencies as a top concern?
  1. Cyclic dependencies. When you hear that your init system depends on DBus, you might argue that there is a cyclic dependency here, because DBus needs to be started by the init system. However, systemd does NOT depend on dbus-daemon (!) to boot your machine. Instead of using the system bus, it uses a private UNIX socket. Therefore, systemd uses DBus merely as a serialization format for IPC between its different processes. Only when you want to access systemd via its API as a user (non-root), you actually use the system bus. Since we are talking about DBus: DBus provides a well-tested serialization format and IPC mechanism so that systemd doesn t have to reinvent the wheel and instead benefits from wide support within languages.
  2. Complicated code. I feel like there is the implicit assumption that lots of dependencies correlate with complicated code that is easy to break. I encourage you to have a look at systemd s source code: look for the places where specific libraries are used, e.g. enforce_user which uses libcap. You ll notice that the code is not complex and usage of the libraries is clear.
  3. Software dragging in lots of library packages. The libraries which systemd uses are already in widespread use (e.g. DBus, udev, selinux, libcap, pcre, ). On a typical Debian installation, only very few of them will be dragged in by systemd, if at all. As an example, on a fresh Debian Wheezy installation, less than 10 packages will end up on your machine when running apt-get install systemd .
  4. More memory use. The Linux kernel maps libraries into memory only once, no matter how many processes use them. As stated in the dependency list, on machines where the libraries are not already loaded, systemd brings in about 500 KiB of additional memory-mapped libraries in the worst case. On the machines we have these days, this is a reasonable cost to pay for all the benefits systemd gets us. This holds true on embedded systems with only a few MiB of RAM and especially on typical workstations with 8+ GiB of RAM.
systemd is bloated Now, let s talk about bloat. Again, this is a point which has many facets. I d like to quote the Wikipedia definition of software bloat:
Software bloat is a process whereby successive versions of a computer program become perceptibly slower, use more memory or processing power, or have higher hardware requirements than the previous version whilst making only dubious user-perceptible improvements.
The first part of the definition certainly does not match systemd it is measurably faster than sysvinit. As for memory usage: systemd s RSS is 1.8 MiB, whereas sysvinit uses 0.8 MiB. As I argued on the More memory use point in the dependencies section, I think the additional resource cost is well worth the benefits. Also note that systemd s features are NOT all implemented in the binary which is PID 1. As explained in the dependency list, systemd consists of many cleanly separated binaries. So if a new version of systemd gathers an additional feature, this does not mean that your PID 1 will be bigger. While systemd runs on any hardware, it has an indirect hardware requirement: it requires some Linux kernel features (which are all enabled in Debian kernels). That might rule out usage of systemd on really old embedded hardware where you don t have a chance to update the kernel. While it is sad that those machines cannot profit from systemd, switching to systemd as a default has no downside either: Debian continues to support sysvinit for quite some time, so these machines will continue to work even with upcoming Debian versions. systemd does too many things The Wikipedia definition continues:
[ ] perceived bloat can occur from the software servicing a large, diverse marketplace with many differing requirements. Most end users will feel they only need some limited subset of the available functions and will regard the others as unnecessary bloat, even if people with different requirements do use them.
I think the last part of the Wikipedia definition applies to systemd: it does service a large and diverse marketplace . That marketplace is the entirety of existing software which is started by an init system. Also, systemd can be used on a wide range of hardware (embedded devices, tablets, phones, notebooks, desktops, servers) which requires different features. As an example: on a desktop system you typically don t care strongly about a watchdog feature, but on embedded or servers that feature is very handy. Similarly, on a tablet, forward secure sealing of logfiles is not as important as on a server. Therefore, I can understand if you feel that you don t need many of the features systemd provides. But please think of other users and maintainers who are very happy with systemd s benefits. Also note that while systemd supports many things (in separate binaries!), you don t have to use them all. It still makes sense to ship them all in the same package. Take coreutils as another example in that area. The binaries belong together, even though you most likely haven t used all of them (e.g. od, pr, ptx, :-)). systemd is too complex The remaining concern is that systemd is too complex. In my experience, complexity is often inherent to a specific area and one cannot simply make it go away. Instead, there are different models of how that complexity is represented. Think of the monolithic Linux kernel versus the MINIX microkernel. The latter has a very small amount of lines of source in the kernel, but puts the complexity into userspace. The former uses a different approach with more source in the kernel. The arguments between both camps show that neither is clearly right or clearly wrong. In a way, sysvinit represents the MINIX model: it has a small core (the init binary itself), but a lot of complexity in shell scripts and external programs. The fact that solutions are copied from one init script to another leads to lots of subtle errors and makes code reuse really hard. systemd however has more source code in the binaries, but requires only very simple, descriptive, textual configuration instead of complex init scripts. To me, it seems preferable to have the complexity in a single place instead of distributed across lots of people and projects. Conclusion In a way, you are right. systemd centralizes complexity from tons of init scripts into a single place. However, it therefore makes it very easy for maintainers to write service files (equivalent of an init script) and provides a consistent and reliable interface for service management. Furthermore, it is different than sysvinit, and different solutions often seem complex at first. While systemd consumes more resources than sysvinit, it uses them to make more information available about services; its finer-grained service management requires more state-keeping, but in turn offers you more control over your services.

Daniel Pocock: Rendition link to PRISM

The Guardian is reporting that Britain's GCHQ first started getting produtive with PRISM early 2012. It was about the same time that their buddies down under, ASIO revised their earlier assessment of a refugee, Ranjini, and scooped her up in Australia's domestic rendition program. This may be more than a notable co-incidince, because it adds further support to the hypothesis that Ranjini is a victim of Big Data and PRISM. If ASIO first gained access to PRISM at the same time as GCHQ, then they may have used some tenuous PRISM data to form their revised assessment of her suitability for a visa. Making such inferences, and using them as the basis for a cruel program of indefinite detention is a gross violation of human rights and goes far beyond the claim that PRISM is about catching real terrorists. I've previously mentioned the systematic persecution of coloured people in my own country. Like many honest people, I'm utterly ashamed of it. The Government also has similar programs for indigineous people (they cooked one aboriginal elder alive on our national holiday) and they've also toyed with outlawing homosexuality. Having seen first hand some of the prejudiced, Government-sanctioned evil that exists in Australia, it's not hard to imagine small-minded members of the public service using PRISM data to target these classes of people for an unhealthy dose of bastardisation. Ranjini was ripped away from her husband by the rendition program and dumped in Sydney's Villawood death camp. Twenty-four hours after the gestapo got their hands on her, it was discovered she was pregnant - her child, an Australian citizen, was recently born and confined to the same concentration camp. Ranjini has racked up more than 12 months in captivity now, most of it while pregnant, and the Government has still not made any official charges against this woman. They say they can't comment on her case for fear of revealing their sources: once again, they don't want to talk about programs like PRISM that they share with the US. Maybe she just had one of the wrong people in her facebook friends list? That is not the sort of evidence that can be used to convict somebody in court, especially if the Government wants to avoid public questioning about their access to a close ally's secret database. Various rapists and murderers have made multiple court appearances in the last 12 months, tried and convicted in accordance with the procedures of justice. Ranjini has not been brought into a court room even once because the spooks don't want to reveal their sinister sources like PRISM.
Potential PRISM victim Ranjini
Australia's close ties with the US Australia has had particularly close ties with the US for many years and just as the British GCHQ has been linked to PRISM, it seems Australia's ASIO is also in on the act. For those not familiar with the depth of this alliance, it is worth checking up on Pine Gap, the ECHELON program and the recent exposure (by Wikileaks) of one of our senators with unauthorised US spy connections - he quietly resigned for family reasons'. Pine Gap
Pine Gap, Australia This is not to say that the US is universally bad or that the strategic alliance is undesirable: rather, it is simply to demonstrate the strength of these links and the real risk that data-sharing is used for inappropriate purposes. While many of us in a technical field treat large volumes of data from a very theoretical perspective, it is worth remembering that in the wrong hands, data can be very dangerous and there are real human victims.

Thorsten Glaser: Waypoint Statistics

mirabilos  found waypoints I ve finally gotten around to listing all Waypoints (Geocaches, Opencaches, Closedcaches, Earthcaches, Terracaches including Locationless, Navicaches, etc.) I ve found a box, enjoyful, educating, a good place to hide one myself, etc. and putting up a list and, of course, generate my own statpic.

I ll put them up for the other project members, too (already made a picture for gecko2@ but bsiegert@ still needs one; we also need to collect offline lists of found, owned and attended waypoints) A bit of background story: I decided, years ago, to have an offline list of cache finds in case something would happen. Just, I had found way too many already, so this was a huge bit of work. Oh well I of course procrastinated, and then something did happen (Opencaching wanting to force a Restricted Commons licence; me disagreeing and suggesting a change; some trigger-happy person immediately deleting my account without waiting for the discussion or the decision period to end; weeks of forum discussions; Opencaching allowing dual-licencing; them telling me they can t restore my data probably never heard of databa sorry, MySQL backups). And I still didn t have the list. Now I do; recreated even the OC information from what was still accessible and with help from one OC supporter ( mic@ , thanks); merged caches that are co-listed on several platforms, etc. (still need to put in the FTF/STF/TTF/4TF/LTF and voting/favourites information) and a statpic, all in Open Source and Open Data, in cvs(1) with mksh(1) and a frontend for libgd2 I admit, but we had been using that for the MirWebsite for a while already. I suggest every geocacher keep an offline or local record of all their finds (and hides and attended logs) for things like this, in case some platform decides to let s say, put your data into the cloud where it is? I don t know .

6 June 2013

Olivier Berger: New paper Authoritative linked data descriptions of debian source packages using ADMS.SW accepted at OSS 2013

I ll be presenting Authoritative linked data descriptions of debian source packages using ADMS.SW at OSS 2013. Here s the abstract :
The Debian Package Tracking System is a Web dashboard for Debian contributors and advanced users. This central tool publishes the status of subsequent releases of source packages in the Debian distribution. It has been improved to generate RDF meta-data documenting the source packages, their releases and links to other packaging artifacts, using the ADMS.SW 1.0 model. This constitutes an authoritative source of machine-readable Debian facts and proposes a reference URI naming scheme for Linked Data resources about Debian packages. This should enable the interlinking of these Debian package descriptions with other ADMS.SW or DOAP descriptions of FLOSS projects available on the Semantic Web also using Linked Data principles. This will be particularly interesting for traceability with upstream projects whose releases are packaged in Debian, derivative distributions reusing Debian source packages, or with other FLOSS distributions.
If you are interested, a previous paper which describes the same experiment is available online. See also previous installments on ADMS.SW in this blog.

5 June 2013

Daniel Pocock: The Gold Standard in Free Communications Technology

In a previous blog entry, I posed the question whether open source communications software is really free and came to the conclusion that additional principles need to be defined for free communications, above and beyond the normal expectations of free software. This is a fundamental problem that projects like the FreedomBox, Lumicall and other privacy-enabling free communications solutions must be familiar with. Otherwise there is a risk that development will never end as there is no finish line in sight. Practical solutions are not so easily defined though: so let's just imagine a perfect solution for a moment. Later, we can contemplate the trade-offs that are necessary to make it practical. Perfect privacy Here are some attributes that may exist for a perfect solution: Privacy must be the default: the user should not have to explicitly request privacy. If there is a risk that an incoming communication will establish a session without full privacy, the user should be able to decline the opportunity to participate. Only participants to a communication can receive the communication A third party should not be able to replay, modify or forge any aspect of the communication or the request to initiate a session Only participants to a communication are aware that a communication occurred Only participants to the communication are aware of who participated in the communication A participant may be anonymous: but in this case, all other participants will be aware that there is an anonymous party present in the communication Participants may not deduce any information about the other participants that is not explicitly shared (e.g. location, type of device, service provider) In the case of real-time communication, a participant may leave the communication without any other party even realising that they left or why. Communication is off-the-record: No participant can save and reproduce a copy of the communication in such a way that a third-party will know it was authentic. Anonymous reception of communications - the perfect post-office box: someone may create an anonymous identifier that allows other people to call them without being able to trace their location or identity Some consequences of a perfect solution Just imagine if all communications worked in this manner. There are many potential consequences. For example, if you call somebody and the call is not connected, you will get no feedback about whether their line is busy, out of service or whether they deliberately chose to reject your call. Another example is somebody who is driving while talking on a telephone. If they have an accident, there will be no way to prove that they were using the phone. This may already be the case if somebody uses a VoIP app on their phone - the police investigating the accident later will simply find no records of calls through the mobile phone account. Conclusion The perfect solution described here is something of a holy grail rather than a recipe that a developer can implement. It is unlikely that such a solution will fall out of the sky in the immediate future. Most software products that offer secure communications only address less than half the issues described above: for example, digital mobile phones prevent eavesdropping with arbitrary radio receivers, but they don't prevent shops detecting the IMEI (serial numbers) of phones that pass through their store and using that information to identify repeat visits to their store.

Guido G nther: Calendar synchronisation between Nokia N900 and the Calypso CalDAV server

One of the replies to the post about Debian's last groupware meeting was from Patrick Ohly of syncevolution fame pointing out that syncevolution already implements calendar autodetection for CalDAV calendars as described in draft-daboo-srv-caldav-10. While looking at the code I noticed that there's a backend for the N900s calendar by Ove K ven as well. When I tried Ove's latest package on my N900 it lead to an immediate crash when doing a:
syncevolution --print-items target-config@webdav calendar
According to Patrick the bug was supposed to be fixed in recent versions so I set up scratchbox and built a newer git snapshot for maemo (sources). This wouldn't crash but didn't show up any items either. It turned out to be a minor bug in calypso returning no content type for REPORT queries which resulted in libneon discarding the whole reply (now already fixed in calypso upstream). With this out of the way setting up synchronisation is quiet simple:
# Configuration
CALDAV_SERVER=192.168.0.10
syncevolution --configure username=<username> password=<password> \
              calendar/backend=caldav calendar/database=https://$ CALDAV_SERVER :5233/private/my_calendar \
              target-config@webdav calendar
syncevolution --configure --template SyncEvolution_Client sync=none syncURL=local://@webdav username= password= webdav
syncevolution --configure sync=two-way backend=calendar webdav calendar
You should then be able to print the items on the local (N900) and from the remote (CalDAV server) end:
# This lists the current calendar items on the server
syncevolution --print-items target-config@webdav calendar
# This lists the current calendar items on the N900
syncevolution --print-items @default calendar
And from there on sync away:
# initial slow sync
syncevolution --sync slow webdav
# from there on
syncevolution webdav
The syncevolution source code has great documentation about debugging problems (e.g. src/backends/webdav/README). So check that in case you run into problems. The tl;dr version is
SYNCEVOLUTION_DEBUG=1 src/syncevolution loglevel=10 --print-items target-config@webdav calendar
to debug CalDAV related problems. In case you need to run syncevoluton from source be sure to set these beforehand:
export SYNCEVOLUTION_TEMPLATE_DIR=$PWD/src/templates/
export SYNCEVOLUTION_XML_CONFIG_DIR=$PWD/src/syncevo/configs/
On the CalDAV side I used current Calypso git which (with some additional minor fixes) now also interoperates nicely with Iceowl/Icowl-Extension aka Sunbird/Lightning on the desktop side. There's also an ITP for it. So it'll hopefully end up in Debian soon.

Next.

Previous.