Search Results: "spa"

29 October 2013

Eddy Petrișor: The stupidest trend in laptop design is...

... numpads on laptop keyboards.

Just because a very, very, very restricted segment of the population is into accounting or other jobs needing frequent numeric input, almost all laptop manufacturers feel the stupid urge to place a numpad on laptops with screens over 14''.

Reasons why a numpad on a laptop is a bad idea:
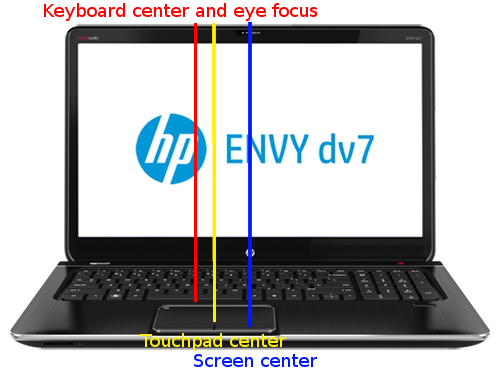
The numpad forces eye focus and users' hands to be way off center.
The touchpad looks as if it was thrown to the side by accident
Note how the designer tried to offset the misalignment forced
by the numpad by "positioning" the touchpad closer to center,
but not in line with the space bar (and the keyboard)

Without numpad the position is almost perfect!
The symmetry of the laptop improves on the design.
Notice how the touchpad is also centered.


What's worse is that most resellers do not have filters for this particular mis-feature, so you can't easily exclude laptops corrupted by this horrendous idea.

So, if you're a laptop designer, please stop putting numpads on laptops.

It will make for better looking laptops and you'll have the opportunity to be the one stating the obvious: numpads are generally useless! Even on desktop keyboards!

Matthew Palmer: Why Your Puppet Module Sucks

I use Puppet a lot at work, and I use a lot of modules written by other people, as well as writing quite a number of my own. Here s a brief list of reasons why I might say that your module sucks.

1. You use global variables This would have to be both the most common idiom that just makes my teeth grind. Defined types exist for a bloody reason. Global variables make it incredibly difficult to reason about what is going to happen when I use a particular global variable (see also You don t write documentation ), and I get no feedback if I typo a global variable name. Add in a healthy heaping of lack of namespacing , and you ve basically guaranteed that your module will be loudly cursed.

2. You use parameterised classes I ve never managed to work out why parameterised classes even exist. They ve got all the problems of regular classes, as well as all the problems of types. There was a fantastic opportunity with parameterised classes to fix some of the really annoying things about regular resources, such as doing conflict checking on parameters and only barfing if there was a conflict but no, if you define the same class twice, even with identical parameters, Puppet will smack you on the hand and take away your biscuit. FFFFFFUUUUUUUUUUUU-

3. You fail at using fail() Modules are supposed to be reusable. That s their whole reason for existence. One of the benefits of Puppet is that you can provide an OS-independent interface for configuring something. However, unless you re some absolute God of cross-platform compatibility, you will only be writing your module to support those OSes or distros that you, personally, care about. That s cool if you don t know anything about OS X, you probably shouldn t be guessing at how to support something on that platform anyway. However, when you do have some sort of platform-specific code, for the love of pete, have a default or else clause that calls fail() with a useful and descriptive error message, to indicate clearly that you haven t included support for whatever environment the module s being used in. Failing to do this can cause some really spectacular explosions, because the rest of your module assumes that certain things have been done in the platform-specific code, and when it hasn t hoo boy.

4. You don t write documentation Yes, it isn t easy to write good documentation. I know that. But without documentation, your module is going to be practically unuseable. So if you don t have docs, your module is basically useless. Well done, you.

5. You have undeclared dependencies This also includes declaring your dependencies in a non-machine-parseable manner; I m not going to grovel through your README for the list of other modules I might need; I have machines to do that kind of thing for me. If I try to use your module, and it craps out on trying to reference some sort of type or class that doesn t appear at all related to your module, I will call into question your ancestry, and die a little more inside.

6. You use common packages without even trying to avoid the pitfalls OK, to be fair this is, ultimately, Puppet s grand fuckup, not yours, but you at least need to pretend to care There is no sane, standardised way in Puppet for multiple modules to install the same package. Let s say that a module I write needs to have a compiler. So I package "gcc": . Then someone else s module also wants a compiler, so it also package "gcc": . FWAKOOM! says Puppet. What the fuck? says the poor sysadmin, who just wanted both a virtualenv and an RVM environment on the one machine. Basically, using packages is going to make your module suck. Does that mean that this makes wide distribution of a large repository of modules written by different people nigh-on impossible? Yes. Fantastic.

Matthew Palmer: Why Your Puppet Module Sucks

I use Puppet a lot at work, and I use a lot of modules written by other people, as well as writing quite a number of my own. Here s a brief list of reasons why I might say that your module sucks.

1. You use global variables This would have to be both the most common idiom that just makes my teeth grind. Defined types exist for a bloody reason. Global variables make it incredibly difficult to reason about what is going to happen when I use a particular global variable (see also You don t write documentation ), and I get no feedback if I typo a global variable name. Add in a healthy heaping of lack of namespacing , and you ve basically guaranteed that your module will be loudly cursed.

2. You use parameterised classes I ve never managed to work out why parameterised classes even exist. They ve got all the problems of regular classes, as well as all the problems of types. There was a fantastic opportunity with parameterised classes to fix some of the really annoying things about regular resources, such as doing conflict checking on parameters and only barfing if there was a conflict but no, if you define the same class twice, even with identical parameters, Puppet will smack you on the hand and take away your biscuit. FFFFFFUUUUUUUUUUUU-

3. You fail at using fail() Modules are supposed to be reusable. That s their whole reason for existence. One of the benefits of Puppet is that you can provide an OS-independent interface for configuring something. However, unless you re some absolute God of cross-platform compatibility, you will only be writing your module to support those OSes or distros that you, personally, care about. That s cool if you don t know anything about OS X, you probably shouldn t be guessing at how to support something on that platform anyway. However, when you do have some sort of platform-specific code, for the love of pete, have a default or else clause that calls fail() with a useful and descriptive error message, to indicate clearly that you haven t included support for whatever environment the module s being used in. Failing to do this can cause some really spectacular explosions, because the rest of your module assumes that certain things have been done in the platform-specific code, and when it hasn t hoo boy.

4. You don t write documentation Yes, it isn t easy to write good documentation. I know that. But without documentation, your module is going to be practically unuseable. So if you don t have docs, your module is basically useless. Well done, you.

5. You have undeclared dependencies This also includes declaring your dependencies in a non-machine-parseable manner; I m not going to grovel through your README for the list of other modules I might need; I have machines to do that kind of thing for me. If I try to use your module, and it craps out on trying to reference some sort of type or class that doesn t appear at all related to your module, I will call into question your ancestry, and die a little more inside.

6. You use common packages without even trying to avoid the pitfalls OK, to be fair this is, ultimately, Puppet s grand fuckup, not yours, but you at least need to pretend to care There is no sane, standardised way in Puppet for multiple modules to install the same package. Let s say that a module I write needs to have a compiler. So I package "gcc": . Then someone else s module also wants a compiler, so it also package "gcc": . FWAKOOM! says Puppet. What the fuck? says the poor sysadmin, who just wanted both a virtualenv and an RVM environment on the one machine. Basically, using packages is going to make your module suck. Does that mean that this makes wide distribution of a large repository of modules written by different people nigh-on impossible? Yes. Fantastic.

28 October 2013

Keith Packard: Quaternions

Tracking Orientation with Quaternions I spent the flight back from china and the weekend adding orientation tracking to AltOS. I d done a bit of research over the last year or so working out the technique, but there s always a big step between reading about something and actually doing it. I know there are a pile of quaternion articles on the net, but I wanted to write down precisely what I did, mostly as a reminder to myself in the future when I need to go fix the code Quaternion Basics Quaternions were invented by Sir William Rowan Hamilton around 1843. It seems to have started off as a purely theoretical piece of math, extending complex numbers from two dimensions to four by introducing two more roots of -1 and defining them to follow:
i  = j  = k  = ijk = -1
Use these new roots to create numbers with four real components, three of which are multiplied by our three roots:
r + ix + jy + kz
With a bit of algebra, you can figure out how to add and multiply these composite values, using the above definition to reduce and combine terms so that you end up with a set which is closed under the usual operations. Then we add a few more definitions, like the conjugate:
q = (r + ix + jy + kz)
q* = (r - ix - jy - kz)
The norm:
  q   =  (qq*) =  (r  + x  + y  + z )
u is a unit quaternion if its norm is one:
  u   = 1
Quaternions and Rotation Ok, so we ve got a cute little 4-dimensional algebra. How does this help with our rotation problem? Let s figure out how to rotate a point in space by an arbitrary rotation, defined by an axis of rotation and an amount in radians. First, take a vector, v , and construct a quaternion, q as follows:
q = 0 + ivx + jvy + kvz
Now, take a unit quaternion u , which represents a vector in the above form along the axis of rotation, and a rotation amount, , and construct a quaternion r as follows:
r = cos  /2 + u sin  /2
With a pile of algebra, you can show that the rotation of q by r is:
q  = r q r*
In addition, if you have two rotations, s and r , then the composite rotation, t , a rotation by r followed by s can be computed with:
q  = s (r q r*) s*
    = (sr) q (r*s*)
    = (sr) q (sr)*
t   = s r
q  = t q t*
That s a whole lot simpler than carrying around a 3x3 matrix to do the rotation, which makes sense as a matrix representation of a rotation has a bunch of redundant information, and it avoids a pile of problems if you try to represent the motion as three separate axial rotations performed in sequence. Computing an initial rotation Ok, so the rocket is sitting on the pad, and it s tilted slightly. I need to compute the initial rotation quaternion based on the accelerometer readings which provide a vector, g pointing up. Essentially, I want to compute the rotation that would take g and make it point straight down. Construct a vector v , which does point straight up:
g = (0, ax, ay, az) / norm(0, ax, ay, az)
v = (0, 0, 0, 1)
G is normalized so that it is also a unit vector. The cross product between g and v will be a vector normal to both, which is the axis of rotation. As both g and v are unit vectors, the length of their cross product will be sin
a = g   v
  = u sin  
The angle between g and v is the dot product of the two vectors, divided by the length of both. As both g and v are unit vectors, the product of their lengths is one, so we have
cos   = g   v
For our quaternion, we need cos /2 and sin /2 which we can get from the half-angle formulae:
cos  /2 =  ((1 + cos  )/2)
sin  /2 =  ((1 - cos  )/2)
Now we construct our quaternion by factoring out sin from the a and:
q = cos  /2 + u sin   sin  /2 / sin  
Updating the rotation based on gyro readings The gyro sensor reports the rate of rotation along all three axes, to compute the change in rotation, we take the instantaneous sensor value and multiply it by the time since the last reading and divide by two (because we want half angles for our quaternions). With the three half angles, (x,y,z), we can compute a composite rotation quaternion:
   cos x cos y cos z + sin x sin y sin z +
i (sin x cos y cos z - cos x sin y sin z) +
j (cos x sin y cos z + sin x cos y sin z) +
k (cos x cos y sin z - sin x sin y cos z)
Now we combine this with the previous rotation to construct our current rotation. Doing this faster If we read our sensor fast enough that the angles were a small fraction of a radian, then we could take advantage of this approximation:
sin x   x
cos x   1
that simplifies the above computation considerably:
1 + xyz + i (x - yz) + j (y + xz) + k (z - xy)
And, as x, y, z 1, we can further simplify by dropping the quadratic and cubic elements as insignificant:
1 + ix + jy + kz
This works at our 100Hz sampling rate when the rotation rates are modest, but quick motions will introduce a bunch of error. Given that we ve got plenty of CPU for this task, there s no reason to use this simpler model. If we did crank up the sensor rate a bunch, we might reconsider. Computing the Current Orientation We have a rotation quaternion which maps the flight frame back to the ground frame. To compute the angle from vertical, we simply take a vector in flight frame along the path of flight (0, 0, 0, 1) and rotate that back to the ground frame:
g = r (0 0 0 1) r*
That will be a unit vector in ground frame pointing along the axis of the rocket. The arc-cosine of the Z element will be the angle from vertical. Results All of the above code is checked into the AltOS git repository I added a test mode to the firmware that just dumps out the current orientation over the USB link which lets you play with rotating the board to see how well the system tracks the current orientation. There s a bit of gyro drift, as you d expect, but overall, the system tracks the current orientation within less than a tenth of a degree per second. Even with all of this computation added, the whole flight software is consuming less than 7% of the STM32L CPU time.

26 October 2013

Russ Allbery: Review: Why We Fail

Review: Why We Fail, by Victor Lombardi
Publisher: Rosenfeld Media
Copyright: 2013
ISBN: 1-933820-17-9
Format: Kindle
Pages: 248
Subtitled Learning from Experience Design Failures, Why We Fail is a case study book. It defines experience design, discusses the usefulness of analyzing failure, and then walks through ten marketplace failures attributed to failures of user experience (as opposed to engineering or user interface) and tries to draw some conclusions about those failures and how they could have been prevented. Lombardi then presents a more general (if fairly simple) framework for iterative experience design, along with some discussion of how that approach could have helped in these cases. Hardware and software designs can work properly but still fail with users and customers because the overall experience isn't right. Sometimes this is because something else got there first with more market share and people got used to it, sometimes it's because a system is too complicated, sometimes it's too simple, sometimes it's just uninspiring. Most of the news media coverage and many of the blog posts on this topic look to inspirational examples of successes. Lombardi points out here that successes can be accidental and failures are often more informative, a concept already common in many more mature areas of engineering. His hope, with Why We Fail, is to push a broader industry practice of taking apart and analyzing the failures. User experience design is still in its infancy, since many of the complex interactions now possible in modern hardware and software have just recently crossed into levels of complexity that qualify as experiences rather than interactions, and could benefit from more rigor. The concept sounds great. The approach in Why We Fail is at least interesting; Lombardi tells good stories, and I think they do tell some useful lessons. Drawing general principles is harder, which is always the weakness of case-study books. Lombardi's own attempt doesn't go far beyond a familiar mantra of the scientific method, small and responsive teams, cross-functional teams with flexibility to address a whole range of technical and business issues, and honest and forthright analysis of and iteration after failure. All of this is doubtless good advice; none of it should surprise anyone with even a smattering of engineering background or familiarity with current software design philosophy. The heart of the book is in the stories, and I did like that Lombardi captured a wide range of different designs. Included are embedded systems (BMW's iDrive), traditional software packages, web services of various types, and even a protocol (OAuth). Some were vaguely familiar and some were not familiar at all, although I don't follow UI and UX discussions to any large extent. In each case, Lombardi gives a short but effective introduction to the problem space and the product, walks through the design choices, and then talks about the failure. Usefully, he doesn't stop with the failure but continues the story through the reaction of the company to the failure and any subsequent actions they took, which in some cases contain their own useful lessons. All of this, I should note, is a bit far afield of my own area of expertise (architectural building blocks and sub-surface components without as much direct interaction with the user), so I'm not the best person to judge the quality and originality of the analysis. But I liked Lombardi's approach and his analysis of multiple possible failure causes, and all of his conclusions seemed quite plausible and sensible given the case studies as described. I'm best-qualified to judge the chapter on OAuth, since I've worked extensively on web authentication systems, and his analysis of the challenges and user experiences in that case closely match my own. I didn't notice any significant errors, which is hopefully a good sign for the rest of the book. As one might expect from a short book about a complex field aimed mostly at starting a conversation, there isn't much here that's earth-shattering, nor are there simple extractable principles that will make your experience designs better. As always, the takeaway boils down to "invest time and resources into this and try to think about it systematically," which of course is true of every possible axis of improvement for any product. (The challenge is usually where to spend those limited resources.) I will also note in passing that Lombardi assumes an entirely market-driven metric for success, and all of the case studies are exclusively commercial not unexpected, since that's where most of the money and a lot of the resources are, but not that helpful for bespoke work where the nature of the problem is subtlely different. But, despite the expected shortcomings and the inherent weakness of the case study approach to analysis, which tries to pluralize anecdote to get data I enjoyed this book. I also got at least one useful trick out of it: the premortem, to look for potential failure points in the experience before rolling out, or even designing, the product. It's a fairly light-weight book, but I think it's moderately inspirational, and I wholeheartedly concur with Lombardi on the merits of failure analysis as an engineering approach. Rating: 7 out of 10

25 October 2013

David Welton: MicroConf Europe

I don't envy conference organizers these days - most of what's being said can be read the next day, for free, on line, at your own pace, from the comfort of your own home, and without spending a bundle of time and money to sleep in a far away hotel. Competing with that is not easy, but the guys at MicroConf managed to. I would sum up the weekend by saying that it was a "very high bandwidth experience". Every day, from breakfast until I turned in, I was chatting with people or listening to speakers during the conference itself. That's aproximately 16 hours of being "on", and by the time I got home to Padova, I was exhausted! But at the end of the day, I felt like it was worth it being there in person, because of all the interaction with other people. The speakers' talks all ended up on line, more or less, but all the chatting and discussion and getting to know everyone is the human element that is tough to replicate on line, and one of the most important reasons to attend a conference in person. Prague is also a beautiful city - I wish I had had more time there to check it out. Here are some highlights and notes, in no particular order: However, since it was a business conference, I also have to put on my cold, hard accountant hat. Will the conference pay for itself? Only time will tell. I learned a variety of interesting and useful things, many of which I think I can put into practice. The problem is finding the time between consulting work and family, but that was a bottleneck before, too - I had, and have, more things to do than time. Also, to be very direct about it, how much of what I learned could not have been learned by carefully reading accounts of the conference, slides, and other material published on the internet? A lot of it. I'm not sure I would have paid attention to all of it though, so the conference was definitely nice in that it exposed me to some talks and ideas that otherwise I might have brushed off before giving them a chance. In terms of dollars and cents, I won't be able to say for a while whether it was a sensible investment or not. Would I go again? I'd like to - it was a lot of fun and the people were great. Like I said, it's tough doing conferences because your competition is the internet!

Enrico Zini: A vision wanted

A vision wanted Today Richard Stallman mailed all Italian LUGs asking that tomorrow's LinuxDay be called "GNU/Linux Day" instead. I wonder how that is ever going to help a community so balkanised, that the only way Italian LUGs manage to do something together, is to say "let's not care what we all do, let's just do it on the same day and call it a national event". Of course a few LUGs still make a point of not doing anything on that day, because you know, Judean People's Front. Cawk. Today a friend asked me if I could help her support people in installing Citrix Whatsit to set up a video conference to network meetings that will take place in a month in different cities. Those meetings are something I look forwad to. It wasn't much of a problem to say "no, I can't do that"; it was a problem to be unable to come up with some viable, Free alternatives. I sometimes have to use Skype to talk with friends who also are Debian Developers, because I still haven't managed to make VoIP work unless I go through a commercial proxy. There was the happy news that our regional administration is switching from MS Word to OpenOffice. It soon became a flamewar, because some people loudly complained that they should have used LibreOffice instead. At DebConf, after spending an hour getting frustrated with the default formatting of bullet points in WhateverOffice Impress, I did my Debian Contributors talk using a text file in vim. And it was a success! Thanks Francois Marier for maintaining cowsay. I can't sync contact lists and appointments between my N900, which runs a Debian derivative, and my laptop, because I don't want to have a Google account, and nothing else would work out of the box. I don't even know how to keep a shared calendar with other DDs, without using a 3rd party cloud service that I don't want to trust with my life's personal schedule. I need to do a code review of every vim plugin I need to use, because you can only get them by cloning GitHub repositories over plain http, and they don't even provide signed tags. That code is run with my own privileges every time I start a text editor, which is, like, all the time. I'm frightened at the idea of how many people blissfully don't think about what that means. Vim users. Programmers. Cool chaps. Yet the most important thing in Debian today seems to be yet another crusade between upstart and systemd. But we haven't had a lengthy discussion on why, although the excellent OpenStreetMap exists and many of us contribute to it, it seems to still be more immediate to hit Google Maps to get a route computed. How can we change that? We haven't had a lengthy discussion on what can we offer to allow anyone to set up some social platform that won't get swamped with spam the first day and cracked open the second; that would allow people to share some photos with their friends only, and some with the rest of the world; that won't required a full-time paid person to maintain. That won't be obsolete and require a migration to a new platform in a year. That isn't Facebook or Google Plus. I stopped taking photos because it's too much work to show them to people. Other people use Instagram. Whatever the hipster trend is for photo sharing today, October 25, 2013, I'm pretty sure it's not a Free platform. But we can do something. We technology leaders. We are those who drive technological change! For example, today I invested two hours of hard effort trying to figure out why libbuffy's test suite fails on kfreebsd. All while wondering why I was doing that, since I know all buffy's users personally, and none of them uses kfreebsd. And I will take a day off work to study the library symbols file specification, so that next time I'll know right away if the new version of a C++ compiler decides that a template-generated symbol isn't worth adding to a library anymore. What is this effort really about? It sometimes feel like micromanaging to me. It's good to have excellent quality standards. But not without a vision. Not until "reliable network printing with all PDF viewers and print servers we ship" is among our release goals. Not until we commit to making sure that "sharing files between Debian users" will work out of the box, without the need of going through a 3rd party website, or email. I'm not interested in spending energy discussing init systems. I'm interested in spending energy sharing stories of what cool stuff we can do in Debian today, out of the box. And what cool stuff we'll be able to do tomorrow. Let's spend time on IRC, on mailing lists, and at the next Debian events, talking about why we are really into this. Talking about a vision! Note: Please don't spend time telling me how to fix the problems I mentioned above. I'm not interested in help fixing some problems for me today. I'm interested in asking help fixing problems for everybody, right in the next stable release. Remember, remember, the 5th of November, 2014.

24 October 2013

Daniel Pocock: Final report on GSoC 2013 projects

Google Summer of Code finished recently. This is the first year that I have participated as a mentor for the Debian Project. Its a big responsibility to be part of the Debian team and to be one of the Debian team members representing Debian at the GSoC Mentor Summit. Birthdays all round This has been a particularly important year for the Debian Project, as the project celebrated our 20th birthday recently, on 16 August 2013, one of the final days of DebConf13 in Switzerland. GSoC celebrates its 10th year in 2014, with a generous 10% boost in the student stipend to mark the occasion. Google: don't be evil Google's "Don't be evil" approach to business has always been an interesting point for discussion. In my view, there are few cases of absolute good or absolute evil that we can universally classify and agree on. At a more pragmatic level, various people have commented that GSoC is a recruiting program for Google: some have even cited this as a reason not to participate. This is a more interesting point for discussion. The results of the program are not exclusive to the headhunters at Google. Anybody can browse through the Debian GSoC weekly student reports from each student to find out exactly what the students were up to and try to recruit them. Mentors and the projects they belong to have not been forced to sign any wide-ranging non-disclosure agreements or non-compete agreements with Google. In one recent example, the xWiki open source project even went as far as setting up a new office in Romania and employing some former GSoC students on a permanent basis.
Assorted images from Iasi, Romania, where xWiki set up an office employing former GSoC students How does Google benefit then? Well, there appear to be several possibilities:
  • Generating a huge amount of goodwill and recognition for the value that they place on the development of the next generation of software engineers
  • Stimulating the expansion of high quality free software projects, many of which they use directly or indirectly for their internal projects
  • Access to private evaluations prepared by the mentors. These evaluations don't take more than an hour for the mentors to complete but they do serve to give Google's headhunters a slight headstart over anybody else who is scouring the web for the names of graduates who completed GSoC
Overall, it appears to fit the definition of a "win-win" scenario: yes, Google gets stuff out of it, but the benefit is not exclusive to Google and projects like Debian are winners too. My initial approach I started by reviewing some of these materials: One particular concept that I took note of was the need to give students some opportunity to be innovative and original in their project proposals. In other words, it has been suggested that students should not be given a precise specification: rather, they should be given some very general concepts or goals and asked to suggest some funky, innovative new idea. The wisdom of this approach varies. If your free software project has some very specific gap that you need to fill, you may only be interested in taking a student who can fill that gap and you may not want to waste the time of other applicants. On the other hand, if you do precisely document this gap you want filled, you may get a bunch of very similar proposals from students and it may be more difficult to distinguish which of them is the most desirable candidate. Furthermore, if your expectations are too rigid, you may not benefit from a top-gun coming in and contributing some really exciting piece of work that you hadn't even thought of. In the end, I opted for providing more generic project briefs and looking at how students responded. The briefs that I published are available here. Coding tasks during the selection process There is no doubt about it, coding tasks are an important part of ensuring students are capable of development work before they are selected. They are also very important for us as mentors. It is not uncommon for some of us to be completely out of touch with the capabilities of other developers. The coding tasks completed by the students during the selection phase allow us to get a feel for their capabilities and set reasonable expectations for how much they can achieve during the course of the project. To simplify the management of coding tasks and engage the students in the Debian community at large, I decided to create tasks as wishlist items in the Debian bug tracking system, such as this dynalogin bug report. The prospective GSoC students were asked to put their name in the bug tracker to take ownership of the task they would complete. Student project proposals For the real-time communications project, I felt all the students slightly underestimated the complexity of this field and would have to be extremely lucky to complete everything they hoped to. After all, this is a field that the free software movement has been wrestling with for years without gaining the upper hand. For somebody with good knowledge of the projects in this space, it is possible to guide the students towards meaningful and achievable subprojects. Nonetheless, the proposals were useful for me in understanding which part of the topics were most attractive to the students. For the other project areas, the student proposals were slightly more specific. Fabian's appeared to be the most specific and well considered proposal for the one-time-password project, in fact, it appeared very much like a project that he could work through from start to finish. Debian teamwork Anybody looking at the GSoC web site will notice that there is a certain amount of overhead in joining the program, promotion, payment administration and optional participation in the GSoC Mentor Summit. As a large organisation, Debian established a dedicated SoC administration team who looked after the GSoC and Outreach Program for Women administrivia. As a developer and mentor, I found this arrangement was highly effective and allowed me to focus over 99% of my efforts on the front-line work, selecting students and supporting them through their projects. Project results One of the more controversial issues during the Debian 7 (wheezy) release cycle was the inclusion of the Mumble voice conferencing software. Although the software has some serious issues, it was eventually escalated to the technical committee and allowed to remain in Debian, partly due to lack of any alternative. One of the first results from Catalin's project was the creation of an alternative, the new reConServer project, based on the librecon conversation manager API from the reSIProcate SIP stack. reConServer is a significantly more generic solution than Mumble, as it allows any SIP peer to participate in an audio conference. It supports TURN for NAT traversal too. Catalin then went on to make the first working implementation of a scheme for passing context information from a web site to SIP WebRTC call as described in the IETF draft. All work has been integrated into release tarballs and packaging. Fabian worked through the latest standards for one-time passwords, extending the oath-toolkit and dynalogin projects to implement mutual two-factor authentication with just about any arbitrary crypto suite using one-time passwords. This work is yet to be merged into an official release of dynalogin as it requires co-ordination with the oath-toolkit release and package updates. However, there is a compelling demonstration in his video from DebConf13 and the source is available under Fabian's github account. In the post-Snowden world, the work from both of these student projects will be hugely valuable to people wanting to tighten up their computer security and communication security practices. The development process Deciding to mentor more than one project turned out to be a worthwhile decision. At first, this might seem like a big risk but it is manageable with support from co-mentors. The upside is that different students work at different speeds, they have different code styles, they even work at different times of the day or week and mentoring more than one student/project allows the mentor to gain a better appreciation of how the students differ than if mentoring only a single project. For Catalin's project, it became obvious at an early stage that he would benefit from having a dedicated server to run the VoIP applications on public IP addresses and low-latency networks while testing them. I spun up a virtual machine with IPv4 and IPv6 in my Xen Cloud Platform and this was extremely helpful for both of us. Throughout the project, I took a hands-off approach and often left the students to their own devices. I gave some suggestions to Catalin about the object-oriented design and this was enough for him to fill in the gaps and write all the code by himself. Fabian's project had fewer ambiguities and he was able to use existing code as a model more frequently than Catalin. It is possible that the students may have produced more code if I had thought through the designs myself and given them definite blue-prints. However, I feel that this would have made it harder for me to appreciate their own abilities and test the limits of their design skills. DebConf13 participation One of the highlights for the students was their participation in DebConf13. Both students presented a session at the conference showcasing some of their work. The DebConf video team produces high quality videos of all sessions at the conference and this in turn provides some great evidence of the students' capabilities and what GSoC adds to Debian and the wider free software universe. I would encourage other mentors to actively contemplate ways to involve their students in conferences during or shortly after the completion of their project work. Looking ahead Google has recently confirmed that Google Summer of Code will be repeated in 2014. It is the 10th anniversary of the program and to celebrate, students will get 10% extra pay. Thank you There are many people to thank for the success of these projects and the wider success of the Debian GSoC team:

  • The Debian GSoC and OPW organisation admin team
  • Google and the Google Open Source Programs Office
  • All the co-mentors who assisted on these projects with me: Simon Josefsson, Luke Faraone, Sylvain Berfini, Eloy Coto and Jes s P rez Rubio
  • The students themselves, C t lin Constantin U urelu and Fabian Gr nbichler
  • All the other very capable and motivated students who applied, submitted code samples but were not selected to participate: many of these students could have also completed a successful project and turning them away is one of the most difficult tasks for mentors in a volunteer organisation like Debian

23 October 2013

Russell Coker: LUV Hardware Library after 20 Months

20 months ago I started the LUV Hardware Library [1]. The aim of the project is to provide a repository of free spare parts for computers for the use of club members. People who have parts that are good but which they can t use can donate them and others who need such parts can take them. Some people have criticised my choice of the name Hardware Library because the word is associated with borrowing while with my Hardware Library it is expected that noone will return the item that they take. The Wikipedia page about libraries is worth reading, my interpretation of that is that the essential aspect of a library is that it is a public collection of items that are useful for study and that borrowing is just one thing that can be done. A book library could consist of a service of printing free books on demand (anyone could do this with access to The Gutenberg Project [2] and a printer) or of just making them available to download. Many libraries don t allow books to be borrowed, they just allow them to be studied and copied in the library. Also every general public library has reference items that can t be borrowed, it s typical for a library to have a full encyclopedia which is not available to be borrowed. Also with the Hardware Library people feel obliged to give something if they take something (as happens with a geocache), so there is an issue of returning something. My main aims with the Hardware Library were to save people money on parts and to help the environment by reducing the need to buy new computers when old ones can be upgraded and remain in service. My next aim was to help people learn about hardware by providing free parts, when a mistake has no financial cost people are more willing to experiment and will learn more. I believe that those aims have been achieved. More Successful Than Expected One thing that surprised me is the social aspect that developed. I had expected that most people would just find some parts that they need and not look at it again for some months. I had also anticipated that some people would poll the Hardware Library every month in the hope that a part they needed might appear. I didn t expect that people would look through it every month because they just like looking at old hardware. I also didn t expect groups of people to hang out by the Hardware Library to discuss various issues related to PC hardware and Linux. During the breaks in the main meeting the location of the Hardware Library often becomes a focus for discussions of various issues related to Linux and hardware. I think that this is really advancing the aims of LUV [3] and I think that members of other LUGs should experiment with similar projects. Starting this didn t require any special skill or authority. I just started bringing a briefcase full of parts to meetings and offering them to whoever was interested. Any member of any LUG can do the same. To start something like this you wouldn t even need a collection of parts, you could just bring a box and ask for donations.

21 October 2013

Aigars Mahinovs: Moved to Mezzanine

After my server that has hosted my blog for some years had given out its last breath (second motherboard failure), I decited it was time for a change. And not just server change, but also change in the blog engine itself. As I now focus on Python and Django almost exclusively at work, it felt logical to use some kind of Django-based blog or CMS. I tried django-cms and mezzanine and ... Mezzanine is so fast and simple, that I simply stopped looking. After simply following the tutorial and creating a skeleton project, I had a ready-to go site with all the CMS features, incuding a blog. I just had to change a few settings to have the blog module be the home page of the site, change site settings for the title and Google Analytics settings and such and tweak the theme a bit to my liking. This was my first real exposure to a Bootstrap design. I must say - it is very simple to understand and modify if your needs fit within its limits. For example, I wanted to remove the left sidebar and expand the main content block to fill that. All I had to do was to remove the div element with class "left-sidebar span-2" and change the class of the main content part from "span-7" to "span-9". To do that I simply copied the templates/base.html file from mezzanine default templates and modified it. The information from django-debug-toolbar showed me what files were used in rendering the page. But the feature that really got me hooked was the Wordpress import. Using a simple management command I was able to feed into Mezzanine instance the XML export file from Wordpress. It created blog posts, categories, comments, static pages and even redirects from Wordpress permalinks to Mezzanine permalinks. It was not flawless - there were a few issues: After that was done it was a relatively straightforward process of picking up the code and data and deploying it to a Django-friendly hosting service. There is a plenty of good competition out there, most now offer a simple one-click Django installation, so I just created a simple Django skeleton via their web interface and then replace what they generated with my app while keeping their settings as local_settings.py . I should probably write a bit more details about the process. After I create a custom fabric file for this. It is quite a strange feeling to have a Mezzanine blog that responds faster from a shared server half a continent away, compared to a Wordpress on dedicated server in the same room There are a few features that I am still missing - most notably draft post autosave. That has bitten me hard while writing this post :P Also a Twitter digest post feature. But on the bright side - that is a great motivation to write such features, preferably in a portable way that other people can use too :)
Aigars Mahinovs: Moved to Mezzanine

After my server that has hosted my blog for some years had given out its last breath (second motherboard failure), I decited it was time for a change. And not just server change, but also change in the blog engine itself. As I now focus on Python and Django almost exclusively at work, it felt logical to use some kind of Django-based blog or CMS. I tried django-cms and mezzanine and ... Mezzanine is so fast and simple, that I simply stopped looking. After simply following the tutorial and creating a skeleton project, I had a ready-to go site with all the CMS features, incuding a blog. I just had to change a few settings to have the blog module be the home page of the site, change site settings for the title and Google Analytics settings and such and tweak the theme a bit to my liking. This was my first real exposure to a Bootstrap design. I must say - it is very simple to understand and modify if your needs fit within its limits. For example, I wanted to remove the left sidebar and expand the main content block to fill that. All I had to do was to remove the div element with class "left-sidebar span-2" and change the class of the main content part from "span-7" to "span-9". To do that I simply copied the templates/base.html file from mezzanine default templates and modified it. The information from django-debug-toolbar showed me what files were used in rendering the page. But the feature that really got me hooked was the Wordpress import. Using a simple management command I was able to feed into Mezzanine instance the XML export file from Wordpress. It created blog posts, categories, comments, static pages and even redirects from Wordpress permalinks to Mezzanine permalinks. It was not flawless - there were a few issues: After that was done it was a relatively straightforward process of picking up the code and data and deploying it to a Django-friendly hosting service. There is a plenty of good competition out there, most now offer a simple one-click Django installation, so I just created a simple Django skeleton via their web interface and then replace what they generated with my app while keeping their settings as local_settings.py . I should probably write a bit more details about the process. After I create a custom fabric file for this. It is quite a strange feeling to have a Mezzanine blog that responds faster from a shared server half a continent away, compared to a Wordpress on dedicated server in the same room There are a few features that I am still missing - most notably draft post autosave. That has bitten me hard while writing this post :P Also a Twitter digest post feature. But on the bright side - that is a great motivation to write such features, preferably in a portable way that other people can use too :)

Daniel Pocock: Debian team at GSoC summit 2013

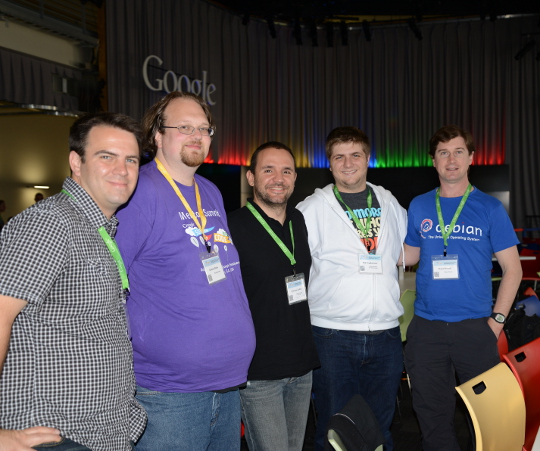
One of the most exciting things about the GSoC mentor summit 2013 has been the large number of participants who are Debian Developers, Debian Maintainers or other members of the wider Debian family Debian team members at GSoC mentor summit 2013
AttachmentSize
debian-gsoc-summit-group.jpg175.13 KB

19 October 2013

Dirk Eddelbuettel: New BH release 1.51.1-3

A new release of the BH package is now on CRAN and its mirrors. BH provides (a subset of) the Boost library for C++, particularly the (large) parts delivered as pure template headers not requiring linking. When this package is installed, an R package developer can deploy it at build-time via a simple LinkingTo: BH declaration (which, despite the title affects only compilation, not linking; don't ask...). This frees developers from having to include the (sizeable) Boost headers in their packages, and provides (parts of) Boost as part of the R build system. A short example of using this BH package with Rcpp is provided in this Rcpp Gallery post; a number of other Boost-related posts are also available. This release expands the scope of the package by a quite bit as shown in the NEWS entry:
Changes in version 1.51.0-3 (2013-10-19)
The other change is that I am now acting as maintainer taking over from Jay who has headed the initial creation and first releases after he, Mike and I had talked about this for way too long without actually doing anything about it. Thanks for getting everything rolling, Jay! Comments and suggestions are welcome via the mailing list or issue tracker available via the package page at R-Forge.

16 October 2013

Matthew Garrett: Standing for the Linux Foundation Technical Advisory Board

According to its charter, the Linux Foundation Technical Advisory Board exists "to advise The Linux Foundation Board of Directors (Board) and the management of The Linux Foundation (Management) on matters related to supporting the technical agenda of The Linux Foundation". It consists of 10 members, with 5 seats up for election each year. Elections take place at an event at Kernel Summit, but are also open to attendees of whichever conference is colocated with the Kernel Summit that year. The election announcement is emailed to the Linux kernel list and tech-board-discuss, a mostly moribund list that springs into life once a year for election announcements.

This arrangement seemed odd to me even back in 2007. Back then the Linux Foundation was already sponsoring development of certain non-kernel components, and now that list is even larger. While nominally open to all, nominations for the TAB tend to end up being people actively involved in the kernel community. That's probably better than people limited to any other single technical community (kernel developers tend to end up dealing with bugs from a fairly wide range of projects, so they're not entirely unaware of what other people have to deal with), but it still seems suboptimal. The current membership is mostly limited to people who spend little to no time working with userspace developers, let alone anyone active in other Linux Foundation projects. I don't think this is a good thing

So, after several years of considering it, I'm finally standing for the TAB. I've been an active developer at most levels of the Linux stack, from the kernel through to desktop environments. I've worked closely with distributions. I've even worked closely with firmware developers. I'm not intimately involved in any of the other Linux Foundation projects, but I have experience that allows me to better understand their needs and motivations than I'd have from having spent my entire life living in the kernel. Being on the TAB would make it easier to ensure that these projects are represented in a meaningful way.

Of the other people who I know are standing (and this list may well grow longer), I'm inclined to vote for:
The election is currently scheduled to be National Museum in Edinburgh on the evening of the 23rd of October. If you're attending Linuxcon or one of the colocated events, please do come along and vote.

(Updated to correct a typo)

comment count unavailable comments

Carl Chenet: Brebis 0.7, the fully automated backup checker

Follow me on Identi.ca or Twitter The new version of Brebis Chevillette 0.7 was published two days ago. Brebis is a fully automated backup checker. Brebis does not create backups. It only performs controls on them. Brebis is able to detect a corrupted archive compressed with different formats, automatically checking the integrity of your archives and lots of parameters of the files inside these archives or inside a tree of files and provide detailed reports if unexpected states are detected. Check out the list of the supported features. What s new? The main features of this new version are: Complete example of installing, configuring and running Brebis How to install from your package manager Brebis is available in Debian, FreeBSD, Archlinux and Frugalware. Use your favorite package manager to install it. How to install from the sources
# wget http://brebisproject.org/attachments/download/8/brebis-0.7.tar.gz
# tar zxvf brebis-0.7.tar.gz && cd brebis-0.7
# python3.3 setup.py install --install-scripts=/usr/bin
# mkdir /etc/brebis
What you need before running brebis Our goal is to check on a regular basis the archive /backups/monthly-backup.tar.gz. Brebis needs two files in order to correctly run: a configuration file with general parameters and the list of files with all their parameters. Don t be afraid, both of theses files will be generated by Brebis with the following command:
# brebis -G /backups/monthly-backup.tar.gz
# ls /backups/
monthly-backup.tar.gz monthly-backup.conf monthly-backup.list
All the files inside your archives have been detected and their names and parameters (uid, gid, mode, md5, ) have been written in the file monthly-backup.list. More information about those files. How to configure Brebis Lets save /backups/monthly-backup.list in /etc/brebis: # mv /backups/monthly-backup.list /etc/brebis For /backups/monthly-backup.conf, we just modify the files_list parameters:
[main]
name=monthly-backup
type=archive
path=/backups/monthly-backup.tar.gz
files_list=/etc/brebis/monthly-backup.list
We also save monthly-backup.conf in /etc/brebis: # mv /backups/monthly-backup.conf /etc/brebis Use Brebis Using Brebis is as simple as: # brebis -c /etc/brebis/ -l /var/log/brebis.log If there is not any difference between the current state of your backup and your list of file, the logfile /var/log/brebis.log will be empty. If any difference happens, they will be reported in /var/log/brebis.log. Show time. I m modifying the md5 hash sum of a file in /etc/brebis/monthly-backup.list, during the next run of brebis, I get the following content in brebis.log:
WARNING:root:1 file with unexpected hash while checking
/backups/monthly-backup.tar.gz:
WARNING:root:toto/titi hash is ce4f8cacd8fc702bdd03531b9447818b.
Should have been ce4f8cacd8fc702bdd03531b94478184.
As you can read, Brebis reports a difference between what was expected and what it checks. Now it s easy to do the same for any backup you want to check on a regular basis. Just add something like the next line in /etc/crontab: 01 00 * * * root brebis -c /etc/brebis/ -l /var/log/brebis.log A brebis run will happen every day at midnight to check your backup. Every configuration files in the directory /etc/brebis/ will be inspected. Feedback about Brebis We at the Brebis Project welcome any feedback about Brebis. Feel free to subscribe to the Brebis-users mailing list, by Twitter or email me directly at carl.chenet@brebisproject.org
Official website: http://www.brebisproject.org
Mailing-list: http://lists.sourceforge.net/lists/listinfo/brebis-users

Brett Parker: Hepworth Spam

There's been a recent spate of spam from domains held by Communicado Ltd, to counter this Martin A Brooks has created a lovely list of domains to easily filter, see his blog post for information on the distribution and usage of this list.

14 October 2013

Bits from Debian: Ada Lovelace Day: meet some of the "women behind Debian"!

Today is Ada Lovelace Day:
"Ada Lovelace Day is about sharing stories of women - whether engineers, scientist, technologists or mathematicians - who have inspired you to become who you are today. The aim is to create new role models for girls and women in these male-dominated fields by raising the profile of other women in STEM". source
To celebrate, we asked to some of the "women behind Debian" to share their stories with us. Enjoy! Alt Ada Lovelace portrait Ana Guerrero Lopez (ana) Who are you? I'm a 30-something years old geek. I'm from Andalusia, Spain but live in France. What do you do in Debian? I work mostly on my packages, in sponsoring new people's packages and in this very blog you're reading now. I also maintain an unofficial Google+ page about Debian. At $PAID job, I work in an internal Debian distribution so from time to time, I get the opportunity to contribute back some of the stuff we do there. How and why did you start contributing to Debian? I started using Debian around 2003 switching from Mandrake. I was a happy Debian user when the Debian Women project started in the summer 2004. When I saw the project announced, I asked myself why I wasn't contributing to Debian and the rest is history... in a couple of weeks it'll be my 7 years DD-versary! If for some reason you want a longer reply to this question, read here. Beatrice Who are you? I am a PhD student with a degree in Biology. I am a computer fan since my first C64 and I am a self-taught computer geek wanna-be. And I am a bug fan - not software bugs, real bugs :) What do you do in Debian? I work on translations - doing the translation work itself, but also reviewing other translators' work and helping in coordinating the translation effort. How and why did you start contributing to Debian? I started using Linux because I liked the idea of an open source operative system based on collaboration and I began reviewing open source software translations. Since my first Linux system was Debian Potato and I sticked to Debian ever since, it only seemed natural to focus my translation work on Debian. Christine Caulfield Who are you? My name is Christine Caulfield. My day job is principal software engineer at Red Hat working on the cluster infrastructure components corosync & pacemaker. Outside computing I'm a musician and sound engineer. I play violin with lots of technology attached, and love avant garde music. What do you do in Debian? I'm not that active on Debian any more due to pressure of time, and maturity of the packages I work on. I currently maintain the, little-used, DECnet userspace packages and the, even less used I suspect, mopd bootloader. I used to maintain lvm2 for a while but dropped that a few years ago. How and why did you start contributing to Debian? My initial reasons for joining Debian were slightly selfish, to find a home for the DECnet project that I was heavily involved in at the time. I was a keep Debian user and people wanted a distribution where the software was easy to set up. DECnet is quite complicated for users to configure, being a totally independant networking stack to IP and so OS support is needed. Debian seemed like the logical place to make this happen. As mentioned above I got quite involved for a time and maintained other packages too. I picked up lvm2 because I was on the lvm2 dev team at work in Red Hat and as it was a new package at that time I seemed a logical choice. Elena Grandi (valhalla) Who are you? I'm a 30-something years old geek and Free Software enthusiast from Italy. What do you do in Debian? I'm currently maintaining a few packages (2 python modules and a python program) as a sponsored uploader; I'm also slowly looking around for other things to do (by preference technical, but not limited to packaging), with the aim to spend more time contributing to Debian. How and why did you start contributing to Debian? For a while I had being distro-hopping between "fun" distributions (the ones that break now and then) on the desktop while using Debian stable on the home server and in chroots. I was already doing marginal contributions to those distributions, where finding stuff that was missing was easy, but my perception as a stable user was that Debian was already working fine and probably didn't really need any help. Then I started to socialize on IRC with some DDs and DMs, and realized that my perception was superficial and that in reality there were dark holes in the depths of the archive where Evil festered and prospered and... ok, sorry, I got carried away :) Anyway, since I was actually using Debian more and more I decided to start contributing: I read documentation, I attended the useful IRC sessions on #debian-women and decided that it was probably best not to add new stuff, but look for things that I used and that needed help. Then nothing happened for a while, because finding stuff that doesn't work is hard (at least on my mostly textual systems). Then one day I was trying to write a python script that needed to verify gpg signed messages; it had to run on my Debian server, so I was trying to use python-pyme and its documentation was painful to use, while I remembered an earlier attempt using python-gnupg that was much more pythonic, but not available in Debian. In a fit of anger I decided to forgo all of my good intentions and actually add a new package: I checked the sources for problems, packaged, sent it to mentors@d-o, got reviews, fixed problems, resent and finally got sponsored and well, everything started. Francesca Ciceri (madamezou) Who are you? I'm Francesca, a 30-something Italian graduated in Social Sciences. What do you do in Debian? I'm a (non uploading) Debian Developer since 2011 and have been DPN editor, press officer, webmaster for www.debian.org and translator for the Italian l10n team. Recently, due to time constraints, I had to reduce my involvement and now only work on two things: writing/editing articles for bits.debian.org together with Ana Guerrero, and creating subtitles for the DebConf talks, in the DebConf Subs team. How and why did you start contributing to Debian? Basically thanks to the sudden abundance of free time - due to an health problem - and the desire to give something back to this wonderful operating system. After that, I found out that Debian is not only a great OS but also a very special community. Today, some of my dearest friends are people I met through Debian. :) Laura Arjona Who are you? I live in Madrid (Spain), and work as IT Assistant in the Technical University of Madrid (UPM). I'm married and I have a 4-years-old son. What do you do in Debian? In 2012 I started to clean spam and to translate Debian web pages into Spanish. I also follow the work of the web and publicity team, I hope I'll get more involved there too. And of course, I'm in Debian Women :) How and why did you start contributing to Debian? I'm using Debian at work since 2007 (servers), and in my desktops since 2010. I like very much that it is a community distro and I wanted to participate. I was already doing translations in other (small) free software projects, so I began here too. The Debian-Women list, the planet, and people in identi.ca helped me to learn a lot and feel part of the community even when I was not contributing yet. M nica Ram rez Arceda (monica) Who are you? My name is M nica Ram rez Arceda and I am an enthusiast of free software and sharing knowledge cultures: for me it's a kind of philosophy of life. I studied Maths a long time ago but ended up working as a developer for some years. Now I'm working as an IT teacher. What do you do in Debian? Debian is a huge project, so you can help in various scopes. Mainly, I work on packaging, fixing wnpp bug inconsistencies in BTS and helping in spam cleaning of the mailing lists. But I also enjoy doing some non-technical work from time to time: the project I am just now involved is organizing, with the rest of Debian Catalan community, a local team to propose Barcelona as the venue for a minidebconf where all the speakers will be women. How and why did you start contributing to Debian? In 2000 I discovered Free Software world and I fell deeply in love with its philosophy. Since then, I've been trying to do my best in different activities, like spreading the word, giving free courses, helping collectives and friends in technical stuff (from installing Debian to developing some helping apps for them)... but two years ago I was looking forward to join a free software project and I decided to try Debian, since it has been my first and only distro in my day-to-day life for about ten years. So, I wanted to give back Debian all what it had offered to me, but.... I thought I couldn't (hey, Debian is for real hackers, not for you little ant!), but I started to adopt some orphaned packages, do some QA uploads, fix some RC bugs, talk with some Debian Developers that helped me and encouraged me more than I expected, I traveled to my first Debconf... And one thing takes you to the other, and on March 2012 I became a DD. Now, I'm glad to see that everything that frightened me is not so scary :-)

Clint Adams: The Windy City is full of meat

As you know, I am not big on reviews, so you should disregard the remainder of this entry. I recently found myself in what is called a theatre complex , watching an adaptation of Moli re's Les Femmes savantes by Freyda Thomas, who is apparently famous for playing Alenis Grem on Deep Space Nine. Called The Learned Ladies, this translation to English manages to approximate some of the rhyme of the original, thereby making it unquestionably better than DS9. Also noteworthy is the all-female cast, cobbled together from two all-female theater groups. Elizabeth Neptune plays Chrysale, occasionally channeling the spirit of Jackie Gleason or bringing adorable ardor to such epic lines as Tea! I won't say anything about her eyes, but I will say something about her slippers. Sara Montgomery, as B lise, is delightfully crazy in her singing, dancing, costume changes, and other antics, which serve to transform this otherwise-completely-serious play into a comedy. I definitely won't say anything about her shoes. Madeleine Maby begins playing Philaminte well before the show starts. Spoiler alert: she sits on the stage, pretending to look through a telescope and make notes from before the house opens until right before the start of the first scene. I still feel exhausted by the thought of having to do that myself. L' pine is portrayed by Alyssa Lott, who also plays three minor roles. Her mastery of physical comedy is not wasted on this production. Marta Kuersten plays Clitandre opposite Sarah Brill's Henriette. While Marta's performance was quite good, she looks much better as a woman. I will not be saying this about everyone. Katie Honaker delivers visceral smarm and sleaze as Trissotin. Even her hairstyle is somehow evocative of contempt. Susan Finch plays Vadius and Le notaire. Susan was definitely most convincing as a man. Despite mutterings to the contrary, some suspension of disbelief was necessary for the other male roles, but not for Vadius, oh no. Finishing out the list we have Janna Emig as Martine, Francesca Day as Armande, and Kathryn Alexander as Ariste, with good performances, particularly in the second half. Even though it didn't have Coppertop from Strangers With Candy and a boy-band song-and-dance cover of To Be with You by Mr. Big, I recommend this play.

13 October 2013

Dirk Eddelbuettel: Chicago Marathon 2013

A gorgeous day in Chicago for the 37th annual Chicago Marathon. Today was the seventh time I ran this race. I had sat out last fall, and ran a smaller local race (well enough for a BQ). But the last time I ran Chicago I mused that maybe next time I'd train more. I tried, but it didn't quite work with a minor injury dragging on a little. Just like in 2010. And so it continues: it is my home course, and the course I have run the most and know the best. Yet it is the one where I have the greatest difficulty coming in with a time that is good enough for Boston. I knew that today wasn't going to be that day, so I aimed lower to just run even splits (ie running about equal halfs). But even that failed: After 1:44 for the first half I lost a good ten minutes to finish at 3:40:42. Oh well. There is always next year... But it was a simply sunningly fabulous day, and the race was once again very, very well put together. We were worried about extra security: not a real issue. The streets were lined with people and even Lisa and Julia managed to cheer me on at mile 13 (still smiles), mile 19 (grimacing, about to fall apart) and 25 (hanging in). And Anna was working the mile 18 water stop. The worst where miles 20 to 22 when I walked a fair bit. The race results have details; maybe I'll update the chart I made in prior years. One minor FAIL was a wait at the end for gear check. That was pathetic. I guess the folks manning the stand didn't keep bags sorted well enough so lines were long, and slow. Oh well -- the rest was fine, and it remains one of the nicest marathon races. Oh, and the other FAIL was that my Nexus 4 phone couldn't hold a charge til I was done. What's up with that? The running tracker traced me til around mile 20, and then the phone shut down for lack of juice. Disappointing too. But hey, it spares you, dear reader, the look of some bad post-race selfies...

John Goerzen: Why are we still backing up to hardlink farms?

A person can find all sorts of implementations of backups using hardlink trees to save space for incrementals. Some of them are fairly rudimentary, using rsync --link-dest. Others, like BackupPC, are more sophisticated, doing file-level dedup to a storage pool indexed by a hash. While these are fairly space-efficient, they are really inefficient in other ways, because they create tons of directory entries. It would not be surprising to find millions of directory entries consumed very quickly. And while any given backup set can be deleted without impact on the others, the act of doing so can be very time-intensive, since often a full directory tree is populated with every day s backup. Much better is possible on modern filesystems. ZFS has been around for quite awhile now, and is stable on Solaris, FreeBSD and derivatives, and Linux. btrfs is also being used for real workloads and is considered stable on Linux. Both have cheap copy-on-write snapshot operations that would work well with a simple rsync --inplace to achieve the same effect ad hardlink farms, but without all the performance penalties. When creating and destroying snapshots is a virtually instantaneous operation, and the snapshots work at a file block level instead of an entire file level, and preserve changing permissions and such as well (which rsync --link-dest can have issues with), why are we not using it more? BackupPC has a very nice scheduler, a helpful web interface, and a backend that doesn t have a mode to take advantage of these more modern filesystems. The only tool I see like this is dirvish, which someone made patches for btrfs snapshots three years ago that never, as far as I can tell, got integrated. A lot of folks are rolling a homegrown solution involving rsync and snapshots. Some are using zfs send / btrfs send, but those mechanisms require the same kind of FS on the machine being backed up as on the destination, and do not permit excluding files from the backup set. Is this an area that needs work, or am I overlooking something? Incidentally, hats off to liw s obnam. It doesn t exactly do this, but sort of implements its own filesystem with CoW semantics.

Next.

Previous.