Search Results: "cas"

14 July 2013

Gregor Herrmann: RC bugs 2013/28

this week(end) I was more in the "RC bug fix flow" than in the last weeks, & here are the results:

Michael Stapelberg: Systemd support in Debian packages: how to help

Sometimes, people show up in our IRC channel #debian-systemd or on our mailing list pkg-systemd-maintainers@lists.alioth.debian.org and ask how they can help. This blog post answers that question. First of all, whatever you end up doing, please coordinate with us first! Saying hi in our IRC channel or on our mailing list and explaining what you intend to do is all we ask for. In the past, people have filed bug reports with service files that are not idiomatic, and we really need to avoid that. Currently, our biggest task is to add/improve systemd support to individual Debian packages, and this is where we can use a lot of help. We have a dashboard which contains two lists:
  1. Packages that ship a service file, but don t use dh-systemd yet.
    These need to be updated to get proper maintscripts (e.g. deb-systemd-helper enable/disable calls, possibly start/stop/restart calls).
  2. Packages that ship an init script but no service file yet.
    These need a service file plus dh-systemd support.
Adding a service file and dh-systemd support After you picked a service from the second list in our dashboard, first double-check that there is no bug filed against it yet (the dashboard might be a few hours behind). Then, search for a service file, either upstream or in other distributions such as Arch Linux, Fedora, Gentoo, etc. In case there is no service file yet, write one. Please carefully test the service file (e.g. does starting/stopping/restarting and reloading work) and send it to us for review. Be careful to avoid obvious regressions from the sysvinit init script. That is, don t just write a very simplistic service file that breaks a use-case which formerly worked. If in doubt, ask pkg-systemd-maintainers or chose a different package to work on. Afterwards, add systemd support by using the dh-systemd helper, see https://wiki.debian.org/Systemd/Packaging. The last step is to file a proper bug report against the package that uses our usertag and CCs pkg-systemd-maintainers. See http://bugs.debian.org/714190 for an example. Replacing custom maintscripts with dh-systemd Check if the package currently has any direct systemctl calls in its maintscripts and remove them if so (see http://bugs.debian.org/713853 for an example). Follow https://wiki.debian.org/Systemd/Packaging to add systemd support using the dh-systemd helper. Check whether the maintscripts look good and generate a debdiff to highlight the differences between the old and the new version:
debdiff --controlfiles=ALL OLD_amd64.changes NEW_amd64.changes
Then file a bug report which uses our usertag and CCs pkg-systemd-maintainers. See http://bugs.debian.org/713853 for an example. Thanks! Thank you for helping us and Debian in general!

Niels Thykier: Britney excuses out of date

In my previous post, I explained about the age excuse in Britney. In this post, I will cover the slightly more tricky out of date excuse. A simple example of excuse is:
out of date on mipsel: blinken (from 4:4.8.4-1)
In this simple case, Britney simply states that the binary blinken on mipsel has not yet been rebuilt. Generally, the presence of an excuse like this is sufficient to stop testing migration. The exception to this rule is if the architecture has been marked as not keeping up . At the moment we do not have any such architectures. The tricky part of an out of date -excuse is that Britney simply identifies a symptom and not a cause. In the excuse above, it is not possible to determine if the build failed on that architecture or simply has not finished yet. But the part that probably confuses the most, is when Britney lists binaries no longer built from that source:
out of date on i386: libfsoframework0 (from 0.11.0-1.1)
This case actually happens quite often and is (usually) a sign of a transition has been started. The part that confuses many is that the build-state of their package will be Installed (as in It was built successfully and has been uploaded to the archive ). From there they tend to conclude Britney is broken , where The excuse information is a bit unhelpful might be more accurate. Caveats:
  1. If the source package has not yet been built on that architecture, these old binaries are interleaved into the regular list of out of date -binaries.
  2. The list of excuses are updated twice a day (and there is also a delay between its update and the PTS picking it up). Thus, if the build-state of your package for that architecture has been Installed for less than 24 hours, you may just want double check before jumping to conclusions.
The problem is that the binary still has reverse dependencies in unstable, so it cannot migrate to testing. When the last reverse dependency has been updated, the FTP masters will usually semi-automatically decruft your package and the excuse will disappear. On the other hand, if the binary still has reverse dependencies, you probably started a transition. In that case, your package will be stuck in unstable until all the reverse dependencies are ready (or, at least, rebuilt to use the replacement package). Generally, it is good if the Release Team was involved before you did this (see this page ). In summary, if your package has Out of date on [architecture] in its excuses it can be one (or more) of:

Nicolas Dandrimont: Bootstrapping fedmsg for Debian

As you might (or might not) know, this summer, I have taken on mentoring of a GSoC project by Simon Chopin (a.k.a. laarmen) which goal is to bring fedmsg, the Fedora Infrastructure message bus, to Debian. Most of the work I ll be talking about here is Simon s work, please send all the praise towards him (I can take the blame, though). What is this about? As the project proposal states, the idea is to provide Debian with a unified, real-time, and open mechanism of communication between its services. This communication bus would allow anyone, anywhere, to start consuming messages and reacting to events happening in Debian s infrastructure: When we told upstream about our plan of adapting fedmsg to work on Debian, they were thrilled. And they have been very supportive of the project. How is the project going? Are you excited? I know I m excited. yep, he's excited too Well, the general idea was easy enough, but the task at hand is a challenge. First of all, fedmsg has a lot of (smallish) dependencies, most of them new to Debian. Thanks to Simon s work during the bonding period, and thanks to paultag s careful reviews, the first batch of packages (the first dependency level, comprising kitchen, bunch, m2ext, grapefruit, txws, txzmq and stomper) is currently sitting in the NEW queue. The four remaining packages (fabulous, moksha.common, moksha.hub and fedmsg proper) are mostly ready, waiting in the Debian Python Module Team SVN repository for a review and sponsorship. While we re waiting for the packages to trickle into Debian, Simon is not twiddling his thumbs. Work has taken place on a few fronts: fedmsging mentors.debian.net Package backports mentors.debian.net was chosen because I m an admin and could do the integration quickly. That involved backporting the eleven aforementioned packages, plus zeromq3 and python-zmq (that only have TCP_KEEPALIVE on recent versions), to wheezy, as that s what the mentors.d.n host is running. (Also, python-zmq needs a new-ish cython to build so I had to backport that too). Thankfully, those were no-changes backports, that were easily scripted, using a pbuilder hook to allow the packages to depend on previously built packages. I have made a wheezy package repository available here. It s signed with my GnuPG key, ID 0xB8E5087766475AAF, which should be fairly well connected. Code changes After Simon s initial setup of debexpo (which is not an easy task), the code changes have been fairly simple (yes, this is just a proof of concept). You can see them on top of the live branch on debexpo s sources. I finally had the time to make them live earlier this week, and mentors.debian.net has been sending messages on Debian s fedmsg bus ever since. Deployment mentors.d.n sends its messages on five endpoints, tcp://mentors.debian.net:3000 through tcp://mentors.debian.net:3004. That is one endpoint per WSGI worker, plus one for the importer process(es). You can tap in directly, by following the instructions below. debmessenger Debmessenger is the stop-gap email-to-fedmsg bridge that Simon is developing. The goal is to create some activity on the bus without disrupting or modifying any infrastructure service. It s written in hy, and it leverages the existing Debian-related python modules to do its work, using inotify to react when a mail gets dropped in a Maildir. Right now, it s supposed to understand changes mails (received from debian-devel-changes) and bugs mail (from debian-bugs-dist). I ll work on deploying an instance of debmessenger this weekend, to create some more traffic on the bus. Reliability of the bus I suggested using fedmsg as this was something that already existed, and that solved a problem identical to the one we wanted to tackle (open interconnection of a distribution s infrastructure services). Reusing a piece of infrastructure that already works in another distro means that we can share tools, share ideas, and come up with solutions that we might not have considered when working alone. The drawback is that we have to either adapt to the tool s idiosyncrasies, or to adapt the tool to our way of working. One of the main points raised by DSA when the idea of using fedmsg was brought up, was that of reliability. Debian s infrastructure is spread in datacenters (and basements :D ) all over the world, and thus faces different challenges than Fedora s infrastructure, which is more tightly integrated. Therefore, we have to ensure that a critical consumer (say, a buildd) doesn t miss any message it would need for its operation (say, that a package got accepted). There has been work upstream, to ensure that fedmsg doesn t lose messages, but we need to take extra steps to make sure that a given consumer can replay the messages it has missed, should the need arise. Simon has started a discussion on the upstream mailing list, and is working on a prototype replay mechanism. Obviously, we need to test scenarios of endpoints dropping off the grid, hence the work on getting some activity on the bus. How can I take a look? a.k.a. Another one rides the bus A parisian bus built in 1932 (Picture Yves-Laurent Allaert, CC-By-SA v2.5 / GFDL v1.2 license) So, the bus is pretty quiet right now, as only two kinds of events are triggering messages: a new upload to mentors.debian.net, and a new comment on a package there. Don t expect a lot of traffic. However, generating some traffic is easy enough: just login to mentors.d.n, pick a package of mine (not much choice there), or a real package you want to review, and leave a comment. poof, a message appears. For the lazy Join #debian-fedmsg on OFTC, and look for messages from the debmsg bot. Current example output:
01:30:25 <debmsg> debexpo.voms-api-java.upload (unsigned) --
02:03:16 <debmsg> debexpo.ocamlbricks.comment (unsigned) --
(definitely needs some work, but it s a start) Listening in by yourself You need to setup fedmsg. I have a repository of wheezy packages and one of sid packages, signed with my GnuPG key, ID 0xB8E5087766475AAF. You can add them to a file in /etc/apt/sources.list.d like this:
deb http://perso.crans.org/dandrimont/fedmsg-<sid wheezy>/ ./
Then, import my GnuPG key into apt (apt-key add), update your sources (apt-get update), and install fedmsg (apt-get install python-fedmsg). The versions are << to anything real, so you should get the real thing as soon as it hits the archive. Finally, in /etc/fedmsg.d/endpoints.py, you can comment-out the Fedora entries, and add a Debian entry like this:
    "debian": [
        "tcp://fedmsg.olasd.eu:9940",
    ],
fedmsg.olasd.eu runs a fedmsg gateway connected to the mentors.d.n endpoints, and thus forwards all the mentors messages. It ll be connected to debmessenger as soon as it s running too. To actually see mesages, disable validate_signatures in /etc/fedmsg.d/ssl.py, setting it to False. The Debian messages aren t signed yet (it s on the roadmap), and we don t ship the Fedora certificates so we can t authenticate their messages either. Finally, you can run fedmsg-tail --really-pretty in a terminal. As soon as there s some activity, you should get that kind of output (color omitted):
 
  "i": 1, 
  "msg":  
    "version": "2.0.9-1.1", 
    "uploader": "Emmanuel Bourg <ebourg@apache.org>"
   , 
  "topic": "org.debian.dev.debexpo.voms-api-java.upload", 
  "username": "expo", 
  "timestamp": 1373758221.491809
 
Enjoy real-time updates from your favorite piece of infrastructure! What s next? While Simon continues working on reliability, and gets started on message signing according to his schedule, I ll take a look at deploying the debmessenger bridge, and making the pretty-printer outputs useful for our topics. There will likely be some changes to the messages sent by debexpo, as we got some feedback from the upstream developers about making them work in the fedmsg tool ecosystem (datanommer and datagrepper come to mind). You can tune in to Simon s weekly reports on the soc-coordination list, and look at the discussions with upstream on the fedora messaging-sig list. You can also catch us on IRC, #debian-soc on OFTC. We re also hanging out on the upstream channel, #fedora-apps on freenode.

13 July 2013

Michael Stapelberg: Survey answers part 3: systemd is not portable and what this means for our ports

This blog post is the third of a series of posts dealing with the results of the Debian systemd survey. I intend to give a presentation at DebConf 2013, too, so you could either read my posts, or watch the talk, or both :-). The second-biggest concern in the survey results was that systemd is not portable to non-Linux systems, for example Debian GNU/kFreeBSD or Debian GNU/HURD. For convenience, I will from now on write kFreeBSD when I really mean all non-Linux ports. systemd not being portable is not an arbitrary decision Some people seem to think that the systemd upstream is just hostile to users of other operating systems when they hear that systemd is not portable. However, keep in mind that Lennart, Kay and other contributors have considerable experience with writing portable software such as Avahi and PulseAudio. The decision to only support Linux in systemd was thus not taken lightly. systemd s design requires many kernel features and certain semantics (e.g. procfs is not enough, /proc/$PID/exe needs to be supported), which are currently only available on Linux. Point 15 of Lennart s blog post 0pointer.de/blog/projects/the-biggest-myths.html contains an incomplete list of these features. Maintaining portable code increases complexity Since systemd is written in C, the canonical way to write portable code is by using conditional compilation, for example with ifdef statements. That makes the code harder to understand and reason about, but more importantly it blows up the test matrix. It also requires any new change to be tested on all supported systems, which is not feasible for most contributors. I think everybody agrees keeping complexity low is a good thing. What are the implications for our non-Linux ports? We, the Debian project, have two realistic options in my point of view:
  1. We stay with sysvinit, the least common denominator, forever.
  2. We use a modern init system such as systemd on Debian GNU/Linux.
In case we go with the first option, Debian will diverge more and more from virtually every other Linux distribution. This also means we are stuck with the limited features and capabilities that sysvinit has. A modern operating system needs to be able to adapt to a changing environment and the once static world in which sysvinit was developed has become much more dynamic. In our opinion, the only reasonable choice is the latter option: use systemd on Debian GNU/Linux. How will this work? For individual maintainers, this means they need to support two init systems. Luckily, systemd service files are usually really simple, but there still is additional maintenance work such as testing whether your service actually starts when using systemd. We think this maintenance overhead is justified due to the advantages a modern init system brings. Of course, not every maintainer can arrange it to install systemd and test his/her package. You are invited to contact us at pkg-systemd-maintainers@lists.alioth.debian.org at any time and we can help you out. Furthermore, automation can be introduced (and we have a proof of concept) to make it easier to spot mistakes and perform some simple tests, such as whether the service can be started. A concern that was voiced is that as sysvinit usage decreases, the init scripts would bit-rot and stop working at some point. If that happens, we rely on the users to file appropriate bug reports. This is no different from the situation today it is not feasible for maintainers to test every single combination of features all the time. Ports are different and that diversity is good The FreeBSD kernel and the Linux kernel are different, and each kernel provides distinct features that the other kernel does not have. As an example, Linux provides cgroups, which are heavily used by systemd. The FreeBSD kernel in turn offers the packet filter pf , which is not available on Linux. There certainly is value in having common infrastructure. But there also is value in providing the best features that each platform has to offer in case of Linux, that is clearly systemd as an init system IMO. Conclusion systemd is not portable because it relies on features only the Linux kernel provides an example is cgroups, which systemd uses to track processes in a reliable way. Not embracing these features and staying with sysvinit indefinitely is not a viable option if Debian wants to remain relevant for today s demands. In the short term, the migration to systemd will cause additional maintenance effort for individual package maintainers, but it will pay off in the long term.

Francesca Ciceri: #debcraft n.2: a Debian cozy for your smartphone

please, do try this at home My second #debcraft project is a crocheted cozy for a phone, with a nice Debian swirl on it.
As the previous one this is a very quick project - I made mine in half an hour - and easy also for crochet newbies.
As I've not mastered yet the tapestry technic in crochet, I opted for a less elegant solution and used a surface slip stitch to add the swirl.
The only downside of this approach is that you'll need a bit of practice before crocheting a decent and regular swirl (it took me a couple of tries to get the hang of it).
My phone is a Samsung Galaxy, so this pattern fits a phone of 6cm x 11cm x 1cm, but you can easily adapt it to yours. This pattern is written in US crochet terms: check this page for a US/UK conversion table. the finished result What you will need Obviously, the crochet hook's size depends on the weight of the yarn you're using. I used a DK/8 ply cotton yarn. Finished size : 11cm x 8cm x 1cm Stitches used : Instructions Ch 15 + 1 for turning. Continue in flat rows, working 15 sc each row, plus one ch at the end to turn.
Continue till the desired dimensions, in my case I ended with a rectangle 22cm long.
Now the fun part: with the red yarn, start creating a swirl with the surface stitches.
Here's a good tutorial on how to do these, with step-by-step photos. the cozy after having added the surface stitches Now the last part: use the single crochet stitch to join the lateral seams of the cozy as showed in this tutorial. And you're finished! Pretty easy, wasn't it? For any questions feel free to contact me.
And if you are a knitter or a crocheter, did you know that on Ravelry exists the Debian Knitters group?

12 July 2013

Justus Winter: Hi, I'm the one who wrote umount...

Everyone enjoys ASCII screenshots as much as I do, right? So here is the Hurd booting with my mtab-prototype bound to /run/mtab:
INIT: version 2.88 booting
Using makefile-style concurrent boot in runlevel S.
Activating swap...done.
Checking root file system...fsck from util-linux 2.20.1
hd2 : tray open or drive not ready
end_request: I/O error, dev 02:00, sector 0
/dev/hd0s1: clean, 44292/181056 files, 287759/723200 blocks
done.
Activating lvm and md swap...(default pager): Already paging to partition hd0s5!
done.
Checking file systems...fsck from util-linux 2.20.1
hd2 : tray open or drive not ready
end_request: I/O error, dev 02:00, sector 0
done.
Cleaning up temporary files... /tmp.
Mounting local filesystems...done.
Activating swapfile swap...(default pager): Already paging to partition hd0s5!
done.
Cleaning up temporary files....
Configuring network interfaces...inetutils-ifconfig: invalid arguments
ifup: failed to open pid file /run/network/ifup-/dev/eth0.pid: No such file or directory
Internet Systems Consortium DHCP Client 4.2.2
Copyright 2004-2011 Internet Systems Consortium.
All rights reserved.
For info, please visit https://www.isc.org/software/dhcp/
can't create /var/lib/dhcp/dhclient./dev/eth0.leases: No such file or directory
Listening on Socket//dev/eth0
Sending on   Socket//dev/eth0
DHCPDISCOVER on /dev/eth0 to 255.255.255.255 port 67 interval 4
DHCPREQUEST on /dev/eth0 to 255.255.255.255 port 67
DHCPOFFER from 10.0.2.2
DHCPACK from 10.0.2.2
can't create /var/lib/dhcp/dhclient./dev/eth0.leases: No such file or directory
bound to 10.0.2.15 -- renewal in 42550 seconds.
done.
Cleaning up temporary files....
Setting up X socket directories... /tmp/.X11-unix /tmp/.ICE-unix.
INIT: Entering runlevel: 2
Using makefile-style concurrent boot in runlevel 2.
Starting enhanced syslogd: rsyslogd.
Starting deferred execution scheduler: atd.
Starting periodic command scheduler: cron.
Starting system message bus: dbusFailed to set socket option"/var/run/dbus/system_bus_socket": Protocol not available.
Starting OpenBSD Secure Shell server: sshd.
GNU 0.3 (debian) (console)
login:
As you can see, the boot process looks quite clean. In particular, there are no issues left with Debians initscripts. The remaining noise comes from: This is accomplished by my mtab translator prototype. It's work in progress, but I have reworked and broken up my initial prototype. My initial prototype only patched libdiskfs, one of three libraries translator authors can use to write filesystem-like translators. I have made the necessary changes to the other two libraries and patched up any loose ends. This is the translator in action:
% fsysopts /run/mtab
/hurd/mtab /
% cat /run/mtab
/dev/hd0s1 / ext2fs writable,no-inherit-dir-group,store-type=typed 0 0
none /dev/ttyp0 /hurd/term name,/dev/ptyp0,type,pty-master 0 0
none /run /hurd/tmpfs writable,no-suid,no-exec,no-inherit-dir-group,no-sync,size=80484K 0 0
none /run/lock /hurd/tmpfs writable,no-suid,no-exec,no-inherit-dir-group,no-sync,size=5M 0 0
none /run/shm /hurd/tmpfs writable,no-suid,no-exec,no-inherit-dir-group,no-sync,size=259480K 0 0
I also patched the sysvinit package. My version includes and switches to runsystem.sysv that uses /sbin/init to start the system. It also carries all the necessary workarounds for the remaining sysvinit related issues. The resulting Debian/Hurd system is very nice, it is getting more and more similar to what a Debian user would expect: I have rebuild the hurd and sysvinit package and uploaded them into an apt repository:
deb http://teythoon.cryptobitch.de/gsoc/heap/debian unstable main
Please use unstable for now. Also make sure that you have a recovery plan for your Debian/Hurd installation if anything goes wrong. For your convenience there's a seed tarball containing packages with the appropriate sources.list.d snippets and the repository key: https://teythoon.cryptobitch.de/gsoc/heap/debian/seed.tar Currently /hurd/console is not started (I'll add a init script for that later), but for now you have to start a getty on the console. Make sure that your /etc/inittab contains a line like this:
7:2345:respawn:/sbin/getty 38400 console
The patched initscripts package contains the runsystem.sysv file and uses the Debian alternatives system to replace the runsystem.gnu variant. It also switches to the appropriate halt and reboot utilities. If you install the package, you must use halt-hurd or reboot-hurd to halt or reboot the system. Running halt or reboot is not harmful though, it just doesn't work. So here I am. I've been coding for the Hurd for four weeks now, and suddenly I'm the guy who wrote umount. My point is, if you ever wanted to work on an operating system, you might want to consider working on the Hurd. It the Debian/Hurd port is very decent and (according to #debian-hurds "Debian GNU/Hurd Doomsday-o-meter") 78.44% of all Debian packages are available, so you've got a familiar environment. Also, if your solution is right and your code is reasonably clean, it is not that hard to get your changes accepted. The list of open issues is long and might contain something that interests you. You could be the one implementing a read-ahead solution to massively improve Hurds overall performance. Also since Hurd is just a Hird of Unix replacing daemons running on-top the GNU Mach microkernel, most of the functionality lies within userspace processes. This makes the whole system very extensible and quite easy to work with. For an overview over the Hurd, see this page. Next week I'll focus on improving my mtab prototype, improving the sysvinit patches and upstreaming the ones that are ready. As always, in case I run out of stuff to do, I'll pick something from my list of issues, most likely the network related issues. In completely unrelated news, my Debian/Linux workstation died with a kernel panic while I was writing this blog entry. It's a good thing Emacs honors "save early, save often". M-x insert-monolithic-kernel-rant-here. This is it for this week, thanks for your attention :)

Daniel Pocock: Practical VPNs with strongSwan, Shorewall, Linux firewalls and OpenWRT routers

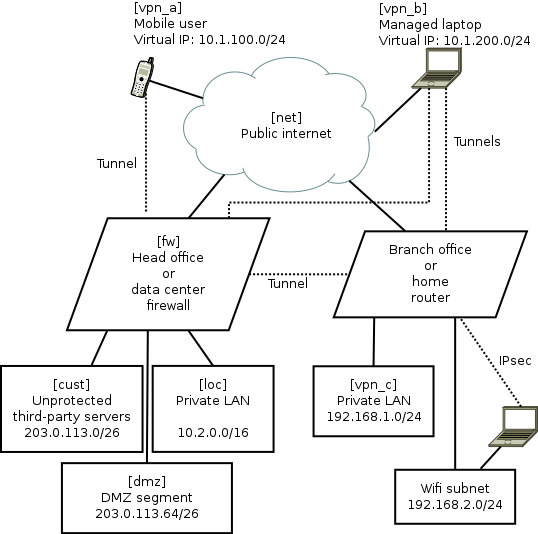
There is intense interest in communications privacy at the moment thanks to the Snowden scandal. Open source software has offered credible solutions for privacy and encryption for many years. Sadly, making these solutions work together is not always plug-and-play. In fact, secure networking, like VoIP, has been plagued by problems with interoperability and firewall/filtering issues although now the solutions are starting to become apparent. Here I will look at some of them, such as the use of firewall zones to simplify management or the use of ECDSA certificates to avoid UDP fragmentation problems. I've drawn together a lot of essential tips from different documents and mailing list discussions to demonstrate how to solve a real-world networking problem. A typical network scenario and requirements Here is a diagram of the network that will be used to help us examine the capabilities of these open source solutions. Some comments about the diagram:
  • The names in square brackets are the zones for Shorewall, they are explained later.
  • The dotted lines are IPsec tunnels over the untrusted Internet.
  • The road-warrior users (mobiles and laptops) get virtual IP addresses from the VPN gateway. The branch offices/home routers do not use virtual IPs.
  • The mobile phones are largely untrusted: easily lost or stolen, many apps have malware, they can only tunnel to the central VPN and only access a very limited range of services.
  • The laptops are managed devices so they are trusted with access to more services. For efficiency they can connect directly to branch office/home VPNs as well as the central server.
  • Smart-phone user browsing habits are systematically monitored by mobile companies with insidious links into mass-media and advertising. Road-warriors sometimes plug-in at client sites or hotels where IT staff may monitor their browsing. Therefore, all these users want to tunnel all their browsing through the VPN.
  • The central VPN gateway/firewall is running strongSwan VPN and Shorewall firewall on Linux. It could be Debian, Fedora or Ubuntu. Other open source platforms such as OpenBSD are also very well respected for building firewall and VPN solutions, but Shorewall, which is one of the key ingredients in this recipe, only works on Linux at present.
  • The branch office/home network could be another strongSwan/Shorewall server or it could also be an OpenWRT router
  • The default configuration for most wifi routers creates a bridge joining wifi users with wired LAN users. Not here, it has been deliberately configured as an independent network. Road-warriors who attach to the wifi must use VPN tunnelling to access the local wired network. In OpenWRT, it is relatively easy to make the Wifi network an independent subnet. This is an essential security precaution because wifi passwords should not be considered secure: they are often transmitted to third parties, for example, by the cloud backup service in many newer smart phones.
Package mayhem The major components are packaged on all the major Linux distributions. Nonetheless, in every case, I found that it is necessary to re-compile fresh strongSwan packages from sources. It is not so hard to do but it is necessary and worth the effort. Here are related blog entries where I provide the details about how to re-build fresh versions of the official packages with all necessary features enabled: Using X.509 certificates as a standard feature of the VPN For convenience, many people building a point-to-point VPN start with passwords (sometimes referred to as pre-shared keys (PSK)) as a security mechanism. As the VPN grows, passwords become unmanageable. In this solution, we only look at how to build a VPN secured by X.509 certificates. The certificate concept is not hard. In this scenario, there are a few things that make it particularly easy to work with certificates:
  • strongSwan comes with a convenient command line tool, ipsec pki. Many of it's functions are equivalent to things you can do with OpenSSL or GnuTLS. However, the ipsec pki syntax is much more lightweight and simply provides a convenient way to do the things you need to do when maintaining a VPN.
  • Many of the routine activities involved in certificate maintainence can be scripted. My recent blog about using Android clients with strongSwan gives a sample script demonstrating how ipsec pki commands can be used to prepare a PKCS#12 (.p12) file that can be easily loaded into an Android device using the SD-card.
  • For building a VPN, there is no need to use a public certificate authority such as Verisign. Consequently, there is no need to fill in all their forms or make any payments for each device/certificate. Some larger organisations do choose to outsource their certificate management to such firms. For smaller organisations, an effective and sometimes better solution can be achieved by maintaining the process in-house with a private root CA.
UDP fragmentation during IPsec IKEv2 key exchange and ECDSA A common problem for IPsec VPNs using X.509 certificates is the fragmentation of key exchange datagrams during session setup. Sometimes it works, sometimes it doesn't. Various workarounds exist, such as keeping copies of all certificates from potential peers on every host. As the network grows, this becomes inconvenient to maintain and to some extent it eliminates the benefits of using PKI. Fortunately, there is a solution: Elliptic Curve Cryptography (ECC). Many people currently use RSA key-pairs. Best practice suggests using RSA keys of at least 2048 bits and often 4096 bits. Using ECC with a smaller 384-bit key is considered to be equivalent to a 7680 bit RSA key pair. Consequently, ECDSA certificates are much smaller than RSA certificates. Furthermore, at these key sizes, the key exchange packets are almost always smaller than the typical 1500 byte MTU. A further demand for ECDSA is arising due to the use of ECC within smart cards. Many smartcards don't support any RSA key larger than 2048 bits. The highly secure 384-bit ECC key is implemented in quite a few common smart cards. Smart card vendors have shown a preference for the ECC keys due to the US Government's preference for ECC and the lower computational overheads make them more suitable for constrained execution environments. Anyone who wants to use smart cards as part of their VPN or general IT security now, or in the future, needs to consider ECC/ECDSA. Making the network simple with Shorewall zones For this example, we are not just taking some easy point-to-point example. We have a real-world, multi-site, multi-device network with road warriors. Simplifying this architecture is important to help us understand and secure it. The solution? Each of these is abstracted to a "zone" in Shorewall. In the diagram above, the zone names are in square brackets. The purpose of each zone is described below:
Zone name Description
loc This is the private LAN and contains servers like databases, private source code respositories and NFS file servers
dmz This is the DMZ and contains web servers that are accessible from the public internet. Some of these servers talk to databases or message queues in the LAN network loc
vpn_a These are road warriors that are not very trustworthy, such as mobile devices. They are occasionally stolen and usually full of spyware (referred to by users as "apps"). They have limited access to ports on some DMZ servers, e.g. for sending and receiving mail using SMTP and IMAP (those ports are not exposed to the public Internet at large). They use the VPN tunnel for general internet access/browsing, to avoid surveillance by their mobile carrier.
vpn_b These are managed laptops that have a low probability of malware infection. They may well be using smart cards for access control. Consequently, they are more trusted than the vpn_a users and have access to some extra intranet pages and file servers. Like the smart-phone users, they use the VPN tunnel for general internet access/browsing, to avoid surveillance by third-party wifi hotspot operators.
vpn_c This firewall zone represents remote sites with managed hardware, such as branch offices or home networks with IPsec routers running OpenWRT.
cust These are servers hosted for third-parties or collaborative testing/development purposes. They have their own firewall arrangements if necessary.
net This zone represents traffic from the public Internet.
A practical Shorewall configuration Shorewall is chosen to manage the iptables and ip6tables firewall rules. Shorewall provides a level of abstraction that makes netfilter much more manageable than manual iptables scripting. The Shorewall concept of zones is very similar to the zones implemented in OpenWRT and this is an extremely useful paradigm for firewall management. Practical configuration of Shorewall is very well explained in the Shorewall quick start. The one thing that is not immediately obvious is a strategy for planning the contents of the /etc/shorewall/policy and /etc/shorewall/rules files. The exact details for making it work effectively with a modern IPsec VPN are not explained in a single document, so I've gathered those details below as well. An effective way to plan the Shorewall zone configuration is with a table like this:
Destination zone
loc dmz vpn_a vpn_b vpn_c cust net
Source zone loc \
dmz ? \ X X X
vpn_a ? ? \ X X
vpn_b ? ? X \ X
vpn_c X \
cust X ? X X X \
net X ? X X X \
The symbols in the table are defined:
Symbol Meaning
ACCEPT in policy file
X REJECT or DROP in policy file
? REJECT or DROP in policy file, but ACCEPT some specific ports in the rules file
Naturally, this modelling technique is valid for both IPv4 and IPv6 firewalling (with Shorewall6) Looking at the diagram in two dimensions, it is easy to spot patterns. Each pattern can be condensed into a single entry in the rules file. For example, it is clear from the first row that the loc zone can access all other zones. That can be expressed very concisely with a single line in the policy file:
loc all ACCEPT
Specific Shorewall tips for use with IPsec VPNs and strongSwan Shorewall has several web pages dedicated to VPNs, including the IPsec specific documentation.. Personally, I found that I had to gather a few details from several of these pages to make an optimal solution. Here are those tips:
  • Ignore everything about the /etc/shorewall/tunnels file. It is not needed and not used any more
  • Name the VPN zones (we call them vpn_a, vpn_b and vpn_c) in the zones file but there is no need to put them in the /etc/shorewall/interfaces file.
  • The /etc/shorewall/hosts file is not just for hosts and can be used to specify network ranges, such as those associated with the VPN virtual IP addresses. The ranges you put in this file should match the rightsourceip pool assignments in strongSwan's /etc/ipsec.conf
  • One of the examples suggests using mss=1400 in the /etc/shorewall/zones file. I found that is too big and leads to packets being dropped in some situations. To start with, try a small value such as 1024 and then try larger values later after you prove everything works. Setting mss for IPsec appears to be essential.
  • Do not use the routefilter feature in the /etc/shorewall/interfaces file as it is not compatible with IPsec
Otherwise, just follow the typical examples from the Shorewall quick start guide and configure it to work the way you want. Here is an example /etc/shorewall/zones file:
fw firewall
net ipv4
dmz ipv4
loc ipv4
cust ipv4
vpn_a ipsec mode=tunnel mss=1024
vpn_b ipsec mode=tunnel mss=1024
vpn_c ipsec mode=tunnel mss=1024
Here is an example /etc/shorewall/hosts file describing the VPN ranges from the diagram:
vpn_a eth0:10.1.100.0/24 ipsec
vpn_b eth0:10.1.200.0/24 ipsec
vpn_c eth0:192.168.1.0/24 ipsec
Here is an example /etc/shorewall/policy file based on the table above:
loc all ACCEPT
vpn_c all ACCEPT
cust net ACCEPT
net cust ACCEPT
all all REJECT
Here is an example /etc/shorewall/rules file based on the network:
SECTION ALL
# allow connections to the firewall itself to start VPNs:
# Rule  source    dest    protocol/port details
ACCEPT   all       fw                ah
ACCEPT   all       fw                esp
ACCEPT   all       fw                udp 500
ACCEPT   all       fw                udp 4500
# allow access to HTTP servers in DMZ:
ACCEPT   all       dmz               tcp 80
# allow connections from HTTP servers to MySQL database in private LAN:
ACCEPT   dmz       loc:10.2.0.43     tcp 3306
# allow connections from all VPN users to IMAPS server in private LAN:
ACCEPT vpn_a,vpn_b,vpn_c loc:10.2.0.58 tcp 993
# allow VPN users (but not the smartphones in vpn_a) to the
# PostgresQL database for PostBooks accounting system:
ACCEPT vpn_b,vpn_c loc:10.2.0.48      tcp 5432
SECTION ESTABLISHED
ACCEPT   all       all
SECTION RELATED
ACCEPT   all       all
Once the files are created, Shorewall can be easily activated with:
# shorewall compile && shorewall restart
strongSwan IPsec VPN setup Like Shorewall, strongSwan is also very well documented and I'm just going to focus on those specific areas that are relevant to this type of VPN project.
  • Allow the road-warriors to send all browsing traffic over the VPN means including leftsubnet=0.0.0.0/0 in the VPN server's /etc/ipsec.conf file. Be wary though: sometimes the road-warriors start sending the DHCP renewal over the tunnel instead of to their local DHCP server.
  • As we are using Shorewall zones for firewalling, you must set the options leftfirewall=no and lefthostaccess=no in ipsec.conf. Shorewall already knows about the remote networks as they are defined in the /etc/shorewall/hosts file and so firewall rules don't need to be manipulated each time a tunnel goes up or down.
  • As discussed above, X.509 certificates are used for peer authentication. In the certificate Distinguished Name (DN), store the zone name in the Organizational Unit (OU) component, for example, OU=vpn_c, CN=gw.branch1.example.org
  • In the ipsec.conf file, match the users to connections using wildcard specifications such as rightid="OU=vpn_a, CN=*"
  • Put a subjectAltName with hostname in every certificate. The --san option to the ipsec pki commands adds the subjectAltName.
  • Keep the certificate distinguished names (DN) short, this makes the certificate smaller and reduces the risk of fragmented authentication packets. Many examples show a long and verbose DN such as C=GB, O=Acme World Wide Widget Corporation, OU=Engineering, CN=laptop1.eng.acme.example.org. On a private VPN, it is rarely necessary to have all that in the DN, just include OU for the zone name and CN for the host name.
  • As discussed above, use the ECDSA scheme for keypairs (not RSA) to ensure that the key exchange datagrams don't suffer from fragmentation problems. For example, generate a keypair with the command ipsec pki --gen --type ecdsa --size 384 > user1Key.der
  • Road warriors should have leftid=%fromcert in their ipsec.conf file. This forces them to use the Distinguished Name and not the subjectAltName (SAN) to identify themselves.
  • For road warriors who require virtual tunnel IPs, configure them to request both IPv4 and IPv6 addresses (dual stack) with leftsourceip=%config4,%config6 and on the VPN gateway, configure the ranges as arguments to rightsourceip
  • To ensure that roadwarriors query the LAN DNS, add the DNS settings to strongswan.conf and make sure road warriors are using a more recent strongSwan version that can dynamically update /etc/resolv.conf. Protecting DNS traffic is important for privacy reasons. It also makes sure that the road-warriors can discover servers that are not advertised in public DNS records.
Central firewall/VPN gateway configuration Although they are not present in the diagram, IPv6 networks are also configured in these strongSwan examples. It is very easy to combine IPv4 and IPv6 into a single /etc/ipsec.conf file. As long as the road-warriors have leftsourceip=%config4,%config6 in their own configurations, they will operate dual-stack IPv4/IPv6 whenver they connect to the VPN. Here is an example /etc/ipsec.conf for the central VPN gateway:
config setup
        charonstart=yes
        charondebug=all
        plutostart=no
conn %default
        ikelifetime=60m
        keylife=20m
        rekeymargin=3m
        keyingtries=1
        keyexchange=ikev2
conn branch1
        left=198.51.100.1
        leftsubnet=203.0.113.0/24,10.0.0.0/8,2001:DB8:12:80:/64
        leftcert=fw1Cert.der
        leftid=@fw1.example.org
        leftfirewall=no
        lefthostaccess=no
        right=%any
        rightid=@branch1-fw.example.org
        rightsubnet=192.168.1.0/24
        auto=add
conn rw_vpn_a
        left=198.51.100.1
        leftsubnet=0.0.0.0/0,::0/0
        leftcert=fw1Cert.der
        leftid=@fw1.example.org
        leftfirewall=no
        lefthostaccess=no
        right=%any
        rightid="OU=vpn_a, CN=*"
        rightsourceip=10.1.100.0/24,2001:DB8:1000:100::/64
        auto=add
conn rw_vpn_b
        left=198.51.100.1
        leftsubnet=0.0.0.0/0,::0/0
        leftcert=fw1Cert.der
        leftid=@fw1.example.org
        leftfirewall=no
        lefthostaccess=no
        right=%any
        rightid="OU=vpn_b, CN=*"
        rightsourceip=10.1.200.0/24,2001:DB8:1000:200::/64
        auto=add
Sample branch office or home router VPN configuration Here is an example /etc/ipsec.conf for the Linux server or OpenWRT VPN at the branch office or home:
conn head_office
        left=%defaultroute
        leftid=@branch1-fw.example.org
        leftcert=branch1-fwCert.der
        leftsubnet=192.168.1.0/24,2001:DB8:12:80:/64
        leftfirewall=no
        lefthostaccess=no
        right=fw1.example.org
        rightid=@fw1.example.org
        rightsubnet=203.0.113.0/24,10.0.0.0/8,2001:DB8:1000::/52
        auto=start
# notice we only allow vpn_b users, not vpn_a
# these users are given virtual IPs from our own
# 192.168.1.0 subnet
conn rw_vpn_b
        left=branch1-fw.example.org
        leftsubnet=192.168.1.0/24,2001:DB8:12:80:/64
        leftcert=branch1-fwCert.der
        leftid=@branch1-fw.example.org
        leftfirewall=no
        lefthostaccess=no
        right=%any
        rightid="OU=vpn_b, CN=*"
        rightsourceip=192.168.1.160/27,2001:DB8:12:80::8000/116
        auto=add
Further topics Shorewall and Shorewall6 don't currently support a unified configuration. This can make it slightly tedious to duplicate rules between the two IP variations. However, the syntax for IPv4 and IPv6 configuration is virtually identical. Shorewall only currently supports Linux netfilter rules. In theory it could be extended to support other types of firewall API, such as pf used by OpenBSD and the related BSD family of systems. A more advanced architecture would split the single firewall into multiple firewall hosts, like the inner and outer walls of a large castle. The VPN gateway would also become a standalone host in the DMZ. This would require more complex routing table entries. Smart cards with PIN numbers provide an effective form of two-factor authentication that can protect certificates for remote users. Smart cards are documented well by strongSwan already so I haven't repeated any of that material in this article. Managing a private X.509 certificate authority in practice may require slightly more effort than I've described, especially when an organisation grows. Small networks and home users don't need to worry about these details too much, but for most deployments it is necessary to consider things like certificate revocation lists and special schemes to protect the root certificate's private key. EJBCA is one open source project that might help. Some users may want to consider ways to prevent the road-warriors from accidentally browsing the Internet when the IPsec tunnel is not active. Such policies could be implemented with some basic iptables firewalls rules in the road-warrior devices. Summary Using these strategies and configuration tips, planning and building a VPN will hopefully be much simpler. Please feel free to ask questions on the mailing lists for any of the projects discussed in this blog.

Keith Packard: Present

The Present Extension I ve finally gotten an initial implementation of the Present extension written and running and thought I should write up the current design and status. Present Design The current Present extension consists of two requests:
  1. PresentRegion. Puts new bits from a pixmap in a window.
  2. PresentSelectInput. Asks for Present events to be delivered.
PresentRegion This request takes a pile of arguments:
 
    PresentRegion
    window: WINDOW
    pixmap: PIXMAP
    valid-area: REGION or None
    update-area: REGION or None
    x-off, y-off: INT16
    target-msc: CARD64
    divisor: CARD64
    remainder: CARD64
    idle-fence: FENCE
 
Errors: Drawable, Pixmap, Match
Provides new content for the specified window, to be made visible at the specified time (defined by target-msc , divisor and remainder ). update-area defines the subset of the window to be updated, or None if the whole window is to be updated. valid-area defines the portion of pixmap which contains valid window contents, or None if the pixmap contains valid contents for the whole window. PresentRegion may use any region of pixmap which contains update-area and which is contained by valid-area . In other words, areas inside update-area will be presented from pixmap , areas outside valid-area will not be presented from pixmap and areas inside valid-area but outside update-area may or may not be presented at the discretion of the X server. x-off and y-off define the location in the window where the 0,0 location of the pixmap will be presented. valid-area and update-area are relative to the pixmap. If target-msc is greater than the current msc for window , the presentation will occur at (or after) the target-msc field. Otherwise, the presentation will occur after the next field where msc % divisor == remainder . If divisor is zero, then the presentation will occur after the current field. idle-fence is triggered when pixmap is no longer in use. This may be at any time following the PresentRegion request, the contents may be immediately copied to another buffer, copied just in time for the vblank interrupt or the pixmap may be used directly for display, in which case it will be busy until some future PresentRegion operation. If window is destroyed before the presentation occurs, then the presentation action will not be completed. PresentRegion holds a reference to pixmap until the presentation occurs, so pixmap may be immediately freed after the request executes, even if that is before the presentation occurs. If idle-fence is destroyed before the presentation occurs, then idle-fence will not be signaled but the presentation will occur normally. PresentSelectInput
 
    PresentSelectInput
    event-id: PRESENTEVENTID
    window: WINDOW
    eventMask: SETofPRESENTEVENT
 
Errors: Window, Value, Match, IDchoice, Access
Selects the set of Present events to be delivered for the specified window and event context. PresentSelectInput can create, modify or delete event contexts. An event context is associated with a specific window; using an existing event context with a different window generates a Match error. If eventContext specifies an existing event context, then if eventMask is empty, PresentSelectInput deletes the specified context, otherwise the specified event context is changed to select a different set of events. If eventContext is an unused XID, then if eventMask is empty no operation is performed. Otherwise, a new event context is created selecting the specified events. Present Extension Events There are three different events for the Present extension:
  1. PresentConfigureNotify
  2. PresentCompleteNotify
  3. PresentRedirectNotify
PresentConfigureNotify This event is moving from the DRI3 extension where it doesn t belong.
 
    PresentConfigureNotify
    type: CARD8         XGE event type (35)
    extension: CARD8        Present extension request number
    length: CARD16          2
    evtype: CARD16          Present_ConfigureNotify
    eventID: PRESENTEVENTID
    window: WINDOW
    x: INT16
    y: INT16
    width: CARD16
    height: CARD16
    off_x: INT16
    off_y: INT16
    pixmap_width: CARD16
    pixmap_height: CARD16
    pixmap_flags: CARD32
 
PresentConfigureNotify events are sent when the window configuration changes if PresentSelectInput has requested it. PresentConfigureNotify events are XGE events and so do not have a unique event type. x and y are the parent-relative location of window . PresentCompleteNotify
 
    PresentCompleteNotify
    type: CARD8         XGE event type (35)
    extension: CARD8        Present extension request number
    length: CARD16          2
    evtype: CARD16          Present_CompleteNotify
    eventID: PRESENTEVENTID
    window: WINDOW
    ust: CARD64
    msc: CARD64
    sbc: CARD64
 
Notify events are delivered when a PresentRegion operation has completed and the specified contents are being displayed. sbc, msc and ust indicate the swap count, frame count and system time of the related PresentRegion request. PresentRedirectNotify This one is not specified yet, but the intent is for it to contain sufficient information for the compositing manager to be able to construct a suitable screen update that includes an application window update. Finishing GLXOMLsync_control At this point, Mesa only exposes the old swapinterval configuration value, it doesn t provide any of the GLXOMLsynccontrol APIs. However, the Present protocol does have the bits necessary to support glXSwapBuffersMscOML in the PresentRegion request. Let s see how the remaining APIs in this GL extension will be supported. glXGetSyncValuesOML This one is easy; it only needs to return the UST/MSC/SBC values from the most recent SwapBuffers request. Those are returned in the PresentCompleteNotify event, so Mesa just needs to capture that event and save the values away for return to the application. We don t need any new Present protocol for this. glXGetMscRateOML This returns the refresh rate of the monitor associated with the specified drawable. RandR exposes all of the necessary data for each monitor, but the monitor each window is going to be synchronized against isn t exposed anywhere, and is effectively implementation-dependent. So, I think the easy thing to do here is to have a Present request which reports which RandR output a window will be synchronized with. glXSwapBuffersMscOML This is the one API which is already directly supported by the Present extension. glXWaitForMscOML This is effectively the same as glXSwapBuffersMscOML, except that it doesn t actually perform a swap. For this, I think we want a new request that generates an X event when the target values are reached, and then have the client block until that event is received. This will avoid blocking other threads using the same X connection. glXWaitForSbcOML Like glXWaitForMscOML, this just needs to trigger an event to be delivered at the right time. Presentation Redirection I m focusing on finishing the above stuff before I start writing the redirection spec and code, but I ve been thinking a bit about it. What we want is for applications that are presenting a new frame within a redirected window to have that presentation delivered directly to the compositing manager instead of having the bits copied to the redirected buffer and have the compositing manager only learn about this when the damage event is received from copying the bits. Once the compositing manager receives notification that there are new bits available for a portion of a window, it can then get those bits onto the screen in one of two ways:
  1. Copy them to the back buffer for the whole screen and then present that back buffer to the screen.
  2. Present them directly to the screen, bypassing the compositing manager s back buffer entirely.
The first option is what you d do if there were more updates than just a single window; it would update the whole screen at the same time. The second option is what you d do if there was only the one window update to act on, and this would automatically take advantage of page flipping to avoid copying data at all. No need to un-redirect windows for the page flip to work. In both cases, we need to inform the original application both when its pixmap is idle and when the swap actually hits the screen. And we need to make sure the final swap happens when the application requested. For the pixmap idle notification, the current PresentRegion idlefence argument should suffice; we just need to pass the idlefence XID along in the redirection event. Simple. For completion notification, we need to make sure the SBC value for the original window gets incremented and that a PresentCompleteNotify event is delivered. I think that means we want to append a chunk of data to the PresentRegion request so that suitable events can be delivered when the compositing manager PresentRegion occur. I think that just needs to be the window of that original window. To make sure the swap happens at the right time, we just need to have the targetmsc value provided to the compositing manager. I m hoping that having this all event driven is that when a later PresentRegion is redirected that has an *earlier* targetmsc, we can simply queue that as well and things should just work . Current Status I ve got the protocol definitions (both X server and XCB) done, and libxcb supporting the extension. I ve got the X server bits working, but the actual updates are not synchronized to the monitor; they re using OS timers and CopyArea for now, mostly so I can test things without also hacking drivers. Mesa is using the extension, but it only provides the swapinterval value and is not yet supporting the full GLXOMLsynccontrol extension. I ve also got a simple 2D core X application using the extension which is in the shmfd repository in my home directory on freedesktop.org. Availability As always, these bits are already published in my home directory on freedesktop.org in various git repositories.

11 July 2013

Johannes Schauer: Using botch to generate transition build orders

In October 2012, Joachim Breitner asked me whether botch (well, it didnt have a name back then) can also be used to calculate a build order for recompiling ~450 haskell-packages with a new ghc version (it was probably the 7.6.1 release) to upload them to experimental. What is still blocking this ability is the inability of botch to directly read *.dsc files instead of having to rely on Packages and Sources files. On the other hand (in case there exists a set of Packages and Sources files) it is now much easier to use botch for such a use case for which it was not originally designed. To demonstrate how botch can be used to calculate the build order for library transitions, I wrote the script create-transition-order.sh which executes the individual tools in the correct order with the correct arguments. To validate the correctness of botch, I compared the output to the order which ben produces for transitions. The create-transition-order.sh script is called with a ben query string and optionally a snapshot.debian.org timestamp as its arguments. The script relies on ben being installed because ben query strings cannot be translated into grep-dctrl query strings as ben query splits fields which contain comma separated values at the comma before searching for strings. Unfortunately the script also currently relies on a yet unreleased ben feature which allows ben download to create a ben.cache file. You can track the progress of this feature as bug#714703. Creating a ben.cache file is necessary because some queries rely on an association between binary and source packages which is not present in all packages in a Packages file. For example the haskell transition query makes use of this feature by including the .source field in its query. The result of these trials was, that botch produced nearly the same build order for nearly all transitions. The only differences are due to shortcomings of ben and botch. For example, ben is not able to create an order for transitions where involved packages form one or more cycles. A prominent example is the haskell transition where ghc itself is only built during step 15 after many other packages which would have needed ghc to be compiled. Botch solves this problem by reducing all strongly connected components in a cyclic graph to a single vertex before creating the order. This operation makes the graph acyclic and creating a build order trivial. The only remaining problems can then be found within the strongly connected components (for Haskell they are of maximum size two) but the overall build order is correct. On the other hand botch has no notion of packages which are affected by a transition and thus creates a build order which in some cases is longer than the one created by ben. When generating the interdependencies between packages, ben only considers those which are part of the transition. Botch on the other hand considers all dependency relationships. It would be simple to solve this issue in botch by removing unaffected packages from the dependency graph through edge contraction (an operation already used by botch for other tasks). This exercise also let me find another bug in dose3 where libdose would not associate a binary package with a binNMU version with its associated source package but instead report a version mismatch error. This problem was also reported in the process.

10 July 2013

Russell Coker: Samsung Galaxy Note 2

A few weeks ago I bought a new Samsung Galaxy Note 2 Android phone. As I predicted in my post about Phone and Tablet Sizes [1] the Note 2 with a 5.55 display is a bit too big for me to have an ideal single handed side grasp (I estimate that about 5.2 would be ideal). But I can stretch a bit and move it around in my hand to touch all parts of the screen with my thumb. Although when doing that I don t have a tight grip, with my previous phone the Samsung Galaxy S3 [2] I could properly wrap my hand around it to grip it tightly while using it with one hand. The Note 2 will be easier for me to drop or for a thief to snatch it from me. While the big screen makes the phone difficult to use with one hand it does allow viewing more data. The ConnectBot SSH client (Play Store link) [3] (F-Droid repository link) [4] works a lot better on a larger screen I ve also discovered that the volume control buttons can be used to change the font size in ConnectBot which is handy as the default is really tiny. Also Klaus Weidner s Hacker s Keyboard (Play Store link) [5] (F-Droid repository link) [6] works a lot better with a larger screen. When I tested the Hacker s keyboard on a smaller phone I found the 5 row layout too difficult to use, but on the Note 2 it works well. As an aside I wish I could quickly and easily toggle between 4 row mode (good for SMS) and 5 row mode (good for sysadmin work) in the Hackers Keyboard. For less serious use the large screen on the Note 2 is good for watching TV. I ve got a collection of mp4s of TV shows that I ve been meaning to watch, now I watch them in bed on my phone. Another advantage of the Note 2 is the battery life. When playing Ingress and doing all the usual email checks etc my Note 2 will last about as long as my wife s Galaxy S3 with it s power case. So without any extra batteries a Note 2 will probably last about twice as long as a Galaxy S3. The Note 2 has more RAM than the S3 I used to use (I had the S3 with 1G of RAM) and it also apparently has a faster CPU. The CPU speed hasn t been an issue for me but the extra RAM is a real benefit, it means that I can usually switch between Ingress and other programs without having to restart Ingress each time. As an aside I think that Google and LG should release a Nexus Ingress 4 phone or some other device that s optimised for Ingress, I m sure it would sell well. Some people make a big deal about the stylus that comes with the Note 2. It is a neat feature to have the device know when the stylus tip is hovering over the screen but it s not very useful for me. If I was going to create art work on a phone (as some people do) then it would interest me, but I m more interested in email and ssh for fine input and my fingers are generally good enough for those tasks. I have got thin fingers, so I think that people with thicker fingers could really benefit from the stylus. I recently bought a batch of stylus pens from Kogan which have a pen at one end and a rubber stylus tip at the other for fat fingered people I know who need to use an Android phone but can t afford a Note or Note 2. I also like the software build on it which is almost the same as that on the Galaxy S3. It seems that many people prefer the apparently stock features on the Nexus 4 but I like the way Samsung does things. Conclusion I m very happy with my new phone. The bigger screen allows me to see things more clearly, this is good for web browsing, reading email, and now that I can use the Hackers Keyboard I can type more effectively. The longer battery life is really good too, although I think that Samsung could have done better if the phone was 3mm thicker then it could have a much bigger battery and have a larger CCD for the camera. I don t think that the phone is really different, at least not for my use. Samsung has promoted it for artistic use and I ve seen evidence to support their claims. But for most people it ll just be a phone with a larger screen and a bigger battery. Some people criticise it for being too big, but it s still smaller than the handsets on most desk phones so it s not big by the standards of old fashioned phones. The increased size has not only allowed me to do the same things more effectively but also allowed me to do things I hadn t tried doing on a phone before such as watching TV. This isn t because of the phone being particularly special in any way, it s just that the change in size gives more possibilities for ways of using it. The Samsung Galaxy Mega is the largest smart phone. The 5.8 version of the Mega has a resolution of only 960*540 (less than the Note and Note 2 not good enough IMHO) and the 6.3 version has the same resolution as the Note 2 of 1280*720. I think that both Mega variants are too big for me, I need to be able to use a phone with one hand. So it seems that the Note 2 is probably the best phone for me right now.

Petter Reinholdtsen: Intel SSD 520 Series 180 GB with Lenovo firmware still lock up from sustained writes

A few days ago, I wrote about the problems I experienced with my new X230 and its SSD disk, which was dying during installation because it is unable to cope with sustained write. My supplier is in contact with Lenovo, and they wanted to send a replacement disk to try to fix the problem. They decided to send an identical model, so my hopes for a permanent fix was slim. Anyway, today I got the replacement disk and tried to install Debian Edu Wheezy with encrypted disk on it. The new disk have the same firmware version as the original. This time my hope raised slightly as the installation progressed, as the original disk used to die after 4-7% of the disk was written to, while this time it kept going past 10%, 20%, 40% and even past 50%. But around 60%, the disk died again and I was back on square one. I still do not have a new laptop with a disk I can trust. I can not live with a disk that might lock up when I download a new Debian Edu / Skolelinux ISO or other large files. I look forward to hearing from my supplier with the next proposal from Lenovo. The original disk is marked Intel SSD 520 Series 180 GB, 11S0C38722Z1ZNME35X1TR, ISN: CVCV321407HB180EGN, SA: G57560302, FW: LF1i, 29MAY2013, PBA: G39779-300, LBA 351,651,888, LI P/N: 0C38722, Pb-free 2LI, LC P/N: 16-200366, WWN: 55CD2E40002756C4, Model: SSDSC2BW180A3L 2.5" 6Gb/s SATA SSD 180G 5V 1A, ASM P/N 0C38732, FRU P/N 45N8295, P0C38732. The replacement disk is marked Intel SSD 520 Series 180 GB, 11S0C38722Z1ZNDE34N0L0, ISN: CVCV315306RK180EGN, SA: G57560-302, FW: LF1i, 22APR2013, PBA: G39779-300, LBA 351,651,888, LI P/N: 0C38722, Pb-free 2LI, LC P/N: 16-200366, WWN: 55CD2E40000AB69E, Model: SSDSC2BW180A3L 2.5" 6Gb/s SATA SSD 180G 5V 1A, ASM P/N 0C38732, FRU P/N 45N8295, P0C38732. The only difference is in the first number (serial number?), ISN, SA, date and WNPP values. Mentioning all the details here in case someone is able to use the information to find a way to identify the failing disk among working ones (if any such working disk actually exist).

9 July 2013

Rapha&#235;l Hertzog: My Free Software Activities in June 2013

This is my monthly summary of my free software related activities. If you re among the people who made a donation to support my work (106.39 , thanks everybody!), then you can learn how I spent your money. Otherwise it s just an interesting status update on my various projects. Debian France I handled some subscriptions that we collected during Solutions Linux at the end of last month and I also worked on updating the accounts in preparation of our annual general assembly. As the current president, I wrote a moral assessment of the organization and I helped Sylvestre Ledru (the treasurer) to prepare an overview of our financial situation (which is rather good). The plan for this general assembly included the renewal of 6 of our 9 board members so I tried to motivate some persons to candidate and I m pretty happy to see that we managed to have 9 candidates for 6 seats, a real election for once. :-) And as usual, I updated Galette to version 0.7.4.2 and I filed a couple of tickets (#621, #622). Debian Package Tracking System We re getting close to one month of work on the Google Summer of Code Project that rewrites the Package Tracking System. On average I spent a good 1h30 per day on reviewing the code, giving my feedback, and preparing the user stories for the next iteration, plus a 2 hour meeting each Wednesday afternoon. This is more than I expected but at I m rather happy with the result so far. We have a live test instance updated each week (after the end of the iteration) at pts.debian.net. The web interface is empty because the bulk of the work has been spent on the email interface for now, but it s now feature complete and already has seen some improvements compared to the current implementation (fixing #340863 for example). You can interact with it by sending mails to control@pts.debian.net. The Debian Administrator s Handbook The fundraising for the liberation of the original book in French met its initial target very quickly and we added new targets with supplementary rewards (more ebook from Eyrolles, donation to Debian). All the supplementary targets were met, although the last one took until the last day! Thanks to all the supporters, we now have a French translation of the Debian Administrator s Handbook which is free and we have collected about 2700 EUR for Debian. Debian Packaging I got a couple of release critical bug reports that I had to fix: And trying to anticipate future issues, I filed an upstream ticket on feed2omb (#33) to see whether upstream had plans to support the new pump.io API that identi.ca is supposed to use soonish. Kali Linux I filed a couple of Debian bugs: #711866 to request a new upstream version of w3af in Debian, #711044 to report a missing dependency in LSB meta-informations of the vsftpd init script. I worked on packaging passing-the-hash. Basically this is a fork of several software just to override some NTLM authentication functions. In some cases, I managed to avoid the fork by transforming the patches in LD_PRELOAD libraries that override the specific symbol of the patched functions. Among the forked software, there was winexe which wasn t packaged yet. So I packaged it but we quickly ran into some segfaults (which was already reported to upstream since a few months). I investigated the problem and prepared a patch. It has been submitted to upstream and merged. Thanks See you next month for a new summary of my activities.

No comment Liked this article? Click here. My blog is Flattr-enabled.

8 July 2013

Olivier Berger: Experimenting with Linked Open Data about FLOSS projects : matching Debian upstream projects

I ve been experimenting with Linked Open Data about FLOSS projects harvested from different sources of DOAP or ADMS.SW descriptions. I ve tried and match upstream projects of Debian packages with upstream projects hosted at Apache, Gnome, or Alioth.debian.org, or catalogued on Pypi. I m matching them on identical values of the Homepage field (comparing the Homepage Control field set by Debian packagers with the doap:homepage meta-data in the RDF documents harvested from the upstream project catalogues). Here are initial results of my little experiment, for number of matched projects, and results on project name s similarity :
Upstream catalogue Total matching projs Exact same project name Same project name (case independant)
apache 31 0 (0 %) 0 (0 %)
alioth 16 13 (81 %) 13 (81 %)
pypi 439 217 (49 %) 273 (62 %)
gnome 21 0 (0 %) 7 (33 %)
Total 507 230 (45%) 293 (58 %)
The data set contains tens of thousands of projects, with probably many duplicates, but from all of these, only 507 have common homepages. As you can see, in some cases, the Debian source package names match the upstream project name (sometimes with lower/upper case variants), but in general, the project names aren t identical, so it is interesting to try and match them by homepage. For the curious ones, the Apache, Gnome and Pypi project catalogues use to provide RDF meta-data for quite some time. More recently have we introduced ADMS.SW meta-data for Debian source packages, and even more recently for the Alioth projects (through the ADMS.SW exporter plugin for FusionForge). There are still some ways for improvements, for instance to normalize homepage URLs which tend to vary (trailing slashes, or different HTTP/HTTPS schemes). Stay tuned for more details.

6 July 2013

Yves-Alexis Perez: Xfce 4.10, final part

Someone recently asked me about the Debian Xfce 4.10 status, as apparently I forgot to update this post series. So, as you might have noticed, the full Xfce 4.10 desktop environment is currently in Debian Jessie (current name for testing). All in all, the transition went well and smooth. One of the most regular question I get about Xfce 4.10 is the panel behavior when it comes to the task bar expansion. In xfce4-panel 4.8, when people wanted to have a full side panel with a task bar plugin inside, they added a Windows buttons plugin and configured the panel to 100% length. Then the Windows buttons would expand to occupy all the free space on the panel. It was a special case plugins, as usually other plugins only used a fixed space. Now, in 4.10, this is not the case anymore. Windows button uses a fixed size. And the plugins are left-aligned, which means usually people end up with some space at the far right of the panel. To restore the previous behavior back (which is actually the pre-4.8 behavior, 4.8 was an exception by itself), one needs to add a Separator plugin, then configure it to expand (and optionnally select a transparent handle). Then move it next right to the Windows buttons plugin. Another thing which might be a bit surprising for upgrading users is the change in the Action buttons plugin, which people usually use to logout. In 4.8, by default, it's set to run the logout dialog. In 4.10, by default, it's set to logout directly (but with a confirmation dialog). If you prefer the previous behavior, you can just configure the Action buttons plugin and select the Log out item instead of the Log out one (I know, it's a bit confusing). If you have any question, don't hesitate to reach us by mail or on irc (#debian-xfce on Freenode). Other than that remember that Xfce really needs you help, both in Debian and upstream (and at that point, I'd say *especially* upstream). There's a lot of unmaintained project under the Xfce umbrella, some of them part of the core (like xfce4-power-manager), so if you have some spare time and some C/GTK+ knowledge, feel free to contact the Xfce team on the mailing list.

4 July 2013

Emanuele Rocca: Useful tools for Python developers

Python is a great language with an impressive number of tools designed to make developers' life easier. Sometimes, however, the problem is getting to know that these tools exist in the first place. By contributing to projects like OpenStack's Nova client and Falcon, I have recently come across some useful tools that can seriously improve the quality of your code. The first one is called pyflakes, a passive checker of Python programs developed by Phil Frost. What it does is parsing your source files and checking for possible errors such as undefined names and unused imports. Let's consider the following example: <figure class="code">
1
2
3
4
import urllib

print "pyflakes example"
urlib.urlopen('http://www.linux.it')
</figure>The code above contains a typo, we have misspelled urllib. Here is what pyflakes thinks about our program:
$ pyflakes example.py
example.py:1: 'urllib' imported but unused
example.py:4: undefined name 'urlib'
On line 4 we try to use urlib which is not defined. Also, we import urllib on line 1 and we do nothing with it. Our typo has been spotted! Notice that, even though our program contains a print statement, 'pyflakes example' has not been printed. That is because pyflakes parses the source files it checks, without importing them, making it safe to use on modules with side effects. pyflakes can be installed with pip or apt-get. The second tool I want to talk about is Ned Batchelder's coverage.py. No doubt you write unit tests for your programs. Right? Good. coverage.py is out there to help you checking how much of your program is actually covered. Let's use as an example codicefiscale, a Python project of mine. First we install coverage:
pip install coverage
Then we run our unit tests:
$ coverage run --source=codicefiscale tests.py
.......
----------------------------------------------------------------------
Ran 7 tests in 0.003s
We pass the module we want to test with --source=codicefiscale so that coverage will only report information about that specific module. Now that our tests have been performed successfully it is time to check how much of our code is covered by unit tests:
$ coverage report -m
Name            Stmts   Miss  Cover   Missing
---------------------------------------------
codicefiscale      73      4    95%   61, 67, 95, 100
Not bad, 95% of our module is covered! Still, coverage let us know that 4 lines have not been touched by the unit tests. With this information, we can go write some meaningful test cases that will also cover the missing lines.

EvolvisForge blog: Fun with ssh pubkey auth

Okay, so imagine this: you just generated an SSH RSA key and threw its public part on system B into ~foo/.ssh/authorized_keys and its private part on system A into ~bar/.ssh/id_rsa but can t login. Why? Automated processes (Jenkins *cough*) often need you to ssh(1) manually once, to accept the remote host s server key. Do that. The id_rsa file on system A must be owned by the user bar and chmod 0600 or 0400 (similarily, the .ssh directory has strict permission checks, and everything in the path until there). Check those. And, the most surprising one of the day: if there s an id_rsa.pub it will be used for offering a key to the remote host (B) even if it does not match the secret key. Deleting A:~bar/.ssh/id_rsa.pub apparently makes OpenSSH generate the public part from the secret key each time (or just put the correct pubkey there), but if one s there, it seems to like to use them. (That was the only part of this post that was news to even me, of course ) And, as bottom line: hello to Planet Debian from mirabilos at work , too. I ll occasionally tag posts so they show up here, if I think they re of interest, since I m doing Debian work at the dayjob, too.

3 July 2013

Ian Campbell: Emesinae -- Yet Another Bug Tracker

Quite a while ago at a Xen hackathon (I think the Cambridge one in 2011, has it really been 2 years?) the topic of bug tracking came up. The developers who were present (myself included) expressed a general dislike for web based bug trackers, and in particular the existing bugzilla wasn't working for us for a variety of reasons (primarily lack of resource for care and general tending of it). They also liked the existing work flow based around mails to the Xen mailing lists, there was a feeling that this fits well with the demographics of the bugs which get reported to Xen: a sizable number of the issues are configuration errors or misunderstandings which can usually quickly be dealt with through a small email thread (followed by a request to please update the wiki). The project also gets quite a few bug reports which are initially "unactionable" due to of lack logs or a coherent description, in these cases a little bit of back and forth can quickly determine whether the reporter is going to provide the necessary additional information (this is something we are also trying to fix with clearer guidance and an ongoing effort to provide a reportbug-like tool for Xen). However there were concerns that bigger issues which couldn't be dealt with quickly were falling through the cracks. We kicked around a few ideas for how a bug tracker that met our needs might work and that was mostly that. Since then I've kicked the ideas around in my head a bit and searched for an existing system which would fit what was required. In the end I didn't find anything which quite fitted the bill and about six months ago I was looking for an interesting hacking project (perhaps something a bit different to my day job, hypervisor and kernel hacking) so I decided to bite the bullet, dust of my rusty Perl skills and hack something together. Yes, that's right, I've written Yet Another Bug Tracker(tm). I confess I feel a bit dirty for doing so. I've taken a fair bit of inspiration from debbugs (the Debian bug tracker) but I've turned the concept a little on its head. Debbugs is effectively instantiating a new mailing list for each bug report (each NNNNNN@bugs.debian.org can be thought of as a mailing list plus some additional bug specific metadata). Instead I implemented a model which takes an existing mailing list and acts as a list archive which provides a mechanism to track individual threads (or subthreads) as bugs (each bug is effectively a root Message-Id plus a little bit of metadata). In common with debbugs bugs are created and subsequently manipulated by sending mail to a special control@ address. Commands are available to create bugs as well as to graft and prune subthreads onto existing bugs (to cope with people who break threading or offtopic subthreads etc). There is also a read-only web interface for browsing the bugs. Internally the system is subscribed to the list and records details of each message and their relationships (e.g. References headers etc) in a sqlite database. A set of CGI scripts (using the Perl CGI module) provide an interface to browse bugs. Since the system tracks bugs based on mailing list threads I've named it Emesinae which is a "thread-legged bug" (yes, I spent longer than is strictly necessary browsing entomological websites). I've made the code available on gitorious under a GPLv2 license, see https://gitorious.org/emesinae. I announced an alpha instance of Emesinae back in May which tracks the xen-devel mailing list. You can find the bug tracker at http://bugs.xenproject.org/xen/. Since then I've been slowly fleshing out some more useful features (such as tagging of affected branches). It's not seen a great deal of uptake from the Xen developers yet but there are already some bugs being tracked and I'm hopeful that it will prove useful in the long run. In any case it was a fun hacking project for a few rainy evenings (and a couple more train and plane journeys).

2 July 2013

Bits from Debian: all Debian source are belong to us

This is a verbatim repost from Stefano Zacchiroli's post TL;DR: go to http://sources.debian.net and enjoy.
Debsources is a new toy I've been working on at IRILL together with Matthieu Caneill. In essence, debsources is a simple web application that allows to publish an unpacked Debian source mirror on the Web. You can deploy Debsources where you please, but there is a main instance at http://sources.debian.net (sources.d.n for short) that you will probably find interesting. sources.d.n follows closely the Debian archive in two ways:
  1. it is updated 4 times a day to reflect the content of the Debian archive
  2. it contains sources coming from official Debian suites: the usual ones (from oldstable to experimental), *-updates (ex volatile), *-proposed-updates, and *-backports (from Wheezy on)
Via sources.d.n you can therefore browse the content of Debian source packages with usual code viewing features like syntax highlighting. More interestingly, you can search through the source code (of unstable only, though) via integration with http://codesearch.debian.net. You can also use sources.d.n programmatically to query available versions or link to specific lines, with the possibility of adding contextual pop-up messages (example). In fact, you might have stumbled upon sources.d.n already in the past few days, via other popular Debian services where it has already been integrated. In particular: codesearch.d.n now defaults to show results via sources.d.n, and the PTS has grown new "browse source code" hyperlinks that point to it. If you've ideas of other Debian services where sources.d.n should be integrated, please let me know. I find Debsources and sources.d.n already quite useful but, as it often happens, there is still a lot TODO. Obviously, it is all Free Software (released under GNU AGPLv3). Do not hesitate to report new bugs and, better, to submit patches for the outstanding ones. Acknowledgements PS in case you were wondering: at present sources.d.n requires ~381 GB of disk space to hold all uncompressed source packages, plus ~83 GB for the local (compressed) source mirror

Stefano Zacchiroli: introducing sources.debian.net

all Debian source are belong to us TL;DR: go to http://sources.debian.net and enjoy.
Debsources is a new toy I've been working on at IRILL together with Matthieu Caneill. In essence, debsources is a simple web application that allows to publish an unpacked Debian source mirror on the Web. You can deploy Debsources where you please, but there is a main instance at http://sources.debian.net (sources.d.n for short) that you will probably find interesting. sources.d.n follows closely the Debian archive in two ways:
  1. it is updated 4 times a day to reflect the content of the Debian archive
  2. it contains sources coming from official Debian suites: the usual ones (from oldstable to experimental), *-updates (ex volatile), *-proposed-updates, and *-backports (from Wheezy on)
Via sources.d.n you can therefore browse the content of Debian source packages with usual code viewing features like syntax highlighting. More interestingly, you can search through the source code (of unstable only, though) via integration with http://codesearch.debian.net. You can also use sources.d.n programmatically to query available versions or link to specific lines, with the possibility of adding contextual pop-up messages (example). In fact, you might have stumbled upon sources.d.n already in the past few days, via other popular Debian services where it has already been integrated. In particular: codesearch.d.n now defaults to show results via sources.d.n, and the PTS has grown new "browse source code" hyperlinks that point to it. If you've ideas of other Debian services where sources.d.n should be integrated, please let me know. I find Debsources and sources.d.n already quite useful but, as it often happens, there is still a lot TODO. Obviously, it is all Free Software (released under GNU AGPLv3). Do not hesitate to report new bugs and, better, to submit patches for the outstanding ones. Acknowledgements PS in case you were wondering: at present sources.d.n requires ~381 GB of disk space to hold all uncompressed source packages, plus ~83 GB for the local (compressed) source mirror

Next.

Previous.