Search Results: "will"

28 May 2016

Russ Allbery: Another small book haul

Book reading is happening, and more book review posting will be happening. I'm a bit behind in writing reviews, but the holiday weekend is a good opportunity to do a bit of catching up. In the meantime, here are some new acquisitions: Roxanne J. Coady & Joy Johannessen (ed.) The Books That Changed My Life (nonfiction)
James S.A. Corey Caliban's War (sff)
James S.A. Corey Abaddon's Gate (sff)
Max Gladstone Full Fathom Five (sff)
Max Gladstone Last First Snow (sff)
N.K. Jemisin The Fifth Season (sff)
Guy Gavriel Kay Children of Earth and Sky (sff)
Naomi Novik Uprooted (sff)
Ada Palmer Too Like the Lightning (sff)
Graydon Saunders Safely You Deliver (sff)
Neal Stephenson Seveneves (sff)
Jeff VanderMeer Annihilation (sff) This is mostly catching up on books that were nominated for awards. I want to read the (legitimate) nominees for Hugo best novel this year if I can find the time, and VanderMeer won the Nebula last year. The rest of Gladstone's series to date was on sale, and I really liked the first book. And of course a new Guy Gavriel Kay is buy on sight. I'm currently re-reading The Sarantine Mosaic, since I read that before I started writing reviews and Children of Earth and Sky is apparently set in historical contact with it. (It's possible all of Kay's historical fantasies are set in the same universe, but they're usually fairly disconnected.)

Evgeni Golov: how to accidentally break DNS for 15 domains or why you maybe could not send mail to me

TL;DR: DNS for golov.de and other (14) domains hosted on my infra was flaky from 15th to 17th of May, which may have resulted in undelivered mail. Yeah, I know, I haven't blogged for quite some time. Even not after I switched the engine of my blog from WordPress to Nikola. Sorry! But this post is not about apologizing or at least not for not blogging. Last Tuesday, mika sent me a direct message on Twitter (around 13:00) that read problem auf deiner Seite? or problem on your side/page? . Given side and page are the same word in German, I thought he meant my (this) website, so I quickly fired up a browser, checked that the site loads (I even checked both, HTTP and HTTPS! :-)) and as everything seemed to be fine and I was at a customer I only briefly replied ? . A couple messages later we found out that mika tried to send a screenshot (from his phone) but that got lost somewhere. A quick protocol change later (yay, Signal!) and I got the screenshot. It said "<evgeni+grml@golov.de>: Host or domain name not found. Name service error for name=golov.de type=AAAA: Host found, but no data record of requested type". Well, yeah, that looks like an useful error message. And here the journey begins. For historical nonsense golov.de currently does not have any AAAA records, so it looked odd that Postfix tried that. Even odder was that dig MX golov.de and dig mail.golov.de worked just fine from my laptop. Still, the message looked worrying and I decided to dig deeper. golov.de is served by three nameservers: ns.die-welt.net, ns2.die-welt and ns.inwx.de and dig was showing proper replies from ns2.die-welt.net and ns.inwx.de but not from ns.die-welt.net, which is the master. That was weird, but gave a direction to look at, and explained why my initial tests were OK. Another interesting data-point was that die-welt.net was served just fine from all three nameservers. Let's quickly SSH into that machine and look what's happening Yeah, but I only have my work laptop with me, which does not have my root key (and I still did not manage to setup a Yubikey/Nitrokey/whatver). Thankfully my key was allowed to access the hypervisor, yay console! Now let's really look. golov.de is served from from the bind backend of my PowerDNS, while die-welt.net is served from the MySQL backend. That explains why one domain didn't work while the other did. The relevant zone file looked fine, but the zones.conf was empty. WTF?! That zones.conf is autogenerated by Froxlor and I had upgraded it during the weekend to get Let's Encrypt support. Oh well, seems I hit a bug, damn. A few PHP hacks later and I got my zones.conf generated properly again and all was good. But what had really happened?
  • On Saturday (around 17:00) I upgraded to Froxlor 0.9.35.1 to get Let's Encrypt support and hit Froxlor bug 1615 without noticing as PowerDNS re-reads zones.conf only when told.

  • On Sunday PowerDNS was restarted because of upgraded packages, thus re-reading zones.conf and properly logging:

    May 15 08:10:59 shokki pdns[2210]: [bindbackend] Parsing 0 domain(s), will report when done
    
  • On Tuesday the issue hit a friend who cared and notified me

  • On Tuesday the issue was fixed (first by a quick restore from etckeeper, later by fixing the generating code):

    May 17 14:56:08 shokki pdns[24422]: [bindbackend] Parsing 15 domain(s), will report when done
    
And the lessons learned?
  • Monitor all your domains, on all your nameservers. (I didn't)
  • Have emergency access to all you servers. (I did, but it was complicated)
  • Use etckeeper, it's easier to use than backups in such cases.
  • When hitting bugs, look in the bugtracker before solving the issue yourself. (I didn't)
  • Have friends who care :-)

Stig Sandbeck Mathisen: Puppet 4 uploaded to Debian unstable

Puppet 4 has been uploaded to Debian unstable. This is a major upgrade from Puppet 3. If you are using Puppet, chances are that it is handling important bits of your infrastructure, and you should upgrade with care. Here are some points to consider.

Read Puppet s upgrade checklist First, there are a number of changes in Puppet itself. There is an upgrade checklist for Puppet (the software) published by Puppet (the company). Please read this before you upgrade, and not after.

Using exported resources? In Puppet 4, using exported resources requires PuppetDB, which is not packaged in Debian.

Getting PuppetDB Puppet provides good installation documentation for PuppetDB, and an apt software repository where you you can get the packages you require.

Editor support packages The packages vim-puppet and puppet-el provide support for editors Vim and Emacs. These are no longer built from the puppet source package. The sources for these have moved to separate repositories, and will get individual source packages. For vim-puppet, there are two alternatives for new packaging, rodjek/vim-puppet, and puppetlabs/puppet-syntax-vim For puppet-el puppetlabs/puppet-syntax-emacs and lunaryorn/puppet-mode are available.

Dirk Eddelbuettel: RcppArmadillo 0.7.100.3.0

armadillo image The first Armadillo release of the 7.* series is out: a new version 7.100.3. We uploaded RcppArmadillo 0.7.100.3.0 to CRAN and Debian. This followed the usual thorough reverse-dependecy checking of by now 230 packages using it. This release now requires a recent enough compiler. As g++ is so common, we explicitly test for version 4.6 or newer. So if you happen to be on an older RHEL or CentOS release, you may need to get yourself a more modern compiler. R on Windows is now at 4.9.3 which is decent (yet stable) choice; the 4.8 series of g++ will also do. For reference, the current LTS of Ubuntu is at 5.3.1, and we have g++ 6.1 available in Debian testing. This new upstream release adds a few new helper functions (which are particularly useful in statistics, but were of course already available to us via Rcpp), more slicing of Cube data structures and a brand new sparse matrix decomposition module courtesy of Yixuan Qiu -- whom R users know as the author of the RSpectra package (which replaces his older rArpack package) and of course all the most excellent work he provided to RcppEigen. Armadillo is a powerful and expressive C++ template library for linear algebra aiming towards a good balance between speed and ease of use with a syntax deliberately close to a Matlab. Changes in this release are as follows:
Changes in RcppArmadillo version 0.7.100.3.0 (2016-05-25)
  • Upgraded to Armadillo test release 7.100.3
    • added erf(), erfc(), lgamma()
    • added .head_slices() and .tail_slices() to subcube views
    • spsolve() now requires SuperLU 5.2
    • eigs_sym(), eigs_gen() and svds() now use a built-in reimplementation of ARPACK for real (non-complex) matrices (code contributed by Yixuan Qiu)
  • The configure code now checks against old g++ version which are no longer sufficient to build the package.
Courtesy of CRANberries, there is also a diffstat report for this release. As always, more detailed information is on the RcppArmadillo page. Questions, comments etc should go to the rcpp-devel mailing list off the R-Forge page.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

Scarlett Clark: Debian: Outreachy, Debian Reproducible builds Week 1 Progress Report

It has been an exciting first week of my internship. I was able to produce a few patches,
and submitted upstream, as well as into debian packaging. I am hopeful they will get accepted,
preferably upstream so all can benefit! kapptemplate:
https://bugs.kde.org/show_bug.cgi?id=363448
https://bugs.debian.org/cgi-bin/bugreport.cgi?bug=825122 choqok:
https://bugs.debian.org/cgi-bin/bugreport.cgi?bug=825322 However, after speaking with Lisandro ( choqok maintainer ) I decided a better course of action
is to try and fix the actual source of the problem, kconfig_compiler from kde4libs is generating
non utf-8 cpp and header files under certain conditions like an environment that does not have a
locale set. Of course, I have some help with this from wonderful folks in KDE, which is good
because kde4libs codebase is HUGE! So I hope to have two new bugs early next week for choqok. I checked up on my existing kdevplatform bug:
https://bugs.debian.org/cgi-bin/bugreport.cgi?bug=815962 And noticed it has not received attention, so I created upstream bug:
https://bugs.kde.org/show_bug.cgi?id=363615 And updated the debian bug patch DEP 3 with upstream bug url. I have been working on kdevelop-php without success yet, looks like build-id
( I still need to find the source ) and embedded kernel which I think I found,
though I will reach out to my awesome mentor to get some help on this one. I did not knock out quite as many builds as I wanted, but I picked some hard ones
that are new to me  So in the end it was a very successful first week, because I
have learned several new things that will help me with future reproducible builds. Have a great weekend.

26 May 2016

Lisandro Dami n Nicanor P rez Meyer: Do you want Qt5's QWebEngine in Debian? Do you have library packaging skills? If so, step up!

So far the only missing submodule in Debian's Qt5 stack is QtWebEngine. None of us the current Qt maintainers have the time/will to do the necessary stuff to have it properly packaged.

So if you would like to have QtWebEngine in Debian and:

Then you are the right person for this task. Do not hesitate in pinging me on #debian-kde, irc.oftc.net.

Norbert Preining: Shotwell vs. digiKam

How to manage your photos? That is probably the biggest question for anyone doing anything with a photo camera. As resolutions of cameras grow, the data we have to manage is growing ever. In my case I am talking about more than 50000 photos and videos measuring up to about 200Gb of disk space, constantly growing. There are several photo management softwares out there, I guess the most commonly used ones are Shotwell for the Gnome desktop, digiKam for the KDE world, and FotoXX. I have not used Shotwell and digiKam for quite some time, and collect here my experiences of strength and weaknesses of the two programs. FotoXX seems to be very powerful, too, but I haven t tested it till now.
shotwell-digikam There is no clear winner here, unfortunately. Both have their strength and their weaknesses. And as a consequence I am using both in parallel. Before I start a clear declaration: I have been using Shotwell for many years, and have myself contributed considerable code to Shotwell, in particular the whole comment system (comments for photos and events), as well as improved the Piwigo upload features. I started using digiKam some month ago when I started to look for offloading parts of my photo library to external devices. Since then I have used both in parallel. Let us start with what these programs say about themselves: Shotwell is declared as a Photo Manager for Gnome 3, with the following features: digiKam says about itself that it is an advanced digital photo management application for Linux, Windows, and Mac-OSX. It has a very long feature page with a short list at the beginning: Now that sounds like they are very similar, but upon using them it turns out that there are huge differences, that can easily be summed up in a short statement:
Shotwell is Gnome 3 that means get rid of functionality. digiKam is KDE that means provide as much functionality as possible.
Now before you run after me with a knife because you do not agree with me on the above, either read on, or stop reading. I am not interested in flame wars over Gnome versus KDE philosophy. I have been using Gnome since many years, and tried to convince myself to G3 for more than a year until I threw out all of it but selected programs but their number is going down. Let us look at those aspects I am using: organization, offline, sharing, editing. Organization In Shotwell, your photos are organized into events, independent from their location on disk. These events can have title and comment and collect a set of related photos. In my case I often have photos from two or more cameras (my camera and mobile, photos of friends), which I keep in separate directories within a main directory for the event. For example I have a folder 2016/05.21-22.Climbing.Tanigakadake with two sub-folders Norbert (for my photos) and Friend (for my friends photos). In Shotwell all the photos are in the same event, which is shown with title 05.21-22 Tanigakawadake Climbing within the 2016 year and May month.
shotwell-events So in short Shotwell distinguishes between disk layout and album/event names. In digiKam there is a strict connection between disk layout and album names 1:1. Albums are directories. One can adjust the viewer to show all photos of sub-albums in the main album, and by this one can achieve the same effect of merging all photos of my friend and myself. The good thing in this approach is that one can easily have sub-albums: Imagine a trip to three different islands of Hawaii during one trip. This is something easy to achieve in digiKam, but hard in Shotwell.
digikam-albums Other organization methods Both Shotwell and digiKam support tags, including hierarchical tags and rating (0-5 stars). Shotwell has in addition a quick flag action that I used quite often for initial selecting photos, as well as accepted and rejected. digiKam also has so called picks (no pick, reject, pending, accepted), and colors (not used by now). Both programs have some face detection support, but also this I haven t used. So in the organization respect there is no clear winner. I like the Event idea of Shotwell, or better, the separation of events from the disk structure. But on the other hand, Shotwell does not allow for sub-albums, which is also a pain. No clear winner draw Offline storage That is simple: Shotwell: forget it, not reasonably possible. One can move parts to an external HD, then unplug it, and Shotwell will tell you that all the photos are missings. And when you plug the external HD in, it will redetect them. But this is not proper support, just a consequence of hash sum storage. Also separation into several libraries (online and offline) is not supported. On the other hand, digiKam supports multiple libraries, partly offline, without a hinch. I would love to have this feature in Shotwell, because I need to free disk space, urgently!!! Clear winner: digiKam Sharing Again here my testing is very restricted I am using my own Piwigo installation exclusively. Here Shotwell is excellent in providing support for various features: upload to existing category, create new category, resize, optionally remove tags, add comments to albums and photos, etc. (partly implemented by me
shotwell-piwigo On the other hand digiKam has a very barebone interface to Piwigo you can upload photos to an existing album and resize them, but that is already everything. One also needs to say that the list of supported services in digiKam is by far longer than the one in Shotwell, but the main services (usual suspects) are supported in both.
digikam-piwigo Clear winner: Shotwell (but I haven t tested other upload services). Editing The editing capabilities of Shotwell are again very restricted: red eyes, resize, levels, .
shotwell-editing digiKam here is more like a photo editor software with loads of tools and features. I haven t even explored all the options maybe I can get rid of GIMP, too?
digikam-editing Clear winner: digiKam Conclusions While I am still working with both, I actually would love to move completely to digiKam. I simply cannot stand the Gnome 3 philosophy of reducing functionality to a minimal for dummy users. There is a market for that, sure, but I am not one of it. Unfortunately, the missing Event support, and much more the completely minimal support for Piwigo sharing in digiKam is a big show stopper at the moment. Even after testing the upcoming digiKam 5.0 version for some time, I didn t see any improvement wrt to sharing. That leaves me with the only option to continue working with both programs, and hope to get a new bigger SSD before the current one runs out of space. Of course I could start hacking into the digiKam source maybe I do this when I have a bit more time to add proper Piwigo support.

24 May 2016

Alberto Garc a: I/O bursts with QEMU 2.6

QEMU 2.6 was released a few days ago. One new feature that I have been working on is the new way to configure I/O limits in disk drives to allow bursts and increase the responsiveness of the virtual machine. In this post I ll try to explain how it works. The basic settings First I will summarize the basic settings that were already available in earlier versions of QEMU. Two aspects of the disk I/O can be limited: the number of bytes per second and the number of operations per second (IOPS). For each one of them the user can set a global limit or separate limits for read and write operations. This gives us a total of six different parameters. I/O limits can be set using the throttling.* parameters of -drive, or using the QMP block_set_io_throttle command. These are the names of the parameters for both cases:
-drive block_set_io_throttle
throttling.iops-total iops
throttling.iops-read iops_rd
throttling.iops-write iops_wr
throttling.bps-total bps
throttling.bps-read bps_rd
throttling.bps-write bps_wr
It is possible to set limits for both IOPS and bps at the same time, and for each case we can decide whether to have separate read and write limits or not, but if iops-total is set then neither iops-read nor iops-write can be set. The same applies to bps-total and bps-read/write. The default value of these parameters is 0, and it means unlimited. In its most basic usage, the user can add a drive to QEMU with a limit of, say, 100 IOPS with the following -drive line:
-drive file=hd0.qcow2,throttling.iops-total=100
We can do the same using QMP. In this case all these parameters are mandatory, so we must set to 0 the ones that we don t want to limit:
     "execute": "block_set_io_throttle",
     "arguments":  
        "device": "virtio0",
        "iops": 100,
        "iops_rd": 0,
        "iops_wr": 0,
        "bps": 0,
        "bps_rd": 0,
        "bps_wr": 0
      
    
I/O bursts While the settings that we have just seen are enough to prevent the virtual machine from performing too much I/O, it can be useful to allow the user to exceed those limits occasionally. This way we can have a more responsive VM that is able to cope better with peaks of activity while keeping the average limits lower the rest of the time. Starting from QEMU 2.6, it is possible to allow the user to do bursts of I/O for a configurable amount of time. A burst is an amount of I/O that can exceed the basic limit, and there are two parameters that control them: their length and the maximum amount of I/O they allow. These two can be configured separately for each one of the six basic parameters described in the previous section, but here we ll use iops-total as an example. The I/O limit during bursts is set using iops-total-max , and the maximum length (in seconds) is set with iops-total-max-length . So if we want to configure a drive with a basic limit of 100 IOPS and allow bursts of 2000 IOPS for 60 seconds, we would do it like this (the line is split for clarity):
   -drive file=hd0.qcow2,
          throttling.iops-total=100,
          throttling.iops-total-max=2000,
          throttling.iops-total-max-length=60
Or with QMP:
     "execute": "block_set_io_throttle",
     "arguments":  
        "device": "virtio0",
        "iops": 100,
        "iops_rd": 0,
        "iops_wr": 0,
        "bps": 0,
        "bps_rd": 0,
        "bps_wr": 0,
        "iops_max": 2000,
        "iops_max_length": 60,
      
    
With this, the user can perform I/O on hd0.qcow2 at a rate of 2000 IOPS for 1 minute before it s throttled down to 100 IOPS. The user will be able to do bursts again if there s a sufficiently long period of time with unused I/O (see below for details). The default value for iops-total-max is 0 and it means that bursts are not allowed. iops-total-max-length can only be set if iops-total-max is set as well, and its default value is 1 second. Controlling the size of I/O operations When applying IOPS limits all I/O operations are treated equally regardless of their size. This means that the user can take advantage of this in order to circumvent the limits and submit one huge I/O request instead of several smaller ones. QEMU provides a setting called throttling.iops-size to prevent this from happening. This setting specifies the size (in bytes) of an I/O request for accounting purposes. Larger requests will be counted proportionally to this size. For example, if iops-size is set to 4096 then an 8KB request will be counted as two, and a 6KB request will be counted as one and a half. This only applies to requests larger than iops-size: smaller requests will be always counted as one, no matter their size. The default value of iops-size is 0 and it means that the size of the requests is never taken into account when applying IOPS limits. Applying I/O limits to groups of disks In all the examples so far we have seen how to apply limits to the I/O performed on individual drives, but QEMU allows grouping drives so they all share the same limits. This feature is available since QEMU 2.4. Please refer to the post I wrote when it was published for more details. The Leaky Bucket algorithm I/O limits in QEMU are implemented using the leaky bucket algorithm (specifically the Leaky bucket as a meter variant). This algorithm uses the analogy of a bucket that leaks water constantly. The water that gets into the bucket represents the I/O that has been performed, and no more I/O is allowed once the bucket is full. To see the way this corresponds to the throttling parameters in QEMU, consider the following values:
  iops-total=100
  iops-total-max=2000
  iops-total-max-length=60
bucket The bucket is initially empty, therefore water can be added until it s full at a rate of 2000 IOPS (the burst rate). Once the bucket is full we can only add as much water as it leaks, therefore the I/O rate is reduced to 100 IOPS. If we add less water than it leaks then the bucket will start to empty, allowing for bursts again. Note that since water is leaking from the bucket even during bursts, it will take a bit more than 60 seconds at 2000 IOPS to fill it up. After those 60 seconds the bucket will have leaked 60 x 100 = 6000, allowing for 3 more seconds of I/O at 2000 IOPS. Also, due to the way the algorithm works, longer burst can be done at a lower I/O rate, e.g. 1000 IOPS during 120 seconds. Acknowledgments As usual, my work in QEMU is sponsored by Outscale and has been made possible by Igalia and the help of the QEMU development team. igalia-outscale Enjoy QEMU 2.6!

23 May 2016

Petter Reinholdtsen: Discharge rate estimate in new battery statistics collector for Debian

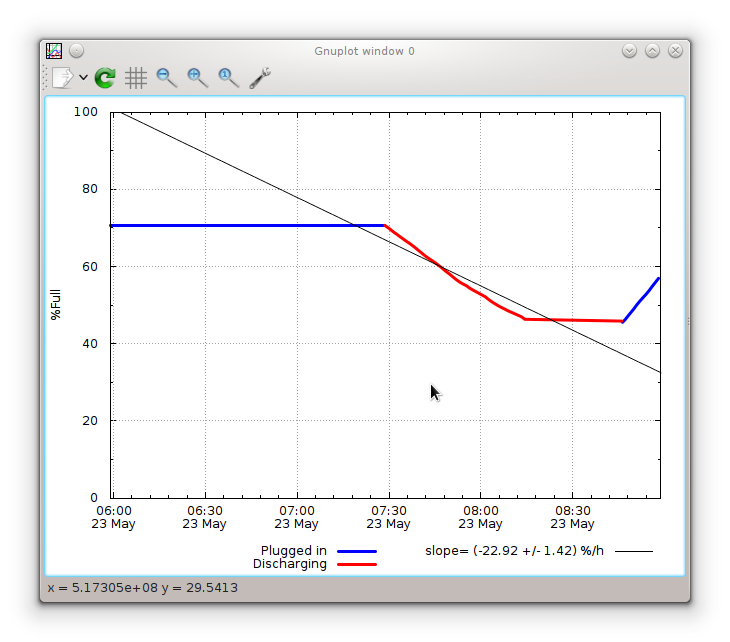
Yesterday I updated the battery-stats package in Debian with a few patches sent to me by skilled and enterprising users. There were some nice user and visible changes. First of all, both desktop menu entries now work. A design flaw in one of the script made the history graph fail to show up (its PNG was dumped in ~/.xsession-errors) if no controlling TTY was available. The script worked when called from the command line, but not when called from the desktop menu. I changed this to look for a DISPLAY variable or a TTY before deciding where to draw the graph, and now the graph window pop up as expected. The next new feature is a discharge rate estimator in one of the graphs (the one showing the last few hours). New is also the user of colours showing charging in blue and discharge in red. The percentages of this graph is relative to last full charge, not battery design capacity.

The other graph show the entire history of the collected battery statistics, comparing it to the design capacity of the battery to visualise how the battery life time get shorter over time. The red line in this graph is what the previous graph considers 100 percent:
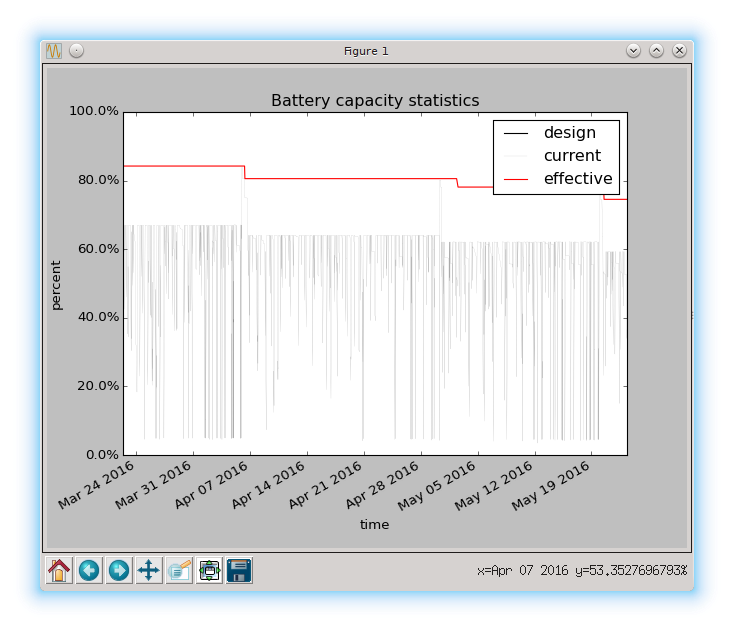
In this graph you can see that I only charge the battery to 80 percent of last full capacity, and how the capacity of the battery is shrinking. :( The last new feature is in the collector, which now will handle more hardware models. On some hardware, Linux power supply information is stored in /sys/class/power_supply/ACAD/, while the collector previously only looked in /sys/class/power_supply/AC/. Now both are checked to figure if there is power connected to the machine. If you are interested in how your laptop battery is doing, please check out the battery-stats in Debian unstable, or rebuild it on Jessie to get it working on Debian stable. :) The upstream source is available from github. Patches are very welcome. As usual, if you use Bitcoin and want to show your support of my activities, please send Bitcoin donations to my address 15oWEoG9dUPovwmUL9KWAnYRtNJEkP1u1b.
22 May 2016

Reproducible builds folks: Reproducible builds: week 56 in Stretch cycle

What happened in the Reproducible Builds effort between May 15th and May 21st 2016: Media coverage Blog posts from our GSoC and Outreachy contributors: Documentation update Ximin Luo clarified instructions on how to set SOURCE_DATE_EPOCH. Toolchain fixes Other upstream fixes Packages fixed The following 18 packages have become reproducible due to changes in their build dependencies: abiword angband apt-listbugs asn1c bacula-doc bittornado cdbackup fenix gap-autpgrp gerbv jboss-logging-tools invokebinder modplugtools objenesis pmw r-cran-rniftilib x-loader zsnes The following packages have become reproducible after being fixed: Some uploads have fixed some reproducibility issues, but not all of them: Patches submitted that have not made their way to the archive yet: Reproducibility-related bugs filed: Package reviews 51 reviews have been added, 19 have been updated and 15 have been removed in this week. 22 FTBFS bugs have been reported by Chris Lamb, Santiago Vila, Niko Tyni and Daniel Schepler. tests.reproducible-builds.org Misc. This week's edition was written by Reiner Herrmann and Holger Levsen and reviewed by a bunch of Reproducible builds folks on IRC.

Antonio Terceiro: Adopting pristine-tar

As of yesterday, I am the new maintainer of pristine-tar. As it is the case for most of Joey Hess creations, it is an extremely useful tool, and used in a very large number of Debian packages which are maintained in git. My first upload was most of a terrain recognition nature: I did some housekeeping tasks, such as making the build idempotent and making sure all binaries are built with security hardening flags, and wrote a few automated test cases to serve as build-time and run-time regression test suite. No functional changes have been made. As Joey explained when he orphaned it, there are a few technical challenges involved in making sure pristine-tar stays useful in the future. Although I did read some of the code, I am not particularly familiar with the internals yet, and will be more than happy to get co-maintainers. If you are interested, please get in touch. The source git repository is right there.

20 May 2016

Zlatan Todori : 4 months of work turned into GNOME, Debian testing based tablet

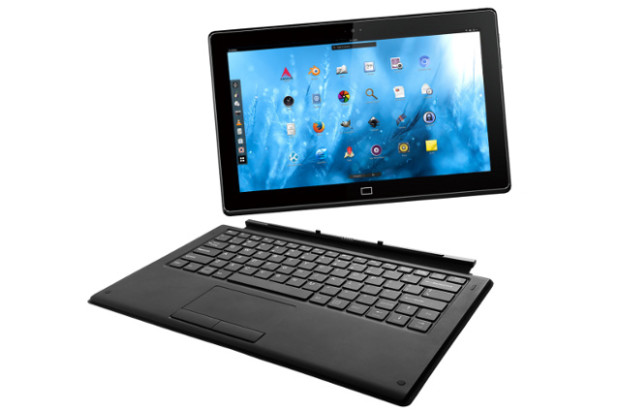
Huh, where do I start. I started working for a great CEO and great company known as Purism. What is so great about it? First of all, CEO (Todd Weaver), is incredible passionate about Free software. Yes, you read it correctly. Free software. Not Open Source definition, but Free software definition. I want to repeat this like a mantra. In Purism we try to integrate high-end hardware with Free software. Not only that, we want our hardware to be Free as much as possible. No, we want to make it entirely Free but at the moment we don't achieve that. So instead going the way of using older hardware (as Ministry of Freedom does, and kudos to them for making such option available), we sacrifice this bit for the momentum we hope to gain - that brings growth and growth brings us much better position when we sit at negotiation table with hardware producers. If negotiations even fail, with growth we will have enough chances to heavily invest in things such as openRISC or freeing cellular modules. We want to provide in future entirely Free hardware&software device that has integrated security and privacy focus while it is easy to use and convenient as any other mainstream OS. And we choose to currently sacrifice few things to stay in loop. Surely that can't be the only thing - and it isn't. Our current hardware runs entirely on Free software. You can install Debian main on it and all will work out of box. I know I did this and enjoy my Debian more than ever. We also have margin share program where part of profit we donate to Free software projects. We are also discussing a lot of new business model where our community will get a lot of influence (stay tuned for this). Besides all this, our OS (called PureOS - yes, a bit misfortune that we took the name of dormant distribution), was Trisquel based but now it is Debian testing based. Current PureOS 2.0 is coming with default DE as Cinnamom but we are already baking PureOS 3.0 which is going to come with GNOME Shell as default. Why is this important? Well, around 12 hours ago we launched a tablet campaign on Indiegogo which comes with GNOME Shell and PureOS as default. Not one, but two tablets actually (although we heavily focus on 11" one). This is the product of mine 4 months dedicated work at Purism. I must give kudos to all Purism members that pushed their parts in preparation for this campaign. It was hell of a ride. Librem11 I have also approached (of course!) Debian for creation of OEM installations ISOs for our Librem products. This way, with every sold Librem that ships with Debian preinstalled, Debian will get donation. It is our way to show gratitude to Debian for all the work our community does (yes, I am still extremely proud Debian dude and I will stay like that!). Oh yes, I am the chief technology person at Purism, and besides all goals we have, I also plan (dream) about Purism being the company that has highest number of Debian Developers. In that terms I am very proud to say that Matthias Klumpp became part of Purism. Hopefully we soon extend the number of Debian population in Purism. Of course, I think it is fairly known that I am easy to approach so if anyone has any questions (as I didn't want this post to be too long) feel free to contact me. Also - in Free software spirit - we welcome any community engagement, suggestion and/or feedback.

19 May 2016

Matthew Garrett: Your project's RCS history affects ease of contribution (or: don't squash PRs)

Github recently introduced the option to squash commits on merge, and even before then several projects requested that contributors squash their commits after review but before merge. This is a terrible idea that makes it more difficult for people to contribute to projects.

I'm spending today working on reworking some code to integrate with a new feature that was just integrated into Kubernetes. The PR in question was absolutely fine, but just before it was merged the entire commit history was squashed down to a single commit at the request of the reviewer. This single commit contains type declarations, the functionality itself, the integration of that functionality into the scheduler, the client code and a large pile of autogenerated code.

I've got some familiarity with Kubernetes, but even then this commit is difficult for me to read. It doesn't tell a story. I can't see its growth. Looking at a single hunk of this diff doesn't tell me whether it's infrastructural or part of the integration. Given time I can (and have) figured it out, but it's an unnecessary waste of effort that could have gone towards something else. For someone who's less used to working on large projects, it'd be even worse. I'm paid to deal with this. For someone who isn't, the probability that they'll give up and do something else entirely is even greater.

I don't want to pick on Kubernetes here - the fact that this Github feature exists makes it clear that a lot of people feel that this kind of merge is a good idea. And there are certainly cases where squashing commits makes sense. Commits that add broken code and which are immediately followed by a series of "Make this work" commits also impair readability and distract from the narrative that your RCS history should present, and Github present this feature as a way to get rid of them. But that ends up being a false dichotomy. A history that looks like "Commit", "Revert Commit", "Revert Revert Commit", "Fix broken revert", "Revert fix broken revert" is a bad history, as is a history that looks like "Add 20,000 line feature A", "Add 20,000 line feature B".

When you're crafting commits for merge, think about your commit history as a textbook. Start with the building blocks of your feature and make them one commit. Build your functionality on top of them in another. Tie that functionality into the core project and make another commit. Add client support. Add docs. Include your tests. Allow someone to follow the growth of your feature over time, with each commit being a chapter of that story. And never, ever, put autogenerated code in the same commit as an actual functional change.

People can't contribute to your project unless they can understand your code. Writing clear, well commented code is a big part of that. But so is showing the evolution of your features in an understandable way. Make sure your RCS history shows that, otherwise people will go and find another project that doesn't make them feel frustrated.

(Edit to add: Sarah Sharp wrote on the same topic a couple of years ago)

comment count unavailable comments

Antoine Beaupr : My free software activities, May 2016

Debian Long Term Support (LTS) This is my 6th month working on Debian LTS, started by Raphael Hertzog at Freexian. This is my largest month so far, for which I had requested 20 hours of work.

Xen work I spent the largest amount of time working on the Xen packages. We had to re-roll the patches because it turned out we originally just imported the package from Ubuntu as-is. This was a mistake because that package forked off the Debian packaging a while ago and included regressions in the packaging itself, not just security fixes. So I went ahead and rerolled the whole patchset and tested it on Koumbit's test server. Brian May then completed the uploaded, which included about 40 new patches, mostly from Ubuntu.

Frontdesk duties Next up was the frontdesk duties I had taken this week. This was mostly uneventful, although I had forgotten how to do some of the work and thus ended up doing extensive work on the contributor's documentation. This is especially important since new contributors joined the team! I also did a lot of Debian documentation work in my non-sponsored work below. The triage work involved chasing around missing DLAs, triaging away OpenJDK-6 (for which, let me remind you, security support has ended in LTS), raised the question of Mediawiki maintenance.

Other LTS work I also did a bunch of smaller stuff. Of importance, I can note that I uploaded two advisories that were pending from April: NSS and phpMyAdmin. I also reviewed the patches for the ICU update, since I built the one for squeeze (but didn't have time to upload before squeeze hit end-of-life). I have tried to contribute to the NTP security support but that was way too confusing to me, and I have left it to the package maintainer which seemed to be on top of things, even if things mean complete chaos and confusion in the world of NTP. I somehow thought that situation had improved with the recent investments in ntpsec and ntimed, but unfortunately Debian has not switched to the ntpsec codebase, so it seems that the NTP efforts have diverged in three different projects instead of closing into a single, better codebase.

Future LTS work This is likely to be my last month of work on LTS until September. I will try to contribute a few hours in June, but July and August will be very busy for me outside of Debian, so it's unlikely that I contribute much to the project during the summer. My backlog included those packages which might be of interest to other LTS contributors:
  • libxml2: no upstream fix, but needs fixing!
  • tiff ,3 : same mess
  • libgd2: maintainer contacted
  • samba regression: mailed bug #821811 to try to revive the effort
  • policykit-1: to be investigated
  • p7zip: same

Other free software work

Debian documentation I wrote an detailed short guide to Debian package development, something I felt was missing from the existing corpus, which seems to be too focus in covering all alternatives. My guide is opinionated: I believe there is a right and wrong way of doing things, or at least, there are best practices, especially when just patching packages. I ended up retroactively publishing that as a blog post - now I can simply tag an item with blog and it shows up in the blog. (Of course, because of a mis-configuration on my side, I have suffered from long delays publishing to Debian planet, so all the posts dates are off in the Planet RSS feed. This will hopefully be resolved around the time this post is published, but this allowed me to get more familiar with the Planet Venus software, as detailed in that other article.) Apart from the guide, I have also done extensive research to collate information that allowed me to create workflow graphs of the various Debian repositories, which I have published in the Debian Release section of the Debian wiki. Here is the graph: It helps me understand how packages flow between different suites and who uploads what where. This emerged after I realized I didn't really understand how "proposed updates" worked. Since we are looking at implementing a similar process for the security queue, I figured it was useful to show what changes would happen, graphically. I have also published a graph that describes the relations between different software that make up the Debian archive. The idea behind this is also to provide an overview of what happens when you upload a package in the Debian archive, but it is more aimed at Debian developers trying to figure out why things are not working as expected. The graphs were done with Graphviz, which allowed me to link to various components in the graph easily, which is neat. I also prefered Graphviz over Dia or other tools because it is easier to version and I don't have to bother (too much) about the layout and tweaking the looks. The downside is, of course, that when Graphviz makes the wrong decision, it's actually pretty hard to make it do the right thing, but there are various workarounds that I have found that made the graphs look pretty good. The source is of course available in git but I feel all this documentation (including the guide) should go in a more official document somewhere. I couldn't quite figure out where. Advice on this would be of course welcome.

Ikiwiki I have made yet another plugin for Ikiwiki, called irker, which enables wikis to send notifications to IRC channels, thanks to the simple irker bot. I had trouble with Irker in the past, since it was not quite reliable: it would disappear from channels and not return when we'd send it a notification. Unfortunately, the alternative, the KGB bot is much heavier: each repository needs a server-side, centralized configuration to operate properly. Irker's design is simpler and more adapted to a simple plugin like this. Let's hope it will work reliably enough for my needs. I have also suggested improvements to the footnotes styles, since they looked like hell in my Debian guide. It turns out this was an issue with the multimarkdown plugin that doesn't use proper semantic markup to identify footnotes. The proper fix is to enable footnotes in the default Discount plugin, which will require another, separate patch. Finally, I have done some improvements (I hope!) on the layout of this theme. I made the top header much lighter and transparent to work around an issue where followed anchors would be hidden under the top header. I have also removed the top menu made out of the sidebar plugin because it was cluttering the display too much. Those links are all on the frontpage anyways and I suspect people were not using them so much. The code is, as before, available in this git repository although you may want to start from the new ikistrap theme that is based on Bootstrap 4 and that may eventually be merged in ikiwiki directly.

DNS diagnostics Through this interesting overview of various *ping tools, I got found out about the dnsdiag tool which currently allows users to do DNS traces, tampering detection and ping over DNS. In the hope of packaging it into Debian, I have requested clarifications regarding a modification to the DNSpython library the tool uses. But I went even further and boldly opened a discussion about replacing DNSstuff, the venerable DNS diagnostic tools that is now commercial. It is somewhat surprising that there is no software that has even been publicly released that does those sanity checks for DNS, given how old DNS is. Incidentally, I have also requested smtpping to be packaged in Debian as well but httping is already packaged.

Link checking In the process of writing this article, I suddenly remembered that I constantly make mistakes in the various links I post on my site. So I started looking at a link checker, another tool that should be well established but that, surprisingly, is not quite there yet. I have found this neat software written in Python called LinkChecker. Unfortunately, it is basically broken in Debian, so I had to do a non-maintainer upload to fix that old bug. I managed to force myself to not take over maintainership of this orphaned package but I may end up doing just that if no one steps up the next time I find issues in the package. One of the problems I had checking links in my blog is that I constantly refer to sites that are hostile to bots, like the Debian bugtracker and MoinMoin wikis. So I published a patch that adds a --no-robots flag to be able to crawl those sites effectively. I know there is the W3C tool but it's written in Perl, and there's probably zero chance for me to convince those guys to bypass robots exclusion rules, so I am sticking to Linkchecker.

Other Debian packaging work At my request, Drush has finally been removed from Debian. Hopefully someone else will pick up that work, but since it basically needs to be redone from scratch, there was no sense in keeping it in the next release of Debian. Similarly, Semanticscuttle was removed from Debian as well. I have uploaded new versions of tuptime, sopel and smokeping. I have also file a Request For Help for Smokeping. I am happy to report there was a quick response and people will be stepping up to help with the maintenance of that venerable monitoring software.

Background radiation Finally, here's the generic background noise of me running around like a chicken with his head cut off: Finally, I should mention that I will be less active in the coming months, as I will be heading outside as the summer finally came! I somewhat feel uncomfortable documenting publicly my summer here, as I am more protective of my privacy than I was before on this blog. But we'll see how it goes, maybe you'll hear non-technical articles here again soon!

Valerie Young: Summer of Reproducible Builds

Hello friend, family, fellow Outreachy participants, and the Debian community!
This blog's primary purpose will be to track the progress of the Outreachy project in which I'm participating this summer    This post is to introduce myself and my project (working on the Debian reproducible builds project).
What is Outreachy? You might not know! Let me empower you: Outreachy is an organization connecting woman and minorities to mentors in the free (as in freedom) software community, /and/ funding for three months to work with the mentors and contribute to a free software project.  If you are a woman or minority human that likes free software, or if you know anyone in this situation, please tell them about Outreachy   Or put them in touch with me, I'd happily tell them more.
So who am I?
My name is Valerie Young. I live in the Boston Metropolitan Area (any other outreachy participants here?) and hella love free software. 
Some bullet pointed Val facts in rough reverse chronological order:
- I run Debian but only began contributing during the Outreachy application process
- If you went to DebConf2015, you might have seen me dye nine people's hair blue, blond or Debian swirl.
- If you stop through Boston I could be easily convinced to dye your hair.
- I worked on electronic medical records web application for the last two years (lotsa Javascriptin' and Perlin' at athenahealth)
- Before that I taught a programming summer program at University of Moratuwain Sri Lanka.
- Before that I got a degrees in physics and computer science at Boston University.
- At BU I helped start a hackerspace where my interest in technology, free software, hacker culture, anarchy, the internet all began.
- I grew up in the very fine San Francisco Bay Area.
What will I be working on?
Reproducible builds!
In the near future I'll write a  What is reproducible builds? Why is it so hot right now?  post.  For now, from a high (and not technical) level, reproducible builds is a broad effort to verify that the computer executable binary programs you run on your computer come from the human readable source code they claim to. It is not presently /impossible/ to do this verification, but it's not easy, and there are a lot of nuanced computer quirks that make it difficult for the most experienced programmer and straight-up impossible for a user with no technical expertise. And without this ability to verify -- the state we are in now -- any executable piece of software could be hiding secret code. 
The first step towards the goal of verifiability is to make reproducibility a essential part of software development. Reproducible builds means this: when you compile a program from the source code, it should always be identical, bit by bit. If the program is always identical, you can compare your version of the software to any trusted programmer with very little effort. If it is identical, you can trust it -- if it's not, you have reason to worry.
The Debian project is undergoing an effort to make the entire Debian operating system verifiable reproducible (hurray!). My outreachy-funded summer contribution involves the improving and updating tests.reproducible-builds.org   a site that presently presently surfaces the results of reproducibility testing of several free software projects (including Debian, Fedora, coreboot, OpenWrt, NetBSD, FreeBSD and ArchLinux). However, the design of test.r-b.org is a bit confusing, making it difficult for a user to find how to check on the reproducibility of a given package for one of the aforementioned projects, or understand the reasons for failure. Additional, the backend test results of Debian are outgrowing the original SQLite database, and many projects do not log the results of package testing at all. I hope, by the end of the summer, we'll have a more beefed-out and pretty site as well as better organized backend data  
This summer there will be 3 other Outreachy participants working on the Debian reproducible builds project! Check out their blogs/projects:
Scarlett
Satyam
Ceridwen
Thanks to our Debian mentors -- Lunar, Holger Levsen, and Mattia Rizzolo -- for taking us on   

Michal &#268;iha&#345;: wlc 0.3

wlc 0.3, a command line utility for Weblate, has been just released. This is probably first release which is worth using so it's probably also worth of bigger announcement. It is built on API introduced in Weblate 2.6 and still being in development. Several commands from wlc will not work properly if executed against Weblate 2.6, first fully supported version will be 2.7 (current git is okay as well, it is now running on both demo and hosting servers). How to use it? First you will probably want to store the credentials, so that your requests are authenticated (you can do unauthenticated requests as well, but obviously only read only and on public objects), so lets create ~/.config/weblate:
[weblate]
url = https://hosted.weblate.org/api/
[keys]
https://hosted.weblate.org/api/ = APIKEY
Now you can do basic commands:
$ wlc show weblate/master/cs
...
last_author: Michal  iha 
last_change: 2016-05-13T15:59:25
revision: 62f038bb0bfe360494fb8dee30fd9d34133a8663
share_url: https://hosted.weblate.org/engage/weblate/cs/
total: 1361
total_words: 6144
translate_url: https://hosted.weblate.org/translate/weblate/master/cs/
translated: 1361
translated_percent: 100.0
translated_words: 6144
url: https://hosted.weblate.org/api/translations/weblate/master/cs/
web_url: https://hosted.weblate.org/projects/weblate/master/cs/
You can find more examples in wlc documentation.

Filed under: Debian English phpMyAdmin SUSE Weblate 0 comments

Petter Reinholdtsen: I want the courts to be involved before the police can hijack a news site DNS domain (#domstolkontroll)

I just donated to the NUUG defence "fond" to fund the effort in Norway to get the seizure of the news site popcorn-time.no tested in court. I hope everyone that agree with me will do the same. Would you be worried if you knew the police in your country could hijack DNS domains of news sites covering free software system without talking to a judge first? I am. What if the free software system combined search engine lookups, bittorrent downloads and video playout and was called Popcorn Time? Would that affect your view? It still make me worried. In March 2016, the Norwegian police seized (as in forced NORID to change the IP address pointed to by it to one controlled by the police) the DNS domain popcorn-time.no, without any supervision from the courts. I did not know about the web site back then, and assumed the courts had been involved, and was very surprised when I discovered that the police had hijacked the DNS domain without asking a judge for permission first. I was even more surprised when I had a look at the web site content on the Internet Archive, and only found news coverage about Popcorn Time, not any material published without the right holders permissions. The seizure was widely covered in the Norwegian press (see for example Hegnar Online and ITavisen and NRK), at first due to the press release sent out by kokrim, but then based on protests from the law professor Olav Torvund and lawyer Jon Wessel-Aas. It even got some coverage on TorrentFreak. I wrote about the case a month ago, when the Norwegian Unix User Group (NUUG), where I am an active member, decided to ask the courts to test this seizure. The request was denied, but NUUG and its co-requestor EFN have not given up, and now they are rallying for support to get the seizure legally challenged. They accept both bank and Bitcoin transfer for those that want to support the request. If you as me believe news sites about free software should not be censored, even if the free software have both legal and illegal applications, and that DNS hijacking should be tested by the courts, I suggest you show your support by donating to NUUG.

Reproducible builds folks: Improving the process for testing build reproducibility

Author: ceridwen Hi! I'm Ceridwen. I'm going to be one of the Outreachy interns working on Reproducible Builds for the summer of 2016. My project is to create a tool, tentatively named reprotest, to make the process of verifying that a build is reproducible easier. The current tools and the Reproducible Builds site have limits on what they can test, and they're not very user friendly. (For instance, I ended up needing to edit the rebuild.sh script to run it on my system.) Reprotest will automate some of the busywork involved and make it easier for maintainers to test reproducibility without detailed knowledge of the process involved. A session during the Athens meeting outlines some of the functionality and command-line and configuration file API goals for reprotest. I also intend to use some ideas, and command-line and config processing boilerplate, from autopkgtest. Reprotest, like autopkgtest, should be able to interface with more build environments, such as schroot and qemu. Both autopkgtest and diffoscope, the program that the Reproducible Builds project uses to check binaries for differences, are written in Python, and as Python is the scripting language I'm most familiar with, I will be writing reprotest in Python too. One of my major goals is to get a usable prototype released in the first three to four weeks. At that point, I want to try to solicit feedback (and any contributions anyone wants to make!). One experience I've had in open source software is that connecting people with software they might want to use is often the hardest part of a project. I've reimplemented existing functionality myself because I simply didn't know that someone else had already written something equivalent, and seen many other people do the same. Once I have the skeleton fleshed out, I'm going to be trying to find and reach out to any other communities, outside the Debian Reproducible Builds project itself, who might find reprotest useful.

18 May 2016

Stig Sandbeck Mathisen: Puppet 4 uploaded to Debian experimental

I ve uploaded puppet 4.4.2-1 to Debian experimental. Please test with caution, and expect sharp corners. This is a new major version of Puppet in Debian, with many new features and potentially breaking changes, as well as a big rewrite of the .deb packaging. Bug reports for src:puppet are very welcome. As previously described in #798636, the new package names are: Lots of hugs to the authors, keepers and maintainers of autopkgtest, debci, piuparts and ruby-serverspec for their software. They helped me figure out when I had reached good enough for experimental . Some notes: I sincerely hope someone finds this useful. :)

Bits from Debian: Imagination accelerates Debian development for 64-bit MIPS CPUs

Imagination Technologies recently donated several high-performance SDNA-7130 appliances to the Debian Project for the development and maintenance of the MIPS ports. The SDNA-7130 (Software Defined Network Appliance) platforms are developed by Rhino Labs, a leading provider of high-performance data security, networking, and data infrastructure solutions. With these new devices, the Debian project will have access to a wide range of 32- and 64-bit MIPS-based platforms. Debian MIPS ports are also possible thanks to donations from the aql hosting service provider, the Eaton remote controlled ePDU, and many other individual members of the Debian community. The Debian project would like to thank Imagination, Rhino Labs and aql for this coordinated donation. More details about GNU/Linux for MIPS CPUs can be found in the related press release at Imagination and their community site about MIPS.

Next.

Previous.