Search Results: "spa"

5 January 2014

Lisandro Damián Nicanor Pérez Meyer: Qt 5.2.0 in Debian experimental, now available for more archs

Qt 5.2.0 is already available in experimental until we get a transition slot, but don't be afraid to test it. With this release we had major improvements. With 5.1.1 currently in sid we have the following buildd chart:

Qt 5.1.1 in Debian Sid
Now with 5.2.0 in Debian experimental we have:

Qt 5.2.0 in Debian experimental

As you can see Qt has compiled in more archs, thanks to the effort of the Debian's porters and from the Qt/KDE team.

Note that Qt JS Backend has dissapeared: it's functionality (the javascript engine) is now in Qt Declarative itself. It has been ported away from Google's v8 to a Qt-based engine, allowing it to build in more archs among other features.

You can also note that we still have quite some FTBFS, mostly coming from Qt Webkit. Feel free to send patches ;-)

3 January 2014

Dirk Eddelbuettel: New BH release 1.51.1-4

A new release of the BH package is now on CRAN and its mirrors. BH provides (a sizeable subset of) the Boost library for C++, particularly the (large) parts delivered as pure template headers not requiring linking. See the BH page for more details. This release comes from a rewritten build script for the package. We no longer drive the initial set of Boost libraries by the requirements of the bigmemory (and synchronicity) packages, but rather explicitly enumerate an equivalent set of Boost libraries. This ensures that these libraries are included completely. We also move the project repository to this GitHub repo. The complete list changes follows below.
Changes in version 1.51.0-4 (2014-01-01)
  • Rewritten main package creation script to no longer scan for what bigmemory and synchronicity use, but rather explicitly copy over an (equivalent) list of explicitly-enumerated Boost libraries
  • Repository moved from R-Forge to GitHub, scripts and layout adjusted accordingly
  • Besides the implicitly expanded coverage by including the complete libraries, we also expanded from math/distributions to all of math.
Courtesy of CRANberries, there is also a diffstat report for the most recent release. Comments and suggestions are welcome via the mailing list or issue tracker still available via the package page at R-Forge.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

2 January 2014

Luke Faraone: Unstandardized standards are the worst: sendmail

Implementing software to replace legacy systems is always a challenge, especially when you're dealing with a system with as much legacy as sendmail, which was first introduced as delivermail in 1979.ref

Each UNIX vendor, it seems, rewrote or heavily customized sendmail. This has lead to sometimes conflicting implementations.
Case in point: -tNormally, you invoke sendmail(8) with a series of arguments indicating the subject of a message, the recipients, etc. When invoked this way, the command expects a message on standard input, waits for EOF, and then sends your message along.

However, sometimes you don't want to have to fiddle with command-line parameters; you've already written a perfectly fine message with headers.

-t is generally passed to sendmail when you want to build a message envelope from an already-formatted message, with headers, etc. For example, if you had a file foo.txt with a body like this:
From: Luke Faraone 
To: John Smith
Subject: Hello, world!

Hi there.

you could send the message with a simple invocation of cat foo.txt sendmail -t. The system would take care of ensuring a Message-id was appended if appropriate, and queue the message to be sent. However, it is when you do slightly more complex invocations of sendmail that things get ambiguous.

It turns out that implementations differ on what exactly it means when you use -t in combination with naming destination addresses after the arguments to sendmail. exim4's documentation describes the situation in greater detail:
extract_addresses_remove_ argumentsUse: mainType: booleanDefault: true
According to some Sendmail documentation (Sun, IRIX, HP-UX), if any addresses are present on the command line when the -t option is used to build an envelope from a message s To:, Cc: and Bcc: headers, the command line addresses are removed from the recipients list. This is also how Smail behaves. However, other Sendmail documentation (the O Reilly book) states that command line addresses are added to those obtained from the header lines. When extract_addresses_remove_arguments is true (the default), Exim subtracts argument headers. If it is set false, Exim adds rather than removes argument addresses.

Thus, there's basically no mechanism for a program to know which behaviour to expect. God forbid two programs are installed on a system that expect different behaviours!

It appears that the default behaviour of Ruby is the opposite of what exim4 (Debian's default mail client) expects. This has resulted in numerous bug reports. Some replies suggest changing exim4's defaults, while others advocate overriding ActionMailer and friends to use sendmail -i instead, without -t.

That said, its not really clear who's wrong here; at no point does there appear to have been a definitive specification for sendmail, and as such we can hope for defined behaviour by common custom at best, and a sea of incompatibility bugs at worst. Amusingly, POSIX standards have nothing to say on this subject of sendmail at all; it defines that a mailx command must exist, but says that its sending mode may be implementation-specific.

As Matthew Garrett writes, there's not enough gin in the world.

Keith Packard: Present-pixmap-lifetimes-part-deux

Pixmap ID Lifetimes under Present Redirection (Part Deux) I recently wrote about pixmap content and ID lifetimes. I think the pixmap content lifetime stuff was useful, but the pixmap ID stuff was not quite right. I ve just copied the section from the previous post and will update it. PresentRedirect pixmap ID lifetimes (reprise) A compositing manager will want to know the lifetime of the pixmaps delivered in PresentRedirectNotify events to clean up whatever local data it has associated with it. For instance, GL compositing managers will construct textures for each pixmap that need to be destroyed when the pixmap disappears. Present encourages pixmap destruction The PresentPixmap request says:
PresentRegion holds a reference to pixmap until the presentation occurs, so pixmap may be immediately freed after the request executes, even if that is before the presentation occurs.
Breaking this when doing Present redirection seems like a bad idea; it s a very common pattern for existing 2D applications. New pixmap IDs for everyone Because pixmap IDs for present contents are owned by the source application (and may be re-used immediately when freed), Present can t use that ID in the PresentRedirectNotify event. Instead, it must allocate a new ID and send that instead. The server has it s own XID space to use, and so it can allocate one of those and bind it to the same underlying pixmap; the pixmap will not actually be destroyed until both the application XID and the server XID are freed. The compositing manager will receive this new XID, and is responsible for freeing it when it doesn t need it any longer. Of course, if the compositing manager exits, all of the XIDs passed to it will automatically be freed. I considered allocating client-specific XIDs for this purpose; the X server already has a mechanism for allocating internal IDs for various things that are to be destroyed at client shut-down time. Those XIDs have bit 30 set, and are technically invalid XIDs as X specifies that the top three bits of every XID will be zero. However, the cost of using a server ID instead (which is a valid XID) is small, and it s always nice to not intentionally break the X protocol (even as we continue to take advantage of accidental breakages). (Reserving the top three bits of XIDs and insisting that they always be zero was a nod to the common practice of weakly typed languages like Lisp. In these languages, 32-bit object references were typed by using few tag bits (2-3) within the value. Most of these were just pointers to data, but small integers, that fit in the remaining bits (29-30), could be constructed without allocating any memory. By making XIDs only 29 bits, these languages could be assured that all XIDs would be small integers.) Pixmap Destroy Notify The Compositing manager needs to know when the application is done with the pixmap so that it can clean up when it is also done; destroying the extra pixmap ID it was given and freeing any other local resources. When the application sends a FreePixmap request, that XID will become invalid, but of course the pixmap itself won t be freed until the compositing manager sends a FreePixmap request with the extra XID it was given. Because the pixmap ID known by the compositing manager is going to be different from the original application XID, we need an event delivered to the compositing manager with the new XID, which makes this event rather Present specific. We don t need to select for this event; the compositing manager must handle it correctly, so we ll just send it whenever the composting manager has received that custom XID. PresentPixmapDestroyNotify
 
    PresentPixmapDestroyNotify
    type: CARD8         XGE event type (35)
    extension: CARD8        Present extension opcode
    sequence-number: CARD16
    length: CARD32          0
    evtype: CARD16          Present_PixmapDestroyNotify
    eventID: XFIXESEVENTID
    event-window: WINDOW
    pixmap: pixmap
 
This event is delivered to the clients selecting for SubredirectNotify for pixmaps which were delivered in a PresentRedirectNotify event and for which the originating application Pixmap has been destroyed. Note that the pixmap may still be referenced by other objects within the X server, by a pending PresentPixmap request, as a window background, GC tile or stipple or Picture drawable (among others), but this event serves to notify the selecting client that the application is no longer able to access the underlying pixmap with it s original Pixmap ID.

1 January 2014

Vincent Bernat: Testing infrastructure with serverspec

Checking if your servers are configured correctly can be done with IT automation tools like Puppet, Chef, Ansible or Salt. They allow an administrator to specify a target configuration and ensure it is applied. They can also run in a dry-run mode and report servers not matching the expected configuration. On the other hand, serverspec is a tool to bring the well known RSpec, a testing tool for the Ruby programming language frequently used for test-driven development, to the infrastructure world. It can be used to remotely test server state through an SSH connection. Why one would use such an additional tool? Many things are easier to express with a test than with a configuration change, like for example checking that a service is correctly installed by checking it is listening to some port.

Getting started Good knowledge of Ruby may help but is not a prerequisite to the use of serverspec. Writing tests feels like writing what we expect in plain English. If you think you need to know more about Ruby, here are two short resources to get started: serverspec s homepage contains a short and concise tutorial on how to get started. Please, read it. As a first illustration, here is a test checking a service is correctly listening on port 80:
describe port(80) do
  it   should be_listening  
end
The following test will spot servers still running with Debian Squeeze instead of Debian Wheezy:
describe command("lsb_release -d") do
  it   should return_stdout /wheezy/  
end
Conditional tests are also possible. For example, we want to check the miimon parameter of bond0, but only when the interface is present:
has_bond0 = file('/sys/class/net/bond0').directory?
# miimon should be set to something other than 0, otherwise, no checks
# are performed.
describe file("/sys/class/net/bond0/bonding/miimon"), :if => has_bond0 do
  it   should be_file  
  its(:content)   should_not eq "0\n"  
end
serverspec comes with a complete documentation of available resource types (like port and command) that can be used after the keyword describe. When a test is too complex to be expressed with simple expectations, it can be specified with arbitrary commands. In the below example, we check if memcached is configured to use almost all the available system memory:
# We want memcached to use almost all memory. With a 2GB margin.
describe "memcached" do
  it "should use almost all memory" do
    total = command("vmstat -s   head -1").stdout #  
    total = /\d+/.match(total)[0].to_i
    total /= 1024
    args = process("memcached").args #  
    memcached = /-m (\d+)/.match(args)[1].to_i
    (total - memcached).should be > 0
    (total - memcached).should be < 2000
  end
end
A bit more arcane, but still understandable: we combine arbitrary shell commands (in ) and use of other serverspec resource types (in ).

Advanced use Out of the box, serverspec provides a strong fundation to build a compliance tool to be run on all systems. It comes with some useful advanced tips, like sharing tests among similar hosts or executing several tests in parallel. I have setup a GitHub repository to be used as a template to get the following features:
  • assign roles to servers and tests to roles;
  • parallel execution;
  • report generation & viewer.

Host classification By default, serverspec-init generates a template where each host has its own directory with its unique set of tests. serverspec only handles test execution on remote hosts: the test execution flow (which tests are executed on which servers) is delegated to some Rakefile1. Instead of extracting the list of hosts to test from a directory hiearchy, we can extract it from a file (or from an LDAP server or from any source) and attach a set of roles to each of them:
hosts = File.foreach("hosts")
  .map    line  line.strip  
  .map do  host 
   
    :name => host.strip,
    :roles => roles(host.strip),
   
end
The roles() function should return a list of roles for a given hostname. It could be something as simple as this:
def roles(host)
  roles = [ "all" ]
  case host
  when /^web-/
    roles << "web"
  when /^memc-/
    roles << "memcache"
  when /^lb-/
    roles << "lb"
  when /^proxy-/
    roles << "proxy"
  end
  roles
end
In the snippet below, we create a task for each server as well as a server:all task that will execute the tests for all hosts (in ). Pay attention, in , at how we attach the roles to each server.
namespace :server do
  desc "Run serverspec to all hosts"
  task :all => hosts.map    h  h[:name]   #  
  hosts.each do  host 
    desc "Run serverspec to host # host[:name] "
    ServerspecTask.new(host[:name].to_sym) do  t 
      t.target = host[:name]
      #  : Build the list of tests to execute from server roles
      t.pattern = './spec/ ' + host[:roles].join(",") + ' /*_spec.rb'
    end
  end
end
You can check the list of tasks created:
$ rake -T
rake check:server:all      # Run serverspec to all hosts
rake check:server:web-10   # Run serverspec to host web-10
rake check:server:web-11   # Run serverspec to host web-11
rake check:server:web-12   # Run serverspec to host web-12
Then, you need to modify spec/spec_helper.rb to tell serverspec to fetch the host to test from the environment variable TARGET_HOST instead of extracting it from the spec file name.

Parallel execution By default, each task is executed when the previous one has finished. With many hosts, this can take some time. rake provides the -j flag to specify the number of tasks to be executed in parallel and the -m flag to apply parallelism to all tasks:
$ rake -j 10 -m check:server:all

Reports rspec is invoked for each host. Therefore, the output is something like this:
$ rake spec
env TARGET_HOST=web-10 /usr/bin/ruby -S rspec spec/web/apache2_spec.rb spec/all/debian_spec.rb
......
Finished in 0.99715 seconds
6 examples, 0 failures
env TARGET_HOST=web-11 /usr/bin/ruby -S rspec spec/web/apache2_spec.rb spec/all/debian_spec.rb
......
Finished in 1.45411 seconds
6 examples, 0 failures
This does not scale well if you have dozens or hundreds of hosts to test. Moreover, the output is mangled with parallel execution. Fortunately, rspec comes with the ability to save results in JSON format. Those per-host results can then be consolidated into a single JSON file. All this can be done in the Rakefile:
  1. For each task, set rspec_opts to --format json --out ./reports/current/# target .json. This is done automatically by the subclass ServerspecTask which also handles passing the hostname in an environment variable and a more concise and colored output.
  2. Add a task to collect the generated JSON files into a single report. The test source code is also embedded in the report to make it self-sufficient. Moreover, this task is executed automatically by adding it as a dependency of the last serverspec-related task.
Have a look at the complete Rakefile for more details on how this is done. A very simple web-based viewer can handle those reports2. It shows the test results as a matrix with failed tests in red: Report viewer example Clicking on any test will display the necessary information to troubleshoot errors, including the test short description, the complete test code, the expectation message and the backtrace: Report viewer showing detailed error I hope this additional layer will help making serverspec another feather in the IT cap, between an automation tool and a supervision tool.

  1. A Rakefile is a Makefile where tasks and their dependencies are described in plain Ruby. rake will execute them in the appropriate order.
  2. The viewer is available in the GitHub repository in the viewer/ directory.

30 December 2013

Carl Chenet: Virtual environments with Python 3.3

Follow me on Identi.ca or Twitter One of the major features of Python 3.3 is the new venv module, allowing the creation of Python virtual environments on your system. 1. What is a virtual environment? A virtual environment is a directory dedicated to the execution of your Python applications. Activating your virtual environment will force Python to execute in this directory as the top level of this directory was the root of your file system. The virtual environments are interesting because of the independence they have toward the host they run on, especially when you want to install several versions of Python or if you want to install lots of dependencies without being the system administrator of the host. python-logo-master-v3-TM If you are a Python developer, you must know virtualenv. This really nice application offers a nice way to create Python virtual environment. Moreover it comes with pip already installed in your virtual environment, in order to install other dependencies you need in a really convenience way. Starting from Python 3.3, the module venv of the Python standard library offers the users to create virtual environments. This new feature will encourage all users to create virtual environments to develop their own Python applications, which is a good practice. Thanks to the experiences of several applications being used in the Python community, the module venv was written to be really efficient and widely available. The Python Enhancement Proposal 405 (PEP405) offers a really interesting reading if you wish to find more information about this topic. 2. Creating a virtual environment with Python 3.3 With Python 3.3 comes pyvenv-3.3, allowing to create Python virtual environment:
$ pyvenv-3.3 myvirtualenv
$ cd myvirtualenv/
$ tree .
.
  bin
    activate
    pydoc
    python -> python3.3
    python3 -> python3.3
    python3.3 -> /usr/bin/python3.3
  include
  lib
    python3.3
        site-packages
  pyvenv.cfg
As we can see, three directories were created.
$ cat pyvenv.cfg 
home = /usr/bin
include-system-site-packages = false
version = 3.3.2
Just before moving on, if you want to use the existing modules in your global site-packages directory on your system, the option system-site-packages is available. 3. Activate the virtual environment Lets activate our virtual environment. We need to use the bin/activate file in this environment:
$ source bin/activate 
(myvirtualenv) $
A change in our prompt indicated the good activation of the virtual environment. 4. Installing applications in the virtual environment But playing around with only the default Python interpreter is not really funny. Lets download pip, the Python installer, but before that we need a dependency setuptools:
(myvirtualenv) $ curl https://bitbucket.org/pypa/setuptools/raw/bootstrap/ez_setup.py -o ez_setup.py
 % Total % Received % Xferd Average Speed Time Time Time Current
 Dload Upload Total Spent Left Speed
 100 11356 100 11356 0 0 18507 0 --:--:-- --:--:-- --:--:-- 18495
(myvirtualenv) $ curl https://raw.github.com/pypa/pip/master/contrib/get-pip.py -o get-pip.py
 % Total % Received % Xferd Average Speed Time Time Time Current
 Dload Upload Total Spent Left Speed
 100 543k 100 543k 0 0 685k 0 --:--:-- --:--:-- --:--:-- 685k
Now lets install Setuptools and Pip:
(myvirtualenv) $ python3.3 ez_setup.py
 Downloading https://pypi.python.org/packages/source/s/setuptools/setuptools-2.0.tar.gz
 Extracting in /tmp/tmpxlrv7q
 Now working in /tmp/tmpxlrv7q/setuptools-2.0
 Installing Setuptools
... (lots of lines)...
Installed /tmp/myvirtualenv/lib/python3.3/site-packages/setuptools-2.0-py3.3.egg
 Processing dependencies for setuptools==2.0
 Finished processing dependencies for setuptools==2.0
(myvirtualenv) $ python3.3 get-pip.py
 Downloading/unpacking pip
 Downloading pip-1.4.1.tar.gz (445kB): 445kB downloaded
 Running setup.py egg_info for package pip
 ... (lots of lines)...
 Successfully installed pip
 Cleaning up...
Ok now we re ready to use pip to install anything we need in our virtual environment. Lets think one more second about what we did: we install the Setuptools and the Pip application inside our virtual environment, with nothing written on our main system. Now lets try to install Brebis, the fully automated backup checker, and run it in this environment:
(myvirtualenv) $ pip-3.3 install brebis
 Downloading/unpacking brebis
 Downloading brebis-0.8.tar.gz
 Running setup.py egg_info for package brebis
Installing collected packages: brebis
 Running setup.py install for brebis
 changing mode of build/scripts-3.3/brebis from 644 to 755
changing mode of /tmp/myvirtualenv/bin/brebis to 755
 Successfully installed brebis
 Cleaning up...
We re now ready to launch Brebis, executing in our virtual environment:
(myvirtualenv) $ brebis -h
usage: brebis [-h] [-c DIR] [-C DIR] [-d DELIMITER] [-g] [-G] [-l FILE]
 [-L DIR] [-O DIR] [-v] 
Fully automated backup checker
positional arguments:
 archives archives to check
optional arguments:
 -h, --help show this help message and exit
 -c DIR, --configpath DIR
 the path to the configurations
 -C DIR, --output-conf-dir DIR
 the directory to store the configuration file
 -d DELIMITER, --delimiter DELIMITER
 delimiter of the fields for the list of files
 -g, --gen-list generate a list of files inside a backup
 -G, --gen-full generate the configuration file and the list of files
 for the backup
 -l FILE, --log FILE the log file
 -L DIR, --output-list-dir DIR
 the directory to store the list of files inside an
 archive or tree
 -O DIR, --output-list-and-conf-dir DIR
 the directory to store the configuration file and the
 list of files inside an archive or tree
 -v, --version print the version of this program and exit
For more information: http://www.brebisproject.org
So we get an execution of the Brebis application inside our virtual environment, installed from our virtual environment with tools installed only in the virtual environment. That s a big step that such a feature is now included in the standard library. In the future, you will enjoy the possibility to create new virtual environments for each Python version right out of the box. Moreover, using the upgrade option of the pyvenv command, you will upgrade, if needed, your virtual environment in a really easy and straightforward way, making environments adaptable in time. What about you? What do you think about the Python 3 virtual environments and their features, given your own needs? Feel free to use the comments section of this post.

29 December 2013

Steve Kemp: A good week?

This week my small collection of sysadmin tools received a lot of attention; I've no idea what triggered it, but it ended up on the front-page of github as a "trending repository". Otherwise I've recently spent some time "playing about" with some security stuff. My first recent report wasn't deemed worthy of a security update, but it was still a fun one. From the package description rush is described as:
GNU Rush is a restricted shell designed for sites providing only limited access to resources for remote users. The main binary executable is configurable as a user login shell, intended for users that only are allowed remote login to the system at hand.
As the description says this is primarily intended for use by remote users, but if it is installed locally you can read "any file" on the local system. How? Well the program is setuid(root) and allows you to specify an arbitrary configuration file as input. The very very first thing I tried to do with this program was feed it an invalid and unreadable-to-me configuration file. Helpfully there is a debugging option you can add --lint to help you setup the software. Using it is as simple as:
shelob ~ $ rush --lint /etc/shadow
rush: Info: /etc/shadow:1: unknown statement: root:$6$zwJQWKVo$ofoV2xwfsff...Mxo/:15884:0:99999:7:::
rush: Info: /etc/shadow:2: unknown statement: daemon:*:15884:0:99999:7:::
rush: Info: /etc/shadow:3: unknown statement: bin:*:15884:0:99999:7:::
rush: Info: /etc/shadow:4: unknown statement: sys:*:15884:0:99999:7:::
..
How nice? The only mitigating factor here is that only the first token on the line is reported - In this case we've exposed /etc/shadow which doesn't contain whitespace for the interesting users, so it's enough to start cracking those password hashes. If you maintain a setuid binary you must be trying things like this. If you maintain a setuid binary you must be confident in the codebase. People will be happy to stress-test, audit, examine, and help you - just ask. Simple security issues like this are frankly embarassing. Anyway that's enough: #733505 / CVE-2013-6889.

28 December 2013

Russ Allbery: rra-c-util 5.0

This package started as my collection of shared C utility code and has turned into the collection of all sorts of glue that I use across multiple packages. The primary changes in this release are to the network utility layer. In order to add proper IPv6 support, I adopted the network_bind_* functions to take the socket type, which changed all the APIs (hence the major version bump). While I was at it, I also cleaned up some of the error reporting in the various functions to make them easier to use. There's a new network_wait_any function that does the select part of network_accept_any, making it useful for UDP servers. This release also contains a new, generalized TAP add-on for spawning background processes used by test cases. Their standard output and standard error is now captured and merged into the test output stream using the new C TAP Harness support for files containing diagnostic messages. The remctl TAP add-on has been rewritten to use this framework. Julien LIE also adapted the Autoconf probes for Berkeley DB and zlib used in INN to the framework used for most probes in rra-c-util, and those probes are included in this release. Finally, the vector utility library's free functions now accept (and do nothing with) NULL, which makes it easier to write cleanup functions. You can get the latest release from the rra-c-util distribution page.

27 December 2013

Richard Hartmann: Random rant

Q: What user space program can reliably lock up a Lenovo X1 Carbon with Intel Core i7-3667U, 8 GB RAM, and an Intel SSDSCMMW240A3L so badly that you can't ssh into it any more and ctrl-alt-f1 does not work? So badly that, after half an hour of waiting, the only thing that's left is to shut if off hard. A: Google Chrome with 50+ Flickr tabs open. Q: Why? A: I honestly don't know.

26 December 2013

Ian Campbell: Running ARM Grub on U-boot on Qemu

At the Mini-debconf in Cambridge back in November there was an ARM Sprint (which Hector wrote up as a Bits from ARM porters mail). During this there a brief discussion about using GRUB as a standard bootloader, particularly for ARM server devices. This has the advantage of providing a more "normal" (which in practice means "x86 server-like") as well as flexible solution compared with the existing flash-kernel tool which is often used on ARM. On ARMv7 devices this will more than likely involve chain loading from the U-Boot supplied by the manufacturer. For test and development it would be useful to be able to set up a similar configuration using Qemu. Cross-compilers Although this can be built and run on an ARM system I am using a cross compiler here. I'm using gcc-linaro-arm-linux-gnueabihf-4.8-2013.08_linux from Linaro, which can be downloaded from the linaro-toolchain-binaries page on Launchpad. (It looks like 2013.10 is the latest available right now, I can't see any reason why that wouldn't be fine). Once the cross-compiler has been downloaded unpack it somewhere, I will refer to the resulting gcc-linaro-arm-linux-gnueabihf-4.8-2013.08_linux directory as $CROSSROOT. Make sure $CROSSROOT/bin (which contains arm-linux-gnueabihf-gcc etc) is in your $PATH. Qemu I'm using the version packaged in Jessie, which is 1.7.0+dfsg-2. We need both qemu-system-arm for running the final system and qemu-user to run some of the tools. I'd previously tried an older version of qemu (1.6.x?) and had some troubles, although they may have been of my own making... Das U-boot for Qemu First thing to do is to build a suitable u-boot for use in the qemu emulated environment. Since we need to make some configuration changes we need to build from scratch. Start by cloning the upstream git tree:
$ git clone git://git.denx.de/u-boot.git
$ cd u-boot
I am working on top of e03c76c30342 "powerpc/mpc85xx: Update CONFIG_SYS_FSL_TBCLK_DIV for T1040" dated Wed Dec 11 12:49:13 2013 +0530. We are going to use the Versatile Express Cortex-A9 u-boot but first we need to enable some additional configuration options: You can add all these to include/configs/vexpress_common.h:
#define CONFIG_API
#define CONFIG_SYS_MMC_MAX_DEVICE   1
#define CONFIG_CMD_EXT2
#define CONFIG_CMD_ECHO
Or you can apply the patch which I sent upstream:
$ wget -O - http://patchwork.ozlabs.org/patch/304786/raw   git apply --index
$ git commit -m "Additional options for grub-on-uboot"
Finally we can build u-boot:
$ make CROSS_COMPILE=arm-linux-gnueabihf- vexpress_ca9x4_config
$ make CROSS_COMPILE=arm-linux-gnueabihf-
The result is a u-boot binary which we can load with qemu. GRUB for ARM Next we can build grub. Start by cloning the upstream git tree:
$ git clone git://git.sv.gnu.org/grub.git
$ cd grub
By default grub is built for systems which have RAM at address 0x00000000. However the Versatile Express platform which we are targeting has RAM starting from 0x60000000 so we need to make a couple of modifications. First in grub-core/Makefile.core.def we need to change arm_uboot_ldflags, from:
-Wl,-Ttext=0x08000000
to
-Wl,-Ttext=0x68000000
and second we need make a similar change to include/grub/offsets.h changing GRUB_KERNEL_ARM_UBOOT_LINK_ADDR from 0x08000000 to 0x68000000. Now we are ready to build grub:
$ ./autogen.sh
$ ./configure --host arm-linux-gnueabihf
$ make
Now we need to build the final grub "kernel" image, normally this would be taken care of by grub-install but because we are cross building grub we cannot use this and have to use grub-mkimage directly. However the version we have just built is for the ARM target and not for host we are building things on. I've not yet figured out how to build grub for ARM while building the tools for the host system (I'm sure it is possible somehow...). Luckily we can use qemu to run the ARM binary:
$ cat load.cfg
set prefix=(hd0)
$ qemu-arm -r 3.11 -L $CROSSROOT/arm-linux-gnueabihf/libc \
    ./grub-mkimage -c load.cfg -O arm-uboot -o core.img -d grub-core/ \
    fat ext2 probe terminal scsi ls linux elf msdospart normal help echo
Here we create load.cfg which is the setup script which will be built into the grub kernel, our version just sets the root device so that grub can find the rest of its configuration. Then we use qemu-arm-static to invoke grub-mkimage. The "-r 3.11" option tells qemu to pretend to be a 3.11 kernel (which is required by the libc used by our cross compiler, without this you will get a fatal: kernel too old message) and "-L $CROSSROOT/..." tells it where to find the basic libraries, such as the dynamic linker (luckily grub-mkimage doesn't need much in the way of libraries so we don't need a full cross library environment. The grub-mkimage command passes in the load.cfg and requests an output kernel targeting arm-uboot, core.img is the output file and the modules are in grub-core (because we didn't actually install grub in the target system, normally these would be found in /boot/grub). Lastly we pass in a list of default modules to build into the kernel, including filesystem drivers (fat, ext2), disk drivers (scsi), partition handling (msdos), loaders (linux, elf), the menu system (normal) and various other bits and bobs. So after all the we now have our grub kernel in core.img. Putting it all together Before we can launch qemu we need to create various disk images. Firstly we need some images for the 2 64M flash devices:
$ dd if=/dev/zero of=pflash0.img bs=1M count=64
$ dd if=/dev/zero of=pflash1.img bs=1M count=64
We will initialise these later from the u-boot command line. Secondly we need an image for the root filesystem on an MMC device. I'm using a FAT formatted image here simply for the convenience of using mtools to update the images during development.
$ dd if=/dev/zero of=mmc.img bs=1M count=16
$ /sbin/mkfs.vfat mmc.img
Thirdly we need a kernel, device tree and grub configuration on our root filesystem. For the first two I extracted them from the standard armmp kernel flavour package. I used the backports.org version 3.11-0.bpo.2-armmp version and extracted /boot/vmlinuz-3.11-0.bpo.2-armmp as vmlinuz and /usr/lib/linux-image-3.11-0.bpo.2-armmp/vexpress-v2p-ca9.dtb as dtb. Then I hand coded a simple grub.cfg:
menuentry 'Linux'  
        echo "Loading vmlinuz"
        set root='hd0'
        linux /vmlinuz console=ttyAMA0 ro debug
        devicetree /dtb
 
In a real system the kernel and dtb would be provided by the kernel packages and grub.cfg would be generated by update-grub. Now that we have all the bits we need copy them into the root of mmc.img. Since we are using a FAT formatted image we can use mcopy from the mtools package.
$ mcopy -v -o -n -i mmc.img core.img dtb vmlinuz grub.cfg ::
Finally after all that we can run qemu passing it our u-boot binary and the mmc and flash images and requesting a Cortex-A9 based Versatile Express system with 1GB of RAM:
$ qemu-system-arm -M vexpress-a9 -kernel u-boot -m 1024m -sd mmc.img \
    -nographic -pflash pflash0.img -pflash pflash1.img
Then at the VExpress# prompt we can configure the default bootcmd to load grub and save the environment to the flash images. The backslash escapes (\$ and \;) should be included as written here so that e.g. the variables are only evaluated when bootcmd is evaluated and not immediately when setting bootcmd and the bootm is set as part of bootcmd instead of executed immediately:
VExpress# setenv bootcmd fatload mmc 0:0 \$ loadaddr  core.img \; bootm \$ loadaddr 
VExpress# saveenv
Now whenever we boot the system it will automatically load boot grub from the mmc and launch it. Grub in turn will load the Linux binary and DTB and launch those. I haven't actually configure Linux with a root filesystem here so it will eventually panic after failing to find root. Future work The most pressing issue is the hard coded load address built in to the grub kernel image. This is something which needs to be discussed with the upstream grub maintainers as well as the Debian package maintainers. Now that the ARM packages have hit Debian (in experimental in the 2.02~beta2-1 package) I also plan to start looking at debian-installer integration as well as updating flash-kernel to setup the chain load of grub instead of loading a kernel directly.

Russ Allbery: C TAP Harness 2.4

I always enjoy this time of year: lots of peace and quiet and time to work on whatever I feel like focusing on. That's been watching a lot of speedrunning and League of Legends, but also experimenting with systemd and upstart. I've now ported lbcd to both "properly," meaning that I make full use of their features as far as I currently understand them. I have some more packaging work to do, and need to make a release, but of course I started fixing various other things since I was in the code anyway, and now I don't want to release it without some testing. And that prompted another digression, since I didn't have a good test framework for spawning the server and pounding on it. That finally brings this journal entry to its actual topic: a new release of C TAP Harness. This release adds a new pair of functions, diag_file_add() and diag_file_remove(), which tell the TAP library to take the contents of log files as an additional source of diag() messages. This produces much nicer, and more readable, output from test cases that involve forking a background server that produces output to standard output and standard error. That output can be directed to a file and then included in the test output stream, properly tagged and in sequence with the result messages. You can get the latest release from the C TAP Harness distribution page.

25 December 2013

Michael Stapelberg: Hosting for Debian Code Search provided by Rackspace

For a number of weeks now, I have been forwarding traffic being sent to codesearch.debian.net to an instance of Debian Code Search running at Rackspace s public cloud offering. I feel like it s overdue to announce how they have been supporting the project and what that means. Context First of all, let s provide some context. Debian Code Search was launched in November 2012, hosted entirely on my private server. Since DebConf 13, I am in contact with DSA in order to get Code Search running on a DSA-provided machine and make it an official Debian service. Code Search runs best on flash storage, and only with adequate resources can we enable some use cases (e.g. package-level results) and make sure the existing use cases work at all (we currently have timeouts for some queries). Unfortunately, flash storage is scarce in Debian, hence we couldn t get any for Code Search. At some point, I got the suggestion to ask Rackspace for help, since they are quite friendly to the Open Source community. They agreed to help us out with a generous amount of resources in their public cloud offering! This means I can run Code Search at Rackspace the way it is meant to be run: with the index sharded onto 6 different machines and the source code being searched on fast flash storage. Concerns Now, when using third-party infrastructure, there are always two big concerns: proprietary infrastructure and vendor lock-in. As for the proprietary aspect, Rackspace s public cloud offering is based on OpenStack, which is FOSS. Granted, they have a couple of extensions that are not (yet?) released in OpenStack, but those are minor details and any automation that we use can trivially be ported to any other OpenStack offering. Who knows, maybe in the future we use OpenStack in Debian, too? Given the OpenStack situation, I am not concerned about vendor lock-in. However, to specifically address this concern and err on the side of caution, attention will be paid to keep Code Search able to run on non-cloud infrastructure, such that we can run our own instance on DSA-provided hardware. My current intention is that this instance will be the fall-back that we can use should there ever be problems with Rackspace. So far, however, I am very happy with Rackspace s stability. Future There are a number of improvements waiting: for users in the United States, traffic first goes to my server in Europe and then back to Rackspace in the US. Eventually, we should get rid of this indirection. Perhaps we can also spin up another instance in Europe eventually. Furthermore, Rackspace recently announced new available hardware, which we are not yet making use of. I expect a big speed-up, but will have to do some careful benchmarking. Also, I have some interesting performance data, which will be shared in subsequent blog posts. Stay tuned :). Conclusion I d like to thank Rackspace very much for their generous support of the Debian project and Code Search in particular. I hope you look forward to the upcoming posts with more details. Also, to be perfectly clear about it: I also thank DSA for their help, and hope they will continue working with me to have our independent (yet slower) instance of Code Search running on Debian hardware.

23 December 2013

B lint R czey: Introducing XBMC from Debian

available from unstable, and hopefully soon from testing, too! The longer story: The xbmc package has been uninstallable and unbuildable in Debian unstable for quite some time. Mainly due to differing preferences of the XBMC project and Debian. Original XBMC source includes several embedded libraries, some patched to work with XBMC perfectly and to provide the best user experience the XBMC project prefers building XBMC with those libraries. In Debian, on the other hand, the recommended practice is not embedding libraries, but using the packaged versions instead to reduce the amount of security updates in case a library needs a security related fix, to save space on mirrors and to avoid divergence between the embedded versions of the libraries. One consequence of using externally packaged libraries is the need for making XMBC work with newer versions of the external libraries even when the embedded one would still work perfectly or (in some cases) there are even breakages due to changing APIs or new bugs in the library. XBMC depends on many libraries and the changes to them in Debian used to break one or another XBMC use case from time to time. The XBMC project received many direct bug reports from users of the Debian-shipped XBMC package which were harder than necessary to handle due to the lack of clear differentiation from the .deb packages provided directly by
them and using the embedded libraries. To help both users and developers the xbmc package starts using the XBMC from Debian name on the main screen and in the logs, the version number used inside the application is set to the Debian package s version, and README.Debian directs users of the package to Debian s BTS instead of XBMC s forums. The most notable difference between XBMC and XBMC from Debian is that XBMC uses
its embedded patched FFmpeg, while XBMC from Debian uses libav. If movies play too slow, too fast, without sound or too loud, you should definitely check BTS first. ;-) Happy Holidays and don t stay too much in front of the screen if XBMC from Debian happens to work for hours without any crash! :-)

Russell Coker: The Nexus 5

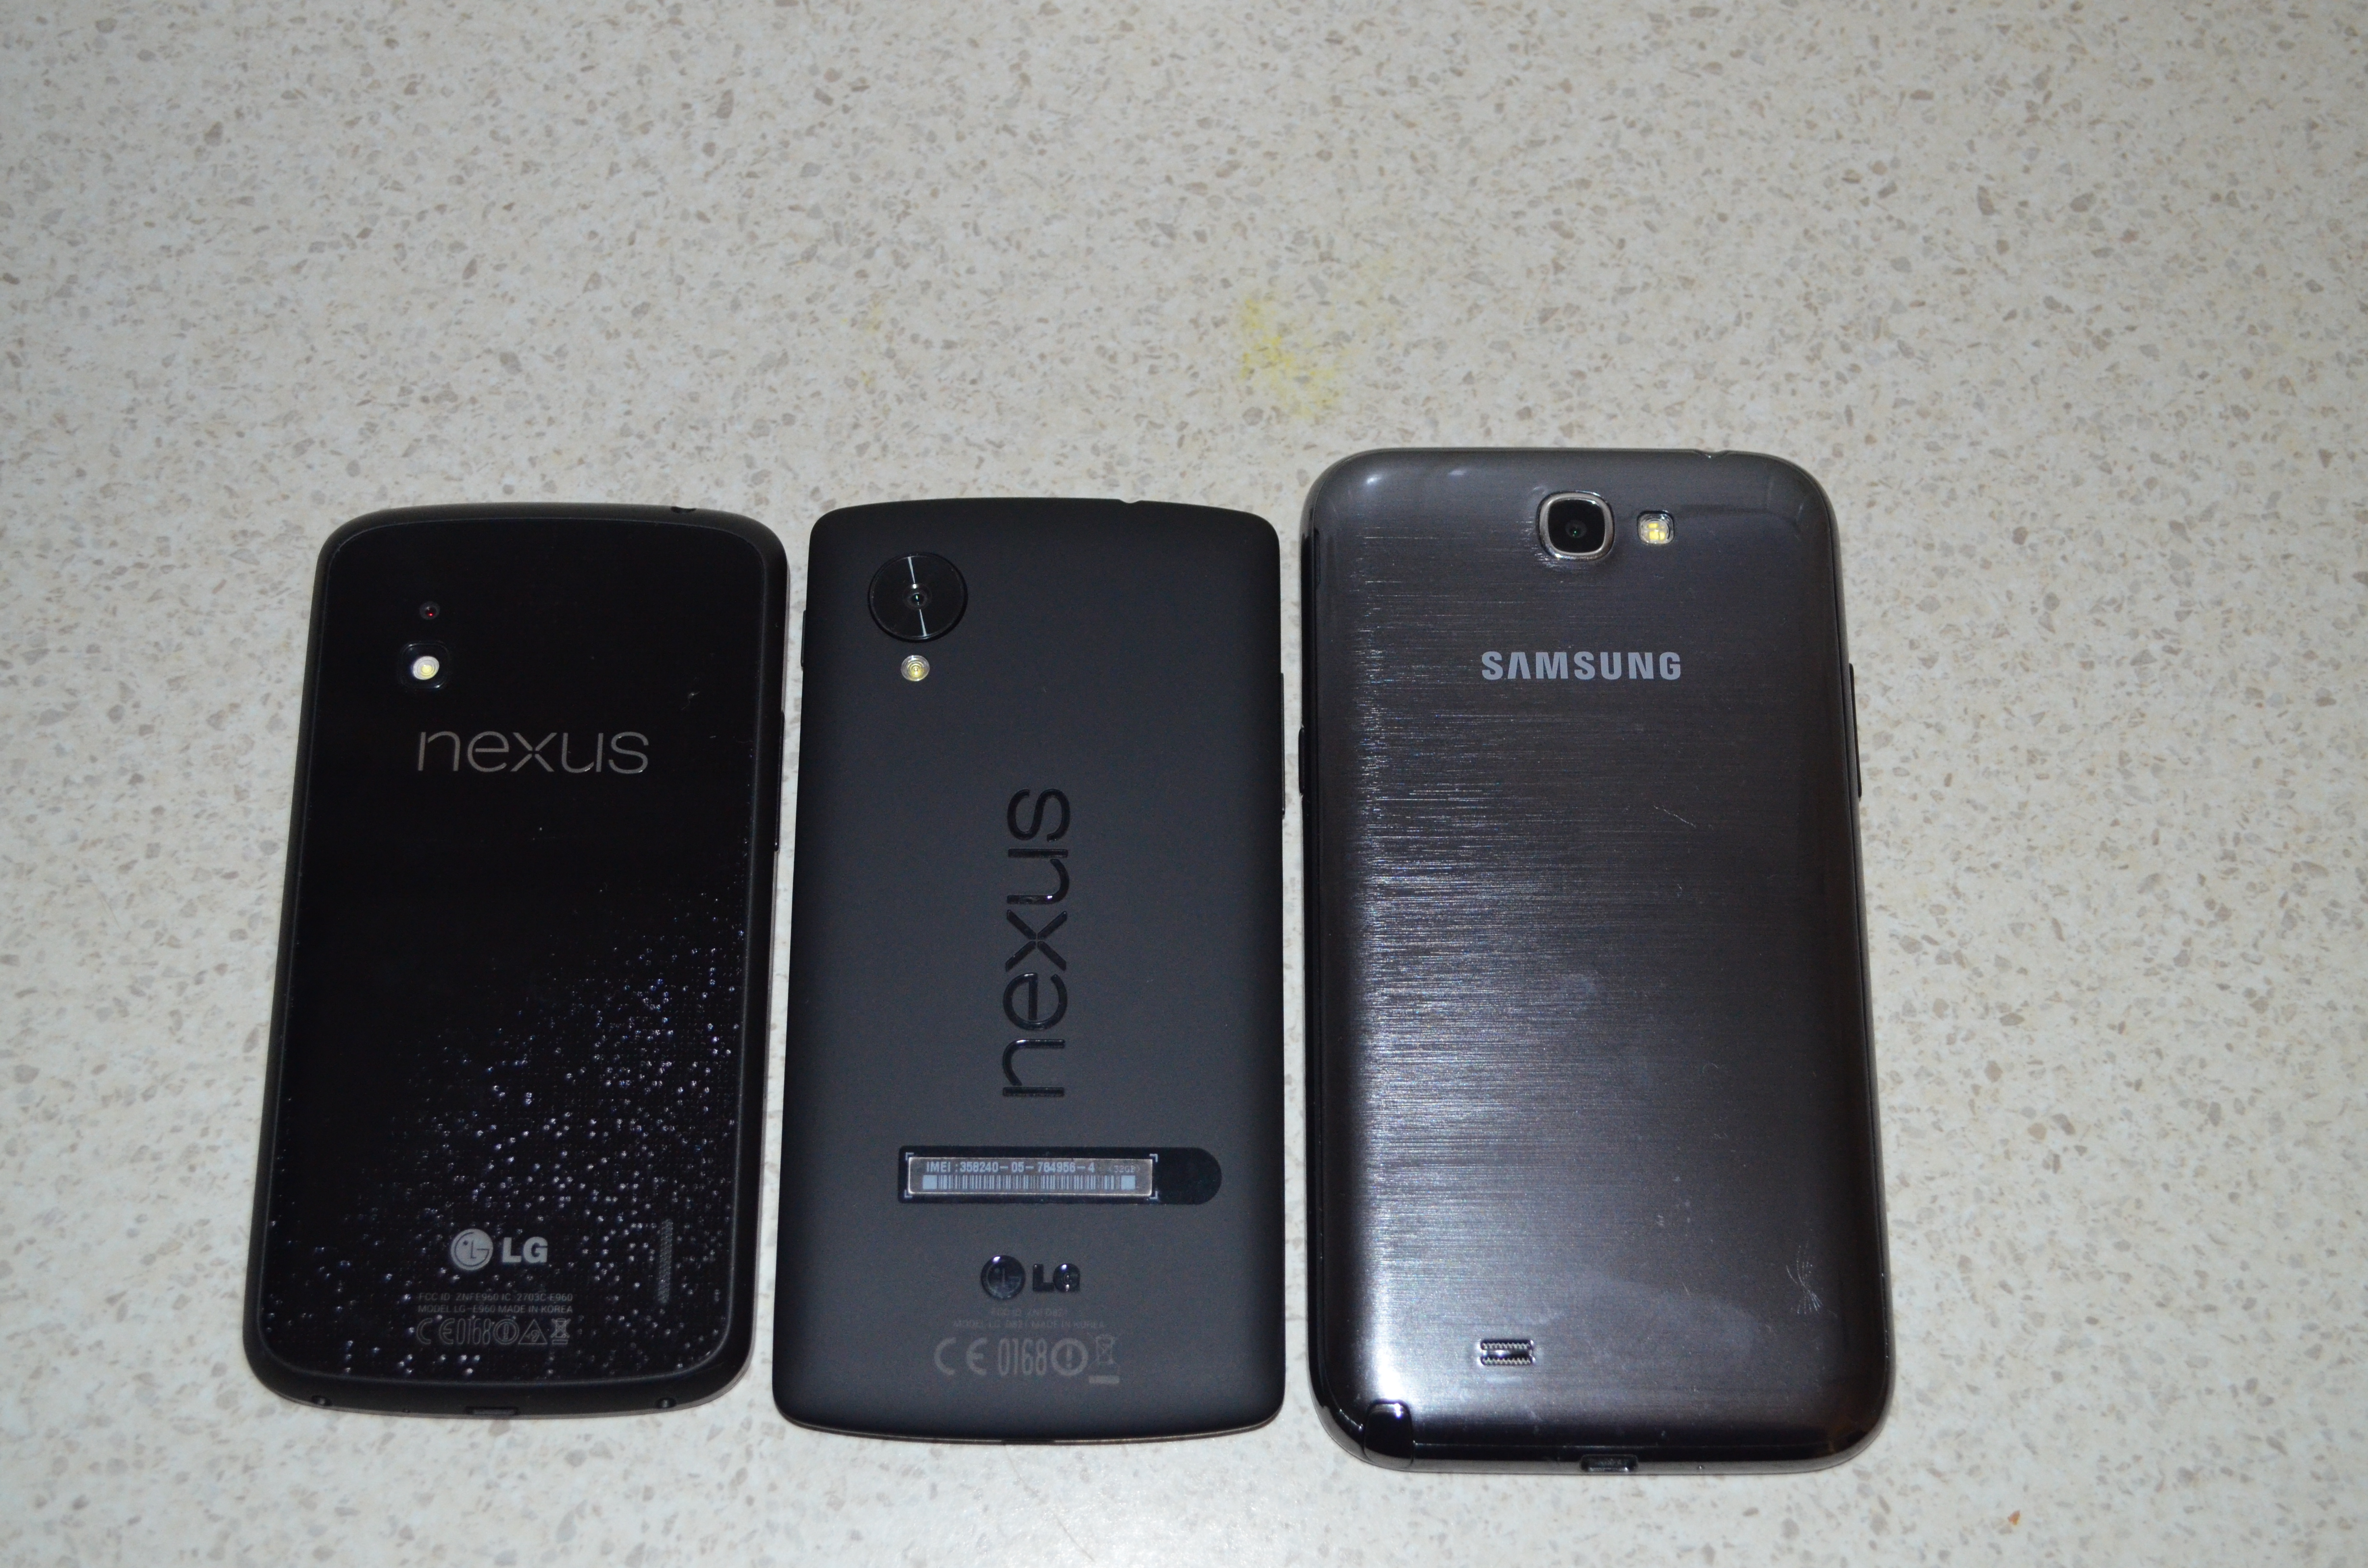
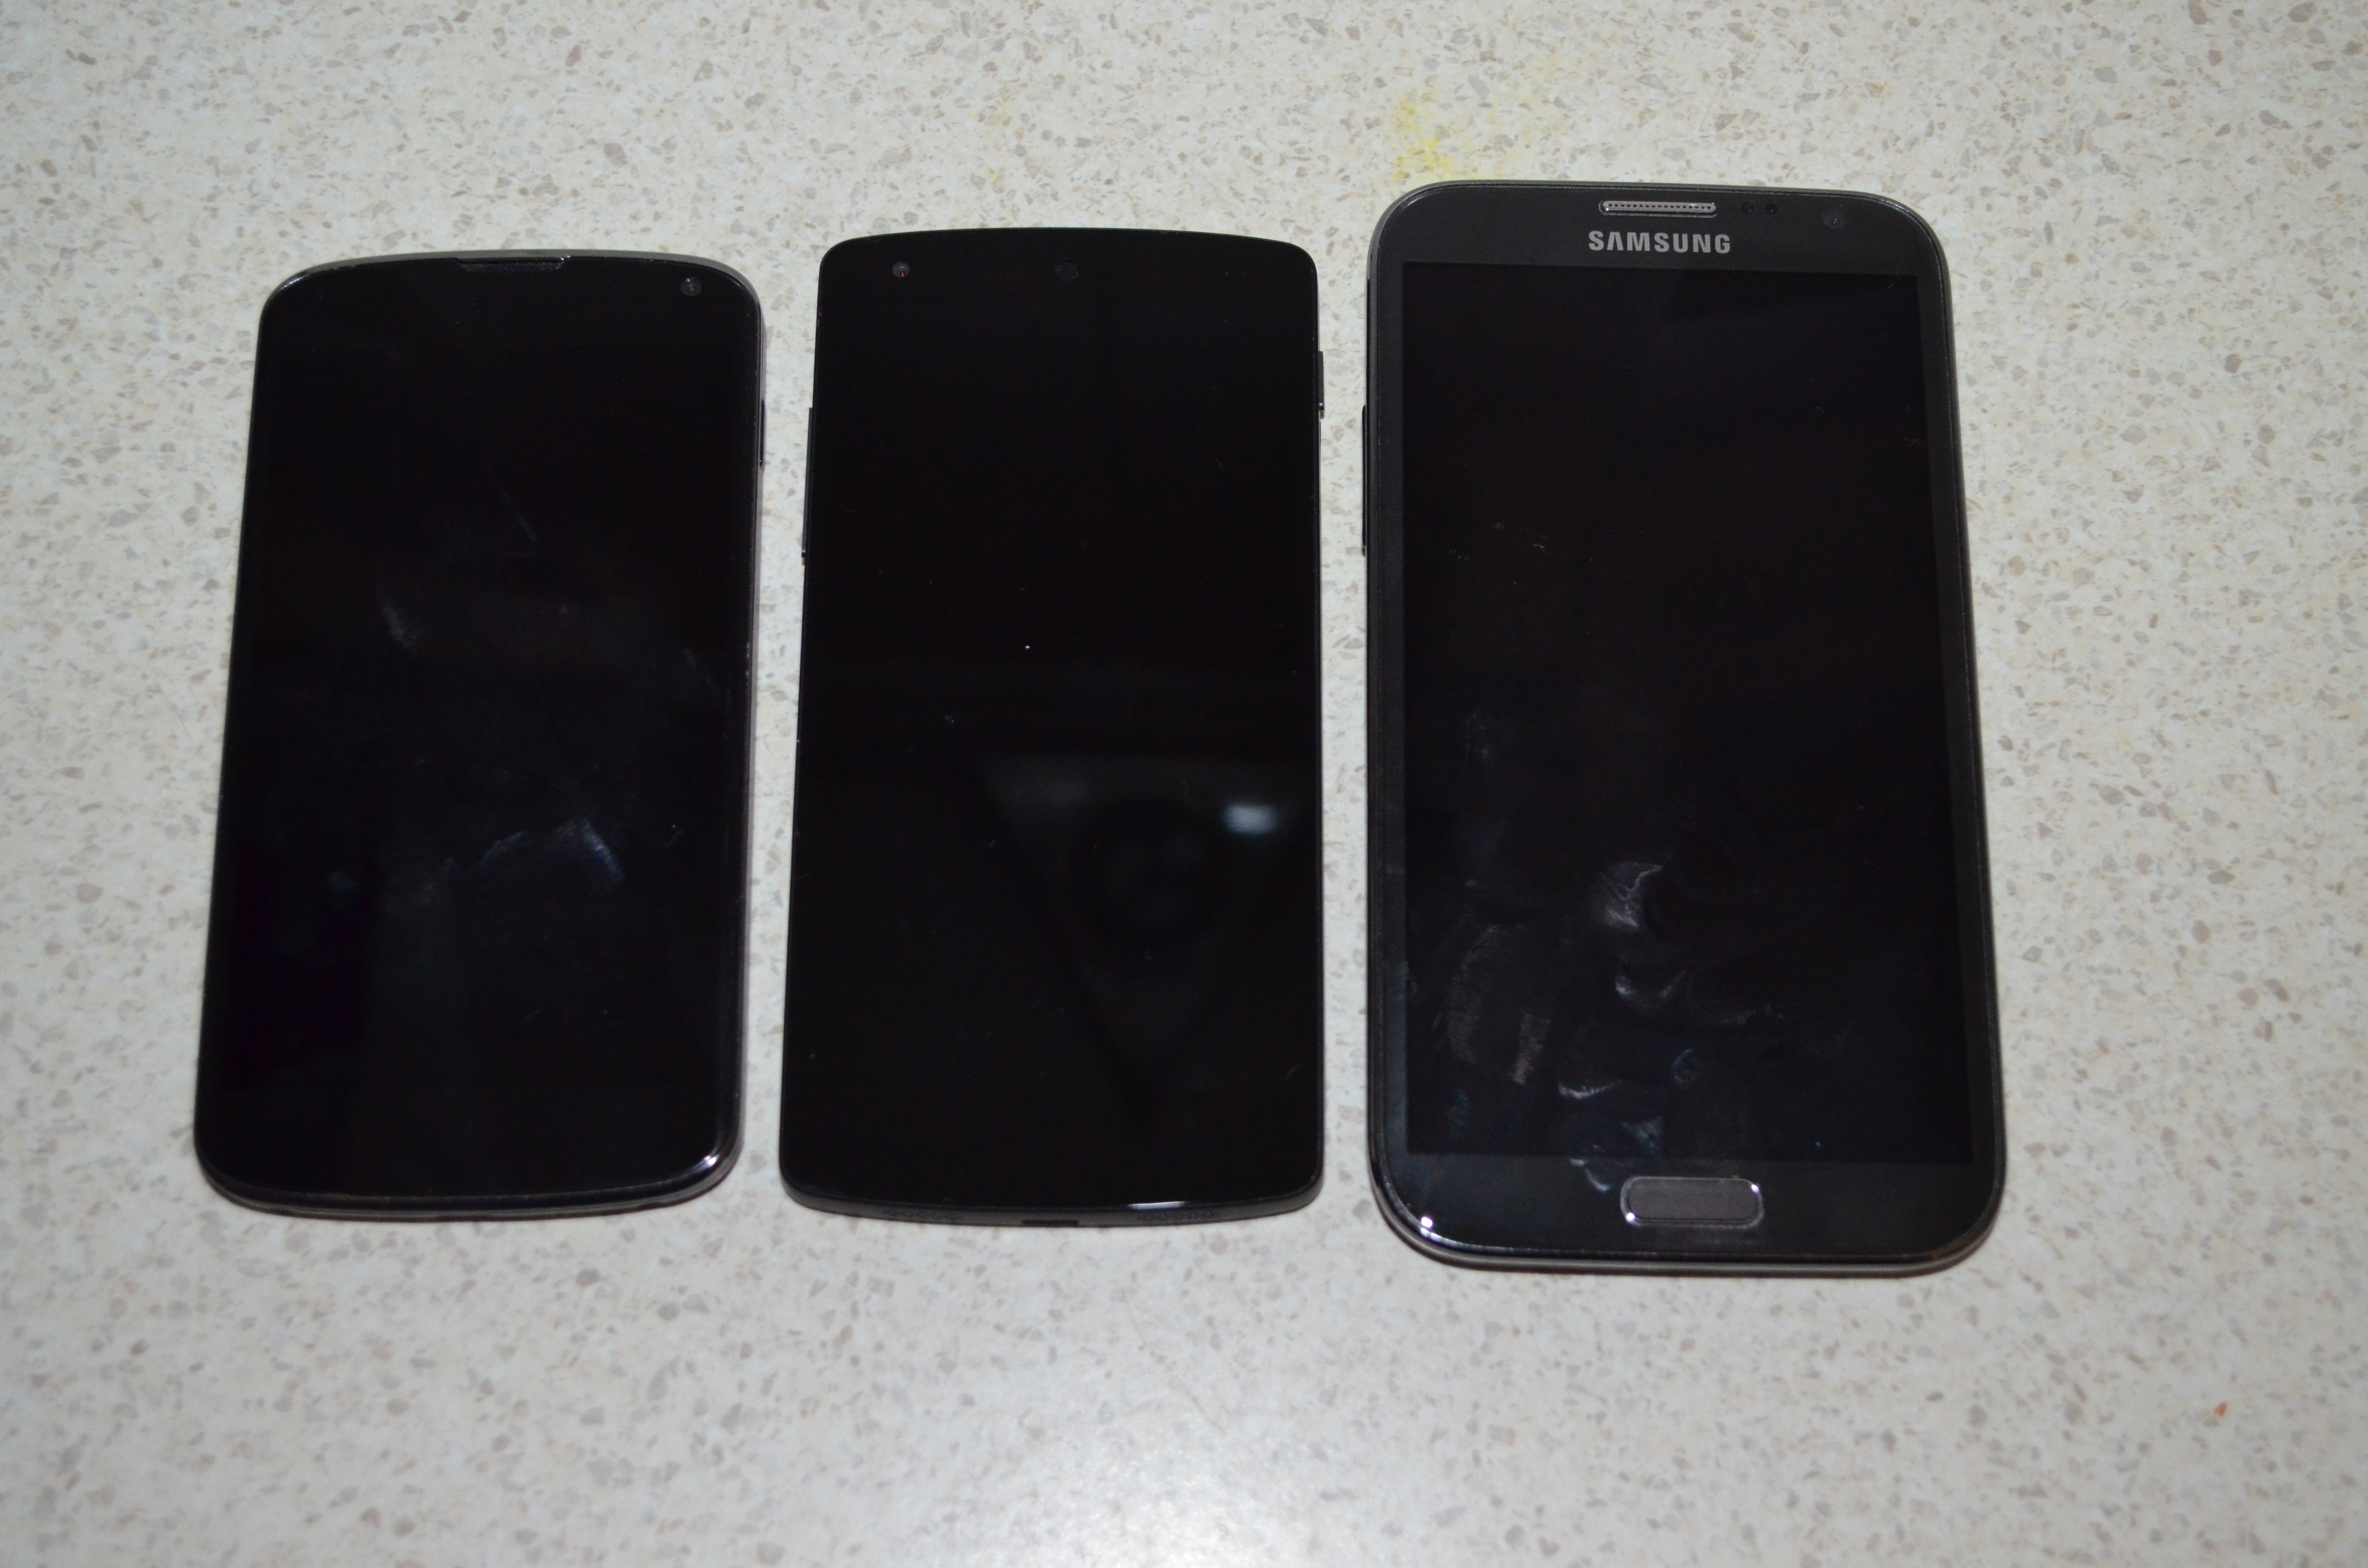
The Nexus 5 is the latest Android phone to be endorsed by Google (and manufactured by LG). It s getting good reviews and the price is good for the specs. I just bought one for my wife, I got her the 32G version because when I bought her a Nexus 4 at the start of the year [1] I chose the 8G version and regretted it ever since. The size of apps is always increasing (some Android games need more than 1G of storage) and higher resolution screens drives the use of high resolution video. Appearance back of Nexus 4, Nexus 5, and Samsung Galaxy Note 2front of Nexus 4, Nexus 5, and Samsung Galaxy Note 2 Above I have pictures of the Nexus 4, the Nexus 5, and the Samsung Galaxy Note 2. The photo of the phone backs captures part of the sparkling pattern on the back of the Nexus 4 and it looks much better in real life (IMHO) because it shimmers as you move the phone. The Nexus 4 looks so good that there s even a transparent case specifically designed to show off the rear panel [2]. It doesn t seem likely that anyone will design such a transparent case for the Nexus 5, it s a good phone to cover up IMHO. The Note 2 isn t the most attractive phone, but I think it has a streamlined elegance of being optimised for it s function. The Nexus 5 has it s camera sticking out, it would be better if they had just made the entire phone thicker and given it a bigger battery but for people who don t want good battery life I guess it s a way of providing a better focal length without making the phone thicker. Sticking the IMEI number on the back of the phone will be useful on rare occasions (and might be a security issue on more occasions) but it definitely makes the phone less attractive. Full HD The quality of the Full HD (1920*1080) display is obvious. The text is slightly clearer when viewing maps and the graphics in Ingress look nicer. Before I used the Nexus 5 I didn t think that there would be any benefit in having such a high resolution in a phone but now I realise that I was wrong. The higher resolution is clearly better. Chris Chavez wrote an article for Phandroid about a rumored Samsung phone with a 2560*1440 display [3]. If such a device had a 6.6 display (IE a new version of the Galaxy Mega) then it would have the same dot-pitch as the Nexus 5. If such a device had a 5.5 display (like the Galaxy Note 3) then it would have a 15% greater DPI than the Nexus 5. It seems that a higher DPI provides a real benefit and this is probably the biggest reason to choose the Nexus 5 over the Nexus 4 and most other Android devices. Comparing with the Nexus 4 The Nexus 5 has the same amount of RAM (2G), a slightly larger display (4.95 vs 4.7 ), higher resolution (a big deal), faster CPU and GPU, and optical zoom. Faster CPU isn t usually going to be a big deal (apart from the fact that more CPU power is needed as well as more GPU power to drive the higher resolution display). The Nexus 5 can come with 16G or 32G of storage while the Nexus 4 has options of 8G and 16G. If you want more than 16G of storage then that s a real benefit for the Nexus 5, but if you only need 16G then it s not an issue. It seems that when playing Ingress on a Nexus 5 it s more likely that running another program (such as Google Hangouts) will cause Ingress to be reloaded than it does on a Nexus 4 or a Galaxy Note 2. While I haven t done a good comparison of the Nexus 4 and the Nexus 5 in this regard I ve compared the Galaxy Note 2 and the Nexus 5 well. My Galaxy Note 2 (which has many daemons running) is much less likely to cause a reload of Ingress (IE have run low on memory and terminated Ingress) than the Nexus 5 my wife is using (which has very little running). So it seems that the OS build on the Nexus 5 uses more memory than the Galaxy Note 2. The Nexus 5 has Gorilla Glass 3 vs Gorilla Glass 2 on the Nexus 4. As my older Android phones with Gorilla Glass 1 (Galaxy S and Sony Ericsson Xperia X10i) didn t get any scratches that matter I don t think this is a benefit for me. Maybe if I lived near a beach I d care more about this. I think that the most significant benefit of the Nexus 5 over the Nexus 4 is the higher resolution display. The optical zoom should provide a theoretical benefit when taking photos, whether that results in better pictures in practice would probably depend on how you hold your phone, the available light, and other factors. I think that if it was possible to buy a Nexus 4 at a sensible price (IE something less than the $250 that Google last charged) then for most people the Nexus 4 would be a better choice than the Nexus 5. But as ebay is full of Nexus 4 phones selling for a higher prices than the Nexus 5 it seems that buying a Nexus 5 is the only option. The range of phones that Kogan sells [4] doesn t have anything for the same price that compares on features. Heat The heat produced by the Nexus 5 is significant and noticable. After some light Ingress playing on a cold day my Galaxy Note 2 with a gel case (that keeps it warm) reported itself as having a battery temperature of 34C. My wife s Nexus 5 reported a temperature of 43C. While the thermometer in the phone might not be the most accurate I don t think there was an accuracy problem, holding my wife s phone was unpleasant and felt like it could burn my hand if I held it tight (40C is the minimum temperature for burns). It seems that a Nexus 5 isn t a good choice if you want to play Ingress in a warm part of the world (EG most of Australia in summer). Also heat dissipated is directly proportional to power use which is going to be a problem for a phone that doesn t permit replacing it s battery. Conclusion I m quite disappointed with the Nexus 5. I expected it to be at least as good as the Nexus 4 in every way and better in many ways. Instead it s not always as good as the Nexus 4 and the ways that it is better won t necessarily provide benefits for everyone. The heat and power use problems are really going to hurt the use of it. But I guess we can always hope that Google release a new Android build that reduces the power use, they might even have a new build that uses less RAM too. I would not consider getting a Nexus 5 for my own use. For my use the Note 2 is clearly more suitable, the larger screen more than compensates for the clarity that the Nexus 5 gets from it s high resolution display. Also I REALLY like having a hardware home button. I ll probably get a Note 3 when the price drops, I m not interested in paying $649 for a phone and I m also not interested in replacing a phone that s less than a year old. So maybe I ll get a Note 3 in the second half of next year.

22 December 2013

Francois Marier: Creating a Linode-based VPN setup using OpenVPN on Debian or Ubuntu

Using a Virtual Private Network is a good way to work-around geoIP restrictions but also to protect your network traffic when travelling with your laptop and connecting to untrusted networks. While you might want to use Tor for the part of your network activity where you prefer to be anonymous, a VPN is a faster way to connect to sites that already know you. Here are my instructions for setting up OpenVPN on Debian / Ubuntu machines where the VPN server is located on a cheap Linode virtual private server. They are largely based on the instructions found on the Debian wiki. An easier way to setup an ad-hoc VPN is to use sshuttle but for some reason, it doesn't seem work on Linode or Rackspace virtual servers.

Generating the keys Make sure you run the following on a machine with good entropy and not a VM! I personally use a machine fitted with an Entropy Key. The first step is to install the required package:
sudo apt-get install openvpn
Then, copy the following file in your home directory (no need to run any of this as root):
mkdir easy-rsa
cp -ai /usr/share/doc/openvpn/examples/easy-rsa/2.0/ easy-rsa/
cd easy-rsa/2.0
and put something like this in your ~/easy-rsa/2.0/vars:
export KEY_SIZE=2084
export KEY_COUNTRY="NZ"
export KEY_PROVINCE="AKL"
export KEY_CITY="Auckland"
export KEY_ORG="fmarier.org"
export KEY_EMAIL="francois@fmarier.org"
export KEY_CN=hafnarfjordur.fmarier.org
export KEY_NAME=hafnarfjordur.fmarier.org
export KEY_OU=VPN
Create this symbolic link:
ln -s openssl-1.0.0.cnf openssl.cnf
and generate the keys:
. ./vars
./clean-all
./build-ca
./build-key-server server  # press ENTER at every prompt, no password
./build-key akranes  # "akranes" as Name, no password
./build-dh
/usr/sbin/openvpn --genkey --secret keys/ta.key

Configuring the server On my server, a Linode VPS called hafnarfjordur.fmarier.org, I installed the openvpn package:
apt-get install openvpn
and then copied the following files from my high-entropy machine:
cp ca.crt dh2048.pem server.key server.crt ta.key /etc/openvpn/
chown root:root /etc/openvpn/*
chmod 600 /etc/openvpn/ta.key /etc/openvpn/server.key
Then I took the official configuration template:
cp /usr/share/doc/openvpn/examples/sample-config-files/server.conf.gz /etc/openvpn/
gunzip /etc/openvpn/server.conf.gz
and set the following in /etc/openvpn/server.conf:
dh dh2048.pem
push "redirect-gateway def1 bypass-dhcp"
push "dhcp-option DNS 74.207.241.5"
push "dhcp-option DNS 74.207.242.5"
tls-auth ta.key 0
cipher AES-128-CBC
user nobody
group nogroup
(These DNS servers are the ones I found in /etc/resolv.conf on my Linode VPS.) Finally, I added the following to these configuration files:
  • /etc/sysctl.conf:
    net.ipv4.ip_forward=1
    
  • /etc/rc.local (just before exit 0):
    iptables -t nat -A POSTROUTING -s 10.8.0.0/24 -o eth0 -j MASQUERADE
    
  • /etc/default/openvpn:
    AUTOSTART="all"
    
and ran sysctl -p before starting OpenVPN:
/etc/init.d/openvpn start
If the server has a firewall, you'll need to open up this port:
iptables -A INPUT -p udp --dport 1194 -j ACCEPT

Configuring the client The final piece of this solution is to setup my laptop, akranes, to connect to hafnarfjordur by installing the relevant Network Manager plugin:
apt-get install network-manager-openvpn-gnome
The laptop needs these files from the high-entropy machine:
cp ca.crt akranes.crt akranes.key ta.key /etc/openvpn/
chown root:francois /etc/openvpn/akranes.key /etc/openvpn/ta.key
chmod 640 /etc/openvpn/ta.key /etc/openvpn/akranes.key
and my own user needs to have read access to the secret keys. To create a new VPN, right-click on Network-Manager and add a new VPN connection of type "OpenVPN":
  • Gateway: hafnarfjordur.fmarier.org
  • Type: Certificates (TLS)
  • User Certificate: /etc/openvpn/akranes.crt
  • CA Certificate: /etc/openvpn/ca.crt
  • Private Key: /etc/openvpn/akranes.key
  • Available to all users: NO
then click the "Avanced" button and set the following:
  • General
    • Use LZO data compression: YES
  • Security
    • Cipher: AES-128-CBC
    • HMAC Authentication: Default
  • TLS Authentication
    • Subject Match: server
    • Verify peer (server) certificate usage signature: YES
    • Remote peer certificate TLS type: Server
    • Use additional TLS authentication: YES
    • Key File: /etc/openvpn/ta.key
    • Key Direction: 1

Debugging If you run into problems, simply take a look at the logs while attempting to connect to the server:
tail -f /var/log/syslog
on both the server and the client. In my experience, searching for the error messages you find in there is usually enough to solve the problem.

Next steps The next thing I'm going to add to this VPN setup is a local unbound DNS resolver that will be offered to all clients. Is there anything else you have in your setup and that I should consider adding to mine?

21 December 2013

Kees Cook: DOM scraping

For a long time now I ve used mechanize (via either Perl or Python) for doing website interaction automation. Stuff like playing web games, checking the weather, or reviewing my balance at the bank. However, as the use of javascript continues to increase, it s getting harder and harder to screen-scrape without actually processing DOM events. To do that, really only browsers are doing the right thing, so getting attached to an actual browser DOM is generally the only way to do any kind of web interaction automation. It seems the thing furthest along this path is Selenium. Initially, I spent some time trying to make it work with Firefox, but gave up. Instead, this seems to work nicely with Chrome via the Chrome WebDriver. And even better, all of this works out of the box on Ubuntu 13.10 via python-selenium and chromium-chromedriver. Running /usr/lib/chromium-browser/chromedriver2_server from chromium-chromedriver starts a network listener on port 9515. This is the WebDriver API that Selenium can talk to. When requests are made, chromedriver2_server spawns Chrome, and all the interactions happen against that browser. Since I prefer Python, I avoided the Java interfaces and focused on the Python bindings:
#!/usr/bin/env python
import sys
from selenium import webdriver
from selenium.common.exceptions import NoSuchElementException
from selenium.webdriver.common.keys import Keys
caps = webdriver.DesiredCapabilities.CHROME
browser = webdriver.Remote("http://localhost:9515", caps)
browser.get("https://bank.example.com/")
assert "My Bank" in browser.title
try:
    elem = browser.find_element_by_name("userid")
    elem.send_keys("username")
    elem = browser.find_element_by_name("password")
    elem.send_keys("wheee my password" + Keys.RETURN)
except NoSuchElementException:
    print "Could not find login elements"
    sys.exit(1)
assert "Account Balances" in browser.title
xpath = "//div[text()='Balance']/../../td[2]/div[contains(text(),'$')]"
balance = browser.find_element_by_xpath(xpath).text
print balance
browser.close()
This would work pretty great, but if you need to save any state between sessions, you ll want to be able to change where Chrome stores data (since by default in this configuration, it uses an empty temporary directory via --user-data-dir=). Happily, various things about the browser environment can be controlled, including the command line arguments. This is configurable by expanding the desired capabilities variable:
caps = webdriver.DesiredCapabilities.CHROME
caps["chromeOptions"] =  
        "args": ["--user-data-dir=/home/user/somewhere/to/store/your/session"],
     
A great thing about this is that you get to actually watch the browser do its work. However, in cases where this interaction is going to be fully automated, you likely won t have a Xorg session running, so you ll need to wrap the WebDriver in one (since it launches Chrome). I used Xvfb for this:
#!/bin/bash
# Start WebDriver under fake X and wait for it to be listening
xvfb-run /usr/lib/chromium-browser/chromedriver2_server &
pid=$!
while ! nc -q0 -w0 localhost 9515; do
    sleep 1
done
the-chrome-script
rc=$?
# Shut down WebDriver
kill $pid
exit $rc
Alternatively, all of this could be done in the python script too, but I figured it s easier to keep the support infrastructure separate from the actual test script itself. I actually leave the xvfb-run call external too, so it s easier to debug the browser in my own X session. One bug I encountered was that the WebDriver s cache of the browser s DOM can sometimes get out of sync with the actual browser s DOM. I didn t find a solution to this, but managed to work around it. I m hoping later versions fix this. :)

2013, Kees Cook. This work is licensed under a Creative Commons Attribution-ShareAlike 3.0 License.
Creative Commons License

20 December 2013

Riku Voipio: Replicant on Galaxy S3

I recently got my self and Galaxy S3 for testing out Replicant, an android image made out of only open source components. Why Galaxy S3? It is well supported in Replicant, almost every driver is already open source. The hardware specs are acceptable, 1.4Ghz quad core, 1GB ram, microsd, and all the peripheral chips one expects for a phone. Galaxy S3 has sold insanely (50 million units supposedly), meaning I won't run out of accessories and aftermarket spare parts any time soon. The massive installed base also means a huge potential user community. S3 is still available as new, with two years of warranty. Why notWhile the S3 is still available new, it is safe to assume production is ending already - 1.5 year old product is ancient history in mobile world! It remains to be seen how much the massive user base will defend against the obsolescence. Upstream kernel support for "old" cpu is open question, replicant is still basing kernel on vendor kernel. Bootloader is unlocked, but it can't be changed due to trusted^Wtreacherous computing, preventing things like boot from sd card. Finally, not everything is open source, the GPU (mali) driver while being reverse engineered, is taking it's time - and the GPS hasn't been reversed yet. Installing replicant Before install, from the original installation, you might want to take a copy of firmware files (since replicant won't provide them). enable developer mode on the S3 and:
sudo apt-get install android-tools
mkdir firmware
adb pull /system/vendor/firmware/
adb pull /system/etc/wifi
After then, just follow official replicant install guide for S3. If you don't mind closed source firmwares, post-install you need to push the firmware files back:

adb shell
mount -o remount,rw /system
adb push . /system/vendor/firmware
Here was my first catch, the wifi firmwares from jelly bean based image were not compatible with older ICS based replicant. Using replicant
Booting to replicant is fast, few seconds to the pin screen. You are treated with the standard android lockscreen, usual slide/pin/pattern options are available. Basic functions like phone, sms and web browsing have icons from the homescreen and work without a hitch. Likewise camera seems to work, really the only smartphone feature missing is GPS. Sidenote - this image looks a LOT better on the S3 than on my thinkpad. No wonder people are flocking to phones and tablets when laptop makers use such crappy components.
The grid menu has the standard android AOSP opensource applications in the ICS style menu with the extra of f-droid icon - which is the installer for open source applications. F-droid is it's own project that complements replicant project by maintaining a catalog of Free Software.
F-droid brings hundreds of open source applications not only for replicant, but for any other android users, including platforms with android compatibility, such as Jolla's Sailfish OS. Of course f-droid client is open source, like the f-droid server (in Debian too). F-droid server is not just repository management, it can take care of building and deploying android apps.
The WebKit based android browser renders web sites without issues, and if you are not happy with, you can download Firefox from f-droid. Many websites will notice you are mobile, and provide mobile web sites, which is sometimes good and sometimes annoying. Worse, some pages detect you are android and only offer you to load their closed android app for viewing the page. OTOH I am already viewing their closed source website, so using closed source app to view it isn't much worse. This keyboard is again the android standard one, but for most unixy people the hacker's keyboard with arrow buttons and ctrl/alt will probably be the one you want. Closing thoughts While using replicant has been very smooth, the lack of GPS is becoming a deal-breaker. I could just copy the gpsd from cyanogen, like some have done, but it kind of beats the purpose of having replicant on the phone. So it might be that I move back to cyanogen, unless I find time to help reverse engineering the BCM4751 GPS.

Christoph Egger

Greetings from the FAU Security Team (FAUST), the Uni Erlangen CTF group. We were participating in the RuCTFe competition and made it to 4th place. Following is my write-up on the nsaless service, the main crypto challenge in the competition. nsaless is a nodejs webservice providing a short message service. People can post messages and their followers receive the message encrypted to their individual RSA key.

About the gameserver protocol
The gameserver created groups of 8 users on the service 7 were just following the first user (and authorized by the first user to do so) while the first user sent a tweet containing the flag. The service used 512bit RSA with 7 as public exponent. While RSA512 is certainly weak, it's strong enough to make it unfeasible to break directly.

Attacking RSA
There are some known attacks against RSA with small exponents if no proper padding is done. The most straightforward version just takes the e-th root of the cipher-text and, if the clear message was small enough, outputs that root as plain-text. As the flag was long enough to make this attack impossible, we need a somewhat improved Attack.

H stad's Broadcast Attack
Reminder:
  • In RSA, given a plain-text A, the sender computes A mod N to build the cipher-text B.
  • Given simultaneous congruences we can efficiently compute a x such that x satisfies all congruences using the Chinese remainder theorem.
For NSAless we actually get several such B for different N (each belonging to different users receiving the tweet because they follow the poster). This effectively means we get A in mod N for different N. Using the Chinese remainder theorem we can now compute a x A mod N . If we use at least e different B for this we are guaranteed that x actually equals A (in ): A needs to be smaller than N for all N used (otherwise we lose information during encryption), therefore A needs to be smaller than N . Computing now the e-th root of x we get the plain-text A the flag.

Fix
Fixing your service is easy enough, just increase e to an suitable number > 8. At the end of the contest 5 Teams had fixed this vulnerability by either using 17 or 65537.

EXPLOIT
The basic exploit is shown below. Unfortunately it needs to retrieve all tweets for all users the compute the flags which just takes too long to be feasible (at least at the end of the competition where tons of users already existed) so you would need some caching to make it actually work. Would have been a great idea to have users expire after an hour or two in the service!
#!/usr/bin/python
import httplib
import urllib
import re
import json
import pprint
import gmpy
import sys
userparse_re = re.compile('<a [^>]*>([^<]*)</a></div>\s*<div>([^<]*)</div>')
tweetparse_re = re.compile("<div id='last_tweet'>([0-9]+)</div>")
followingparse_re = re.compile('<div><a href="/[0-9]+">([0-9]+)</a></div>')
def my_parse_number(number):
    string = "%x" % number
    if len(string) != 64:
        return ""
    erg = []
    while string != '':
        erg = erg + [chr(int(string[:2], 16))]
        string = string[2:]
    return ''.join(erg)
def extended_gcd(a, b):
    x,y = 0, 1
    lastx, lasty = 1, 0
    while b:
        a, (q, b) = b, divmod(a,b)
        x, lastx = lastx-q*x, x
        y, lasty = lasty-q*y, y
    return (lastx, lasty, a)
def chinese_remainder_theorem(items):
  N = 1
  for a, n in items:
    N *= n
  result = 0
  for a, n in items:
    m = N/n
    r, s, d = extended_gcd(n, m)
    if d != 1:
      raise "Input not pairwise co-prime"
    result += a*s*m
  return result % N, N
def get_tweet(uid):
    try:
        conn = httplib.HTTPConnection("%s:48879" % sys.argv[1], timeout=60)
        conn.request("GET", "/%s" % uid)
        r1 = conn.getresponse()
        data = r1.read()
        tweet = re.findall(tweetparse_re, data)
        if len(tweet) != 1:
            return None
        followers = re.findall(followingparse_re, data)
        return tweet[0], followers
    except:
        return None
def get_users():
    conn = httplib.HTTPConnection("%s:48879" % sys.argv[1], timeout=60)
    conn.request("GET", "/users")
    r1 = conn.getresponse()
    data1 = r1.read(1024 * 1024)
    data = dict()
    for i in re.findall(userparse_re, data1)[:100]:
        userinfo = get_tweet(i[0])
        if userinfo != None:
            data[i[0]] = (json.loads(i[1].replace('&quot;', '"'))['n'], userinfo)
    return data
users = get_users()
allusers = users.keys()
masters = [ user for user in allusers if len(users[user][1][1]) > 0 ]
for test in masters:
    try:
        followers = users[test][1][1]
        data = []
        for fol in followers:
            n = int(users[fol][0])
            tweet = int(users[fol][1][0])
            data = data + [(tweet, n)]
        x, n = chinese_remainder_theorem(data)
        realnum = gmpy.mpz(x).root(7)[0].digits()
        print my_parse_number(int(realnum))
    except:
        pass

18 December 2013

Ingo Juergensmann: Debian donation to m68k arrived

The Debian m68k port has been entitled by the DPL to receive a donation of five memory expansion cards for the m68k autobuilders. The cards arrived two weeks ago and are now being shipped to the appropriate buildd admins. Adding those 256 MB memory expansion will have a huge effect to the m68k buildds, because most of them are Amigas that are currently running with "just" 128 MB. The problem with those expansion cards is to make use of them. Sounds strange but this is the story behind it.... Those memory expansion cards, namely it is the BigRamPlus from Individual Computers, are Zorro III bus cards, which has some speed limitations. The Amiga memory model is best described in the Amiga Hardware Reference Manual. For Zorro III based Amigas this is described in the section "A3000 memory map", where you can see that the memory model is divided into different address space. The most important address space is the "Coprocessor Slot Expansion" space, starting at $0800 0000. This is where the memory on the CPU accelerator cards will be found and which runs at full CPU speed. The BigRamPlus, however, is located within "Zorro III Expansion" address space at $1000 0000 and will have transfer rates of about 13 MB/s. Then again there's still the motherboard expansion memory and others like Zorro II expansion memory. Unfortunately the current kernel does not support SPARSEMEM on m68k, but is using DISCONTIGMEM as Geert Uytterhoven explained. In short: we need SPARSEMEM support to easily make use of all available memory chunks that can be found. To make it a little more difficult, Amigas do use some kind of memory priority. Memory on accelerator cards usually has a priority of 40, motherboard expansion memory has a priority of, let's say, 20 and chip memory a pri of 0. This priority usually is equivalent to speed of memory. So, we want to have the kernel loaded to accelerator memory, of course. Basically we could do that by using a memfile and define the different memory chunks in the appropriate priority list like this one:
2097152
0x08000000 67108864
0x07400000 12582912
0x05000000 268435424
Would be an easy solution, right? Except that this doesn't work out. Currently the kernel will be loaded into the first memory chunk that is defined and ignore all memory chunks before that address space. As you can see 0x07400000 and 0x05000000 would be ignored because of this. Getting confused? No problem! It will get worse! ;) There's another method of accessing memory for Amigas: it's called z2ram and will use Zorro II as, let's say, swapping area. But maybe you guessed it: z2ram does not work for Zorro III memory (yet). So, this won't work either. Geert suggested to use that Zorro III memory as mtd device and finally this worked out! You'll need these modules in your kernel:
CONFIG_MTD=m
CONFIG_MTD_CMDLINE_PARTS=m
CONFIG_MTD_BLKDEVS=m
CONFIG_MTD_SWAP=m
CONFIG_MTD_MAP_BANK_WIDTH_1=y
CONFIG_MTD_MAP_BANK_WIDTH_2=y
CONFIG_MTD_MAP_BANK_WIDTH_4=y
CONFIG_MTD_CFI_I1=y
CONFIG_MTD_CFI_I2=y
CONFIG_MTD_SLRAM=m
CONFIG_MTD_PHRAM=m
Then you just need to create the mtd device and configure it as swap space:
/sbin/modprobe phram phram=bigram0,0x50000000,0xfffffe0
/sbin/modprobe mtdblock
/sbin/mkswap /dev/mtdblock0
/sbin/swapon -p 5 /dev/mtdblock0
And then you're done:
# swapon -s
Filename Type Size Used Priority
/dev/sda3 partition 205932 8 1
/dev/sdb3 partition 875536 16 1
/dev/mtdblock0 partition 262136 53952 5
To make it even worse (yes, there's still room for that! ;)) you can put two memory expansion cards into one box:
# lszorro -v
00: MacroSystems USA Warp Engine 40xx [Accelerator, SCSI Host Adapter and RAM Expansion]
40000000 (512K) 01: Unknown device 0e3b:20:00
50000000 (256M) 02: Village Tronic Picasso II/II+ RAM [Graphics Card]
00200000 (2M) 03: Village Tronic Picasso II/II+ [Graphics Card]
00e90000 (64K) 04: Hydra Systems Amiganet [Ethernet Card]
00ea0000 (64K) 05: Unknown device 0e3b:20:00
60000000 (256M)
The two "Unknown device" entries are the two BigRamPlus cards. As you can see card #1 starts at 0x50000000 and card #2 starts at 0x60000000. Unfortunately the phram kernel module can be loaded twice with different start addresses, but the idea to start at 0x50000000 with a size of 512M won't work either as there seems to be a reserved 0x20 bytes a range at the beginning of each card. Anyway... So, to make a very long and weird story short: the donated memory cards from Debian can now be used as additional and fast swap space for the buildds as long as it takes to get SPARSEMEM support working. Thanks again for donating the money for those memory expansion cards for the good old m68k port. Once done SPARSEMEM support in the m68k will benefit not only these cards in Amigas but Ataris as well.
Kategorie:

16 December 2013

Dirk Eddelbuettel: RProtoBuf 0.3.2

A new version 0.3.2 of RProtoBuf, is now on CRAN. RProtoBuf provides GNU R bindings for the Google Protobuf data encoding library used and released by Google. As for the last few releases, Murray took charge of most changes. The NEWS file entry follows:
Changes in RProtoBuf version 0.3.2 (2013-12-15)
  • Fixed a bug that erroneously prevented users from setting raw byte fields in protocol buffers under certain circumstances.
  • Give a user friendly error message when seting an extension to a message of the wrong type instead of causing a C++ check failure that terminates the Rsession.
  • Change object table lookup slightly to allow users to use the <<- operator in code using RProtoBuf without hitting a stop() error in the lookup routine.
  • Add missing enum_type method and improve show method for EnumValueDescriptors.
  • Improve documentation and tests for all of the above.
  • Rewrote tests/ script calling RUnit tests
CRANberries also provides a diff to the previous release 0.3.1. More information is at the RProtoBuf page which has a draft package vignette, a 'quick' overview vignette and a unit test summary vignette. Questions, comments etc should go to the rprotobuf mailing list off the RProtoBuf page at R-Forge.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

Next.

Previous.