Search Results: "cas"

10 August 2013

Kurt Roeckx: Anti-piracy and privacy

In the Dutch language area (Netherlands and Flanders) most e-book publishers changed from using DRM to using a watermark since February. It's now something like 62% with watermark, 24% with DRM and 14% without either. I was hoping that more with move to the watermark, but it doesn't seem to change much. The watermark in the e-books are used to find the original buyer in case of piracy. The information in the e-book does not itself identify the buyer, it just some random ID. That ID can then be used to trace back to buyer. We work with a 3rd party to deliver the e-books to our consumers. They get a random string from us that we can use to trace back the order, and from there we can trace back who bought it. The 3rd party than generates their own random string and puts that in the e-book. They only only keep those 2 random strings, and so have no way to trace this back to the buyer, we are the only one that known who bought it. And I think this is how it should work. I think this is also what the privacy laws require us to do. But now we got a new contract that states that we must directly give information about the buyer if some anti-piracy agency (BREIN) finds an e-book file online. We must keep the information about the buyer for minimum of 2 years and maximum of 5 years. And if we don't sign the contract we won't be allowed to sell e-books with watermark anymore. So this means that they want to bypass the normal judicial system, and probably contact those buyers they accuse of piracy directly. I questioned that this was legal. They say that it is legal according to the Dutch privacy law, but I have a hard time interpreting any of the options in article 8 as that we can give that information without the explicit consent of the person. I guess you can interpret option f in several ways, and that their lawyers do it differently than me. This will probably remain unclear until some court decides on it.

Matthew Garrett: When to add a platform-specific quirk to a Linux driver

If you're tempted to add a platform-specific quirk to a Linux driver, pause and do the following:

  1. Check whether the platform works correctly with the generic Windows driver for the hardware in question. If it requires a platform-specific driver rather than the generic one, adding a quirk is probably ok.
  2. If the generic Windows driver works, check whether there's any evidence of platform-specific code in the Windows driver. This will typically be in the .inf file, but occasionally you'll want to run strings against the Windows driver and see whether any functions or strings match the platform in question. If there's evidence of special-casing in the generic Windows driver, adding a quirk is probably ok
  3. If the generic Windows driver works and doesn't appear to have any platform-specific special casing, don't add a quirk. You'll plausibly fix the machine you care about, but you won't fix any others that have the same behaviour. Even worse, if someone does eventually fix the problem properly, there's a risk that your special-casing will now break your system.

The moral to this story is: if you think adding a quirk is the right solution, you're almost certainly wrong.

comment count unavailable comments

9 August 2013

Gunnar Wolf: Not in Switzerland But still, cheering for Debian's 20th anniversary!

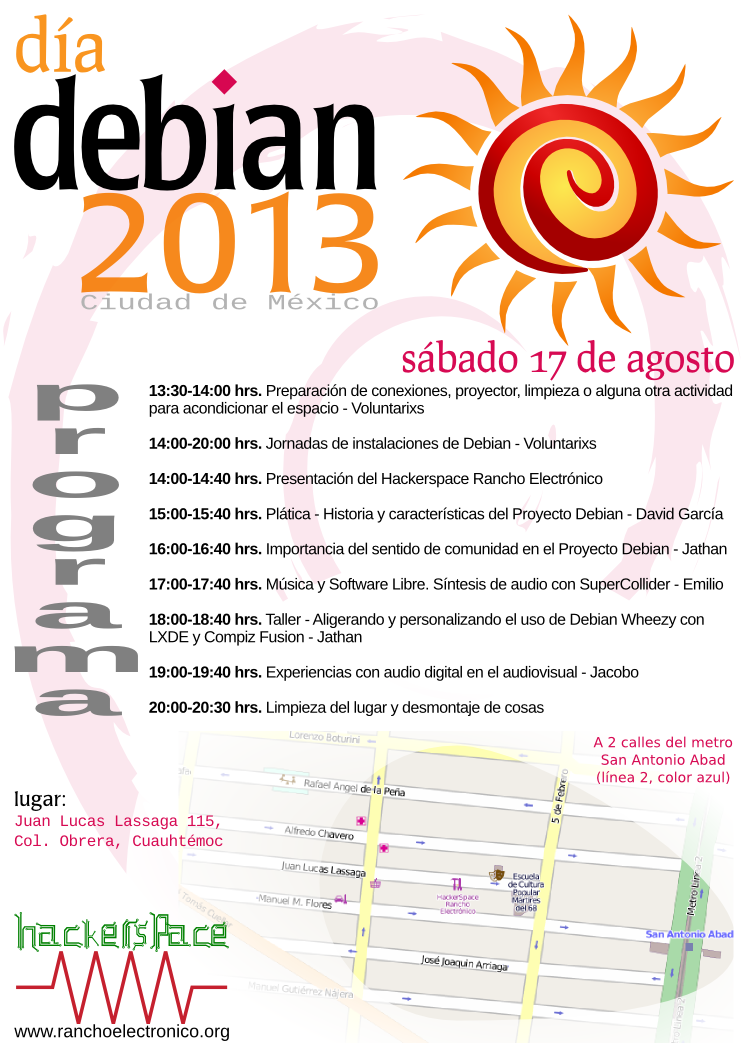
So... Well, contrary to the popular sentiment in Planet Debian, this year I'm very sorry to inform that... -( This is the first DebConf I miss in ten years, so... Yes, it's a big bummer for me. I'm not attending because this year, DebC(amp onf) coincide with the two first weeks of classes at my university And as a new teacher, I cannot afford to miss it! Anyway, but that should not stand in the way to attend a nice Debian 20th anniversary party! Parties will be held around the world. (Didn't find your city? Plan something and add it *now!*). In Mexico City, the nice guys at the very interesting Rancho Electr nico hackerspace took the lead, and organized the following activities: Debian Day 2013 Mexico City program Don't you yet know the hackerspace? You should go there! It's in a very centric location, just two blocks West from Metro San Antonio Abad (Juan Lucas Lassaga 114, col. Obrera). And the only two times I have been there, it has been good fun. Surely this Saturday we can have a nice party as well! The planned activities are from 13:30 to 20:30. See you there!

Dirk Eddelbuettel: inline 0.3.13

A minor maintenance release of inline is now on CRAN, and has just been already included in Debian. This release contains a patch kindly contributed by Mikhail Umorin which fixes the of \code cfunction with lists of signatures and function bodies. The complete NEWS entry is below.
Changes in inline version 0.3.13 (2013-08-08)
  • Applied contributed patch by Mikhail Umorin which corrects cfunction() in the case of a list of signature and body arguments.
Courtesy of CRANberries, there is also a diffstat report for the most recent release. A few more details are available at the R-Forge page.

Craig Small: pidof moving to procps

pidof is a program that finds the PID of a named program. In some ways it is like a cut-down pgrep found in the procps package. pidof currently sits in sysvinit-tools. There are plans to move all utilities that use the proc filesystem under one package which will make the maintenance of them simpler, which in effect means moving pidof from sysvinit-tools to procps. The short-term bump should make it better in the long term. Now as I wear two hats (Debian maintainer and procps upstream) there are two very important things I/we need to know. Debian developers can chime in on the debian-devel email list, or email myself. If its an upstream issue then either email me, or even better, the procps email list

Daniel Pocock: GSoC students progress

I've been lucky enough to be involved in a team mentoring two students contributing to Debian under the Google Summer of Code program this year. Both students have demonstrated a lot of enthusiasm and talent and have just passed their mid-term evaluations. Students often provide a fresh insight to projects. Their potential is not to be underestimated: one diligent student, Thomas Herndon from UMass Amherst recently came to fame exposing fundamental spreadsheet errors in calculations used to back the IMF case for austerity. Herndon was lucky to receive a copy of the spreadsheet (the source was not published openly as in free software): that is one problem that GSoC students don't have to wrestle with. Both of our GSoC students have exposed previously unknown issues in the code they are working on: Fabian discovered API differences in GnuTLS caused problems for dynalogin, while Catalin helped discover that some headers from reSIProcate are susceptible to ABI-breaking behavior dependending on the combination of CPPFLAGS. DebConf this month Both students are going to discuss some of their work on 17 August at DebConf - they are particularly keen to meet with other members of the Debian community throughout the week and find out how their work can best be leveraged by the community and Debian's wider userbase (and derivatives). Fabian Gr nbichler : one time passwords Fabian's project has been working on oath-toolkit and dynalogin. These are excellent projects, helping us realise new opportunities to use tokens for various types of authentication exchanges, such as login. Part of his project involves implementing the recently formalized IETF RFC 6287 for OCRA in a practical way that developers can use. Catalin Usurelu : real-time communications Catalin's project involves working with a variety of open source communications applications to make them work well together on a Debian system. One piece of work he is just completing provides a turn-key SIP conferencing solution that could replace Mumble (which attracted quite some controversy in the previous Debian release cycle) Community development These are all community projects and any feedback from users and other developers is always very welcome. For example, if you have time to test or provide suggestions, please feel free to jump in on the mailing lists we use for these projects.

8 August 2013

Nicolas Dandrimont: Hello from DebCamp

DebConf flag (minus the wind) Small update as someone was complaining about the lack of pictures from DebCamp on planet. Not to worry, everything is going fine, and some of the most important stuff is ready s3kr3t You can see a few pictures from the gallery. The view from the venue is quite outstanding (it was better when there was some sun on Tuesday, but my camera battery was out ). On my TODO-list: See you there!

Michael Stapelberg: Going to DebConf

I will arrive at DebConf 2013 on Sunday afternoon. In case you are interested in Go (the programming language), systemd, i3 or getting your package reviewed, please talk to me! :-) Looking forward to meeting many of you in real life.

Francois Marier: Server Migration Plan

I recently had to migrate the main Libravatar server to a new virtual machine. In order to minimize risk and downtime, I decided to write a migration plan ahead of time. I am sharing this plan here in case it gives any ideas to others who have to go through a similar process.

Prepare DNS
  • Change the TTL on the DNS entry for libravatar.org to 3600 seconds.
  • Remove the mirrors I don't control from the DNS load balancer (cdn and seccdn).
  • Remove the main server from cdn and seccdn in DNS.

Preparing the new server
  • Setup the new server.
  • Copy the database from the old site and restore it.
  • Copy /var/lib/libravatar from the old site.
  • Hack my local /etc/hosts file to point to the new server's IP address:
    xxx.xxx.xxx.xxx www.libravatar.org stats.libravatar.org cdn.libravatar.org
    
  • Test all functionality on the new site.

Preparing the old server
  • Prepare a static "under migration" Apache config in /etc/apache2/sites-enables.static/:
    <VirtualHost *:80>
        RewriteEngine On
        RewriteRule ^ https://www.libravatar.org [redirect=301,last]
    </VirtualHost>
    <VirtualHost *:443>
        SSLEngine on
        SSLProtocol TLSv1
        SSLHonorCipherOrder On
        SSLCipherSuite RC4-SHA:HIGH:!kEDH
        SSLCertificateFile /etc/libravatar/www.crt
        SSLCertificateKeyFile /etc/libravatar/www.pem
        SSLCertificateChainFile /etc/libravatar/www-chain.pem
        RewriteEngine On
        RewriteRule ^ /var/www/migration.html [last]
        <Directory /var/www>
            Allow from all
            Options -Indexes
        </Directory>
    </VirtualHost>
    
  • Put this static file in /var/www/migration.html:
    <html>
    <body>
    <p>We are migrating to a new server. See you soon!</p>
    <p>- <a href="http://identi.ca/libravatar">@libravatar</a></p>
    </body>
    </html>
    
  • Enable the rewrite module:
    a2enmod rewrite
    
  • Prepare an Apache config proxying to the new server in /etc/apache2/sites-enabled.proxy/:
    <VirtualHost *:80>
        RewriteEngine On
        RewriteRule ^ https://www.libravatar.org [redirect=301,last]
    </VirtualHost>
    <VirtualHost *:443>
        SSLEngine on
        SSLProtocol TLSv1
        SSLHonorCipherOrder On
        SSLCipherSuite RC4-SHA:HIGH:!kEDH
        SSLCertificateFile /etc/libravatar/www.crt
        SSLCertificateKeyFile /etc/libravatar/www.pem
        SSLCertificateChainFile /etc/libravatar/www-chain.pem
        SSLProxyEngine on
        ProxyPass / https://www.libravatar.org/
        ProxyPassReverse / https://www.libravatar.org/
    </VirtualHost>
    
  • Enable the proxy-related modules for Apache:
    a2enmod proxy
    a2enmod proxy_connect
    a2enmod proxy_http
    

Migrating servers
  • Tweet and dent about the upcoming migration.
  • Enable the static file config on the old server (disabling the Django app).
  • Copy the database from the old server and restore it on the new server.
  • Copy /var/lib/libravatar from the old server to the new one.

Disable mirror sync
  • Log into each mirror and comment out the sync cron jobs in /etc/cron.d/libravatar-slave.
  • Make sure mirrors are no longer able to connect to the old server by deleting /var/lib/libravatar/master/.ssh/authorized_keys on the old server.

Testing the main site
  • Hack my local /etc/hosts file to point to the new server's IP address:
    xxx.xxx.xxx.xxx www.libravatar.org stats.libravatar.org cdn.libravatar.org
    
  • Test all functionality on the new site.
  • If testing is successful, update DNS to point to the new server with a short TTL (in case we need to revert).
  • Enable the proxy config on the old server.
  • Hack my local /etc/hosts file to point to the old server's IP address.
  • Test basic functionality going through the proxy.
  • Remove local /etc/hosts/ hacks.

Re-enable mirror sync
  • Build a new libravatar-slave package with an updated known_hosts file for the new server.
  • Log into each server I control and update that package.
  • Test the connection to the master (hacking /etc/hosts on the mirror if needed):
    sudo -u libravatar-slave ssh libravatar-master@0.cdn.libravatar.org
    
  • Uncomment the sync cron jobs in /etc/cron.d/libravatar-slave.
  • An hour later, make sure that new images are copied over and that the TLS certs are still working.
  • Remove /etc/hosts hacks from all mirrors.

Post migration steps
  • Tweet and dent about the fact that the migration was successful.
  • Send a test email to the support address included in the tweet/dent.
  • Take a backup of config files and data on the old server in case I forgot to copy something to the new one.
  • Get in touch with mirror owners to tell them to update libravatar-slave package and test ssh configuration.
  • Add third-party controlled mirrors back to the DNS load-balancer once they are up to date.
  • A few days later, change the TTL for the main site back to 43200 seconds.
  • A week later, kill the proxy on the old server by shutting it down.

7 August 2013

Keith Packard: Cursor tracking

Tracking Cursor Position I spent yesterday morning in the Accessibility BOF here at Guadec and was reminded that one persistent problem with tools like screen magnifiers and screen readers is that they need to know the current cursor position all the time, independent of which window the cursor is in and independent of grabs. The current method that these applications are using to track the cursor is to poll the X server using XQueryPointer. This is obviously terrible for at least a couple of reasons: These two problems also conflict with one another. Reducing input latency comes at the cost of further reducing the opportunities for power saving, and vice versa. XInput2 to the rescue (?) XInput2 has the ability to deliver raw device events right to applications, bypassing the whole event selection mechanism within the X server. This was designed to let games and other applications see relative mouse motion events and drawing applications see the whole tablet surface. These raw events are really raw though; they do not include the cursor position, and so cannot be directly used for tracking. However, we do know that the cursor only moves in response to input device events, so we can easily use the arrival of a raw event to trigger a query for the mouse position. A better plan? Perhaps what we should do is to actually create a new event type to report the cursor position and the containing window so that applications can simply track that. Yeah, it s a bit of a special case, but it s a common requirement for accessibility tools.
 
    CursorEvent
        EVENTHEADER
        detail:                    CARD32
        sourceid:                  DEVICEID
        flags:                     DEVICEEVENTFLAGS
    root:                      WINDOW
    window:                    WINDOW
    root-x, root-y:            INT16
    window-x, window-y:        INT16
 
A CursorEvent is sent whenever a sprite moves on the screen. sourceid is the master pointer which is moving. root is the root window containing the cursor, window is the window that the pointer is in. root-x and root-y indicate the position within the root window, window-x and window-y indicate the position within window . Demo Application Here s a short application, hacked from Peter Hutterer s part1.c
/* cc -o track_cursor track_cursor.c  pkg-config --cflags --libs xi x11  */
#include <stdio.h>
#include <string.h>
#include <X11/Xlib.h>
#include <X11/extensions/XInput2.h>
/* Return 1 if XI2 is available, 0 otherwise */
static int has_xi2(Display *dpy)
 
    int major, minor;
    int rc;
    /* We support XI 2.2 */
    major = 2;
    minor = 2;
    rc = XIQueryVersion(dpy, &major, &minor);
    if (rc == BadRequest)  
    printf("No XI2 support. Server supports version %d.%d only.\n", major, minor);
    return 0;
      else if (rc != Success)  
    fprintf(stderr, "Internal Error! This is a bug in Xlib.\n");
     
    printf("XI2 supported. Server provides version %d.%d.\n", major, minor);
    return 1;
 
static void select_events(Display *dpy, Window win)
 
    XIEventMask evmasks[1];
    unsigned char mask1[(XI_LASTEVENT + 7)/8];
    memset(mask1, 0, sizeof(mask1));
    /* select for button and key events from all master devices */
    XISetMask(mask1, XI_RawMotion);
    evmasks[0].deviceid = XIAllMasterDevices;
    evmasks[0].mask_len = sizeof(mask1);
    evmasks[0].mask = mask1;
    XISelectEvents(dpy, win, evmasks, 1);
    XFlush(dpy);
 
int main (int argc, char **argv)
 
    Display *dpy;
    int xi_opcode, event, error;
    XEvent ev;
    dpy = XOpenDisplay(NULL);
    if (!dpy)  
    fprintf(stderr, "Failed to open display.\n");
    return -1;
     
    if (!XQueryExtension(dpy, "XInputExtension", &xi_opcode, &event, &error))  
       printf("X Input extension not available.\n");
          return -1;
     
    if (!has_xi2(dpy))
    return -1;
    /* select for XI2 events */
    select_events(dpy, DefaultRootWindow(dpy));
    while(1)  
    XGenericEventCookie *cookie = &ev.xcookie;
    XIRawEvent      *re;
    Window          root_ret, child_ret;
    int         root_x, root_y;
    int         win_x, win_y;
    unsigned int        mask;
    XNextEvent(dpy, &ev);
    if (cookie->type != GenericEvent  
        cookie->extension != xi_opcode  
        !XGetEventData(dpy, cookie))
        continue;
    switch (cookie->evtype)  
    case XI_RawMotion:
        re = (XIRawEvent *) cookie->data;
        XQueryPointer(dpy, DefaultRootWindow(dpy),
                  &root_ret, &child_ret, &root_x, &root_y, &win_x, &win_y, &mask);
        printf ("raw %g,%g root %d,%d\n",
            re->raw_values[0], re->raw_values[1],
            root_x, root_y);
        break;
     
    XFreeEventData(dpy, cookie);
     
    return 0;
 
Hacks in xeyes Of course, one common mouse tracking application is xeyes, so I ve hacked up that code (on top of my present changes) here:
git clone git://people.freedesktop.org/~keithp/xeyes.git

5 August 2013

Ian Wienand: Skipping bash history for command-lines starting with space

I was recently reading about a case where part of the evidence appears to be a deleted bash history-file. From what I gather, the accused says that the removal was a clean-up job to remove inadvertently stored passwords rather than an attempt to hide nefarious activity. What had managed to pass me by in 15 or so years of using bash but not reading man bash properly is the HISTCONTROL variable. If it is set to ignorespace then commands entered with a leading-space will not be stored in the history. Like all the best discoveries I found this only by accident on a machine where it was turned on. It's been quite useful in keeping my history pruned. However, not usually for security reasons around hiding passwords passwords on the command-line have other problems and I'm sure any security person would tell you not to use them just from a defense-in-depth perspective. That said, from a "keeping ctrl-r reversi-search useful" point-of-view it's often helpful; for example I've mostly trained my fingers to <space>rm -rf because I'm sure I'm not the only one who has deleted the wrong thing via a history-recall-combined-with-typing-to-fast scenario. So, HISTCONTROL=ignoreboth (which also ignores duplicates) is certainly a useful one to slip into your .bashrc. At least it would be one-less thing to explain to the FBI!

Wouter Verhelst: Hard disk partition pregap and grub2

A week or so back, I was at a customer to upgrade his server to wheezy. This server had originally been installed, not as squeeze but as something older, and was installed using an LVM-on-mdraid setup. Booting off such a setup (without a /boot partition outside of the raid/LVM) is certainly possible with several boot loaders, including grub2; however, it was having issues in this particular instance, producing an error message along the likes of:
/sbin/grub2-setup: warn: Your embedding area is unusually small. core.img won't fit in it..
It took me a while to figure out what that meant, but the Internet to the rescue:
Disk /dev/sda: 160.0 GB, 160041885696 bytes
255 heads, 63 sectors/track, 19457 cylinders, total 312581808 sectors
Units = sectors of 1 * 512 = 512 bytes
Sector size (logical/physical): 512 bytes / 512 bytes
I/O size (minimum/optimal): 512 bytes / 512 bytes
Disk identifier: 0x000b3c3b
   Device Boot      Start         End      Blocks   Id  System
/dev/sda1   *        2048   312580095   156289024   83  Linux
That partition starts at the 2048th block, resulting in a 1MiB gap before the first partition. The older default was to start on the 63rd block, for a pregap of just short of 32KiB. Unfortunately, the only way to fix this issue without ugly hacks (such as the chainloading suggested in this fedora forum thread) is to repartition. Luckily, thanks to the magic of LVM, this isn't difficult (if a little involved). Steps:
pvmove -v /dev/md0
vgreduce -a
mdadm -S /dev/md0
(...repartition the hard disks that make up /dev/md0...)
mdadm -C /dev/md0 (... other options required to recreate /dev/md0 on the desired RAID level...)
pvcreate /dev/md0
vgextend /dev/vg /dev/md0
... and then rinse, repeat for md1. At that point, installing grub will work as usual. An alternative (since we were using RAID1) could have been to remove one disk from the RAID array, repartition it, create a new RAID1 array in degraded mode, pvmove over to that, destroy the original array, and add the second disk to the new array. This would probably be a better idea when you only have one RAID array, for instance, or when you have more than one array and have more data than fits on a single array. However, that wasn't the case here (at least not after a resize2fs -M call followed by an appropriate lvresize one), and so I thought that not reducing redundancy, even if only temporarily, was a better move.

Daniel Pocock: Effectively supporting virtual domains with Mailman

When I first decided to run my own list server, I was well aware of the popularity of Mailman but I was deterred from using it by the complexity of setting up virtual hosts. In particular, 99% of the software I use for servers is packaged. Whenever I choose a new piece of software, using something that is packaged and supported is high on my list of priorities. Mailman's distribution tarball and the packages built from it only have limited support for virtual hosting. My own objective is to host lists for open source projects. As some of these projects don't have dedicated budgets, it is particularly important to find lightweight, low-maintenance solutions. Furthermore, it is important that those solutions don't detract from the time I want to invest in the projects themselves. I've developed some scripts to solve the problem: to start using them quickly, please see the README file. Here I provide a more detailed overview of the logic behind this approach. Mailman's limitations and workarounds For me, the biggest limitation of Mailman is that the site list is always linked to a single domain, which has to be chosen arbitrarily from the list of domains being hosted. Although it is not emphasized in the documentation, there is also the inconvenience of having all the lists from potentially unrelated projects appearing together on Mailman's main index page. Another limitation is that each list name must be globally unique across all domains. Some existing workarounds exist but they have limitations too. There is a virtual domain patch, but it is not clear how this handles the site list or the site index page. There is also the postfix-to-mailman script distributed by Debian and Ubuntu: using a transport-based solution looks elegant at first, but when you realise that you need to whitelist the addresses (to ensure messages are rejected at ingress rather than bounced), it becomes just as much work to maintain as the alternatives it aims to avoid: Mailman's authors do not endorse this approach. Experimenting with Sympa Deterred by Mailman's limitations, I initially went with Sympa and that seemed to run quite well for a number of years. In particular, it supports full virtual hosting out-of-the-box and all this is standard in the convenient Debian packages. From time-to-time, users have complained about the use of JavaScript in the web UI, but that was not something I could immediately resolve. However, when I upgraded to Debian 7 (wheezy), more serious problems appeared. Initially, the web UI (used for subscribing or browsing the archives) was completely broken. Anybody accessing the site would be given a download of the wws binary rather than the page that was supposed to be generated by the binary. I discovered errors about this in Apache's error.log and tried installing libapache2-mod-fcgid. The problem was resolved, but from then on, my whole web server became unstable and at least once every day I would have to restart the Apache process or it would become inaccessible. I put the details into a bug report and after not getting any feedback, decided to go and have another look at Mailman. A closer look at Mailman Looking at Mailman again, it appeared that the only way to achieve a relatively "pure" virtual hosting solution would be to run multiple installations of Mailman in different directory trees. Initially, I hoped this could be done by sharing copies of the binaries and just creating replicas of the structure under /var/lib/mailman. Looking under the hood, I discovered that the paths were compiled into the binaries and could not be easily overriden. It appears that this limitation could be overcome with some trivial patches to read directory names from the environment. The main aims of using shared binaries are disk space efficiency and also being able to benefit from security updates for the binary packages. However, if I had to patch the binaries, then I wouldn't be able to benefit from the security update packages anyway. So, it became inevitable that I would have to build binaries from source one way or another: either with a patch or by building multiple copies of each binary, each hardcoded with a different path. Putting it into practice Looking over the Mailman architecture, there are four things to be replicated for each installation:
  • init script to start a standalone qrunner per domain
  • cron jobs
  • CGI configuration from Apache (easily isolated by using a different ScriptAlias inside each Apache <VirtualHost>
  • Invocation of the Mailman binary from the mailer's aliases file
The init scripts and crontabs can be easily generated from a template (I used Debian's copies of these files as a base for that). Some of the Apache configuration can be handled by putting wildcards in the <Directory> specifications and the rest can be easily cut-and-pasted into <VirtualHost> definitions. Based on all of the above, all I had to do was run Mailman's configure script and make once for each virtual domain. I've scripted the whole process - my script is available here Managing the aliases file One particular limitation of my mailer (Postfix) is that the Mailman message processor can't be invoked directly from a rule in the virtual alias map. Scripts like this can only be invoked from the normal /etc/aliases file. This problem is not unique to Mailman: for Sympa, I also had to deal with this. The most common solution is to use the virtual file to translate all the virtual list addresses into very verbose usernames within the local domain:
Address Mapped to
widget-users@lists.example.org lists.example.org-widget-users@my-local-domain
The local part, lists.example.org-widget-users can then be used in the regular /etc/aliases file. This approach is described in the Sympa documentation and also in one of the virtual domain patches for Mailman. I've included a script for generating these alias mappings in the repository with my other scripts for building virtual Mailman installations. It would also be possible to patch Mailman itself to generate such files dynamically when new lists are created. Conclusion and next steps Using the techniques described and these small scripts, I successfully built independent virtual hosts for two of my domains, lists.lumicall.org and lists.dynalogin.org on a single mail host. Notice how each of them has the appearance of a clean, standalone Mailman installation? Going forward, I believe it would not be hard for the 2.x branch of Mailman to support this approach to virtual hosting with three changes:
  • Allowing the binaries to take their directory tree name from an environment variable or command line option or by inspecting argv[0] to discover their own location,
  • Generating the aliases file in the more verbose format and
  • Providing some convenient init script and crontab that iterates over all the domains

4 August 2013

Steve Kemp: TAB completion is hard

I've spent the past few days overhauling the TAB-completion which is included in lumail. Completing a single token is easy, if there is only one match, and you limit yourself to completing at the start of a line. But doing real completion is hard. Consider the case where you want to complete something like this:
unread_message_colour("re[TAB]
Clearly completing the first part "unread_[TAB]" is simple. But to complete "re" to "red" you need to split up your input line into tokens so that you can recognize a quote as a valid completion point. Similarly you need to split on "(" to allow:
-- show the path to the editor
msg(edit[TAB]
To allow this to be changed/controlled by the user I defined completion_chars() which contains: SPACE, QUOTE, "(", etc. I'm pleased with the user-callback for offering completion suggestions, my own is pretty basic and just includes all user-defined functions as well as an address book. The latter allows steve.org.uk[TAB] to complete to: "Steve Kemp" <steve@steve.org.uk> - because we allow matches anywhere in the completion string, rather than just prefix-matching. I struggled with resolving ambiguities, but now that is handled correctly too. Press "TAB" when there are multiple choices available and you can graphically TAB-through the available choices, or press Esc to cancel. In conclusion I've spent a few days fighting with user-interface stuff and now the mail-client is better, but I've still to tackle RFC 2047 header decoding because that is really hard!

3 August 2013

Steve Langasek: Network services and Upstart

So Debian bug #710747 led to an interesting discussion the other night on IRC which made me realize there are a lot of people who have yet to understand why sysvinit needs replacing. I can't speak to whether upstart solves this bug in particular. The tftpd-hpa package in Ubuntu (and in Debian experimental) does have an upstart job, and I have used tftpd-hpa on systems whose network interfaces are managed entirely with NetworkManager, and I have not seen this bug; but I can't say that this is more than coincidence. However, I can speak to how upstart provides facilities that address the general problem of starting services that require a working network connection to be present before they start up. Traditionally on Linux systems, init scripts could assume that the network connection is up before starting any services for the target runlevel. With LSB dependencies, you could also express this as
Required-Start:    $network
The trouble with both of these approaches is that they assume that there is a single point in time, early in the boot of the system, when the "network" is up. This was an ok assumption 15 years ago, when the Linux kernel initialized all devices serially and all our network configuration was static. But nowadays, you simply cannot rely on systems booting in such a way that the network is fully up shortly after boot - or in a way that you can block the system boot waiting for the network to be up. If all of our services would cope gracefully with being started without the network, this would be a non-issue. Unfortunately, not all network services are written in such a way as to work without a network; nor do they all cope with dynamic changes to interfaces or addresses. While it would be better if these services were written more robustly, since there's no shortage of daemons written this way, it's convenient that upstart provides tools for coping with this behavior in the meantime. Here's a real (simplified) example of an upstart job for a service that needs to wait for a non-loopback interface before it starts:
start on (local-filesystems and net-device-up IFACE!=lo)
stop on runlevel [!2345]
expect fork
respawn
exec nmbd -D
Now, you might also have a service that you only want to start up when a particular network device comes up. This is easily expressed in upstart, and might look like this hypothetical job:
start on net-device-up IFACE=wlan0
stop on net-device-down IFACE=wlan0
expect daemon
respawn
exec mydaemon
If you need to restart a daemon whenever the set of active network connections changes, that's less straightforward. Upstart doesn't have the notion of a 'restart' rule, so you would need two jobs to handle this - one for the daemon itself that starts on the first network connection, and a second job to trigger a restart of the daemon when the network status changes. For the tftpd-hpa case in the abovementioned bug, this might look like:
$ cat /etc/init/tftpd-hpa.conf
start on runlevel [2345]
stop on runlevel [!2345]
expect fork
respawn
script
        if [ -f $ DEFAULTS  ]; then
                . $ DEFAULTS 
        fi
        exec /usr/sbin/in.tftpd --listen  --user $ TFTP_USERNAME  --address $ TFTP_ADDRESS  $ TFTP_OPTIONS  $ TFTP_DIRECTORY 
end script
$ cat /etc/init/tftpd-hpa-restart.conf
start on net-device-up
task
instance $IFACE
script
        status tftpd-hpa   grep -q start/   stop
        restart tftpd-hpa
end script
For this case, upstart doesn't provide quite so great an advantage. It's nice to be able to use upstart natively for both pieces, but you can do the same thing with an init script plus an if-up.d script for ifupdown, which is what maintainers do today. I think adding a restart on stanza to upstart in the future to address this would be a good idea. Though in any event, this is far simpler to do with upstart than with any if-up.d script I've ever seen for managing an initscript-based service. Between the more friendly declarative syntax, and the enhanced semantics for expressing when to run (or restart) a job, upstart offers clear advantages over other init systems.

Daniel Leidert: Setting up a network buildd with pbuilder, ccache, inoticoming and NFS

I recently bought an N54L HP microserver, which shall act as a build-daemon (buildd) for Debian packaging. The idea of my workflow is the following:
  1. do the maintenance tasks locally, usually using svn-buildpackage, quilt etc.pp
  2. build a source package locally
  3. upload the source to an incoming directory on the server
  4. watch this incoming directory and start a build process as soon as a package is uploaded
  5. put the result into an accessible directory
  6. support different vendors (debian, ubuntu)
  7. support different releases (experimental, unstable, stable, oldstable)
  8. support different architectures (amd64, i386)
  9. speed up the build process
Setting up the building environmentMy first idea was to use sbuild as described in several places. However I went with pbuilder for a long time having a setup I personally like. So I decided to stay with it. I reduce the time and work to update the configure files by using
  • one central file /etc/pbuilderrc.inc defining all the common/shared settings and
  • small configure files defining vendor, release, architecture and mirrors
Here are the relevant parts of my central configure snippet:

[..]
EXTRAPACKAGES="apt-utils debconf debconf-utils libfile-fcntllock-perl"
[..]
BASETGZ="/var/cache/pbuilder/base.$DISTRIBUTION.$ARCHITECTURE.tgz"
APTCACHE="/var/cache/pbuilder/aptcache/$DISTRIBUTION/$ARCHITECTURE/"
BUILDRESULT="/var/cache/pbuilder/result/$DISTRIBUTION/$ARCHITECTURE/"
[..]
case "$VENDOR" in
ubuntu)
MIRRORSITE="http://archive.ubuntu.com/ubuntu"
COMPONENTS="main restricted universe multiverse"
OTHERMIRROR="\
deb http://de.archive.ubuntu.com/ubuntu $DISTRIBUTION main restricted universe multiverse \
deb http://archive.ubuntu.com/ubuntu $DISTRIBUTION-updates main restricted universe multiverse \
deb http://security.ubuntu.com/ubuntu $DISTRIBUTION-security main restricted universe multiverse \
"
;;
*)
MIRRORSITE="http://ftp.debian.org/debian"
COMPONENTS="main contrib non-free"
OTHERMIRROR="\
deb http://ftp.de.debian.org/debian $DISTRIBUTION main contrib non-free \
"
;;
esac
[..]
DEBBUILDOPTS="-us -uc -j2"
AUTO_DEBSIGN=no
USE_PDEBUILD_INTERNAL=yes
[..]
You get the main idea, right? Create own files and directories for each architecture, release and vendor. Further I only want to pull build related packages into the build environment, not into the server environment. So I enabled USE_PDEBUILD_INTERNAL. I don't want to sign anything on the buildd itself and use both cores. That's what DEBBUILDOPTS and AUTO_DEBSIGN are used for. Further I saw some warnings reported during build processes. I therefor install the packages mentioned in EXTRAPACKAGES to every build enviroment. The following are the configure files for the unstable amd64 (default) and the stable i386 build environments:

VENDOR="debian"
DISTRIBUTION="sid"
ARCHITECTURE="amd64"

. /etc/pbuilderrc.inc

VENDOR="debian"
DISTRIBUTION="wheezy"
ARCHITECTURE="i386"

. /etc/pbuilderrc.inc

OTHERMIRROR+="\
deb http://security.debian.org $DISTRIBUTION/updates main contrib non-free \
"
Now to not having to update all of these environments manually there is a small parallelized script /usr/local/sbin/update-pbuilder-chroots:

#!/bin/sh

t=$(tempfile -p .upc. -s .list) exit 1

cat > $t << EOF
/etc/pbuilderrc.amd64.sid
/etc/pbuilderrc.i386.sid
/etc/pbuilderrc.amd64.wheezy
/etc/pbuilderrc.i386.wheezy
/etc/pbuilderrc.amd64.squeeze
/etc/pbuilderrc.i386.squeeze
EOF

parallel /usr/sbin/pbuilder update --override-config --configfile :::: $t tee -a /var/log/pbuilder.log

rm -f $t

exit 0
The script will make sure, that every change to the configuration file(s) will be considered (--override-config) and is run once a week via cron. The default build environment is updated on a daily base without this restriction:

@reboot root rm -rf /var/cache/pbuilder/build/*/ >> /dev/null 2>&1
@daily root test -x /usr/sbin/pbuilder && /usr/sbin/pbuilder update --configfile /etc/pbuilderrc.amd64.sid tee -a /var/log/pbuilder.log >> /dev/null 2>&1
@weekly root test -x /usr/local/sbin/update-pbuilder-chroots && /usr/local/sbin/update-pbuilder-chroots >> /dev/null 2>&1
Speeding up the build processSometimes it is necessary to recompile a package. The tool to speed up this process is ccache, which can be easily integrated into pbuilder by setting CCACHEDIR in /etc/pbuilderrc.inc. It acts like a cache for compiled files and avoids recompilation in several buildd runs.

CCACHEDIR=/var/cache/pbuilder/ccache
It is also possible to use a TMPFS for BUILDPLACE to speed up the build process itself. In this case APTCACHEHARDLINK must be disabled. Well, yeah, I don't do this.Watch an incoming directory and start the build processNot much to say about this except that the user nobody is used to run the pbuilder command. Therefor it is necessary to mention this in /etc/sudoers to allow him to do this via sudo command:

Defaults env_keep = "DH_OPTIONS DH_VERBOSE DEB_BUILD_OPTIONS DH_OPTIONS MAKEFLAGS CC CXX CPP F77 F90"
[..]
nobody ALL=NOPASSWD:/usr/sbin/pbuilder
The first line is only necessary, if a pbuilder command is started with one of these environmental variables set. This can be useful when e.g. debugging a build failure with a future gcc version that is not yet the default or when debugging a clang build issue or when creating non-stripped binary packages for creating a backtrace (BTW: When there is a common repository of all debugging symbols created?).Now to start the build process, I created an incoming directory with mods 777 at /var/cache/pbuilder/incoming/ and use inoticoming to watch it. This is started during boot via cron. The following shows the entry for the default unstable amd64 build environment:

@reboot root /usr/bin/inoticoming --logfile /var/log/inoticoming.log --pid-file /var/run/inoticoming.pid /var/cache/pbuilder/incoming --chdir /var/cache/pbuilder/incoming --suffix .dsc --stderr-to-log --stdout-to-log /bin/su -c '/usr/bin/sudo /usr/sbin/pbuilder build --autocleanaptcache ' nobody \;
Done. That's how the basic buildd works.Getting the resultsThe pbuilder BUILDRESULT directory with mods 777 is shared via NFS mount to the workstation. After successfully building the package, debsign and dput can be used as usual.Setting up the workstationI use svn-buildpackage for most of my packages. Because pbuilder won't download source tarballs on demand by default (maybe via hook?), the tarball must always be included building the source package, which then gets uploaded via dput to the buildd. This is considered in the command listed in svn-builder in ~/.svn-buildpackage.conf (note, below shows my personal layout):

svn-builder=debuild --post-dpkg-buildpackage-hook=\"dput -f buildd /usr/local/src/packages/$PACKAGE/%p_%v_source.changes\" --no-lintian -d -sa -us -uc -S
svn-override=origDir=/usr/local/src/packages/$PACKAGE
svn-override=buildArea=/usr/local/src/packages/$PACKAGE
[..]
The host buildd has been added to ~/.dput.cf:

[buildd]
fqdn = mybuildd
login = mylogin
method = scp
incoming = /var/cache/pbuilder/incoming
allow_unsigned_uploads = 1
run_lintian = 0
Done. Now the svn-buildpackage command will create a source package including the source tarball and upload it to the buildd, where the package building starts right after the upload.ConclusionsThis is the main setup which works nicely for the default build environment so far. On the TODO list is to extend this setup so I can easily deal with all the architectures and releases (point 6..8 at the beginning).

Russell Coker: Religious Conversion

Today I was in the center of Melbourne and I saw two stands run by Muslims advocating their faith. They had a selection of DVDs and brochures to give away and seemed friendly enough for anyone who wanted a chat. I think that this is a good thing, if the majority of the Australian population would think of the Muslim minority as people who give away DVDs rather than as potential suicide bombers then it would be a great benefit for society. Then I saw a Christian stand which had placards indicating that Jesus loves Muslims, which is fine. One of the workers on that stand then gleefully told me that there had been a Muslim stand in that area but the Muslims departed when they arrived. It would be good if advocates for the various religions could work together to promote positive things that they all agree on (generally related to being nice to other people). When they seem to be essentially bullying other religious groups into leaving the area they aren t making a good case for a kind and caring god. The Christian who was so happy about the Muslims departing then tried to convert me. He started by talking about a mobile phone not being able to appear from nothing which was the start of an utterly stupid argument about creationism. That was stupid firstly because it s obvious that evolution doesn t apply to consumer electronics, if I leave a phone lying on top of another phone overnight I m not going to get some little phones appearing as a result. But the bigger stupidity is in even promoting creationism in the first place. Advocating creationism is essentially claiming that god is so incapable that ze can t manage an evolutionary process. An all-seeing all-knowing god of infinite intelligence could just create a plasma cloud that will form into a solar system and evolve life. People who argue for creationism don t believe in a capable god, they believe in a being that resembles a god in the way a magician resembles someone who can actually perform magic. Arguing for creationism is arguing for a limited being which probably isn t worthy of worship (why worship space aliens who are probably only a few thousand years ahead of us). Regardless of the scientific evidence (which is strongly in favor of evolution) just logically thinking about the issue in regard to what a being with infinite powers might actually do suggests that ze could just as easily create or evolve all life and probably wouldn t care about what we believe. Genesis should be taken as metaphor because it s obvious that nothing that s taught in a year 7 science class could be taught to your typical stone age goat-herd, but even if it was taken literally it s not specified as a required belief (as opposed to a belief in a single god, repenting sins, and other beliefs which are required). The greatest stupidity however is the fact that even if it made any sense to promote creationism it wouldn t make sense to do so immediately. Any time you want to convert someone to a set of beliefs it s a good strategy to start with the ones which will seem least wacky. I can have have a conversation with Christians about positive things which we generally agree on such as donating to charity and trying to do good things in various ways. But when they start with the stupid stuff I walk away. When the weather is better I plan to interview representatives of the various religious groups who are trying to convert people on the street and rate them according to how wacky they are. I ll be a little limited in my ability to review them by the total lack of any right to free speech in Australia (our laws are much the same as those in the UK). But I should still be able to give them a reasonable review.

Paul Tagliamonte: Hy: The survival guide

One of my new favorite languages is a peppy little lisp called hy. I like it a lot since it's a result of a hilarious idea I had while talking with some coworkers over mexican food. Since I'm the most experienced Hypster on the planet, I figured I should write a survival guide. This will go a lot easier if you already know Lisp, but you can get away with quite a bit of Python. The Tao of Hy We don't have many rules (yet), but we do have quite a bit of philosophy. The collective Hyve Mind has spent quite a bit of time working out Hy's internals, and we do spend a bit of time looking at how the language feels . The following is a brief list of some of the design decisions we've picked out.
  1. Look like a lisp, DTRT with it (e.g. dashes turn to underscores, earmuffs turn to all-caps.)
  2. We're still Python. Most of the internals translate 1:1 to Python internals.
  3. Use unicode everywhere.
  4. Tests or it doesn't exist.
  5. Fix the bad decisions in Python 2 when we can (see true_division)
  6. When in doubt, defer to Python.
  7. If you're still unsure, defer to Clojure
  8. If you're even more unsure, you're fucked (see also: defer to Common Lisp)
Naturally, this doesn't cover everything, but if you can drop into that mindset, things start to make quite a bit of sense. The Style of Hy Although I am perhaps the least qualified person to do so (I still don't write idiomatic Lisp all the time), I'm going to set up a few ground-rules when it comes to idiomatic Hy code. We borrow quite a bit of syntax from Common Lisp and Clojure, so again, feel free to defer to either if you're not working on Hy internals. I prefer the Clojure Style Guidelines myself. As such, these are what we will defer to in the case that the Hy style is undefined. Clojure-isms Hy has quite a few Clojure-isms that I rather prefer, such as the threading macro, and dot-notation (for accessing methods on an Object), which I would rather see used throught the hylands.
;; good:
(with [fd (open "/etc/passwd")]
    (print (.readlines fd)))
;; bad:
(with [fd (open "/etc/passwd")]
    (print (fd.readlines)))
Some other hy devs very much disagree, and there's nothing syntactically invalid about the latter, and it will continue to be supported (in fact, it makes some things easier!), but it will not be considered for Hy internal code. We also very much encourage use of the threading macro throughout code where it makes sense.
;; good:
(import [sh [cat grep]])
(-> (cat "/usr/share/dict/words") (grep "-E" "tag$"))
;; bad:
(import [sh [cat grep]])
(grep (cat "/usr/share/dict/words") "-E" "tag$")
However, do use it when it helps aid in clarity, like all things, there are cases where it makes a mess out of something that ought to not be futzed with. Python-isms In addition to stealing quite a bit of syntax from Clojure, I'm going to take a few Python rules from PEP8 that apply to Hy as well. These are taken because PEP8 is a really great set of rules, and Hy code ends up pretty, well, Pythonic. The following are a collection of Pythonic rules that explicitly apply to Hy code. Trailing spaces is a huge one. Never ever ever shall it be OK to have trailing spaces on internal Hy code. For they suck. As with Python, you shall always double-space module-level definitions if seperated with a newline. All public functions must always contain docstrings. Inline comments shall be two spaces from the end of the code, if they are inline comments. They must always have a space between the comment character and the start of the comment. Hy-isms Indentation shall be two spaces, except where matching the indentation of the previous line.
;; good (and prefered):
(defn fib [n]
  (if (<= n 2)
      n
      (+ (fib (- n 1)) (fib (- n 2)))))
;; still OK:
(defn fib [n]
  (if (<= n 2) n (+ (fib (- n 1)) (fib (- n 2)))))
;; still OK:
(defn fib [n]
  (if (<= n 2)
    n
    (+ (fib (- n 1)) (fib (- n 2)))))
;; Stupid as hell
(defn fib [n]
    (if (<= n 2)
            n
      (+ (fib (- n 1)) (fib (- n 2)))))
Parens must never be alone, sad, all by their lonesome on their own line.
;; good (and prefered):
(defn fib [n]
  (if (<= n 2)
      n
      (+ (fib (- n 1)) (fib (- n 2)))))
;; Stupid as hell
(defn fib [n] 
    (if (<= n 2)
      n
      (+ (fib (- n 1)) (fib (- n 2)))
    )
)  ; GAH, BURN IT WITH FIRE
Don't use S-Expression syntax where vector syntax is really required. For instance, the fact that:
;; bad (and evil)
(defn foo (x) (print x))
(foo 1)
works is just because the compiler isn't overly strict. In reality, the correct syntax in places such as this is:
;; good (and prefered):
(defn foo [x] (print x))
(foo 1)
Notice This guide is, above all, a guide. This is also only truely binding for working on Hy code internally. This post is also super subject to change in the future, whenever I can be bothered to ensure that we have more of the de facto rules written down.

2 August 2013

Joey Hess: DIY crowdfunding and bitcoin

Well, my git-annex crowdfunding campaign is half way to its August 15th conclusion. So far it's raised more than five times what I hoped it would. I wish I could say I'm like some canny NASA engineer who intentionally sets low expectations for their Mars rover, but in both the previous kickstarter and this campaign I've really had no idea how far it'd go. I'm glad that I'll be working on git-annex for another year. I was particularly unsure if it'd be successful to move off Kickstarter. During the git-annex assistant Kickstarter campaign, I saw many small contributions from people who learned of it due to it being a successfully funded project, a staff pick, etc. Losing that easy network effect is a gamble. So far I've had only half the number of contributors that I got on Kickstarter. I've basically missed out entirely on the $5 level casual contributors. On the other hand, my backers have generally been more generous (and some have been exceedingly generous). And I've avoided rewards that will cost much money, so I may end up in the same ballpark funding level in the end! Incidentially, I'm really enjoying getting in touch to let people know when I make their sponsored commits. There's still time to sponsor one of your own ;) Bitcoin I also was curious to experiment with Bitcoin in this campaign. Partly because Paypal isn't available everywhere internationally, and takes really obnoxious percentages of transactions (though probably not as bad as Kickstarter taking its percentage followed by Amazon payments taking its percentage..) and partly because there seem to be interesting possibilities for supporting free software with Bitcoin. (Especially if any of the microtransactions on top of Bitcoin take off.) So far 5% of backers have used Bitcoin. It's been quite strange to actually have significant amounts of bitcoins in my wallet. Wordpress has had 94 bitcoin payments over 9 months since starting accepting them. I've had 47 payments in the two weeks my campaign has run so far. Wow! Most of the bitcoin payments have come in via Coinbase (a few people have found my direct payment address), but of those very few were using bitcoin purchased on Coinbase. Most are probably transfers of bitcoin they already had, or perhaps bitcoin purchased on other sites. The one technical issue I've had with using bitcoin is that Coinbase has not provided details about who sent most of the donations. Probably some of them are intentionally anonymous, but I suspect Coinbase's interface to claim incoming bitcoin transactions failed for some of them. (If you donated bitcoin and want to actually get a reward, please email me.) By the way, I'm converting most of the bitcoins back to USD pretty quickly. I'm not interested in speculating on currency exchange rates with money that has been donated so I can accomplish a particular task.. DIY I put up the campaign website without any means in place to handle updating it. This is because I never automate anything until I've done it at least 10 times by hand. ;) After the first trickle of donations became a flood, I quickly realized I needed at least something to handle keeping the numbers straight. What I whipped up in an hour of coding is a system where I enter incoming payments into a hledger file and a small haskell program parses that and writes out various files that are included into the website. Amusingly the percentage calculation and display code was copied from git-annex, so part of git-annex is helping run its own fundraising campaign. The campaign video is itself hosted in a public git-annex repository, come to think of it. The rest of the site is built using ikiwiki. Given that it's hosted at Branchable, this is a high level of dogfooding and DIY. There are certianly better crowdfunding platforms, but all I miss in this one is automated transaction entry. And I have total flexability, double entry accounting, and a powerful static website generator that handled being on the top of Hacker News without a sweat. Oh, and some money. What's not to like?

Next.

Previous.