Search Results: "tar"

7 July 2016

Lior Kaplan: Anonymous CVE requests

A year ago I ve blogged about people requesting CVE without letting upstream know. On the other hand, per requests from Debian, I m working on improving PHP upstream CVE request process. For the last few release this means I ask the security list members which issues they think should have CVE and ask for them in parallel to the release being made (usually in the space between the release being tagged publicly and is actually announced). In the last week, I ve encountered a case where a few CVE were assigned to old PHP issues without any public notice. The fixes for these issues have been published a year ago (August 2015). And I find out about these assignment through warning published by the distributions (mostly Debian, which I m close to). Sometimes things fall between the chairs, and it s perfectly OK to ask for CVE to make sure security issues do get attention even if time has passed. But after the issues (and fixes) are public, I don t see a reason to do so without making the request itself public as well. And even if the request wasn t public, at least notify upstream so this info can be added to the right places. Most of these bug were found out when I started to add sequential number into the CVE search after getting an a notice from Debian for two of the issues. And while working on processing these issues for PHP, I also notice they weren t updated for libGD where appropriate (including recent issues). Beyond keeping the eco-system up to date, another aspect of publicity is getting opinions from other parties. For example, in the case of CVE-2015-8879, RedHat doesn t agree with the classification of the bug as security. To give an example of a way things should happen is the request of CVE for PHP 5.5.34 in April, in which the Gentoo security team asked for assignment without upstream knowledge, Debian representative CCs upstream (Thanks!) and also asks CVE for issues covered by Ubuntu, to which the Ubuntu guy then adds some details. I hope this blog post will reach the anonymous people behind these CVE requests, and also the people assigning them. Without transparency and keeping things in synchronization, the idea of having a centralized location for security warning is not going to accomplish its goals.
Filed under: Debian GNU/Linux, PHP

Michal Čihař: uTidylib 0.3

Several years ago I've complained about uTidylib not being maintained upstream. Since that time I've occasionally pushed some fixes to my GitHub repository with uTidylib code, but without any clear intentions to take it over. Time has gone and there was still no progress and I started to consider becoming upstream maintainer as well. I quickly got approval from Cory Dodt, who was the original author of this code, unfortunately he is not owner of the PyPI entry and the claim request seems to have no response (if you know how to get in touch with "cntrlr" or how to take over PyPI module please let me know). Anyway the amount of patches in my repository is big enough to warrant new release. Additionally Debian bug report about supporting new HTML tidy library came in and that made me push towards releasing 0.3 version of the uTidylib. As you might guess, the amount of changes against original uTidylib is quite huge, to name the most important ones: Anyway as I can not update PyPI entry, the downloads are currently available only on my website: https://cihar.com/software/utidylib/

Filed under: Debian English uTidylib 0 comments

Joey Hess: twenty years of free software -- part 10 shell-monad

shell-monad is a small project, done over a couple days and not needing many changes since, but I'm covering it separately because it was a bit of a milestone for me. As I learned Haskell, I noticed that the libraries were excellent and did things to guide their users that libraries in other languages don't do. Starting with using types and EDSLs and carefully constrained interfaces, but going well beyond that, as far as applying category theory. Using these libraries push you toward good solutions. shell-monad was a first attempt at building such a library. The shell script it generates should always be syntactically valid, and never forgets to quote a shell variable. That's only the basics. It goes further by making it impossible to typo the name of a shell variable or shell function. And it uses phantom types so that the Haskell type checker can check the types of shell variables and functions match up. So I think shell-monad is pretty neat, and I certianly learned a lot about writing Haskell libraries making it. Including how much I still have to learn! I have not used shell-monad much, but keep meaning to make propellor and git-annex use it for some of their shell script needs. And ponder porting etckeeper to generate its shell scripts using it. Next: twenty years of free software -- part 11 concurrent-output

Petter Reinholdtsen: Unlocking HTC Desire HD on Linux using unruu and fastboot

Yesterday, I tried to unlock a HTC Desire HD phone, and it proved to be a slight challenge. Here is the recipe if I ever need to do it again. It all started by me wanting to try the recipe to set up an hardened Android installation from the Tor project blog on a device I had access to. It is a old mobile phone with a broken microphone The initial idea had been to just install CyanogenMod on it, but did not quite find time to start on it until a few days ago. The unlock process is supposed to be simple: (1) Boot into the boot loader (press volume down and power at the same time), (2) select 'fastboot' before (3) connecting the device via USB to a Linux machine, (4) request the device identifier token by running 'fastboot oem get_identifier_token', (5) request the device unlocking key using the HTC developer web site and unlock the phone using the key file emailed to you. Unfortunately, this only work fi you have hboot version 2.00.0029 or newer, and the device I was working on had 2.00.0027. This apparently can be easily fixed by downloading a Windows program and running it on your Windows machine, if you accept the terms Microsoft require you to accept to use Windows - which I do not. So I had to come up with a different approach. I got a lot of help from AndyCap on #nuug, and would not have been able to get this working without him. First I needed to extract the hboot firmware from the windows binary for HTC Desire HD downloaded as 'the RUU' from HTC. For this there is is a github project named unruu using libunshield. The unshield tool did not recognise the file format, but unruu worked and extracted rom.zip, containing the new hboot firmware and a text file describing which devices it would work for. Next, I needed to get the new firmware into the device. For this I followed some instructions available from HTC1Guru.com, and ran these commands as root on a Linux machine with Debian testing:
adb reboot-bootloader
fastboot oem rebootRUU
fastboot flash zip rom.zip
fastboot reboot
The flash command apparently need to be done twice to take effect, as the first is just preparations and the second one do the flashing. The adb command is just to get to the boot loader menu, so turning the device on while holding volume down and the power button should work too. With the new hboot version in place I could start following the instructions on the HTC developer web site. I got the device token like this:
fastboot oem get_identifier_token 2>&1   sed 's/(bootloader) //'
And once I got the unlock code via email, I could use it like this:
fastboot flash unlocktoken Unlock_code.bin
And with that final step in place, the phone was unlocked and I could start stuffing the software of my own choosing into the device. So far I only inserted a replacement recovery image to wipe the phone before I start. We will see what happen next. Perhaps I should install Debian on it. :)

Daniel Pocock: Can you help with monitoring packages in Debian and Ubuntu?

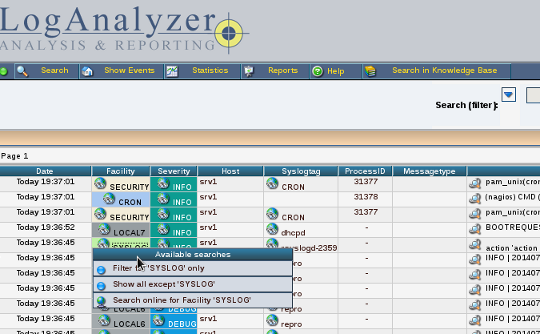
Debian (and consequently Ubuntu) contains a range of extraordinarily useful monitoring packages. I've been maintaining several of them at a basic level but as more of my time is taken up by free Real-Time Communications software, I haven't been able to follow the latest upstream releases for all of the other packages I maintain. The versions we are distributing now still serve their purpose well, but as some people would like newer versions, I don't want to stand in the way. Monitoring packages are for everyone. Even if you are a single user or developer with a single desktop or laptop and no servers, you may still find some of these packages useful. For example, after doing an apt-get upgrade or dist-upgrade, it can be extremely beneficial to look at your logs in LogAnalyzer with all the errors and warnings colour-coded so you can see at a glance whether your upgrade broke anything. If you are testing new software before a release or trying to troubleshoot erratic behavior, this type of colour-coded feedback can also help you focus on possible problems without the eyestrain of tailing a logfile. LogAnalyzer How to help A good first step is simply looking over the packages maintained by the pkg-monitoring group and discovering whether any of them are useful for your own needs. You may be familiar with alternatives that exist in Debian, if so, feel free to comment on whether you believe any of these packages should be dropped by cre

ating a wishlist bug against the package concerned. The next step is joining the pkg-monitoring mailing list. If you are a Debian Developer or Debian Maintainer with upload rights already, you can join the group on alioth. If you are not at that level yet, you are still very welcome to test new versions of the packages and upload them on mentors.debian.net and then join the mentors mailing list to look for a member of the community who can help review your work and sponsor an upload for you. Each of the packages should have a README.source file in the repository explaining more about how the package is maintained. Familiarity with Git is essential. Note that all of the packages keep their debian/* artifacts in a branch called debian/sid while the master branch tracks the upstream repository. You can clone the Debian package repositories for any of these projects from alioth and build them yourself, try building packages of new upstream versions and try to investigate any of the bug reports submitted to Debian. Some of the bugs may have already been fixed by upstream changes and can be marked appropriately. Integrating your monitoring systems Two particular packages I would like to highlight are ganglia-nagios-bridge and syslog-nagios-bridge. They are not exclusively for Nagios and could also be used with Icinga or other monitoring dashboards. The key benefit of these packages is that all the alerting is consolidated in a single platform, Nagios, which is able to display them in a colour-coded dashboard and intelligently send notifications to people in a manner that is fully configurable. If you haven't integrated your monitoring systems already, these projects provide a simple and lightweight way to start doing so.

Ben Hutchings: Debian LTS work, June 2016

I was assigned another 15 hours of work by Freexian's Debian LTS initiative and carried over 5 from last month. I worked a total of 19 hours, carrying over 1. I spent a week in the Front Desk role and triaged many new security issues for wheezy. I prepared the Linux 3.2.81 stable update, sent it out for review and finally released it. I then rebased the wheezy-security branch on top of that and added some later security fixes that were not yet suitable for a kernel.org update. I uploaded to wheezy-security and issued DLA-516-1. I started working on the next Linux stable updates (3.2.82 and the next wheezy LTS update) and on an update for imagemagick, but haven't uploaded anything for them yet.

Markus Koschany: My Free Software Activities in June 2016

My monthly report covers what I have been doing for Debian. I write it for Debian s Long Term Support sponsors but also for the wider free software community in the hope that it might inspire people to get more involved with Debian or free software in general. Debian Android Debian Games Debian Java Debian LTS This was my fifth month as a paid contributor and I have been paid to work 19,75 hours on Debian LTS. In that time I did the following: QA uploads
6 July 2016

Daniel Pocock: Avoiding SMS vendor lock-in with SMPP

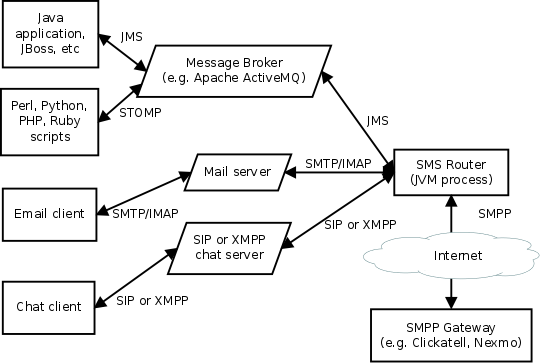
There is increasing demand for SMS notifications about monitoring alerts, trading notifications, flight delays and other events. Various companies are offering SMS transmission services to meet this demand and many of them aggressively pushing their own proprietary interfaces to the SMS world rather than using the more open and widely supported SMPP. There is good reason for this: if users write lots of of scripts to access the REST API of an SMS service, the users won't be able to change their service provider without having to change all their code. Well, that is good if you are an SMPP vendor but not if you are their customer. If an SMS gateway company goes out of business or has a system meltdown, the customers linked to their REST API will have a much bigger effort to migrate to a new provider than those using SMPP. The HTTP REST APIs offered by many vendors hide some details of the SMS protocol and payload. At first glance, this may feel easier. In fact, this leads to unpredictable results when delivering messages to users in different countries and different character sets/languages. It is better to start with SMPP from the beginning and avoid discovering those pitfalls later. The SMS Router free/open source software project helps overcome the SMPP learning curve by using APIs you are already familiar with. More troublesome for large organizations, some of the REST APIs offered by SMS gateways want to make callbacks to your own servers: this means your servers need public IP addresses accessible from the Internet. In some organizations that can take months to organize. SMPP works over one or more outgoing TCP connections initiated from your own server(s) and doesn't require any callback connections from the SMPP gateway. SMS Router lets SMS users have the best of both worlds: the flexibility of linking to any provider who supports SMPP and the convenience of putting messages into the system using any of the transports supported by an Apache Camel component. Popular examples include camel-jms (JMS) for Java and J2EE users, STOMP for scripting languages, camel-mail (SMTP and IMAP) for email integration and camel-sip (SIP) or camel-xmpp (XMPP) for chat/instant messaging systems. If you really want to, you can also create your own in-house HTTP REST API too using camel-restlet for internal applications. In all these cases, SMS Router always uses standard SMPP to reach any gateway of your choice. Architecture overview SMS Router is based on Apache Camel. Multiple instances can be operated in parallel for clustering, load balancing and high availability. It can be monitored using JMX solutions such as JMXetric. The SMPP support is based on the camel-smpp component which is in turn based on the jSMPP library, which comprehensively implements the SMPP protocol in Java. camel-smpp can be used with minimal configuration but for those who want to, many SMPP features can be tweaked on a per-message basis using various headers. The SMPP gateway settings can be configured and changed at will using the sms-router.properties file. The process doesn't require any other files or databases at runtime. The SMS Router is ready-to-run with one queue for sending messages and another queue for incoming messages. The routing logic can be customized by editing the RouteBuilder class to use other Camel components or any of Camel's wide range of functions for inspecting, modifying and routing messages. For example, you can extend it to failover to multiple SMPP gateways using Camel's load-balancer pattern. SMS Router based projects are already used successfully in production, for example, the user registration mechanism for the Lumicall secure VoIP app for Android. Getting started See the README for instructions. Feel free to ask questions about this project on the Camel users mailing list. Disclaimer SMS is not considered secure, the SMS Router developers and telecommunications industry experts discourage the use of this technology for two-factor authentication. Please see the longer disclaimer in the README file and my earlier blog about SMS logins: an illusion of security. The bottom line: if your application is important enough to need two-factor authentication, do it correctly using smart cards or tokens. There are many popular free software projects based on these full cryptographic solutions, for example, the oath-toolkit and dynalogin.

Mike Gabriel: [Arctica Project] Release of nx-libs (version 3.5.99.0)

Introduction NX is a software suite which implements very efficient compression of the X11 protocol. This increases performance when using X applications over a network, especially a slow one. NX (v3) has been originally developed by NoMachine and has been Free Software ever since. Since NoMachine obsoleted NX (v3) some time back in 2013/2014, the maintenance has been continued by a versatile group of developers. The work on NX (v3) is being continued under the project name "nx-libs". History Until January 2015, nx-libs was more mainly a redistribution approach of the original NX (v3) software. We (we as in mainly a group of X2Go developers) kept changes applied to the original NoMachine sources as minimal as possible. We also kept the original files and folders structure. Patches had been maintained via the quilt utility on top of a Git repository, the patches had always been kept separate. That was the 3.5.0.x series of nx-libs. In January 2015, the characteristics of nx-libs as maintained by the X2Go project between 2011 and 2015 changed. A decision was reached: This effort is now about to be released as "nx-libs 3.6.0.0". Contributors Since 2011, the nx-libs code base has to a great extent been maintained in the context of the X2Go Project [1]. Qindel Group joining in... In 2014, developers from the Qindel Group [2] joined the nx-libs maintenance. They found X2Go's work on nx-libs and suggested joining forces as best as possible on hacking nx-libs. The Arctica Project comming up... Starting in January 2015, the development on the 3.6.x branch of the project was moved into a new project called the Arctica Project [3]. Development Funding by Qindel In September 2015, a funding project was set up at Qindel. Since then, the Qindel group greatly supports the development of nx-libs 3.6.x monetarily and with provided man power. The funding project officially is a cooperation between Qindel and DAS-NETZWERKTEAM (business run by Mike Gabriel, long term maintainer of nx-libs). The funding is split into two subprojects and lasts until August 2017: The current nx-libs development effort is coordinated in the context of the Arctica Project (by Mike Gabriel), with use cases in Arctica, X2Go and TheQVD (VDI product worked on at Qindel) in mind. People involved There are various people involved in nx-libs 3.6.x maintenance and development, some of them shall be explicitly named here (in alphabetical order of surnames): Some other people have contributed, but have left the project already. Thanks for your work on nx-libs: A big thanks to everyone involved!!! Special thanks go to Stefan Baur for employing Mihai Moldovan and handling all the bureaucracy, so that Mihai can work on this project and get funded for his work. Achievements of nx-libs 3.5.99.0 We are very close to our self-defined release goal 3.6.0. The below tasks have already been (+/-) completed for version 3.5.99.0: In a previous blog post [4], the code reduction in nx-libs has already been discussed. With this announcement, we want to give a status update about our effort of shrinking the nx-libs code base:
    [mike@minobo nx-libs (3.6.x)]$ cloc --match-f '.*\.(c cpp h)' .
        1896 text files.
        1896 unique files.                                          
        7430 files ignored.
    http://cloc.sourceforge.net v 1.60  T=5.88 s (307.3 files/s, 143310.5 lines/s)
    -------------------------------------------------------------------------------
    Language                     files          blank        comment           code
    -------------------------------------------------------------------------------
    C                              958          68574          74891         419638
    C/C++ Header                   730          25683          33957         130418
    C++                            120          17007          11721          61292
    -------------------------------------------------------------------------------
    SUM:                          1808         111264         120569         611348
    -------------------------------------------------------------------------------
The previous statistics had these sums in the last line. First the nx-libs 3.5.0.x code tree (where we came from):
    -------------------------------------------------------------------------------
    SUM:                          5614         329279         382337        1757743
    -------------------------------------------------------------------------------
Then the nx-libs 3.6.x status as it was on May 9th 2016:
    -------------------------------------------------------------------------------
    SUM:                          1922         118581         126783         662635
    -------------------------------------------------------------------------------
Another 50.000 lines of code have been removed over the past two months. Work pending for the final 3.6.0 release goal Known Issues There are several open issues on the nx-libs Github project space, see https://github.com/ArcticaProject/nx-libs/issues. Testing the nx-libs 3.5.99.0 We are currently working on provisioning release builds and nightly builds of nx-libs for various recent Linux distributions. Please stay tuned and watch Mike Gabriel's blog [5]. We already have nightly builds of nx-libs for Debian and Ubuntu [6], but there are more to come soon. Until now, please use the build recipes provided in the README.md file of the nx-libs source tree [7]. References

4 July 2016

Benjamin Mako Hill: Studying the relationship between remixing & learning

With more than 10 million users, the Scratch online community is the largest online community where kids learn to program. Since it was created, a central goal of the community has been to promote remixing the reworking and recombination of existing creative artifacts. As the video above shows, remixing programming projects in the current web-based version of Scratch is as easy is as clicking on the see inside button in a project web-page, and then clicking on the remix button in the web-based code editor. Today, close to 30% of projects on Scratch are remixes. Remixing plays such a central role in Scratch because its designers believed that remixing can play an important role in learning. After all, Scratch was designed first and foremost as a learning community with its roots in the Constructionist framework developed at MIT by Seymour Papert and his colleagues. The design of the Scratch online community was inspired by Papert s vision of a learning community similar to Brazilian Samba schools (Henry Jenkins writes about his experience of Samba schools in the context of Papert s vision here), and a comment Marvin Minsky made in 1984:
Adults worry a lot these days. Especially, they worry about how to make other people learn more about computers. They want to make us all computer-literate. Literacy means both reading and writing, but most books and courses about computers only tell you about writing programs. Worse, they only tell about commands and instructions and programming-language grammar rules. They hardly ever give examples. But real languages are more than words and grammar rules. There s also literature what people use the language for. No one ever learns a language from being told its grammar rules. We always start with stories about things that interest us.
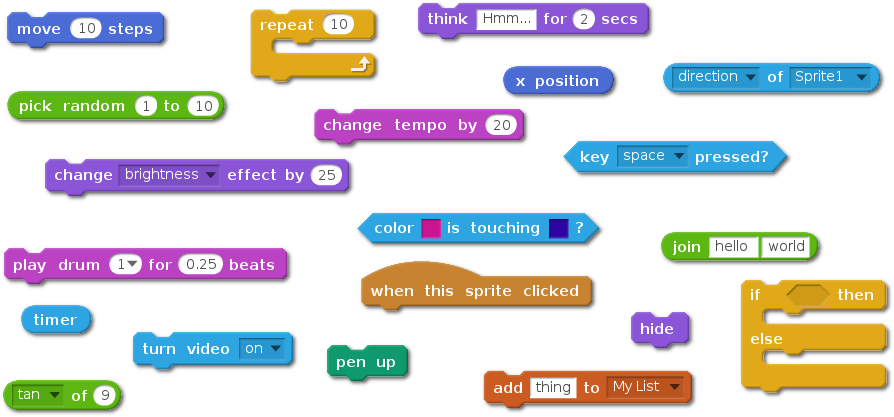
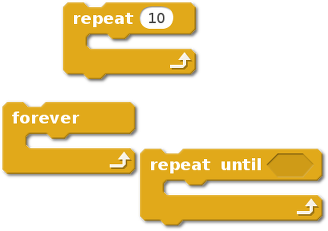
In a new paper titled Remixing as a pathway to Computational Thinking that was recently published at the ACM Conference on Computer Supported Collaborative Work and Social Computing (CSCW) conference, we used a series of quantitative measures of online behavior to try to uncover evidence that might support the theory that remixing in Scratch is positively associated with learning. scratchblocksOf course, because Scratch is an informal environment with no set path for users, no lesson plan, and no quizzes, measuring learning is an open problem. In our study, we built on two different approaches to measure learning in Scratch. The first approach considers the number of distinct types of programming blocks available in Scratch that a user has used over her lifetime in Scratch (there are 120 in total) something that can be thought of as a block repertoire or vocabulary. This measure has been used to model informal learning in Scratch in an earlier study. Using this approach, we hypothesized that users who remix more will have a faster rate of growth for their code vocabulary. Controlling for a number of factors (e.g. age of user, the general level of activity) we found evidence of a small, but positive relationship between the number of remixes a user has shared and her block vocabulary as measured by the unique blocks she used in her non-remix projects. Intriguingly, we also found a strong association between the number of downloads by a user and her vocabulary growth. One interpretation is that this learning might also be associated with less active forms of appropriation, like the process of reading source code described by Minksy. The second approach we used considered specific concepts in programming, such as loops, or event-handling. To measure this, we utilized a mapping of Scratch blocks to key programming concepts found in this paper by Karen Brennan and Mitchel Resnick. For example, in the image below are all the Scratch blocks mapped to the concept of loop . scratchblocksctWe looked at six concepts in total (conditionals, data, events, loops, operators, and parallelism). In each case, we hypothesized that if someone has had never used a given concept before, they would be more likely to use that concept after encountering it while remixing an existing project. Using this second approach, we found that users who had never used a concept were more likely to do so if they had been exposed to the concept through remixing. Although some concepts were more widely used than others, we found a positive relationship between concept use and exposure through remixing for each of the six concepts. We found that this relationship was true even if we ignored obvious examples of cutting and pasting of blocks of code. In all of these models, we found what we believe is evidence of learning through remixing. Of course, there are many limitations in this work. What we found are all positive correlations we do not know if these relationships are causal. Moreover, our measures do not really tell us whether someone has understood the usage of a given block or programming concept.However, even with these limitations, we are excited by the results of our work, and we plan to build on what we have. Our next steps include developing and utilizing better measures of learning, as well as looking at other methods of appropriation like viewing the source code of a project.

This blog post and the paper it describes are collaborative work with Sayamindu Dasgupta, Andr s Monroy-Hern ndez, and William Hale. The paper is released as open access so anyone can read the entire paper here. This blog post was also posted on Sayamindu Dasgupta s blog and on Medium by the MIT Media Lab.

Paul Wise: Check All The thingS!

check-all-the-things (aka cats, Meow!) is a tool that aims to make it easy to know which tools can be used to check a directory tree and to make it easy to run those tools on the directory tree. The tree could either be a source tree or a build tree or both. It aims to check as much of the tree as possible so the output can be very verbose and have many false positives. It is not for the busy, lazy or noise intolerant. It runs the checks by matching file names and MIME types against those registered for a list of checks. Each check has a set of dependencies, flags, filename wildcards, MIME type wildcards, comments and prerequisite commands. By default it: It runs all checks for the current distro/release except: There are command-line options to customise the behaviour and automatic bash shell completion via argcomplete. There are 177 checks (including TODO ones) in 73 different categories. There are an additional 224 not-well-specified TODO items for new checks in comments. It is exceptionally easy to add new checks once one knows how to use the tool one wants to add. At this point in time it is probably not a good idea to run it in an untrusted directory tree for several reasons: The project initially started as really hacky wiki page full of commands to run. At some point I figured it was time to make this actually be maintainable and started on a project to do that. At around the same time Jakub Wilk was working on maquack to replace the wiki page. Somehow I found out about it and talked to him about it. It was vastly less hacky than my version so I ended up taking it over and continuing it under the check-all-the-things name. I polished it for the last two years and finally released it into Debian unstable during DebCamp16.

3 July 2016

Reproducible builds folks: Reproducible builds: week 61 in Stretch cycle

What happened in the Reproducible Builds effort between June 19th and June 25th 2016. Media coverage GSoC and Outreachy updates Toolchain fixes Other upstream fixes Emil Velikov searched on IRC for hints on how to guarantee unique values during build to invalidate shader caches in Mesa, when also no VCS information is available. A possible solution is a timestamp, which is unique enough for local builds, but can still be reproducible by allowing it to be overwritten with SOURCE_DATE_EPOCH. Packages fixed The following 9 packages have become reproducible due to changes in their build dependencies: cclib librun-parts-perl llvm-toolchain-snapshot python-crypto python-openid r-bioc-shortread r-bioc-variantannotation ruby-hdfeos5 sqlparse The following packages have become reproducible after being fixed: Some uploads have fixed some reproducibility issues, but not all of them: Patches submitted that have not made their way to the archive yet: Package reviews 139 reviews have been added, 20 have been updated and 21 have been removed in this week. New issues found: 53 FTBFS bugs have been reported by Chris Lamb, Santiago Vila and Mateusz ukasik. diffoscope development Quote of the week "My builds are so reproducible, they fail exactly every second time." Johannes Ziemke (@discordianfish) Misc. This week's edition was written by Chris Lamb (lamby), Reiner Herrmann and Holger Levsen and reviewed by a bunch of Reproducible builds folks on IRC.

Joey Hess: twenty years of free software -- part 7 git-annex

My first Haskell program, and the only software I've written that was inspired by living in a particular place, git-annex has received the lion's share of my time for five years. It was written just to solve my own problem, but in a general way, that turned out to be useful in lots of other situations. So over the first half a year or so, it started attracting some early adopters who made some very helpful suggestions. Then I did the git-annex assistant kickstarter, and started blogging about each day I worked on it. Four years of funding and seven hundred and twenty one posts later, the git-annex devblog is still going. So, I won't talk about technical details in this post, they've all been covered. One thing I wondered when starting git-annex -- besides whether I would be able to write it in Haskell at all -- was would that prevent it from getting many patches. I count roughly 65 "thanks" messages in the changelog, so it gets perhaps one patch contributed per month. It's hard to say if that's a lot or a little. Part of git-annex is supporting various cloud storage systems via "special remotes". Of those not written by me, only 1 was contributed in Haskell. Compare with 13 that use the plugin system that lets other programming languages be used. The other question about using Haskell is, did it make git-annex a better program. I think it did. The strong type system did prevent plenty of bugs, although there have still been some real howlers. The code is still not taking full advantage of the power of Haskell's type system, on the other hand it uses many Haskell libraries that do leverage the type system more. I've done more small and large refactorings of git-annex than on any other program I've written, because the strong types and referential transparency makes refactoring easier and safer in Haskell. And the code has turned out to be much more flexible, for all its static types, than the kind of code I was writing before. Examples include building the git-annex assistant, which uses the rest of git-annex as a library, and making git-annex run actions concurrently, thanks to there being no global variables to complicate things (and excellent support for concurrency and parallelism in Haskell). So: Glad I wrote it, glad I used Haskell for it, estatic that many other people have found it useful, and astounded that I've been funded to work on it for four years. Next: twenty years of free software -- part 8 github-backup

Iustin Pop: A relaxation week

A (forced) relaxation week This was an interesting week, much more so than I expected. The start of the week was the usual: on Monday a run, although at an easier pace after Sunday's longer indoor bike ride, on Tuesday a 30Km outside bike ride (flat, on road, with a mountain bike so not fast at all). On Wednesday however, I had a planned "intervention" at my dentist bone reconstruction (or regeneration, not sure what the right term is for the implantation of scaffolding). The dentist told me I won't be allowed to do sports, especially in the first few days after the procedure, so I knew I will have to take it easy; easy bike rides are fine, but not anything more (e.g. especially not running). The procedure went well and after that I went to work (the dentist looked at me in a funny way when I mentioned I'm not going home but instead back to work). There was a bit of pain a couple of hours after the local anaesthesia went away, but the painkillers did work, so I was able to function somewhat OK. Laughing was the only thing that caused pain, so I tried to be very serious; didn't work well On Thursday morning however, I did feel funny and when I looked into the mirror, I got a shock. The affected side of my face was heavily swollen, and I was feeling as bad as I looked. I had a followup checkup at the dentist, so I went there, and they told me Oh, this is normal. Bone reconstruction is much more difficult on the body as opposed to extraction, since the body actually has to rebuild stuff, instead of just healing the wound. And yes, you should just go back home and take the day off! . OK, logically that explanation makes sense, but my dental extraction had a very predictable pain/recovery curve (spike right at the extraction, plateau for that day, then slow recovery that went to faster recovery after a few days). This procedure was very different, with the first day easy, and the second day much worse. The dentist continued Oh, and by the way, expect this to be worse in the morning, as the body can work all night; also, this should go away by itself over the weekend, so let's meet again on Monday. At this point I realised than I'm not allowed to do sports is not by doctor's orders, but rather my condition doesn't allow me to do sport . Sad panda Friday was even worse; my face was swollen in a different way, such that I looked even more like a monster from the Witcher games. I had to stay at home again, not being able to do much, as the painkillers I got were mostly ineffective. From my usual ~10K steps a day (or more if I run), my Friday was a paltry sub-2K step day. The only thing I was able to do was watch anime. I found Log Horizon to be a pretty interesting anime, much more so than what the synopsis said; the ramification on politics and how to interaction between the two cultures unfolded was much more in-depth than I presumed. Didn't finish it yet, so this is a partial but very strong recommendation for it. Besides watching stuff, I also went to the shop to buy some food, which turned out to be an excuse for "junk food foraging!". The pain took my willpower away and instead of the planned and short grocery list, I found myself with lots of chocolate and ice cream on my hands. Funny how the brain works On Saturday I was a bit better; the swelling went partially away, so if you squinted you could pretend I look my normal-ugly, not the monster-ugly from before. I was able to go outside of the house, do some shopping, etc. so I was able to go back to a ~9K steps day. I also stopped taking painkillers since anyway they weren't of much help, and kept myself entertained with movies and other stuff (cough cough Grim Dawn , since it's a mindless click-kill-loot-repeat ARPG that one can play even when only partially functional). Today (Sunday) was swelling was slightly worse; however, I was feeling well enough to try to go back on the bike trainer (the first three days of "no sports" were over), and planned to do a slow/relaxing one hour Zwift ride. Right, as all the people who ever tried this, it works as long as only fast people overtake you (since you can't catch them anyway), or as long as you don't get to sprint sections. I did slightly improve my Watopia 300m sprint personal record (29.20s 28.29s), which was good enough. After the first lap I took it easier as in had to, since I was not really in shape. I was in any case very glad about ending my 4 days long break from sports! So, my dentist was right indeed. The swelling did by and large clear up over the weekend (although I'll have to see how tomorrow will be), and was also right about how much more difficult this was. On one hand makes sense (growing bone does sound complex), on the other hand, I couldn't imagine that the body works so hard that it puts you out. The dentist was however slightly wrong with the you should not do any strenuous activity, especially in the first three days ; they should have said, ha ha, you'll be flat out for the first days, take it easy and enjoy the painkillers instead. Looking forward now to get back into my regular routine; relaxation is good, but only when done by choice like most things in life

Jonathan McDowell: Confirming all use of an SSH agent

For a long time I ve wanted an ssh-agent setup that would ask me before every use, so I could slightly more comfortably forward authentication over SSH without worrying that my session might get hijacked somewhere at the remote end (I often find myself wanting to pull authenticated git repos on remote hosts). I m at DebConf this week, which is an ideal time to dig further into these things, so I did so today. As is often the case it turns out this is already possible, if you know how. I began with a setup that was using GNOME Keyring to manage my SSH keys. This isn t quite what I want (eventually I want to get to the point that I can sometimes forward a GPG agent to remote hosts for signing purposes as well), so I set about setting up gpg-agent. I used Chris excellent guide to GnuPG/SSH Agent setup as a starting point and ended up doing the following:

$ echo use-agent >> ~/.gnupg/options
$ echo enable-ssh-support >> ~/.gnupg/gpg-agent.conf
$ sudo sed -i.bak "s/^use-ssh-agent/# use-ssh-agent/" /etc/X11/Xsession.options
$ sudo rm /etc/xdg/autostart/gnome-keyring-ssh.desktop
The first 2 commands setup my local agent, and told it to do SSH agent foo. The next stopped X from firing up ssh-agent, and the final one prevents GNOME Keyring from being configured to be the SSH agent, without having to remove libpam-gnome-keyring as Chris did. After the above I logged out of and into X again, and could see ~/.gnupg/S.gpg-agent.ssh getting created and env grep SSH showing SSH_AUTH_SOCK pointing to it (if GNOME Keyring is still handling things it ends up pointing to something like /run/user/1000/keyring/ssh). [Update: Luca Capello emailed to point out this was a bad approach; there s thankfully no need to do the last 2 commands that require root. #767341 removed the need to edit Xsession.options and you can prevent GNOME Keyring starting on a per user basis with:
(cat /etc/xdg/autostart/gnome-keyring-ssh.desktop ;
 echo 'X-GNOME-Autostart-enabled=false') > \
 ~/.config/autostart/gnome-keyring-ssh.desktop
] After this it turned out all I need to do was ssh-add -c <ssh keyfile>. The -c says confirm use and results in the confirm flag being appended to the end of ~/.gnupg/sshcontrol (so if you ve already done the ssh-add you can go and add the confirm if that s the behaviour you d like). Simple when you know how, but I ve had conversations with several people in the past who wanted the same thing and hadn t figured out how, so hopefully this is helpful to others.

Elena 'valhalla' Grandi: Debconf streaming and kudos to the video team

Debconf streaming and kudos to the video team

With http://debconf16.debconf.org/ being in South Africa, a lot of people (like me) probably weren't able to attend and are missing the cheese and wine party, mao games and general socialization that is happening there.

One thing we don't have to miss, however, are the talks: as usual the video team https://wiki.debconf.org/wiki/DebConf16/Videoteam is doing a great job recording and https://debconf16.debconf.org/video/live-streaming/ all talks so that people can still participate a bit from their home.

What they do, however, requires a lot of manpower, so if you are attending Debconf please consider volunteering https://wiki.debconf.org/wiki/Videoteam/roles_for_volunteers to help: from my experience last year they are very nice people who are welcoming towards new contributors and they have periodical training sessions to help people getting started with the various tasks. More informations about video team meetings and training session are in the topic of the IRC channel, #debconf-video@OFTC.

I don't think there are cookies involved (which just proves that the video team isn't evil), but you may get a t-shirt and you will get a warm fuzzy feeling of having helped people around the world.

@Debian #debconf

Petter Reinholdtsen: How to use the Signal app if you only have a land line (ie no mobile phone)

For a while now, I have wanted to test the Signal app, as it is said to provide end to end encrypted communication and several of my friends and family are already using it. As I by choice do not own a mobile phone, this proved to be harder than expected. And I wanted to have the source of the client and know that it was the code used on my machine. But yesterday I managed to get it working. I used the Github source, compared it to the source in the Signal Chrome app available from the Chrome web store, applied patches to use the production Signal servers, started the app and asked for the hidden "register without a smart phone" form. Here is the recipe how I did it. First, I fetched the Signal desktop source from Github, using
git clone https://github.com/WhisperSystems/Signal-Desktop.git
Next, I patched the source to use the production servers, to be able to talk to other Signal users:
cat <<EOF   patch -p0
diff -ur ./js/background.js userdata/Default/Extensions/bikioccmkafdpakkkcpdbppfkghcmihk/0.15.0_0/js/background.js
--- ./js/background.js  2016-06-29 13:43:15.630344628 +0200
+++ userdata/Default/Extensions/bikioccmkafdpakkkcpdbppfkghcmihk/0.15.0_0/js/background.js    2016-06-29 14:06:29.530300934 +0200
@@ -47,8 +47,8 @@
          );
      );
 
-    var SERVER_URL = 'https://textsecure-service-staging.whispersystems.org';
-    var ATTACHMENT_SERVER_URL = 'https://whispersystems-textsecure-attachments-staging.s3.amazonaws.com';
+    var SERVER_URL = 'https://textsecure-service-ca.whispersystems.org:4433';
+    var ATTACHMENT_SERVER_URL = 'https://whispersystems-textsecure-attachments.s3.amazonaws.com';
     var messageReceiver;
     window.getSocketStatus = function()  
         if (messageReceiver)  
diff -ur ./js/expire.js userdata/Default/Extensions/bikioccmkafdpakkkcpdbppfkghcmihk/0.15.0_0/js/expire.js
--- ./js/expire.js      2016-06-29 13:43:15.630344628 +0200
+++ userdata/Default/Extensions/bikioccmkafdpakkkcpdbppfkghcmihk/0.15.0_0/js/expire.js2016-06-29 14:06:29.530300934 +0200
@@ -1,6 +1,6 @@
 ;(function()  
     'use strict';
-    var BUILD_EXPIRATION = 0;
+    var BUILD_EXPIRATION = 1474492690000;
 
     window.extension = window.extension    ;
 
EOF
The first part is changing the servers, and the second is updating an expiration timestamp. This timestamp need to be updated regularly. It is set 90 days in the future by the build process (Gruntfile.js). The value is seconds since 1970 times 1000, as far as I can tell. Based on a tip and good help from the #nuug IRC channel, I wrote a script to launch Signal in Chromium.
#!/bin/sh
cd $(dirname $0)
mkdir -p userdata
exec chromium \
  --proxy-server="socks://localhost:9050" \
  --user-data-dir= pwd /userdata --load-and-launch-app= pwd 
The script start the app and configure Chromium to use the Tor SOCKS5 proxy to make sure those controlling the Signal servers (today Amazon and Whisper Systems) as well as those listening on the lines will have a harder time location my laptop based on the Signal connections if they use source IP address. When the script starts, one need to follow the instructions under "Standalone Registration" in the CONTRIBUTING.md file in the git repository. I right clicked on the Signal window to get up the Chromium debugging tool, visited the 'Console' tab and wrote 'extension.install("standalone")' on the console prompt to get the registration form. Then I entered by land line phone number and pressed 'Call'. 5 seconds later the phone rang and a robot voice repeated the verification code three times. After entering the number into the verification code field in the form, I could start using Signal from my laptop. As far as I can tell, The Signal app will leak who is talking to whom and thus who know who to those controlling the central server, but such leakage is hard to avoid with a centrally controlled server setup. It is something to keep in mind when using Signal - the content of your chats are harder to intercept, but the meta data exposing your contact network is available to people you do not know. So better than many options, but not great. And sadly the usage is connected to my land line, thus allowing those controlling the server to associate it to my home and person. I would prefer it if only those I knew could tell who I was on Signal. There are options avoiding such information leakage, but most of my friends are not using them, so I am stuck with Signal for now.

Russ Allbery: Review: Coming Home

Review: Coming Home, by Jack McDevitt
Series: Alex Benedict #7
Publisher: Ace
Copyright: November 2014
Printing: November 2015
ISBN: 0-425-26088-7
Format: Mass market
Pages: 356
Coming Home is a direct sequel to Firebird, the first time McDevitt has done that in this series. You therefore don't want to start here, although the nature of the sequel doesn't require that you remember Firebird in that much detail. The mystery of the disappearing starships was understood in Firebird but not resolved. The title advertises that as a major theme in this book, but it progresses very slowly. There's more media bickering and various factional attempts to draw Alex (and, to a lesser extent, Chase) into the controversies. McDevitt does a good job writing popular media, the strange position of public intellectual and talk-show favorite, and the way this filters into popular arguments. But with Alex trying to take a nuanced and unsure position and with a lot of talk but little action, it's not the most compelling reading. Coming Home holds to form in balancing a mystery and a second plot. Since the starship problem is understood, it can't be the central mystery of the book. That role is taken by the discovery of communication device from the very early days of space flight, which takes Alex and Chase to Earth for the first time in this series (at least that I can recall). This time, the search is for a legendary trove of historical artifacts that was moved from a space flight museum in Florida when the ocean rose to cover the state. From there, its location was lost in the middle of a general economic collapse called the Time of Troubles that destroyed most of Earth's governmental systems (and, apparently rather more importantly to McDevitt, the space program). Anyone who has gotten this far in the series will know the standard problem with McDevitt's futures: they're indistinguishable from the 1960s except that they have flying cars. There is a tiny break from that tradition here, since climate change has clearly happened to Earth, covering Florida with the ocean and shifting the major cities north. But the sense of deep history that McDevitt is trying for in this series doesn't work: I just don't believe as much time has gone by as the story claims. He does offer an explanation for why technology has been stagnant for apparently millennia, but it's just a contention that science ran out of more things to discover due to authorial fiat and is now just a matter of engineering and step-wise refinement. (I think the science behind the disappearing starships happening in this very same book undermines that contention considerably.) Even if one can put that aside, Earth is, well, boring. This is partly an intriguing stylistic choice by McDevitt: Earth is intended to be just one more world. It might have a longer history than many other human-occupied worlds, but history is so long everywhere that this only matters to a few people like Alex and Chase. The choice makes sense, but it doesn't make a good story. And there are other things that I flatly didn't believe, such as the supposed isolation of Earth from the communication network of Alex's home world of Rimway for... no apparent reason other than that different communication networks don't talk to each other except via, essentially, letters. Even if one is willing to ignore the mysterious failure of forward progress in technology, this makes no social or engineering sense given the capabilities already shown in the series. I found the main mystery at best mildly interesting. McDevitt does a good job showing the research and investigation process, with all its tedium and dead ends, but I wasn't as invested in the search as he wanted me to be. The endless space boosterism started getting on my nerves, as it so often does in science fiction of a certain type, and I had a much harder time swallowing McDevitt's Earth than his fictional Rimway. I will give him credit for a surprisingly affecting conclusion of the main mystery, but the missing starship subplot putters to an undistinguished end. I think this series is running out of steam. It's become increasingly formulaic, and the characters, like McDevitt's future technology, have stopped developing. I was hoping the reunion foreshadowed since Firebird would shake things up, but at least in this book it doesn't. Maybe it will in subsequent books, but I'm starting to question whether I really want to keep reading. Rating: 5 out of 10

Lisandro Dami n Nicanor P rez Meyer: Upcoming KDEPIM changes in unstable (KMail, Kontact, KOrganizer, etc)

For those who care about kdepim (kmail, kontact, korganizer, etc)

Currently the latest version of kdepim is available in experimental. According to our limited tests it's working way better than kdepim 4.14 (more stable, more performant, less bugs). However migrating from one to the other is not a trivial process (distribution wise, hopefully not for our users).

Among the drawbacks in the new kdepim: knode, ktimetracker and kjots were dropped from the official kdepim components. kjots is now an independent project, not tied to the kdepim release cycle. But more importantly, knode and ktimetracker are not maintained upstream any more, we are temporarily still shipping the old KDE 4 versions, but we will drop them after stretch unless they get new upstream maintainers.

To iron out the wrinkles that are surely still there, we are now planning to start a transition for kdepim, effectively blocking all kdepim related packages in unstable until the transition is complete. This will allow us to keep the current kdepim in testing unchanged until kdepim 16.04 is ready to migrate fully to testing.

If you want to test the new kdepim versions right now, please use the version in experimental, as uploading all the packages to unstable will take some time until there is a working kdepim in unstable (mixing experimental and the unstable uploads should be fine).

If you depend on having a working kdepim, please avoid installing the new kdepim packages that will be landing in unstable in the following days, until all the components are available. We expect this will take a couple of weeks, we will post another entry when the packages are ready in unstable.

A list of the binary packages involved in the transition can be found [here].

If you find issues in the new packages, please let us know either via irc in #debian-kde, the kde mailing list debian-kde@lists.debian.org, or send us a bug report (please make sure that it wasn't reported before).

We'll send an updated note when kdepim is fully uploaded to unstable.

Happy hacking,

The Debian Qt/KDE Team.

2 July 2016

Thorsten Alteholz: APU and Debian

I just got an APU1D4 made by PC Engines. I bought it from a German retailer called VARIA System GmbH. They are also located in Chemnitz, so at least I could support the local economy. I purchased a bundle consisting of mainboard, case, power supply and 16GB SSD. The board has 4GB RAM and three network adapters and shall replace my old PC that I use as router to the internet. As there is no VGA/HDMI output, the first hurdle was organizing a null-modem cable. Of course I could have prepared the SSD on another PC, but I wanted to try PXE. After finding the cable on the ground of a box, deeply buried under other boxes, I could start. The DHCP server got an entry
host apu1d4  
  hardware ethernet 00:0d:b9:42:a0:e8;
  fixed-address apu1d4;
  option broadcast-address 10.42.255.255;
  option routers 10.42.10.1;
  next-server 10.42.10.1;
  filename "pxelinux.0";
 
and the TFTP server got a file /tftp/pxelinux.cfg/01-00-0d-b9-42-a0-e8
default install
label install
        menu label ^Install
        menu default
        kernel debian-installer/amd64/linux
        append initrd=debian-installer/amd64/initrd.gz --- vga=off console=ttyS0,115200n8
The files debian-installer/amd64/linux and debian-installer/amd64/initrd.gz are the normal debian installer files obtained from the official Debian servers. That s it, the installer starts, spits its output over the serial line and I can install the system. Great! Thanks DebianInstaller team. Why couldn t everything be always so easy?

Next.

Previous.