Search Results: "tar"

17 July 2016

Michael Stapelberg: mergebot: easily merging contributions

Recently, I was wondering why I was pushing off accepting contributions in Debian for longer than in other projects. It occurred to me that the effort to accept a contribution in Debian is way higher than in other FOSS projects. My remaining FOSS projects are on GitHub, where I can just click the Merge button after deciding a contribution looks good. In Debian, merging is actually a lot of work: I need to clone the repository, configure it, merge the patch, update the changelog, build and upload. I wondered how close we can bring Debian to a model where accepting a contribution is just a single click as well. In principle, I think it can be done. To demonstrate the feasibility and collect some feedback, I wrote a program called mergebot. The first stage is done: mergebot can be used on your local machine as a command-line tool. You provide it with the source package and bug number which contains the patch in question, and it will do the rest:
midna ~ $ mergebot -source_package=wit -bug=#831331
2016/07/17 12:06:06 will work on package "wit", bug "831331"
2016/07/17 12:06:07 Skipping MIME part with invalid Content-Disposition header (mime: no media type)
2016/07/17 12:06:07 gbp clone --pristine-tar git+ssh://git.debian.org/git/collab-maint/wit.git /tmp/mergebot-743062986/repo
2016/07/17 12:06:09 git config push.default matching
2016/07/17 12:06:09 git config --add remote.origin.push +refs/heads/*:refs/heads/*
2016/07/17 12:06:09 git config --add remote.origin.push +refs/tags/*:refs/tags/*
2016/07/17 12:06:09 git config user.email stapelberg AT debian DOT org
2016/07/17 12:06:09 patch -p1 -i ../latest.patch
2016/07/17 12:06:09 git add .
2016/07/17 12:06:09 git commit -a --author Chris Lamb <lamby AT debian DOT org> --message Fix for  wit: please make the build reproducible  (Closes: #831331)
2016/07/17 12:06:09 gbp dch --release --git-author --commit
2016/07/17 12:06:09 gbp buildpackage --git-tag --git-export-dir=../export --git-builder=sbuild -v -As --dist=unstable
2016/07/17 12:07:16 Merge and build successful!
2016/07/17 12:07:16 Please introspect the resulting Debian package and git repository, then push and upload:
2016/07/17 12:07:16 cd "/tmp/mergebot-743062986"
2016/07/17 12:07:16 (cd repo && git push)
2016/07/17 12:07:16 (cd export && debsign *.changes && dput *.changes)
midna ~ $ cd /tmp/mergebot-743062986/repo
midna /tmp/mergebot-743062986/repo $ git log HEAD~2..
commit d983d242ee546b2249a866afe664bac002a06859
Author: Michael Stapelberg <stapelberg AT debian DOT org>
Date:   Sun Jul 17 13:32:41 2016 +0200
    Update changelog for 2.31a-3 release
commit 5a327f5d66e924afc656ad71d3bfb242a9bd6ddc
Author: Chris Lamb <lamby AT debian DOT org>
Date:   Sun Jul 17 13:32:41 2016 +0200
    Fix for  wit: please make the build reproducible  (Closes: #831331)
midna /tmp/mergebot-743062986/repo $ git push
Counting objects: 11, done.
Delta compression using up to 8 threads.
Compressing objects: 100% (11/11), done.
Writing objects: 100% (11/11), 1.59 KiB   0 bytes/s, done.
Total 11 (delta 6), reused 0 (delta 0)
remote: Sending notification emails to: dispatch+wit_vcs@tracker.debian.org
To git+ssh://git.debian.org/git/collab-maint/wit.git
   650ee05..d983d24  master -> master
 * [new tag]         debian/2.31a-3 -> debian/2.31a-3
midna /tmp/mergebot-743062986/repo $ cd ../export
midna /tmp/mergebot-743062986/export $ debsign *.changes && dput *.changes
[ ]
Uploading wit_2.31a-3.dsc
Uploading wit_2.31a-3.debian.tar.xz
Uploading wit_2.31a-3_amd64.deb
Uploading wit_2.31a-3_amd64.changes
Of course, this is not quite as convenient as clicking a Merge button yet. I have some ideas on how to make that happen, but I need to know whether people are interested before I spend more time on this. Please see github.com/Debian/mergebot for more details, and please get in touch if you think this is worthwhile or would even like to help. Feedback is accepted in the GitHub issue tracker for mergebot or the project mailing list mergebot-discuss. Thanks!

Vasudev Kamath: Switching from approx to apt-cacher-ng

After a long ~5 years (from 2011) journey with approx I finally wanted to switch to something new like apt-cacher-ng. And after a bit of changes I finally managed to get apt-cacher-ng into my work flow.
Bit of History I should first give you a brief on how I started using approx. It all started in MiniDebconf 2011 which I organized at my Alma-mater. I met Jonas Smedegaard here and from him I learned about approx. Jonas has a bunch of machines at his home and he was active user of approx and he showed it to me while explaining the Boxer project. I was quite impressed with approx. Back then I was using a 230kbps slow INTERNET connection and I was also maintaining a couple of packages in Debian. Updating the pbuilder chroots was time consuming task for me as I had to download multiple times over slow net. And approx largely solved this problem and I started using it. 5 years fast forward I now have quite fast INTERNET with good FUP. (About 50GB a month), but I still tend to use approx which makes building packages quite faster. I also use couple of containers on my laptop which all use my laptop as approx cache.
Why switch? So why change to apt-cacher-ng?. Approx is a simple tool, it runs mainly with inetd and sits between apt and the repository on INTERNET. Where as apt-cacher-ng provides a lot of features. Below are some listed from the apt-cacher-ng manual.
  • use of TLS/SSL repositories (may be possible with approx but I'm notsure how to do it)
  • Access control of who can access caching server
  • Integration with debdelta (I've not tried, approx also supports debdelta)
  • Avoiding use of apt-cacher-ng for some hosts
  • Avoiding caching of some file types
  • Partial mirroring for offline usage.
  • Selection of ipv4 or ipv6 for connections.
The biggest change I see is the speed difference between approx and apt-cacher-ng. I think this is mainly because apt-cacher-ng is threaded where as approx runs using inetd. I do not want all features of apt-cacher-ng at the moment, but who knows in future I might need some features and hence I decided to switch to apt-cacher-ng over approx.
Transition Transition from approx to apt-cacher-ng was smoother than I expected. There are 2 approaches you can use one is explicit routing another is transparent routing. I prefer transparent routing and I only had to change my /etc/apt/sources.list to use the actual repository URL.
deb http://deb.debian.org/debian unstable main contrib non-free
deb-src http://deb.debian.org/debian unstable main
deb http://deb.debian.org/debian experimental main contrib non-free
deb-src http://deb.debian.org/debian experimental main
After above change I had to add a 01proxy configuration file to /etc/apt/apt.conf.d/ with following content.
Acquire::http::Proxy "http://localhost:3142/"
I use explicit routing only when using apt-cacher-ng with pbuilder and debootstrap. Following snippet shows explicit routing through /etc/apt/sources.list.
deb http://localhost:3142/deb.debian.org/debian unstable main
Usage with pbuilder and friends To use apt-cacher-ng with pbuilder you need to modify /etc/pbuilderrc to contain following line
MIRRORSITE=http://localhost:3142/deb.debian.org/debian
Usage with debootstrap To use apt-cacher-ng with debootstrap, pass MIRROR argument of debootstrap as http://localhost:3142/deb.debian.org/debian.
Conclusion I've now completed full transition of my work flow to apt-cacher-ng and purged approx and its cache.
Though it works fine I feel that there will be 2 caches created when you use transparent and explicit proxy using localhost:3142 URL. I'm sure it is possible to configure this to avoid duplication, but I've not yet figured it. If you know how to fix this do let me know.
Update Jonas told me that its not 2 caches but 2 routing paths, one for transparent routing and another for explicit routing. So I guess there is nothing here to fix :-).

16 July 2016

Paul Tagliamonte: The Open Source License API

Around a year ago, I started hacking together a machine readable version of the OSI approved licenses list, and casually picking parts up until it was ready to launch. A few weeks ago, we officially announced the osi license api, which is now live at api.opensource.org. I also took a whack at writing a few API bindings, in Python, Ruby, and using the models from the API implementation itself in Go. In the following few weeks, Clint wrote one in Haskell, Eriol wrote one in Rust, and Oliver wrote one in R. The data is sourced from a repo on GitHub, the licenses repo under OpenSourceOrg. Pull Requests against that repo are wildly encouraged! Additional data ideas, cleanup or more hand collected data would be wonderful! In the meantime, use-cases for using this API range from language package managers pulling OSI approval of a licence programatically to using a license identifier as defined in one dataset (SPDX, for exampele), and using that to find the identifer as it exists in another system (DEP5, Wikipedia, TL;DR Legal). Patches are hugly welcome, as are bug reports or ideas! I'd also love more API wrappers for other languages!

Rapha&#235;l Hertzog: Freexian s report about Debian Long Term Support, June 2016

A Debian LTS logoLike each month, here comes a report about the work of paid contributors to Debian LTS. Individual reports In June, 158.25 work hours have been dispatched among 11 paid contributors. Their reports are available: DebConf 16 Presentation If you want to know more about how the LTS project is organized, you can watch the presentation I gave during DebConf 16 in Cape Town. Evolution of the situation The number of sponsored hours increased a little bit at 135 hours per month thanks to 3 new sponsors (Laboratoire LEGI UMR 5519 / CNRS, Quarantainenet BV, GNI MEDIA). Our funding goal is getting closer but it s not there yet. The security tracker currently lists 40 packages with a known CVE and the dla-needed.txt file lists 38 packages awaiting an update. Thanks to our sponsors New sponsors are in bold.

15 July 2016

Lars Wirzenius: Two-factor auth for local logins in Debian using U2F keys

Warning: This blog post includes instructions for a procedure that can lead you to lock yourself out of your computer. Even if everything goes well, you'll be hunted by dragons. Keep backups, have a rescue system on a USB stick, and wear flameproof clothing. Also, have fun, and tell your loved ones you love them. I've recently gotten two U2F keys. U2F is a open standard for authentication using hardware tokens. It's probably mostly meant for website logins, but I wanted to have it for local logins on my laptop running Debian. (I also offer a line of stylish aluminium foil hats.) Having two-factor authentication (2FA) for local logins improves security if you need to log in (or unlock a screen lock) in a public or potentially hostile place, such as a cafe, a train, or a meeting room at a client. If they have video cameras, they can film you typing your password, and get the password that way. If you set up 2FA using a hardware token, your enemies will also need to lure you into a cave, where a dragon will use a precision flame to incinerate you in a way that leaves the U2F key intact, after which your enemies steal the key, log into your laptop and leak your cat GIF collection. Looking up information for how to set this up, I found a blog post by Sean Brewer, for Ubuntu 14.04. That got me started. Here's what I understand: Here are the detailed steps for Debian stretch, with minute differences from those for Ubuntu 14.04. If you follow these, and lock yourself out of your system, it wasn't my fault, you can't blame me, and look, squirrels! Also not my fault if you don't wear sufficient protection against dragons.
  1. Install pamu2fcfg and libpam-u2f.
  2. As your normal user, mkdir ~/.config/Yubico. The list of allowed U2F keys will be put there.
  3. Insert your U2F key and run pamu2fcfg -u$USER > ~/.config/Yubico/u2f_keys, and press the button on your U2F key when the key is blinking.
  4. Edit /etc/pam.d/common-auth and append the line auth required pam_u2f.so cue.
  5. Reboot (or at least log out and back in again).
  6. Log in, type in your password, and when prompted and the U2F key is blinking, press its button to complete the login.
pamu2fcfg reads the hardware token and writes out its identifying data in a form that the PAM module understands; see the pam-u2f documentation for details. The data can be stored in the user's home directory (my preference) or in /etc/u2f_mappings. Once this is set up, anything that uses PAM for local authentication (console login, GUI login, sudo, desktop screen lock) will need to use the U2F key as well. ssh logins won't. Next, add a second key to your u2f_keys. This is important, because if you lose your first key, or it's damaged, you'll otherwise have no way to log in.
  1. Insert your second U2F key and run pamu2fcfg -n > second, and press the second key's button when prompted.
  2. Edit ~/.config/Yubico/u2f_keys and append the output of second to the line with your username.
  3. Verify that you can log in using your second key as well as the first key. Note that you should have only one of the keys plugged in at the same time when logging in: the PAM module wants the first key it finds so you can't test both keys plugged in at once.
This is not too difficult, but rather fiddly, and it'd be nice if someone wrote at least a way to manage the list of U2F keys in a nicer way.

14 July 2016

Sune Vuorela: Leaky lambdas and self referencing shared pointers

After a bit of a debugging session, I ended up looking at some code in a large project
m_foo = std::make_shared<SomeQObject>();
/* plenty of lines and function boundaries left out */ 
(void)connect(m_foo.get(), &SomeQObject::someSignal, [m_foo]()  
  /* */
 );
The connection gets removed when the pointer inside m_foo gets de-allocated by the shared_ptr.
But the connection target is a lambda that has captured a copy of the shared_ptr There is at least a couple of solutions. I guess the lesson learnt is be careful when capturing shared pointers.

Norbert Preining: Osamu Dazai No Longer Human

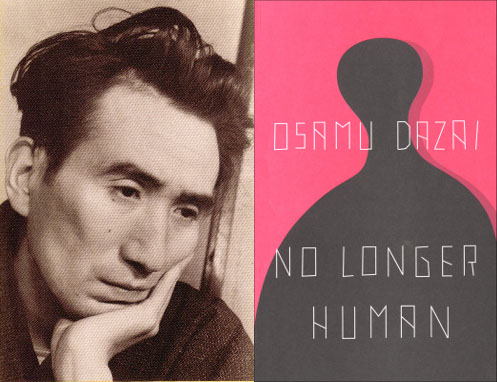
Japanese authors have a tendency to commit suicide, it seems. I have read Ryunosuke Akutagawa ( , at 35), Yukio Mishima ( , at 45), and also Osamu Dazai ( , at 39). Their end often reflects in their writings, and one of these examples is the book I just finished, No Longer Human. Dazai_Osamu-No_Longer_Human Considered as Dazai s master piece, and with Soseki s Kokoro the best selling novels in Japan. The book recounts the life of Oba Yozo, from childhood to the end in a mental hospital. The early years, described in the first chapter ( Memorandum ), are filled with the feeling of differentness, alienation from the rest, and Oba starts his way of living by playing the clown, permanently making jokes. The Second Memorandom spans the time to university, where he drops out, tries to become a painter, indulges in alcohol, smoking and prostitutes, leading to a suicide attempt together with a married woman, but he survived. The first part of the Third Memorandom sees a short recovering due to his relationship with a woman. He stops drinking and works as cartoonist, but in the last part his drinking pal from university times shows up again and they return into an ever increasing vicious drinking. Eventually he is separated from his wife, and confined to a mental hospital. Very depressing to read, but written in a way that one cannot stop reading. The disturbing thing about this book is that, although the main actor conceives many bad actions, we feel somehow attached to him and feel pity for him. It is somehow a exercise how circumstances and small predispositions can make a huge change in our lives. And it warns us that each one of us can easily come to this brink.
12 July 2016

Norbert Preining: Michael K hlmeier: Zwei Herren am Strand

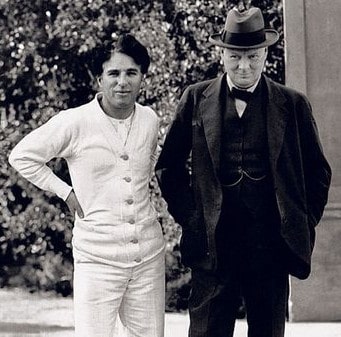
This recent book of the Austrian author Michael K hlmeier, Zwei Herren am Strand (Hanser Verlag), spins a story about an imaginative friendship between Charlie Chaplin and Winston Churchill. While there might not as be more different people than these two, in the book they are connected by a common fight the fight against their own depression, explicitly as well as implicitly by fighting Nazi Germany. Zwei Herren am Strand_ Roman - Michael Koehlmeier Michael K hlmeier s recently released book Zwei Herren am Strand tells the fictive story of Charlie Chaplin and Winston Churchill meeting and becoming friends, helping each other fighting depression and suicide thoughts. Based on a bunch of (fictive) letters of a (fictive) private secretary of Churchill, as well as (fictive) book on Chaplin, the first person narrator dives into the interesting time of the mid-20ies to about the Second World War. churchill-chaplinChaplin is having a hard time after the divorce from his wife Rita, paired with the difficulties at the production of The Circus, and is contemplating suicide. He is conveying this fact to Churchill during a walk on the beach. Churchill is reminded of his own depressions he suffers from early age on. The two of them agree to make a pact fighting the Black Dog inside. Later Churchill asks Chaplin about his method to overcome the phases of depression, and Chaplin explains him the Method of the Clown : Put a huge page of paper on the floor, lie yourself facing down onto the paper and start writing a letter to yourself while rotating clockwise and creating a spiral inward. According to Chaplin, he took this method from Buster Keaton and Harold Lloyd (hard to verify), and it works by making oneself ridiculous, so that one part of oneself can laugh about the other part. The story continues into the early stages of the world war, with both sides fighting Hitler, one politically, one by comedy. The story finishes somewhere in the middle when the two meet while Chaplin is in a deep depression during cutting his movie
The great dictator, and together to manage once more to overcome the black dog .
The book is pure fiction, and K hlmeier dives into a debaucherous story telling, jumping back and forth between several strands of narration lines. An entertaining and very enjoyable book if you are the type of reader that enjoys story telling. For me this book is in best tradition of Michael K hlmeier, whom I consider an excellent story teller. I loved his (unfinished trilogy of) books on Greek mythology (Telemach and Calypso), but found that after these books he got lost too much in radio programs of story telling. While in itself good, I preferred his novels. Thus, I have to admit that I have forgotten about K hlmeier for some years, until recently I found this little book, which reminded me of him and his excellent stories. A book that is if you are versed in German well worth enjoying, especially if one likes funny and a bit queer stories.

Mateus Bellomo: Get presence from buddies

Now it s also implemented the functionality that allows a user to see his contacts presence. At first week I ve implemented only the Telepathy part of this methods and back then I didn t comprehend that this information would come in the form of a NOTIFY SIP message. I also needed to use the SUBSCRIPTION mechanism properly so the presence server could send me the NOTIFY message. To be able to create those messages was necessary a better understanding of resip/stack, resip/recon and resip/dum API s. Not that I master this libraries now, but at least I m not totally lost anymore =) Looking into this libraries I could see how much work was done by all of resiprocate contributors (and I imagine I don t even saw the tip of the iceberg). There is so many features ready for use that now I think twice before start implementing something. Since I didn t find any reference explicitly showing the contact s status in RFC3863 [1], I got this information by changing a contact presence (in a different machine logged in Jitsi [2]) and looking into the NOTIFY message received at resiprocate. Follow some images about contact s presence at Empathy:
status_OnlineOnline status
status_OfflineOffline status
status_Busy (DND)Busy DND status
status_AwayAway status
status_In a meetingIn a meeting status
status_UnknownUnknow status
[1] https://tools.ietf.org/html/rfc3863 [2] https://jitsi.org/

Joey Hess: twenty years of free software -- part 13 past and future

This series has focused on new projects. I could have said more about significant work that didn't involve starting new projects. A big example was when I added dh to debhelper, which led to changes in a large percentage of debian/rules files. And I've contributed to many other free software projects. I guess I've focused on new projects becuase it's easier to remember things I've started myself. And because a new project is more wide open, with more scope for interesting ideas, especially when it's free software being created just because I want to, with no expectations of success. But starting lots of your own projects also makes you responsible for maintaining a lot of stuff. Ten years ago I had dozens of projects that I'd started and was still maintaining. Over time I started pulling away from Debian, with active projects increasingly not connected with it. By the end, I'd left and stopped working on the old projects. Nearly everything from my first decade in free software was passed on to new maintainers. It's good to get out from under old projects and concentrate on new things. I saved propellor for last in this series, because I think it may point toward the future of my software. While git-annex was the project that taught me Haskell, propellor's design is much more deeply influenced by the Haskell viewpoint. Absorbing that viewpoint has itself been a big undertaking for me this decade. It's like I was coasting along feeling at the top of my game and wham got hit by the type theory bus. And now I see that I was stuck in a rut before, and begin to get a feeling of many new possibilities. That's a good feeling to have, twenty years in.

11 July 2016

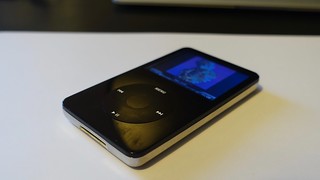
Jonathan Dowland: iPod

iPod iPod with rockbox
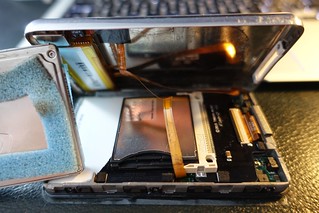
opened up open iPod with iFlash
It's been four years since I last wrote about music players. In the meantime of my Sansa Fuzes broke, and the third does not have great rockbox support. I've also been using a Sansa Clip+ (a leaving present from my last job, thanks again!) and a Sansa Clip Zip. Unfortunately Sandisk's newer Sansa devices (Sport, Jam - the only ones still in production) are not supported by Rockbox. The Clips have been very reliable and sturdy players, but I have missed the larger display of the Fuze. Since I've been exploring HD audio I've also been interested in something with an A/D converter that can handle it. I also still wish to carry my entire music library around with me, which limits my options. I decided to try an iPod. The older iPods had a Wolfson-manufacturered ADC which had a good reputation and supported (in headline terms at least) 24/48. The iPod colour (aka "4th gen") and subsequent models have a large colour display. The click-wheel interface is also very nice. Apple have now discontinued the "classic" iPod and their second hand value has greatly increased, but I managed to get an older 5th generation model ("video", with a base capacity of 30G) whilst trading in some unwanted DVDs. The case was scratched to heck but a replacement was readily and cheaply available from auction sites. Rockbox support in these iPods is pretty good, and you can mod the hardware to support CF or SD cards with kits such as the iFlash kits by Tarkan Akdam, which I picked up, along with a new 128G SD card. Unfortunately I have found writing to the iPod to be very poor with Rockbox, but it's fine for playback, and booting the iPod in OF or DFU mode is very easy and works reliably. Whilst Rockbox on the iPod works pretty well, installing it is far harder than on the Sandisk Sansa devices. The difficulty in my case is because rockbox requires a PC-formatted iPod to install, and I had a Mac-formatted one. I couldn't find a way to convert the iPod to PC format using a Mac. I tried doing so on a PC but for some reason the PC wasn't playing ball so I gave up after a few hours. In the end I assembled the filesystem by hand using dd(1) and dumps of partition tables from other people's iPods, via a Linux machine. This was enough to convince iTunes on Mac to restore it's hidden partition and boot software without reverting back to a Mac disklabel format.

Daniel Pocock: Let's Encrypt torpedoes cost and maintenance issues for Free RTC

Many people have now heard of the EFF-backed free certificate authority Let's Encrypt. Not only is it free of charge, it has also introduced a fully automated mechanism for certificate renewals, eliminating a tedious chore that has imposed upon busy sysadmins everywhere for many years. These two benefits - elimination of cost and elimination of annual maintenance effort - imply that server operators can now deploy certificates for far more services than they would have previously. The TLS chapter of the RTC Quick Start Guide has been updated with details about Let's Encrypt so anybody installing SIP or XMPP can use Let's Encrypt from the outset. For example, somebody hosting basic Drupal or Wordpress sites for family, friends and small community organizations can now offer them all full HTTPS encryption, WebRTC, SIP and XMPP without having to explain annual renewal fees or worry about losing time in their evenings and weekends renewing certificates manually. Even people who were willing to pay for a single certificate for their main web site may have snubbed their nose at the expense and ongoing effort of having certificates for their SMTP mail server, IMAP server, VPN gateway, SIP proxy, XMPP server, WebSocket and TURN servers too. Now they can all have certificates. Early efforts at SIP were doomed without encryption In the early days, SIP messages would be transported across the public Internet in UDP datagrams without any encryption. SIP itself wasn't originally designed for NAT and a variety of home routers were created with "NAT helper" algorithms that would detect and modify SIP packets to try and work through NAT. Sadly, in many cases these attempts to help actually clash with each other and lead to further instability. Conversely, many rogue ISPs could easily detect and punish VoIP users by blocking their calls or even cutting their DSL line. Operating SIP over TLS, usually on the HTTPS port (TCP port 443) has been an effective way to quash all of these different issues. While the example of SIP is one of the most extreme, it helps demonstrate the benefits of making encryption universal to ensure stability and cut out the "man-in-the-middle", regardless of whether he is trying to help or hinder the end user. Is one certificate enough? Modern SIP, XMPP and WebRTC require additional services, TURN servers and WebSocket servers. If they are all operated on port 443 then it is necessary to use different hostnames for each of them (e.g. turn.example.org and ws.example.org. Each different hostname requires a certificate. Let's Encrypt can provide those additional certificates too, without additional cost or effort. The future with Let's Encrypt The initial version of the Let's Encrypt client, certbot, fully automates the workflow for people using popular web servers such as Apache and nginx. The manual or certonly modes can be used for other services but hopefully certbot will evolve to integrate with many other popular applications too. Currently, Let's Encrypt's certbot tool issues certificates to servers running on TCP port 443 or 80. These are considered to be a privileged ports whereas any port over 1023, including the default ports used by applications such as SIP (5061), XMPP (5222, 5269) and TURN (5349), are not privileged ports. As long as certbot maintains this policy, it is generally necessary to either run a web server for the domain associated with each certificate or run the services themselves on port 443. There are other mechanisms for domain validation and various other clients supporting different subsets of them. Running the services themselves on port 443 turns out to be a good idea anyway as it ensures that RTC services can be reached through HTTP proxy servers who fail to let the HTTP CONNECT method access any other ports. Many configuration tasks are already scripted during the installation of packages on a GNU/Linux distribution (such as Debian or Fedora) or when setting up services using cloud images (for example, in Docker or OpenStack). Due to the heavily standardized nature of Let's Encrypt and the widespread availability of the tools, many of these package installation scripts can be easily adapted to find or create Let's Encrypt certificates on the target system, ensuring every service is running with TLS protection from the minute it goes live. If you have questions about Let's Encrypt for RTC or want to share your experiences, please come and discuss it on the Free-RTC mailing list.

10 July 2016

Ritesh Raj Sarraf: Leprosy in India

During my recent travel, I had quite a long layover at the Doha International Airport in Qatar. While killing time, I watched an interesting programme on the Al Jazeera network. The program aired on Al Jazeera is Lifelines. This special episode I watched, covered about "Leprosy in India". After having watched the entire programme, I felt the urge to blog about it. First of all, it was quite depressing to me, to know through the programme, that the Govt. of India had officially marked "Leprosy" eradicated from India in 2005. As per Wikipedia, "Globally in 2012, the number of chronic cases of leprosy was 189,000, down from some 5.2 million in the 1980s. The number of new cases was 230,000. Most new cases occur in 16 countries, with India accounting for more than half." Of the data presented on Lifelines, they just covered a couple of districts from 2 States (of the 28+ States) of India. So, with many states remaining, and unserveyed, and uncounted, we are far away from making such statements. Given that the Govt., on paper, has marked Leprosy eradicated; so does WHO. Which means that there is no more funding to help people suffering from the disease. And with no Govt. (or International) funding, it is a rather disappointing situation. I come from a small town on the Indo-Nepal intl. border, named Raxaul. And here, I grew up seeing many people who suffered from Leprosy. As a child, I never much understood the disease, because as is mentioned in the programme, I was told it was a communicable disease. Those suffering, were (and are) tagged as Untouchables (Hindi: ). Of my small town, there was and still is a sub-town, named Sunderpur. This town houses patients suffering from Leprosy, from around multiple districts closeby. I've never been there, but have been told that it is run by an NGO, and helps patients fight the disease. Lifelines also reported that fresh surveys done by the Lepra society, just a 3 day campaign, resulted in 3808 new cases of people suffering from Leprosy. That is a big number, given accessibility to small towns only happens once a week on market day. And in 3 days the team hardly covered a couple of district towns. My plea to the Media Houses of India. Please spend some time to look beyond the phony stuff that you mostly present. There are real issues that could be brought to a wider audience. As for the government, it is just depressing to know how rogue some/most of your statements are.

Categories:

Keywords:

Like:

Joey Hess: twenty years of free software -- part 12 propellor

Propellor is my second big Haskell program. I recently described the motivation for it like this, in a proposal for a Linux.Conf.Au talk:
The configuration of Linux hosts has become increasingly declarative, managed by tools like puppet and ansible, or by the composition of containers. But if a server is a collection of declarative properties, how do you make sure that changes to that configuration make sense? You can test them, but eventually it's 3 AM and you have an emergency fix that needs to go live immediately. Data types to the rescue! While data types are usually used to prevent eg, combining an Int and a Bool, they can be used at a much more abstract level, for example to prevent combining a property that needs a Debian system with a property that needs a Red Hat system. Propellor leverages Haskell's type system to prove the consistency of the properties it will apply to a host.
The real origin story though, is that I wanted to finally start using configuration management, but the tools for it all seemed very complicated and built on shaky foundations (like piles of yaml), and it seemed it would be easier to write my own than deal with that. Meanwhile, I had Haskell burning a hole in my pocket, ready to be used in a second large project after git-annex. Propellor has averaged around 2.5 contributions per month from users since it got started, but increasing numbers recently. That's despite having many fewer users than git-annex, which remember gets perhaps 1 patch per month. Of course, I've "cheated" by making sure that propellor's users know Haskell, or are willing to learn some. And, propellor is very compositional; adding a new property to it is not likely to be complicated by any of the existing code. So it's easy to extend, if you're able to use it. At this point propellor has a small community of regular contributors, and I spend some pleasant weekend afternoons reviewing and merging their work. Much of my best work on propellor has involved keeping the behavior of the program the same while making its types better, to prevent mistakes. Propellor's core data types have evolved much more than in any program I worked on before. That's exciting! Next: twenty years of free software -- part 13 past and future

Paul Tagliamonte: SNIff

A while back, I found myself in need of two webservers that would terminate TLS (with different rules). I wanted to run some custom code I d written (which uses TLS peer authentication), and also nginx on port 443. The best way I figured out how to do this was to write a tool to sit on port 443, and parse TLS Client Hello packets, and dispatch to the correct backend depending on the SNI name. SNI, or Server Name Indication allows the client to announce (yes over cleartext!) what server it s looking for, similar to the HTTP Host header. Sometimes, like in the case above, the Host header won t work, since you ve already done a TLS handshake by the time you figure out who they re looking for. I also spun the Client Hello parser out into its own importable package, just in case someone else finds themselves in this same boat. The code s up on github.com/paultag/sniff!

9 July 2016

Matthew Garrett: "I recieved a free or discounted product in return for an honest review"

My experiences with Amazon reviewing have been somewhat unusual. A review of a smart switch I wrote received enough attention that the vendor pulled the product from Amazon. At the time of writing, I'm ranked as around the 2750th best reviewer on Amazon despite having a total of 18 reviews. But the world of Amazon reviews is even stranger than that, and the past couple of weeks have given me some insight into it.

Amazon's success is fairly phenomenal. It's estimated that there's over 50 million people in the US paying $100 a year to get free shipping on Amazon purchases, and combined with Amazon's surprisingly customer friendly service there's a lot of people with a very strong preference for choosing Amazon rather than any other retailer. If you're not on Amazon, you're hurting your sales.

And if you're an established brand, this works pretty well. Some people will search for your product directly and buy it, leaving reviews. Well reviewed products appear higher up in search results, so people searching for an item type rather than a brand will still see your product appear early in the search results, in turn driving sales. Some proportion of those customers will leave reviews, which helps keep your product high up in the results. As long as your products aren't utterly dreadful, you'll probably maintain that position.

But if you're a brand nobody's ever heard of, things are more difficult. People are unlikely to search for your product directly, so you're relying on turning up in the results for more generic terms. But if you're selling a more generic kind of item (say, a Bluetooth smart bulb) then there's probably a number of other brands nobody's ever heard of selling almost identical objects. If there's no reason for anybody to choose your product then you're probably not going to get any reviews and you're not going to move up the search rankings. Even if your product is better than the competition, a small number of sales means a tiny number of reviews. By the time that number's large enough to matter, you're probably onto a new product cycle.

In summary: if nobody's ever heard of you, you need reviews but you're probably not getting any.

The old way of doing this was to send review samples to journalists, but nobody's going to run a comprehensive review of 3000 different USB cables and even if they did almost nobody would read it before making a decision on Amazon. You need Amazon reviews, but you're not getting any. The obvious solution is to send review samples to people who will leave Amazon reviews. This is where things start getting more dubious.

Amazon run a program called Vine which is intended to solve this problem. Send samples to Amazon and they'll distribute them to a subset of trusted reviewers. These reviewers write a review as normal, and Amazon tag the review with a "Vine Voice" badge which indicates to readers that the reviewer received the product for free. But participation in Vine is apparently expensive, and so there's a proliferation of sites like Snagshout or AMZ Review Trader that use a different model. There's no requirement that you be an existing trusted reviewer and the product probably isn't free. You sign up, choose a product, receive a discount code and buy it from Amazon. You then have a couple of weeks to leave a review, and if you fail to do so you'll lose access to the service. This is completely acceptable under Amazon's rules, which state "If you receive a free or discounted product in exchange for your review, you must clearly and conspicuously disclose that fact". So far, so reasonable.

In reality it's worse than that, with several opportunities to game the system. AMZ Review Trader makes it clear to sellers that they can choose reviewers based on past reviews, giving customers an incentive to leave good reviews in order to keep receiving discounted products. Some customers take full advantage of this, leaving a giant number of 5 star reviews for products they clearly haven't tested and then (presumably) reselling them. What's surprising is that this kind of cynicism works both ways. Some sellers provide two listings for the same product, the second being significantly more expensive than the first. They then offer an attractive discount for the more expensive listing in return for a review, taking it down to approximately the same price as the original item. Once the reviews are in, they can remove the first listing and drop the price of the second to the original price point.

The end result is a bunch of reviews that are nominally honest but are tied to perverse incentives. In effect, the overall star rating tells you almost nothing - you still need to actually read the reviews to gain any insight into whether the customer actually used the product. And when you do write an honest review that the seller doesn't like, they may engage in heavy handed tactics in an attempt to make the review go away.

It's hard to avoid the conclusion that Amazon's review model is broken, but it's not obvious how to fix it. When search ranking is tied to reviews, companies have a strong incentive to do whatever it takes to obtain positive reviews. What we're left with for now is having to laboriously click through a number of products to see whether their rankings come from thoughtful and detailed reviews or are just a mass of 5 star one liners.

comment count unavailable comments

8 July 2016

Reproducible builds folks: Managing container and environment state

Author: ceridwen With some more help from Martin Pitt, it became clear to me that my previous mental model of how autopkgtest worked is very different from how it does work. I'll illustrate by borrowing my previous example. I know that schroot has the following behavior:
The default behaviour is as follows (all directory paths are inside the chroot). A login shell is run in the current working directory. If this is not available, it will try $HOME (when --preserve-environment is used), then the user's home directory, and / inside the chroot in turn. A command is always run in the current working directory inside the chroot. If none of the directories are available, schroot will exit with an error status.
I was naively thinking that the way autopkgtest would work is that it would set the current working directory of the schroot call and the ensuing subprocess call would thus take place in that directory inside the schroot. That is not how it works. If you want to change directories inside the virtual server, you have to use cd. The same is true of, at least, environment variables, which have their own specific handling in the adt_testbed.Testbed methods but have to be passed as strings, and umask. I'm assuming this is because the direct methods with qemu images or LXC containers don't work. What this means is that I was thinking about the problem the wrong way: what reprotest needs to do is generate shell scripts. This is how autopkgtest works. If this goes beyond laying out commands linearly one after another, for instance if it demands conditionals or other nested constructs, the right way to do it is to build an abstract syntax tree representation of the shell script and then convert it to code. Whether I need more complicated shell scripts depends on my approach to handling state in the containers. I need to know what state persists across separate command executions: if I call adt_testbed.Testbed.execute() twice, what if any changes I make to the container will carry forward from the first to the second? There are three categories here. First, some properties of a system aren't preserved even from one command execution to the next, like working directory and environment variables. (I thought working directory would be preserved, but it's not). The second is state that persists while the testbed is open and is then automatically reverted when it's closed, like files copied into temporary directories on the tesbed. The third is state that persists across different sessions on the same container and must be cleaned up by reprotest. It's worth noting that which state falls into which category may vary by the container in question, though for the most part I can either do unnecessary cleanup or issue unnecessary commands to handle the differences. autopkgtest itself has a very different approach to cleanup, as it relies almost entirely on the builtin reversion capabilities from some of its containers. I would prefer to avoid doing the same, partly because I know that some of the modifications I need to make, for instance creating new users or mounting disorderfs, can't be reverted by the faster, simpler containers like schroot. From discussions with Lunar, I think that the variations that correspond to environment variables (captures_environment, home, locales, path, and timezone) fall into the first category, but because of the special handling for them they don't require sending a separate command. The shell (bash foo) accepts a script or command as an argument so it also doesn't need a separate command. Setting the working directory and umask require separate commands that have to be joined. On Linux, setarch also accepts a command/script as an argument so can be handled like the shell, but there's no unified POSIX protocol for mocking uname so other OSes will require different approaches. Users, groups, file ordering, host, and domain will require cleanup in all containers except for (maybe) qemu. If I want to handle the cleanup in the shell scripts themselves, I need conditionals so that for instance the shell script only tries to unmount disorderfs if disorderfs was successfully mounted. This approach would simplify the error handling problems I've had before, where when a build crashes cleanup code run from Python doesn't get run until after the testbed stop accepting commands. Lunar suggested the Plumbum library to me, and I think I can use it to avoid writing my own shell AST library. It has a method that converts the Python representation of a shell script into a string that can be passed to Testbed.command(). Integrating Plumbum to generate the necessary scripts is where I'm going in the next week. Any feedback on any of this is welcome. I'm also curious what other projects are using autopkgtest code. Holger brought to my attention piuparts, which brings the list up to four that I'm aware of, autopkgtest itself, sbuild, piuparts, and now reprotest.

Steve Kemp: I've been moving and updating websites.

I've spent the past days updating several of my websites to be "responsive". Mostly that means I open the site in firefox then press Ctrl-alt-m to switch to mobile-view. Once I have the mobile-view I then fix the site to look good in small small space. Because my general design skills are poor I've been fixing most sites by moving to bootstrap, and ensuring that I don't use headers/footers that are fixed-position. Beyond the fixes to appearances I've also started rationalizing the domains, migrating content across to new homes. I've got a provisional theme setup at steve.fi, and I've moved my blog over there too. The plan for blog-migration went well: The plan was originally to setup a HTTP-redirect, but I realized that this would mean I'd need to keep the redirect in-place forever, as visitors would have no incentive to fix their links, or update their feeds. By adding the fake-RSS-feed, pointing to the new location, I am able to assume that eventually people will update, and I can drop the dns record for blog.steve.org.uk entirely - Already google seems to have updated its spidering and searching shows the new domain already.

7 July 2016

Matthew Garrett: Bluetooth LED bulbs

The best known smart bulb setups (such as the Philips Hue and the Belkin Wemo) are based on Zigbee, a low-energy, low-bandwidth protocol that operates on various unlicensed radio bands. The problem with Zigbee is that basically no home routers or mobile devices have a Zigbee radio, so to communicate with them you need an additional device (usually called a hub or bridge) that can speak Zigbee and also hook up to your existing home network. Requests are sent to the hub (either directly if you're on the same network, or via some external control server if you're on a different network) and it sends appropriate Zigbee commands to the bulbs.

But requiring an additional device adds some expense. People have attempted to solve this in a couple of ways. The first is building direct network connectivity into the bulbs, in the form of adding an 802.11 controller. Go through some sort of setup process[1], the bulb joins your network and you can communicate with it happily. Unfortunately adding wifi costs more than adding Zigbee, both in terms of money and power - wifi bulbs consume noticeably more power when "off" than Zigbee ones.

There's a middle ground. There's a large number of bulbs available from Amazon advertising themselves as Bluetooth, which is true but slightly misleading. They're actually implementing Bluetooth Low Energy, which is part of the Bluetooth 4.0 spec. Implementing this requires both OS and hardware support, so older systems are unable to communicate. Android 4.3 devices tend to have all the necessary features, and modern desktop Linux is also fine as long as you have a Bluetooth 4.0 controller.

Bluetooth is intended as a low power communications protocol. Bluetooth Low Energy (or BLE) is even lower than that, running in a similar power range to Zigbee. Most semi-modern phones can speak it, so it seems like a pretty good choice. Obviously you lose the ability to access the device remotely, but given the track record on this sort of thing that's arguably a benefit. There's a couple of other downsides - the range is worse than Zigbee (but probably still acceptable for any reasonably sized house or apartment), and only one device can be connected to a given BLE server at any one time. That means that if you have the control app open while you're near a bulb, nobody else can control that bulb until you disconnect.

The quality of the bulbs varies a great deal. Some of them are pure RGB bulbs and incapable of producing a convincing white at a reasonable intensity[2]. Some have additional white LEDs but don't support running them at the same time as the colour LEDs, so you have the choice between colour or a fixed (and usually more intense) white. Some allow running the white LEDs at the same time as the RGB ones, which means you can vary the colour temperature of the "white" output.

But while the quality of the bulbs varies, the quality of the apps doesn't really. They're typically all dreadful, competing on features like changing bulb colour in time to music rather than on providing a pleasant user experience. And the whole "Only one person can control the lights at a time" thing doesn't really work so well if you actually live with anyone else. I was dissatisfied.

I'd met Mike Ryan at Kiwicon a couple of years back after watching him demonstrate hacking a BLE skateboard. He offered a couple of good hints for reverse engineering these devices, the first being that Android already does almost everything you need. Hidden in the developer settings is an option marked "Enable Bluetooth HCI snoop log". Turn that on and all Bluetooth traffic (including BLE) is dumped into /sdcard/btsnoop_hci.log. Turn that on, start the app, make some changes, retrieve the file and check it out using Wireshark. Easy.

Conveniently, BLE is very straightforward when it comes to network protocol. The only thing you have is GATT, the Generic Attribute Protocol. Using this you can read and write multiple characteristics. Each packet is limited to a maximum of 20 bytes. Most implementations use a single characteristic for light control, so it's then just a matter of staring at the dumped packets until something jumps out at you. A pretty typical implementation is something like:

0x56,r,g,b,0x00,0xf0,0x00,0xaa

where r, g and b are each just a single byte representing the corresponding red, green or blue intensity. 0x56 presumably indicates a "Set the light to these values" command, 0xaa indicates end of command and 0xf0 indicates that it's a request to set the colour LEDs. Sending 0x0f instead results in the previous byte (0x00 in this example) being interpreted as the intensity of the white LEDs. Unfortunately the bulb I tested that speaks this protocol didn't allow you to drive the white LEDs at the same time as anything else - setting the selection byte to 0xff didn't result in both sets of intensities being interpreted at once. Boo.

You can test this out fairly easily using the gatttool app. Run hcitool lescan to look for the device (remember that it won't show up if anything else is connected to it at the time), then do gatttool -b deviceid -I to get an interactive shell. Type connect to initiate a connection, and once connected send commands by doing char-write-cmd handle value using the handle obtained from your hci dump.

I did this successfully for various bulbs, but annoyingly hit a problem with one from Tikteck. The leading byte of each packet was clearly a counter, but the rest of the packet appeared to be garbage. For reasons best known to themselves, they've implemented application-level encryption on top of BLE. This was a shame, because they were easily the best of the bulbs I'd used - the white LEDs work in conjunction with the colour ones once you're sufficiently close to white, giving you good intensity and letting you modify the colour temperature. That gave me incentive, but figuring out the protocol took quite some time. Earlier this week, I finally cracked it. I've put a Python implementation on Github. The idea is to tie it into Ulfire running on a central machine with a Bluetooth controller, making it possible for me to control the lights from multiple different apps simultaneously and also integrating with my Echo.

I'd write something about the encryption, but I honestly don't know. Large parts of this make no sense to me whatsoever. I haven't even had any gin in the past two weeks. If anybody can explain how anything that's being done there makes any sense at all[3] that would be appreciated.

[1] typically via the bulb pretending to be an access point, but also these days through a terrifying hack involving spewing UDP multicast packets of varying lengths in order to broadcast the password to associated but unauthenticated devices and good god the future is terrifying

[2] For a given power input, blue LEDs produce more light than other colours. To get white with RGB LEDs you either need to have more red and green LEDs than blue ones (which costs more), or you need to reduce the intensity of the blue ones (which means your headline intensity is lower). Neither is appealing, so most of these bulbs will just give you a blue "white" if you ask for full red, green and blue

[3] Especially the bit where we calculate something from the username and password and then encrypt that using some random numbers as the key, then send 50% of the random numbers and 50% of the encrypted output to the device, because I can't even

comment count unavailable comments

Next.

Previous.