Search Results: "reg"

20 May 2013

Daniel Kahn Gillmor: gpg --ask-cert-level considered harmful

Occasionally, someone asks me whether we should encourage use of the --ask-cert-level option when certifying OpenPGP keys with gpg. I see no good reason to use this option, and i think we should discourage people from trying to use it. I don't think there is a satisfactory answer to the question "how will specifying the level of identity certification concretely benefit anyone involved?", and i don't see why we should want one. gpg gets it absolutely right by not asking users this question by default. People should not be enabling this option. Some background: gpg's --ask-cert-level option allows the user who is making an OpenPGP identity certification to indicate just how sure they are of the identity they are certifying. The user's choice is then mapped into four levels of OpenPGP certification of a User ID and Public-Key packet, which i'll refer to by their signature type identifiers in the OpenPGP spec:
0x10: Generic certification
The issuer of this certification does not make any particular assertion as to how well the certifier has checked that the owner of the key is in fact the person described by the User ID.
0x11: Persona certification
The issuer of this certification has not done any verification of the claim that the owner of this key is the User ID specified.
0x12: Casual certification
The issuer of this certification has done some casual verification of the claim of identity.
0x13: Positive certification
The issuer of this certification has done substantial verification of the claim of identity.
Most OpenPGP implementations make their "key signatures" as 0x10 certifications. Some implementations can issue 0x11-0x13 certifications, but few differentiate between the types.
By default (if --ask-cert-level is not supplied), gpg issues certificates ("signs keys") using 0x10 (generic) certifications, with the exception of self-sigs, which are made as type 0x13 (positive). When interpreting certifications, gpg does distinguish between different certifications in one particular way: 0x11 (persona) certifications are ignored; other certifications are not. (users can change this cutoff with the --min-cert-level option, but it's not clear why they would want to do so). So there is no functional gain in declaring the difference between a "normal" certification and a "positive" one, even if there were a well-defined standard by which to assess the difference between the "generic" and "casual" or "positive" levels; and if you're going to make a "persona" certification, you might as well not make one at all. And it gets worse: the problem is not just that such an indication is functionally useless; encouraging people to make these kind of assertions actively encourages leaks of a more-detailed social graph than just encouraging everyone to use the default blanket 0x13-for-self-sigs, 0x10-for-everyone-else policy. A richer public social graph means more data that can feed the ravenous and growing appetite of the advertising-and-surveillance regimes. i find these regimes troubling. I admit that people often leak much more information than this indication of "how well do you know X" via tools like Facebook, but that's no excuse to encourage them to leak still more or to acclimatize people to the idea that the details of their personal relationships should by default be public knowledge. Lastly, the more we keep the OpenPGP network of identity certifications (a.k.a. the "web of trust") simple, the easier it is to make sensible and comprehensible and predictable inferences from the network about whether a key really does belong to a given user. Minimizing the complexity and difficulty of deciding to make a certification helps people streamline their signing processes and reduces the amount of cognitive overhead people spend just building the network in the first place.Tags: openpgp

19 May 2013

Nicolas Dandrimont: Hello world

Or rather, hello Planet! Here s a somewhat traditional introductory post. I m Nicolas Dandrimont, I m French, I m sysadmin in a grande cole, where I m mostly in charge of the GNU/Linux workstations and servers. In Debian, I m a DM, currently in the NM queue, so I might become a DD soon-ish. I am (rather inactively) co-maintaining a few packages. In my Debian career , I have been involved in OCaml packaging and Python packaging, although lately most of my time has been spent on Google Summer of Code (mentor for two mentors.debian.net projects in 2012, org admin for Debian in 2013), and on mentors.debian.net. In other free-software related projects, I own a RepRap 3D printer, and I grew some interest in the related software, e.g. Slic3r and printrun. There have been a lot of action in Fedora about packaging 3D-printing-related software, and it d be great to get a team together to work on that in Debian during the jessie release cycle. Consider this a call for interested parties :) Unrelatedly, paultag has tricked me into working on hy, which is way too much fun. Blame him if you feel that I have been inactive lately, this has been eating way too much of my free time ;) Hopefully I ll be able to make regular updates on the work I do in Debian and free software, so stay tuned!

Gregor Herrmann: RC bugs 2013/20

besides working on the preparation of the Perl 5.18 transition, I also looked into some RC bugs:

17 May 2013

Rob Bradford: GNOME in Moblin: People panel

Previously i d talked about how we use GNOME technologies in the Moblin Myzone. Now i m going to talk about another component that i m responsible for, the People Panel. An important aspect of the Moblin user experience is about communicating with others and this panel provides quick access to do this. The core of the content is provided by an abstraction, simplification and aggregation library called Anerley. This provides a feed of items (an addressbook of people) that aggregates across the system addressbook, powered by EDS, and your IM roster, powered by Telepathy. You have small set of actions you can do on these people such as start an IM conversation / email / edit them with Contacts. The core of our IM experience is supplied by the awesome Empathy. We ve been working with the upstream maintainers to accomodate some of the needs of Moblin into the upstream source. This included the improvements to the accounts dialog and wizard that landed for GNOME 2.28. One of the biggest problems with the IM experience in Moblin 2.0 was that it was easy to miss when somebody was talking to you. If you were looking away when the notification popped up, whoops, it s gone. With our switch to Mission Control 5 I was able to integrate a Telepathy Observer into Anerley and the People Panel. An Observer will be informed of channels that are requested on the system. This allows us to show ongoing conversations in the panel and by exploiting channel requests and window presentation allow the user to switch between ongoing conversations. This wouldn t have been possible without the assistance of the nice folks in #telepathy and at Collabora: Sjoerd, Will, Jonny and countless others.

Daniel Pocock: Zermatt, Matterhorn and Gornergrat

The DebConf13 registration deadline for developers requesting sponsorship has been extended up to Sunday, so for those still undecided or anybody else thinking about a visit to .ch, I'm sharing some more pictures today. The Matterhorn is one of the iconic symbols of Switzerland's natural beauty and appears on many postcards. The car-free town of Zermatt is at the bottom and is the final stop on the Matterhorn Gotthard Bahn railway, so it is really easy to get there with one or two trains every hour of the day. One of the most exciting places to view the Matterhorn is from the nearby observatory at Gornergrat, which is 3,089m above sea level. It is great for a single day trip of hiking and there is a convenient train station there too. The scenic train to Zermatt is included in any of the Swiss rail passes, but the train up to Gornergrat is a private railway and a special ticket must be purchased. Discounts are sometimes offered at rail stations in Swiss cities or online or it is possible to hike up and down.

Russell Coker: Effective Conference Calls

I ve been part of many conference calls for work and found them seriously lacking. Firstly there s a lack of control over the call, so when someone does something stupid like putting an unmuted phone handset near a noise source there s no way to discover who did it and disconnect them. Another problem is that of noise on the line when some people don t mute their phones, which is related to the lack of control as it s impossible to determine who isn t muting their phone. Possibly the biggest problem is how to determine who gets to speak next. When group discussions take place in person non-verbal methods are used to determine who gets to speak next. With a regular phone call (two people) something like the CSMACD algorithm for network packets works well. But when there are 8+ people involved it becomes time consuming to resolve issues of who speaks next even when there are no debates. This is more difficult for multinational calls which can have a signal round trip time of 700ms or more. I think that we need a VOIP based conference call system for smart phones to manage this. I think that an ideal system would be based on the push to talk concept with software control that only allows one phone to transmit at a time. If someone else is speaking and you want to say something then you would push a button to indicate your desire but your microphone wouldn t go live while the other person was speaking. The person speaking would be notified of your request and one of the following things would happen: Did I miss any obvious ways for the system to react to a talk request? Is there any free software to do something like this? A quick search of the Google Play store didn t find anything that seems to match.

16 May 2013

DebConf team: DebConf13 registration extended and DebConf12 Final Report (Posted by Didier Raboud)

Dear all,
Going to DebConf13!
DebConf13 sponsorship application date extended As communicated through the debconf-announce@lists.debconf.org mailing list, the deadline to apply for DebConf13 sponsorship has been extended to the end of this week, May 19th. If you intend to attend DebConf13 in August and would like to apply for sponsored registration, now is the time to register in Penta! After this deadline you will no longer be able to apply for sponsored food, accomodation or travel. Please refer to the announcement and to the registration documentation for details. Please contact us on the debconf-discuss mailing list if you have any questions. DebConf12 final report The DebConf team is also happy to announce the release of the DebConf12 Final Report. It s a 39-page document which gives the reader an idea about the conference as a whole. It includes descriptions of talks, DebCamp and Debian Day activities, personal impressions, attendee and budgeting numbers, the work of various teams, social events and so on. If you attended Debconf12, the report may refresh some of your memories and bring you closer to the organization team work. If not, it will certainly encourage you to be part of future Debian events. We thank the Universidad Centroamericana, the Government of Nicaragua, Google and all other DebConf12 sponsors for their support that made the event possible. The DebConf team

Vincent Sanders: True art selects and paraphrases, but seldom gives a verbatim translation

In my professional life I am sometimes required to provide technical support to one of our salesmen. I find this an interesting change in pace though sometimes challenging.

Occasionally I fail to clearly convey the solution we are trying to sell because of my tendency to focus on detail the customer probably does not need to understand but I think is the interesting part of the problem.

Conversely sometimes the sales people gloss over important technology choices which have a deeper impact on the overall solution. I was recently in such a situation where as part of a larger project the subject of internationalisation (you can see why it gets abbreviated to i18n) was raised.

I had little direct personal experience with handling this within a project workflow so could not give any guidance but the salesman recommended the Transifex service as he had seen it used before, indicated integration was simple and we moved onto the next topic.

Unfortunately previous experience tells me that sometime in the near future someone is going to ask me hard technical questions about i18n and possibly how to integrate Transifex into their workflow (or at least give a good estimate on the work required).
LearningBeing an engineer I have few coping strategies available for situations when I do not know how something works. The approach I best know how to employ is to give myself a practical crash course and write up what I learned...so I did.

I proceeded to do all the usual things you do when approaching something unfamiliar (wikipedia, google, colleagues etc.) and got a basic understanding of internationalisation and localisation and how they fit together.

This enabled me to understand that the Transifex workflow proposed only covered the translation part of the problem and that, as Aldrich observed in my title quote, there is an awful lot more to translation than I suspected.
PlatformsMy research indicated that there are numerous translation platforms available for both open source and commercial projects and Transifex is one of many solutions.

Although the specific platform used was Transifex most of these observations apply to all these other platforms. The main lesson though is that all platforms are special snowflakes and once a project invests effort and time into one platform it will result in the dreaded lock in. The effort to move to another platform afterwards is at least as great as the initial implementation.

It became apparent to me that all of these services, regardless of their type, boil down to a very simple data structure. They appear to be a trivial table of Key:Language:Value wrapped in a selection of tools to perform format conversions and interfaces to manipulate the data.

There may be facilities to attach additional metadata to the table such as groupings for specific sets of keys (often referred to as resources) or translator hints to provide context but the fundamental operation is common.

The pseudo workflow is:
The first three steps are almost always performed together by the uploading of a resource file containing an initial set of translations in the "default" language and due to the world being the way it is this is almost always english (some services are so poorly tested with other defaults they fail if this is not the case!)

The platforms I looked at generally follow this pattern with a greater or lesser degree of freedom in what the keys are, how the groupings into resources are made and the languages that can be used. The most common issue with these platforms (especially open source ones) is that the input convertors will only accept a very limited number of formats and often restricted to just GNU gettext PO files. This means that to use those platforms a project would have to be able to convert any internal resources into gettext translatable format.

The prevalence of the PO format pushes assumptions into almost every platform I examined, mainly that a resource is for a single language translation and that the Key (msgid in gettext terms) is the untranslated default language string in the C locale.

The Transifex service does at least allow for the Key values to be arbitrary although the resources are separated by language.

Even assuming a project uses gettext PO files and UTF-8 character encoding (and please can we kill every other character encoding and move the whole world to UTF-8) the tools to integrate the import/export into the project must be written.

A project must decide some pretty important policies, including:
These are project policy decisions and, as I discovered, just as difficult to answer as the technical challenges.

Armed with my basic understanding it was time to move on and see how the transifex platform could be integrated into a real project workflow.
ImplementingProof of conceptMy first exercise was to take a trivial command line tool, use xgettext to generate a PO file and add the relevant libintl calls to produce gettext internationalised tool.

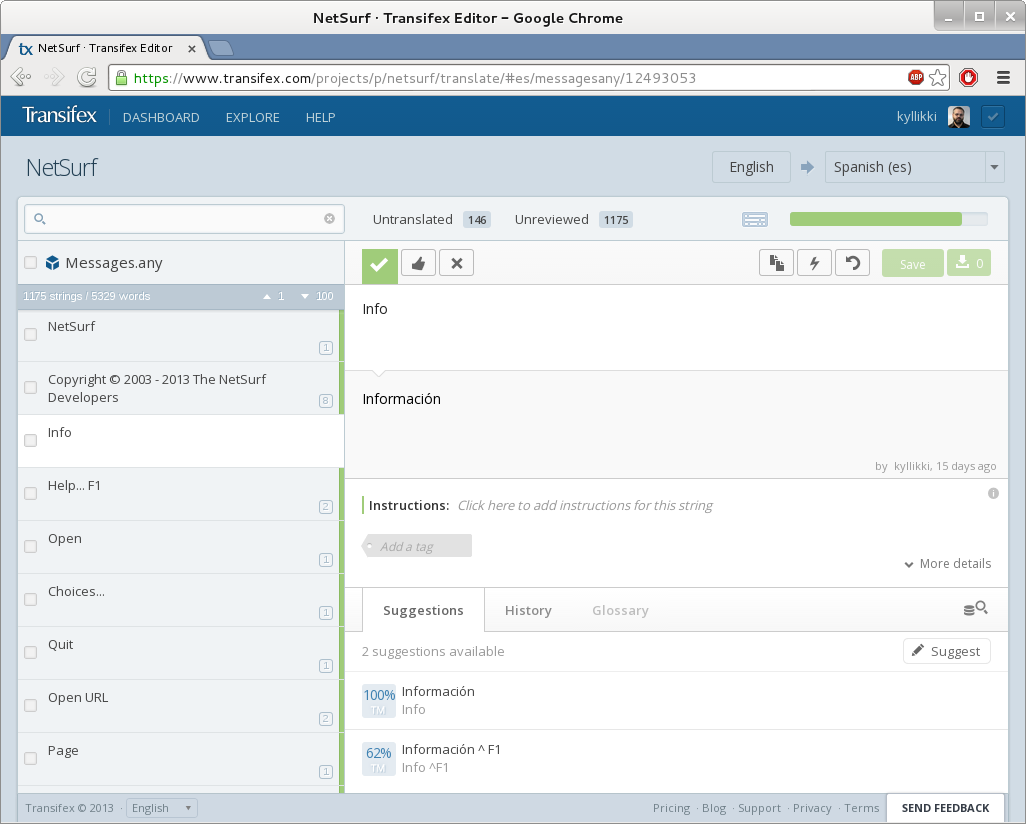
A transifex project was created and the english po file uploaded as the initial resource. A french language was added and the online editor used to provide translations for some strings. The PO resource file for french was exported and the tool executed with LANGUAGE=fr and the french translation seen.

This proved the trivial workflow was straightforward to implement. It also provided insight into the need to automate the process as the manual website operation would soon become exceptionally tedious and error prone.
Something more usefulTo get a better understanding of a real world workflow I needed a project that:
I selected the NetSurf web browser as it best fit this list.

Internally NetSurf keeps all the translated messages in a simple associative array this is serialised to an equally straightforward file named FatMessages. The file is UTF-8 encoded with keys separated from values by a colon. The Key is constrained to be ASCII characters with no colons and is structured as language.toolkit.identifier and is unique on identifier part alone.

This file is processed at build time into a simple identifier:value dictionary for each language and toolkit.

Transifex can import several resource formats similar to this, after experimenting with YAML and Android Resource format I immediately discovered a problem, the services import and export routines were somewhat buggy.

These routines coped ok with simple use cases but having more complex characters such as angle brackets and quotation marks in the translated strings would completely defeat the escaping mechanisms employed by both these formats (through entity escaping in android resource format XML is problematic anyway)

Finally the Java property file format was used (with UTF-8 encoding) which while having bugs in the import and export escaping these could at least be worked around. The existing tool that was used to process the FatMessages file was rewritten to cope with generating different output formats and a second tool to merge the java property format resources.

To create these two tools I enlisted the assistance of my colleague Vivek Dasmohapatra as his Perl language skills exceeded my own. He eventually managed to overcome the format translation issues and produce correct input and output.
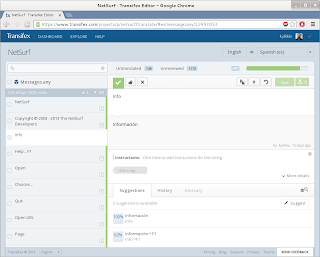
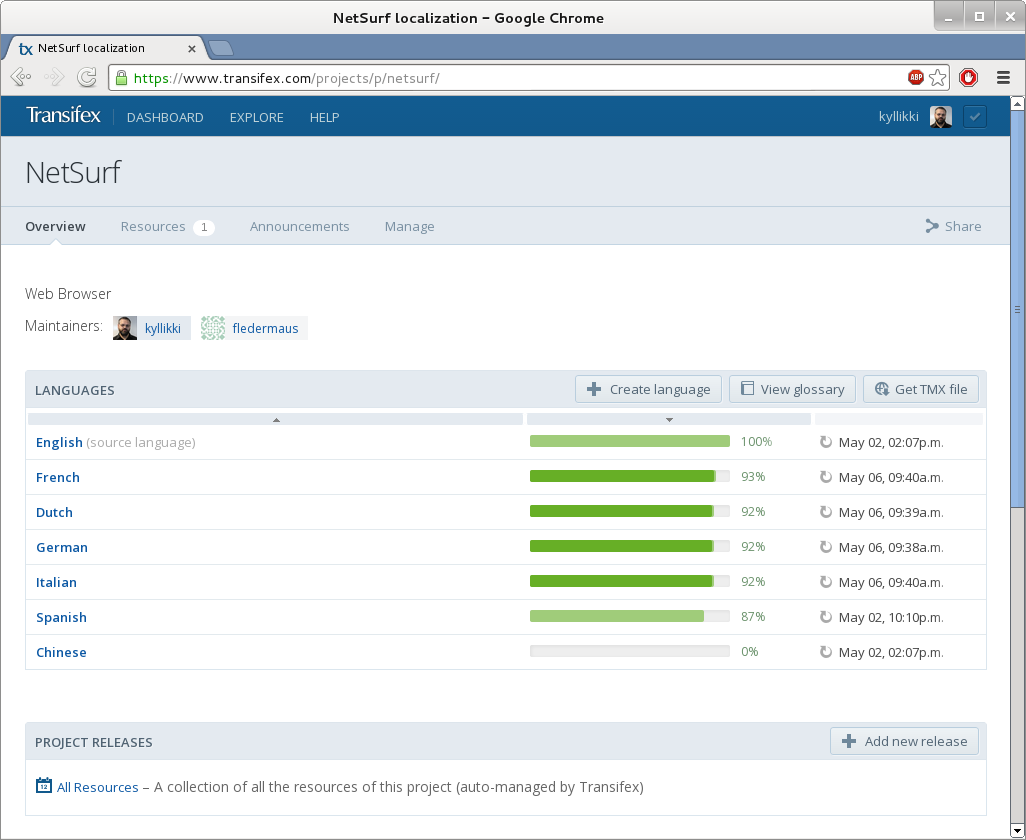
I used the Transifex platforms free open source product, created a new project and configured it for free machine translation from the Microsoft service, all of which is pretty clearly documented by Transifex.

Once this was done the messages file was split up tinto resources for the supported languages and uploaded to the transifex system.

I manually marked all the uploaded translations as "verified" and then added a few machine translations to a couple of languages. I also created spanish as a new language and machine translated most of the keys.

The resources for each language were then downloaded and merged and the resulting FatMessages file checked for differences and verified only the changes I expected appeared.

I quickly determined that manually downloading the language resources every time was not going to work with any form of automation, so I wrote a perl script to retrieve the resources automatically (might be useful for other projects too).

Once these tools were written and integrated into the build system I could finally make an evaluation as to how successful this exercise had been.
ConclusionsThe main things I learned from this investigation were:

Overall I think the final observation has to be that integrating translation services is not a straightforward operation and each project has unique challenges and requirements which reduce the existing platforms to compromise solutions.

Wouter Verhelst: Single-stepping init systems

The Linux init systems are a bit in flux at the moment. That is, they're in flux in Debian; outside Debian, most other distributions have stepped away from sysvinit and towards something else (systemd, openrc, or upstart). I've not been a proponent of any switch, though I understand the reasoning, and it probably makes sense for us to switch at some point. But yesterday, the fact that this customer's system was running sysvinit and not systemd or upstart saved me quite a bit. There's a server. It has one quadcore processor. For reasons that I won't go into here, the customer wants an extra quadcore processor to be added to the system. After having done so, I power on the system... only to see it power itself off at some point during boot. I did notice some kernel messages fly by just moments before the system would power itself off, but it was impossible for me to read them. So what did I do? That last bit is, obviously, a bit of an ugly workaround; the better way to fix this issue would have been to debug what the actual issue was, and implement a proper fix. However, I didn't have time for that (the fact that there was need for a second quadcore chip explains how much this system is in use), and the workaround was acceptable for the customer. It is not the first time that this ability to single-step the init system has saved me. The fact that sysvinit is so simplistic is what makes this possible, and I consider that one of its most important features. Recently, I came into contact with a distribution that uses systemd as its init system (in casu, Arch Linux). I had made a mistake in configuration; I had installed and enabled a graphical login system, but had no xterm or similar available, and had done something else wrong through which I couldn't get a regular shell on the console anymore, either. To fix this, I tried doing something like the above (running with init=/bin/bash and single-stepping the init system), but found that doing so with systemd is nigh impossible. In the end, I knew what exactly the problem was and could disable automatically starting the login manager through removing a symlink, but it brought home the issue that debugging a similar issue when running systemd rather than sysvinit might be a lot harder to do. We'll see what the future brings.

Russ Allbery: Review: Asimov's, July 2011

Review: Asimov's Science Fiction, July 2011
Editor: Sheila Williams
Issue: Volume 35, No. 7
ISSN: 1065-2698
Pages: 112
Williams's editorial is a mildly interesting piece about story titles. Silverberg's column is a more interesting (and rather convincing) rebuttal of the joke that fiction authors are "professional liars," combined with an examination of a fake and fantastic 14th travelogue that (at least in Silverberg's telling) was widely believed at the time. The precis of Silverberg's argument is that lying requires an intent to deceive, which is a property of deceptive memoir writers but not of fiction authors. Di Filippo's review column, as usual, is devoted almost entirely to esoterica, although I was moderately interested to hear of Stableford's continued work on translating early French SF. None of it seems compelling enough to go buy, but good translations of early works seem like a good thing to have in the world. "Day 29" by Chris Beckett: The conceit of this novelette is an interstellar travel system akin to a transporter that allows near-instantaneous travel between worlds. The drawback is that all memories from somewhere between 40 and 29 days before transit up until transit are wiped. The progatonist is a data analyst who is about to travel, and therefore by agency rule is required to stop doing work on day 40 before transmission since he can't be held legally liable for anything he has no recollection of doing. (I would like to say that I find this implausible, since one could always keep records, but it's exactly the sort of ass-covering regulation that a human resources department would come up with.) The premise is quite interesting: what do you do during that period that you're going to forget? Beckett wisely mixes Stephen's current waiting period on the colony world with his diary of his original waiting period on Earth the first time he went through the transmission process, and the latter adds greatly to the reader's appreciation of the weirdness of the forgotten interval. Unfortunately, this is a story more about psychological exploration than about plot, and Stephen just isn't very interesting. The telepathic but possibly nonsentient aliens add weirdness but not much else, and the ending of the story provided little sense of closure or conclusion for me. A good idea, but not the execution I wanted. (5) "Pug" by Theodora Goss: Since I grew up with a pug, I have a soft spot for a story featuring one; sadly, though, this story has insufficient pug in it. This is a quiet fantasy (Asimov's calls it SF, presumably on the basis of parallel worlds and a hypothesized scientific explanation, but it reads like fantasy to me) featuring Victorian girls, including one with a bad heart. They discover a hidden door to other versions of their world and do some minor exploration. There's little or nothing in the way of plot; the story is more of an attempt to capture a mood. It's mildly diverting, but I wish it had gone somewhere more substantial. (5) "Dunyon" by Kristine Kathryn Rusch: A Rusch story is often the highlight of an issue, and this is no exception. The protagonist is the owner of a bar in a space station that's become a combination of a refugee camp and a slum. War and chaos have created desperate people, most of whom are attempting to find some way to resources and get out of the bottom of society. The story is about a rumor: a mythical system named Dunyon that's safe and far away. And it's about how people react to that rumor. There's nothing particularly surprising about the direction the story goes (it's fairly short), but Rusch is always a good storyteller. (7) "The Music of the Sphere" by Norman Spinrad: I've had mixed feelings about Spinrad's fiction (and some of his essays), but I liked this story, despite its implausibility. It's set in the near future, featuring an expert in cetaceans and dolphin perception and a composer obsessed with both loud music and classical musical style. Just from that description, you can probably predict much of the story, but I thought it had some neat ideas about dolphins, whales, and alternate perception and aesthetics. (Note: neat, not necessarily biologically plausible.) Enjoyable. (6) "Bring on the Rain" by Josh Roseman: In a change of pace from the rest of the issue, this is a post-apocalyptic story of caravans of wheeled ships traversing a scorched and ruined landscape in search of weather systems and rain. The feel is of an inverted Waterworld, but with more emphasis on military tactics and cooperating fleets. The transposition of fleet maneuvers to huge ground vehicles adds some extra fun. The plot has little to do with the background and is a fairly stock military adventure scenario, but it's reasonably well-told. The story feels like an excerpt from a larger military-SF-inspired adventure, but the length keeps the quantity of tactics and maneuvering below the threshold where I would get bored. (6) "Twelvers" by Leah Cypess: This is a sharp and occasionally mean story of adolescent cruelty and alienation. Darla is a "twelver," a child who was carried an extra three months in the womb using newly-invented medical technology because of a belief in the advantages this would bring in later life. Unfortunately for all those who used this technique, what it also brought was a preternatural calm and an unusual reaction to emotions. Darla finds it almost impossible to get upset at anything, and that, of course, prompts the cruelty and abuse of other children. Most of the story is a description of that abuse, leading up to Darla stumbling into a nasty solution to her immediate problem. It's all very believable (well, apart from the motivating biology), but I didn't enjoy reading about it, and I'm certainly not convinced that the ending will lead to anything good. (5) "The Messenger" by Bruce McAllister: This is a very short time travel story, where time travel is used to try to unwind old family pain. This world follows the unalterable history model: no changes to the past are possible, and anything you do in the past has already happened. The mechanics are mostly avoided. Instead, McAllister concentrates on his mother, his father, and their complex relationship. I would have needed a bit more background on the characters to care enough about them for the story to be fully effective, but while the heartstring-pulling is kind of obvious, it's still a solid story. (6) "The Copenhagen Interpretation" by Paul Cornell: This is the most ingenious of the stories in this issue. It's set in a future world that extends what seemed to me to be pre-World-War-I great power politics, although there may be a hint of the Cold War. Great nations have reached a careful balance of power, and spies and secret services work to sustain that balance. The progatonist is one of those agents, making use of advanced technology like space folds in the service of a cause that he doesn't entirely believe in. Cornell mixes in mental conditioning, artificial people, space travel, and even aliens (maybe) in a taut thriller plot that, for me, gained a great deal from the unexplained strangeness of its background. If you like diving into the deep end and following a fast-moving plot against a background of strangeness, this is the sort of SF you'll enjoy. (7) Rating: 6 out of 10

15 May 2013

Craig Small: itools is back

My last post I said that I had to remove my internet query tools due to some bugs that were a concern. Some of the code was hard to maintain and probably had holes and I had noticed that it looped at times. I m happy to say that I have restored some of those tools now, still located at http://enc.com.au/itools This code is completely re-written in Python using the TurboGears toolkit which means it is a lot cleaner in how it works and how it looks. Some of the lookup tables use a database rather than an array for ease of updating and querying. The downside is the backends will take time. It currently only does nslookup queries and whois only works for IPv4 addresses. The domain name queries will be a while off as these are the most complicated to handle. To give you an idea, all IPv4 and IPv6 address information comes from 5 sources with two formats while domain names come from over 200 sources with about 40 formats. This means the information from Regional Internet Registries will be done first.

13 May 2013

Daniel Pocock: Get WebRTC going fast

A question that comes up more and more these days: what's the quickest way to try WebRTC and see it working? How can a web developer start experimenting with WebRTC in their blog or demo site? Good news: it's no longer necessary to compile anything from source - and many of the components are available on Debian-based systems (including Ubuntu) or RPM-based solutions like Fedora A quick look at how easy it is, explanation below:
# apt-get update
# apt-get install -t experimental repro resiprocate-turn-server
# apt-get install -t unstable chromium sipml5-web-phone
# cd /var/www && mkdir jssip && cd jssip
# wget -r -nH http://tryit.jssip.net
# vi /etc/repro/repro.config
# vi /etc/reTurnServer.config
# vi /var/www/jssip/js/custom.REMOVE_THIS.js
and then try browsing to /jssip or /sipml5-web-phone Start with a SIP proxy As explained in the RTC Quick Start guide for regular RTC, a SIP proxy is a clean and simple component to start with. The same is true for WebRTC: start with a proxy. There are two I'll emphasize here:
  • repro from reSIProcate is quick and easy to set up and has built in TLS support. A 1.9 alpha release with WebSocket support for WebRTC has just been uploaded to Debian experimental and is ready to use on wheezy. RPM users just need to download the alpha release tarball and use rpmbuild to get packages from it.
  • Kamailio provides very good WebRTC support too. The packages are available but due to GPL license issues must be recompiled with TLS, see the README.Debian file for details. Also feel free to try the upstream package repository for binaries that do include TLS
Get a TURN server TURN servers help media streams traverse NAT. They are very easy to set up, but must have real IP addresses. Put the JavaScript in the web server Adding WebRTC to a web site can be as simple as cutting and pasting some JavaScript code into the HTML. Three working samples to start with: Browser Users need a recent browser. The latest Chromium packages in Debian are based on Google Chrome M26 code and this should work. Help and support Please come and ask on the users mailing lists or IRC channels for any of the packages mentioned here.

12 May 2013

Gregor Herrmann: RC bugs 2013/19

after the release is before the release. this week I started to pick up my RC bug squashing activities again. first results: besides that I've also started to look at the "FTBFS with perl 5.18 in experimental" bugs which are not RC yet. yes, perl 5.18 is already in experimental!

11 May 2013

Russell Coker: Geographic Sorting Lessons to Learn from Ingress

I ve recently been spending a bit of my spare time playing Ingress (see the Wikipedia page if you haven t heard of it). A quick summary is that Ingress is an Android phone game that involves geo-location of portals that you aim to control and most operations on a portal can only be performed when you are within 40 meters so you do a lot of travelling to get to portals at various locations. One reasonably common operation that can be performed remotely is recharging a portal by using it s key, after playing for a while you end up with a collection of keys which can be difficult to manage. Until recently the set of portal keys was ordered alphabetically. This isn t particularly useful given the fact that portal names are made up by random people who photograph things that they consider to be landmarks. If people tried to use a consistent geographic naming system (which was short enough to fit in large print on a phone display) then it would be really difficult to make it usable. But as joke names are accepted there s just no benefit in having a sort by name. A recent update to the Ingress client (the program which runs on the Android phone and is used for all game operations) changed the sort order to be by distance. This makes it really easy to see the portals which are near you (which is really useful) but also means that the order changes whenever you move which isn t such a good idea for use on a mobile phone. It s quite common for Ingress players to recharge portals while on public transport. But with the new Ingress client the list order will change as you move so anyone who does recharging on a train will find the order of the list changing during the process and it s really difficult to find items in a list which is in a different order each time you look at it. This problem of ordering by location has a much greater scope than Ingress. One example is collections of GPS tagged photographs, it wouldn t make any sense to mix the pictures of two different sets of holiday pictures because they were both taken in countries that are the same distance from my current location (as the current Ingress algorithm would do). It seems to me that the best way of sorting geo-tagged items (Ingress portals, photos, etc) is to base it on the distance from a fixed point which the user can select. It could default to the user s current location but in that case the order of the list should remain unchanged at least until the user returns to the main menu and I think it would be ideal for the order to remain unchanged until the user requests it. I think that most Ingress players would agree with me that fixing annoying mis-features of the Ingress client such as this one would be better for the game than adding new features. While most computer games have some degree of make-work (in almost every case a computer could do things better than a person) I don t think that finding things in a changing list should be part of the make-work. Also it would be nice if Google released some code for doing this properly to reduce the incidence of other developers implementing the same mistakes as the Ingress developers in this regard.

Joachim Breitner: How to play Rock-Paper-Scissors online?

There was an interesting question by Fool recently on the StackExchange site for Boardgames: How do you play a game like Rock-Paper-Scissors with friends online? Or any other game where players have to simultaneously submit their moves (e.g. Diplomacy, or Rock-Paper-Scissors-Lizzard-Spock), which, as I just learned, are simultaneous action selection games. While there are websites dedicated to playing specific games, such as webdiplomacy.net, we could not find a generic one that you can use if you, for example, invent your own variants of a game.
So I created one: At you-say-first.nomeata.de you can enter rooms and share the URL with your friends. On the one hand, you have a regular chat room there. But there is also the possibility to enter moves (whatever a move may be to you) and only when all players have done that and marked the move as final, it is shown to everyone. If you want to try it out: There is an integrated, not very fancy Rock-Paper-Scissors-playing bot. Just enter a room, join and say I want to play!
Note that this site can be used for more than just for games. Have you ever observed that persons would often want other to express their preference (e.g. where to dine) first to not reveal their own preference, so that they can (or pretend to) change their mind if they would contradict? In such situations simultaneous action selection can be a fairer method. A technical note: I created this web app using meteor (a JavaScript framework building on node.js and MongoDB that allows for reactive programming), and it is also hosted on meteor.com. I chose Meteor after someone mentioned Firebase to me, which looked very slick, but was not Free Software, so I looked for alternatives. I did not do any cross-browser-testing, and the UI design could be improved, so if you want to help out (or just complain), please use the GitHub code repository and issue tracker.

10 May 2013

Julien Danjou: Rant about Github pull-request workflow implementation

One of my recent innocent tweet about Gerrit vs Github triggered much more reponses and debate that I expected it to. I realize that it might be worth explaining a bit what I meant, in a text longer than 140 characters. <script async="async" charset="utf-8" src="http://platform.twitter.com/widgets.js"></script> The problems with Github pull-requests I always looked at Github from a distant eye, mainly because I always disliked their pull-request handling, and saw no value in the social hype it brings. Why? One click away isn't one click effort The pull-request system looks like an incredible easy way to contribute to any project hosted on Github. You're a click away to send your contribution to any software. But the problem is that any worthy contribution isn't an effort of a single click. Doing any proper and useful contribution to a software is never done right the first time. There's a dance you will have to play. A slowly rhythmed back and forth between you and the software maintainer or team. You'll have to dance it until your contribution is correct and can be merged. But as a software maintainer, not everybody is going to follow you on this choregraphy, and you'll end up with pull-request you'll never get finished unless you wrap things up yourself. So the gain in pull-requests here, isn't really bigger than a good bug report in most cases. This is where the social argument of Github isn't anymore. As soon as you're talking about projects bigger than a color theme for your favorite text editor, this feature is overrated. Contribution rework If you're lucky enough, your contributor will play along and follow you on this pull-request review process. You'll make suggestions, he will listen and will modify his pull-request to follow your advice. At this point, there's two technics he can use to please you. Technic #1: the Topping Github's pull-requests invite you to send an entire branch, eclipsing the fact that it is composed of several commits. The problem is that a lot of one-click-away contributors do not masterize Git and/or do not make efforts to build a logical patchset, and nothing warns them that their branch history is wrong. So they tend to change stuff around, commit, make a mistake, commit, fix this mistake, commit, etc. This kind of branch is composed of the whole brain's construction process of your contributor, and is a real pain to review. To the point I quite often give up. <figure> <figcaption> A typical case: 3 commits to build a 4 lines long file. </figcaption> </figure> Without Github, the old method that all software used, and that many software still use (e.g. Linux), is to send a patch set over e-mail (or any other medium like Gerrit). This method has one positive effect, that it forces the contributor to acknowledge the list of commits he is going to publish. So, if the contributor he has fixup commits in his history, they are going to be seen as first class citizen. And nobody is going to want to see that, neither your contributor, nor the software maintainers. Therefore, such a system tend to push contributors to write atomic, logical and self-contained patchset that can be more easily reviewed. Technic #2: the History Rewriter This is actually the good way to build a working and logical patchset using Git. Rewriting history and amending problematic patches using the famous git rebase --interactive trick. The problem is that if your contributor does this and then repush the branch composing your pull-request to Github, you will both lose the previous review done, each time. There's no history on the different versions of the branch that has been pushed. In the old alternative system like e-mail, no information is lost when reworked patches are resent, obviously. This is far better because it eases the following of the iterative discussions that the patch triggered. Of course, it would be possible for Github to enhance this and fix it, but currently it doesn't handle this use case correctly.. <figure> <figcaption> Exercise for the doubtful readers: good luck finding all revisions of my patch in the pull-request #157 of Hy.</figcaption> </figure> A quick look at OpenStack workflow It's not a secret for anyone that I've been contributing to OpenStack as a daily routine for the last 18 months. The more I contribute, the more I like the contribution workflow and process. It's already well and longly described on the wiki, so I'll summarize here my view and what I like about it. Gerrit To send a contribution to any OpenStack project, you need to pass via Gerrit. This is way simpler than doing a pull-request on Github actually, all you have to do is do your commit(s), and type git review. That's it. Your patch will be pushed to Gerrit and available for review. Gerrit allows other developers to review your patch, add comments anywhere on it, and score your patch up or down. You can build any rule you want for the score needed for a patch to be merged; OpenStack requires one positive scoring from two core developers before the patch is merged. Until a patch is validated, it can be reworked and amended locally using Git, and then resent using git review again. That simple. The historic and the different version of the patches are available, with the whole comments. Gerrit doesn't lose any historic information on your workflow. Finally, you'll notice that this is actually the same kind of workflow projects use when they work by patch sent over e-mail. Gerrit just build a single place to regroup and keep track of patchsets, which is really handy. It's also much easier for people to actually send patch using a command line tool than their MUA or git send-email. Gate testing Testing is mandatory for any patch sent to OpenStack. Unit tests and functionnals test are run for each version of each patch of the patchset sent. And until your patch passes all tests, it will be impossible to merge it. Yes, this implies that all patches in a patchset must be working commits and can be merged on their own, without the entire patchset going in! With such a restricution, it's impossible to have "fixup commits" merged in your project and pollute the history and the testability of the project. Once your patch is validated by core developers, the system checks that there is not any merge conflicts. If there's not, tests are re-run, since the branch you are pushing to might have changed, and if everything's fine, the patch is merged. This is an uncredible force for the quality of the project. This implies that no broken patchset can ever sneak in, and that the project pass always all tests. Conclusion: accessibility vs code review In the end, I think that one of the key of any development process, which is code review, is not well covered by Github pull-request system. It is, along with history integrity, damaged by the goal of making contributions easier. Choosing between these features is probably a trade-off that each project should do carefully, considering what are its core goals and the quality of code it want to reach. I tend to find that OpenStack found one of the best trade-off available using Gerrit and plugging testing automation via Jenkins on it, and I would probably recommend it for any project taking seriously code reviews and testing.

9 May 2013

Benjamin Mako Hill: The Remixing Dilemma: The Trade-off Between Generativity and Originality

This post was written with Andr s Monroy-Hern ndez. It is a summary of a paper just published in American Behavioral Scientist. You can also read the full paper: The remixing dilemma: The trade-off between generativity and originality. It is part of a series of papers I have written with Monroy-Hern ndez using data from Scratch. You can find the others on my academic website.
Remixing the reworking and recombination of existing creative artifacts represents a widespread, important, and controversial form of social creativity online. Proponents of remix culture often speak of remixing in terms of rich ecosystems where creative works are novel and highly generative. However, examples like this can be difficult to find. Although there is a steady stream of media being shared freely on the web, only a tiny fraction of these projects are remixed even once. On top of this, many remixes are not very different from the works they are built upon. Why is some content more attractive to remixers? Why are some projects remixed in deeper and more transformative ways?
Remix Diagram
We try to shed light on both of these questions using data from Scratch a large online remixing community. Although we find support for several popular theories, we also present evidence in support of a persistent trade-off that has broad practical and theoretical implications. In what we call the remixing dilemma, we suggest that characteristics of projects that are associated with higher rates of remixing are also associated with simpler and less transformative types of derivatives.

Our study is focused on two interrelated research questions. First, we ask why some projects shared in remixing communities are more or less generative than others. Generativity a term we borrow from Jonathan Zittrain describes creative works that are likely to inspire follow-on work. Several scholars have offered suggestions for why some creative works might be more generative than others. We focus on three central theories:
  1. Projects that are moderately complicated are more generative. The free and open source software motto release early and release often suggests that simple projects will offer more obvious opportunities for contribution than more polished projects. That said, projects that are extremely simple (e.g., completely blank slates) may also uninspiring to would-be contributors.
  2. Projects by prominent creators are more generative. The reasoning for this claim comes from the suggestion that remixing can act as a form of cultural conversation and that the work of popular creators can act like a common medium or language.
  3. Projects that are remixes themselves are more generative. The reasoning for this final claim comes from the idea that remixing thrives through the accumulation of contributions from groups of people building on each other s work.
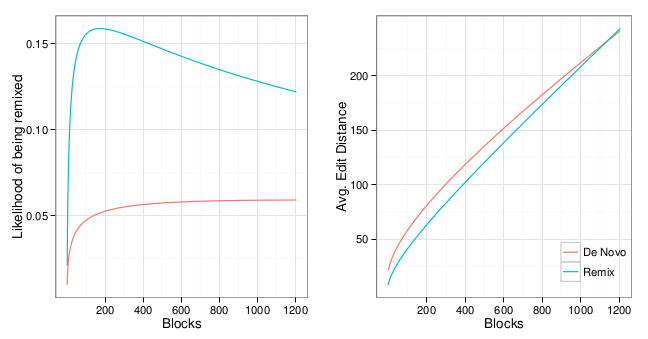
Our second question focuses on the originality of remixes and asks when more or less transformative remixing occurs. For example, highly generative projects may be less exciting if the projects produced based on them are all near-identical copies of antecedent projects. For a series of reasons including the fact that increased generativity might come by attracting less interested, skilled, or motivated individuals we suggest that each of the factors associated with generativity will also be associated with less original forms of remixing. We call this trade-off the remixing dilemma. We answer both of our research questions using a detailed dataset from Scratch, where young people build, share, and collaborate on interactive animations and video games. The community was built to support users of the Scratch programming environment, a desktop application with functionality similar to Flash created by the Lifelong Kindergarten Group at the MIT Media Lab. Scratch is designed to allow users to build projects by integrating images, music, sound, and other media with programming code. Scratch is used by more than a million users, most of them under 18 years old. To test our three theories about generativity, we measure whether or not, as well as how many times, Scratch projects were remixed in a dataset that includes every shared project. Although Scratch is designed as a remixing community, only around one tenth of all Scratch projects are ever remixed. Because more popular projects are remixed more frequently simply because of exposure, we control for the number of times each project is viewed. Our analysis shows at least some support for all three theories of generativity described above. (1) Projects with moderate amounts of code are remixed more often than either very simple or very complex projects. (2) Projects by more prominent creators are more generative. (3) Remixes are more likely to attract remixers than de novo projects. To test our theory that there is a trade-off between generativity and originality, we build a dataset that includes every Scratch remix and its antecedent. For each pair, we construct a measure of originality by comparing the remix to its antecedent and computing an edit distance (a concept we borrow from software engineering) to determine how much the projects differ. We find strong evidence of a trade-off: (1) Projects of moderate complexity are remixed more lightly than more complicated projects. (2) Projects by more prominent creators tend to be remixed in less transformative ways. (3) Cumulative remixing tends to be associated with shallower and less transformative derivatives. That said, our support for (1) is qualified in that we do not find evidence of the increased originality for the simplest projects as our theory predicted.
Two plots of estimated values for prototypical projects. Panel 1 (left) display predicted probabilities of being remixed. Panel 2 (right) display predicted edit distances. Both panels show predicted values for both remixes and de novo projects from 0 to 1,204 blocks (99th percentile).

Two plots of estimated values for prototypical projects. Panel 1 (left) displays predicted probabilities of being remixed. Panel 2 (right) displays predicted edit distances. Both panels show predicted values for both remixes and de novo projects from 0 to 1,204 blocks (99th percentile).

We feel that our results raise difficult but important challenges, especially for the designers of social media systems. For example, many social media sites track and display user prominence with leaderboards or lists of aggregate views. This technique may lead to increased generativity by emphasizing and highlighting creator prominence. That said, it may also lead to a decrease in originality of the remixes elicited. Our results regarding the relationship of complexity to generativity and originality of remixes suggest that supporting increased complexity, at least for most projects, may have fewer drawbacks. As supporters and advocates of remixing, we feel that although highly generative works that lead to highly original derivatives may be rare and difficult for system designers to support, understanding remixing dynamics and encouraging these rare projects remain a worthwhile and important goal. Benjamin Mako Hill, Massachusetts Institute of Technology
Andr s Monroy-Hern ndez, Microsoft Research
For more, see our full paper, The remixing dilemma: The trade-off between generativity and originality. Published in American Behavioral Scientist. 57-5, Pp. 643 663. (Official Link, Pay-Walled ).

Gunnar Wolf: Still more e-voting related rants

Some weeks ago, I contacted Rosa Mart nez, a tech journalist with some questions regarding what I regarded as a trick interview with an e-voting salesman. Well, not only she offered me to publish an answer to that interview, but she also offered me to write another article on a second site she also works with. So, I accepted. Being quite time-deprived, although I managed to send her the first answer quickly, by April 22, I only sent the second article yesterday night. Anyway, the links. The texts are published in Spanish:

Niels Thykier: Wheezy was brought to you by

During the Wheezy freeze, the Debian release team deployed 3254 hints[1]. This number may include some duplicates (i.e. where two members of the team hinted the same package), it certainly does not include a lot of rejected requests <insert more disclaimers here>. The top hinter was *drum roll* Adam, who did 1799 hints(That is 55% of all hints during the freeze). For comparison, the second and third runner ups added together did 1023 hints (or 31.4%). Put in a different way, on average Julien Cristau and I would both add about 1.5 hints each day and Adam would on his own add 5.6 hints a day. Of course, this is not intended to diminish the work other the rest of the team. Reviewing and unblocking packages is not all there is to a release. Particularly, a great thanks to Cyril Brulebois for his hard work on the Debian Installer (without which Debian Wheezy could not be released at all). Enjoy! [1] Determined by:
  egrep -c 'done 201(3 2-?(07 08 09 10 11 12)) $HINT_FILE
It does not count hints, but the little header we add above our hints. One header can apply to multiple hints (which is good, because udeb unblocks are usually paired with a regular unblock and we don t want to count them as two separate hints).

8 May 2013

Steve Langasek: Plymouth is not a bootsplash

Congrats to the Debian release team on the new release of Debian 7.0 (wheezy)! Leading up to the release, a meme making the rounds on Planet Debian has been to play a #newinwheezy game, calling out some of the many new packages in 7.0 that may be interesting to users. While upstart as a package is nothing new in wheezy, the jump to upstart 1.6.1 from 0.6.6 is quite a substantial change. It does bring with it a new package, mountall, which by itself isn't terribly interesting because it just provides an upstart-ish replacement for some core scripts from the initscripts package (essentially, /etc/rcS.d/*mount*). Where things get interesting (and, typically, controversial) is the way in which mountall leverages plymouth to achieve this. What is plymouth? There is a great deal of misunderstanding around plymouth, a fact I was reminded of again while working to get a modern version of upstart into wheezy. When Ubuntu first started requiring plymouth as an essential component of the boot infrastructure, there was a lot of outrage from users, particularly from Ubuntu Server users, who believed this was an attempt to force pretty splash screen graphics down their throats. Nothing could be further from the truth. Plymouth provides a splash screen, but that's not what plymouth is. What plymouth is, is a boot-time I/O multiplexer. And why, you ask, would upstart - or mountall, whose job is just to get the filesystem mounted at boot - need a boot-time I/O multiplexer? Why use plymouth? The simple answer is that, like everything else in a truly event-driven boot system, filesystem mounting is handled in parallel - with no defined order. If a filesystem is missing or fails an fsck, mountall may need to interact with the user to decide how to handle it. And if there's more than one missing or broken filesystem, and these are all being found in parallel, there needs to be a way to associate each answer from the user to the corresponding question from mountall, to avoid crossed signals... and lost data. One possible way to handle this would be for mountall to serialize the fsck's / mounts. But this is a pretty unsatisfactory answer; all other things (that is, boot reliability) being equal, admins would prefer their systems to boot as fast as possible, so that they can get back to being useful to users. So we reject the idea of solving the problem of serializing prompts by making mountall serialize all its filesystem checks. Another option would be to have mountall prompt directly on the console, doing its own serialization of the prompts (even though successful mounts / fscks continue to be run in parallel). This, too, is not desirable in the general case, both because some users actually would like to have pretty splash screens at boot time, and this would be incompatible with direct console prompting; and because mountall is not the only piece of software that need to prompt at boot time (see also: cryptsetup). Plymouth: not just a pretty face Enter plymouth, which provides the framework for serializing requests to the user while booting. It can provide a graphical boot splash, yes; ironically, even its own homepage suggests that this is its purpose. But it can also provide a text-only console interface, which is what you get automatically when booting without a splash boot argument, or even handle I/O over a serial console. Which is why, contrary to the initial intuitions of the s390 porters upon seeing this package, plymouth is available for all of Debian's Linux architectures in wheezy, s390 and s390x included, providing a consistent architecture for boot-time I/O for systems that need it - which is any machine using a modern boot system, such as upstart or systemd. Room for improvement Now, having a coherent architecture for your boot I/O is one thing; having a bug-free splash screen is another. The experience of plymouth in Ubuntu has certainly not been bug-free, with plymouth making significant demands of the kernel video layer. Recently, the binary video driver packages in Ubuntu have started to blacklist the framebuffer kernel driver entirely due to stability concerns, making plymouth splash screens a non-starter for users of these drivers and regressing the boot experience. One solution for this would be to have plymouth offload the video handling complexity to something more reliable and better tested. Plymouth does already have an X backend, but we don't use that in Ubuntu because even if we do have an X server, it normally starts much later than when we would want to display the splash screen. With Mir on the horizon for Ubuntu, however, and its clean separation between system and session compositors, it's possible that using a Mir backend - that can continue running even after the greeter has started, unlike the current situation where plymouth has to cede the console to the display manager when it starts - will become an appealing option. This, too, is not without its downsides. Needing to load plymouth when using crypted root filesystems already makes for a bloated initramfs; adding a system compositor to the initramfs won't make it any better, and introduces further questions about how to hand off between initramfs and root fs. Keeping your system compositor running from the initramfs post-boot isn't really ideal, particularly for low-memory systems; whereas killing the system compositor and restarting it will make it harder to provide a flicker-free experience. But for all that, it does have its architectural appeal, as it lets us use plymouth as long as we need to after boot. As the concept of static runlevels becomes increasingly obsolete in the face of dynamic systems, we need to design for the world where the distinction between "booting" and "booted" doesn't mean what it once did.

Next.

Previous.