Search Results: "cas"

7 September 2013

Russell Coker: The 2013 Federal Election

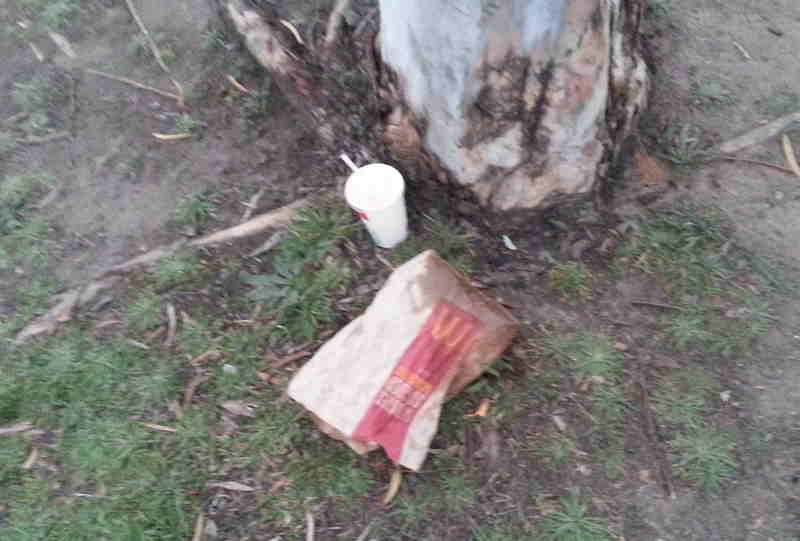
picture of rubbish left after the federal election Seven hours ago I was handing out how to vote cards for the Greens at the 2013 Australian Federal election. I was hoping that either we would have a Labor/Greens coalition or an outright majority for Labor. Unfortunately we got a Liberal majority in the lower house and it looks like some extreme right wing groups may get into the senate (replacements for Family First the anti-Gay party). For some reason the polling station where I was working only had volunteers from the three major parties (Greens, Labor, and Liberal) while other polling stations in the same electorate had volunteers from smaller parties such as the Sex Party and the Socialist Alliance. The volunteers from the Liberal party ate McDonalds outside the polling station and afterwards McDonalds rubbish was left on the ground, the above picture isn t particularly clear because I took it after 6PM when the polls closed. The Liberals didn t care enough to put their rubbish in a bin, it s an externality for them, if they get enough seats in the senate they will surely take the same approach to governing Australia. The Labor people didn t take the effort to clean up the Liberal mess even though it wasn t particularly difficult to do so, I think that s the type of attitude that led to this election defeat. In the case of the McDonalds rubbish in question I put it in the bin so that when the primary school kids return on Monday their school won t be too messy after the election. But in the case of the mess that is being made in Australian politics it will take many more Greens votes to allow us to clean it up.

6 September 2013

Vincent Bernat: High availability with ExaBGP

When it comes to provide redundant services, several options are available: A common setup is a combination of those solutions: web servers are behind a couple of load-balancers achieving both redundancy and load-balancing. The load-balancers use VRRP to ensure redundancy. The whole setup is replicated to another datacenter and round-robin DNS is used to ensure both redundancy and load-balacing of the datacenters. There is a fourth option which is similar to VRRP but relies on dynamic routing and therefore is not limited to nodes in the same subnet: We will explore how to implement this fourth option using ExaBGP, the BGP swiss army knife of networking, in a small lab based on KVM. You can grab the complete lab from GitHub. ExaBGP 3.2.5 is needed to run this lab.

Environment We will be working in the following (IPv6-only) environment: Lab with three web nodes

BGP configuration BGP is enabled on ER2 and ER3 to exchange routes with peers and transits (only R1 for this lab). BIRD is used as a BGP daemon. Its configuration is pretty basic. Here is a fragment:
router id 1.1.1.2;
protocol static NETS   #  
  import all;
  export none;
  route 2001:db8::/40 reject;
 
protocol bgp R1   #  
  import all;
  export where proto = "NETS";
  local as 64496;
  neighbor 2001:db8:1000::1 as 64511;
 
protocol bgp ER3   #  
  import all;
  export all;
  next hop self;
  local as 64496;
  neighbor 2001:db8:1::3 as 64496;
 
First, in , we declare the routes that we want to export to our peers. We don t try to summarize them from the IGP. We just unconditonnaly export the networks that we own. Then, in , R1 is defined as a neighbor and we export the static route we declared previously. We import any route that R1 is willing to send us. In , we share everything we know with our pal, ER3, using internal BGP.

OSPF configuration OSPF will distribute routes inside the AS. It is enabled on ER2, ER3, DR6, DR7 and DR8. For example, here is the relevant part of the configuration of DR6:
router id 1.1.1.6;
protocol kernel  
   persist;
   import none;
   export all;
 
protocol ospf INTERNAL  
  import all;
  export none;
  area 0.0.0.0  
    networks  
      2001:db8:1::/64;
      2001:db8:6::/64;
     ;
    interface "eth0";
    interface "eth1"   stub yes;  ;
   ;
 
ER2 and ER3 inject a default route into OSPF:
protocol static DEFAULT  
  import all;
  export none;
  route ::/0 via 2001:db8:1000::1;
 
filter default_route  
  if proto = "DEFAULT" then accept;
  reject;
 
protocol ospf INTERNAL  
  import all;
  export filter default_route;
  area 0.0.0.0  
    networks  
      2001:db8:1::/64;
     ;
    interface "eth1";
   ;
 

Web nodes The web nodes are pretty basic. They have a default static route to the nearest router and that s all. The interesting thing here is that they are each on a separate IP subnet: we cannot share an IP using VRRP2. Why are those web servers on different subnets? Maybe they are not in the same datacenter or maybe your network architecture is using a routed access layer. Let s see how to use BGP to enable redundancy of those web nodes.

Redundancy with ExaBGP ExaBGP is a convenient tool to plug scripts into BGP. They can then receive and advertise routes. ExaBGP does the hard work of speaking BGP with your routers. The scripts just have to read routes from standard input or advertise them on standard output.

The big picture Here is the big picture: Using ExaBGP to advertise web services Let s explain it step by step:
  1. Three IP addresses will be allocated for our web service: 2001:db8:30::1, 2001:db8:30::2 and 2001:db8:30::3. Those are distinct from the real IP addresses of W1, W2 and W3.
  2. Each web node will advertise all of them to the route servers we added in the network. I will talk more about those route servers later.
  3. Each route comes with a metric to help the route server choose where it should be routed. We choose the metrics such that each IP address will be routed to a distinct web node (unless there is a problem).
  4. The route servers (which are not routers) will then advertise the best routes they learned to all the routers in our network. This is still done using BGP.
  5. Now, for a given IP address, each router knows to which web node the traffic should be directed.
Here are the respective metrics announced routes for W1, W2 and W3 when everything works as expected:
Route W1 W2 W3 Best Backup
2001:db8:30::1 102 101 100 W3 W2
2001:db8:30::2 101 100 102 W2 W1
2001:db8:30::3 100 102 101 W1 W3

ExaBGP configuration The configuration of ExaBGP is quite simple:
group rs  
  neighbor 2001:db8:1::4  
    router-id 1.1.1.11;
    local-address 2001:db8:6::11;
    local-as 65001;
    peer-as 65002;
   
  neighbor 2001:db8:8::5  
    router-id 1.1.1.11;
    local-address 2001:db8:6::11;
    local-as 65001;
    peer-as 65002;
   
  process watch-nginx  
      run /usr/bin/python /lab/healthcheck.py -s --config /lab/healthcheck-nginx.conf --start-ip 0;
   
 
A script is entailed to check if the service (an nginx web server) is up and running and advertise the appropriate IP addresses to the two declared route servers. If we run the script manually, we can see the advertised routes:
$ python /lab/healthcheck.py --config /lab/healthcheck-nginx.conf --start-ip 0
INFO[healthcheck] send announces for UP state to ExaBGP
announce route 2001:db8:30::3/128 next-hop self med 100
announce route 2001:db8:30::2/128 next-hop self med 101
announce route 2001:db8:30::1/128 next-hop self med 102
[...]
WARNING[healthcheck] Check command was unsuccessful: 7
INFO[healthcheck] Output of check command:  curl: (7) Failed connect to ip6-localhost:80; Connection refused
WARNING[healthcheck] Check command was unsuccessful: 7
INFO[healthcheck] Output of check command:  curl: (7) Failed connect to ip6-localhost:80; Connection refused
WARNING[healthcheck] Check command was unsuccessful: 7
INFO[healthcheck] Output of check command:  curl: (7) Failed connect to ip6-localhost:80; Connection refused
INFO[healthcheck] send announces for DOWN state to ExaBGP
announce route 2001:db8:30::3/128 next-hop self med 1000
announce route 2001:db8:30::2/128 next-hop self med 1001
announce route 2001:db8:30::1/128 next-hop self med 1002
When the service becomes unresponsive, the healthcheck script detect the situation and retry several times before acknowledging that the service is dead. Then, the IP addresses are advertised with higher metrics and the service will be routed to another node (the one advertising 2001:db8:30::3/128 with metric 101). This healthcheck script is now part of ExaBGP.

Route servers We could have connected our ExaBGP servers directly to each router. However, if you have 20 routers and 10 web servers, you now have to manage a mesh of 200 sessions. The route servers are here for three purposes:
  1. Reduce the number of BGP sessions (from 200 to 60) between equipments (less configuration, less errors).
  2. Avoid modifying the configuration on routers each time a new service is added.
  3. Separate the routing decision (the route servers) from the routing process (the routers).
You may also ask yourself: why not use OSPF? . Good question!
  • OSPF could be enabled on each web node and the IP addresses advertised using this protocol. However, OSPF has several drawbacks: it does not scale, there are restrictions on the allowed topologies, it is difficult to filter routes inside OSPF and a misconfiguration will likely impact the whole network. Therefore, it is considered a good practice to limit OSPF to network equipments.
  • The routes learned by the route servers could be injected into OSPF. On paper, OSPF has a next-hop field to provide an explicit next-hop. This would be handy as we wouldn t have to configure adjacencies with each router. However, I have absolutely no idea how to inject BGP next-hop into OSPF next-hop. What happens is that BGP next-hop is resolved locally using OSPF routes. For example, if we inject BGP routes into OSPF from RS4, RS4 will know the appropriate next-hop but other routers will route the traffic to RS4.
Let s look at how to configure our route servers. RS4 will use BIRD while RS5 will use Quagga. Using two different implementations will help with resiliency by avoiding a bug to hit the two route servers at the same time.

Bird configuration There are two sides for BGP configuration: the BGP sessions with the ExaBGP nodes and the ones with the routers. Here is the configuration for the later:
template bgp INFRABGP  
  export all;
  import none;
  local as 65002;
  rs client;
 
protocol bgp ER2 from INFRABGP  
  neighbor 2001:db8:1::2 as 65003;
 
protocol bgp ER3 from INFRABGP  
  neighbor 2001:db8:1::3 as 65003;
 
protocol bgp DR6 from INFRABGP  
  neighbor 2001:db8:1::6 as 65003;
 
protocol bgp DR7 from INFRABGP  
  neighbor 2001:db8:1::7 as 65003;
 
protocol bgp DR8 from INFRABGP  
  neighbor 2001:db8:1::8 as 65003;
 
The AS number used by our route server is 65002 while the AS number used for routers is 65003 (the AS numbers for web nodes will be 65001). They are reserved for private use by RFC 6996. All routes known by the route server are exported to the routers but no routes are accepted from them. Let s have a look at the other side:
# Only import loopback IPs
filter only_loopbacks   #  
  if net ~ [ 2001:db8:30::/64 128,128  ] then accept;
  reject;
 
# General template for an EXABGP node
template bgp EXABGP  
  local as 65002;
  import filter only_loopbacks; #  
  export none;
  route limit 10; #  
  rs client;
  hold time 6; #  
  multihop 10;
  igp table internal;
 
protocol bgp W1 from EXABGP  
  neighbor 2001:db8:6::11 as 65001;
 
protocol bgp W2 from EXABGP  
  neighbor 2001:db8:7::12 as 65001;
 
protocol bgp W3 from EXABGP  
  neighbor 2001:db8:8::13 as 65001;
 
To ensure separation of concerns, we are being a bit more picky. With and , we only accept loopback addresses and only if they are contained in the subnet that we reserved for this use. No server should be able to inject arbitrary addresses into our network. With , we also limit the number of routes that a server can advertise. With , we reduce the hold time from 240 to 6. It means that after 6 seconds, the peer is considered dead. This is quite important to be able to recover quickly from a dead machine. The minimal value is 3. We could have use a similar setting with the session with the routers.

Quagga configuration Quagga s configuration is a bit more verbose but should be strictly equivalent:
router bgp 65002 view EXABGP
 bgp router-id 1.1.1.5
 bgp log-neighbor-changes
 no bgp default ipv4-unicast
 neighbor R peer-group
 neighbor R remote-as 65003
 neighbor R ebgp-multihop 10
 neighbor EXABGP peer-group
 neighbor EXABGP remote-as 65001
 neighbor EXABGP ebgp-multihop 10
 neighbor EXABGP timers 2 6
!
 address-family ipv6
 neighbor R activate
 neighbor R soft-reconfiguration inbound
 neighbor R route-server-client
 neighbor R route-map R-IMPORT import
 neighbor R route-map R-EXPORT export
 neighbor 2001:db8:1::2 peer-group R
 neighbor 2001:db8:1::3 peer-group R
 neighbor 2001:db8:1::6 peer-group R
 neighbor 2001:db8:1::7 peer-group R
 neighbor 2001:db8:1::8 peer-group R
 neighbor EXABGP activate
 neighbor EXABGP soft-reconfiguration inbound
 neighbor EXABGP maximum-prefix 10
 neighbor EXABGP route-server-client
 neighbor EXABGP route-map RSCLIENT-IMPORT import
 neighbor EXABGP route-map RSCLIENT-EXPORT export
 neighbor 2001:db8:6::11 peer-group EXABGP
 neighbor 2001:db8:7::12 peer-group EXABGP
 neighbor 2001:db8:8::13 peer-group EXABGP
 exit-address-family
!
ipv6 prefix-list LOOPBACKS seq 5 permit 2001:db8:30::/64 ge 128 le 128
ipv6 prefix-list LOOPBACKS seq 10 deny any
!
route-map RSCLIENT-IMPORT deny 10
!
route-map RSCLIENT-EXPORT permit 10
  match ipv6 address prefix-list LOOPBACKS
!
route-map R-IMPORT permit 10
!
route-map R-EXPORT deny 10
!
The view is here to not install routes in the kernel3.

Routers Configuring BIRD to receive routes from route servers is straightforward:
# BGP with route servers
protocol bgp RS4  
  import all;
  export none;
  local as 65003;
  neighbor 2001:db8:1::4 as 65002;
  gateway recursive;
 
protocol bgp RS5  
  import all;
  export none;
  local as 65003;
  neighbor 2001:db8:8::5 as 65002;
  multihop 4;
  gateway recursive;
 
It is important to set gateway recursive because most of the time, the next-hop is not reachable directly. In this case, by default, BIRD will use the IP address of the advertising router (the route servers).

Testing Let s check that everything works as expected. Here is the view from RS5:
# show ipv6  bgp  
BGP table version is 0, local router ID is 1.1.1.5
Status codes: s suppressed, d damped, h history, * valid, > best, i - internal,
              r RIB-failure, S Stale, R Removed
Origin codes: i - IGP, e - EGP, ? - incomplete
   Network          Next Hop            Metric LocPrf Weight Path
*  2001:db8:30::1/128
                    2001:db8:6::11         102             0 65001 i
*>                  2001:db8:8::13         100             0 65001 i
*                   2001:db8:7::12         101             0 65001 i
*  2001:db8:30::2/128
                    2001:db8:6::11         101             0 65001 i
*                   2001:db8:8::13         102             0 65001 i
*>                  2001:db8:7::12         100             0 65001 i
*> 2001:db8:30::3/128
                    2001:db8:6::11         100             0 65001 i
*                   2001:db8:8::13         101             0 65001 i
*                   2001:db8:7::12         102             0 65001 i
Total number of prefixes 3
For example, traffic to 2001:db8:30::2 should be routed through 2001:db8:7::12 (which is W2). Other IP are affected to W1 and W3. RS4 should see the same thing4:
$ birdc6 show route 
BIRD 1.3.11 ready.
2001:db8:30::1/128 [W3 22:07 from 2001:db8:8::13] * (100/20) [AS65001i]
                   [W1 23:34 from 2001:db8:6::11] (100/20) [AS65001i]
                   [W2 22:07 from 2001:db8:7::12] (100/20) [AS65001i]
2001:db8:30::2/128 [W2 22:07 from 2001:db8:7::12] * (100/20) [AS65001i]
                   [W1 23:34 from 2001:db8:6::11] (100/20) [AS65001i]
                   [W3 22:07 from 2001:db8:8::13] (100/20) [AS65001i]
2001:db8:30::3/128 [W1 23:34 from 2001:db8:6::11] * (100/20) [AS65001i]
                   [W3 22:07 from 2001:db8:8::13] (100/20) [AS65001i]
                   [W2 22:07 from 2001:db8:7::12] (100/20) [AS65001i]
Let s have a look at DR6:
$ birdc6 show route
2001:db8:30::1/128 via fe80::5054:56ff:fe6e:98a6 on eth0 * (100/20) [AS65001i]
                   via fe80::5054:56ff:fe6e:98a6 on eth0 (100/20) [AS65001i]
2001:db8:30::2/128 via fe80::5054:60ff:fe02:3681 on eth0 * (100/20) [AS65001i]
                   via fe80::5054:60ff:fe02:3681 on eth0 (100/20) [AS65001i]
2001:db8:30::3/128 via 2001:db8:6::11 on eth1 * (100/10) [AS65001i]
                   via 2001:db8:6::11 on eth1 (100/10) [AS65001i]
So, 2001:db8:30::3 is owned by W1 which is behind DR6 while the two others are in another part of the network and will be reached through the appropriate link-local addresses learned by OSPF. Let s kill W1 by stopping nginx. A few seconds later, DR6 learns the new routes:
$ birdc6 show route
2001:db8:30::1/128 via fe80::5054:56ff:fe6e:98a6 on eth0 * (100/20) [AS65001i]
                   via fe80::5054:56ff:fe6e:98a6 on eth0 (100/20) [AS65001i]
2001:db8:30::2/128 via fe80::5054:60ff:fe02:3681 on eth0 * (100/20) [AS65001i]
                   via fe80::5054:60ff:fe02:3681 on eth0 (100/20) [AS65001i]
2001:db8:30::3/128 via fe80::5054:56ff:fe6e:98a6 on eth0 * (100/20) [AS65001i]
                   via fe80::5054:56ff:fe6e:98a6 on eth0 (100/20) [AS65001i]

Demo For a demo, have a look at the following video (it is also available as an Ogg Theora video).

  1. The primary target of VRRP is to make a default gateway for an IP network highly available by exposing a virtual router which is an abstract representation of multiple routers. The virtual IP address is held by the master router and any backup router can be promoted to master in case of a failure. In practice, VRRP can be used to achieve high availability of services too.
  2. However, you could deploy an L2 overlay network using, for example, VXLAN and use VRRP on it.
  3. I have been told on the Quagga mailing-list that such a setup is quite uncommon and that it would be better to not use views but use --no_kernel flag for bgpd instead. You may want to look at the whole thread for more details.
  4. The output of birdc6 shows both the next-hop as advertised in BGP and the resolved next-hop if the route have to be exported into another protocol. I have simplified the output to avoid confusion.

NOKUBI Takatsugu: The Internet Timeline in Japan

JPNIC published The Internet Timeline (Japanese version is also there). My first contact with the Internet was about 20 years ago. I was a Universal student. The University had 64kbps bandwidth, it was really slow. Nowerday, I have 128kbps mobile network with 950 yen/month. It is usable for some use case, like text messaging.

Steve Kemp: Dynamically discovering settings for a cluster?

Pretend I run a cluster, for hosting a site. Pretend that I have three-six web-nodes, and each one needs to know which database host to contact. How do I control that? Right now I have a /etc/settings.conf file, more or less, deployed by Slaughter. That works. Another common pattern is to use a hostname - for example pmaster.example.org. However failover isn't considered here. If I wanted to update to point to a secondary database I'd need to either: In short I'm imagining there are several situations where you want to abstract away the configuration in a cluster-wide manner. (A real solution is obviously floating per-service IPs. Via HAProxy, Keepalived, ucarp, etc. People do that quite often for database specifically, but not for redis-servers, etc.) So I'm pondering what is essentially a multi-cast accessible key-value storage system. Have a deamon on the VLAN which will respond to multicast questions like "get db", or "get cache", with a hostname/IP/result. Suddenly your code would read: To me that seems like it should be genuinely useful. But I'm unsure if I'm trading one set of problems for another. I can't find any examples of existing tools/deamons in this area, which either means I'm being novel, innovate, and interesting. Or I'm over thinking...

5 September 2013

Vincent Sanders: Strive for continuous improvement, instead of perfection.


Kim Collins was perhaps thinking more about physical improvement but his advice holds well for software.

A lot has been written about the problems around software engineers wanting to rewrite a codebase because of "legacy" issues. Experience has taught me that refactoring is a generally better solution than rewriting because you always have something that works and can be released if necessary.

Although that observation applies to the whole of a project, sometimes the technical debt in component modules means they need reimplementing. Within NetSurf we have historically had problems when such a change was done because of the large number of supported platforms and configurations.
HistoryA year ago I implemented a Continuous Integration (CI) solution for NetSurf which, combined with our switch to GIT for revision control, has transformed our process. Making several important refactor and rewrites possible while being confident about the overall project stability.

I know it has been a year because the VPS hosting bill from Mythic turned up and we are still a very happy customer. We have taken the opportunity to extend the infrastructure to add additional build systems which is still within the NetSurf projects means.

Over the last twelve months the CI system has attempted over 100,000 builds including the projects libraries and browser. Each commit causes an attempt to build for eight platforms, in multiple configurations with multiple compilers. Because of this the response time to a commit is dependant on the slowest build slave (the mac mini OS X leopard system).

Currently this means a browser build, not including the support libraries, completes in around 450 seconds. The eleven support libraries range from 30 to 330 seconds each. This gives a reasonable response time for most operations. The worst case involves changing the core buildsystem which causes everything to be rebuilt from scratch taking some 40 minutes.

The CI system has gained capability since it was first set up, there are now jobs that:
DownsidesIt has not all been positive though, the administration required to keep the builds running has been more than expected and it has highlighted just how costly supporting all our platforms is. When I say costly I do not just refer to the physical requirements of providing build slaves but more importantly the time required.

Some examples include:
  • Procuring the hardware, installing the operating system and configuring the build environment for the OS X slaves
  • Getting the toolchain built and installed for cross compilation
  • Dealing with software upgrades and updates on the systems
  • Solving version issues with interacting parts, especially limiting is the lack of JAVA 1.6 on PPC OS X preventing jenkins updates
This administration is not interesting to me and consumes time which could otherwise be spent improving the browser. Though the benefits of having the system are considered by the development team to outweigh the disadvantages.

The highlighting of the costs of supporting so many platforms has lead us to reevaluate their future viability. Certainly the PPC mac os X port is in gravest danger of being imminently dropped and was only saved when the build slaves drive failed because there were actual users.

There is also the question of the BeOS platform which we are currently unable to even build with the CI system at all as it cannot be targeted for cross compilation and cannot run a sufficiently complete JAVA implementation to run a jenkins slave.

An unexpected side effect of publishing every CI build has been that many non developer user are directly downloading and using these builds. In some cases we get messages to the mailing list about a specific build while the rest of the job is still ongoing.

Despite the prominent warning on the download area and clear explanation on the mailing lists we still get complaints and opinions about what we should be "allowing" in terms of stability and features with these builds. For anyone else considering allowing general access to CI builds I would recommend a very clear statement of intent and to have a policy prepared for when when users ignore the statement.
Tools
Using jenkins has also been a learning experience. It is generally great but there are some issues I have which, while not insurmountable, are troubling:
Configuration and history cannot easily be stored in a revision control system.
This means our system has to be restored from a backup in case of failure and I cannot simply redeploy it from scratch.

Job filtering, especially for matrix jobs with many combinations, is unnecessarily complicated.
This requires the use of a single text line "combination filter" which is a java expression limiting which combinations are built. An interface allowing the user to graphically select from a grid similar to the output tables showing success would be preferable. Such a tool could even generate the textural combination filter if thats easier.

This is especially problematic of the main browser job which has options for label (platform that can compile the build), javascript enablement, compiler and frontend (the windowing toolkit if you prefer e.g. linux label can build both gtk and framebuffer). The filter for this job is several kilobytes of text which due to the first issue has to be cut and pasted by hand.

Handling of simple makefile based projects is rudimentary.
This has been worked around mainly by creating shell scripts to perform the builds. These scripts are checked into the repositories so they are readily modified. Initially we had the text in each job but that quickly became unmanageable.

Output parsing is limited.
Fortunately several plugins are available which mitigate this issue but I cannot help feeling that they ought to be integrated by default.

Website output is not readily modifiable.
Instead of perhaps providing a default css file and all generated content using that styling someone with knowledge of JAVA must write a plugin to change any of the look and feel of the jenkins tool. I understand this helps all jenkins instances look like the same program but it means integrating jenkins into the rest of our projects web site is not straightforward.
ConclusionIn conclusion I think the CI system is an invaluable tool for almost any non trivial software project but the implementation costs with current tools should not be underestimated.

Gergely Nagy: What's cooking in syslog-ng 3.5?

The first alpha of syslog-ng 3.4 was released more than a year ago, and the first stable release earlier this year, development on syslog-ng 3.5 has been going on steadlily since then, with a lot of interesting features and changes pouring in. While the 3.5 release will not bring as many overwhelming changes as the previous two releases did, the sheer number of improvements is still substantial. Our focus was on smaller developments all over the place this time, instead of big sweeping changes. In this post, we will go over most of these features, with use-cases, examples and a few words about why they are so useful and awesome.Multi-line support, new destinations, new template functions, type hinting, unit suffixes, and other things. Read on, and be amazed!These are only bigger features, there has been a lot of small tweaking going on, and of course, all of the fixes that went into prior versions will also be in 3.5 too, and there's still a chance that something else may find its way in before the feature freeze.Multi-line supportOne of the major new features in the 3.5 release will be support for multi-line messages, a feature that has been available in syslog-ng PE for a good while, and which has been ported to and improved upon to the open source edition. Two variants of multi-line are supported, which will be detailed below. Both of them are available for the file() and pipe() sources only.Indented multi-lineThe easiest variant is indented multi-line, where each line can be followed by others, indented by whitespace, and the message continues until the first non-indented line. This is the format used by the Linux kernel too, from version 3.5, for /dev/log. This type of multi-line can be used as follows:
source s_multiline   file("/path/to/file" multi-line-mode(indented));  ;
Consider that /path/to/file has the following content:
First line
 Continuation 1;
 Continuation 2;
Second line
With the indented multi-line-mode() setting, this would turn into two log messages:
First line\n Continuation 1;\n Continuation 2;
Second line
Regexp-based multilineIf multi-line input is not based on indentation, one can use the regexp multi-line-mode() instead, which makes two new settings available: multi-line-prefix() and multi-line-garbage(). These can be used to define the start and the end of a log message: any string between a the beginning matching prefix and a matching garbage will be considered a single message. That is, the prefix will be included, the garbage will not be: it will be discarded.To illustrate:
source s_multiline  
 file("/path/to/file" multi-line-mode(regexp)
                      multi-line-prefix("^prefix")
                      multi-line-garbage(" garbage$"));
 ;
If the source contains these lines:
prefix message
continuing garbage
This will turn into the following log message:
prefix message\ncontinuing
New destinationsIt would be pretty hard to do a syslog-ng release without new destinations, and with 3.5, we will have three of them!STOMPWhile we had AMQP before, we now have a STOMP destination too, so we can stream logs to any STOMP server, with a few simple lines:
stomp(
 host("localhost")
 port(61613)
 destination("/topic/syslog")
 routing_key("")
 persistent(yes)
 ack(no)
 username("someone")
 password("something")
 body("This is the body! YAY! Here's a message: $MESSAGE!\n")
 value-pairs(scope(nv-pairs, syslog-proto, selected-macros))
)
Of course, none of these settings need to be set, you can just use the defaults, and it will just work!RiemannDid you know that syslog-ng is far more than a log collector and processor? No? You do now. When you have access to a lot of logs, and a tremendous amount of power in parsing them, you can use these tools for monitoring easily! And when we're talking monitoring, riemann is a great asset in our toolbox, and with the new destination, we can easily forward metrics to it:
riemann(
 server("localhost")
 port(5555)
 host("$HOST")
 service("$PROGRAM")
 description("$PROGRAM pids")
 metric(int("$PID"))
 ttl(300)
);
Of course, the above is a very silly example, it would make much more sense to extract data from a log message instead, but this will serve as an example.New template functions
$(upper-case TEXT...), $(lower-case TEXT...)
To turn some text into *upper-* or *lower-case*, these two template functions come in handy. They simply turn all their arguments into the respecitve case.
$(delimit DELIMITERS NEW-DELIMITER TEXT)
Sometimes one has a delimited string, where one wishes to replace the delimiters. This function does just that: give it a list of delimiters (you may need to quote it, if it contains whitespace), a replacement, and a text to replace delimiters in, and it does the rest. For example, to replace tabs and spaces with a vertical bar, one could write a template like this:
template("$(delimit \"\t \" \" \" $MESSAGE)\n")
$(env VARIABLE...)
Have you ever felt the need to check an environment variable from within syslog-ng? I did, and now I can.
Type hintingWhile syslog-ng supported sending log messages into various data stores and message queues for a while (SQL at first, MongoDB, JSON and AMQP later), even when those supported different types of data than strings, we could not do anything else. Until now. It is now possible - at places where it makes sense - to annotate templates with type hints, which the destination driver can optionally use. Type hinting is implemented for the mongodb() destination and the $(format-json) template function for now. When no type hint is specified, syslog-ng defaults to string.To add type hints, simply wrap the respective template with the hinted type, like this:
mongodb(
 value-pairs(pair("date", datetime("$UNIXDATE"))
             pair("pid", int64("$PID")))
);
Currently the following type hints exist: boolean (anything that begins with a t or 1 is true, anything that begins with f or 0 is false, everything else is an error), string, literal (same as string, but not quoted if it would be quoted otherwise), int32 (int is an alias for this), int64, and datetime. Only UNIX timestamps can be type-hinted to datetime, anything else will likely result in a casting error.It is also possible to control what happens when type casting fails: syslog-ng can drop the whole message, drop the property, or fall back to string. It can also do all of these silently:
options  
 typecast(on-error(silently-drop-property));
 ;
Using this feature with $(format-json) is very similary too:
$(format-json date=datetime("$UNIXDATE") pid=int64("$PID"))
With this feature in place, you can now store your non-string values with their proper types!Unit suffixesUnit suffixes make it considerably easier to set limits and describe numbers within the syslog-ng configuration. We no longer need to spell out sizes to the byte precious, it is now enough to write: log-fifo-size(200MiB). Now, syslog-ng will understand suffixes for kilo-, mega-, and giga-bytes, (K, M, G, respectively) either in base-10 or base-2 (with an extra i after the suffix). One can also omit the trailing b from the end.So, to set the log-fifo-size() to 2097152 bytes, one can simply use 2MiB. Or, to set it to 2000000, 2Mb. That's a whole lot easier, isn't it? No more counting zeros, no more silly typos in a ten-digit number, no more pain, but easily readable units!Miscellaneous featuresApart from the features above, there have been a lot of other changes and improvements in the code base:

Tanguy Ortolo: PluXml, a file-based, database-free blog

The blog engine PluXml is now available as a Debian package:
Package: pluxml
Version: 5.2-2
Description-en: Light blog engine using XML files
 PluXml is a light and simple blog and CMS engine that uses simple XML
 files to store its data and requires no database. It has all the usual
 features (static pages, comments, categories, tags, medias, RSS
 feed...) and supports multiple users, customizable themes and plugins.
Homepage: http://www.pluxml.org/
Section: web
Priority: extra
PluXml logo: a leaf with its petiole used as one bar of the word  Xml
PluXml is a French blog engine that uses XML files to store its data, thus avoiding the need for an external database system as most blogs do. The name PluXml is a French portmanteau between plume (feather, evoking something light) and XML. Apart from that, although it was started in French only and its official website is still in French, it was internationalized about a year ago. It is designed to be easy enough to use, targeting regular users, but not too fancy: for instance, it provides a web-based administration interface, but content editing uses HTML code unless you install a graphical content editor plugin. That package may be of interest to people like me, that consider the almost systematic use of relational database systems in many web applications as a disease, and more generally to self-hosted people that would rather avoid running an additional database server on their small home servers. The package includes an interactive configuration, that allows to choose the blog language, title, description, admin login and password. Unless debconf was configured not to ask questions, in which case nothing is asked and the blog is left in an barely unusable state, of course.

4 September 2013

Russell Coker: Ownership of a Club

Last night at the Annual General Meeting we had a motion to disincorporate The Linux Users of Victoria (LUV) [1]. The proposal was for LUV to cease being an incorporated society on condition that Linux Australia (LA) [2] accepts us as a sub-committee. As a sub-committee of LA we would elect our own committee to run things locally but have LA hold the finances, deal with all the paperwork that the government demands, and generally do as many of the non-core tasks associated with running a users group as possible. When we discussed this at the LUV committee meetings it didn t seem like a big deal. But as is often the case with political discussions it turned out to be difficult. There was a lot of discussion about LUV supposedly ceasing to exist, people seem to think that LUV is defined by having an incorporated society. My impression was always that it was defined by a mailing list and having meetings and I was involved in both before there was an incorporated society. Lurkers and Ownership During the discussion we had some input from members who were typically lurkers who seemed to feel that their property rights towards LUV were being infringed, this annoys me. I think that if someone chooses not to be involved in running an organisation then they should choose not to concern themselves with the details of how the organisation is to be run. People who attend the meetings should have a say in how the meetings are run and have reason to be concerned about anything that might affect them and the opinions of speakers also matter. People who are involved with mailing list discussions should have a say in how the lists are run. But people who have never volunteered for a position on the committee shouldn t be greatly concerned about the internal issues of how things are run. Finance Some concern was expressed about the financial situation of LUV and whether we would still get enough donations to keep it running when combined with LA. There was even some FUD suggesting that LA would just take our money (they had assured us that all funds and donations would be ear-marked for us). The current LUV financial situation is that Red Hat pays for the venue for the monthly meetings and the rent for the venue comprises about 2/3 of all donations. The remaining 1/3 comes from one company. So in the current situation if Red Hat ceased donating then we would have 18 months to find another donor or cease holding meetings before our bank balance became unreasonably low. If the company which gives the other significant annual donation was to cease doing so then we could operate for a few years on savings but we would need to find some other source of funding. It seems to me that joining LA would give us more financial security. Then if Red Hat ceased paying for the venue then LA could keep things running until we found another donor, I m confident that LA wouldn t allow LUV to just shut down because of a shortage of donations. If people are really concerned about the financial situation of LUV then they should urgently seek further donations such that if any one donor decided to stop giving then we could still operate as normal. To achieve that goal I think we need at least another $1,000 per annum. This issue of redundancy in donations is something I raise every time that LUV finances are discussed. My conclusion is that people aren t really bothered about the financial security of LUV except when they are looking for reasons to avoid change. Doing New Things During the course of discussion about the future of LUV there were a number of requests for improvement. One significant request was for more support for regional Linux users. Some years ago we held a mini-conference in Ballarat which went well. I think it would be good to do such things again, the cost is not particularly great and I m sure it would be accepted by LA for funding, but we need to organise it. Organising such events is something that anyone can do. Any LUV member can plan an event, get costs for everything that is needed (food, accommodation, travel, etc) and then pitch it to the LUV committee in terms of which things should be paid by LUV and which by the members concerned. We could then work on getting additional funding from LA if necessary. But planning an event takes some effort and it s often effort that can only be done by a local. Finding a suitable venue and getting some assurance that a large enough audience will attend is something that can t be done remotely. I think that the problem for LUV in regard to such things isn t a lack of money or independence. I think that the problem is that the committee spends too much volunteer time on administrative tasks and not enough time directly doing things that benefit members and the community in general. In the past I have declined nomination to the LUV committee because I felt that I could contribute more by giving lectures, finding other speakers, and doing other things to directly improve the group. I was on the committee last year and have now been elected to it again, but I m starting to think that I made a mistake. Maybe I should have declined and let others work on the new model rules and other paperwork. One committee member has claimed that the time taken on administrative tasks isn t taking time away from other LUV related tasks, I invite any committee members who feel that way to address some of the services that members are requesting. Speaking for myself my lack of time directly impacts that I can do for the club. I think that ownership of a club should be related to what people do for the club. If you have a feeling of ownership and lack ideas for how to contribute then you can ask the LUV mailing list, there are lots of people with suggestions for things to do.

2 September 2013

Francesca Ciceri: Gems from DebConf13 talks

"I think that we need to be better at accepting mistakes. It's OK to not know everything, it's OK to not be perfect right from the start, but it's better to be vocal about things you don't know, things you are unsure, than to just hide it under the carpet and hope nobody will notice."
Lucas Nussbaum, Bits from the DPL "This is my definition for a team: waking up in the morning and realizing that somebody else has solved your problem from yesterday."
Andreas Tille, How to attract new developers for your team
While working on English subtitles for DC13 talks, you can stumble upon some real gems. The subtitling work is progressing nicely: four talks have now subtitles available (you can find them here), thanks to the work of Daniel, Gunnar and myself (as well as the reviews from Justin, Andreas and Michael!). In the meanwhile we created an alioth group and a related repository for the sub team, and there are several subtitles in progress! How can you help?

1 September 2013

Eddy Petrișor: Integrating Beyond Compare with Semanticmerge

Note: This post will probably not be on the liking of those who think free software is always preferable to closed source software, so if you are such a person, please take this article as an invitation to implement better open source alternatives that can realistically compete with the closed source applications I am mentioning here. I am not going to mention here where the open source alternatives are not up to the same level as the commercial tools, I'll leave that for the readers or for another article.



Semanticmerge is a merge tool that attempts to do the right thing when it comes to merging source code. It is language aware and it currently supports Java and C#. Just today the creators of the software have started working on the support for C.

Recently they added Debian packages, so I installed it on my system. For open source development Codice Software, the creators of Semanticmerge, offers free licenses, so I decided to ask for one today, and, although is Sunday, I received an answer and I will get my license on Monday.

When a method is moved from one place to another and changed in a conflicting way in two parallel development lines, Semanticmerge can isolate the offending method and can pass all its incarnations (base, source and destination or, if you prefer, base, mine and theirs) to a text based merge tool to allow the developer to decide how to resolve the merge. On Linux, the Semanticmerge samples are using kdiff3 as the text-based merge tool, which is nice, but I don't use kdiff3, I use Meld, another open source visual tool for merges and comparisons.


OTOH, Beyond Compare is a merge and compare tool made by Scooter Software which provides a very good text based 3-way merge with a 3 sources + 1 result pane, and can compare both files and directories. Two of its killer features is having the ability split differences into important and non-important ones according to the syntax of the compared/merged files, and the ability to easily change or add to the syntax rules in a very user-friendly way. This allows to easily ignore changes in comments, but also basic refactoring such as variable renaming, or other trivial code-wide changes, which allows the developer to focus on the important changes/differences during merges or code reviews.

Syntax support for usual file formats like C, Java, shell, Perl etc. is built in (but can be modified, which is a good thing) and new file types with their syntaxes can be added via the GUI from scratch or based on existing rules.

I evaluated Beyond Compare at my workplace and we decided it would be a good investment to purchases licenses for it for the people in our department.


Having these two software separate is good, but having them integrated with each other would be even better. So I decided I would try to see how it can be done. I installed Beyond compare on my system, too and looked through the examples


The first thing I discovered is that the main assumption of Semanticmerge developers was that the application would be called via the SCM when merges are to be done, so passing lots of parameters would not be problem. I realised that when I saw how one of the samples' starting script invoked semantic merge:
semanticmergetool -s=$sm_dir/src.java -b=$sm_dir/base.java -d=$sm_dir/dst.java -r=/tmp/semanticmergetoolresult.java -edt="kdiff3 \"#sourcefile\" \"#destinationfile\"" -emt="kdiff3 \"#basefile\" \"#sourcefile\" \"#destinationfile\" --L1 \"#basesymbolic\" --L2 \"#sourcesymbolic\" --L3 \"#destinationsymbolic\" -o \"#output\"" -e2mt="kdiff3 \"#sourcefile\" \"#destinationfile\" -o \"#output\""
Can you see the problem? It seems Semanticmerge has no persistent knowledge of the user preferences with regards to the text-based merge tool and exports the issue to the SCM, at the price of overcomplicating the command line. I already mentioned this issue in my license request mail and added the issue and my fix suggestion in their voting system of features to be implemented.

The upside was that by comparing the command line for kdiff3 invocations, the kdiff3 documentation and, by comparison, the Beyond Compare SCM integration information, I could deduce what is the command line necessary for Semanticmerge to use Beyond Compare as an external merge and diff tool.

The -edt, -emt and -e2mt options are the ones which specify how the external diff tool, external 3-way merge tool and external 2-way merge tool is to be called. Once I understood that, I split the problem in its obvious parts, each invocation had to be mapped, from kdiff3 options to beyond compare options, adding the occasional bell and whistle, if possible.

The parts to figure out, ordered by compexity, were:

  1. -edt="kdiff3 \"#sourcefile\" \"#destinationfile\"

  2. -e2mt="kdiff3 \"#sourcefile\" \"#destinationfile\" -o \"#output\""

  3. -emt="kdiff3 \"#basefile\" \"#sourcefile\" \"#destinationfile\" --L1 \"#basesymbolic\" --L2 \"#sourcesymbolic\" --L3 \"#destinationsymbolic\" -o \"#output\""

Semantic merge integrates with kdiff3 in diff mode via the -edt option. This was easy to map to Beyond Compare, I just replaced kdiff3 with bcompare:
-edt="bcompare \"#sourcefile\" \"#destinationfile\""
Integration for 2-way merges was also quite easy, the mapping to Beyond Compare was:
-e2mt="bcompare \"#sourcefile\" \"#destinationfile\" -savetarget=\"#output\""
For the 3-way merge I was a little confused because the Beyond Compare documentation and options were inconsistent between Windows and Linux. On Windows, for some of the SCMs, the options that set the titles for the panes are '/title1', '/title2', '/title3' and '/title4' (way too descriptive for my taste /sarcasm), but for some others are '/lefttitle', '/centertitle', '/righttitle', '/outputtitle', while on Linux the options are the more explicit kind, but with a '-' instead of a '/'.

The basic things were easy, ordering the parameters in the 'source, destination, base, output' instead of kdiff3's 'base, source, destination, -o ouptut', so I wanted to add the bells and whistles, since it really makes more sense for the developer to see something like 'Destination: [method] readOptions' instead of '/tmp/tmp4327687242.tmp', and because that's exactly what is necessary for Semanticmerge when merging methods, since on conflicts the various versions of the functions are placed in temporary files which don't mean anything.

So, after some digging into the examples from Beyond Compare and kdiff3 documentation, I ended up with:
-emt="bcompare \"#sourcefile\" \"#destinationfile\" \"#basefile\" \"#output\" -lefttitle='#sourcesymbolic' -righttitle='#destinationsymbolic' -centertitle='#basesymbolic' -outputtitle='merge result'"

Sadly, I wasn't able to identify the symbolic name for the output, so I added the hard coded 'merge result'. If Codice people would like to help with with this information (or if it exists), I would be more than willing to do update the information and do the necessary changes.

Then I added the bells and whistles for the -edt and -e2mt options, so I ended up with an even more complicated command line. The end result was this monstrosity:
semanticmergetool -s=$sm_dir/src.java -b=$sm_dir/base.java -d=$sm_dir/dst.java -r=/tmp/semanticmergetoolresult.java -edt="bcompare \"#sourcefile\" \"#destinationfile\" -lefttitle='#sourcesymbolic' -righttitle='#destinationsymbolic'" -emt="bcompare \"#sourcefile\" \"#destinationfile\" \"#basefile\" \"#output\" -lefttitle='#sourcesymbolic' -righttitle='#destinationsymbolic' -centertitle='#basesymbolic' -outputtitle='merge result'" -e2mt="bcompare \"#sourcefile\" \"#destinationfile\" -savetarget=\"#output\" -lefttitle='#sourcesymbolic' -righttitle='#destinationsymbolic'"
So when I 3-way merge a function I get something like this (sorry for high resolution, lower resolutions don't do justice to the tools):


I don't expect this post to remain relevant for too much time, because after sending my feedback to Codice, they were open to my suggestion to have persistent settings for the external tool integration, so, in the future, the command line could probably be as simple as:
semanticmergetool -s=$sm_dir/src.java -b=$sm_dir/base.java -d=$sm_dir/dst.java -r=/tmp/semanticmergetoolresult.java
And the integration could be done via the GUI, while the command line can become a way to override the defaults.

Raphaël Hertzog: My Free Software Activities in August 2013

This is my monthly summary of my free software related activities. If you re among the people who made a donation to support my work (47.50 , thanks everybody!), then you can learn how I spent your money. Otherwise it s just an interesting status update on my various projects. Package Tracking System There are only 2-3 weeks left in the summer of code project dedicated to rewrite the package tracking system. We have come a long way during August check it out yourself in pts.debian.net. The rewrite doesn t have all the features of the old PTS yet, but I opted to keep some of the easy and less interesting features for others to re-implement. Instead I asked Marko to work in the coming weeks on new features that will bring more value, like the possibility to have user accounts with the possibility to easily review and tweak all your subscriptions on the web, and like the possibility to subscribe to groups of packages (i.e. those managed by a team). Our main problem right now is that exim has a pretty poor default behavior of forking hundreds of processes if you get hundreds of mails (in a batch) to an address that delivers via a pipe (postfix is saner, it serializes the deliveries on pipes). The new PTS is much more modular and its memory footprint is bigger (about 3 times more for the process that delivers mails, 30Mb instead of 10Mb), and in such a situation we managed to run out of memory for now we worked around the situation with an exim setting that queues mails once the load gets too high but it s a poor workaround IMO. We could obviously implement our own queue and a daemon but I d like to avoid this. So who knows how to tell exim to behave? :-) On the positive side, Marko has gotten some feedback from people who like the new PTS and are using it daily already. And several persons have expressed their interest to work on the new codebase already. On my side, I created a package so that it s easy to deploy for derivatives. In this process, I revamped the way we manage the Django settings (for development and for production). The package is not finished yet, but it s mostly usable already. But I still want to do some cleanup/refactoring in the models before others start deploying it. We must also enable South to make it possible to upgrade easily afterwards. DebConf 13 in Vaumarcus From August 10th to 17th, I was attending DebConf 13. It matched the only week of vacation that my wife had this summer so we went there with the whole family (that is with a 3 years old son, and 6 months old one). Thus I could not immerse myself in Debconf and missed all the nice things that happen outside of the talk rooms. I picked 3-4 interesting talks per day and I spent the rest with my family. On the positive side, I was pleased that my wife could meet (or at least see) some other Debian people. She knows quite a few (of you) by name because I have been telling her Debian stories for years now Debian France Debian France sold quite some merchandise during Debconf but I didn t take care of that. It was supervised by Sylvestre Ledru but fortunately he got the help of multiple persons, both to bring everything there, to sell it, and to bring back the rest. The good news of the month is that the upstream author of galette published a new version with all the features that we ordered him a few months ago. We send now automatic reminders to members who must renew their subscription, we have automatic update of our accounting books (in a ledger file in a git repository) when we people donate or pay their subscription via the paypal form on our website. I was so pleased to finally have this that I took some hours to finalize the packaging of galette, so that it could be uploaded to Debian. It s now waiting in the NEW queue. I also spent multiple hours to write the python script that is executed by galette and that updates the accounting files. Misc Debian stuff Debian Packaging. I did two uploads of logidee-tools to fix bugs #718671 and #718836. I created a package for Dolibarr a PHP-based CRM and ERP software (it doesn t do accounting however), it s sitting in the NEW queue for almost a month already. I forwarded #719000 to the upstream Publican developers. I filed #720393 to request a new upstream version of libphp-mailer. git-multimail. After its deployment on Alioth last month, Niels Thykier reported me a case where it lead to bounces, I filed this as a new upstream ticket and in fact I fixed it myself a few days after. I got the fixed version installed on Alioth. dpkg. I investigated why the the automatic builds of dpkg were no longer happening and asked Michael Prokop if he could install a newer version of gettext in the build chroot. He told me that he would need a backport for that so I asked Santiago Vila if he was willing to provide it and he kindly accepted. A few days after, the package was in backports and I m now again running the latest dpkg out of git thanks to the nice service provided by Michael. Misc discussions. The thread about user planets drifted into a discussion of how to avoid promotional posts on such planets and in that context someone again brought up the Debian Machine Usage Policy as a way to shut down any kind of (self-)promotional content on planet if there s money involved. This always irritates me and this time I opted to ask James Troup about the origin of that clause in the DMUP. So who is willing to work with DSA to fix the DMUP so that people stop abusing it in contexts where it doesn t make sense? I also participated in some discussions concerning dgit. I like the ideas behind the tool, but I m saddened by the behavior of Ian Jackson. I helped him to fill his gap of knowledge about new sources formats but he keeps on bashing about the 3.0 (quilt) source format both in the manual page and in the output of the program. He believes that dgit is no longer an experiment but the truth is that it s still a poorly commented Perl script doing lots of hackish things. Kali Linux Between Debconf and all, I haven t done much for Kali except a couple of fixes. There s a nice story of how I tracked a bug in live-installer on the Kali blog. That fix has been committed to Debian. I also improved live-build to include xfsprogs/jfsutils on the ISO image when you include the debian-installer (so that you don t end up in problems when you pick JFS or XFS as file systems for your installation). Thanks See you next month for a new summary of my activities.

One comment Liked this article? Click here. My blog is Flattr-enabled.

Russ Allbery: Review: An Artificial Night

Review: An Artificial Night, by Seanan McGuire
Series: October Daye #3
Publisher: DAW
Copyright: September 2010
ISBN: 1-101-44276-X
Format: Kindle
Pages: 368
This is the third book of the October Daye series, following A Local Habitation. It could be read out of order, as each chapter of Toby's story so far is somewhat standalone, but I wouldn't recommend it. You'd miss the character development and the background behind several friendships. As with the previous book review, a caveat: I am reviewing this book four months after finishing it, rather than the normal couple of weeks, so apologies in advance for any thinness or inaccuracies. The first sign that something is about to go seriously wrong in Toby's life this time is a visitor. She says her name is May Daye, and apparently she's Toby's Fetch: a duplicate in nearly every respect except personality, manifested to guide someone to their death. Their imminent death. The second sign is that her best friend's children are kidnapped. The children who treat her like an aunt. And the cause of that kidnapping is far, far beyond the level of power that Toby could be expected to deal with. I have profound mixed feelings about this book. On one hand, McGuire further expands Toby's web of connections and shows us more of Toby's friends and their background, and that's becoming my favorite part of this series. She introduces May, who I think is a great character: at first apparently much different than Toby, but with a similarity beneath surface impressions that one notices more over time. And I thought the climax of the story, once we finally got there, was very moving and well-done. Also, I just love the way that McGuire uses children's rhymes and doggerel throughout this series as a magical element, and that's particularly well-handled here. Due to the nature of the antagonist, McGuire has a good excuse to bring that front and center, and the process of familiar rhymes expanding into deep magical rules was a fun intellectual experience. Best of all, the Luidaeg plays a significant role in the story again. The Luidaeg is, hands down, my favorite character in McGuire's constructed universe, and she becomes even more so over the course of this story. Her complex relationship with Toby is clearly blossoming into a friendship that's surprising both of them deeply, but a friendship that has to play by an odd set of rules (like so much else in Toby's life). I loved her here. Seeing someone that difficult and abrupt show unexpected emotional depths is one of the story elements I enjoy the most. The problem, though, is that quite a lot of An Artificial Night is very, very dark. And by that, I don't mean that there is a lot of tension, or that Toby is struggling against monsterous things, although both of those statements are also true. Rather, Toby is not only out of her league but ends up in some viciously nasty situations, and they persist for rather more of this book than I would have preferred. Putting one's protagonist through hell has a long tradition in urban fantasy, but I found the level of sheer helplessness that Toby struggled through to be a bit more than I wanted to read about. It was too reminiscent of events from Toby's background (as discussed in Rosemary and Rue) that I still don't like to think about. There is, of course, an eventual payoff, as dark as the interim events seem. One knows that, given the genre and given that this is an ongoing series, and even just given the nature of stories. But as much as I like the growing cast of this series, and adored the scenes with the Luidaeg, I found parts of this journey to be deeply disturbing, and not in an enjoyable dramatic tension sort of way. I don't mind protagonists being seriously hurt (although it's not my favorite plot), or even some amount of despair, but this went beyond that. I think McGuire was going for a story about sacrifice and self-definition, about trying even when one can't possibly win, and I can appreciate the narrative arc. But parts of the book were simply awful to read for me. I'm therefore not quite sure what to say in terms of a recommendation. I'm still reading the series, and will definitely read the next book. I think my reaction is somewhat idiosyncratic; the events here will probably not bother others as much as they bothered me. And I can't disagree with their dramatic effectiveness, or with the way that McGuire builds conflict out of the rules of fairy and is building Toby into a stronger and more capable person than she ever thought she could be. But there were still spots where I wished I were reading a different book. Hopefully the next book in the series will be that book I wanted to read. Followed by Late Eclipses. Rating: 6 out of 10

Russ Allbery: Review: Redshirts

Review: Redshirts, by John Scalzi
Publisher: Tor
Copyright: June 2012
ISBN: 1-4299-6360-3
Format: Kindle
Pages: 317
The next few reviews deserve a small apology in advance. Normally, I try to write reviews within a few weeks, or at most a month, after reading a book, while it's still fresh in my mind. This is particularly important since I read a lot and sometimes don't have a good memory for specific detail. But this summer has made it completely impossible to keep to any sort of regular writing schedule. As a result, this book, and the subjects of the next few reviews that follow, are books that I read four months ago and am reviewing from memory. Hopefully, I'll still get the details right. Ensign Andrew Dahl is one of the newest crew members of the Universal Union Capital Ship Intrepid. It's his first posting, just out of the Academy. He's one of five new ensigns, expecting a normal tour of duty (albeit with the pride of being on a capital ship of the fleet). But very shortly after arriving on the ship, Andrew and and the other new ensigns discover that something is very... strange. The casualty rate on the ship is surprisingly high (as foreshadowed in a prologue). The other crew members avoid the bridge crew, and particularly away missions, with startling effectiveness (and desperation). And things regularly happen on the ship that, for lack of a better description, simply make no sense. Redshirts starts off as a very obvious Star Trek parody. So obvious, in fact, that it's eyeroll-inducing. The prologue reads exactly like a section of a Star Trek episode written by a third-rate hack, leavened with some of the humor that readers of Scalzi's blog have come to expect. But it's obvious that Scalzi is doing this intentionally, and it doesn't take long before the subject of the book shifts. It's a Star Trek parody that functions much more like a Star Trek parody than any universe should, to the degree that it becomes obvious to the characters. And the characters, despite being straight from central casting, are clearly not expecting their universe to act that way and find this extremely strange. By far the best part of this book is the second quarter: the characters have been introduced, they're starting to figure out what's going on, and they have to do so while dodging away-team duty (or trying to survive it) and participating in the ridiculous plot contrivances that keep occurring. Scalzi mixes a feeling of serious consequences with wry humor and handles the mix deftly. I was both laughing and eagerly reading to see what comes next. The last half of the book, though, has problems. How many problems the reader perceives will, I think, depend on how hard one thinks about the situation Scalzi has set up, or how much one has thought about similar constructs in the past. But I'm afraid the setup does not survive serious scrutiny in ways that, for me at least, seriously damaged my ability to engage with the story. I'm going to avoid saying explicitly where Scalzi goes with this plot, since it is a spoiler (although it's commonly mentioned in discussions of this book on the Internet). But it happens to be an idea that some friends of mine and I pounded on for years in some of our role-playing scenarios, poking at the corners and implications, and subsequently gave up on because it doesn't work for storytelling. The idea is compelling, and on first glance seems like a great story seed. But it's too large. The problem with really big ideas with huge implications is that they can change the nature of a story so much that there's no longer any point of commonality for the reader and the entire nature of story falls apart. And I think that's what happens here. Scalzi handles the deeper implications of the concept by, essentially, ignoring them. He focuses on one narrow set of implications for one specific set of people, largely skips over any discussion of anything larger, and tries a pivot from wry humor (and a bit of slapstick) into serious emotional depth. For me, in part because I'm so familiar with the concept, none of this really worked. The implications of the discovery that drives this story are so much broader and so much more significant than the characters seem to admit that it threw me right out of the story. The ethical implications are absolutely paralyzing, to the point that I don't think you can write a coherent story about them, but ignoring them doesn't work either. It's the kind of discovery that requires action of some kind beyond the attempt by the characters to go back to what they consider a normal life, even if I have a hard time imagining what that action could be. To be fair, he does try to salvage this in the first epilogue, which is all about the implications of his idea and its effects. But it's still too small. That epilogue just barely touches on the implications on a single person, but if one thinks a bit longer, one starts coming up with more and more implications for all of society, for how we talk about story, for how we raise children, for nearly every form of creativity. Implications that involve nasty concepts like slavery and mind control and murder and the nature of consent in ways that are very difficult to avoid. I think Scalzi's attempts at serious emotional connection, including in the other two attached epilogues (which are perspective-shifting close focuses on some of the characters), also suffer from his world setup, but in a different way. The characters are simply too bland to sustain the level of emotional connection he's striving for. They're bland for a very specific reason that is entirely justified by the story that Scalzi is handling, and the implications of that for the primary protagonist were, I thought, one of the best-handled moments of the book. But they're still bland, which undermines the attempted pivot. All that being said, this is not a bad book. Parts of it, particularly the second quarter, are excellent. And even when I wasn't engaging with the characters, Scalzi's writing on a paragraph level is snappy and often quite funny. The first epilogue in particular is hilarious, even if I think it was too limited in the scope of implications that it considers and a bit too meta in where it goes with those implications. And the story is a fun romp, with drama and humor and tension and a fairly satisfying ending. Everyone's a bit too bland and earnest when Scalzi isn't being funny, but he's funny enough that I didn't mind that much. Despite the relatively low rating, I actually recommend this book. If you don't dive into the metaphysical implications, it's a lot of fun, and if you've thought a lot about this particular set of metaphysical implications, it's somewhat satisfying to argue with (and to internally point out all of the hard questions that Scalzi is skipping over). It's particularly fun if you've watched a lot of Star Trek, since Scalzi gets some of the absurdities note-perfect. But be aware that the character reactions to Scalzi's concept don't hold up to much scrutiny. Rating: 7 out of 10

31 August 2013

Christian Perrier: DebConf 13: running outcome

This DebConf has been the first one where I ran every day. That proved to be kinda hard on some mornings, but I found a way to circumvent that by proposing group runs at the end of the relevant days. In total, I managed to run 12 days in a row, for a grand total of 186.88km, in 21h22', for a total height difference of 6972m. In short, I nearly climbed Mount Aconcagua, Americas highest peak..:-) Most of these runs were quite slow ones and rather "short" ones (around 15km), because of the nature of the paths around (nearly impossible to find something flat except by running around the football field). The longest run was for the DayTrip, with about 25km in about 4 hours (including some pauses) and 1600m height difference. I'm definitely working on my moutain running skills more than marathon and other kind of "speed" races. That followed a great results for my last race, the "EDF Cenis Tour" 50km trail race in Lanslebourg, French Alps, where I completed the race in 6h38, nearly the sametime than Mont-Blanc marathon, 1 month earlier....which was 8 kilometers shorter. I'm apparently ready for very long distance mountain races, now, as it seems. Thanks you DebConf 13 organizers for choosing such a great locations for us, crazy runners. And, despite that, my next running goal is a "classical" marathon, the Toulouse marathon in late October, where I expect breaking the 3h30 barrier, that would indeed be a qualifier for the Boston Marathon, one of my dreams for the future (and, yes, it is still a dream, despite this year's events).

30 August 2013

Daniel Pocock: Big decision?

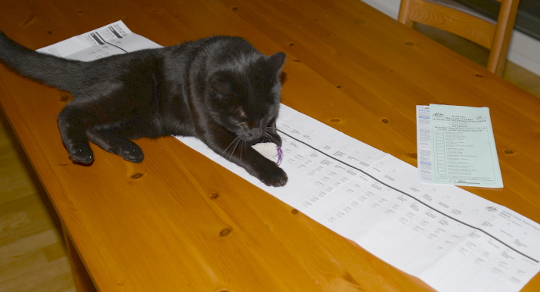
Most people have probably heard that elections are on in Australia. I just received my postal ballot paper the other day and in the spirit of transparency, I'm sharing it here on my blog. Spoilt for choice There are two ballots, one for the Lower House and the other for the Senate. The big one is for the Senate. Our cat is on top of it to help give some perspective on how big it is. Like the columns on a bloated spreadsheet, the parties are designated with symbols from A to AM and then there are some leftover candidates too. Animal instincts With so many candidates to choose from, even our kitty may have found an opportunity in the Animal Justice Party - although that little snack in her claws suggests that she is more interested in the law of the jungle than any political debate. She may want to be wary not to fall under the wheel of the party next to them, Motoring Enthusiasts. The Senate, a place for convicted hackers? The next party in the picture is Wikileaks and their number one candidate, of course, is the first person to successfully claim asylum from Australia, Julian Assange. It's no secret that he has a string of convictions for computer hacking in the 90s and that when US authorities catch up with him, their drone won't just be dropping him a letter demanding a $2,100 penalty fine through the window. So how do they compare? As I contemplate my decision, lets look at the numbers:
Party Seats won in 2010
House of Reps, Senate
Criminal charges against members in last 3 years
Labor Party 72, 31 173, mainly fraud
Liberal/National coalition (conservative) 73, 34 3, including shoplifting and assault
Wikileaks 0 None - Assange is not actually charged with any crime
All of a sudden, in a country that is often the butt of British jokes about convicts, Assange starts to look squeaky clean. He may take further comfort from knowing that out of all those crimes, hacking is the only one that appears to have the presidential seal of approval. Conclusion Whichever way I vote may or may not make so much difference. With so many candidates to choose from though, there is little sign of any quality leadership from any corner of Australian politics. Whether Mr Assange is elected or not, many people will have a chuckle when they realise he almost ended up alongside the Australian Sex Party out of 38 other possible parties randomly distributed across the ballot. Please feel free to comment: which party is the most ridiculous?

Joey Hess: best DebConf ever

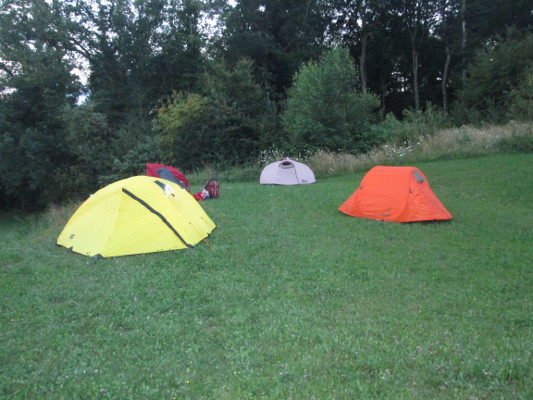
For me, DebConf13 in Switzerland was a perfect DebConf, and generally an great developer meeting and conference. I've attended several past DebConfs in Canada, Norway, Brazil, Finland, Mexico, Scotland, Spain, NYC, Bosnia, and Nicaragua. I have special memories of each. DebConf13 was ideal in every way. Let's start with the camping. Only a minority of us did it, and my campsite was located in a small field behind a bar that was often noisy late into the night, when I was trying to rest and preserve my European jetlag remedy of inverted sleeping schedule. Still, I love sleeping cocooned in a tent, and going through the routines of camping and spending time alone there was a good counterpoint to DebConf. I generally find myself retreating for a day or two in the middle of a week-long conference, burnt out with social interactions. That didn't happen this time. I need to find way to camp at future DebConfs. (Also special shout out to wonderful people who lent me a warmer sleeping bag, and bought me a pillow while on a trip to town! Upgraded my first backpacking in Europe experience's comfort level a lot!) The next perfect thing for me were the talks I gave at DebConf. I always enjoy presenting at DebConf, and barely remember when I'd get nervous doing it. But I really felt comfortable giving these talks in a way I've not before. I'm pleased with how the Debian Cosmology talk turned out; I'd worried it would be a downer talk, or too light, or not well received, and none of those problems surfaced. I was especially happy with my dh_busfactor session, which I prepared for all of 10 minutes and was structured entirely to benefit me by talking over my thoughts and getting feedback, and in which I probably drove the camerapeople crazy running my own mic into the audience. Despite all that, I think it succeeded being interesting for the participants as well as for me. Hope to follow up on it soon.. But beyond the two talks I submitted, there were a series of ad-hoc scheduled talks. It seemed that every day I spent at least an hour discussing something I'm deeply involved in. This started with the Ikiwiki bof, and then there was an epic series of (unrecorded) BoFs about git stuff, which basically turned into an unofficial git track at DebConf. Much, much discussion of git-annex and other things I'm involved in. BTW, I really like that DebConf, as well as being a formal conference on top, is really an un-conference underneath, with new BoFs and things popping up on the schedule all week long. You can even have completely unscheduled meetings that somehow get just the right mix of people to make something awesome happen.
But it wasn't all about talks. Indeed, I only attended 2 or 3 sessions a day. The DebConf13 venue was controversial, but I found it excellent for getting things done. Rather than one or two massive rooms that get too noisy to think in, this venue had many little nooks and crannies suited for different types of work. There were so many I only discovered some while walking down the hill as I was leaving the venue! Anchoring it all was the excellent view, and I particularly enjoyed the "scenic hacklab". I was particularly impressed with the flexability of the venue's management. Someone asked if we could have cheese for breakfast, and every breakfast thereafter had not one but often three excellent cheeses. One day we'd be complaining that there were not enough vegetables in the food, and the next we'd be eating an excellent vegetarian Swiss lunch. They even apparently relaxed stringent Swiss rules on not allowing tents in sightlines visible from people further up the hill. They were clearly happy to welcome our crazy gathering to Le Camp. They let a DD borrow and use a chain saw and build a bonfire! The venue also encouraged getting out and exploring the surrounding countryside. Too often I end up spending the whole DebConf without seeing much of the area around. This time I at least got down the hill to see the castle in Vaumarcus a few times, and enjoyed many evening walks amoung the grape fields. The conference dinner (on a boat!) tied into this well too. And the daytrip to CERN was a great addition. We got to poke around the control center for a massive particle accellerator! My only regret is we didn't get a chance to actually go inside the LHC tunnels. Back to DebConf, another thing I really liked about this one was that its location allowed several upstream authors of software in Debian (other than the usual suspects who are both upstreams and Debian Developers) to attend. I don't know if Lennart Poettering changed any minds about systemd with his talk, but I was happy for the opportunity to buy him a beer. I didn't get to Monty's talk, but it was excellent to see him attend as well. Finally, I got to meet old friends I'd not seen in years, and new ones I've not met in real life before. We're still not sure where this whole DebConf thing is going -- will it be all about the cheese and wine party and greybeards in 20 years time? But one thing we know is we enjoy our little slice of the year where kilts and coding are equally unremarkable, where problems that seem intractable online somehow solve themselves in person, where we come away with ideas for an entire year and memories for a lifetime.

Michael Stapelberg: How git performs when you throw all of Debian at it

During DebConf, Asheesh presented the idea of using git instead of the file system for storing the contents of Debian Code Search. The hope was that it would lead to fewer disk seeks and less data due to gits delta-encoding. Maybe the reduction would be big enough that enough data could be held in RAM to allow for fast retrieval. Joey Hess helped me out with a couple of details: he revealed that using git repack -a -d will lead to a single packfile that optimally contains HEAD, not caring about the history. Also, he showed me how to use git cat-file. We did a small-scale experiment and the results were promising. I told him I ll do the experiment of just committing the entire unpacked source mirror to git and promised to follow up with the results, so here goes:
stapelberg@couper ~/unpacked master $ time cat <<EOT   git cat-file --batch >/dev/null
:linux_3.2.32-1/sound/pci/ice1712/aureon.c
:linux_3.2.32-1/sound/soc/codecs/sgtl5000.c
:linux_3.2.32-1/sound/pci/hda/patch_conexant.c
EOT
cat <<<''  0,00s user 0,00s system 62% cpu 0,006 total
git cat-file --batch > /dev/null  4,38s user 1,08s system 99% cpu 5,477 total
stapelberg@couper ~/unpacked master $ time cat linux_3.2.32-1/sound/pci/ice1712/aureon.c linux_3.2.32-1/sound/soc/codecs/sgtl5000.c linux_3.2.32-1/sound/pci/hda/patch_conexant.c >/dev/null
cat linux_3.2.32-1/sound/pci/ice1712/aureon.c   > /dev/null  0,00s user 0,00s system 69% cpu 0,006 total
stapelberg@couper ~/unpacked master $ time cat <<EOT   git cat-file --batch >/dev/null
:i3-wm_4.6-1/libi3/font.c
EOT
cat <<<':i3-wm_4.6-1/libi3/font.c'  0,00s user 0,00s system 51% cpu 0,008 total
git cat-file --batch > /dev/null  4,30s user 1,18s system 99% cpu 5,533 total
stapelberg@couper ~/unpacked master $ time cat i3-wm_4.6-1/libi3/font.c >/dev/null
cat i3-wm_4.6-1/libi3/font.c > /dev/null  0,00s user 0,00s system 0% cpu 0,004 total
Even after repeating those tests a couple of times to get a warm page cache, the result stays the same: git takes about 5 seconds to resolve the deltas in a large repository. Even if this was 5 seconds startup time and a very small amount of additional time per file, it would not be acceptable for our use case. The conclusion is that git is clearly not suitable for this kind of usage, which is not surprising after having heard a couple of times that git does not scale :-). For the curious, the .git/objects directory is 29 GiB for roughly 140 GiB of source code, so the delta encoding is quite impressive in terms of saving space. However, keep in mind that the compressed (!) Debian source archive is about 35 GiB, so the savings are not that huge.

Scott Kitterman: skitterman

This hit my Washington Post Top Stories feed tonight: The case against software patents Maybe the word is getting out

28 August 2013

Vincent Sanders: Men admire the man who can organize their wishes and thoughts in stone and wood and steel and brass.


I would probably not yet worthy of the admiration Emerson was alluding to but I do like to make things. As anyone who has read previous posts knows I have pretty much embraced the "do things, tell people" idea.

One small wrinkle is doing things needs somewhere to work. Since moving myself and the family to rented accommodation in Cambridge (swampy 3,500 year old English city, not the one in Massachusetts) I have been lacking space to do practical projects.

The main space
To fix this lack I have joined the cambridge makespace which, in addition to somewhere I can work gives me access to some tools I was previously unable to afford. The space gives practical training on the more complex machines (any tool can be dangerous if you do not use it correctly) which recently allowed my induction on the CNC router.

My instructor , Mark Mellors, who was good enough to give up some of his valuable making time to train me (and accidentally get his car stuck in a car park overnight by staying late) suggested that it was a good idea to have a design to try.

I decided to use this opportunity to actually create something useful (though now I re-read Marks message it did suggest a simple design...oopsy). I had been working at the electronics bench in previous weeks and been uncomfortable using the existing stools and chairs as they were either a bit high or unable to be adjusted high enough for the 80cm tall benches. I decided to design a 60cm tall stool for use at this workbench.

My initial idea was for a simple three leg stool, round top, three legs, how hard could it be? Initial research showed that showed that above 30cm the legs needed to be braced to each other. This is because the leg to seat joints simply cannot handle the stress caused by leverage which longer legs introduce.

I looked at the structure of several stools online and was initially drawn towards creating something like the IKEA Dalfred bar stool. It was discovered that the design would be easier to realise if it were made from sheet material which give a smaller challenge to a naive operator of a CNC router. Because of this simpler designs were researched and I eventually found a simple design I liked.

The design could not however be used directly as it was for imperial sized material which is not available in europe. I selected the QCAD open source CAD package and recaptured the design adjusting for the available 12mm plywood sheet material. This resulted in an imperial measurement design for metric materials.

Mark helped me transfer the DXF into the CAM software (vcarve pro 7, after I discovered the demo version of this software generates files which cannot be imported into the full edition!) and generate toolpaths for our machine. Once the toolpaths are saved to a USB stick (no modern conveniences like direct upload here) the job can be run on the machine.

Here I ran into reality, turns out that tolerances in imperial combined with lack of understanding how plywood reacts resulted in excessive play in the joints. This resulted in an unusable stool, which simply tried to rotate around its central axis and become flatpack. I had successfully turned 10 worth of plywood into some sawdust and a selection of useless shapes. On the other hand I did become competent with the router workflow so it was not a complete failure.

I was determined to make the design work so I decided to start from scratch with a similar design but entirely in metric. I performed some material research both online and practically (why yes i did spend an informative hour in several cambridge DIY shops with digital calipers, why do you ask?) it turns out that generally available 12mm thick plywood actually ranges between 11.9 and 12mm thick.

I did some test slot cuts of varying width and determined that the available stock can be "persuaded" to fit into a 11.8mm wide slot. This Interference fit joint is strong and removes the need for adhesive in most cases.

Second cut still attached to the bed. Leftovers of first attempt in the background
The sheet plywood material is readily available with a width of 1220mm and a height of 606mm (a full sheet is 2440mm long which is cut into four with a 4mm wide saw blade) so making the legs fit within a sheet and be close to the 60cm target should be possible.

I selected a suitable seat radius (175mm) and from that determined the minimal gap to the base ring with a 6mm end mill tool (20mm for two toolpaths and some separation) and hence the minimum suitable width of the base ring (50mm) giving a total radius of 245mm.

For the legs allowance was made for two joints of 30mm with 30mm separation between them the legs come out at 90mm width. If a 6mm space and a 6mm toolpath top and bottom of the sheet is accounted for a 582mm height (606 - 24) is available in which to fit the legs. The top of the leg which fits into the seat is 12mm tall leaving 570mm total leg height.

12mm plywood stool design
At this point I selected some arbitrary values for the leg positioning and angle (30mm from seat centre and 15 ) using a right angle triangle triganometry this produced a stool with a base of around 550mm or 100mm outside the radius of the seat. This seemed a pleasing shape and when the values for the holding ring were calculated it is at 104mm height which also seems to work out well.

This design was cut on the machine, lightly finished with some sandpaper and assembled. The legs slotted into the ring first and then the legs eased into the seat slots, the whole thing flipped and the seat hammered home onto the legs.

Anne Harrison volunteering to try the wobbly stool of doom
Success! It physically fit together and if you were brave enough you could sit on it. Unfortunately the plywood seemed to flex around the central axis of rotation in a rather alarming way, fine if you are under 70 kilos but not giving the impression of security most people want from their seating.

Ok, lets try with five legs instead of three (at least we can reuse the existing three legs)...nope still not good enough and another 10 gone.

18mm Plywood stool design
The others in the space suggested a few ideas to improve matters and the one I selected was to use 18mm plywood instead of 12mm, this should improve rigidity. There was a brief pause in proceedings to discover 18mm sheet is actually 17.7mm and needs a 17.5mm slot to make the interference fit work.

Completed 18mm stool
A swift redesign later altering the seat radius, gap, ring width and leg height to accommodate the new material and we have version 4 and it works without caveat. Tested up to 150Kg load without trouble, there is a small amount of flex still but nothing that feels worrying.

I finished the stool by rounding the seat top edge with a ball bearing rounding bit in a manual router and applying a couple of coats of gloss acrylic varnish. Finished stool is now doing service at the space.

In conclusion the final design allows someone with a CNC router to create a useful 580mm high fixed stool for 7.50 in timber plus cutter wear and varnish so maybe 8.50 total.

You can actually get five legs and a seat/ring out of a 1220x606 sheet and with intelligent arrangement a single 1220x2440 sheet will probably yield five or possibly six stools in total

I am making the design files of the proven 18mm version available (heck they are all there...but you have been warned, none of the other solutions produce a satisfactory result) under the MIT licence so anyone can reproduce. More pretty pictures are also available.

Matt Zimmerman: Scaling Human Systems: Roles and Responsibilities

This is part 5 in a series on organizational design and growth. What it means

Each of us has a job to do, probably more than one, and our teammates should know what they are. Why it s important

Roles are a kind of standing commitment we make to each other. They re a way of dividing up work which is easy to understand and simple to apply. Utilizing this tool will make it easier for us to coordinate our day to day work, and manage the changes and growth we re going through. Old Status Quo

Roles are vague or nonexistent. Management roles in particular are probably not well understood. Many people juggle multiple roles, all of which are implicit. Moving to a new team means learning from scratch what other people do. People take responsibility for tasks and decisions largely on a case-by-case basis, or based on implicit knowledge of what someone does (or doesn t do). In many cases, there is only one person in the company who knows how to perform a certain function. When someone leaves or goes on vacation, gaps are left behind. New Status Quo

Each individual has a clear understanding of the scope of their job. We have a handful of well defined roles, which are used by multiple teams and have written definitions. People who are new or transfer between teams have a relatively easy time understanding what the people around them are doing. Many day to day responsibilities are defined by roles, and more than one person can fill that role. When someone leaves a team, another person can cover their critical roles. Behaviors that help

Obstacles that stand in our way

Next.

Previous.