Search Results: "reg"

5 June 2013

Steve Kemp: How do people deal with email?

As part of writing a new mail client I'm wondering about how to change my email-life, and how other people process/handle their incoming email. I sort my incoming email into folders at delivery-time using procmail. Mail is generally filtered into mailboxes on the basis of the company that sent it, the person that sent it, or the machine which generated it. Because I manage a lot of machines personally I've split things up so that I have a folder per host. So on a morning I might have unread mail in the following folders:
machines.steve.org.uk/
machines.da-db1/
machines.da-db2/
machines.da-web1/
machines.da-web2/
machines.da-web3/
machines.da-web4/
The per-machine mailboxes usually contain a single mail every day from LogWatch, along with output from any cron-jobs. For example today I received the mail:
From: Cron Daemon
To: steve@steve.org.uk
Subject: Cron steve@steve.org.uk /home/steve/bin/download-check
URL http://nodejs.org/ - no longer matches v0.10.9
Generally speaking I don't need to read the per-machine messages. I'll keep the most recent 100 for reference, but only need to look if something seems "off" on a machine. But if I don't look I'd not see the node upgrade notice, so find that I do read them after all. This suggest to me that email isn't the right way to handle this kind of thing. Instead I should use a notification system - at work we have a central service called MauveAlert (yes, Red Dwarf reference). Mauve receives "alerts" of various kinds, via UDP. The alerts are then fanned out to appropriate people via XMPP, Email, or SMSs. I have a similarly-inspired system I use on my Debian Administration cluster. A (node) service runs non-stop collecting UDP messages and showing them on a dashboard. I look at it throughout the day to see when slaughter runs, etc. Anyway in conslusion I get a lot of mail. Some of it is related to random projects, and all ends up in the steve.org.uk/ mailbox, some of it relates to machines, and gets filed away, and I have regular conversions with folk so I have a .people.kirsi/ folder which receives a lot of attention, for example. ObRandom:daily() - Mark ~/Maildir/.machines.*, etc, read.

4 June 2013

Keith Packard: dri3 extension

Completing the DRI3 Extension This week marks a pretty significant milestone for the glorious DRI3000 future. The first of the two new extensions is complete and running both full Gnome and KDE desktops. DRI3 Extension Overview The DRI3 extension provides facilities for building direct rendering libraries to work with the X window system. DRI3 provides three basic mechanisms:
  1. Open a DRM device.
  2. Share kernel objects associated with X pixmaps. The direct rendering client may allocate kernel objects itself and ask the X server to construct a pixmap referencing them, or the client may take an existing X pixmap and discover the underlying kernel object for it.
  3. Synchronize access to the kernel objects. Within the X server, Sync Fences are used to serialize access to objects. These Sync Fences are exposed via file descriptors which the underlying driver can use to implement synchronization. The current Intel DRM driver passes a shared page containing a Linux Futex.
Opening the DRM Device Ideally, the DRM application would be able to just open the graphics device and start drawing, sending the resulting buffers to the X server for display. There s work going on to make this possible, but the current situation has the X server in charge of blessing the file descriptors used by DRM clients. DRI2 does this by having the DRM client fetch a magic cookie from the kernel and pass that to the X server. The cookie is then passed to the kernel which matches it up with the DRM client and turns on rendering access for that application. For DRI3, things are much simpler the DRM client asks the X server to pass back a file descriptor for the device. The X server opens the device, does the magic cookie dance all by itself (at least for now), and then passes the file descriptor back to the application.
 
    DRI3Open
    drawable: DRAWABLE
    driverType: DRI3DRIVER
    provider: PROVIDER
       
    nfd: CARD8
    driver: STRING
    device: FD
 
    Errors: Drawable, Value, Match
    This requests that the X server open the direct rendering
    device associated with drawable, driverType and RandR
    provider. The provider must support SourceOutput or SourceOffload.
    The direct rendering library used to implement the specified
    'driverType' is returned in 'driver'. The file
    descriptor for the device is returned in 'device'. 'nfd' will
    be set to one (this is strictly a convenience for XCB which
    otherwise would need request-specific information about how
    many file descriptors were associated with this reply).
Sharing Kernel Pixel Buffers An explicit non-goal of DRI3 is support for sharing buffers that don t map directly to regular X pixmaps. So, GL ancillary buffers like depth and stencil just don t apply here. The shared buffers in DRI3 are regular X pixmaps in the X server. This provides a few obvious benefits over the DRI2 scheme: In the kernel, the buffers are referenced by DMA-BUF handles, which provides a nice driver-independent mechanism.
  1. Lifetimes are easily managed. Without being associated with a separate drawable, it s easy to know when to free the Pixmap.
  2. Regular X requests apply directly. For instance, copying between buffers can use the core CopyArea request.
To create back- and fake-front- buffers for Windows, the application creates a kernel buffer, associates a DMA-BUF file descriptor with that and then sends the fd to the X server with a pixmap ID to create the associated pixmap. Doing it in this direction avoids a round trip.
 
    DRI3PixmapFromBuffer
    pixmap: PIXMAP
    drawable: DRAWABLE
    size: CARD32
    width, height, stride: CARD16
    depth, bpp: CARD8
    buffer: FD
 
    Errors: Alloc, Drawable, IDChoice, Value, Match
    Creates a pixmap for the direct rendering object associated
    with 'buffer'. Changes to pixmap will be visible in that
    direct rendered object and changes to the direct rendered
    object will be visible in the pixmap.
    'size' specifies the total size of the buffer bytes. 'width',
    'height' describe the geometry (in pixels) of the underlying
    buffer. 'stride' specifies the number of bytes per scanline in
    the buffer. The pixels within the buffer may not be arranged
    in a simple linear fashion, but 'size' will be at least
    'height' * 'stride'.
    Precisely how any additional information about the buffer is
    shared is outside the scope of this extension.
    If buffer cannot be used with the screen associated with
    drawable, a Match error is returned.
    If depth or bpp are not supported by the screen, a Value error
    is returned.
To provide for texture-from-pixmap, the application takes the pixmap ID and passes that to the X server which returns the a file descriptor for a DMA-BUF which is associated with the underlying kernel buffer.
 
    DRI3BufferFromPixmap
    pixmap: PIXMAP
       
    depth: CARD8
    size: CARD32
    width, height, stride: CARD16
    depth, bpp: CARD8
    buffer: FD
 
    Errors: Pixmap, Match
    Pass back a direct rendering object associated with
    pixmap. Changes to pixmap will be visible in that
    direct rendered object and changes to the direct rendered
    object will be visible in the pixmap.
    'size' specifies the total size of the buffer bytes. 'width',
    'height' describe the geometry (in pixels) of the underlying
    buffer. 'stride' specifies the number of bytes per scanline in
    the buffer. The pixels within the buffer may not be arranged
    in a simple linear fashion, but 'size' will be at least
    'height' * 'stride'.
    Precisely how any additional information about the buffer is
    shared is outside the scope of this extension.
    If buffer cannot be used with the screen associated with
    drawable, a Match error is returned.
Tracking Window Size Changes When Eric Anholt and I first started discussing DRI3, we hoped to avoid needing to learn about the window size from the X server. The thought was that the union of all of the viewports specified by the application would form the bounds of the drawing area. When the window size changed, we expected the application would change the viewport. Alas, this simple plan isn t sufficient here a few GL functions are not limited to the viewport. So, we need to track the actual window size and monitor changes to it. DRI2 does this by delivering invalidate events to the application whenever the current buffer isn t valid; the application discovers that this event has been delivered and goes to as the X server for the new buffers. There are a couple of problems with this approach:
  1. Any outstanding DRM rendering requests will still draw to the old buffers.
  2. The Invalidate events must be captured before the application sees the related ConfigureNotify event so that the GL library can react appropriately.
The first problem is pretty intractable within DRI2 the application has no way of knowing whether a frame that it has drawn was delivered to the correct buffer as the underlying buffer object can change at any time. DRI3 fixes this by having the application in control of buffer management; it can easily copy data from the previous back buffer to the new back buffer synchronized to its own direct rendering. The second problem was solved in DRI2 by using the existing Xlib event hooks; the GL library directly implements the Xlib side of the DRI2 extension and captures the InvalidateBuffers events within that code, delivering those to the driver code. The problem with this solution is that Xlib holds the Display structure mutex across this whole mess, and Mesa must be very careful not to make any Xlib calls during the invalidate call. For DRI3, I considered placing the geometry data in a shared memory buffer, but my future plans for the Present extension led me to want an X event instead (more about the Present extension in a future posting). An X ConfigureNotify event is sufficient for the current requirements to track window sizes accurately. However, there s no easy way for the GL library to ensure that ConfigureNotify events will be delivered to the application other application code may (and probably will) adjust the window event mask for its own uses. I considered adding the necessary event mask tracking code within XCB, but again, knowing that the Present extension would probably need additional information anyhow, decided to create a new event instead. Using an event requires that XCB provide some mechanism to capture those events, keep them from the regular X event stream, and deliver them to the GL library. A further requirement is that the GL library be absolutely assured of receiving notification about these events before the regular event processing within the application will see a core ConfigureNotify event. The method I came up with for XCB is fairly specific to my requirements. The events are always XGE events, and are tagged with a special event context ID , an XID allocated for this purpose. The combination of the extension op-code, the event type and this event context ID are used to split off these events to custom event queues using the following APIs:
/**
 * @brief Listen for a special event
 */
xcb_special_event_t *xcb_register_for_special_event(xcb_connection_t *c,
                                                    uint8_t extension,
                                                    uint16_t evtype,
                                                    uint32_t eid,
                                                    uint32_t *stamp);
This creates a special event queue which will contain only events matching the specified extension/type/event-id triplet.
/**
 * @brief Returns the next event from a special queue
 */
xcb_generic_event_t *xcb_check_for_special_event(xcb_connection_t *c,
                                                 xcb_special_event_t *se);
This pulls an event from a special event queue. These events will not appear in the regular X event queue and so applications will never see them. There s one more piece of magic here the stamp value passed to xcbregisterforspecialevent. This pointer refers to a location in memory which will be incremented every time an event is placed in the special event queue. The application can cheaply monitor this memory location for changes and known when to check the queue for events. Within GL, the value used is the existing dri2 stamp value. That is checked at the top of the rendering operation; if it has changed, the drawing buffers will be re-acquired. Part of the buffer acquisition process is a check for special events related to the window. For now, I ve placed these events in the DRI3 extension. However, they will move to the Present extension once that is working.
 
    DRI3SelectInput
    eventContext: DRI3EVENTID
    window: WINDOW
    eventMask: SETofDRI3EVENT
 
    Errors: Window, Value, Match, IDchoice
    Selects the set of DRI3 events to be delivered for the
    specified window and event context. DRI3SelectInput can
    create, modify or delete event contexts. An event context is
    associated with a specific window; using an existing event
    context with a different window generates a Match error.
    If eventContext specifies an existing event context, then if
    eventMask is empty, DRI3SelectInput deletes the specified
    context, otherwise the specified event context is changed to
    select a different set of events.
    If eventContext is an unused XID, then if eventMask is empty
    no operation is performed. Otherwise, a new event context is
    created selecting the specified events.
The events themselves look a lot like a configure notify event:
 
    DRI3ConfigureNotify
    type: CARD8         XGE event type (35)
    extension: CARD8        DRI3 extension request number
    length: CARD16          2
    evtype: CARD16          DRI3_ConfigureNotify
    eventID: DRI3EVENTID
    window: WINDOW
    x: INT16
    y: INT16
    width: CARD16
    height: CARD16
    off_x: INT16
    off_y: INT16
    pixmap_width: CARD16
    pixmap_height: CARD16
    pixmap_flags: CARD32
 
    'x' and 'y' are the parent-relative location of 'window'.
Note that there are a couple of odd additional fields offx, offy, pixmapwidth, pixmapheight and pixmap_flags are all place-holders for what I expect to end up in the Present extension. For now, in DRI3, they should be ignored. Synchronization The DRM application needs to know when various X requests related to its buffers have finished. In particular, when performing a buffer swap, the client wants to know when that completes, and be able to block until it has. DRI2 does this by having the application make a synchronous request from the X server to get the names of the new back buffer for drawing the next frame. This has two problems:
  1. The synchronous round trip to the X server isn t free. Other running applications may cause fairly arbitrary delays in getting the reply back from the X server.
  2. Synchronizing with the X server doesn t ensure that GPU operations are necessarily serialized between the application and the X server.
What we want is a serialization guarantee between the X server and the DRM application that operates at the GPU level. I ve written a couple of times (dri3k first steps and Shared Memory Fences) about using X Sync extension Fences (created by James Jones and Aaron Plattner) for this synchronization and wanted to get a bit more specific here. With the X server, a Sync extension Fence is essentially driver-specific, allowing the hardware design to control how the actual synchronization is performed. DRI3 creates a way to share the underlying operating system object by passing a file descriptor from application to the X server which somehow references that device object. Both sides of the protocol need to tacitly agree on what it means.
 
    DRI3FenceFromFD
    drawable: DRAWABLE
    fence: FENCE
    initially-triggered: BOOL
    fd: FD
 
    Errors: IDchoice, Drawable
    Creates a Sync extension Fence that provides the regular Sync
    extension semantics along with a file descriptor that provides
    a device-specific mechanism to manipulate the fence directly.
    Details about the mechanism used with this file descriptor are
    outside the scope of the DRI3 extension.
For the current GEM kernel interface, because all GPU access is serialized at the kernel API, it s sufficient to serialize access to the kernel itself to ensure operations are serialized on the GPU. So, for GEM, I m using a shared memory futex for the DRI3 synchronization primitive. That does not mean that all GPUs will share this same mechanism. Eliminate the kernel serialization guarantee and some more GPU-centric design will be required. What about Swap Buffers? None of the above stuff actually gets bits onto the screen. For now, the GL implementation is simply taking the X pixmap and copying it to the window at SwapBuffers time. This is sufficient to run applications, but doesn t provide for all of the fancy swap options, like limiting to frame rate or optimizing full-screen swaps. I ve decided to relegate all of that functionality to the as-yet-unspecified Present extension. Because the whole goal of DRI3 was to get direct rendered application contents into X pixmaps, the Present extension will operate on those X objects directly. This means it will also be usable with non-DRM applications that use simple X pixmap based double buffering, a class which includes most existing non-GL based Gtk+ and Qt applications. So, I get to reduce the size of the DRI3 extension while providing additional functionality for non direct-rendered applications. Current Status As I said above, all of the above functionality is running on my systems and has booted both complete KDE and Gnome sessions. There have been some recent DMA-BUF related fixes in the kernel, so you ll need to run the latest 3.9.x stable release or a 3.10 release candidate. Here s references to all of the appropriate git repositories: DRI3 protocol and spec:
git://people.freedesktop.org/~keithp/dri3proto      master
XCB protocol
git://people.freedesktop.org/~keithp/xcb/proto.git  dri3
XCB library
git://people.freedesktop.org/~keithp/xcb/libxcb.git dri3
xshmfence library:
git://people.freedesktop.org/~keithp/libxshmfence.git   master
X server:
git://people.freedesktop.org/~keithp/xserver.git    dri3
Mesa:
git://people.freedesktop.org/~keithp/mesa.git       dri3
Next Steps Now it s time to go write the Present extension and get that working. I ll start coding and should have another posting here next week.

Daniel Pocock: Using reSIProcate to connect Asterisk with WebRTC

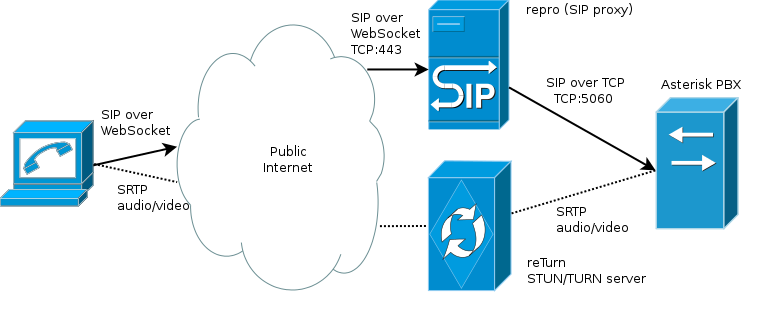
In my previous blog entry about how to get WebRTC going fast I looked at the basics of setting up a SIP proxy (also known as a SIP router) to accept connections from WebRTC clients. As in a traditional, non-WebRTC world, the SIP proxy simply facilitates calling between all the clients it knows. In practice, deployments usually want to add additional functionality in the form of a PBX with queues, voicemail, menus and conferencing. The recent Asterisk 11 release includes support for WebRTC although it is still evolving and I don't currently recomend connecting Asterisk directly to the public Internet. In particular, Asterisk doesn't support features like mutual TLS authentication with the WSS (secure WebSocket) transport. Here, we look at how repro can accept connections from Internet/web users and relay them to an internal Asterisk server. Here is an architecture diagram: Notice that the SIP messages are accepted over repro's WebSocket transport and relayed to Asterisk over a regular SIP TCP transport. This means that we benefit from repro's TLS support too, so the WebSocket client has a much higher chance of escaping their client-side firewall if port 443 is used (repro pretending to be a HTTPS server) and clients can be authenticated with certificates in their browser. Here are the steps to get it running: repro and reTurn setup Set up repro and reTurn server on a Debian server as per my previous blog post. Verify that the clients can talk to repro. Asterisk source build Digium, the creators of Asterisk, are not currently supporting Debian packages, but they do provide RPM packages in their Asterisk package repository However, the pre-built binary packages for Asterisk 11.4 don't include SRTP support. SRTP is a mandatory part of WebRTC. Therefore, we take the Source RPM (SRPM) and build it manually. First, it is recommended that you start with a completely fresh CentOS 6 or RHEL6 server. I built a fresh virtual machine in my XCP environment using a procedure similar to that documented by Grant. After installing and setting a root password, configure yum to access EPEL6 Make sure SELinux and firewall are disabled on the box (they are often enabled by default). A quick way to do this:
# sed -i s/SELINUX=enforcing/SELINUX=disabled/g /etc/selinux/config
# reboot
...
# iptables -I INPUT -j ACCEPT
Next you can tell yum about the Digium repository and install all the necessary dependencies for building Asterisk:
# rpm -Uvh http://packages.asterisk.org/centos/6/current/x86_64/RPMS/asterisknow-version-3.0.0-1_centos6.noarch.rpm
# yum update
# yum install rpm-build libsrtp-devel
In your home directory, set up a work tree for rpmbuild:
$ mkdir ~/rpmbuild
$ cd ~/rpmbuild
$ mkdir BUILD BUILDROOT RPMS SOURCES SPECS SRPMS
$ cd SPECS
$ wget http://danielpocock.com/sites/danielpocock.com/files/asterisk.spec
$ cd ../SRPMS
$ wget http://packages.asterisk.org/centos/6/asterisk-11/SRPMS/asterisk-11.4.0-1_centos6.src.rpm
$ rpmbuild --rebuild asterisk-11.4.0-1_centos6.src.rpm
At this stage, you will have some errors, but it has successfully extracted the tarball into the SOURCES directory:
$ ls -l ../SOURCES
-rw-r--r--   1 daniel daniel 11573400 May 20 23:07 asterisk-sources-11.4.0.tar.gz
$
It will also complain about missing dependencies, you install them using yum:
# yum install make gcc gcc-c++ ....
Notice that you have downloaded a slightly modified version of the asterisk.spec file, the reasons for this are explained in this mailing list discussion. The following should now trigger a successful build:
$ rpmbuild -bb \
  --without tds \
    --without misdn \
    --without odbc \
   ~/rpmbuild/SOURCES/asterisk.spec
Hopefully, Digium will add the SRTP support in the 11.4.1 packages so that source build won't be necessary for every future release. Asterisk configuration: demo application Here we just have to install the RPMs and make a quick configuration change:
$ cd ~/rpmbuild/RPMS/x86_64
$ su -
# rpm -i asterisk*rpm
# yum install asterisk-sounds-core-en-ulaw asterisk-sounds-extra-en-ulaw --enablerepo=asterisk-11
# ln -s /usr/share/asterisk/sounds/demo-* /var/lib/asterisk/sounds/en/
To enable connections from the proxy, we must set a few non-default settings. It is essential to use the TCP transport as the SIP messages from WebSocket clients are usually too big for UDP packets. It is also necessary to enable SRTP and AVPF, as these are mandatory in WebRTC. Here is a diff against the default /etc/asterisk/sip.conf:
--- /etc/asterisk.orig/sip.conf	2013-06-04 10:57:49.428617785 +0200
+++ /etc/asterisk/sip.conf	2013-06-04 11:18:17.825604261 +0200
@@ -207,7 +207,7 @@
 ; subject to change in any release.  If they are changed, the changes will
 ; be reflected in this sample configuration file, as well as in the UPGRADE.txt file.
 ;
-tcpenable=no                    ; Enable server for incoming TCP connections (default is no)
+tcpenable=yes                    ; Enable server for incoming TCP connections (default is no)
 tcpbindaddr=0.0.0.0             ; IP address for TCP server to bind to (0.0.0.0 binds to all interfaces)
                                 ; Optionally add a port number, 192.168.1.1:5062 (default is port 5060)
 
@@ -1371,6 +1371,13 @@
 ; ...
 ;
 
+[1001](public-phone,ulaw-phone)
+avpf = yes
+encryption = yes
+context = public
+icesupport = yes
+
+
 ; Standard configurations not using templates look like this:
 ;
 ;[grandstream1]
This assumes that the SIP user ID of your WebSocket user is 1001 Now you can start Asterisk:
# service asterisk start
Configuring the repro SIP proxy to send calls to Asterisk This is a relatively simple demonstration. The goal is to send calls for the number 1000 to the demo application in Asterisk In repro's web interface, click ADD ROUTE in the menu. Use the following parameters and leave all other options blank:
  • URI: ^sip:1000@
  • Destination: sip:$1@pbx.example.org?transport=tcp
Note: replace pbx.example.org with the hostname or IP address of the box running Asterisk Go to the ADD USER menu link and add a user called 1001. The user ID and password have to be placed in the custom.js file for JsSIP Testing from JsSIP I assume JsSIP was set up following the instructions from my previous blog post Asterisk doesn't support the video codec from a WebRTC client. To work around this, in the custom.js file for JsSIP, make sure video is disabled by default. In the WebRTC client, dial 1000. You should hear the demo greeting from Asterisk. Troubleshooting
  • Check the JavaScript log in the browser
  • Check the logs on the repro proxy and increase the verbosity of the logs if necessary. If the level is set to STACK, you will see full copies of each SIP message sent and received.
  • Connect to the Asterisk console (UNIX command: asterisk -r -vvv) and enable SIP message display: sip set debug on.

Steve Kemp: Minimalism still works out

When people ask me why I chose to embed Lua in my mail-client I'll point to my on_idle() documentation. Moving from a callback which runs once every second, or so, to allowing the user to schedule tasks on arbitrary boundaries is pretty cool - and obviously requires no explicit support from myself. Now I've fixed a couple of bugs which went unspotted/unreported in the first release I'm ready for a new one "soon". In the meantime I'm running the client exclusively, and loving the ability to view all unread mail, only, regardless of the parent folder.

3 June 2013

NeuroDebian: Running 64bit Matlab on 32bit host OS

Running 64bit Matlab on 32bit host OS Some of you have experienced problems due the recent move of Mathworks to drop 32-bit Linux builds of their products (i.e. Matlab R2013a and co.). Please note that this is not the first time Mathworks values its own costs higher than the benefits of a few scientists. In 1998 PowerPC builds for Macs were abandoned, causing a furious reaction of the community. Luckily, users of the fresh Debian stable release wheezy (or more recent variants of Debian and its derivatives) who still need a 32bit OS on 64bit-capable hardware can take advantage of the new multiarch support. Multiarch allows for multiple architecturesi to co-exist on a hardware/kernel that is capable of supporting both (e.g. i386 and amd64). Below we describe how you can use multiarch support and in few simple steps that prepare your existing 32bit user-land for running 64bit Matlab.
Procedure
  • [2-10 min] Install 64-bit kernel and reboot:

    sudo apt-get install linux-image-amd64
  • [1-3 min] Enable multi-arch support for amd64 architecture:

    sudo dpkg --add-architecture amd64
    sudo apt-get update
  • [1-5 min] Install 64bit libraries (and compilers) needed for matlab:

    sudo apt-get install libstdc++6:amd64 zlib1g:amd64 libncurses5:amd64 \
      libxp6:amd64 libstdc++6-4.4-dev:amd64 libxt6:amd64 libxmu6:amd64 libxtst6:amd64 \
      g++:amd64 gcc:amd64 binutils:amd64
Now your 64bit matlab (which you hopefully registered with matlab-support) is ready to run. If you have any comments (typos, improvements, etc) feel welcome to leave a comment below, or contact us .

2 June 2013

Gregor Herrmann: RC bugs 2013/22

here's the overview about my RC bug fixing activities for the last week:

1 June 2013

Daniel Pocock: Democracy down-under is not democracy

This weekend we have the AGM of a local community organisation. Like many organisations I am involved in, there will be a democratic process of decision making, board election and a low-budget social activity afterwards. We take it for granted that democracy is a good thing. In my own country, Australia, people are supposedly happier than they've ever been, no doubt people will suggest that our democracy is part of the recipe for success. While this example is from Australia, it could well happen anywhere. While everybody was slapping themselves on the back about our officially confirmed contentment, the politicians tried to slip something under the radar. With elections expected in September, the press exposed a secret deal between the two biggest political parties, raiding the public piggy bank for $60 million to prop up their campaign accounts. There is even a leaked copy of a letter confirming the deal. It was to be voted through parliament in a stitch-up within 48 hours after the happiness' announcement. Why would these two big political parties engage in a such a gross conspiracy? Weren't they already content with their whopping big pay increases that put our Prime Minister on a bigger salary than the US president or the UK Prime Minister? Well, you don't have to look hard to find out what this special funding was all about: Not long ago, the post office at the University of Melbourne where Wikileaks operates a post-office box was mysteriously shut down. While that may seem like it could just be a co-incidence on it's own, it's worth considering in the wider context: the Wikileaks party is one of the most widely recognised names in Australian politics right now. The party's leader, like the new pope, is seen as somebody who puts his principles ahead of his own comfort, living a humble life in exile while our politicians romp around with prostitutes paid for with stolen money. Whatever you think of Wikileaks or Mr Assange's private life, they are not the only example here. There are other democratic movements in our country that are equally frightening for those who are currently drunk on power. One of the independent MPs holding the balance of power is a former Lieutenant Colonel in Australia's spy agency who was ridiculed by a prior Government and forced out of his job when he exposed the sham of the Iraq war. Neither of the major political parties wants to continue being held accountable by someone who has shown such strong principles against their campaign of death and deception. That $60 million welfare payment to big political parties was intended to be something akin to a weapon of mass destruction, obliterating independent representatives out of the parliament. More recently, the same independent MP has been equally vigorous in his campagin to break the scourge of our mafia-style gambling industry with it's cosy links to Australian politicians. Now it is starting to become obvious just how scary democracy can be. Motivated by the spectacle of a few independents holding our incumbent politicians to account, other Australians have also volunteered to get in on the act and try their hand at running the country. One of Australia's richest men, Clive Palmer has found that even with his enormous wealth (and having started planning more than a year before the election), his plans to form a political party are dampened by the fact that it can't be registered with a proper name to be listed on the ballot paper and all the candidates have to be listed under his name, Palmer, or their own names, barely distinguishable from the independent candidates. This discriminatory approach to the creation of political parties clearly favours the two big incumbent groups. Now it is a lot clearer why existing politicians needed an extra $60 million war chest: like Lance Armstrong's illegal doping program, it was intended to keep themselves ahead of the pack. It all goes to show that people should not take democracy for granted: constant vigilence and involvement is needed to hold leaders to account or replace them when they deviate.
AttachmentSize
piggy-bank.jpg32.83 KB

28 May 2013

Russell Coker: SCSI Failures

For a long time it was widely regarded that SCSI was the interface for all serious drives that were suitable for Enterprise Use or for anything else which requires reliable operation. On the other hand IDE was for cheap disks that were only suitable for home use. The SCSI vs IDE issue continues to this day but now we have SAS and SATA filling the same market niches with the main difference between the current debate and the debate a decade ago being that a SATA disk can be connected on a SAS bus. Both SAS and SATA have a single data cable for each disk which avoids the master/slave configuration on IDE and the issue of bus device ID number (from 0-7 or 0-15) and termination on SCSI. Termination When a high speed electrical signal travels through a cable some portion of the signal will be reflected from any cable end point or any point of damage. To prevent the signal reflection from the end of a cable you can have a set of resistors (or some other terminating device) at the end of the cable, see the Terminator(electrical) Wikipedia page [1] for a brief overview. As an aside I think that page could do with some work, if you are an EE with a bit of spare time then improving that page would be a good thing. SCSI was always designed to have termination while IDE never was. I presume that this was largely due to the cable length (18 for IDE vs 1.5m to 25m for SCSI) and the number of devices (2 for IDE vs 7 or 15 for SCSI). I also presume that some of the problems that I ve had with IDE systems have been related to signal problems that could have been avoided with a terminated bus. My first encounter with SCSI was when working for a small business that focused on WindowsNT software development. Everyone in the office knew a reasonable amount about computers and was happy to adjust the hardware of their own workstation. A room full of people who didn t understand termination who fiddled with SCSI buses tended to give a bad result. On the up-side I learned that a SCSI bus can work most of the time if you have a terminator in the middle of the cable and a hard drive at the end. There have been two occasions when I ve been at ground zero for a large deployment of servers from a company I ll call Moon Computers. In both cases there were two particularly large and expensive servers in a cluster and one of the cluster servers had data loss from bad SCSI termination. This is particularly annoying as the terminators have different colours, all that was needed to get the servers working was to change the hardware to make them look the same. As an aside the company with no backups [2] had one of the servers with bad SCSI termination. Heat SCSI disks and now SAS disks tend to be designed for higher performance, this usually means greater heat dissipation. A disk that dissipates a lot of heat won t necessarily work well in a desktop case with small and quiet fans. This can become a big problem if you have workstations running 24*7 in a hot place (such as any Australian city that s not in Tasmania) and turn the air-conditioner off on the weekends. One of my clients lost a few disks before they determined that IDE disks are the only option for systems that are to survive Australian heat without any proper cooling. Differences between IDE/SATA and SCSI/SAS In 2009 I wrote about vibration and SATA performance [3]. Rumor has it that SCSI/SAS disks are designed to operate in environments where there is a lot of vibration (servers with lots of big fans and fast disks) while IDE/SATA disks are designed for desktop and laptop systems in quiet environments. One thing I d like to do is to test performance of SATA vs SAS disks in a server that vibrates. SCSI/SAS disks have apparently been designed for operation in a RAID array and therefore will give a faster timeout on a read error (so another disk can return the data). While IDE/SATA disks are designed for a non-RAID situation and will spend longer trying to read the data. There are also various claims about the error rates from SCSI/SAS disks being better than those of IDE/SATA disks. But I think that in all cases the error rates are small enough not to be a problem if you use a filesystem like ZFS or BTRFS but they are also large enough to be a significant risk with modern data volumes if you have a lesser filesystem. Data Loss from Storage Failure In the data loss that I ve personally observed from storage failures the loss from SCSI problems (termination and heat) is about equal to all the hardware related data loss I ve seen on IDE disks. Given that the majority of disks I ve been responsible for have been IDE and SATA that s a bad sign for SCSI use in practice. But all serious data loss that I ve seen has involved the use of a single disk (no RAID) and inadequate backups. So a basic RAID-1 or RAID-5 installation will solve most hardware related data loss problems. There was one occasion when heat caused two disks in a RAID-1 to give errors at the same time, but by reading from both disks I managed to get almost all the data back, RAID can save you from some extreme error conditions. That situation would have been ideal for BTRFS or ZFS to recover data. Conclusion SCSI and SAS are designed for servers, using them in non-server systems seems to be a bad idea. Using SATA disks in servers can have problems too, but not typically problems that involve massive data loss. Using technology that is too complex for the people who install it seems risky. That includes allowing programmers to plug SCSI disks into their workstations and whoever it was from Moon computers or their resellers who apparently couldn t properly terminate a SCSI bus. It seems that the biggest advantage of SAS over SCSI is that SAS is simple enough for most people to be able to correctly install it. Making servers similar to the systems that the system administrators use at home seems like a really good idea. I think that one of the biggest benefits of using x86 systems as servers is that skills learned on home PCs can be transferred to administration of servers. Of course it would also be a good idea to have test servers that are identical to servers in production so that the sysadmin team can practice and make mistakes on systems that aren t mission critical, but companies seem to regard that as a waste of money apparently the risk of down-time is cheaper.

Johannes Schauer: New bootstrap analysis results

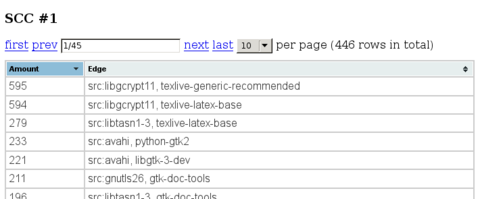
I wrote a small wiki page for botch. It includes links to some hopefully useful resources like my FOSDEM 2013 talk or my master thesis about botch. The final goal of botch is to generate a build order with which Debian can be bootstrapped from zero to more than 18000 source packages. But such a build order can only be generated once enough source packages (by now the number is around 70) incorporate build profiles which allow to compile them with less build dependencies and thereby break all build dependency cycles. So an intermediary goal of botch is, to find a "good" (i.e. a close to minimal amount) selection of such build dependencies that should be dropped from their source packages. So far, the results of all heuristics we use for this task were just dumped to standard output. Since this textual format was hard to read for a human developer and even worse machine readable, that tool now outputs its results in JSON. This data is then converted by another tool to a more human readable format. One such format is HTML and with the help of javascript for sortable and pageable tables, the data can then be presented without producing too much visual clutter (at least compared to the initial textual format). Another advantage of HTML is, that the data can now easily be shared with other developers without them having to run botch or install any other program first. So without further ado, please find the result of running our heuristics on Debian Sid as of 2013-01-01 here: http://mister-muffin.de/bootstrap/stats/ Here is a screenshot of what you can expect (you can see part of the table of edges with most cycles through them): As a developer uses this information to add build profiles to source packages, this HTML page can be regenerated and will show which strongly connected components are now left in the graph and how to best make them acyclic as well. Besides other improvements I also updated the data I used to generate the graphs from this post. I found this update to be necessary since we found and fixed several implementation bugs since October 2012, so this new plot should be more accurate. Here a graph which shows the amount of vertices in the biggest strongly connected component of Debian Sid by date. Some datapoints are missing for dates for which important source packages in Sid were not compilable.

Russ Allbery: Collected haul

I've been slow lately in writing these up (and, for that matter, in doing most other things related to reading; things have been rather busy lately). This is a bunch of here-and-there purchases over the last few months, including Powell's Indiespensible shipments. Sandra Barret Face of the Enemy (sff)
Anne Bishop Written in Red (sff)
Lois McMaster Bujold Captain Vorpatril's Alliance (sff)
Cary Caffrey The Girls from Alcyone (sff)
Jenni Fagan The Panopticon (mainstream)
Niels Ferguson, et al. Cryptography Engineering (non-fiction)
Jen Kirchner The Fourth Channel (sff)
Anothony Marra A Constellation of Vital Phenomena (mainstream)
Steve McConnell Code Complete (non-fiction)
Seanan McGuire Velveteen vs. The Junior Super-Patriots (sff)
Patrick Nielsen Hayden, et al. (ed.) Some of the Best from Tor.com: 2012 (sff anthology)
Lisa O'Donnell The Death of Bees (mainstream)
Susan Palwich Flying in Place (sff)
Kim Stanley Robinson 2312 (sff)
John Scalzi Redshirts (sff)
Ian Tregillis Bitter Seeds (sff)
Leon Trotsky The History of the Russian Revolution (non-fiction)
Simon Van Booy The Illusion of Separateness (mainstream)
Chris Anne Wolfe Shadows of Aggar (sff)
Barbara Ann Wright The Pyramid Waltz (sff) That's a lot of stuff. It includes a couple of non-fiction O'Reilly books from sales, a few months of Powell's Indiespensible subscriptions, a variety of books I picked up after a discussion of good lesbian fiction on Tor.com (romance without the obnoxious gender tropes, or at least as many of them), and the rest of the Hugo nominees for the year. I got a ton of reading done earlier this month. I wish I could say the same thing about reviews, but I only wrote a few. That's something that I want to try to catch up on soon, so there will probably be a flurry of those posted soon. I've already read Blackout and Redshirts of this year's nominees (a review of the latter is coming), so at least I'm not too far behind on the reading. Throne of the Crescent Moon is in progress now.

27 May 2013

Michael Stapelberg: Results of the Debian systemd survey

A week ago, we started the Debian systemd survey. The goal was to figure out a few trends and answer the following two questions:
  1. Do our subjective impressions from the discussions on debian-devel reflect the general sentiment about systemd?
  2. What are the main concerns that most people have?
Thank you all for your participation! General I am happy to tell that 2113 people had a look at the survey and 573 people actually participated. Of those, 45.7% said they are a DD, DM or otherwise maintaining packages. 74.5% said they actually booted and used a computer running systemd. With regards to having systemd in Debian at all, not necessarily as the default init system, answers are as follows: 43.9% said they personally want systemd as the default init system in Debian, while 32.2% don t want that. The remaining 23.7% don t know yet. Top concerns About 50% of participants provided one or more concerns. Evaluating this part of the survey is obviously the hardest, since the answers were provided as free text. I tried categorizing the feedback into a few buckets. Each bucket comes with a number which is a weighted (!) count, i.e. the top concern counts 3 times, the second concern counts 2 times and the last concern just once. If you cannot find your personal concerns, that is because those which were just voiced by less then five people are not listed here. As I said, we cared about trends in this survey, not individual opinions.
  1. systemd is too complex, or bloated, or it does too many things, or has too many dependencies (weight: 217)
  2. systemd is not portable to non-linux systems, e.g. Debian/kFreeBSD or HURD (weight: 199)
  3. Debugging the boot process is harder than in sysvinit (weight: 106)
  4. I have a problem with systemd upstream and/or Lennart in particular (weight: 87)
  5. systemd violates the UNIX philosophy (weight: 35)
  6. I dislike binary logs and/or the journal in general (weight: 30)
  7. systemd is too new, still untested, unstable and experimental (weight: 24)
  8. I cannot find enough documentation in general or about the transition from sysvinit to systemd in particular (weight: 20)
  9. People need to learn new commands/how the new system works (weight: 20)
  10. I don t know what problems systemd solves and/or have no problems with sysvinit currently (weight: 19)
  11. I think the configuration is binary and/or the configuration format is weird (weight: 13)
  12. systemd s code is not good (memory leaks, performance problems) and/or upstream s development lacks best practices such as long-term stable branches (weight: 9)
  13. There are problems with systemd in Debian (e.g. Debian-specific extensions to /etc/fstab not supported, system doesn t boot) (weight: 9)
  14. Customizing the boot is harder than with sysvinit (weight: 8)
  15. systemd is not compatible with sysvinit (weight: 8)
I realize that the choice of buckets is somewhat broad and there are many different, finely nuanced opinions out there. Again, this is for seeing a trend, not accounting for every single individual opinion. In case you strongly believe that I did something wrong when evaluating the survey results, please contact me and we can work something out. Conclusions/Actions I know this is a controversial topic. Please don t start yet another systemd discussion on debian-devel. We, the systemd Debian maintainers, will try to come up with good answers to all listed concerns and communicate them in a friendly and concise way soon. Furthermore, we have recognized the need for more documentation/information about how things are supposed to work with regards to the transition (and systemd in general) and will address that, too. Raw questions/numbers
Total records in survey: 573
Are you a Debian Developer (DD) or Debian Maintainer (DM) or otherwise currently maintaining Debian packages?
262 Yes
311 No
Did you ever boot and use a computer running systemd? It does not matter whether that computer was running Debian or a different operating system.
427 Yes
146 No
What is your general sentiment towards having systemd in Debian (not necessarily as default)?
358 I welcome systemd in Debian, everything is fine.
 81 I am not sure yet.
 46 I don t care.
 88 I don t want systemd in Debian.
Would you personally want systemd as the default init system in Debian?
252 Yes
136 I don t know
185 No

26 May 2013

Gregor Herrmann: RC bugs 2013/21

like last week, I was working on the preparation of the Perl 5.18 transition. besides that I also uploaded some RC bug fixes, mostly by taking patches that came from Ubuntu (kudos!): as a side note (or better: question): why are the bugs for the upcoming Apache 2.4 and openjdk-7 transitions classified as 'serious', instead of as 'important', like the Perl 5.18 ones?

Andrew Pollock: [life] Maker Fair 2013 virtual trip report

The Maker Faire is one of the Bay Area things that I'll really miss. Zoe had a ball last year (for weeks afterwards every outing was "Maker Faire!" regardless of what or where it was) Last year I didn't really get to cover it very well, so I ended up doing a bit of a virtual tour via the exhibitor list on their website, and so this year I thought I'd be there in spirit by doing the same thing again. Here's my picks:

25 May 2013

Petter Reinholdtsen: How can I install Linux on a Packard Bell Easynote LV preinstalled with Windows 8?

I've run into quite a problem the last few days. I bought three new laptops for my parents and a few others. I bought Packard Bell Easynote LV to run Kubuntu on and use as their home computer. But I am completely unable to figure out how to install Linux on it. The computer is preinstalled with Windows 8, and I suspect it uses UEFI instead of a BIOS to boot. The problem is that I am unable to get it to PXE boot, and unable to get it to boot the Linux installer from my USB stick. I have yet to try the DVD install, and still hope it will work. when I turn on the computer, there is no information on what buttons to press to get the normal boot menu. I expect to get some boot menu to select PXE or USB stick booting. When booting, it first ask for the language to use, then for some regional settings, and finally if I will accept the Windows 8 terms of use. As these terms are completely unacceptable to me, I have no other choice but to turn off the computer and try again to get it to boot the Linux installer. I have gathered my findings so far on a Linlap page about the Packard Bell EasyNote LV model. If you have any idea how to get Linux installed on this machine, please get in touch or update that wiki page. If I can't find a way to install Linux, I will have to return the laptop to the seller and find another machine for my parents. I wonder, is this the way Linux will be forced out of the market using UEFI and "secure boot" by making it impossible to install Linux on new Laptops?

23 May 2013

Russell Coker: Noise from Shaving

About 10 years ago I started using an electric shaver. An electric shaver is more convenient to use as it doesn t require any soap, foam, or water. It is also almost impossible to cut yourself properly with an electric shaver which is a major benefit for anyone who s not particularly alert in the morning. Generally my experience of electric shavers has been good, although the noise is quite annoying. Recently a friend told me that an electric shaver is as noisy as a chain-saw. Given the inverse-square law and the fact that the shaver operates within 1cm of my ears that sounds plausible. So the risk of hearing loss is a great concern. Disposable ear plugs are very cheap and they can be used multiple times (they don t get particularly dirty while shaving or get squashed in the short time needed to shave). So for a few weeks I ve been using ear plugs while shaving which reduces the noise and presumable saves me from some hearing damage although after 10 years of using electric shavers I may have already sustained some damage. According to Cooper Safety their ear plugs reduce noise by 29dB, [1] I presume that the cheap ones I bought from Bunnings would be good for at least 15dB. According to Better Hearing Sydney the noise from an electric shaver is typically around 90dB, less than the 100dB that is typical of a chain-saw [2]. So if my ear-plugs are good for 15dB then they would reduce the noise from a typical electric shaver to 75dB which is well below the 85dB that will cause hearing damage. Given that the noise from a typical shaver is only slightly above the damage threshold it seems that I might not need particularly good ear-plugs when shaving. A quick scan of shaver reviews indicates that the amount of noise differs by brand and technology. The Hubpages review suggests that rotary shavers tend to make less noise than foil shavers [3], but I m sure that it varies enough between brands that some rotary shavers are louder than the quietest foil shavers. It seems that the best thing to do when buying a new shaver would be to go to a specialised shaver shop (which has many models on offer) and get the staff to demonstrate them to determine which is the quietest. If a typical shaver produces 90dB then it seems likely that one of the more quiet models would produce less than 85dB. Another item on my todo list is to buy a noise meter to measure the amount of noise produced in the places where I spend time. There are some Android apps to measure noise, I m currently playing with the Smart Tools Co Sound Meter [4] which gives some interesting information. The documentation notes that phone microphones are limited to the typical volume and frequencies of human voice, so my Galaxy S3 can t measure anything about 81dB. My wife s Nexus 4 doesn t seem to register anything above 74dB. Additionally there is some uncertainty about the accuracy of the microphone, there is a calibration feature but that requires another meter. Anyway the Sound Meter app suggests that my shaver (a Philips HQ7380/B) produces only 71dB at the closest possible range and drops down to 67dB at the range I would use if I grew sideburns. Conclusion Getting a proper noise meter to protect one s hearing seems like a good idea. An Android app for measuring noise is a good thing to have, even though it s not going to be accurate it s convenient and will give an indication. When buying a shaver one should listen to all the options and choose a quiet one (I might have got a quiet one by luck). Sideburns seem like a good idea if you value your hearing.

Ian Wienand: Stuck keyboard with Fedora 17 under VirtualBox

For a while now, I've been plagued with this ridiculous problem of the keyboard becoming "stuck" in my Fedora 17 VM running under VirtualBox. Keys would stop working until you held them down for several seconds, making typing close to impossible. Of course, my first thought was to blame VirtualBox, since it has a lot to do with the keyboard. I found out some interesting things, like you can send scan-codes directly to virtual-machines with something like
$ VBoxManage controlvm UUID keyboardputscancode aa
(get the UUID via VBoxManage list vms; figuring out scan-codes is left to the reader!). I noticed the problem primarily happening while emacs was in the foreground, meaning I was working on code or an email ... my theory was when I typed too fast some race got hit and put the keyboard into a weird state that a reboot fixed. Well it turns out the problem is almost the exact opposite. Luckily, today I noticed "slow keys enabled" warning that sprung-up and went away quickly just before the keyboard stopped. Once I saw that the game was up; turns out this is a well-known bug that is easily fixed with xkbset -sl. It happens because I was typing too slowly; holding down the shift-key while I thought about something probably. Hopefully this saves someone else a few hours!

21 May 2013

Erich Schubert: Google Hangouts drops XMPP support

Update: today I've been receiving XMPP messages in the Google+ variant of Hangouts. Looks as if it currently is back (at least while you are logged in via XMPP - havn't tried without pidgin at the same time yet). Let's just hope that XMPP federation will continue to be supported on the long run.
It's been all over the internet, so you probably heard it already: Google Hangouts no longer receives messages from XMPP users. Before, you could easily chat with "federated" users from other Jabber servers.
While of course the various open-source people are not amused -- for me, most of my contacts disappeared, so I then uninstalled Hangouts to get back Google Talk (apparently this works if Talk was preinstalled in your phones firmware) -- this bears some larger risks for Google:
  • Reputation: Google used to have the reputation of being open. XMPP support was open, the current "Hangups" protocol is not. This continuing trend of abandoning open standards and moving to "walled garden" solutions will likely harm the companies reputation in the open source community
  • Legal risk of an antitrust action: Before, other competitors could interface with Google using an indepentend and widely accepted standard. An example is United Internet in Germany, which operates for example the Web.de and GMX platforms, mail.com, the 1&1 internet provider. By effectively locking out its competitors - without an obvious technical reason, as XMPP was working fine just before, and apparently continues to be used at Google for example in AppEngine - bears a high risk of running into an antitrust action in Europe. If I were 1&1, I would try to get my lawyers started... or if I were Microsoft, who apparently just wanted to add XMPP messaging to Hotmail?
  • Users: Google+ is not that big yet. Especially in Germany. Since 90% of my contacts were XMPP contacts, where am I likely going to move to: Hangouts or another XMPP server? Or back to Skype? I still use Skype for more Voice calls than Google (which I used like twice), because there are some people that prefer Skype. One of these calls probably was not using the Google plugin, but an open source phone. Because with XMPP and Jingle, my regular chat client would interoperate. An in fact, the reason I started using Google Talk the first place was because it would interoperate with other networks, too, and I assumed they would be good at operating a Jabber server.
In my opinion, Google needs to quickly restore a functioning XMPP bridge. It is okay if they offer add-on functionality only for Hangout users (XMPP was always designed to allow for add-on functionality); it is also okay if they propose an entirely new open protocol to migrate to on the long run, if they can show good reasons such as scalability issues. But the way they approached the Hangup rollout looks like a big #fail to me.
Oh, and there are other issues, too. For example Linus Torvalds complains about the fonts being screwed up (not hinted properly) in the new Google+, others complain about broken presence indicators (but then you might as well just send an email, if you can't tell whether the recepient will be able to receive and answer right away), but using Hangouts will apparently also (for now -- rumor has it that Voice will also be replaced by Hangups entirely) lose you Google Voice support. The only thing that seems to give positive press are the easter eggs...
All in all, I'm not surprised to see over 20% of users giving the lowest rating in the Google Play Store, and less than 45% giving the highest rating - for a Google product, this must be really low.

Russell Coker: No Backups WTF

Some years ago I was working on a project that involved a database cluster of two Sun E6500 servers that were fairly well loaded. I believe that the overall price was several million pounds. It s the type of expensive system where it would make sense to spend adequately to do things properly in all ways. The first interesting thing was the data center where it was running. The front door had a uniformed security guard and a sign threatening immediate dismissal for anyone who left the security door open. The back door was wide open for the benefit of the electricians who were working there. Presumably anyone who had wanted to steal some servers could have gone to the back door and asked the electricians for assistance in removing them. The system was poorly tested. My colleagues thought that with big important servers you shouldn t risk damage by rebooting them. My opinion has always been that rebooting a cluster should be part of standard testing and that it s especially important with clusters which have more interesting boot sequences. But I lost the vote and there was no testing of rebooting. Along the way there were a number of WTFs in that project. One of which was when the web developers decided to force all users to install the latest beta release of Internet Explorer, a decision that was only revoked when the IE install process broke MS-Office on the PC of a senior manager. Another was putting systems with a default Solaris installation live on the Internet with all default services running, there s never a reason for a database server to be directly accessible over the Internet. No Backups At All But I think that the most significant failing was the decision not to make any backups. This wasn t merely forgetting to make backups, when I raised the issue I received a negative reaction from almost everyone. As an aside I find it particularly annoying when someone implies that I want backups because I am likely to stuff things up. There are many ways of proving that there s a general lack of competence in the computer industry. But I think that one of the best is the number of projects where the person who wants backups has their competence questioned instead of all the people who don t want backups. A decision to make no backups relies on one of two conditions, either the service has to be entirely unimportant or you need to have no bugs in the OS or hardware defects that can corrupt data, no application bugs, and a team of sysadmins who never make mistakes. The former condition raises the question of why the service is being run and the latter is impossible. As I m more persistent than most people I kept raising the issue via email and adding more people to the CC list until I got a positive reaction. Eventually I CC d someone who responded with What the fuck which I consider to be a reasonable response to a huge and expensive project with no backups. However the managers on the CC list regarded the use of profanity in email to be a much more serious problem. To the best of my knowledge there were never any backups of that system but the policy on email was strongly enforced. This is only a partial list of WTF incidents that assisted in my decision to leave the UK and migrate to the Netherlands. Not Doing Much About a year after leaving I returned to London for a holiday and had dinner with a former colleague. When I asked what he was working on he said Not much . It turned out that proximity to the nearest manager determined the amount of work that was assigned. As his desk was a long way from the nearest manager he had spent about 6 months getting paid to read Usenet. That wasn t really a surprise given my observations of the company in question.

Russell Coker: Advice on Buying a PC

A common topic of discussion on computer users group mailing lists is advice on buying a PC. I think that most of the offered advice isn t particularly useful with an excessive focus on building or upgrading PCs and on getting the latest and greatest. So I ll blog about it instead of getting involved in more mailing-list debates. A Historical Perspective the PC as an Investment In the late 80 s a reasonably high-end white-box PC cost a bit over $5,000 in Australia (or about $4,000 without a monitor). That was cheaper than name-brand PCs which cost upwards of $7,000 but was still a lot of money. $5,000 in 1988 would be comparable to $10,000 in today s money. That made a PC a rather expensive item which needed to be preserved. There weren t a lot of people who could just discard such an investment so a lot of thought was given to upgrading a PC. Now a quite powerful desktop PC can be purchased for a bit under $400 (maybe $550 if you include a good monitor) and a nice laptop is about the same price as a desktop PC and monitor. Laptops are almost impossible to upgrade apart from adding more RAM or storage but hardly anyone cares because they are so cheap. Desktop PCs can be upgraded in some ways but most people don t bother apart from RAM, storage, and sometimes a new video card. If you have the skill required to successfully replace a CPU or motherboard then your time is probably worth enough that getting more value out of a PC that was worth $400 when new and is worth maybe $100 when it s a couple of years old probably isn t a good investment. Times have changed and PCs just aren t worth enough to be bothered upgrading. A PC is a disposable item not an investment. Buying Something Expensive? There are a range of things that you can buy. You can spend $200 on a second-hand PC that s a couple of years old, $400 on a new PC that s OK but not really fast, or you can spend $1000 or more on a very high end PC. The $1000 PC will probably perform poorly when compared to a PC that sells for $400 next year. The $400 PC will probably perform poorly when compared to the second-hand systems that are available next year. If you spend more money to get a faster PC then you are only getting a faster PC for a year until newer cheaper systems enter the market. As newer and better hardware is continually being released at low enough prices that make upgrades a bad deal I recommend just not buying expensive systems. For my own use I find that e-waste is a good source of hardware. If I couldn t do that then I d buy from an auction site that specialises in corporate sales, they have some nice name-brand systems in good condition at low prices. One thing to note is that this is more difficult for Windows users due to anti-piracy features. With recent versions of Windows you can t just put an old hard drive in a new PC and have it work. So the case for buying faster hardware is stronger for Windows than for Linux. That said, $1,000 isn t a lot of money. So spending more money for a high-end system isn t necessarily a big deal. But we should keep in mind that it s just a matter of getting a certain level of performance a year before it is available in cheaper systems. Getting a $1,000 high-end system instead of a $400 cheap system means getting that level of performance maybe a year earlier and therefore at a price premium of maybe $2 per day. I m sure that most people spend more than $2 per day on more frivolous things than a faster PC. Understanding How a Computer Works As so many things are run by computers I believe that everyone should have some basic knowledge about how computers work. But a basic knowledge of computer architecture isn t required when selecting parts to assemble to make a system, one can know all about selecting a CPU and motherboard to match without understanding what a CPU does (apart from a vague idea that it s something to do with calculations). Also one can have a good knowledge of how computers work without knowing anything about the part numbers that could be assembled to make a working system. If someone wants to learn about the various parts on sale then sites such as Tom s Hardware [1] provide a lot of good information that allows people to learn without the risk of damaging expensive parts. In fact the people who work for Tom s Hardware frequently test parts to destruction for the education and entertainment of readers. But anyone who wants to understand computers would be better off spending their time using any old PC to read Wikipedia pages on the topic instead of spending their time and money assembling one PC. To learn about the basics of computer operation the Wikipedia page for CPU is a good place to start. Then the Wikipedia page for hard drive is a good start for learning about storage and the Wikipedia page for Graphics Processing Unit to learn about graphics processing. Anyone who reads those three pages as well as a selection of pages that they link to will learn a lot more than they could ever learn by assembling a PC. Of course there s lots of other things to learn about computers but Wikipedia has pages for every topic you can imagine. I think that the argument that people should assemble PCs to understand how they work was not well supported in 1990 and ceased to be accurate once Wikipedia became popular and well populated. Getting a Quality System There are a lot of arguments about quality and reliability, most without any supporting data. I believe that a system designed and manufactured by a company such as HP, Lenovo, NEC, Dell, etc is likely to be more reliable than a collection of parts uniquely assembled by a home user but I admit to a lack of data to support this belief. One thing that is clear however is the fact that ECC RAM can make a significant difference to system reliability as many types of error (including power problems) show up as corrupted memory. The cheapest Dell PowerEdge server (which has ECC RAM) is advertised at $699 so it s not a feature that s out of reach of regular users. I think that anyone who makes claims about PC reliability and fails to mention the benefits of ECC RAM (as used in Dell PowerEdge tower systems, Dell Precision workstations, and HP XW workstations among others) hasn t properly considered their advice. Also when discussing overall reliability the use of RAID storage and a good backup scheme should be considered. Good backups can do more to save your data than anything else. Conclusion I think it s best to use a system with ECC RAM as a file server. Make good backups. Use ZFS (in future BTRFS) for file storage so that data doesn t get corrupted on disk. Use reasonably cheap systems as workstations and replace them when they become too old. Update: I find it rather ironic when a discussion about advice on buying a PC gets significant input from people who are well paid for computer work. It doesn t take long for such a discussion to take enough time that the people involved could spent their time working instead, put enough money in a hat to buy a new PC for the user in question, and still had money left over.

20 May 2013

Michael Stapelberg: Debian systemd survey

In the past, we have had multiple heated discussions involving systemd. We (the pkg-systemd-maintainers team) would like to better understand why some people dislike systemd. Therefore, we have created a survey, which you can find at http://survey.zekjur.net/index.php/391182 Please only submit your feedback to the survey and not this thread, we are not particularly interested in yet another systemd discussion at this point. The deadline for participating in that survey is 7 days from now, that is 2013-05-26 23:59:00 UTC. Please participate only if you consider yourself an active member of the Debian community (for example participating in the debian-devel mailing list, maintaining packages, etc.). Of course, we will publish the results after the survey ends. Thanks! Best regards,
the Debian systemd maintainers

Next.

Previous.