Search Results: "nate"

31 March 2025

Dirk Eddelbuettel: Rblpapi 0.3.15 on CRAN: Several Refinements

bloomberg terminal Version 0.3.16 of the Rblpapi package arrived on CRAN today. Rblpapi provides a direct interface between R and the Bloomberg Terminal via the C++ API provided by Bloomberg (but note that a valid Bloomberg license and installation is required). This is the sixteenth release since the package first appeared on CRAN in 2016. It contains several enhancements. Two contributed PRs improve an error message, and extended connection options. We cleaned up a bit of internal code. And this release also makes the build conditional on having a valid build environment. This has been driven by the fact CRAN continues to builder under macOS 13 for x86_64, but Bloomberg no longer supplies a library and headers. And our repeated requests to be able to opt out of the build were, well, roundly ignored. So now the builds will succeed, but on unviable platforms such as that one we will only offer empty functions. But no more build ERRORS yelling at us for three configurations. The detailed list of changes follow below.

Changes in Rblpapi version 0.3.16 (2025-03-31)
  • A quota error message is now improved (Rodolphe Duge in #400)
  • Convert remaining throw into Rcpp::stop (Dirk in #402 fixing #401)
  • Add optional appIdentityKey argument to blpConnect (Kai Lin in #404)
  • Rework build as function of Blp library availability (Dirk and John in #406, #409, #410 fixing #407, #408)

Courtesy of my CRANberries, there is also a diffstat report for the this release. As always, more detailed information is at the Rblpapi repo or the Rblpapi page. Questions, comments etc should go to the issue tickets system at the GitHub repo.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. If you like this or other open-source work I do, you can sponsor me at GitHub.

Dirk Eddelbuettel: RProtoBuf 0.4.24 on CRAN: Minor Polish

A new maintenance release 0.4.24 of RProtoBuf arrived on CRAN today. RProtoBuf provides R with bindings for the Google Protocol Buffers ( ProtoBuf ) data encoding and serialization library used and released by Google, and deployed very widely in numerous projects as a language and operating-system agnostic protocol. This release brings an both an upstream API update affecting one function, and an update to our use of the C API of R, also in one function. Nothing user-facing, and no surprises expected. The following section from the NEWS.Rd file has full details.

Changes in RProtoBuf version 0.4.24 (2025-03-31)
  • Add bindings to EnumValueDescriptor::name (Mike Kruskal in #108)
  • Replace EXTPTR_PTR with R_ExternalPtrAddr (Dirk)

Thanks to my CRANberries, there is a diff to the previous release. The RProtoBuf page has copies of the (older) package vignette, the quick overview vignette, and the pre-print of our JSS paper. Questions, comments etc should go to the GitHub issue tracker off the GitHub repo.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. If you like this or other open-source work I do, you can sponsor me at GitHub.

Simon Josefsson: On Binary Distribution Rebuilds

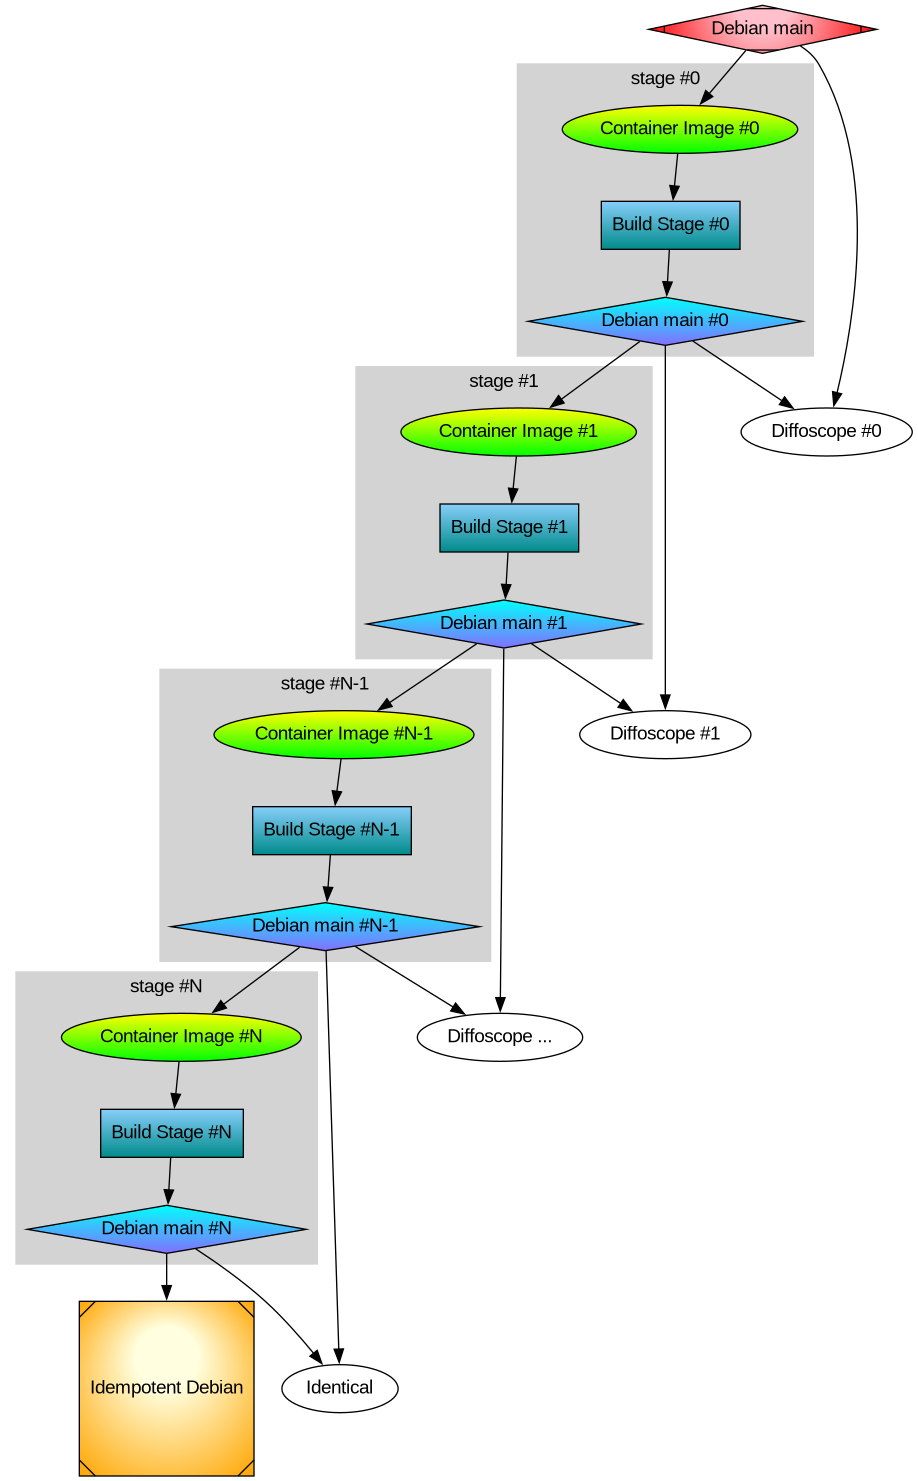
I rebuilt (the top-50 popcon) Debian and Ubuntu packages, on amd64 and arm64, and compared the results a couple of months ago. Since then the Reproduce.Debian.net effort has been launched. Unlike my small experiment, that effort is a full-scale rebuild with more architectures. Their goal is to reproduce what is published in the Debian archive. One differences between these two approaches are the build inputs: The Reproduce Debian effort use the same build inputs which were used to build the published packages. I m using the latest version of published packages for the rebuild. What does that difference imply? I believe reproduce.debian.net will be able to reproduce more of the packages in the archive. If you build a C program using one version of GCC you will get some binary output; and if you use a later GCC version you are likely to end up with a different binary output. This is a good thing: we want GCC to evolve and produce better output over time. However it means in order to reproduce the binaries we publish and use, we need to rebuild them using whatever build dependencies were used to prepare those binaries. The conclusion is that we need to use the old GCC to rebuild the program, and this appears to be the Reproduce.Debian.Net approach. It would be a huge success if the Reproduce.Debian.net effort were to reach 100% reproducibility, and this seems to be within reach. However I argue that we need go further than that. Being able to rebuild the packages reproducible using older binary packages only begs the question: can we rebuild those older packages? I fear attempting to do so ultimately leads to a need to rebuild 20+ year old packages, with a non-negligible amount of them being illegal to distribute or are unable to build anymore due to bit-rot. We won t solve the Trusting Trust concern if our rebuild effort assumes some initial binary blob that we can no longer build from source code. I ve made an illustration of the effort I m thinking of, to reach something that is stronger than reproducible rebuilds. I am calling this concept a Idempotent Rebuild, which is an old concept that I believe is the same as John Gilmore has described many years ago.
The illustration shows how the Debian main archive is used as input to rebuild another stage #0 archive. This stage #0 archive can be compared with diffoscope to the main archive, and all differences are things that would be nice to resolve. The packages in the stage #0 archive is used to prepare a new container image with build tools, and the stage #0 archive is used as input to rebuild another version of itself, called the stage #1 archive. The differences between stage #0 and stage #1 are also useful to analyse and resolve. This process can be repeated many times. I believe it would be a useful property if this process terminated at some point, where the stage #N archive was identical to the stage #N-1 archive. If this would happen, I label the output archive as an Idempotent Rebuild of the distribution. How big is N today? The simplest assumption is that it is infinity. Any build timestamp embedded into binary packages will change on every iteration. This will cause the process to never terminate. Fixing embedded timestamps is something that the Reproduce.Debian.Net effort will also run into, and will have to resolve. What other causes for differences could there be? It is easy to see that generally if some output is not deterministic, such as the sort order of assembler object code in binaries, then the output will be different. Trivial instances of this problem will be caught by the reproduce.debian.net effort as well. Could there be higher order chains that lead to infinite N? It is easy to imagine the existence of these, but I don t know how they would look like in practice. An ideal would be if we could get down to N=1. Is that technically possible? Compare building GCC, it performs an initial stage 0 build using the system compiler to produce a stage 1 intermediate, which is used to build itself again to stage 2. Stage 1 and 2 is compared, and on success (identical binaries), the compilation succeeds. Here N=2. But this is performed using some unknown system compiler that is normally different from the GCC version being built. When rebuilding a binary distribution, you start with the same source versions. So it seems N=1 could be possible. I m unhappy to not be able to report any further technical progress now. The next step in this effort is to publish the stage #0 build artifacts in a repository, so they can be used to build stage #1. I already showed that stage #0 was around ~30% reproducible compared to the official binaries, but I didn t save the artifacts in a reusable repository. Since the official binaries were not built using the latest versions, it is to be expected that the reproducibility number is low. But what happens at stage #1? The percentage should go up: we are now compare the rebuilds with an earlier rebuild, using the same build inputs. I m eager to see this materialize, and hope to eventually make progress on this. However to build stage #1 I believe I need to rebuild a much larger number packages in stage #0, it could be roughly similar to the build-essentials-depends package set. I believe the ultimate end goal of Idempotent Rebuilds is to be able to re-bootstrap a binary distribution like Debian from some other bootstrappable environment like Guix. In parallel to working on a achieving the 100% Idempotent Rebuild of Debian, we can setup a Guix environment that build Debian packages using Guix binaries. These builds ought to eventually converge to the same Debian binary packages, or there is something deeply problematic happening. This approach to re-bootstrap a binary distribution like Debian seems simpler than rebuilding all binaries going back to the beginning of time for that distribution. What do you think? PS. I fear that Debian main may have already went into a state where it is not able to rebuild itself at all anymore: the presence and assumption of non-free firmware and non-Debian signed binaries may have already corrupted the ability for Debian main to rebuild itself. To be able to complete the idempotent and bootstrapped rebuild of Debian, this needs to be worked out.

30 March 2025

Dirk Eddelbuettel: RcppSpdlog 0.0.21 on CRAN: New Upstream

Version 0.0.21 of RcppSpdlog arrived on CRAN today and has been uploaded to Debian. RcppSpdlog bundles spdlog, a wonderful header-only C++ logging library with all the bells and whistles you would want that was written by Gabi Melman, and also includes fmt by Victor Zverovich. You can learn more at the nice package documention site. This release updates the code to the version 1.15.2 of spdlog which was released this weekend as well. The NEWS entry for this release follows.

Changes in RcppSpdlog version 0.0.21 (2025-03-30)
  • Upgraded to upstream release spdlog 1.15.2 (including fmt 11.1.4)

Courtesy of my CRANberries, there is also a diffstat report. More detailed information is on the RcppSpdlog page, or the package documention site.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. If you like this or other open-source work I do, you can sponsor me at GitHub.

Dirk Eddelbuettel: RcppZiggurat 0.1.8 on CRAN: Build Refinements

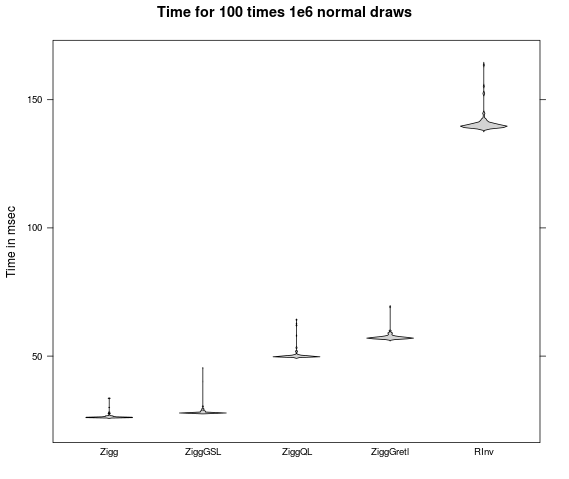
ziggurats A new release 0.1.8 of RcppZiggurat is now on the CRAN network for R, following up on the 0.1.7 release last week which was the first release in four and a half years. The RcppZiggurat package updates the code for the Ziggurat generator by Marsaglia and others which provides very fast draws from a Normal (or Exponential) distribution. The package provides a simple C++ wrapper class for the generator improving on the very basic macros, and permits comparison among several existing Ziggurat implementations. This can be seen in the figure where Ziggurat from this package dominates accessing the implementations from the GSL, QuantLib and Gretl all of which are still way faster than the default Normal generator in R (which is of course of higher code complexity). This release switches the vignette to the standard trick of premaking it as a pdf and including it in a short Sweave document that imports it via pdfpages; this minimizes build-time dependencies on other TeXLive components. It also incorporates a change contributed by Tomas to rely on the system build of the GSL on Windows as well if Rtools 42 or later is found. No other changes. The NEWS file entry below lists all changes.

Changes in version 0.1.8 (2025-03-30)
  • The vignette is now premade and rendered as Rnw via pdfpage to minimize the need for TeXLive package at build / install time (Dirk)
  • Windows builds now use the GNU GSL when Rtools is 42 or later (Tomas Kalibera in #25)

Courtesy of my CRANberries, there is a diffstat report relative to previous release. More detailed information is on the Rcppziggurat page or the GitHub repository.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. If you like this or other open-source work I do, you can sponsor me at GitHub.

Utkarsh Gupta: FOSS Activites in March 2025

Here s my 66th monthly but brief update about the activities I ve done in the F/L/OSS world.

Debian
This was my 75th month of actively contributing to Debian. I became a DM in late March 2019 and a DD on Christmas 19! \o/ There s a bunch of things I do, both, technical and non-technical. Here s what I did:
  • Updating Rails to v7.2.2.1 for Trixie.
  • Updating Redmine to v6.0.4 for Trixie.
  • Kickstarting the bursary team for DC25.
  • Mentoring for newcomers.
  • Moderation of -project mailing list.

Ubuntu
This was my 50th month of actively contributing to Ubuntu. Now that I joined Canonical to work on Ubuntu full-time, there s a bunch of things I do! \o/ I mostly worked on different things, I guess. I was too lazy to maintain a list of things I worked on so there s no concrete list atm. Maybe I ll get back to this section later or will start to list stuff from the fall, as I was doing before. :D

Debian (E)LTS
Debian Long Term Support (LTS) is a project to extend the lifetime of all Debian stable releases to (at least) 5 years. Debian LTS is not handled by the Debian security team, but by a separate group of volunteers and companies interested in making it a success. And Debian Extended LTS (ELTS) is its sister project, extending support to the stretch and jessie release (+2 years after LTS support). This was my 66th month as a Debian LTS and 53rd month as a Debian ELTS paid contributor.
I worked for 15.00 hours for LTS and 7.50 hours for ELTS. I did the following things:
  • [ELTS] Worked on backporting patches for adminer.
  • [E/LTS] Working on the musl fixes for bullseye. Taking it forward from where it was left off by Chris.
    • Co-ordiating with Santiago to see how to best get the reproducer to test the update.
    • Plan is to reproduce it myself but then reach out to Adrian if that doesn t work out.
    • Also makes sense to upload to LTS first, let it settle there, and then look at ELTS.
  • [LTS] Attended the LTS meeting on IRC. Summary here.
  • [stable] Co-ordinated with the Security team to fix rails in bookworm via 2:6.1.7.10+dfsg-1~deb12u1.
    • Fixes: CVE-2023-28362, CVE-2023-38037, CVE-2024-26144, CVE-2024-28103, CVE-2024-41128, CVE-2024-47887, CVE-2024-47888, CVE-2024-47889, and CVE-2024-54133.
    • Released as DSA 5881-1.
  • [stable] Co-ordinated with the Security team to fix ruby-rack in bookworm via 2.2.13-1~deb12u1.
    • Fixes: CVE-2025-27610, CVE-2025-27111, and CVE-2025-25184.
    • Released as DSA 5886-1.
  • [stable] Partly co-ordinated with the Security team to fix ruby-saml in bookworm.

Until next time.
:wq for today.

Russ Allbery: Review: Cascade Failure

Review: Cascade Failure, by L.M. Sagas
Series: Ambit's Run #1
Publisher: Tor
Copyright: 2024
ISBN: 1-250-87126-3
Format: Kindle
Pages: 407
Cascade Failure is a far-future science fiction adventure with a small helping of cyberpunk vibes. It is the first of a (so far) two-book series, and was the author's first novel. The Ambit is an old and small Guild ship, not much to look at, but it holds a couple of surprises. One is its captain, Eoan, who is an AI with a deep and insatiable curiosity that has driven them and their ship farther and farther out into the Spiral. The other is its surprisingly competent crew: a battle-scarred veteran named Saint who handles the fighting, and a talented engineer named Nash who does literally everything else. The novel opens with them taking on supplies at Aron Outpost. A supposed Guild deserter named Jalsen wanders into the ship looking for work. An AI ship with a found-family crew is normally my catnip, so I wanted to love this book. Alas, I did not. There were parts I liked. Nash is great: snarky, competent, and direct. Eoan is a bit distant and slightly more simplistic of a character than I was expecting, but I appreciated the way Sagas put them firmly in charge of the ship and departed from the conventional AI character presentation. Once the plot starts in earnest (more on that in a moment), we meet Anke, the computer hacker, whose charming anxiety reaction is a complete inability to stop talking and who adds some needed depth to the character interactions. There's plenty of action, a plot that makes at least some sense, and a few moments that almost achieved the emotional payoff the author was attempting. Unfortunately, most of the story focuses on Saint and Jal, and both of them are irritatingly dense cliches. The moment Jal wanders onto the Ambit in the first chapter, the reader is informed that Jal, Saint, and Eoan have a history. The crew of the Ambit spent a year looking for Jal and aren't letting go of him now that they've found him. Jal, on the other hand, clearly blames Saint for something and is not inclined to trust him. Okay, fine, a bit generic of a setup but the writing moved right along and I was curious enough. It then takes a full 180 pages before the reader finds out what the hell is going on with Saint and Jal. Predictably, it's a stupid misunderstanding that could have been cleared up with one conversation in the second chapter. Cascade Failure does not contain a romance (and to the extent that it hints at one, it's a sapphic romance), but I swear Saint and Jal are both the male protagonist from a certain type of stereotypical heterosexual romance novel. They're both the brooding man with the past, who is too hurt to trust anyone and assumes the worst because he's unable to use his words or ask an open question and then listen to the answer. The first half of this book is them being sullen at each other at great length while both of them feel miserable. Jal keeps doing weird and suspicious things to resolve a problem that would have been far more easily resolved by the rest of the crew if he would offer any explanation at all. It's not even suspenseful; we've read about this character enough times to know that he'll turn out to have a heart of gold and everything will be a misunderstanding. I found it tedious. Maybe people who like slow burn romances with this character type will have a less negative reaction. The real plot starts at about the time Saint and Jal finally get their shit sorted out. It turns out to have almost nothing to do with either of them. The environmental control systems of worlds are suddenly failing (hence the book title), and Anke, the late-arriving computer programmer and terraforming specialist, has a rather wild theory about what's happening. This leads to a lot of action, some decent twists, and a plot that felt very cyberpunk to me, although unfortunately it culminates in an absurdly-cliched action climax. This book is an action movie that desperately wants to make you feel all the feels, and it worked about as well as that typically works in action movies for me. Jaded cynicism and an inability to communicate are not the ways to get me to have an emotional reaction to a book, and Jal (once he finally starts talking) is so ridiculously earnest that it's like reading the adventures of a Labrador puppy. There was enough going on that it kept me reading, but not enough for the story to feel satisfying. I needed a twist, some depth, way more Nash and Anke and way less of the men, something. Everyone is going to compare this book to Firefly, but Firefly had better banter, created more complex character interactions due to the larger and more varied crew, and played the cynical mercenary for laughs instead of straight, all of which suited me better. This is not a bad book, particularly once it gets past the halfway point, but it's not that memorable either, at least for me. If you're looking for a space adventure with heavy action hero and military SF vibes that wants to be about Big Feelings but gets there in mostly obvious ways, you could do worse. If you're looking for a found-family starship crew story more like Becky Chambers, I think you'll find this one a bit too shallow and obvious. Not really recommended, although there's nothing that wrong with it and I'm sure other people's experience will differ. Followed by Gravity Lost, which I'm unlikely to read. Rating: 6 out of 10

29 March 2025

Dirk Eddelbuettel: tinythemes 0.0.3 at CRAN: Nags

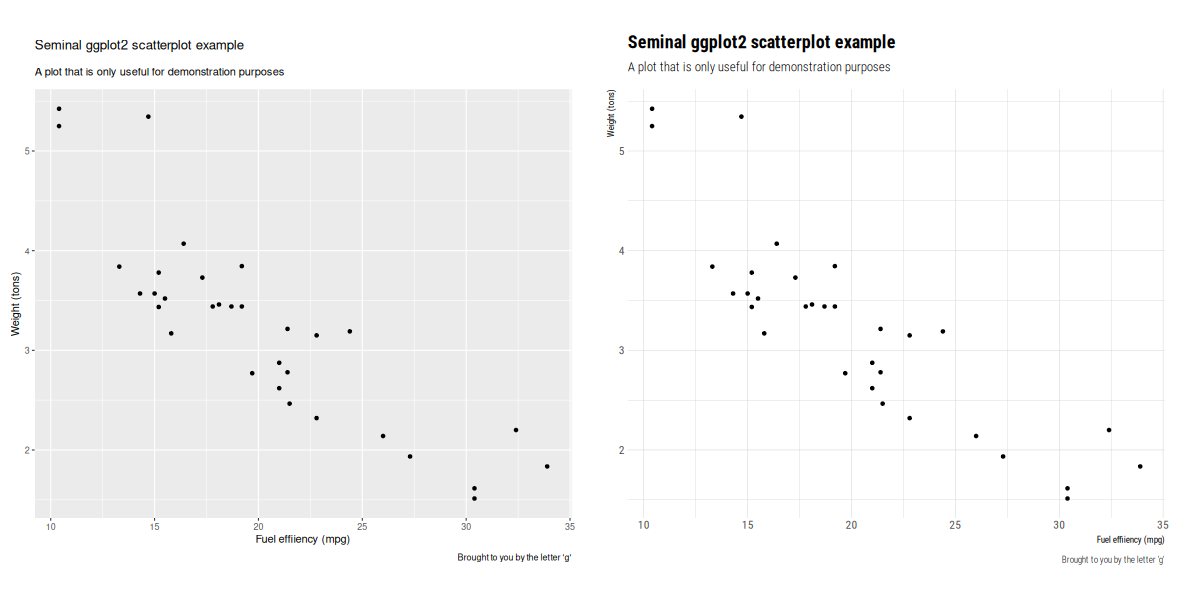
tinythemes demo A second maintenance release of our still young-ish package tinythemes arrived on CRAN today. tinythemes provides the theme_ipsum_rc() function from hrbrthemes by Bob Rudis in a zero (added) dependency way. A simple example is (also available as a demo inside the package) contrasts the default style (on the left) with the one added by this package (on the right): This version responds solely to things CRAN now nags about. As these are all package quality improvement we generally oblige happily (and generally fix in the respective package repo when we notice). I am currently on a quest to get most/all of my nags down so new releases are sometimes the way to go even when not under a deadline gun (as with other releases this week). The full set of changes since the last release (a little over a year ago) follows.

Changes in tinythemes version 0.0.3 (2025-03-29)
  • Updated a badge URL in README.md
  • Updated manual pages with proper anchor links
  • Rewrote one example without pipe to not require minimum R version

Courtesy of my CRANberries, there is a diffstat report relative to previous release. More detailed information is on the repo where comments and suggestions are welcome.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. If you like this or other open-source work I do, you can sponsor me at GitHub.

28 March 2025

Dirk Eddelbuettel: RcppArmadillo 14.4.1-1 on CRAN: Small Upstream Fix

armadillo image Armadillo is a powerful and expressive C++ template library for linear algebra and scientific computing. It aims towards a good balance between speed and ease of use, has a syntax deliberately close to Matlab, and is useful for algorithm development directly in C++, or quick conversion of research code into production environments. RcppArmadillo integrates this library with the R environment and language and is widely used by (currently) 1236 other packages on CRAN, downloaded 39 million times (per the partial logs from the cloud mirrors of CRAN), and the CSDA paper (preprint / vignette) by Conrad and myself has been cited 620 times according to Google Scholar. This release brings a small upstream bug fix to the two FFTW3-interfacing functions, something not likely to hit many CRAN packages. The changes since the last and fairly recent CRAN release are summarised below.

Changes in RcppArmadillo version 14.4.1-1 (2025-03-27)
  • Upgraded to Armadillo release 14.4.1 (Filtered Espresso)
    • Fix for fft() and ifft() when using FFTW3 in multi-threaded contexts (such as OpenMP)

Courtesy of my CRANberries, there is a diffstat report relative to previous release. More detailed information is on the RcppArmadillo page. Questions, comments etc should go to the rcpp-devel mailing list off the Rcpp R-Forge page.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. If you like this or other open-source work I do, you can sponsor me at GitHub.

Dirk Eddelbuettel: tint 0.1.5 on CRAN: Maintenance

A new version 0.1.5 of the tint package arrived at CRAN today. tint provides a style not unlike Tufte for use in html and pdf documents created from markdown. The github repo shows several examples in its README, more as usual in the package documentation. This is the first release in one and a half years and contains only routine maintenance. As CRAN now bags about missing anchors in the common \code \link use, I added these today. Otherwise the usual mix of updates to continuous integration, to badges and URLs and other small packaging details but nothing user-facing.

Changes in tint version 0.1.5 (2025-03-27)
  • Standard package maintenance for continuous integration, URL updates, and packaging conventions
  • Correct two minor nags in the Rd file

Courtesy of my CRANberries, there is a diffstat report relative to previous release. More information is on the tint page. For questions or comments use the issue tracker off the GitHub repo.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. If you like this or other open-source work I do, you can sponsor me at GitHub.

Freexian Collaborators: Monthly report about Debian Long Term Support, February 2025 (by Roberto C. S nchez)

Like each month, have a look at the work funded by Freexian s Debian LTS offering.

Debian LTS contributors In February, 18 contributors have been paid to work on Debian LTS, their reports are available:
  • Abhijith PA did 10.0h (out of 8.0h assigned and 6.0h from previous period), thus carrying over 4.0h to the next month.
  • Adrian Bunk did 12.0h (out of 0.0h assigned and 63.5h from previous period), thus carrying over 51.5h to the next month.
  • Andrej Shadura did 10.0h (out of 6.0h assigned and 4.0h from previous period).
  • Bastien Roucari s did 20.0h (out of 20.0h assigned).
  • Ben Hutchings did 12.0h (out of 8.0h assigned and 16.0h from previous period), thus carrying over 12.0h to the next month.
  • Chris Lamb did 18.0h (out of 18.0h assigned).
  • Daniel Leidert did 23.0h (out of 20.0h assigned and 6.0h from previous period), thus carrying over 3.0h to the next month.
  • Emilio Pozuelo Monfort did 53.0h (out of 53.0h assigned and 0.75h from previous period), thus carrying over 0.75h to the next month.
  • Guilhem Moulin did 11.0h (out of 3.25h assigned and 16.75h from previous period), thus carrying over 9.0h to the next month.
  • Jochen Sprickerhof did 27.0h (out of 30.0h assigned), thus carrying over 3.0h to the next month.
  • Lee Garrett did 11.75h (out of 9.5h assigned and 44.25h from previous period), thus carrying over 42.0h to the next month.
  • Markus Koschany did 40.0h (out of 40.0h assigned).
  • Roberto C. S nchez did 7.0h (out of 14.75h assigned and 9.25h from previous period), thus carrying over 17.0h to the next month.
  • Santiago Ruano Rinc n did 19.75h (out of 21.75h assigned and 3.25h from previous period), thus carrying over 5.25h to the next month.
  • Sean Whitton did 6.0h (out of 6.0h assigned).
  • Sylvain Beucler did 52.5h (out of 14.75h assigned and 39.0h from previous period), thus carrying over 1.25h to the next month.
  • Thorsten Alteholz did 11.0h (out of 11.0h assigned).
  • Tobias Frost did 17.0h (out of 17.0h assigned).

Evolution of the situation In February, we have released 38 DLAs.
  • Notable security updates:
    • pam-u2f, prepared by Patrick Winnertz, fixed an authentication bypass vulnerability
    • openjdk-17, prepared by Emilio Pozuelo Monfort, fixed an authorization bypass/information disclosure vulnerability
    • firefox-esr, prepared by Emilio Pozuelo Monfort, fixed several vulnerabilities
    • thunderbird, prepared by Emilio Pozuelo Monfort, fixed several vulnerabilities
    • postgresql-13, prepared by Christoph Berg, fixed an SQL injection vulnerability
    • freerdp2, prepared by Tobias Frost, fixed several vulnerabilities
    • openssh, prepared by Colin Watson, fixed a machine-in-the-middle vulnerability
LTS contributors Emilio Pozuelo Monfort and Santiago Ruano Rinc n coordinated the administrative aspects of LTS updates of postgresql-13 and pam-u2f, which were prepared by the respective maintainers, to whom we are most grateful. As has become the custom of the LTS team, work is under way on a number of package updates targeting Debian 12 (codename bookworm ) with fixes for a variety of vulnerabilities. In February, Guilhem Moulin prepared an upload of sssd, while several other updates are still in progress. Bastien Roucari s prepared an upload of krb5 for unstable as well. Given the importance of the Debian Security Tracker to the work of the LTS Team, we regularly contribute improvements to it. LTS contributor Emilio Pozuelo Monfort reviewed and merged a change to improve performance, and then dealt with unexpected issues that arose as a result. He also made improvements in the processing of CVEs which are not applicable to Debian. Looking to the future (the release of Debian 13, codename trixie , and beyond), LTS contributor Santiago Ruano Rinc n has initiated a conversation among the broader community involved in the development of Debian. The purpose of the discussion is to explore ways to improve the long term supportability of packages in Debian, specifically by focusing effort on ensuring that each Debian release contains the best supported upstream version of packages with a history of security issues.

Thanks to our sponsors Sponsors that joined recently are in bold.

26 March 2025

Dirk Eddelbuettel: RcppRedis 0.2.5 on CRAN: Fix Bashism in Configure, Maintenance

A new minor release 0.2.5 of our RcppRedis package arrived on CRAN today. RcppRedis is one of several packages connecting R to the fabulous Redis in-memory datastructure store (and much more). RcppRedis does not pretend to be feature complete, but it may do some things faster than the other interfaces, and also offers an optional coupling with MessagePack binary (de)serialization via RcppMsgPack. The package has been deployed in production as a risk / monitoring tool on a trading floor for several years. It also supports pub/sub dissemination of streaming market data as per this earlier example. Given the changes around Redis, it is worth stressing that the package works just as well with valkey and uses only hiredis which remains proper open source. This update is again somewhat mechanical as a few maintenance things bubbled up in since the last release in the summer of 2023. As with other packages, continuous integration was updated a few times as were URLs and badges, and we update the use of our RApiSerialize. And, just as we did today and yesterday with littler, RQuantLib and RDieHarder, this addresses a nag from CRAN about implicit bash dependency in configure.ac (which we fixed in January as for the other packages but are under deadline now). Last but not least the newly-added extension of forbidden symbols in static libraries revealed that yes indeed I had forgotten to set -DNDEBUG when building the embedded hiredis in fallback mode and I now also converted its four uses of sprintf to snprintf so we are clean there too. The detailed changes list follows.

Changes in version 0.2.5 (2025-03-26)
  • The continuous integration setup was updated several times
  • Badges and URLs in README.md have been updated
  • An updated interface from RApiSerialize is now used, and a versioned dependency on version 0.1.4 or later has been added
  • The DESCRIPTION file now uses Authors@R
  • Two possible bashisms have been converted in configure.ac
  • The (fallback if needed) build of libhiredis.a now sets -DNDEBUG, four uses of sprintf converted to snprintf

Courtesy of my CRANberries, there is also a diffstat report for this this release. More information is on the RcppRedis page and at the repository and its issue tracker.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. If you like this or other open-source work I do, you can sponsor me at GitHub.

Dirk Eddelbuettel: RDieHarder 0.2.7 on CRAN: Fix Bashism in Configure, Maintenance

An new version 0.2.7 of the random-number generator tester RDieHarder (based on the DieHarder suite developed / maintained by Robert Brown with contributions by David Bauer and myself along with other contributors) is now on CRAN. This release contains only internal maintenance changes: continuous integration was updated as was a badge URL, and a bashism issue in configure.ac was addressed (months ago) but as CRAN now sends NOTEs it triggered this update (just like littler and RQuantLib yesterday). Thanks to CRANberries, you can also look at the most recent diff to the previous release. If you like this or other open-source work I do, you can now sponsor me at GitHub.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

Dirk Eddelbuettel: crc32c 0.0.3 on CRAN: Accommodate Unreleased (!!) cmake Version

A third release of the crc32c package is now on CRAN. The package bring the Google library crc32c to R and offers cyclical checksums with parity in hardware-accelerated form on (recent enough) intel cpus as well as on arm64. This release is one hundred percent maintenance. Brian Ripley reached out as he already tests the (still very much unreleased) cmake 4.0.0 release, currently at rc5. And that version is now picky about minimum cmake version statements in CMakeLists.txt. As we copied the upstream one here, with its setting of the jurassic 3.1 version, our build conked out. A simple switch to 3.5..4.0, declaring a from .. to scheme with a minimally supported version (here 3.5, released in 2016) up to a tested version works. No other changes, really, besides an earlier helping hand from Jeroen concerning cross-compilation support he needed or encountered (and that happened right after the 0.0.2 release). The NEWS entry for this (as well the initial release) follows.

Changes in version 0.0.3 (2025-03-25)
  • Support cross-compilation by setting CC and CXX in Makevars.in (Jeroen Ooms in #1)
  • Support pre-release 4.0.0 of cmake by moving the minimum stated version from 3.1 to 3.5 per CRAN request, also sent PR upstream

My CRANberries service provides a comparison to the previous release. The code is available via the GitHub repo, and of course also from its CRAN page and via install.packages("crc32c"). Comments and suggestions are welcome at the GitHub repo.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. If you like this or other open-source work I do, you can sponsor me at GitHub.

25 March 2025

Dirk Eddelbuettel: littler 0.3.21 on CRAN: Lots Moar Features!

max-heap image The twentysecond release of littler as a CRAN package landed on CRAN just now, following in the now nineteen year history (!!) as a (initially non-CRAN) package started by Jeff in 2006, and joined by me a few weeks later. littler is the first command-line interface for R as it predates Rscript. It allows for piping as well for shebang scripting via #!, uses command-line arguments more consistently and still starts faster. It also always loaded the methods package which Rscript only began to do in recent years. littler lives on Linux and Unix, has its difficulties on macOS due to some-braindeadedness there (who ever thought case-insensitive filesystems as a default were a good idea?) and simply does not exist on Windows (yet the build system could be extended see RInside for an existence proof, and volunteers are welcome!). See the FAQ vignette on how to add it to your PATH. A few examples are highlighted at the Github repo:, as well as in the examples vignette. This release, the first is almost exactly one year, brings enhancements to six scripts as well as three new ones. The new ones crup.r offers CRan UPloads from the command-line, deadliners.r lists CRAN package by CRAN deadline, and wb.r uploads to win-builder (replacing an older shell script of mine). Among the updated ones, kitten.r now creates more complete DESCRIPTION files in the packages it makes, and several scripts support additional options. A number of changes were made to packaging as well, some of which were contributed by Jon and Michael which is of course always greatly appreciated. The trigger for the release was, just like for RQuantLib earlier today, a CRAN nag on bashisms half of which actually false here it was in a comment only. Oh well. The full change description follows.

Changes in littler version 0.3.21 (2025-03-24)
  • Changes in examples scripts
    • Usage text for ciw.r is improved, new options were added (Dirk)
    • The noble release is supported by r2u.r (Dirk)
    • The installRub.r script has additional options (Dirk)
    • The ttlt.r script has a new load_package argument (Dirk)
    • A new script deadliners.r showing CRAN packages 'under deadline' has been added, and then refined (Dirk)
    • The kitten.r script can now use whoami and argument githubuser on the different *kitten helpers it calls (Dirk)
    • A new script wb.r can upload to win-builder (Dirk)
    • A new script crup.r can upload a CRAN submission (Dirk)
    • In rcc.r, the return from rcmdcheck is now explicitly printed (Dirk)
    • In r2u.r the dry-run option is passed to the build command (Dirk)
  • Changes in package
    • Regular updates to badges, continuous integration, DESCRIPTION and configure.ac (Dirk)
    • Errant osVersion return value are handled more robustly (Michael Chirico in #121)
    • The current run-time path is available via variable LITTLER_SCRIPT_PATH (Jon Clayden in #122)
    • The cleanup script remove macOS debug symbols (Jon Clayden in #123)

My CRANberries service provides a comparison to the previous release. Full details for the littler release are provided as usual at the ChangeLog page, and also on the package docs website. The code is available via the GitHub repo, from tarballs and now of course also from its CRAN page and via install.packages("littler"). Binary packages are available directly in Debian as well as (in a day or two) Ubuntu binaries at CRAN thanks to the tireless Michael Rutter. Comments and suggestions are welcome at the GitHub repo.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. If you like this or other open-source work I do, you can sponsor me at GitHub.

Dirk Eddelbuettel: RQuantLib 0.4.25 on CRAN: Fix Bashism in Configure

A new minor release 0.4.25 of RQuantLib arrived on CRAN this morning, and has just now been uploaded to Debian too. QuantLib is a rather comprehensice free/open-source library for quantitative finance. RQuantLib connects (some parts of) it to the R environment and language, and has been part of CRAN for nearly twenty-two years (!!) as it was one of the first packages I uploaded to CRAN. This release of RQuantLib is tickled by a request to remove bashisms in shell scripts, or, as in my case here, configure.ac where I used the non-portable form of string comparison. That has of course been there for umpteen years and not bitten anyone as the default shell for most is in fact bash but the change has the right idea. And is of course now mandatory affecting quite a few packages is I tooted yesterday. It also contains an improvement to the macOS 14 build kindly contributed by Jeroen.

Changes in RQuantLib version 0.4.25 (2025-03-24)
  • Support macOS 14 with a new compiler flag (Jeroen in #190)
  • Correct two bashisms in configure.ac

One more note, though: This may however be the last release I make with Windows support. CRAN now also checks for forbidden symbols (such as assert or (s)printf or ) in static libraries, and this release tickled one such warning from the Windows side (which only uses static libraries). I have no desire to get involved in also maintaing QuantLib (no R here) for Windows and may simply turn the package back to OS_type: unix to avoid the hassle. To avoid that, it would be fabulous if someone relying on RQuantLib on Windows could step up and lend a hand looking after that library build. Courtesy of my CRANberries, there is also a diffstat report for the this release. As always, more detailed information is on the RQuantLib page. Questions, comments etc should go to the rquantlib-devel mailing list. Issue tickets can be filed at the GitHub repo. If you like this or other open-source work I do, you can now sponsor me at GitHub.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

24 March 2025

Jonathan McDowell: Who pays the cost of progress in software?

I am told, by friends who have spent time at Google, about the reason Google Reader finally disappeared. Apparently it had become a 20% Project for those who still cared about it internally, and there was some major change happening to one of it upstream dependencies that was either going to cause a significant amount of work rearchitecting Reader to cope, or create additional ongoing maintenance burden. It was no longer viable to support it as a side project, so it had to go. This was a consequence of an internal culture at Google where service owners are able to make changes that can break downstream users, and the downstream users are the ones who have to adapt. My experience at Meta goes the other way. If you own a service or other dependency and you want to make a change that will break things for the users, it s on you to do the migration, or at the very least provide significant assistance to those who own the code. You don t just get to drop your new release and expect others to clean up; doing that tends to lead to changes being reverted. The culture flows the other way; if you break it, you fix it (nothing is someone else s problem). There are pluses and minuses to both approaches. Users having to drive the changes to things they own stops them from blocking progress. Service/code owners having to drive the changes avoids the situation where a wildly used component drops a new release that causes a lot of high priority work for folk in order to adapt. I started thinking about this in the context of Debian a while back, and a few incidents since have resulted in my feeling that we re closer to the Google model than the Meta model. Anyone can upload a new version of their package to unstable, and that might end up breaking all the users of it. It s not quite as extreme as rolling out a new service, because it s unstable that gets affected (the clue is in the name, I really wish more people would realise that), but it can still result in release critical bugs for lots other Debian contributors. A good example of this are toolchain changes. Major updates to GCC and friends regularly result in FTBFS issues in lots of packages. Now in this instance the maintainer is usually diligent about a heads up before the default changes, but it s still a whole bunch of work for other maintainers to adapt (see the list of FTBFS bugs for GCC 15 for instance - these are important, but not serious yet). Worse is when a dependency changes and hasn t managed to catch everyone who might be affected, so by the time it s discovered it s release critical, because at least one package no longer builds in unstable. Commercial organisations try to avoid this with a decent CI/CD setup that either vendors all dependencies, or tracks changes to them and tries rebuilds before allowing things to land. This is one of the instances where a monorepo can really shine; if everything you need is in there, it s easier to track the interconnections between different components. Debian doesn t have a CI/CD system that runs for every upload, allowing us to track exact causes of regressions. Instead we have Lucas, who does a tremendous job of running archive wide rebuilds to make sure we can still build everything. Unfortunately that means I am often unfairly grumpy at him; my heart sinks when I see a bug come in with his name attached, because it often means one of my packages has a new RC bug where I m going to have to figure out what changed elsewhere to cause it. However he s just (very usefully) surfacing an issue someone else created, rather than actually being the cause of the problem. I don t know if I have a point to this post. I think it s probably that I wish folk in Free Software would try and be mindful of the incompatible changes they might introducing, and the toil they create for other volunteer developers, often not directly visible to the person making the change. The approach done by the Debian toolchain maintainers strikes me as a good balance; they do a bunch of work up front to try and flag all the places that might need to make changes, far enough in advance of the breaking change actually landing. However they don t then allow a tardy developer to block progress.

Simon Josefsson: Reproducible Software Releases

Around a year ago I discussed two concerns with software release archives (tarball artifacts) that could be improved to increase confidence in the supply-chain security of software releases. Repeating the goals for simplicity: While implementing these ideas for a small project was accomplished within weeks see my announcement of Libntlm version 1.8 adressing this in complex projects uncovered concerns with tools that had to be addressed, and things stalled for many months pending that work. I had the notion that these two goals were easy and shouldn t be hard to accomplish. I still believe that, but have had to realize that improving tooling to support these goals takes time. It seems clear that these concepts are not universally agreed on and implemented generally. I m now happy to recap some of the work that led to releases of libtasn1 v4.20.0, inetutils v2.6, libidn2 v2.3.8, libidn v1.43. These releases all achieve these goals. I am working on a bunch of more projects to support these ideas too. What have the obstacles so far been to make this happen? It may help others who are in the same process of addressing these concerns to have a high-level introduction to the issues I encountered. Source code for projects above are available and anyone can look at the solutions to learn how the problems are addressed. First let s look at the problems we need to solve to make git-archive style tarballs usable:

Version Handling To build usable binaries from a minimal tarballs, it need to know which version number it is. Traditionally this information was stored inside configure.ac in git. However I use gnulib s git-version-gen to infer the version number from the git tag or git commit instead. The git tag information is not available in a git-archive tarball. My solution to this was to make use of the export-subst feature of the .gitattributes file. I store the file .tarball-version-git in git containing the magic cookie like this:
$Format:%(describe)$
With this, git-archive will replace with a useful version identifier on export, see the libtasn1 patch to achieve this. To make use of this information, the git-version-gen script was enhanced to read this information, see the gnulib patch. This is invoked by ./configure to figure out which version number the package is for.

Translations We want translations to be included in the minimal source tarball for it to be buildable. Traditionally these files are retrieved by the maintainer from the Translation project when running ./bootstrap, however there are two problems with this. The first one is that there is no strong authentication or versioning information on this data, the tools just download and place whatever wget downloaded into your source tree (printf-style injection attack anyone?). We could improve this (e.g., publish GnuPG signed translations messages with clear versioning), however I did not work on that further. The reason is that I want to support offline builds of packages. Downloading random things from the Internet during builds does not work when building a Debian package, for example. The translation project could solve this by making a monthly tarball with their translations available, for distributors to pick up and provide as a separate package that could be used as a build dependency. However that is not how these tools and projects are designed. Instead I reverted back to storing translations in git, something that I did for most projects back when I was using CVS 20 years ago. Hooking this into ./bootstrap and gettext workflow can be tricky (ideas for improvement most welcome!), but I used a simple approach to store all directly downloaded po/*.po files directly as po/*.po.in and make the ./bootstrap tool move them in place, see the libidn2 commit followed by the actual make update-po commit with all the translations where one essential step is:
# Prime po/*.po from fall-back copy stored in git.
for poin in po/*.po.in; do
    po=$(echo $poin   sed 's/.in//')
    test -f $po   cp -v $poin $po
done
ls po/*.po   sed 's .*/ ; s \.po$ ' > po/LINGUAS

Fetching vendor files like gnulib Most build dependencies are in the shape of You need a C compiler . However some come in the shape of source-code files intended to be vendored , and gnulib is a huge repository of such files. The latter is a problem when building from a minimal git archive. It is possible to consider translation files as a class of vendor files, since they need to be copied verbatim into the project build directory for things to work. The same goes for *.m4 macros from the GNU Autoconf Archive. However I m not confident that the solution for all vendor files must be the same. For translation files and for Autoconf Archive macros, I have decided to put these files into git and merge them manually occasionally. For gnulib files, in some projects like OATH Toolkit I also store all gnulib files in git which effectively resolve this concern. (Incidentally, the reason for doing so was originally that running ./bootstrap took forever since there is five gnulib instances used, which is no longer the case since gnulib-tool was rewritten in Python.) For most projects, however, I rely on ./bootstrap to fetch a gnulib git clone when building. I like this model, however it doesn t work offline. One way to resolve this is to make the gnulib git repository available for offline use, and I ve made some effort to make this happen via a Gnulib Git Bundle and have explained how to implement this approach for Debian packaging. I don t think that is sufficient as a generic solution though, it is mostly applicable to building old releases that uses old gnulib files. It won t work when building from CI/CD pipelines, for example, where I have settled to use a crude way of fetching and unpacking a particular gnulib snapshot, see this Libntlm patch. This is much faster than working with git submodules and cloning gnulib during ./bootstrap. Essentially this is doing:
GNULIB_REVISION=$(. bootstrap.conf >&2; echo $GNULIB_REVISION)
wget -nv https://gitlab.com/libidn/gnulib-mirror/-/archive/$GNULIB_REVISION/gnulib-mirror-$GNULIB_REVISION.tar.gz
gzip -cd gnulib-mirror-$GNULIB_REVISION.tar.gz   tar xf -
rm -fv gnulib-mirror-$GNULIB_REVISION.tar.gz
export GNULIB_SRCDIR=$PWD/gnulib-mirror-$GNULIB_REVISION
./bootstrap --no-git
./configure
make

Test the git-archive tarball This goes without saying, but if you don t test that building from a git-archive style tarball works, you are likely to regress at some point. Use CI/CD techniques to continuously test that a minimal git-archive tarball leads to a usable build.

Mission Accomplished So that wasn t hard, was it? You should now be able to publish a minimal git-archive tarball and users should be able to build your project from it. I recommend naming these archives as PROJECT-vX.Y.Z-src.tar.gz replacing PROJECT with your project name and X.Y.Z with your version number. The archive should have only one sub-directory named PROJECT-vX.Y.Z/ containing all the source-code files. This differentiate it against traditional PROJECT-X.Y.Z.tar.gz tarballs in that it embeds the git tag (which typically starts with v) and contains a wildcard-friendly -src substring. Alas there is no consistency around this naming pattern, and GitLab, GitHub, Codeberg etc all seem to use their own slightly incompatible variant. Let s go on to see what is needed to achieve reproducible make dist source tarballs. This is the release artifact that most users use, and they often contain lots of generated files and vendor files. These files are included to make it easy to build for the user. What are the challenges to make these reproducible?

Build dependencies causing different generated content The first part is to realize that if you use tool X with version A to generate a file that goes into the tarball, version B of that tool may produce different outputs. This is a generic concern and it cannot be solved. We want our build tools to evolve and produce better outputs over time. What can be addressed is to avoid needless differences. For example, many tools store timestamps and versioning information in the generated files. This causes needless differences, which makes audits harder. I have worked on some of these, like Autoconf Archive timestamps but solving all of these examples will take a long time, and some upstream are reluctant to incorporate these changes. My approach meanwhile is to build things using similar environments, and compare the outputs for differences. I ve found that the various closely related forks of GNU/Linux distributions are useful for this. Trisquel 11 is based on Ubuntu 22.04, and building my projects using both and comparing the differences only give me the relevant differences to improve. This can be extended to compare AlmaLinux with RockyLinux (for both versions 8 and 9), Devuan 5 against Debian 12, PureOS 10 with Debian 11, and so on.

Timestamps Sometimes tools store timestamps in files in a way that is harder to fix. Two notable examples of this are *.po translation files and Texinfo manuals. For translation files, I have resolved this by making sure the files use a predictable POT-Creation-Date timestamp, and I set it to the modification timestamps of the NEWS file in the repository (which I set to the git commit of the latest commit elsewhere) like this:
dist-hook: po-CreationDate-to-mtime-NEWS
.PHONY: po-CreationDate-to-mtime-NEWS
po-CreationDate-to-mtime-NEWS: mtime-NEWS-to-git-HEAD
  $(AM_V_GEN)for p in $(distdir)/po/*.po $(distdir)/po/$(PACKAGE).pot; do \
    if test -f "$$p"; then \
      $(SED) -e 's,POT-Creation-Date: .*\\n",POT-Creation-Date: '"$$(env LC_ALL=C TZ=UTC0 stat --format=%y $(srcdir)/NEWS   cut -c1-16,31-)"'\\n",' < $$p > $$p.tmp && \
      if cmp $$p $$p.tmp > /dev/null; then \
        rm -f $$p.tmp; \
      else \
        mv $$p.tmp $$p; \
      fi \
    fi \
  done
Similarily, I set a predictable modification time of the texinfo source file like this:
dist-hook: mtime-NEWS-to-git-HEAD
.PHONY: mtime-NEWS-to-git-HEAD
mtime-NEWS-to-git-HEAD:
  $(AM_V_GEN)if test -e $(srcdir)/.git \
                && command -v git > /dev/null; then \
    touch -m -t "$$(git log -1 --format=%cd \
      --date=format-local:%Y%m%d%H%M.%S)" $(srcdir)/NEWS; \
  fi
However I ve realized that this needs to happen earlier and probably has to be run during ./configure time, because the doc/version.texi file is generated on first build before running make dist and for some reason the file is not rebuilt at release time. The Automake texinfo integration is a bit inflexible about providing hooks to extend the dependency tracking. The method to address these differences isn t really important, and they change over time depending on preferences. What is important is that the differences are eliminated.

ChangeLog Traditionally ChangeLog files were manually prepared, and still is for some projects. I maintain git2cl but recently I ve settled with gnulib s gitlog-to-changelog because doing so avoids another build dependency (although the output formatting is different and arguable worse for my git commit style). So the ChangeLog files are generated from git history. This means a shallow clone will not produce the same ChangeLog file depending on how deep it was cloned. For Libntlm I simply disabled use of generated ChangeLog because I wanted to support an even more extreme form of reproducibility: I wanted to be able to reproduce the full make dist source archives from a minimal git-archive source archive. However for other projects I ve settled with a middle ground. I realized that for git describe to produce reproducible outputs, the shallow clone needs to include the last release tag. So it felt acceptable to assume that the clone is not minimal, but instead has some but not all of the history. I settled with the following recipe to produce ChangeLog's covering all changes since the last release.
dist-hook: gen-ChangeLog
.PHONY: gen-ChangeLog
gen-ChangeLog:
  $(AM_V_GEN)if test -e $(srcdir)/.git; then			\
    LC_ALL=en_US.UTF-8 TZ=UTC0					\
    $(top_srcdir)/build-aux/gitlog-to-changelog			\
       --srcdir=$(srcdir) --					\
       v$(PREV_VERSION)~.. > $(distdir)/cl-t &&			\
         printf '\n\nSee the source repo for older entries\n'	\
         >> $(distdir)/cl-t &&					\
         rm -f $(distdir)/ChangeLog &&				\
         mv $(distdir)/cl-t $(distdir)/ChangeLog;  		\
  fi
I m undecided about the usefulness of generated ChangeLog files within make dist archives. Before we have stable and secure archival of git repositories widely implemented, I can see some utility of this in case we lose all copies of the upstream git repositories. I can sympathize with the concept of ChangeLog files died when we started to generate them from git logs: the files no longer serve any purpose, and we can ask people to go look at the git log instead of reading these generated non-source files.

Long-term reproducible trusted build environment Distributions comes and goes, and old releases of them goes out of support and often stops working. Which build environment should I chose to build the official release archives? To my knowledge only Guix offers a reliable way to re-create an older build environment (guix gime-machine) that have bootstrappable properties for additional confidence. However I had two difficult problems here. The first one was that I needed Guix container images that were usable in GitLab CI/CD Pipelines, and this side-tracked me for a while. The second one delayed my effort for many months, and I was inclined to give up. Libidn distribute a C# implementation. Some of the C# source code files included in the release tarball are generated. By what? You guess it, by a C# program, with the source code included in the distribution. This means nobody could reproduce the source tarball of Libidn without trusting someone elses C# compiler binaries, which were built from binaries of earlier releases, chaining back into something that nobody ever attempts to build any more and likely fail to build due to bit-rot. I had two basic choices, either remove the C# implementation from Libidn (which may be a good idea for other reasons, since the C and C# are unrelated implementations) or build the source tarball on some binary-only distribution like Trisquel. Neither felt appealing to me, but a late christmas gift of a reproducible Mono came to Guix that resolve this.

Embedded images in Texinfo manual For Libidn one section of the manual has an image illustrating some concepts. The PNG, PDF and EPS outputs were generated via fig2dev from a *.fig file (hello 1985!) that I had stored in git. Over time, I had also started to store the generated outputs because of build issues. At some point, it was possible to post-process the PDF outputs with grep to remove some timestamps, however with compression this is no longer possible and actually the grep command I used resulted in a 0-byte output file. So my embedded binaries in git was no longer reproducible. I first set out to fix this by post-processing things properly, however I then realized that the *.fig file is not really easy to work with in a modern world. I wanted to create an image from some text-file description of the image. Eventually, via the Guix manual on guix graph, I came to re-discover the graphviz language and tool called dot (hello 1993!). All well then? Oh no, the PDF output embeds timestamps. Binary editing of PDF s no longer work through simple grep, remember? I was back where I started, and after some (soul- and web-) searching I discovered that Ghostscript (hello 1988!) pdfmarks could be used to modify things here. Cooperating with automake s texinfo rules related to make dist proved once again a worthy challenge, and eventually I ended up with a Makefile.am snippet to build images that could be condensed into:
info_TEXINFOS = libidn.texi
libidn_TEXINFOS += libidn-components.png
imagesdir = $(infodir)
images_DATA = libidn-components.png
EXTRA_DIST += components.dot
DISTCLEANFILES = \
  libidn-components.eps libidn-components.png libidn-components.pdf
libidn-components.eps: $(srcdir)/components.dot
  $(AM_V_GEN)$(DOT) -Nfontsize=9 -Teps < $< > $@.tmp
  $(AM_V_at)! grep %%CreationDate $@.tmp
  $(AM_V_at)mv $@.tmp $@
libidn-components.pdf: $(srcdir)/components.dot
  $(AM_V_GEN)$(DOT) -Nfontsize=9 -Tpdf < $< > $@.tmp
# A simple sed on CreationDate is no longer possible due to compression.
# 'exiftool -CreateDate' is alternative to 'gs', but adds ~4kb to file.
# Ghostscript add <1kb.  Why can't 'dot' avoid setting CreationDate?
  $(AM_V_at)printf '[ /ModDate ()\n  /CreationDate ()\n  /DOCINFO pdfmark\n' > pdfmarks
  $(AM_V_at)$(GS) -q -dBATCH -dNOPAUSE -sDEVICE=pdfwrite -sOutputFile=$@.tmp2 $@.tmp pdfmarks
  $(AM_V_at)rm -f $@.tmp pdfmarks
  $(AM_V_at)mv $@.tmp2 $@
libidn-components.png: $(srcdir)/components.dot
  $(AM_V_GEN)$(DOT) -Nfontsize=9 -Tpng < $< > $@.tmp
  $(AM_V_at)mv $@.tmp $@
pdf-recursive: libidn-components.pdf
dvi-recursive: libidn-components.eps
ps-recursive: libidn-components.eps
info-recursive: $(top_srcdir)/.version libidn-components.png
Surely this can be improved, but I m not yet certain in what way is the best one forward. I like having a text representation as the source of the image. I m sad that the new image size is ~48kb compared to the old image size of ~1kb. I tried using exiftool -CreateDate as an alternative to GhostScript, but using it to remove the timestamp added ~4kb to the file size and naturally I was appalled by this ignorance of impending doom.

Test reproducibility of tarball Again, you need to continuously test the properties you desire. This means building your project twice using different environments and comparing the results. I ve settled with a small GitLab CI/CD pipeline job that perform bit-by-bit comparison of generated make dist archives. It also perform bit-by-bit comparison of generated git-archive artifacts. See the Libidn2 .gitlab-ci.yml 0-compare job which essentially is:
0-compare:
  image: alpine:latest
  stage: repro
  needs: [ B-AlmaLinux8, B-AlmaLinux9, B-RockyLinux8, B-RockyLinux9, B-Trisquel11, B-Ubuntu2204, B-PureOS10, B-Debian11, B-Devuan5, B-Debian12, B-gcc, B-clang, B-Guix, R-Guix, R-Debian12, R-Ubuntu2404, S-Trisquel10, S-Ubuntu2004 ]
  script:
  - cd out
  - sha256sum */*.tar.* */*/*.tar.*   sort   grep    -- -src.tar.
  - sha256sum */*.tar.* */*/*.tar.*   sort   grep -v -- -src.tar.
  - sha256sum */*.tar.* */*/*.tar.*   sort   uniq -c -w64   sort -rn
  - sha256sum */*.tar.* */*/*.tar.*   grep    -- -src.tar.   sort   uniq -c -w64   grep -v '^      1 '
  - sha256sum */*.tar.* */*/*.tar.*   grep -v -- -src.tar.   sort   uniq -c -w64   grep -v '^      1 '
# Confirm modern git-archive tarball reproducibility
  - cmp b-almalinux8/src/*.tar.gz b-almalinux9/src/*.tar.gz
  - cmp b-almalinux8/src/*.tar.gz b-rockylinux8/src/*.tar.gz
  - cmp b-almalinux8/src/*.tar.gz b-rockylinux9/src/*.tar.gz
  - cmp b-almalinux8/src/*.tar.gz b-debian12/src/*.tar.gz
  - cmp b-almalinux8/src/*.tar.gz b-devuan5/src/*.tar.gz
  - cmp b-almalinux8/src/*.tar.gz r-guix/src/*.tar.gz
  - cmp b-almalinux8/src/*.tar.gz r-debian12/src/*.tar.gz
  - cmp b-almalinux8/src/*.tar.gz r-ubuntu2404/src/*v2.*.tar.gz
# Confirm old git-archive (export-subst but long git describe) tarball reproducibility
  - cmp b-trisquel11/src/*.tar.gz b-ubuntu2204/src/*.tar.gz
# Confirm really old git-archive (no export-subst) tarball reproducibility
  - cmp b-debian11/src/*.tar.gz b-pureos10/src/*.tar.gz
# Confirm 'make dist' generated tarball reproducibility
  - cmp b-almalinux8/*.tar.gz b-rockylinux8/*.tar.gz
  - cmp b-almalinux9/*.tar.gz b-rockylinux9/*.tar.gz
  - cmp b-pureos10/*.tar.gz b-debian11/*.tar.gz
  - cmp b-devuan5/*.tar.gz b-debian12/*.tar.gz
  - cmp b-trisquel11/*.tar.gz b-ubuntu2204/*.tar.gz
  - cmp b-guix/*.tar.gz r-guix/*.tar.gz
# Confirm 'make dist' from git-archive tarball reproducibility
  - cmp s-trisquel10/*.tar.gz s-ubuntu2004/*.tar.gz
Notice that I discovered that git archive outputs differ over time too, which is natural but a bit of a nuisance. The output of the job is illuminating in the way that all SHA256 checksums of generated tarballs are included, for example the libidn2 v2.3.8 job log:
$ sha256sum */*.tar.* */*/*.tar.*   sort   grep -v -- -src.tar.
368488b6cc8697a0a937b9eb307a014396dd17d3feba3881e6911d549732a293  b-trisquel11/libidn2-2.3.8.tar.gz
368488b6cc8697a0a937b9eb307a014396dd17d3feba3881e6911d549732a293  b-ubuntu2204/libidn2-2.3.8.tar.gz
59db2d045fdc5639c98592d236403daa24d33d7c8db0986686b2a3056dfe0ded  b-debian11/libidn2-2.3.8.tar.gz
59db2d045fdc5639c98592d236403daa24d33d7c8db0986686b2a3056dfe0ded  b-pureos10/libidn2-2.3.8.tar.gz
5bd521d5ecd75f4b0ab0fc6d95d444944ef44a84cad859c9fb01363d3ce48bb8  s-trisquel10/libidn2-2.3.8.tar.gz
5bd521d5ecd75f4b0ab0fc6d95d444944ef44a84cad859c9fb01363d3ce48bb8  s-ubuntu2004/libidn2-2.3.8.tar.gz
7f1dcdea3772a34b7a9f22d6ae6361cdcbe5513e3b6485d40100b8565c9b961a  b-almalinux8/libidn2-2.3.8.tar.gz
7f1dcdea3772a34b7a9f22d6ae6361cdcbe5513e3b6485d40100b8565c9b961a  b-rockylinux8/libidn2-2.3.8.tar.gz
8031278157ce43b5813f36cf8dd6baf0d9a7f88324ced796765dcd5cd96ccc06  b-clang/libidn2-2.3.8.tar.gz
8031278157ce43b5813f36cf8dd6baf0d9a7f88324ced796765dcd5cd96ccc06  b-debian12/libidn2-2.3.8.tar.gz
8031278157ce43b5813f36cf8dd6baf0d9a7f88324ced796765dcd5cd96ccc06  b-devuan5/libidn2-2.3.8.tar.gz
8031278157ce43b5813f36cf8dd6baf0d9a7f88324ced796765dcd5cd96ccc06  b-gcc/libidn2-2.3.8.tar.gz
8031278157ce43b5813f36cf8dd6baf0d9a7f88324ced796765dcd5cd96ccc06  r-debian12/libidn2-2.3.8.tar.gz
acf5cbb295e0693e4394a56c71600421059f9c9bf45ccf8a7e305c995630b32b  r-ubuntu2404/libidn2-2.3.8.tar.gz
cbdb75c38100e9267670b916f41878b6dbc35f9c6cbe60d50f458b40df64fcf1  b-almalinux9/libidn2-2.3.8.tar.gz
cbdb75c38100e9267670b916f41878b6dbc35f9c6cbe60d50f458b40df64fcf1  b-rockylinux9/libidn2-2.3.8.tar.gz
f557911bf6171621e1f72ff35f5b1825bb35b52ed45325dcdee931e5d3c0787a  b-guix/libidn2-2.3.8.tar.gz
f557911bf6171621e1f72ff35f5b1825bb35b52ed45325dcdee931e5d3c0787a  r-guix/libidn2-2.3.8.tar.gz
I m sure I have forgotten or suppressed some challenges (sprinkling LANG=C TZ=UTC0 helps) related to these goals, but my hope is that this discussion of solutions will inspire you to implement these concepts for your software project too. Please share your thoughts and additional insights in a comment below. Enjoy Happy Hacking in the course of practicing this!

Arnaud Rebillout: Buid container images with buildah/podman in GitLab CI

Oh no, it broke again! Today, this .gitlab-ci.yml file no longer works in GitLab CI:
build-container-image:
  stage: build
  image: debian:testing
  before_script:
    - apt-get update
    - apt-get install -y buildah ca-certificates
  script:
    - buildah build -t $CI_REGISTRY_IMAGE .
The command buildah build ... fails with this error message:
STEP 2/3: RUN  apt-get update
internal:0:0-0: Error: Could not process rule: No such file or directory
error running container: did not get container start message from parent: EOF
Error: building at STEP "RUN apt-get update": setup network: netavark: nftables error: nft did not return successfully while applying ruleset
After some investigation, it's caused by the recent upload of netavark 1.14.0-2. In this version, netavark switched from iptables to nftables as the default firewall driver. That doesn't really fly on GitLab Saas shared runners. For the complete background, refer to https://discussion.fedoraproject.org/t/125528. Note that the issue with GitLab was reported back in November, but at this point the conversation had died out. Fortunately, it's easy to workaround, we can tell netavark to keep using iptables via the environment variables NETAVARK_FW. The .gitlab-ci.yml file above becomes:
build-container-image:
  stage: build
  image: debian:testing
  variables:
    # Cf. https://discussion.fedoraproject.org/t/125528/7
    NETAVARK_FW: iptables
  before_script:
    - apt-get update
    - apt-get install -y buildah ca-certificates
  script:
    - buildah build -t $CI_REGISTRY_IMAGE .
And everything works again! If you're interested in this issue, feel free to fork https://gitlab.com/arnaudr/gitlab-build-container-image and try it by yourself.

22 March 2025

Dirk Eddelbuettel: RcppZiggurat 0.1.7 on CRAN: New Generators, Many Updates

ziggurats A new release 0.1.7 of RcppZiggurat is now on the CRAN network for R. This marks the first release in four and a half years. The RcppZiggurat package updates the code for the Ziggurat generator by Marsaglia and others which provides very fast draws from a Normal distribution. The package provides a simple C++ wrapper class for the generator improving on the very basic macros, and permits comparison among several existing Ziggurat implementations. This can be seen in the figure where Ziggurat from this package dominates accessing the implementations from the GSL, QuantLib and Gretl all of which are still way faster than the default Normal generator in R (which is of course of higher code complexity). This release brings a number of changes. Notably, based on the work we did with the new package zigg (more on that in a second), we now also expose the Exponential generator, and the underlying Uniform generator. Otherwise many aspects of the package have been refreshed: updated builds, updated links, updated CI processes, more use of DOIs and more. The other big news is zigg which should now be the preference for deployment of Ziggurat due to its much lighter-weight and zero-dependency setup. The NEWS file entry below lists all changes.

Changes in version 0.1.7 (2025-03-22)
  • The CI setup was updated to use run.sh from r-ci (Dirk).
  • The windows build was updated to GSL 2.7, and UCRT support was added (Jeroen in #16).
  • Manual pages now use JSS DOIs for references per CRAN request
  • README.md links and badges have been updated
  • Continuous integration actions have been updated several times
  • The DESCRIPTION file now uses Authors@R as mandated
  • Use of multiple cores is eased via a new helper function reflecting option mc.core or architecture defaults, used in tests
  • An inline function has been added to avoid a compiler nag
  • Support for exponential RNG draws zrexp has been added, the internal uniform generator is now also exposed via zruni
  • The vignette bibliography has been updated, and switched to DOIs
  • New package zigg is now mentioned in DESCRIPTION and vignette

Courtesy of my CRANberries, there is a diffstat report relative to previous release. More detailed information is on the Rcppziggurat page or the GitHub repository.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. If you like this or other open-source work I do, you can sponsor me at GitHub.

Next.

Previous.