Search Results: "cts"

24 May 2025

Julian Andres Klode: A SomewhatMaxSAT Solver

As you may recall from previous posts and elsewhere I have been busy writing a new solver for APT. Today I want to share some of the latest changes in how to approach solving. The idea for the solver was that manually installed packages are always protected from removals in terms of SAT solving, they are facts. Automatically installed packages become optional unit clauses. Optional clauses are solved after manual ones, they don t partake in normal unit propagation. This worked fine, say you had
A                                   # install request for A
B                                   # manually installed, keep it
A depends on: conflicts-B   C
Installing A on a system with B installed installed C, as it was not allowed to install the conflicts-B package since B is installed. However, I also introduced a mode to allow removing manually installed packages, and that s where it broke down, now instead of B being a fact, our clauses looked like:
A                               # install request for A
A depends on: conflicts-B   C
Optional: B                     # try to keep B installed
As a result, we installed conflicts-B and removed B; the steps the solver takes are:
  1. A is a fact, mark it
  2. A depends on: conflicts-B C is the strongest clause, try to install conflicts-B
  3. We unit propagate that conflicts-B conflicts with B, so we mark not B
  4. Optional: B is reached, but not satisfiable, ignore it because it s optional.
This isn t correct: Just because we allow removing manually installed packages doesn t mean that we should remove manually installed packages if we don t need to. Fixing this turns out to be surprisingly easy. In addition to adding our optional (soft) clauses, let s first assume all of them! But to explain how this works, we first need to explain some terminology:
  1. The solver operates on a stack of decisions
  2. enqueue means a fact is being added at the current decision level, and enqueued for propagation
  3. assume bumps the decision level, and then enqueues the assumed variable
  4. propagate looks at all the facts and sees if any clause becomes unit, and then enqueues it
  5. unit is when a clause has a single literal left to assign
To illustrate this in pseudo Python code:
  1. We introduce all our facts, and if they conflict, we are unsat:
    for fact in facts:
        enqueue(fact)
    if not propagate():
        return False
    
  2. For each optional literal, we register a soft clause and assume it. If the assumption fails, we ignore it. If it succeeds, but propagation fails, we undo the assumption.
    for optionalLiteral in optionalLiterals:
        registerClause(SoftClause([optionalLiteral]))
        if assume(optionalLiteral) and not propagate():
            undo()
    
  3. Finally we enter the main solver loop:
    while True:
        if not propagate():
            if not backtrack():
                return False
        elif <all clauses are satisfied>:
            return True
        elif it := find("best unassigned literal satisfying a hard clause"):
            assume(it)
        elif it := find("best literal satisfying a soft clause"):
            assume(it)
    
The key point to note is that the main loop will undo the assumptions in order; so if you assume A,B,C and B is not possible, we will have also undone C. But since C is also enqueued as a soft clause, we will then later find it again:
  1. Assume A: State=[Assume(A)], Clauses=[SoftClause([A])]
  2. Assume B: State=[Assume(A),Assume(B)], Clauses=[SoftClause([A]),SoftClause([B])]
  3. Assume C: State=[Assume(A),Assume(B),Assume(C)], Clauses=[SoftClause([A]),SoftClause([B]),SoftClause([C])]
  4. Solve finds a conflict, backtracks, and sets not C: State=[Assume(A),Assume(B),not(C)]
  5. Solve finds a conflict, backtracks, and sets not B: State=[Assume(A),not(B)] C is no longer assumed either
  6. Solve, assume C as it satisfies SoftClause([C]) as next best literal: State=[Assume(A),not(B),Assume(C)]
  7. All clauses are satisfied, solution is A, not B, and C.
This is not (correct) MaxSAT, because we actually do not guarantee that we satisfy as many soft clauses as possible. Consider you have the following clauses:
Optional: A
Optional: B
Optional: C
B Conflicts with A
C Conflicts with A
There are two possible results here:
  1. A If we assume A first, we are unable to satisfy B or C.
  2. B,C If we assume either B or C first, A is unsat.
The question to ponder though is whether we actually need a global maximum or whether a local maximum is satisfactory in practice for a dependency solver If you look at it, a naive MaxSAT solver needs to run the SAT solver 2**n times for n soft clauses, whereas our heuristic only needs n runs. For dependency solving, it seems we do not seem have a strong need for a global maximum: There are various other preferences between our literals, say priorities; and empirically, from evaluating hundreds of regressions without the initial assumptions, I can say that the assumptions do fix those cases and the result is correct. Further improvements exist, though, and we can look into them if they are needed, such as:

22 May 2025

Simon Quigley: Bootstrapping and Bikeshedding

When you learn to write, one of the major pieces is writing an introduction. You could say quite a bit about the formal process and the way formal writing is typically structured.That being said, I m not your typical writer. I didn t exactly plan to be in this spot, and honestly, it s just a hobby of mine. If you enjoy reading my posts, great. I appreciate it.My entire point, from the very beginning of this week, has been to bootstrap my own platform, on my own two feet. As you all know, rumors were going around, and I felt as if I wasn t in that great of a position to go out and say everything that I ve said, in one long post. I ve needed to break it apart, and work through some of my own notes again. Prove myself, rather than asking for it to be handed to me. Keep people guessing on some elements, to let the people who have been doing wrong firmly prove themselves. At least twelve people at this point have sent me undeniable proof. I don t want to do anything with it. I want to move on, and I want to write about technology, and other things I actually enjoy writing about.I really don t enjoy conflict, or writing about it, at all. I just know how to defend myself if I need to. If you think I actively want to make everyone mad for no good reason, you re honestly fooling yourself.I already know that I m not going to agree with everything I write in a few years, or maybe even weeks. But I ll hold myself to the same standard I hold everyone else. If you say something and a few years pass, I m not going to assume you still have the same opinion. I ll give you the opportunity to correct it. I d ask you lend me the same courtesy.I do this because I enjoy it, not out of anger, sadness, or anything like that. A number of people have approached me now simply asking why I m doing what I m doing. I planned to write this blog post at the very end all along. I just haven t revealed the plans before publishing. [I wrote the outline for this more than a day ago.]My entire point here is to give the common person a voice. I know exactly what it s like to start from nothing, and work your way up to a comfortable spot. I didn t only do it once, I did it twice. This is my third time. I genuinely don t appreciate it when people silence other people s voices just because they don t like them. I wasn t raised that way, and that s not how I run my own projects. In fact, I d say that if you silence opinions or values that don t exactly match yours, you re missing out on the variety of life.You can lead a horse to water, but you can t make them drink. If you still think there are issues on my end, you re being misinformed. Plain and simple. I m not going to spend any more time on it, I actually want to start what I ve always wanted to do for years, just never had the opportunity to.This is my last post for the week. I feel like I ve bootstrapped enough where next week I can focus on another topic, as originally planned.Thanks for reading. I appreciate your support. Talk to you on Monday. If you have topic suggestions, feel free to leave them in the comments. Feel free to leave your hate mail too, so I know where I m at.If you read Piaget, you know that silence is concerning with respect to socialization. I just took a look at the view count for the first time, and I m already up to more than 2k views. In the first week. Without actually digging into the content I want to write about, yet.I don t mean to say that to brag, I m just telling you for a fact that I m not ranting into thin air. I m not even ranting at all. In fact, every single one of my posts has been written either calmly or with happiness, including this one.My entire point is this: debate me on the merits of the subject, not on me as a person. If you don t like me, that s okay. Go play elsewhere.But, I m still going to keep writing. Next week, different metaphors.We re bootstrapped now.

Dirk Eddelbuettel: RcppArmadillo 14.4.3-1 on CRAN: Small Upstream Bug Fix

armadillo image Armadillo is a powerful and expressive C++ template library for linear algebra and scientific computing. It aims towards a good balance between speed and ease of use, has a syntax deliberately close to Matlab, and is useful for algorithm development directly in C++, or quick conversion of research code into production environments. RcppArmadillo integrates this library with the R environment and language and is widely used by (currently) 1251 other packages on CRAN, downloaded 39.8 million times (per the partial logs from the cloud mirrors of CRAN), and the CSDA paper (preprint / vignette) by Conrad and myself has been cited 628 times according to Google Scholar. Conrad released a minor bugfix version yesterday which addresses corner cases with non-finite values in sparse matrices. And despite conference traveling, I managed to wrap this up and ship it to CRAN where it appeared yesterday. The changes since the last CRAN release are summarised below.

Changes in RcppArmadillo version 14.4.3-1 (2025-05-21)
  • Upgraded to Armadillo release 14.4.3 (Filtered Espresso)
    • Fix for several corner cases involving handling of non-finite elements by sparse matrices

Courtesy of my CRANberries, there is a diffstat report relative to previous release. More detailed information is on the RcppArmadillo page. Questions, comments etc should go to the rcpp-devel mailing list off the Rcpp R-Forge page.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. If you like this or other open-source work I do, you can sponsor me at GitHub.

21 May 2025

Simon Quigley: AI and what it actually means

A popular topic of public conversation in 2025 is balance. How do we balance budgets, how do we balance entities, and how do we balance perspectives? How do we balance the right of free expression with our ability to effectively convey a message?Here s another popular topic of conversation AI. What is it? What does it do?I m going to give you some resources, as someone who first learned the inner workings of AI about ten years ago.I ll start with the presentation I gave in middle school. Our objective was to give a presentation on a topic of our choice, and we would be graded on our ability to give a presentation. Instead of talking about specific things or events, I talked about the broader idea of fully establishing an artificial form of intelligence.This is the video I used as a basis for that presentation:https://medium.com/media/21d2427a502b7c7cb669220e2e3478c8/hrefNot only did I explain exactly how this specific video game worked, it helped me understand machine learning and genetic algorithms. If I m recalling correctly, the actual title of my presentation had to do with genetic algorithms specifically.In the presentation, I specifically tied in Darwin s readings on evolution (of course, I had to keep it secular ), directly relating the information I learned about evolution in science class into a presentation about what would become AI. But Simon, the title of that video says Machine Learning. Do you have your glasses on?!? Yes, yes I do. It took me a few years to watch this space evolve, as I focused on other portions of the open source world. This changed when I attended SCaLE 21x. At that conference, the product manager for AI at Canonical (apologies if I m misquoting your exact title) gave a presentation on how she sees this space evolving. It s a must watch, in my opinion:https://medium.com/media/a13b2e46fc8acaa3bebf01a7f7bdeebb/hrefThis comprehensive presentation really covers the entire space, and does an excellent job at giving the whole picture.The short of it is this calling everything AI is inaccurate. Using AI for everything under the sun also isn t accurate. Speaking of the sun, it will get us if we don t find a sustainable way to get all that energy we ll need.I also read a paper on this issue, which I believe ties it together nicely. Published in June 2024, it s titled Situational Awareness The Decade Ahead and does an excellent job in predicting how this space will evolve. So far, it s been very accurate.The reason I m explaining this is fairly simple. In 2025, I still don t think many people have taken the time to dig into the content. From many conversations I ve heard, including one I took notes on in an entirely personal capacity, I m finding that not many people have a decent idea for where this space is going.It s been researched! :)If someone can provide a dissent for this view of the artificial intelligence space in the comments, I d be more than happy to hear it. Here s where I think this connects to the average person Many of the open source companies right now, without naming names, are focusing too much on the corporate benefits of AI. Yes, AI will be an incredibly useful tool for large organizations, and it will have a great benefit for how we conduct business over the course of the next decade. But do we have enough balance?Before you go all-in on AI, just do your research, please. Take a look at your options, and choose one that is correctly calibrated with the space as you see it.Lastly, when I talk about AI, I always bring up Orwell. I m a very firm, strong believer in free speech. AI must not be used to censor content, and the people who design your AI stack are very important. Look at which one of the options, as a company, enforces a diversity policy that is consistent with your values. The values of that company will carry over into its product. If you think I m wrong about this point, seriously, go read 1984 by George Orwell a few times over. You ll get the picture on what we re looking to avoid.In short, there s no need to over-complicate AI to those who don t understand it. Use the video game example. It s simple, and it works. Try using that same sentiment in your messaging, too. Appealing to both companies and individual users, together, should be important for open source companies, especially those with a large user base.I wish you all well. If you re getting to the end of this post and you re mad at me, sorry about that. Go re-read 1984 just one more time, please. ;)

Bits from Debian: EDF Platinum Sponsor of DebConf25

edf-logo We are pleased to announce that EDF has committed to sponsor DebConf25 as a Platinum Sponsor. EDF is a leading global utility company focused on low-carbon power generation. The group uses advanced engineering and scientific computing tools to drive innovation and efficiency in its operations, especially in nuclear power plant design and safety assessment. Since 2003, the EDF Group has been using Debian as its main scientific computing environment. Debian's focus on stability and reproducibility ensures that EDF's calculations and simulations produce consistent and accurate results. With this commitment as Platinum Sponsor, EDF is contributing to the annual Debian Developers' Conference, directly supporting the progress of Debian and Free Software. EDF contributes to strengthening the worldwide community that collaborates on Debian projects year-round. Thank you very much, EDF, for your support of DebConf25! Become a sponsor too! DebConf25 will take place from 14th to July 19th 2025 in Brest, France, and will be preceded by DebCamp, from 7th to 13th July 2025. DebConf25 is accepting sponsors! Interested companies and organizations may contact the DebConf team through sponsors@debconf.org, and visit the DebConf25 website at https://debconf25.debconf.org/sponsors/become-a-sponsor/.

20 May 2025

Arturo Borrero Gonz lez: Wikimedia Cloud VPS: IPv6 support

Cape Town (ZA), Sea Point, Nachtansicht Dietmar Rabich, Cape Town (ZA), Sea Point, Nachtansicht 2024 1867-70 2, CC BY-SA 4.0 This post was originally published in the Wikimedia Tech blog, authored by Arturo Borrero Gonzalez. Wikimedia Cloud VPS is a service offered by the Wikimedia Foundation, built using OpenStack and managed by the Wikimedia Cloud Services team. It provides cloud computing resources for projects related to the Wikimedia movement, including virtual machines, databases, storage, Kubernetes, and DNS. A few weeks ago, in April 2025, we were finally able to introduce IPv6 to the cloud virtual network, enhancing the platform s scalability, security, and future-readiness. This is a major milestone, many years in the making, and serves as an excellent point to take a moment to reflect on the road that got us here. There were definitely a number of challenges that needed to be addressed before we could get into IPv6. This post covers the journey to this implementation. The Wikimedia Foundation was an early adopter of the OpenStack technology, and the original OpenStack deployment in the organization dates back to 2011. At that time, IPv6 support was still nascent and had limited implementation across various OpenStack components. In 2012, the Wikimedia cloud users formally requested IPv6 support. When Cloud VPS was originally deployed, we had set up the network following some of the upstream-recommended patterns: In order for us to be able to implement IPv6 in a way that aligned with our architectural goals and operational requirements, pretty much all the elements in this list would need to change. First of all, we needed to migrate from nova-networks into Neutron, a migration effort that started in 2017. Neutron was the more modern component to implement software-defined networks in OpenStack. To facilitate this transition, we made the strategic decision to backport certain functionalities from nova-networks into Neutron, specifically the dmz_cidr mechanism and some egress NAT capabilities. Once in Neutron, we started to think about IPv6. In 2018 there was an initial attempt to decide on the network CIDR allocations that Wikimedia Cloud Services would have. This initiative encountered unforeseen challenges and was subsequently put on hold. We focused on removing the previously backported nova-networks patches from Neutron. Between 2020 and 2021, we initiated another significant network refresh. We were able to introduce the cloudgw project, as part of a larger effort to rework the Cloud VPS edge network. The new edge routers allowed us to drop all the custom backported patches we had in Neutron from the nova-networks era, unblocking further progress. Worth mentioning that the cloudgw router would use nftables as firewalling and NAT engine. A pivotal decision in 2022 was to expose the OpenStack APIs to the internet, which crucially enabled infrastructure management via OpenTofu. This was key in the IPv6 rollout as will be explained later. Before this, management was limited to Horizon the OpenStack graphical interface or the command-line interface accessible only from internal control servers. Later, in 2023, following the OpenStack project s announcement of the deprecation of the neutron-linuxbridge-agent, we began to seriously consider migrating to the neutron-openvswitch-agent. This transition would, in turn, simplify the enablement of tenant networks a feature allowing each OpenStack project to define its own isolated network, rather than all virtual machines sharing a single flat network. Once we replaced neutron-linuxbridge-agent with neutron-openvswitch-agent, we were ready to migrate virtual machines to VXLAN. Demonstrating perseverance, we decided to execute the VXLAN migration in conjunction with the IPv6 rollout. We prepared and tested several things, including the rework of the edge routing to be based on BGP/OSPF instead of static routing. In 2024 we were ready for the initial attempt to deploy IPv6, which failed for unknown reasons. There was a full network outage and we immediately reverted the changes. This quick rollback was feasible due to our adoption of OpenTofu: deploying IPv6 had been reduced to a single code change within our repository. We started an investigation, corrected a few issues, and increased our network functional testing coverage before trying again. One of the problems we discovered was that Neutron would enable the enable_snat configuration flag for our main router when adding the new external IPv6 address. Finally, in April 2025, after many years in the making, IPv6 was successfully deployed. Compared to the network from 2011, we would have: Over time, the WMCS team has skillfully navigated numerous challenges to ensure our service offerings consistently meet high standards of quality and operational efficiency. Often engaging in multi-year planning strategies, we have enabled ourselves to set and achieve significant milestones. The successful IPv6 deployment stands as further testament to the team s dedication and hard work over the years. I believe we can confidently say that the 2025 Cloud VPS represents its most advanced and capable iteration to date. This post was originally published in the Wikimedia Tech blog, authored by Arturo Borrero Gonzalez.

19 May 2025

Melissa Wen: A Look at the Latest Linux KMS Color API Developments on AMD and Intel

This week, I reviewed the last available version of the Linux KMS Color API. Specifically, I explored the proposed API by Harry Wentland and Alex Hung (AMD), their implementation for the AMD display driver and tracked the parallel efforts of Uma Shankar and Chaitanya Kumar Borah (Intel) in bringing this plane color management to life. With this API in place, compositors will be able to provide better HDR support and advanced color management for Linux users. To get a hands-on feel for the API s potential, I developed a fork of drm_info compatible with the new color properties. This allowed me to visualize the display hardware color management capabilities being exposed. If you re curious and want to peek behind the curtain, you can find my exploratory work on the drm_info/kms_color branch. The README there will guide you through the simple compilation and installation process. Note: You will need to update libdrm to match the proposed API. You can find an updated version in my personal repository here. To avoid potential conflicts with your official libdrm installation, you can compile and install it in a local directory. Then, use the following command: export LD_LIBRARY_PATH="/usr/local/lib/" In this post, I invite you to familiarize yourself with the new API that is about to be released. You can start doing as I did below: just deploy a custom kernel with the necessary patches and visualize the interface with the help of drm_info. Or, better yet, if you are a userspace developer, you can start developing user cases by experimenting with it. The more eyes the better.

KMS Color API on AMD The great news is that AMD s driver implementation for plane color operations is being developed right alongside their Linux KMS Color API proposal, so it s easy to apply to your kernel branch and check it out. You can find details of their progress in the AMD s series. I just needed to compile a custom kernel with this series applied, intentionally leaving out the AMD_PRIVATE_COLOR flag. The AMD_PRIVATE_COLOR flag guards driver-specific color plane properties, which experimentally expose hardware capabilities while we don t have the generic KMS plane color management interface available. If you don t know or don t remember the details of AMD driver specific color properties, you can learn more about this work in my blog posts [1] [2] [3]. As driver-specific color properties and KMS colorops are redundant, the driver only advertises one of them, as you can see in AMD workaround patch 24. So, with the custom kernel image ready, I installed it on a system powered by AMD DCN3 hardware (i.e. my Steam Deck). Using my custom drm_info, I could clearly see the Plane Color Pipeline with eight color operations as below:
 "COLOR_PIPELINE" (atomic): enum  Bypass, Color Pipeline 258  = Bypass
     Bypass
     Color Pipeline 258
         Color Operation 258
             "TYPE" (immutable): enum  1D Curve, 1D LUT, 3x4 Matrix, Multiplier, 3D LUT  = 1D Curve
             "BYPASS" (atomic): range [0, 1] = 1
             "CURVE_1D_TYPE" (atomic): enum  sRGB EOTF, PQ 125 EOTF, BT.2020 Inverse OETF  = sRGB EOTF
         Color Operation 263
             "TYPE" (immutable): enum  1D Curve, 1D LUT, 3x4 Matrix, Multiplier, 3D LUT  = Multiplier
             "BYPASS" (atomic): range [0, 1] = 1
             "MULTIPLIER" (atomic): range [0, UINT64_MAX] = 0
         Color Operation 268
             "TYPE" (immutable): enum  1D Curve, 1D LUT, 3x4 Matrix, Multiplier, 3D LUT  = 3x4 Matrix
             "BYPASS" (atomic): range [0, 1] = 1
             "DATA" (atomic): blob = 0
         Color Operation 273
             "TYPE" (immutable): enum  1D Curve, 1D LUT, 3x4 Matrix, Multiplier, 3D LUT  = 1D Curve
             "BYPASS" (atomic): range [0, 1] = 1
             "CURVE_1D_TYPE" (atomic): enum  sRGB Inverse EOTF, PQ 125 Inverse EOTF, BT.2020 OETF  = sRGB Inverse EOTF
         Color Operation 278
             "TYPE" (immutable): enum  1D Curve, 1D LUT, 3x4 Matrix, Multiplier, 3D LUT  = 1D LUT
             "BYPASS" (atomic): range [0, 1] = 1
             "SIZE" (atomic, immutable): range [0, UINT32_MAX] = 4096
             "LUT1D_INTERPOLATION" (immutable): enum  Linear  = Linear
             "DATA" (atomic): blob = 0
         Color Operation 285
             "TYPE" (immutable): enum  1D Curve, 1D LUT, 3x4 Matrix, Multiplier, 3D LUT  = 3D LUT
             "BYPASS" (atomic): range [0, 1] = 1
             "SIZE" (atomic, immutable): range [0, UINT32_MAX] = 17
             "LUT3D_INTERPOLATION" (immutable): enum  Tetrahedral  = Tetrahedral
             "DATA" (atomic): blob = 0
         Color Operation 292
             "TYPE" (immutable): enum  1D Curve, 1D LUT, 3x4 Matrix, Multiplier, 3D LUT  = 1D Curve
             "BYPASS" (atomic): range [0, 1] = 1
             "CURVE_1D_TYPE" (atomic): enum  sRGB EOTF, PQ 125 EOTF, BT.2020 Inverse OETF  = sRGB EOTF
         Color Operation 297
             "TYPE" (immutable): enum  1D Curve, 1D LUT, 3x4 Matrix, Multiplier, 3D LUT  = 1D LUT
             "BYPASS" (atomic): range [0, 1] = 1
             "SIZE" (atomic, immutable): range [0, UINT32_MAX] = 4096
             "LUT1D_INTERPOLATION" (immutable): enum  Linear  = Linear
             "DATA" (atomic): blob = 0
Note that Gamescope is currently using AMD driver-specific color properties implemented by me, Autumn Ashton and Harry Wentland. It doesn t use this KMS Color API, and therefore COLOR_PIPELINE is set to Bypass. Once the API is accepted upstream, all users of the driver-specific API (including Gamescope) should switch to the KMS generic API, as this will be the official plane color management interface of the Linux kernel.

KMS Color API on Intel On the Intel side, the driver implementation available upstream was built upon an earlier iteration of the API. This meant I had to apply a few tweaks to bring it in line with the latest specifications. You can explore their latest work here. For a more simplified handling, combining the V9 of the Linux Color API, Intel s contributions, and my necessary adjustments, check out my dedicated branch. I then compiled a kernel from this integrated branch and deployed it on a system featuring Intel TigerLake GT2 graphics. Running my custom drm_info revealed a Plane Color Pipeline with three color operations as follows:
 "COLOR_PIPELINE" (atomic): enum  Bypass, Color Pipeline 480  = Bypass
     Bypass
     Color Pipeline 480
         Color Operation 480
             "TYPE" (immutable): enum  1D Curve, 1D LUT, 3x4 Matrix, 1D LUT Mult Seg, 3x3 Matrix, Multiplier, 3D LUT  = 1D LUT Mult Seg
             "BYPASS" (atomic): range [0, 1] = 1
             "HW_CAPS" (atomic, immutable): blob = 484
             "DATA" (atomic): blob = 0
         Color Operation 487
             "TYPE" (immutable): enum  1D Curve, 1D LUT, 3x4 Matrix, 1D LUT Mult Seg, 3x3 Matrix, Multiplier, 3D LUT  = 3x3 Matrix
             "BYPASS" (atomic): range [0, 1] = 1
             "DATA" (atomic): blob = 0
         Color Operation 492
             "TYPE" (immutable): enum  1D Curve, 1D LUT, 3x4 Matrix, 1D LUT Mult Seg, 3x3 Matrix, Multiplier, 3D LUT  = 1D LUT Mult Seg
             "BYPASS" (atomic): range [0, 1] = 1
             "HW_CAPS" (atomic, immutable): blob = 496
             "DATA" (atomic): blob = 0
Observe that Intel s approach introduces additional properties like HW_CAPS at the color operation level, along with two new color operation types: 1D LUT with Multiple Segments and 3x3 Matrix. It s important to remember that this implementation is based on an earlier stage of the KMS Color API and is awaiting review.

A Shout-Out to Those Who Made This Happen I m impressed by the solid implementation and clear direction of the V9 of the KMS Color API. It aligns with the many insightful discussions we ve had over the past years. A huge thank you to Harry Wentland and Alex Hung for their dedication in bringing this to fruition! Beyond their efforts, I deeply appreciate Uma and Chaitanya s commitment to updating Intel s driver implementation to align with the freshest version of the KMS Color API. The collaborative spirit of the AMD and Intel developers in sharing their color pipeline work upstream is invaluable. We re now gaining a much clearer picture of the color capabilities embedded in modern display hardware, all thanks to their hard work, comprehensive documentation, and engaging discussions. Finally, thanks all the userspace developers, color science experts, and kernel developers from various vendors who actively participate in the upstream discussions, meetings, workshops, each iteration of this API and the crucial code review process. I m happy to be part of the final stages of this long kernel journey, but I know that when it comes to colors, one step is completed for new challenges to be unlocked. Looking forward to meeting you in this year Linux Display Next hackfest, organized by AMD in Toronto, to further discuss HDR, advanced color management, and other display trends.

17 May 2025

Andrew Cater: 20250517 - Debian point release - Bookworm 12.11 today

In Cottenham with Andy and the usual suspects. The point release update files are already on the servers - anyone can do an "apt-get update ; apt-get dist-upgrade" and update any running machine. This machine has just been upgraded and "just worked".

Here to do release testing for the images that we will end up publishing later in the day.Expecting one more of us to turn up a bit later. Team will be working on IRC on #debian-cd


16 May 2025

Freexian Collaborators: Monthly report about Debian Long Term Support, April 2025 (by Roberto C. S nchez)

Like each month, have a look at the work funded by Freexian s Debian LTS offering.

Debian LTS contributors In April, 22 contributors have been paid to work on Debian LTS, their reports are available:
  • Adrian Bunk did 56.25h (out of 56.25h assigned).
  • Andreas Henriksson did 15.0h (out of 20.0h assigned), thus carrying over 5.0h to the next month.
  • Andrej Shadura did 10.0h (out of 6.0h assigned and 4.0h from previous period).
  • Bastien Roucari s did 31.5h (out of 31.5h assigned).
  • Ben Hutchings did 8.0h (out of 0.0h assigned and 12.0h from previous period), thus carrying over 4.0h to the next month.
  • Carlos Henrique Lima Melara did 11.0h (out of 12.0h assigned), thus carrying over 1.0h to the next month.
  • Chris Lamb did 18.0h (out of 18.0h assigned).
  • Daniel Leidert did 26.0h (out of 26.0h assigned).
  • Emilio Pozuelo Monfort did 30.0h (out of 39.25h assigned and 0.25h from previous period), thus carrying over 9.5h to the next month.
  • Guilhem Moulin did 8.5h (out of 3.25h assigned and 11.75h from previous period), thus carrying over 6.5h to the next month.
  • Jochen Sprickerhof did 12.5h (out of 20.75h assigned and 9.25h from previous period), thus carrying over 17.5h to the next month.
  • Lee Garrett did 26.25h (out of 7.75h assigned and 31.75h from previous period), thus carrying over 13.25h to the next month.
  • Lucas Kanashiro did 50.0h (out of 0.0h assigned and 52.0h from previous period), thus carrying over 2.0h to the next month.
  • Markus Koschany did 39.5h (out of 39.5h assigned).
  • Roberto C. S nchez did 9.0h (out of 0.0h assigned and 12.0h from previous period), thus carrying over 3.0h to the next month.
  • Santiago Ruano Rinc n did 12.5h (out of 7.5h assigned and 7.5h from previous period), thus carrying over 2.5h to the next month.
  • Sean Whitton did 7.0h (out of 7.0h assigned).
  • Stefano Rivera did 0.5h (out of 0.0h assigned and 10.0h from previous period), thus carrying over 9.5h to the next month.
  • Sylvain Beucler did 39.5h (out of 39.25h assigned and 0.25h from previous period).
  • Thorsten Alteholz did 15.0h (out of 15.0h assigned).
  • Tobias Frost did 12.0h (out of 7.75h assigned and 4.25h from previous period).
  • Utkarsh Gupta did 2.0h (out of 2.0h assigned).

Evolution of the situation In April, we released 46 DLAs.
  • Notable security updates:
    • jetty9, prepared by Markus Koschany, fixes an information disclosure and potential remote code execution vulnerability
    • zabbix, prepared by Tobias Frost, fixes several vulnerabilities, encompassing denial of service, information disclosure or remote code inclusion
    • glibc, prepared by Sean Whitton, fixes a buffer overflow vulnerability
  • Notable non-security updates:
    • tzdata, prepared by Emilio Pozuelo Monfort, brings the latest timezone database release
    • php-horde-editor and php-horde-imp, prepared by Sylvain Beucler, have been updated to switch from CKEditor v3, which is EOL, to CKEditor v4; this builds upon work done last month by Sylvain and Bastien for the complete removal of ckeditor3
    • distro-info-data, prepared by Stefano Rivera, adds information concerning future Debian and Ubuntu releases
The LTS team continues to welcome the collaboration of maintainers and other interested parties from outside the regular team. In April, we had external updates contributed by: Yadd - lemonldap-ng and Moritz Schlarb - libapache2-mod-auth-openidc A point release of the current stable Debian 12 (codename bookworm ) is planned for mid-May and several LTS contributors have prepared packages for this update, many of them prepared in conjunction with related LTS updates of the same packages:
  • glib2.0, haproxy, imagemagick, poppler, and python-h11, prepared by Adrian Bunk
  • rubygems, prepared by Lucas Kanashiro
  • ruby3.1 (in collaboration with Lucas Kanashiro), twitter-bootstrap3, twitterboot-strap4, wpa, and erlang, prepared by Bastien Roucari s (corresponding updates of twitter-bootstrap3 and twitter-bootstrap4 were also uploaded to Debian unstable)
  • abseil, prepared by Tobias Frost (a corresponding update was also uploaded to Debian unstable)
  • vips, prepared by Guilhem Moulin
Additional updates of ruby3.3 and rubygems were prepared for Debian unstable by Lucas Kanashiro. And finally, a highlight of our continued commitment to enhancing long term support efforts in upstream projects. Freexian, as the primary entity behind the management and execution of the LTS project, has partnered with Invisible Things Lab to extend the upstream security support of Xen 4.17, which is shipped in Debian 12 bookworm (the current stable release). This partnership will result in significantly improved lifecycle support for users of Xen on bookworm, and members of the LTS team will play a part in this endeavour. The Freexian announcement has additional details.

Thanks to our sponsors Sponsors that joined recently are in bold.

14 May 2025

Jonathan McDowell: Local Voice Assistant Step 3: A Detour into Tensorflow

To build our local voice satellite on a Debian system rather than using the ATOM Echo device we need something that can handle the wake word component; the piece that means we only send audio to the Home Assistant server for processing by whisper.cpp when we ve detected someone is trying to talk to us. openWakeWord seems to be one of the better ways to do this, and is well supported. However. It relies on TensorFlow Lite (now LiteRT) which is a complicated mess of machine learning code. tflite-runtime is available from PyPI, but that s prebuilt and we re trying to avoid that. Despite, on initial impressions, it looking quite complicated to deal with building TensorFlow - Bazel is an immediate warning - it turns out to be incredibly simple to build your own .deb:

$ wget -O tensorflow-v2.15.1.tar.gz https://github.com/tensorflow/tensorflow/archive/refs/tags/v2.15.1.tar.gz
 
$ tar -axf tensorflow-v2.15.1.tar.gz
$ cd tensorflow-2.15.1/
$ BUILD_NUM_JOBS=$(nproc) BUILD_DEB=y tensorflow/lite/tools/pip_package/build_pip_package_with_cmake.sh
 
$ find . -name *.deb
./tensorflow/lite/tools/pip_package/gen/tflite_pip/python3-tflite-runtime-dbgsym_2.15.1-1_amd64.deb
./tensorflow/lite/tools/pip_package/gen/tflite_pip/python3-tflite-runtime_2.15.1-1_amd64.deb
This is hiding an awful lot of complexity, however. In particular the number of 3rd party projects that are being downloaded in the background (and compiled, to be fair, rather than using binary artefacts). We can build the main C++ wrapper .so directly with cmake, allowing us to investigate a bit more:
mkdir tf-build
cd tf-build/
cmake \
    -DCMAKE_C_FLAGS="-I/usr/include/python3.11" \
    -DCMAKE_CXX_FLAGS="-I/usr/include/python3.11" \
    ../tensorflow-2.15.1/tensorflow/lite/
cmake --build . -t _pywrap_tensorflow_interpreter_wrapper
 
[100%] Built target _pywrap_tensorflow_interpreter_wrapper
$ ldd _pywrap_tensorflow_interpreter_wrapper.so
    linux-vdso.so.1 (0x00007ffec9588000)
    libm.so.6 => /lib/x86_64-linux-gnu/libm.so.6 (0x00007f22d00d0000)
    libstdc++.so.6 => /lib/x86_64-linux-gnu/libstdc++.so.6 (0x00007f22cf600000)
    libgcc_s.so.1 => /lib/x86_64-linux-gnu/libgcc_s.so.1 (0x00007f22d00b0000)
    libc.so.6 => /lib/x86_64-linux-gnu/libc.so.6 (0x00007f22cf81f000)
    /lib64/ld-linux-x86-64.so.2 (0x00007f22d01d1000)
Looking at the output we can see that pthreadpool, FXdiv, FP16 + PSimd are all downloaded, and seem to have ways to point to a local copy. That seems positive. However, there are even more hidden dependencies, which we can see if we look in the _deps/ subdirectory of the build tree. These don t appear to be as easy to override, and not all of them have packages already in Debian. First, the ones that seem to be available: abseil-cpp, cpuinfo, eigen, farmhash, flatbuffers, gemmlowp, ruy + xnnpack (lots of credit to the Debian Deep Learning Team for these, and in particular Mo Zhou) Dependencies I couldn t see existing packages for are: OouraFFT, ml_dtypes & neon2sse. At this point I just used the package I built with the initial steps above. I live in hope someone will eventually package this properly for Debian, or that I ll find the time to try and help out, but that s not going to be today. I wish upstream developers made it easier to use system copies of their library dependencies. I wish library developers made it easier to build and install system copies of their work. pkgconf is not new tech these days (pkg-config appears to date back to 2000), and has decent support in CMake. I get that there can be issues with incompatibilities even in minor releases, or awkwardness in doing builds of multiple connected projects, but at least give me the option to do so.

13 May 2025

Ben Hutchings: Report for Debian BSP near Leuven in April 2025

On 26th and 27th April we held a Debian bug-squashing party near Leuven, Belgium. Several longstanding and new Debian contributors gathered to work through some of the highest priority bugs affecting the upcoming release of Debian 13 trixie . We were hosted by the Familia community centre in Tildonk. As this venue currently does not have an Internet connection, we brought a mobile hotspot and a local Debian mirror. In attendance were: The new contributors were variously using Arch, Fedora, and Ubuntu, and the DDs spent some some time setting them up with Debian dvelopment environments. The bugs we worked on included:
12 May 2025

Reproducible Builds: Reproducible Builds in April 2025

Welcome to our fourth report from the Reproducible Builds project in 2025. These monthly reports outline what we ve been up to over the past month, and highlight items of news from elsewhere in the increasingly-important area of software supply-chain security. Lastly, if you are interested in contributing to the Reproducible Builds project, please visit our Contribute page on our website. Table of contents:
  1. reproduce.debian.net
  2. Fifty Years of Open Source Software Supply Chain Security
  3. 4th CHAINS Software Supply Chain Workshop
  4. Mailing list updates
  5. Canonicalization for Unreproducible Builds in Java
  6. OSS Rebuild adds new TUI features
  7. Distribution roundup
  8. diffoscope & strip-nondeterminism
  9. Website updates
  10. Reproducibility testing framework
  11. Upstream patches

reproduce.debian.net The last few months have seen the introduction, development and deployment of reproduce.debian.net. In technical terms, this is an instance of rebuilderd, our server designed monitor the official package repositories of Linux distributions and attempt to reproduce the observed results there. This month, however, we are pleased to announce that reproduce.debian.net now tests all the Debian trixie architectures except s390x and mips64el. The ppc64el architecture was added through the generous support of Oregon State University Open Source Laboratory (OSUOSL), and we can support the armel architecture thanks to CodeThink.

Fifty Years of Open Source Software Supply Chain Security Russ Cox has published a must-read article in ACM Queue on Fifty Years of Open Source Software Supply Chain Security. Subtitled, For decades, software reuse was only a lofty goal. Now it s very real. , Russ article goes on to outline the history and original goals of software supply-chain security in the US military in the early 1970s, all the way to the XZ Utils backdoor of 2024. Through that lens, Russ explores the problem and how it has changed, and hasn t changed, over time. He concludes as follows:
We are all struggling with a massive shift that has happened in the past 10 or 20 years in the software industry. For decades, software reuse was only a lofty goal. Now it s very real. Modern programming environments such as Go, Node and Rust have made it trivial to reuse work by others, but our instincts about responsible behaviors have not yet adapted to this new reality. We all have more work to do.

4th CHAINS Software Supply Chain Workshop Convened as part of the CHAINS research project at the KTH Royal Institute of Technology in Stockholm, Sweden, the 4th CHAINS Software Supply Chain Workshop occurred during April. During the workshop, there were a number of relevant workshops, including: The full listing of the agenda is available on the workshop s website.

Mailing list updates On our mailing list this month:
  • Luca DiMaio of Chainguard posted to the list reporting that they had successfully implemented reproducible filesystem images with both ext4 and an EFI system partition. They go on to list the various methods, and the thread generated at least fifteen replies.
  • David Wheeler announced that the OpenSSF is building a glossary of sorts in order that they consistently use the same meaning for the same term and, moreover, that they have drafted a definition for reproducible build . The thread generated a significant number of replies on the definition, leading to a potential update to the Reproducible Build s own definition.
  • Lastly, kpcyrd posted to the list with a timely reminder and update on their repro-env tool. As first reported in our July 2023 report, kpcyrd mentions that:
    My initial interest in reproducible builds was how do I distribute pre-compiled binaries on GitHub without people raising security concerns about them . I ve cycled back to this original problem about 5 years later and built a tool that is meant to address this. [ ]

Canonicalization for Unreproducible Builds in Java Aman Sharma, Benoit Baudry and Martin Monperrus have published a new scholarly study related to reproducible builds within Java. Titled Canonicalization for Unreproducible Builds in Java, the article s abstract is as follows:
[ ] Achieving reproducibility at scale remains difficult, especially in Java, due to a range of non-deterministic factors and caveats in the build process. In this work, we focus on reproducibility in Java-based software, archetypal of enterprise applications. We introduce a conceptual framework for reproducible builds, we analyze a large dataset from Reproducible Central and we develop a novel taxonomy of six root causes of unreproducibility. We study actionable mitigations: artifact and bytecode canonicalization using OSS-Rebuild and jNorm respectively. Finally, we present Chains-Rebuild, a tool that raises reproducibility success from 9.48% to 26.89% on 12,283 unreproducible artifacts. To sum up, our contributions are the first large-scale taxonomy of build unreproducibility causes in Java, a publicly available dataset of unreproducible builds, and Chains-Rebuild, a canonicalization tool for mitigating unreproducible builds in Java.
A full PDF of their article is available from arXiv.

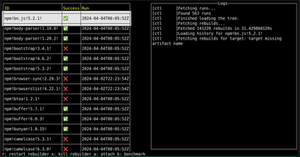
OSS Rebuild adds new TUI features OSS Rebuild aims to automate rebuilding upstream language packages (e.g. from PyPI, crates.io and npm registries) and publish signed attestations and build definitions for public use. OSS Rebuild ships a text-based user interface (TUI) for viewing, launching, and debugging rebuilds. While previously requiring ownership of a full instance of OSS Rebuild s hosted infrastructure, the TUI now supports a fully local mode of build execution and artifact storage. Thanks to Giacomo Benedetti for his usage feedback and work to extend the local-only development toolkit. Another feature added to the TUI was an experimental chatbot integration that provides interactive feedback on rebuild failure root causes and suggests fixes.

Distribution roundup In Debian this month:
  • Roland Clobus posted another status report on reproducible ISO images on our mailing list this month, with the summary that all live images build reproducibly from the online Debian archive .
  • Debian developer Simon Josefsson published another two reproducibility-related blog posts this month, the first on the topic of Verified Reproducible Tarballs. Simon sardonically challenges the reader as follows: Do you want a supply-chain challenge for the Easter weekend? Pick some well-known software and try to re-create the official release tarballs from the corresponding Git checkout. Is anyone able to reproduce anything these days? After that, they also published a blog post on Building Debian in a GitLab Pipeline using their multi-stage rebuild approach.
  • Roland also posted to our mailing list to highlight that there is now another tool in Debian that generates reproducible output, equivs . This is a tool to create trivial Debian packages that might Depend on other packages. As Roland writes, building the [equivs] package has been reproducible for a while, [but] now the output of the [tool] has become reproducible as well .
  • Lastly, 9 reviews of Debian packages were added, 10 were updated and 10 were removed this month adding to our extensive knowledge about identified issues.
The IzzyOnDroid Android APK repository made more progress in April. Thanks to funding by NLnet and Mobifree, the project was also to put more time into their tooling. For instance, developers can now easily run their own verification builder in less than 5 minutes . This currently supports Debian-based systems, but support for RPM-based systems is incoming.
  • The rbuilder_setup tool can now setup the entire framework within less than five minutes. The process is configurable, too, so everything from just the basics to verify builds up to a fully-fledged RB environment is also possible.
  • This tool works on Debian, RedHat and Arch Linux, as well as their derivates. The project has received successful reports from Debian, Ubuntu, Fedora and some Arch Linux derivates so far.
  • Documentation on how to work with reproducible builds (making apps reproducible, debugging unreproducible packages, etc) is available in the project s wiki page.
  • Future work is also in the pipeline, including documentation, guidelines and helpers for debugging.
NixOS defined an Outreachy project for improving build reproducibility. In the application phase, NixOS saw some strong candidates providing contributions, both on the NixOS side and upstream: guider-le-ecit analyzed a libpinyin issue. Tessy James fixed an issue in arandr and helped analyze one in libvlc that led to a proposed upstream fix. Finally, 3pleX fixed an issue which was accepted in upstream kitty, one in upstream maturin, one in upstream python-sip and one in the Nix packaging of python-libbytesize. Sadly, the funding for this internship fell through, so NixOS were forced to abandon their search. Lastly, in openSUSE news, Bernhard M. Wiedemann posted another monthly update for their work there.

diffoscope & strip-nondeterminism diffoscope is our in-depth and content-aware diff utility that can locate and diagnose reproducibility issues. This month, Chris Lamb made the following changes, including preparing and uploading a number of versions to Debian:
  • Use the --walk argument over the potentially dangerous alternative --scan when calling out to zipdetails(1). [ ]
  • Correct a longstanding issue where many >-based version tests used in conditional fixtures were broken. This was used to ensure that specific tests were only run when the version on the system was newer than a particular number. Thanks to Colin Watson for the report (Debian bug #1102658) [ ]
  • Address a long-hidden issue in the test_versions testsuite as well, where we weren t actually testing the greater-than comparisons mentioned above, as it was masked by the tests for equality. [ ]
  • Update copyright years. [ ]
In strip-nondeterminism, however, Holger Levsen updated the Continuous Integration (CI) configuration in order to use the standard Debian pipelines via debian/salsa-ci.yml instead of using .gitlab-ci.yml. [ ]

Website updates Once again, there were a number of improvements made to our website this month including:
  • Aman Sharma added OSS-Rebuild s stabilize tool to the Tools page. [ ][ ]
  • Chris Lamb added a configure.ac (GNU Autotools) example for using SOURCE_DATE_EPOCH. [ ]. Chris also updated the SOURCE_DATE_EPOCH snippet and move the archive metadata to a more suitable location. [ ]
  • Denis Carikli added GNU Boot to our ever-evolving Projects page.

Reproducibility testing framework The Reproducible Builds project operates a comprehensive testing framework running primarily at tests.reproducible-builds.org in order to check packages and other artifacts for reproducibility. In April, a number of changes were made by Holger Levsen, including:
  • reproduce.debian.net-related:
    • Add armel.reproduce.debian.net to support the armel architecture. [ ][ ]
    • Add a new ARM node, codethink05. [ ][ ]
    • Add ppc64el.reproduce.debian.net to support testing of the ppc64el architecture. [ ][ ][ ]
    • Improve the reproduce.debian.net front page. [ ][ ]
    • Make various changes to the ppc64el nodes. [ ][ ]9[ ][ ]
    • Make various changes to the arm64 and armhf nodes. [ ][ ][ ][ ]
    • Various changes related to the rebuilderd-worker entry point. [ ][ ][ ]
    • Create and deploy a pkgsync script. [ ][ ][ ][ ][ ][ ][ ][ ]
    • Fix the monitoring of the riscv64 architecture. [ ][ ]
    • Make a number of changes related to starting the rebuilderd service. [ ][ ][ ][ ]
  • Backup-related:
    • Backup the rebuilder databases every week. [ ][ ][ ][ ]
    • Improve the node health checks. [ ][ ]
  • Misc:
    • Re-use existing connections to the SSH proxy node on the riscv64 nodes. [ ][ ]
    • Node maintenance. [ ][ ][ ]
In addition:
  • Jochen Sprickerhof fixed the risvc64 host names [ ] and requested access to all the rebuilderd nodes [ ].
  • Mattia Rizzolo updated the self-serve rebuild scheduling tool, replacing the deprecated SSO -style authentication with OpenIDC which authenticates against salsa.debian.org. [ ][ ][ ]
  • Roland Clobus updated the configuration for the osuosl3 node to designate 4 workers for bigger builds. [ ]

Upstream patches The Reproducible Builds project detects, dissects and attempts to fix as many currently-unreproducible packages as possible. We endeavour to send all of our patches upstream where appropriate. This month, we wrote a large number of such patches, including:

Finally, if you are interested in contributing to the Reproducible Builds project, please visit our Contribute page on our website. However, you can get in touch with us via:

Sergio Talens-Oliag: Playing with vCluster

After my previous posts related to Argo CD (one about argocd-autopilot and another with some usage examples) I started to look into Kluctl (I also plan to review Flux, but I m more interested on the kluctl approach right now). While reading an entry on the project blog about Cluster API somehow I ended up on the vCluster site and decided to give it a try, as it can be a valid way of providing developers with on demand clusters for debugging or run CI/CD tests before deploying things on common clusters or even to have multiple debugging virtual clusters on a local machine with only one of them running at any given time. On this post I will deploy a vcluster using the k3d_argocd kubernetes cluster (the one we created on the posts about argocd) as the host and will show how to:
  • use its ingress (in our case traefik) to access the API of the virtual one (removes the need of having to use the vcluster connect command to access it with kubectl),
  • publish the ingress objects deployed on the virtual cluster on the host ingress, and
  • use the sealed-secrets of the host cluster to manage the virtual cluster secrets.

Creating the virtual cluster

Installing the vcluster applicationTo create the virtual clusters we need the vcluster command, we can install it with arkade:
  arkade get vcluster

The vcluster.yaml fileTo create the cluster we are going to use the following vcluster.yaml file (you can find the documentation about all its options here):
controlPlane:
  proxy:
    # Extra hostnames to sign the vCluster proxy certificate for
    extraSANs:
    - my-vcluster-api.lo.mixinet.net
exportKubeConfig:
  context: my-vcluster_k3d-argocd
  server: https://my-vcluster-api.lo.mixinet.net:8443
  secret:
    name: my-vcluster-kubeconfig
sync:
  toHost:
    ingresses:
      enabled: true
    serviceAccounts:
      enabled: true
  fromHost:
    ingressClasses:
      enabled: true
    nodes:
      enabled: true
      clearImageStatus: true
    secrets:
      enabled: true
      mappings:
        byName:
          # sync all Secrets from the 'my-vcluster-default' namespace to the
          # virtual "default" namespace.
          "my-vcluster-default/*": "default/*"
          # We could add other namespace mappings if needed, i.e.:
          # "my-vcluster-kube-system/*": "kube-system/*"
On the controlPlane section we ve added the proxy.extraSANs entry to add an extra host name to make sure it is added to the cluster certificates if we use it from an ingress. The exportKubeConfig section creates a kubeconfig secret on the virtual cluster namespace using the provided host name; the secret can be used by GitOps tools or we can dump it to a file to connect from our machine. On the sync section we enable the synchronization of Ingress objects and ServiceAccounts from the virtual to the host cluster:
  • We copy the ingress definitions to use the ingress server that runs on the host to make them work from the outside world.
  • The service account synchronization is not really needed, but we enable it because if we test this configuration with EKS it would be useful if we use IAM roles for the service accounts.
On the opposite direction (from the host to the virtual cluster) we synchronize:
  • The IngressClass objects, to be able to use the host ingress server(s).
  • The Nodes (we are not using the info right now, but it could be interesting if we want to have the real information of the nodes running pods of the virtual cluster).
  • The Secrets from the my-vcluster-default host namespace to the default of the virtual cluster; that synchronization allows us to deploy SealedSecrets on the host that generate secrets that are copied automatically to the virtual one. Initially we only copy secrets for one namespace but if the virtual cluster needs others we can add namespaces on the host and their mappings to the virtual one on the vcluster.yaml file.

Creating the virtual clusterTo create the virtual cluster we run the following command:
vcluster create my-vcluster --namespace my-vcluster --upgrade --connect=false \
  --values vcluster.yaml
It creates the virtual cluster on the my-vcluster namespace using the vcluster.yaml file shown before without connecting to the cluster from our local machine (if we don t pass that option the command adds an entry on our kubeconfig and launches a proxy to connect to the virtual cluster that we don t plan to use).

Adding an ingress TCP route to connect to the vcluster apiAs explained before, we need to create an IngressTcpRoute object to be able to connect to the vcluster API, we use the following definition:
apiVersion: traefik.containo.us/v1alpha1
kind: IngressRouteTCP
metadata:
  name: my-vcluster-api
  namespace: my-vcluster
spec:
  entryPoints:
    - websecure
  routes:
    - match: HostSNI( my-vcluster-api.lo.mixinet.net )
      services:
        - name: my-vcluster
          port: 443
  tls:
    passthrough: true
Once we apply those changes the cluster API will be available on the https://my-cluster-api.lo.mixinet.net:8443 URL using its own self signed certificate (we have enabled TLS passthrough) that includes the hostname we use (we adjusted it on the vcluster.yaml file, as explained before).

Getting the kubeconfig for the vclusterOnce the vcluster is running we will have its kubeconfig available on the my-vcluster-kubeconfig secret on its namespace on the host cluster. To dump it to the ~/.kube/my-vcluster-config we can do the following:
  kubectl get -n my-vcluster secret/my-vcluster-kubeconfig \
    --template=" .data.config "   base64 -d > ~/.kube/my-vcluster-config
Once available we can define the vkubectl alias to adjust the KUBECONFIG variable to access it:
alias vkubectl="KUBECONFIG=~/.kube/my-vcluster-config kubectl"
Or we can merge the configuration with the one on the KUBECONFIG variable and use kubectx or a similar tool to change the context (for our vcluster the context will be my-vcluster_k3d-argocd). If the KUBECONFIG variable is defined and only has the PATH to a single file the merge can be done running the following:
KUBECONFIG="$KUBECONFIG:~/.kube/my-vcluster-config" kubectl config view \
  --flatten >"$KUBECONFIG.new"
mv "$KUBECONFIG.new" "$KUBECONFIG"
On the rest of this post we will use the vkubectl alias when connecting to the virtual cluster, i.e. to check that it works we can run the cluster-info subcommand:
  vkubectl cluster-info
Kubernetes control plane is running at https://my-vcluster-api.lo.mixinet.net:8443
CoreDNS is running at https://my-vcluster-api.lo.mixinet.net:8443/api/v1/namespaces/kube-system/services/kube-dns:dns/proxy
To further debug and diagnose cluster problems, use 'kubectl cluster-info dump'.

Installing the dummyhttpd applicationTo test the virtual cluster we are going to install the dummyhttpd application using the following kustomization.yaml file:
apiVersion: kustomize.config.k8s.io/v1beta1
kind: Kustomization
resources:
  - https://forgejo.mixinet.net/blogops/argocd-applications.git//dummyhttp/?ref=dummyhttp-v1.0.0
# Add the config map
configMapGenerator:
  - name: dummyhttp-configmap
    literals:
      - CM_VAR="Vcluster Test Value"
    behavior: create
    options:
      disableNameSuffixHash: true
patches:
  # Change the ingress host name
  - target:
      kind: Ingress
      name: dummyhttp
    patch:  -
      - op: replace
        path: /spec/rules/0/host
        value: vcluster-dummyhttp.lo.mixinet.net
  # Add reloader annotations -- it will only work if we install reloader on the
  # virtual cluster, as the one on the host cluster doesn't see the vcluster
  # deployment objects
  - target:
      kind: Deployment
      name: dummyhttp
    patch:  -
      - op: add
        path: /metadata/annotations
        value:
          reloader.stakater.com/auto: "true"
          reloader.stakater.com/rollout-strategy: "restart"
It is quite similar to the one we used on the Argo CD examples but uses a different DNS entry; to deploy it we run kustomize and vkubectl:
  kustomize build .   vkubectl apply -f -
configmap/dummyhttp-configmap created
service/dummyhttp created
deployment.apps/dummyhttp created
ingress.networking.k8s.io/dummyhttp created
We can check that everything worked using curl:
  curl -s https://vcluster-dummyhttp.lo.mixinet.net:8443/   jq -cM .
 "c": "Vcluster Test Value","s": "" 
The objects available on the vcluster now are:
  vkubectl get all,configmap,ingress
NAME                             READY   STATUS    RESTARTS   AGE
pod/dummyhttp-55569589bc-9zl7t   1/1     Running   0          24s
NAME                 TYPE        CLUSTER-IP     EXTERNAL-IP   PORT(S)   AGE
service/dummyhttp    ClusterIP   10.43.51.39    <none>        80/TCP    24s
service/kubernetes   ClusterIP   10.43.153.12   <none>        443/TCP   14m

NAME                        READY   UP-TO-DATE   AVAILABLE   AGE
deployment.apps/dummyhttp   1/1     1            1           24s
NAME                                   DESIRED   CURRENT   READY   AGE
replicaset.apps/dummyhttp-55569589bc   1         1         1       24s
NAME                            DATA   AGE
configmap/dummyhttp-configmap   1      24s
configmap/kube-root-ca.crt      1      14m
NAME                                CLASS   HOSTS                             ADDRESS                          PORTS AGE
ingress.networking.k8s.io/dummyhttp traefik vcluster-dummyhttp.lo.mixinet.net 172.20.0.2,172.20.0.3,172.20.0.4 80    24s
While we have the following ones on the my-vcluster namespace of the host cluster:
  kubectl get all,configmap,ingress -n my-vcluster
NAME                                                      READY   STATUS    RESTARTS   AGE
pod/coredns-bbb5b66cc-snwpn-x-kube-system-x-my-vcluster   1/1     Running   0          18m
pod/dummyhttp-55569589bc-9zl7t-x-default-x-my-vcluster    1/1     Running   0          45s
pod/my-vcluster-0                                         1/1     Running   0          19m
NAME                                           TYPE        CLUSTER-IP      EXTERNAL-IP   PORT(S)                  AGE
service/dummyhttp-x-default-x-my-vcluster      ClusterIP   10.43.51.39     <none>        80/TCP                   45s
service/kube-dns-x-kube-system-x-my-vcluster   ClusterIP   10.43.91.198    <none>        53/UDP,53/TCP,9153/TCP   18m
service/my-vcluster                            ClusterIP   10.43.153.12    <none>        443/TCP,10250/TCP        19m
service/my-vcluster-headless                   ClusterIP   None            <none>        443/TCP                  19m
service/my-vcluster-node-k3d-argocd-agent-1    ClusterIP   10.43.189.188   <none>        10250/TCP                18m

NAME                           READY   AGE
statefulset.apps/my-vcluster   1/1     19m
NAME                                                     DATA   AGE
configmap/coredns-x-kube-system-x-my-vcluster            2      18m
configmap/dummyhttp-configmap-x-default-x-my-vcluster    1      45s
configmap/kube-root-ca.crt                               1      19m
configmap/kube-root-ca.crt-x-default-x-my-vcluster       1      11m
configmap/kube-root-ca.crt-x-kube-system-x-my-vcluster   1      18m
configmap/vc-coredns-my-vcluster                         1      19m
NAME                                                        CLASS   HOSTS                             ADDRESS                          PORTS AGE
ingress.networking.k8s.io/dummyhttp-x-default-x-my-vcluster traefik vcluster-dummyhttp.lo.mixinet.net 172.20.0.2,172.20.0.3,172.20.0.4 80    45s
As shown, we have copies of the Service, Pod, Configmap and Ingress objects, but there is no copy of the Deployment or ReplicaSet.

Creating a sealed secret for dummyhttpdTo use the hosts sealed secrets controller with the virtual cluster we will create the my-vcluster-default namespace and add there the sealed secrets we want to have available as secrets on the default namespace of the virtual cluster:
  kubectl create namespace my-vcluster-default
  echo -n "Vcluster Boo"   kubectl create secret generic "dummyhttp-secret" \
    --namespace "my-vcluster-default" --dry-run=client \
    --from-file=SECRET_VAR=/dev/stdin -o yaml >dummyhttp-secret.yaml
  kubeseal -f dummyhttp-secret.yaml -w dummyhttp-sealed-secret.yaml
  kubectl apply -f dummyhttp-sealed-secret.yaml
  rm -f dummyhttp-secret.yaml dummyhttp-sealed-secret.yaml
After running the previous commands we have the following objects available on the host cluster:
  kubectl get sealedsecrets.bitnami.com,secrets -n my-vcluster-default
NAME                                        STATUS   SYNCED   AGE
sealedsecret.bitnami.com/dummyhttp-secret            True     34s
NAME                      TYPE     DATA   AGE
secret/dummyhttp-secret   Opaque   1      34s
And we can see that the secret is also available on the virtual cluster with the content we expected:
  vkubectl get secrets
NAME               TYPE     DATA   AGE
dummyhttp-secret   Opaque   1      34s
  vkubectl get secret/dummyhttp-secret --template=" .data.SECRET_VAR " \
    base64 -d
Vcluster Boo
But the output of the curl command has not changed because, although we have the reloader controller deployed on the host cluster, it does not see the Deployment object of the virtual one and the pods are not touched:
  curl -s https://vcluster-dummyhttp.lo.mixinet.net:8443/   jq -cM .
 "c": "Vcluster Test Value","s": "" 

Installing the reloader applicationTo make reloader work on the virtual cluster we just need to install it as we did on the host using the following kustomization.yaml file:
apiVersion: kustomize.config.k8s.io/v1beta1
kind: Kustomization
namespace: kube-system
resources:
- github.com/stakater/Reloader/deployments/kubernetes/?ref=v1.4.2
patches:
# Add flags to reload workloads when ConfigMaps or Secrets are created or deleted
- target:
    kind: Deployment
    name: reloader-reloader
  patch:  -
    - op: add
      path: /spec/template/spec/containers/0/args
      value:
        - '--reload-on-create=true'
        - '--reload-on-delete=true'
        - '--reload-strategy=annotations'
We deploy it with kustomize and vkubectl:
  kustomize build .   vkubectl apply -f -
serviceaccount/reloader-reloader created
clusterrole.rbac.authorization.k8s.io/reloader-reloader-role created
clusterrolebinding.rbac.authorization.k8s.io/reloader-reloader-role-binding created
deployment.apps/reloader-reloader created
As the controller was not available when the secret was created the pods linked to the Deployment are not updated, but we can force things removing the secret on the host system; after we do that the secret is re-created from the sealed version and copied to the virtual cluster where the reloader controller updates the pod and the curl command shows the new output:
  kubectl delete -n my-vcluster-default secrets dummyhttp-secret
secret "dummyhttp-secret" deleted
  sleep 2
  vkubectl get pods
NAME                         READY   STATUS        RESTARTS   AGE
dummyhttp-78bf5fb885-fmsvs   1/1     Terminating   0          6m33s
dummyhttp-c68684bbf-nx8f9    1/1     Running       0          6s
  curl -s https://vcluster-dummyhttp.lo.mixinet.net:8443/   jq -cM .
 "c":"Vcluster Test Value","s":"Vcluster Boo" 
If we change the secret on the host systems things get updated pretty quickly now:
  echo -n "New secret"   kubectl create secret generic "dummyhttp-secret" \
    --namespace "my-vcluster-default" --dry-run=client \
    --from-file=SECRET_VAR=/dev/stdin -o yaml >dummyhttp-secret.yaml
  kubeseal -f dummyhttp-secret.yaml -w dummyhttp-sealed-secret.yaml
  kubectl apply -f dummyhttp-sealed-secret.yaml
  rm -f dummyhttp-secret.yaml dummyhttp-sealed-secret.yaml
  curl -s https://vcluster-dummyhttp.lo.mixinet.net:8443/   jq -cM .
 "c":"Vcluster Test Value","s":"New secret" 

Pause and restore the vclusterThe status of pods and statefulsets while the virtual cluster is active can be seen using kubectl:
  kubectl get pods,statefulsets -n my-vcluster
NAME                                                                 READY   STATUS    RESTARTS   AGE
pod/coredns-bbb5b66cc-snwpn-x-kube-system-x-my-vcluster              1/1     Running   0          127m
pod/dummyhttp-587c7855d7-pt9b8-x-default-x-my-vcluster               1/1     Running   0          4m39s
pod/my-vcluster-0                                                    1/1     Running   0          128m
pod/reloader-reloader-7f56c54d75-544gd-x-kube-system-x-my-vcluster   1/1     Running   0          60m
NAME                           READY   AGE
statefulset.apps/my-vcluster   1/1     128m

Pausing the vclusterIf we don t need to use the virtual cluster we can pause it and after a small amount of time all Pods are gone because the statefulSet is scaled down to 0 (note that other resources like volumes are not removed, but all the objects that have to be scheduled and consume CPU cycles are not running, which can translate in a lot of savings when running on clusters from cloud platforms or, in a local cluster like the one we are using, frees resources like CPU and memory that now can be used for other things):
  vcluster pause my-vcluster
11:20:47 info Scale down statefulSet my-vcluster/my-vcluster...
11:20:48 done Successfully paused vcluster my-vcluster/my-vcluster
  kubectl get pods,statefulsets -n my-vcluster
NAME                           READY   AGE
statefulset.apps/my-vcluster   0/0     130m
Now the curl command fails:
  curl -s https://vcluster-dummyhttp.localhost.mixinet.net:8443
404 page not found
Although the ingress is still available (it returns a 404 because there is no pod behind the service):
  kubectl get ingress -n my-vcluster
NAME                                CLASS     HOSTS                               ADDRESS                            PORTS   AGE
dummyhttp-x-default-x-my-vcluster   traefik   vcluster-dummyhttp.lo.mixinet.net   172.20.0.2,172.20.0.3,172.20.0.4   80      120m
In fact, the same problem happens when we try to connect to the vcluster API; the error shown by kubectl is related to the TLS certificate because the 404 page uses the wildcard certificate instead of the self signed one:
  vkubectl get pods
Unable to connect to the server: tls: failed to verify certificate: x509: certificate signed by unknown authority
  curl -s https://my-vcluster-api.lo.mixinet.net:8443/api/v1/
404 page not found
  curl -v -s https://my-vcluster-api.lo.mixinet.net:8443/api/v1/ 2>&1   grep subject
*  subject: CN=lo.mixinet.net
*  subjectAltName: host "my-vcluster-api.lo.mixinet.net" matched cert's "*.lo.mixinet.net"

Resuming the vclusterWhen we want to use the virtual cluster again we just need to use the resume command:
  vcluster resume my-vcluster
12:03:14 done Successfully resumed vcluster my-vcluster in namespace my-vcluster
Once all the pods are running the virtual cluster goes back to its previous state, although all of them were started, of course.

Cleaning upThe virtual cluster can be removed using the delete command:
  vcluster delete my-vcluster
12:09:18 info Delete vcluster my-vcluster...
12:09:18 done Successfully deleted virtual cluster my-vcluster in namespace my-vcluster
12:09:18 done Successfully deleted virtual cluster namespace my-vcluster
12:09:18 info Waiting for virtual cluster to be deleted...
12:09:50 done Virtual Cluster is deleted
That removes everything we used on this post except the sealed secrets and secrets that we put on the my-vcluster-default namespace because it was created by us. If we delete the namespace all the secrets and sealed secrets on it are also removed:
  kubectl delete namespace my-vcluster-default
namespace "my-vcluster-default" deleted

ConclusionsI believe that the use of virtual clusters can be a good option for two of the proposed use cases that I ve encountered in real projects in the past:
  • need of short lived clusters for developers or teams,
  • execution of integration tests from CI pipelines that require a complete cluster (the tests can be run on virtual clusters that are created on demand or paused and resumed when needed).
For both cases things can be set up using the Apache licensed product, although maybe evaluating the vCluster Platform offering could be interesting. In any case when everything is not done inside kubernetes we will also have to check how to manage the external services (i.e. if we use databases or message buses as SaaS instead of deploying them inside our clusters we need to have a way of creating, deleting or pause and resume those services).

Freexian Collaborators: Debian Contributions: DebConf 25 preparations, PyPA tools updates, Removing libcrypt-dev from build-essential and more! (by Anupa Ann Joseph)

Debian Contributions: 2025-04 Contributing to Debian is part of Freexian s mission. This article covers the latest achievements of Freexian and their collaborators. All of this is made possible by organizations subscribing to our Long Term Support contracts and consulting services.

DebConf 25 Preparations, by Stefano Rivera and Santiago Ruano Rinc n DebConf 25 preparations continue. In April, the bursary team reviewed and ranked bursary applications. Santiago Ruano Rinc n examined the current state of the conference s finances, to see if we could allocate any more money to bursaries. Stefano Rivera supported the bursary team s work with infrastructure and advice and added some metrics to assist Santiago s budget review. Santiago was also involved in different parts of the organization, including Content team matters, as reviewing the first of proposals, preparing public information about the new Academic Track; or coordinating different aspects of the Day trip activities and the Conference Dinner.

PyPA tools updates, by Stefano Rivera Around the beginning of the freeze (in retrospect, definitely too late) Stefano looked at updating setuptools in the archive to 78.1.0. This brings support for more comprehensive license expressions (PEP-639), that people are expected to adopt soon upstream. While the reverse-autopkgtests all passed, it all came with some unexpected complications, and turned into a mini-transition. The new setuptools broke shebangs for scripts (pypa/setuptools#4952). It also required a bump of wheel to 0.46 and wheel 0.46 now has a dependency outside the standard library (it de-vendored packaging). This meant it was no longer suitable to distribute a standalone wheel.whl file to seed into new virtualenvs, as virtualenv does by default. The good news here is that setuptools doesn t need wheel any more, it included its own implementation of the bdist_wheel command, in 70.1. But the world hadn t adapted to take advantage of this, yet. Stefano scrambled to get all of these issues resolved upstream and in Debian: We re now at the point where python3-wheel-whl is no longer needed in Debian unstable, and it should migrate to trixie.

Removing libcrypt-dev from build-essential, by Helmut Grohne The crypt function was originally part of glibc, but it got separated to libxcrypt. As a result, libc6-dev now depends on libcrypt-dev. This poses a cycle during architecture cross bootstrap. As the number of packages actually using crypt is relatively small, Helmut proposed removing the dependency. He analyzed an archive rebuild kindly performed by Santiago Vila (not affiliated with Freexian) and estimated the necessary changes. It looks like we may complete this with modifications to less than 300 source packages in the forky cycle. Half of the bugs have been filed at this time. They are tracked with libcrypt-* usertags.

Miscellaneous contributions
  • Carles uploaded a new version of simplemonitor.
  • Carles improved the documentation of salsa-ci-team/pipeline regarding piuparts arguments.
  • Carles closed an FTBFS on gcc-15 on qnetload.
  • Carles worked on Catalan translations using po-debconf-manager: reviewed 57 translations and created their merge requests in salsa, created 59 bug reports for packages that didn t merge in more than 30 days. Followed-up merge requests and comments in bug reports. Managed some translations manually for packages that are not in Salsa.
  • Lucas did some work on the DebConf Content and Bursary teams.
  • Lucas fixed multiple CVEs and bugs involving the upgrade from bookworm to trixie in ruby3.3.
  • Lucas fixed a CVE in valkey in unstable.
  • Stefano updated beautifulsoup4, python-authlib, python-html2text, python-packaging, python-pip, python-soupsieve, and unidecode.
  • Stefano packaged python-dependency-groups, a new vendored library in python-pip.
  • During an afternoon Bug Squashing Party in Montevideo, Santiago uploaded a couple of packages fixing RC bugs #1057226 and #1102487. The latter was a sponsored upload.
  • Thorsten uploaded new upstream versions of brlaser, ptouch-driver and sane-airscan to get the latest upstream bug fixes into Trixie.
  • Rapha l filed an upstream bug on zim for a graphical glitch that he has been experiencing.
  • Colin Watson upgraded openssh to 10.0p1 (also known as 10.0p2), and debugged various follow-up bugs. This included adding riscv64 support to vmdb2 in passing, and enabling native wtmpdb support so that wtmpdb last now reports the correct tty for SSH connections.
  • Colin fixed dput-ng s override option, which had never previously worked.
  • Colin fixed a security bug in debmirror.
  • Colin did his usual routine work on the Python team: 21 packages upgraded to new upstream versions, 8 CVEs fixed, and about 25 release-critical bugs fixed.
  • Helmut filed patches for 21 cross build failures.
  • Helmut uploaded a new version of debvm featuring a new tool debefivm-create to generate EFI-bootable disk images compatible with other tools such as libvirt or VirtualBox. Much of the work was prototyped in earlier months. This generalizes mmdebstrap-autopkgtest-build-qemu.
  • Helmut continued reporting undeclared file conflicts and suggested package removals from unstable.
  • Helmut proposed build profiles for libftdi1 and gnupg2. To deal with recently added dependencies in the architecture cross bootstrap package set.
  • Helmut managed the /usr-move transition. He worked on ensuring that systemd would comply with Debian s policy. Dumat continues to locate problems here and there yielding discussion occasionally. He sent a patch for an upgrade problem in zutils.
  • Anupa worked with the Debian publicity team to publish Micronews and Bits posts.
  • Anupa worked with the DebConf 25 content team to review talk and event proposals for DebConf 25.

11 May 2025

Bits from Debian: Bits from the DPL

Dear Debian community, This is bits from the DPL for April. End of 10 I am sure I was speaking in the interest of the whole project when joining the "End of 10" campaign. Here is what I wrote to the initiators:
Hi Joseph and all drivers of the "End of 10" campaign, On behalf of the entire Debian project, I would like to say that we proudly join your great campaign. We stand with you in promoting Free Software, defending users' freedoms, and protecting our planet by avoiding unnecessary hardware waste. Thank you for leading this important initiative.
Andreas Tille Debian Project Leader
I have some goals I would like to share with you for my second term. Ftpmaster delegation This splits up into tasks that can be done before and after Trixie release. Before Trixie: 1. Reducing Barriers to DFSG Compliance Checks Back in 2002, Debian established a way to distribute cryptographic software in the main archive, whereas such software had previously been restricted to the non-US archive. One result of this arrangement which influences our workflow is that all packages uploaded to the NEW queue must remain on the server that hosts it. This requirement means that members of the ftpmaster team must log in to that specific machine, where they are limited to a restricted set of tools for reviewing uploaded code. This setup may act as a barrier to participation--particularly for contributors who might otherwise assist with reviewing packages for DFSG compliance. I believe it is time to reassess this limitation and work toward removing such hurdles. In October last year, we had some initial contact with SPI's legal counsel, who noted that US regulations around cryptography have been relaxed somewhat in recent years (as of 2021). This suggests it may now be possible to revisit and potentially revise the conditions under which we manage cryptographic software in the NEW queue. I plan to investigate this further. If you have expertise in software or export control law and are interested in helping with this topic, please get in touch with me. The ultimate goal is to make it easier for more people to contribute to ensuring that code in the NEW queue complies with the DFSG. 2. Discussing Alternatives My chances to reach out to other distributions remained limited. However, regarding the processing of new software, I learned that OpenSUSE uses a Git-based workflow that requires five "LGTM" approvals from a group of trusted developers. As far as I know, Fedora follows a similar approach. Inspired by this, a recent community initiative--the Gateway to NEW project--enables peer review of new packages for DFSG compliance before they enter the NEW queue. This effort allows anyone to contribute by reviewing packages and flagging potential issues in advance via Git. I particularly appreciate that the DFSG review is coupled with CI, allowing for both license and technical evaluation. While this process currently results in some duplication of work--since final reviews are still performed by the ftpmaster team--it offers a valuable opportunity to catch issues early and improve the overall quality of uploads. If the community sees long-term value in this approach, it could serve as a basis for evolving our workflows. Integrating it more closely into DAK could streamline the process, and we've recently seen that merge requests reflecting community suggestions can be accepted promptly. For now, I would like to gather opinions about how such initiatives could best complement the current NEW processing, and whether greater consensus on trusted peer review could help reduce the burden on the team doing DFSG compliance checks. Submitting packages for review and automated testing before uploading can improve quality and encourage broader participation in safeguarding Debian's Free Software principles. My explicit thanks go out to the Gateway to NEW team for their valuable and forward-looking contribution to Debian. 3. Documenting Critical Workflows Past ftpmaster trainees have told me that understanding the full set of ftpmaster workflows can be quite difficult. While there is some useful documentation thanks in particular to Sean Whitton for his work on documenting NEW processing rules many other important tasks carried out by the ftpmaster team remain undocumented or only partially so. Comprehensive and accessible documentation would greatly benefit current and future team members, especially those onboarding or assisting in specific workflows. It would also help ensure continuity and transparency in how critical parts of the archive are managed. If such documentation already exists and I have simply overlooked it, I would be happy to be corrected. Otherwise, I believe this is an area where we need to improve significantly. Volunteers with a talent for writing technical documentation are warmly invited to contact me--I'd be happy to help establish connections with ftpmaster team members who are willing to share their knowledge so that it can be written down and preserved. Once Trixie is released (hopefully before DebConf): 4. Split of the Ftpmaster Team into DFSG and Archive Teams As discussed during the "Meet the ftpteam" BoF at DebConf24, I would like to propose a structural refinement of the current Ftpmaster team by introducing two different delegated teams:
  1. DFSG Team
  2. Archive Team (responsible for DAK maintenance and process tooling, including releases)
(Alternative name suggestions are, of course, welcome.) The primary task of the DFSG team would be the processing of the NEW queue and ensuring that packages comply with the DFSG. The Archive team would focus on maintaining DAK and handling the technical aspects of archive management. I am aware that, in the recent past, the ftpmaster team has decided not to actively seek new members. While I respect the autonomy of each team, the resulting lack of a recruitment pipeline has led to some friction and concern within the wider community, including myself. As Debian Project Leader, it is my responsibility to ensure the long-term sustainability and resilience of our project, which includes fostering an environment where new contributors can join and existing teams remain effective and well-supported. Therefore, even if the current team does not prioritize recruitment, I will actively seek and encourage new contributors for both teams, with the aim of supporting openness and collaboration. This proposal is not intended as criticism of the current team's dedication or achievements--on the contrary, I am grateful for the hard work and commitment shown, often under challenging circumstances. My intention is to help address the structural issues that have made onboarding and specialization difficult and to ensure that both teams are well-supported for the future. I also believe that both teams should regularly inform the Debian community about the policies and procedures they apply. I welcome any suggestions for a more detailed description of the tasks involved, as well as feedback on how best to implement this change in a way that supports collaboration and transparency. My intention with this proposal is to foster a more open and effective working environment, and I am committed to working with all involved to ensure that any changes are made collaboratively and with respect for the important work already being done. I'm aware that the ideas outlined above touch on core parts of how Debian operates and involve responsibilities across multiple teams. These are not small changes, and implementing them will require thoughtful discussion and collaboration. To move this forward, I've registered a dedicated BoF for DebConf. To make the most of that opportunity, I'm looking for volunteers who feel committed to improving our workflows and processes. With your help, we can prepare concrete and sensible proposals in advance--so the limited time of the BoF can be used effectively for decision-making and consensus-building. In short: I need your help to bring these changes to life. From my experience in my last term, I know that when it truly matters, the Debian community comes together--and I trust that spirit will guide us again. Please also note: we had a "Call for volunteers" five years ago, and much of what was written there still holds true today. I've been told that the response back then was overwhelming--but that training such a large number of volunteers didn't scale well. This time, I hope we can find a more sustainable approach: training a few dedicated people first, and then enabling them to pass on their knowledge. This will also be a topic at the DebCamp sprint. Dealing with Dormant Packages Debian was founded on the principle that each piece of software should be maintained by someone with expertise in it--typically a single, responsible maintainer. This model formed the historical foundation of Debian's packaging system and helped establish high standards of quality and accountability. However, as the project has grown and the number of packages has expanded, this model no longer scales well in all areas. Team maintenance has since emerged as a practical complement, allowing multiple contributors to share responsibility and reduce bottlenecks--depending on each team's internal policy. While working on the Bug of the Day initiative, I observed a significant number of packages that have not been updated in a long time. In the case of team-maintained packages, addressing this is often straightforward: team uploads can be made, or the team can be asked whether the package should be removed. We've also identified many packages that would fit well under the umbrella of active teams, such as language teams like Debian Perl and Debian Python, or blends like Debian Games and Debian Multimedia. Often, no one has taken action--not because of disagreement, but simply due to inattention or a lack of initiative. In addition, we've found several packages that probably should be removed entirely. In those cases, we've filed bugs with pre-removal warnings, which can later be escalated to removal requests. When a package is still formally maintained by an individual, but shows signs of neglect (e.g., no uploads for years, unfixed RC bugs, failing autopkgtests), we currently have three main tools:
  1. The MIA process, which handles inactive or unreachable maintainers.
  2. Package Salvaging, which allows contributors to take over maintenance if conditions are met.
  3. Non-Maintainer Uploads (NMUs), which are limited to specific, well-defined fixes (which do not include things like migration to Salsa).
These mechanisms are important and valuable, but they don't always allow us to react swiftly or comprehensively enough. Our tools for identifying packages that are effectively unmaintained are relatively weak, and the thresholds for taking action are often high. The Package Salvage team is currently trialing a process we've provisionally called "Intend to NMU" (ITN). The name is admittedly questionable--some have suggested alternatives like "Intent to Orphan"--and discussion about this is ongoing on debian-devel. The mechanism is intended for situations where packages appear inactive but aren't yet formally orphaned, introducing a clear 21-day notice period before NMUs, similar in spirit to the existing ITS process. The discussion has sparked suggestions for expanding NMU rules. While it is crucial not to undermine the autonomy of maintainers who remain actively involved, we also must not allow a strict interpretation of this autonomy to block needed improvements to obviously neglected packages. To be clear: I do not propose to change the rights of maintainers who are clearly active and invested in their packages. That model has served us well. However, we must also be honest that, in some cases, maintainers stop contributing--quietly and without transition plans. In those situations, we need more agile and scalable procedures to uphold Debian's high standards. To that end, I've registered a BoF session for DebConf25 to discuss potential improvements in how we handle dormant packages. These discussions will be prepared during a sprint at DebCamp, where I hope to work with others on concrete ideas. Among the topics I want to revisit is my proposal from last November on debian-devel, titled "Barriers between packages and other people". While the thread prompted substantial discussion, it understandably didn't lead to consensus. I intend to ensure the various viewpoints are fairly summarised--ideally by someone with a more neutral stance than myself--and, if possible, work toward a formal proposal during the DebCamp sprint to present at the DebConf BoF. My hope is that we can agree on mechanisms that allow us to act more effectively in situations where formerly very active volunteers have, for whatever reason, moved on. That way, we can protect both Debian's quality and its collaborative spirit. Building Sustainable Funding for Debian Debian incurs ongoing expenses to support its infrastructure--particularly hardware maintenance and upgrades--as well as to fund in-person meetings like sprints and mini-DebConfs. These investments are essential to our continued success: they enable productive collaboration and ensure the robustness of the operating system we provide to users and derivative distributions around the world. While DebConf benefits from generous sponsorship, and we regularly receive donated hardware, there is still considerable room to grow our financial base--especially to support less visible but equally critical activities. One key goal is to establish a more constant and predictable stream of income, helping Debian plan ahead and respond more flexibly to emerging needs. This presents an excellent opportunity for contributors who may not be involved in packaging or technical development. Many of us in Debian are engineers first--and fundraising is not something we've been trained to do. But just like technical work, building sustainable funding requires expertise and long-term engagement. If you're someone who's passionate about Free Software and has experience with fundraising, donor outreach, sponsorship acquisition, or nonprofit development strategy, we would deeply value your help. Supporting Debian doesn't have to mean writing code. Helping us build a steady and reliable financial foundation is just as important--and could make a lasting impact. Kind regards Andreas. PS: In April I also planted my 5000th tree and while this is off-topic here I'm proud to share this information with my fellow Debian friends.

10 May 2025

Taavi V n nen: Wikimedia Hackathon Istanbul 2025

It's that time of the year again: the Wikimedia Hackathon 2025 happened last weekend in Istanbul. This year was my third time attending what has quickly become one of my favourite events of the year simply due to the concentration of friends and other like-minded nerds in a single location.1 Valerio, Lucas, me and a shark.
Image by Chlod Alejandro is licensed under CC BY-SA 4.0.
This year I did a short presentation about the MediaWiki packages in Debian (slides), which is something I do but I suspect is fairly obscure to most people in the MediaWiki community. I was hoping to do some work on reproducibility of MediaWiki releases, but other interests (plus lack of people involved in the release process at the hackathon) meant that I didn't end up getting any work done on that (assuming this does not count). Other long-standing projects did end up getting some work done! MusikAnimal and I ended up fixing the Commons deletion notification bot, which had been broken for well over two years at that point (and was at some point in the hackathon plans for last year for both of us). Other projects that I made progress on include supporting multiple types of two-factor devices, and LibraryUpgrader which gained support for rebasing and updating existing patches2. In addition to hacking, the other highlight of these events is the hallway track. Some of the crowd is people who I've seen at previous events and/or interact very frequently with, but there are also significant parts of the community and the Foundation that I don't usually get to interact with outside of these events. (Although it still feels extremely weird to heard from various mostly-WMF people with whom I haven't spoken with before that they've heard various (usually positive) rumours stories about me.) Unfortunately we did not end up having a Cuteness Association meetup this year, but we had an impromptu PGP key signing party which is basically almost as good, right? However, I did continue a tradition from last year: I ended up nominating Chlod, a friend of mine, to receive +2 access to mediawiki/* during the hackathon. The request is due to be closed sometime tomorrow. (Usual disclosure: My travel was funded by the Wikimedia Foundation. Thank you! This is my personal blog and these are my own opinions.) Now that you've read this post, maybe check out posts from others?

  1. Unfortunately you can never have absolutely everyone attending :(
  2. Amir, I still have not forgiven you about this.

9 May 2025

Uwe Kleine-K nig: The Linux kernel's PGP Web of Trust

The Linux kernel's development process makes use of PGP. The most relevant part here is that subsystem maintainers are supposed to use signed tags in their pull requests to Linus Torvalds. As the concept of keyservers is considered broken, Konstantin Ryabitsev maintains a collection of relevant keys in a git repository. As of today (at commit a0bc65fb27f5033beddf9d1ad97d67c353849be2) there are 602 valid keys tracked in that repository. The requirement for a key to be added there is that there must be at least one trust path from Linus Torvalds' key to this key of length at most 5 within that keyring. Occasionally it happens that a key loses its trust paths because someone in these paths replaced their key, or keys expired. Currently this affects 2 keys. However there is a problem on the horizon: GnuPG 2.4.x started to reject third-party key signatures using the SHA-1 hash algorithm. In general that's good, SHA-1 isn't considered secure any more for more than 20 years. This doesn't directly affect the kernel-pgpkeys repo, because the trust path checking doesn't rely on GnuPG trusting the signatures; there is a dedicated tool that parses the keyring contents and currently accepts signatures using SHA-1. Also signatures are not thrown away usually, but there are exceptions: Recently Theodore Ts'o asked to update his certificate. When Konstantin imported the updated certificate GnuPG's "cleaning" was applied which dropped all SHA-1 signatures. So Theodore Ts'o's key lost 168 signatures, among them one by Linus Torvalds on his primary UID. That made me wonder what would be the effect on the web of trust if all SHA-1 signatures were dropped. Here are the facts: If you attend Embedded Recipes 2025 next week, there is an opportunity to improve the situation: Together with Ahmad Fatoum I'm organizing a keysigning session. If you want to participate, send your public key to er2025-keysigning@baylibre.com before 2025-05-12 08:00 UTC.

7 May 2025

Jonathan Dowland: procmail versus exim filters

I ve been using Procmail to filter mail for a long time. Reading Antoine s blog post procmail considered harmful, I felt motivated (and shamed) into migrating to something else. Luckily, Enrico's shared a detailed roadmap for moving to Sieve, in particular Dovecot's Sieve implementation (which provides "pipe" and "filter" extensions). My MTA is Exim, and for my first foray into this, I didn't want to change that1. Exim provides two filtering languages for users: an implementation of Sieve, and its own filter language. Requirements A good first step is to look at what I'm using Procmail for:
  1. I invoke external mail filters: processes which read the mail and emit a possibly altered mail (headers added, etc.). In particular, crm114 (which has worked remarkably well for me) to classify mail as spam or not, and dsafilter, to mark up Debian Security Advisories
  2. I file messages into different folders depending on the outcome of the above filters
  3. I drop mail ("killfile") some sender addresses (persistent pests on mailing lists); and mails containing certain hosts in the References header (as an imperfect way of dropping mailing list threads which are replies to someone I've killfiled); and mail encoded in a character set for a language I can't read (Russian, Korean, etc.), and several other simple static rules
  4. I move mailing list mail into folders, semi-automatically (see list filtering)
  5. I strip "tagged" subjects for some mailing lists: i.e., incoming mail has subjects like "[cs-historic-committee] help moving several tons of IBM360", and I don't want the "[cs-historic-committee]" bit.
  6. I file a copy of some messages, the name of which is partly derived from the current calendar year
Exim Filters I want to continue to do (1), which rules out Exim's implementation of Sieve, which does not support invoking external programs. Exim's own filter language has a pipe function that might do what I need, so let's look at how to achieve the above with Exim Filters. autolists Here's an autolist recipe for Debian's mailing lists, in Exim filter language. Contrast with the Procmail in list filtering:
if $header_list-id matches "(debian.*)\.lists\.debian\.org"
then
  save Maildir/l/$1/
  finish
endif
Hands down, the exim filter is nicer (although some of the rules on escape characters in exim filters, not demonstrated here, are byzantine). killfile An ideal chunk of configuration for kill-filing a list of addresses is light on boiler plate, and easy to add more addresses to in the future. This is the best I could come up with:
if foranyaddress "someone@example.org,\
                  another@example.net,\
                  especially-bad.example.com,\
                 "
   ($reply_address contains $thisaddress
    or $header_references contains $thisaddress)
then finish endif
I won't bother sharing the equivalent Procmail but it's pretty comparable: the exim filter is no great improvement. It would be lovely if the list of addresses could be stored elsewhere, such as a simple text file, one line per address, or even a database. Exim's own configuration language (distinct from this filter language) has some nice mechanisms for reading lists of things like addresses from files or databases. Sadly it seems the filter language lacks anything similar. external filters With Procmail, I pass the mail to an external program, and then read the output of that program back, as the new content of the mail, which continues to be filtered: subsequent filter rules inspect the headers to see what the outcome of the filter was (is it spam?) and to decide what to do accordingly. Crucially, we also check the return status of the filter, to handle the case when it fails. With Exim filters, we can use pipe to invoke an external program:
pipe "$home/mail/mailreaver.crm -u $home/mail/"
However, this is not a filter: the mail is sent to the external program, and the exim filter's job is complete. We can't write further filter rules to continue to process the mail: the external program would have to do that; and we have no way of handling errors. Here's Exim's documentation on what happens when the external command fails:
Most non-zero codes are treated by Exim as indicating a failure of the pipe. This is treated as a delivery failure, causing the message to be returned to its sender.
That is definitely not what I want: if the filter broke (even temporarily), Exim would seemingly generate a bounce to the sender address, which could be anything, and I wouldn't have a copy of the message. The documentation goes on to say that some shell return codes (defaulting to 73 and 75) cause Exim to treat it as a temporary error, spool the mail and retry later on. That's a much better behaviour for my use-case. Having said that, on the rare occasions I've broken the filter, the thing which made me notice most quickly was spam hitting my inbox, which my Procmail recipe achieves. removing subject tagging Here, Exim's filter language gets unstuck. There is no way to add or alter headers for a message in a user filter. Exim uses the same filter language for system-wide message filtering, and in that context, it has some extra functions: headers add <string>, headers remove <string>, but (for reasons I don't know) these are not available for user filters. copy mail to archive folder I can't see a way to derive a folder name from the calendar year. next steps Exim Sieve implementation and its filter language are ruled out as Procmail replacements because they can't do at least two of the things I need to do. However, based on Enrico's write-up, it looks like Dovecot's Sieve implementation probably can. I was also recommended maildrop, which I might look at if Dovecot Sieve doesn't pan out.

  1. I should revisit this requirement because I could probably reconfigure exim to run my spam classifier at the system level, obviating the need to do it in a user filter, and also raising the opportunity to do smtp-time rejection based on the outcome

5 May 2025

Sergio Talens-Oliag: Argo CD Usage Examples

As a followup of my post about the use of argocd-autopilot I m going to deploy various applications to the cluster using Argo CD from the same repository we used on the previous post. For our examples we are going to test a solution to the problem we had when we updated a ConfigMap used by the argocd-server (the resource was updated but the application Pod was not because there was no change on the argocd-server deployment); our original fix was to kill the pod manually, but the manual operation is something we want to avoid. The proposed solution to this kind of issues on the helm documentation is to add annotations to the Deployments with values that are a hash of the ConfigMaps or Secrets used by them, this way if a file is updated the annotation is also updated and when the Deployment changes are applied a roll out of the pods is triggered. On this post we will install a couple of controllers and an application to show how we can handle Secrets with argocd and solve the issue with updates on ConfigMaps and Secrets, to do it we will execute the following tasks:
  1. Deploy the Reloader controller to our cluster. It is a tool that watches changes in ConfigMaps and Secrets and does rolling upgrades on the Pods that use them from Deployment, StatefulSet, DaemonSet or DeploymentConfig objects when they are updated (by default we have to add some annotations to the objects to make things work).
  2. Deploy a simple application that can use ConfigMaps and Secrets and test that the Reloader controller does its job when we add or update a ConfigMap.
  3. Install the Sealed Secrets controller to manage secrets inside our cluster, use it to add a secret to our sample application and see that the application is reloaded automatically.

Creating the test project for argocd-autopilotAs we did our installation using argocd-autopilot we will use its structure to manage the applications. The first thing to do is to create a project (we will name it test) as follows:
  argocd-autopilot project create test
INFO cloning git repository: https://forgejo.mixinet.net/blogops/argocd.git
Enumerating objects: 18, done.
Counting objects: 100% (18/18), done.
Compressing objects: 100% (16/16), done.
Total 18 (delta 1), reused 0 (delta 0), pack-reused 0
INFO using revision: "", installation path: "/"
INFO pushing new project manifest to repo
INFO project created: 'test'
Now that the test project is available we will use it on our argocd-autopilot invocations when creating applications.

Installing the reloader controllerTo add the reloader application to the test project as a kustomize application and deploy it on the tools namespace with argocd-autopilot we do the following:
  argocd-autopilot app create reloader \
    --app 'github.com/stakater/Reloader/deployments/kubernetes/?ref=v1.4.2' \
    --project test --type kustomize --dest-namespace tools
INFO cloning git repository: https://forgejo.mixinet.net/blogops/argocd.git
Enumerating objects: 19, done.
Counting objects: 100% (19/19), done.
Compressing objects: 100% (18/18), done.
Total 19 (delta 2), reused 0 (delta 0), pack-reused 0
INFO using revision: "", installation path: "/"
INFO created 'application namespace' file at '/bootstrap/cluster-resources/in-cluster/tools-ns.yaml'
INFO committing changes to gitops repo...
INFO installed application: reloader
That command creates four files on the argocd repository:
  1. One to create the tools namespace:
    bootstrap/cluster-resources/in-cluster/tools-ns.yaml
    apiVersion: v1
    kind: Namespace
    metadata:
      annotations:
        argocd.argoproj.io/sync-options: Prune=false
      creationTimestamp: null
      name: tools
    spec:  
    status:  
  2. Another to include the reloader base application from the upstream repository:
    apps/reloader/base/kustomization.yaml
    apiVersion: kustomize.config.k8s.io/v1beta1
    kind: Kustomization
    resources:
    - github.com/stakater/Reloader/deployments/kubernetes/?ref=v1.4.2
  3. The kustomization.yaml file for the test project (by default it includes the same configuration used on the base definition, but we could make other changes if needed):
    apps/reloader/overlays/test/kustomization.yaml
    apiVersion: kustomize.config.k8s.io/v1beta1
    kind: Kustomization
    namespace: tools
    resources:
    - ../../base
  4. The config.json file used to define the application on argocd for the test project (it points to the folder that includes the previous kustomization.yaml file):
    apps/reloader/overlays/test/config.json
     
      "appName": "reloader",
      "userGivenName": "reloader",
      "destNamespace": "tools",
      "destServer": "https://kubernetes.default.svc",
      "srcPath": "apps/reloader/overlays/test",
      "srcRepoURL": "https://forgejo.mixinet.net/blogops/argocd.git",
      "srcTargetRevision": "",
      "labels": null,
      "annotations": null
     
We can check that the application is working using the argocd command line application:
  argocd app get argocd/test-reloader -o tree
Name:               argocd/test-reloader
Project:            test
Server:             https://kubernetes.default.svc
Namespace:          tools
URL:                https://argocd.lo.mixinet.net:8443/applications/test-reloader
Source:
- Repo:             https://forgejo.mixinet.net/blogops/argocd.git
  Target:
  Path:             apps/reloader/overlays/test
SyncWindow:         Sync Allowed
Sync Policy:        Automated (Prune)
Sync Status:        Synced to  (2893b56)
Health Status:      Healthy
KIND/NAME                                          STATUS  HEALTH   MESSAGE
ClusterRole/reloader-reloader-role                 Synced
ClusterRoleBinding/reloader-reloader-role-binding  Synced
ServiceAccount/reloader-reloader                   Synced           serviceaccount/reloader-reloader created
Deployment/reloader-reloader                       Synced  Healthy  deployment.apps/reloader-reloader created
 ReplicaSet/reloader-reloader-5b6dcc7b6f                  Healthy
   Pod/reloader-reloader-5b6dcc7b6f-vwjcx                 Healthy

Adding flags to the reloader serverThe runtime configuration flags for the reloader server are described on the project README.md file, in our case we want to adjust three values:
  • We want to enable the option to reload a workload when a ConfigMap or Secret is created,
  • We want to enable the option to reload a workload when a ConfigMap or Secret is deleted,
  • We want to use the annotations strategy for reloads, as it is the recommended mode of operation when using argocd.
To pass them we edit the apps/reloader/overlays/test/kustomization.yaml file to patch the pod container template, the text added is the following:
patches:
# Add flags to reload workloads when ConfigMaps or Secrets are created or deleted
- target:
    kind: Deployment
    name: reloader-reloader
  patch:  -
    - op: add
      path: /spec/template/spec/containers/0/args
      value:
        - '--reload-on-create=true'
        - '--reload-on-delete=true'
        - '--reload-strategy=annotations'
After committing and pushing the updated file the system launches the application with the new options.

The dummyhttp applicationTo do a quick test we are going to deploy the dummyhttp web server using an image generated using the following Dockerfile:
# Image to run the dummyhttp application <https://github.com/svenstaro/dummyhttp>
# This arg could be passed by the container build command (used with mirrors)
ARG OCI_REGISTRY_PREFIX
# Latest tested version of alpine
FROM $ OCI_REGISTRY_PREFIX alpine:3.21.3
# Tool versions
ARG DUMMYHTTP_VERS=1.1.1
# Download binary
RUN ARCH="$(apk --print-arch)" && \
  VERS="$DUMMYHTTP_VERS" && \
  URL="https://github.com/svenstaro/dummyhttp/releases/download/v$VERS/dummyhttp-$VERS-$ARCH-unknown-linux-musl" && \
  wget "$URL" -O "/tmp/dummyhttp" && \
  install /tmp/dummyhttp /usr/local/bin && \
  rm -f /tmp/dummyhttp
# Set the entrypoint to /usr/local/bin/dummyhttp
ENTRYPOINT [ "/usr/local/bin/dummyhttp" ]
The kustomize base application is available on a monorepo that contains the following files:
  1. A Deployment definition that uses the previous image but uses /bin/sh -c as its entrypoint (command in the k8s Pod terminology) and passes as its argument a string that runs the eval command to be able to expand environment variables passed to the pod (the definition includes two optional variables, one taken from a ConfigMap and another one from a Secret):
    apiVersion: apps/v1
    kind: Deployment
    metadata:
      name: dummyhttp
      labels:
        app: dummyhttp
    spec:
      selector:
        matchLabels:
          app: dummyhttp
      template:
        metadata:
          labels:
            app: dummyhttp
        spec:
          containers:
          - name: dummyhttp
            image: forgejo.mixinet.net/oci/dummyhttp:1.0.0
            command: [ "/bin/sh", "-c" ]
            args:
            - 'eval dummyhttp -b \" \\\"c\\\": \\\"$CM_VAR\\\", \\\"s\\\": \\\"$SECRET_VAR\\\" \"'
            ports:
            - containerPort: 8080
            env:
            - name: CM_VAR
              valueFrom:
                configMapKeyRef:
                  name: dummyhttp-configmap
                  key: CM_VAR
                  optional: true
            - name: SECRET_VAR
              valueFrom:
                secretKeyRef:
                  name: dummyhttp-secret
                  key: SECRET_VAR
                  optional: true
  2. A Service that publishes the previous Deployment (the only relevant thing to mention is that the web server uses the port 8080 by default):
    apiVersion: v1
    kind: Service
    metadata:
      name: dummyhttp
    spec:
      selector:
        app: dummyhttp
      ports:
      - name: http
        port: 80
        targetPort: 8080
  3. An Ingress definition to allow access to the application from the outside:
    apiVersion: networking.k8s.io/v1
    kind: Ingress
    metadata:
      name: dummyhttp
      annotations:
        traefik.ingress.kubernetes.io/router.tls: "true"
    spec:
      rules:
        - host: dummyhttp.localhost.mixinet.net
          http:
            paths:
              - path: /
                pathType: Prefix
                backend:
                  service:
                    name: dummyhttp
                    port:
                      number: 80
  4. And the kustomization.yaml file that includes the previous files:
    apiVersion: kustomize.config.k8s.io/v1beta1
    kind: Kustomization
    resources:
    - deployment.yaml
    - service.yaml
    - ingress.yaml

Deploying the dummyhttp application from argocdWe could create the dummyhttp application using the argocd-autopilot command as we ve done on the reloader case, but we are going to do it manually to show how simple it is. First we ve created the apps/dummyhttp/base/kustomization.yaml file to include the application from the previous repository:
apiVersion: kustomize.config.k8s.io/v1beta1
kind: Kustomization
resources:
  - https://forgejo.mixinet.net/blogops/argocd-applications.git//dummyhttp/?ref=dummyhttp-v1.0.0
As a second step we create the apps/dummyhttp/overlays/test/kustomization.yaml file to include the previous file:
apiVersion: kustomize.config.k8s.io/v1beta1
kind: Kustomization
resources:
- ../../base
And finally we add the apps/dummyhttp/overlays/test/config.json file to configure the application as the ApplicationSet defined by argocd-autopilot expects:
 
  "appName": "dummyhttp",
  "userGivenName": "dummyhttp",
  "destNamespace": "default",
  "destServer": "https://kubernetes.default.svc",
  "srcPath": "apps/dummyhttp/overlays/test",
  "srcRepoURL": "https://forgejo.mixinet.net/blogops/argocd.git",
  "srcTargetRevision": "",
  "labels": null,
  "annotations": null
 
Once we have the three files we commit and push the changes and argocd deploys the application; we can check that things are working using curl:
  curl -s https://dummyhttp.lo.mixinet.net:8443/   jq -M .
 
  "c": "",
  "s": ""
 

Patching the applicationNow we will add patches to the apps/dummyhttp/overlays/test/kustomization.yaml file:
  • One to add annotations for reloader (one to enable it and another one to set the roll out strategy to restart to avoid touching the deployments, as that can generate issues with argocd).
  • Another to change the ingress hostname (not really needed, but something quite reasonable for a specific project).
The file diff is as follows:
--- a/apps/dummyhttp/overlays/test/kustomization.yaml
+++ b/apps/dummyhttp/overlays/test/kustomization.yaml
@@ -2,3 +2,22 @@ apiVersion: kustomize.config.k8s.io/v1beta1
 kind: Kustomization
 resources:
 - ../../base
+patches:
+# Add reloader annotations
+- target:
+    kind: Deployment
+    name: dummyhttp
+  patch:  -
+    - op: add
+      path: /metadata/annotations
+      value:
+        reloader.stakater.com/auto: "true"
+        reloader.stakater.com/rollout-strategy: "restart"
+# Change the ingress host name
+- target:
+    kind: Ingress
+    name: dummyhttp
+  patch:  -
+    - op: replace
+      path: /spec/rules/0/host
+      value: test-dummyhttp.lo.mixinet.net
After committing and pushing the changes we can use the argocd cli to check the status of the application:
  argocd app get argocd/test-dummyhttp -o tree
Name:               argocd/test-dummyhttp
Project:            test
Server:             https://kubernetes.default.svc
Namespace:          default
URL:                https://argocd.lo.mixinet.net:8443/applications/test-dummyhttp
Source:
- Repo:             https://forgejo.mixinet.net/blogops/argocd.git
  Target:
  Path:             apps/dummyhttp/overlays/test
SyncWindow:         Sync Allowed
Sync Policy:        Automated (Prune)
Sync Status:        Synced to  (fbc6031)
Health Status:      Healthy
KIND/NAME                           STATUS  HEALTH   MESSAGE
Deployment/dummyhttp                Synced  Healthy  deployment.apps/dummyhttp configured
 ReplicaSet/dummyhttp-55569589bc           Healthy
   Pod/dummyhttp-55569589bc-qhnfk          Healthy
Ingress/dummyhttp                   Synced  Healthy  ingress.networking.k8s.io/dummyhttp configured
Service/dummyhttp                   Synced  Healthy  service/dummyhttp unchanged
 Endpoints/dummyhttp
 EndpointSlice/dummyhttp-x57bl
As we can see, the Deployment and Ingress where updated, but the Service is unchanged. To validate that the ingress is using the new hostname we can use curl:
  curl -s https://dummyhttp.lo.mixinet.net:8443/
404 page not found
  curl -s https://test-dummyhttp.lo.mixinet.net:8443/
 "c": "", "s": "" 

Adding a ConfigMapNow that the system is adjusted to reload the application when the ConfigMap or Secret is created, deleted or updated we are ready to add one file and see how the system reacts. We modify the apps/dummyhttp/overlays/test/kustomization.yaml file to create the ConfigMap using the configMapGenerator as follows:
--- a/apps/dummyhttp/overlays/test/kustomization.yaml
+++ b/apps/dummyhttp/overlays/test/kustomization.yaml
@@ -2,6 +2,14 @@ apiVersion: kustomize.config.k8s.io/v1beta1
 kind: Kustomization
 resources:
 - ../../base
+# Add the config map
+configMapGenerator:
+- name: dummyhttp-configmap
+  literals:
+  - CM_VAR="Default Test Value"
+  behavior: create
+  options:
+    disableNameSuffixHash: true
 patches:
 # Add reloader annotations
 - target:
After committing and pushing the changes we can see that the ConfigMap is available, the pod has been deleted and started again and the curl output includes the new value:
  kubectl get configmaps,pods
NAME                             READY   STATUS        RESTARTS   AGE
configmap/dummyhttp-configmap   1      11s
configmap/kube-root-ca.crt      1      4d7h
NAME                            DATA   AGE
pod/dummyhttp-779c96c44b-pjq4d   1/1     Running       0          11s
pod/dummyhttp-fc964557f-jvpkx    1/1     Terminating   0          2m42s
  curl -s https://test-dummyhttp.lo.mixinet.net:8443   jq -M .
 
  "c": "Default Test Value",
  "s": ""
 

Using helm with argocd-autopilotRight now there is no direct support in argocd-autopilot to manage applications using helm (see the issue #38 on the project), but we want to use a chart in our next example. There are multiple ways to add the support, but the simplest one that allows us to keep using argocd-autopilot is to use kustomize applications that call helm as described here. The only thing needed before being able to use the approach is to add the kustomize.buildOptions flag to the argocd-cm on the bootstrap/argo-cd/kustomization.yaml file, its contents now are follows:
bootstrap/argo-cd/kustomization.yaml
apiVersion: kustomize.config.k8s.io/v1beta1
configMapGenerator:
- behavior: merge
  literals:
  # Enable helm usage from kustomize (see https://github.com/argoproj/argo-cd/issues/2789#issuecomment-960271294)
  - kustomize.buildOptions="--enable-helm"
  -  
    repository.credentials=- passwordSecret:
        key: git_token
        name: autopilot-secret
      url: https://forgejo.mixinet.net/
      usernameSecret:
        key: git_username
        name: autopilot-secret
  name: argocd-cm
  # Disable TLS for the Argo Server (see https://argo-cd.readthedocs.io/en/stable/operator-manual/ingress/#traefik-v30)
- behavior: merge
  literals:
  - "server.insecure=true"
  name: argocd-cmd-params-cm
kind: Kustomization
namespace: argocd
resources:
- github.com/argoproj-labs/argocd-autopilot/manifests/base?ref=v0.4.19
- ingress_route.yaml
On the following section we will explain how the application is defined to make things work.

Installing the sealed-secrets controllerTo manage secrets in our cluster we are going to use the sealed-secrets controller and to install it we are going to use its chart. As we mentioned on the previous section, the idea is to create a kustomize application and use that to deploy the chart, but we are going to create the files manually, as we are not going import the base kustomization files from a remote repository. As there is no clear way to override helm Chart values using overlays we are going to use a generator to create the helm configuration from an external resource and include it from our overlays (the idea has been taken from this repository, which was referenced from a comment on the kustomize issue #38 mentioned earlier).

The sealed-secrets applicationWe have created the following files and folders manually:
apps/sealed-secrets/
  helm
    chart.yaml
    kustomization.yaml
  overlays
      test
          config.json
          kustomization.yaml
          values.yaml
The helm folder contains the generator template that will be included from our overlays. The kustomization.yaml includes the chart.yaml as a resource:
apps/sealed-secrets/helm/kustomization.yaml
apiVersion: kustomize.config.k8s.io/v1beta1
kind: Kustomization
resources:
- chart.yaml
And the chart.yaml file defines the HelmChartInflationGenerator:
apps/sealed-secrets/helm/chart.yaml
apiVersion: builtin
kind: HelmChartInflationGenerator
metadata:
  name: sealed-secrets
releaseName: sealed-secrets
name: sealed-secrets
namespace: kube-system
repo: https://bitnami-labs.github.io/sealed-secrets
version: 2.17.2
includeCRDs: true
# Add common values to all argo-cd projects inline
valuesInline:
  fullnameOverride: sealed-secrets-controller
# Load a values.yaml file from the same directory that uses this generator
valuesFile: values.yaml
For this chart the template adjusts the namespace to kube-system and adds the fullnameOverride on the valuesInline key because we want to use those settings on all the projects (they are the values expected by the kubeseal command line application, so we adjust them to avoid the need to add additional parameters to it). We adjust global values as inline to be able to use a the valuesFile from our overlays; as we are using a generator the path is relative to the folder that contains the kustomization.yaml file that calls it, in our case we will need to have a values.yaml file on each overlay folder (if we don t want to overwrite any values for a project we can create an empty file, but it has to exist). Finally, our overlay folder contains three files, a kustomization.yaml file that includes the generator from the helm folder, the values.yaml file needed by the chart and the config.json file used by argocd-autopilot to install the application. The kustomization.yaml file contents are:
apps/sealed-secrets/overlays/test/kustomization.yaml
apiVersion: kustomize.config.k8s.io/v1beta1
kind: Kustomization
# Uncomment if you want to add additional resources using kustomize
#resources:
#- ../../base
generators:
- ../../helm
The values.yaml file enables the ingress for the application and adjusts its hostname:
apps/sealed-secrets/overlays/test/values.yaml
ingress:
  enabled: true
  hostname: test-sealed-secrets.lo.mixinet.net
And the config.json file is similar to the ones used with the other applications we have installed:
apps/sealed-secrets/overlays/test/config.json
 
  "appName": "sealed-secrets",
  "userGivenName": "sealed-secrets",
  "destNamespace": "kube-system",
  "destServer": "https://kubernetes.default.svc",
  "srcPath": "apps/sealed-secrets/overlays/test",
  "srcRepoURL": "https://forgejo.mixinet.net/blogops/argocd.git",
  "srcTargetRevision": "",
  "labels": null,
  "annotations": null
 
Once we commit and push the files the sealed-secrets application is installed in our cluster, we can check it using curl to get the public certificate used by it:
  curl -s https://test-sealed-secrets.lo.mixinet.net:8443/v1/cert.pem
-----BEGIN CERTIFICATE-----
[...]
-----END CERTIFICATE-----

The dummyhttp-secretTo create sealed secrets we need to install the kubeseal tool:
  arkade get kubeseal
Now we create a local version of the dummyhttp-secret that contains some value on the SECRET_VAR key (the easiest way for doing it is to use kubectl):
  echo -n "Boo"   kubectl create secret generic dummyhttp-secret \
    --dry-run=client --from-file=SECRET_VAR=/dev/stdin -o yaml \
    >/tmp/dummyhttp-secret.yaml
The secret definition in yaml format is:
apiVersion: v1
data:
  SECRET_VAR: Qm9v
kind: Secret
metadata:
  creationTimestamp: null
  name: dummyhttp-secret
To create a sealed version using the kubeseal tool we can do the following:
  kubeseal -f /tmp/dummyhttp-secret.yaml -w /tmp/dummyhttp-sealed-secret.yaml
That invocation needs to have access to the cluster to do its job and in our case it works because we modified the chart to use the kube-system namespace and set the controller name to sealed-secrets-controller as the tool expects. If we need to create the secrets without credentials we can connect to the ingress address we added to retrieve the public key:
  kubeseal -f /tmp/dummyhttp-secret.yaml -w /tmp/dummyhttp-sealed-secret.yaml \
    --cert https://test-sealed-secrets.lo.mixinet.net:8443/v1/cert.pem
Or, if we don t have access to the ingress address, we can save the certificate on a file and use it instead of the URL. The sealed version of the secret looks like this:
apiVersion: bitnami.com/v1alpha1
kind: SealedSecret
metadata:
  creationTimestamp: null
  name: dummyhttp-secret
  namespace: default
spec:
  encryptedData:
    SECRET_VAR: [...]
  template:
    metadata:
      creationTimestamp: null
      name: dummyhttp-secret
      namespace: default
This file can be deployed to the cluster to create the secret (in our case we will add it to the argocd application), but before doing that we are going to check the output of our dummyhttp service and get the list of Secrets and SealedSecrets in the default namespace:
  curl -s https://test-dummyhttp.lo.mixinet.net:8443   jq -M .
 
  "c": "Default Test Value",
  "s": ""
 
  kubectl get sealedsecrets,secrets
No resources found in default namespace.
Now we add the SealedSecret to the dummyapp copying the file and adding it to the kustomization.yaml file:
--- a/apps/dummyhttp/overlays/test/kustomization.yaml
+++ b/apps/dummyhttp/overlays/test/kustomization.yaml
@@ -2,6 +2,7 @@ apiVersion: kustomize.config.k8s.io/v1beta1
 kind: Kustomization
 resources:
 - ../../base
+- dummyhttp-sealed-secret.yaml
 # Create the config map value
 configMapGenerator:
 - name: dummyhttp-configmap
Once we commit and push the files Argo CD creates the SealedSecret and the controller generates the Secret:
  kubectl apply -f /tmp/dummyhttp-sealed-secret.yaml
sealedsecret.bitnami.com/dummyhttp-secret created
  kubectl get sealedsecrets,secrets
NAME                                        STATUS   SYNCED   AGE
sealedsecret.bitnami.com/dummyhttp-secret            True     3s
NAME                      TYPE     DATA   AGE
secret/dummyhttp-secret   Opaque   1      3s
If we check the command output we can see the new value of the secret:
  curl -s https://test-dummyhttp.lo.mixinet.net:8443   jq -M .
 
  "c": "Default Test Value",
  "s": "Boo"
 

Using sealed-secrets in production clustersIf you plan to use sealed-secrets look into its documentation to understand how it manages the private keys, how to backup things and keep in mind that, as the documentation explains, you can rotate your sealed version of the secrets, but that doesn t change the actual secrets. If you want to rotate your secrets you have to update them and commit the sealed version of the updates (as the controller also rotates the encryption keys your new sealed version will also be using a newer key, so you will be doing both things at the same time).

Final remarksOn this post we have seen how to deploy applications using the argocd-autopilot model, including the use of helm charts inside kustomize applications and how to install and use the sealed-secrets controller. It has been interesting and I ve learnt a lot about argocd in the process, but I believe that if I ever want to use it in production I will also review the native helm support in argocd using a separate repository to manage the applications, at least to be able to compare it to the model explained here.

4 May 2025

Dirk Eddelbuettel: #47: r2u at its Third Birthday

Welcome to post 47 in the $R^4 series! r2u provides Ubuntu binaries for all CRAN packages for the R system. It started three years ago, and offers for Linux users on Ubuntu what windows and macOS users already experience: fast, easy and reliable installation of binary packages. But by integrating with the system package manager (which is something that cannot be done on those other operating systems) we can fully and completely integrate it with underlying system. External libraries are resolved as shared libraries and handled by the system package manager. This offers fully automatic installation both at the initial installation and all subsequent upgrades. R users just say, e.g., install.packages("sf") and spatial libraries proj, gdal, geotiff (as well as several others) are automatically installed as dependencies in the correct versions. And they remain installed along with sf as the system manager now knows of the dependency. Work on r2u began as a quick weekend experiment in March 2022, and by May 4 a first release was marked in the NEWS file after a few brave alpha testers kicked tires quite happily. This makes today the third anniversary of that first release, and marks a good time to review where we are. This short post does this, and stresses three aspects: overall usage, current versions, and new developments.

Steadily Growing Usage at 42 Million Packages Shipped r2u ships from two sites. Its main repository is at the University of Illinois campus providing ample and heavily redundant bandwidth. We remain very grateful for the sponsorship from Atlas. It also still ships from my own server though that may be discontinued or could be spotty as it is on retail fiber connectivity. As we have access to the both sets of server logs, we can tabulate and chart usage. As of yesterday, total downloads were north of 42 million with current weekly averages around 500 thousand. These are quite staggering numbers for what started as a small hobby project, and are quite humbling. Usage is driven by deployment in continuous integration (as for example the Ubuntu-use at GitHub makes this both an easy and obvious choice), cloud computing (as it is easy to spin up Ubuntu instances, it is as easy to add r2u via four simple commands or one short script), explorative use (for example on Google Colab) or of course in general laptop, desktop, or server settings.

Current Versions Since r2u began, we added two Ubuntu LTS releases, three annual R releases as well as multiple BioConductor releases. BioConductor support is on a best-efforts basis motivated primarily to support the CRAN packages having dependencies. It has grown to around 500 packages and includes the top-250 by usage. Right now, current versions R 4.5.0 and BioConductor 3.21, both released last month, are supported.

New Development: arm64 A recent change is the support of the arm64 platform. As discussed in the introductory post, it is a popular and increasingly common CPU choice seen anywhere from the Raspberry Pi 5 and it Cortex CPU to in-house cloud computing platforms (called, respectively, Graviton at AWS and Axiom at GCS), general server use via Ampere CPUs, Cortex-based laptops that start to appears and last but not least on the popular M1 to M4-based macOS machines. (For macOS, one key appeal is in use of lighterweight Docker use as these M1 to M4 cpus can run arm64-based containers without a translation layer making it an attractive choice.) This is currently supported only for the noble aka 24.04 release. GitHub Actions, where we compile these packages, now also supports jammy aka 22.04 but it may not be worth it to expand there as the current latest release is available. We have not yet added BioConductor support but may do so. Drop us a line (maybe via an issue) if this of interest. With the provision of arm64 binaries, we also started to make heavier use of GitHub Actions. The BioConductor 3.21 release binaries were also created there. This makes the provision more transparent as well as the configuration repo as well as the two builder repos (arm64, bioc) are public, as is of course the main r2u repo.

Summing Up This short post summarised the current state of r2u along with some recent news. If you are curious, head over to the r2u site and try it, for example in a rocker/r2u container.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. If you like this or other open-source work I do, you can now sponsor me at GitHub.

Next.

Previous.