Search Results: "cas"

5 July 2025

Taavi V n nen: Tracking my train travel by parsing tickets in emails

Rumour has it that I might be a bit of a train nerd. At least I want to collect various nerdy data about my travels. Historically that data has lived in manual form in several places,1 but over the past year and a half I've been working on a toy project to collect most of that information into a custom tool. That toy project2 uses various sources to get information about trains to fill up its database: for example, in Finland Fintraffic, the organization responsible for railway traffic management, publishes very comprehensive open data about almost everything that's moving on the Finnish railway network. Unfortunately, I cannot be on all of the trains.3 Thus I need to tell the system details about my journeys. The obvious solution is to make a form that lets me save that data. Which I did, but I got very quickly bored of filling out that form, and as regular readers of this blog know, there is no reason to settle for a simple but boring solution when the alternative is to make something that is ridiculously overengineered.

Parsing data out of my train tickets Finnish long-distance trains generally require train-specific seat reservations, which means VR (the train company) knows which trains I am on. We just need to find a way to extract that information in some machine-readable format. So my plan for the ridiculously overengineered solution was to parse the booking emails to get the details I need. Now, VR ticket emails include the data I want in a couple of different formats: they're included as text in the HTML email body, they're in the embedded calendar invite, as text in the included PDF ticket, and encoded in the Aztec Code in the included PDF ticket. I chose to parse the last option with the hopes of building something that could be ported to parse other operators' tickets with relative ease.
Example Aztec code
Example Aztec code
After a bit of digging (thank you to the KDE Itinerary people for documenting this!) I stumbled upon an European Union Agency for Railways PDF titled ELECTRONIC SEAT/BERTH RESERVATION AND ELECTRONIC PRODUCTION OF TRANSPORT DOCUMENTS - TRANSPORT DOCUMENTS (RCT2 STANDARD) which, in its Appendix C.1, describes how the information is encoded in the code.4 (As a side note, various sources call these codes SSB version 1 codes, although that term isn't used in this specification. So maybe there are more specifications about the format that I haven't discovered yet!) I then wrote a parser in Go for the binary data embedded in these codes. So far it works, although I wouldn't be surprised if there are some edge cases that it doesn't handle. In particular, the spec specifies a custom lookup table for converting between text and binary data, and that only has support for characters 0-9 and A-Z. But Finnish railway station codes can also use and .. maybe I need to buy a ticket to a station with one of those.

Extracting barcodes out of emails A parser just for the binary format isn't enough here if the intended source input is the emails that VR sends upon making a booking. Time to write a single-purpose email server! In short, the logic in the server, again written in Go and with the help of go-smtp and go-message, is:
  • Accept any mail with a reasonable body size
  • Process through all body parts
  • For all PDF parts, extract all images
  • For all images, run them through ZXing
  • For all decoded barcodes, try to parse them with my new ticket parsing library I mentioned earlier
  • If any tickets are found, send the data from them and any metadata to the main backend, which will save them to a database
The custom mail server exposes an LMTP interface over TCP for my internet-facing mail servers to forward to. I chose LMTP for this because it seemed like a better fit in theory than normal (E)SMTP. I've since discovered that curl doesn't support LMTP which makes development much harder, and in practice there's no benefit of LMTP here as all mails are being sent to the backend in a single request regardless of the number of recipients, so maybe I'll migrate it to regular SMTP at some point.

Side quest time The last missing part is automatically forwarding the ticket mails to the new service. I've routed a dedicated subdomain to the new service, and the backend is configured to allocate addresses like i2v44g2pygkcth64stjgyuqz@somedomain.example for each user. That's great if we wanted to manually forward mails to the service, but we can go one step above that. I created a dedicated email alias in my mail server config that routes both to my regular mailbox and the service address. That way I can update my VR account to use the alias and have mails automatically processed while still receiving backup copies of the tickets (and any other important mail that VR might send me). Unfortunately that last part turns out something that's easier said than done. Logging in on the website, I'm greeted by this text stating I need to contact customer service by phone to change the address associated with my account.5 After a bit of digging, I noticed that the mobile app suggests filling out a feedback form in order to change the address. So I filled that, and after a day or two I got a "confirm you want to change your email" mail. Success!

  1. Including (but not limited to): a page of this website, the notes app on my phone, and an uMap map.
  2. Which I'm not directly naming here because I still think it needs a lot more work before being presentable, but if you're really interested it's not that hard to find out.
  3. Someone should invent human cloning so that we can fix this.
  4. People who know much more about railway ticketing than I do were surprised when I told them this format is still in use somewhere. So, uh, sorry if you were expecting a nice universal worldwide standard!
  5. In case you have not guessed yet, I do not like making phone calls.

4 July 2025

Russell Coker: Function Keys

For at least 12 years laptops have been defaulting to not having the traditional PC 101 key keyboard function key functionality and instead have had other functions like controlling the volume and have had a key labelled Fn to toggle the functions. It s been a BIOS option to control whether traditional function keys or controls for volume etc are the default and for at least 12 years I ve configured all my laptops to have the traditional function keys as the default. Recently I ve been working in corporate IT and having exposure to many laptops with the default BIOS settings for those keys to change volume etc and no reasonable option for addressing it. This has made me reconsider the options for configuring these things. Here s a page listing the standard uses of function keys [1]. Here is a summary of the relevant part of that page: The keys F1, F3, F4, F7, F9, F10, and F12 don t get much use for me and for the people I observe. The F2 and F8 keys aren t useful in most programs, F6 is only really used in web browsers but the web browser counts as most programs nowadays. Here s the description of Thinkpad Fn keys [2]. I use Thinkpads for fun and Dell laptops for work, so it would be nice if they both worked in similar ways but of course they don t. Dell doesn t document how their Fn keys are laid out, but the relevant bit is that F1 to F4 are the same as on Thinkpads which is convenient as they are the ones that are likely to be commonly used and needed in a hurry. I have used the KDE settings on my Thinkpad to map the function F1 to F3 keys to the Fn equivalents which are F1 to mute-audio, F2 for vol-down, and F3 for vol-up to allow using them without holding down the Fn key while having other function keys such as F5 and F6 have their usual GUI functionality. Now I have to could train myself to use F8 in situations where I usually use F2, at least when using a laptop. The only other Fn combinations I use are F5 and F6 for controlling screen brightness, but that s not something I use much. It s annoying that the laptop manufacturers forced me to this. Having a Fn key to get extra functions and not need 101+ keys on a laptop size device is a reasonable design choice. But they could have done away with the PrintScreen key to make space for something else. Also for Thinkpads a touch pad is something that could obviously be removed to gain some extra space as the Trackpoint does all that s needed in that regard.

Sahil Dhiman: Secondary Authoritative Name Server Options for Self-Hosted Domains

In the past few months, I have moved authoritative name servers (NS) of two of my domains (sahilister.net and sahil.rocks) in house using PowerDNS. Subdomains of sahilister.net see roughly 320,000 hits/day across my IN and DE mirror nodes, so adding secondary name servers with good availability (in addition to my own) servers was one of my first priorities. I explored the following options for my secondary NS, which also didn t cost me anything:

1984 Hosting

Hurriance Electric

Afraid.org

Puck

NS-Global

Asking friends Two of my friends and fellow mirror hosts have their own authoritative name server setup, Shrirang (ie albony) and Luke. Shirang gave me another POP in IN and through Luke (who does have an insane amount of in-house NS, see dig ns jing.rocks +short), I added a JP POP. If we know each other, I would be glad to host a secondary NS for you in (IN and/or DE locations).

Some notes
  • Adding a third-party secondary is putting trust that the third party would serve your zone right.
  • Hurricane Electric and 1984 hosting provide multiple NS. One can use some or all of them. Ideally, you can get away with just using your own with full set from any of these two. Play around with adding and removing secondaries, which gives you the best results. . Using everyone is anyhow overkill, unless you have specific reasons for it.
  • Moving NS in-house isn t that hard. Though, be prepared to get it wrong a few times (and some more). I have already faced partial outages because:
    • Recursive resolvers (RR) in the wild behave in a weird way and cache the wrong NS response for longer time than in TTL.
    • NS expiry took more than time. 2 out of 3 of my Netim s NS (my domain registrar) had stopped serving my domain, while RRs in the wild hadn t picked up my new in-house NS. I couldn t really do anything about it, though.
    • Dot is pretty important at the end.
    • With HE.net, I forgot to delegate my domain on their panel and just added in my NS set, thinking I ve already done so (which I did but for another domain), leading to a lame server situation.
  • In terms of serving traffic, there s no distinction between primary and secondary NS. RR don t really care who they re asking the query to. So one can have hidden primary too.
  • I initially thought of adding periodic RIPE Atlas measurements from the global set but thought against it as I already host a termux mirror, which brings in thousands of queries from around the world leading to a diverse set of RRs querying my domain already.
  • In most cases, query resolution time would increase with out of zone NS servers (which most likely would be in external secondary). 1 query vs. 2 queries. Pay close attention to ADDITIONAL SECTION Shrirang s case followed by mine:
$ dig ns albony.in
; <<>> DiG 9.18.36 <<>> ns albony.in
;; global options: +cmd
;; Got answer:
;; ->>HEADER<<- opcode: QUERY, status: NOERROR, id: 60525
;; flags: qr rd ra; QUERY: 1, ANSWER: 4, AUTHORITY: 0, ADDITIONAL: 9
;; OPT PSEUDOSECTION:
; EDNS: version: 0, flags:; udp: 65494
;; QUESTION SECTION:
;albony.in.			IN	NS
;; ANSWER SECTION:
albony.in.		1049	IN	NS	ns3.albony.in.
albony.in.		1049	IN	NS	ns4.albony.in.
albony.in.		1049	IN	NS	ns2.albony.in.
albony.in.		1049	IN	NS	ns1.albony.in.
;; ADDITIONAL SECTION:
ns3.albony.in.		1049	IN	AAAA	2a14:3f87:f002:7::a
ns1.albony.in.		1049	IN	A	82.180.145.196
ns2.albony.in.		1049	IN	AAAA	2403:44c0:1:4::2
ns4.albony.in.		1049	IN	A	45.64.190.62
ns2.albony.in.		1049	IN	A	103.77.111.150
ns1.albony.in.		1049	IN	AAAA	2400:d321:2191:8363::1
ns3.albony.in.		1049	IN	A	45.90.187.14
ns4.albony.in.		1049	IN	AAAA	2402:c4c0:1:10::2
;; Query time: 29 msec
;; SERVER: 127.0.0.53#53(127.0.0.53) (UDP)
;; WHEN: Fri Jul 04 07:57:01 IST 2025
;; MSG SIZE  rcvd: 286
vs mine
$ dig ns sahil.rocks
; <<>> DiG 9.18.36 <<>> ns sahil.rocks
;; global options: +cmd
;; Got answer:
;; ->>HEADER<<- opcode: QUERY, status: NOERROR, id: 64497
;; flags: qr rd ra; QUERY: 1, ANSWER: 11, AUTHORITY: 0, ADDITIONAL: 1
;; OPT PSEUDOSECTION:
; EDNS: version: 0, flags:; udp: 65494
;; QUESTION SECTION:
;sahil.rocks.			IN	NS
;; ANSWER SECTION:
sahil.rocks.		6385	IN	NS	ns5.he.net.
sahil.rocks.		6385	IN	NS	puck.nether.net.
sahil.rocks.		6385	IN	NS	colin.sahilister.net.
sahil.rocks.		6385	IN	NS	marvin.sahilister.net.
sahil.rocks.		6385	IN	NS	ns2.afraid.org.
sahil.rocks.		6385	IN	NS	ns4.he.net.
sahil.rocks.		6385	IN	NS	ns2.albony.in.
sahil.rocks.		6385	IN	NS	ns3.jing.rocks.
sahil.rocks.		6385	IN	NS	ns0.1984.is.
sahil.rocks.		6385	IN	NS	ns1.1984.is.
sahil.rocks.		6385	IN	NS	ns-global.kjsl.com.
;; Query time: 24 msec
;; SERVER: 127.0.0.53#53(127.0.0.53) (UDP)
;; WHEN: Fri Jul 04 07:57:20 IST 2025
;; MSG SIZE  rcvd: 313
  • Theoretically speaking, a small increase/decrease in resolution would occur based on the chosen TLD and the popularity of the TLD in query originators area (already cached vs. fresh recursion).
  • One can get away with having only 3 NS (or be like Google and have 4 anycast NS or like Amazon and have 8 or like Verisign and make it 13 :P).
  • Nowhere it s written, your NS needs not to be called dns* or ns1, ns2 etc. Get creative with naming NS; be deceptive with the naming :D.
  • A good understanding of RR behavior can help engineer a good authoritative NS system.

Further reading

3 July 2025

Russell Coker: The Fuss About AI

There are many negative articles about AI (which is not about actual Artificial Intelligence also known as AGI ). Which I think are mostly overblown and often ridiculous. Resource Usage Complaints about resource usage are common, training Llama 3.1 could apparently produce as much pollution as 10,000 round trips by car between Los Angeles and New York City . That s not great but when you compare to the actual number of people doing such drives in the US and the number of people taking commercial flights on that route it doesn t seem like such a big deal. Apparently commercial passenger jets cause CO2 emissions per passenger about equal to a car with 2 people. Why is it relevant whether pollution comes from running servers, driving cars, or steel mills? Why not just tax polluters for the damage they do and let the market sort it out? People in the US make a big deal about not being communist, so why not have a capitalist solution, make it more expensive to do undesirable things and let the market sort it out? ML systems are a less bad use of compute resources than Bitcoin, at least ML systems give some useful results while Bitcoin has nothing good going for it. The Dot-Com Comparison People often complain about the apparent impossibility of AI companies doing what investors think they will do. But this isn t anything new, that all happened before with the dot com boom . I m not the first person to make this comparison, The Daily WTF (a high quality site about IT mistakes) has an interesting article making this comparison [1]. But my conclusions are quite different. The result of that was a lot of Internet companies going bankrupt, the investors in those companies losing money, and other companies then bought up their assets and made profitable companies. The cheap Internet we now have was built on the hardware from bankrupt companies which was sold for far less than the manufacture price. That allowed it to scale up from modem speeds to ADSL without the users paying enough to cover the purchase of the infrastructure. In the early 2000s I worked for two major Dutch ISPs that went bankrupt (not my fault) and one of them continued operations in the identical manner after having the stock price go to zero (I didn t get to witness what happened with the other one). As far as I m aware random Dutch citizens and residents didn t suffer from this and employees just got jobs elsewhere. There are good things being done with ML systems and when companies like OpenAI go bankrupt other companies will buy the hardware and do good things. NVidia isn t ever going to have the future sales that would justify a market capitalisation of almost 4 Trillion US dollars. This market cap can support paying for new research and purchasing rights to patented technology in a similar way to the high stock price of Google supported buying YouTube, DoubleClick, and Motorola Mobility which are the keys to Google s profits now. The Real Upsides of ML Until recently I worked for a company that used ML systems to analyse drivers for signs of fatigue, distraction, or other inappropriate things (smoking which is illegal in China, using a mobile phone, etc). That work was directly aimed at saving human lives with a significant secondary aim of saving wear on vehicles (in the mining industry drowsy drivers damage truck tires and that s a huge business expense). There are many applications of ML in medical research such as recognising cancer cells in tissue samples. There are many less important uses for ML systems, such as recognising different types of pastries to correctly bill bakery customers technology that was apparently repurposed for recognising cancer cells. The ability to recognise objects in photos is useful. It can be used for people who want to learn about random objects they see and could be used for helping young children learn about their environment. It also has some potential for assistance for visually impaired people, it wouldn t be good for safety critical systems (don t cross a road because a ML system says there are no cars coming) but could be useful for identifying objects (is this a lemon or a lime). The Humane AI pin had some real potential to do good things but there wasn t a suitable business model [2], I think that someone will develop similar technology in a useful way eventually. Even without trying to do what the Humane AI Pin attempted, there are many ways for ML based systems to assist phone and PC use. ML systems allow analysing large quantities of data and giving information that may be correct. When used by a human who knows how to recognise good answers this can be an efficient way of solving problems. I personally have solved many computer problems with the help of LLM systems while skipping over many results that were obviously wrong to me. I believe that any expert in any field that is covered in the LLM input data could find some benefits from getting suggestions from an LLM. It won t necessarily allow them to solve problems that they couldn t solve without it but it can provide them with a set of obviously wrong answers mixed in with some useful tips about where to look for the right answers. Jobs and Politics Noema Magazine has an insightful article about how AI can allow different models of work which can enlarge the middle class [3]. I don t think it s reasonable to expect ML systems to make as much impact on society as the industrial revolution, and the agricultural revolutions which took society from more than 90% farm workers to less than 5%. That doesn t mean everything will be fine but it is something that can seem OK after the changes have happened. I m not saying apart from the death and destruction everything will be good , the death and destruction are optional. Improvements in manufacturing and farming didn t have to involve poverty and death for many people, improvements to agriculture didn t have to involve overcrowding and death from disease. This was an issue of political decisions that were made. The Real Problems of ML Political decisions that are being made now have the aim of making the rich even richer and leaving more people in poverty and in many cases dying due to being unable to afford healthcare. The ML systems that aim to facilitate such things haven t been as successful as evil people have hoped but it will happen and we need appropriate legislation if we aren t going to have revolutions. There are documented cases of suicide being inspired by Chat GPT systems [4]. There have been people inspired towards murder by ChatGPT systems but AFAIK no-one has actually succeeded in such a crime yet. There are serious issues that need to be addressed with the technology and with legal constraints about how people may use it. It s interesting to consider the possible uses of ChatGPT systems for providing suggestions to a psychologist, maybe ChatGPT systems could be used to alleviate mental health problems. The cases of LLM systems being used for cheating on assignments etc isn t a real issue. People have been cheating on assignments since organised education was invented. There is a real problem of ML systems based on biased input data that issue decisions that are the average of the bigotry of the people who provided input. That isn t going to be worse than the current situation of bigoted humans making decisions based on hate and preconceptions but it will be more insidious. It is possible to search for that so for example a bank could test it s mortgage approval ML system by changing one factor at a time (name, gender, age, address, etc) and see if it changes the answer. If it turns out that the ML system is biased on names then the input data could have names removed. If it turns out to be biased about address then there could be weights put in to oppose that. For a long time there has been excessive trust in computers. Computers aren t magic they just do maths really fast and implement choices based on the work of programmers who have all the failings of other humans. Excessive trust in a rule based system is less risky than excessive trust in a ML system where no-one really knows why it makes the decisions it makes. Self driving cars kill people, this is the truth that Tesla stock holders don t want people to know. Companies that try to automate everything with AI are going to be in for some nasty surprises. Getting computers to do everything that humans do in any job is going to be a large portion of an actual intelligent computer which if it is achieved will raise an entirely different set of problems. I ve previously blogged about ML Security [5]. I don t think this will be any worse than all the other computer security problems in the long term, although it will be more insidious. How Will It Go? Companies spending billions of dollars without firm plans for how to make money are going to go bankrupt no matter what business they are in. Companies like Google and Microsoft can waste some billions of dollars on AI Chat systems and still keep going as successful businesses. Companies like OpenAI that do nothing other than such chat systems won t go well. But their assets can be used by new companies when sold at less than 10% the purchase price. Companies like NVidia that have high stock prices based on the supposed ongoing growth in use of their hardware will have their stock prices crash. But the new technology they develop will be used by other people for other purposes. If hospitals can get cheap diagnostic ML systems because of unreasonable investment into AI then that could be a win for humanity. Companies that bet their entire business on AI even when it s not necessarily their core business (as Tesla has done with self driving) will have their stock price crash dramatically at a minimum and have the possibility of bankruptcy. Having Tesla go bankrupt is definitely better than having people try to use them as self driving cars.

2 July 2025

Dirk Eddelbuettel: Rcpp 1.1.0 on CRAN: C++11 now Minimum, Regular Semi-Annual Update

rcpp logo With a friendly Canadian hand wave from vacation in Beautiful British Columbia, and speaking on behalf of the Rcpp Core Team, I am excited to shared that the (regularly scheduled bi-annual) update to Rcpp just brought version 1.1.0 to CRAN. Debian builds haven been prepared and uploaded, Windows and macOS builds should appear at CRAN in the next few days, as will builds in different Linux distribution and of course r2u should catch up tomorrow as well. The key highlight of this release is the switch to C++11 as minimum standard. R itself did so in release 4.0.0 more than half a decade ago; if someone is really tied to an older version of R and an equally old compiler then using an older Rcpp with it has to be acceptable. Our own tests (using continuous integration at GitHub) still go back all the way to R 3.5.* and work fine (with a new-enough compiler). In the previous release post, we commented that we had only reverse dependency (falsely) come up in the tests by CRAN, this time there was none among the well over 3000 packages using Rcpp at CRAN. Which really is quite amazing, and possibly also a testament to our rigorous continued testing of our development and snapshot releases on the key branch. This release continues with the six-months January-July cycle started with release 1.0.5 in July 2020. As just mentioned, we do of course make interim snapshot dev or rc releases available. While we not longer regularly update the Rcpp drat repo, the r-universe page and repo now really fill this role admirably (and with many more builds besides just source). We continue to strongly encourage their use and testing I run my systems with these versions which tend to work just as well, and are of course also fully tested against all reverse-dependencies. Rcpp has long established itself as the most popular way of enhancing R with C or C++ code. Right now, 3038 packages on CRAN depend on Rcpp for making analytical code go faster and further. On CRAN, 13.6% of all packages depend (directly) on Rcpp, and 61.3% of all compiled packages do. From the cloud mirror of CRAN (which is but a subset of all CRAN downloads), Rcpp has been downloaded 100.8 million times. The two published papers (also included in the package as preprint vignettes) have, respectively, 2023 (JSS, 2011) and 380 (TAS, 2018) citations, while the the book (Springer useR!, 2013) has another 695. As mentioned, this release switches to C++11 as the minimum standard. The diffstat display in the CRANberries comparison to the previous release shows how several (generated) sources files with C++98 boilerplate have now been removed; we also flattened a number of if/else sections we no longer need to cater to older compilers (see below for details). We also managed more accommodation for the demands of tighter use of the C API of R by removing DATAPTR and CLOENV use. A number of other changes are detailed below. The full list below details all changes, their respective PRs and, if applicable, issue tickets. Big thanks from all of us to all contributors!

Changes in Rcpp release version 1.1.0 (2025-07-01)
  • Changes in Rcpp API:
    • C++11 is now the required minimal C++ standard
    • The std::string_view type is now covered by wrap() (Lev Kandel in #1356 as discussed in #1357)
    • A last remaining DATAPTR use has been converted to DATAPTR_RO (Dirk in #1359)
    • Under R 4.5.0 or later, R_ClosureEnv is used instead of CLOENV (Dirk in #1361 fixing #1360)
    • Use of lsInternal switched to lsInternal3 (Dirk in #1362)
    • Removed compiler detection macro in a header cleanup setting C++11 as the minunum (Dirk in #1364 closing #1363)
    • Variadic templates are now used onconditionally given C++11 (Dirk in #1367 closing #1366)
    • Remove RCPP_USING_CXX11 as a #define as C++11 is now a given (Dirk in #1369)
    • Additional cleanup for __cplusplus checks (I aki in #1371 fixing #1370)
    • Unordered set construction no longer needs a macro for the pre-C++11 case (I aki in #1372)
    • Lambdas are supported in a Rcpp Sugar functions (I aki in #1373)
    • The Date(time)Vector classes now have default ctor (Dirk in #1385 closing #1384)
    • Fixed an issue where Rcpp::Language would duplicate its arguments (Kevin in #1388, fixing #1386)
  • Changes in Rcpp Attributes:
    • The C++26 standard now has plugin support (Dirk in #1381 closing #1380)
  • Changes in Rcpp Documentation:
    • Several typos were correct in the NEWS file (Ben Bolker in #1354)
    • The Rcpp Libraries vignette mentions PACKAGE_types.h to declare types used in RcppExports.cpp (Dirk in #1355)
    • The vignettes bibliography file was updated to current package versions, and now uses doi references (Dirk in #1389)
  • Changes in Rcpp Deployment:
    • Rcpp.package.skeleton() creates URL and BugReports if given a GitHub username (Dirk in #1358)
    • R 4.4.* has been added to the CI matrix (Dirk in #1376)
    • Tests involving NA propagation are skipped under linux-arm64 as they are under macos-arm (Dirk in #1379 closing #1378)

Thanks to my CRANberries, you can also look at a diff to the previous release Questions, comments etc should go to the rcpp-devel mailing list off the R-Forge page. Bugs reports are welcome at the GitHub issue tracker as well (where one can also search among open or closed issues).

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. If you like this or other open-source work I do, you can sponsor me at GitHub.

1 July 2025

Ben Hutchings: FOSS activity in June 2025

Guido G nther: Free Software Activities June 2025

Another short status update of what happened on my side last month. Phosh 0.48.0 is out with nice improvements, phosh.mobi e.V. is alive, helped a bit to get cellbroadcastd out, osk bugfixes and some more: See below for details on the above and more: phosh phoc phosh-mobile-settings stevia (formerly phosh-osk-stub) phosh-osk-data phosh-vala-plugins pfs xdg-desktop-portal-phosh xdg-desktop-portal phosh-debs meta-phosh feedbackd feedbackd-device-themes gmobile GNOME clocks Debian Mobian ModemManager libmbim libqmi mobile-broadband-provider-info Cellbroadcastd iio-sensor-proxy twenty-twenty-hugo gotosocial Reviews This is not code by me but reviews on other peoples code. The list is (as usual) slightly incomplete. Thanks for the contributions! Help Development If you want to support my work see donations. Comments? Join the Fediverse thread

30 June 2025

Colin Watson: Free software activity in June 2025

My Debian contributions this month were all sponsored by Freexian. This was a very light month; I did a few things that were easy or that seemed urgent for the upcoming trixie release, but otherwise most of my energy went into Debusine. I ll be giving a talk about that at DebConf in a couple of weeks; this is the first DebConf I ll have managed to make it to in over a decade, so I m pretty excited. You can also support my work directly via Liberapay or GitHub Sponsors. PuTTY After reading a bunch of recent discourse about X11 and Wayland, I decided to try switching my laptop (a Framework 13 AMD running Debian trixie with GNOME) over to Wayland. I don t remember why it was running X; I think I must have either inherited some configuration from my previous laptop (in which case it could have been due to anything up to ten years ago or so), or else I had some initial problem while setting up my new laptop and failed to make a note of it. Anyway, the switch was hardly noticeable, which was great. One problem I did notice is that my preferred terminal emulator, pterm, crashed after the upgrade. I run a slightly-modified version from git to make some small terminal emulation changes that I really must either get upstream or work out how to live without one of these days, so it took me a while to notice that it only crashed when running from the packaged version, because the crash was in code that only runs when pterm has a set-id bit. I reported this upstream, they quickly fixed it, and I backported it to the Debian package. groff Upstream bug #67169 reported URLs being dropped from PDF output in some cases. I investigated the history both upstream and in Debian, identified the correct upstream patch to backport, and uploaded a fix. libfido2 I upgraded libfido2 to 1.16.0 in experimental. Python team I upgraded pydantic-extra-types to a new upstream version, and fixed some resulting fallout in pendulum. I updated python-typing-extensions in bookworm-backports, to help fix python3-tango: python3-pytango from bookworm-backports does not work (10.0.2-1~bpo12+1). I upgraded twisted to a new upstream version in experimental. I fixed or helped to fix a few release-critical bugs:

Gunnar Wolf: Get your personalized map of DebConf25 in Brest

As I often do, this year I have also prepared a set of personalized maps for your OpenPGP keysigning in DebConf25, in Brest! What is that, dare you ask? Partial view of my OpenPGP map One of the not-to-be-missed traditions of DebConf is a Key-Signing Party (KSP) that spans the whole conference! Travelling from all the corners of the world to a single, large group gathering, we have the ideal opportunity to spread some communicable diseases trust on your peers identities and strengthen Debian s OpenPGP keyring. But whom should you approach for keysigning? Go find yourself in the nice listing I have prepared. By clicking on your long keyid (in my case, the link labeled 0x2404C9546E145360), anybody can download your certificate (public key + signatures). The SVG and PNG links will yield a graphic version of your position within the DC25 keyring, and the TXT link will give you a textual explanation of it. (of course, your links will differ, yada yada ) Please note this is still a preview of our KSP information: You will notice there are outstanding several things for me to fix before marking the file as final. First, some names have encoding issues I will fix. Second, some keys might be missing if you submitted your key as part of the conference registration form but it is not showing, it must be because my scripts didn t find it in any of the queried keyservers. My scripts are querying the following servers:
hkps://keyring.debian.org/
hkps://keys.openpgp.org/
hkps://keyserver.computer42.org/
hkps://keyserver.ubuntu.com/
hkps://pgp.mit.edu/
hkps://pgp.pm/
hkps://pgp.surf.nl/
hkps://pgpkeys.eu/
hkps://the.earth.li/
Make sure your key is available in at least some of them; I will try to do a further run on Friday, before travelling, or shortly after arriving to France. If you didn t submit your key in time, but you will be at DC25, please mail me stating [DC25 KSP] in your mail title, and I will manually add it to the list. On (hopefully!) Friday, I ll post the final, canonical KSP coordination page which you should download and calculate its SHA256-sum. We will have printed out convenience sheets to help you do your keysigning at the front desk.

David Bremner: Hibernate on the pocket reform 1/n

Configuration
  • script: https://docs.kernel.org/power/basic-pm-debugging.html
  • kernel is 6.15.4-1~exp1+reform20250628T170930Z

State of things
  • normal reboot works
  • Either from the console, or from sway, the intial test of reboot mode hibernate fails. In both cases it looks very similar to halting.
    • the screen is dark (but not completely black)
    • the keyboard is still illuminated
    • the system-controller still seems to work, althought I need to power off before I can power on again, and any "hibernation state" seems lost.

Running tests
  • this is 1a from above
  • freezer test passes
  • devices test from console
    • console comes back (including input)
    • networking (both wired and wifi) seems wedged.
    • console is full of messages from mt76x2u about vendor request 06 and 07 failing. This seems related to https://github.com/morrownr/7612u/issues/17
    • at some point the console becomes non-responsive, except for the aforementioned messages from the wifi module.
  • devices test under sway
    • display comes back
    • keyboard/mouse seem disconnected
    • network down / disconnected?
next episode

Otto Kek l inen: Corporate best practices for upstream open source contributions

Featured image of post Corporate best practices for upstream open source contributions
This post is based on presentation given at the Validos annual members meeting on June 25th, 2025.
When I started getting into Linux and open source over 25 years ago, the majority of the software development in this area was done by academics and hobbyists. The number of companies participating in open source has since exploded in parallel with the growth of mobile and cloud software, the majority of which is built on top of open source. For example, Android powers most mobile phones today and is based on Linux. Almost all software used to operate large cloud provider data centers, such as AWS or Google, is either open source or made in-house by the cloud provider. Pretty much all companies, regardless of the industry, have been using open source software at least to some extent for years. However, the degree to which they collaborate with the upstream origins of the software varies. I encourage all companies in a technical industry to start contributing upstream. There are many benefits to having a good relationship with your upstream open source software vendors, both for the short term and especially for the long term. Moreover, with the rollout of CRA in EU in 2025-2027, the law will require software companies to contribute security fixes upstream to the open source projects their products use. To ensure the process is well managed, business-aligned and legally compliant, there are a few do s and don t do s that are important to be aware of.

Maintain your SBOMs For every piece of software, regardless of whether the code was done in-house, from an open source project, or a combination of these, every company needs to produce a Software Bill of Materials (SBOM). The SBOMs provide a standardized and interoperable way to track what software and which versions are used where, what software licenses apply, who holds the copyright of which component, which security fixes have been applied and so forth. A catalog of SBOMs, or equivalent, forms the backbone of software supply-chain management in corporations.

Identify your strategic upstream vendors The SBOMs are likely to reveal that for any piece of non-trivial software, there are hundreds or thousands of upstream open source projects in use. Few organizations have resources to contribute to all of their upstreams. If your organization is just starting to organize upstream contribution activities, identify the key projects that have the largest impact on your business and prioritize forming a relationship with them first. Organizations with a mature contribution process will be collaborating with tens or hundreds of upstreams.

Appoint an internal coordinator and champions Having a written policy on how to contribute upstream will help ensure a consistent process and avoid common pitfalls. However, a written policy alone does not automatically translate into a well-running process. It is highly recommended to appoint at least one internal coordinator who is knowledgeable about how open source communities work, how software licensing and patents work, and is senior enough to have a good sense of what business priorities to optimize for. In small organizations it can be a single person, while larger organizations typically have a full Open Source Programs Office. This coordinator should oversee the contribution process, track all contributions made across the organization, and further optimize the process by working with stakeholders across the business, including legal experts, business owners and CTOs. The marketing and recruiting folks should also be involved, as upstream contributions will have a reputation-building aspect as well, which can be enhanced with systematic tracking and publishing of activities. Additionally, at least in the beginning, the organization should also appoint key staff members as open source champions. Implementing a new process always includes some obstacles and occasional setbacks, which may discourage employees from putting in the extra effort to reap the full long-term benefits for the company. Having named champions will empower them to make the first few contributions themselves, setting a good example and encouraging and mentoring others to contribute upstream as well.

Avoid excessive approvals To maintain a high quality bar, it is always good to have all outgoing submissions reviewed by at least one or two people. Two or three pairs of eyeballs are significantly more likely to catch issues that might slip by someone working alone. The review also slows down the process by a day or two, which gives the author time to sleep on it , which usually helps to ensure the final submission is well-thought-out by the author. Do not require more than one or two reviewers. The marginal utility goes quickly to zero beyond a few reviewers, and at around four or five people the effect becomes negative, as the weight of each approval decreases and the reviewers begin to take less personal responsibility. Having too many people in the loop also makes each feedback round slow and expensive, to the extent that the author will hesitate to make updates and ask for re-reviews due to the costs involved. If the organization experiences setbacks due to mistakes slipping through the review process, do not respond by adding more reviewers, as it will just grind the contribution process to a halt. If there are quality concerns, invest in training for engineers, CI systems and perhaps an internal certification program for those making public upstream code submissions. A typical software engineer is more likely to seriously try to become proficient at their job and put effort into a one-off certification exam and then make multiple high-quality contributions, than it is for a low-skilled engineer to improve and even want to continue doing more upstream contributions if they are burdened by heavy review processes every time they try to submit an upstream contribution.

Don t expect upstream to accept all code contributions Sure, identifying the root cause of and fixing a tricky bug or writing a new feature requires significant effort. While an open source project will certainly appreciate the effort invested, it doesn t mean it will always welcome all contributions with open arms. Occasionally, the project won t agree that the code is correct or the feature is useful, and some contributions are bound to be rejected. You can minimize the chance of experiencing rejections by having a solid internal review process that includes assessing how the upstream community is likely to understand the proposal. Sometimes how things are communicated is more important than how they are coded. Polishing inline comments and git commit messages help ensure high-quality communication, along with a commitment to respond quickly to review feedback and conducting regular follow-ups until a contribution is finalized and accepted.

Start small to grow expertise and reputation In addition to keeping the open source contribution policy lean and nimble, it is also good to start practical contributions with small issues. Don t aim to contribute massive features until you have a track record of being able to make multiple small contributions. Keep in mind that not all open source projects are equal. Each has its own culture, written and unwritten rules, development process, documented requirements (which may be outdated) and more. Starting with a tiny contribution, even just a typo fix, is a good way to validate how code submissions, reviews and approvals work in a particular project. Once you have staff who have successfully landed smaller contributions, you can start planning larger proposals. The exact same proposal might be unsuccessful when proposed by a new person, and successful when proposed by a person who already has a reputation for prior high-quality work.

Embrace all and any publicity you get Some companies have concerns about their employees working in the open. Indeed, every email and code patch an employee submits, and all related discussions become public. This may initially sound scary, but is actually a potential source of good publicity. Employees need to be trained on how to conduct themselves publicly, and the discussions about code should contain only information strictly related to the code, without any references to actual production environments or other sensitive information. In the long run most employees contributing have a positive impact and the company should reap the benefits of positive publicity. If there are quality issues or employee judgment issues, hiding the activity or forcing employees to contribute with pseudonyms is not a proper solution. Instead, the problems should be addressed at the root, and bad behavior addressed rather than tolerated. When people are working publicly, there tends to also be some degree of additional pride involved, which motivates people to try their best. Contributions need to be public for the sponsoring corporation to later be able to claim copyright or licenses. Considering that thousands of companies participate in open source every day, the prevalence of bad publicity is quite low, and the benefits far exceed the risks.

Scratch your own itch When choosing what to contribute, select things that benefit your own company. This is not purely about being selfish - often people working on resolving a problem they suffer from are the same people with the best expertise of what the problem is and what kind of solution is optimal. Also, the issues that are most pressing to your company are more likely to be universally useful to solve than any random bug or feature request in the upstream project s issue tracker.

Remember there are many ways to help upstream While submitting code is often considered the primary way to contribute, please keep in mind there are also other highly impactful ways to contribute. Submitting high-quality bug reports will help developers quickly identify and prioritize issues to fix. Providing good research, benchmarks, statistics or feedback helps guide development and the project make better design decisions. Documentation, translations, organizing events and providing marketing support can help increase adoption and strengthen long-term viability for the project. In some of the largest open source projects there are already far more pending contributions than the core maintainers can process. Therefore, developers who contribute code should also get into the habit of contributing reviews. As Linus law states, given enough eyeballs, all bugs are shallow. Reviewing other contributors submissions will help improve quality, and also alleviate the pressure on core maintainers who are the only ones providing feedback. Reviewing code submitted by others is also a great learning opportunity for the reviewer. The reviewer does not need to be better than the submitter - any feedback is useful; merely posting review feedback is not the same thing as making an approval decision. Many projects are also happy to accept monetary support and sponsorships. Some offer specific perks in return. By human nature, the largest sponsors always get their voice heard in important decisions, as no open source project wants to take actions that scare away major financial contributors.

Starting is the hardest part Long-term success in open source comes from a positive feedback loop of an ever-increasing number of users and collaborators. As seen in the examples of countless corporations contributing open source, the benefits are concrete, and the process usually runs well after the initial ramp-up and organizational learning phase has passed. In open source ecosystems, contributing upstream should be as natural as paying vendors in any business. If you are using open source and not contributing at all, you likely have latent business risks without realizing it. You don t want to wake up one morning to learn that your top talent left because they were forbidden from participating in open source for the company s benefit, or that you were fined due to CRA violations and mismanagement in sharing security fixes with the correct parties. The faster you start with the process, the less likely those risks will materialize.

24 June 2025

Dirk Eddelbuettel: RcppRedis 0.2.6 on CRAN: Extensions

A new minor release 0.2.6 of our RcppRedis package arrived on CRAN today. RcppRedis is one of several packages connecting R to the fabulous Redis in-memory datastructure store (and much more). It works equally well with the newer fork Valkey. RcppRedis does not pretend to be feature complete, but it may do some things faster than the other interfaces, and also offers an optional coupling with MessagePack binary (de)serialization via RcppMsgPack. The package has been deployed in production as a risk / monitoring tool on a trading floor for several years. It also supports pub/sub dissemination of streaming market data as per this earlier example. This update brings new functions del, lrem, and lmove (for the matching Redis / Valkey commands) which may be helpful in using Redis (or Valkey) as a job queue. We also extended the publish accessor by supporting text (i.e. string) mode along with raw or rds (the prior default which always serialized R objects) just how listen already worked with these three cases. The change makes it possible to publish from R to subscribers not running R as they cannot rely on the R deserealizer. An example is provided by almm, a live market monitor, which we introduced in this blog post. Apart from that the continuous integration script received another mechanical update. The detailed changes list follows.

Changes in version 0.2.6 (2025-06-24)
  • The commands DEL, LREM and LMOVE have been added
  • The continuous integration setup was updated once more
  • The pub/sub publisher now supports a type argument similar to the listener, this allows string message publishing for non-R subscribers

Courtesy of my CRANberries, there is also a diffstat report for this this release. More information is on the RcppRedis page and at the repository and its issue tracker.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. If you like this or other open-source work I do, you can sponsor me at GitHub.

Matthew Garrett: Why is there no consistent single signon API flow?

Single signon is a pretty vital part of modern enterprise security. You have users who need access to a bewildering array of services, and you want to be able to avoid the fallout of one of those services being compromised and your users having to change their passwords everywhere (because they're clearly going to be using the same password everywhere), or you want to be able to enforce some reasonable MFA policy without needing to configure it in 300 different places, or you want to be able to disable all user access in one place when someone leaves the company, or, well, all of the above. There's any number of providers for this, ranging from it being integrated with a more general app service platform (eg, Microsoft or Google) or a third party vendor (Okta, Ping, any number of bizarre companies). And, in general, they'll offer a straightforward mechanism to either issue OIDC tokens or manage SAML login flows, requiring users present whatever set of authentication mechanisms you've configured.


This is largely optimised for web authentication, which doesn't seem like a huge deal - if I'm logging into Workday then being bounced to another site for auth seems entirely reasonable. The problem is when you're trying to gate access to a non-web app, at which point consistency in login flow is usually achieved by spawning a browser and somehow managing submitting the result back to the remote server. And this makes some degree of sense - browsers are where webauthn token support tends to live, and it also ensures the user always has the same experience.

But it works poorly for CLI-based setups. There's basically two options - you can use the device code authorisation flow, where you perform authentication on what is nominally a separate machine to the one requesting it (but in this case is actually the same) and as a result end up with a straightforward mechanism to have your users socially engineered into giving Johnny Badman a valid auth token despite webauthn nominally being unphisable (as described years ago), or you reduce that risk somewhat by spawning a local server and POSTing the token back to it - which works locally but doesn't work well if you're dealing with trying to auth on a remote device. The user experience for both scenarios sucks, and it reduces a bunch of the worthwhile security properties that modern MFA supposedly gives us.

There's a third approach, which is in some ways the obviously good approach and in other ways is obviously a screaming nightmare. All the browser is doing is sending a bunch of requests to a remote service and handling the response locally. Why don't we just do the same? Okta, for instance, has an API for auth. We just need to submit the username and password to that and see what answer comes back. This is great until you enable any kind of MFA, at which point the additional authz step is something that's only supported via the browser. And basically everyone else is the same.

Of course, when we say "That's only supported via the browser", the browser is still just running some code of some form and we can figure out what it's doing and do the same. Which is how you end up scraping constants out of Javascript embedded in the API response in order to submit that data back in the appropriate way. This is all possible but it's incredibly annoying and fragile - the contract with the identity provider is that a browser is pointed at a URL, not that any of the internal implementation remains consistent.

I've done this. I've implemented code to scrape an identity provider's auth responses to extract the webauthn challenges and feed those to a local security token without using a browser. I've also written support for forwarding those challenges over the SSH agent protocol to make this work with remote systems that aren't running a GUI. This week I'm working on doing the same again, because every identity provider does all of this differently.

There's no fundamental reason all of this needs to be custom. It could be a straightforward "POST username and password, receive list of UUIDs describing MFA mechanisms, define how those MFA mechanisms work". That even gives space for custom auth factors (I'm looking at you, Okta Fastpass). But instead I'm left scraping JSON blobs out of Javascript and hoping nobody renames a field, even though I only care about extremely standard MFA mechanisms that shouldn't differ across different identity providers.

Someone, please, write a spec for this. Please don't make it be me.

comment count unavailable comments

22 June 2025

Sahil Dhiman: Case of (broken) maharashtra.gov.in Authoritative Name Servers

Maharashtra is a state here in India, which has Mumbai, the financial capital of India, as its capital. maharashtra.gov.in is the official website of the State Government of Maharashtra. We re going to talk about authoritative name servers serving it (and bunch of child zones under maharashtra.gov.in). Here s a simple trace for the main domain:
$ dig +trace maharashtra.gov.in
; <<>> DiG 9.18.33-1~deb12u2-Debian <<>> +trace maharashtra.gov.in
;; global options: +cmd
.            33128    IN    NS    j.root-servers.net.
.            33128    IN    NS    h.root-servers.net.
.            33128    IN    NS    l.root-servers.net.
.            33128    IN    NS    k.root-servers.net.
.            33128    IN    NS    i.root-servers.net.
.            33128    IN    NS    g.root-servers.net.
.            33128    IN    NS    f.root-servers.net.
.            33128    IN    NS    e.root-servers.net.
.            33128    IN    NS    b.root-servers.net.
.            33128    IN    NS    d.root-servers.net.
.            33128    IN    NS    c.root-servers.net.
.            33128    IN    NS    m.root-servers.net.
.            33128    IN    NS    a.root-servers.net.
.            33128    IN    RRSIG    NS 8 0 518400 20250704050000 20250621040000 53148 . pGxGZftwj+6VNTSQtstTKVN95Z7/b5Q8GSjRCXI68GoVYbVai9HNelxs OGIRKL4YmSrsiSsndXuEsBuvL9QvQ+qbybNLkekJUAiicKYNgr3KM3+X 69rsS9KxHgT2T8/oqG8KN8EJLJ8VkuM2PJ2HfSKijtF7ULtgBbERNQ4i u2I/wQ7elOyeF2M76iEOa7UGhgiBHSBqPulsbpnB//WbKL71yyFhWSk0 tiFEPuZM+iLrN2qBsElriF4kkw37uRHq8sSGcCjfBVdkpbb3/Sb3sIgN /zKU17f+hOvuBQTDr5qFIymqGAENA5UZ2RQjikk6+zK5EfBUXNpq1+oo 2y64DQ==
;; Received 525 bytes from 9.9.9.9#53(9.9.9.9) in 3 ms
in.            172800    IN    NS    ns01.trs-dns.com.
in.            172800    IN    NS    ns01.trs-dns.net.
in.            172800    IN    NS    ns10.trs-dns.org.
in.            172800    IN    NS    ns10.trs-dns.info.
in.            86400    IN    DS    48140 8 2 5EE4748C2069B99C98BC39A56881A64AF17CC78711E6297D43AC5A4F 4B5BB6E5
in.            86400    IN    RRSIG    DS 8 1 86400 20250704050000 20250621040000 53148 . jkCotYosapreoKKPvr9zPOEDECYVe9OtJLjkQbFfTin8uYbm/kdWzieW CkN5sabif5IHTFU4FEVOShfu4DFeUolhNav56TPKjGqEGjQ7qCghpqTj dNN4iY2s8BcJ2ujHwhm6HRfdbQRVoKYQ73UUZ+oWSute6lXWHE9+Snk2 1ZCAYPdZ2s1s7NZhrZW2YXVw/nHIcRl/rHqWIQ9sgUlsd6MwmahcAAG+ v15HG9Q48rCG1A2gJlJPbxWpVe0EUEu8LzDsp+ORqy1pHhzgJynrJHJz qMiYU0egv2j7xVPSoQHXjx3PG2rsOLNnqDBYCA+piEXOLsY3d+7c1SZl w9u66g==
;; Received 679 bytes from 199.7.83.42#53(l.root-servers.net) in 3 ms
maharashtra.gov.in.    900    IN    NS    ns8.maharashtra.gov.in.
maharashtra.gov.in.    900    IN    NS    ns9.maharashtra.gov.in.
maharashtra.gov.in.    900    IN    NS    ns10.maharashtra.gov.in.
maharashtra.gov.in.    900    IN    NS    ns18.maharashtra.gov.in.
maharashtra.gov.in.    900    IN    NS    ns20.maharashtra.gov.in.
npk19skvsdmju264d4ono0khqf7eafqv.gov.in. 300 IN    NSEC3 1 1 0 - P0KKR4BMBGLJDOKBGBI0KDM39DSM0EA4 NS SOA MX TXT RRSIG DNSKEY NSEC3PARAM
npk19skvsdmju264d4ono0khqf7eafqv.gov.in. 300 IN    RRSIG NSEC3 8 3 300 20250626140337 20250528184339 48544 gov.in. Khcq3n1Jn34HvuBEZExusVqoduEMH6DzqkWHk9dFkM+q0RVBYBHBbW+u LsSnc2/Rqc3HAYutk3EZeS+kXVF07GA/A486dr17Hqf3lHszvG/MNT/s CJfcdrqO0Q8NZ9NQxvAwWo44bCPaECQV+fhznmIaVSgbw7de9xC6RxWG ZFcsPYwYt07yB5neKa99RlVvJXk4GHX3ISxiSfusCNOuEKGy5cMxZg04 4PbYsP0AQNiJWALAduq2aNs80FQdWweLhd2swYuZyfsbk1nSXJQcYbTX aONc0VkYFeEJzTscX8/wNbkJeoLP0r/W2ebahvFExl3NYpb7b2rMwGBY omC/QA==
npk19skvsdmju264d4ono0khqf7eafqv.gov.in. 300 IN    RRSIG NSEC3 13 3 300 20250718144138 20250619135610 22437 gov.in. mbj7td3E6YE7kIhYoSlDTZR047TXY3Z60NY0aBwU7obyg5enBQU9j5nl GUxn9zUiwVUzei7v5GIPxXS7XDpk7g==
6bflkoouitlvj011i2mau7ql5pk61sks.gov.in. 300 IN    NSEC3 1 1 0 - 78S0UO5LI1KV1SVMH1889FHUCNC40U6T TXT RRSIG
6bflkoouitlvj011i2mau7ql5pk61sks.gov.in. 300 IN    RRSIG NSEC3 8 3 300 20250626133905 20250528184339 48544 gov.in. M2yPThQpX0sEf4klooQ06h+rLR3e3Q/BqDTSFogyTIuGwjgm6nwate19 jGmgCeWCYL3w/oxsg1z7SfCvDBCXOObH8ftEBOfLe8/AGHAEkWFSu3e0 s09Ccoz8FJiCfBJbbZK5Vf4HWXtBLfBq+ncGCEE24tCQLXaS5cT85BxZ Zne6Y6u8s/WPgo8jybsvlGnL4QhIPlW5UkHDs7cLLQSwlkZs3dwxyHTn EgjNWClhghGXP9nlvOlnDjUkmacEYeq5ItnCQjYPl4uwh9fBJ9CD/8LV K+Tn3+dgqDBek6+2HRzjGs59NzuHX8J9wVFxP7/nd+fUgaSgz+sST80O vrXlHA==
6bflkoouitlvj011i2mau7ql5pk61sks.gov.in. 300 IN    RRSIG NSEC3 13 3 300 20250718141148 20250619135610 22437 gov.in. raWzWsQnPkXYtr2v1SRH/fk2dEAv/K85NH+06pNUwkxPxQk01nS8eYlq BPQ41b26kikg8mNOgr2ULlBpJHb1OQ==
couldn't get address for 'ns18.maharashtra.gov.in': not found
couldn't get address for 'ns20.maharashtra.gov.in': not found
;; Received 1171 bytes from 2620:171:813:1534:8::1#53(ns10.trs-dns.org) in 0 ms
;; communications error to 10.187.202.24#53: timed out
;; communications error to 10.187.202.28#53: timed out
;; communications error to 10.187.203.201#53: timed out
;; no servers could be reached
Quick takeaways: It s a hit or miss for this DNS query resolution.

Looking at in zone data Let s look at NS added in zone itself (with 9.9.9.9):
$ dig ns maharashtra.gov.in
; <<>> DiG 9.18.33-1~deb12u2-Debian <<>> ns maharashtra.gov.in
;; global options: +cmd
;; Got answer:
;; ->>HEADER<<- opcode: QUERY, status: NOERROR, id: 172
;; flags: qr rd ra; QUERY: 1, ANSWER: 2, AUTHORITY: 0, ADDITIONAL: 3
;; OPT PSEUDOSECTION:
; EDNS: version: 0, flags:; udp: 1232
;; QUESTION SECTION:
;maharashtra.gov.in.        IN    NS
;; ANSWER SECTION:
maharashtra.gov.in.    300    IN    NS    ns8.maharashtra.gov.in.
maharashtra.gov.in.    300    IN    NS    ns9.maharashtra.gov.in.
;; ADDITIONAL SECTION:
ns9.maharashtra.gov.in.    300    IN    A    10.187.202.24
ns8.maharashtra.gov.in.    300    IN    A    10.187.202.28
;; Query time: 180 msec
;; SERVER: 9.9.9.9#53(9.9.9.9) (UDP)
;; WHEN: Sat Jun 21 23:00:49 IST 2025
;; MSG SIZE  rcvd: 115
Pay special attention to ADDITIONAL SECTION . Running dig ns9.maharashtra.gov.in and dig ns8.maharashtra.gov.in, return RFC 1918 ie these private addresses. This is coming from zone itself, so in zone A records of NS8 and NS9 point to 10.187.202.28 and 10.187.202.24 respectively. Cloudflare s 1.1.1.1 has a slightly different version:
$ dig ns maharashtra.gov.in @1.1.1.1
; <<>> DiG 9.18.33-1~deb12u2-Debian <<>> ns maharashtra.gov.in @1.1.1.1
;; global options: +cmd
;; Got answer:
;; ->>HEADER<<- opcode: QUERY, status: NOERROR, id: 36005
;; flags: qr rd ra; QUERY: 1, ANSWER: 3, AUTHORITY: 0, ADDITIONAL: 1
;; OPT PSEUDOSECTION:
; EDNS: version: 0, flags:; udp: 1232
;; QUESTION SECTION:
;maharashtra.gov.in.        IN    NS
;; ANSWER SECTION:
maharashtra.gov.in.    300    IN    NS    ns8.
maharashtra.gov.in.    300    IN    NS    ns10.maharashtra.gov.in.
maharashtra.gov.in.    300    IN    NS    ns9.
;; Query time: 7 msec
;; SERVER: 1.1.1.1#53(1.1.1.1) (UDP)
;; WHEN: Sun Jun 22 10:38:30 IST 2025
;; MSG SIZE  rcvd: 100
Interesting response here for sure :D. The reason for difference between response from 1.1.1.1 and 9.9.9.9 is in the next section.

Looking at parent zone gov.in is the parent zone here. Tucows is operator for gov.in as well as .in ccTLD zone:
$ dig ns gov.in +short
ns01.trs-dns.net.
ns01.trs-dns.com.
ns10.trs-dns.org.
ns10.trs-dns.info.
Let s take a look at what parent zone (NS) hold:
$ dig ns maharashtra.gov.in @ns01.trs-dns.net.
; <<>> DiG 9.18.36 <<>> ns maharashtra.gov.in @ns01.trs-dns.net.
;; global options: +cmd
;; Got answer:
;; ->>HEADER<<- opcode: QUERY, status: NOERROR, id: 56535
;; flags: qr rd; QUERY: 1, ANSWER: 0, AUTHORITY: 5, ADDITIONAL: 6
;; WARNING: recursion requested but not available
;; OPT PSEUDOSECTION:
; EDNS: version: 0, flags:; udp: 1232
; COOKIE: f13027aa39632404010000006856fa2a9c97d6bbc973ba4f (good)
;; QUESTION SECTION:
;maharashtra.gov.in.        IN    NS
;; AUTHORITY SECTION:
maharashtra.gov.in.    900    IN    NS    ns8.maharashtra.gov.in.
maharashtra.gov.in.    900    IN    NS    ns18.maharashtra.gov.in.
maharashtra.gov.in.    900    IN    NS    ns10.maharashtra.gov.in.
maharashtra.gov.in.    900    IN    NS    ns9.maharashtra.gov.in.
maharashtra.gov.in.    900    IN    NS    ns20.maharashtra.gov.in.
;; ADDITIONAL SECTION:
ns20.maharashtra.gov.in. 900    IN    A    52.183.143.210
ns18.maharashtra.gov.in. 900    IN    A    35.154.30.166
ns10.maharashtra.gov.in. 900    IN    A    164.100.128.234
ns9.maharashtra.gov.in.    900    IN    A    103.23.150.89
ns8.maharashtra.gov.in.    900    IN    A    103.23.150.88
;; Query time: 28 msec
;; SERVER: 64.96.2.1#53(ns01.trs-dns.net.) (UDP)
;; WHEN: Sun Jun 22 00:00:02 IST 2025
;; MSG SIZE  rcvd: 248
The ADDITIONAL SECTION gives a completely different picture (different from in zone NSes). Maybe this was how it was supposed to be, but none of the IPs listed for NS10, NS18 and NS20 are responding to any DNS query. Assuming NS8 as 103.23.150.88 and NS9 as 103.23.150.89, checking SOA on each gives following:
$ dig soa maharashtra.gov.in @103.23.150.88 +short
ns8.maharashtra.gov.in. postmaster.maharashtra.gov.in. 2013116777 1200 600 1296000 300
$ dig soa maharashtra.gov.in @103.23.150.89 +short
ns8.maharashtra.gov.in. postmaster.maharashtra.gov.in. 2013116757 1200 600 1296000 300
NS8 (which is marked as primary in SOA) has serial 2013116777 and NS9 is on serial 2013116757, so looks like the sync (IXFR/AXFR) between primary and secondary is broken. That s why NS8 and NS9 are serving different responses, evident from the following:
$ dig ns8.maharashtra.gov.in @103.23.150.88 +short
103.23.150.88
$ dig ns8.maharashtra.gov.in @103.23.150.89 +short
10.187.202.28
$ dig ns9.maharashtra.gov.in @103.23.150.88 +short
103.23.150.89
$ dig ns9.maharashtra.gov.in @103.23.150.89 +short
10.187.202.24
$ dig ns maharashtra.gov.in @103.23.150.88 +short
ns9.
ns8.
ns10.maharashtra.gov.in.
$ dig ns maharashtra.gov.in @103.23.150.89 +short
ns9.maharashtra.gov.in.
ns8.maharashtra.gov.in.
$ dig ns10.maharashtra.gov.in @103.23.150.88 +short
10.187.203.201
$ dig ns10.maharashtra.gov.in @103.23.150.89 +short
# No/empty response ^
This is the reason for difference in 1.1.1.1 and 9.9.9.9 responses in previous section.

To summarize:
  • Primary and secondary NS aren t in sync. Serials aren t matching, while NS8 and NS9 are responding differently for same queries.
  • NSes have A records with private address, not reachable on the internet, so lame servers.
  • Incomplete NS address, not even FQDN in some cases.
  • Difference between NS delegated in parent zone and NS added in actual zone.
  • Name resolution works in very particular order (in my initial trace it failed).
Initially, I thought of citing RFCs, but I don t really think it s even required. 1.1.1.1, 8.8.8.8 and 9.9.9.9 are handling (lame servers, this probelm) well, handing out the A record for the main website, so dig maharashtra.gov.in would mostly pass and that was the reason I started this post with +trace to recurse the complete zone to show the problem. For later reference:
$ dig maharashtra.gov.in @8.8.8.8 +short
103.8.188.109

Email to SOA address I have sent the following email to address listed in SOA:
Subject - maharashtra.gov.in authoritative DNS servers not reachable Hello, I wanted to highlight the confusing state of maharashtra.gov.in authoritative DNS servers. Parent zone list following as name servers for your DNS zone:
  • ns8.maharashtra.gov.in.
  • ns18.maharashtra.gov.in.
  • ns10.maharashtra.gov.in.
  • ns9.maharashtra.gov.in.
  • ns20.maharashtra.gov.in.
Out of these, ns18 and ns20 don t have public A/AAAA records and are thus not reachable. ns10 keeps on shuffling between NO A record and 10.187.203.201 (private, not reachable address). ns8 keeps on shuffling between 103.23.150.88 and 10.187.202.28 (private, not reachable address). ns9 keeps on shuffling between 103.23.150.89 and 10.187.202.24 (private, not reachable address). These are leading to long, broken, or no DNS resolution for the website(s). Can you take a look at the problem? Regards, Sahil
I ll update here if I get a response. Hopefully, they ll listen and fix their problem.

20 June 2025

Matthew Garrett: My a11y journey

23 years ago I was in a bad place. I'd quit my first attempt at a PhD for various reasons that were, with hindsight, bad, and I was suddenly entirely aimless. I lucked into picking up a sysadmin role back at TCM where I'd spent a summer a year before, but that's not really what I wanted in my life. And then Hanna mentioned that her PhD supervisor was looking for someone familiar with Linux to work on making Dasher, one of the group's research projects, more usable on Linux. I jumped.

The timing was fortuitous. Sun were pumping money and developer effort into accessibility support, and the Inference Group had just received a grant from the Gatsy Foundation that involved working with the ACE Centre to provide additional accessibility support. And I was suddenly hacking on code that was largely ignored by most developers, supporting use cases that were irrelevant to most developers. Being in a relatively green field space sounds refreshing, until you realise that you're catering to actual humans who are potentially going to rely on your software to be able to communicate. That's somewhat focusing.

This was, uh, something of an on the job learning experience. I had to catch up with a lot of new technologies very quickly, but that wasn't the hard bit - what was difficult was realising I had to cater to people who were dealing with use cases that I had no experience of whatsoever. Dasher was extended to allow text entry into applications without needing to cut and paste. We added support for introspection of the current applications UI so menus could be exposed via the Dasher interface, allowing people to fly through menu hierarchies and pop open file dialogs. Text-to-speech was incorporated so people could rapidly enter sentences and have them spoke out loud.

But what sticks with me isn't the tech, or even the opportunities it gave me to meet other people working on the Linux desktop and forge friendships that still exist. It was the cases where I had the opportunity to work with people who could use Dasher as a tool to increase their ability to communicate with the outside world, whose lives were transformed for the better because of what we'd produced. Watching someone use your code and realising that you could write a three line patch that had a significant impact on the speed they could talk to other people is an incomparable experience. It's been decades and in many ways that was the most impact I've ever had as a developer.

I left after a year to work on fruitflies and get my PhD, and my career since then hasn't involved a lot of accessibility work. But it's stuck with me - every improvement in that space is something that has a direct impact on the quality of life of more people than you expect, but is also something that goes almost unrecognised. The people working on accessibility are heroes. They're making all the technology everyone else produces available to people who would otherwise be blocked from it. They deserve recognition, and they deserve a lot more support than they have.

But when we deal with technology, we deal with transitions. A lot of the Linux accessibility support depended on X11 behaviour that is now widely regarded as a set of misfeatures. It's not actually good to be able to inject arbitrary input into an arbitrary window, and it's not good to be able to arbitrarily scrape out its contents. X11 never had a model to permit this for accessibility tooling while blocking it for other code. Wayland does, but suffers from the surrounding infrastructure not being well developed yet. We're seeing that happen now, though - Gnome has been performing a great deal of work in this respect, and KDE is picking that up as well. There isn't a full correspondence between X11-based Linux accessibility support and Wayland, but for many users the Wayland accessibility infrastructure is already better than with X11.

That's going to continue improving, and it'll improve faster with broader support. We've somehow ended up with the bizarre politicisation of Wayland as being some sort of woke thing while X11 represents the Roman Empire or some such bullshit, but the reality is that there is no story for improving accessibility support under X11 and sticking to X11 is going to end up reducing the accessibility of a platform.

When you read anything about Linux accessibility, ask yourself whether you're reading something written by either a user of the accessibility features, or a developer of them. If they're neither, ask yourself why they actually care and what they're doing to make the future better.

comment count unavailable comments

Russell Coker: The Intel Arc B580 and PCIe Slot Size

A few months ago I bought a Intel Arc B580 for the main purpose of getting 8K video going [1]. I had briefly got it working in a test PC but then I wanted to deploy it on my HP z840 that I use as a build server and for playing with ML stuff [2]. I only did brief tests of it previously and this was my first attempt at installing it in a system I use. My plan was to keep the NVidia RTX A2000 in place and run 2 GPUs, that s not an uncommon desire among people who want to do ML stuff and it s the type of thing that the z840 is designed for, the machine has slots 2, 4, and 6 being PCIe*16 so it should be able to fit 3 cards that each take 2 slots. So having one full size GPU, the half-height A2000, and a NVMe controller that uses *16 to run four NVMe devices should be easy. Intel designed the B580 to use every millimeter of space possible while still being able to claim to be a 2 slot card. On the circuit board side there is a plastic cover over the board that takes all the space before the next slot so a 2 slot card can t go on that side without having it s airflow blocked. On the other side it takes all the available space so that any card that wants to blow air through can t fit and also such that a medium size card (such as the card for 4 NVMe devices) would block it s air flow. So it s impossible to have a computer with 6 PCIe slots run the B580 as well as 2 other full size *16 cards. Support for this type of GPU is something vendors like HP should consider when designing workstation class systems. For HP there is no issue of people installing motherboards in random cases (the HP motherboard in question uses proprietary power connectors and won t even boot with an ATX PSU without significant work). So they could easily design a motherboard and case with a few extra mm of space between pairs of PCIe slots. The cards that are double width are almost always *16 so you could pair up a *16 slot and another slot and have extra space on each side of the pair. I think for most people a system with 6 PCIe slots with a bit of extra space for GPU cooling would be more useful than having 7 PCIe slots. But as HP have full design control they don t even need to reduce the number of PCIe slots, they could just make the case taller. If they added another 4 slots and increased the case size accordingly it still wouldn t be particularly tall by the standards of tower cases from the 90s! The z8 series of workstations are the biggest workstations that HP sells so they should design them to do these things. At the time that the z840 was new there was a lot of ML work being done and HP was selling them as ML workstations, they should have known how people would use them and design them accordingly. So I removed the NVidia card and decided to run the system with just the Arc card, things should have been fine but Intel designed the card to be as high as possible and put the power connector on top. This prevented installing the baffle for directing air flow over the PCIe slots and due to the design of the z840 (which is either ingenious or stupid depending on your point of view) the baffle is needed to secure the PCIe cards in place. So now all the PCIe cards are just secured by friction in the slots, this isn t an unusual situation for machines I assemble but it s not something I desired. This is the first time I ve felt compelled to write a blog post reviewing a product before even getting it working. But the physical design of the B580 is outrageously impractical unless you are designing your entire computer around the GPU. As an aside the B580 does look very nice. The plastic surround is very fancy, it s a pity that it interferes with the operation of the rest of the system.

19 June 2025

Jonathan Carter: My first tag2upload upload

Tag2upload? The tag2upload service has finally gone live for Debian Developers in an open beta. If you ve never heard of tag2upload before, here is a great primer presented by Ian Jackson and prepared by Ian Jackson and Sean Whitton. In short, the world has moved on to hosting and working with source code in Git repositories. In Debian, we work with source packages that are used to generated the binary artifacts that users know as .deb files. In Debian, there is so much tooling and culture built around this. For example, our workflow passes what we call the island test you could take every source package in Debian along with you to an island with no Internet, and you ll still be able to rebuild or modify every package. When changing the workflows, you risk losing benefits like this, and over the years there has been a number of different ideas on how to move to a purely or partially git flow for Debian, none that really managed to gain enough momentum or project-wide support. Tag2upload makes a lot of sense. It doesn t take away any of the benefits of the current way of working (whether technical or social), but it does make some aspects of Debian packages significantly simpler and faster. Even so, if you re a Debian Developer and more familiar with how the sausage have made, you ll have noticed that this has been a very long road for the tag2upload maintainers, they ve hit multiple speed bumps since 2019, but with a lot of patience and communication and persistence from all involved (and almost even a GR), it is finally materializing.

Performing my first tag2upload So, first, I needed to choose which package I want to upload. We re currently in hard freeze for the trixie release, so I ll look for something simple that I can upload to experimental.
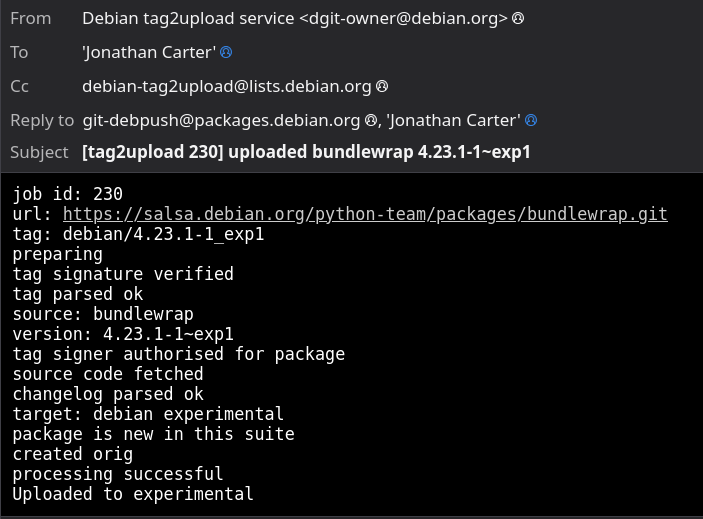
I chose bundlewrap, it s quote a straightforward python package, and updates are usually just as straightforward, so it s probably a good package to work on without having to deal with extra complexities in learning how to use tag2upload. So, I do the usual uscan and dch -i to update my package
And then I realise that I still want to build a source package to test it in cowbuilder. Hmm, I remember that Helmut showed me that building a source package isn t necessary in sbuild, but I have a habit of breaking my sbuild configs somehow, but I guess I should revisit that. So, I do a dpkg-buildpackage -S -sa and test it out with cowbuilder, because that s just how I roll (at least for now, fixing my local sbuild setup is yak shaving for another day, let s focus!). I end up with a binary that looks good, so I m satisfied that I can upload this package to the Debian archives. So, time to configure tag2upload. The first step is to set up the webhook in Salsa. I was surprised two find two webhooks already configured:
I know of KGB that posts to IRC, didn t know that this was the mechanism it does that by before. Nice! Also don t know what the tagpending one does, I ll go look into that some other time. Configuring a tag2upload webhook is quite simple, add a URL, call the name tag2upload, and select only tag push events:
I run the test webhook, and it returned a code 400 message about a missing message header, which the documentation says is normal. Next, I install git-debpush from experimental. The wiki page simply states that you can use the git-debpush command to upload, but doesn t give any examples on how to use it, and its manpage doesn t either. And when I run just git-debpush I get:
jonathan@lapcloud:~/devel/debian/python-team/bundlewrap/bundlewrap-4.23.1$ git-debpush
git-debpush: check failed: upstream tag upstream/4.22.0 is not an ancestor of refs/heads/debian/master; probably a mistake ('upstream-nonancestor' check)
pristine-tar is /usr/bin/pristine-tar
git-debpush: some check(s) failed; you can pass --force to ignore them
I have no idea what that s supposed to mean. I was also not sure whether I should tag anything to begin with, or if some part of the tag2upload machinery automatically does it. I think I might have tagged debian/4.23-1 before tagging upstream/4.23 and perhaps it didn t like it, I reverted and did it the other way around and got a new error message. Progress!
jonathan@lapcloud:~/devel/debian/python-team/bundlewrap/bundlewrap-4.23.1$ git-debpush
git-debpush: could not determine the git branch layout
git-debpush: please supply a --quilt= argument
Looking at the manpage, it looks like quilt=baredebian matches my package the best, so I try that:
jonathan@lapcloud:~/devel/debian/python-team/bundlewrap/bundlewrap-4.23.1$ git-debpush --quilt=baredebian
Enumerating objects: 70, done.
Counting objects: 100% (70/70), done.
Delta compression using up to 12 threads
Compressing objects: 100% (37/37), done.
Writing objects: 100% (37/37), 8.97 KiB   2.99 MiB/s, done.
Total 37 (delta 30), reused 0 (delta 0), pack-reused 0 (from 0)
To salsa.debian.org:python-team/packages/bundlewrap.git
6f55d99..3d5498f debian/master -> debian/master
 * [new tag] upstream/4.23.1 -> upstream/4.23.1
 * [new tag] debian/4.23.1-1_exp1 -> debian/4.23.1-1_exp1
Ooh! That looked like it did something! And a minute later I received the notification of the upload in my inbox:
So, I m not 100% sure that this makes things much easier for me than doing a dput, but, it s not any more difficult or more work either (once you know how it works), so I ll be using git-debpush from now on, and I m sure as I get more used to the git workflow of doing things I ll understand more of the benefits. And at last, my one last use case for using FTP is now properly dead. RIP FTP :)

Russell Coker: Matching Intel CPUs

To run a SMP system with multiple CPUs you need to have CPUs that are identical , the question is what does identical mean. In this case I m interested in Intel CPUs because SMP motherboards and server systems for Intel CPUs are readily available and affordable. There are people selling matched pairs of CPUs on ebay which tend to be more expensive than randomly buying 2 of the same CPU model, so if you can identify 2 CPUs that are identical which are sold separately then you can save some money. Also if you own a two CPU system with only one CPU installed then buying a second CPU to match the first is cheaper and easier than buying two more CPUs and removing a perfectly working CPU. e5-2640 v4 cpus
Intel (R) Xeon (R)
E5-2640V4
SR2NZ 2.40GHZ
J717B324 (e4)
7758S4100843
Above is a pic of 2 E5-2640v4 CPUs that were in a SMP system I purchased along with a plain ASCII representation of the text on one of them. The bottom code (starting with 77 ) is apparently the serial number, one of the two codes above it is what determines how identical those CPUs are. The code on the same line as the nominal clock speed (in this case SR2NZ) is the spec number which is sometimes referred to as sspec [1]. The line below the sspec and above the serial number has J717B324 which doesn t have a google hit. I looked at more than 20 pics of E5-2640v4 CPUs on ebay, they all had the code SR2NZ but had different numbers on the line below. I conclude that the number on the line below probably indicates the model AND stepping while SR2NZ just means E5-2640v4 regardless of stepping. As I wasn t able to find another CPU on ebay with the same number on the line below the sspec I believe that it will be unreasonably difficult to get a match for an existing CPU. For the purpose of matching CPUs I believe that if the line above the serial number matches then the CPUs can be used together. I am not certain that CPUs with this number slightly mismatching won t work but I definitely wouldn t want to spend money on CPUs with this number being different.
smpboot: CPU0: Intel(R) Xeon(R) CPU E5-2699A v4 @ 2.40GHz (family: 0x6, model: 0x4f, stepping: 0x1)
When you boot Linux the kernel identifies the CPU in a manner like the above, the combination of family and model seem to map to one spec number. The combination of family, model, and stepping should be all that s required to have them work together. I think that Intel did the wrong thing in not making this clearer. It would have been very easy to print the stepping on the CPU case next to the sspec or the CPU model name. It also wouldn t have been too hard to make the CPU provide the magic number that is apparently the required match for SMP to the OS. Having the Intel web site provide a mapping of those numbers to steppings of CPUs also shouldn t be difficult for them. If anyone knows more about these issues please let me know.

Debian Outreach Team: GSoC 2025 Introduction: Make Debian for Raspberry Pi Build Again

Hello everyone! I am Kurva Prashanth, Interested in the lower level working of system software, CPUs/SoCs and Hardware design. I was introduced to Open Hardware and Embedded Linux while studying electronics and embedded systems as part of robotics coursework. Initially, I did not pay much attention to it and quickly moved on. However, a short talk on Liberating SBCs using Debian by Yuvraj at MiniDebConf India, 2021 caught my interest. The talk focused on Open Hardware platforms such as Olimex and BeagleBone Black, as well as the Debian distributions tailored for these ARM-based single-board computers has intrigued me to delve deeper into the realm of Open Hardware and Embedded Linux. These days I m trying to improve my abilities to contribute to Debian and Linux Kernel development. Before finding out about the Google Summer of Code project, I had already started my journey with Debian. I extensively used Debian system build tools(debootstrap, sbuild, deb-build-pkg, qemu-debootstrap) for Building Debian Image for Bela Cape a real-time OS for music making to achieve extremely fast audio and sensor processing times. In 2023, I had the opportunity to attend DebConf23 in Kochi, India - thanks to Nilesh Patra (@nilesh) and I met Hector Oron (@zumbi) over dinner at DebConf23 and It was nice talking about his contributions/work at Debian on armhf port and Debian System Administration that conversation got me interested in knowing more about Debian ARM, Installer and I found it fascinating that EmDebian was once a external project bringing Debian to embedded systems and now, Debian itself can be run on many embedded systems. And, also during DebCamp I got Introduced to PGP/GPG keys and the web of trust by Carlos Henrique Lima Melara (@charles) I learned how to use and generate GPG keys. After DebConf23 I tried debian packaging and I miserably failed to get sponsorship for a python library I packaged. I came across the Debian project for this year s Google Summer of Code and found the project titled Make Debian for Raspberry Pi Build Again quite interesting to me and applied. Gladly, on May 8th, I received an acceptance e-mail from GSoC. I got excited that I ll spend the summer working on something that I like doing. I am thrilled to be part of this project and I am super excited for the summer of 25. I m looking forward to work on what I most like, new connections and learning opportunities. So, let me talk a bit more about my project. I will be working on to Make Debian for Raspberry Pi SBC s under the guidance of Gunnar Wolf (@gwolf). In this post, I will describe the project I will be working on.

Why make Debian for Raspberry Pi build again? There is an available set of images for running Debian in Raspberry Pi computers (all models below the 5 series)! However, the maintainer severely lacking time to take care for them; called for help for somebody to adopt them, but have not been successful. The image generation scripts might have bitrotted a bit, but it is mostly all done. And there is a lot of interest and use still in having the images freshly generated and decently tested! This GSoC project is about getting the [https://raspi.debian.net/ Raspberry Pi Debian images] site working reliably, daily-built images become automatic again and ideally making it easily deployable to be run in project machines and migrating exsisting hosting infrastructure to Debian.

How much it differ from Debian build process? While the goal is to stay as close as possible to the Debian build process, Raspberry Pi boards require some necessary platform-specific changes primarily in the early boot sequence and firmware handling. Unlike typical Debian systems, Raspberry Pi boards depend on a non-standard bootloader and use non-free firmware (raspi-firmware), Introducing some hardware-specific differences in the initialization process. These differences are largely confined to the early boot and hardware initialization stages. Once the system boots, the userspace remains closely aligned with a typical Debian install, using Debian packages. The current modifications are required due to non-free firmware. However, several areas merit review: but there are a few parts that might be worth changing.
  1. Boot flow: Transitioning to a U-Boot based boot process (as used in Debian installer images for many other SBCs) would reduce divergence and better align with Debian Installer.
  2. Current scripts/workarounds: Some existing hacks may now be redundant with recent upstream support and could be removed.
  3. Board-specific images: Shift to architecture-specific base images with runtime detection could simplify builds and reduce duplication.
Debian already already building SD card images for a wide range of SBCs (e.g., BeagleBone, BananaPi, OLinuXino, Cubieboard, etc.) installer-arm64/images/u-boot and installer-armhf/images/u-boot, a similar approach for Raspberry Pi could improve maintainability and consistency with Debian s broader SBC support.

Quoted from Mail Discussion Thread with Mentor (Gunnar Wolf)
"One direction we wanted to explore was whether we should still be building one image per family, or whether we could instead switch to one image per architecture (armel, armhf, arm64). There were some details to iron out as RPi3 and RPi4 were quite different, but I think it will be similar to the differences between the RPi 0 and 1, which are handled at first-boot time. To understand what differs between families, take a look at Cyril Brulebois generate-recipe (in the repo), which is a great improvement over the ugly mess I had before he contributed it"
In this project, I intend to to build one image per architecture (armel, armhf, arm64) rather than continuing with the current model of building one image per board. This change simplifies image management, reduces redundancy, and leverages dynamic configuration at boot time to support all supported boards within each architecture. By using U-Boot and flash-kernel, we can detect the board type and configure kernel parameters, DTBs, and firmware during the first boot, reducing duplication across images and simplifying the maintenance burden and we can also generalize image creation while still supporting board-specific behavior at runtime. This method aligns with existing practices in the DebianInstaller team and aligns with Debian s long-term maintainability goals and better leverages upstream capabilities, ensuring a consistent and scalable boot experience. To streamline and standardize the process of building bootable Debian images for Raspberry Pi devices, I proposed a new workflow that leverages U-Boot and flash-kernel Debian packages. This provides a clean, maintainable, and reproducible way to generate images for armel, armhf and arm64 boards. The workflow is vmdb2, a lightweight, declarative tool designed to automate the creation of disk images. A typical vmdb2 recipe defines the disk layout, base system installation (via debootstrap), architecture-specific packages, and any custom post-install hooks and the image should includes U-Boot (the u-boot-rpi package), flash-kernel, and a suitable Debian kernel package like linux-image-arm64 or linux-image-armmp. U-Boot serves as the platform s bootloader and is responsible for loading the kernel and initramfs. Unlike Raspberry Pi s non-free firmware/proprietary bootloader, U-Boot provides an open and scriptable interface, allowing us to follow a more standard Debian boot process. It can be configured to boot using either an extlinux.conf or a boot.scr script generated automatically by flash-kernel. The role of flash-kernel is to bridge Debian s kernel installation system with the specifics of embedded bootloaders like U-Boot. When installed, it automatically copies the kernel image, initrd, and device tree blobs (DTBs) to the /boot partition. It also generates the necessary boot.scr script if the board configuration demands it. To work correctly, flash-kernel requires that the target machine be identified via /etc/flash-kernel/machine, which must correspond to an entry in its internal machine database.\ Once the vmdb2 build is complete, the resulting image will contain a fully configured bootable system with all necessary boot components correctly installed. The image can be flashed to an SD card and used to boot on the intended device without additional manual configuration. Because all key packages (U-Boot, kernel, flash-kernel) are managed through Debian s package system, kernel updates and boot script regeneration are handled automatically during system upgrades.

Current Workflow: Builds one Image per family The current vmdb2 recipe uses the Raspberry Pi GPU bootloader provided via the raspi-firmware package. This is the traditional boot process followed by Raspberry Pi OS, and it s tightly coupled with firmware files like bootcode.bin, start.elf, and fixup.dat. These files are installed to /boot/firmware, which is mounted from a FAT32 partition labeled RASPIFIRM. The device tree files (*.dtb) are manually copied from /usr/lib/linux-image-*-arm64/broadcom/ into this partition. The kernel is installed via the linux-image-arm64 package, and the boot arguments are injected by modifying /boot/firmware/cmdline.txt using sed commands. Booting depends on the root partition being labeled RASPIROOT, referenced through that file. There is no bootloader like UEFI-based or U-Boot involved the Raspberry Pi firmware directly loads the kernel, which is standard for Raspberry Pi boards.
- apt: install
  packages:
    ...
    - raspi-firmware  
The boot partition contents and kernel boot setup are tightly controlled via scripting in the recipe. Limitations of Current Workflow: While this setup works, it is
  1. Proprietary and Raspberry Pi specific It relies on the closed-source GPU bootloader the raspi-firmware package, which is tightly coupled to specific Raspberry Pi models.
  2. Manual DTB handling Device tree files are manually copied and hardcoded, making upgrades or board-specific changes error-prone.
  3. Not easily extendable to future Raspberry Pi boards Any change in bootloader behavior (as seen in the Raspberry Pi 5, which introduces a more flexible firmware boot process) would require significant rework.
  4. No UEFI-based/U-Boot The current method bypasses the standard bootloader layers, making it inconsistent with other Debian ARM platforms and harder to maintain long-term.
As Raspberry Pi firmware and boot processes evolve, especially with the introduction of Pi 5 and potentially Pi 6, maintaining compatibility will require more flexibility - something best delivered by adopting U-Boot and flash-kernel.

New Workflow: Building Architecture-Specific Images with vmdb2, U-Boot, flash-kernel, and Debian Kernel This workflow outlines an improved approach to generating bootable Debian images architecture specific, using vmdb2, U-Boot, flash-kernel, and Debian kernels and also to move away from Raspberry Pi s proprietary bootloader to a fully open-source boot process which improves maintainability, consistency, and cross-board support.

New Method: Shift to U-Boot + flash-kernel U-Boot (via Debian su-boot-rpi package) and flash-kernel bring the image building process closer to how Debian officially boots ARM devices. flash-kernel integrates with the system s initramfs and kernel packages to install bootloaders, prepare boot.scr or extlinux.conf, and copy kernel/initrd/DTBs to /boot in a format that U-Boot expects. U-Boot will be used as a second-stage bootloader, loaded by the Raspberry Pi s built-in firmware. Once U-Boot is in place, it will read standard boot scripts ( boot.scr) generated by flash-kernel, providing a Debian-compatible and board-flexible solution. Extending YAML spec for vmdb2 build with U-Boot and flash-kernel To improve an existing vmdb2 YAML spec(https://salsa.debian.org/raspi-team/image-specs/raspi_master.yaml), to integrate U-Boot, flash-kernel, and the architecture-specific Debian kernel into the image build process. By incorporating u-boot-rpi and flash-kernel from Debian packages, alongside the standard initramfs-tools, we align the image closer to Debian best practices while supporting both armhf and arm64 architectures. Below are key additions and adjustments needed in a vmdb2 YAML spec to support the workflow: Install U-Boot, flash-kernel, initramfs-tools and the architecture-specific Debian kernel.
- apt: install
  packages:
    - u-boot-rpi
    - flash-kernel
    - initramfs-tools
    - linux-image-arm64 # or linux-image-armmp for armhf 
  tag: tag-root
Replace linux-image-arm64 with the correct kernel package for specific target architecture. These packages should be added under the tag-root section in YAML spec for vmdb2 build recipe. This ensures that the necessary bootloader, kernel, and initramfs tools are included and properly configured in the image. Configure Raspberry Pi firmware to Load U-Boot Install the U-Boot binary as kernel.img in /boot/firmware we can also download and build U-Boot from source, but Debian provides tested binaries.
- shell:  
    cp /usr/lib/u-boot/rpi_4/u-boot.bin $ ROOT? /boot/firmware/kernel.img
    echo "enable_uart=1" >> $ ROOT? /boot/firmware/config.txt
  root-fs: tag-root
This makes the RPi firmware load u-boot.bin instead of the Linux kernel directly. Set Up flash-kernel for Debian-style Boot flash-kernel integrates with initramfs-tools and writes boot config suitable for U-Boot. We need to make sure /etc/flash-kernel/db contains an entry for board (most Raspberry Pi boards already supported in Bookworm). Set up /etc/flash-kernel.conf with:
- create-file: /etc/flash-kernel.conf
  contents:  
    MACHINE="Raspberry Pi 4"
    BOOTPART="/dev/disk/by-label/RASPIFIRM"
    ROOTPART="/dev/disk/by-label/RASPIROOT"
  unless: rootfs_unpacked
This allows flash-kernel to write an extlinux.conf or boot.scr into /boot/firmware. Clean up Proprietary/Non-Free Firmware Bootflow Remove the direct kernel loading flow:
- shell:  
    rm -f $ ROOT? /boot/firmware/vmlinuz*
    rm -f $ ROOT? /boot/firmware/initrd.img*
    rm -f $ ROOT? /boot/firmware/cmdline.txt
  root-fs: tag-root
Let U-Boot and flash-kernel manage kernel/initrd and boot parameters instead. Boot Flow After This Change
[SoC ROM] -> [start.elf] -> [U-Boot] -> [boot.scr] -> [Linux Kernel]
  1. This still depends on the Raspberry Pi firmware to start, but it only loads U-Boot, not Linux kernel.
  2. U-Boot gives you more flexibility (e.g., networking, boot menus, signed boot).
  3. Using flash-kernel ensures kernel updates are handled the Debian Installer way.
  4. Test with a serial console (enable_uart=1) in case HDMI doesn t show early boot logs.
Advantage of New Workflow
  1. Replaces the proprietary Raspberry Pi bootloader with upstream U-Boot.
  2. Debian-native tooling Uses flash-kernel and initramfs-tools to manage boot configuration.
  3. Consistent across boards Works for both armhf and arm64, unifying the image build process.
  4. Easier to support new boards Like the Raspberry Pi 5 and future models.
This transition will standardize a bit image-building process, making it aligned with upstream Debian Installer workflows.

vmdb2 configuration for arm64 using u-boot and flash-kernel NOTE: This is a baseline example and may require tuning.
# Raspberry Pi arm64 image using U-Boot and flash-kernel
steps:
  # ... (existing mkimg, partitions, mount, debootstrap, etc.) ...
  # Install U-Boot, flash-kernel, initramfs-tools and architecture specific kernel
  - apt: install
    packages:
      - u-boot-rpi
      - flash-kernel
      - initramfs-tools
      - linux - image - arm64 # or linux - image - armmp for armhf
    tag: tag-root
  # Install U-Boot binary as kernel.img in firmware partition
  - shell:  
      cp /usr/lib/u-boot/rpi_arm64 /u-boot.bin $ ROOT? /boot/firmware/kernel.img
      echo "enable_uart=1" >> $ ROOT? /boot/firmware/config.txt
    root-fs: tag-root
  # Configure flash-kernel for Raspberry Pi
  - create-file: /etc/flash-kernel.conf
    contents:  
      MACHINE="Generic Raspberry Pi ARM64"
      BOOTPART="/dev/disk/by-label/RASPIFIRM"
      ROOTPART="/dev/disk/by-label/RASPIROOT"
    unless: rootfs_unpacked
  # Remove direct kernel boot files from Raspberry Pi firmware
  - shell:  
      rm -f $ ROOT? /boot/firmware/vmlinuz*
      rm -f $ ROOT? /boot/firmware/initrd.img*
      rm -f $ ROOT? /boot/firmware/cmdline.txt
    root-fs: tag-root
  # flash-kernel will manage boot scripts and extlinux.conf
  # Rest of image build continues...

Required Changes to Support Raspberry Pi Boards in Debian (flash-kernel + U-Boot)

Overview of Required Changes
Component Required Task
Debian U-Boot Package Add build target for rpi_arm64 in u-boot-rpi. Optionally deprecate legacy 32-bit targets.
Debian flash-kernel Package Add or verify entries in db/all.db for Pi 4, Pi 5, Zero 2W, CM4. Ensure boot script generation works via bootscr.uboot-generic.
Debian Kernel Ensure DTBs are installed at /usr/lib/linux-image-<version>/ and available for flash-kernel to reference.

flash-kernel

Already Supported Boards in flash-kernel Debian Package https://sources.debian.org/src/flash-kernel/3.109/db/all.db/#L1700
Model Arch DTB-Id
Raspberry Pi 1 A/B/B+, Rev2 armel bcm2835-*
Raspberry Pi CM1 armel bcm2835-rpi-cm1-io1.dtb
Raspberry Pi Zero/Zero W armel bcm2835-rpi-zero*.dtb
Raspberry Pi 2B armhf bcm2836-rpi-2-b.dtb
Raspberry Pi 3B/3B+ arm64 bcm2837-*
Raspberry Pi CM3 arm64 bcm2837-rpi-cm3-io3.dtb
Raspberry Pi 400 arm64 bcm2711-rpi-400.dtb

uboot

Already Supported Boards in Debian U-Boot Package https://salsa.debian.org/installer-team/flash-kernel/-/blob/master/db/all.db

arm64 Model Arch Upstream Defconfig Debian Target - - - Raspberry Pi 3B arm64 rpi_3_defconfig rpi_3 Raspberry Pi 4B arm64 rpi_4_defconfig rpi_4 Raspberry Pi 3B/3B+/CM3/CM3+/4B/CM4/400/5B/Zero 2W arm64 rpi_arm64_defconfig rpi_arm64
armhf Model Arch Upstream Defconfig Debian Target - - - Raspberry Pi 2 armhf rpi_2_defconfig rpi_2 Raspberry Pi 3B (32-bit) armhf rpi_3_32b_defconfig rpi_3_32b Raspberry Pi 4B (32-bit) armhf rpi_4_32b_defconfig rpi_4_32b
armel Model Arch Upstream Defconfig Debian Target - - - Raspberry Pi armel rpi_defconfig rpi Raspberry Pi 1/Zero armel rpi_0_w rpi_0_w These boards are already defined in debian/rules under the u-boot-rpi source package and generates usable U-Boot binaries for corresponding Raspberry Pi models.

To-Do: Add Missing Board Support to U-Boot and flash-kernel in Debian Several Raspberry Pi models are missing from the Debian U-Boot and flash-kernel packages, even though upstream support and DTBs exist in the Debian kernel but are missing entries in the flash-kernel database to enable support for bootloader installation and initrd handling.

Boards Not Yet Supported in flash-kernel Debian Package
Model Arch DTB-Id
Raspberry Pi 3A+ (32 & 64 bit) armhf, arm64 bcm2837-rpi-3-a-plus.dtb
Raspberry Pi 4B (32 & 64 bit) armhf, arm64 bcm2711-rpi-4-b.dtb
Raspberry Pi CM4 arm64 bcm2711-rpi-cm4-io.dtb
Raspberry Pi CM 4S arm64 -
Raspberry Zero 2 W arm64 bcm2710-rpi-zero-2-w.dtb
Raspberry Pi 5 arm64 bcm2712-rpi-5-b.dtb
Raspberry Pi CM5 arm64 -
Raspberry Pi 500 arm64 -

Boards Not Yet Supported in Debian U-Boot Package
Model Arch Upstream defconfig(s)
Raspberry Pi 3A+/3B+ arm64 -, rpi_3_b_plus_defconfig
Raspberry Pi CM 4S arm64 -
Raspberry Pi 5 arm64 -
Raspberry Pi CM5 arm64 -
Raspberry Pi 500 arm64 -

So, what next? During the Community Bonding Period, I got hands-on with workflow improvements, set up test environments, and began reviewing Raspberry Pi support in Debian s U-Boot and flash-kernel and these are the logs of the project, where I provide weekly reports on the work done. You can check here: Community Bonding Period logs. My next steps include submitting patches to the u-boot and flash-kernel packages to ensure all missing Raspberry Pi entries are built and shipped. And, also to confirm the kernel DTB installation paths and make sure the necessary files are included for all Raspberry Pi variants. Finally, plan to validate changes with test builds on Raspberry Pi hardware. In parallel, I m organizing my tasks and setting up my environment to contribute more effectively. It s been exciting to explore how things work under the hood and to prepare for a summer of learning and contributing to this great community.

18 June 2025

Sergio Durigan Junior: GCC, glibc, stack unwinding and relocations A war story

I ve been meaning to write a post about this bug for a while, so here it is (before I forget the details!). First, I d like to thank a few people: I ll probably forget some details because it s been more than a week (and life at $DAYJOB moves fast), but we ll see.

The background story Wolfi OS takes security seriously, and one of the things we have is a package which sets the hardening compiler flags for C/C++ according to the best practices recommended by OpenSSF. At the time of this writing, these flags are (in GCC s spec file parlance):
*self_spec:
+ % !O:% !O1:% !O2:% !O3:% !O0:% !Os:% !0fast:% !0g:% !0z:-O2  -fhardened -Wno-error=hardened -Wno-hardened % !fdelete-null-pointer-checks:-fno-delete-null-pointer-checks  -fno-strict-overflow -fno-strict-aliasing % !fomit-frame-pointer:-fno-omit-frame-pointer  -mno-omit-leaf-frame-pointer
*link:
+ --as-needed -O1 --sort-common -z noexecstack -z relro -z now
The important part for our bug is the usage of -z now and -fno-strict-aliasing. As I was saying, these flags are set for almost every build, but sometimes things don t work as they should and we need to disable them. Unfortunately, one of these problematic cases has been glibc. There was an attempt to enable hardening while building glibc, but that introduced a strange breakage to several of our packages and had to be reverted. Things stayed pretty much the same until a few weeks ago, when I started working on one of my roadmap items: figure out why hardening glibc wasn t working, and get it to work as much as possible.

Reproducing the bug I started off by trying to reproduce the problem. It s important to mention this because I often see young engineers forgetting to check if the problem is even valid anymore. I don t blame them; the anxiety to get the bug fixed can be really blinding. Fortunately, I already had one simple test to trigger the failure. All I had to do was install the py3-matplotlib package and then invoke:
$ python3 -c 'import matplotlib'
This would result in an abortion with a coredump. I followed the steps above, and readily saw the problem manifesting again. OK, first step is done; I wasn t getting out easily from this one.

Initial debug The next step is to actually try to debug the failure. In an ideal world you get lucky and are able to spot what s wrong after just a few minutes. Or even better: you also can devise a patch to fix the bug and contribute it to upstream. I installed GDB, and then ran the py3-matplotlib command inside it. When the abortion happened, I issued a backtrace command inside GDB to see where exactly things had gone wrong. I got a stack trace similar to the following:
#0  0x00007c43afe9972c in __pthread_kill_implementation () from /lib/libc.so.6
#1  0x00007c43afe3d8be in raise () from /lib/libc.so.6
#2  0x00007c43afe2531f in abort () from /lib/libc.so.6
#3  0x00007c43af84f79d in uw_init_context_1[cold] () from /usr/lib/libgcc_s.so.1
#4  0x00007c43af86d4d8 in _Unwind_RaiseException () from /usr/lib/libgcc_s.so.1
#5  0x00007c43acac9014 in __cxxabiv1::__cxa_throw (obj=0x5b7d7f52fab0, tinfo=0x7c429b6fd218 <typeinfo for pybind11::attribute_error>, dest=0x7c429b5f7f70 <pybind11::reference_cast_error::~reference_cast_error() [clone .lto_priv.0]>)
    at ../../../../libstdc++-v3/libsupc++/eh_throw.cc:93
#6  0x00007c429b5ec3a7 in ft2font__getattr__(std::__cxx11::basic_string<char, std::char_traits<char>, std::allocator<char> >) [clone .lto_priv.0] [clone .cold] () from /usr/lib/python3.13/site-packages/matplotlib/ft2font.cpython-313-x86_64-linux-gnu.so
#7  0x00007c429b62f086 in pybind11::cpp_function::initialize<pybind11::object (*&)(std::__cxx11::basic_string<char, std::char_traits<char>, std::allocator<char> >), pybind11::object, std::__cxx11::basic_string<char, std::char_traits<char>, std::allocator<char> >, pybind11::name, pybind11::scope, pybind11::sibling>(pybind11::object (*&)(std::__cxx11::basic_string<char, std::char_traits<char>, std::allocator<char> >), pybind11::object (*)(std::__cxx11::basic_string<char, std::char_traits<char>, std::allocator<char> >), pybind11::name const&, pybind11::scope const&, pybind11::sibling const&):: lambda(pybind11::detail::function_call&)#1 ::_FUN(pybind11::detail::function_call&) [clone .lto_priv.0] ()
   from /usr/lib/python3.13/site-packages/matplotlib/ft2font.cpython-313-x86_64-linux-gnu.so
#8  0x00007c429b603886 in pybind11::cpp_function::dispatcher(_object*, _object*, _object*) () from /usr/lib/python3.13/site-packages/matplotlib/ft2font.cpython-313-x86_64-linux-gnu.so
...
Huh. Initially this didn t provide me with much information. There was something strange seeing the abort function being called right after _Unwind_RaiseException, but at the time I didn t pay much attention to it. OK, time to expand our horizons a little. Remember when I said that several of our packages would crash with a hardened glibc? I decided to look for another problematic package so that I could make it crash and get its stack trace. My thinking here is that maybe if I can compare both traces, something will come up. I happened to find an old discussion where Dann Frazier mentioned that Emacs was also crashing for him. He and I share the Emacs passion, and I totally agreed with him when he said that Emacs crashing is priority -1! (I m paraphrasing). I installed Emacs, ran it, and voil : the crash happened again. OK, that was good. When I ran Emacs inside GDB and asked for a backtrace, here s what I got:
#0  0x00007eede329972c in __pthread_kill_implementation () from /lib/libc.so.6
#1  0x00007eede323d8be in raise () from /lib/libc.so.6
#2  0x00007eede322531f in abort () from /lib/libc.so.6
#3  0x00007eede262879d in uw_init_context_1[cold] () from /usr/lib/libgcc_s.so.1
#4  0x00007eede2646e7c in _Unwind_Backtrace () from /usr/lib/libgcc_s.so.1
#5  0x00007eede3327b11 in backtrace () from /lib/libc.so.6
#6  0x000059535963a8a1 in emacs_backtrace ()
#7  0x000059535956499a in main ()
Ah, this backtrace is much simpler to follow. Nice. Hmmm. Now the crash is happening inside _Unwind_Backtrace. A pattern emerges! This must have something to do with stack unwinding (or so I thought keep reading to discover the whole truth). You see, the backtrace function (yes, it s a function) and C++ s exception handling mechanism use similar techniques to do their jobs, and it pretty much boils down to unwinding frames from the stack. I looked into Emacs source code, specifically the emacs_backtrace function, but could not find anything strange over there. This bug was probably not going to be an easy fix

The quest for a minimal reproducer Being able to easily reproduce the bug is awesome and really helps with debugging, but even better is being able to have a minimal reproducer for the problem. You see, py3-matplotlib is a huge package and pulls in a bunch of extra dependencies, so it s not easy to ask other people to just install this big package plus these other dependencies, and then run this command , especially if we have to file an upstream bug and talk to people who may not even run the distribution we re using. So I set up to try and come up with a smaller recipe to reproduce the issue, ideally something that s not tied to a specific package from the distribution. Having all the information gathered from the initial debug session, especially the Emacs backtrace, I thought that I could write a very simple program that just invoked the backtrace function from glibc in order to trigger the code path that leads to _Unwind_Backtrace. Here s what I wrote:
#include <execinfo.h>

int
main(int argc, char *argv[])
 
  void *a[4096];
  backtrace (a, 100);
  return 0;
 
After compiling it, I determined that yes, the problem did happen with this small program as well. There was only a small nuisance: the manifestation of the bug was not deterministic, so I had to execute the program a few times until it crashed. But that s much better than what I had before, and a small price to pay. Having a minimal reproducer pretty much allows us to switch our focus to what really matters. I wouldn t need to dive into Emacs or Python s source code anymore. At the time, I was sure this was a glibc bug. But then something else happened.

GCC 15 I had to stop my investigation efforts because something more important came up: it was time to upload GCC 15 to Wolfi. I spent a couple of weeks working on this (it involved rebuilding the whole archive, filing hundreds of FTBFS bugs, patching some programs, etc.), and by the end of it the transition went smooth. When the GCC 15 upload was finally done, I switched my focus back to the glibc hardening problem. The first thing I did was to yes, reproduce the bug again. It had been a few weeks since I had touched the package, after all. So I built a hardened glibc with the latest GCC and the bug did not happen anymore! Fortunately, the very first thing I thought was this must be GCC , so I rebuilt the hardened glibc with GCC 14, and the bug was there again. Huh, unexpected but very interesting.

Diving into glibc and libgcc At this point, I was ready to start some serious debugging. And then I got a message on Signal. It was one of those moments where two minds think alike: Gabriel decided to check how I was doing, and I was thinking about him because this involved glibc, and Gabriel contributed to the project for many years. I explained what I was doing, and he promptly offered to help. Yes, there are more people who love low level debugging! We spent several hours going through disassembles of certain functions (because we didn t have any debug information in the beginning), trying to make sense of what we were seeing. There was some heavy GDB involved; unfortunately I completely lost the session s history because it was done inside a container running inside an ephemeral VM. But we learned a lot. For example:
  • It was hard to actually understand the full stack trace leading to uw_init_context_1[cold]. _Unwind_Backtrace obviously didn t call it (it called uw_init_context_1, but what was that [cold] doing?). We had to investigate the disassemble of uw_init_context_1 in order to determined where uw_init_context_1[cold] was being called.
  • The [cold] suffix is a GCC function attribute that can be used to tell the compiler that the function is unlikely to be reached. When I read that, my mind immediately jumped to this must be an assertion , so I went to the source code and found the spot.
  • We were able to determine that the return code of uw_frame_state_for was 5, which means _URC_END_OF_STACK. That s why the assertion was triggering.
After finding these facts without debug information, I decided to bite the bullet and recompiled GCC 14 with -O0 -g3, so that we could debug what uw_frame_state_for was doing. After banging our heads a bit more, we found that fde is NULL at this excerpt:
// ...
  fde = _Unwind_Find_FDE (context->ra + _Unwind_IsSignalFrame (context) - 1,
                          &context->bases);
  if (fde == NULL)
     
#ifdef MD_FALLBACK_FRAME_STATE_FOR
      /* Couldn't find frame unwind info for this function.  Try a
         target-specific fallback mechanism.  This will necessarily
         not provide a personality routine or LSDA.  */
      return MD_FALLBACK_FRAME_STATE_FOR (context, fs);
#else
      return _URC_END_OF_STACK;
#endif
     
// ...
We re debugging on amd64, which means that MD_FALLBACK_FRAME_STATE_FOR is defined and therefore is called. But that s not really important for our case here, because we had established before that _Unwind_Find_FDE would never return NULL when using a non-hardened glibc (or a glibc compiled with GCC 15). So we decided to look into what _Unwind_Find_FDE did. The function is complex because it deals with .eh_frame , but we were able to pinpoint the exact location where find_fde_tail (one of the functions called by _Unwind_Find_FDE) is returning NULL:
if (pc < table[0].initial_loc + data_base)
  return NULL;
We looked at the addresses of pc and table[0].initial_loc + data_base, and found that the former fell within libgcc s text section, which the latter fell within /lib/ld-linux-x86-64.so.2 text. At this point, we were already too tired to continue. I decided to keep looking at the problem later and see if I could get any further.

Bisecting GCC The next day, I woke up determined to find what changed in GCC 15 that caused the bug to disappear. Unless you know GCC s internals like they are your own home (which I definitely don t), the best way to do that is to git bisect the commits between GCC 14 and 15. I spent a few days running the bisect. It took me more time than I d have liked to find the right range of commits to pass git bisect (because of how branches and tags are done in GCC s repository), and I also had to write some helper scripts that:
  • Modified the gcc.yaml package definition to make it build with the commit being bisected.
  • Built glibc using the GCC that was just built.
  • Ran tests inside a docker container (with the recently built glibc installed) to determine whether the bug was present.
At the end, I had a commit to point to:
commit 99b1daae18c095d6c94d32efb77442838e11cbfb
Author: Richard Biener <rguenther@suse.de>
Date:   Fri May 3 14:04:41 2024 +0200
    tree-optimization/114589 - remove profile based sink heuristics
Makes sense, right?! No? Well, it didn t for me either. Even after reading what was changed in the code and the upstream bug fixed by the commit, I was still clueless as to why this change fixed the problem (I say fixed because it may very well be an unintended consequence of the change, and some other problem might have been introduced).

Upstream takes over After obtaining the commit that possibly fixed the bug, while talking to Dann and explaining what I did, he suggested that I should file an upstream bug and check with them. Great idea, of course. I filed the following upstream bug: https://gcc.gnu.org/bugzilla/show_bug.cgi?id=120653 It s a bit long, very dense and complex, but ultimately upstream was able to find the real problem and have a patch accepted in just two days. Nothing like knowing the code base. The initial bug became: https://sourceware.org/bugzilla/show_bug.cgi?id=33088 In the end, the problem was indeed in how the linker defines __ehdr_start, which, according to the code (from elf/dl-support.c):
if (_dl_phdr == NULL)
   
    /* Starting from binutils-2.23, the linker will define the
       magic symbol __ehdr_start to point to our own ELF header
       if it is visible in a segment that also includes the phdrs.
       So we can set up _dl_phdr and _dl_phnum even without any
       information from auxv.  */


    extern const ElfW(Ehdr) __ehdr_start attribute_hidden;
    assert (__ehdr_start.e_phentsize == sizeof *GL(dl_phdr));
    _dl_phdr = (const void *) &__ehdr_start + __ehdr_start.e_phoff;
    _dl_phnum = __ehdr_start.e_phnum;
   
But the following definition is the problematic one (from elf/rtld.c):
extern const ElfW(Ehdr) __ehdr_start attribute_hidden;
This symbol (along with its counterpart, __ehdr_end) was being run-time relocated when it shouldn t be. The fix that was pushed added optimization barriers to prevent the compiler from doing the relocations. I don t claim to fully understand what was done here, and Jakub s analysis is a thing to behold, but in the end I was able to confirm that the patch fixed the bug. And in the end, it was indeed a glibc bug.

Conclusion This was an awesome bug to investigate. It s one of those that deserve a blog post, even though some of the final details of the fix flew over my head. I d like to start blogging more about these sort of bugs, because I ve encountered my fair share of them throughout my career. And it was great being able to do some debugging with another person, exchange ideas, learn things together, and ultimately share that deep satisfaction when we find why a crash is happening. I have at least one more bug in my TODO list to write about (another one with glibc, but this time I was able to get to the end of it and come up with a patch). Stay tunned. P.S.: After having published the post I realized that I forgot to explain why the -z now and -fno-strict-aliasing flags were important. -z now is the flag that I determined to be the root cause of the breakage. If I compiled glibc with every hardening flag except -z now, everything worked. So initially I thought that the problem had to do with how ld.so was resolving symbols at runtime. As it turns out, this ended up being more a symptom than the real cause of the bug. As for -fno-strict-aliasing, a Gentoo developer who commented on the GCC bug above mentioned that this OpenSSF bug had a good point against using this flag for hardening. I still have to do a deep dive on what was discussed in the issue, but this is certainly something to take into consideration. There s this very good write-up about strict aliasing in general if you re interested in understanding it better.

Next.

Previous.