Search Results: "ema"

11 January 2013

Russ Allbery: release 1.45 and multiple PGP signatures

release is the tool that I use to manage software releases. This version adds support for signing a tarball with multiple PGP keys at once. For WebAuth, we have an official signing key, but I also wanted to add my personal signature. The minimum supported version of Python was also bumped to 2.5 (see below for why). You can get the latest version from my scripts page. Normally, I wouldn't announce this to everyone, since it's a fairly minor change, except I had a question and a quick Python note. The question: how does one get GnuPG to verify multiple signatures? When I run GnuPG on the resulting detached *.asc file created by this new code, I get the following:
gpg: WARNING: multiple signatures detected.  Only the first will be checked.
gpg: Signature made Thu 10 Jan 2013 03:58:43 PM PST using RSA key ID 5736DE75
gpg: Good signature from "Russ Allbery <rra@stanford.edu>"
gpg:                 aka "Russ Allbery <rra@debian.org>"
gpg:                 aka "Russ Allbery <eagle@windlord.stanford.edu>"
gpg:                 aka "Russ Allbery <eagle@eyrie.org>"
That's nice, I suppose, but it's not as helpful as it could be. Why not verify both signatures and report all of the results? I searched both the gpg man page and the Internet for some option I'm missing, without any luck. (Searching Google for that exact message amusingly turns up lots of verbatim output from Debian repository verification and almost nothing else.) If anyone knows, send me email (rra@stanford.edu or any other convenient address), and I'll update this post with the answer. UPDATE: gpg can currently only verify multiple signatures if the signatures are from keys with the same class and digest. I was attempting this with a 2048-bit RSA key and a 1024-bit DSA key, which gpg does not support. (Yet another reason to replace the WebAuth signing key with a newly-generated key.) Thanks to Philip Martin and Bernhard R. Link for the information! The note is that, way back when I was first learning Python, one of the things that bothered me the most was the lack of safe program execution. The best available was os.spawnv(), which left something to be desired. If you too were bothered by this but don't program in Python enough to keep track of the current state of the art, there's now a subprocess module that has much saner interfaces that work properly, do reasonable things, and avoid the shell. It was added in Python 2.4, with some nicer interfaces added in Python 2.5, so it's fairly safe to use at this point.

10 January 2013

Vincent Fourmond: Introducing dvdcopy, an error-resistant command-line DVD copier

My wife likes watching DVDs a lot, which is why she borrows many from the public library. The problem is that many of those were handled by people who have no clue whatsoever about the proper handling of DVDs, which means that they are in a state ranging from moderately scratched in the best cases to properly scarred in the worst ones... xine or VLC fail miserably to read such DVDs. What's worse is that failures happen right in the middle of DVDs, which is quite frustrating !That's why I've started quite some time ago to write a small C wrapper around libdvdread to first copy the DVD files onto the disk and then read them from there. It was also an easy solution to copy files to a driveless netbook to watch the DVD there. With time, this project evolved into a neat C++ command-line utility that's able to keep track of badly read sectors and come back to them later.Today is the 0.0 release of dvdcopy. You can get the tarball there. It follows the standard autoconf dance:
~ ./configure
~ make
~ make install
Using it is as simple as running:
~ dvdcopy /dev/dvd MyMovieDirectory
If everything went fine, you're set, and you can open the directory created with vlc or xine:
~ xine dvd:// pwd /MyMovieDirectory
(yes, xine needs the full path, I haven't checked with VLC, but from what I remember, you can open DVD directories directly from a menu).If you're not that lucky and dvdcopy found some bad sectors, try reading again using
~ dvdcopy --second-pass /dev/dvd MyMovieDirectory
I found that in many cases, one or two second passes get all the sectors back. While that wasn't really the intended purpose, the fact that most copy protection schemes (in addition to CSS) are implemented using bad sectors make dvdcopy quite resistant to them.I have no plan of making a Debian package for it at the time being, but if there is demand for that, I may reconsider. Enjoy !

Raphael Geissert: Email security vs. MUAs

So much for security, when using a "smart" MUA

Also note that the https URL is now http due to the email security best practice.

9 January 2013

Petter Reinholdtsen: Lets make hardware dongles easier to use in Debian

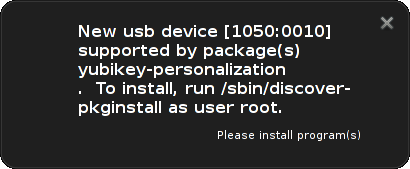
One thing that annoys me with Debian and Linux distributions in general, is that there is a great package management system with the ability to automatically install software packages by downloading them from the distribution mirrors, but no way to get it to automatically install the packages I need to use the hardware I plug into my machine. Even if the package to use it is easily available from the Linux distribution. When I plug in a LEGO Mindstorms NXT, it could suggest to automatically install the python-nxt, nbc and t2n packages I need to talk to it. When I plug in a Yubikey, it could propose the yubikey-personalization package. The information required to do this is available, but no-one have pulled all the pieces together. Some years ago, I proposed to use the discover subsystem to implement this. The idea is fairly simple: I am not sure what the best way to implement this is, but my initial idea was to use dbus events to discover new hardware, the discover database to find packages and PackageKit to install packages. Yesterday, I found time to try to implement this idea, and the draft package is now checked into the Debian Edu subversion repository. In the process, I updated the discover-data package to map the USB ids of LEGO Mindstorms and Yubikey devices to the relevant packages in Debian, and uploaded a new version 2.2013.01.09 to unstable. I also discovered that the current discover package in Debian no longer discovered any USB devices, because /proc/bus/usb/devices is no longer present. I ported it to use libusb as a fall back option to get it working. The fixed package version 2.1.2-6 is now in experimental (didn't upload it to unstable because of the freeze). With this prototype in place, I can insert my Yubikey, and get this desktop notification to show up (only once, the first time it is inserted):

For this prototype to be really useful, some way to automatically install the proposed packages by pressing the "Please install program(s)" button should to be implemented. If this idea seem useful to you, and you want to help make it happen, please help me update the discover-data database with mappings from hardware to Debian packages. Check if 'discover-pkginstall -l' list the package you would like to have installed when a given hardware device is inserted into your computer, and report bugs using reportbug if it isn't. Or, if you know of a better way to provide such mapping, please let me know. This prototype need more work, and there are several questions that should be considered before it is ready for production use. Is dbus the correct way to detect new hardware? At the moment I look for HAL dbus events on the system bus, because that is the events I could see on my Debian Squeeze KDE desktop. Are there better events to use? How should the user be notified? Is the desktop notification mechanism the best option, or should the background daemon raise a popup instead? How should packages be installed? When should they not be installed? If you want to help getting such feature implemented in Debian, please send me an email. :)

7 January 2013

Thomas Koch: searching a job: Debian, Java, Python, ...

I'm looking for a new position as a Software Developer in eastern Switzerland, southern Germany or remote. Please have a look at my CV if some of the following buzzwords sound interesting to you:

Java, Python, Debian packaging, Git, Gerrit, Eclipse, JUnit, Java QA tools, Hadoop, HBase, ZooKeeper, Lucene, REST, ATOM, HTTP, Guava, Guice, LaTeX, Emacs, OTRS, GnuPG, SSH, Web Crawling and Indexing, Big Data, Scrum, functional programming, web development (Apache Webserver, MySQL, PHP, HTML, CSS, Javascript), D, Scala, PostgreSQL, semantic technologies, XMPP

Russ Allbery: faq2html 1.31 and VCS migrations

faq2html is my version of that script that so many different people have written: a tool to convert text files into HTML for the web. This script is specifically tuned to the way that I format text files and has a lot of special logic to deal with my eccentricities, so I have no idea how well it would work for anyone else. This release adds a new -l option, which says to add a subheading to the HTML output giving the last modified date based on the file modification timestamp. Previously, these subheadings were only added in some situations and based on RCS/CVS-style Id keywords in the file. Since I'm converting my personal repositories to Git, that was going to stop working. You can get the current version of faq2html from my web tools distribution page. With this update, I was able to convert my FAQs repository from Subversion to Git, which means that I only have one personal repository left in Subversion (PGP::Sign, which I will probably convert to Git shortly). That leaves a few CVS repositories, and therein lies a problem. There are a few places where I'm still using CVS for a conventional package or for some random files, and those can move to Git without much trouble whenever I get around to it. But most of my remaining use of CVS is for storing individual scripts that, if I distribute them at all, I distribute individually. And, for that, CVS seems to have a lot of advantages that are hard to implement with Git: I'm not at all sure what I'm going to do about this. Some of my scripts currently maintained in CVS, such as all the AFS tools, should move into larger packages that are more conventionally distributed, with a separate README file and similar machinery, and I'm slowly in the process of doing that. But many of my scripts are small programs that don't fit into any larger whole and don't warrant that sort of treatment. Honestly, I'm moderately tempted to just keep using CVS for scripts, since everything newer goes to repository-wide instead of per-file version numbers (for exceptionally good reasons when working on a unified piece of software, rather than a conglomeration of individual scripts), and I'm unenthused about writing my own machinery using Git hooks and smart Git log and diff parsing. But the CVS command-line interface is awful and the CVS repository format is even worse. If there are any brilliant ideas that I'm missing, I'd be interested in hearing about them in email (or other blog posts on Planet Debian or somewhere else I read). If I come up with some solution or get any great advice, I'll post a follow-up.

5 January 2013

Ian Wienand: Position Independent Code and x86-64 libraries

A comment pointed out that the original article from 2008 made a few simplifications that were a bit misleading, so I have taken some time to update this. Thanks for the feedback. If you've ever tried to link non-position independent code into a shared library on x86-64, you should have seen a fairly cryptic error about invalid relocations and missing symbols. Hopefully this will clear it up a little. Let's start with a small program to illustrate.
int global = 100;
int function(int i)  
    return i + global;
 
Firstly, inspect the disassembley of this function:
$gcc -c function.c
$objdump --disassemble function.o
0000000000000000 <function>:
   0:   55                      push   %rbp
   1:   48 89 e5                mov    %rsp,%rbp
   4:   89 7d fc                mov    %edi,-0x4(%rbp)
   7:   8b 05 00 00 00 00       mov    0x0(%rip),%eax        # d <function+0xd>
   d:   03 45 fc                add    -0x4(%rbp),%eax
  10:   c9                      leaveq
  11:   c3                      retq
Lets just go through that for clarity: The IP relative move is really the trick here. We know from the code that it has to move the value of the global variable here. The zero value is simply a place holder - the compiler currently does not determine the required address (i.e. how far away from the instruction pointer the memory holding the global variable is). It leaves behind a relocation -- a note that says to the linker "you should determine the correct address of foo (global in our case), and then patch this bit of the code to point to that addresss". Relocations with addend The top portion of the image above gives some idea of how it works. We can examine relocations in binaries with the readelf tool.
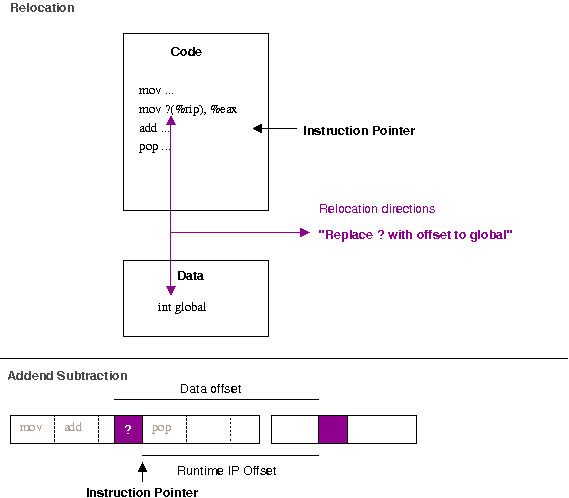
$ readelf --relocs ./function.o
Relocation section '.rela.text' at offset 0x518 contains 1 entries:
  Offset          Info           Type           Sym. Value    Sym. Name + Addend
000000000009  000800000002 R_X86_64_PC32     0000000000000000 global + fffffffffffffffc
There are many different types of relocations for different situations; the exact rules for different relocation types are described in the ABI documentation for the architecture. The R_X86_64_PC32 relocation is defined as "the base of the section the symbol is within, plus the symbol value, plus the addend". The addend makes it look more tricky than it is; remember that when an instruction is executing the instruction pointer points to the next instruction to be executed. Therefore, to correctly find the data relative to the instruction pointer, we need to subtract the extra. This can be seen more clearly when layed out in a linear fashion (as in the bottom of the above diagram). If you try and build a shared object (dynamic library) with an object file with this type of relocation, you should get something like:
$ gcc -shared function.c
/usr/bin/ld: /tmp/ccQ2ttcT.o: relocation R_X86_64_32 against  a local symbol' can not be used when making a shared object; recompile with -fPIC
/tmp/ccQ2ttcT.o: could not read symbols: Bad value
collect2: ld returned 1 exit status
If you look back at the disassembly, we notice that the R_X86_64_32 relocation has left only 4-bytes (32-bits) of space left for the relocation entry (the zeros in 7: 8b 15 00 00 00 00). So why does this matter when you're creating a shared library? The first thing to remember is that in a shared library situation, we can not depend on the local value of global actually being the one we want. Consider the following example, where we override the value of global with a LD_PRELOAD library.
$ cat function.c
int global = 100;
int function(int i)  
    return i + global;
 
$ gcc -fPIC -shared -o libfunction.so function.c
$ cat preload.c
int global = 200;
$ gcc -shared preload.c -o libpreload.so
$ cat program.c
#include <stdio.h>
int function(int i);
int main(void)  
   printf("%d\n", function(10));
 
$ gcc -L. -lfunction program.c -o program
$ LD_LIBRARY_PATH=. ./program
110
$ LD_PRELOAD=libpreload.so LD_LIBRARY_PATH=. ./program
210
If the code in libfunction.so were to have a fixed offset into its own data section, it will not be able to be overridden at run-time by the value provided by libpreload.so. Additionally, there are only 4-bytes available to patch in for the address of global -- since a shared library could conceivably be loaded anywhere in the 64-bit (8-byte) address space we therefore need 8-bytes of space to cover ourselves for all possible addresses global might turn up at. The two basic possibilities for an object file are to be either linked into an executable or linked into a shared-library. In the executable case, the value of global will be in the exectuable's data section, which should definitely be reachable with a 32-bit offset of the current instruction-pointer. The instruction-pointer relative address can simply be patched in and the executable is finalised. But what about the shared-library case, where we know the value of global could essentially be anywhere within the 64-bit address space? It is possible to leave 8-bytes of space for the address of global, by telling gcc to use the large-code model. e.g.
$ gcc -c -mcmodel=large function.c
$ objdump --disassemble ./function.o
./function.o:     file format elf64-x86-64
Disassembly of section .text:
0000000000000000 <function>:
   0:  55                      push   %rbp
   1:  48 89 e5                mov    %rsp,%rbp
   4:  89 7d fc                mov    %edi,-0x4(%rbp)
   7:  48 b8 00 00 00 00 00    movabs $0x0,%rax
   e:  00 00 00
  11:  8b 10                   mov    (%rax),%edx
  13:  8b 45 fc                mov    -0x4(%rbp),%eax
  16:  01 d0                   add    %edx,%eax
  18:  5d                      pop    %rbp
  19:  c3                      retq
However, this creates a problem if you really want to share this code. By having to patch in an address of global directly, this means the run-time code above does not remain unchanged. Two separate processes therefore can't share this code -- they each need separate copies that are identical but for their own addresses of global patched into it. By enabling Position Independent Code (PIC, with the flag -fPIC) you can ensure the code remains share-able. PIC means that the output binary does not expect to be loaded at a particular base address, but is happy being put anywhere in memory (compare the output of readelf --segments on a binary such as /bin/ls to that of any shared library). This is obviously critical for implementing lazy-loading (i.e. only loaded when required) shared-libraries, where you may have many libraries loaded in essentially any order at any location. Of course, any problem in computer science can be solved with a layer of abstraction and that is essentially what is done when compiling with -fPIC. To examine this case, let's see what happens with PIC turned on.
$ gcc -fPIC -shared -c  function.c
$ objdump --disassemble ./function.o
./function.o:     file format elf64-x86-64
Disassembly of section .text:
0000000000000000 <function>:
   0:   55                      push   %rbp
   1:   48 89 e5                mov    %rsp,%rbp
   4:   89 7d fc                mov    %edi,-0x4(%rbp)
   7:   48 8b 05 00 00 00 00    mov    0x0(%rip),%rax        # e <function+0xe>
   e:   8b 00                   mov    (%rax),%eax
  10:   03 45 fc                add    -0x4(%rbp),%eax
  13:   c9                      leaveq
  14:   c3                      retq
It's almost the same! We setup the frame pointer with the first two instructions as before. We push the first argument into memory in the pre-allocated "red-zone" as before. Then, however, we do an IP relative load of an address into rax. Next we de-reference this into eax (e.g. eax = *rax in C) before adding the incoming argument to it and returning.
$ readelf --relocs ./function.o
Relocation section '.rela.text' at offset 0x550 contains 1 entries:
  Offset          Info           Type           Sym. Value    Sym. Name + Addend
00000000000a  000800000009 R_X86_64_GOTPCREL 0000000000000000 global + fffffffffffffffc
The magic here is again in the relocations. Notice this time we have a P_X86_64_GOTPCREL relocation. This says "replace the data at offset 0xa with the global offset table (GOT) entry of global. Global Offset Table operation with data variables As shown above, the GOT ensures the abstraction required so symbols can be diverted as expected. Each entry is essentially a pointer to the real data (hence the extra dereference in the code above). Since we can assume the GOT is at a fixed offset from the program code within plus or minus 2Gib, the code can use a 32-bit IP relative address to gain access to the table entries. So, taking a look a the final shared-library binary we see a final offset hard-coded
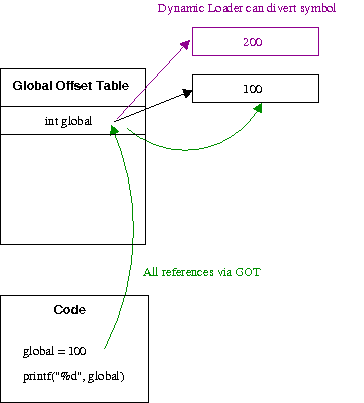
$ gcc -shared -fPIC -o libfunction.so function.c
$ objdump --disassemble ./libfunction.so
00000000000006b0 <function>:
 6b0:  55                      push   %rbp
 6b1:  48 89 e5                mov    %rsp,%rbp
 6b4:  89 7d fc                mov    %edi,-0x4(%rbp)
 6b7:  48 8b 05 8a 02 20 00    mov    0x20028a(%rip),%rax        # 200948 <_DYNAMIC+0x1d8>
 6be:  8b 10                   mov    (%rax),%edx
 6c0:  8b 45 fc                mov    -0x4(%rbp),%eax
 6c3:  01 d0                   add    %edx,%eax
 6c5:  5d                      pop    %rbp
 6c6:  c3                      retq
 6c7:  90                      nop
Every process who wants to share this code just needs to make sure they have their unique address of global at 0x20028a(%rip). Since each process has a separate address-space, this means they can all have different values for global but share the same code! Thus the default of the small-code model is sensible. It is exceedingly rare for an executable to need more than 4-byte offsets for a relative access to a variable in it's data region, so using a full 8-byte value would just be a waste of space. Although leaving 8-bytes would allow access to the variable anywhere in the 64-bit address space; when building a shared library, you really want to use -fPIC to ensure the library can actually be shared, which introduces a different relocation and access to data via the GOT. This should explain why gcc -shared function.c works on x86-32, but does not work on x86-64. Inspecting the code reveals why:
$ objdump --disassemble ./function.o
00000000 <function>:
   0:   55                      push   %ebp
   1:   89 e5                   mov    %esp,%ebp
   3:   a1 00 00 00 00          mov    0x0,%eax
   8:   03 45 08                add    0x8(%ebp),%eax
   b:   5d                      pop    %ebp
   c:   c3                      ret
$ readelf --relocs ./function.o
Relocation section '.rel.text' at offset 0x2ec contains 1 entries:
 Offset     Info    Type            Sym.Value  Sym. Name
00000004  00000701 R_386_32          00000000   global
We start out the same, with the first two instructions setting up the frame pointer. However, next we load a memory value into eax -- as we can see from the relocation information, the address of global. Next we add the incoming argument from the stack (0x8(%ebp)) to the value in this memory location; implicitly dereferencing it. But since we only have a 32-bit address-space, the 4-bytes allocated is enough to access any possible address. So while this can work, you're not creating position-independent code and hence not enabling code-sharing. The disadvantage of PIC code is that you require "bouncing" through the GOT, which requires more loads and reads to find an address than directly referencing it. However, if your program is at the point that this is becoming a performance issue you're probably not reading this blog! Hopefully, this helps clear up that possibly cryptic error message. Further searches around position-independent code, global-offset tables and code-sharing should also yield you more information if it remains unclear.

4 January 2013

Thorsten Glaser: on the linguistic gender of hosts, with an xz reminder

Let s start a convention: bare-metal machines have the linguistic male gender ( der Computer , he needs to be rebooted), whereas VMs have the linguistic female gender ( die virtuelle Maschine , she runs better since the last upgrade of Linux-KVM), and neutral linguistic gender is used when you cannot or do not want or need to make such distinction.
This is, of course, entirely unrelated to human gender, but not unrelated to #debian-68k (on OFTC) discussions ;-) ObRant: DO NOT USE xz COMPRESSION LEVELS ABOVE 6! (For -7 we can make exceptions, for example in Debian *-dbg or *-source packages.) You may use -e if you absolutely need the better compression, but please think of the poor sods who have to create the archives. You must not use the highest compression levels -8 or -9 since they have absolutely insane memory requirements on compression and will still hinder machines with less RAM on decompression. (Using -e only affects CPU usage at compression time; decompression is exactly as fast and memory-consuming as without.) Furthermore, DO NOT CHOOSE A COMPRESSION LEVEL WITH A DICTIONARY SIZE MUCH LARGER THAN THE DATA TO COMPRESS, as that makes absolutely no sense and will rather worsen than improve compression. As a reminder, xz uses the following dictionary sizes: Decompression uses less than 1 MiB more than the dictionary size, but the dictionary must always be allocated wholly. (You re fine to use custom presets, but mind the RAM usage!) As a general rule, if you have something of up to 20 MiB to compress, -4 is fine, and -5 will only be better if you have similar data spread across the whole of the file instead of close to each other. When I make mksh distfiles, I instead put files close to each other that have related content, which improves compression much more nicely without penalising low-memory systems; for example, you could put documentation, Makefiles, scripts, m4(1) files, and C source code into groups before archiving, instead of doing it alphabetically. Another note on bzip2: its decompression is slow. I see no reason to use it any more, at all. Use gzip(1) if you care for compatibility or have an issue with xz not having a free copyright licence, and xz otherwise.

Ian Wienand: Tagging handbrake output for iTunes

If you rip your DVD's with a unix-y name like longish-show-name-season-01-01.m4v then the iPad and iPhone video player only shows the prefix of the file-name to it's string limit, so you only ever see longish-show-na and can never tell what episode is what in the overview list. You can edit the files in iTunes to add meta-data information, but that's annoying and non-unix-y. It is of course easy, but I went down several dead-ends with tools that didn't recognise file-extensions, corrupted files and plain didn't work. The package I had most success with is mp4v2-utils and the mp4tags utility. The help is fairly self-explanatory, but something like
mp4tags -show "Show Name" -season <season> -episode <episode> -type "tvshow"  file.m4v
will mean that when you import your file into iTunes it displays correctly as a TV show (and not a movie), is grouped correctly into series and has a name you can see. Unfortunately, it doesn't seem my Nexus 7 tablet picks up these tags. And both players interfaces remain terrible at indicating which episodes have been watched and which have not. But this has allowed me to re-visit my old box-set of Yes Minister which, despite a few odd references to Quango's still seems as relevant as ever!

1 January 2013

Craig Small: procps 3.3.6 and Mudlet 2.0

Mudlet - Graphical MUD clientYesterday was a busy Debian day for me with the release of not one but two packages. procps procps version 3.3.6 was released both as an upstream and a Debian package. While there were many bug fixes in this release, the main new feature for it was the top inspect feature. The top inspect feature allows you to run top in the normal way then you can inspect a specific process you have selected within top for more information. Examples of this include fuser or lsof type output to see what files or libraries are open but really the limit is how clever the operator is and how often you would need this information. Even scripts can be run off this feature if you have some customised or cooked output you need to see. Once the output is there, you can search for text. There will be a small hold-up with the Debian packages as the section for the library has been moved to libs, where it should be. At least I think that s why there is a delay. procps infrastructure procps currently has only an email list and a gitorious git repository. While this works most of the time, there are two main problems with this setup. The first is that the only two ways you can report bugs is send an email to the list or create a git merge request. The email has the problem with tracking and gathering history while the git sets the bar pretty high for reporting something has gone wrong. Second problem is there is no tarball file repository. gitorious does have the feature of downloading tarballs of the tag checkpoints, but this is the raw repository. When you make a tarball with make dist there are some generated files included in the tarball that don t appear in the gitorious ones, which means its not a simple for some as you expect. So I ll be creating a project for these two features soon. Not sure where they will be but I use sourceforge for both these for a few other projects so that might be where they end up. Mudlet Mudlet, the multi-user dungeon or MUD client, has finally made it to version 2.0! It looks a lot more stable and polished at least from the scripting side than the previous RC versions but has all the features that we ve come to expect with it. The most important thing is that the developers have finally put a line in the sand and said this is version 2.0 . The Debian package was uploaded yesterday and should be on its way to your local mirror soon.

Vincent Sanders: I don't drink coffee I take tea my dear, I like my toast done on one side...

Choices, options, selections if you rather. These are what set us all apart from our fellow man, perhaps it is only the appearance of free will and individuality but our world is full of choice.

In software it might be argued programming is nothing more than making thousands perhaps millions of choices which result in a list of instructions for a machine incapable of making decisions of its own.

On a more mundane level sometimes a programmer cannot make a choice suitable for all expected use cases and a user option is created. These options have become something of a cause for arguments within certain sections of the open source software community especially amongst the groups that influence the graphical user experience.

The discussion should be nuanced and varied (perhaps that is my age, or maybe I am more diplomatic than I thought?) but there seems to be little compromise on this discussion which (from an outsiders point of view) splits into two viewpoints:


The reductionist group is currently winning the argument in the popular graphical environments and seem to be removing functionality which requires user choice wherever they can find it. This results in the absurd "joke" that the UI will become a single button, which they are trying to remove.

Personally my view is that an option should be present only when an option cannot be satisfactorily selected by the computer and even then a default suitable for as many users as possible should be picked.

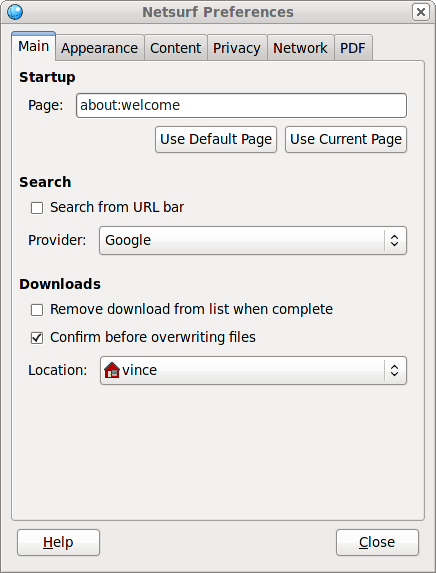
You may ask why I have raised this topic at all? well over the last few days I have been trying to fix the preferences selection for the GTK port of NetSurf. The NetSurf project follows my view on this subject pretty closely but being a browser its very difficult to do the right thing for everyone

NetSurf has numerous frontends for the core browser, I use the term frontend because in some places the toolkit and OS are conflated (windows, cocoa) and not in others (gtk). For each frontend NetSurf is a native application, this is an important distinction, the windows and widgets a user interfaces with are produced by that platforms toolkit.

Old NetSurf Preferences Dialog
This is a deliberate choice unlike other browsers which render their UI themselves as web content, this is a beguiling solution when the authors wish there to be a single browsing "experience" with a common look and feel. However NetSurf looks and feels like a native browser for each frontend, which is what the project decided it wanted to achieve.

Given this the gtk frontend (is it a Gnome application? not sure of the distinction TBH) has had no dedicated maintainer for some time it has suffered from a bad case of bitrot from both GTK library changes and general neglect.

I have slowly been improving this situation, the browser can now be compiled with GTK version 2 (2.12 onwards) or 3, the menus and other UI elements have been translated for the supported languages and now the turn has come for the options dialog.

Oh, right, its "Preferences" not options, fair enough a common semantic throughout all applications does give a degree of homogeneousness but the word choice does seem to indicate the users control has been reduced. At this point I gained an education in just how unfriendly GTK and its tools have become towards the casual programmer.

The dialog I wanted to construct was a pretty standard tabbed layout which reflected the current options and allowed the user to change them in an obvious way. Given that I have constructed and equivalent interface in idiomatic manner for cocoa and windows I thought this would be straightforward, I was very wrong.

The interface construction tool is called glade which used to be the name of the UI "resource" file and interfaces. However the tool is still called glade but the interface is now GtkBuilder which has a different (but similar) XML based file format. Then we discover that despite it being an extensible file format the UI files are specifically versioned against the GTK library. Also why on earth can these resources not be compiled into my program? OK make them over-ridable perhaps. Generally it is yet another file to distribute and update in step with the executable.

New NetSurf Properties Dialog open on Main tab
New NetSurf Preferences
So because I want to support back to version 2.12 of GTK I do not get to use any of the features from 2.16 in my UI unless I load a different UI builder file...oh and GTK3? requires a completely different version of glade and the UI files which are incompatible with gtk 2. Once this was worked round with having multiple UI files I then moved on to the next issue.

The GTK model uses function callbacks on events, these are known as signals. Perfectly reasonable but because the ui files are loaded at runtime and not compiled in there must be a way for the GTKBuilder to map the textural signal names to function pointers.

The way the GTK developers have chosen to do this is to search the global function table which means any signal handler function symbol has also to be global which means unnecessary overhead for the ELF loader increasing load times.

This lookup should have been confined to a single object or even placed in an alternative section to avoid these issues, this would not have seemed especially challenging to implement as all callback handlers have to use a preprocessor to define already (G_MODULE_EXPORT).

Another thing that makes developing GTK applications worse is the documentation, this seems to be a continuous complaint about may open source projects, which is taciturn or simply missing in many cases. GTK seems to suffer dreadfully from having multiple API versions all subtly different resulting in a lot of work on the developers part to simply find what they want.

A specific example of this is the signals and under what circumstance they occur I wanted to update all the widgets with the current configuration state whenever the options window is shown (using gtk_widget_show()) so I figured that would be the "show" signal...right? nope, never did find the right one to use, ended up with "realize" which occurs once when the dialog is created, not what I wanted, but is at least consistent and works.

NetSurf with is Properties dialog open on the content tab
NetSurf with Preferences Dialog
Overall my impression of developing just one small dialog (60 widgets total exclusing labels and containers) for a GTK program is that the toolkit and its tooling is missing the facilities to make developers life easier when doing the drudge work that a good proportion of graphical program development.

It is not the case that one cannot do things, just that everything has to be done manually instead of having the tools do the work, and because of the documentation that tedium is magnified.

I did eventually reach the stage that the thought of writing the boilerplate to add another check button to enable "do not track" had me thinking "do they really need this or can I avoid the work?" perhaps that is why they are all reductionist?


31 December 2012

Benjamin Mako Hill: Freedom for Users, Not for Software

I finally published a short essay I wrote about a year ago: Freedom for Users, Not for Software. Anybody who has hung around the free software community for a while will be familiar with the confusion created by the ambiguity between "free as in price" versus "free as freedom." In the essay I argue that there is a less appreciated semantic ambiguity that arises when we begin to think that what matters is that software is free. Software doesn't need freedom, of course; Users of software need freedom. My essay looks at how the focus on free software, as opposed to on free users, has created challenges and divisions in the free software movement. The essay was recently published in Wealth of the Commons: A World Beyond Market and State, a book edited by David Bollier and Silke Helfrich and published by Levellers Press. The book includes essays by 73 authors that include some other folks from the free software and free culture communities along with a ton of people working on very different types of commons. My essay is short and has two parts: The first is basically a short introduction to free software movement. The second lays out what I see as major challenges for free software. I will point out that these are some of the areas that I am working most closely with the FSF who are having their annual fundraiser at the moment to support and build advocacy programs around.

Joey Hess: no longer a perl programmer

This year, I've gradually realized that I no longer identify as a perl programmer. For a decade and a half, perl was the language I reached for to solve any problem that didn't have a good reason to be solved in some other language. Now I only reach for it in the occasional one-liner -- and even then I'm more likely to find myself in ghci and end up with a small haskell program. I still maintain plenty of perl code, but even when I do, I'm not thinking in perl, but traslating from some internal lambda calculus. There's quite a few new-ish perl features that I have not bothered to learn, and I can feel some of the trivia that perl encourages be kept in mind slipping gradually away. Although the evil gotchas remain fresh in my mind! More importantly, my brain's own evaluation of code has changed; it doesn't evaluate it imperatively (unless forced to by an appropriate monad), but sees the gesalt, sees the data flow, and operates lazily and sometimes, I think in parallel. The closest I can come to explaining the feeling is how you might feel when thinking about a shell pipeline, rather than a for loop. Revisiting some of my older haskell code, I could see the perl thinking that led to it. And rewriting it into pure, type-driven, code that took advantage of laziness for automatic memoization, I saw, conclusively that the way I think about code has changed. (See the difference for yourself: before after ) I hear of many people who enjoy learning lots of programming languages, one after the other. A new one every month, or year. I suspect this is a fairly shallow learning. I like to dive deep. It took me probably 6 years to fully explore every depth of perl. And I never saw a reason to do the same with python or ruby or their ilk; they're too similar to perl for it to seem worth the bother. Though they have less arcania in their learning curves and are probably better, there's not enough value to redo that process. I'm glad haskell came along as a language that is significantly different enough that it was worth learning. The deep dive for haskell goes deep indeed. I'm already 5 years in, and have more to learn now than I ever did before. I'm glad I didn't get stuck on perl. But I may be stuck on haskell now instead, for the foreseeable future. I'd sort of like to get really fluent in javascript, but only as a means to an end -- and haskell to javascript compilers are getting sufficiently good that I may avoid it. Other than that, I sense adga and coq beckoning with their promises of proof. Perhaps one of these years. Of course if Bradley Kuhn is right and perl is the new cobol, I know what I'll be doing come the unix rollover in 2038. ;)

30 December 2012

Neil McGovern: Fleeing Google

For some time, I have been concerned about the amount of data I store on Google. This post aims to show alternatives to the service. This is primarily for two reasons. The first is simple. I would like to avoid a single point of failure, and the risk that I could be suspended for a number of months with no recourse. The second if more political. I'm worried about the way that certain governments can subpoena information which they may not be able to collect directly. Now, don't get me wrong. Google is good at transparency. They also provide a very useful service that works incredibly well. In fact, the quality of the integration and services provided is the primary reason I have not changed previously. Calendaring is something that I naturally feel shouldn't be hard, but somehow is. Google Calendaring service is rather good, and far outstrips anything open source I've found so far. However, I've managed to migrate to Zoho which offers a very similar level of functionality. It's also very easy to extract your entire calendar from Google, which makes the transition easier. Reader is a service provided to subscribe and read RSS feeds. In the past, I've used Gregarius as a self hosted solution, but this seems to have disappeared recently. I briefly flirted with NetVibes, which works well once you turn off the frustrating 'widget' mode, but has completely failed to address the need to have native tablet apps. In the end, I settled for NewsBlur which also has the clever use of hotkeys for navigation which I found essential in Google's products. Picasa has stood me well for hosting photos for some time. And photo hosting is something I have quite a large amount of professional experience with :) Despite having previously been in competition with them, I can heartily recommend Flickr, even with it's dogmatic reliance to creating a Yahoo! email address for each account. Search still has some way to go to find a viable replacement. I've tried DuckDuckGo, but found it lacking. Much like the mistake that Apple seem to have made with the launch of Apple Maps, there seems to be a misunderstanding that search is actually HARD.
There are two camps when it comes to searching. You can be dumb, or you can be smart. By being dumb, the user can provide enough information to help narrow the results down to a single (or at least manageable) result set. This works fine, and is a traditional model. The opposite is to be smart. Simply get the results right, using a variety of metrics to work out what the user wanted in the first place. This is obviously more difficult, but infinitely more valuable, and is something that Google excels at. The problem lies when you fall in between these stalls. Unfortunately, it seems that there is no viable alternative to the big G at the moment.

Keith Packard: MicroPeakSerial

MicroPeak Serial Interface Flight Logging for MicroPeak MicroPeak was original designed as a simple peak-recording altimeter. It displays the maximum height of the last flight by blinking out numbers on the LED. Peak recording is fun and easy, but you need a log across apogee to check for unexpected bumps in baro data caused by ejection events. NAR also requires a flight log for altitude records. So, we wondered what could be done with the existing MicroPeak hardware to turn it into a flight logging altimeter. Logging the data The 8-bit ATtiny85 used in MicroPeak has 8kB of flash to store the executable code, but it also has 512B (yes, B as in bytes ) of eeprom storage for configuration data. Unlike the code flash, the little eeprom can be rewritten 100,000 times, so it should last for a lifetime of rocketry. The original MicroPeak firmware already used that to store the average ground pressure and minimum pressure (in Pascals) seen during flight; those are used to compute the maximum height that is shown on the LED. If we store just the two low-order bytes of the pressure data, we d have room left for 251 data points. That means capturing data at least every 32kPa, which is about 3km at sea level. 251 points isn t a whole lot of storage, but we really only need to capture the ascent and arc across apogee, which generally occurs within the first few seconds of flight. MicroPeak samples air pressure once every 96ms, if we record half of those samples, we ll have data every 192ms. 251 samples every 192ms captures 48 seconds of flight. A flight longer than that will just see the first 48 seconds. Of course, if apogee occurs after that limit, MicroPeak will still correctly record that value, it just won t have a continuous log. Downloading the data Having MicroPeak record data to the internal eeprom is pretty easy, but it s not a lot of use if you can t get the data into your computer. However, there aren t a whole lot of interfaces avaialble on MicroPeak. We ve only got: First implementation I changed the MicroPeak firmware to capture data to eeprom and made a test flight using my calibrated barometric chamber (a large syringe). I was able to read out the flight data using the AVR programming pins and got the flight logging code working that way. The plots I created looked great, but using an AVR programmer to read the data looked daunting for most people as it requires: With the hardware running at least $120 retail, and requiring a pile of software installed from various places around the net, this approach didn t seem like a great way to let people easily capture flight data from their tiny altimeter. The Blinking LED The only other interface available is the MicroPeak LED. It s a nice LED, bright and orange and low power. But, it s still just a single LED. However, it seemed like it might be possible to have it blink out the data and create a device to watch the LED and connect that to a USB port. The simplest idea I had was to just blink out the data in asynchronous serial form; a start bit, 8 data bits and a stop bit. On the host side, I could use a regular FTDI FT230 USB to serial converter chip. Those even have a 3.3V regulator and can supply a bit of current to other components on the board, eliminating the need for an external power supply. To see the LED blink, I needed a photo-transistor that actually responds to the LED s wavelength. Most photo-transistors are designed to work with infrared light, which nicely makes the whole setup invisible. There are a few photo-transistors available which do respond in the visible range, and ROHM RPM-075PT actually has its peak sensitivity right in the same range as the LED. In between the photo-transistor and the FT230, I needed a detector circuit which would send a 1 when the light was present and a 0 when it wasn t. To me, that called for a simple comparator made from an op-amp. Set the voltage on the negative input to somewhere between light and dark and then drive the positive input from the photo-transistor; the output would swing from rail to rail. Bit-banging async The ATtiny85 has only a single serial port , which is used on MicroPeak to talk to the barometric sensor in SPI mode. So, sending data out the LED requires that it be bit-banged directly modulated with the CPU. I wanted the data transmission to go reasonably fast, so I picked a rate of 9600 baud as a target. That means sending one bit every 104 S. As the MicroPeak CPU is clocked at only 250kHz, that leaves only about 26 cycles per bit. I need all of the bits to go at exactly the same speed, so I pack the start bit, 8 data bits and stop bit into a single 16 bit value and then start sending. Of course, every pass around the loop would need to take exactly the same number of cycles, so I carefully avoided any conditional code. With that, 14 of the 26 cycles were required to just get the LED set to the right value. I padded the loop with 12 nops to make up the remaining time. At 26 cycles per bit, it s actually sending data at a bit over 9600 baud, but the FT230 doesn t seem to mind. A bit of output structure I was a bit worried about the serial converter seeing other light as random data, so I prefixed the data transmission with MP ; that made it easy to ignore anything before those two characters as probably noise. Next, I decided to checksum the whole transmission. A simple 16-bit CRC would catch most small errors; it s easy enough to re-try the operation if it fails after all. Finally, instead of sending the data in binary, I displayed each byte as two hex digits, and sent some newlines along to keep the line lengths short. This makes it easy to ship flight logs in email or whatever. Here s a sample of the final data format:
MP
dc880100fec000006800f56d8f63b059
73516447273fa93728301927d91b7712
730bbf0491fe88f7c5ee8ee896e3fadc
9dd9d3d502d1afcea2cbafc6b4c34ec1
bfbfcabf10c03dc05dc070c084c08fc0
9cc0abc0b9c0c1c0ccc0dcc020c152c4
71c9a6cf45d623db7de05ee758edd9f2
b4f9fd00aa074311631a9221c4291330
c035873b2943084bbb52695c0c67eb6b
d26ee5707472fb74a4781f7dee802b84
09860a87e786ad868a866e8659865186
4e8643863e863986368638862e862d86
2f862d86298628862a86268629862686
28862886258625862486
d925
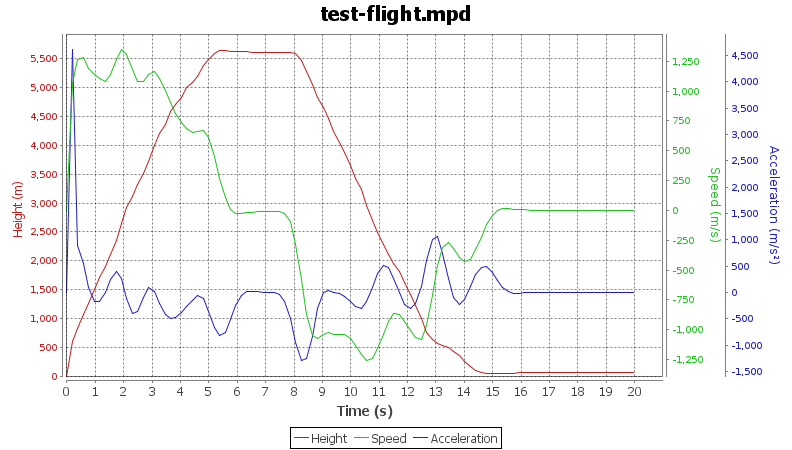
Making the photo-transistor go fast enough The photo-transistor acts as one half of a voltage divider on the positive op-amp terminal, with a resistor making the other half. However, the photo-transistor acts a bit like a capacitor, so when I initially chose a fairly large value for the resistor, it actually took too long to switch between on and off the transistor would spend a bunch of time charging and discharging. I had to reduce the resistor to 1k for the circuit to work. Remaining hardware design I prototyped the circuit on a breadboard using a through-hole op-amp that my daughter designed into her ultrasonic guided robot and a prefabricated FTDI Friend board. I wanted to use the target photo-transistor, so I soldered a couple of short pieces of wire onto the SMT pads and stuck that into the breadboard. Once I had that working, I copied the schematic to gschem, designed a board and had three made at OSHPark for the phenomenal sum of $1.35. Aside from goofing up on the FT230 USB data pins (swapping D+ and D-), the board worked perfectly. The final hardware design includes an LED connected to the output of the comparator that makes it easier to know when things are lined up correctly, otherwise it will be essentially the same. Host software Our AltosUI code has taught us a lot about delivering code that runs on Linux, Mac OS X and Windows, so I m busy developing something based on the same underlying Java bits to support MicroPeak. Here s a sample of the graph results so far: Production plans I ve ordered a couple dozen raw boards from OSH Park, and once those are here, I ll build them and make them available for sale in a couple of weeks. The current plan is to charge $35 for the MicroPeak serial interface board, or sell it bundled with MicroPeak for $75.

29 December 2012

Russell Coker: Samsung Galaxy Camera a Quick Review

I recently had a chance to briefly play with the new Samsung Galaxy Camera [1]. The Galaxy Camera is an Android device with a 4.8 display (the same size as the Samsung Galaxy S3) that has a fairly capable camera (IE nothing like a typical phone camera). It runs Android 4.1 (Jelly Bean) and the camera has 21* zoom with a 16 megapixel sensor. Camera Features It seems that professional photographers are often annoyed when they see someone with a DSLR set in auto mode. It s widely regarded that auto mode is a waste of a good camera, although the better lenses used with DSLRs will usually give a better result than any compact camera even when it s in auto mode. The problem is that photography is quite complex, in an earlier post about digital cameras I summarised some of the technical issues related to cameras and even without any great detail it became a complex issue [2]. The Galaxy Camera has a reasonably friendly GUI for changing camera settings which even includes help on some of the terms, I expect that most people who use it will end up using most of the features which could make it a good training camera for someone who is going to move to a DSLR. A DSLR version of the Galaxy Camera could also be an interesting product. The camera also has modes such as Waterfall and Panorama , hopefully the settings for those would be exposed to the user so they could devise their own similar groups of settings. I ve seen the phone criticised for the lack of physical controls as the expert mode in software is inherently slower than manually turning dials on a DSLR. But it seems obvious to me that anyone who knows how to use the controls manually should be using a DSLR or bridge camera and anyone who doesn t already know how to do such things will be better suited by the software controls. It supports 120fps video at 720*480 resolution (with a file format stating that it s 30fps to give 1/4 speed) which could be useful. I used to have a LG Viewty smart-phone that did 120fps video but the resolution was too low to be useful. 720*480 is enough resolution to see some detail and has the potential for some interesting video, one use that I ve heard of is filming athletes to allow them to analyse their performance in slow motion. It also does 60fps video at 720p (1280*720) resolution. One down-side to the device is that the lens cover doesn t seem particularly sturdy. It s quite OK for a device that will be stored in a camera case but not so good for a device that will be used as a tablet. I didn t get to poke at the lens cover (people don t like it if you mess with their Christmas presents) but it s design is a couple of thin flaps that automatically retract when the camera is enabled which looks quite weak. I d like to see something solid which doesn t look like it will slide back if the device is treated as roughly as a phone. I think that the lack of a solid lens cover could be the one factor that prevents it from being used as a replacement for a smart phone. Apart from that a Galaxy Camera and a cheap GSM phone could perform all the functions of a high end phone such as the Galaxy S3 while also producing great pictures. It would probably make sense for retailers to bundle a cheap phone with a Galaxy Camera for this purpose. Tablet Features The device boasts WiFi Direct to allow multiple cameras and phones to talk to each other without a regular WiFi access point [3]. I didn t test this and I don t think it would be particularly useful to me, but it seems like a handy feature for less technical users. It can connect to the Internet via Wifi or 3G, supports automatic upload of pictures (it comes with Dropbox support by default like the Galaxy S3), and has a suite of photo and video editing software. I don t expect that any photo editing software that runs on an Android device would be much good (I think that you really need fine cursor control with a mouse and a high resolution screen), but it would probably be handy for sending out a first draft of photos. Most Android apps should just work, the exceptions being apps that rely on a camera that faces the user or full phone functionality. So the Galaxy Camera can do almost anything that an Android phone or tablet can do. Value The RRP for the Galaxy Camera is $599, that puts it in the same price range as a DSLR with a single lens. While that s not a bad price when compared to smart-phones (it s cheaper than the LTE version of the Galaxy S3 phone) it s still quite expensive for a camera that s not a DSLR. Fortunately Kogan is selling it for $469 and has free shipping at the moment [4]. This still makes it more expensive than some of Bridge Cameras which probably have significantly better optical features, but in terms of what the typical user can do with a camera the Galaxy Camera will probably give a much better result. The sensor in the Galaxy Camera is smaller than that in the Nokia 808 PureView [5] (1/2.3 vs 1/1.2 ) so the Nokia PureView should be able to take better pictures in some situations. Unfortunately the Nokia 808 doesn t run Android, I d probably own one if it did. Some of the reviews are rather harsh, the Verge has a harsh but fair review by Aaron Souppouris which makes a number of negative comparisons to cheaper cameras [6]. I really recommend reading Aaron s review as there s a lot of good information there. But I think that Aaron is missing some things, for example he criticises the inclusion of ebook software by saying that he wouldn t read a book on a camera. But the device is a small tablet computer which also has a compact camera included. I can easily imagine someone reading a book or playing Angry Birds on their camera/tablet while in transit to where they are will photograph something. I can also imagine a Galaxy Camera being a valuable tool for a journalist who wants to be able to write short articles and upload pictures and video when out of the office. Aaron concludes by suggesting that the Galaxy Camera is a $200 camera with $300 of editing features. I think of it as $200 in camera hardware with software that allows less skilled users to take full advantage of the hardware and the ability to do all the software/Internet things that you would do on a $450+ smart-phone. Would I Buy One? No. The Galaxy Camera is among other things a great toy, I d love to have one to play with but I can t spare $469 on one. Part of the reason for this is that my wife just bought a DSLR and is getting lessons from a professional photographer, so I really won t get better pictures from a Galaxy Camera. The DSLR on auto mode will allow me to take pictures that will usually be better than a Galaxy Camera can achieve (sometimes you just can t beat a good lens). For more demanding pictures my wife can tweak the DSLR. The 120fps video is a really nice feature, I don t know if my wife s DSLR can do that, but it s a toy feature not something I really need. I ve just bought a Galaxy S3 which is a great little tablet computer (most of the time it won t be used for phone calls). I don t need another 4.8 tablet so a significant part of the use of the Galaxy Camera doesn t apply to me. I recommend the Galaxy Camera to anyone who wants to take good photos but can t get a DSLR and lessons on how to use it properly. But if you would rather get a 35mm camera with interchangeable lenses that runs Android then it might be worth waiting. I expect that the Galaxy Camera will be a great success in the market (it s something you will love when you see it). That will drive the development of similar products, if Samsung doesn t release a 35mm Android camera soon then someone else will (for example Sony develops both high end cameras and Android phones). If my wife didn t have a DSLR then I d probably have bought a Galaxy Camera already. I will recommend it to my parents and many other people I know who want an OK camera and can benefit from a tablet, but don t know how to use a DSLR properly (or don t want to carry a bulky camera).

Mike Hommey: Firefox in Debian?

Got your attention? Don t hold your breath, we re not there yet, but we re a step closer: it s now possible to build Firefox from the Iceweasel package, since version 17.0.1-2 in experimental as of writing, 18.0~b6-1 from the iceweasel-beta repository, or 19.0~a2+20121228042015-1 from the iceweasel-aurora repository. Before letting you know how you can get yourself a packaged Firefox based on the Iceweasel source, I ll remind you that redistribution of Firefox packages requires a trademark license from Mozilla, so please keep the packages you build for yourself for now. That being said, now it s clear that such Firefox packages are not official, you can still test them for yourself. First download the Iceweasel source version of your liking, and extract it, then rename all source files from iceweasel_* to firefox_* (rename s/iceweasel/firefox/ iceweasel_* should do it). Edit debian/changelog so that the first line reads:
firefox (x.y.z-r) distribution; urgency=low
instead of:
iceweasel (x.y.z-r) distribution; urgency=low
and run the following command:
$ debian/rules debian/control
Now you re all set. You can build the package the usual way. Note there are a few differences between the xulrunner packages you get from building Iceweasel vs. from building Firefox that need to be addressed, and a few other details to sort out.

Russ Allbery: Review: Dragonhaven

Review: Dragonhaven, by Robin McKinley
Publisher: Ace
Copyright: September 2007
Printing: October 2008
ISBN: 0-441-01643-X
Format: Mass market
Pages: 338
With a title like Dragonhaven from a well-established fantasy author like Robin McKinley, one's first expectations are probably some variety of medieval fantasy, perhaps with a boy or girl who encounters a rare dragon and befriends them. To some extent, those expectations are right: there is a boy, a rare dragon, and a friendship. But they're mostly wrong. Dragonhaven could easily pass for science fiction if one allowed a bit of handwaving, and the setting is contemporary. Jake is the first-person narrator and the center of this story. He lives with his father and a small group of park rangers and other scientists at Smokehill National Park, one of the few remaining reserves for dragons in the world. McKinley's world is much like ours, with the same politics and governments, except that dragons exist: huge, flying dragons that breathe fire. But they've been hunted to near-extinction, including via an actual war in Australia, and are now dwindling in a small handful of isolated reserves. No one is entirely sure how many are left since, for huge creatures, they're remarkably hard to find and document. The Smokehill staff mostly estimate them from prey kills and other indirect signs. This book is Jake's telling of his story, and McKinley goes to quite a bit of effort to find the right tone for a teenage boy. It's more verbal than written in style, with lots of capital letters, italics, tangents, digressions, and short sentences. He's also trying to tell the story in order without skipping ahead but sometimes failing, which turns into a mechanism to do foreshadowing as he slips in comments or mentions things he wasn't aware of at the time. The voice McKinley constructs is very strong and makes this book read unlike any other books of hers I've read. How much you enjoy the book will probably depend heavily on your opinion of Jake's storytelling style. The story proper starts when Jake, on his first overnight trip in the park, encounters a dying dragon and a dead poacher. This is a catastrophe for the park: the dead poacher will provide ammunition for everyone who thinks dragons are too dangerous and should be wiped out. But for Jake, it's a more immediately life-changing event. The dragon was a mother with newborn infants, one of whom has survived and who promptly bonds with Jake. This may sound like it's moving back into traditional fantasy territory, but it's not. Jake's relationship with Lois (the name he gives the baby dragon) is very unlike fantasy bonds with baby hatchlings and quite a bit like taking care of an actual infant. Except the infant is hot enough to burn the skin. And wants to be in a pouch (McKinley's dragons are marsupial, sort of) and therefore needs to crawl inside Jake's clothing and press against skin. And that's not mentioning the smell. Or the excretions. The vast majority of the book is concerned with Jake raising Lois, so you'd better be prepared for lots of description of this. Thankfully, Jake is not the sort to describe in gruesome detail (at least most of the time), and some of the description is quite funny. I was particularly fond of his account of the Smell being so intense and overwhelming that it became a third person in the room. But still, it is a lot of pages of, essentially, child-rearing, and I got tired of it before it was over. Also frustrating is that Jake obviously has never read any science fiction or fantasy. He doesn't even guess at certain aspects of the situation that are immediately obvious to any experienced SFF reader early on. One of those reveals is dragged out until nearly the end of the book. (I'll refrain from spoiling it, but I'll be very surprised if any regular reader of my reviews takes long to pick up on it.) McKinley does a good job with that part of the plot when Jake finally figures out what's going on, but it was still exasperating to have it take so long. Dragonhaven is already somewhat slow-paced due its detailed descriptions of Lois's rearing, and adding an obvious plot element that the protagonist is too dense to figure out makes the pace feel even slower. About a third of the way into this book, I didn't care for it. It was sort of gross, Lois wasn't very interesting, Jake was more frustrating than entertaining, and nothing was happening. But then it started to win me over, and the last part of the book wasn't bad at all. McKinley's best talent is her ability to mix the fantastic with the quotidian and give them equal weight and importance, to embed the reader so thoroughly with the character that one thinks about all the day-to-day impact of fantastic events that is normally skimmed over in books of this type. If you get engrossed in that angle of Jake and Lois's story, Dragonhaven can be quite enjoyable. When you're waiting for the plot to advance, it's a bit painful. Probably the best thing to do with this book, if you can, is read the first chapter or so and see what you think of Jake's voice. If you enjoy reading it, that's probably a good sign for the rest of the book. I do like McKinley's dragons: she avoids the traps of both making them too human and making them too much like animals, and manages to give Lois (once she's a bit older) a sort of intelligence that's inhuman but still canny and clearly sharper than a dog's. You'll likely get tired, as I did, of Jake's omnipresent headache and Lois's endless upbringing, but there is a payoff in the end. Rating: 7 out of 10

28 December 2012

Russ Allbery: Review: Perl Best Practices

Review: Perl Best Practices, by Damian Conway
Publisher: O'Reilly
Copyright: July 2005
Printing: April 2011
ISBN: 0-596-00173-8
Format: Trade paperback
Pages: 492
I had a rather bad first reaction to this book or, rather, the existence of this book. Some time ago, I started hearing about a new program named perlcritic that served as a lint program for Perl and decided to give it a try. I was taken aback by the flood of diagnostics, but even more taken aback by the fact that most of them were apparently explained only by a reference to a book that I didn't own. It struck me wrong in an open source project and gave me a negative reaction towards the book, which lingered for years. That was exacerbated by discovering that it recommended using use English in some circumstances, something that I consider to be a horrible idea. So, when a coworker recommended it and suggested I really should read it, I was dubious. I'm glad I gave it a chance, since it turns out that nearly all of my objections were based on misunderstandings or false information. (Well, except for the use English part, but more on that in a moment.) Perl Best Practices does provide a lot of advice, explaining that flood of diagnostics, but perlcritic also warns about the same thing repeatedly, inflating a handful of issues into a lot of messages. Most of the recommendations in Perl Best Practices were things I was doing already; most of the rest are entirely sensible. Also, perlcritic does come with complete explanations of its diagnostics once you know where they're hidden (the perldoc of Perl::Critic::Policy modules whose names you can get at by insisting perlcritic divulge them). And, even more delightfully, once I got past my objections, I discovered that Perl Best Practices is one of the best books on coding style that I've read. Coding style is a notoriously difficult subject, since nearly everyone is convinced their personal style is the best (or at least that they don't want to change). Conway acknowledges that up-front, and acknowledges that some things are just arbitrary and consistency with any rule set is better than following some specific rule set. He then spends surprisingly little time on the sorts of things that dominate most coding style discussions (indentation, spacing, commenting, etc.). Instead, this is primarily a book about how to write efficient and transparent Perl code, one that focuses much more on the content and structure of that code than on how it is indented. The best part is that there are no undefended rules here. Perl Best Practices contains 256 separate guidelines, some quite general ("Provide an optimal interface, rather than a minimal one") and some quite specific ("Pass constructor arguments as labeled values, using a hash reference"), but every one of them has a supporting argument and specific reasons behind it. Conway backs up every recommendation with code samples and practical scenarios showing the pluses and minuses of different approaches. This is a book unconcerned with being an authority; rather, it reads like optional advice from a good mentor, complete with insightful discussions on each point raised. You may come away from it disagreeing with Conway's specific recommendation (and I did, in several places), but you'll almost certainly be better-informed about the problem for having read it. Plus, this book is just fun to read. Admittedly, I love this sort of thing; I spend lots of time thinking about coding style in any language, and a lot more time refactoring coding style when working on my own projects to try to achieve clarity and simplicity. But even without sharing my love of the material, I think this book will be a delight for any practicing Perl programmer who hasn't yet read it. Conway clearly has a wealth of experience and years in the trenches of working with other people's Perl code. The examples he draws on are brief, comprehensible, and illuminating. He also gave me a tour of a variety of helper modules and libraries that I didn't know existed. List::Util is the most prominant example; this incredibly helpful supply of list manipulation functions that I've always half-known I wanted but never bothered to write is now part of Perl core (as of 5.7.3), so there's no reason to avoid it. You too can stop using grep when you actually mean first, or rewriting max in ad hoc ways. That does raise two of the rare flaws in this book, though. One is that I disagree (partially) with Conway's willingness to recommend non-core modules. He is a particular champion of the Readonly module over either normal file global variables or use constant, for very good reasons. But making Readonly a prerequisite for all other Perl code that one releases seems a bit annoying (speaking as someone who used to maintain local Perl installations). Maybe this isn't as big of a deal in these days of ubiquitous Linux distributions and willingness to use the CPAN shell, but I still dislike releasing code that depends on a half-dozen (or more) other CPAN modules for reasons of coding convenience and minor readability rather than core functionality. (His advocacy of Sub::Install raised similar objections.) The second flaw is not something Conway could have done anything about: this book is from 2005, and it's now 2012. Now, the Perl ecosystem is now quite mature, so that hampers the book much less than it would a corresponding book about Ruby or even Python. I also aim for compatibility with the oldest thing out there I know someone is still running, so I'm still hesitant to require anything newer than Perl 5.8. But still, this book was written seven years ago, and Perl is now at 5.14. In the meantime, we've seen core language features like given/when added, the addition of state variables, the need for substantial reworking of how Unicode I/O is handled, the addition of the new // operator, and the new package syntax, among many other things. The Perl taught here is a bit dated, and I would love to hear Conway's opinion about when (or if) to use say. Maybe someday we'll get a second edition. There are two other points that I do have to argue with. One is that Conway does advocate, in a limited way, use English. I could almost go along with his recommendation to use it only for those variables that one has to look up, except that in nearly every case there are other options and one can take the much better approach of simply not using those variables at all. But he then writes the remaining examples in the book using $EVAL_ERROR rather than $@, and I'm sorry, but no. One could not construct a more frustrating annoyance for an experienced Perl programmer than sending them on a futile hunt for where the global variable $EVAL_ERROR is defined. One can debate the merits of Larry Wall's original decision to use variables like $_, @_, $?, $!, and $?, but for better or ill this is Perl, and marginal readability gains for inexperienced programmers do not warrant confusing experienced programmers. This is particularly true when the use English variables are completely indistinguishable from normal global variables, and not infrequently look like a global variable that a programmer might choose. The second is more of an amusement that a real disagreement. Conway rightfully points out that Perl OO, and particularly the way that Perl stores object instance data, is awkward, and none of the commonly-used techniques are particularly satisfying. He then introduces a completely new way of doing instance data that, while having some advantages, has a very strange syntax and is utterly unlike how any OO code one finds in the wild is written. While the discussion of the problem that he's trying to solve is still interesting, I think the solutions he proposes will be more of a curiosity than a style that most programmers will adopt. But, those disagreements aside, I thoroughly enjoyed this book. I found it so engrossing that I kept reading it straight through a long train ride rather than switching to fiction halfway, like I do with most programming books. I've since recommended it to several other coworkers, and we're in the process of revising our internal Perl coding style based heavily on it. It's the sort of book that I expect to re-read several times to refresh my memory of Conway's analysis. If you've been avoiding this one due to misconceptions like I had, or because you think it might be too dry, or even just because you're afraid it's outdated, I strongly recommend it. If you're worried about the price of a printed (or electronic) book on this topic and you do Perl programming as part of your job, see if your employer will buy you a copy as training. It's worth it. I've been writing Perl professionally for more than fifteen years, and I learned a ton from this book. (And if it inspires you to change your coding style, take a look at perlcritic. It requires some configuration, and getting started is quite frustrating, but it reliably detects a surprisingly high percentage of the issues discussed here and can help a great deal in making the coding style shift stick until you can build new habits.) Rating: 9 out of 10

27 December 2012

Russ Allbery: Charity review

I'm thankfully in a place where I can afford to give money to charity, and I've slowly built up a set of charities that I give money to. But I've never been that systematic about it. I've had a vague target for how much I want to give, I add new charities when they seem neat, I'll rarely drop a charity when it doesn't seem to be effective, and I probably spread my money out too much. Recently, I followed a chain of blog references and discovered GiveWell, a site that's devoted to doing more in-depth analysis of charities than the basic financial analysis done by sites like Charity Navigator. In particular, they do literature surveys to try to dig into the effectiveness of particular interventions and take a closer look at how effectively a charity can use new donations. After reading quite a bit on their site and some related sites, I sat down yesterday and did a comprehensive review of my goals and principles and then put together a new plan. Some of that may be interesting to other people, so I'll write up that process here. This will be somewhat US-centric, since charities vary a lot by tax regime, but I think some of the general principles will still apply elsewhere. (But most of my specific examples will be US charities.) First, a few basic principles about charitable giving:
  1. Charity goals cannot be evaluated uniformly. Different types of organizations need different criteria. I've found that charities divide generally into ones that are trying to accomplish a specific task and ones that are trying to create political change. For the former, small and quiet organizations are often the best. For the latter, the charity has to get to a certain size before it's part of the conversation, and that involves a different set of tradeoffs.
  2. When you care about efficiency (number of lives saved or quality of life improvement per dollar spent), don't give money to organizations you've heard about via means other than word of mouth or third-party evaluations. This is for a simple reason: if the charity has successfully made you aware of it, that means they're advertising themselves to you. Advertising generally costs quite a bit of money. That's money they're not spending on whatever they're trying to accomplish. Excellent examples are many of the health research and education charities, such as the American Heart Association and the American Lung Association, or the massive disaster relief organizations like the American Red Cross. These are not efficient organizations. If you're trying to get the most impact for your dollar, this isn't a good place to spend it. As a special case of this, please don't ever give money to any organization that produces TV commercials showing starving children in Africa. If the commercial makes you want to give money, that's great; just don't give it to the organization on TV. TV commercials are extremely expensive, and those organizations are notorious for being some of the least efficient charities in existence (in some cases bordering on scams). You'll be lucky if 50% of your money actually goes to Africa, and the money that is spent probably isn't spent wisely.
  3. If your donation gets you a membership that comes with a glossy magazine, remember that means that the organization is spending your money producing that magazine. This is counted as program funding, not administrative costs, in sites like Charity Navigator because the charity probably counts the magazine as part of their educational mission. If you want to subscribe to the magazine and enjoy it, there's not necessarily anything wrong with this. But if you were giving them money to do something else, be aware that money is being used to produce the magazine (and the Christmas cards and the mailing labels and the tote bag) instead of doing things that you might consider program funding. For example, I stopped giving money to the Audubon Foundation because I want my environmental giving to go directly to protecting the environment, not towards printing calendars and making a glossy magazine full of bird pictures. As a counter-example, I consider the Southern Poverty Law Center to be one of the most effective US political charities, despite the fact that they produce a glossy magazine. That's because a large part of their mission is investigative reporting and research, and that magazine is how they publish that research. In this case, I both want to read the magazine and consider the magazine something that I'm happy to fund.
  4. Efficiency isn't everything. For some types of charities, the charity has to be huge in order to be effective. This is particularly true of political charities. For example, the ACLU is not a particularly efficient charity and has several fund-raising practices that I dislike. However, what the ACLU does requires that they have extensive media access and respect from legislators and the judicial system. It cannot be done effectively by a smaller and more efficient organization. Similar principles apply to a lot of political and environmental charities, and to some international aid charities such as Doctors without Borders (M decins Sans Fronti res).
If you're looking to increase the efficiency and effectiveness of your giving according to objective measures, I highly recommend reading through GiveWell's site. They recommend charities that avoid all the pitfalls above. You've probably never heard of them because they don't spend their money on advertising and marketing. However, keep in mind that efficiency isn't everything. With those principles in mind, and after doing a lot of reading on GiveWell, I redid my charity plan by dividing my giving up into five categories with different goals. Services. There are some things that I use that I think should be paid for by tax dollars but aren't, and are instead funded by charitable donations. I don't consider this charity in the same sense as the rest of this list. Rather, I'm paying for what I use plus some extra so that other people who can't afford it can use the service for free. Efficiency doesn't matter as much because there's usually only one organization supporting the thing that I personally use. Examples include my local PBS (public broadcasting) station, the non-profit that works with city government to support the local library system, and the trust that helps maintain the state parks where I go on vacation. Education. This is a special category for me since I regularly give money to the community college I attended. I know the region and the college and have some idea of what they need and what matters to the students there, so I can make specific choices. I give all the money in this category to the same place. Free software. Here, I know that my donations won't be used as efficiently in terms of quality of life as they could be if sent somewhere else, but this is my community and I want to support it because it's my community. Here, as with education, I have a lot more data and can pick and choose places that I think can use my money. Examples here are the Ada Initiative and the Free Software Foundation. Politics. This is the hardest area for efficiency, since it's so difficult to measure effectiveness in any organization where much of the goal of the organization is to persuade politicians or the general public. I try to measure effectiveness by how many concrete actions the organization takes (rather than press releases), which is easiest for organizations like the ACLU or the EFF that file lawsuits or legal documents and requests. As mentioned above, I think the standout in this area is the Southern Poverty Law Center, but political charities are so targeted that I give to multiple charities to cover my range of interests. I've found environmental charities particularly difficult to evaluate, but the one that appears the most effective to me so far is the Environmental Defense Fund, so that's where I concentrate my environmental money. I used to give to small political charities but have given up on that as basically useless, at least for national politics. I think the charity has to be of a minimum size to get anyone in government to listen to them. Poverty and Health. This is where efficiency matters much more than size. GiveWell's analysis is very interesting here, and sadly shows that most interventions either don't work or at least can't be proven to work. Here, I abandoned nearly all of my traditional large charities and have gone almost entirely with GiveWell's recommendations, with two exceptions. I still cycle money through Kiva (a microfinance support charity) because I have a bit of an emotional attachment to it, although microfinance is looking increasingly suspect as an effective charity method and I may yet drop them. And I still give money to Doctors without Borders because, despite being less efficient, I think their size and history has won them an international credibility that lets them get into areas that smaller, more efficient charities wouldn't be able to help. One of GiveWell's recommendations is my new favorite charity: GiveDirectly. All aid charities run a serious risk of having a colonialist bent, where rich countries come into poor countries and build things or tell them how to do things following the priorities of the rich countries. (This is one of the reasons why I prefer medical charities, since they're less susceptible to this.) GiveDirectly identifies the poorest people in a region (using a very transparent process) and transfers money to them directly using the M-Pesa cell system to spend however they choose, with no strings attached other than some due diligence to protect against fraud. This is refreshingly non-paternalistic and makes me far more comfortable than typical aid projects. Originally, I was going to assign money into those buckets and then break the buckets down further, but I ended up not quite doing that. The services bucket is more driven by the services I use than by an even allocation. Of the rest, it goes approximately three shares to poverty and health, two to politics, and one each to education and free software. I think I've managed to eliminate most of the places where I'm giving money to multiple organizations that do the same thing, but I'm still spreading my money rather widely and could stand to focus it more. That's hard, though; there are a lot of different things that I care about, and political charities in particular aren't very interchangeable. I'm currently not giving locally very much, which might be worth changing. The easiest way to do so would be to find a good local food bank and start donating to them (giving cash, not food). For a more comprehensive list of charities I support, see my charities link page.

Next.

Previous.