Search Results: "reg"

5 August 2013

Daniel Pocock: Effectively supporting virtual domains with Mailman

When I first decided to run my own list server, I was well aware of the popularity of Mailman but I was deterred from using it by the complexity of setting up virtual hosts. In particular, 99% of the software I use for servers is packaged. Whenever I choose a new piece of software, using something that is packaged and supported is high on my list of priorities. Mailman's distribution tarball and the packages built from it only have limited support for virtual hosting. My own objective is to host lists for open source projects. As some of these projects don't have dedicated budgets, it is particularly important to find lightweight, low-maintenance solutions. Furthermore, it is important that those solutions don't detract from the time I want to invest in the projects themselves. I've developed some scripts to solve the problem: to start using them quickly, please see the README file. Here I provide a more detailed overview of the logic behind this approach. Mailman's limitations and workarounds For me, the biggest limitation of Mailman is that the site list is always linked to a single domain, which has to be chosen arbitrarily from the list of domains being hosted. Although it is not emphasized in the documentation, there is also the inconvenience of having all the lists from potentially unrelated projects appearing together on Mailman's main index page. Another limitation is that each list name must be globally unique across all domains. Some existing workarounds exist but they have limitations too. There is a virtual domain patch, but it is not clear how this handles the site list or the site index page. There is also the postfix-to-mailman script distributed by Debian and Ubuntu: using a transport-based solution looks elegant at first, but when you realise that you need to whitelist the addresses (to ensure messages are rejected at ingress rather than bounced), it becomes just as much work to maintain as the alternatives it aims to avoid: Mailman's authors do not endorse this approach. Experimenting with Sympa Deterred by Mailman's limitations, I initially went with Sympa and that seemed to run quite well for a number of years. In particular, it supports full virtual hosting out-of-the-box and all this is standard in the convenient Debian packages. From time-to-time, users have complained about the use of JavaScript in the web UI, but that was not something I could immediately resolve. However, when I upgraded to Debian 7 (wheezy), more serious problems appeared. Initially, the web UI (used for subscribing or browsing the archives) was completely broken. Anybody accessing the site would be given a download of the wws binary rather than the page that was supposed to be generated by the binary. I discovered errors about this in Apache's error.log and tried installing libapache2-mod-fcgid. The problem was resolved, but from then on, my whole web server became unstable and at least once every day I would have to restart the Apache process or it would become inaccessible. I put the details into a bug report and after not getting any feedback, decided to go and have another look at Mailman. A closer look at Mailman Looking at Mailman again, it appeared that the only way to achieve a relatively "pure" virtual hosting solution would be to run multiple installations of Mailman in different directory trees. Initially, I hoped this could be done by sharing copies of the binaries and just creating replicas of the structure under /var/lib/mailman. Looking under the hood, I discovered that the paths were compiled into the binaries and could not be easily overriden. It appears that this limitation could be overcome with some trivial patches to read directory names from the environment. The main aims of using shared binaries are disk space efficiency and also being able to benefit from security updates for the binary packages. However, if I had to patch the binaries, then I wouldn't be able to benefit from the security update packages anyway. So, it became inevitable that I would have to build binaries from source one way or another: either with a patch or by building multiple copies of each binary, each hardcoded with a different path. Putting it into practice Looking over the Mailman architecture, there are four things to be replicated for each installation:
  • init script to start a standalone qrunner per domain
  • cron jobs
  • CGI configuration from Apache (easily isolated by using a different ScriptAlias inside each Apache <VirtualHost>
  • Invocation of the Mailman binary from the mailer's aliases file
The init scripts and crontabs can be easily generated from a template (I used Debian's copies of these files as a base for that). Some of the Apache configuration can be handled by putting wildcards in the <Directory> specifications and the rest can be easily cut-and-pasted into <VirtualHost> definitions. Based on all of the above, all I had to do was run Mailman's configure script and make once for each virtual domain. I've scripted the whole process - my script is available here Managing the aliases file One particular limitation of my mailer (Postfix) is that the Mailman message processor can't be invoked directly from a rule in the virtual alias map. Scripts like this can only be invoked from the normal /etc/aliases file. This problem is not unique to Mailman: for Sympa, I also had to deal with this. The most common solution is to use the virtual file to translate all the virtual list addresses into very verbose usernames within the local domain:
Address Mapped to
widget-users@lists.example.org lists.example.org-widget-users@my-local-domain
The local part, lists.example.org-widget-users can then be used in the regular /etc/aliases file. This approach is described in the Sympa documentation and also in one of the virtual domain patches for Mailman. I've included a script for generating these alias mappings in the repository with my other scripts for building virtual Mailman installations. It would also be possible to patch Mailman itself to generate such files dynamically when new lists are created. Conclusion and next steps Using the techniques described and these small scripts, I successfully built independent virtual hosts for two of my domains, lists.lumicall.org and lists.dynalogin.org on a single mail host. Notice how each of them has the appearance of a clean, standalone Mailman installation? Going forward, I believe it would not be hard for the 2.x branch of Mailman to support this approach to virtual hosting with three changes:
  • Allowing the binaries to take their directory tree name from an environment variable or command line option or by inspecting argv[0] to discover their own location,
  • Generating the aliases file in the more verbose format and
  • Providing some convenient init script and crontab that iterates over all the domains

4 August 2013

Francois Marier: Debugging Gearman configuration

Gearman is a queuing system that has been in Debian for a long time and is quite reliable. I ran into problems however when upgrading a server from Debian squeeze to wheezy however. Here's how I debugged my Gearman setup.

Log verbosity First of all, I started by increasing the verbosity level of the daemon by adding --verbose=INFO to /etc/default/gearman-job-server (the possible values of the verbose option are in the libgearman documentation) and restarting the daemon:
/etc/init.d/gearman-job-server restart
I opened a second terminal to keep an eye on the logs:
tail -f /var/log/gearman-job-server/gearman.log

Listing available workers Next, I registered a very simple worker:
gearman -w -f mytest cat
and made sure it was connected properly by telneting into the Gearman process:
telnet localhost 4730
and listing all currently connected workers using the workers command (one of the commands available in the Gearman TEXT protocol). There should be an entry similar to this one:
30 127.0.0.1 - : mytest
Because there are no exit or quit commands in the TEXT protocol, you need to terminate the telnet connection like this:
  1. Press Return
  2. Press Ctrl + ]
  3. Press Return
  4. Type quit at the telnet prompt and press Return.
Finally, I sent some input to the simple worker I setup earlier:
echo "hi there"   gearman -f mytest
and got my input repeated on the terminal:
hi there

Gearman bug I traced my problems down to this error message when I sent input to the worker:
gearman: gearman_client_run_tasks : connect_poll(Connection refused)
getsockopt() failed -> libgearman/connection.cc:104
It turns out that it is a known bug that was fixed upstream but still affects Debian wheezy and some versions of Ubuntu. The bug report is pretty unhelpful since the work-around is hidden away in the comments of this "invalid" answer: be explicit about the hostname and port number in both gearman calls. So I was able to make it work like this:
gearman -w -h 127.0.0.1 -p 4730 -f mytest cat    
echo "hi there"   gearman -h 127.0.0.1 -p 4730 -f mytest
where the hostname matches exactly what's in /etc/default/gearman-job-server.

Ond&#345;ej &#268;ert&iacute;k: How to support both Python 2 and 3

I'll start with the conclusion: making backwards incompatible version of a language is a terrible idea, and it was bad a mistake. This mistake was somewhat corrected over the years by eventually adding features to both Python 2.7 and 3.3 that actually allow to run a single code base on both Python versions --- which, as I show below, was discouraged by both Guido and the official Python documents (though the latest docs mention it)... Nevertheless, a single code base fixes pretty much all the problems and it actually is fun to use Python again. The rest of this post explains my conclusion in great detail. My hope is that it will be useful to other Python projects to provide tips and examples how to support both Python 2 and 3, as well as to future language designers to keep languages backwards compatible. When Python 3.x got released, it was pretty much a new language, backwards incompatible with Python 2.x, as it was not possible to run the same source code in both versions. I was extremely unhappy about this situation, because I simply didn't have time to port all my Python code to a new language. I read the official documentation about how the transition should be done, quoting:
You should have excellent unit tests with close to full coverage.
  1. Port your project to Python 2.6.
  2. Turn on the Py3k warnings mode.
  3. Test and edit until no warnings remain.
  4. Use the 2to3 tool to convert this source code to 3.0 syntax. Do not manually edit the output!
  5. Test the converted source code under 3.0.
  6. If problems are found, make corrections to the 2.6 version of the source code and go back to step 3.
  7. When it's time to release, release separate 2.6 and 3.0 tarballs (or whatever archive form you use for releases).
I've also read Guido's blog post, which repeats the above list and adds an encouraging comment:
Python 3.0 will break backwards compatibility. Totally. We're not even aiming for a specific common subset.
In other words, one has to maintain a Python 2.x code base, then run 2to3 tool to get it converted. If you want to develop using Python 3.x, you can't, because all code must be developed using 2.x. As to the actual porting, Guido says in the above post:
If the conversion tool and the forward compatibility features in Python 2.6 work out as expected, steps (2) through (6) should not take much more effort than the typical transition from Python 2.x to 2.(x+1).
So sometime in 2010 or 2011 I started porting SymPy, which is now a pretty large code base (sloccount says over 230,000 lines of code, and in January 2010 it said almost 170,000 lines). I remember spending a few full days on it, and I just gave up, because it wasn't just changing a few things, but pretty fundamental things inside the code base, and one cannot just do it half-way, one has to get all the way through and then polish it up. We ended up using one full Google Summer of Code project for it, you can read the final report. I should mention that we use metaclasses and other things, that make such porting harder. Conclusion: this was definitely not "the typical transition from Python 2.x to 2.(x+1)". Ok, after months of hard work by a lot of people, we finally have a Python 2.x code base that can be translated using the 2to3 tool and it works and tests pass in Python 3.x. The next problem is that Python 3.x is pretty much like a ghetto -- you can use it as a user, but you can't develop in it. The 2to3 translation takes over 5 minutes on my laptop, so any interactivity is gone. It is true that the tool can cache results, so the next pass is somewhat faster, but in practice this still turns out to be much much worse than any compilation of C or Fortran programs (done for example with cmake), both in terms of time and in terms of robustness. And I am not even talking about pip issues or setup.py issues regarding calling 2to3. What a big mess... Programming should be fun, but this is not fun. I'll be honest, this situation killed a lot of my enthusiasm for Python as a platform. I learned modern Fortran in the meantime and with admiration I noticed that it still compiles old F77 programs without modification and I even managed to compile a 40 year old pre-F77 code with just minimal modifications (I had to port the code to F77). Yet modern Fortran is pretty much a completely different language, with all the fancy features that one would want. Together with my colleagues I created a fortran90.org website, where you can compare Python/NumPy side by side with modern Fortran, it's pretty much 1:1 translation and a similar syntax (for numerical code), except that you need to add types of course. Yet Fortran is fully backwards compatible. What a pleasure to work with! Fast forward to last week. A heroic effort by Sean Vig who ported SymPy to single code base (#2318) was merged. Earlier this year similar pull requests by other people have converted NumPy (#3178, #3191, #3201, #3202, #3203, #3205, #3208, #3216, #3223, #3226, #3227, #3231, #3232, #3235, #3236, #3237, #3238, #3241, #3242, #3244, #3245, #3248, #3249, #3257, #3266, #3281, #3191, ...) and SciPy (#397) codes as well. Now all these projects have just one code base and it works in all Python versions (2.x and 3.x) without the need to call the 2to3 tool. Having a single code base, programming in Python is fun again. You can choose any Python version, be it 2.x or 3.x, and simply submit a patch. The patch is then tested using Travis-CI, so that it works in all Python versions. Installation has been simplified (no need to call any 2to3 tools and no more hacks to get setup.py working). In other words, this is how it should be, that you write your code once, and you can use any supported language version to run it/compile it, or develop in. But for some reason, this obvious solution has been discouraged by Guido and other Python documents, as seen above. I just looked up the latest official Python docs, and that one is not upfront negative about a single code base. But it still does not recommend this approach as the one. So let me fix that: I do recommend a single code base as the solution. The newest Python documentation from the last paragraph also mentions
Regardless of which approach you choose, porting is not as hard or time-consuming as you might initially think.
Well, I encourage you to browse through the pull requests that I linked to above for SymPy, NumPy or SciPy. I think it is very time consuming, and that's just converting from 2to3 to single code base, which is the easy part. The hard part was to actually get SymPy to work with Python 3 (as I discussed above, that took couple months of hard work), and I am pretty sure it was pretty hard to port NumPy and SciPy as well. The docs also says:
It /single code base/ does lead to code that is not entirely idiomatic Python
That is true, but our experience has been, that with every Python version that we drop, we also delete lots of ugly hacks from our code base. This has been true for dropping support for 2.3, 2.4 and 2.5, and I expect it will also be true for dropping 2.6 and especially 2.7, when we can simply use the Python 3.x syntax. So not a big deal overall. To sum this blog post up, as far as I am concerned, pretty much all the problems with supporting Python 2.x and 3.x are fixed by having a single code base. You can read the pull requests above to see how to implemented things (like metaclasses, and other fancy stuff...). Python is still quite the same language, you write your code, you use a Python version of your choice and things will just work. Not a big deal overall. The official documentation should be fixed to recommend this approach, and deprecate the other approaches. I think that Python is great and I hope it will be used more in the future.
Written with StackEdit.

3 August 2013

Russell Coker: Religious Conversion

Today I was in the center of Melbourne and I saw two stands run by Muslims advocating their faith. They had a selection of DVDs and brochures to give away and seemed friendly enough for anyone who wanted a chat. I think that this is a good thing, if the majority of the Australian population would think of the Muslim minority as people who give away DVDs rather than as potential suicide bombers then it would be a great benefit for society. Then I saw a Christian stand which had placards indicating that Jesus loves Muslims, which is fine. One of the workers on that stand then gleefully told me that there had been a Muslim stand in that area but the Muslims departed when they arrived. It would be good if advocates for the various religions could work together to promote positive things that they all agree on (generally related to being nice to other people). When they seem to be essentially bullying other religious groups into leaving the area they aren t making a good case for a kind and caring god. The Christian who was so happy about the Muslims departing then tried to convert me. He started by talking about a mobile phone not being able to appear from nothing which was the start of an utterly stupid argument about creationism. That was stupid firstly because it s obvious that evolution doesn t apply to consumer electronics, if I leave a phone lying on top of another phone overnight I m not going to get some little phones appearing as a result. But the bigger stupidity is in even promoting creationism in the first place. Advocating creationism is essentially claiming that god is so incapable that ze can t manage an evolutionary process. An all-seeing all-knowing god of infinite intelligence could just create a plasma cloud that will form into a solar system and evolve life. People who argue for creationism don t believe in a capable god, they believe in a being that resembles a god in the way a magician resembles someone who can actually perform magic. Arguing for creationism is arguing for a limited being which probably isn t worthy of worship (why worship space aliens who are probably only a few thousand years ahead of us). Regardless of the scientific evidence (which is strongly in favor of evolution) just logically thinking about the issue in regard to what a being with infinite powers might actually do suggests that ze could just as easily create or evolve all life and probably wouldn t care about what we believe. Genesis should be taken as metaphor because it s obvious that nothing that s taught in a year 7 science class could be taught to your typical stone age goat-herd, but even if it was taken literally it s not specified as a required belief (as opposed to a belief in a single god, repenting sins, and other beliefs which are required). The greatest stupidity however is the fact that even if it made any sense to promote creationism it wouldn t make sense to do so immediately. Any time you want to convert someone to a set of beliefs it s a good strategy to start with the ones which will seem least wacky. I can have have a conversation with Christians about positive things which we generally agree on such as donating to charity and trying to do good things in various ways. But when they start with the stupid stuff I walk away. When the weather is better I plan to interview representatives of the various religious groups who are trying to convert people on the street and rate them according to how wacky they are. I ll be a little limited in my ability to review them by the total lack of any right to free speech in Australia (our laws are much the same as those in the UK). But I should still be able to give them a reasonable review.

Richard Hartmann: Death of a slowly demising platform

Let's assume you have been running a platform for over a decade. Let's assume you used to be one of the cornerstones, one of the central pillars, maybe even part of the very foundation FLOSS was built upon. Let's assume you slept through several major shifts and stopped innovating a long time ago (along with your other large sister project, owned by the same people). Let's assume you realize all this. You then try and get your act together, work over your feature set, create a UI that's easy and pleasant to use, encourage collaboration, visualize important data, and otherwise revamp yourself, start innovating again and regain your status of a platform which really matters. Or you just do this and call it a day.

2 August 2013

Rapha&#235;l Hertzog: My Free Software Activities in July 2013

This is my monthly summary of my free software related activities. If you re among the people who made a donation to support my work (167.67 , thanks everybody!), then you can learn how I spent your money. Otherwise it s just an interesting status update on my various projects. The Debian Administrator s Handbook After the successful crowdfunding campaign, I had a bunch of rewards to ship: I subcontracted most of the job but I had to take care of the books with dedication. I also dealt regularly with books/stickers coming back to the sender (due to invalid address or people not picking up their parcels in the post-office). After the rewards, we had to take care to actually finalize the liberation of the French translation. I merged the translations we had in Git and Roland updated/translated a few strings that weren t in the original book in French. Then I have put the book online. Last but not least, I started to work on updating the English book for Debian 7 (Roland started way before me) and we have put some updated chapters up for review. Debian France Elections. After Debian France s general assembly, the new board of administrators voted the officers: I have been re-elected as President, Sylvestre continues as Treasurer but we have a new Secretary in the person of Alexandre Delano . Welcome Alexandre! I did the administrative work to register the new board/officers in the Tribunal d instance and to give access to the internal git repositories to the new members. Galette. I also did a bunch of tests on Galette s new features that Debian France ordered to the upstream author. They should all land in the next upstream release due in the next weeks. \o/ Accounting. I worked on the accounting to bring it up-to-date so that Sylvestre can pick up the work from now on. We re learning how to best use ledger for our needs. PTS rewrite I continued to spend about 12 hours a week to mentor Marko Lalic who is rewriting the Package Tracking System. I m pretty happy with the results so far so I marked him as pass for the mid-term evaluation required by Google. You can have a look at the documentation and the web interface is starting to show some content. The email interface is fully working and I have configured the real PTS to forward all mails to our test instance (pts.debian.net) so that you can use the rewritten PTS for real-life work. Mail your subscription commands to control@pts.debian.net and start using it! Thanks to the test driven development methodology we re using, we re pretty confident that it works reasonably well! :-) I also packaged python-django-jsonfield (still in NEW) since Marko has been using this python module in his code, and filed bug #717900 on sqlite3 to raise a limit that we have hit with queries made by the PTS. Kali Linux I used the Calxeda Highbank node donated to Debian by Offensive Security to test the new -armmp kernel flavor on it. It seemed to work except for a missing network driver (filed in #717269). Misc Debian work Issues with social networks. With the move of identi.ca to pump.io, we don t have any possibility to auto-post status updates based on RSS feeds. Identi.ca s @debian account was also configured to push updates to the @debian account on twitter.com (and from there it was grabbed in the Debian page on Facebook). This is also gone so to limit the damage, I setup twitterfeed.com so that the twitter/facebook accounts continue to have updates). If you re looking for a development project, here s an area that is not well covered by free software! We need code to do what twitterfeed does and we need that code to also support pump.io. Dpkg work. It s been a long time since I last pushed some code to dpkg s git repository. I took care of reworking and merging a patch submitted by Steve Langasek to fix #716948 (an issue with dpkg-maintscript-helper rm_conffile messing with conffiles that the package no longer owns). Git mail notification. When I was still administrator of Alioth, I wrote git-commit-notice (a fork of Git s post-receive-email) and many packaging projects are using this hook script to send commit notices to mailing lists. This script has not been updated for multiple years and it started spewing warnings recently due to deprecated features in Wheezy s git. So I looked at updating it and while doing so I discovered a much better replacement with git-multimail. Thus I adapted git-commit-notice to work on top of this new script. The result has now been installed on git.debian.org (this is to be properly announced in the next DeveloperNews). Misc work. I packaged sql-ledger 3.0.5-1, forwarded #714739 on publican, and I participated in discussions to move the French Debian planets to planet.debian.org. Thanks See you next month for a new summary of my activities.

10 comments Liked this article? Click here. My blog is Flattr-enabled.

Jonathan Wiltshire: Cold caller: 1, jmw: 0

Some evil nasty cold callers who want to sell us windows and doors have been on the phone for a third time. Previously they have been cagey and haven t given away any information that could identify them, except the name Status . They always claim to have made an appointment with the homeowner (that s me) to call (which is a lie) but can never say who arranged the appointment because it s not on the file (probably the only true thing in the conversation). We re listed at the Telephone Preference Service so this kind of call shouldn t be arriving in the first place. However, the TPS gives very little recourse to subscribers when companies ignore it and call anyway. Tonight I thought I d got somewhere by feigning interest and getting a phone number out of them while I have a think about whether to replace our windows. That s one piece of information I can access to make a start on finding out who they are. I was so surprised to get an answer straight away that I didn t bother to gather anything else. The number is for the regional branch of a well-known national children s charity.
Cold caller: 1, jmw: 0 is a post from: jwiltshire.org.uk Flattr

1 August 2013

Julien Danjou: The definitive guide on how to use static, class or abstract methods in Python

Doing code reviews is a great way to discover things that people might struggle to comprehend. While proof-reading OpenStack patches recently, I spotted that people were not using correctly the various decorators Python provides for methods. So here's my attempt at providing me a link to send them to in my next code reviews. :-) How methods work in Python A method is a function that is stored as a class attribute. You can declare and access such a function this way:
>>> class Pizza(object):
... def __init__(self, size):
... self.size = size
... def get_size(self):
... return self.size
...
>>> Pizza.get_size
<unbound method Pizza.get_size>

What Python tells you here, is that the attribute get_size of the class Pizza is a method that is unbound. What does this mean? We'll know as soon as we'll try to call it:
>>> Pizza.get_size()
Traceback (most recent call last):
File "<stdin>", line 1, in <module>
TypeError: unbound method get_size() must be called with Pizza instance as first argument (got nothing instead)

We can't call it because it's not bound to any instance of Pizza. And a method wants an instance as its first argument (in Python 2 it must be an instance of that class; in Python 3 it could be anything). Let's try to do that then:
>>> Pizza.get_size(Pizza(42))
42

It worked! We called the method with an instance as its first argument, so everything's fine. But you will agree with me if I say this is not a very handy way to call methods; we have to refer to the class each time we want to call a method. And if we don't know what class is our object, this is not going to work for very long. So what Python does for us, is that it binds all the methods from the class Pizza to any instance of this class. This means that the attribute get_size of an instance of Pizza is a bound method: a method for which the first argument will be the instance itself.
>>> Pizza(42).get_size
<bound method Pizza.get_size of <__main__.Pizza object at 0x7f3138827910>>
>>> Pizza(42).get_size()
42

As expected, we don't have to provide any argument to get_size, since it's bound, its self argument is automatically set to our Pizza instance. Here's a even better proof of that:
>>> m = Pizza(42).get_size
>>> m()
42

Indeed, you don't even have to keep a reference to your Pizza object. Its method is bound to the object, so the method is sufficient to itself. But what if you wanted to know which object this bound method is bound to? Here's a little trick:
>>> m = Pizza(42).get_size
>>> m.__self__
<__main__.Pizza object at 0x7f3138827910>
>>> # You could guess, look at this:
...
>>> m == m.__self__.get_size
True

Obviously, we still have a reference to our object, and we can find it back if we want. In Python 3, the functions attached to a class are not considered as unbound method anymore, but as simple functions, that are bound to an object if required. So the principle stays the same, the model is just simplified.
>>> class Pizza(object):
... def __init__(self, size):
... self.size = size
... def get_size(self):
... return self.size
...
>>> Pizza.get_size
<function Pizza.get_size at 0x7f307f984dd0>

Static methods Static methods are a special case of methods. Sometimes, you'll write code that belongs to a class, but that doesn't use the object itself at all. For example:
class Pizza(object):
@staticmethod
def mix_ingredients(x, y):
return x + y

def cook(self):
return self.mix_ingredients(self.cheese, self.vegetables)

In such a case, writing mix_ingredients as a non-static method would work too, but it would provide it a self argument that would not be used. Here, the decorator @staticmethod buys us several things:
>>> Pizza().cook is Pizza().cook
False
>>> Pizza().mix_ingredients is Pizza.mix_ingredients
True
>>> Pizza().mix_ingredients is Pizza().mix_ingredients
True

Class methods Having said that, what are class methods? Class methods are methods that are not bound to an object, but to a class!
>>> class Pizza(object):
... radius = 42
... @classmethod
... def get_radius(cls):
... return cls.radius
...
>>>
>>> Pizza.get_radius
<bound method type.get_radius of <class '__main__.Pizza'>>
>>> Pizza().get_radius
<bound method type.get_radius of <class '__main__.Pizza'>>
>>> Pizza.get_radius is Pizza().get_radius
True
>>> Pizza.get_radius()
42

Whatever the way you use to access this method, it will be always bound to the class it is attached too, and its first argument will be the class itself (remember that classes are objects too). When to use this kind of methods? Well class methods are mostly useful for two types of methods:
class Pizza(object):
def __init__(self, ingredients):
self.ingredients = ingredients

@classmethod
def from_fridge(cls, fridge):
return cls(fridge.get_cheese() + fridge.get_vegetables())

class Pizza(object):
def __init__(self, radius, height):
self.radius = radius
self.height = height

@staticmethod
def compute_circumference(radius):
return math.pi * (radius ** 2)

@classmethod
def compute_volume(cls, height, radius):
return height * cls.compute_circumference(radius)

def get_volume(self):
return self.compute_volume(self.height, self.radius)

Abstract methods An abstract method is a method defined in a base class, but that may not provide any implementation. In Java, it would describe the methods of an interface. So the simplest way to write an abstract method in Python is:
class Pizza(object):
def get_radius(self):
raise NotImplementedError

Any class inheriting from Pizza should implement and override the get_radius method, otherwise an exception would be raised. This particular way of implementing abstract method has a drawback. If you write a class that inherits from Pizza and forget to implement get_radius, the error will only be raised when you'll try to use that method.
>>> Pizza()
<__main__.Pizza object at 0x7fb747353d90>
>>> Pizza().get_radius()
Traceback (most recent call last):
File "<stdin>", line 1, in <module>
File "<stdin>", line 3, in get_radius
NotImplementedError

There's a way to triggers this way earlier, when the object is being instantiated, using the abc module that's provided with Python.
import abc

class BasePizza(object):
__metaclass__ = abc.ABCMeta

@abc.abstractmethod
def get_radius(self):
"""Method that should do something."""

Using abc and its special class, as soon as you'll try to instantiate BasePizza or any class inheriting from it, you'll get a TypeError.
>>> BasePizza()
Traceback (most recent call last):
File "<stdin>", line 1, in <module>
TypeError: Can't instantiate abstract class BasePizza with abstract methods get_radius

Mixing static, class and abstract methods When building classes and inheritances, the time will come where you will have to mix all these methods decorators. So here's some tips about it. Keep in mind that declaring a class as being abstract, doesn't freeze the prototype of that method. That means that it must be implemented, but i can be implemented with any argument list.
import abc

class BasePizza(object):
__metaclass__ = abc.ABCMeta

@abc.abstractmethod
def get_ingredients(self):
"""Returns the ingredient list."""

class Calzone(BasePizza):
def get_ingredients(self, with_egg=False):
egg = Egg() if with_egg else None
return self.ingredients + egg

This is valid, since Calzone fulfil the interface requirement we defined for BasePizza objects. That means that we could also implement it as being a class or a static method, for example:
import abc

class BasePizza(object):
__metaclass__ = abc.ABCMeta

@abc.abstractmethod
def get_ingredients(self):
"""Returns the ingredient list."""

class DietPizza(BasePizza):
@staticmethod
def get_ingredients():
return None

This is also correct and fulfil the contract we have with our abstract BasePizza class. The fact that the get_ingredients method don't need to know about the object to return result is an implementation detail, not a criteria to have our contract fulfilled. Therefore, you can't force an implementation of your abstract method to be a regular, class or static method, and arguably you shouldn't. Starting with Python 3 (this won't work as you would expect in Python 2, see issue5867), it's now possible to use the @staticmethod and @classmethod decorators on top of @abstractmethod:
import abc

class BasePizza(object):
__metaclass__ = abc.ABCMeta

ingredient = ['cheese']

@classmethod
@abc.abstractmethod
def get_ingredients(cls):
"""Returns the ingredient list."""
return cls.ingredients

Don't misread this: if you think this going to force your subclasses to implement get_ingredients as a class method, you are wrong. This simply implies that your implementation of get_ingredients in the BasePizza class is a class method. An implementation in an abstract method? Yes! In Python, contrary to methods in Java interfaces, you can have code in your abstract methods and call it via super():
import abc

class BasePizza(object):
__metaclass__ = abc.ABCMeta

default_ingredients = ['cheese']

@classmethod
@abc.abstractmethod
def get_ingredients(cls):
"""Returns the ingredient list."""
return cls.default_ingredients

class DietPizza(BasePizza):
def get_ingredients(self):
return ['egg'] + super(DietPizza, self).get_ingredients()

In such a case, every pizza you will build by inheriting from BasePizza will have to override the get_ingredients method, but will be able to use the default mechanism to get the ingredient list by using super().

Matthew Garrett: Don't ship 32-bit UEFI firmware on x86

Shipping a UEFI-bootable Linux distribution is a touch awkward[1], with the main sticking point being the necessity to produce boot media with multiple El-Torito images. An El-Torito image is either an image of a floppy disk or a small hard drive, embedded into the ISO. This allows BIOS systems to look for an El Torito image, hook some interrupts and then boot without the BIOS having to care about the fact that the image is embedded in an ISO-9660 filesystem. UEFI systems will look for an El-Torito image with a special tag - if they find it they'll mount it as a FAT filesystem and look for a bootloader, and if not they'll fall back to BIOS compatibility.
So, if you want a CD that'll boot on both BIOS and UEFI systems, you need two El-Torito images - one for BIOS, one for UEFI. Unfortunately, various BIOSes deal exceptionally badly with CD images that contain more than one El-Torito image. The most common failure case is to print a menu asking you to choose an option without labelling the options, but some will just fail outright. Thankfully, this is pretty much exclusively limited to 32-bit systems.

Things get irritatingly more complicated due to a quirk of UEFI. UEFI is based on executing code in native mode. That means that 32-bit UEFI systems can't execute 64-bit code in firmware, even if the CPU is capable of it. A 64-bit OS can only boot on 32-bit UEFI if it has very ugly compatibility hacks, including having to rewrite structures and register state every time it makes a UEFI call. The only OS I'm aware of that implements this is MacOS X. Having looked into what it'd take to implement it in Linux, I decided that hammering rusty nails through my feet would be a preferable use of time. Thankfully, I went drinking instead.

So distributions have a choice. They can either produce UEFI-bootable CD images for 32-bit x86 and risk failures on actual 32-bit systems, or they can ignore UEFI entirely on 32-bit and succeed in booting on all the hardware that people actually own[2]. Unsurprisingly, they tend to choose the second option.

So, if you're building an x86 hardware platform, don't ship with 32-bit UEFI. If you're stuck with a 32-bit CPU then just ship BIOS. If you have a 64-bit CPU then ship a 64-bit UEFI. If you ship with 32-bit UEFI, no significant existing Linux distribution will support you, and you'll face an uphill battle to convince them to do so.

32-bit UEFI. Just say what on earth were you thinking, please, no, can't you find a solution that doesn't involve me getting tetanus jabs.

(If you're worried about the extra memory consumption of 64-bit OSes, just encourage 32-bit userspace on a 64-bit kernel. Or just boot via BIOS)

[1] See the number that still don't manage it despite having had several years to adapt
[2] Until recently, the only vendor to ship 32-bit UEFI firmware on volume hardware was Apple. This was fine on their 32-bit systems, but on their 64-bit systems with 32-bit UEFI booting a 64-bit version of Windows would result in boot failure. Apple rectified this by stating that 64-bit Windows wasn't supported on platforms with 32-bit UEFI, which is a neat trick if you can manage it. 32-bit Windows (and Linux) was fine because it didn't include a UEFI boot image and so didn't trigger the bug.

comment count unavailable comments

Russ Allbery: Review: And Playing the Role of Herself

Review: And Playing the Role of Herself, by K.E. Lane
Publisher: Regal Crest
Copyright: 2006
Printing: June 2010
ISBN: 1-932300-72-4
Format: Kindle
Pages: 336
Caidence Harris is an actress who has finally gotten her big shot: a starring role in the hit police drama 9th Precinct. She plays half of a police partnership; the other half is played by her best friend, the considerably more famous Liz Stokley. She's quite happy with her life and her work, and only tentatively pondering what to do about coming out (at least to herself) as a lesbian. But matters get considerably more complicated when she starts falling for Robyn Ward, a star in a parallel legal drama. And the very high-profile girlfriend of one of the best male tennis players in the world. Yes, another lesbian romance. This one has won several awards, including the highest recommendation from my friend who's been prefiltering the genre for me and pointing out only the best stories. And despite being set firmly among the rich and famous and involving TV dramas with the serial numbers filed off, he was right. This is a thoroughly enjoyable story. One of its strongest parts is how Lane develops the romance between Caidence and Robyn. There is a bit of the inevitable physical chemistry so common in romances (I still don't believe kisses work that way), and a few descriptions of physical beauty (after all, there's a built-in excuse for everyone to be TV-star beautiful). But Lane avoids putting either at the center of the relationship. Instead, this is a romance built on trust, tentative at first and then growing but rocky. That speaks to me a lot more than all the descriptions of physical chemistry. For example, we don't see Caidence and Robyn meet for the first time in the novel, as is usually the case. They've been around each other before, with Caidence acting rather tongue-tied and a bit star-struck and Robyn thinking she's rather silly. The story begins when, for whatever reason, Caidence finally manages to relax and become genuine, and then both of them become closer as they find themselves lowering barriers around each other that they normally don't lower. Lane does an excellent job using a few key facial expressions as symbols and hallmarks of that, letting the reader follow the way that trust builds through the story. The other great element of this book is Caidence's friend Liz. She could have been a stereotype of a movie star: drop-dead gorgeous, a new boyfriend each week, but not particularly intelligent. That's how she comes off at first. But as the story progresses, Lane shows more and more of their friendship, and the reader gets to see just how much Liz's first impression is a combination of an act and her unapologetic tendency to do what she wants. Underneath, she's a strong female character and an excellent, if meddling friend; by the end of the book, she was in the running for my favorite character. This is characterization of a quality that I rarely see in any genre of novel. Given that it's a romance that I enjoyed, you can correctly expect there not to be a lot of obnoxious communication breakdowns or chapters full of the main characters refusing to communicate with each other. There are, of course, a wide variety of barriers in the way of a relationship for the main characters, not the least of which being that neither of them was looking for something serious. But while they both do occasionally thoughtless or hurtful things, it's always clear just why they were thoughtless, or where their buttons were accidentally pressed, and few of the character actions are outright stupid. And, delightfully, Lane structures the story so that there are multiple, incremental payoffs. One can not only enjoy the characters getting together in the end, as they always do in this genre, but a lot of important and meaningful steps along the way. Lane does a great job putting the reader in Caidence's head, helped by first-person narration, so that one can feel just how much some moments mean to her emotionally. Add in several other fleshed-out and interesting supporting characters, some incredible architecture that was fun to imagine, and rather more in the way of plot twists and dramatic moments than I usually expect in a romance (and although the book worried me once, none of them go to the dark places that would have been less fun), and one gets a novel that kept me engrossed from start to finish. I'm tempted to read it again, and that's rare for me for a romance novel. If you're in the mood for a heart-warming story about intelligent people learning how to be together, I highly recommend this book. It's a great book to read as a stress relief when you want a story that you know will turn out "right." Rating: 9 out of 10

31 July 2013

Russell Coker: Links July 2013

Wayne Mcgregor gave an interesting TED talk about the creative processes of a choreographer [1]. The dancing in this talk is really good. Melissa McEwan wrote an interesting article on whether being an ally to members of a disadvantaged group is a state or a process [2]. It seems to me that the word ally is a problem here, maybe a word like supporter would be more useful. Ken Murray wrote an insightful article How Doctors Die about the end of life choices that people with medical experience make [3]. He makes a good case for rejecting the type of treatment which has a low probability of success and a certainty of lowering the quality of life. It would be good if health insurance offered patients with terminal illness an option of $1000 per day party funds if they chose to reject the expensive and painful methods that might extend their life, that might even save enough money to allow cheaper health insurance! Rick Falkvinge wrote an interesting post about the copyright to translations of the Bible [4]. I used to think that copyright issues with religious works was only a problem with cults Joshua Foer wrote an interesting article for the New Yorker about the invention of the language Quijada which is designed for maximum precision [5]. It also has a lot of background information on constructed languages and the way that they are used.

30 July 2013

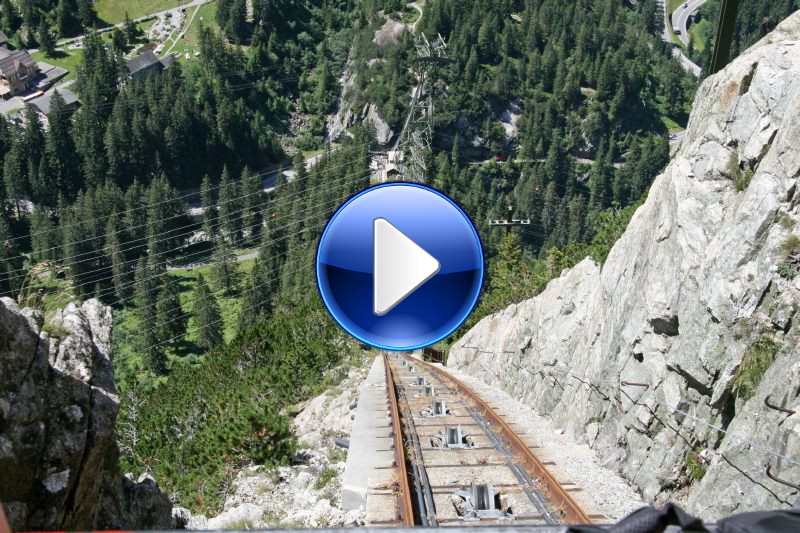
Daniel Pocock: Switzerland's scariest railway (video)

Although promoted as a funicular railway, the Gelmerbahn funicular has the appearance of a giant roller coaster and all of the fun too. For all those still having nightmares about recent rail tragedies in the age of non-stop surveillance and on-line replays, the 108 degree ascent (or descent) may not be your thing. On the other hand, for those who experience the London Underground each morning, "mind the gap" takes on a whole new meaning as you see your feet hanging out the bottom of the train and the tracks descending vertically into the valley below. <video controls="" height="340" poster="http://danielpocock.com/sites/danielpocock.com/files/gbahn-preview.jpg" width="560">

<source src="http://video.danielpocock.com/Gelmerbahn.webm" type="video/webm"></source>
Click to access video on original page
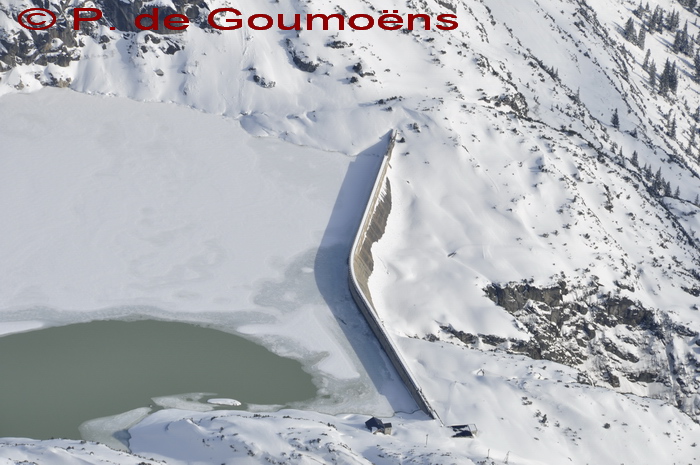
</video> and here are download links for those who prefer to download now and watch later (about 160MB): At the top At the top, there is a scenic two hour walk around Lake Gelmer, the path takes you across the top of a dam built for hydro-electric power generation. Lake Gelmer - hydro-electric dam Getting there from DebConf13 and the Debian 20th birthday For those coming to Switzerland for DebConf13 next month, the Gelmerbahn is probably a little bit too far for a day trip but makes an excellent place to stop during a 2 or 3 day tour around Switzerland. It is accessible using the all-day bus pass for the tour of 3 or 4 mountain passes or by train to Innertkirchen and then a short ride on the bus. The busses are irregular, use sbb.ch to plan the journey. Walking down the mountain from the lake to the bus stop takes about 90 minutes and for those who choose this option, the ticket is cheaper. More Swiss travel blogs Please click here to access some of my previous blogs about Swiss travel with videos and useful ideas for day trips.

28 July 2013

Joey Hess: git-annex as a podcatcher

As a Sunday diversion, I wrote 150 lines of code and turned git-annex into a podcatcher! I've been using hpodder, a podcatcher written in Haskell. But John Goerzen hasn't had time to maintain it, and it fell out of Debian a while ago. John suggested I maintain it, but I have not found the time, and it'd be another mass of code for me to learn and worry about. Also, hpodder has some misfeatures common to the "podcatcher" genre: So, here's a rethink of the podcatcher genre:
cd annex; git annex importfeed http://url/to/podcast http://another/podcast
There is no database of feeds at all. Although of course you can check a list of them right into the same git repository, next to the files it adds. git-annex already keeps track of urls associated with content, so it reuses that to know which urls it's already downloaded. So when you're done with a podcast file and delete it, it won't download it again. This is a podcatcher that doesn't need to actually download podcast files! With --fast, it only records the existence of files in git, so git annex get will download them from the web (or perhaps from a nearer location that git-annex knows about). Took just 3 hours to write, and that's including full control over the filenames it uses (--template='$ feedtitle)/$ itemtitle $ extension '), and automatic resuming of interrupted downloads. Most of what I needed was already available in git-annex's utility libraries or Hackage. Technically, the only part of this that was hard at all was efficiently querying the git repository for a list of all known urls. I found a pretty fast way to do it, but might add a local cache file later on.

Francois Marier: FISL for foreigners HOWTO

FISL (pronounced FIZZ lay by the locals) is a large Free and Open Source software gathering in Porto Alegre, Brazil. While the primary audience of that conference is the Latin America "libre software" community, a number of overseas speakers also participate in that conference. This is my contribution to them: a short guide for international guests visiting the F rum Internacional do Software Livre.

Planning Before you fly out, make sure you look up the visa requirements for your country of citizenship. Many western countries will require a visa and you will need to visit the local Brazillian embassy ahead of time to get one. Next, have a look at the list of recommended immunizations. As with most destinations, it is recommended that your routine immunizations be up to date, but there are also other specialized ones such as Yellow Fever that are recommended by the Brazillian government. You should therefore visit a travel clinic a few weeks ahead of time. Other than that, I suggest reading up on the country and keeping an eye on the various travel advisories.

Arrival You will be flying at the Porto Alegre airport. If you need to exchange overseas money for Brazilian Reals, you can do that there. You'll probably also want to pick up a power adapter at the airport if you intend to charge your laptop while you're in the country :) Brazil has both 127V and 220V outlets using Type N sockets. Privacy note: using the free airport wifi will require giving your Passport details as part of the registration process.

Language If you don't speak Portuguese, expect a few challenges since most of the people you'll meet (including taxi drivers, many airport workers, some hotel staff) won't speak English. I highly recommend getting a phrase book before you leave and printing paper maps of where you are planning to go (to show to taxi drivers when you get lost). Native Spanish speakers seem to get by speaking Spanish to Portuguese speakers and understanding enough Portuguese to hold a conversation. I wouldn't count on it unless your Spanish is quite good though. Also, the official conference blog posts get eventually translated to English, but there is a delay, so you may want to subscribe to the Portuguese feed and use Google Translate to keep up with FISL news before you get there.

The conference FISL is a large conference and it has a very "decentralized" feel to it. From the outside, it looks like it's organized by an army of volunteers where everyone is taking care of some portion of it without a whole lot of top-down direction. It seems to work quite well! What this means for you as a foreign speaker however is that you're unlikely to be provided with a lot of information or help finding your way around the conference (i.e. no "speaker liaison"). There is a separate registration desk for speakers but that's about all of the attention you'll receive before you deliver your talk. So make sure you know where to go and show up in your assigned room early to speak with the person introducing you. If your talk is in English, it will be live-transated by an interpreter. It's therefore a good idea to speak a bit more slowly and to pause a bit more. Other than that, the organizers make an effort to schedule an English talk in each timeslot so non-Portuguese speakers should still be able to get a lot out of the conference. FISL was a lot of fun for me and I hope that some of these tips will help you enjoy the biggest FLOSS gathering in the southern hemisphere!

27 July 2013

Christian Perrier: [life] Running update July 27th 2013: Bubulle now runs in moutains

My last running update was sent after I had a great April month with two successful trail races (35km then 44km). The next target was Mont-Blanc marathon in Chamonix valley in early July, so it's time for me to send a new update before summer. May and June was mostly training. Huge training. Very long distances with 375km in May and over 430 in June (breaking my former monthly record by over 50 kilometers). Yes, that means over 14 kilometers every day..:-) I indeed achieved that with my "go to work partly by running" habits, which are now deeply included in my daily schedule. Much more convenient than bus ride (with the typical random schedules of RATP, which French people translate by "Rentre Avec Tes Pieds" or "Come back home by walking"....which is exactly what I'm doing). With such training (sometimes including extra rides in the forests, with short but steep ups and downs)....I was well prepared for THE early summer goal : Marathon du Mont-Blanc in Chamonix (not Ultra Trail du Mont-blanc : this one, I'm not ready for....yet).. My first mountain trail race, and what race! Imagine 42km in the moutain lovers heaven, namely the Chamonix Valley, with the Mont-Blanc, Aiguille Verte, Aiguille du Midi, Aiguilles Rouges, etc. above your head. Of course, not only in the valley but goind up and down "slightly"....in short 2200 meters positive climb..:-) I ran it with a female friend of mine, who I met in local races and through runners web forums. Sabine has about the same running skills than me and we developed a good and nice friendship, sharing our love for running in the nature. So, during May and June, we decided to run this race together as we were both registered for it. A first trial in a local 35km trail race two weeks before the MMB was very successful. We ended up in 3h40 and Sabine was ranked 5th female runner. And, moreover, we had a tremendous pleasure by crossing the finishing line together. So, we did it again in Chamonix. And, hell, we did it well: I had set the goal to 6 hours and 30 minutes and we completed the race in..... 6 hours and 34 minutes. Much much better than I and she would have expected. And, believe me, crossing the finishing line was again a special moment, particularly because the crowd at the end of this race make it look like l'Alpe d'Huez on the Tour de France. And, this on a wonderful sunny day, arriving at Planpraz, facing the Mont-Blanc. If you've ever been to Chamonix, you know what I mean. So, first moutain trail and, hell, not the last one! For those of you who can read French...or just want to see some pictures of a running bubulle, here is the link to the story. And these 42 kilometers were indeed so well done that the day after, while coming down from the famous Aiguille du Midi with Elisabeth (who came with me to Chamonix, of course)...I decided to run down from the cable car intermediate stop (2300m altitude) to Chamonix (1050m). Over 1200 meters down in 48 minutes... :-). Just a bit slower than the cable car....:) The remaining of July saw me again running back and forth to work and I'm indeed about to break my monthly record, eventually reaching 450 kilometers in one month and only two days NOT running in the whole month. Yeah, crazy. The upcoming Sunday, August 4th, just before going to Debconf 13, I'll spend a few days in Lanslebourg and will be running the EDF Cenis Tour trail, for 50 kilometers and 2600 meters positive climb. This time, a very "small" race, with no more than 150 runners. So, that will be another experience by running nearly entirely alone between 1400 and 2700 meters altitude. I'll post the outcome (or you'll probably hear about it at DC13....). See you, hopefully not in 3 months, for another update about running Bubulle.

Christian Perrier: Developers per country (July 2013)

This is time again for my annual report about the number of developers per country. This is now the fifth edition of this report, after the 2012, 2011, 2010 and 2009 editions. So, here we are with the July 2013 version, sorted by the ratio of *active* developers per million population for each country.
Act: number of active developers
Dev: total number of developers
A/M: number of active devels per million pop.
D/M: number of devels per million pop.
2009: rank in 2009
2010: rank in 2010
2011: rank in 2011 (June)
2011: rank in 2012 (June)
2013: rank now
Code Name Population Act Dev Dev Act/Million Dev/Million 2009 2010 June 2011 June 2012 July 2013
fi Finland 5259250 19 31 3,61 5,89 1 1 1 1 1
ie Ireland 4670976 12 15 2,57 3,21 13 9 6 2 2
ch Switzerland 7870134 20 27 2,54 3,43 2 2 2 3 3
mq Martinique 396404 1 1 2,52 2,52

3 4 4
se Sweden 9088728 22 37 2,42 4,07 3 6 7 5 5
no Norway 4973029 12 15 2,41 3,02 5 4 4 6 6
nz New Zealand 4331600 10 15 2,31 3,46 4 3 5 7 7
de Germany 81471834 165 235 2,03 2,88 7 7 9 9 8 *
lu Luxemburg 503302 1 1 1,99 1,99 8 5 8 8 9 *
at Austria 8217280 16 26 1,95 3,16 6 8 10 10 10
fr France 65350000 100 130 1,53 1,99 12 12 11 11 11
au Australia 22607571 31 59 1,37 2,61 9 10 12 12 12
be Belgium 11071483 14 17 1,26 1,54 10 11 13 13 13
uk United-Kingdom 62698362 73 114 1,16 1,82 14 14 14 14 14
nl Netherlands 16728091 19 40 1,14 2,39 11 13 15 15 15
ca Canada 33476688 32 61 0,96 1,82 15 15 17 16 16
dk Denmark 5529888 5 10 0,9 1,81 17 17 16 17 17
es Spain 46754784 35 56 0,75 1,2 16 16 19 18 18
it Italy 59464644 36 51 0,61 0,86 23 22 22 19 19
cz Czech Rep 10190213 6 6 0,59 0,59 21 20 21 21 20 *
lt Lithuania 3535547 2 2 0,57 0,57 28 19 20 22 21 *
us USA 313232044 173 378 0,55 1,21 19 21 25 24 22 *
il Israel 7740900 4 6 0,52 0,78 24 24 24 25 23 *
hu Hungary 10076062 5 10 0,5 0,99 18 25 26 20 24 *
hr Croatia 4290612 2 2 0,47 0,47 20 18 18 26 25 *
lv Latvia 2204708 1 1 0,45 0,45 26 26 27 27 26 *
bg Bulgaria 7364570 3 3 0,41 0,41 25 23 23 23 27 *
uy Uruguay 3477778 1 2 0,29 0,58 22 27 28 28 28
jp Japan 127078679 35 50 0,28 0,39 30 28 29 29 29
pl Poland 38441588 10 14 0,26 0,36 29 29 30 30 30
cr Costa Rica 4301712 1 1 0,23 0,23 31 30 31 31 31
by Belarus 9577552 2 2 0,21 0,21 35 36 39 39 32 *
sg Singapore 5183700 1 1 0,19 0,19


33 33
pt Portugal 10561614 2 4 0,19 0,38 27 32 32 34 34
gr Greece 10787690 2 3 0,19 0,28 33 38 34 35 35
sk Slovakia 5477038 1 1 0,18 0,18 32 31 33 36 36
ar Argentina 40677348 6 8 0,15 0,2 34 33 35 32 37 *
rs Serbia 7186862 1 1 0,14 0,14


38 *
tw Taiwan 23040040 3 3 0,13 0,13 37 34 37 37 39 *
br Brazil 192376496 21 23 0,11 0,12 36 35 38 38 40 *
cu Cuba 11241161 1 1 0,09 0,09
38 41 41 41
kr South Korea 48754657 4 6 0,08 0,12 39 39 42 42 42
gt Guatemala 13824463 1 1 0,07 0,07


43 *
ve Venezuela 28047938 2 2 0,07 0,07 40 45 50 49 44 *
ec Ecuador 15007343 1 1 0,07 0,07
40 43 43 45 *
co Colombia 45566856 3 4 0,07 0,09 41 44 46 47 46 *
cl Chile 16746491 1 2 0,06 0,12 42 41 44 44 47 *
za South Africa 50590000 3 10 0,06 0,2 38 48 48 48 48
ru Russia 143030106 7 8 0,05 0,06 43 42 47 45 49 *
mg Madagascar 21281844 1 1 0,05 0,05 44 37 40 40 50 *
ro Romania 21904551 1 2 0,05 0,09 45 43 45 46 51 *
my Malaysia 28250000 1 1 0,04 0,04

49 50 52 *
pe Peru 29907003 1 1 0,03 0,03 46 46 51 51 53 *
tr Turkey 74724269 2 2 0,03 0,03 47 47 52 52 54 *
ua Ukraine 45134707 1 1 0,02 0,02 48 53 58 59 55 *
th Thailand 66720153 1 2 0,01 0,03 50 50 54 54 56 *
eg Egypt 80081093 1 3 0,01 0,04 51 51 55 55 57 *
mx Mexico 112336538 1 1 0,01 0,01 49 49 53 53 58 *
cn China 1344413526 10 14 0,01 0,01 53 53 57 56 59 *
in India 1210193422 9 9 0,01 0,01 52 52 56 57 60 *
sv El Salvador 7066403 0 1 0 0,14

36 58 61 *


957 1535 62,35%


A few interesting facts:

26 July 2013

Ian Wienand: Converting an American propane appliance to Australian gas bottles

Here's something I just spent too much time figuring out... If you have an Australian "gas" or "LPG bottle"; the type you'd pick-up at any "service" or "petrol" station in Australia, it has a female POL connector. I'm not sure what POL stands for; possibly related to some company who made connectors long ago and it became standard. If you have an American "propane" device such as a grill, turkey fryer or smoker, or indeed something that plugs into a "propane bottle" you would pick-up at a "gas station" -- it will have a "Type 1", "ACME", "ACME Type 1", "QCC", "QCC1" or "QCC Type 1" connector (each seems to be an interchangeable term for the other). The appliance side of this has a big (usually black) plastic nut that is apparently safer or something. Once you have figured this out, you can buy something like the "Grillpro Model 11051 Universal Fit Propane Tank Adapter" and I can attest, based upon empirical evidence, that things will "just work". Of course your other choice might be just to replace the regulator, hoses, etc.; however if everything seems super-glued together the adapter is much easier. In other empirical evidence you won't find anywhere else on the internet : the Vizio M3D550KD LCD television works just fine on 240V, despite not being rated for it on the back.

Justus Winter: Bootstrapping the Hurd

Due to popular demand this weeks report contains another awesome ascii screenshot. I added some lines to /etc/hurd/runsystem.sysv to inspect the environment very early in the boot process:
start ext2fs: Hurd server bootstrap: ext2fs[device:hd0s1] exec init proc auth
[...]
+ echo my pid is 1
my pid is 1
+ ps Ax
+ head
USER       PID TT STAT     TIME COMMAND
-            0  ? R<mo  0:00.01 /hurd/proc
root         1  - Sslow 0:00.02 /bin/sh /etc/hurd/runsystem
-            2  - Sp    0:00.00 /hurd/init root=device:hd0s1 console=com0
-            3  ? D<p   0:00.01 root=device:hd0s1 console=com0
-            4  - S<o   0:00.18 ext2fs --readonly --multiboot-command-line=root
-            5  - S<o   0:00.02 /hurd/exec
-            6  - S<o   0:00.00 /hurd/auth
root         7  - S<o   0:00.04 /hurd/term /dev/console device console
root         8  - S<o   0:00.00 /hurd/pflocal
+ pstree -p
sh(1)-+-init(2)-+-auth(6)
                 -ext2fs(4)-+-exec(5)
                             -pflocal(8)
                             -procfs(12)
                             -term(7)
       -pstree(11)
       -root=device:hd0s1(3)
Those who are familiar with the Hurd might note that /etc/hurd/runsystem.sysv runs as PID 1. At the end of this script /sbin/init is exec(2)uted, so sysvinit gets run as PID 1. This is the result of a fairly small patch series. It still took me like two days to come up with it since bootstrapping a Hurd system (or any microkernel OS, or like bootstrapping in general) is complicated. If you look at the screenshot above you will note the /hurd/pflocal process running with PID 8. This is the server providing pipe(2)s and Unix sockets. Before that server is started, one cannot use pipes to connect two processes with pipes like I did with ps and head (I actually lied a little here, because the way Debian/Hurd is set up, the pflocal server is started on demand courtesy of a Hurd feature called "passive translators", very similar to what the cool kids call "socket activation" today). Process 0 is the /hurd/proc server. It maps Mach tasks to the concept of Unix processes. Before that server is started, the notion of a process does not even exist. Pid 4 is the root filesystem. Without that, no other server can be read from the disk. But if the root filesystem is to be started first, it cannot be registered as a Unix process at the proc server, because that has not been started yet. So the first few processes are started in a weird way and order, and since they need to talk to each other, they need to register at each other. No Unix concepts exist yet, only Mach concepts like tasks and messages can be used. The boot sequence is roughly this (the numbers in parenthesis are the PIDs):
  1. Grub loads GNU Mach(3), the statically linked root filesystem translator (4) and the /hurd/exec (5) server (the exec server loads executables into Mach tasks, implementing most parts of execve(2)).
  2. The rootfs translator is started.
  3. The rootfs initiates the Hurd server bootstrap by starting /hurd/exec and /hurd/init (2).
  4. /hurd/init starts /hurd/proc (0) and /hurd/auth (6).
  5. The translators perform several rendezvouses to introduce themselves to each other.
  6. The proc servers state with respect to the already running processes is fixed.
  7. /hurd/init starts /etc/hurd/runsystem (1) which starts the pager (that pages out memory to disk) and later execs /sbin/init.
  8. From this point on the initialization of Debian/Hurd is no different from Debian/Linux.
Besides the pid one issue I spent my time on: Next week I hope to fully address the killall5 issue and to clean up, polish and submit my patch series for sysvinit. I will then revise my mtab translator prototype which is currently in its third iteration. As always, if there is time left, I will look at the network related issues.

Steve Kemp: International character sets and encodings are hard.

Today I've made the 0.15 release of lumail, which has several fixups and cleanups. The previous release included a rewrite of the scrolling code, courtesy of kain88-de. This release fixes a few corner cases in that update which caused empty messages/Maildirs to be highlighted - operating on such ghost-entries would cause a segfault. Oops. I've received several more great contributions from 7histle, and trou and I'm very happy with the state of the code and the usefulness of the application. The biggest outstanding issue is RFC 2047 header decoding. Converting subject/to/from fields to readable versions of their encoded form:
Subject: =?utf-8?Q?Blipfoto=20=2D=20Introducing=20the=20all=2Dnew=20Bli
This is annoying because I'm using mimetic for handling all MIME-related code, and this doesn't seem to offer the facilities that I need. The current plan is to use the RFC-2047 handling from vmime, but I've fought with that library unsucessfully for two days now - and a further complication is that the library is included in Squeeze/Sid, but not the stable release of Debian. In conclusion I still regard the client as complete, because I'm using it exclusively and I rarely get "foreign" mails. But there is one more push required to fix all the outstanding bugs which generall boil down to: Randomly I'm wondering if I can call out to Lua to do the header decoding. Add "on_header_field()" and display the results. So today I'll be looking at how sensible that is, probably not very.

25 July 2013

DebConf team: DebConf13 preliminary schedule available (Posted by Talks team)

We are happy to announce that the schedule for the upcoming DebConf13 in Vaumarcus, Switzerland, is available! It is still possible for some changes to occur, as we always try to accept new proposals, even those submitted during the conference. DebConf13 talks will mostly happen in two rooms simultaneously, except for a few plenaries which will be presented in the main room with no parallel event. A third room will be available for discussion groups and ad-hoc sessions. As usual, we ve tried to cluster related activities in sequence, even though it was not always possible. Besides that there will be many tracks covering specific topics, which are: There will also be two special tracks, since DebConf is not only about hacking, talks and discussions: As in previous years, we provide various ways to access the schedule: the DebConf team

Next.

Previous.

