Search Results: "spa"

28 April 2014

Daniel Pocock: SMS logins: an illusion of security

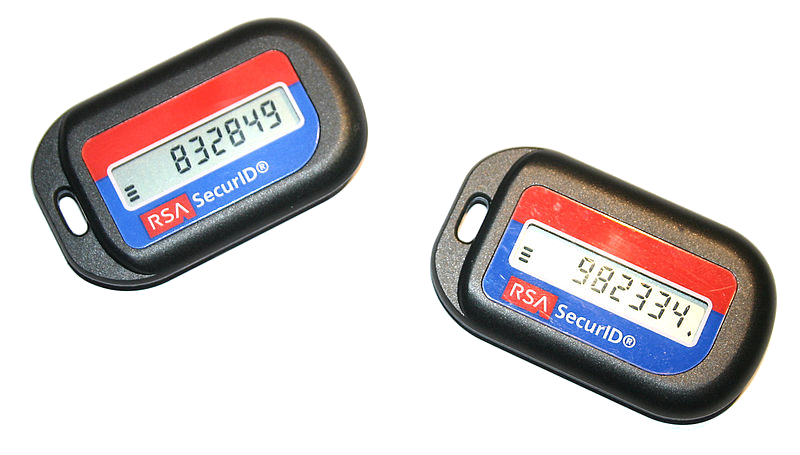
The IT security world is still reeling from the impact of the OpenSSL Heartbleed bug. Thanks to the bug, many experts have been reviewing other technologies to try and find similar risks. While Heartbleed was hidden away in the depths of the OpenSSL code base, another major security risk has been hiding in plain sight: SMS authentication for web site logins. Remarkably, a number of firms have started giving customers the ability to receive single-use passwords over SMS for logging into their secure web sites. Some have even insisted that customers can no longer log in without it, denying customers the right to make an important choice about their own security preferences. Unfortunately, SMS is no substitute to the one-time-passwords generated using proper authentication tokens or the use of other strong authentication schemes such as cryptographic smart cards. Even telephone companies themselves advise that SMS should not be used to secure financial transactions. Ocean's 11 in real life: exploiting the weakest link in the chain To deliver single-use SMS passwords, the SMS must travel through various networks from the firm's headquarters, to a wholesale SMS gateway, international SMS network and finally down the line of the local phone company. In comparison, properly certified token devices generate a code inside the device in the palm of your hand. The code only travels from the screen to your eyes. In a litany of frauds coming in all shapes and sizes, telephone networks have been exploited over and over again because they are almost always the weakest link in the chain. Using the mobile SMS network for authentication is not building on solid ground - some experts even feel it is downright stupidity. One of the most serious examples was the theft of $150,000,000 from a pension fund deposited with JP Morgan: it was described as a real-life case of Ocean's 11. The authentication was meant to be a phone call rather than an SMS: a phone company employee who was in on the scam duly ensured the call never reached the correct place. The insecurity of traditional telephone networks has been on display for all the world to see in the ongoing trial of News Corporation executives for phone hacking. If journalists from a tabloid newspaper can allegedly hack a dozen phones before their first cigarette of the day, is it really wise to use an insecure technology like SMS as the cornerstone of a security system for authorizing transactions? A fraud recently played out on many credit card holders in the UK exploited a low-tech feature of the phone system to trick people to believe they were safe by "calling back" to their bank. A plethora of new attack vectors The staggering reality of the situation is that attackers don't even have to directly hack their victim's phones to access SMS messages. As the Android API documentation demonstrates, SMS reception is notified to all apps in real-time. Apps can process the messages even when the phone is sleeping and the message is not read by the user. Just consider all the apps on a phone that have requested permission to read incoming messages. There was an uproar recently when a new version of the Facebook app started demanding permissions to read incoming SMS. The app can't be installed if the user doesn't agree to these new permissions. WhatsApp, another popular app that has SMS access rights, was recently exposed in a major security scandal which revealed they use a phone's IMEI number as the password. When people install an app like Tinder (which does not yet request SMS access) is the security of their bank account likely to be at the front of their mind? Even if Facebook intends no harm, they have opened the floodgates by further de-sensitizing users to the risks of giving apps un-necessary access to their data. These companies are looking for every piece of data that could give them an edge in their customer profiling and marketing programs. Having real-time access to your SMS is a powerful way for them to understand your activities and feelings at every moment in the day. To facilitate these data analysis techniques, replicating and archiving your messages into their cloud databases (whether you can see them there or not) is par for the course. The cloud, of course, has become a virtual smorgasboard for cyber-criminals, including both hackers and occasionally insiders wanting to peek at private data or harvest it en-masse. Social networking and communication sites are built on a philosophy of sharing data to create interaction and excitement. Unfortunately, this is orthogonal to the needs of security. In this context, the telephone network itself may no longer be the weakest link in the chain. The diligent attacker only needs to look for the cloud operator with an unplugged security hole and use their system as a stepping stone to read any SMS they want, when they want. Would you notice a stray SMS? Maybe you feel that you would notice a stray SMS carrying a login code for your bank account. Would you always be able to react faster than the criminal however? Thanks to social networks, or location data inadvertently leaked by other apps the attacker can easily work out whether you are on holiday, at the gym, at a party or sleeping or in some other situation where you are not likely to check messages immediately. If you receive a flood of SMS spam messages (deliberately sent by an attacker) in the middle of the night and you put your phone into silent mode and ignore it, you may well miss one message that was a login to your bank account. SMS technology was never designed for secure activities. The inconvenience of SMS While security is a headline issue these days, it is also worth reflecting on the inconvenience of SMS in some situations. Travel is at the top of the list: SMS doesn't work universally when abroad. These are usually the times when the only way to access the bank is through the web site. After dealing with the irritations of the hotel or airport wifi registration, do you really need more stress from your bank's systems too? For some networks, SMS can be delayed by hours or days, sometimes never arriving at all. Many people swap their SIM cards when travelling to avoid the excessive roaming charges and there is extra inconvenience in swapping SIM cards back again just to log in to a bank account. Worst of all, if you are tethering with a SIM card from the country you are visiting, then it is impossible for you to receive the SMS message from the bank on your regular SIM card while simultaneously maintaining the SSL connection to their web site over your new SIM card. Other problems like a flat battery, water damage or PIN permanently blocked by children playing with the phone can also leave you without access to your bank account for varying lengths of time. Is there any up-side to SMS authentication? The only potential benefit to SMS authentication is that it weeds out some of the most amateur attempts to compromise your bank account, but this is a false sense of security and it opens up new attack vectors through the cloud as we have just demonstrated. For all other purposes, it smells like a new form of security theater. A more likely reason why it has become popular amongst some firms is that many lenders want to ensure they have mobile phone numbers to contact customers when loan or credit card payments are missed. Making the mobile phone number mandatory for login ensures they almost always have the correct phone number for almost 100% of customers. It is not clear that this benefit justifies the failure to provide proper security and the inconvenience when travelling though. Opting out Next time you log in to a web site, if the firm does try to enrol you in an SMS authentication scheme, it may be a good idea to click the "No thanks" option. If you have already been registered into an SMS authentication scheme, fill out the online complaint form and inform the firm that you will only accept a proper authentication token or cryptographic smart card. These solutions are tried and tested and they are the correct tool for the job.

Evgeni Golov: Debian Bug Squashing Party Salzburg 2014

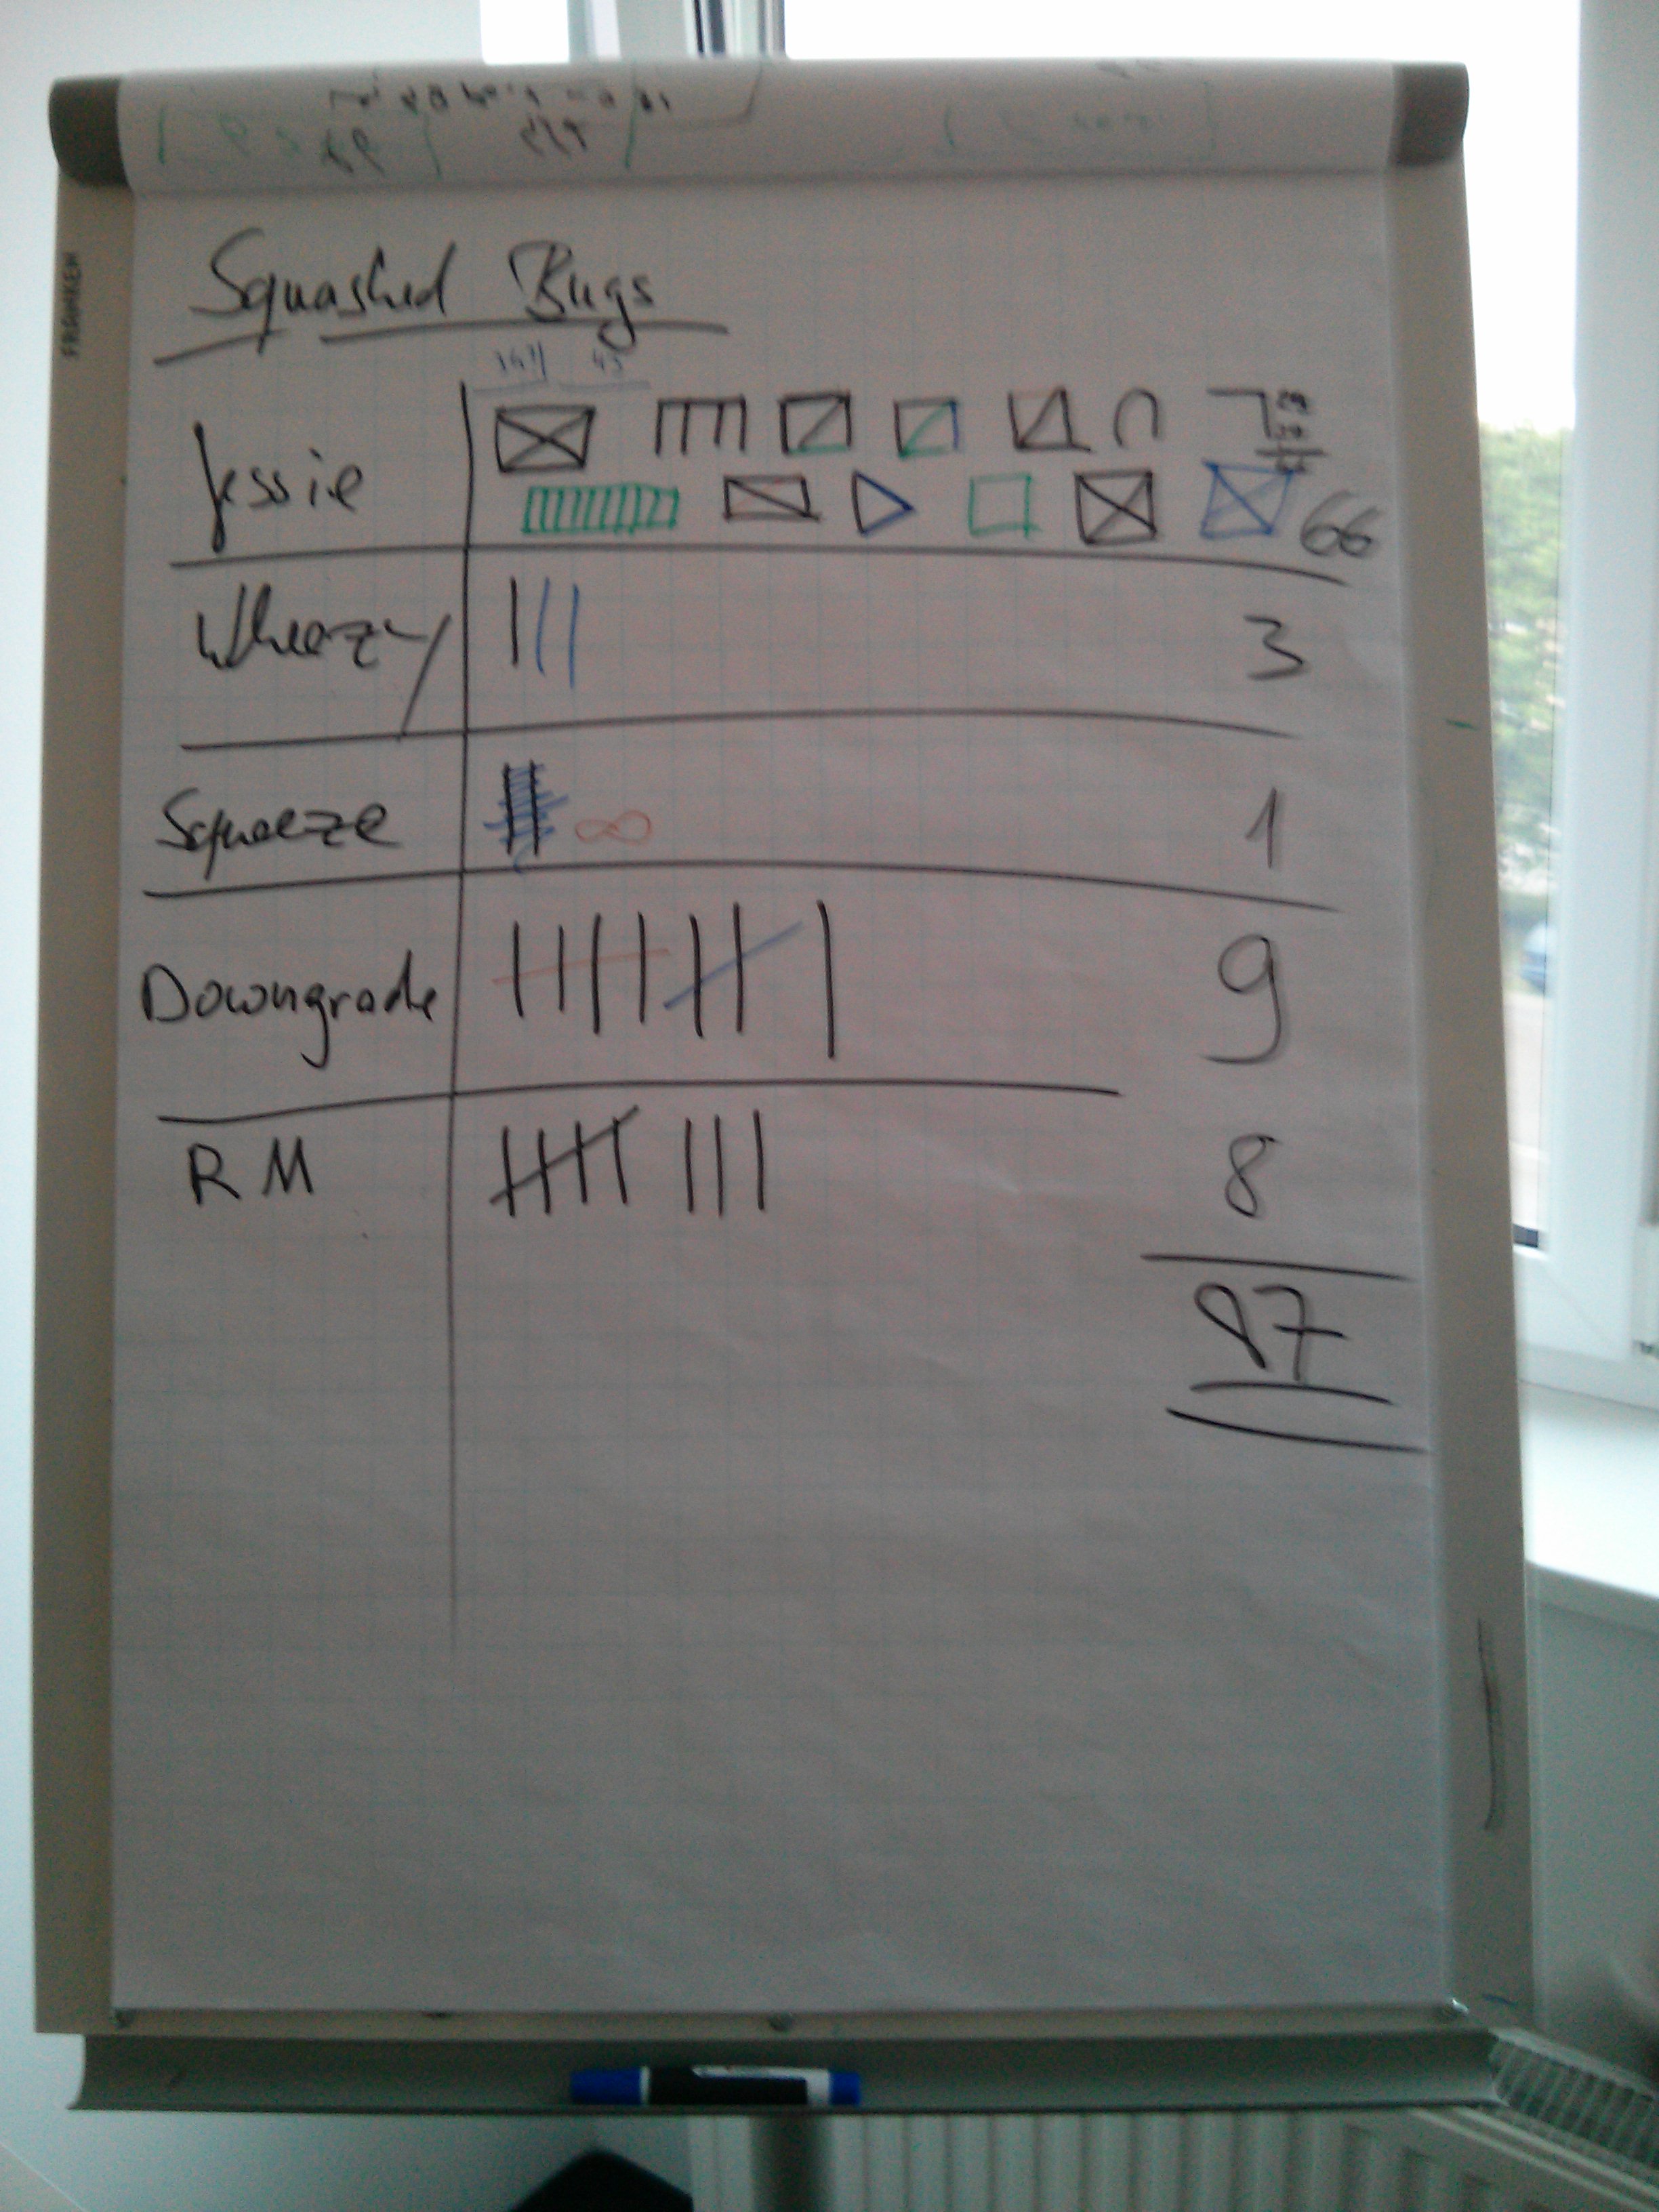
bsp2014_small This weekend, Bernd Zeimetz organized a BSP at the offices of conova in Salzburg, Austria. Three days of discussions, bugfixes, sparc removals and a lot of fun and laughter. We squashed a total of 87 bugs: 66 bugs affecting Jessie/Sid were closed, 9 downgraded and 8 closed via removals. As people tend to care about (old)stable, 3 bugs were fixed in Wheezy and one in Squeeze. These numbers might be not totaly correct, as were kinda creative at counting Marga promised a talk about an introduction to properly counting bugs using the Haus vom Nikolaus algorithm to the base of 7 . IMG_20140427_182902 Speaking of numbers, I touched the following bugs (not all RC): A couple of (non-free) pictures are available at Uwe s salzburg-cityguide.at. Thanks again to Bernd for organizing and conova and credativ for sponsoring!

27 April 2014

Vincent Bernat: Local corporate APT repositories

Distributing software efficiently accross your platform can be difficult. Every distribution comes with a package manager which is usually suited for this task. APT can be relied upon on when using Debian or a derivative. Unfortunately, the official repositories may not contain everything you need. When you require unpackaged software or more recent versions, it is possible to setup your own local repository. Most of what is presented here was setup for Dailymotion and was greatly inspired by the work done by Rapha l Pinson at Orange.

Setting up your repositories There are three kinds of repositories you may want to setup:
  1. A distribution mirror. Such a mirror will save bandwidth, provide faster downloads and permanent access, even when someone searches Google on Google.
  2. A local repository for your own packages with the ability to have a staging zone to test packages on some servers before putting them in production.
  3. Mirrors for unofficial repositories, like Ubuntu PPA. To avoid unexpected changes, such a repository will also get a staging and a production zone.
Before going further, it is quite important to understand what a repository is. Let s illustrate with the following line from my /etc/apt/sources.list:
deb http://ftp.debian.org/debian/ unstable main contrib non-free
In this example, http://ftp.debian.org/debian/ is the repository and unstable is the distribution. A distribution is subdivided into components. We have three components: main, contrib and non-free. To setup repositories, we will use reprepro. This is not the only solution but it has a good balance between versatility and simplicity. reprepro can only handle one repository. So, the first choice is about how you will split your packages in repositories, distributions and components. Here is what matters:
  • A repository cannot contain two identical packages (same name, same version, same architecture).
  • Inside a component, you can only have one version of a package.
  • Usually, a distribution is a subset of the versions while a component is a subset of the packages. For example, in Debian, with the distribution unstable, you choose to get the most recent versions while with the component main, you choose to get DFSG-free software only.
If you go for several repositories, you will have to handle several reprepro instances and won t be able to easily copy packages from one place to another. At Dailymotion, we put everything in the same repository but it would also be perfectly valid to have three repositories:
  • one to mirror the distribution,
  • one for your local packages, and
  • one to mirror unofficial repositories.
Here is our target setup: Local APT repository

Initial setup First, create a system user to work with the repositories:
$ adduser --system --disabled-password --disabled-login \
>         --home /srv/packages \
>         --group reprepro
All operations should be done with this user only. If you want to setup several repositories, create a directory for each of them. Each repository has those subdirectories:
  • conf/ contains the configuration files,
  • gpg/ contains the GPG stuff to sign the repository1,
  • logs/ contains the logs,
  • www/ contains the repository that should be exported by the web server.
Here is the content of conf/options:
outdir +b/www
logdir +b/logs
gnupghome +b/gpg
Then, you need to create the GPG key to sign the repository:
$ GNUPGHOME=gpg gpg --gen-key
Please select what kind of key you want:
   (1) RSA and RSA (default)
   (2) DSA and Elgamal
   (3) DSA (sign only)
   (4) RSA (sign only)
Your selection? 1
RSA keys may be between 1024 and 4096 bits long.
What keysize do you want? (2048) 4096
Requested keysize is 4096 bits
Please specify how long the key should be valid.
         0 = key does not expire
      <n>  = key expires in n days
      <n>w = key expires in n weeks
      <n>m = key expires in n months
      <n>y = key expires in n years
Key is valid for? (0) 10y
Key expires at mer. 08 nov. 2023 22:30:58 CET
Is this correct? (y/N) y
Real name: Dailymotion Archive Automatic Signing Key
Email address: the-it-operations@dailymotion.com
Comment: 
[...]
By setting an empty password, you allow reprepro to run unattended. You will have to distribute the public key of your new repository to let APT check the archive signature. An easy way is to ship it in some package.

Local mirror of an official distribution Let s start by mirroring a distribution. We want a local mirror of Ubuntu Precise. For this, we need to do two things:
  1. Setup a new distribution in conf/distributions.
  2. Configure the update sources in conf/updates.
Let s add this block to conf/distributions:
# Ubuntu Precise
Origin: Ubuntu
Label: Ubuntu
Suite: precise
Version: 12.04
Codename: precise
Architectures: i386 amd64
Components: main restricted universe multiverse
UDebComponents: main restricted universe multiverse
Description: Ubuntu Precise 12.04 (with updates and security)
Contents: .gz .bz2
UDebIndices: Packages Release . .gz
Tracking: minimal
Update: - ubuntu-precise ubuntu-precise-updates ubuntu-precise-security
SignWith: yes
This defines the precise distribution in our repository. It contains four components: main, restricted, universe and multiverse (like the regular distribution in official repositories). The Update line starts with a dash. This means reprepro will mark everything as deleted before updating with the provided sources. Old packages will not be kept when they are removed from Ubuntu. In conf/updates, we define the sources:
# Ubuntu Precise
Name: ubuntu-precise
Method: http://fr.archive.ubuntu.com/ubuntu
Fallback: http://de.archive.ubuntu.com/ubuntu
Suite: precise
Components: main main multiverse restricted universe
UDebComponents: main restricted universe multiverse
Architectures: amd64 i386
VerifyRelease: 437D05B5
GetInRelease: no
# Ubuntu Precise Updates
Name: ubuntu-precise-updates
Method: http://fr.archive.ubuntu.com/ubuntu
Fallback: http://de.archive.ubuntu.com/ubuntu
Suite: precise-updates
Components: main restricted universe multiverse
UDebComponents: main restricted universe multiverse
Architectures: amd64 i386
VerifyRelease: 437D05B5
GetInRelease: no
# Ubuntu Precise Security
Name: ubuntu-precise-security
Method: http://fr.archive.ubuntu.com/ubuntu
Fallback: http://de.archive.ubuntu.com/ubuntu
Suite: precise-security
Components: main restricted universe multiverse
UDebComponents: main restricted universe multiverse
Architectures: amd64 i386
VerifyRelease: 437D05B5
GetInRelease: no
The VerifyRelease lines are GPG key fingerprint to use to check the remote repository. The key needs to be imported in the local keyring:
$ gpg --keyring /usr/share/keyrings/ubuntu-archive-keyring.gpg \
>     --export 437D05B5   GNUPGHOME=gpg gpg --import
Another important point is that we merge three distributions (precise, precise-updates and precise-security) into a single distribution (precise) in our local repository. This may cause some difficulties with tools expecting the three distributions to be available (like the Debian Installer2). Next, you can run reprepro and ask it to update your local mirror:
$ reprepro update
This will take some time on the first run. You can execute this command every night. reprepro is not the fastest mirror solution but it is easy to setup, flexible and reliable.

Repository for local packages Let s configure the repository to accept local packages. For each official distribution (like precise), we will configure two distributions:
  • precise-staging contains packages that have not been fully tested and not ready to go to production.
  • precise-prod contains production packages copied from precise-staging.
In our workflow, packages are introduced in precise-staging where they can be tested and will be copied to precise-prod when we want them to be available for production. You can adopt a more complex workflow if you need. The reprepro part is quite easy. We add the following blocks into conf/distributions:
# Dailymotion Precise packages (staging)
Origin: Dailymotion #  
Label: dm-staging   #  
Suite: precise-staging
Codename: precise-staging
Architectures: i386 amd64 source
Components: main role/dns role/database role/web #  
Description: Dailymotion Precise staging repository
Contents: .gz .bz2
Tracking: keep
SignWith: yes
NotAutomatic: yes #  
Log: packages.dm-precise-staging.log
 --type=dsc email-changes
# Dailymotion Precise packages (prod)
Origin: Dailymotion #  
Label: dm-prod      #  
Suite: precise-prod
Codename: precise-prod
Architectures: i386 amd64 source
Components: main role/dns role/database role/web #  
Description: Dailymotion Precise prod repository
Contents: .gz .bz2
Tracking: keep
SignWith: yes
Log: packages.dm-precise-prod.log
First notice we use several components (in ):
  • main will contain packages that are not specific to a subset of the platform. If you put a package in main, it should work correctly on any host.
  • role/* are components dedicated to a subset of the platform. For example, in role/dns, we ship a custom version of BIND.
The staging distribution has the NotAutomatic flag (in ) which disallows the package manager to install those packages except if the user explicitely requests it. Just below, when a new dsc file is uploaded, the hook email-changes will be executed. It should be in the conf/ directory. The Origin and Label lines (in ) are quite important to be able to define an explicit policy of which packages should be installed. Let s say we use the following /etc/apt/sources.list file:
# Ubuntu packages
deb http://packages.dm.gg/dailymotion precise main restricted universe multiverse
# Dailymotion packages
deb http://packages.dm.gg/dailymotion precise-prod    main role/dns
deb http://packages.dm.gg/dailymotion precise-staging main role/dns
All servers have the precise-staging distribution. We must ensure we won t install those packages by mistake. The NotAutomatic flag is one possible safe-guard. We also use a tailored /etc/apt/preferences:
Explanation: Dailymotion packages of a specific component should be more preferred
Package: *
Pin: release o=Dailymotion, l=dm-prod, c=role/*
Pin-Priority: 950
Explanation: Dailymotion packages should be preferred
Package: *
Pin: release o=Dailymotion, l=dm-prod
Pin-Priority: 900
Explanation: staging should never be preferred
Package: *
Pin: release o=Dailymotion, l=dm-staging
Pin-Priority: -100
By default, packages will have a priority of 500. By setting a priority of -100 to the staging distribution, we ensure the packages cannot be installed at all. This is stronger than NotAutomatic which sets the priority to 1. When a package exists in Ubuntu and in our local repository, we ensure that, if this is a production package, we will use ours by using a priority of 900 (or 950 if we match a specific role component). Have a look at the How APT Interprets Priorities section of apt_preferences(5) manual page for additional information. Keep in mind that version matters only when the priority is the same. To check if everything works as you expect, use apt-cache policy:
$ apt-cache policy php5-memcache
  Installed: 3.0.8-1~precise2~dm1
  Candidate: 3.0.8-1~precise2~dm1
  Version table:
 *** 3.0.8-1~precise2~dm1 0
        950 http://packages.dm.gg/dailymotion/ precise-prod/role/web amd64 Packages
        100 /var/lib/dpkg/status
     3.0.8-1~precise1~dm4 0
        900 http://packages.dm.gg/dailymotion/ precise-prod/main amd64 Packages
       -100 http://packages.dm.gg/dailymotion/ precise-staging/main amd64 Packages
     3.0.6-1 0
        500 http://packages.dm.gg/dailymotion/ precise/universe amd64 Packages
If we want to install a package from the staging distribution, we can use apt-get with the -t precise-staging option to raise the priority of this distribution to 990. Once you have tested your package, you can copy it from the staging distribution to the production distribution:
$ reprepro -C main copysrc precise-prod precise-staging wackadoodle

Local mirror of third-party repositories Sometimes, you want a software published on some third-party repository without to repackage it yourself. A common example is the repositories edited by hardware vendors. Like for an Ubuntu mirror, there are two steps: defining the distribution and defining the source. We chose to put such mirrors into the same distributions as our local packages but with a dedicated component for each mirror. This way, those third-party packages will share the same workflow as our local packages: they will appear in the staging distribution, we validate them and copy them to the production distribution. The first step is to add the components and an appropriate Update line to conf/distributions:
Origin: Dailymotion
Label: dm-staging
Suite: precise-staging
Components: main role/dns role/database role/web vendor/hp
Update: hp
# [...]
Origin: Dailymotion
Label: dm-prod
Suite: precise-prod
Components: main role/dns role/database role/web vendor/hp
# [...]
We added the vendor/hp component to both the staging and the production distributions. However, only the staging distribution gets an Update line (remember, packages will be copied manually into the production distribution). We declare the source in conf/updates:
# HP repository
Name: hp
Method: http://downloads.linux.hp.com/SDR/downloads/ManagementComponentPack/
Suite: precise/current
Components: non-free>vendor/hp
Architectures: i386 amd64
VerifyRelease: 2689B887
GetInRelease: no
Don t forget to add the GPG key to your local keyring. Notice an interesting feature of reprepro: we copy the remote non-free component to our local vendor/hp component. Then, you can synchronize the mirror with reprepro update. Once the packages have been tested, you will have to copy them in the production distribution.

Building Debian packages Our reprepro setup seems complete, but how do we put packages into the staging distribution? You have several options to build Debian packages for your local repository. It really depends on how much time you want to invest in this activity:
  1. Build packages from source by adding a debian/ directory. This is the classic way of building Debian packages. You can start from scratch or use an existing package as a base. In the latest case, the package can be from the official archive but for a more recent distribution or a backport or from an unofficial repository.
  2. Use a tool that will create a binary package from a directory, like fpm. Such a tool will try to guess a lot of things to minimize your work. It can even download everything for you.
There is no universal solution. If you don t have the time budget for building packages from source, have a look at fpm. I would advise you to use the first approach when possible because you will get those perks for free:
  • You keep the sources in your repository. Whenever you need to rebuild something to fix an emergency bug, you won t have to hunt the sources which may be unavailable when you need them the most. Of course, this only works if you build packages that don t download stuff directly from the Internet.
  • You also keep the recipe3 to build the package in your repository. If someone enables some option and rebuild the package, you won t accidently drop this option on the next build. Those changes can be documented in debian/changelog. Moreover, you can use a version control software for the whole debian/ directory.
  • You can propose your package for inclusion into Debian. This will help many people once the package hits the archive.

Builders We chose pbuilder as a builder4. Its setup is quite straightforward. Here is our /etc/pbuilderrc:
DISTRIBUTION=$DIST
NAME="$DIST-$ARCH"
MIRRORSITE=http://packages.dm.gg/dailymotion
COMPONENTS=("main" "restricted" "universe" "multiverse")
OTHERMIRROR="deb http://packages.dm.gg/dailymotion $ DIST -staging main"
HOOKDIR=/etc/pbuilder/hooks.d
BASE=/var/cache/pbuilder/dailymotion
BASETGZ=$BASE/$NAME/base.tgz
BUILDRESULT=$BASE/$NAME/results/
APTCACHE=$BASE/$NAME/aptcache/
DEBBUILDOPTS="-sa"
KEYRING="/usr/share/keyrings/dailymotion-archive.keyring.gpg"
DEBOOTSTRAPOPTS=("--arch" "$ARCH" "--variant=buildd" "$ DEBOOTSTRAPOPTS[@] " "--keyring=$KEYRING")
APTKEYRINGS=("$KEYRING")
EXTRAPACKAGES=("dailymotion-archive-keyring")
pbuilder is expected to be invoked with DIST, ARCH and optionally ROLE environment variables. Building the initial bases can be done like this:
for ARCH in i386 amd64; do
  for DIST in precise; do
    export ARCH
    export DIST
    pbuilder --create
  done
done
We don t create a base for each role. Instead, we use a D hook to add the appropriate source:
#!/bin/bash
[ -z "$ROLE" ]    
  cat >> /etc/apt/sources.list <<EOF
deb http://packages.dm.gg/dailymotion $ DIST -staging role/$ ROLE 
EOF
 
apt-get update
We ensure packages from our staging distribution are preferred over other packages by adding an /etc/apt/preferences file in a E hook:
#!/bin/bash
cat > /etc/apt/preferences <<EOF
Explanation: Dailymotion packages are of higher priority
Package: *
Pin: release o=Dailymotion
Pin-Priority: 900
EOF
We also use a C hook to get a shell in case there is an error. This is convenient to debug a problem:
#!/bin/bash
apt-get install -y --force-yes vim less
cd /tmp/buildd/*/debian/..
/bin/bash < /dev/tty > /dev/tty 2> /dev/tty
A manual build can be run with:
$ ARCH=amd64 DIST=precise ROLE=web pbuilder \
>         --build somepackage.dsc

Version numbering To avoid to apply complex rules to chose a version number for a package, we chose to treat everything as a backport, even in-house software. We use the following scheme: X-Y~preciseZ+dmW.
  • X is the upstream version5.
  • Y is the Debian version. If there is no Debian version, use 0.
  • Z is the Ubuntu backport version. Again, if such a version doesn t exist, use 0.
  • W is our version of the package. We increment it when we make a change to the packaging. This is the only number we are allowed to control. All the others are set by an upstream entity, unless it doesn t exist and in this case, you use 0.
Let s suppose you need to backport wackadoodle. It is available in a more recent version of Ubuntu as 1.4-3. Your first backport will be 1.4-3~precise0+dm1. After a change to the packaging, the version will be 1.4-3~precise0+dm2. A new upstream version 1.5 is available and you need it. You will use 1.5-0~precise0+dm1. Later, this new upstream version will be available in some version of Ubuntu as 1.5-3ubuntu1. You will rebase your changes on this version and get 1.5-3ubuntu1~precise0+dm1. When using Debian instead of Ubuntu, a compatible convention could be : X-Y~bpo70+Z~dm+W.

Uploading To upload a package, a common setup is the following workflow:
  1. Upload the source package to an incoming directory.
  2. reprepro will notice the source package, check its correctness (signature, distribution) and put it in the archive.
  3. The builder will notice a new package needs to be built and build it.
  4. Once the package is built, the builder will upload the result to the incoming directory.
  5. reprepro will notice again the new binary package and integrate it in the archive.
This workflow has the disadvantage to have many moving pieces and to leave the user in the dark while the compilation is in progress. As an alternative, a simple script can be used to execute each step synchronously. The user can follow on their terminal that everything works as expected. Once we have the .changes file, the build script just issues the appropriate command to include the result in the archive:
$ reprepro -C main include precise-staging \
>      wackadoodle_1.4-3~precise0+dm4_amd64.changes
Happy hacking!

  1. The gpg/ directory could be shared by several repositories.
  2. We teached Debian Installer to work with our setup with an appropriate preseed file.
  3. fpm-cookery is a convenient tool to write recipes for fpm, similar to Homebrew or a BSD port tree. It could be used to achieve the same goal.
  4. sbuild is an alternative to pbuilder and is the official builder for both Debian and Ubuntu. Historically, pbuilder was more focused on developers needs.
  5. For a Git snapshot, we use something like 1.4-git20130905+1-ae42dc1 which is a snapshot made after version 1.4 (use 0.0 if no version has ever been released) at the given date. The following 1 is to be able to package different snapshots at the same date while the hash is here in case you need to retrieve the exact snapshot.

Keith Packard: Glamor performance

Current Glamor Performance I finally managed to get a Gigabyte Brix set up running Debian so that I could do some more reasonable performance characterization of Glamor in its current state. I wanted to use this particular machine because it has enough cooling to keep from thermally throttling the CPU/GPU package. This is running my glamor-server branch of the X server, which completes the core operation rework and then has some core X server performance improvements as well for filled and outlined arcs. Changes in X11perf First off, I did some analysis of what x11perf was doing and found that it wasn t quite measuring what we thought. I m not interested in competing on x11perf numbers absolutely, I m only interested in doing relative measurements of useful operations, so fixing the tool to measure what I want seems reasonable to me. When x11perf was first written, it drew 100x100 rectangles tight against one another without any gap. And, it filled the window with them, drawing a 6x6 grid of 100x100 rectangles in a 600x600 window. To better exercise the rectangle code and check edge conditions better, we added a one pixel gap between the rectangles. However, we didn t reduce the number of rectangles drawn, so we ended up drawing 11 of the 36 rectangles on top of the first set of 25. Simple region computations would allow the X server to draw only 25 most of the time, skipping the redundant rectangles. The vertical and horizontal line tests were added a while after the first set of tests, and were done without regard to how an X server might optimize for them. x11perf draws these lines packed tightly together, creating a single square of pixels for the result. EXA, UXA and SNA all take vertical and horizontal lines and convert them to rectangles, then take the rectangles and clip them against the window clip list by computing a region from them and intersecting that with the GC composite clip. It s a completely reasonable plan, however, when you take what x11perf was drawing and run it through this code, you end up with a single solid rectangle. Which is surprisingly fast, compared with drawing individual lines. I fixed the overlapping rectangle case by reducing the number of boxes drawn from 36 to 25, and I fixed the vertical and horizontal line case by spacing the lines a pixel apart. I ve pushed out these changes to my x11perf repository on freedesktop.org. What s Fast Things that match GL s capabilities are fast, things which don t are slow. No surprises there. What s interesting is precisely what matches GL Patterns For Free Because GL makes it easy to program fill patterns into the GPU, there are essentially no performance differences between solid and patterned operations. GL Lines Glamor uses GL lines, which can be programmed to match X semantics, to quite good effect. The only trick required was to deal with cap styles. GL never draws the final pixel in a line, while X does unless the cap style is CapNotLast. The solution was to draw an extra line segment containing a single pixel at the end of every joined set of lines for this case. The other implicit requirement is that all zero width lines look the same. Right now, I ve solved that for fill styles and raster ops as they re all drawn with the same GL operations. However, for plane masks, we re currently falling back to software, which may draw something different. Fixing that isn t impossible, it s just tedious. Text Pushing all of the work of drawing core text into glamor wasn t terribly difficult, and the results are pretty spectacular. What s Slow We ve still got room for improvement in Glamor, but there aren t any obvious show-stoppers to getting great performance for reasonable X applications anymore. Wide Lines and Arcs One of the speed-ups I ve made in my glamor branch is to merge all of drawing of multiple filled and zero-width arcs into a single giant GL request. That turned out to both improve performance and save a bit of code. Right now, drawing wide lines and wide arcs doesn t do this, and so we suffer from submitting many smaller requests to GL. It s hard to get excited about speeding any of this up as all of the wide primitives are essentially unused these days. Filled Polygons Because X only lets applications draw a single polygon in each request, Glamor can t really gain any efficiency from batching work unless we start looking ahead in the X protocol stream to see if the next request is another polygon. Alternatively, we could leave the span operation pending to see if more spans were coming before the X serve went idle. Neither of these is all that exciting though; X polygons just aren t that useful. Render Operations These are still not structured to best fit modern GL; some work here would help a bunch. We ve got a gsoc student ready to go at this though, so I expect we ll have much better numbers in a few months. Window Operations You wouldn t think that moving and resizing windows would be so limited by drawing performance, but x11perf tests these with tiny little windows, and each operation draws or copies only a couple of little rectangles, which makes GL quite expensive. Working on speeding up GL for small numbers of operations would help a bunch here. Unexpected Results Solid rectangles are actually running slower than patterned rectangles, and I really have no idea why. The CPU is close to idle during the 500x500 solid rectangle test (as you d expect, given the workload), the vertex and fragment shaders look correct out of the compiler, and yet solid rectangles run at only 0.80 of the performance of the patterned rectangles. GL semantics for copying data essentially preclude overlapping blts of any form. There s the NVtexturebarrier extension which at least lets us do blts within the same object, but even that doesn t define how overlapping blts work. So, we have to create a temporary copy for this operation to make it work right. I was worried that this would slow things down, but the Iris Pro 3D engine is enough faster than the 2D engine that even with the extra copy, large scrolls and copies within the same object are actually faster. Results Here s a giant image showing the ratio of Glamor to both UXA and SNA running on the same machine, with all of the same software; the only change between runs was to switch the configured acceleration architecture.

Russell Coker: Swap Breaking SSD

I ve seen many comments about swap space and SSD claiming that swap will inherently destroy SSD through using too many writes. The latest was in the comments of my post about swap space and SSD performance [1]. Note that I m not criticising the person who commented on my blog, everyone has heard lots of reports about possible problems that they avoid without analysing them in detail. The first thing to note is that the quality of flash memory varies a lot, the chips that are used in SSDs for workstation/server use are designed to last while those in USB-flash devices aren t. I ve documented my unsuccessful experiments with using USB-flash for the root filesystem of a gateway server [2] (and the flash device that wasn t used for swap died too). The real issue when determining whether swap will break your SSD is the amount of writes. While swapping can do a lot of writing quickly that usually doesn t happen unless something has gone wrong. The workstation that I m currently using has writes to the root fileystem outnumbering writes to swap by a factor of 130:1 (by volume of data written). On other days I ve seen it as low as 42:1, in either case it s writes to the root filesystem (which is BTRFS and includes /home etc) that will break the SSD if anything. For some other workstations I run I see ratios of 201:1 (that s with 8G of RAM), 57:1, and 23:1. In a quick search I couldn t find a single system I run where even 10% of disk writes were attributed to swap. This really isn t surprising given that adding RAM is a cheap way to improve the performance of most systems. If a SSD didn t do any write leveling (as is rumored to be the case with cheap USB flash devices) then swap use might still cause a problem because of the number of writes in a small area, but if that was the case then filesystem journals and other fixed data structures would be more likely to cause a problem and any swap based breakage would break swap not the root filesystem (although if swap was the first partition then it might also break the MBR). Of the workstations that are convenient to inspect the one with the most writes to the root filesystem and swap space (IE everything on /dev/sda) had 128G written per day for 1.2 days of uptime, but that involved running a filesystem balance and some torrent downloads (not the typical use). Among the two systems which had been running for more than 48 hours with typical use the most writes was 24G in a day. If a SSD can sustain 10,000 writes per block (which is smaller than quoted by most flash manufacturers nowadays) and has perfect wear leveling (which is unlikely) then the system with a 120G SSD and 128G written in a day could continue like that for almost 10,000 days or 27 years much longer than storage is expected to work or be useful. So for workstation use (where even 24G of writes per day probably counts as heavy use) a 120G SSD that can sustain 10,000 writes per block shouldn t be at great risk of wearing out. Conclusion I believe that swap is much less likely to break SSDs than regular file access on every system with a reasonable amount of RAM. For systems which don t have enough RAM you probably want the speed of SSD for swap space anyway in spite of the risks. If wear leveling works as designed and the 10,000+ writes per block claims are accurate then SSDs will massively outlast their useful life. Long before they wear out they should be too small, too slow, and probably not compatible. 26 years ago I had a 5.25 full height ST-506 disk in my desktop PC, it wouldn t physically fit in most systems I own now (unless I removed the DVD drive), there is no possibility of buying a controller (I don t own a system with an ISA bus), and that disk was too slow and small by today s standards. A 27yo SSD isn t going to be useful for anything, even for archive storage it s no good as no-one has tested long term storage and data could decay before then.

26 April 2014

Russell Coker: BTRFS Status April 2014

Since my blog post about BTRFS in March [1] not much has changed for me. Until yesterday I was using 2.13 kernels on all my systems and dealing with the occasional kmail index file corruption problem. Yesterday my main workstation ran out of disk space and went read-only. I started a BTRFS balance which didn t seem to be doing any good because most of the space was actually in use so I deleted a bunch of snapshots. Then my X session aborted (some problem with KDE or the X server I ll never know as logs couldn t be written to disk). I rebooted the system and had kernel threads go into infinite loops with repeated messages about a lack of response for 22 seconds (I should have photographed the screen). When it got into that state the ALT-Fn keys to change a virtual console sometimes worked but nothing else worked the terminal usually didn t respond to input. To try and stop the kernel from entering an infinite loop on every boot that I used rootflags=skip_balance on the kernel command line to stop it from continuing the balance which made the system usable for a little longer, unfortunately the skip_balance mount option doesn t permanently apply, the kernel will keep trying to balance the filesystem on every mount until a btrfs balance cancel operation succeeds. But my attempts to cancel the balance always failed. When I booted my system with skip_balance it would sometimes free some space from the deleted snapshots, after two good runs I got to 17G free. But after that every time I rebooted it would report another Gig or two free (according to btrfs filesystem df ) and then hang without committing the changes to disk. I solved this problem by upgrading my USB rescue image to kernel 3.14 from Debian/Experimental and mounting the filesystem from the rescue image. After letting kernel 3.14 work on the filesystem for a while it was in a stage where I could use it with kernel 3.13 and then boot the system normally to upgrade it to kernel 3.14. I had a minor extra complication due to the fact that I was running apt-get dist-upgrade at the time the filesystem went read-only do the dpkg records of which packages were installed were a bit messed up. But that was easy to fix by running a diff against /var/lib/dpkg/info on a recent snapshot. In retrospect I should have copied from an old snapshot of the root filesystem, but I fixed the problems faster than I could think of better ways to fix them. When running a balance the system had a peak IO rate of about 30MB/s reads and 30MB/s writes. That compares to the maximum contiguous file IO speed of 260MB/s for reads and 320MB/s for writes. During that time it had about 50% CPU time used for my Q8400 quad-core CPU. So far the only tasks that I do regularly which have CPU speed as a significant bottleneck are BTRFS filesystem balancing and recoding MP4 files. Compiling hasn t been an issue because recently I haven t been compiling many programs that are particularly big. Lessons Learned I should photograph the screen regularly when doing things that won t be logged, those kernel error messages might have been useful to me or someone else. The fact that the only kernel that runs BTRFS the way I need comes from the Experimental repository in Debian stands in contrast to the recent kernel patch that stops describing BTRFS as experimental. While I have a high opinion of the people who provide support for the kernel in commercial distributions and their ability to back-port fixes from newer kernels I m concerned about their decision to support BTRFS. I m also dubious about whether we can offer BTRFS support in Debian/Jessie (the next version of Debian) without a significant warning. OTOH if you find yourself with a BTRFS system that isn t working well you could always hire me to fix it. I accept payment via Paypal, bank transfer, or Bitcoin. If you want to pay me in Grange then I assure you I will never forget about it. ;) I thought that I wouldn t have CPU speed issues when I started using the AMD64 architecture, for most tasks that s been the case. But for systems for which storage is important I ll look at getting faster CPUs because of BTRFS. Using faster CPUs for storage isn t that uncommon (I used to work for SGI and dealt with some significant CPU power used for file serving), but needing a fast quad-core CPU to drive a single SSD is a little disappointing. While recovery from file system corner cases isn t going to be particularly common it s something that you want completed quickly, for personal systems you want to be doing something else and for work systems you don t want down-time. The BTRFS problems with running out of disk space are really serious. It seems that even workstations used at home can t survive without monitoring. For any other filesystem used at home you can just let it get full and then delete stuff. Include rootflags=skip_balance in the boot loader configuration for every system with a BTRFS root filesystem and in the /etc/fstab for every non-root BTRFS filesystem. I haven t yet encountered a single situation where continuing the balance did any good or when it didn t do any harm.

25 April 2014

Matthias Klumpp: AppStream 0.6.1 released a quick look at what you can do with the cli tool

Today I released AppStream and libappstream 0.6.1, which feature mostly bugfixes, so nothing incredibly exciting to see there (but this also means no API/ABI breaks). The release clarifies some paragraphs in the spec which people found confusing, and fixes a few issues (like one example in the docs not being valid AppStream metadata). As only spec extension, we introduce a priority property in distro metadata to allow metadata from one repository to override data shipped by another one. This is used (although with a similar syntax) in Fedora already to have placeholder data for non-free stuff, which gets overridden by the real metadata if a new application was added. In general, the property tag was added to make the answer to the question which data is preferred much less magic. The libappstream library got some new API to query component data in different ways, and I also brought back support for Vala (so if you missed the Vapi file: It s back now, although you have to manually enable this feature). The CLI tool also got some extensions to query AppStream data. Here is a brief introduction: First of all, we need to make sure the database is up-to-date, which should be the case already (it is rebuilt automatically):
$ sudo appstream-index --refresh
The database will only be rebuilt when necessary, if you want to force a rebuild anyway, use the force parameter. Now imagine we want to search for an app containing the word media (in description, keywords, summary, ):
$ appstream-index -s media
which will return:
Identifier: gnome-media-player.desktop [desktop-app]
Name: GNOME Media Player
Summary: A simple media player for GNOME
Package: gnome-media-player
----
Identifier: mediaplayer-app.desktop [desktop-app]
Name: Media Player
Summary: Media Player
Package: mediaplayer-app
----
Identifier: kde4__plasma-mediacenter.desktop [desktop-app]
Name: Plasma Media Center
Summary: A mediacenter user interface written with the Plasma framework
Package: plasma-mediacenter
----
etc.
If we already know the name if a .desktop-file or the ID of a component, we can have the tool print out information about the application, including which package it was installed from:
$ appstream-index --get lyx.desktop
If we want to see more details, including e.g. a screenshot URL and a longer description, we can pass details to the tool:
Identifier: lyx.desktop [desktop-app]
Name: LyX
Summary: An advanced document processor with the power of LaTeX.
Package: lyx-common
Homepage: http://www.lyx.org/
Icon: lyx.png
Description: LyX is a document processor that encourages an approach to writing
 based on the structure of your documents (WYSIWYM) and not simply
 their appearance (WYSIWYG).
 
 LyX combines the power and flexibility of TeX/LaTeX[...]
Sample Screenshot URL: http://alt.fedoraproject.org/pub/alt/screenshots/f21/source/lyx-ea535ddf18b5c7328c5e88d2cd2cbd8c.png
License: GPLv2+
(I truncated the results slightly ;-) ) Okay, so far so good. But now it gets really exciting (and this is a feature added with 0.6.1): We can now query a component by the items it provides. For example, I want to know which software provides the library libfoo.2:
appstream-index --what-provides -t lib -v libfoo.so.2
This also works with binaries, or Python modules:
appstream-index --what-provides -t bin -v apper
This stuff works distribution-agnostic, and as long as software ships upstream metadata with a valid <provides/> field, or the distributor adds it while generating AppStream distro metadata.
This means that software can as soon as we have sufficient metadata of this kind declare it s dependencies upstream in form of a simple text file, referencing the needed components to build and run it on any Linux distribution. Users can simply install missing stuff by passing that file to their package manager, which can look up the components->packaging mapping and versions and do the right thing in installing the dependencies. So basically, this allows things pip -r does for Python, but for any application (not only Python stuff), and based on the distributors package database. With the provides-items, we can also scan software to detect it s dependencies automatically (and have it in a distro-agnostic form directly). We can also easily search for missing mimetype-handlers, missing kernel-modules, missing firmware etc. to install it on-demand, making the system much smarter in handling it s dependencies. And users don t need to do search orgies to find the right component for a given task. Also on my todo list for the future, based on this feature: A small tool telling upstream authors which distribution has their application in which version, using just one command (and AppStream data from multiple distros). Also planned: A cross-distro information page showing which distros ship which library versions, Python modules and application versions (and also the support status of the distro), so developers know which library versions (or GCC versions etc.) they should at least support to make their application easily available on most distributions. As always, you can get the releases on Freedesktop, as well es the AppStream specification.

23 April 2014

Russ Allbery: On learning, growth, and trust

Here are two separate ideas about programming, Internet security, Internet architecture, and free software. Both of them are fundamental to everything those of us who work on free software are doing.
  1. Writing secure and reliable code is a highly complex and demanding task. It's something that one has to learn, like any other skilled profession. It's not something we're very good at teaching via any mechanism other than apprenticeship and experimentation. The field is changing quickly; if you took ten years off from writing security-critical code, you would expect to have to learn multiple new tools (static analysis, testing techniques, security features), possibly new programming languages, and not infrequently new ways of thinking about threat models and vulnerabilities.
  2. Nearly every computer user trusts tens of thousands of other programmers and millions of lines of code with their day-to-day computer security and reliability, without auditing that code themselves. Even if you have the skill required to audit the code (and very, very few people have the skill to audit all of the code that they use), you do not have the time. Therefore, our computer security is built on trust. We're trusting other programmers not to be malicious, which is obvious, but we're also trusting other programmers to be highly skilled, careful, cautious (but still fast and productive, since we quickly abandon software that isn't "actively developed"), and constantly adopting new techniques and treat models.
I think both of those principles are very widely understood and widely acknowledged. And, as we all know, both of those principles have failure modes, and those failures mean that our computers are nowhere near as secure as we would like them to be. There has been quite a lot of technical discussion about both of these principles in recent days and months, ranging from better code analysis and testing through the flaws in particular programming languages to serious questions about the trust model we use for verifying the code that we're running. I'm going to switch gears away from that discussion for a moment to talk about a social aspect. When a piece of code that one is using has a security vulnerability, it is not unusual to treat that as a trust failure. In other words, technical flaws are very quickly escalated to social flaws. This is less likely among practitioners, since we're all painfully aware of how many bugs we have in our own code, but it's still not unheard of, particularly if the authors of the code do not immediately and publicly show a socially-acceptable level of humility and contrition (in the middle of what is often a horrifically stressful experience). I think this reaction comes largely from fear. Anyone who has given it a moment's thought is painfully aware of just how much code they are running on trust, and just how many ways it could be compromised, accidentally or maliciously. And how frequently that code is compromised. The less control one has over a situation, the more terrifying it is, and the cold reality is that we have very little control over our computer security. There is a natural tendency, when afraid, to look for targets for that fear. Now, go back and think about the first principle. Anyone who has ever worked on or near free software is painfully aware that we have far more good ideas about how to improve computing and security than we have skilled resources to execute on those ideas. My own backlog of things that I've already thought about, know would be good ideas, and simply have to implement is probably longer than my remaining lifespan. I suspect that's the case for nearly all of us. In other words, we have a severe shortage of programmers who care and who have skill. We desperately need more skilled programmers who can write secure and reliable code. We may (and I think do) also need better tools, techniques, languages, protocols, and all the other machinery that we, as technical people, spend most of our time thinking about. But none of that changes the fact that we need more skilled people. In fact, it makes that need more acute: in addition to skilled people to write the code we use, we need skilled people to write the tools. Skilled people are not born. They're made. And in professions where training techniques are still in their infancy and where we don't have a good formal grasp on which techniques work, those skilled people are made primarily through apprenticeship, experimentation, and learning from failure. Worse, people who were skilled do not remain skilled without continually participating in that learning process. See the above point about a fast-changing field with evolving best practices. It's not enough to know how to write secure code to the best known practices today, or even enough to retrofit all of your existing code to current knowledge (which is often so large of an effort as to be practically impossible). You have to constantly, continually learn more, for which there is no reliable formal training. We have to try, fail, try again, and fail better. But failure that leads to a security vulnerability is treated as a loss of trust. We trusted that person to write secure code that we could use. They failed. Now we can't trust them. Based on the trust model of security, we should revoke their ability to try again and instead rely on people who have not failed, since that will make us more secure. Except now we just broke the learning process. And there's no such thing as a programmer who can stop learning. So what does that do to our resource pool? It's sadly ironic, but I believe the free software community writ large has a very serious collaboration problem: we do not tolerate each other's learning processes. This leads to a wide variety of social failures around hostile communities and the failures of meritocracy that other people have talked about at much greater length. But even if you set that all aside, it threatens our security. We need secure code, a lot of it, a lot more than we have right now. To get that code, we need people who can write it. We need to grow, encourage, and support those people and enable their learning processes. Code is written by people. If we rip people apart when they write bad, insecure code, we don't get better, secure code. We get fewer people writing security code. We get far fewer people writing security code in public, since some of the people who haven't been ripped apart will look at that experience and say, "No way am I going near that problem area. It's too scary. I don't want to end up like those programmers." Fewer people writing security code means fewer people learning how to write better security code. Fewer people capable of writing good, secure code is not a solution to any of our problems. If we do not tolerate, support, and encourage the learning process required to become a skilled programmer, or maintain one's skill in programming, we are destroying our future as a community. When you find code that is broken and badly written, you have found a problem that should be reported, analyzed, and corrected. You have also found a programmer who is about to have one of two very different types of experiences. Either they are about to learn how to become a better programmer, or they are about to be publicly shamed, humiliated, and treated as untrustworthy. Which branch they take is partly up to them, but it's also heavily influenced by how all of us react socially to the discovery of bad code. One of those branches leads to more good, secure code being written in the future. The other does not.

22 April 2014

Erich Schubert: Kernel-density based outlier detection and the need for customization

Outlier detection (also: anomaly detection, change detection) is an unsupervised data mining task that tries to identify the unexpected.
Most outlier detection methods are based on some notion of density: in an appropriate data representation, "normal" data is expected to cluster, and outliers are expected to be further away from the normal data.
This intuition can be quantified in different ways. Common heuristics include kNN outlier detection and the Local Outlier Factor (which uses a density quotient). One of the directions in my dissertation was to understand (also from a statistical point of view) how the output and the formal structure of these methods can be best understood.
I will present two smaller results of this analysis at the SIAM Data Mining 2014 conference: instead of the very heuristic density estimation found in above methods, we design a method (using the same generalized pattern) that uses a best-practise from statistics: Kernel Density Estimation. We aren't the first to attempt this (c.f. LDF), but we actuall retain the properties of the kernel, whereas the authors of LDF tried to mimic the LOF method too closely, and this way damaged the kernel.
The other result presented in this work is the need to customize. When working with real data, using "library algorithms" will more often than not fail. The reason is that real data isn't as nicely behaved - it's dirty, it seldom is normal distributed. And the problem that we're trying to solve is often much narrower. For best results, we need to integrate our preexisting knowledge of the data into the algorithm. Sometimes we can do so by preprocessing and feature transformation. But sometimes, we can also customize the algorithm easily.
Outlier detection algorithms aren't black magic, or carefully adjusted. They follow a rather simple logic, and this means that we can easily take only parts of these methods, and adjust them as necessary for our problem at hand!
The article persented at SDM will demonstrate such a use case: analyzing 1.2 million traffic accidents in the UK (from data.gov.uk) we are not interested in "classic" density based outliers - this would be a rare traffic accident on a small road somewhere in Scotland. Instead, we're interested in unusual concentrations of traffic accidents, i.e. blackspots.
The generalized pattern can be easily customized for this task. While this data does not allow automatic evaluation, many outliers could be easily verified using Google Earth and search: often, historic imagery on Google Earth showed that the road layout was changed, or that there are many news reports about the dangerous road. The data can also be nicely visualized, and I'd like to share these examples with you. First, here is a screenshot from Google Earth for one of the hotspots (Cherry Lane Roundabout, North of Heathrow airport, which used to be a double cut-through roundabout - one of the cut-throughs was removed since):
Screenshot of Cherry Lane Roundabout hotspot
Google Earth is best for exploring this result, because you can hide and show the density overlay to see the crossroad below; and you can go back in time to access historic imagery. Unfortunately, KML does not allow easy interactions (at least it didn't last time I checked).
I have also put the KML file on Google Drive. It will automatically display it on Google Maps (nice feature of Drive, kudos to Google!), but it should also allow you to download it. I've also explored the data on an Android tablet (but I don't think you can hide elements there, or access historic imagery as in the desktop application).
With a classic outlier detection method, this analysis would not have been possible. However, it was easy to customize the method; and the results are actually more meaningful: instead of relying on some heuristic to choose kernel bandwidth, I opted for choosing the bandwidth by physical arguments: 50 meters is a reasonable bandwidth for a crossroad / roundabout, and for comparison a radius of 2 kilometers is used to model the typical accident density in this region (there should other crossroads within 2 km in Europe).
Since I advocate reproducible science, the source code of the basic method will be in the next ELKI release. For the customization case studies, I plan to share them as a how-to or tutorial type of document in the ELKI wiki; probably also detailing data preprocessing and visualization aspects. The code for the customizations is not really suited for direct inclusion in the ELKI framework, but can serve as an example for advanced usage.
Reference:
E. Schubert, A. Zimek, H.-P. Kriegel
Generalized Outlier Detection with Flexible Kernel Density Estimates
In Proceedings of the 14th SIAM International Conference on Data Mining (SDM), Philadelphia, PA, 2014.
So TLDR of the story: A) try to use more established statistics (such as KDE), and B) don't expect an off-the-shelf solution to do magic, but customize the method for your problem.
P.S. if you happen to know nice post-doc positions in academia:
I'm actively looking for a position to continue my research. I'm working on scaling these methods to larger data and to make them work with various real data that I can find. Open-source, modular and efficient implementations are very important to me, and one of the directions I'd like to investigate is porting these methods to a distributed setting, for example using Spark. In order to get closer to "real" data, I've started to make these approaches work e.g. on textual data, mixed type data, multimedia etc. And of course, I like teaching; which is why I would prefer a position in academia.

21 April 2014

Russ Allbery: Review: Hyperbole and a Half

Review: Hyperbole and a Half, by Allie Brosh
Publisher: Touchstone
Copyright: November 2013
ISBN: 1-4767-6459-X
Format: Graphic novel
Pages: 373
It's fundamentally pointless to write this review. Some number of you have already heard of Hyperbole and a Half. Most of that group already own this book and are only reading this review so that you can remember how much fun you had reading it. But, even better, you could just stop reading this review and go read the book again. Some of you who have heard of Hyperbole and a Half didn't know that Allie Brosh had published a book. If that's you, you're probably not reading this review any more, since you're now at your favorite book seller buying a copy of the book, rendering the review somewhat pointless. For those of you who have not heard of Hyperbole and a Half, there's no need to read a review, because it's a blog. So, rather than reading this review, you can just follow that link and read it for yourself. If you find yourself laughing uncontrollably (and occasionally crying) and going "where can I get more of this?", well, there's a book. Which you could have also found out from the blog itself. Like I said, not much point. If you read the blog and don't particularly care for it, well, I greatly respect your position. The diversity of taste in the human race is what leads to our wonderful variety of culture, philosophy, and art, and I appreciate your substantial contribution to that diversity. However, you should now make a mental note to never trust my humor recommendations, and you shouldn't let this review change your mind. But, since I'm here, I may as well write a review anyway. Hyperbole and a Half is, as mentioned, a blog by Allie Brosh. Most of the posts are quite long and substantial and in the form of cartoons mixed with text, usually (but not always) telling some sort of story. The cartoon style is what is often called "MS Paint," meaning that it looks like something drawn in Microsoft Paint with its most basic tools. (Other examples of this style are the Oatmeal and Homestuck, although Brosh stays consistently with a rawer art style than either of those.) It looks extremely simple, like child drawings (and early childhood inspires much of Brosh's material), but once one gets used to it, one realizes that Brosh gets amazing expressiveness and character out of the art style. As an aside, yes, I am wholeheartedly recommending a book that is full of material about young children. Brosh is that good. The subtitle of this book is "unfortunate situations, flawed coping mechanisms, mayhem, and other things that happened," and it's mostly based on (exaggerated) incidents that occurred in Brosh's life. Most of them are hilarious. Some of them are both hilarious and stunning psychological insights. She has an amazing knack for storytelling and for exaggerating just the right moments of the story, or summing up emotions in a wonderful turn of phrase or a picture. She's also amazingly good at telling embarrassing stories about herself in a way that makes you empathize rather than just cringe, and then come away feeling like you understand both her and yourself better. If you've wandered around the Internet much, you have probably run across the phrase "clean ALL the things!" and the corresponding picture. That's from Hyperbole and a Half (specifically, "This is Why I'll Never Be an Adult") and is included in this book (improved; see below). It's even better in context. But, beyond storytelling, the other thing Brosh is amazingly good at is capturing internal mental states and emotions in a way that the reader understands and those who have experienced the emotion immediately go "yes, THAT." The apex of this is her two-part post on depression, which is hands-down the best description of depression that I've ever read. That judgment has been echoed by multiple friends of mine with depression. And yes, both of those posts are included in the book as well, although you can also read them on the web. As you've probably noticed, this book is partly a collection of material that's freely available on the web. Unlike some web comics collections, it's not entirely a reprint collection; there are entirely new stories here (which for me was enough by itself to buy the book). Brosh's post on the book says that it's about 50% new material. But the ones that aren't original have been edited and improved, sometimes substantially. For example, I did a quick comparison of the book version with the web version of "This is Why I'll Never be an Adult" and found Brosh redrew all of the cartoons for the story. The book is also gorgeous, if you care about such things like I do: high quality paper, thick pages, vibrant colors, and a comfortable heft to the hardcover version. It's the sort of book that feels like it will survive for decades, which is good since I intend to re-read it for decades. Brosh has a lot of material on-line, so obviously only a small fraction made it into the book and there's more to discover on the blog. I can particularly recommend "The Alot is Better Than You at Everything" and "Boyfriend Doesn't Have Ebola. Probably.". The latter, which is mostly about creating a better pain scale, is my favorite from the blog that didn't make it into the book. And there are two more examples of the sort of thing that you'll getting here. So ends the probably pointless review. I absolutely adore Hyperbole and a Half. It is my favorite web comic, even surpassing XKCD, which is saying something. Even if there were no material, I would have bought this book in hardcover to support Brosh and to have a high-quality printing of the blog posts. The reworkings and improvements of the republished material and the brand new additions are just bonuses. But there's no need to take my word for it; the best possible advertisement for Brosh's work is on-line, from which you can easily determine if you'll enjoy this book as much as I did. Even the back cover and the inside flaps are awesome. Rating: 10 out of 10

Matthew Garrett: Home entertainment implementations are pretty appalling

I picked up a Panasonic BDT-230 a couple of months ago. Then I discovered that even though it appeared fairly straightforward to make it DVD region free (I have a large pile of PAL region 2 DVDs), the US models refuse to play back PAL content. We live in an era of software-defined functionality. While Panasonic could have designed a separate hardware SKU with a hard block on PAL output, that would seem like unnecessary expense. So, playing with the firmware seemed like a reasonable start.

Panasonic provide a nice download site for firmware updates, so I grabbed the most recent and set to work. Binwalk found a squashfs filesystem, which was a good sign. Less good was the block at the end of the firmware with "RSA" written around it in large letters. The simple approach of hacking the firmware, building a new image and flashing it to the device didn't appear likely to work.

Which left dealing with the installed software. The BDT-230 is based on a Mediatek chipset, and like most (all?) Mediatek systems runs a large binary called "bdpprog" that spawns about eleventy billion threads and does pretty much everything. Runnings strings over that showed, well, rather a lot, but most promisingly included a reference to "/mnt/sda1/vudu/vudu.sh". Other references to /mnt/sda1 made it pretty clear that it was the mount point for USB mass storage. There were a couple of other constraints that had to be satisfied, but soon attempting to run Vudu was actually setting a blank root password and launching telnetd.

/acfg/config_file_global.txt was the next stop. This is a set of tokens and values with useful looking names like "IDX_GB_PTT_COUNTRYCODE". I tried changing the values, but unfortunately made a poor guess - on next reboot, the player had reset itself to DVD region 5, Blu Ray region C and was talking to me in Russian. More inconveniently, the Vudu icon had vanished and I couldn't launch a shell any more.

But where there's one obvious mechanism for running arbitrary code, there's probably another. /usr/local/bin/browser.sh contained the wonderful line:
export LD_PRELOAD=/mnt/sda1/bbb/libSegFault.so
, so then it was just a matter of building a library that hooked open() and launched inetd and dropping that into the right place, and then opening the browser.

This time I set the country code correctly, rebooted and now I can actually watch Monkey Dust again. Hurrah! But, at the same time, concerning. This software has been written without any concern for security, and it listens on the network by default. If it took me this little time to find two entirely independent ways to run arbitrary code on the device, it doesn't seem like a stretch to believe that there are probably other vulnerabilities that can be exploited with less need for physical access.

The depressing part of this is that there's no reason to believe that Panasonic are especially bad here - especially since a large number of vendors are shipping much the same Mediatek code, and so probably have similar (if not identical) issues. The future is made up of network-connected appliances that are using your electricity to mine somebody else's Dogecoin. Our nightmarish dystopia may be stranger than expected.

comment count unavailable comments

20 April 2014

Russell Coker: Sociological Images 2012

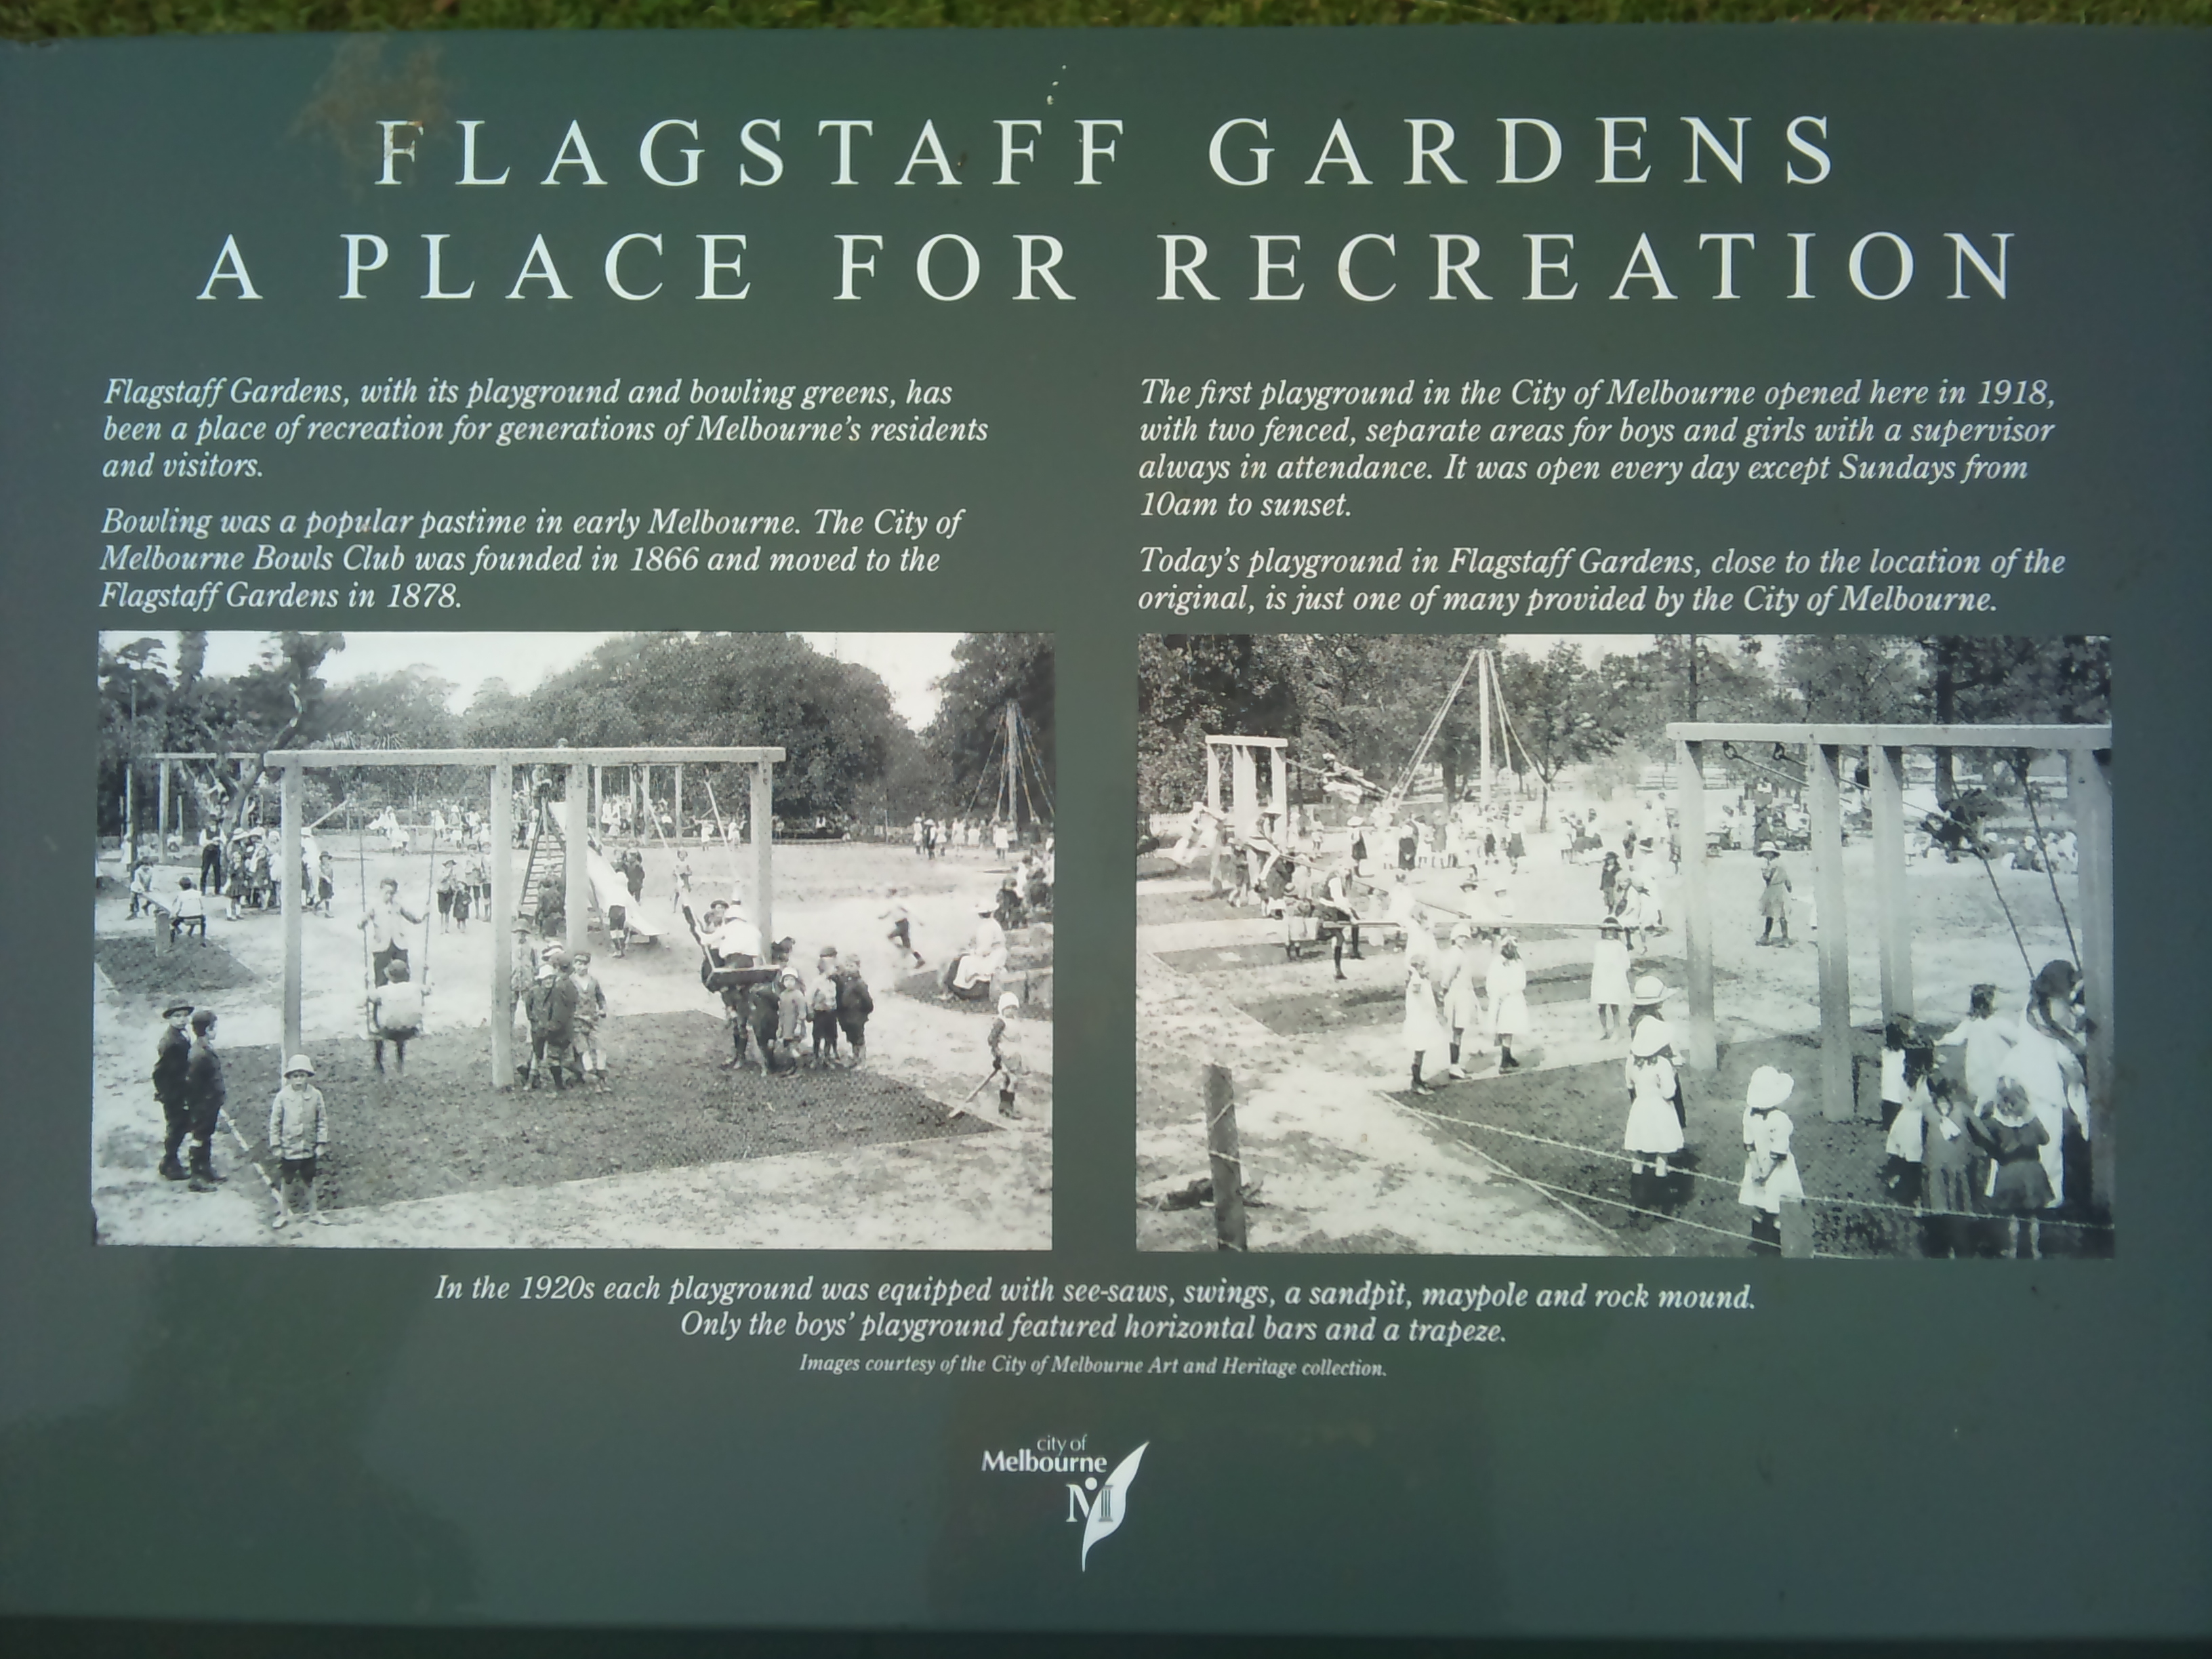
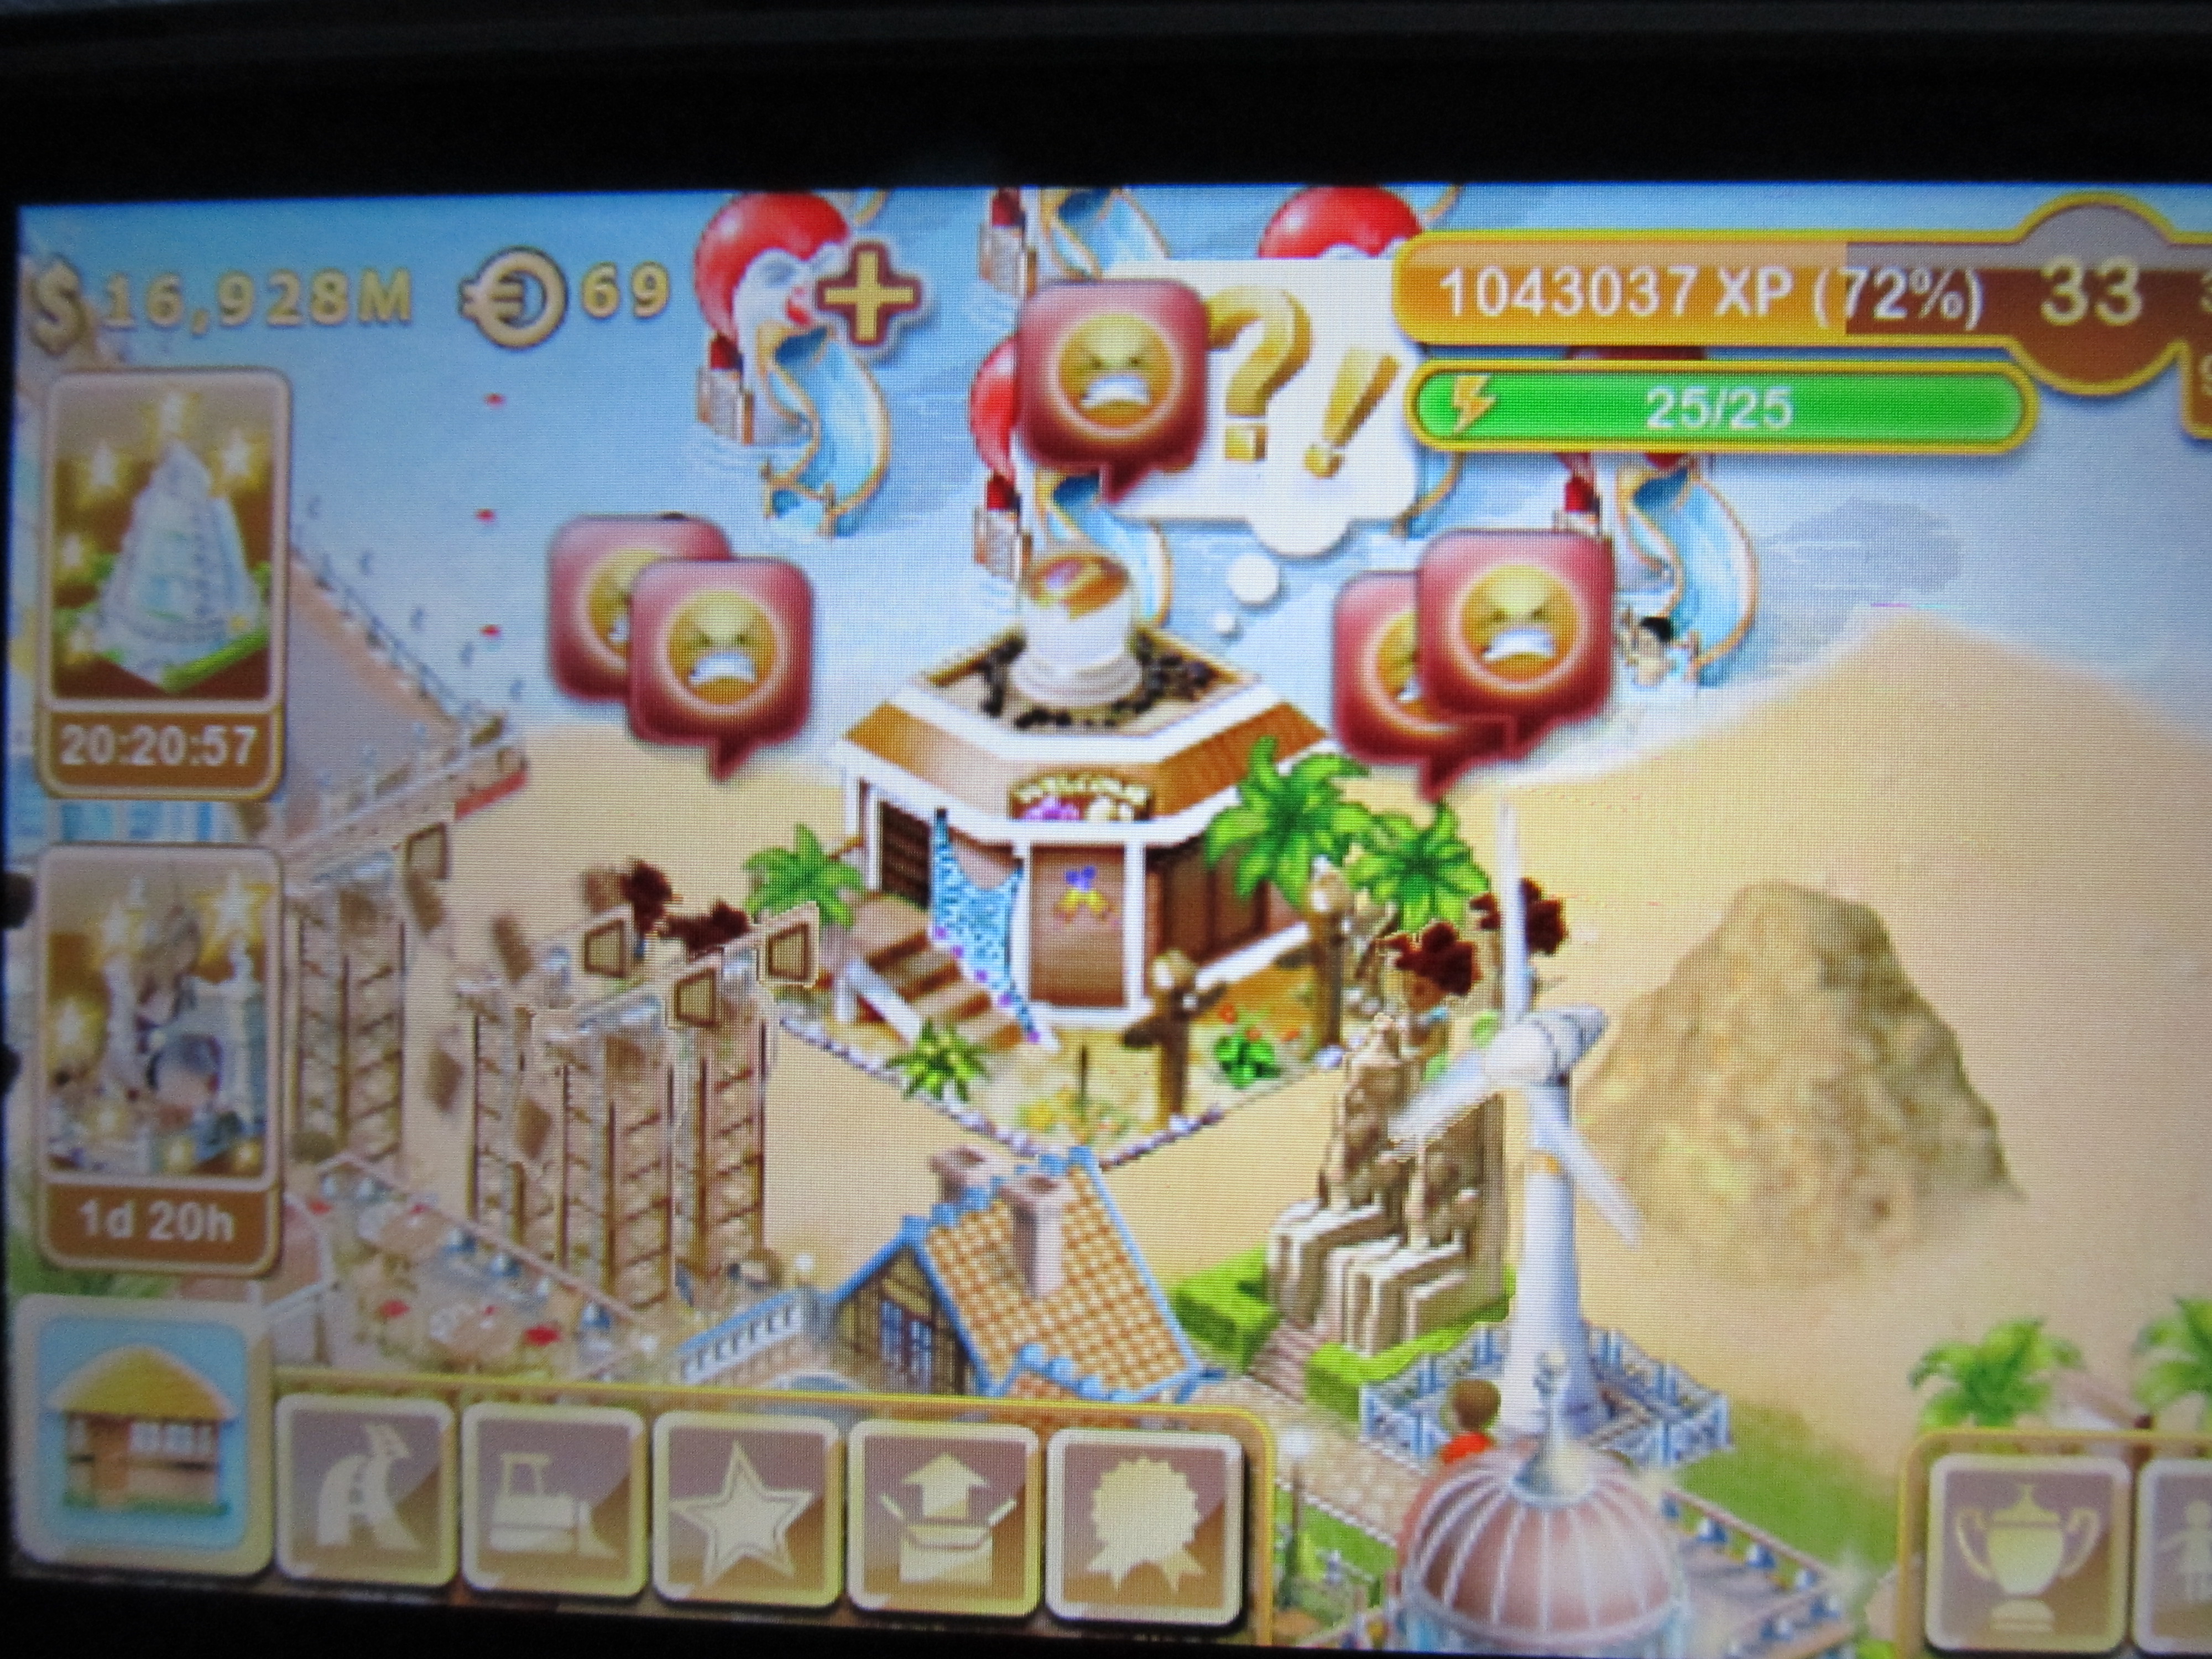
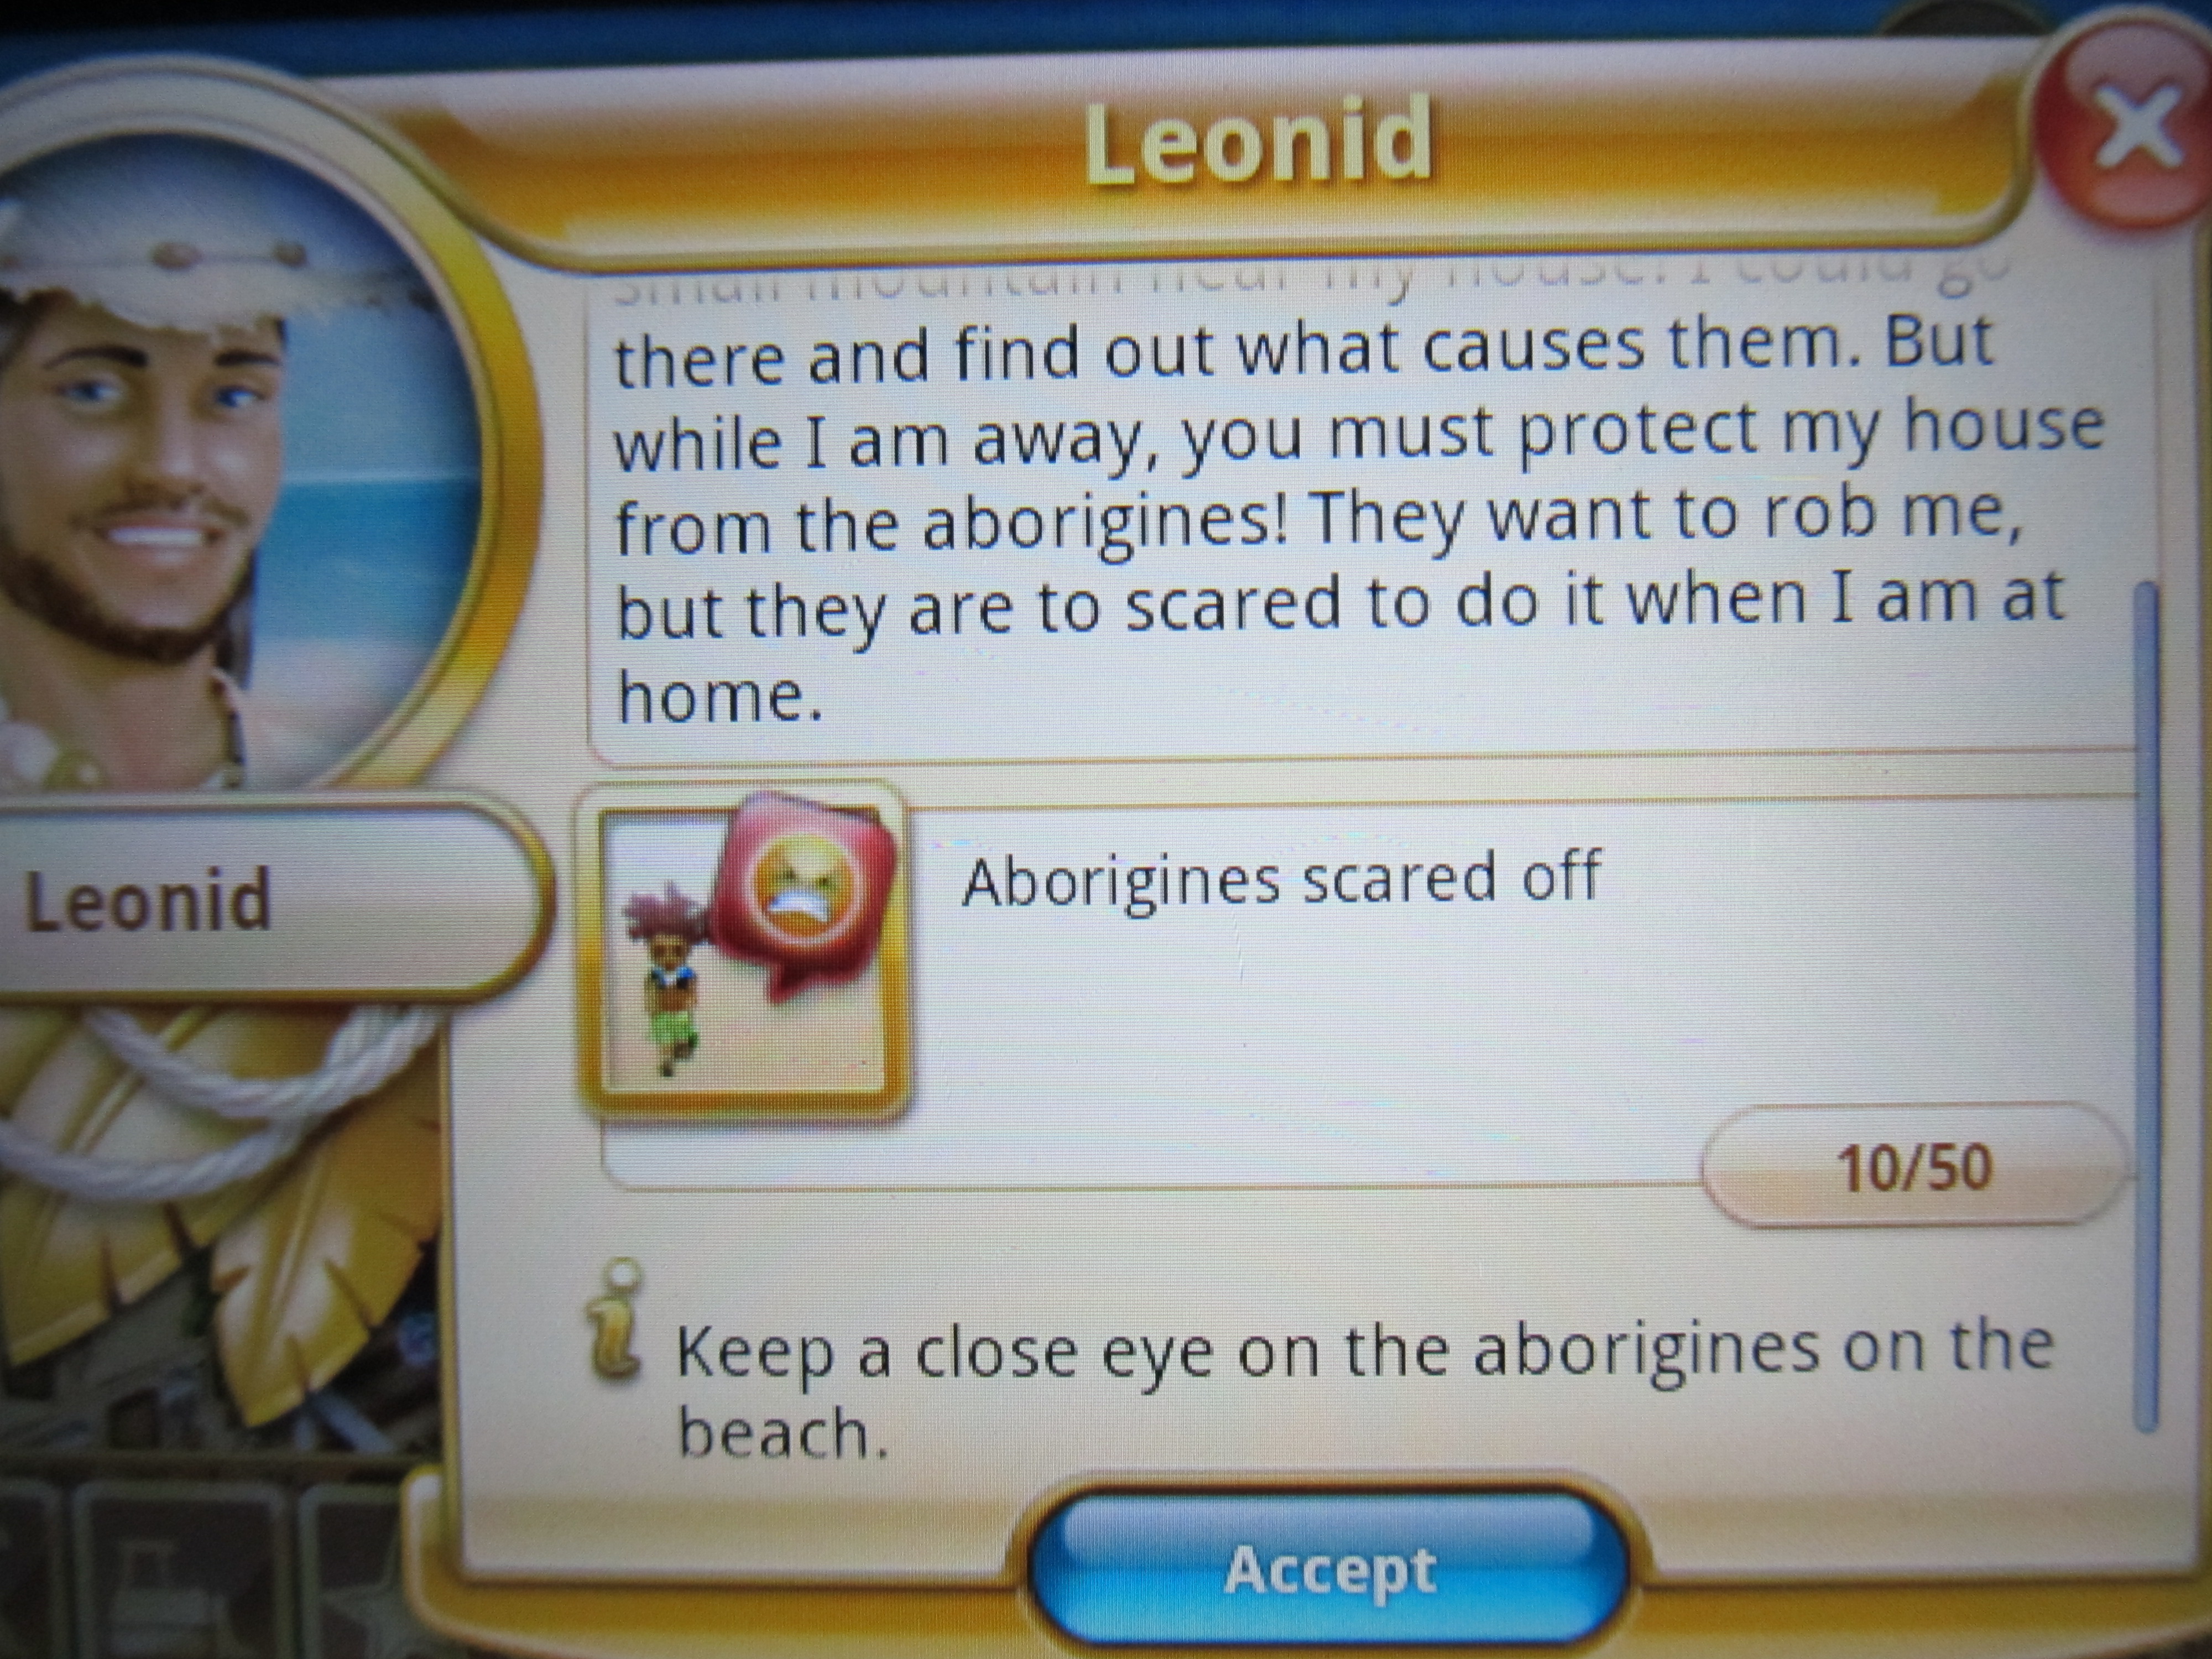
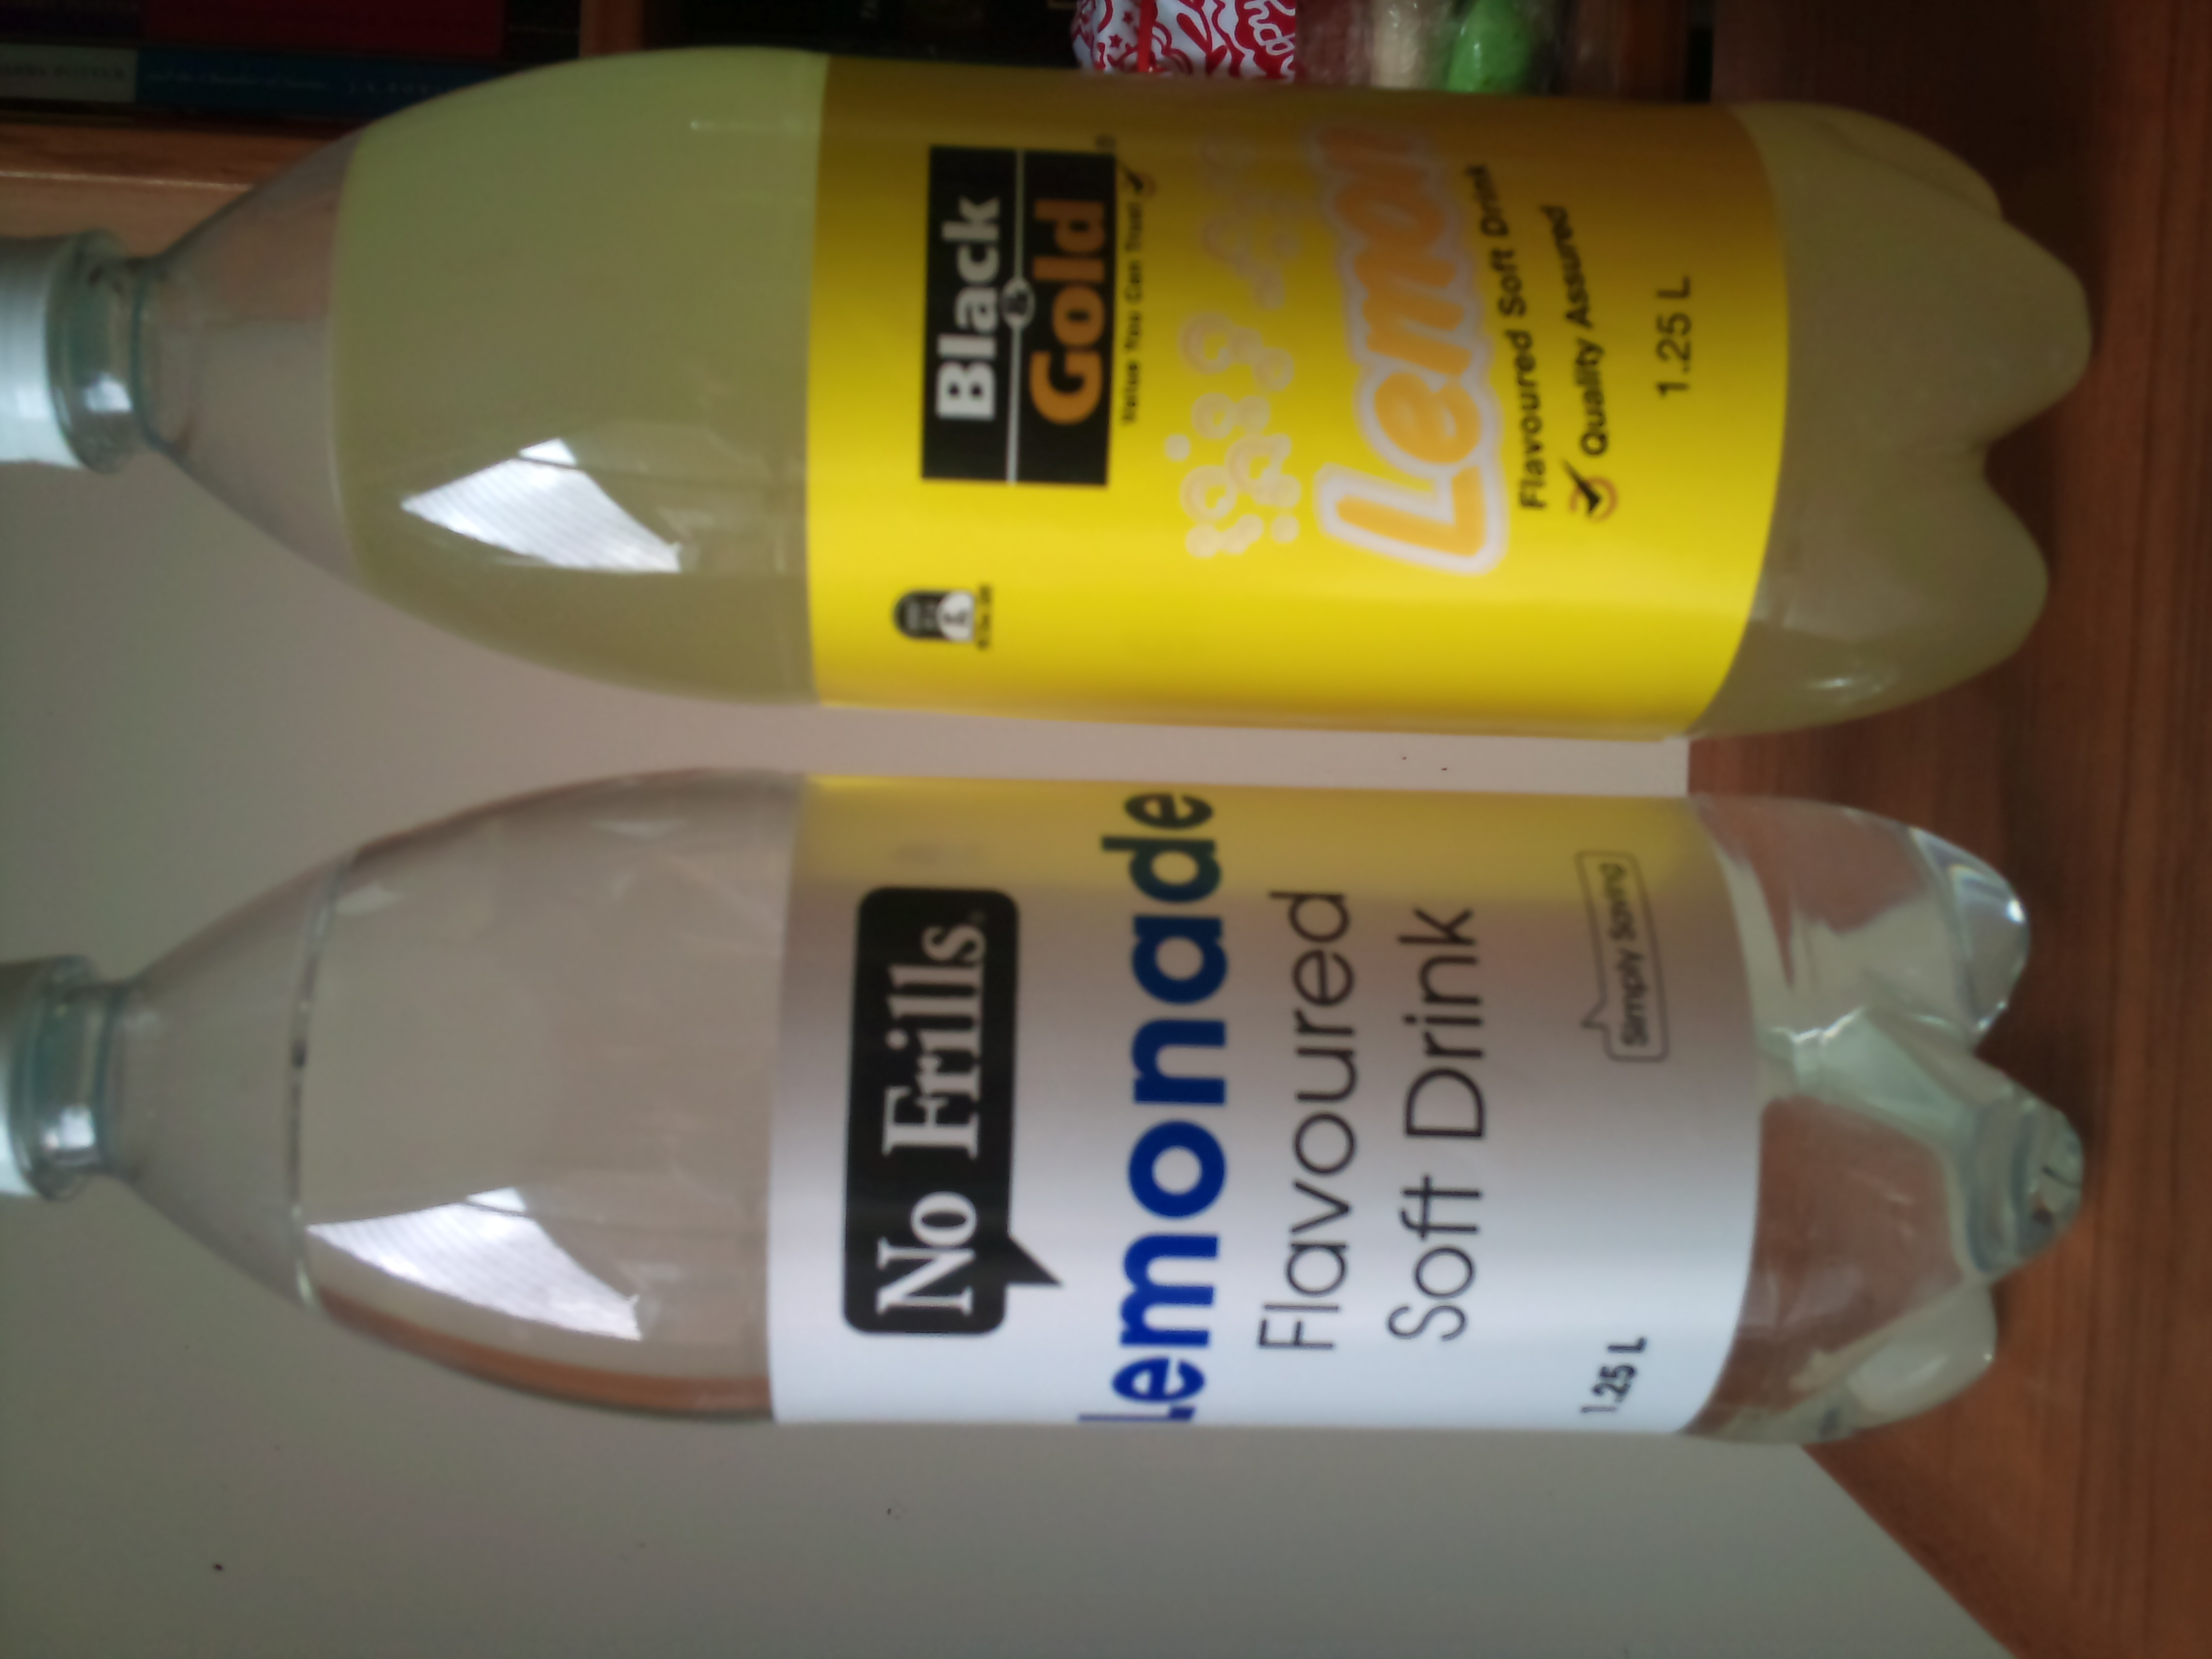
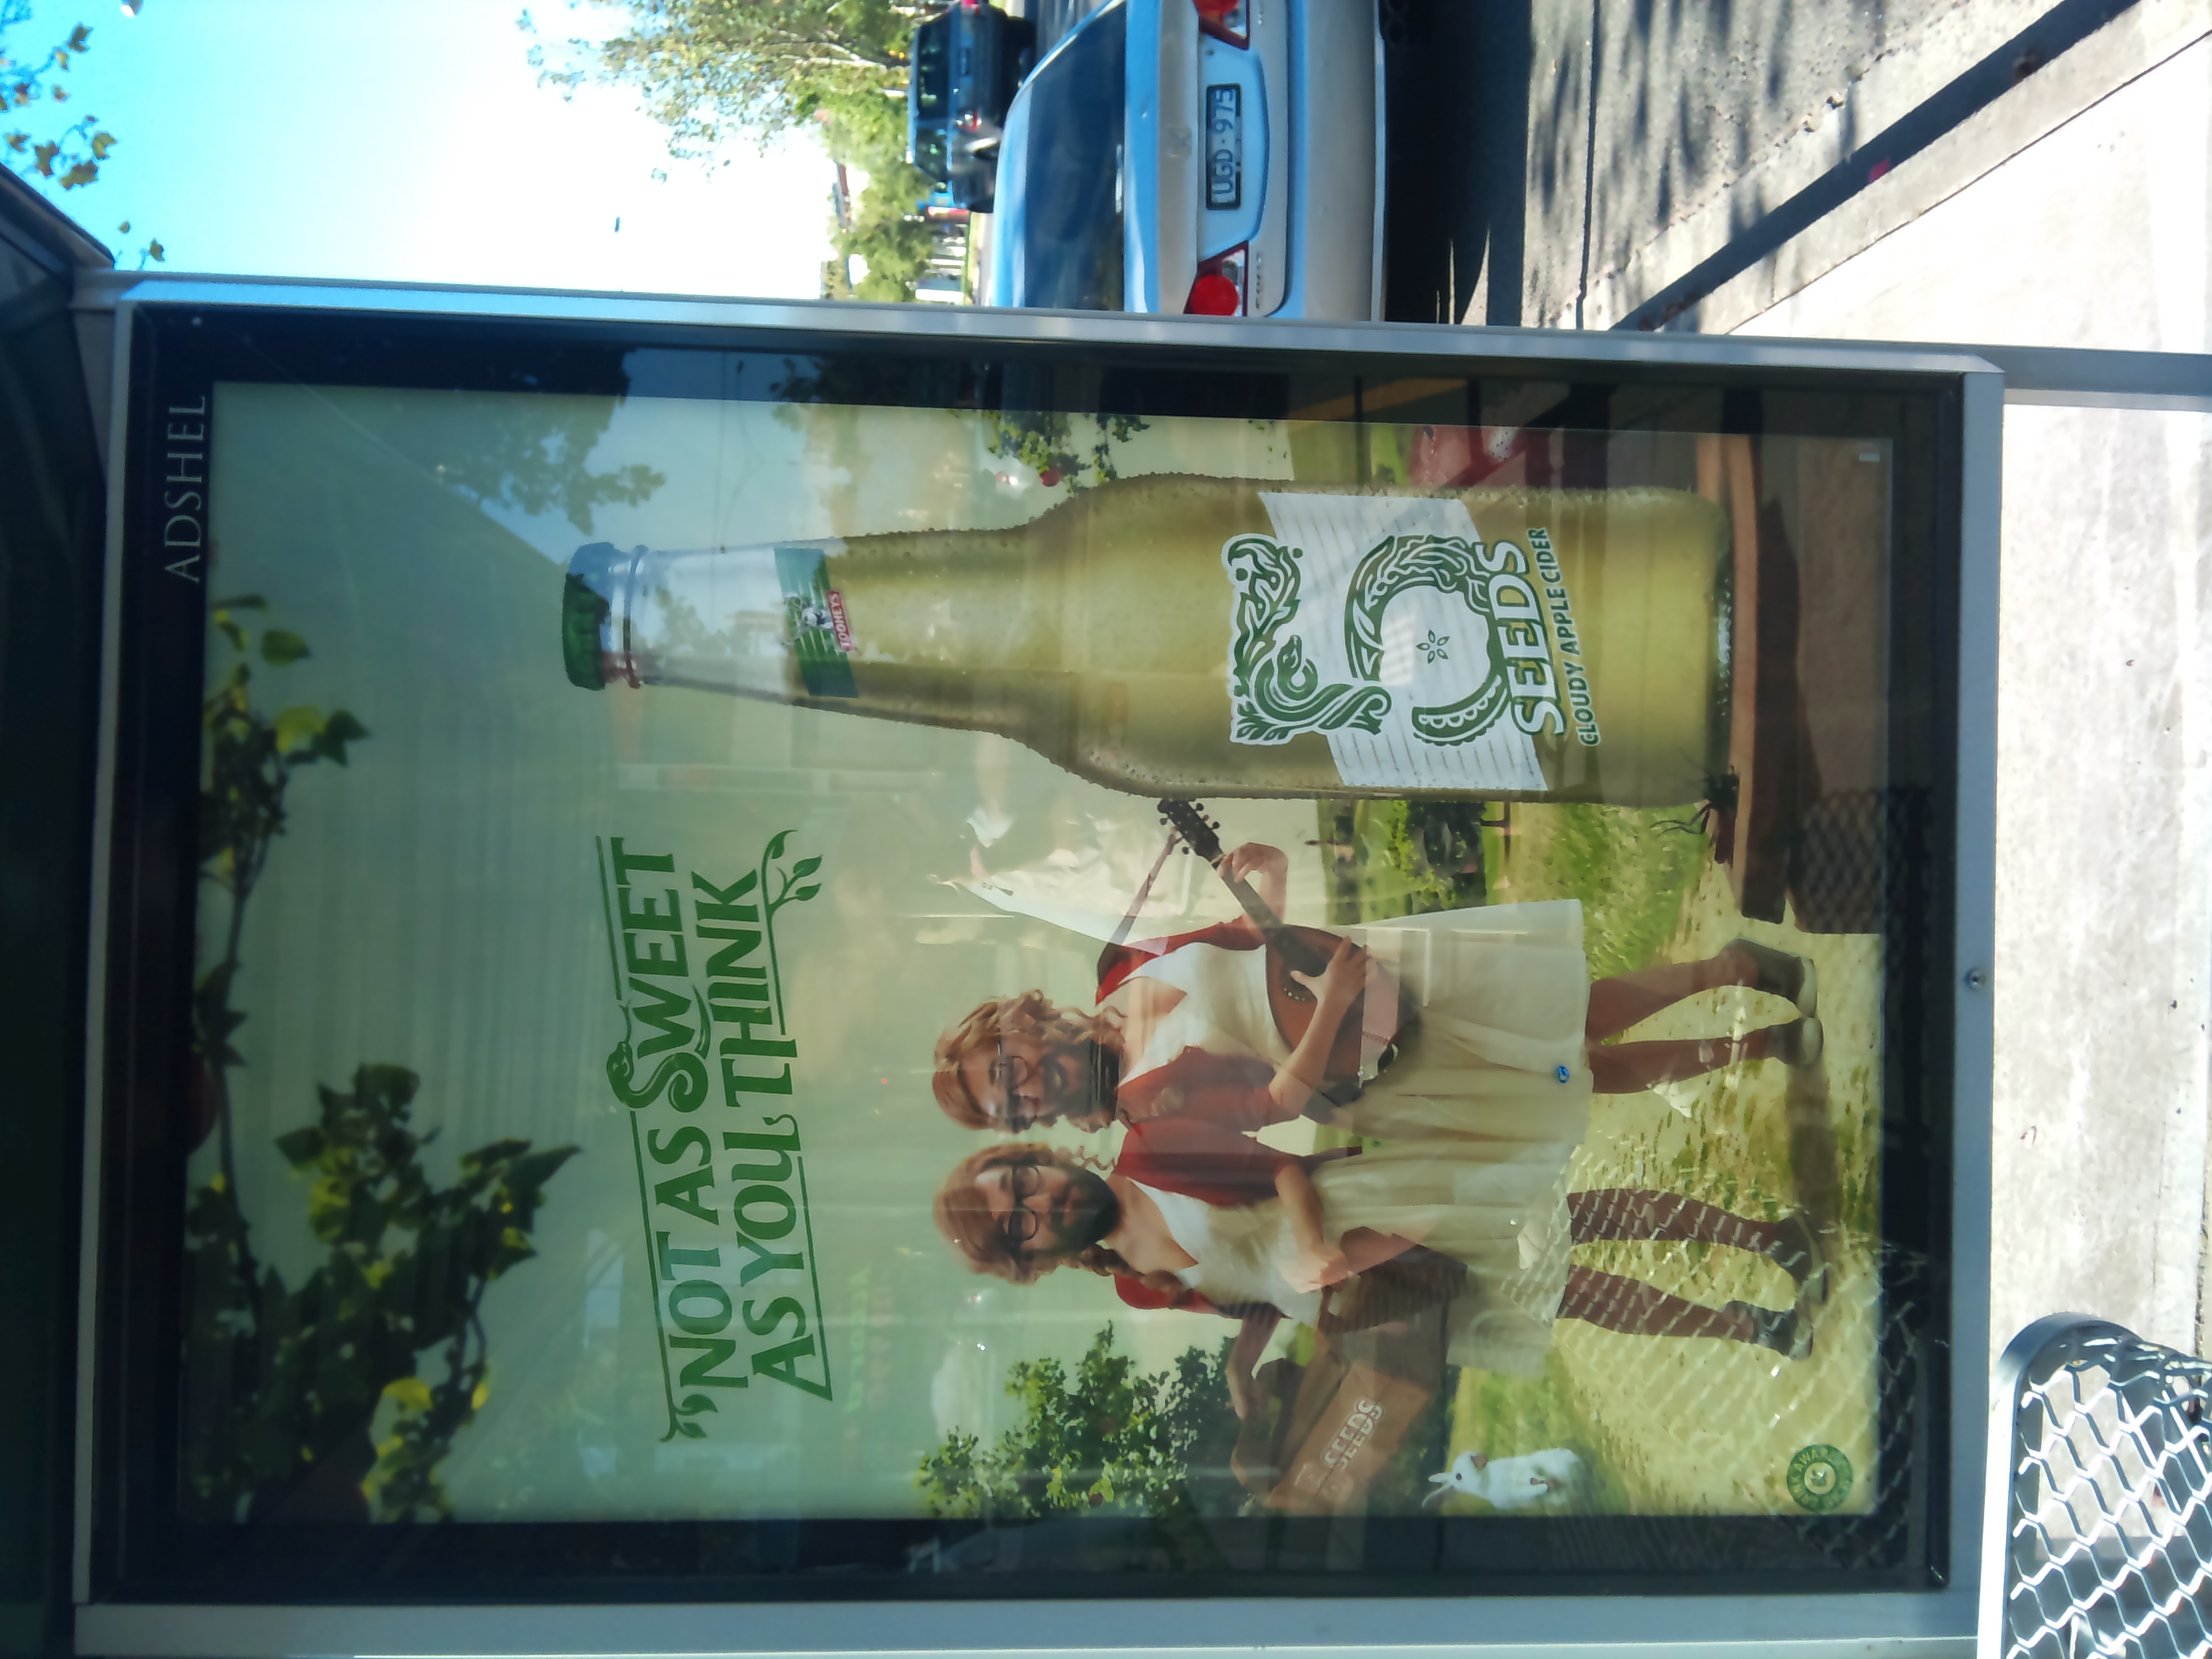
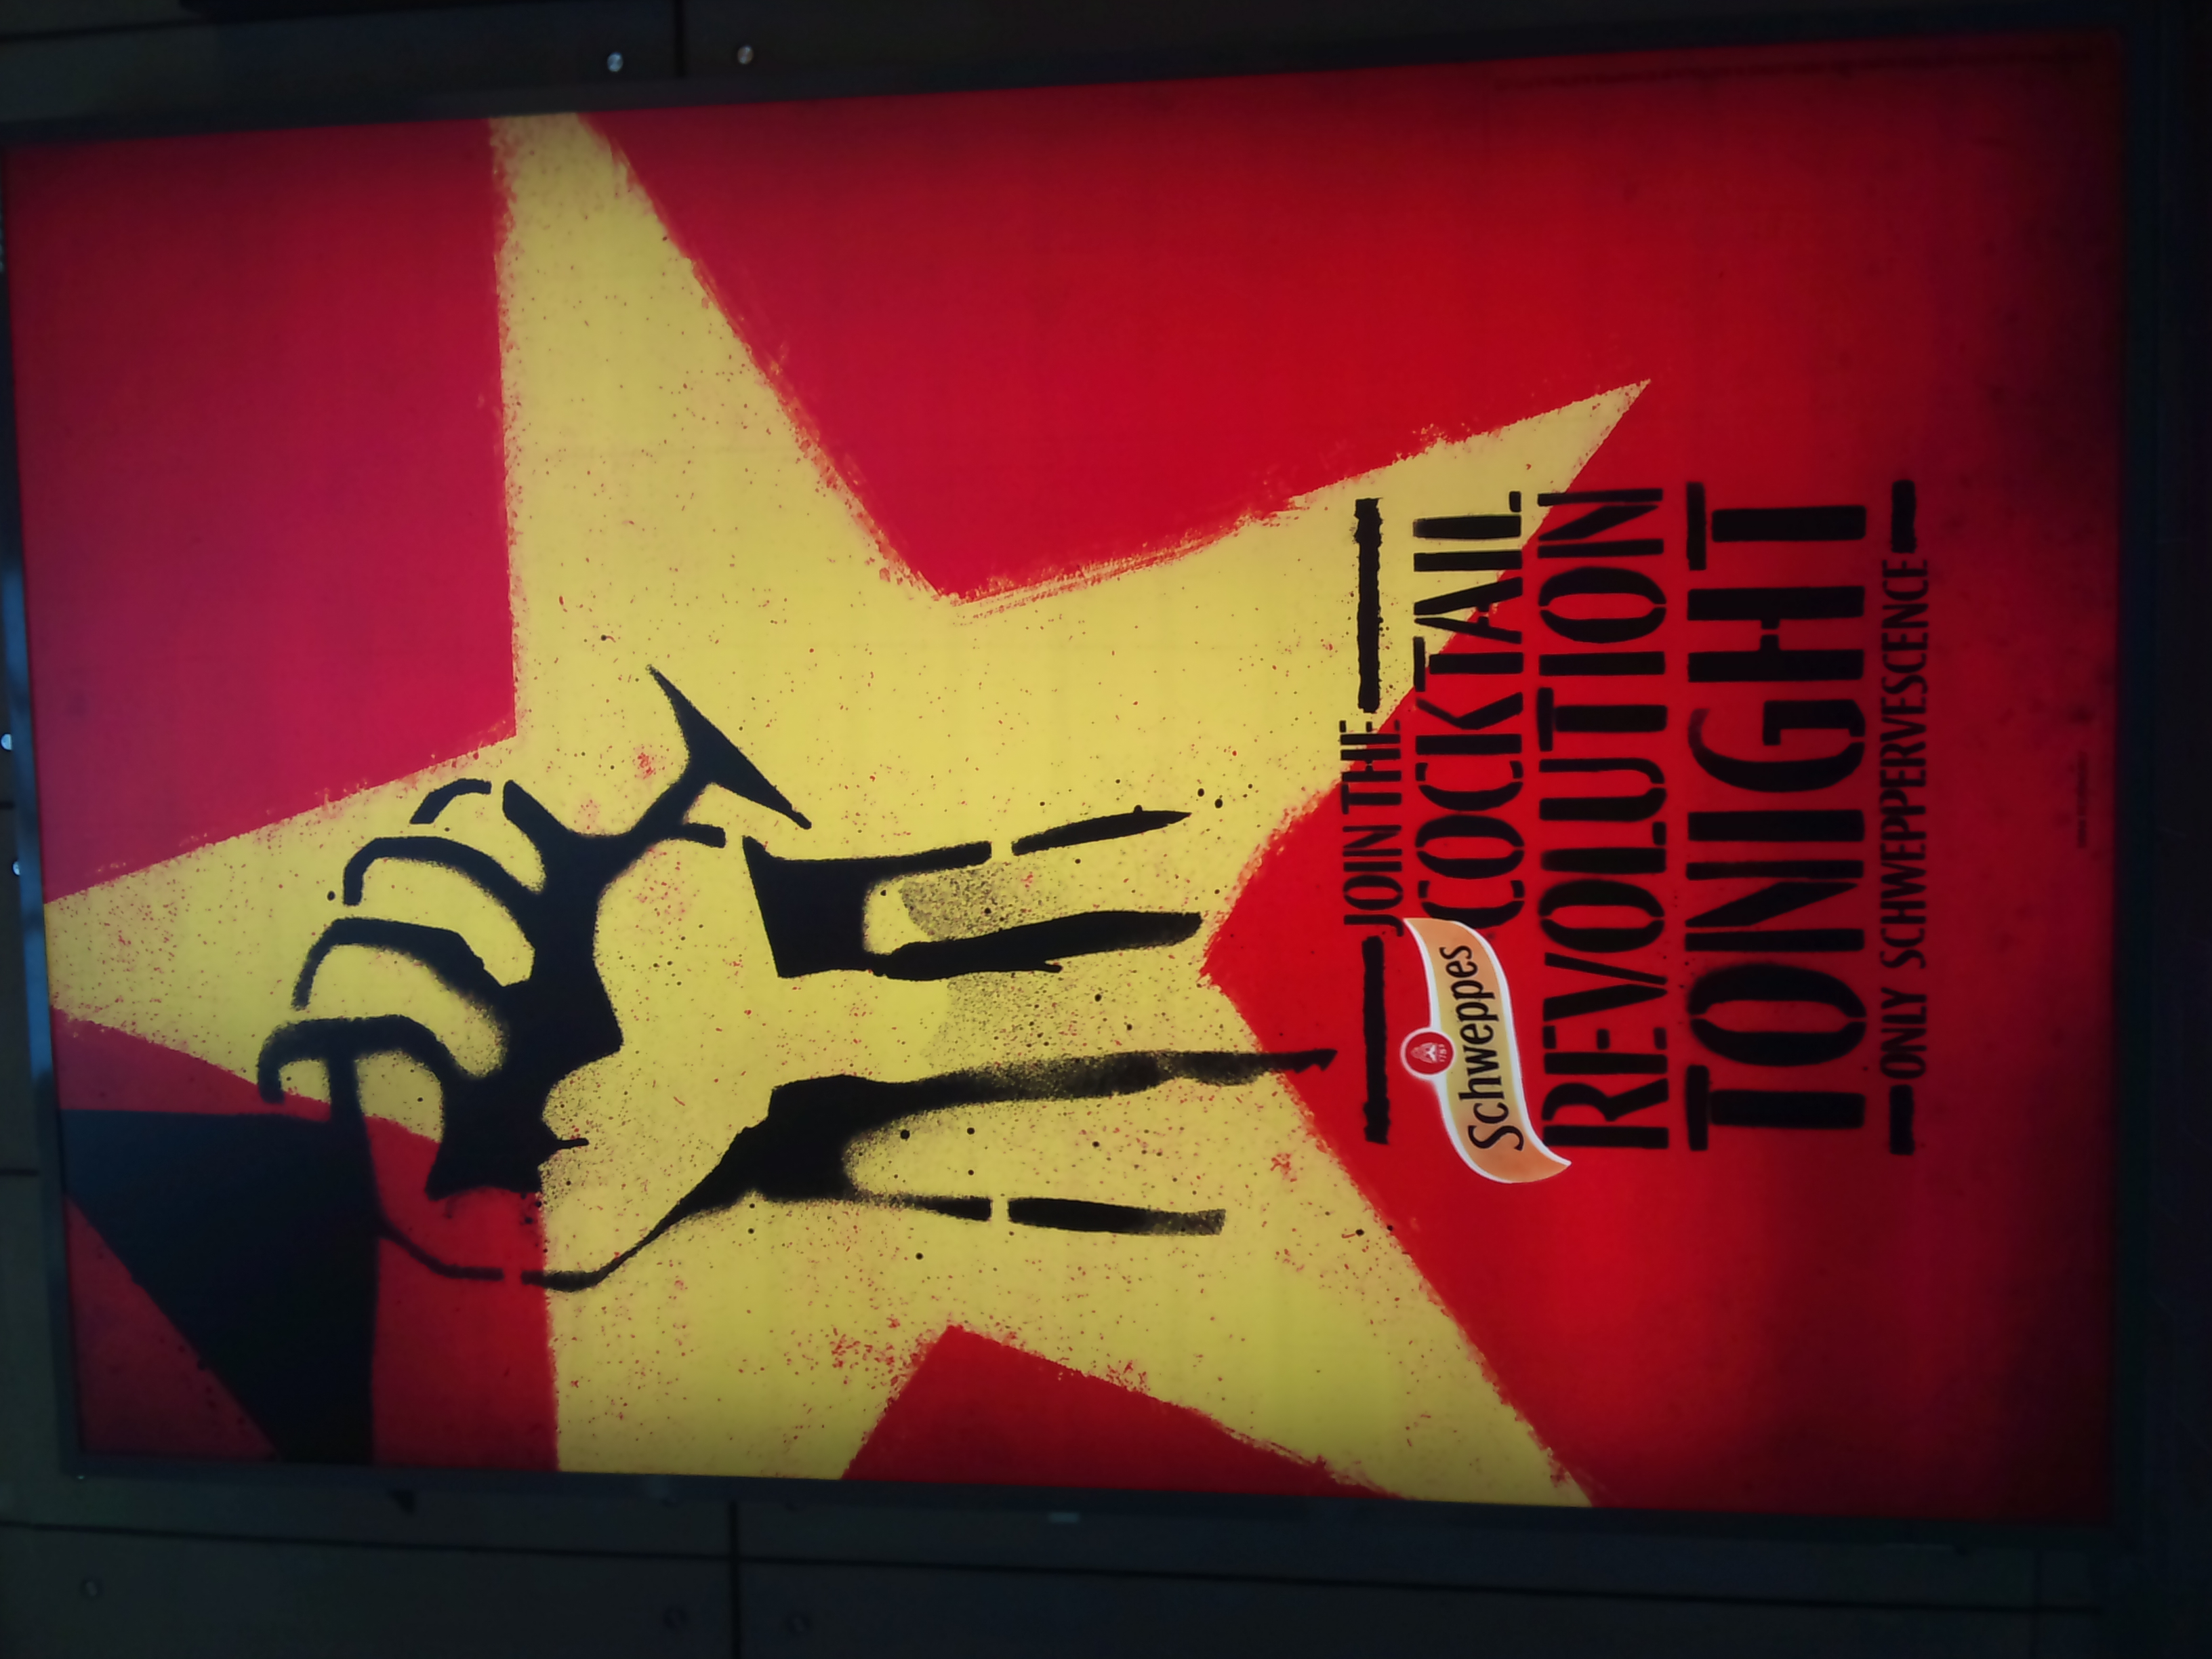
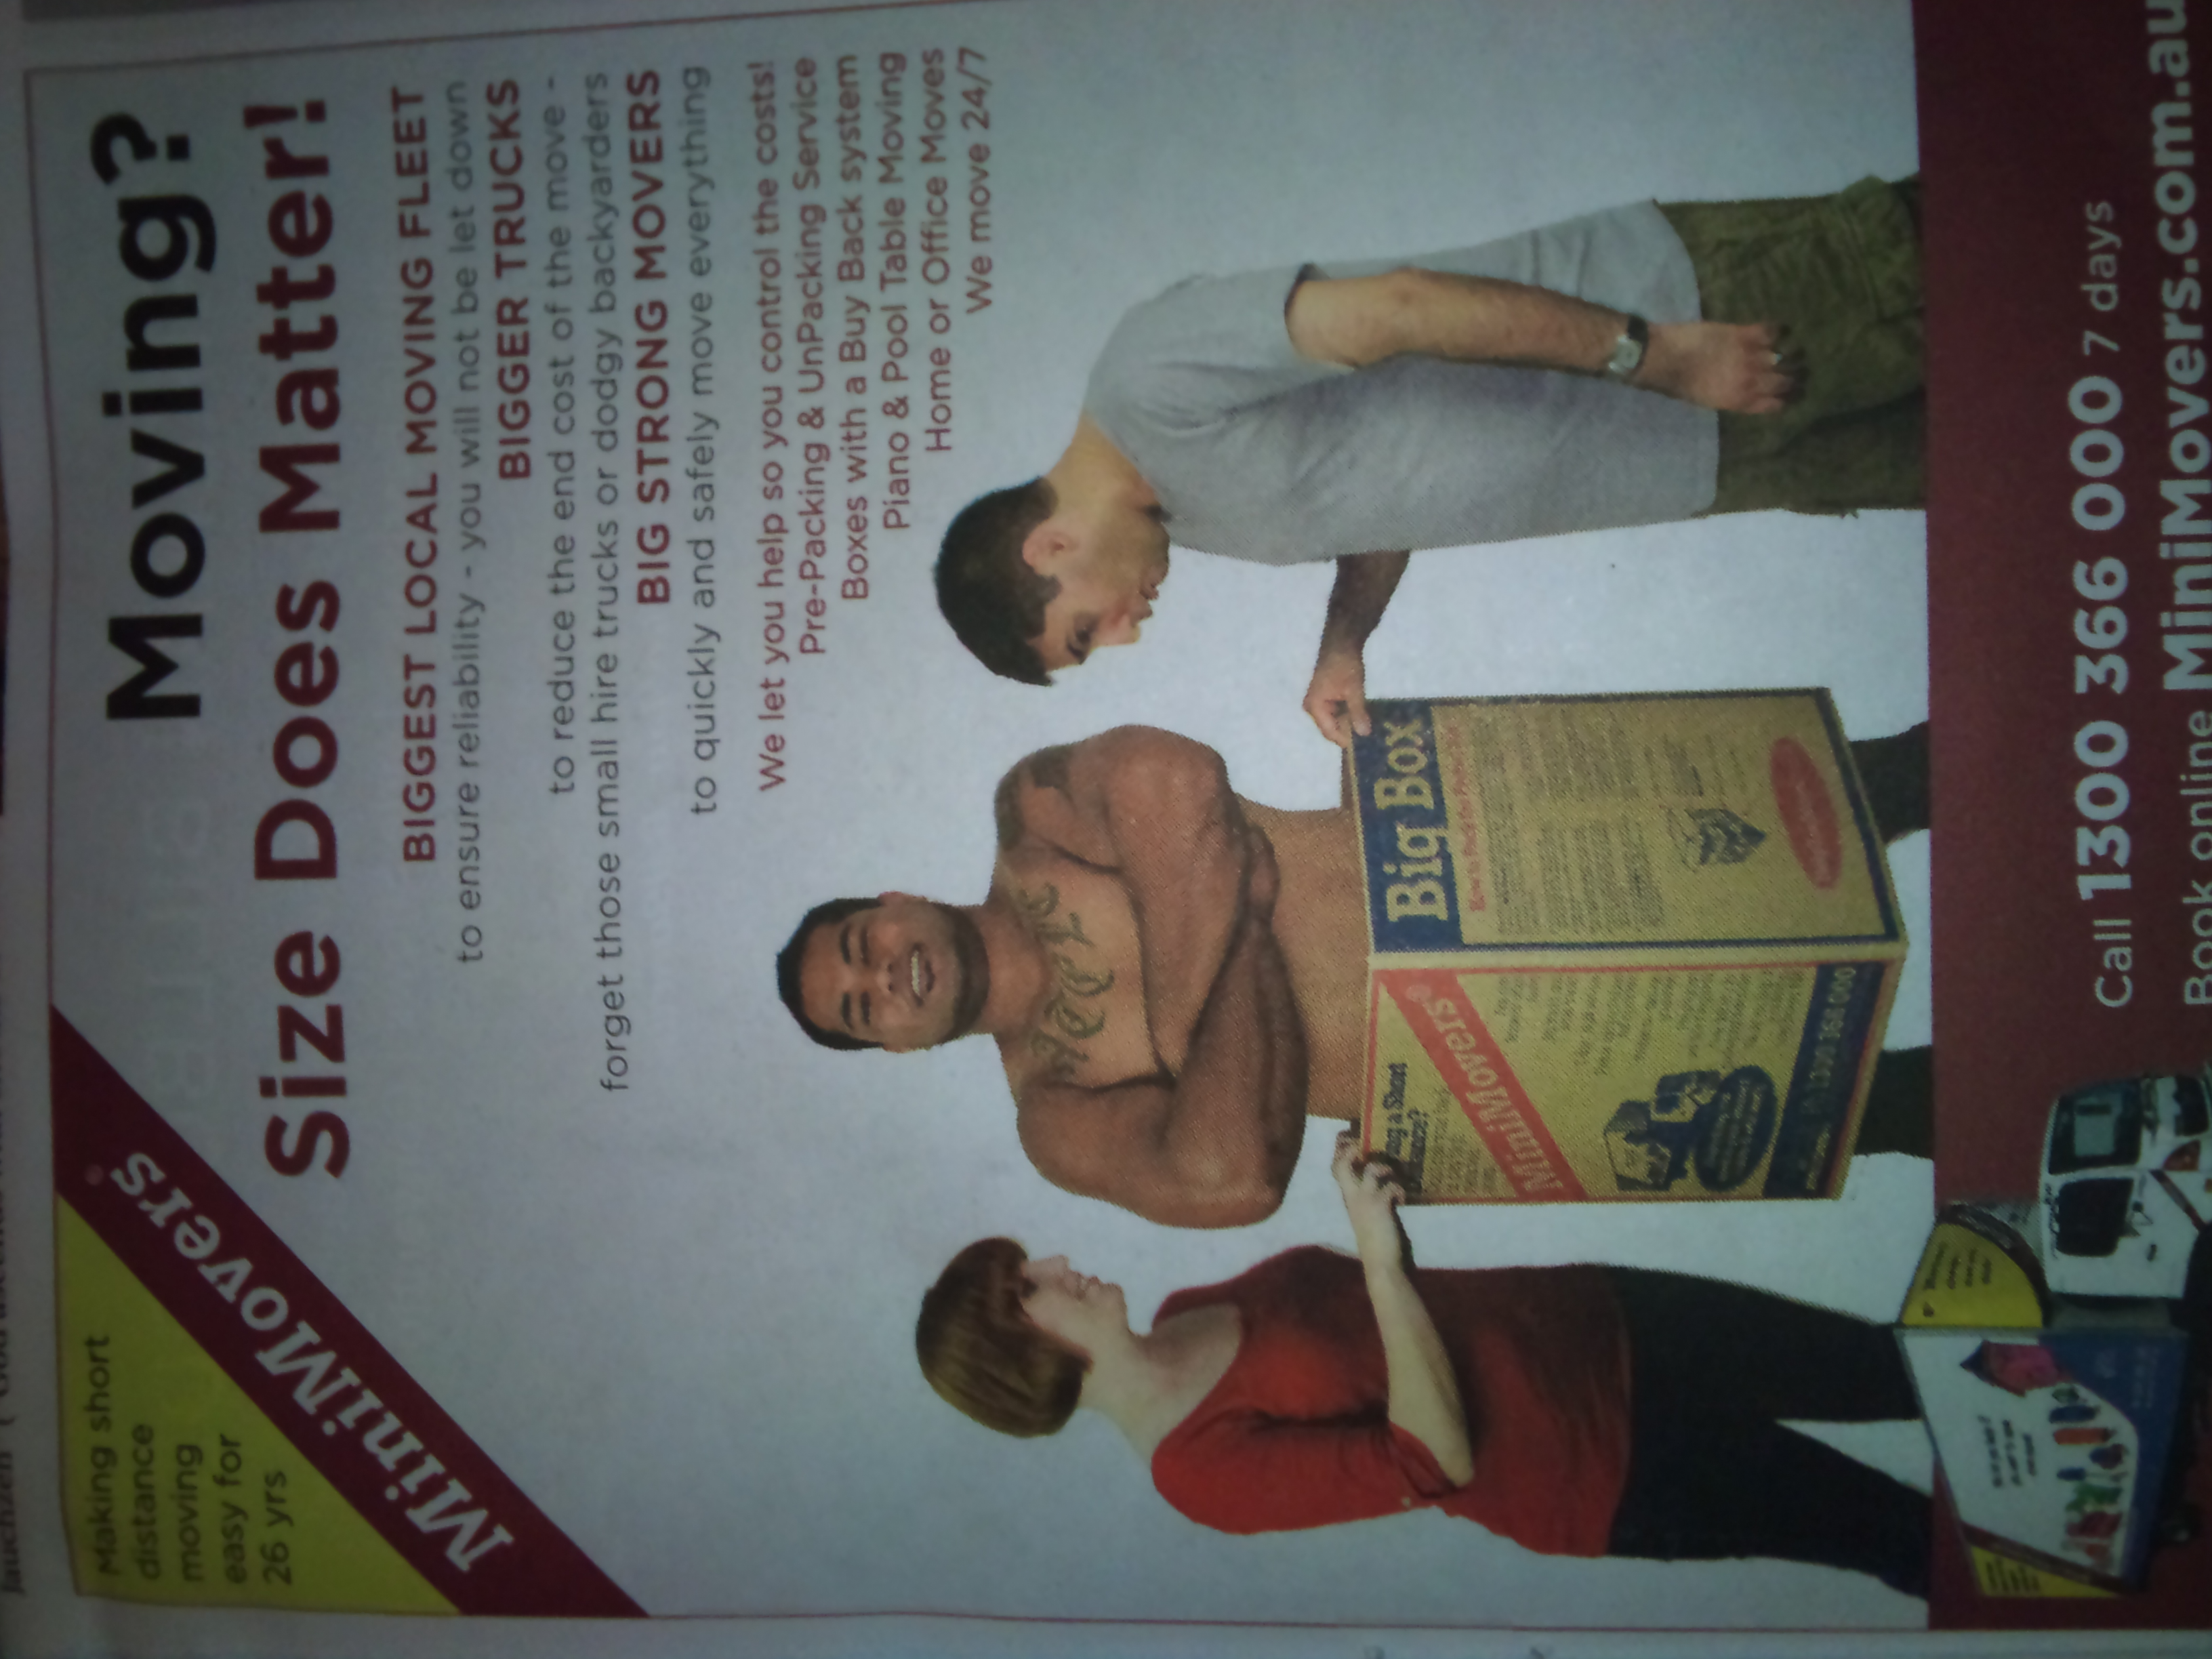
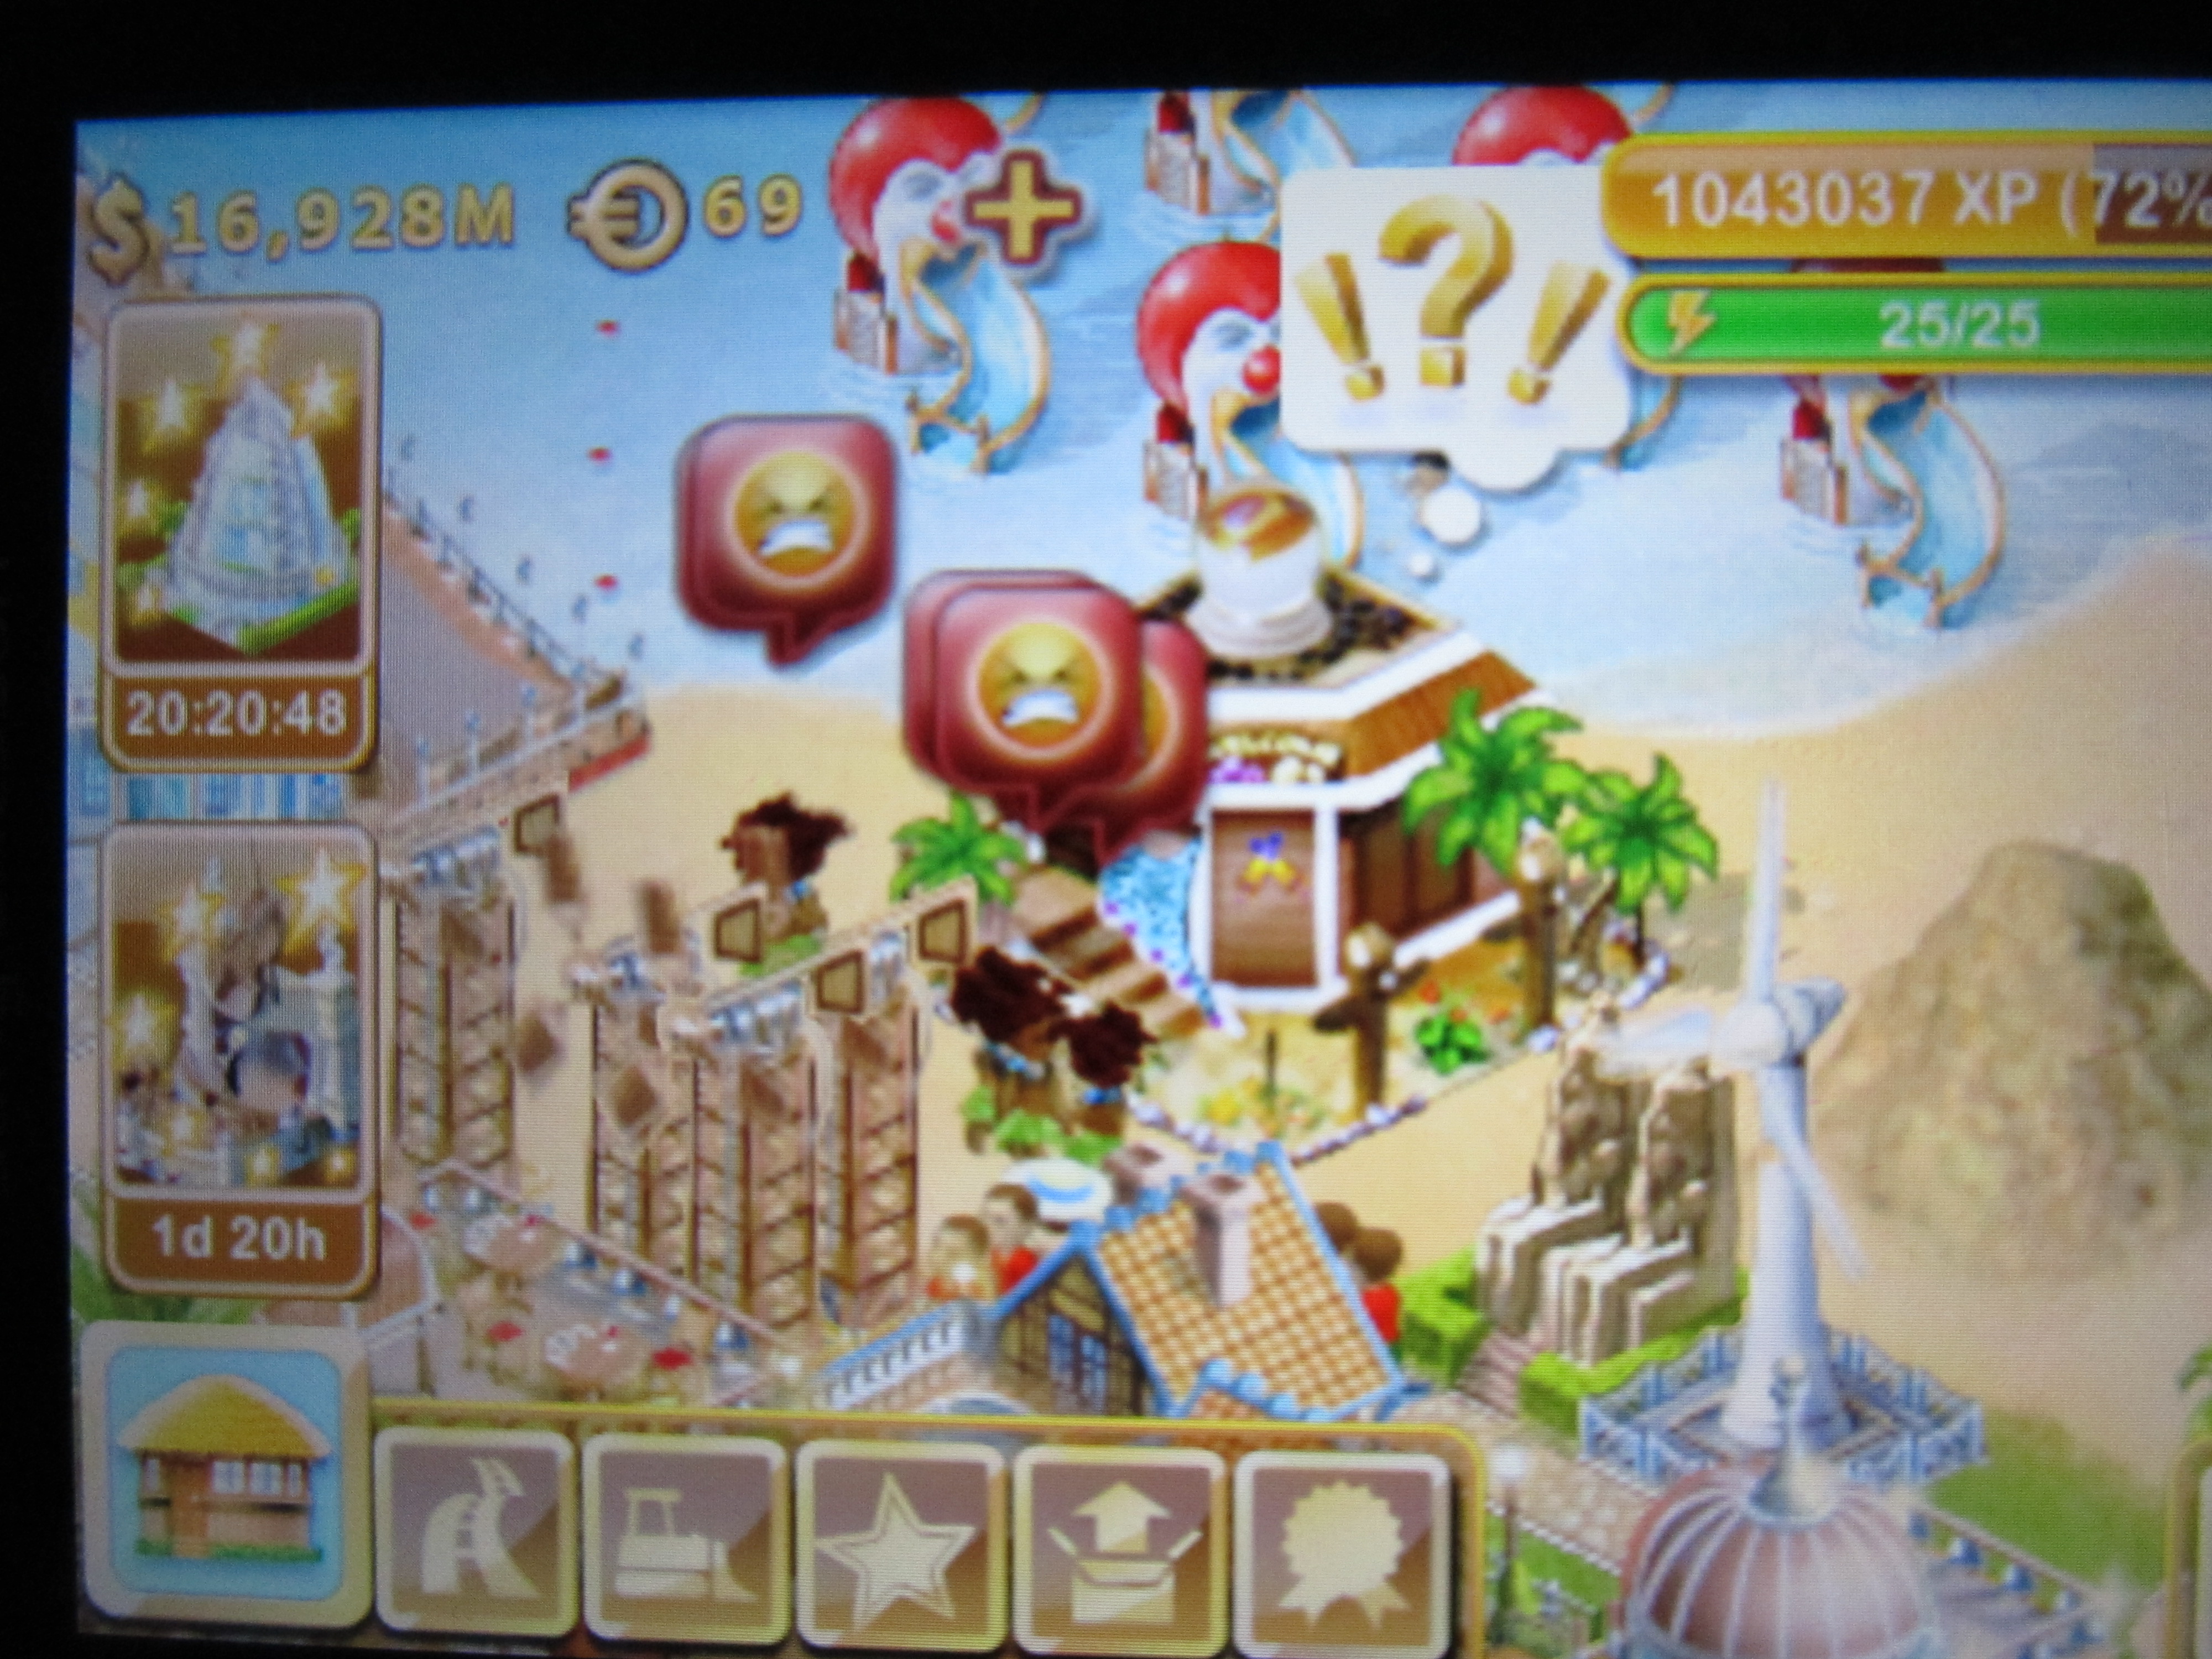
In 2011 I wrote a post that was inspired by the Sociological Images blog [1]. After some delay here I ve written another one. I plan to continue documenting such things. Playground gender segregated playground in 1918 In 2011 I photographed a plaque at Flagstaff Gardens in Melbourne. It shows a picture of the playground in 1918 with segregated boys and girls sections. It s interesting that the only difference between the two sections is that the boys have horizontal bars and a trapeze. Do they still have gender segregated playgrounds anywhere in Australia? If so what is the difference in the sections? Aborigines The Android game Paradise Island [2] has a feature where you are supposed to stop Aborigines from stealing, it plays on the old racist stereotypes about Aborigines which are used to hide the historical record that it s always been white people stealing from the people that they colonise. Angry face icons over AboriginesAborigines described as thieves There is also another picture showing the grass skirts. Nowadays the vast majority of Aborigines don t wear such clothing, the only time they do is when doing some sort of historical presentation for tourists. I took those pictures in 2012, but apparently the game hasn t changed much since then. Lemonade lemonade flavored fizzy drink Is lemonade a drink or a flavour? Most people at the party where I took the above photo regard lemonade as a drink and found the phrase Lemonade Flavoured Soft Drink strange when it was pointed out to them. Incidentally the drink on the right tastes a bit like the US version of lemonade (which is quite different from the Australian version). For US readers, the convention in Australia is that lemonade has no flavor of lemons. Not Sweet maybe gender queer people on bikes In 2012 an apple cider company made a huge advertising campaign featuring people who might be gender queer, above is a picture of a bus stop poster and there were also TV ads. The adverts gave no information at all about what the drink might taste like apart from not being as sweet as you think . So it s basically an advertising campaign with no substance other than a joke about people who don t conform to gender norms. Also it should be noted that some women naturally grow beards and have religious reasons for not shaving [3]. Episode 2 of the TV documentary series Am I Normal has an interesting interview of a woman with a beard. Revolution communist revolution Schweppes drinks A violent political revolution is usually a bad thing, using such revolutions to advertise sugar drinks seems like a bad idea. But it seems particularly interesting to note the different attitudes to such things in various countries. In 2012 Schweppes in Australia ran a marketing campaign based on imagery related to a Communist revolution (the above photo was taken at Southern Cross station in Melbourne), I presume that Schweppes in the US didn t run that campaign. I wonder whether global media will stop such things, presumably that campaign has the potential to do more harm in the US than good in Australia. Racist Penis Size Joke at Southbank racist advert in Southbank paper The above advert was in a free newspaper at Southbank in 2012. Mini Movers thought that this advert was a good idea and so did the management of Southbank who approved the advert for their paper. Australia is so racist that people don t even realise they are being racist.

19 April 2014

Joey Hess: propellor-driven DNS and backups

Took a while to get here, but Propellor 0.4.0 can deploy DNS servers and I just had it deploy mine. Including generating DNS zone files. Configuration is dead simple, as far as DNS goes:
     & alias "ns1.example.com"
        & Dns.secondary hosts "joeyh.name"
                & Dns.primary hosts "example.com"
                        (Dns.mkSOA "ns1.example.com" 100)
                        [ (RootDomain, NS $ AbsDomain "ns1.example.com")
            , (RootDomain, NS $ AbsDomain "ns2.example.com")
                        ]
The awesome thing is that propellor fills in all the other information in the zone file by looking at the properties of the hosts it knows about.
 , host "blue.example.com"
        & ipv4 "192.168.1.1"
        & ipv6 "fe80::26fd:52ff:feea:2294"
        & alias "example.com"
        & alias "www.example.com"
        & alias "example.museum"
        & Docker.docked hosts "webserver"
             requres  backedup "/var/www"
        
        & alias "ns2.example.com"
        & Dns.secondary hosts "example.com"
When it sees this host, Propellor adds its IP addresses to the example.com DNS zone file, for both its main hostname ("blue.example.com"), and also its relevant aliases. (The .museum alias would go into a different zone file.) Multiple hosts can define the same alias, and then you automaticlly get round-robin DNS. The web server part of of the blue.example.com config can be cut and pasted to another host in order to move its web server to the other host, including updating the DNS. That's really all there is to is, just cut, paste, and commit! I'm quite happy with how that worked out. And curious if Puppet etc have anything similar.
One tricky part of this was how to ensure that the serial number automtically updates when changes are made. The way this is handled is Propellor starts with a base serial number (100 in the example above), and then it adds to it the number of commits in its git repository. The zone file is only updated when something in it besides the serial number needs to change. The result is nice small serial numbers that don't risk overflowing the (so 90's) 32 bit limit, and will be consistent even if the configuration had Propellor setting up multiple independent master DNS servers for the same domain.
Another recent feature in Propellor is that it can use Obnam to back up a directory. With the awesome feature that if the backed up directory is empty/missing, Propellor will automcatically restore it from the backup. Here's how the backedup property used in the example above might be implemented:
backedup :: FilePath -> Property
backedup dir = Obnam.backup dir daily
    [ "--repository=sftp://rsync.example.com/~/webserver.obnam"
    ] Obnam.OnlyClient
     requires  Ssh.keyImported SshRsa "root"
     requires  Ssh.knownHost hosts "rsync.example.com" "root"
     requires  Gpg.keyImported "1B169BE1" "root"
Notice that the Ssh.knownHost makes root trust the ssh host key belonging to rsync.example.com. So Propellor needs to be told what that host key is, like so:
 , host "rsync.example.com"
        & ipv4 "192.168.1.4"
        & sshPubKey "ssh-rsa blahblahblah"
Which of course ties back into the DNS and gets this hostname set in it. But also, the ssh public key is available for this host and visible to the DNS zone file generator, and that could also be set in the DNS, in a SSHFP record. I haven't gotten around to implementing that, but hope at some point to make Propellor support DNSSEC, and then this will all combine even more nicely.
By the way, Propellor is now up to 3 thousand lines of code (not including Utility library). In 20 days, as a 10% time side project.

Russell Coker: Swap Space and SSD

In 2007 I wrote a blog post about swap space [1]. The main point of that article was to debunk the claim that Linux needs a swap space twice as large as main memory (in summary such advice is based on BSD Unix systems and has never applied to Linux and that most storage devices aren t fast enough for large swap). That post was picked up by Barrapunto (Spanish Slashdot) and became one of the most popular posts I ve written [2]. In the past 7 years things have changed. Back then 2G of RAM was still a reasonable amount and 4G was a lot for a desktop system or laptop. Now there are even phones with 3G of RAM, 4G is about the minimum for any new desktop or laptop, and desktop/laptop systems with 16G aren t that uncommon. Another significant development is the use of SSDs which dramatically improve speed for some operations (mainly seeks). As SATA SSDs for desktop use start at about $110 I think it s safe to assume that everyone who wants a fast desktop system has one. As a major limiting factor in swap use is the seek performance of the storage the use of SSDs should allow greater swap use. My main desktop system has 4G of RAM (it s an older Intel 64bit system and doesn t support more) and has 4G of swap space on an Intel SSD. My work flow involves having dozens of Chromium tabs open at the same time, usually performance starts to drop when I get to about 3.5G of swap in use. While SSD generally has excellent random IO performance the contiguous IO performance often isn t much better than hard drives. My Intel SSDSC2CT12 300i 128G can do over 5000 random seeks per second but for sustained contiguous filesystem IO can only do 225M/s for writes and 274M/s for reads. The contiguous IO performance is less than twice as good as a cheap 3TB SATA disk. It also seems that the performance of SSDs aren t as consistent as that of hard drives, when a hard drive delivers a certain level of performance then it can generally do so 24*7 but a SSD will sometimes reduce performance to move blocks around (the erase block size is usually a lot larger than the filesystem block size). It s obvious that SSDs allow significantly better swap performance and therefore make it viable to run a system with more swap in use but that doesn t allow unlimited swap. Even when using programs like Chromium (which seems to allocate huge amounts of RAM that aren t used much) it doesn t seem viable to have swap be much bigger than 4G on a system with 4G of RAM. Now I could buy another SSD and use two swap spaces for double the overall throughput (which would still be cheaper than buying a PC that supports 8G of RAM), but that still wouldn t solve all problems. One issue I have been having on occasion is BTRFS failing to allocate kernel memory when managing snapshots. I m not sure if this would be solved by adding more RAM as it could be an issue of RAM fragmentation I won t file a bug report about this until some of the other BTRFS bugs are fixed. Another problem I have had is when running Minecraft the driver for my ATI video card fails to allocate contiguous kernel memory, this is one that almost certainly wouldn t be solved by just adding more swap but might be solved if I tweaked the kernel to be more aggressive about swapping out data. In 2007 when using hard drives for swap I found that the maximum space that could be used with reasonable performance for typical desktop operations was something less than 2G. Now with a SSD the limit for usable swap seems to be something like 4G on a system with 4G of RAM. On a system with only 2G of RAM that might allow the system to be usable with swap being twice as large as RAM, but with the amounts of RAM in modern PCs it seems that even SSD doesn t allow using a swap space larger than RAM for typical use unless it s being used for hibernation. Conclusion It seems that nothing has significantly changed in the last 7 years. We have more RAM, faster storage, and applications that are more memory hungry. The end result is that swap still isn t very usable for anything other than hibernation if it s larger than RAM. It would be nice if application developers could stop increasing the use of RAM. Currently it seems that the RAM requirements for Linux desktop use are about 3 years behind the RAM requirements for Windows. This is convenient as a PC is fully depreciated according to the tax office after 3 years. This makes it easy to get 3 year old PCs cheaply (or sometimes for free as rubbish) which work really well for Linux. But it would be nice if we could be 4 or 5 years behind Windows in terms of hardware requirements to reduce the hardware requirements for Linux users even further.

18 April 2014

Thorsten Glaser: Stay off my computer, puppet!

I was out, seeing something that wasn t there yet when I was at school (the web was not ubiquitous, back then), and decided to have a look:
pageok

Ugh. Oh well, PocketIE doesn t provide a View Source thingy, so I asked Natureshadow (who got the same result on his Android, and had no View Source either apparently, so he used cURL to see it). We saw (here, re-enacted using ftp(1)):

	tg@blau:~ $ ftp -Vo - http://www.draitschbrunnen.de/
	<!-- pageok -->
	<!-- managed by puppet -->
	<html>
	<pre>pageok</pre>
	</html>
 

This is the final straw after puppet managed to trash a sudoers(5) at work (I warned people to not introduce it) now it breaks websites.

(Of course, tools are useful, but at best to the skill of their users. Merely dumbly copying recipes from the net without any understanding just makes debugging harder for those of us with skills.) ObQuestion: Does anyone have a transcript (into UTF-8) and a translation for the other half of the OpenBSD 2.8 poster? (I get asked this regularily.)
Update: One person sent me the Kanji and Kana for it in UTF-8 , and they and one more person told me it s Hands off my machine! or Don t lay a hand on my machine! . Now I m not studying Japanese, but it LGTM in FixedMisc [MirOS], and JMdict from MirPorts says: ore no mashin ni te (w)o dasu na (roughly: my machine; particle; hands; particle; put out; prohibition) Thanks all, now I know what to tell visitors who wonder about that poster on my wall. ObTip: I can install a few hundred Debian VMs at work manually before the effort needed to automate d-i would amortise. So I decided not to. Coworkers are shocked. I keep flexibility (can decide to have machines differ), and the boss accepts my explanations. Think before doing automation just for the sake of automation!

17 April 2014

Andrew Pollock: [life] Day 79: Magic, flu shots, and play dates and dinner

Zoe slept until 7:45am this morning, which is absolutely unheard of in our house. She did wake up at about 5:15am yelling out for me because she'd kicked her doona off and lost Cowie, but went back to sleep once I sorted that out. She was super grumpy when she woke up, which I mostly attributed to being hungry, so I got breakfast into her as quickly as possible and she perked up afterwards. Today there was a free magic show at the Bulimba Library at 10:30am, so we biked down there. I really need to work on curbing Zoe's procrastination. We started trying to leave the house at 10am, and as it was, we only got there with 2 minutes to spare before the show started. Magic Glen put on a really good show. He was part comedian, part sleight of hand magician, and he did a very entertaining show. There were plenty of gags in it for the adults. Zoe started out sitting in my lap, but part way through just got up and moved closer to the front to sit with the other kids. I think she enjoyed herself. I'd have no hesitation hiring this guy for a future birthday party. Zoe had left her two stuffed toys from the car at Megan's house on Tuesday after our Port of Brisbane tour, and so after the magic show we biked to her place to retrieve them. It was close to lunch by this stage, so we stayed for lunch, and the girls had a bit of a play in the back yard while Megan's little sister napped. It was getting close to time to leave for our flu shots, so I decided to just bike directly to the doctor from Megan's place. I realised after we left that we'd still left the stuffed toys behind, but the plan was to drive back after our flu shots and have another swim their neighbour's pool, so it was all good. We got to the doctor, and waited for Sarah to arrive. Sarah and I weren't existing patients at Zoe's doctor, but we'd decided to get the flu shot as a family to try and ease the experience for Zoe. We both had to do new patient intake stuff before we had a consult with Zoe's doctor and got prescriptions for the flu shot. I popped next door to the adjacent pharmacy get the prescriptions filled, and then the nurse gave us the shots. For the last round of vaccinations that Zoe received, she needed three, and she screamed the building down at the first jab. The poor nurse was very shaken, so we've been working to try and get her to feel more at ease about this one. Zoe went first, and she took a deep breath, and she was winding up to freak out when she had her shot, but then it was all over, and she let the breath go, and looked around with a kind of "is that it?" reaction. She didn't even cry. I was so proud of her. I got my shot, and then Sarah got hers, and we had to sit in the waiting room for 10 minutes to make sure we didn't turn into pumpkins, and we were on our way. We biked home, I grabbed our swim gear, and we drove back to Megan's place. The pool ended up being quite cold. Megan didn't want to get in, and Zoe didn't last long either. Megan's Mum was working back late, so I invited Megan, her Dad and her sister over for dinner, and we headed home so I could prepare it. One of Zoe's stuffed toys had been located. We had a nice dinner of deviled sausages made in the Thermomix, and for a change I didn't have a ton of leftovers. Jason had found the other stuffed toy in his truck, so we'd finally tracked them both down. After Megan and family went home, I got Zoe to bed without much fuss, and pretty much on time. I think she should sleep well tonight.

15 April 2014

Colin Watson: Porting GHC: A Tale of Two Architectures

We had some requests to get GHC (the Glasgow Haskell Compiler) up and running on two new Ubuntu architectures: arm64, added in 13.10, and ppc64el, added in 14.04. This has been something of a saga, and has involved rather more late-night hacking than is probably good for me. Book the First: Recalled to a life of strange build systems You might not know it from the sheer bulk of uploads I do sometimes, but I actually don't speak a word of Haskell and it's not very high up my list of things to learn. But I am a pretty experienced build engineer, and I enjoy porting things to new architectures: I'm firmly of the belief that breadth of architecture support is a good way to shake out certain categories of issues in code, that it's worth doing aggressively across an entire distribution, and that, even if you don't think you need something now, new requirements have a habit of coming along when you least expect them and you might as well be prepared in advance. Furthermore, it annoys me when we have excessive noise in our build failure and proposed-migration output and I often put bits and pieces of spare time into gardening miscellaneous problems there, and at one point there was a lot of Haskell stuff on the list and it got a bit annoying to have to keep sending patches rather than just fixing things myself, and ... well, I ended up as probably the only non-Haskell-programmer on the Debian Haskell team and found myself fixing problems there in my free time. Life is a bit weird sometimes. Bootstrapping packages on a new architecture is a bit of a black art that only a fairly small number of relatively bitter and twisted people know very much about. Doing it in Ubuntu is specifically painful because we've always forbidden direct binary uploads: all binaries have to come from a build daemon. Compilers in particular often tend to be written in the language they compile, and it's not uncommon for them to build-depend on themselves: that is, you need a previous version of the compiler to build the compiler, stretching back to the dawn of time where somebody put things together with a big magnet or something. So how do you get started on a new architecture? Well, what we do in this case is we construct a binary somehow (usually involving cross-compilation) and insert it as a build-dependency for a proper build in Launchpad. The ability to do this is restricted to a small group of Canonical employees, partly because it's very easy to make mistakes and partly because things like the classic "Reflections on Trusting Trust" are in the backs of our minds somewhere. We have an iron rule for our own sanity that the injected build-dependencies must themselves have been built from the unmodified source package in Ubuntu, although there can be source modifications further back in the chain. Fortunately, we don't need to do this very often, but it does mean that as somebody who can do it I feel an obligation to try and unblock other people where I can. As far as constructing those build-dependencies goes, sometimes we look for binaries built by other distributions (particularly Debian), and that's pretty straightforward. In this case, though, these two architectures are pretty new and the Debian ports are only just getting going, and as far as I can tell none of the other distributions with active arm64 or ppc64el ports (or trivial name variants) has got as far as porting GHC yet. Well, OK. This was somewhere around the Christmas holidays and I had some time. Muggins here cracks his knuckles and decides to have a go at bootstrapping it from scratch. It can't be that hard, right? Not to mention that it was a blocker for over 600 entries on that build failure list I mentioned, which is definitely enough to make me sit up and take notice; we'd even had the odd customer request for it. Several attempts later and I was starting to doubt my sanity, not least for trying in the first place. We ship GHC 7.6, and upgrading to 7.8 is not a project I'd like to tackle until the much more experienced Haskell folks in Debian have switched to it in unstable. The porting documentation for 7.6 has bitrotted more or less beyond usability, and the corresponding documentation for 7.8 really isn't backportable to 7.6. I tried building 7.8 for ppc64el anyway, picking that on the basis that we had quicker hardware for it and didn't seem likely to be particularly more arduous than arm64 (ho ho), and I even got to the point of having a cross-built stage2 compiler (stage1, in the cross-building case, is a GHC binary that runs on your starting architecture and generates code for your target architecture) that I could copy over to a ppc64el box and try to use as the base for a fully-native build, but it segfaulted incomprehensibly just after spawning any child process. Compilers tend to do rather a lot, especially when they're built to use GCC to generate object code, so this was a pretty serious problem, and it resisted analysis. I poked at it for a while but didn't get anywhere, and I had other things to do so declared it a write-off and gave up. Book the Second: The golden thread of progress In March, another mailing list conversation prodded me into finding a blog entry by Karel Gardas on building GHC for arm64. This was enough to be worth another look, and indeed it turned out that (with some help from Karel in private mail) I was able to cross-build a compiler that actually worked and could be used to run a fully-native build that also worked. Of course this was 7.8, since as I mentioned cross-building 7.6 is unrealistically difficult unless you're considerably more of an expert on GHC's labyrinthine build system than I am. OK, no problem, right? Getting a GHC at all is the hard bit, and 7.8 must be at least as capable as 7.6, so it should be able to build 7.6 easily enough ... Not so much. What I'd missed here was that compiler engineers generally only care very much about building the compiler with older versions of itself, and if the language in question has any kind of deprecation cycle then the compiler itself is likely to be behind on various things compared to more typical code since it has to be buildable with older versions. This means that the removal of some deprecated interfaces from 7.8 posed a problem, as did some changes in certain primops that had gained an associated compatibility layer in 7.8 but nobody had gone back to put the corresponding compatibility layer into 7.6. GHC supports running Haskell code through the C preprocessor, and there's a __GLASGOW_HASKELL__ definition with the compiler's version number, so this was just a slog tracking down changes in git and adding #ifdef-guarded code that coped with the newer compiler (remembering that stage1 will be built with 7.8 and stage2 with stage1, i.e. 7.6, from the same source tree). More inscrutably, GHC has its own packaging system called Cabal which is also used by the compiler build process to determine which subpackages to build and how to link them against each other, and some crucial subpackages weren't being built: it looked like it was stuck on picking versions from "stage0" (i.e. the initial compiler used as an input to the whole process) when it should have been building its own. Eventually I figured out that this was because GHC's use of its packaging system hadn't anticipated this case, and was selecting the higher version of the ghc package itself from stage0 rather than the version it was about to build for itself, and thus never actually tried to build most of the compiler. Editing ghc_stage1_DEPS in ghc/stage1/package-data.mk after its initial generation sorted this out. One late night building round and round in circles for a while until I had something stable, and a Debian source upload to add basic support for the architecture name (and other changes which were a bit over the top in retrospect: I didn't need to touch the embedded copy of libffi, as we build with the system one), and I was able to feed this all into Launchpad and watch the builders munch away very satisfyingly at the Haskell library stack for a while. This was all interesting, and finally all that work was actually paying off in terms of getting to watch a slew of several hundred build failures vanish from arm64 (the final count was something like 640, I think). The fly in the ointment was that ppc64el was still blocked, as the problem there wasn't building 7.6, it was getting a working 7.8. But now I really did have other much more urgent things to do, so I figured I just wouldn't get to this by release time and stuck it on the figurative shelf. Book the Third: The track of a bug Then, last Friday, I cleared out my urgent pile and thought I'd have another quick look. (I get a bit obsessive about things like this that smell of "interesting intellectual puzzle".) slyfox on the #ghc IRC channel gave me some general debugging advice and, particularly usefully, a reduced example program that I could use to debug just the process-spawning problem without having to wade through noise from running the rest of the compiler. I reproduced the same problem there, and then found that the program crashed earlier (in stg_ap_0_fast, part of the run-time system) if I compiled it with +RTS -Da -RTS. I nailed it down to a small enough region of assembly that I could see all of the assembly, the source code, and an intermediate representation or two from the compiler, and then started meditating on what makes ppc64el special. You see, the vast majority of porting bugs come down to what I might call gross properties of the architecture. You have things like whether it's 32-bit or 64-bit, big-endian or little-endian, whether char is signed or unsigned, that sort of thing. There's a big table on the Debian wiki that handily summarises most of the important ones. Sometimes you have to deal with distribution-specific things like whether GL or GLES is used; often, especially for new variants of existing architectures, you have to cope with foolish configure scripts that think they can guess certain things from the architecture name and get it wrong (assuming that powerpc* means big-endian, for instance). We often have to update config.guess and config.sub, and on ppc64el we have the additional hassle of updating libtool macros too. But I've done a lot of this stuff and I'd accounted for everything I could think of. ppc64el is actually a lot like amd64 in terms of many of these porting-relevant properties, and not even that far off arm64 which I'd just successfully ported GHC to, so I couldn't be dealing with anything particularly obvious. There was some hand-written assembly which certainly could have been problematic, but I'd carefully checked that this wasn't being used by the "unregisterised" (no specialised machine dependencies, so relatively easy to port but not well-optimised) build I was using. A problem around spawning processes suggested a problem with SIGCHLD handling, but I ruled that out by slowing down the first child process that it spawned and using strace to confirm that SIGSEGV was the first signal received. What on earth was the problem? From some painstaking gdb work, one thing I eventually noticed was that stg_ap_0_fast's local stack appeared to be being corrupted by a function call, specifically a call to the colourfully-named debugBelch. Now, when IBM's toolchain engineers were putting together ppc64el based on ppc64, they took the opportunity to fix a number of problems with their ABI: there's an OpenJDK bug with a handy list of references. One of the things I noticed there was that there were some stack allocation optimisations in the new ABI, which affected functions that don't call any vararg functions and don't call any functions that take enough parameters that some of them have to be passed on the stack rather than in registers. debugBelch takes varargs: hmm. Now, the calling code isn't quite in C as such, but in a related dialect called "Cmm", a variant of C-- (yes, minus), that GHC uses to help bridge the gap between the functional world and its code generation, and which is compiled down to C by GHC. When importing C functions into Cmm, GHC generates prototypes for them, but it doesn't do enough parsing to work out the true prototype; instead, they all just get something like extern StgFunPtr f(void);. In most architectures you can get away with this, because the arguments get passed in the usual calling convention anyway and it all works out, but on ppc64el this means that the caller doesn't generate enough stack space and then the callee tries to save its varargs onto the stack in an area that in fact belongs to the caller, and suddenly everything goes south. Things were starting to make sense. Now, debugBelch is only used in optional debugging code; but runInteractiveProcess (the function associated with the initial round of failures) takes no fewer than twelve arguments, plenty to force some of them onto the stack. I poked around the GCC patch for this ABI change a bit and determined that it only optimised away the stack allocation if it had a full prototype for all the callees, so I guessed that changing those prototypes to extern StgFunPtr f(); might work: it's still technically wrong, not least because omitting the parameter list is an obsolescent feature in C11, but it's at least just omitting information about the parameter list rather than actively lying about it. I tweaked that and ran the cross-build from scratch again. Lo and behold, suddenly I had a working compiler, and I could go through the same build-7.6-using-7.8 procedure as with arm64, much more quickly this time now that I knew what I was doing. One upstream bug, one Debian upload, and several bootstrapping builds later, and GHC was up and running on another architecture in Launchpad. Success! Epilogue There's still more to do. I gather there may be a Google Summer of Code project in Linaro to write proper native code generation for GHC on arm64: this would make things a good deal faster, but also enable GHCi (the interpreter) and Template Haskell, and thus clear quite a few more build failures. Since there's already native code generation for ppc64 in GHC, getting it going for ppc64el would probably only be a couple of days' work at this point. But these are niceties by comparison, and I'm more than happy with what I got working for 14.04. The upshot of all of this is that I may be the first non-Haskell-programmer to ever port GHC to two entirely new architectures. I'm not sure if I gain much from that personally aside from a lot of lost sleep and being considered extremely strange. It has, however, been by far the most challenging set of packages I've ported, and a fascinating trip through some odd corners of build systems and undefined behaviour that I don't normally need to touch.

14 April 2014

Christine Spang: PyCon 2014 retrospective

PyCon 2014 happened. (Sprints are still happening.) This was my 3rd PyCon, but my first year as a serious contributor to the event, which led to an incredibly different feel. I also came as a person running a company building a complex system in Python, and I loved having the overarching mission of what I'm building driving my approach to what I chose to do. PyCon is one of the few conferences I go to where the feeling of acceptance and at-homeness mitigates the introvert overwhelm at nonstop social interaction. It's truly a special event and community. Here are some highlights: I didn't get to go to a lot of talks in person this year since my personal schedule was so full, but the PyCon video team is amazing as usual, so I'm looking forward to checking out the archive. It really is a gift to get the videos up while energy from the conference is still so high and people want to check out things they missed and share the talks they loved. Thanks to everyone, hugs, peace out, et cetera!

Andrew Pollock: [life] Day 76: Dora + Fever

We had a bit of a rough night last night. I noticed Zoe was pretty hot when she had a nap yesterday after not really eating much lunch. She still had a mild fever after her nap, so I gave her some paracetamol (aka acetaminophen, that one weirded me out when I moved to the US) and called for a home doctor to check her ears out. Her ears were fine, but her throat was a little red. The doctor said it was probably a virus. Her temperature wasn't so high at bed time, so I skipped the paracetamol, and she went to bed fine. She did wake up at about 1:30am and it took me until 3am to get her back to bed. I think it was a combination of the fever and trying to phase out her white noise, but she just didn't want to sleep in her bed or her room. At 3am I admitted defeat and let her sleep with me. She had only a slightly elevated temperature this morning, and otherwise seemed in good spirits. We were supposed to go to a family lunch today, because my sister and brother are in town with their respective families, but I figured we'd skip that on account that Zoe may have still had something, and coupled with the poor night's sleep, I wasn't sure how much socialising she was going to be up for. My ear has still been giving me grief, and I had a home doctor check it yesterday as well, and he said the ear canal was 90% blocked. First thing this morning I called up to make an appointment with my regular doctor to try and get it flushed out. The earliest appointment I could get was 10:15am. So we trundled around the corner to my doctor after a very slow start to the day. I got my ear cleaned out and felt like a million bucks afterwards. We went to Woolworths to order an undecorated mud slab cake, so I can try doing a trial birthday cake. I've given up on trying to do the sitting minion, and significantly scaled back to just a flat minion slab cake. The should be ready tomorrow. The family thing was originally supposed to be tomorrow, and was only moved to today yesterday. My original plan had been to take Zoe to a free Dora the Explorer live show that was on in the Queen Street Mall. I decided to revert back to the original plan, but by this stage, it was too late to catch the 11am show, so the 1pm show was the only other option. We had a "quick" lunch at home, which involved Zoe refusing the eat the sandwich I made for her and me convincing her otherwise. Then I got a time-sensitive phone call from a friend, and once I'd finished dealing with that, there wasn't enough time to take any form of public transport and get there in time, so I decided to just drive in. We parked in the Myer Centre car park, and quickly made our way up to the mall, and made it there comfortably with 5 minutes to spare. The show wasn't anything much to phone home about. It was basically just 20 minutes of someone in a giant Dora suit acting out was was essentially a typical episode of Dora the Explorer, on stage, with a helper. Zoe started out wanting to sit on my lap, but made a few brief forays down to the "mosh pit" down the front with the other kids, dancing around. After the show finished, we had about 40 minutes to kill before we could get a photo with Dora, so we wandered around the Myer Centre. I let Zoe choose our destinations initially, and we browsed a cheap accessories store that was having a sale, and then we wandered downstairs to one of the underground bus station platforms. After that, we made our way up to Lincraft, and browsed. We bought a $5 magnifying glass, and I let Zoe do the whole transaction by herself. After that it was time to make our way back down for the photo. Zoe made it first in line, so we were in and out nice and quick. We got our photos, and they gave her a little activity book as well, which she thought was cool, and then we headed back down the car park. In my haste to park and get top side, I hadn't really paid attention to where we'd parked, and we came down via different elevators than we went up, so by the time I'd finally located the car, the exit gate was trying to extract an extra $5 parking out of me. Fortunately I was able to use the intercom at the gate and tell my sob story of being a nincompoop, and they let us out without further payment. We swung by the Valley to clear my PO box, and then headed home. Zoe spontaneously announced she'd had a fun day, so that was lovely. We only had about an hour and half to kill before Sarah was going to pick up Zoe, so we just mucked around. Zoe looked at stuff around the house with her magnifying glass. She helped me open my mail. We looked at some of the photos on my phone. Dayframe and a Chromecast is a great combination for that. We had a really lovely spell on the couch where we took turns to draw on her Magna Doodle. That was some really sweet time together. Zoe seemed really eager for her mother to arrive, and kept asking how much longer it was going to be, and going outside our unit's front door to look for her. Sarah finally arrived, and remarked that Zoe felt hot, and so I checked her temperature, and her fever had returned, so whatever she has she's still fighting off. I decided to do my Easter egg shopping in preparation for Sunday. A friend suggested this cool idea of leaving rabbit paw tracks all over the house in baby powder, and I found a template online and got that all ready to go. I had a really great yoga class tonight. Probably one of the best I've had in a while in terms of being able to completely clear my head. I'm looking forward to an uninterrupted night's sleep tonight.

Matthew Garrett: Real-world Secure Boot attacks

MITRE gave a presentation on UEFI Secure Boot at SyScan earlier this month. You should read the the presentation and paper, because it's really very good.

It describes a couple of attacks. The first is that some platforms store their Secure Boot policy in a run time UEFI variable. UEFI variables are split into two broad categories - boot time and run time. Boot time variables can only be accessed while in boot services - the moment the bootloader or kernel calls ExitBootServices(), they're inaccessible. Some vendors chose to leave the variable containing firmware settings available during run time, presumably because it makes it easier to implement tools for modifying firmware settings at the OS level. Unfortunately, some vendors left bits of Secure Boot policy in this space. The naive approach would be to simply disable Secure Boot entirely, but that means that the OS would be able to detect that the system wasn't in a secure state[1]. A more subtle approach is to modify the policy, such that the firmware chooses not to verify the signatures on files stored on fixed media. Drop in a new bootloader and victory is ensured.

But that's not a beautiful approach. It depends on the firmware vendor having made that mistake. What if you could just rewrite arbitrary variables, even if they're only supposed to be accessible in boot services? Variables are all stored in flash, connected to the chipset's SPI controller. Allowing arbitrary access to that from the OS would make it straightforward to modify the variables, even if they're boot time-only. So, thankfully, the SPI controller has some control mechanisms. The first is that any attempt to enable the write-access bit will cause a System Management Interrupt, at which point the CPU should trap into System Management Mode and (if the write attempt isn't authorised) flip it back. The second is to disable access from the OS entirely - all writes have to take place in System Management Mode.

The MITRE results show that around 0.03% of modern machines enable the second option. That's unfortunate, but the first option should still be sufficient[2]. Except the first option requires on the SMI actually firing. And, conveniently, Intel's chipsets have a bit that allows you to disable all SMI sources[3], and then have another bit to disable further writes to the first bit. Except 40% of the machines MITRE tested didn't bother setting that lock bit. So you can just disable SMI generation, remove the write-protect bit on the SPI controller and then write to arbitrary variables, including the SecureBoot enable one.

This is, uh, obviously a problem. The good news is that this has been communicated to firmware and system vendors and it should be fixed in the future. The bad news is that a significant proportion of existing systems can probably have their Secure Boot implementation circumvented. This is pretty unsurprisingly - I suggested that the first few generations would be broken back in 2012. Security tends to be an iterative process, and changing a branch of the industry that's historically not had to care into one that forms the root of platform trust is a difficult process. As the MITRE paper says, UEFI Secure Boot will be a genuine improvement in security. It's just going to take us a little while to get to the point where the more obvious flaws have been worked out.

[1] Unless the malware was intelligent enough to hook GetVariable, detect a request for SecureBoot and then give a fake answer, but who would do that?
[2] Impressively, basically everyone enables that.
[3] Great for dealing with bugs caused by YOUR ENTIRE COMPUTER BEING INTERRUPTED BY ARBITRARY VENDOR CODE, except unfortunately it also probably disables chunks of thermal management and stops various other things from working as well.

comment count unavailable comments

Next.

Previous.