Search Results: "ron"

9 December 2014

Hideki Yamane: ThinkPad X121e with UFEI boot

I have ThinkPad X121e and recenly exchanged its HDD to SSD, then I've tried to boot from UEFI but I couldn't. And I considered its something wrong with this old BIOS verion but new one can improve the situation, tried to update it. Steps are below.
  1. get iso image file from Lenovo (Japanese site) (release note)
  2. put iso image into /boot
  3. add custom grub file as /etc/grub.d/99_bios (note: I don't separate /boot partition, maybe you should specify path for file if you don't do so).
    $ sudo sh -c "touch /etc/grub.d/99_bios; chmod +x /etc/grub.d/99_bios"
    and edit /etc/grub.d/99_bio file.
    #! /bin/sh
    menuentry "BIOS Update"
    linux16 memdisk iso
    initrd16 xxxxxxxxxx.iso

  4. update grub menu with and check /boot/grub/grub.cfg file
    $ sudo update-grub
    $ tail /boot/grub/grub.cfg
  5. make sure memdisk command is installed
    $ sudo apt-get install syslinux
  6. just reboot and select bios update menu
Looks okay, its firmware update was success but I cannot boot it (installation was okay). Hmm...

As Matthew Garrett blogged before, probably ThinkPad X121e's firmware doesn't allow to boot from any entries in UEFI except "Windows Boot Manager" :-(

...So I have to back to legacy BIOS. *sigh*

8 December 2014

Bernhard R. Link: The Colon in the Shell.

I was recently asked about some construct in a shell script starting with a colon(:), leading me into a long monologue about it. Afterwards I realized I had forgotten to mention half of the nice things. So here for your amusement some usage for the colon in the shell: To find the meaning of ":" in the bash manpage[1], you have to look at the start of the SHELL BUILTIN COMMANDS section. There you find:
: [arguments]
	No effect; the command does nothing beyond expanding arguments and performing any specified redirections.  A zero exit code is returned.
If you wonder what the difference to true is: I don't know any difference (except that there is no /bin/:) So what is the colon useful for? You can use it if you need a command that does nothing, but still is a command. Then there is more things you can do with the colon, most I'd put under "abuse": This is of course not a complete list. But unless I missed something else, those are the most common cases I run into. [1] <rant>If you never looked at it, better don't start: the bash manpage is legendary for being quite useless as hiding all information in other information in a quite absurd order. Unless you look at documentation about how to write a shell script parser, then the bash manpage is really what you want to read.</rant>

Andrew Pollock: [tech] A geek Dad goes to Kindergarten with a box full of Open Source and some vegetables

Zoe's Kindergarten encourages parents to come in and spend some time with the kids. I've heard reports of other parents coming in and doing baking with the kids or other activities at various times throughout the year. Zoe and I had both wanted me to come in for something, but it had taken me until the last few weeks of the year to get my act together and do something. I'd thought about coming in and doing some baking, but that seemed rather done to death already, and it's not like baking is really my thing, so I thought I'd do something technological. I just wracked my brains for something low effort and Kindergarten-age friendly. The Kindergarten has a couple of eduss touch screens. They're just some sort of large-screen with a bunch of inputs and outputs on them. I think the Kindergarten mostly uses them for showing DVDs and hooking up a laptop and possibly doing something interactive on them. As they had HDMI input, and my Raspberry Pi had HDMI output, it seemed like a no-brainer to do something using the Raspberry Pi. I also thought hooking up the MaKey MaKey to it would make for a more fun experience. I just needed to actually have it all do something, and that's where I hit a bit of a creative brick wall. I thought I'd just hack something together where based on different inputs on the MaKey MaKey, a picture would get displayed and a sound played. Nothing fancy at all. I really struggled to get a picture displayed full screen in a time efficient manner. My Pi was running Raspbian, so it was relatively simple to configure LightDM to auto-login and auto-start something. I used triggerhappy to invoke a shell script, which took care of playing a sound and an image. Playing a sound was easy. Displaying an image less so, especially if I wanted the image loaded fast. I really wanted to avoid having to execute an image viewer every time an input fired, because that would be just way too slow. I thought I'd found a suitable application in Geeqie, because it supported being out of band managed, but it's problem was it also responded to the inputs from the MaKey MaKey, so it became impossible to predictably display the right image with the right input. So the night before I was supposed to go to Kindergarten, I was up beating my head against it, and decided to scrap it and go back to the drawing board. I was looking around for a Kindergarten-friendly game that used just the arrow keys, and I remembered the trusty old Frozen Bubble. This ended up being absolutely perfect. It had enough flags to control automatic startup, so I could kick it straight into a dumbed-down full screen 1 player game (--fullscreen --solo --no-time-limit) The kids absolutely loved it. They were cycled through in groups of four and all took turns having a little play. I brought a couple of heads of broccoli, a zucchini and a potato with me. I started out using the two broccoli as left and right and the zucchini to fire, but as it turns out, not all the kids were as good with the "left" and "right" as Zoe, so I swapped one of the broccoli for a potato and that made things a bit less ambiguous. The responses from the kids were varied. Quite a few clearly had their minds blown and wanted to know how the broccoli was controlling something on the screen. Not all of them got the hang of the game play, but a lot did. Some picked it up after having a play and then watching other kids play and then came back for a more successful second attempt. Some weren't even sure what a zucchini was. Overall, it was a very successful activity, and I'm glad I switched to Frozen Bubble, because what I'd originally had wouldn't have held up to the way the kids were using it. There was a lot of long holding/touching of the vegetables, which would have fired hundreds of repeat events, and just totally overwhelmed triggerhappy. Quite a few kids wanted to pick up and hold the vegetables instead of just touch them to send an event. As it was, the Pi struggled to play Frozen Bubble enough as it was. The other lesson I learned pretty quickly was that an aluminium BBQ tray worked a lot better as the grounding point for the MaKey MaKey than having to tether an anti-static strap around each kid's ankle as they sat down in front of the screen. Once I switched to the tray, I could rotate kids through the activity much faster. I just wish I was a bit more creative, or there were more Kindergarten-friendly arrow-key driven Linux applications out there, but I was happy with what I managed to hack together with a fairly minimal amount of effort.

Clint Adams: I don't care about the sunshine, yeah

Rhoda is guarded. She is secretly in love with her brother. When he gets a girlfriend, she finds a boyfriend. She tells no one what she's really thinking. Rhoda likes to seize the day. In the midst of evening conversation, she will excuse herself to use the bathroom or come right back , then, within literally two minutes, she will go home with an acquaintance or stranger. Often these encounters or the aftermaths thereof do not go according to her liking, and she will make veiled remarks of hostility, should she see those people again. Rhoda was unhappy so she changed everything in her life. Though multiple things remained constant, she concluded that she was, in fact, the problem. Rhoda does not make enough money on which to live. She works part-time, and turns down all other job offers. Other people make up for her financial shortcomings so that she is not homeless and starving. Rhoda is certain that it is more difficult to be female than male.

7 December 2014

Sven Hoexter: Failing with F5: Implementing HTTP session persistence

In the old days people deployed the Apache HTTPD together with mod_jk and mod_balancer in front of Apache Tomcat instances to achieve scalability and resilience. That sooner or later turns out to not provide features you nowadays would like to have to run a service 24/7. So it happened that I had to jump into the sometimes cold sea of managing services fronted by F5 BigIP devices, a somewhat common load balancing solution. Soon after you start to introduce loadbalancing, because you grow beyond the "one fat webserver" state, you'll have the requirement to implement some way of session persistence. In the old days you might have added a unique jvmRoute value to your mod_balancer pool and to your tomcat configuration to match the connection to the right pool member. If you're clever you've set it on the Tomcat as a variable that automatically builds up the jvmRoute based on the hostname, so you can add new instances without having to touch the Tomcat configuration. In case you were not that clever (like we were when we started) you might have added placeholders in the server.xml to set the jvmRoute value in your deployment script. I think in a somewhat better world your first step usually is to introduce a shared session store, be it the php session handler backed by a memcached or Hazelcast for the Java afficionados, to avoid the persistence requirement on your balancer. But if you grow even bigger the requirement will soon reappear because you might have to add some form of sharding and now have to sent users to the same cluster serving a specific shard. In the end all of that is not cool and your developers have to be aware of those issues. For all cases where fault tolerance within the session is not a priority we aimed for something that we can enable or disable on the balancer without application code changes. The "let the box do its job" solution The nicest solution from our point of view is letting the F5 inject a cookie that points the device on subsequent requests to the right pool node. If you like you can define the cookie name, a timeout, force the injection on replies and some other tunables. Take a look at the help for ltm persistence cookie if you'd like to have a look at the details. The "let's do it by hand but on the box" solution Most Java frameworks provide a session cookie called JSESSIONID. Why not use that one and add a persistence table entry on the BigIP with the cookie as the lookup key? As always if there's no solution provided out of the box you can implement an iRule for it. Kind of an F5 mantra. There are many examples out there, here is what we ended up with:
when HTTP_REQUEST  
    if   [HTTP::cookie "JSESSIONID"] ne ""  
        persist uie [string tolower [HTTP::cookie "JSESSIONID"]] 1800 
     
 
when HTTP_RESPONSE  
    if   [HTTP::cookie "JSESSIONID"] ne ""  
        persist add uie [string tolower [HTTP::cookie "JSESSIONID"]] 1800
     
 
And here is where I failed Now imagine you're running an application that so far handles only machine to machine traffic without session persistence. A few month later you're approached to enable session persistence, because someone introduced a management console for the application as a web user interface. Without further ado you jump on board and provide - showcasing the flexibility of the new balancer - session persistence based on cookies injected by the BigIP. You've done it before, you enable it for the test environment, everything looks fine, you enable it for the production setup. Everything is fine (at least for now ...), the WUI workes fine, sessions are persistent to the node the user hit first. A month or two later someone from the development team approaches you again, this time asking if the balancing setup has some issues because over 90% of the live traffic hit one of the two machines in the pool until it wents down due to a crash or a deployment. Then about 90% hit the other node, even after the crashed one is resurrected. But every time the developer tests the balancing with a "while true" loop sending several hundred requests via curl the balancing is perfectly equal. After beeing puzzled by the behaviour myself we started to look at the live traffic with tcpdump and suddenly it was all clear when I saw the BigIP cookie beeing passed around. Actually everything behaved as we configured it. The application used a proper HTTP library and that one implemented cookies: If you receive one you're polite and pass it back to the sender. The original sender of course also implements HTTP with cookie support and now, due to the natur of the traffic, we have long living connections between two applications passing around the same cookie. On every single HTTP request sent through this connection. And every time the balancer will look at the cookie and happily base the routing decision on the pool member noted in this cookie. When we tested with curl we did not have the usage of cookies on our mind. Because our false assumption was that the applications do not create cookies for machine to machine traffic. Nobody, including myself, actively remembered the decision to base the session persistence on cookies injected by the balancer. We went on and switched to the iRule mentioned above. Luckily we already had that one implemented and tested for a different use case with the requirement to not inject additional cookies.
  1. Can we maybe improve the change process for the balancer to handle a mixed traffic scenario?
  2. Do we need monitoring to monitor the balancing of requests?
  3. Is it a wise idea to mix machine2machine and user2machine traffic on the same port?
  4. Should we maybe, if we seperate properly, place management applications on a different system?
  5. Is our documentation sufficient?
Combine 3. and 4. and ask yourself how resilient you are if someone tries to exhaust the memory of the balancer with a lot of connection attempts that have random JSESSIONID cookies? Or is it even possible to exhaust ressource with faked BigIP cookies you inject? Maybe it's even a vector for something like http://events.ccc.de/congress/2011/Fahrplan/attachments/2007_28C3_Effective_DoS_on_web_application_platforms.pdf? Quite some questions left to think about and draft answers for.

5 December 2014

Rhonda D'Vine: Fiona Apple

I do hang out in #debian-women on IRC, which shouldn't be much of a surprise after my last blog entry about my Feminist Year. And for readers of my blog it also shouldn't be much of a surprise that Music is an important part of my life. Recently a colleague from Debian though asked me in said IRC channel about whether I can recommend some female artists or bands. Which got me looking through my recommendations so far, and actually, there weren't many of those in here, unfortunately. So I definitely want to work on that because there are so many female singers, songwriters and bands out there that I totally would like to share with the broader audience. I want to start out with a strong female voice who was introduced to me by another strong woman thanks for that! Fiona Apple definitely has her own style and is something special, she stands out. Here are my suggestions: Like always, enjoy!

/music permanent link Comments: 0 Flattr this

Joey Hess: clean OS reinstalls with propellor

You have a machine someplace, probably in The Cloud, and it has Linux installed, but not to your liking. You want to do a clean reinstall, maybe switching the distribution, or getting rid of the cruft. But this requires running an installer, and it's too difficult to run d-i on remote machines. Wouldn't it be nice if you could point a program at that machine and have it do a reinstall, on the fly, while the machine was running? This is what I've now taught propellor to do! Here's a working configuration which will make propellor convert a system running Fedora (or probably many other Linux distros) to Debian:
testvm :: Host
testvm = host "testvm.kitenet.net"
        & os (System (Debian Unstable) "amd64")
        & OS.cleanInstallOnce (OS.Confirmed "testvm.kitenet.net")
                 onChange  propertyList "fixing up after clean install"
                        [ User.shadowConfig True
                        , OS.preserveRootSshAuthorized
                        , OS.preserveResolvConf
                        , Apt.update
                        , Grub.boots "/dev/sda"
                                 requires  Grub.installed Grub.PC
                        ]
        & Hostname.sane
        & Hostname.searchDomain
        & Apt.installed ["linux-image-amd64"]
        & Apt.installed ["ssh"]
        & User.hasSomePassword "root"
And here's a video of it in action.
It was surprisingly easy to build this. Propellor already knew how to create a chroot, so from there it basically just has to move files around until the chroot takes over from the old OS. After the cleanInstallOnce property does its thing, propellor is running inside a freshly debootstrapped Debian system. Then we just need a few more Propertites to get from there to a bootable, usable system: Install grub and the kernel, turn on shadow passwords, preserve a few config files from the old OS, etc. It's really astounding to me how much easier this was to build than it was to build d-i. It took years to get d-i to the point of being able to install a working system. It took me a few part days to add this capability to propellor (It's 200 lines of code), and I've probably spent a total of less than 30 days total developing propellor in its entirity. So, what gives? Why is this so much easier? There are a lot of reasons: This seems like the opposite of the Second System effect to me. So perhaps d-i was the second system all along? I don't know if I'm going to take this all the way to propellor is d-i 2.0. But in theory, all that's needed now is:
cleanInstallOnce and associated Properties will be included in propellor's upcoming 1.1.0 release, and are available in git now. Oh BTW, you could parameterize a few Properties by OS, and Propellor could be used to install not just Debian or Ubuntu, but whatever Linux distribution you want. Patches welcomed...

Iustin Pop: Jump!

Jump!!! What Why At the end of November, we had a team offsite planned, with lots of fun and exciting activities in a somewhat exotic location. I was quite looking forward to it, when - less than two weeks before the event - a colleague asked if anyone is interested in going skydiving as an extra activity. Without thinking too much, I said "yes" immediately, because: a) I've never done it before, and b) it sounded really cool! Other people said yes as well, so we were set up to have a really good time! Of course, as the time counted down and we were approaching the offsite, I was thinking: OK, this sounds cool, but: will I be fine? do I have altitude sickness? All kinds of such, rather logistical, questions. In order to not think too much, I did exactly zero research on the topic (all mentions of Wikipedia above are from post-fact reading). So, we went on the offsite - which was itself cool - and then, on the last day, right before going back, the skydive event! How it went The weather on the day of the jump was nice, the sky not perfectly clear, just a bit of small clouds and some haze. We waited for our turn, got the instruction for what to do (and not to do!), got hooked into the harness, prepared everything, and then boarded the plane; it needed only a very short run before taking off the ground. It took around ten minutes or so to get to the jump altitude, which I spent partially looking forward to it, partially trying to calm the various emotions I had - a very interesting mix. It was actually annoying just having to wait and wait the ten long minutes, I wished that we actually get to the jumping altitude faster. The altimeter on the instructor's hand was showing 4'000, then 4'100, 4'150, then he reminded me again what I need to do (or rather, not to do), and then - people were already jumping from the plane! I was third from our team to jump, and I had the opportunity to see how people were not simply "exiting" the plane, but rather - exiting and then immediately disappearing from view! Finally we were on the edge of the door, a push and then - I'm looking down, more than two and a half miles of nothing between me and the ground. Just air and the thought - "Why did I do this"? - as I start falling. For the first around ten seconds, it's actually a free fall, gaining speed almost at standard acceleration, and the result - Weightlessness - it's the weirdest feeling ever: all your organs floating in your body, no compression or torsion forces. Much more weird a roller-coaster that never ends; then most I had on roller-coasters was around one second of such acceleration, and you still are in contact with the chair or the restraints, whereas this long fall was very confusing for my brain - it felt somewhat like when you're tripping and you need to do something to regain balance, except in sky-diving you can't do anything, of course. There's nothing to grab, nothing to hold on, and you keep falling. After ten long seconds we reached terminal velocity, phase 1 ends, and phase 2 begins, in which - while still falling - the friction with the air compensates exactly the earth's pull and one is falling at a constant speed and it's the most wonderful state ever. Like floating on the air, except that you're actually falling at almost 200kph, and yes, the closest feeling to flying, I guess. It doesn't hurt that you're no longer weightless, which means back to some level of normality. The location of the skydive was very beautiful: the blue ocean beneath, the blue sky above, somewhere to the side the beach, and the air filling the mouth and lungs without any effort is the only sign that I'm moving really fast. The way this whole thing feels is very alien if you never jumped before, but one gets accustomed to it quite fast - and that means I got too comfortable and excited and forgot the correct position to keep my legs in, the instructor reminded me, and as I put my legs back in the correct position, which is (among others) with the soles of the feet pointing up, I felt again the air going strongly into my shoes, and a thought crossed my mind: what if I the air blows off one of my shoes (the right one, more precisely) and I lose it? How do I get to the airport for the trip back? Will I look suspicious at the security check? The banality of this thought, given that I was still up in the air somewhere and travelling quite fast, was so comical that I started laughing And then, an unexpected noise, the chute opens, and I feel like someone is pulling me strongly up. Of course nobody is pulling "up", I'm just slowing down very fast on this final phase (Wikipedia says: 3 to 4g). And then, once at the new terminal velocity, the lack of wind noise and the quietness of everything around gives a different kind of awesome - more majestic and serene this time, rather than the adrenaline-filled moments before. Because one is still up and the beach looks small, you actually feel that you're suspended in the air, almost frozen. Of course, that feeling goes away quickly when the instructor start telling me to pull the strings, and we enter a fast spin - so fast that my body is almost horizontal again - a reminder that we're still in the air, going somewhat fast, and not in "normal" conditions. I'm again reminded of the speed once we get closer to the earth, the people on the beach start to get bigger fast, and now we're gliding over the beach and finally land in the sand. The adventure is over, but I'm still pumped up and my body is still full of adrenaline, and I feel like you've just been in heaven - which is true, for some definitions of . The first thing I realise is that the earth is very solid. And not moving at all. Everything is very very slow which is both good and bad. My body is confused at the very fast sequence of events, and why did everything stop?? Conclusion I learned all about the terminal velocity, how fast you get there, and so on a day later, from Wikipedia and other sources. It helped explain and clarify the things I experienced during the dive, because there in the air I was quite confused (and my body even more so). Knowing this in advance would have spoiled the surprise, but on the other hand would have allowed me to enjoy the experience slightly better. Looking back, I can say a few of things. First, it was really awesome - not what I was expecting, much more awesome (in the real sense of awe) than I thought, but also not as easy or trivial as I believed from just seeing videos of people "floating" during their dive. Yep, worth doing, and hard to actually put in words (I tried to, but I think this rambling is more confusing than helping). Phase one was too long (and a bit scary), phase two was too short (and the best thing), phase three was relaxing (and just the right length). I also wonder how it is to jump alone - without the complicated and heavy harness, without an instructor, just you up there. Oh, and the parachute. And the reserve parachute , of course. Point is, this was awesome, but I was mostly a passive spectator, so I wonder what it feels like to be actually in control (as much as one can be, falling down) and responsible. And finally, as we left the offsite location just a couple of hours after the skydive, and we had a 4 hours flight back, I couldn't believe myself how slow everything was. I never experienced quite such a thing, I was sitting in this normal airplane flying high and fast, but for me everything was going in slow motion and I was bored out of my mind. Adrenaline aftershock or something like that? Also interesting!

4 December 2014

Chris Lamb: Don't ask your questions in private

(If I've linked you to this page, it is my feeble attempt to provide a more convincing justification.)


I often receive instant messages or emails requesting help or guidance at work or on one of my various programming projects. When asked why they asked privately, the responses vary; mostly along the lines of it simply being an accident, not knowing where else to ask, as well as not wishing to "disturb" others with their bespoke question. Some will be more candid and simply admit that they were afraid of looking unknowledgable in front of others. It is always tempting to simply reply with the answer, especially as helping another human is inherently rewarding unless one is a psychopath. However, one can actually do more good overall by insisting the the question is re-asked in a more public forum.
This is for many reasons. Most obviously, public questions are simply far more efficient as soon as more than one person asks that question the response can be found in a search engine or linked to in the future. These time savings soon add up, meaning that simply more stuff can be done in any given day. After all, most questions are not as unique as people think. Secondly, a private communication cannot be corrected or elaborated on if someone else notices it is incorrect or incomplete. Even this rather banal point is more subtle that it first appears the lack of possible corrections deprives both the person asking and the person responding of the true and correct answer. Lastly, conversations that happen in private are depriving others of the answer as well. Perhaps someone was curious but hadn't got around to asking? Maybe the answer or even the question! contains a clue to solving some other issue. None of this can happen if this is occurs behind closed doors. (There are lots of subtler reasons too in a large organisation or team, simply knowing what other people are curious about can be curiously valuable information.)
Note that this is not as you might immediately suspect simply a way of ensuring that one gets the public recognition or "kudos" from being seen helping others. I wouldn't deny that technical communities work on a gift economy basis to some degree, but to attribute all acts of assistance as "selfish" and value-extracting would be to take the argument too far in the other direction. Saying that, the lure and appeal of public recognition should not be understated and can certainly provide an incentive to elaborate and provide a generally superior response.

More philosophically, there's also something fundamentally "honest" about airing issues in an appropriately public and transparent manner. I feel it promotes a culture of egoless conversations, of being able to admit one's mistakes and ultimately a healthy personal mindset. So please, take care not only in the way you phrase and frame your question, but also consider wider context in which you are asking it. And don't take it too personally if I ask you to re-ask elsewhere...

3 December 2014

Holger Levsen: 20141201-lts-november-2014

My LTS November In November I resumed work on Debian LTS and worked on the following packages: Thanks to everyone who is supporting Squeeze LTS in whatever form, according to the wide feedback there are quite many people appreciating the work! (As this was asked on IRC: if you are a maintainer preparing something for squeeze-lts, that's totally great, thanks!, just please tell us about it as this is the assumption we are working under: if noone tells the LTS team, we think we need to prepare upgrades for squeeze-lts.)

Diego Escalante Urrelo: Link pack #01

Following the lead of my dear friend Daniel and his fantastic and addictive Summing up series, here s a link pack of recent stuff I read around the web. Link pack is definitely a terrible name, but I m working on it.
How to Silence Negative Thinking
On how to avoid the pitfall of being a Negatron and not an Optimist Prime. You might be your own worst enemy and you might not even know it:
Psychologists use the term automatic negative thoughts to describe the ideas that pop into our heads uninvited, like burglars, and leave behind a mess of uncomfortable emotions. In the 1960s, one of the founders of cognitive therapy, Aaron Beck, concluded that ANTs sabotage our best self, and lead to a vicious circle of misery: creating a general mindset that is variously unhappy or anxious or angry (take your pick) and which is (therefore) all the more likely to generate new ANTs. We get stuck in the same old neural pathways, having the same negative thoughts again and again.
Meet Harlem s Official Street Photographer
A man goes around Harlem with his camera, looking to give instead of taking. Makes you think about your approach to people and photography, things can be simpler. Kinda like Humans of New York, but in Harlem. And grittier, and on film but as touching, or more:
I tell people that my camera is a healing mechanism, Allah says. Let me photograph it and take it away from you.
What Happens When We Let Industry and Government Collect All the Data They Want
Why having nothing to hide is not about the now, but about the later. It s not that someone is going to judge for pushing every detail of your life to Twitter and Instagram, it s just that something you do might be illegal a few years later:
There was a time when it was essentially illegal to be gay. There was a time when it was legal to own people and illegal for them to run away. Sometimes, society gets it wrong. And it s not just nameless bureaucrats; it s men like Thomas Jefferson. When that happens, strong privacy protections including collection controls that let people pick who gets their data, and when allow the persecuted and unpopular to survive.
The Sex-Abuse Scandal Plaguing USA Swimming
Abusive coaches and a bullying culture in sports training are the perfect storm for damaging children. And it s amazing the extent to which a corporation or institution is willing to look the other way, as long as they save face. Very long piece, but intriguing to read. What Cities Would Look Like if Lit Only by the Stars
Thierry Cohen goes around the world and builds beautiful and realistic composite images of how would big cities look like if lit only by stars. The original page has some more cities: Villes teintes (Darkened Cities). On Muppets & Merchandise: How Jim Henson Turned His Art into a Business
Lessons from how Jim Henson managed to juggle both art and business without selling out for the wrong reasons. Really interesting, and reminds you to put Henson in perspective as a very smart man who managed to convince everyone to give him money for playing with muppets. The linked video on How the Muppet Show is Made is also cool. Made me curious enough to get the book. Barbie, Remixed: I (really!) can be a computer engineer
Mattel launched the most misguided book about empowering Barbie to be anything but a computer engineer in a book about being a computer engineer. The internet did not disappoint and fixed the problem within hours. There s now even an app for that (includes user submitted pages).

2 December 2014

Matthias Klumpp: How to build a cross-distro package with Limba

Disclaimer: Limba is stilllimba-small in a very early stage of development. Bugs happen, and I give to guarantees on API stability yet. Limba is a very simple cross-distro package installer, utilizing OverlayFS found in recent Linux kernels (>= 3.18). As example I created a small Limba package for one of the Qt5 demo applications, and I would like to share the process of creating Limba packages it s quite simple, and I could use some feedback on how well the resulting packages work on multiple distributions. I assume that you have compiled Limba and installed it how that is done is described in its README file. So, let s start. 1. Prepare your application The cool thing about Limba is that you don t really have to do many changes on your application. There are a few things to pay attention to, though: This needs to be done so your application will find its data at runtime. Additionally, you need to write an AppStream metadata file, and find out which stuff your application depends on. 2. Create package metadata & install software 1.1 Basics Now you can create the metadata necessary to build a Limba package. Just run
cd /path/to/my/project
lipkgen make-template
This will create a pkginstall directory, containing a control file and a metainfo.xml file, which can be a symlink to the AppStream metadata, or be new metadata. Now, configure your application with /opt/bundle as install prefix (-DCMAKE_INSTALL_PREFIX=/opt/bundle, prefix=/opt/bundle, etc.) and install it to the pkginstall/inst_target directory. 1.2 Handling dependencies If your software has dependencies on other packages, just get the Limba packages for these dependencies, or build new ones. Then place the resulting IPK packages in the pkginstall/repo directory. Ideally, you should be able to fetch Limba packages which contain the software components directly from their upstream developers. Then, open the pkginstall/control file and adjust the Requires line. The names of the components you depend on match their AppStream-IDs (<id/> tag in the AppStream XML document). Any version-relation (>=, >>, <<, <=, <>) is supported, and specified in brackets after the component-id. The resulting control-file might look like this:
Format-Version: 1.0

Requires: Qt5Core (>= 5.3), Qt5DBus (>= 5.3), libpng12
If the specified dependencies are in the repo/ subdirectory, these packages will get installed automatically, if your application package is installed. Otherwise, Limba depends on the user to install these packages manually there is no interaction with the distribution s package-manager (yet?). 3. Building the package In order to build your package, make sure the content in inst_target/ is up to date, then run
lipkgen build pkginstall/
This will build your package and output it in the pkginstall/ directory. 4. Testing the package You can now test your package, Just run
sudo lipa install package.ipk
Your software should install successfully. If you provided a .desktop file in $prefix/share/applications, you should find your application in your desktop s application-menu. Otherwise, you can run a binary from the command-line, just append the version of your package to the binary name (bash-comletion helps). Alternatively, you can use the runapp command, which lets you run any binary in your bundle/package, which is quite helpful for debugging (since the environment a Limba-installed application is run is different from the one of other applications). Example:
runapp $ component_id -$ version :/bin/binary-name
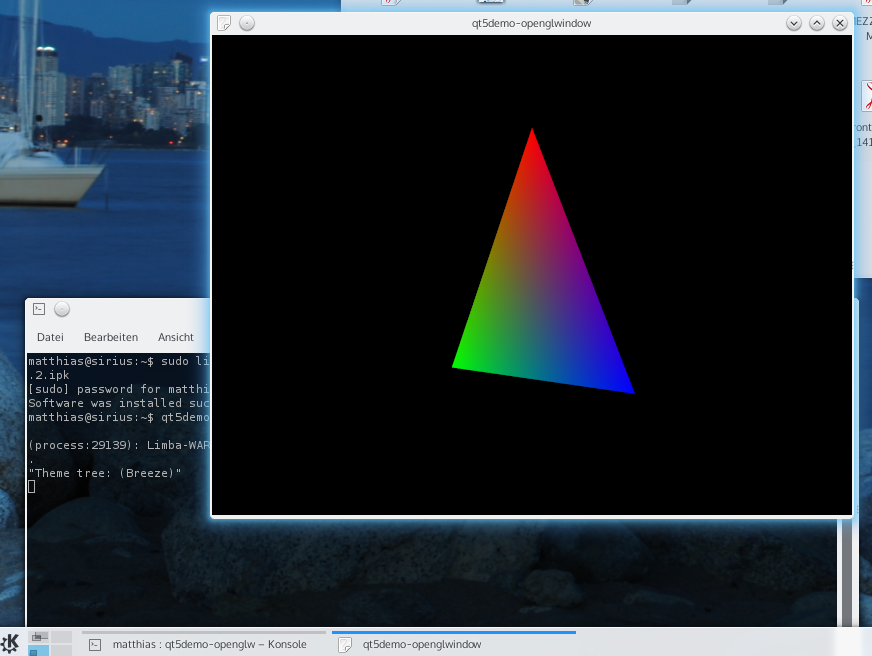
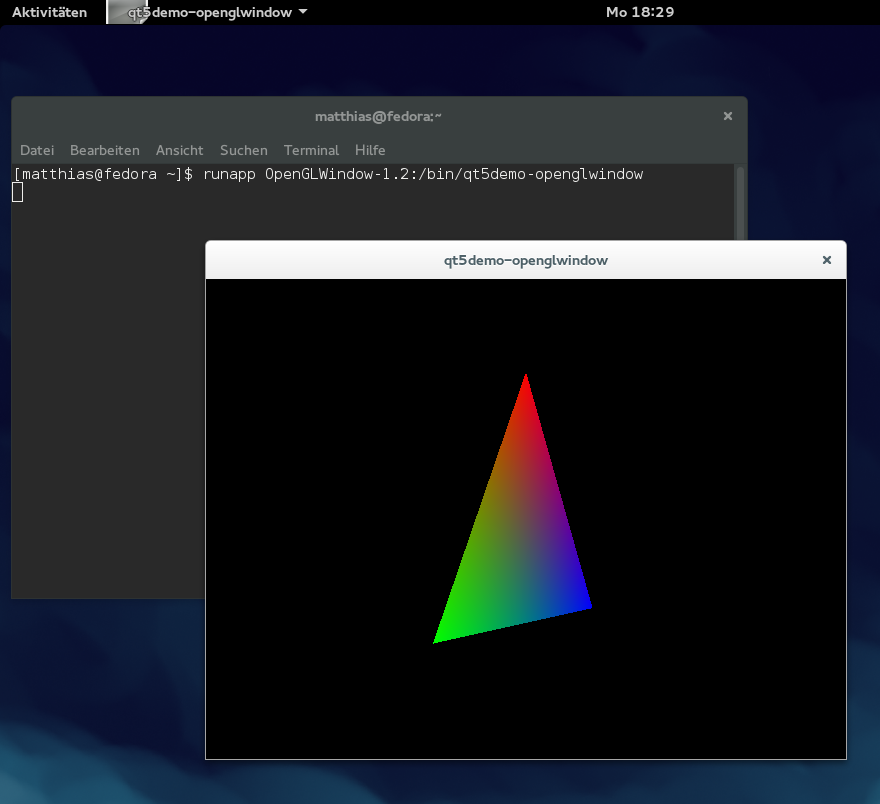
And that s it! :-) I used these steps to create a Limba package for the OpenGL Qt5 demo on Tanglu 2 (Bartholomea), and tested it on Kubuntu 15.04 (Vivid) with KDE, as well as on an up-to-date Fedora 21, with GNOME and without any Qt or KDE stuff installed: qt5demo-limba-kubuntuqt5demo-limba-fedora I encountered a few obstacles when building the packages, e.g. Qt5 initially didn t find the right QPA plugin that has been fixed by adjusting a config file in the Qt5Gui package. Also, on Fedora, a matching libpng was missing, so I included that as well. You can find the packages at Github, currently (but I am planning to move them to a different place soon). The biggest issue with Limba is at time, that it needs Linux 3.18, or an older kernel with OverlayFS support compiled in. Apart from that and a few bugs, the experience is quite smooth. As soon as I am sure there are now hidden fundamental issues, I can think of implementing more features, like signing packages and automatically updating them. Have fun playing around with Limba!

DebConf team: Sponsors for DebConf15 (Posted by Laura Arjona Reina)

The Debian project recently welcomed the first nine sponsors for Debconf15: credativ and sipgate as Gold sponsors, Google, Farsight Security, Inc., Martin Alfke / Buero 2.0 and Ubuntu as silver sponsors, and Logilab, Netways and Hetzner as Bronze-level. But things have kept moving! The Matanel Foundation just committed to support DebConf15 as Gold-level sponsor, and Mirantis as Silver-level. So, at the time of writing this, we have 11 sponsors. We are very thankful for that! The DebConf team aims to organize the Debian Conference as a self-sustaining event, despite its size and complexity (the Final Report for DebConf14 gives a good indication). The financial contributions by individuals, companies and organizations, as well as the support by our infrastructure sponsors, media partners, and volunteers, are pivotal to our success. There are many different possibilities to support DebConf. If you know any company or organization that could be interested, don t hesitate to point them at our sponsorship brochure (also available in German) or tell us about any leads.

Peter Eisentraut: ccache and clang, part 3

In part 1 and part 2 I investigated how to use ccache with clang. That was more than three years ago. I got an email the other day that ccache bug 8118, which I filed while writing part 1, was closed, as ccache 3.2 was released. The release notes of clang 3.2 contain several items related to clang. So it was time to give this another look. Basically, the conclusions from part 2 still stand: You cannot use ccache with clang without using CCACHE_CPP2. And it is now becoming clear to me that this is an issue that is not going to go away, and it s not really even Clang s fault. Warnings! The problem is that clang s -Wall can cause warnings when compiling the preprocessed version of otherwise harmless C code. This can be illustrated by this piece of C code:
int
foo()
 
        int *p, *q;
        p = q = 0;
        p = p;
        if (p == p)
                return 1;
        if ((p == q))
                return 2;
        return 0;
 
When compiled by gcc-4.9 -Wall, this gives no warnings. When compiled by clang-3.5 -Wall, this results in test.c:7:4: warning: explicitly assigning value of variable of type 'int *' to itself [-Wself-assign] test.c:8:8: warning: self-comparison always evaluates to true [-Wtautological-compare] test.c:10:9: warning: equality comparison with extraneous parentheses [-Wparentheses-equality] test.c:10:9: note: remove extraneous parentheses around the comparison to silence this warning test1.c:10:9: note: use '=' to turn this equality comparison into an assignment You wouldn t normally write code like this, but the C preprocessor could create code with self-assignments, self-comparisons, extra parentheses, and so on. This example represents the issues I saw when trying to compile PostgreSQL 9.4 with ccache and clang; there might be others. You can address this issue in two ways:
  1. Use CCACHE_CPP2, as discussed in part 2. With ccache 3.2, you can now also put this into a configuration file: run_second_cpp = true in ~/.ccache/ccache.conf
  2. Turn off the warnings mentioned above: -Wno-parentheses-equality, -Wno-tautological-compare, -Wno-self-assign (and any others you might find). One might think that these are actually useful warnings that one might want to keep, but GCC doesn t warn about them, and if you develop primarily with GCC, your code might contain these issues anyway. In particular, I have found that -Wno-tautological-compare is necessary for legitimate code.
I think CCACHE_CPP2 is the way to go, for two reasons. Firstly, having to add more and more options to turn off warnings is obviously somewhat stupid. Secondly and more importantly, there is nothing stopping GCC from adding warnings similar to Clang s that would trigger on preprocessed versions of otherwise harmless C code. Unless they come up with a clever way to annotate the preprocessed code to the effect of this code might look wrong to you, but it looked OK before preprocessing, so don t warn about it , in a way that creates no extra warnings and doesn t lose any warnings, I don t think this issue can be solved. Speed! Now the question is, how much would globally setting CCACHE_CPP2 slow things down? To test this, I have built PostgreSQL 9.4rc1 with clang-3.5 and gcc-4.8 (not gcc-4.9 because it creates some unrelated warnings that I don t want to deal with here). I have set export CCACHE_RECACHE=true so that the cache is not read but new cache entries are computed. That way, the overhead of ccache on top of the compiler is measured. Results: (There different percentages between gcc and clang arise because gcc is faster than clang (yes, really, more on that in a future post), but the overhead of ccache doesn t change.) 10% or so is not to be dismissed, but let s remember that this applies only if there is a cache miss. If everything is cached, both methods do the same thing. Also, if you use parallel make, the overhead is divided by the number of parallel jobs. With that in mind, I have decided to put the issue to rest for myself and have made myself a ~/.ccache/ccache.conf containing
run_second_cpp = true
Now Clang or any other compiler should run without problems through ccache. Color! There is one more piece of news in the new ccache release: Another thing I talked about in part 1 was that ccache will disable the colored output of clang, and I suggested workarounds. This was actually fixed in ccache 3.2, so the workarounds are no longer necessary, and the above configuration change is really the only thing to make Clang work smoothly with ccache.

Martin-&#201;ric Racine: GNOME is destroying the whole GTK universe

When GNOME 3.14 components were uploaded into Debian (just a few days before the Jessie freeze started), GNOME stopped working on two video platforms: Geode (xf86-video-geode) and NVIDIA (xf86-video-nouveau). On Geode, GDM launches into a black screen. On NVIDIA, GDM launches as expected, but then the GNOME session itself barfs with the dreaded "Oh No! Something went wrong. [Logout]" dialog during session initialization. Basically, components in GNOME have become too tightly dependent upon some video driver features. Thinking out loud, I figured that reverting to a desktop environment that is based upon GTK+3, without GNOME's bells and whistles, would at least restore operation on my NVDIA hosts. Alas, it does not: Cinnamon, too, barfs during session initialization. Great. Now what?

1 December 2014

Joey Hess: snowdrift - sustainable crowdfunding for free software development

In a recent blog post, I mentioned how lucky I feel to keep finding ways to work on free software. In the past couple years, I've had a successful Kickstarter, and followed that up with a second crowdfunding campaign, and now a grant is funding my work. A lot to be thankful for. A one-off crowdfunding campaign to fund free software development is wonderful, if you can pull it off. It can start a new project, or kick an existing one into a higher gear. But in many ways, free software development is a poor match for kickstarter-type crowdfunding. Especially when it comes to ongoing development, which it's really hard to do a crowdfunding pitch for. That's why I was excited to find Snowdrift.coop, which has a unique approach. Imagine going to a web page for a free software project that you care about, and seeing this button: 1283 patrons will donate MORE when you pledge That's a lot stronger incentive than some paypal donation button or flattr link! The details of how it works are explained on their intro page, or see the ever-insightful and thoughtful Mike Linksvayer's blog post about it. When I found out about this, I immediately sent them a one-off donation. Later, I got to meet one of the developers face to face in Portland. I've also done a small amount of work on the Snowdrift platform, which is itself free software. (My haskell code will actually render that button above!) Free software is important, and its funding should be based, not on how lucky or good we are at kickstarter pitches, but on its quality and how useful it is to everyone. Snowdrift is the most interesting thing I've seen in this space, and I really hope they succeed. If you agree, they're running their own crowdfunding campaign right now.

30 November 2014

Gregor Herrmann: RC bugs 2014/47-48

these are the RC bugs I've worked on during the last two weeks:

Enrico Zini: cxx11-talk-notes

C++11 talk notes On 2014-11-27 I gave a talk about C++ and new features introduced with C++11: these are the talk notes. See cxx11-talk-examples for the examples. (note: I had to add U+2063 INVISIBLE SEPARATOR to prevent noreturn statements to be misinterpreted by the blog formatter. If you copypaste the code and encounter issues, you may want to delete the noreturn statements and retype them) Overview of programming languages
It has to be as fast as possible, so interpreted languages are out. You don't want to micro manage memory, so C is out. You don't want to require programmers to have a degree, so C++ is out. You want fast startup and not depend on a big runtime, so Java is out. [...] (Bram Moolenaar)
C++ secret cultist protip
Do not call up what you cannot put down.
C++ is a compiled language It is now possible to use the keyword constexpr to mark functions and objects that can be used at compile time:
/*
 * constexpr tells the compiler that a variable or function can be evaluated at
 * compile time.
 *
 * constexpr functions can also be run at run time, if they are called with
 * values not known at compile time.
 *
 * See http://en.cppreference.com/w/cpp/language/constexpr for more nice examples
 *
 * It can be used to avoid using constants in code, and using instead functions
 * for computing hardware bitfields or physical values, without losing in
 * efficiency.
 */
#include <iostream>
using namespace std;
constexpr int factorial(int n)
 
    return n <= 1 ? 1 : (n * factorial(n-1));
 
int main()
 
    cout << "Compile time factorial of 6: " << factorial(6) << endl;
    cout << "Enter a number: ";
    int a;
    cin >> a;
    cout << "Run time factorial of " << a << ": " << factorial(a) << endl;
 
See also this for more nice examples. See this and this for further discussion. Multiline strings
        const char* code = R"--(
          printf("foo\tbar\n");
          return 0;
        )--";
See this. C++ memory management protip RAII: Resource Acquisition Is Instantiation This is not new in C++11, but in my experience I have rarely seen it mentioned in C++ learning material, and it does make a huge difference in my code. See this and this for details. Constructors and member initializer lists Initializers in curly braces now have their own type: std::initializer_list:
#include <string>
#include <iostream>
#include <unordered_set>
using namespace std;
// std::initializer_list< >
//   will have as its value all the elements inside the curly braces
string join(initializer_list<string> strings)
 
    string res;
    for (auto str: strings)
     
        if (!res.empty())
            res += ", ";
        res += str;
     
    return res;
 
int main()
 
    unordered_set<string> blacklist  ".", "..", ".git", ".gitignore"  ;
    cout << join(  "antani", "blinda"  ) << endl;
 
See this for details, including the new uniform initialization trick of omitting parentesis in constructors so that you can call normal constructors and initializer_list constructors with the same syntax, which looks like an interesting thing when writing generic code in templates. Type inference I can now use auto instead of a type to let the compiler automatically compute the value of something I assign to:
        auto i = 3 + 2;
        // See also https://github.com/esseks/monicelli
        vector<string> names  "antani", "blinda", "supercazzola"  ;
        for (auto i = names.cbegin(); i != names.cend(); ++i)
            cout << i;
        template<typename T>
        T frobble(const T& stuff)
         
             // This will work whatever type is returned by stuff.read()
             auto i = stuff.read();
             //  
         
See this for more details. Range-based for loop C++ now has an equivalent of the various foreach constructs found in several interpreted languages!
        for (auto i: list_of_stuff)
                cout << i << endl;
        for (auto n:  0,1,2,3,4,5 )
                cout << n << endl;
        // This construct:
        for (auto i: stuff)
        // If stuff is an array, it becomes:
        for (i = stuff, i < stuff + sizeof(stuff) / sizeof(stuff[0]); ++i)
        // If stuff has .begin() and .end() methods it becomes:
        for (i = stuff.begin(); i != stuff.end(); ++i)
        // Otherwise it becomes:
        for (i = begin(stuff); i != end(stuff); ++i)
        // And you can define begin() and end() functions for any type you
        // want, at any time
See this and this for details. Lambda functions and expressions Lambdas! Closures! Something like this:
// JavaScript
var add = function(a, b)   return a + b;  
# Python
add = lambda a, b: a + b
Becomes this:
auto add = [](int a, int b)   return a + b;  
And something like this:
// JavaScript
var a = 0;
$.each([1, 2, 3, 4], function(idx, el)   a += el  );
Becomes this:
unsigned a = 0;
std::for_each(  1, 2, 3, 4  , [&a](int el)   return a += el;  );
See this, this and this. Tuple types C++ now has a std::tuple type, that like in Python can be used to implement functions that return multiple values:
        tuple<int, string, vector<string>> parse_stuff()
         
                return make_tuple(id, name, values);
         
        string name; vector<string> values;
        // std::ignore can be used to throw away a result
        tie(ignore, name, values) = parse_stuff();
        // std::tie can also be used to do other kind of
        // multi-operations besides assignment:
        return tie(a, b, c) < tie(a1, b1, c1);
        // Is the same as:
        if (a != a1) return a < a1;
        if (b != b1) return b < b1;
        return c < c1;
See here, here and here. Regular expressions We now have regular expressions!
        std::regex re(R"((\w+)\s+(\w+))");
        string s("antani blinda");
        smatch res;
        if (regex_match(s, res, re))
            cout << "OK " << res[1] << " -- " << res[2] << endl;
The syntax is ECMAScript by default and can be optionally changed to basic, extended, awk, grep, or egrep. See here and here. General-purpose smart pointers There is std::unique_ptr to code memory ownership explicitly, and std::shared_ptr as a reference counted pointer, and smart pointers can have custom destructors:
    unique_ptr<dirent, std::function<void(void*)>> dirbuf((dirent*)malloc(len), free);
See here and here. Miscellaneous other cool things Standard attribute specifiers
string errno_str(int error)
 
    char buf[256];
#if (_POSIX_C_SOURCE >= 200112L   _XOPEN_SOURCE >= 600) && ! _GNU_SOURCE
    strerror_r(errno, buf, 256);
    string res(buf);
#else
    string res(strerror_r(errno, buf, 256));
#endif
    return res;
 
[ [noreturn]] void throw_libc_error(int error)
 
    throw runtime_error(errno_str(error));
 
See here. Hash tables See here and look at the new containers unordered_set, unordered_map, unordered_multiset, and unordered_multimap. Multithreading There is a standard threading model, with quite a bit of library support: see here, here, here, and here for atomic data structures. Variadic templates Templates can now take variable number of arguments, and that opens possibilities for interesting code generation, like implementing a generic, type-safe printf statement, or something like this:
db.query(R"(
   INSERT INTO table NAMES (id, name, description)
     VALUES (?, ?, ?)
)", 4, "genio", "fantasia, intuizione, decisione, e velocit  di esecuzione");
See here and here. Essential tools You need at least g++ 4.8 or clang 3.3 to have full C++11 support. They will be both available in jessie, and for wheezy you can use the nightly clang packages repository. I cannot think of a good excuse not to use -Wall on new code. scan-build from clang is another nice resource for catching even more potential problems at compile time. valgrind is a great tool for runtime code analysis: valgrind --tool=memcheck (the default) will check your program for wrong memory accesses and memory leaks. valgrind --tool=callgrind will trace function calls for profiling, to be analyzed with kcachegrind. valgrind --tool=helgrind can check multi-threaded programs for suspicious concurrent memory accesse patterns. And of course gdb: a nice trick with C++ is to issue catch throw to get a breakpoint at the point where an exception is being thrown. help catch provides a list of other interesting catch examples. Coredump tips: ulimit -c to enable core dumps, triggering a core dump with ^\, opening a core with gdb program core, and more details on man 5 core. An extra gdb tip, which is not related to C++ but helped me considerably recently, is that it can be attached to running python programs to get a live Python traceback.

Johannes Schauer: simple email setup

I was unable to find a good place that describes how to create a simple self-hosted email setup. The most surprising discovery was, how much already works after:
apt-get install postfix dovecot-imapd
Right after having finished the installation I was able to receive email (but only in in /var/mail in mbox format) and send email (bot not from any other host). So while I expected a pretty complex setup, it turned out to boil down to just adjusting some configuration parameters.

Postfix The two interesting files to configure postfix are /etc/postfix/main.cf and /etc/postfix/master.cf. A commented version of the former exists in /usr/share/postfix/main.cf.dist. Alternatively, there is the ~600k word strong man page postconf(5). The latter file is documented in master(5).

/etc/postfix/main.cf I changed the following in my main.cf
@@ -37,3 +37,9 @@
mailbox_size_limit = 0
recipient_delimiter = +
inet_interfaces = all
+
+home_mailbox = Mail/
+smtpd_recipient_restrictions = permit_mynetworks reject_unauth_destination permit_sasl_authenticated
+smtpd_sasl_type = dovecot
+smtpd_sasl_path = private/auth
+smtp_helo_name = my.reverse.dns.name.com
At this point, also make sure that the parameters smtpd_tls_cert_file and smtpd_tls_key_file point to the right certificate and private key file. So either change these values or replace the content of /etc/ssl/certs/ssl-cert-snakeoil.pem and /etc/ssl/private/ssl-cert-snakeoil.key. The home_mailbox parameter sets the default path for incoming mail. Since there is no leading slash, this puts mail into $HOME/Mail for each user. The trailing slash is important as it specifies qmail-style delivery'' which means maildir. The default of the smtpd_recipient_restrictions parameter is permit_mynetworks reject_unauth_destination so this just adds the permit_sasl_authenticated option. This is necessary to allow users to send email when they successfully verified their login through dovecot. The dovecot login verification is activated through the smtpd_sasl_type and smtpd_sasl_path parameters. I found it necessary to set the smtp_helo_name parameter to the reverse DNS of my server. This was necessary because many other email servers would only accept email from a server with a valid reverse DNS entry. My hosting provider charges USD 7.50 per month to change the default reverse DNS name, so the easy solution is, to instead just adjust the name announced in the SMTP helo.

/etc/postfix/master.cf The file master.cf is used to enable the submission service. The following diff just removes the comment character from the appropriate section.
@@ -13,12 +13,12 @@
#smtpd pass - - - - - smtpd
#dnsblog unix - - - - 0 dnsblog
#tlsproxy unix - - - - 0 tlsproxy
-#submission inet n - - - - smtpd
-# -o syslog_name=postfix/submission
-# -o smtpd_tls_security_level=encrypt
-# -o smtpd_sasl_auth_enable=yes
-# -o smtpd_client_restrictions=permit_sasl_authenticated,reject
-# -o milter_macro_daemon_name=ORIGINATING
+submission inet n - - - - smtpd
+ -o syslog_name=postfix/submission
+ -o smtpd_tls_security_level=encrypt
+ -o smtpd_sasl_auth_enable=yes
+ -o smtpd_client_restrictions=permit_sasl_authenticated,reject
+ -o milter_macro_daemon_name=ORIGINATING
#smtps inet n - - - - smtpd
# -o syslog_name=postfix/smtps
# -o smtpd_tls_wrappermode=yes

Dovecot Since above configuration changes made postfix store email in a different location and format than the default, dovecot has to be informed about these changes as well. This is done in /etc/dovecot/conf.d/10-mail.conf. The second configuration change enables postfix to authenticate users through dovecot in /etc/dovecot/conf.d/10-master.conf. For SSL one should look into /etc/dovecot/conf.d/10-ssl.conf and either adapt the parameters ssl_cert and ssl_key or store the correct certificate and private key in /etc/dovecot/dovecot.pem and /etc/dovecot/private/dovecot.pem, respectively. The dovecot-core package (which dovecot-imapd depends on) ships tons of documentation. The file /usr/share/doc/dovecot-core/dovecot/documentation.txt.gz gives an overview of what resources are available. The path /usr/share/doc/dovecot-core/dovecot/wiki contains a snapshot of the dovecot wiki at http://wiki2.dovecot.org/. The example configurations seem to be the same files as in /etc/ which are already well commented.

/etc/dovecot/conf.d/10-mail.conf The following diff changes the default email location in /var/mail to a maildir in ~/Mail as configured for postfix above.
@@ -27,7 +27,7 @@
#
# <doc/wiki/MailLocation.txt>
#
-mail_location = mbox:~/mail:INBOX=/var/mail/%u
+mail_location = maildir:~/Mail

# If you need to set multiple mailbox locations or want to change default
# namespace settings, you can do it by defining namespace sections.

/etc/dovecot/conf.d/10-master.conf And this enables the authentication socket for postfix:
@@ -93,9 +93,11 @@


# Postfix smtp-auth
- #unix_listener /var/spool/postfix/private/auth
- # mode = 0666
- #
+ unix_listener /var/spool/postfix/private/auth
+ mode = 0660
+ user = postfix
+ group = postfix
+

# Auth process is run as this user.
#user = $default_internal_user

Aliases Now Email will automatically put into the '~/Mail' directory of the receiver. So a user has to be created for whom one wants to receive mail...
$ adduser josch
...and any aliases for it to be configured in /etc/aliases.
@@ -1,2 +1,4 @@
-# See man 5 aliases for format
-postmaster: root
+root: josch
+postmaster: josch
+hostmaster: josch
+webmaster: josch
After editing /etc/aliases, the command
$ newaliases
has to be run. More can be read in the aliases(5) man page.

Finishing up Everything is done and now postfix and dovecot have to be informed about the changes. There are many ways to do that. Either restart the services, reboot or just do:
$ postfix reload
$ doveadm reload
Have fun!

28 November 2014

Richard Hartmann: Release Critical Bug report for Week 48

Holy bug-count-drop, Batman! Some bugs which need loving: The UDD bugs interface currently knows about the following release critical bugs: How do we compare to the Squeeze release cycle?
Week Squeeze Wheezy Jessie
43 284 (213+71) 468 (332+136) 319 (240+79)
44 261 (201+60) 408 (265+143) 274 (224+50)
45 261 (205+56) 425 (291+134) 295 (229+66)
46 271 (200+71) 401 (258+143) 427 (313+114)
47 283 (209+74) 366 (221+145) 342 (260+82)
48 256 (177+79) 378 (230+148) 274 (189+85)
49 256 (180+76) 360 (216+155)
50 204 (148+56) 339 (195+144)
51 178 (124+54) 323 (190+133)
52 115 (78+37) 289 (190+99)
1 93 (60+33) 287 (171+116)
2 82 (46+36) 271 (162+109)
3 25 (15+10) 249 (165+84)
4 14 (8+6) 244 (176+68)
5 2 (0+2) 224 (132+92)
6 release! 212 (129+83)
7 release+1 194 (128+66)
8 release+2 206 (144+62)
9 release+3 174 (105+69)
10 release+4 120 (72+48)
11 release+5 115 (74+41)
12 release+6 93 (47+46)
13 release+7 50 (24+26)
14 release+8 51 (32+19)
15 release+9 39 (32+7)
16 release+10 20 (12+8)
17 release+11 24 (19+5)
18 release+12 2 (2+0)
Graphical overview of bug stats thanks to azhag:

Next.

Previous.