Search Results: "ema"

21 February 2013

MJ Ray: In Praise of Consensus

The constitution of the debian operating system project says things like consistent with the consensus of the opinions of the Developers at various points but doesn t say how strong a consensus or how the project will test for consensus. I think those were mistakes, breaking a couple of the conditions for consensus. Wikipedia s understanding of consensus is even worse. Wikipedia seems to treat consensus as a synonym for unanimity. Its testing methods allow an infinite loop to form where the casual observer can t differentiate between a controversial proposal and consensus. I think those were mistakes. These famous-but-imperfect implementations frequently lead to misdirected rants which seem to misunderstand consensus as requiring perpetual bikeshedding. Apache s implementation is rather better and it may surprise you to learn that our co-op is mostly run by consensus. There are two key differences which I feel makes consensus work for us: we ve set limits beforehand on some decisions where we need to act fast where not making a decision would usually be the same as making a bad decision and our methods of testing for consensus are better. We test for consensus with secret-at-vote-time-but-published-after straw polls, or using Crowd Wise by email. I summarise Crowd Wise as follows: gather all ideas plus option 0 (do nothing) if possible, carry out a de Borda (preference) voting round 1, merge/amend/consolidate ideas, voting round 2 if needed. It does still work better if participants put their ego aside a little and co-operate, but it does put limits on non-co-operators. Anyway, as described in Xana/ xana2/ bamamba/ Why Russ is wrong, debian isn t exactly using consensus much at the moment, anyway. Should we try to fix its bugs? Do you know other projects where consensus is working?

20 February 2013

Thorsten Glaser: GNU autotools generated files

On Planet Debian, Vincent Bernat wrote:

The drawback of this approach is that if you rebuild configure from the released tarball, you don t have the git tree and the version will be a date. Just don t do that.

Excuse me This is totally inacceptable. Regenerating files like aclocal.m4 and Makefile.in (for automake), configure (for autoconf), and the likes is one of the absolute duties of a software package. Things will break sooner or later if people do not do that. Additionally, generated files must be remakable from the distfile, so do not break this! May I suggest, constructively, an alternative? (People rightfully, I must admit complain I m just ranting too much.)
When making a release from git, write the git describe output into a file. Then, use that file instead of trying to run the git executable if .git/. is not a directory ( test -d .git/. ). Do not call git, because, in packages, it s either not installed or/and also undesired. Couldn t comment on your blog, but felt strongly enough about this I took the effort of writing a full post of my own. (But thanks for the book recommendation.)

Vincent Bernat: lldpd 0.7.1

A few weeks ago, a new version of lldpd, a 802.1AB (aka LLDP) implementation for various Unices, has been released. LLDP is an industry standard protocol designed to supplant proprietary Link-Layer protocols such as EDP or CDP. The goal of LLDP is to provide an inter-vendor compatible mechanism to deliver Link-Layer notifications to adjacent network devices. In short, LLDP allows you to know exactly on which port is a server (and reciprocally). To illustrate its use, I have made a xkcd-like strip: xkcd-like strip for the use of LLDP If you would like more information about lldpd, please have a look at its new dedicated website. This blog post is an insight of various technical changes that have affected lldpd since its latest major release one year ago. Lots of C stuff ahead!

Version & changelog UPDATED: Guillem Jover told me how he met the same goals for libbsd :
  1. Save the version from git into .dist-version and use this file if it exists. This allows one to rebuild ./configure from the published tarball without losing the version. This also handles Thorsten Glaser s critic.
  2. Include CHANGELOG in DISTCLEANFILES variable.
Since this is a better solution, I have adopted the appropriate line of codes from libbsd. The two following sections are partly technically outdated.

Automated version In configure.ac, I was previously using a static version number that I had to increase when releasing:
AC_INIT([lldpd], [0.5.7], [bernat@luffy.cx])
Since the information is present in the git tree, this seems a bit redundant (and easy to forget). Taking the version from the git tree is easy:
AC_INIT([lldpd],
        [m4_esyscmd_s([git describe --tags --always --match [0-9]* 2> /dev/null   date +%F])],
        [bernat@luffy.cx])
If the head of the git tree is tagged, you get the exact tag (0.7.1 for example). If it is not, you get the nearest one, the number of commits since it and part of the current hash (0.7.1-29-g2909519 for example). The drawback of this approach is that if you rebuild configure from the released tarball, you don t have the git tree and the version will be a date. Just don t do that.

Automated changelog Generating the changelog from git is a common practice. I had some difficulties to make it right. Here is my attempt (I am using automake):
dist_doc_DATA = README.md NEWS ChangeLog
.PHONY: $(distdir)/ChangeLog
dist-hook: $(distdir)/ChangeLog
$(distdir)/ChangeLog:
        $(AM_V_GEN)if test -d $(top_srcdir)/.git; then \
          prev=$$(git describe --tags --always --match [0-9]* 2> /dev/null) ; \
          for tag in $$(git tag   grep -E '^[0-9]+(\.[0-9]+) 1, $$'   sort -rn); do \
            if [ x"$$prev" = x ]; then prev=$$tag ; fi ; \
            if [ x"$$prev" = x"$$tag" ]; then continue; fi ; \
            echo "$$prev [$$(git log $$prev -1 --pretty=format:'%ai')]:" ; \
            echo "" ; \
            git log --pretty=' - [%h] %s (%an)' $$tag..$$prev ; \
            echo "" ; \
            prev=$$tag ; \
          done > $@ ; \
        else \
          touch $@ ; \
        fi
ChangeLog:
        touch $@
Changelog entries are grouped by version. Since it is a bit verbose, I still maintain a NEWS file with important changes.

Core

C99 I have recently read 21st Century C which has some good bits and also handles the ecosystem around C. I have definitively adopted designated initializers in my coding style. Being a GCC extension since a long time, this is not a major compatibility problem. Without designated initializers:
struct netlink_req req;
struct iovec iov;
struct sockaddr_nl peer;
struct msghdr rtnl_msg;
memset(&req, 0, sizeof(req));
memset(&iov, 0, sizeof(iov));
memset(&peer, 0, sizeof(peer));
memset(&rtnl_msg, 0, sizeof(rtnl_msg));
req.hdr.nlmsg_len = NLMSG_LENGTH(sizeof(struct rtgenmsg));
req.hdr.nlmsg_type = RTM_GETLINK;
req.hdr.nlmsg_flags = NLM_F_REQUEST   NLM_F_DUMP;
req.hdr.nlmsg_seq = 1;
req.hdr.nlmsg_pid = getpid();
req.gen.rtgen_family = AF_PACKET;
iov.iov_base = &req;
iov.iov_len = req.hdr.nlmsg_len;
peer.nl_family = AF_NETLINK;
rtnl_msg.msg_iov = &iov;
rtnl_msg.msg_iovlen = 1;
rtnl_msg.msg_name = &peer;
rtnl_msg.msg_namelen = sizeof(struct sockaddr_nl);
With designated initializers:
struct netlink_req req =  
    .hdr =  
        .nlmsg_len = NLMSG_LENGTH(sizeof(struct rtgenmsg)),
        .nlmsg_type = RTM_GETLINK,
        .nlmsg_flags = NLM_F_REQUEST   NLM_F_DUMP,
        .nlmsg_seq = 1,
        .nlmsg_pid = getpid()  ,
    .gen =   .rtgen_family = AF_PACKET  
 ;
struct iovec iov =  
    .iov_base = &req,
    .iov_len = req.hdr.nlmsg_len
 ;
struct sockaddr_nl peer =   .nl_family = AF_NETLINK  ;
struct msghdr rtnl_msg =  
    .msg_iov = &iov,
    .msg_iovlen = 1,
    .msg_name = &peer,
    .msg_namelen = sizeof(struct sockaddr_nl)
 ;

Logging Logging in lldpd was not extensive. Usually, when receiving a bug report, I asked the reporter to add some additional printf() calls to determine where the problem was. This was clearly suboptimal. Therefore, I have added many log_debug() calls with the ability to filter out some of them. For example, to debug interface discovery, one can run lldpd with lldpd -ddd -D interface. Moreover, I have added colors when logging to a terminal. This may seem pointless but it is now far easier to spot warning messages from debug ones. logging output of lldpd

libevent In lldpd 0.5.7, I was using my own select()-based event loop. It worked but I didn t want to grow a full-featured event loop inside lldpd. Therefore, I switched to libevent. The minimal required version of libevent is 2.0.5. A convenient way to check the changes in API is to use Upstream Tracker, a website tracking API and ABI changes for various libraries. This version of libevent is not available in many stable distributions. For example, Debian Squeeze or Ubuntu Lucid only have 1.4.13. I am also trying to keep compatibility with very old distributions, like RHEL 2, which does not have a packaged libevent at all. For some users, it may be a burden to compile additional libraries. Therefore, I have included libevent source code in lldpd source tree (as a git submodule) and I am only using it if no suitable system libevent is available. Have a look at m4/libevent.m4 and src/daemon/Makefile.am to see how this is done.

Client

Serialization lldpctl is a client querying lldpd to display discovered neighbors. The communication is done through an Unix socket. Each structure to be serialized over this socket should be described with a string. For example:
#define STRUCT_LLDPD_DOT3_MACPHY "(bbww)"
struct lldpd_dot3_macphy  
        u_int8_t                 autoneg_support;
        u_int8_t                 autoneg_enabled;
        u_int16_t                autoneg_advertised;
        u_int16_t                mau_type;
 ;
I did not want to use stuff like Protocol Buffers because I didn t want to copy the existing structures to other structures before serialization (and the other way after deserialization). However, the serializer in lldpd did not allow to handle reference to other structures, lists or circular references. I have written another one which works by annotating a structure with some macros:
struct lldpd_chassis  
    TAILQ_ENTRY(lldpd_chassis) c_entries;
    u_int16_t        c_index;
    u_int8_t         c_protocol;
    u_int8_t         c_id_subtype;
    char            *c_id;
    int              c_id_len;
    char            *c_name;
    char            *c_descr;
    u_int16_t        c_cap_available;
    u_int16_t        c_cap_enabled;
    u_int16_t        c_ttl;
    TAILQ_HEAD(, lldpd_mgmt) c_mgmt;
 ;
MARSHAL_BEGIN(lldpd_chassis)
MARSHAL_TQE  (lldpd_chassis, c_entries)
MARSHAL_FSTR (lldpd_chassis, c_id, c_id_len)
MARSHAL_STR  (lldpd_chassis, c_name)
MARSHAL_STR  (lldpd_chassis, c_descr)
MARSHAL_SUBTQ(lldpd_chassis, lldpd_mgmt, c_mgmt)
MARSHAL_END;
Only pointers need to be annotated. The remaining of the structure can be serialized with just memcpy()1. I think there is still room for improvement. It should be possible to add annotations inside the structure and avoid some duplication. Or maybe, using a C parser? Or using the AST output from LLVM?

Library In lldpd 0.5.7, there are two possible entry points to interact with the daemon:
  1. Through SNMP support. Only information available in LLDP-MIB are exported. Therefore, implementation-specific values are not available. Moreover, SNMP support is currently read-only.
  2. Through lldpctl. Thanks to a contribution from Andreas Hofmeister, the output can be requested to be formatted as an XML document.
Integration of lldpd into a network stack was therefore limited to one of those two channels. As an exemple, you can have a look at how Vyatta made the integration using the second solution. To provide a more robust solution, I have added a shared library, liblldpctl, with a stable and well-defined API. lldpctl is now using it. I have followed those directions2:
  • Consistent naming (all exported symbols are prefixed by lldpctl_). No pollution of the global namespace.
  • Consistent return codes (on errors, all functions returning pointers are returning NULL, all functions returning integers are returning -1).
  • Reentrant and thread-safe. No global variables.
  • One well-documented include file.
  • Reduce the use of boilerplate code. Don t segfault on NULL, accept integer input as string, provide easy iterators,
  • Asynchronous API for input/output. The library delegates reading and writing by calling user-provided functions. Those functions can yield their effects. In this case, the user has to callback the library when data is available for reading or writing. It is therefore possible to integrate the library with any existing event-loop. A thin synchronous layer is provided on top of this API.
  • Opaque types with accessor functions.
Accessing bits of information is done through atoms which are opaque containers of type lldpctl_atom_t. From an atom, you can extract some properties as integers, strings, buffers or other atoms. The list of ports is an atom. A port in this list is also an atom. The list of VLAN present on this port is an atom, as well as each VLAN in this list. The VLAN name is a NULL-terminated string living in the scope of an atom. Accessing a property is done by a handful of functions, like lldpctl_atom_get_str(), using a specific key. For example, here is how to display the list of VLAN assuming you have one port as an atom:
vlans = lldpctl_atom_get(port, lldpctl_k_port_vlans);
lldpctl_atom_foreach(vlans, vlan)  
    vid = lldpctl_atom_get_int(vlan,
                               lldpctl_k_vlan_id));
    name = lldpctl_atom_get_str(vlan,
                                lldpctl_k_vlan_name));
    if (vid && name)
        printf("VLAN %d: %s\n", vid, name);
 
lldpctl_atom_dec_ref(vlans);
Internally, an atom is typed and reference counted. The size of the API is greatly limited thanks to this concept. There are currently more than one hundred pieces of information that can be retrieved from lldpd. Ultimately, the library will also enable the full configuration of lldpd. Currently, many aspects can only be configured through command-line flags. The use of the library does not replace lldpctl which will still be available and be the primary client of the library.

CLI Having a configuration file was requested since a long time. I didn t want to include a parser in lldpd: I am trying to keep it small. It was already possible to configure lldpd through lldpctl. Locations, network policies and power policies were the three items that could be configured this way. So, the next step was to enable lldpctl to read a configuration file, parse it and send the result to lldpd. As a bonus, why not provide a full CLI accepting the same statements with inline help and completion?

Parsing & completion Because of completion, it is difficult to use a YACC generated parser. Instead, I define a tree where each node accepts a word. A node is defined with this function:
struct cmd_node *commands_new(
    struct cmd_node *,
    const char *,
    const char *,
    int(*validate)(struct cmd_env*, void *),
    int(*execute)(struct lldpctl_conn_t*, struct writer*,
        struct cmd_env*, void *),
    void *);
A node is defined by:
  • its parent,
  • an optional accepted static token,
  • an help string,
  • an optional validation function and
  • an optional function to execute if the current token is accepted.
When walking the tree, we maintain an environment which is both a key-value store and a stack of positions in the tree. The validation function can check the environment to see if we are in the right context (we want to accept the keyword foo only once, for example). The execution function can add the current token as a value in the environment but it can also pop the current position in the tree to resume walk from a previous node. As an example, see how nodes for configuration of a coordinate-based location are registered:
/* Our root node */
struct cmd_node *configure_medloc_coord = commands_new(
    configure_medlocation,
    "coordinate", "MED location coordinate configuration",
    NULL, NULL, NULL);
/* The exit node.
   The validate function will check if we have both
   latitude and longitude. */
commands_new(configure_medloc_coord,
    NEWLINE, "Configure MED location coordinates",
    cmd_check_env, cmd_medlocation_coordinate,
    "latitude,longitude");
/* Store latitude. Once stored, we pop two positions
   to go back to the "root" node. The user can only
   enter latitude once. */
commands_new(
    commands_new(
        configure_medloc_coord,
        "latitude", "Specify latitude",
        cmd_check_no_env, NULL, "latitude"),
    NULL, "Latitude as xx.yyyyN or xx.yyyyS",
    NULL, cmd_store_env_value_and_pop2, "latitude");
/* Same thing for longitude */
commands_new(
    commands_new(
        configure_medloc_coord,
        "longitude", "Specify longitude",
        cmd_check_no_env, NULL, "longitude"),
    NULL, "Longitude as xx.yyyyE or xx.yyyyW",
    NULL, cmd_store_env_value_and_pop2, "longitude");
The definition of all commands is still a bit verbose but the system is simple enough yet powerful enough to cover all needed cases.

Readline When faced with a CLI, we usually expect some perks like completion, history handling and help. The most used library to provide such features is the GNU Readline Library. Because this is a GPL library, I have first searched an alternative. There are several of them: From an API point of view, the first three libraries support the GNU Readline API. They also have a common native API. Moreover, this native API also handles tokenization. Therefore, I have developed the first version of the CLI with this API3. Unfortunately, I noticed later this library is not very common in the Linux world and is not available in RHEL. Since I have used the native API, it was not possible to fallback to the GNU Readline library. So, let s switch! Thanks to the appropriate macro from the Autoconf Archive (with small modifications), the compilation and linking differences between the libraries are taken care of. Because GNU Readline library does not come with a tokenizer, I had to write one myself. The API is also badly documented and it is difficult to know which symbol is available in which version. I have limited myself to:
  • readline(), addhistory(),
  • rl_insert_text(),
  • rl_forced_update_display(),
  • rl_bind_key()
  • rl_line_buffer and rl_point.
Unfortunately, the various libedit libraries have a noop for rl_bind_key(). Therefore, completion and online help is not available with them. I have noticed that most BSD come with GNU Readline library preinstalled, so it could be considered as a system library. Nonetheless, linking with libedit to avoid licensing issues is possible and help can be obtained by prefixing the command with help.

OS specific support

BSD support Until version 0.7, lldpd was Linux-only. The rewrite to use Netlink was the occasion to abstract interfaces and to port to other OS. The first port was for Debian GNU/kFreeBSD, then for FreeBSD, OpenBSD and NetBSD. They all share the same source code:
  • getifaddrs() to get the list of interfaces,
  • bpf(4) to attach to an interface to receive and send packets,
  • PF_ROUTE socket to be notified when a change happens.
Each BSD has its own ioctl() to retrieve VLAN, bridging and bonding bits but they are quite similar. The code was usually adapted from ifconfig.c. The BSD ports have the same functionalities than the Linux port, except for NetBSD which lacks support for LLDP-MED inventory since I didn t find a simple way to retrieve DMI related information. They also offer greater security by filtering packets sent. Moreover, OpenBSD allows to lock the filters set on the socket:
/* Install write filter (optional) */
if (ioctl(fd, BIOCSETWF, (caddr_t)&fprog) < 0)  
    rc = errno;
    log_info("privsep", "unable to setup write BPF filter for %s",
        name);
    goto end;
 
/* Lock interface */
if (ioctl(fd, BIOCLOCK, (caddr_t)&enable) < 0)  
    rc = errno;
    log_info("privsep", "unable to lock BPF interface %s",
        name);
    goto end;
 
This is a very nice feature. lldpd is using a privileged process to open the raw socket. The socket is then transmitted to an unprivileged process. Without this feature, the unprivileged process can remove the BPF filters. I have ported the ability to lock a socket filter program to Linux. However, I still have to add a write filter.

OS X support Once FreeBSD was supported, supporting OS X seemed easy. I got sponsored by xcloud.me which provided a virtual Mac server. Making lldpd work with OS X took only two days, including a full hour to guess how to get Apple Xcode without providing a credit card. To help people installing lldpd on OS X, I have also written a lldpd formula for Homebrew which seems to be the most popular package manager for OS X.

Upstart and systemd support Many distributions propose upstart and systemd as a replacement or an alternative for the classic SysV init. Like most daemons, lldpd detaches itself from the terminal and run in the background, by forking twice, once it is ready (for lldpd, this just means we have setup the control socket). While both upstart and systemd can accommodate daemons that behave like this, it is recommended to not fork. How to advertise readiness in this case? With upstart, lldpd will send itself the SIGSTOP signal. upstart will detect this, resume lldpd with SIGCONT and assume it is ready. The code to support upstart is therefore quite simple. Instead of calling daemon(), do this:
const char *upstartjob = getenv("UPSTART_JOB");
if (!(upstartjob && !strcmp(upstartjob, "lldpd")))
    return 0;
log_debug("main", "running with upstart, don't fork but stop");
raise(SIGSTOP);
The job configuration file looks like this:
# lldpd - LLDP daemon
description "LLDP daemon"
start on net-device-up IFACE=lo
stop on runlevel [06]
expect stop
respawn
script
  . /etc/default/lldpd
  exec lldpd $DAEMON_ARGS
end script
systemd provides a socket to achieve the same goal. An application is expected to write READY=1 to the socket when it is ready. With the provided library, this is just a matter of calling sd_notify("READY=1\n"). Since sd_notify() has less than 30 lines of code, I have rewritten it to avoid an external dependency. The appropriate unit file is:
[Unit]
Description=LLDP daemon
Documentation=man:lldpd(8)
[Service]
Type=notify
NotifyAccess=main
EnvironmentFile=-/etc/default/lldpd
ExecStart=/usr/sbin/lldpd $DAEMON_ARGS
Restart=on-failure
[Install]
WantedBy=multi-user.target

OS include files Linux-specific include files were a major pain in previous versions of lldpd. The problems range from missing header files (like linux/if_bonding.h) to the use of kernel-only types. Those headers have a difficult history. They were first shipped with the C library but were rarely synced and almost always outdated. They were then extracted from kernel version with almost no change and lagged behind the kernel version used by the released distribution4. Today, the problem is acknowledged and is being solved by both the distributions which extract the headers from the packaged kernel and by kernel developers with a separation of kernel-only headers from user-space API headers. However, we still need to handle legacy. A good case is linux/ethtool.h:
  • It can just be absent.
  • It can use u8, u16 types which are kernel-only types. To work around this issue, type munging can be setup.
  • It can miss some definition, like SPEED_10000. In this case, you either define the missing bits and find yourself with a long copy of the original header interleaved with #ifdef or conditionally use each symbol. The latest solution is a burden by itself but it also hinders some functionalities that can be available in the running kernel.
The easy solution to all this mess is to just include the appropriate kernel headers into the source tree of the project. Thanks to Google ripping them for its Bionic C library, we know that copying kernel headers into a program does not create a derivative work.

  1. Therefore, the use of u_int16_t and u_int8_t types is a left-over of the previous serializer where the size of all members was important.
  2. For more comprehensive guidelines, be sure to check Writing a C library.
  3. Tokenization is not the only advantage of libedit native API. The API is also cleaner, does not have a global state and has a better documentation. All the implementations are also BSD licensed.
  4. For example, in Debian Sarge, the Linux kernel was a 2.6.8 (2004) while the kernel headers were extracted from some pre-2.6 kernel.

Keith Packard: DRI3000

DRI3000 Even Better Direct Rendering This all started with the presentation that Eric Anholt and I did at the 2012 X developers conference, and subsequently wrote about in my DRI-Next posting. That discussion sketched out the goals of changing the existing DRI2-based direct rendering infrastructure. Last month, I gave a more detailed presentation at Linux.conf.au 2013 (the best free software conference in the world). That presentation was recorded, so you can watch it online. Or, you can read Nathan Willis summary at lwn.net. That presentation contained a lot more details about the specific techniques that will be used to implement the new system, in particular it included some initial indications of what kind of performance benefits the overall system might be able to produce. I sat down today and wrote down an initial protocol definition for two new extensions (because two extensions are always better than one). Together, these are designed to provide complete support for direct rendering APIs like OpenGL and offer a better alternative to DRI2. The DRI3 extension Dave Airlie and Eric Anholt refused to let me call either actual extension DRI3000, so the new direct rendering extension is called DRI3. It uses POSIX file descriptor passing to share kernel objects between the X server and the application. DRI3 is a very small extension in three requests:
  1. Open. Returns a file descriptor for a direct rendering device along with the name of the driver for a particular API (OpenGL, Video, etc).
  2. PixmapFromBuffer. Takes a kernel buffer object (Linux uses DMA-BUF) and creates a pixmap that references it. Any place a Pixmap can be used in the X protocol, you can now talk about a DMA-BUF object. This allows an application to do direct rendering, and then pass a reference to those results directly to the X server.
  3. BufferFromPixmap. This takes an existing pixmap and returns a file descriptor for the underlying kernel buffer object. This is needed for the GL Texture from Pixmap extension.
For OpenGL, the plan is to create all of the buffer objects on the client side, then pass the back buffer to the X server for display on the screen. By creating pixmaps, we avoid needing new object types in the X server and can use existing X apis that take pixmaps for these objects. The Swap extension Once you ve got direct rendered content in a Pixmap, you ll want to display it on the screen. You could simply use CopyArea from the pixmap to a window, but that isn t synchronzied to the vertical retrace signal. And, the semantics of the CopyArea operation precludes us from swapping the underlying buffers around, making it more expensive than strictly necessary. The Swap extension fills those needs. Because the DRI3 extension provides an X pixmap reference to the direct rendered content, the Swap extension doesn t need any new object types for its operation. Instead, it talks strictly about core X objects, using X pixmaps as the source of the new data and X drawables as the destination. The core of the Swap extension is one request SwapRegion. This request moves pixels from a pixmap to a drawable. It uses an X fixes Region object to specify the area of the destination being painted, and an offset within the source pixmap to align the two areas. A bunch of data are included in the reply from the SwapRegion request. First, you get a 64-bit sequence number identifying the swap itself. Then, you get a suggested geometry for the next source pixmap. Using the suggested geometry may result in performance improvements from the techniques described in the LCA talk above. The last bit of data included in the SwapRegion reply is a list of pixmaps which were used as source operands to earlier SwapRegion requests to the same drawable. Each pixmap is listed along with the 64-bit sequence number associated with an earlier SwapRegion operation which resulted in the contents which the pixmap now contains. Ok, so that sounds really confusing. Some examples are probably necessary. I m hoping you ll be able to tell that in both cases, the idle swap count tries to name the swap sequence at which time the destination drawable contained the contents currently in the pixmap. Note that even if the SwapRegion is implemented as a Copy operation, the provided source pixmap may not be included in the idle list as the copy may be delayed to meet the synchronization requirements specfied by the client. Finally, if you want to throttle rendering based upon when frames appear on the screen, Swap offers an event that can be delivered to the drawable after the operation actually takes place. Because the Swap extension needs to supply all of the OpenGL SwapBuffers semantics (including a multiplicity of OpenGL extensions related to that), I ve stolen a handful of DRI2 requests to provide the necessary bits for that:
  1. SwapGetMSC
  2. SwapWaitMSC
  3. SwapWaitSBC
These work just like the DRI2 requests of the same names. Current State of the Extensions Both of these extensions have an initial protocol specification written down and stored in git:
  1. DRI3 protocol
  2. Swap protocol

19 February 2013

Roland Mas: A challenge for whoever feels they have too much free time

Open question to enthusiasts, theoretical computing scientists and mathematicians of all sorts: is it possible to construct a valid QR-code that leads to interesting results when used as an initial configuration for the Game of Life? The rules: For Science! Update: The answer seems to be yes. Jurij Smakov assembled a QR-code generator and a Life engine and plugged them together for easy experimenting. And Stefano Zacchiroli noticed that using "free software" (no quotes) as the input leads to a couple of gliders endlessly traveling a field with a few still lifes. This is way beyond awesome.

18 February 2013

Dirk Eddelbuettel: New Rcpp master class scheduled for New York

A new Rcpp master class is scheduled for March 9 in New York. The format will an updated version of the one-day workshops I have given at the University of Rochester in 2010, in San Franciso in 2011 (organised by Revolution Analytics) and at the UseR! conference in 2012. The style will be hands-on, with numerous concrete examples and solid coverage of most aspects of Rcpp and related packages. As before, about six hours of instruction, split into four sessions of around ninety minutes focussing (loosely) on motivation/intro, core parts, extensions and applications. This should leave ample time for informal discussions and Q+A---as well as for lunch and coffee breaks---for a total of eight hours in the classroom. This is being put together in New York with the help of Jared Lander, and we will have some technical assistance from RStudio in order to use their EC2 farm for exercises with Rcpp. Registrations details are available here; information about other Rcpp events is also available. Feel free to contact me or Jared at our usual email addresses with questions.

Jan Wagner: Airprint support broken in Debian wheezy?

Some of our customers are using central CUPS systems for managing their printer infrastructure. In the last years the demand for support printing (called Airprint) from mobile apple products increased. This worked well for us on Debian squeeze as documented here (updated scrips). I tried this on a fresh installed Debian wheezy amd64, but no printer was found on any IOS device. Hmm .... let's see if the printer is announces via avahi:
$ avahi-browse -a   grep -i print
+   eth0 IPv6 Kyocera FS-1020D @ service                    Internet Printer     local
+   eth0 IPv6 AirPrint Kyocera @ service                    Internet Printer     local
+   eth0 IPv4 Kyocera FS-1020D @ service                    Internet Printer     local
+   eth0 IPv4 AirPrint Kyocera @ service                    Internet Printer     local
WTF?!? Fortunately we have an Ubuntu 12.04 running in our office and printing from IOS devices works without problems (without copying any files to /etc/avahi/services/):
$ avahi-browse -a   grep -i print
+   eth2 IPv6 Ricoh Aficio MP C2800 @ printing              Internet Printer     local
+   eth2 IPv6 Ricoh Aficio MP 171 @ printing                Internet Printer     local
+   eth2 IPv4 Ricoh Aficio MP 171 @ printing                Internet Printer     local
+   eth2 IPv4 Ricoh Aficio MP C2800 @ printing              Internet Printer     local
I just copied the whole configuration over to my wheezy system, but it didn't worked out. I tried this all on a kfreebsd-i386 system again without success. Sorry, but I don't understand the source of this issue. Cups on wheezy has the same upstream version as on precise. Avahi-daemon on wheezy is just one minor version ahead off precise. Is this a bug/incompatibility in cups and/or avahi? A missing patch compared to the packages of precise? Is this a configuration problem? Update: Looking into LP #1054495 and the debdiff of cups 1.5.3-0ubuntu6 indicates, that there seems modifications beside simple changes of mime configurations files. Update: The fix for LP #1054495 does really fix the problem on wheezy too. With the help of Didier Raboud I was able test a binary package with this fixapplied on our test setup. The good news is, there are no extra modifications needed beside just configuring cups to export it's printers for enabling support for iOS devices. I opened #700961 and hopefully release managment will accept this fix for wheezy. Hints, rants and comments could be send to 'blog - at - waja - dot - info' or via @blogwajainfo.

Paul Tagliamonte: GSoC Project Idea: Debian Android app

Hello, World! There are details coming out soon with regards to GSoC:2013, so all this is without any official hat of any sort on. However, I had an idea, and I was wondering if there were people interested in mentoring it. For a long time, I ve wanted a Debian android application one that will use API calls to fetch PTS info, BTS info, and intercept bug URLs to display Debian related information on the native interface. It d also be neat to set a profile (e.g. my emails) and get notifications when things happen that I care about. Anyone know how to code for android and interested in GSoC?

Jan Wagner: Server Management

Server management on daily basis in a growing environment could be a challenge. Most of the tasks is here done with ClusterSSH in help with a homebrew mail notification. Unfortunately this workflow is not scaling well for 200+ systems. I had a look into apt-dater but this seems not to fit our workflow. FAI looks a bit overengineered at the first glance. Maybe Puppet is an option? There seems to be many extensions for it, unfortunately ruby is needed on every single node. Is there a CTO-compatible overview about puppet, any other alternatives? ;) Update: Many thanks for the hints from Andr Lu s Lopes, Stig Sandbeck Mathisen, Phil Miller, Steve Kemp, Andrew Latham, Bob Proulx and Natxo Asenjo Old but conceptual still valid: www.infrastructures.org, for example Bootstrapping an Infrastructure Other thoughts: push- or pull-infrastructure? Software footprint (on nodes and your central instance)! Hints, rants and comments could be send to 'blog - at - waja - dot - info' or via @blogwajainfo.

15 February 2013

Robert Collins: More subunit needs

Of course, as happens sadly often, the scope creeps.. Additional pain points Zope s test runner runs things that are not tests, but which users want to know about layers . At the moment these are reported as individual tests, but this is problematic in a couple of ways. Firstly, the same test runs on multiple backend runners, so timing and stats get more complex. Secondly, if a layer fails to setup or teardown, tools like testrepository that have watched the stream will think a test failed, and on the next run try to explicitly run that test but that test doesn t really exist, so it won t run [unless an actual test that needs the layer is being run]. Openstack uses python coverage to gather coverage statistics during test runs. Each worker running tests needs to gather and return such statistics. The current subunit protocol has no space to hand this around, without it pretending to be a test [see a pattern here?]. And that has the same negative side effect test runners like testrepository will try to run that test . While testrepository doesn t want to know about coverage itself, it would be nice to be able to pass everything around and have a local hook handle the aggregation of that data. The way TAP is reflected into subunit today is to mangle each tap test into a subunit test , but for full benefits subunit tests have a higher bar they are individually addressable and runnable. So a TAP test script is much more equivalent to a subunit test. A similar concept is landing in Python s unittest soon subtests which will give very lightweight additional assertions within a larger test concept. Many C test runners that emit individual tests as simple assertions have this property as well there may be 5 or 10 executables each with dozens of assertions, but only the executables are individually addressable there is no way to run just one assertion from an executable as a test . It would be nice to avoid the friction that currently exists when dealing with that situation. Minimum requirements to support these Layers can be supported via timestamped stdout output, or fake tests. Neither is compelling, as the former requires special casing in subunit processors to data mine it, and the latter confuses test runners. A way to record something that is structured like a test (has an id the layer, an outcome in progress / ok / failed, and attachment data for showing failure details) but isn t a test would allow the data to flow around without causing confusion in the system. TAP support could change to just show the entire output as progress on one test and then fail or not at the end. This would result in a cognitive mismatch for folk from the TAP world, as TAP runners report each assertion as a test , and this would be hidden from subunit. Having a way to record something that is associated with an actual test, and has a name, status, attachment content for the TAP comments field that would let subunit processors report both the addressable tests (each TAP script) and the individual items, but know that only the overall scripts are runnable. Python subtests could use a unique test for each subtest, but that has the same issue has layers. Python will ensure a top level test errors if a subtest errors, so strictly speaking we probably don t need an associated-with concept, but we do need to be able to say that a test-like thing happened that isn t actually addressable. Coverage information could be about a single test, or even a subtest, or it could be about the entire work undertaken by the test process. I don t think we need a single standardised format for Coverage data (though that might be an excellent project for someone to undertake). It is also possible to overthink things :) . We have the idea of arbitrary attachments for tests. Perhaps arbitrary attachments outside of test scope would be better than specifying stdout/stderr as specific things. On the other hand stdout and stderr are well known things. Proposal version 2 A packetised length prefixed binary protocol, with each packet containing a small signature, length, routing code, a binary timestamp in UTC, a set of UTF8 tags (active only, no negative tags), a content tag one of (estimate + number, stdin, stdout, stderr, file, test), test-id, runnable, test-status (one of exists/inprogress/xfail/xsuccess/success/fail/skip), an attachment name, mime type, a last-block marker and a block of bytes. The std/stdout/stderr content tags are gone, replaced with file. The names stdin,stdout,stderr can be placed in the attachment name field to signal those well known files, and any other files that the test process wants to hand over can be simply embedded. Processors that don t expect them can just pass them on. Runnable is a boolean, indicating whether this packet is describing a test that can be executed deliberately (vs an individual TAP assertion, Python sub-test etc). This permits describing things like zope layers which are top level test-like things (they start, stop and can error) though they cannot be run.. and it doesn t explicitly model the setup/teardown aspect that they have. Should we do that? Testid is for identifying tests. With the runnable flag to indicate whether a test really is a test, subtests can just be namespaced by the generator reporters can choose whether to be naive and report every test , or whether to use simple string prefix-with-non-character-seperator to infer child elements. Impact on Python API If we change the API to:
class TestInfo(object):
    id = unicode
    status = ('exists', 'inprogress', 'xfail', 'xsuccess', 'success', 'fail', 'error', 'skip')
    runnable = boolean
class StreamingResult(object):
    def startTestRun(self):
        pass
    def stopTestRun(self):
        passs
    def estimate(self, count, route_code=None, timestamp=None):
        pass
    def file(self, name, bytes, eof=False, mime=None, test_info=None, route_code=None, timestamp=None):
        """Inform the result about the contents of an attachment."""
    def status(self, test_info, route_code=None, timestamp=None):
        """Inform the result about a test status with no attached data."""
This would permit the full semantics of a subunit stream to be represented I think, while being a narrow interface that should be easy to implement. Please provide feedback! I ll probably start implementing this soon.

14 February 2013

Ian Campbell: FOSDEM 2013

So as previously mentioned I gave a talk at FOSDEM this year on the future of paravirtualisation under Xen. I thought the talk was reasonably well attended despite being at six o'clock in the evening. In the end I underran my half hour slot but fortunately people had plenty of interesting questions! I've posted my slides on my xenbits space. I spent a fair chunk of the rest of the time on the Xen.org booth, which is hard work but it is always nice to speak to users and other developers. I also managed to catch up with various friends from other projects and managed to meet a few folks who I've only ever met in email before. I didn't get to see as many talks as I wanted (for example I missed pretty much all of the ARM track :-() due to clashes with my stints on the booth, my own talk, and talks clashing with each other. Still it was all in all a worthwhile, hopefully I'll be able to make it again next year! Next up: LinaroConnect in Hong Kong!

Robert Collins: Time to revise the subunit protocol

Subunit is seven and a half years old now Conrad Parker and I first sketched it up at a CodeCon camping and coding, a brilliant combination in mid 2005.
revno: 1
committer: Robert Collins <robertc@robertcollins.net>
timestamp: Sat 2005-08-27 15:01:20 +1000
message:  design up a protocol with kfish
It has proved remarkably resilient as a protocol the basic nature hasn t changed at all, even though we ve added tags, timestamps, support for attachments of arbitrary size. However a growing number of irritations have been building up with it. I think it is time to design another iteration of the protocol, one that will retain the positive qualities of the current protocol, while helping it become suitable for the next 7 years. Ideally we can keep compatibility and make it possible for a single stream to be represented in any format. Existing design The existing design is a mostly human readable line orientated protocol that can be sniffed out from the regular output of make or other build systems. Binary attachments are done using HTTP chunking, and the parser has to maintain state about the current test, tags, timing data and test progression [a simple stack of progress counters]. How to arrange subunit output is undefined, how to select tests to run is undefined. This makes writing a parser quite easy, and the tagging and timestamp facility allow multiplexing streams from two or more concurrent test runs into one with good fidelity but also requires that state be buffered until the end of a test, as two tests cannot be executing at once. Dealing with debuggers The initial protocol was intended to support dropping into a debugger just pass each line read through to stdout, and connect stdin to the test process, and voila, you have a working debugger connection. This works, but the current line based parsers make using it tedious the line buffered nature of it makes feedback on what has been typed fiddly, and stdout tends to be buffered, leading to an inability to see print statements and the like. All in-principle fixable, right ? When running two or more test processes, which test process should stdin be connected to? What if two or more drop into a debugger at once? What is being typed to which process is more luck than anything else. We ve added some idioms in testrepository that control test execution by a similar but different format one test per line to list tests, and have runners permit listing and selecting by a list. This works well, but the inconsistency with subunit itself is a little annoying you need two parsers, and two output formats. Good points The current protocol is extremely easy to implement for emitters, and the arbitrary attachments and tagging features have worked extremely well. There is a comprehensive Python parser which maps everything into Python unittest API calls (an extended version of the standard, with good backwards compatibility). Pain points The debugging support was a total failure, and the way the parser depraminates it s toys when a test process corrupts an outcome line is extremely frustrating. (other tests execute but the parser sees them as non-subunit chatter and passes the lines on through stdout). Dealing with concurrency The original design didn t cater for concurrency. There are three concurrency issues the corruption issue (see below for more detail) and multiplexing. Consider two levels of nested concurrency: A supervisor process such as testrepository starts 2 (or more but 2 is sufficient to reason about the issue) subsidiary worker processes (I1 and I2), each of which starts 2 subsidiary processes of their own (W1, W2, W3, W4). Each of the 4 leaf processes is outputting subunit which gets multiplexed in the 2 intermediary processes, and then again in the supervisor. Why would there be two layers? A concrete example is using testrepository to coordinate test runs on multiple machines at once, with each machine running a local testrepository to broker tests amongst the local CPUs. This could be done with 4 separate ssh sessions and no intermediaries, but that only removes a fraction of the issues. What issues? Well, consider some stdout chatter that W1 outputs. That will get passed to I1 and from there to the supervisor and captured. But there is nothing marking the chatter as belonging to W1: there is no way to tell where it came from. If W1 happened to fail, and there was a diagnostic message printed, we ve lost information. Or at best muddled it all up. Secondly, buffering imagine that a test on W1 hangs. I1 will know that W1 is running a test, but has no way to tell the supervisor (and thus the user) that this is the case, without writing to stdout [and causing a *lot* of noise if that happens a lot]. We could have I1 write to stdout only if W1 s test is taking more than 5 seconds or something but this is a workaround for a limitation of the protocol. Adding to the confusion, the clock on W1 and W3 may be very skewed, so timestamps for everything have to be carefully synchronised by the multiplexer. Thirdly, scheduling if W1/W2 are on a faster machine than W3/W4 then a partition of equal-timed tests onto each machine will lead one idle before the other finishes. It would be nice to be able to pass tests to run to the faster machine when it goes idle, rather than having to start a new runner each time. Lastly, what to do when W1 and W2 both wait for user input on stdin (e.g. passphrases, debugger input, $other). Naively connecting stdin to all processes doesn t work well. A GUI supervisor could connect a separate fd to each of I1 and I2, but that doesn t help when it is W1 and W2 reading from stdin. So additional requirement over baseline subunit:
  1. make it possible for stdout and stderr output to be captured from W1 and routed through I1 to the supervisor without losing its origin. It might be chatter from a noisy test, or it might be build output. Either way, the user probably will benefit if we can capture it and show it to them later when they review the test run. The supervisor should probably show it immediately as well the protocol doesn t need to care about that, just make it possible.
  2. make it possible to pass information about tests that have not completed through one subunit stream while they are still incomplete.
  3. make it possible (but optional) to pass tests to run to a running process that accepts subunit.
  4. make it possible to route stdin to a specific currently process like W1. This and point 3 suggest that we need a bidirectional protocol rather than the solely unidirectional protocol we have today. I don t know of a reliable portable way to tell when some process is seeking such input, so that will be up to the user I think. (e.g. printing (pdb) to stdout might be a sufficiently good indicator.)
Dealing with corruption Consider the following subunit fragment:
test: foo
starting serversuccess:foo
This is a classic example of corruption: the test foo started a server and helpfully wrote to stdout explaining that it did that, but missed the newline. As a result the success message for the test wasn t printed on a line of its own, and the subunit parser will believe that foo never completed. Every subsequent test is then ignored. This is usually easy to identify and fix, but its a head-scratcher when it happens. Another way it can happen is when a build tool like make runs tests in parallel, and they output subunit onto the same stdout file handle. A third way is when a build tool like make runs two separate test scripts serially, and the first one starts a test but errors hard and doesn t finish it. That looks like:
test: foo
test: bar
success: bar
One way that this sort of corruption can be mitigated is to put subunit on it s own file descriptor, but this has several caveats: it is harder to tunnel through things like ssh and it doesn t solve the failing test script case. I think it is unreasonable to require a protocol where arbitrary interleaving of bytes between different test runner streams will work so the make -j2 case can be ignored at the wire level though we should create a simple way to safely mux the output from such tests when the execute. The root of the issue is that a dropped update leaves bad state in the parser and it never recovers. So some way to recover, or less state to carry in the parser, would neatly solve things. I favour reducing parser state as that should shift stateful complexity onto end nodes / complex processors, rather than being carried by every node in the transmission path. Dependencies Various suggestions have been made JSON, Protobufs, etc A key design goal of the first subunit was a low barrier to entry. We keep that by being backward compatible, but being easy to work with for the new revision is also a worthy goal. High level proposal A packetised length prefixed binary protocol, with each packet containing a small signature, length, routing code, a binary timestamp in UTC, a set of UTF8 tags (active only, no negative tags), a content tag one of (estimate + number, stdin, stdout, stderr, test- + test id), test status (one of exists/inprogress/xfail/xsuccess/success/fail/skip), an attachment name, mime type, a last-block marker and a block of bytes. The content tags: Test status values are pretty ordinary. Exists is used to indicate a test that can be run when listing tests, and inprogress is used to report a test that has started but not necessarily completed. Attachment names must be unique per routing code + testid. So how does this line up? Interleaving and recovery We could dispense with interleaving and say the streams are wholly binary, or we can say that packets can start either after a \n or directly after another packet. If we say that binary-only is the approach to take, it would be possible to write a filter that would apply the newline heuristic (or even look for packet headers at every byte offset. I think mandating adjacent to a packet or after \n is a small concession to make and will avoid tools like testrepository forcing users to always configure a heuristic filter. Non-subunit content can be wrapped in subunit for forwarding (the I1 in W1->I1->Supervisor chain would do the wrapping). This won t eliminate corruption but it will localise it and permit the stream to recover: the test that was corrupted will show up as incomplete, or with incomplete attachment data. listing Test listing would emit many small non-timestamped packets. It may be useful to have a wrapper packet for bulk amounts of fine grained data like listing is, or for multiplexers with many input streams that will often have multiple data packets available to write at once. Selecting tests to run Same as for listing while passing regexes down to the test runner to select groups of tests is a valid use case, thats not something subunit needs to worry about : if the selection is not the result of the supervisor selecting by test id, then it is known at the start of the test run and can just be a command line parameter to the backend : subunit is relevant for passing instructions to a runner mid-execution. Because the supervisor cannot just hand out some tests and wait for the thing it ran to report that it can accept incremental tests on stdin, supervisor processes will need to be informed about that out of band. Debugging Debugging is straight forward . The parser can read the first 4 or so bytes of a packet one at a time to determine if it is a packet or a line of stdout/stderr, and then either read to end of line, or the binary length of the packet. So, we combine a few things; non-subunit output should be wrapped and presented to the user. Subunit that is being multiplexed and forwarded should prepend a routing code to the packet (e.g. I1 would append 1 or 2 to select which of W1/W2 the content came from, and then forward the packet. S would append 1 or 2 to indicate I1/I2 the routing code is a path through the tree of forwarding processes). The UI the user is using needs to supply some means to switch where stdin is attached. And stdin input should be routed via stdin packets. When there is no routing code left, the packet should be entirely unwrapped and presented as raw bytes to the process in question. Multiplexing Very straight forward unwrap the outer layer of the packet, add or adjust the routing code, serialise a header + adjusted length + rest of packet as-is. No buffering is needed, so the supervisor can show in-progress tests (and how long they have been running for). Parsing / representation in Python or other languages The parser should be very simple to write. Once parsed, this will be fundamentally different to the existing Python TestCase->TestResult API that is in used today. However it should be easy to write two adapters: old-style <-> this new-style. old-style -> new-style is useful for running existing tests suites and generating subunit, because thats way the subunit generation is transparent. new-style->old-style is useful for using existing test reporting facilities (such as junitxml or html TestResult objects) with subunit streams. Importantly though, a new TestResult style that supports the features of this protocol would enable some useful features for regular Python test suites: The API might be something like:
class StreamingResult(object):
    def startTestRun(self):
        pass
    def stopTestRun(self):
        pass
    def estimate(self, count, route_code=None):
        pass
    def stdin(self, bytes, route_code=None):
        pass
    def stdout(self, bytes, route_code=None):
        pass
    def test(self, test_id, status, attachment_name=None, attachment_mime=None, attachment_eof=None, attachment_bytes=None):
        pass
This would support just-in-time debugging by wiring up pdb to the stdin/stdout handlers of the result object, rather than actual stdin/stdout of the process a simple matter once written. Alternatively, the test runner could replace sys.stdin/stdout etc with thunk file-like objects, which might be a good idea anyway to capture spurious output happening during a test run. That would permit pdb to Just Work (even if the test process is internally running concurrent tests.. until it has two pdb objects running concurrently :) Generation new streams Should be very easy in anything except shell. For shell, we can have a command line tool that when invoked outputs a subunit stream for one instruction. E.g. test foo completed + some attachments or test foo starting .

Jon Dowland: Managing Puppet modules with puppet

Over the last few days I've done quite a lot of work to try and get our puppet configuration up to modern best practises. The Puppet Labs folks strongly encourage you to make as much use of puppet modules as possible. A puppet module gathers together puppet manifests, facter facts and other bits and pieces into a reusable component that you could potentially share with others. Many modules (of very mixed quality) are available on the web, in particular at github and via Puppet Lab's own Forge. Since version 2.7.14, the puppet command-line tool has built-in support for managing modules:
# puppet module list
/etc/puppet/modules
  auth (???)
  interfaces (???)
 
# puppet module install puppetlabs-apt
 
However, they have not provided support for managing modules in puppet manifests themselves. This strikes me as a bit odd: the whole point of using puppet to manage your machines is to capture the configuration in one place. If your configuration depends on a collection of modules and module versions, you'd ideally record that in the puppet configuration itself. Otherwise building a new puppet master is a mixture of manually installing modules and setting it up as a client of your existing master. Other people to the rescue: Ryan Coleman (and Pieter van de Bruggen) have written puppet_module_provider which does exactly this. (Note that they both work for Puppet Labs). Now I can define which modules and what versions are necessary:
class puppetmaster  
   
  module   'rcoleman/puppet_module': ensure => '0.0.3',  
  module   'puppetlabs/firewall':    ensure => '0.0.4',  
  module   'puppetlabs/lvm':         ensure => '0.1.1',  
  module   'puppetlabs/ntp':         ensure => '0.2.0',  
   
I've decided to pin specific versions given the highly variable nature of module quality. There's no guarantee of backwards compatibility except by reputation of the publisher. The puppetlabs modules are likely to be of higher quality than average, so over time I'll probably gain confidence to change the specific versioning to 'latest' or similar. I also want to double-check how secure the module selection and downloading is (whether it's over HTTPS or cryptographic signatures are checked etc.)

13 February 2013

Patrick Matth i: otrs and geoip-database updates

I have just uploaded the monthly update of geoip-database to Debian unstable and squeeze-backports, unblock request already filled. I also uploaded otrs2 in the new version 3.2.1+dfsg1-1, which is also fixing bug #690306, fixing because the upgrade will abort with a list of MySQL tables where the administrator has to fix ether the engine from MyISAM to InnoDB (or the other way, as he want to) and by fxing the default engine of his MySQL database server. Ugly issue, ugly hack, but there is no better solution.. Full changelog of otrs Debian packaging:
   * New upstream release.
     - Add new dependency libyaml-libyaml-perl.
     - Refresh patch 03-postmaster.
     - Refresh patch 05-opt.
     - Refresh patch 13-dont-chown-links.
     - Refresh patch 16-disable-DashboardProductNotify.
     - Refresh patch 19-fix-SetPermissions-to-include-some-more-dirs.
     - Rewrite patch 25-use-locale-country, since all_country_names() does not
       accept arguments.
     - Refresh patch 26-font-paths.
     - Rewrite patch 04-backup.
     - Rewrite patch 15-usable-apache-config.
     - Rewrite patch 21-use-debian-libjs-packages.
     - Rewrite patch 23-load-debian-libjs.
     - Remove old database schemas and add new 3.2 ones.
   * Monitor all releases again.
   * Drop patch 24-default-myisam and check with the new otrs.CheckDB.pl script,
     if the available tables and the used storage engine are equal. If it is not
     the case the installation should abort, so that the administrator can fix
     his MySQL server or the already created tables.
     Closes: #690306
   * Remove deprecated packaging notes from README.Debian.
   * Remove deprecated NEWS file from packaging.
   * Remove deprecated files from otrs2.examples.
   * Solve duplicate-changelog-files by not installing the CHANGES file.
   * Remove some more deprecated files from otrs2.docs.
   * Add lintian override for empty-binary package otrs.
   * Remove some old permission fixes from debian/rules.
   * Add upstream patch 01-innodb-fk-error to fix some foreign key errors if the
     tables are created with InnoDB.

12 February 2013

Martin Pitt: umockdev: record and mock hardware for debugging and testing

What is this? umockdev is a set of tools and a library to mock hardware devices for programs that handle Linux hardware devices. It also provides tools to record the properties and behaviour of particular devices, and to run a program or test suite under a test bed with the previously recorded devices loaded. This allows developers of software like gphoto or libmtp to receive these records in bug reports and recreate the problem on their system without having access to the affected hardware, as well as writing regression tests for those that do not need any particular privileges and thus are capable of running in standard make check. After working on it for several weeks and lots of rumbling on G+, it s now useful and documented enough for the first release 0.1! Component overview umockdev consists of the following parts: Example: Record and replay PtP/MTP USB devices So how do you use umockdev? For the debug a problem use case you usually don t want to write a program that uses libumockdev, but just use the command line tools. Let s capture some runs from libmtp tools, and replay them in a mock environment: Example: using the library to fake a battery If you want to write regression tests, it s usually more flexible to use the library instead of calling everything through umockdev-run. As a simple example, let s pretend we want to write tests for upower. Batteries, and power supplies in general, are simple devices in the sense that userspace programs such as upower only communicate with them through sysfs and uevents. No /dev nor ioctls are necessary. docs/examples/ has two example programs how to use libumockdev to create a fake battery device, change it to low charge, sending an uevent, and running upower on a local test system D-BUS in the testbed, with watching what happens with upower --monitor-detail. battery.c shows how to do that with plain GObject in C, battery.py is the equivalent program in Python that uses the GI binding. You can just run the latter like this:
  umockdev-wrapper python3 docs/examples/battery.py
and you will see that upowerd (which runs on a temporary local system D-BUS in the test bed) will report a single battery with 75% charge, which gets down to 2.5% a second later. The gist of it is that you create a test bed with
  UMockdevTestbed *testbed = umockdev_testbed_new ();
and add a device with certain sysfs attributes and udev properties with
    gchar *sys_bat = umockdev_testbed_add_device (
            testbed, "power_supply", "fakeBAT0", NULL,
            /* attributes */
            "type", "Battery",
            "present", "1",
            "status", "Discharging",
            "energy_full", "60000000",
            "energy_full_design", "80000000",
            "energy_now", "48000000",
            "voltage_now", "12000000",
            NULL,
            /* properties */
            "POWER_SUPPLY_ONLINE", "1",
            NULL);
You can then e. g. change an attribute and synthesize a change uevent with
  umockdev_testbed_set_attribute (testbed, sys_bat, "energy_now", "1500000");
  umockdev_testbed_uevent (testbed, sys_bat, "change");
With Python or other introspected languages, or in Vala it works the same way, except that it looks a bit leaner due to proper object semantics. Packages I have a packaging branch for Ubuntu and a recipe to do daily builds with the latest upstream code into my daily builds PPA (for 12.10 and raring). I will soon upload it to Raring proper, too. What s next? The current set of features should already get you quite far for a range of devices. I d love to get feedback from you if you use this for anything useful, in particular how to improve the API, the command line tools, or the text dump format. I m not really happy with the split between umockdev (sys/dev) and ioctl files and the relatively complicated CLI syntax of umockdev-record, so any suggestion is welcome. One use case that I have for myself is to extend the coverage of ioctls for input devices such as touch screens and wacom tablets, so that we can write some tests for gnome-settings-daemon plugins. I also want to find a way to pass ioctls back to the test suite/calling program instead of having to handle them all in the preload library, which would make it a lot more flexible. However, due to the nature of the ioctl ABI this is not easy. Where to go to The code is hosted on github in the umockdev project; this started out as a systemd branch to add this functionality to libudev, but after a discussion with Kay we decided to keep it separate. But I kept it in git anyway, given how popular it is today. For the bzr lovers, Launchpad has an import at lp:umockdev. Release tarballs will be on Launchpad as well. Please file bugs and enhancement requests in the git hub tracker. Finally, if you have questions or want to discuss something, you can always find me on IRC (pitti on Freenode or GNOME). Thanks for your attention and happy testing!

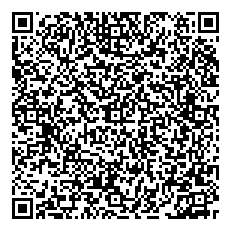
Petter Reinholdtsen: "Electronic" paper invoices - using vCard in a QR code

Here in Norway, electronic invoices are spreading, and the solution promoted by the Norwegian government require that invoices are sent through one of the approved facilitators, and it is not possible to send electronic invoices without an agreement with one of these facilitators. This seem like a needless limitation to be able to transfer invoice information between buyers and sellers. My preferred solution would be to just transfer the invoice information directly between seller and buyer, for example using SMTP, or some HTTP based protocol like REST or SOAP. But this might also be overkill, as the "electronic" information can be transferred using paper invoices too, using a simple bar code. My bar code encoding of choice would be QR codes, as this encoding can be read by any smart phone out there. The content of the code could be anything, but I would go with the vCard format, as it too is supported by a lot of computer equipment these days. The vCard format support extentions, and the invoice specific information can be included using such extentions. For example an invoice from SLX Debian Labs (picked because we ask for donations to the Debian Edu project and thus have bank account information publicly available) for NOK 1000.00 could have these extra fields:
X-INVOICE-NUMBER:1
X-INVOICE-AMOUNT:NOK1000.00
X-INVOICE-KID:123412341234
X-INVOICE-MSG:Donation to Debian Edu
X-BANK-ACCOUNT-NUMBER:16040884339
X-BANK-IBAN-NUMBER:NO8516040884339
X-BANK-SWIFT-NUMBER:DNBANOKKXXX
The X-BANK-ACCOUNT-NUMBER field was proposed in a stackoverflow answer regarding how to put bank account information into a vCard. For payments in Norway, either X-INVOICE-KID (payment ID) or X-INVOICE-MSG could be used to pass on information to the seller when paying the invoice. The complete vCard could look like this:
BEGIN:VCARD
VERSION:2.1
ORG:SLX Debian Labs Foundation
ADR;WORK:;;Gunnar Schjelderups vei 29D;OSLO;;0485;Norway
URL;WORK:http://www.linuxiskolen.no/slxdebianlabs/
EMAIL;PREF;INTERNET:sdl-styret@rt.nuug.no
REV:20130212T095000Z
X-INVOICE-NUMBER:1
X-INVOICE-AMOUNT:NOK1000.00
X-INVOICE-MSG:Donation to Debian Edu
X-BANK-ACCOUNT-NUMBER:16040884339
X-BANK-IBAN-NUMBER:NO8516040884339
X-BANK-SWIFT-NUMBER:DNBANOKKXXX
END:VCARD
The resulting QR code created using qrencode would look like this, and should be readable (and thus checkable) by any smart phone, or for example the zbar bar code reader and feed right into the approval and accounting system. The extension fields will most likely not show up in any normal vCard reader, so those parts would have to go directly into a system handling invoices. I am a bit unsure how vCards without name parts are handled, but a simple test indicate that this work just fine. Update 2013-02-12 11:30: Added KID to the proposal based on feedback from Sturle Sunde.

11 February 2013

Jon Dowland: Steam for Debian

So you can download Steam for Linux now!. Or at least Ubuntu. The 1.0.0.22-version package needs a bit of tweaking to make it installable on Debian. There's a good writeup of some of the issues in this blog post (more recent packages seem to have much more simple dependencies). I run amd64 with multiarch enabled for i386. I chose to update my libc to the version in experimental rather than embed a newer version in a private steam directory. The remaining issues are mostly package version differences between Ubuntu (who seem to be very epoch-happy, I guess they've made a lot more packaging mistakes) and Debian. I wrote the following script to do the work. It takes two arguments: the original steam .deb and then the output filename to write a modified .deb to. Feel free to try it.
#!/bin/sh
set -u
set -e
[ $# -eq 2 ]     echo "$0 <in-deb> <out-deb>" >&2; exit 1;  
wd=$(mktemp -td $0.XXXXXX)
trap "rm -r '$wd'" INT QUIT EXIT
dpkg-deb -x "$1" "$wd/steam"
dpkg-deb -e "$1" "$wd/steam/DEBIAN"
sed -i  -e 's/\(libpulse0 (>= \)1:/\1/' -e '# remove ubuntu epoch' \
    -e 's/^\(Version:.*\)$/\1+jmtd/' \
    -e 's/xterm   gnome-terminal,//' -e '# seems to be an apt bug here' \
    -e 's/\(multiarch-support (>= 2.15\)[^)]*/\1/' -e '# remove ubuntu epoch' \
    "$wd/steam/DEBIAN/control"
mv "$wd/steam/usr/bin/steamdeps" "$wd/steam/usr/bin/steamdeps.orig"
ln -s "/bin/true" "$wd/steam/usr/bin/steamdeps"
fakeroot dpkg-deb -b "$wd/steam" "$2"
The most interesting (to me, anyway) package foible was the dependency on xterm gnome-terminal. I have both installed, but neither for i386. Of course, steam doesn't need a 32 bit terminal emulator, it can spawn the 64 bit one perfectly well. It turns out that you can't express such a dependency at the moment. Even changing that to a virtual package x-terminal-emulator didn't work: aptitude still wanted to pull in a 32 bit match and all the supporting libraries. For this package I just delete the dependency outright.

10 February 2013

Stefano Zacchiroli: bits from the DPL for January 2013

(insert here: I've been to FOSDEM, I got a nasty flu, and other $lame_excuses for the delay in sending out this report) Dear Project Members, here's the monthly DPL activity report, this time for January 2013. About the next DPL This is the last DPL report before the start of the election process for the next term: around early March, about 20 days from now, the Secretary will send out the call for nominations. I'd like to respond (also) here to inquiries I'm receiving these days: I will not run again as DPL. So you have about 20 days to mob^Wconvince other DDs to run, or decide to run yourself. Do not to wait for the vary last minute, as that makes for lousy campaigns. I'm available to give feedback about my DPL experience to prospective candidates, ... and also to join mobbing^Wconvincing actions toward potential candidates. Just contact me. Call for helps Assets Cloud Images Work has gone on also on the front of supporting Debian installation in public "clouds". Thanks to Arnaud Patard, Jose Miguel Parrella Romero, Pierre Couzy, and Gianugo Rabellino, we now have Debian testing images for Microsoft Azure. Together with Amazon EC2, this is the second large provider supporting Debian via images maintained by Debian Developers. More providers are welcome, exactly as more hardware/CD vendors shipping Debian are always welcome. If you want to contribute support for other providers just show up on the -cloud mailing list and say so. Some documentation effort in view of Wheezy are in need of help too, in order to let our users know about "cloud" options, see #695681. DPL helpers The DPL helpers experiment goes on. We have had 2 more IRC meetings in January (see the minutes). Documentation of the "team" communication channels (mailing list, IRC, Git, etc.) is now available from the DPL wiki page. Talks I've given an invited Debian talk at Polytech'Grenoble, as part of a free software event organized for students of local universities. Slides of the talk are available. I'd like to thank Vincent Danjean for the event organization. Let's release Wheezy now!
Cheers.
PS the day-to-day activity log for January 2013 is available at the usual place master:/srv/leader/news/bits-from-the-DPL.txt.201301

Hideki Yamane: license for MIBs

Unfortunately, most of MIBs doesn't meet DFSG since RFC is non-free. However, RFC5378 was released and it says "code components in RFCs are licensed under Simplified BSD license (BSD-3-clause)", See Trust Legal Provisions (TLP) Documents page.

Code components are

ABNF definitions, XML Schemas, XML DTDs, XML RelaxNG definitions, tables of values, MIBs, PIBs, ASN.1, and classical programming source code
So, recent MIBs can be included to Debian package :)

But it isn't enough because those RFCs are almost 30/260, 90% are not DFSG-free. And 190/260 RFCs are owned by ISOC and IETF trustee, I hope thay will release old MIBs code in RFCs under DFSG-free license as same as after RFC5378.

8 February 2013

Olivier Berger: RDF development in PHP with a PostGreSQL triple store thanks to the LibRDF OO wrapper for redland/librdf

Redland/librdf offers powerful features like being able to persist an RDF model to a relational database (only PostGreSQL seems to work on my setup with 1.0.16, but I may have misconfigured it). You can then do SPARQL queries over the model, and lots of other nice things. Unfortunately, the default PHP bindings are not really object-oriented, so the code isn t looking so good. But thanks to a gentleman named David Shea, there is an object-oriented library named LibRDF (case is sensitive), that helps write nice looking PHP. I discovered it via the blog post of Felix Ostrowski, who took over the maintenance of the LibRDF library (still the docs live on the original author s site). In his post, Felix illustrates how you may use it to parse Richard Cyganiak s FOAF profile. But the examples he gives don t illustrate the full potential of persistence of the RDF graph into the DB. Here s my contribution in 2 examples that will hopefully help : first, one that load Richard s FOAF to the DB, and one, that later retrieve the saved model and perform the same query (both pushed to my github clone of the library). There may be some problems with the use of librdf, including its availability, as it is not full PHP of course and I ve heard of memory management problems, but, depening on your needs, this may be quite handy for writing Linked Data applications.

Next.

Previous.