Search Results: "ed"

6 December 2021

Matthias Klumpp: New things in AppStream 0.15

On the road to AppStream 1.0, a lot of items from the long todo list have been done so far only one major feature is remaining, external release descriptions, which is a tricky one to implement and specify. For AppStream 1.0 it needs to be present or be rejected though, as it would be a major change in how release data is handled in AppStream. Besides 1.0 preparation work, the recent 0.15 release and the releases before it come with their very own large set of changes, that are worth a look and may be interesting for your application to support. But first, for a change that affects the implementation and not the XML format: 1. Completely rewritten caching code Keeping all AppStream data in memory is expensive, especially if the data is huge (as on Debian and Ubuntu with their large repositories generated from desktop-entry files as well) and if processes using AppStream are long-running. The latter is more and more the case, not only does GNOME Software run in the background, KDE uses AppStream in KRunner and Phosh will use it too for reading form factor information. Therefore, AppStream via libappstream provides an on-disk cache that is memory-mapped, so data is only consuming RAM if we are actually doing anything with it. Previously, AppStream used an LMDB-based cache in the background, with indices for fulltext search and other common search operations. This was a very fast solution, but also came with limitations, LMDB s maximum key size of 511 bytes became a problem quite often, adjusting the maximum database size (since it has to be set at opening time) was annoyingly tricky, and building dedicated indices for each search operation was very inflexible. In addition to that, the caching code was changed multiple times in the past to allow system-wide metadata to be cached per-user, as some distributions didn t (want to) build a system-wide cache and therefore ran into performance issues when XML was parsed repeatedly for generation of a temporary cache. In addition to all that, the cache was designed around the concept of one cache for data from all sources , which meant that we had to rebuild it entirely if just a small aspect changed, like a MetaInfo file being added to /usr/share/metainfo, which was very inefficient. To shorten a long story, the old caching code was rewritten with the new concepts of caches not necessarily being system-wide and caches existing for more fine-grained groups of files in mind. The new caching code uses Richard Hughes excellent libxmlb internally for memory-mapped data storage. Unlike LMDB, libxmlb knows about the XML document model, so queries can be much more powerful and we do not need to build indices manually. The library is also already used by GNOME Software and fwupd for parsing of (refined) AppStream metadata, so it works quite well for that usecase. As a result, search queries via libappstream are now a bit slower (very much depends on the query, roughly 20% on average), but can be mmuch more powerful. The caching code is a lot more robust, which should speed up startup time of applications. And in addition to all of that, the AsPool class has gained a flag to allow it to monitor AppStream source data for changes and refresh the cache fully automatically and transparently in the background. All software written against the previous version of the libappstream library should continue to work with the new caching code, but to make use of some of the new features, software using it may need adjustments. A lot of methods have been deprecated too now. 2. Experimental compose support Compiling MetaInfo and other metadata into AppStream collection metadata, extracting icons, language information, refining data and caching media is an involved process. The appstream-generator tool does this very well for data from Linux distribution sources, but the tool is also pretty heavyweight with lots of knobs to adjust, an underlying database and a complex algorithm for icon extraction. Embedding it into other tools via anything else but its command-line API is also not easy (due to D s GC initialization, and because it was never written with that feature in mind). Sometimes a simpler tool is all you need, so the libappstream-compose library as well as appstreamcli compose are being developed at the moment. The library contains building blocks for developing a tool like appstream-generator while the cli tool allows to simply extract metadata from any directory tree, which can be used by e.g. Flatpak. For this to work well, a lot of appstream-generator s D code is translated into plain C, so the implementation stays identical but the language changes. Ultimately, the generator tool will use libappstream-compose for any general data refinement, and only implement things necessary to extract data from the archive of distributions. New applications (e.g. for new bundling systems and other purposes) can then use the same building blocks to implement new data generators similar to appstream-generator with ease, sharing much of the code that would be identical between implementations anyway. 2. Supporting user input controls Want to advertise that your application supports touch input? Keyboard input? Has support for graphics tablets? Gamepads? Sure, nothing is easier than that with the new control relation item and supports relation kind (since 0.12.11 / 0.15.0, details):
<supports>
  <control>pointing</control>
  <control>keyboard</control>
  <control>touch</control>
  <control>tablet</control>
</supports>
3. Defining minimum display size requirements Some applications are unusable below a certain window size, so you do not want to display them in a software center that is running on a device with a small screen, like a phone. In order to encode this information in a flexible way, AppStream now contains a display_length relation item to require or recommend a minimum (or maximum) display size that the described GUI application can work with. For example:
<requires>
  <display_length compare="ge">360</display_length>
</requires>
This will make the application require a display length greater or equal to 300 logical pixels. A logical pixel (also device independent pixel) is the amount of pixels that the application can draw in one direction. Since screens, especially phone screens but also screens on a desktop, can be rotated, the display_length value will be checked against the longest edge of a display by default (by explicitly specifying the shorter edge, this can be changed). This feature is available since 0.13.0, details. See also Tobias Bernard s blog entry on this topic. 4. Tags This is a feature that was originally requested for the LVFS/fwupd, but one of the great things about AppStream is that we can take very project-specific ideas and generalize them so something comes out of them that is useful for many. The new tags tag allows people to tag components with an arbitrary namespaced string. This can be useful for project-internal organization of applications, as well as to convey certain additional properties to a software center, e.g. an application could mark itself as featured in a specific software center only. Metadata generators may also add their own tags to components to improve organization. AppStream gives no recommendations as to how these tags are to be interpreted except for them being a strictly optional feature. So any meaning is something clients and metadata authors need to negotiate. It therefore is a more specialized usecase of the already existing custom tag, and I expect it to be primarily useful within larger organizations that produce a lot of software components that need sorting. For example:
<tags>
  <tag namespace="lvfs">vendor-2021q1</tag>
  <tag namespace="plasma">featured</tag>
</tags>
This feature is available since 0.15.0, details. 5. MetaInfo Creator changes The MetaInfo Creator (source) tool is a very simple web application that provides you with a form to fill out and will then generate MetaInfo XML to add to your project after you have answered all of its questions. It is an easy way for developers to add the required metadata without having to read the specification or any guides at all. Recently, I added support for the new control and display_length tags, resolved a few minor issues and also added a button to instantly copy the generated output to clipboard so people can paste it into their project. If you want to create a new MetaInfo file, this tool is the best way to do it! The creator tool will also not transfer any data out of your webbrowser, it is strictly a client-side application. And that is about it for the most notable changes in AppStream land! Of course there is a lot more, additional tags for the LVFS and content rating have been added, lots of bugs have been squashed, the documentation has been refined a lot and the library has gained a lot of new API to make building software centers easier. Still, there is a lot to do and quite a few open feature requests too. Onwards to 1.0!

Paul Tagliamonte: Proxying Ethernet Frames to PACKRAT (Part 5/5)

This post is part of a series called "PACKRAT". If this is the first post you've found, it'd be worth reading the intro post first and then looking over all posts in the series.
In the last post, we left off at being able to send and recieve PACKRAT frames to and from devices. Since we can transport IPv4 packets over the network, let s go ahead and see if we can read/write Ethernet frames from a Linux network interface, and on the backend, read and write PACKRAT frames over the air. This has the benifit of continuing to allow Linux userspace tools to work (like cURL, as we ll try!), which means we don t have to do a lot of work to implement higher level protocols or tactics to get a connection established over the link. Given that this post is less RF and more Linuxy, I m going to include more code snippits than in prior posts, and those snippits are closer to runable Go, but still not complete examples. There s also a lot of different ways to do this, I ve just picked the easiest one for me to implement and debug given my existing tooling for you, you may find another approach easier to implement! Again, deviation here is very welcome, and since this segment is the least RF centric post in the series, the pace and tone is going to feel different. If you feel lost here, that s OK. This isn t the most important part of the series, and is mostly here to give a concrete ending to the story arc. Any way you want to finish your own journy is the best way for you to finish it!

Implement Ethernet conversion code This assumes an importable package with a Frame struct, which we can use to convert a Frame to/from Ethernet. Given that the PACKRAT frame has a field that Ethernet doesn t (namely, Callsign), that will need to be explicitly passed in when turning an Ethernet frame into a PACKRAT Frame.
...
// ToPackrat will create a packrat frame from an Ethernet frame.
func ToPackrat(callsign [8]byte, frame *ethernet.Frame) (*packrat.Frame, error)  
var frameType packrat.FrameType
switch frame.EtherType  
case ethernet.EtherTypeIPv4:
frameType = packrat.FrameTypeIPv4
default:
return nil, fmt.Errorf("ethernet: unsupported ethernet type %x", frame.EtherType)
 
return &packrat.Frame 
Destination: frame.Destination,
Source: frame.Source,
Type: frameType,
Callsign: callsign,
Payload: frame.Payload,
 , nil
 
// FromPackrat will create an Ethernet frame from a Packrat frame.
func FromPackrat(frame *packrat.Frame) (*ethernet.Frame, error)  
var etherType ethernet.EtherType
switch frame.Type  
case packrat.FrameTypeRaw:
return nil, fmt.Errorf("ethernet: unsupported packrat type 'raw'")
case packrat.FrameTypeIPv4:
etherType = ethernet.EtherTypeIPv4
default:
return nil, fmt.Errorf("ethernet: unknown packrat type %x", frame.Type)
 
// We lose the Callsign here, which is sad.
 return &ethernet.Frame 
Destination: frame.Destination,
Source: frame.Source,
EtherType: etherType,
Payload: frame.Payload,
 , nil
 
Our helpers, ToPackrat and FromPackrat can now be used to transmorgify PACKRAT into Ethernet, or Ethernet into PACKRAT. Let s put them into use!

Implement a TAP interface On Linux, the networking stack can be exposed to userland using TUN or TAP interfaces. TUN devices allow a userspace program to read and write data at the Layer 3 / IP layer. TAP devices allow a userspace program to read and write data at the Layer 2 Data Link / Ethernet layer. Writing data at Layer 2 is what we want to do, since we re looking to transform our Layer 2 into Ethernet s Layer 2 Frames. Our first job here is to create the actual TAP interface, set the MAC address, and set the IP range to our pre-coordinated IP range.
...
import (
"net"
"github.com/mdlayher/ethernet"
"github.com/songgao/water"
"github.com/vishvananda/netlink"
)
...
config := water.Config DeviceType: water.TAP 
config.Name = "rat0"
iface, err := water.New(config)
...
netIface, err := netlink.LinkByName("rat0")
...
// Pick a range here that works for you!
 //
 // For my local network, I'm using some IPs
 // that AMPR (ampr.org) was nice enough to
 // allocate to me for ham radio use. Thanks,
 // AMPR!
 //
 // Let's just use 10.* here, though.
 //
 ip, cidr, err := net.ParseCIDR("10.0.0.1/24")
...
cidr.IP = ip
err = netlink.AddrAdd(netIface, &netlink.Addr 
IPNet: cidr,
Peer: cidr,
 )
...
// Add all our neighbors to the ARP table
 for _, neighbor := range neighbors  
netlink.NeighAdd(&netlink.Neigh 
LinkIndex: netIface.Attrs().Index,
Type: netlink.FAMILY_V4,
State: netlink.NUD_PERMANENT,
IP: neighbor.IP,
HardwareAddr: neighbor.MAC,
 )
 
// Pick a MAC that is globally unique here, this is
 // just used as an example!
 addr, err := net.ParseMAC("FA:DE:DC:AB:LE:01")
...
netlink.LinkSetHardwareAddr(netIface, addr)
...
err = netlink.LinkSetUp(netIface)
var frame = &ethernet.Frame 
var buf = make([]byte, 1500)
for  
n, err := iface.Read(buf)
...
err = frame.UnmarshalBinary(buf[:n])
...
// process frame here (to come)
  
...
Now that our network stack can resolve an IP to a MAC Address (via ip neigh according to our pre-defined neighbors), and send that IP packet to our daemon, it s now on us to send IPv4 data over the airwaves. Here, we re going to take packets coming in from our TAP interface, and marshal the Ethernet frame into a PACKRAT Frame and transmit it. As with the rest of the RF code, we ll leave that up to the implementer, of course, using what was built during Part 2: Transmitting BPSK symbols and Part 4: Framing data.
...
for  
// continued from above

n, err := iface.Read(buf)
...
err = frame.UnmarshalBinary(buf[:n])
...
switch frame.EtherType  
case 0x0800:
// ipv4 packet
 pack, err := ToPackrat(
// Add my callsign to all Frames, for now
 [8]byte 'K', '3', 'X', 'E', 'C' ,
frame,
)
...
err = transmitPacket(pack)
...
 
 
...
Now that we have transmitting covered, let s go ahead and handle the recieve path here. We re going to listen on frequency using the code built in Part 3: Receiving BPSK symbols and Part 4: Framing data. The Frames we decode from the airwaves are expected to come back from the call packratReader.Next in the code below, and the exact way that works is up to the implementer.
...
for  
// pull the next packrat frame from
 // the symbol stream as we did in the
 // last post
 packet, err := packratReader.Next()
...
// check for CRC errors and drop invalid
 // packets
 err = packet.Check()
...
if bytes.Equal(packet.Source, addr)  
// if we've heard ourself transmitting
 // let's avoid looping back
 continue
 
// create an ethernet frame
 frame, err := FromPackrat(packet)
...
buf, err := frame.MarshalBinary()
...
// and inject it into the tap
 err = iface.Write(buf)
...
 
...
Phew. Right. Now we should be able to listen for PACKRAT frames on the air and inject them into our TAP interface.

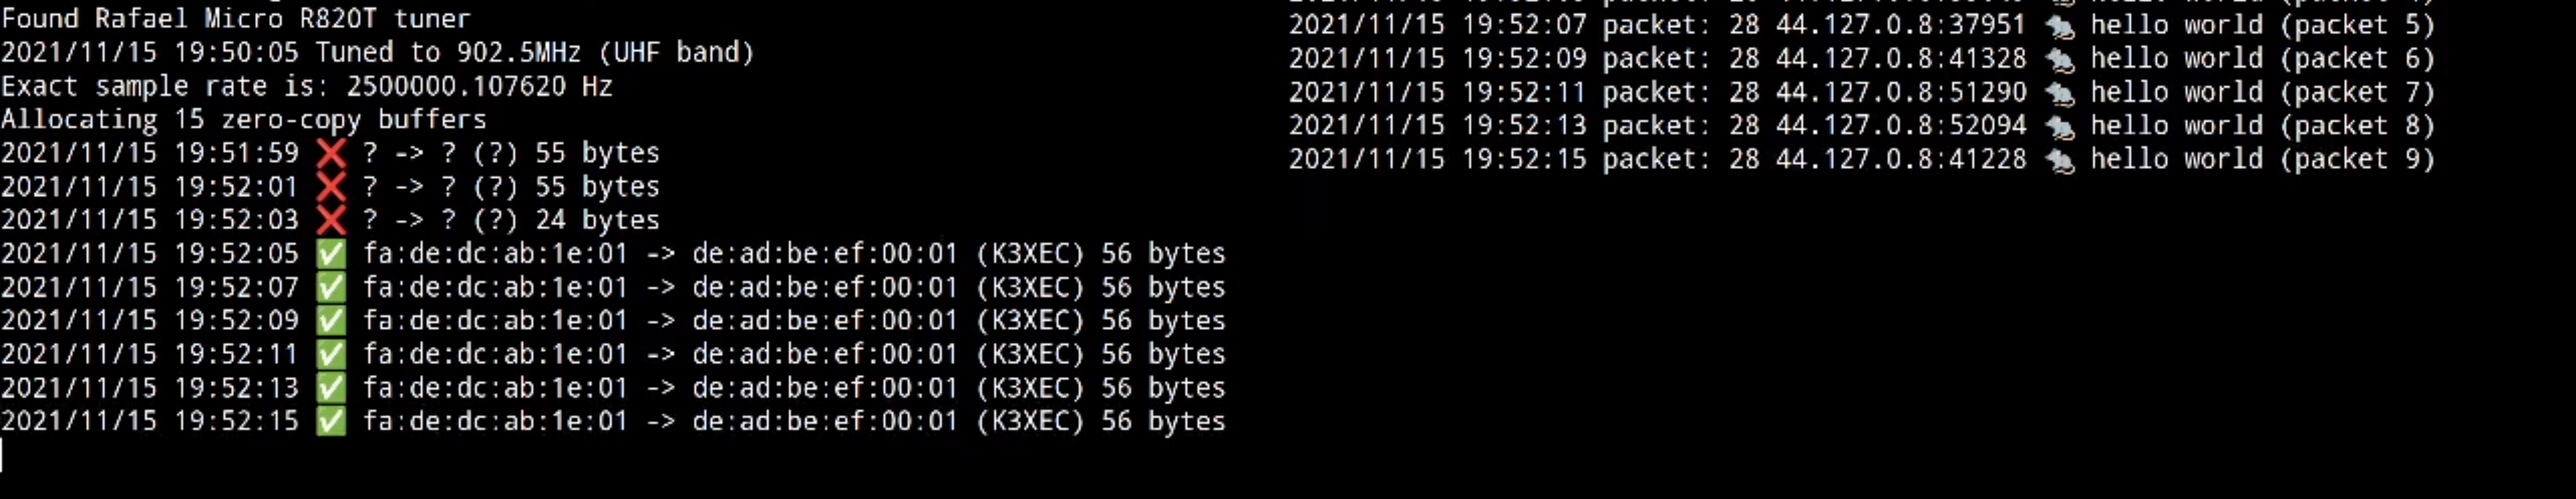
Putting it all Together After all this work weeks of work! we can finally get around to putting some real packets over the air. For me, this was an incredibly satisfying milestone, and tied together months of learning! I was able to start up a UDP server on a remote machine with an RTL-SDR dongle attached to it, listening on the TAP interface s host IP with my defined MAC address, and send UDP packets to that server via PACKRAT using my laptop, /dev/udp and an Ettus B210, sending packets into the TAP interface. Now that UDP was working, I was able to get TCP to work using two PlutoSDRs, which allowed me to run the cURL command I pasted in the first post (both simultaneously listen and transmit on behalf of my TAP interface). It s my hope that someone out there will be inspired to implement their own Layer 1 and Layer 2 as a learning exercise, and gets the same sense of gratification that I did! If you re reading this, and at a point where you ve been able to send IP traffic over your own Layer 1 / Layer 2, please get in touch! I d be thrilled to hear all about it. I d love to link to any posts or examples you publish here!

Dirk Eddelbuettel: tidyCpp 0.0.6 on CRAN: Package Maintenance

Another small release of the tidyCpp package arrived on CRAN this morning. The packages offers a clean C++ layer (as well as one small C++ helper class) on top of the C API for R which aims to make use of this robust (if awkward) C API a little easier and more consistent. See the vignette for motivating examples. This release makes a tiny code change, remove a YAML file for the disgraced former continuous integration service we shall not name (yet that we all used to use). And just like digest five days ago, drat four days ago, littler three days ago, RcppAPT two days ago, and RcppSpdlog yesterday, we converted the vignettes from using the minidown package to the (fairly new) simplermarkdown package which is so much more appropriate for our use of the minimal water.css style. The NEWS entry follows.

Changes in tidyCpp version 0.0.6 (2021-12-06)
  • Assign nullptr in dtor for Protect class
  • Switch vignette engine to simplermarkdown

Thanks to my CRANberries, there is also a diffstat report for this release. For questions, suggestions, or issues please use the issue tracker at the GitHub repo. If you like this or other open-source work I do, you can now sponsor me at GitHub.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

5 December 2021

Dirk Eddelbuettel: RcppSpdlog 0.0.7 on CRAN: Package Maintenance

A new version 0.0.7 of RcppSpdlog is now on CRAN. RcppSpdlog bundles spdlog, a wonderful header-only C++ logging library with all the bells and whistles you would want that was written by Gabi Melman, and also includes fmt by Victor Zverovich. This release brings upstream bugfix releases 1.9.1 and 1.9.2 of spdlog. We also removed the YAML file (and badge) for the disgraced former continuous integration service we shall not name (yet that we all used to use). And just like digest four days ago, drat three days ago, littler two days ago, and RcppAPT yesterday, we converted the vignettes from using the minidown package to the (fairly new) simplermarkdown package which is so much more appropriate for our use of the minimal water.css style. The (minimal) NEWS entry for this release follows.

Changes in RcppSpdlog version 0.0.7 (2021-12-05)
  • Upgraded to upstream bug fix releases spdlog 1.9.1 and 1.9.2
  • Travis artifacts and badges have been pruned
  • Vignette now uses simplermarkdown

Courtesy of my CRANberries, there is also a diffstat report. More detailed information is on the RcppSpdlog page, or the package documention site. If you like this or other open-source work I do, you can sponsor me at GitHub.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

Reproducible Builds: Reproducible Builds in November 2021

Welcome to the November 2021 report from the Reproducible Builds project. As a quick recap, whilst anyone may inspect the source code of free software for malicious flaws, almost all software is distributed to end users as pre-compiled binaries. The motivation behind the reproducible builds effort is therefore to ensure no flaws have been introduced during this compilation process by promising identical results are always generated from a given source, thus allowing multiple third-parties to come to a consensus on whether a build was compromised. If you are interested in contributing to our project, please visit our Contribute page on our website.
On November 6th, Vagrant Cascadian presented at this year s edition of the SeaGL conference, giving a talk titled Debugging Reproducible Builds One Day at a Time:
I ll explore how I go about identifying issues to work on, learn more about the specific issues, recreate the problem locally, isolate the potential causes, dissect the problem into identifiable parts, and adapt the packaging and/or source code to fix the issues.
A video recording of the talk is available on archive.org.
Fedora Magazine published a post written by Zbigniew J drzejewski-Szmek about how to Use Diffoscope in packager workflows, specifically around ensuring that new versions of a package do not introduce breaking changes:
In the role of a packager, updating packages is a recurring task. For some projects, a packager is involved in upstream maintenance, or well written release notes make it easy to figure out what changed between the releases. This isn t always the case, for instance with some small project maintained by one or two people somewhere on GitHub, and it can be useful to verify what exactly changed. Diffoscope can help determine the changes between package releases. [ ]

kpcyrd announced the release of rebuilderd version 0.16.3 on our mailing list this month, adding support for builds to generate multiple artifacts at once.
Lastly, we held another IRC meeting on November 30th. As mentioned in previous reports, due to the global events throughout 2020 etc. there will be no in-person summit event this year.

diffoscope diffoscope is our in-depth and content-aware diff utility. Not only can it locate and diagnose reproducibility issues, it can provide human-readable diffs from many kinds of binary formats. This month, Chris Lamb made the following changes, including preparing and uploading versions 190, 191, 192, 193 and 194 to Debian:
  • New features:
    • Continue loading a .changes file even if the referenced files do not exist, but include a comment in the returned diff. [ ]
    • Log the reason if we cannot load a Debian .changes file. [ ]
  • Bug fixes:
    • Detect XML files as XML files if file(1) claims if they are XML files or if they are named .xml. (#999438)
    • Don t duplicate file lists at each directory level. (#989192)
    • Don t raise a traceback when comparing nested directories with non-directories. [ ]
    • Re-enable test_android_manifest. [ ]
    • Don t reject Debian .changes files if they contain non-printable characters. [ ]
  • Codebase improvements:
    • Avoid aliasing variables if we aren t going to use them. [ ]
    • Use isinstance over type. [ ]
    • Drop a number of unused imports. [ ]
    • Update a bunch of %-style string interpolations into f-strings or str.format. [ ]
    • When pretty-printing JSON, mark the difference as being reformatted, additionally avoiding including the full path. [ ]
    • Import itertools top-level module directly. [ ]
Chris Lamb also made an update to the command-line client to trydiffoscope, a web-based version of the diffoscope in-depth and content-aware diff utility, specifically only waiting for 2 minutes for try.diffoscope.org to respond in tests. (#998360) In addition Brandon Maier corrected an issue where parts of large diffs were missing from the output [ ], Zbigniew J drzejewski-Szmek fixed some logic in the assert_diff_startswith method [ ] and Mattia Rizzolo updated the packaging metadata to denote that we support both Python 3.9 and 3.10 [ ] as well as a number of warning-related changes[ ][ ]. Vagrant Cascadian also updated the diffoscope package in GNU Guix [ ][ ].

Distribution work In Debian, Roland Clobus updated the wiki page documenting Debian reproducible Live images to mention some new bug reports and also posted an in-depth status update to our mailing list. In addition, 90 reviews of Debian packages were added, 18 were updated and 23 were removed this month adding to our knowledge about identified issues. Chris Lamb identified a new toolchain issue, absolute_path_in_cmake_file_generated_by_meson.
Work has begun on classifying reproducibility issues in packages within the Arch Linux distribution. Similar to the analogous effort within Debian (outlined above), package information is listed in a human-readable packages.yml YAML file and a sibling README.md file shows how to classify packages too. Finally, Bernhard M. Wiedemann posted his monthly reproducible builds status report for openSUSE and Vagrant Cascadian updated a link on our website to link to the GNU Guix reproducibility testing overview [ ].

Software development The Reproducible Builds project detects, dissects and attempts to fix as many currently-unreproducible packages as possible. We endeavour to send all of our patches upstream where appropriate. This month, we wrote a large number of such patches, including: Elsewhere, in software development, Jonas Witschel updated strip-nondeterminism, our tool to remove specific non-deterministic results from a completed build so that it did not fail on JAR archives containing invalid members with a .jar extension [ ]. This change was later uploaded to Debian by Chris Lamb. reprotest is the Reproducible Build s project end-user tool to build the same source code twice in widely different environments and checking whether the binaries produced by the builds have any differences. This month, Mattia Rizzolo overhauled the Debian packaging [ ][ ][ ] and fixed a bug surrounding suffixes in the Debian package version [ ], whilst Stefano Rivera fixed an issue where the package tests were broken after the removal of diffoscope from the package s strict dependencies [ ].

Testing framework The Reproducible Builds project runs a testing framework at tests.reproducible-builds.org, to check packages and other artifacts for reproducibility. This month, the following changes were made:
  • Holger Levsen:
    • Document the progress in setting up snapshot.reproducible-builds.org. [ ]
    • Add the packages required for debian-snapshot. [ ]
    • Make the dstat package available on all Debian based systems. [ ]
    • Mark virt32b-armhf and virt64b-armhf as down. [ ]
  • Jochen Sprickerhof:
    • Add SSH authentication key and enable access to the osuosl168-amd64 node. [ ][ ]
  • Mattia Rizzolo:
    • Revert reproducible Debian: mark virt(32 64)b-armhf as down - restored. [ ]
  • Roland Clobus (Debian live image generation):
    • Rename sid internally to unstable until an issue in the snapshot system is resolved. [ ]
    • Extend testing to include Debian bookworm too.. [ ]
    • Automatically create the Jenkins view to display jobs related to building the Live images. [ ]
  • Vagrant Cascadian:
    • Add a Debian package set group for the packages and tools maintained by the Reproducible Builds maintainers themselves. [ ]


If you are interested in contributing to the Reproducible Builds project, please visit our Contribute page on our website. However, you can get in touch with us via:

Paul Tagliamonte: Framing data (Part 4/5)

This post is part of a series called "PACKRAT". If this is the first post you've found, it'd be worth reading the intro post first and then looking over all posts in the series.
In the last post, we we were able to build a functioning Layer 1 PHY where we can encode symbols to transmit, and receive symbols on the other end, we re now at the point where we can encode and decode those symbols as bits and frame blocks of data, marking them with a Sender and a Destination for routing to the right host(s). This is a Layer 2 scheme in the OSI model, which is otherwise known as the Data Link Layer. You re using one to view this website right now I m willing to bet your data is going through an Ethernet layer 2 as well as WiFi or maybe a cellular data protocol like 5G or LTE. Given that this entire exercise is hard enough without designing a complex Layer 2 scheme, I opted for simplicity in the hopes this would free me from the complexity and research that has gone into this field for the last 50 years. I settled on stealing a few ideas from Ethernet Frames namely, the use of MAC addresses to identify parties, and the EtherType field to indicate the Payload type. I also stole the idea of using a CRC at the end of the Frame to check for corruption, as well as the specific CRC method (crc32 using 0xedb88320 as the polynomial). Lastly, I added a callsign field to make life easier on ham radio frequencies if I was ever to seriously attempt to use a variant of this protocol over the air with multiple users. However, given this scheme is not a commonly used scheme, it s best practice to use a nearby radio to identify your transmissions on the same frequency while testing or use a Faraday box to test without transmitting over the airwaves. I added the callsign field in an effort to lean into the spirit of the Part 97 regulations, even if I relied on a phone emission to identify the Frames. As an aside, I asked the ARRL for input here, and their stance to me over email was I d be OK according to the regs if I were to stick to UHF and put my callsign into the BPSK stream using a widely understood encoding (even with no knowledge of PACKRAT, the callsign is ASCII over BPSK and should be easily demodulatable for followup with me). Even with all this, I opted to use FM phone to transmit my callsign when I was active on the air (specifically, using an SDR and a small bash script to automate transmission while I watched for interference or other band users). Right, back to the Frame:
sync
dest
source
callsign
type
payload
crc
With all that done, I put that layout into a struct, so that we can marshal and unmarshal bytes to and from our Frame objects, and work with it in software.
type FrameType [2]byte
type Frame struct  
Destination net.HardwareAddr
Source net.HardwareAddr
Callsign [8]byte
Type FrameType
Payload []byte
CRC uint32
 

Time to pick some consts I picked a unique and distinctive sync sequence, which the sender will transmit before the Frame, while the receiver listens for that sequence to know when it s in byte alignment with the symbol stream. My sync sequence is [3]byte 'U', 'f', '~' which works out to be a very pleasant bit sequence of 01010101 01100110 01111110. It s important to have soothing preambles for your Frames. We need all the good energy we can get at this point.
var (
FrameStart = [3]byte 'U', 'f', '~' 
FrameMaxPayloadSize = 1500
)
Next, I defined some FrameType values for the type field, which I can use to determine what is done with that data next, something Ethernet was originally missing, but has since grown to depend on (who needs Length anyway? Not me. See below!)
FrameType Description Bytes
Raw Bytes in the Payload field are opaque and not to be parsed. [2]byte 0x00, 0x01
IPv4 Bytes in the Payload field are an IPv4 packet. [2]byte 0x00, 0x02
And finally, I decided on a maximum length of the Payload, and decided on limiting it to 1500 bytes to align with the MTU of Ethernet.
var (
FrameTypeRaw = FrameType 0, 1 
FrameTypeIPv4 = FrameType 0, 2 
)
Given we know how we re going to marshal and unmarshal binary data to and from Frames, we can now move on to looking through the bit stream for our Frames.

Why is there no Length field? I was initially a bit surprised that Ethernet Frames didn t have a Length field in use, but the more I thought about it, the more it seemed like a big ole' failure mode without a good implementation outcome. Either the Length is right (resulting in no action and used bits on every packet) or the Length is not the length of the Payload and the driver needs to determine what to do with the packet does it try and trim the overlong payload and ignore the rest? What if both the end of the read bytes and the end of the subset of the packet denoted by Length have a valid CRC? Which is used? Will everyone agree? What if Length is longer than the Payload but the CRC is good where we detected a lost carrer? I decided on simplicity. The end of a Frame is denoted by the loss of the BPSK carrier when the signal is no longer being transmitted (or more correctly, when the signal is no longer received), we know we ve hit the end of a packet. Missing a single symbol will result in the Frame being finalized. This can cause some degree of corruption, but it s also a lot easier than doing tricks like bit stuffing to create an end of symbol stream delimiter.

Finding the Frame start in a Symbol Stream First thing we need to do is find our sync bit pattern in the symbols we re receiving from our BPSK demodulator. There s some smart ways to do this, but given that I m not much of a smart man, I again decided to go for simple instead. Given our incoming vector of symbols (which are still float values) prepend one at a time to a vector of floats that is the same length as the sync phrase, and compare against the sync phrase, to determine if we re in sync with the byte boundary within the symbol stream. The only trick here is that because we re using BPSK to modulate and demodulate the data, post phaselock we can be 180 degrees out of alignment (such that a +1 is demodulated as -1, or vice versa). To deal with that, I check against both the sync phrase as well as the inverse of the sync phrase (both [1, -1, 1] as well as [-1, 1, -1]) where if the inverse sync is matched, all symbols to follow will be inverted as well. This effectively turns our symbols back into bits, even if we re flipped out of phase. Other techniques like NRZI will represent a 0 or 1 by a change in phase state which is great, but can often cascade into long runs of bit errors, and is generally more complex to implement. That representation isn t ambiguous, given you look for a phase change, not the absolute phase value, which is incredibly compelling. Here s a notional example of how I ve been thinking about the phrase sliding window and how I ve been thinking of the checks. Each row is a new symbol taken from the BPSK receiver, and pushed to the head of the sliding window, moving all symbols back in the vector by one.
 var (
sync = []float  ...  
buf = make([]float, len(sync))
incomingSymbols = []float  ...  
)
for _, el := range incomingSymbols  
copy(buf, buf[1:])
buf[len(buf)-1] = el
if compare(sync, buf)  
// we're synced!
 break
 
 
Given the pseudocode above, let s step through what the checks would be doing at each step:
Buffer Sync Inverse Sync
[ ]float 0, ,0 [ ]float -1, ,-1 [ ]float 1, ,1
[ ]float 0, ,1 [ ]float -1, ,-1 [ ]float 1, ,1
[more bits in] [ ]float -1, ,-1 [ ]float 1, ,1
[ ]float 1, ,1 [ ]float -1, ,-1 [ ]float 1, ,1
After this notional set of comparisons, we know that at the last step, we are now aligned to the frame and byte boundary the next symbol / bit will be the MSB of the 0th Frame byte. Additionally, we know we re also 180 degrees out of phase, so we need to flip the symbol s sign to get the bit. From this point on we can consume 8 bits at a time, and re-assemble the byte stream. I don t know what this technique is called or even if this is used in real grown-up implementations, but it s been working for my toy implementation.

Next Steps Now that we can read/write Frames to and from PACKRAT, the next steps here are going to be implementing code to encode and decode Ethernet traffic into PACKRAT, coming next in Part 5!

Reproducible Builds (diffoscope): diffoscope 195 released

The diffoscope maintainers are pleased to announce the release of diffoscope version 195. This version includes the following changes:
[ Chris Lamb ]
* Don't use the runtime platform's native endianness when unpacking .pyc
  files to fix test failures on big-endian machines.
You find out more by visiting the project homepage.

4 December 2021

Jonathan Dowland: Haskell mortgage calculator

A few months ago I was trying to compare two mortgage offers, and ended up writing a small mortgage calculator to help me. Both mortgages were fixed-term for the same time period (5 years). One of the mortgages had a lower rate than the other, but much higher arrangement fees. A broker recommended the mortgage with the higher rate but lower fee, on an affordability basis for the fixed term: over all, we would spend less money within the fixed term on that deal than the other. (I thought) this left one bit of information missing: what remaining balance would there be at the end of the term? The mortgages I want to model are defined in terms of a monthly repayment figure and an annual interest rate for the fixed period. I think interest is usually recalculated on a daily basis, so I convert the annual rate down to a daily rate. Repayments only happen once a month. Months are not all the same size. Using mod 30 on the 'day' approximates a monthly payment. Over 5 years, there would be 60 months, meaning 60 repayments. (I'm ignoring leap years)
 > length . filter id .take (5*365) $ [ x mod 30==0   x <- [1..]]
60
Here's what I came up with. I was a little concerned the repayment approximation was too far out so I compared the output with a more precise (but boring) spreadsheet and they agreed to within an acceptable tolerance. The numbers that follow are all made up to illustrate the function and don't reflect my actual mortgage. :)
borrowed = 1000000 -- day 0 amount outstanding
aer   = 0.89
repay = 1000
der   = aer / 36
owed n   n == 0          = borrowed
         n  mod  30 == 0 = last + interest - repay
         otherwise       = last + interest
    where
        last     = owed (n - 1)
        interest = last * der

Paul Tagliamonte: Receiving BPSK symbols (Part 3/5)

This post is part of a series called "PACKRAT". If this is the first post you've found, it'd be worth reading the intro post first and then looking over all posts in the series.
In the last post, we worked through how to generate a BPSK signal, and hopefully transmit it using one of our SDRs. Let s take that and move on to Receiving BPSK and turning that back into symbols! Demodulating BPSK data is a bit more tricky than transmitting BPSK data, mostly due to tedious facts of life such as space, time, and hardware built with compromises because not doing that makes the problem impossible. Unfortunately, it s now our job to work within our imperfect world to recover perfect data. We need to handle the addition of noise, differences in frequency, clock synchronization and interference in order to recover our information. This makes life a lot harder than when we transmit information, and as a result, a lot more complex.

Coarse Sync Our starting point for this section will be working from a capture of a number of generated PACKRAT packets as heard by a PlutoSDR at (xz compressed interleaved int16, 2,621,440 samples per second) Every SDR has its own oscillator, which eventually controls a number of different components of an SDR, such as the IF (if it s a superheterodyne architecture) and the sampling rate. Drift in oscillators lead to drifts in frequency such that what one SDR may think is 100MHz may be 100.01MHz for another radio. Even if the radios were perfectly in sync, other artifacts such as doppler time dilation due to motion can cause the frequency to appear higher or lower in frequency than it was transmitted. All this is a long way of saying, we need to determine when we see a strong signal that s close-ish to our tuned frequency, and take steps to roughly correct it to our center frequency (in the order of 100s of Hz to kHz) in order to acquire a phase lock on the signal to attempt to decode information contained within. The easiest way of detecting the loudest signal of interest is to use an FFT. Getting into how FFTs work is out of scope of this post, so if this is the first time you re seeing mention of an FFT, it may be a good place to take a quick break to learn a bit about the time domain (which is what the IQ data we ve been working with so far is), frequency domain, and how the FFT and iFFT operations can convert between them. Lastly, because FFTs average power over the window, swapping phases such that the transmitted wave has the same number of in-phase and inverted-phase symbols the power would wind up averaging to zero. This is not helpful, so I took a tip from Dr. Marc Lichtman s PySDR project and used complex squaring to drive our BPSK signal into a single detectable carrier by squaring the IQ data. Because points are on the unit circle and at tau/2 (specifically, tau/(2^1) for BPSK, 2^2 for QPSK) angles, and given that squaring has the effect of doubling the angle, and angles are all mod tau, this will drive our wave comprised of two opposite phases back into a continuous wave effectively removing our BPSK modulation, making it much easier to detect in the frequency domain. Thanks to Tom Bereknyei for helping me with that!
...
var iq []complex 
var freq []complex 
for i := range iq  
iq[i] = iq[i] * iq[i]
 
// perform an fft, computing the frequency
 // domain vector in  freq  given the iq data
 // contained in  iq .
 fft(iq, freq)
// get the array index of the max value in the
 // freq array given the magnitude value of the
 // complex numbers.
 var binIdx = max(abs(freq))
...
Now, most FFT operations will lay the frequency domain data out a bit differently than you may expect (as a human), which is that the 0th element of the FFT is 0Hz, not the most negative number (like in a waterfall). Generally speaking, zero first is the most common frequency domain layout (and generally speaking the most safe assumption if there s no other documentation on fft layout). Negative first is usually used when the FFT is being rendered for human consumption such as a waterfall plot. Given that we now know which FFT bin (which is to say, which index into the FFT array) contains the strongest signal, we ll go ahead and figure out what frequency that bin relates to. In the time domain, each complex number is the next time instant. In the frequency domain, each bin is a discrete frequency or more specifically a frequency range. The bandwidth of the bin is a function of the sampling rate and number of time domain samples used to do the FFT operation. As you increase the amount of time used to preform the FFT, the more precise the FFT measurement of frequency can be, but it will cover the same bandwidth, as defined by the sampling rate.
...
var sampleRate = 2,621,440
// bandwidth is the range of frequencies
 // contained inside a single FFT bin,
 // measured in Hz.
 var bandwidth = sampleRate/len(freq)
...
Now that we know we have a zero-first layout and the bin bandwidth, we can compute what our frequency offset is in Hz.
...
// binIdx is the index into the freq slice
 // containing the frequency domain data.
 var binIdx = 0
// binFreq is the frequency of the bin
 // denoted by binIdx
 var binFreq = 0
if binIdx > len(freq)/2  
// This branch covers the case where the bin
 // is past the middle point - which is to say,
 // if this is a negative frequency.
 binFreq = bandwidth * (binIdx - len(freq))
  else  
// This branch covers the case where the bin
 // is in the first half of the frequency array,
 // which is to say - if this frequency is
 // a positive frequency.
 binFreq = bandwidth * binIdx
 
...
However, sice we squared the IQ data, we re off in frequency by twice the actual frequency if we are reading 12kHz, the bin is actually 6kHz. We need to adjust for that before continuing with processing.
...
var binFreq = 0
...
// [compute the binFreq as above]
 ...
// Adjust for the squaring of our IQ data
 binFreq = binFreq / 2
...
Finally, we need to shift the frequency by the inverse of the binFreq by generating a carrier wave at a specific frequency and rotating every sample by our carrier wave so that a wave at the same frequency will slow down (or stand still!) as it approaches 0Hz relative to the carrier wave.
 var tau = pi * 2
// ts tracks where in time we are (basically: phase)
 var ts float
// inc is the amount we step forward in time (seconds)
 // each sample.
 var inc float = (1 / sampleRate)
// amount to shift frequencies, in Hz,
 // in this case, shift +12 kHz to 0Hz
 var shift = -12,000
for i := range iq  
ts += inc
if ts > tau  
// not actually needed, but keeps ts within
 // 0 to 2*pi (since it is modulus 2*pi anyway)
 ts -= tau
 
// Here, we're going to create a carrier wave
 // at the provided frequency (in this case,
 // -12kHz)
 cwIq = complex(cos(tau*shift*ts), sin(tau*shift*ts))
iq[i] = iq[i] * cwIq
 
Now we ve got the strong signal we ve observed (which may or may not be our BPSK modulated signal!) close enough to 0Hz that we ought to be able to Phase Lock the signal in order to begin demodulating the signal.

Filter After we re roughly in the neighborhood of a few kHz, we can now take some steps to cut out any high frequency components (both positive high frequencies and negative high frequencies). The normal way to do this would be to do an FFT, apply the filter in the frequency domain, and then do an iFFT to turn it back into time series data. This will work in loads of cases, but I ve found it to be incredibly tricky to get right when doing PSK. As such, I ve opted to do this the old fashioned way in the time domain. I ve again opted to go simple rather than correct, and haven t used nearly any of the advanced level trickery I ve come across for fear of using it wrong. As a result, our process here is going to be generating a sinc filter by computing a number of taps, and applying that in the time domain directly on the IQ stream.
// Generate sinc taps

func sinc(x float) float  
if x == 0  
return 1
 
var v = pi * x
return sin(v) / v
 
...
var dst []float
var length = float(len(dst))
if int(length)%2 == 0  
length++
 
for j := range dst  
i := float(j)
dst[j] = sinc(2 * cutoff * (i - (length-1)/2))
 
...
then we apply it in the time domain
...
// Apply sinc taps to an IQ stream

var iq []complex
// taps as created in  dst  above
 var taps []float
var delay = make([]complex, len(taps))
for i := range iq  
// let's shift the next sample into
 // the delay buffer
 copy(delay[1:], delay)
delay[0] = iq[i]
var phasor complex
for j := range delay  
// for each sample in the buffer, let's
 // weight them by the tap values, and
 // create a new complex number based on
 // filtering the real and imag values.
 phasor += complex(
taps[j] * real(delay[j]),
taps[j] * imag(delay[j]),
)
 
// now that we've run this sample
 // through the filter, we can go ahead
 // and scale it back (since we multiply
 // above) and drop it back into the iq
 // buffer.
 iq[i] = complex(
real(phasor) / len(taps),
imag(phasor) / len(taps),
)
 
...
After running IQ samples through the taps and back out, we ll have a signal that s been filtered to the shape of our designed Sinc filter which will cut out captured high frequency components (both positive and negative). Astute observers will note that we re using the real (float) valued taps on both the real and imaginary values independently. I m sure there s a way to apply taps using complex numbers, but it was a bit confusing to work through without being positive of the outcome. I may revisit this in the future!

Downsample Now, post-filter, we ve got a lot of extra RF bandwidth being represented in our IQ stream at our high sample rate All the high frequency values are now filtered out, which means we can reduce our sampling rate without losing much information at all. We can either do nothing about it and process at the fairly high sample rate we re capturing at, or we can drop the sample rate down and help reduce the volume of numbers coming our way. There s two big ways of doing this; either you can take every Nth sample (e.g., take every other sample to half the sample rate, or take every 10th to decimate the sample stream to a 10th of what it originally was) which is the easiest to implement (and easy on the CPU too), or to average a number of samples to create a new sample. A nice bonus to averaging samples is that you can trade-off some CPU time for a higher effective number of bits (ENOB) in your IQ stream, which helps reduce noise, among other things. Some hardware does exactly this (called Oversampling ), and like many things, it has some pros and some cons. I ve opted to treat our IQ stream like an oversampled IQ stream and average samples to get a marginal bump in ENOB. Taking a group of 4 samples and averaging them results in a bit of added precision. That means that a stream of IQ data at 8 ENOB can be bumped to 9 ENOB of precision after the process of oversampling and averaging. That resulting stream will be at 1/4 of the sample rate, and this process can be repeated 4 samples can again be taken for a bit of added precision; which is going to be 1/4 of the sample rate (again), or 1/16 of the original sample rate. If we again take a group of 4 samples, we ll wind up with another bit and a sample rate that s 1/64 of the original sample rate.

Phase Lock Our starting point for this section is the same capture as above, but post-coarse sync, filtering downsampling (xz compressed interleaved float32, 163,840 samples per second) The PLL in PACKRAT was one of the parts I spent the most time stuck on. There s no shortage of discussions of how hardware PLLs work, or even a few software PLLs, but very little by way of how to apply them and/or troubleshoot them. After getting frustrated trying to follow the well worn path, I decided to cut my own way through the bush using what I had learned about the concept, and hope that it works well enough to continue on. PLLs, in concept are fairly simple you generate a carrier wave at a frequency, compare the real-world SDR IQ sample to where your carrier wave is in phase, and use the difference between the local wave and the observed wave to adjust the frequency and phase of your carrier wave. Eventually, if all goes well, that delta is driven as small as possible, and your carrier wave can be used as a reference clock to determine if the observed signal changes in frequency or phase. In reality, tuning PLLs is a total pain, and basically no one outlines how to apply them to BPSK signals in a descriptive way. I ve had to steal an approach I ve seen in hardware to implement my software PLL, with any hope it s close enough that this isn t a hazard to learners. The concept is to generate the carrier wave (as above) and store some rolling averages to tune the carrier wave over time. I use two constants, alpha and beta (which appear to be traditional PLL variable names for this function) which control how quickly the frequency and phase is changed according to observed mismatches. Alpha is set fairly high, which means discrepancies between our carrier and observed data are quickly applied to the phase, and a lower constant for Beta, which will take long-term errors and attempt to use that to match frequency. This is all well and good. Getting to this point isn t all that obscure, but the trouble comes when processing a BPSK signal. Phase changes kick the PLL out of alignment and it tends to require some time to get back into phase lock, when we really shouldn t even be loosing it in the first place. My attempt is to generate two predicted samples, one for each phase of our BPSK signal. The delta is compared, and the lower error of the two is used to adjust the PLL, but the carrier wave itself is used to rotate the sample.
 var alpha = 0.1
var beta = (alpha * alpha) / 2
var phase = 0.0
var frequency = 0.0
...
for i := range iq  
predicted = complex(cos(phase), sin(phase))
sample = iq[i] * conj(predicted)
delta = phase(sample)
predicted2 = complex(cos(phase+pi), sin(phase+pi))
sample2 = iq[i] * conj(predicted2)
delta2 = phase(sample2)
if abs(delta2) < abs(delta)  
// note that we do not update 'sample'.
 delta = delta2
 
phase += alpha * delta
frequency += beta * delta
// adjust the iq sample to the PLL rotated
 // sample.
 iq[i] = sample
 
...
If all goes well, this loop has the effect of driving a BPSK signal s imaginary values to 0, and the real value between +1 and -1.

Average Idle / Carrier Detect Our starting point for this section is the same capture as above, but post-PLL (xz compressed interleaved float32, 163,840 samples per second) When we start out, we have IQ samples that have been mostly driven to an imaginary component of 0 and real value range between +1 and -1 for each symbol period. Our goal now is to determine if we re receiving a signal, and if so, determine if it s +1 or -1. This is a deceptively hard problem given it spans a lot of other similarly entertaining hard problems. I ve opted to not solve the hard problems involved and hope that in practice my very haphazard implementation works well enough. This turns out to be both good (not solving a problem is a great way to not spend time on it) and bad (turns out it does materially impact performance). This segment is the one I plan on revisiting, first. Expect more here at some point! Given that I want to be able to encapsulate three states in the output from this section (our Symbols are no carrier detected ( 0 ), real value 1 ( 1 ) or real value -1 ("-1")), which means spending cycles to determine what the baseline noise is to try and identify when a signal breaks through the noise becomes incredibly important.
var idleThreshold
var thresholdFactor = 10
...
// sigThreshold is used to determine if the symbol
 // is -1, +1 or 0. It's 1.3 times the idle signal
 // threshold.
 var sigThreshold = (idleThreshold * 0.3) + idleThreshold
// iq contains a single symbol's worth of IQ samples.
 // clock alignment isn't really considered; so we'll
 // get a bad packet if we have a symbol transition
 // in the middle of this buffer. No attempt is made
 // to correct for this yet.
 var iq []complex
// avg is used to average a chunk of samples in the
 // symbol buffer.
 var avg float
var mid = len(iq) / 2
// midNum is used to determine how many symbols to
 // average at the middle of the symbol.
 var midNum = len(iq) / 50
for j := mid; j < mid+midNum; j++  
avg += real(iq[j])
 
avg /= midNum
var symbol float
switch  
case avg > sigThreshold:
symbol = 1
case avg < -sigThreshold:
symbol = -1
default:
symbol = 0
// update the idleThreshold using the thresholdFactor
 // to average the idleThreshold over more samples to
 // get a better idea of average noise.
 idleThreshold = (
(idleThreshold*(thresholdFactor-1) + symbol) \
/ thresholdFactor
)
 
// write symbol to output somewhere
...

Next Steps Now that we have a stream of values that are either +1, -1 or 0, we can frame / unframe the data contained in the stream, and decode Packets contained inside, coming next in Part 4!

Dirk Eddelbuettel: RcppAPT 0.0.8: Package Maintenance

A new version of the RcppAPT package interfacing from R to the C++ library behind the awesome apt, apt-get, apt-cache, commands and their cache powering Debian, Ubuntu and the like arrived on CRAN earlier today. RcppAPT allows you to query the (Debian or Ubuntu) package dependency graph at will, with build-dependencies (if you have deb-src entries), reverse dependencies, and all other goodies. See the vignette and examples for illustrations. This release updates some package metadata, adds a new package testing helper, and, just like digest three days ago, drat two days ago, and littler yesterday, we converted the vignettes from using the minidown package to the (fairly new) simplermarkdown package which is so much more appropriate for our use of the minimal water.css style.

Changes in version 0.0.8 (2021-12-04)
  • New test file version.R ensures NEWS file documents current package version
  • Travis artifacts and badges have been pruned
  • Vignettes now use simplermarkdown

Courtesy of my CRANberries, there is also a diffstat report for this release. A bit more information about the package is available here as well as as the GitHub repo. If you like this or other open-source work I do, you can now sponsor me at GitHub.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

3 December 2021

Paul Tagliamonte: Transmitting BPSK symbols (Part 2/5)

This post is part of a series called "PACKRAT". If this is the first post you've found, it'd be worth reading the intro post first and then looking over all posts in the series.
In the last post, we worked through what IQ is, and different formats that it may be sent or received in. Let s take that and move on to Transmitting BPSK using IQ data! When we transmit and receive information through RF using an SDR, data is traditionally encoded into a stream of symbols which are then used by a program to modulate the IQ stream, and sent over the airwaves. PACKRAT uses BPSK to encode Symbols through RF. BPSK is the act of modulating the phase of a sine wave to carry information. The transmitted wave swaps between two states in order to convey a 0 or a 1. Our symbols modulate the transmitted sine wave s phase, so that it moves between in-phase with the SDR s transmitter and 180 degrees (or radians) out of phase with the SDR s transmitter. The difference between a Bit and a Symbol in PACKRAT is not incredibly meaningful, and I ll often find myself slipping up when talking about them. I ve done my best to try and use the right word at the right stage, but it s not as obvious where the line between bit and symbol is at least not as obvious as it would be with QPSK or QAM. The biggest difference is that there are three meaningful states for PACKRAT over BPSK - a 1 (for In phase ), -1 (for 180 degrees out of phase ) and 0 (for no carrier ). For my implementation, a stream of all zeros will not transmit data over the airwaves, a stream of all 1s will transmit all 1 bits over the airwaves, and a stream of all -1s will transmit all 0 bits over the airwaves. We re not going to cover turning a byte (or bit) into a symbol yet I m going to write more about that in a later section. So for now, let s just worry about symbols in, and symbols out.

Transmitting a Sine wave at 0Hz If we go back to thinking about IQ data as a precisely timed measurements of energy over time at some particular specific frequency, we can consider what a sine wave will look like in IQ. Before we dive into antennas and RF, let s go to something a bit more visual. For the first example, you can see an example of a camera who s frame rate (or Sampling Rate!) matches the exact number of rotations per second (or Frequency!) of the propeller and it appears to stand exactly still. Every time the Camera takes a frame, it s catching the propeller in the exact same place in space, even though it s made a complete rotation. The second example is very similar, it s a light strobing (in this case, our sampling rate, since the darkness is ignored by our brains) at the same rate (frequency) as water dropping from a faucet and the video creator is even nice enough to change the sampling frequency to have the droplets move both forward and backward (positive and negative frequency) in comparison to the faucet. IQ works the same way. If we catch something in perfect frequency alignment with our radio, we ll wind up with readings that are the same for the entire stream of data. This means we can transmit a sine wave by setting all of the IQ samples in our buffer to 1+0i, which will transmit a pure sine wave at exactly the center frequency of the radio.
 var sine []complex 
for i := range sine  
sine[i] = complex(1.0, 0.0)
 
Alternatively, we can transmit a Sine wave (but with the opposite phase) by flipping the real value from 1 to -1. The same Sine wave is transmitted on the same Frequency, except when the wave goes high in the example above, the wave will go low in the example below.
 var sine []complex 
for i := range sine  
sine[i] = complex(-1.0, 0.0)
 
In fact, we can make a carrier wave at any phase angle and amplitude by using a bit of trig.
 // angle is in radians - here we have
 // 1.5 Pi (3 Tau) or 270 degrees.
 var angle = pi * 1.5
// amplitude controls the transmitted
 // strength of the carrier wave.
 var amplitude = 1.0
// output buffer as above
 var sine []complex 
for i := range sine  
sine[i] = complex(
amplitude*cos(angle),
amplitude*sin(angle),
)
 
The amplitude of the transmitted wave is the absolute value of the IQ sample (sometimes called magnitude), and the phase can be computed as the angle (or argument). The amplitude remains constant (at 1) in both cases. Remember back to the airplane propeller or water droplets we re controlling where we re observing the sine wave. It looks like a consistent value to us, but in reality it s being transmitted as a pure carrier wave at the provided frequency. Changing the angle of the number we re transmitting will control where in the sine wave cycle we re observing it at.

Generating BPSK modulated IQ data Modulating our carrier wave with our symbols is fairly straightforward to do we can multiply the symbol by 1 to get the real value to be used in the IQ stream. Or, more simply - we can just use the symbol directly in the constructed IQ data.
 var sampleRate = 2,621,440
var baudRate = 1024
// This represents the number of IQ samples
 // required to send a single symbol at the
 // provided baud and sample rate. I picked
 // two numbers in order to avoid half samples.
 // We will transmit each symbol in blocks of
 // this size.
 var samplesPerSymbol = sampleRate / baudRate
var samples = make([]complex, samplesPerSymbol)
// symbol is one of 1, -1 or 0.
 for each symbol in symbols  
for i := range samples  
samples[i] = complex(symbol, 0)
 
// write the samples out to an output file
 // or radio.
 write(samples)
 
If you want to check against a baseline capture, here s 10 example packets at 204800 samples per second.

Next Steps Now that we can transmit data, we ll start working on a receive path in Part 3, in order to check our work when transmitting the packets, as well as being able to hear packets we transmit from afar, coming up next in Part 3!!

Dirk Eddelbuettel: littler 0.3.15 on CRAN: Package Updates

max-heap image The sixteenth release of littler as a CRAN package just landed, following in the now fifteen year history (!!) as a package started by Jeff in 2006, and joined by me a few weeks later. littler is the first command-line interface for R as it predates Rscript. It allows for piping as well for shebang scripting via #!, uses command-line arguments more consistently and still starts faster. It also always loaded the methods package which Rscript only started to do in recent years. littler lives on Linux and Unix, has its difficulties on macOS due to yet-another-braindeadedness there (who ever thought case-insensitive filesystems as a default were a good idea?) and simply does not exist on Windows (yet the build system could be extended see RInside for an existence proof, and volunteers are welcome!). See the FAQ vignette on how to add it to your PATH. A few examples are highlighted at the Github repo, as well as in the examples vignette. This release brings a more robust and featureful install2.r script (thanks to Gergely Dar czi), corrects some documentation typos (thanks to John Kerl), and now compacts pdf vignette better when using the build.r helper. It also one more updates the URLs for the two RStudio downloaders, and adds a simplermarkdown wrapper. Next, we removed the YAML file (and badge) for the disgraced former continuous integration service we shall not name (yet that we all used to use). And, following digest two days ago and drat yesterday, we converted the vignettes from using the minidown package to the (fairly new) simplermarkdown package which is so much more appropriate for our use of the minimal water.css style. The full change description follows.

Changes in littler version 0.3.15 (2021-12-03)
  • Changes in examples
    • The install2 script can select download methods, and cope with errors from parallel download (thanks to Gergely Daroczi)
    • The build.r now uses both as argument to --compact-vignettes
    • The RStudio download helper were once again updated for changed URLs
    • New caller for simplermarkdown::mdweave_to_html
  • Changes in package
    • Several typos were correct (thanks to John Kerl)
    • Travis artifacts and badges have been pruned
    • Vignettes now use simplermarkdown

My CRANberries service provides a comparison to the previous release. Full details for the littler release are provided as usual at the ChangeLog page, and also on the package docs website. The code is available via the GitHub repo, from tarballs and now of course also from its CRAN page and via install.packages("littler"). Binary packages are available directly in Debian as well as soon via Ubuntu binaries at CRAN thanks to the tireless Michael Rutter. Comments and suggestions are welcome at the GitHub repo. If you like this or other open-source work I do, you can now sponsor me at GitHub.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

Petter Reinholdtsen: A Brazilian Portuguese translation of the book Made with Creative Commons

A few days ago, a productive translator started working on a new translation of the Made with Creative Commons book for Brazilian Portuguese. The translation take place on the Weblate web based translation system. Once the translation is complete and proof read, we can publish it on paper as well as in PDF, ePub and HTML format. The translation is already 16% complete, and if more people get involved I am conviced it can very quickly reach 100%. If you are interested in helping out with this or other translations of the Made with Creative Commons book, start translating on Weblate. There are partial translations available in Azerbaijani, Bengali, Brazilian Portuguese, Dutch, French, German, Greek, Polish, Simplified Chinese, Swedish, Thai and Ukrainian. The git repository for the book contain all source files needed to build the book for yourself. HTML editions to help with proof reading is also available. As usual, if you use Bitcoin and want to show your support of my activities, please send Bitcoin donations to my address 15oWEoG9dUPovwmUL9KWAnYRtNJEkP1u1b.

Evgeni Golov: Dependency confusion in the Ansible Galaxy CLI

I hope you enjoyed my last post about Ansible Galaxy Namespaces. In there I noted that I originally looked for something completely different and the namespace takeover was rather accidental. Well, originally I was looking at how the different Ansible content hosting services and their client (ansible-galaxy) behave in regard to clashes in naming of the hosted content. "Ansible content hosting services"?! There are currently three main ways for users to obtain Ansible content:
  • Ansible Galaxy - the original, community oriented, free hosting platform
  • Automation Hub - the place for Red Hat certified and supported content, available only with a Red Hat subscription, hosted by Red Hat
  • Ansible Automation Platform - the on-premise version of Automation Hub, syncs content from there and allows customers to upload own content
Now the question I was curious about was: how would the tooling behave if different sources would offer identically named content? This was inspired by Alex Birsan: Dependency Confusion: How I Hacked Into Apple, Microsoft and Dozens of Other Companies and zofrex: Bundler is Still Vulnerable to Dependency Confusion Attacks (CVE - 2020 - 36327), who showed that the tooling for Python, Node.js and Ruby can be tricked into fetching content from "the wrong source", thus allowing an attacker to inject malicious code into a deployment. For the rest of this article, it's not important that there are different implementations of the hosting services, only that users can configure and use multiple sources at the same time. The problem is that, if the user configures their server_list to contain multiple Galaxy-compatible servers, like Ansible Galaxy and Automation Hub, and then asks to install a collection, the Ansible Galaxy CLI will ask every server in the list, until one returns a successful result. The exact order seems to differ between versions, but this doesn't really matter for the issue at hand. Imagine someone wants to install the redhat.satellite collection from Automation Hub (using ansible-galaxy collection install redhat.satellite). Now if their configuration defines Galaxy as the first, and Automation Hub as the second server, Galaxy is always asked whether it has redhat.satellite and only if the answer is negative, Automation Hub is asked. Today there is no redhat namespace on Galaxy, but there is a redhat user on GitHub, so The canonical answer to this issue is to use a requirements.yml file and setting the source parameter. This parameter allows you to express "regardless which sources are configured, please fetch this collection from here". That's is nice, but I think this not being the default syntax (contrary to what e.g. Bundler does) is a bad approach. Users might overlook the security implications, as the shorter syntax without the source just "magically" works. However, I think this is not even the main problem here. The documentation says: Once a collection is found, any of its requirements are only searched within the same Galaxy instance as the parent collection. The install process will not search for a collection requirement in a different Galaxy instance. But as it turns out, the source behavior was changed and now only applies to the exact collection it is set for, not for any dependencies this collection might have. For the sake of the example, imagine two collections: evgeni.test1 and evgeni.test2, where test2 declares a dependency on test1 in its galaxy.yml. Actually, no need to imagine, both collections are available in version 1.0.0 from galaxy.ansible.com and test1 version 2.0.0 is available from galaxy-dev.ansible.com. Now, given our recent reading of the docs, we craft the following requirements.yml:
collections:
- name: evgeni.test2
  version: '*'
  source: https://galaxy.ansible.com
In a perfect world, following the documentation, this would mean that both collections are fetched from galaxy.ansible.com, right? However, this is not what ansible-galaxy does. It will fetch evgeni.test2 from the specified source, determine it has a dependency on evgeni.test1 and fetch that from the "first" available source from the configuration. Take for example the following ansible.cfg:
[galaxy]
server_list = test_galaxy, release_galaxy, test_galaxy
[galaxy_server.release_galaxy]
url=https://galaxy.ansible.com/
[galaxy_server.test_galaxy]
url=https://galaxy-dev.ansible.com/
And try to install collections, using the above requirements.yml:
% ansible-galaxy collection install -r requirements.yml -vvv                 
ansible-galaxy 2.9.27
  config file = /home/evgeni/Devel/ansible-wtf/collections/ansible.cfg
  configured module search path = ['/home/evgeni/.ansible/plugins/modules', '/usr/share/ansible/plugins/modules']
  ansible python module location = /usr/lib/python3.10/site-packages/ansible
  executable location = /usr/bin/ansible-galaxy
  python version = 3.10.0 (default, Oct  4 2021, 00:00:00) [GCC 11.2.1 20210728 (Red Hat 11.2.1-1)]
Using /home/evgeni/Devel/ansible-wtf/collections/ansible.cfg as config file
Reading requirement file at '/home/evgeni/Devel/ansible-wtf/collections/requirements.yml'
Found installed collection theforeman.foreman:3.0.0 at '/home/evgeni/.ansible/collections/ansible_collections/theforeman/foreman'
Process install dependency map
Processing requirement collection 'evgeni.test2'
Collection 'evgeni.test2' obtained from server explicit_requirement_evgeni.test2 https://galaxy.ansible.com/api/
Opened /home/evgeni/.ansible/galaxy_token
Processing requirement collection 'evgeni.test1' - as dependency of evgeni.test2
Collection 'evgeni.test1' obtained from server test_galaxy https://galaxy-dev.ansible.com/api
Starting collection install process
Installing 'evgeni.test2:1.0.0' to '/home/evgeni/.ansible/collections/ansible_collections/evgeni/test2'
Downloading https://galaxy.ansible.com/download/evgeni-test2-1.0.0.tar.gz to /home/evgeni/.ansible/tmp/ansible-local-133/tmp9uqyjgki
Installing 'evgeni.test1:2.0.0' to '/home/evgeni/.ansible/collections/ansible_collections/evgeni/test1'
Downloading https://galaxy-dev.ansible.com/download/evgeni-test1-2.0.0.tar.gz to /home/evgeni/.ansible/tmp/ansible-local-133/tmp9uqyjgki
As you can see, evgeni.test1 is fetched from galaxy-dev.ansible.com, instead of galaxy.ansible.com. Now, if those servers instead would be Galaxy and Automation Hub, and somebody managed to snag the redhat namespace on Galaxy, I would be now getting the wrong stuff Another problematic setup would be with Galaxy and on-prem Ansible Automation Platform, as you can have any namespace on the later and these most certainly can clash with namespaces on public Galaxy. I have reported this behavior to Ansible Security on 2021-08-26, giving a 90 days disclosure deadline, which expired on 2021-11-24. So far, the response was that this is working as designed, to allow cross-source dependencies (e.g. a private collection referring to one on Galaxy) and there is an issue to update the docs to match the code. If users want to explicitly pin sources, they are supposed to name all dependencies and their sources in requirements.yml. Alternatively they obviously can configure only one source in the configuration and always mirror all dependencies. I am not happy with this and I think this is terrible UX, explicitly inviting people to make mistakes.

2 December 2021

Jonathan McDowell: Building a desktop to improve my work/life balance

ASRock DeskMini X300 It s been over 20 months since the first COVID lockdown kicked in here in Northern Ireland and I started working from home. Even when the strict lockdown was lifted the advice here has continued to be If you can work from home you should work from home . I ve been into the office here and there (for new starts given you need to hand over a laptop and sort out some login details it s generally easier to do so in person, and I ve had a couple of whiteboard sessions that needed the high bandwidth face to face communication), but day to day is all from home. Early on I commented that work had taken over my study. This has largely continued to be true. I set my work laptop on the stand on a Monday morning and it sits there until Friday evening, when it gets switched for the personal laptop. I have a lovely LG 34UM88 21:9 Ultrawide monitor, and my laptops are small and light so I much prefer to use them docked. Also my general working pattern is to have a lot of external connections up and running (build machine, test devices, log host) which means a suspend/resume cycle disrupts things. So I like to minimise moving things about. I spent a little bit of time trying to find a dual laptop stand so I could have both machines setup and switch between them easily, but I didn t find anything that didn t seem to be geared up for DJs with a mixer + laptop combo taking up quite a bit of desk space rather than stacking laptops vertically. Eventually I realised that the right move was probably a desktop machine. Now, I haven t had a desktop machine since before I moved to the US, realising at the time that having everything on my laptop was much more convenient. I decided I didn t want something too big and noisy. Cheap GPUs seem hard to get hold of these days - I m not a gamer so all I need is something that can drive a ~ 4K monitor reliably enough. Looking around the AMD Ryzen 7 5700G seemed to be a decent CPU with one of the better integrated GPUs. I spent some time looking for a reasonable Mini-ITX case + motherboard and then I happened upon the ASRock DeskMini X300. This turns out to be perfect; I ve no need for a PCIe slot or anything more than an m.2 SSD. I paired it with a Noctua NH-L9a-AM4 heatsink + fan (same as I use in the house server), 32GB DDR4 and a 1TB WD SN550 NVMe SSD. Total cost just under 650 inc VAT + delivery (and that s a story for another post). A desktop solves the problem of fitting both machines on the desk at once, but there s still the question of smoothly switching between them. I read Evgeni Golov s article on a simple KVM switch for 30. My monitor has multiple inputs, so that s sorted. I did have a cheap USB2 switch (all I need for the keyboard/trackball) but it turned out to be pretty unreliable at the host detecting the USB change. I bought a UGREEN USB 3.0 Sharing Switch Box instead and it s turned out to be pretty reliable. The problem is that the LG 32UM88 turns out to have a poor DDC implementation, so while I can flip the keyboard easily with the UGREEN box I also have to manually select the monitor input. Which is a bit annoying, but not terrible. The important question is whether this has helped. I built all this at the end of October, so I ve had a month to play with it. Turns out I should have done it at some point last year. At the end of the day instead of either sitting at work for a bit longer, or completely avoiding the study, I m able to lock the work machine and flick to my personal setup. Even sitting in the same seat that disconnect , and the knowledge I won t see work Slack messages or emails come in and feeling I should respond, really helps. It also means I have access to my personal setup during the week without incurring a hit at the start of the working day when I have to set things up again. So it s much easier to just dip in to some personal tech stuff in the evening than it was previously. Also from the point of view I don t need to setup the personal config, I can pick up where I left off. All of which is really nice. It s also got me thinking about other minor improvements I should make to my home working environment to try and improve things. One obvious thing now the winter is here again is to improve my lighting; I have a good overhead LED panel but it s terribly positioned for video calls, being just behind me. So I think I m looking some sort of strip light I can have behind the large monitor to give a decent degree of backlight (possibly bouncing off the white wall). Lots of cheap options I m not convinced about, and I ve had a few ridiculously priced options from photographer friends; suggestions welcome.

Steve Kemp: It has been some time..

I realize it has been quite some time since I last made a blog-post, so I guess the short version is "I'm still alive", or as Granny Weatherwax would have said:
I ATE'NT DEAD
Of course if I die now this would be an awkward post! I can't think of anything terribly interesting I've been doing recently, mostly being settled in my new flat and tinkering away with things. The latest "new" code was something for controlling mpd via a web-browser: This is a simple HTTP server which allows you to minimally control mpd running on localhost:6600. (By minimally I mean literally "stop", "play", "next track", and "previous track"). I have all my music stored on my desktop, I use mpd to play it locally through a pair of speakers plugged into that computer. Sometimes I want music in the sauna, or in the bedroom. So I have a couple of bluetooth speakers which are used to send the output to another room. When I want to skip tracks I just open the mpd-web site on my phone and tap the button. (I did look at android mpd-clients, but at the same time it seemed like installing an application for this was a bit overkill). I guess I've not been doing so much "computer stuff" outside work for a year or so. I guess lack of time, lack of enthusiasm/motivation. So looking forward to things? I'll be in the UK for a while over Christmas, barring surprises. That should be nice as I'll get to see family, take our child to visit his grandparents (on his birthday no less) and enjoy playing the "How many Finnish people can I spot in the UK?" game

Paul Tagliamonte: Processing IQ data formats (Part 1/5)

This post is part of a series called "PACKRAT". If this is the first post you've found, it'd be worth reading the intro post first and then looking over all posts in the series.
When working with SDRs, information about the signals your radio is receiving are communicated by streams of IQ data. IQ is short for In-phase and Quadrature , which means 90 degrees out of phase. Values in the IQ stream are complex numbers, so converting them to a native complex type in your language helps greatly when processing the IQ data for meaning. I won t get too deep into what IQ is or why complex numbers (mostly since I don t think I fully understand it well enough to explain it yet), but here s some basics in case this is your first interaction with IQ data before going off and reading more.
Before we get started at any point, if you feel lost in this post, it's OK to take a break to do a bit of learning elsewhere in the internet. I'm still new to this, so I'm sure my overview in one paragraph here won't help clarify things too much. This took me months to sort out on my own. It's not you, really! I particularly enjoyed reading visual-dsp.switchb.org when it came to learning about how IQ represents signals, and Software-Defined Radio for Engineers for a more general reference.
Each value in the stream is taken at a precisely spaced sampling interval (called the sampling rate of the radio). Jitter in that sampling interval, or a drift in the requested and actual sampling rate (usually represented in PPM, or parts per million how many samples out of one million are missing) can cause errors in frequency. In the case of a PPM error, one radio may think it s 100.1MHz and the other may think it s 100.2MHz, and jitter will result in added noise in the resulting stream. A single IQ sample is both the real and imaginary values, together. The complex number (both parts) is the sample. The number of samples per second is the number of real and imaginary value pairs per second. Each sample is reading the electrical energy coming off the antenna at that exact time instant. We re looking to see how that goes up and down over time to determine what frequencies we re observing around us. If the IQ stream is only real-valued measures (e.g., float values rather than complex values reading voltage from a wire), you can still send and receive signals, but those signals will be mirrored across your 0Hz boundary. That means if you re tuned to 100MHz, and you have a nearby transmitter at 99.9MHz, you d see it at 100.1MHz. If you want to get an intuitive understanding of this concept before getting into the heavy math, a good place to start is looking at how Quadrature encoders work. Using complex numbers means we can see up in frequency as well as down in frequency, and understand that those are different signals. The reason why we need negative frequencies is that our 0Hz is the center of our SDR s tuned frequency, not actually at 0Hz in nature. Generally speaking, it s doing loads in hardware (and firmware!) to mix the raw RF signals with a local oscillator to a frequency that can be sampled at the requested rate (fundamentally the same concept as a superheterodyne receiver), so a frequency of -10MHz means that signal is 10 MHz below the center of our SDR s tuned frequency. The sampling rate dictates the amount of frequency representable in the data stream. You ll sometimes see this called the Nyquist frequency. The Nyquist Frequency is one half of the sampling rate. Intuitively, if you think about the amount of bandwidth observable as being 1:1 with the sampling rate of the stream, and the middle of your bandwidth is 0 Hz, you would only have enough space to go up in frequency for half of your bandwidth or half of your sampling rate. Same for going down in frequency.

Float 32 / Complex 64 IQ samples that are being processed by software are commonly processed as an interleaved pair of 32 bit floating point numbers, or a 64 bit complex number. The first float32 is the real value, and the second is the imaginary value.
I#0
Q#0
I#1
Q#1
I#2
Q#2
The complex number 1+1i is represented as 1.0 1.0 and the complex number -1-1i is represented as -1.0 -1.0. Unless otherwise specified, all the IQ samples and pseudocode to follow assumes interleaved float32 IQ data streams. Example interleaved float32 file (10Hz Wave at 1024 Samples per Second)

RTL-SDR IQ samples from the RTL-SDR are encoded as a stream of interleaved unsigned 8 bit integers (uint8 or u8). The first sample is the real (in-phase or I) value, and the second is the imaginary (quadrature or Q) value. Together each pair of values makes up a complex number at a specific time instant.
I#0
Q#0
I#1
Q#1
I#2
Q#2
The complex number 1+1i is represented as 0xFF 0xFF and the complex number -1-1i is represented as 0x00 0x00. The complex number 0+0i is not easily representable since half of 0xFF is 127.5.
Complex Number Representation
1+1i []uint8 0xFF, 0xFF
-1+1i []uint8 0x00, 0xFF
-1-1i []uint8 0x00, 0x00
0+0i []uint8 0x80, 0x80 or []uint8 0x7F, 0x7F
And finally, here s some pseudocode to convert an rtl-sdr style IQ sample to a floating point complex number:
...
in = []uint8 0x7F, 0x7F 
real = (float(iq[0])-127.5)/127.5
imag = (float(iq[1])-127.5)/127.5
out = complex(real, imag)
....
Example interleaved uint8 file (10Hz Wave at 1024 Samples per Second)

HackRF IQ samples from the HackRF are encoded as a stream of interleaved signed 8 bit integers (int8 or i8). The first sample is the real (in-phase or I) value, and the second is the imaginary (quadrature or Q) value. Together each pair of values makes up a complex number at a specific time instant.
I#0
Q#0
I#1
Q#1
I#2
Q#2
Formats that use signed integers do have one quirk due to two s complement, which is that the smallest negative number representable s absolute value is one more than the largest positive number. int8 values can range between -128 to 127, which means there s bit of ambiguity in how +1, 0 and -1 are represented. Either you can create perfectly symmetric ranges of values between +1 and -1, but 0 is not representable, have more possible values in the negative range, or allow values above (or just below) the maximum in the range to be allowed. Within my implementation, my approach has been to scale based on the max integer value of the type, so the lowest possible signed value is actually slightly smaller than -1. Generally, if your code is seeing values that low the difference in step between -1 and slightly less than -1 isn t very significant, even with only 8 bits. Just a curiosity to be aware of.
Complex Number Representation
1+1i []int8 127, 127
-1+1i []int8 -128, 127
-1-1i []int8 -128, -128
0+0i []int8 0, 0
And finally, here s some pseudocode to convert a hackrf style IQ sample to a floating point complex number:
...
in = []int8 -5, 112 
real = (float(in[0]))/127
imag = (float(in[1]))/127
out = complex(real, imag)
....
Example interleaved int8 file (10Hz Wave at 1024 Samples per Second)

PlutoSDR IQ samples from the PlutoSDR are encoded as a stream of interleaved signed 16 bit integers (int16 or i16). The first sample is the real (in-phase or I) value, and the second is the imaginary (quadrature or Q) value. Together each pair of values makes up a complex number at a specific time instant. Almost no SDRs capture at a 16 bit depth natively, often you ll see 12 bit integers (as is the case with the PlutoSDR) being sent around as 16 bit integers. This leads to the next possible question, which is are values LSB or MSB aligned? The PlutoSDR sends data LSB aligned (which is to say, the largest real or imaginary value in the stream will not exceed 4095), but expects data being transmitted to be MSB aligned (which is to say the lowest set bit possible is the 5th bit in the number, or values can only be set in increments of 16). As a result, the quirk observed with the HackRF (that the range of values between 0 and -1 is different than the range of values between 0 and +1) does not impact us so long as we do not use the whole 16 bit range.
Complex Number Representation
1+1i []int16 32767, 32767
-1+1i []int16 -32768, 32767
-1-1i []int16 -32768, -32768
0+0i []int16 0, 0
And finally, here s some pseudocode to convert a PlutoSDR style IQ sample to a floating point complex number, including moving the sample from LSB to MSB aligned:
...
in = []int16 -15072, 496 
// shift left 4 bits (16 bits - 12 bits = 4 bits)
 // to move from LSB aligned to MSB aligned.
 in[0] = in[0] << 4
in[1] = in[1] << 4
real = (float(in[0]))/32767
imag = (float(in[1]))/32767
out = complex(real, imag)
....
Example interleaved i16 file (10Hz Wave at 1024 Samples per Second)

Next Steps Now that we can read (and write!) IQ data, we can get started first on the transmitter, which we can (in turn) use to test receiving our own BPSK signal, coming next in Part 2!

Paul Tagliamonte: Intro to PACKRAT (Part 0/5)

Hello! Welcome. I m so thrilled you re here. Some of you may know this (as I ve written about in the past), but if you re new to my RF travels, I ve spent nights and weekends over the last two years doing some self directed learning on how radios work. I ve gone from a very basic understanding of wireless communications, all the way through the process of learning about and implementing a set of libraries to modulate and demodulate data using my now formidable stash of SDRs. I ve been implementing all of the RF processing code from first principals and purely based on other primitives I ve written myself to prove to myself that I understand each concept before moving on. I ve just finished a large personal milestone I was able to successfully send a cURL HTTP request through a network interface into my stack of libraries, through my own BPSK implementation, framed in my own artisanal hand crafted Layer 2 framing scheme, demodulated by my code on the other end, and sent into a Linux network interface. The combination of the Layer 1 PHY and Layer 2 Data Link is something that I ve been calling PACKRAT .
$ curl http://44.127.0.8:8000/
* Connected to 44.127.0.8 (44.127.0.8) port 8000 (#0)
> GET / HTTP/1.1
> Host: localhost:1313
> User-Agent: curl/7.79.1
> Accept: */*
>
* Mark bundle as not supporting multiuse
* HTTP/1.0, assume close after body
< HTTP/1.0 200 OK
< Content-Length: 236
<
____ _ ____ _ ______ _ _____
  _ \ / \ / ___   / / _ \ / \ _ _ 
   _) / _ \      ' /   _)   / _ \    
  __/ ___ \  ___  . \  _ < / ___ \   
 _  /_/ \_\____ _ \_\_  \_\/_/ \_\_ 
* Closing connection 0
In an effort to pay it forward to thank my friends for their time walking me through huge chunks of this, and those who publish their work, I m now spending some time documenting how I was able to implement this protocol. I would never have gotten as far as I did without the incredible patience and kindness of friends spending time working with me, and educators publishing their hard work for the world to learn from. Please accept my deepest thanks and appreciation. The PACKRAT posts are written from the perspective of a novice radio engineer, but experienced software engineer. I ll be leaving out a lot of the technical details on the software end and specific software implementation, focusing on the general gist of the implementation in the radio critical components exclusively. The idea here is this is intended to be a framework a jumping off point for those who are interested in doing this themselves. I hope that this series of blog posts will come to be useful to those who embark on this incredibly rewarding journey after me. This is the first post in the series, and it will contain links to all the posts to follow. This is going to be the landing page I link others to as I publish additional posts, I ll be updating the links on this page. The posts will also grow a tag, which you can check back on, or follow along with here.

Tau Tau ( ) is a much more natural expression of the mathematical constant used for circles which I use rather than Pi ( ). You may see me use Tau in code or text Tau is the same as 2 , so if you see a Tau and don t know what to do, feel free to mentally or textually replace it with 2 . I just hate always writing 2 everywhere and only using (or worse yet 2 /2) .when I mean 1/2 of a circle (or, /2).

Psuedo-code Basicaly none of the code contained in this series is valid on its own. It s very lightly basically Go, and only meant to express concepts in term of software. The examples in the post shouldn t be taken on their own as working snippits to process IQ data, but rather, be used to guide implementations to process the data in question. I d love to invite all readers to try to play at home with the examples, and try and work through the example data captures!

Captures Speaking of captures, I ve included live on-the-air captures of PACKRAT packets, as transmitted from my implementation, in different parts of these posts. This means you can go through the process of building code to parse and receive PACKRAT packets, and then build a transmitter that is validated by your receiver. It s my hope folks will follow along at home and experiment with software to process RF data on their own!

Posts in this series

Dirk Eddelbuettel: drat 0.2.2 on CRAN: Package Maintenance

drat user A fresh and new minor release of drat arrived on CRAN overnight. This is another small update relative to the 0.2.0 release in April followed by a 0.2.1 update in July. This release follows the changes made in digest yesterday. We removed the YAML file (and badge) for the disgraced former continuous integration service we shall not name (yet that we all used to use). And we converted the vignette from using the minidown package to the (fairly new) simplermarkdown package which is so much more appropriate for our use of the minimal water.css style. drat stands for drat R Archive Template, and helps with easy-to-create and easy-to-use repositories for R packages. Since its inception in early 2015 it has found reasonably widespread adoption among R users because repositories with marked releases is the better way to distribute code. See below for a few custom reference examples. Because for once it really is as your mother told you: Friends don t let friends install random git commit snapshots. Properly rolled-up releases it is. Just how CRAN shows us: a model that has demonstrated for two-plus decades how to do this. And you can too: drat is easy to use, documented by six vignettes and just works. Detailed information about drat is at its documentation site. The NEWS file summarises the release as follows:

Changes in drat version 0.2.2 (2021-12-01)
  • Travis artifacts and badges have been pruned
  • Vignettes now use simplermarkdown

Courtesy of my CRANberries, there is a comparison to the previous release. More detailed information is on the drat page as well as at the documentation site. If you like this or other open-source work I do, you can now sponsor me at GitHub.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

1 December 2021

Junichi Uekawa: December.

December. The world is turbulent and I am still worried where we are going.

Next.

Previous.