Search Results: "cas"

11 January 2014

Johannes Schauer: Why do I need superuser privileges when I just want to write to a regular file

I have written a number of scripts to create Debian foreign architecture (mostly armel and armhf) rootfs images for SD cards or NAND flashing. I started with putting Debian on my Openmoko gta01 and gta02 and continued with devices like the qi nanonote, a marvel kirkwood based device, the Always Innovating Touchbook (close to the Beagleboard), the Notion Ink Adam and most recently the Golden Delicious gta04. Once it has been manufactured, I will surely also get my hands dirty with the Neo900 whose creators are currently looking for potential donors/customers to increase the size of the first batch and get the price per unit further down. Creating a Debian rootfs disk image for all these devices basically follows the same steps:
  1. create an disk image file, partition it, format the partitions and mount the / partition into a directory
  2. use debootstrap or multistrap to extract a selection of armel or armhf packages into the directory
  3. copy over /usr/bin/qemu-arm-static for qemu user mode emulation
  4. chroot into the directory to execute package maintainer scripts with dpkg --configure -a
  5. copy the disk image onto the sd card
It was not long until I started wondering why I had to run all of the above steps with superuser privileges even though everything except the final step (which I will not cover here) was in principle nothing else than writing some magic bytes to files I had write access to (the disk image file) in some more or less fancy ways. So I tried using fakeroot+fakechroot and after some initial troubles I managed to build a foreign architecture rootfs without needing root priviliges for steps two, three and four. I wrote about my solution which still included some workarounds in another article here. These workarounds were soon not needed anymore as upstream fixed the outstanding issues. As a result I wrote the polystrap tool which combines multistrap, fakeroot, fakechroot and qemu user mode emulation. Recently I managed to integrate proot support in a separate branch of polystrap. Last year I got the LEGO ev3 robot for christmas and since it runs Linux I also wanted to put Debian on it by following the instructions given by the ev3dev project. Even though ev3dev calls itself a "distribution" it only deviates from pure Debian by its kernel, some configuration options and its initial package selection. Otherwise it's vanilla Debian. The project also supplies some multistrap based scripts which create the rootfs and then partition and populate an SD card. All of this is of course done as the superuser. While the creation of the file/directory structure of the foreign Debian armel rootfs can by now easily be done without superuser priviliges by running multistrap under fakeroot/fakechroot/proot, creating the SD card image still seems to be a bit more tricky. While it is no problem to write a partition table to a regular file, it turned out to be tricky to mount these partition because tools like kpartx and losetup require superuser permissions. Tools like mkfs.ext3 and fuse-ext2 which otherwise would be able to work on a regular file without superuser privileges do not seem to allow to specify the required offsets that the partitions have within the disk image. With fuseloop there exists a tool which allows to "loop-mount" parts of a file in userspace to a new file and thus allows tools like mkfs.ext3 and fuse-ext2 to work as they normally do. But fuseloop is not packaged for Debian yet and thus also not in the current Debian stable. An obvious workaround would be to create and fill each partition in a separate file and concatenate them together. But why do I have to write my data twice just because I do not want to become the superuser? Even worse: because parted refuses to write a partition table to a file which is too small to hold the specified partitions, one spends twice the disk space of the final image: the image with the partition table plus the image with the main partition's content. So lets summarize: a bootable foreign architecture SD card disk image is nothing else than a regular file representing the contents of the SD card as a block device. This disk image is created in my home directory and given enough free disk space there is nothing stopping me from writing any possible permutation of bits to that file. Obviously I'm interested in a permutation representing a valid partition table and file systems with sensible content. Why do I need superuser privileges to generate such a sensible permutation of bits? Gladly it seems that the (at least in my opinion) hardest part of faking chroot and executing foreign architecture package maintainer scripts is already possible without superuser privileges by using fakeroot and fakechroot or proot together with qemu user mode emulation. But then there is still the blocker of creating the disk image itself through some user mode loop mounting of a filesystem occupying a virtual "partition" in the disk image. Why has all this only become available so very recently and still requires a number of workarounds to fully work in userspace? There exists a surprising amount of scripts which wrap debootstrap/multistrap. Most of them require superuser privileges. Does everybody just accept that they have to put a sudo in front of every invocation and hope for the best? While this might be okay for well tested code like debootstrap and multistrap the countless wrapper scripts might accidentally (be it a bug in the code or a typo in the given command line arguments) write to your primary hard disk instead of your SD card. Such behavior can easily be mitigated by not executing any such script with superuser privileges in the first place. Operations like loop mounting affect the whole system. Why do I have to touch anything outside of my home directory (/dev/loop in this case) to populate a file in it with some meaningful bits? Virtualization is no option because every virtualization solution again requires root privileges. One might argue that a number of solutions just require some initial setup by root to then later be used by a regular user (for example /etc/fstab configuration or the schroot approach). But then again: why do I have to write anything outside of my home directory (even if it is only once) to be able to write something meaningful to a file in it? The latter approach also does not work if one cannot become root in the first place or is limited by a virtualized environment. Imagine you are trying to build a Debian rootfs on a machine where you just have a regular user account. Or a situation I was recently in: I had a virtual server which denied me operations like loop mounting. Given all these downsides, why is it still so common to just assume that one is able and willing to use sudo and be done with it in most cases? I really wonder why technologies like fakeroot and fakechroot have only been developed this late. Has this problem not been around since the earliest days of Linux/Unix? Am I missing something and rambling around for nothing? Is this idea a lost cause or something that is worth spending time and energy on to extend and fix the required tools?

8 January 2014

Gunnar Wolf: [review] Packt's Instant Haml

Packt Publishing sent me Krzysztof Niki ski's Instant Haml to do a short blog review... Thing is, and those who read me know, I cannot write short reviews ;-) So lets see how this goes. Packt's Instant series First, as for the format this book follows and the series it fits in: They are very short books. I was the tech reviewer for their Instant Debian Build a Web Server , and when I opened it for the first time, I thought I had received only the first chapter. This series' motto is Short Fast Focused so, yes, the books are ~50 pages long, with ample margins and many big screenshots. I told the editors I was quite unsure about the value this kind of publications add, as they are very similar to online tutorials, but given they have so many books in this series (printed and electronic), there must be a market for them. They surely know their business better than me! There is one other detail regarding the publisher I'll stick in this section, although it is not specific to their Instant series: I do most of my reading in my Kindle. Packt seems to have chosen to specify a very small font for their texts. Besides the two books mentioned, I also have their Object Oriented JavaScript book. For all of the other books I read, I use the smallest font setting. Packt books in mobi format (what they present as Amazon format in their web site) are basically illegible without bumping up the font size through the roof. As I understand it, publishers should use industry-wide default sizes, and let the reader adjust their reading experience. Yes, books of technical nature (such as Packt's) often benefit from having more displayed information than what an ebook reader normally shows... But that's for me to decide! And no, this is not a Kindle-specific glitch: I also get a similar experience when opening it from Calibre. And as for the book... I am a long-time Haml convert/fan; I packaged its Ruby implementation for Debian (and should update it soon :-/ as new versions have appeared), the corresponding Emacs Lisp mode, and I use it for basically all of my static HTML sites and Ruby-based Web systems. Haml is a great templating language, meant to make dynamic HTML generation leaner and easier. It is a clean and elegant technology, and can clearly sell itself. And the project webpage has very good documentation, ranging from a short tutorial and a full API documentation for people to contribute to the project. The first part of this book, of course, covers the "why is Haml so great?" part, presenting the basic equivalences with HTML. In my opinion, the book could be structured a bit differently and would generate a stronger following. Why? Because, even given that Haml is greatly benefited from its Ruby integration and has many hooks to be tightly integrated in a Rails workflow, it can also be used by people who don't want to do Ruby. I have some static websites that are just a bunch of Haml files, compiled by a very simple Makefile and calling the haml command from the shell. I think there would be some value in presenting this invocation before learning how to call it from the Gems environment (i.e. bundle install). Using Haml as a standalone tool is only presented almost as an appendix ("Using HAML outside of Rails" section). Even more so if the author presents four different static-site solutions (probably more non-programmer-friendly than my trusty Makefile). Oh, and this little section uses the (old? obsolete?) uppercase HAML notation for the project's name instead of the now-standard Haml. Dirty screenshots About the screenshots presented in this first section (and I refer mainly to the scaffolding examples), they are meant to show how easy things are, but have an important stylistic mistake: Terminals with transparency might look cool (I hate using them, but then again I'm a very boring person when it comes to my computer habits ;-) ), but transparencies have no place in a book (be it printed or e-book), as the images appear very uncrisp. In the Kindle, they just seemed dirty Now that I'm browsing the PDF from my desktop, I see that the screenshot in "Step 1" has a photo of Earth from space behind the terminal, and even worse, in "Step 2" it is shown over a Web page detailing the installation! These elements are just distracting, and the text would be much cleaerer if it were presented typeset just as a regular code fragment. Opening many of those screenshots in the Kindle was plain useless. Editor integration It is perfectly clear from this text that the author strongly prefers Sublime Text, sometimes uses TextMate, and has just heard reports that Haml has some support in Vim, Rubymine, Emacs and Coda. Of course, devoting a full page (as it is for the first case) for each editor would be out of proportion for this size of book... I just felt the imbalance too big, specially given that most editors will sport approximately the same feature set. Text redundancy If the Instant series is about making short books, I would expect them to be loaded with easy to follow content (as they are), but free of repetition. I felt, however, a large chunk of step 1 of the "Quick start" chapter to be repeated with the the first section of the "Top 6 features" chapter. Yes, the second one adds some depth, but very little. Still, in the later parts of this "Top 6 features" chapter, a more thorough explanation could be used for the Filters, Multiline attributes/code/strings and helpers and extensions sections. It seems the author was on a hurry trying to get it finished, as it is barely explained Explaining a bit more deeply would surely benefit readers. Wrapping up Reading my review, I'm mostly talking about negative issues. IMO, the book is not excellent, but it is clearly not bad. Specially given it fits very well the format for which it was designed. There are many items that could be fixed, and I hope some of them can be fixed (i.e. the screenshots) before the book goes to print If I understand Packt's page correctly, it is currently only available as ebook, contrary to most of the Instant series' titles.

7 January 2014

Vincent Sanders: Healthy discontent is the prelude to progress

Back in the mists of Internet time (2002) when spirits were brave, the stakes were high, men were real men, women were real women and small furry creatures from Alpha Centauri were real small furry creatures from Alpha Centauri there were few hosting options for a budding open source project.

Despite the meteoric rise of many dot com companies in the early noughties a project either had to go it alone by running everything themselves or pick from a small selection of companies that had not yet worked out how to turn free hosting into money.

One such company, arguably the first, was VA Research with their SourceForge system. Many projects used their platform including a small niche web browser called NetSurf. For years the service was great, there were rough edges but nothing awful.

Netsurf issue tracker in the new SourceForge interface
Over time the NetSurf projects requirements grew beyond what SourceForge could provide and service after service was migrated away eventually all that was left was the bug tracking system. This remained the state of affairs until mid 2013 when SourceForge forced a migration to their new platform which made them unsuitable for the projects use case.

Aside from the issue trackers questionable user interface SourceForge had started aggressively placing advertising throughout their platform. Some of the placements so inadvisable that projects started taking the decision to leave.

While I appreciate that SourceForge had to make money to provide a service they appear to have sown discontent within a large part of their user base without understanding that there are a number of alternatives solutions with a much less onerous funding model.

NetSurf used this as an opportunity to move the remaining issue tracking service to our own infrastructure. Rob Kendrick proceeded to evaluate several solutions and in December 2013 I finally found the time to migrate an XML dump of the old data from SourceForge into MantisBT.

Migrating data from one database into another via incompatible formats took me back to my roots. My early career started with programming tasks moving historical business data from ancient large systems which were about to be scrapped to modern Sparc based systems. Later I would be in a role where financial data needed to be retrieved from obsolete proprietary systems and moved into databases on x86 servers.

My experience in this field was not really stretched as it turns out that modern systems can process a few tens of megabytes in seconds rather than the days for a run in my youth! So some ugly perl scripts and a few hours later I had a nice shiny SQL database filled with NetSurfs bugs and MantisBT instance configured to use them.

NetSurf MantisBT instance showing most recently updated open bugs
Then came the hard bit, triaging all the open bugs, fixing up all the bugs submitted as an anonymous user but with email addresses in, removing duplicates and checking every open bug was still valid took almost two weeks of tedious drudge.

I set up an initial bug workflow within the system that the project developers are still fine tuning to better suit their needs but overall Mantis is proving a very flexible tool. The main deficiencies center around configuration for the projects useage, especially removing unused fields from filters and making the workflow more intuitive..

The resulting system is now getting bug reports submitted again where the sourceforge system had had three in the six months since the forced migration.

The issue tracker is once more a useful tool for the developers allowing us to focus on areas actually causing problems for our users and allowing us to see progress we are making fixing issues.

Overall this was a successful migration and provides a platform the NetSurf project can control where we can offer guarantees to our users about their personal information usage and having a clean rapid interface with no advertisements.

6 January 2014

Julian Andres Klode: python-apt now native Python 3 code

Today I made an important change to the python-apt code: It is now native Python 3 code (but also works under Python 2). The previous versions all run 2to3 during the build process to create a Python 3 version. This is no longer needed, as the code is now identical. As part of that change, python-apt now only supports Python 2.7, Python 3.3, and newer. I m using some features only present in 3.3 like Python2 unicode literal syntax in order to keep the code simple. Here s how I did it: I took the Python 2 code and ran 2to3 -f print -x future on it. This turned every print statement in a call to the print function. I then went ahead and added a from __future__ import print_function to the top of each module. This was the first commit. For the second commit, I ran 2to3 -p -x future to convert the remaining stuff to Python 3, and then undid some changes (like unicode literals) and fixed the rest of the changes to work under both Python 2 and 3. Sometimes I added a top-level code like:
if sys.version_info_major >= 3:
    unicode = str
So I could use unicode in the code for the Python 2 cases. I used various backported modules like io and stuff only available in Python 2.7, so dropped support for Python 2.6.
Filed under: Debian, Python

Julien Danjou: Databases integration testing strategies with Python

The Ceilometer project supports various database backend that can be used as storage. Among them are MongoDB, SQLite MySQL, PostgreSQL, HBase, DB2 All Ceilometer's code is unit tested, but when dealing with external storage services, one cannot be sure that the code is really working. You could be inserting data with an incorrect SQL statement, or in the wrong table. Only having the real database storage running and being used can tell you that.
Over the months, we developed integration testing on top of our unit testing to validate that our storage drivers are able to deal with real world databases. That is not really different from generic integration testing. Integration testing is about plugging all the pieces of your software all together and running. In what I call "database integration testing", the pieces will be both your software and the database system that you are going to rely on. The only difference here is that one of the module is not coming from the application itself but is an external project. The type of database that you use (RDBMS, NoSQL ) does not matter. Taking a step back, what I will describe here could also apply to a lot of other different software modules, even something that would not be a database sytem at all. Writing tests for integration Presumably, your Python application has unit tests. In order to test against a database back-end, you need to write a few specific classes of tests that will use the database subsystem for real. For example:
import unittest
import os
import sqlalchemy

class TestDB(unittest.TestCase):
def setUp(self):
url = os.getenv("DB_TEST_URL")
if not url:
self.skipTest("No database URL set")
self.engine = sqlalchemy.create_engine(url)

This code will try to fetch the database URL to use from an environment variable, and then will rely on SQLAlchemy to create a database connection.
import unittest
import os
import sqlalchemy

import myapp

class TestDB(unittest.TestCase):
def setUp(self):
url = os.getenv("DB_TEST_URL")
if not url:
self.skipTest("No database URL set")
self.engine = sqlalchemy.create_engine(url)

def test_foobar(self):
self.assertTrue(myapp.store_integer(self.engine, 42))

You can then add as many tests as you want using the connection stored in self.engine. If no test database URL is, the tests will be skipped; however that decision is up to you. You may want to have these tests always run and fail if they can't be run. In the setUp() method, you may also need to do more work, like create a database and delete a database.
import unittest
import os
import sqlalchemy

class TestDB(unittest.TestCase):
def setUp(self):
url = os.getenv("DB_TEST_URL")
if not url:
self.skipTest("No database URL set")
self.engine = sqlalchemy.create_engine(url)
self.connection = self.engine.connect()
self.connection.execute("CREATE DATABASE testdb")

def tearDown(self):
self.connection.execute("DROP DATABASE testdb")

This will make sure that the database you need is clean and ready to be used to testing. Launching modules, a.k.a. databases
The main problem we encountered when building integration testing with databases, is to find a way to start them. Most users are used to start them system-wide with some sort of init script, but when running sandboxed tests, that is not really a good option. Browsing the documentation of each storage allowed us to find a way to start them in foreground and control them "interactively" via a shell script. The following is a script that you can use to run Python tests using nose and is heavily inspired by the one we wrote for Ceilometer.
#!/bin/bash
set -e

clean_exit()
local error_code="$?"
kill -9 $(jobs -p) >/dev/null 2>&1 true
rm -rf "PGSQL_DATA"
return $error_code


check_for_cmd ()
if ! which "$1" >/dev/null 2>&1
then
echo "Could not find $1 command" 1>&2
exit 1
fi


wait_for_line ()
while read line
do
echo "$line" grep -q "$1" && break
done < "$2"
# Read the fifo for ever otherwise process would block
cat "$2" >/dev/null &


check_for_cmd mongod

trap "clean_exit" EXIT

# Start PostgreSQL process for tests
PGSQL_DATA= mktemp -d /tmp/PGSQL-XXXXX
PGSQL_PATH= pg_config --bindir
PGSQL_PATH /initdb $ PGSQL_DATA
mkfifo $ PGSQL_DATA /out
$ PGSQL_PATH /postgres -F -k $ PGSQL_DATA -D $ PGSQL_DATA &> $ PGSQL_DATA /out &
# Wait for PostgreSQL to start listening to connections
wait_for_line "database system is ready to accept connections" $ PGSQL_DATA /out
export DB_TEST_URL="postgresql:///?host=$ PGSQL_DATA &dbname=template1"

# Run the tests
nosetests

If you use tox to automatize your test run, you can use this scripts (I call it run-test.sh) in your tox.ini file.
[testenv]
commands = toxinidir /run-tests.sh posargs

Most databases are able to be run in some sort of standalone mode where you can connect to them using a either a Unix domain socket, or a fixed port. Here are the snippet used in Ceilometer to run with MongoDB and MySQL:
# Start MongoDB process for tests
MONGO_DATA=$(mktemp -d /tmp/MONGODB-XXXXX)
MONGO_PORT=29000
mkfifo $ MONGO_DATA /out
mongod --maxConns 32 --nojournal --noprealloc --smallfiles --quiet --noauth --port $ MONGO_PORT --dbpath "$ MONGO_DATA " --bind_ip localhost &>$ MONGO_DATA /out &
# Wait for Mongo to start listening to connections
wait_for_line "waiting for connections on port $ MONGO_PORT " $ MONGO_DATA /out
export DB_TEST_URL="mongodb://localhost:$ MONGO_PORT /testdb"

# Start MySQL process for tests
MYSQL_DATA=$(mktemp -d /tmp/MYSQL-XXXXX)
mkfifo $ MYSQL_DATA /out
mysqld --datadir=$ MYSQL_DATA --pid-file=$ MYSQL_DATA /mysql.pid --socket=$ MYSQL_DATA /mysql.socket --skip-networking --skip-grant-tables &> $ MYSQL_DATA /out &
# Wait for MySQL to start listening to connections
wait_for_line "mysqld: ready for connections." $ MYSQL_DATA /out
export DB_TEST_URL="mysql://root@localhost/testdb?unix_socket=$ MYSQL_DATA /mysql.socket&charset=utf8"

The mechanism is always the same. We create a fifo with mkfifo, and then run the database daemon with the output redirected to that fifo. We then read from it until we find a line stating the the database is ready to be used. At that point, we can continue and start running the tests. You have to read continuously from the fifo, otherwise the process writing to it will block. We redirect the output to /dev/null, but you could also redirect it to a different log file, or not at all. One step further: using parallelism and scenarios The described approach is quite simple, as it only support one database type. When using an abstraction layer, such as SQLAlchemy, it would be a good idea to run all these tests against different RDBMS, such as MySQL and PostgreSQL for example. The snippet above allows to run both RDBMS in parallel, but the classic approach of unit tests does not allow that. Using one scenario for each database backend would be a great idea. To that end, you can use the testscenarios library.
import unittest
import os
import sqlalchemy
import testscenarios

load_tests = testscenarios.load_tests_apply_scenarios

class TestDB(unittest.TestCase):
scenarios = [
('mysql', dict(database_connection=os.getenv("MYSQL_TEST_URL")),
('postgresql', dict(database_connection=os.getenv("PGSQL_TEST_URL")),
]

def setUp(self):
if not self.database_connection:
self.skipTest("No database URL set")
self.engine = sqlalchemy.create_engine(self.database_connection)
self.connection = self.engine.connect()
self.connection.execute("CREATE DATABASE testdb")

def tearDown(self):
self.connection.execute("DROP DATABASE testdb")

$ python -m subunit.run test_scenario   subunit2pyunit
test_scenario.TestDB.test_foobar(mysql)
test_scenario.TestDB.test_foobar(mysql) ... ok
test_scenario.TestDB.test_foobar(postgresql)
test_scenario.TestDB.test_foobar(postgresql) ... ok

---------------------------------------------------------
Ran 2 tests in 0.061s

OK

To speed up tests run, you could also run the test in parallel. It can be intesting as you'll be able to spread the workload among a lot of different CPUs. However, note that it can require a different database for each test or a locking mechanism to be in place. It's likely that your tests won't be able to work altogether at the same time on only one database. (Both usage of scenarios and parallelism in testing will be covered in The Hacker's Guide to Python, in case you wonder.)
The Hacker's Guide to Python
A book I'm writing that will be launched soon, talking about designing Python applications, state of the art, and various Python tips. If you want to be the first to hear about the launch, subscribe now.

5 January 2014

Jon Dowland: 2013 In Fiction

I read a lot this year - I'll write more about that and reflections on goodreads in another post - but most of the things I read weren't published in 2013. (I should also write a bit about my thoughts on e-readers). However, it seems I have enough to write about 2013's novels to make a round-up post worthwhile, so here we go.
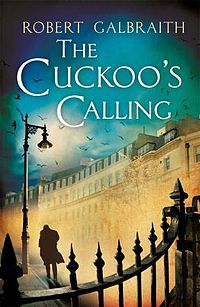
The Cuckoos Calling UK cover
This year, crime author Robert Galbraith published his first novel The Cuckoo's Calling. I'd never have heard of it if Galbraith was not outed as an alias for Joanne "JK" Rowling. Clues that Rowling was working on a detective story exist as early as a Guardian preview article in 2012 for her last novel, The Casual Vacancy. Further hints, for me, that this was no first-time author were the taglines from Ian Rankin and Val McDermid on the cover, writers of a calibre I'd be surprised a new author could attract. However I don't know whether they were on the pre-unveiling cover or not. Rowling was upset be outed, having enjoyed the freedom to write without the baggage of expectation that she is subject to. I hope she's pleased: prior to her unmasking the novel was warmly received by the (admittedly relatively small) number of people who read it. And a very good novel it is too. It starts with a genre clich of a grizzled, meloncholy detective, Mr. Cormoran Strike, in an upstairs office with a neon light flickering through the window, but fleshes the story out both forwards - a client, a mysterious death - and backwards - how did Mr. Strike end up in that upstairs office - living out of it, no less? As is traditional for the genre there's a very clever twist. What I really enjoyed about Cormoran Strike was Galbraith/Rowling moving quickly from Chandler-esque everyman to a well fleshed-out, complex protagonist, intertwining the development of the character with the unfolding of the wider plot. I'm looking forward to the sequel, expected in 2014.
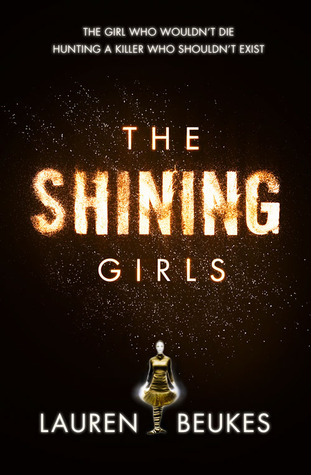
The Shining Girls UK cover
A second surprise favourite this year was Lauren Beukes' time-tripping crime story The Shining Girls. A monsterous murder of women somehow finds a room in Chicago that lets him travel through time (or perhaps the room finds him). He uses this facility to stalk and murder a set of Shining Girls: women who, for one reason or another, literally 'shine' in his perception of them. One such woman survives his first attack and decides to try and find out who attacked her, and why. The crimes are described in a brutal fashion which - from a distance - resemble the sometimes glorified violence for which crime fiction is sometimes criticised, but the focus of the story is very much on the victims: they are fully fleshed out characters and each death is felt by the reader as a genuine tragedy. I discovered Beukes when her earlier novel Zoo City was included in a Humble eBook bundle. On reading The Shining Girls I felt that the novel deserved to be more widely known than I would expect it to be trapped in the ghetto of genre fiction, so I was pleased to discover that the very mainstream Richard and Judy Book Club discovered it. In established author news, Terry Pratchett, having adopted speech recognition for writing (to combat his debilitating Alzheimer's) has seemingly managed to accelerate his rate of production and squeezed out at least two this year: The Long War with Stephen Baxter is the sequel to 2012's The Long Earth which I very much enjoyed, but it really felt like "difficult second novel" to me. Hopefully there'll be a third. Raising Steam, the 40th Discworld novel, was an enjoyable romp around the concept of steam trains, featuring the relatively new Moist von Lipwig who has managed to become one of my favourite Discworld characters. I can't think of much more to say about the novel, really. It's a Discworld novel, probably not the best introduction to the series for a new reader, but will give a reader familiar with the franchise everything they expect, and possibly no more. Iain Banks sadly died this year, shortly after the publication of his last novel, The Quarry. It's sat on my hardback shelf for the time being. I couldn't bring myself to read it in 2013. I did read his last SF offering from the year prior, The Hydrogen Sonata. Sadly, yet coincidentally, both of these books examine the nature of living and dying, The Quarry in particular from the point of view of a terminal cancer sufferer. I have a small backlog of unread Banks fiction which I want to take my time over with. Finally, whilst not really a book, I thoroughly enjoyed the BBC's 2013 adaptation of Neil Gaiman's Neverwhere. Natalie Dormer wrote a piece on the making of the drama which should serve as a good introduction. At the time of writing, most of the programmes have disappeared from iPlayer, but I would be surprised if this wasn't released commercially at some point.

3 January 2014

Russ Allbery: A quick copy-paste UNIX trick

I ran across this trick a long time ago and now use it regularly, but it occurred to me today that I don't remember seeing anyone else mention it. So, just in case it helps someone else: I often find myself wanting to copy and paste the contents of several small files into an email message, particularly when explaining Debian packaging. I want to show all the file contents with little headers showing which lines come from each file. This gets tedious if I actually do this file-by-file. The obvious approaches, from including them into my editor to cat'ing them one-by-one and pasting them, are tedious and require writing the headers by hand. Obviously, cat doesn't help, since it obliterates the difference between the files. What does help, however, is good old head (or tail, for that matter). People normally use those utilities with standard input or a single file, but you can give them multiple files, and they do just about exactly what you want. Consider this shell transcript:
    % head -n 20 *.install
    ==> liblog4shib-dev.install <==
    usr/bin/log4shib-config
    usr/include/*
    usr/lib/*/lib*.a
    usr/lib/*/lib*.so
    usr/lib/*/pkgconfig/log4shib.pc
    usr/share/aclocal/log4shib.m4
    debian/log4shib-config.1 usr/share/man/man1
    ==> liblog4shib-doc.install <==
    usr/share/doc/log4shib-*/api/html usr/share/doc/liblog4shib-doc
    ==> liblog4shib1.install <==
    usr/lib/*/lib*.so.*
Just pick some value for -n that's longer than any of the files (I normally want to show the contents of small files anyway), run head on all the files whose contents you want to show, and then you can cut and paste its full output directly into your email message. Bonus: This behavior is even guaranteed by POSIX (something that I didn't realize until I checked while writing this post).

2 January 2014

Luke Faraone: Unstandardized standards are the worst: sendmail

Implementing software to replace legacy systems is always a challenge, especially when you're dealing with a system with as much legacy as sendmail, which was first introduced as delivermail in 1979.ref

Each UNIX vendor, it seems, rewrote or heavily customized sendmail. This has lead to sometimes conflicting implementations.
Case in point: -tNormally, you invoke sendmail(8) with a series of arguments indicating the subject of a message, the recipients, etc. When invoked this way, the command expects a message on standard input, waits for EOF, and then sends your message along.

However, sometimes you don't want to have to fiddle with command-line parameters; you've already written a perfectly fine message with headers.

-t is generally passed to sendmail when you want to build a message envelope from an already-formatted message, with headers, etc. For example, if you had a file foo.txt with a body like this:
From: Luke Faraone 
To: John Smith
Subject: Hello, world!

Hi there.

you could send the message with a simple invocation of cat foo.txt sendmail -t. The system would take care of ensuring a Message-id was appended if appropriate, and queue the message to be sent. However, it is when you do slightly more complex invocations of sendmail that things get ambiguous.

It turns out that implementations differ on what exactly it means when you use -t in combination with naming destination addresses after the arguments to sendmail. exim4's documentation describes the situation in greater detail:
extract_addresses_remove_ argumentsUse: mainType: booleanDefault: true
According to some Sendmail documentation (Sun, IRIX, HP-UX), if any addresses are present on the command line when the -t option is used to build an envelope from a message s To:, Cc: and Bcc: headers, the command line addresses are removed from the recipients list. This is also how Smail behaves. However, other Sendmail documentation (the O Reilly book) states that command line addresses are added to those obtained from the header lines. When extract_addresses_remove_arguments is true (the default), Exim subtracts argument headers. If it is set false, Exim adds rather than removes argument addresses.

Thus, there's basically no mechanism for a program to know which behaviour to expect. God forbid two programs are installed on a system that expect different behaviours!

It appears that the default behaviour of Ruby is the opposite of what exim4 (Debian's default mail client) expects. This has resulted in numerous bug reports. Some replies suggest changing exim4's defaults, while others advocate overriding ActionMailer and friends to use sendmail -i instead, without -t.

That said, its not really clear who's wrong here; at no point does there appear to have been a definitive specification for sendmail, and as such we can hope for defined behaviour by common custom at best, and a sea of incompatibility bugs at worst. Amusingly, POSIX standards have nothing to say on this subject of sendmail at all; it defines that a mailx command must exist, but says that its sending mode may be implementation-specific.

As Matthew Garrett writes, there's not enough gin in the world.

1 January 2014

Debian Sysadmin Team: Martin Zobel-Helas: Dropping security.geo.debian.org zone

While setting up GeoDNS for parts of the debian.org zone, we set up a new subzone security.geo.debian.org. This was mainly due to the fact we didn't want to mess up the existing zone while experimenting with GeoDNS. Now that our GeoDNS setup has been working for more than half a year without any problems, we will drop this zone. We will do that in two phases.

Phase 1 Beginning on July 1st, we will redirect all requests to security.geo.debian.org to a static webpage indicating that this subzone is deprecated and should not be used any more. If you still have security.geo.debian.org in your apt sources.list, updates will fail.

Phase 2 On August 1st, we will stop serving the subzone security.geo.debian.org from our DNS servers.

Conclusion In case you use a security.geo.debian.org entry in your /etc/apt/sources.list, now is the best time to change that entry to security.debian.org. Both zones currently serve the same content.

Vincent Bernat: Testing infrastructure with serverspec

Checking if your servers are configured correctly can be done with IT automation tools like Puppet, Chef, Ansible or Salt. They allow an administrator to specify a target configuration and ensure it is applied. They can also run in a dry-run mode and report servers not matching the expected configuration. On the other hand, serverspec is a tool to bring the well known RSpec, a testing tool for the Ruby programming language frequently used for test-driven development, to the infrastructure world. It can be used to remotely test server state through an SSH connection. Why one would use such an additional tool? Many things are easier to express with a test than with a configuration change, like for example checking that a service is correctly installed by checking it is listening to some port.

Getting started Good knowledge of Ruby may help but is not a prerequisite to the use of serverspec. Writing tests feels like writing what we expect in plain English. If you think you need to know more about Ruby, here are two short resources to get started: serverspec s homepage contains a short and concise tutorial on how to get started. Please, read it. As a first illustration, here is a test checking a service is correctly listening on port 80:
describe port(80) do
  it   should be_listening  
end
The following test will spot servers still running with Debian Squeeze instead of Debian Wheezy:
describe command("lsb_release -d") do
  it   should return_stdout /wheezy/  
end
Conditional tests are also possible. For example, we want to check the miimon parameter of bond0, but only when the interface is present:
has_bond0 = file('/sys/class/net/bond0').directory?
# miimon should be set to something other than 0, otherwise, no checks
# are performed.
describe file("/sys/class/net/bond0/bonding/miimon"), :if => has_bond0 do
  it   should be_file  
  its(:content)   should_not eq "0\n"  
end
serverspec comes with a complete documentation of available resource types (like port and command) that can be used after the keyword describe. When a test is too complex to be expressed with simple expectations, it can be specified with arbitrary commands. In the below example, we check if memcached is configured to use almost all the available system memory:
# We want memcached to use almost all memory. With a 2GB margin.
describe "memcached" do
  it "should use almost all memory" do
    total = command("vmstat -s   head -1").stdout #  
    total = /\d+/.match(total)[0].to_i
    total /= 1024
    args = process("memcached").args #  
    memcached = /-m (\d+)/.match(args)[1].to_i
    (total - memcached).should be > 0
    (total - memcached).should be < 2000
  end
end
A bit more arcane, but still understandable: we combine arbitrary shell commands (in ) and use of other serverspec resource types (in ).

Advanced use Out of the box, serverspec provides a strong fundation to build a compliance tool to be run on all systems. It comes with some useful advanced tips, like sharing tests among similar hosts or executing several tests in parallel. I have setup a GitHub repository to be used as a template to get the following features:
  • assign roles to servers and tests to roles;
  • parallel execution;
  • report generation & viewer.

Host classification By default, serverspec-init generates a template where each host has its own directory with its unique set of tests. serverspec only handles test execution on remote hosts: the test execution flow (which tests are executed on which servers) is delegated to some Rakefile1. Instead of extracting the list of hosts to test from a directory hiearchy, we can extract it from a file (or from an LDAP server or from any source) and attach a set of roles to each of them:
hosts = File.foreach("hosts")
  .map    line  line.strip  
  .map do  host 
   
    :name => host.strip,
    :roles => roles(host.strip),
   
end
The roles() function should return a list of roles for a given hostname. It could be something as simple as this:
def roles(host)
  roles = [ "all" ]
  case host
  when /^web-/
    roles << "web"
  when /^memc-/
    roles << "memcache"
  when /^lb-/
    roles << "lb"
  when /^proxy-/
    roles << "proxy"
  end
  roles
end
In the snippet below, we create a task for each server as well as a server:all task that will execute the tests for all hosts (in ). Pay attention, in , at how we attach the roles to each server.
namespace :server do
  desc "Run serverspec to all hosts"
  task :all => hosts.map    h  h[:name]   #  
  hosts.each do  host 
    desc "Run serverspec to host # host[:name] "
    ServerspecTask.new(host[:name].to_sym) do  t 
      t.target = host[:name]
      #  : Build the list of tests to execute from server roles
      t.pattern = './spec/ ' + host[:roles].join(",") + ' /*_spec.rb'
    end
  end
end
You can check the list of tasks created:
$ rake -T
rake check:server:all      # Run serverspec to all hosts
rake check:server:web-10   # Run serverspec to host web-10
rake check:server:web-11   # Run serverspec to host web-11
rake check:server:web-12   # Run serverspec to host web-12
Then, you need to modify spec/spec_helper.rb to tell serverspec to fetch the host to test from the environment variable TARGET_HOST instead of extracting it from the spec file name.

Parallel execution By default, each task is executed when the previous one has finished. With many hosts, this can take some time. rake provides the -j flag to specify the number of tasks to be executed in parallel and the -m flag to apply parallelism to all tasks:
$ rake -j 10 -m check:server:all

Reports rspec is invoked for each host. Therefore, the output is something like this:
$ rake spec
env TARGET_HOST=web-10 /usr/bin/ruby -S rspec spec/web/apache2_spec.rb spec/all/debian_spec.rb
......
Finished in 0.99715 seconds
6 examples, 0 failures
env TARGET_HOST=web-11 /usr/bin/ruby -S rspec spec/web/apache2_spec.rb spec/all/debian_spec.rb
......
Finished in 1.45411 seconds
6 examples, 0 failures
This does not scale well if you have dozens or hundreds of hosts to test. Moreover, the output is mangled with parallel execution. Fortunately, rspec comes with the ability to save results in JSON format. Those per-host results can then be consolidated into a single JSON file. All this can be done in the Rakefile:
  1. For each task, set rspec_opts to --format json --out ./reports/current/# target .json. This is done automatically by the subclass ServerspecTask which also handles passing the hostname in an environment variable and a more concise and colored output.
  2. Add a task to collect the generated JSON files into a single report. The test source code is also embedded in the report to make it self-sufficient. Moreover, this task is executed automatically by adding it as a dependency of the last serverspec-related task.
Have a look at the complete Rakefile for more details on how this is done. A very simple web-based viewer can handle those reports2. It shows the test results as a matrix with failed tests in red: Report viewer example Clicking on any test will display the necessary information to troubleshoot errors, including the test short description, the complete test code, the expectation message and the backtrace: Report viewer showing detailed error I hope this additional layer will help making serverspec another feather in the IT cap, between an automation tool and a supervision tool.

  1. A Rakefile is a Makefile where tasks and their dependencies are described in plain Ruby. rake will execute them in the appropriate order.
  2. The viewer is available in the GitHub repository in the viewer/ directory.

Russ Allbery: Review: The Female Man

Review: The Female Man, by Joanna Russ
Publisher: Beacon
Copyright: 1975
Printing: 1986
ISBN: 0-8070-6299-5
Format: Trade paperback
Pages: 214
The Female Man is one of the most famous novels of feminist science fiction, written by a giant of the field. Joanna Russ was one of the strongest writers of the first era of explicitly feminist SF and one of the most challenging. Along with Alice Sheldon (James Tiptree, Jr.) and Sheri Tepper, she's probably the best known author whose approach tended towards the directly confrontational. She was also a noted essayist, critic, and reviewer; her book How to Suppress Women's Writing is one of the most famous works of feminist literary criticism. That said, I wasn't sure what to expect from this book. I'd heard that it was about four different women: Jeannine, Joanna, Janet, and Jael. They're parallels of sorts but from far different cultures, alternate worlds displaced in time. I'd also heard that it was full of biting, accurate sarcasm, which is certainly the case. This is a book written from a place of righteous anger combined with keen social observation and a desire to point out how different the world could be. And how toxic male behavior towards women currently is. What it's not, however, is much of a novel, in the sense of having a clear plot that carries the reader through the book. There is a story of sorts, which revolves around the appearance of Janet in Joanna's time. Janet is a native of Whileaway, an alternate future Earth in which there are no men at all and social organization is significantly different. We get a fairly detailed description of her life and of some Whileaway customs over the course of the book. But they're mixed with excerpts from the lives of both Jeannine (from an alternate past in which the Great Depression never ended) and Joanna. If Janet's story is a sort of utopian alternate future, following the basic model of female separatist societies, Jeannine's is the dystopia drawn from our past. She's locked entirely into traditional gender roles and the desire to catch a man and be a wife. I found her the hardest character to read about by far, largely because she locks herself into the worst constraints of that role. She's almost entirely passive, and she's devoted to a man for whom it's difficult to have any respect at all. Janet is interesting in part because she's not particularly exceptional in either ability or intelligence. She just reflects the Whileaway culture, which leads to some sharp conflicts with the norms of Joanna's time. It's a very effective tactic for alienating the reader from current gender roles (or, at least, roles from the 1970s) and showing how absurd they appear with a different set of starting assumptions. Russ makes the point clearly; this is not a book that tends towards the subtle, although it can be a little hard to track the characters' progress through alternate timelines. Towards the end of the book, they meet the fourth character. (This is not really the sort of book that is possible to spoil by summary.) Jael is by far the most aggressive of any of them, the closest that any of them come to the caricature of a "man-hating feminist." One of the strengths of The Female Man is that, by the time the story reaches her, I at least was feeling quite a lot of sympathy towards her aggressively violent approach, after watching Joanna be put down and Jeannine simper ineffectually. However, it's worth nothing that Janet, the representative of the supposed utopia, does not agree with Jael or her methods, and the relationship between their worlds is interestingly complex. None of the four characters are exactly wrong (although Jeannine comes close); none of them are entirely right either. They're all struggling in different ways with how to define femininity. While the quiet and simplicity of Janet's world has definite appeal, it's the sort of utopia that one isn't sure one would actually want. And Jael has some pointed commentary on how wanting such a world is one thing, but the acts required to create it is quite another. I can see why this book is so well-known. Many of the scenes that show gender relations and male behavior are both painful and funny. Reading it forty years after it was written, it's clear that social norms have changed; men do and say things here that they would no longer be able to get away with, that are clearly from another era. But it's also clear that some of the underlying attitudes have not changed, just been cloaked in different language. And Russ's bluntness here is refreshing: this book does not pull its punches, both in openly ridiculing sexist behavior, and in showing how oppressive it is for women. That said, it didn't work as a story for me, in part because the plot is sketchy at best. It's a collection of individual excerpts and commentary, only some of which are shaped like a story. Much of it feels stream of consciousness, and when cut between three different viewpoints, it's also occasionally confusing. There are also a few too-obvious characters: some of the men, particularly in Jael's section, but also Jeannine, who I never liked even after she starts changing her mind about women's roles. I wanted a bit more story and a bit less introspection. I think this is an important book that's worth reading, and sadly it's not as obsolete as one would like. But I don't think it's entirely successful as a novel. Best treated as a piece of literary history. Rating: 6 out of 10

Andrew Pollock: [life] It's a new year, it's a new me

Well, it's 2014. The annus horribilus of 2013 is behind me. I'm entering 2014 in a much better place (on multiple levels) than I did for 2013. I'm positively excited to see what 2014 brings me. I was very fortunate to have someone I looked up to reach out to help me when my marriage fell apart. One of the things he said to me was "A year from now, you won't recognise yourself". He was right. I am such a different person today than I was a year ago. I'm happier, fitter, more self-confident. I'm focusing on different things in my life. One thing that has been a casualty, has been my geeky pursuits. There were a few times last year where I questioned if I was still a geek. I am. I've just deprioritised it. Instead, I've been putting my own self-care and my daughter above all else, meaning that my running has probably been the one thing I'd call a "hobby" at the moment. I've got some stuff in the pipeline that I'm not quite ready to write about yet, but I'm expecting a rearrangement of my time that will hopefully allow for some more geeky endeavours in 2014. I'm also hoping I can regain some momentum on blogging. Here's what I'd say my goals are, going into 2014: plus some other stuff I'm not ready to talk about yet.

31 December 2013

Paul Tagliamonte: Hy 0.9.12 released

Good morning all my hungover friends. New Hy release - sounds like the perfect thing to do while you re waiting for your headaches to go away. Here s a short-list of the changes (from NEWS) - enjoy!
Changes from Hy 0.9.11
   tl;dr:
    0.9.12 comes with some massive changes,
    We finally took the time to implement gensym, as well as a few
    other bits that help macro writing. Check the changelog for
    what exactly was added. 
    
    The biggest feature, Reader Macros, landed later
    in the cycle, but were big enough to warrent a release on it's
    own. A huge thanks goes to Foxboron for implementing them
    and a massive hug goes out to olasd for providing ongoing
    reviews during the development.
    
    Welcome to the new Hy contributors, Henrique Carvalho Alves,
    Kevin Zita and Kenan B l kba . Thanks for your work so far,
    folks!
    
    Hope y'all enjoy the finest that 2013 has to offer,
      - Hy Society
    * Special thanks goes to Willyfrog, Foxboron and theanalyst for writing
      0.9.12's NEWS. Thanks, y'all! (PT)
    [ Language Changes ]
    * Translate foo? -> is_foo, for better Python interop. (PT)
    * Reader Macros!
    * Operators + and * now can work without arguments
    * Define kwapply as a macro
    * Added apply as a function
    * Instant symbol generation with gensym
    * Allow macros to return None
    * Add a method for casting into byte string or unicode depending on python version
    * flatten function added to language
    * Add a method for casting into byte string or unicode depending on python version
    * Added type coercing to the right integer for the platform
    [ Misc. Fixes ]
    * Added information about core team members
    * Documentation fixed and extended
    * Add astor to install_requires to fix hy --spy failing on hy 0.9.11.
    * Convert stdout and stderr to UTF-8 properly in the run_cmd helper.
    * Update requirements.txt and setup.py to use rply upstream.
    * tryhy link added in documentation and README
    * Command line options documented
    * Adding support for coverage tests at coveralls.io
    * Added info about tox, so people can use it prior to a PR
    * Added the start of hacking rules
    * Halting Problem removed from example as it was nonfree
    * Fixed PyPI is now behind a CDN. The --use-mirrors option is deprecated.
    * Badges for pypi version and downloads.
    [ Syntax Fixes ]
    * get allows multiple arguments
    [ Bug Fixes ]
    *  OSX: Fixes for readline Repl problem which caused HyREPL not allowing 'b'
    * Fix REPL completions on OSX
    *  Make HyObject.replace more resilient to prevent compiler breakage.
    [ Contrib changes ]
    * Anaphoric macros added to contrib
    * Modified eg/twisted to follow the newer hy syntax
    * Added (experimental) profile module

30 December 2013

Russ Allbery: Init system evaluation thanks

Most people who follow Debian are probably aware that we're currently in the middle of a major debate over the future of Debian's init system. Over the past month, and particularly over the past week, I undertook an evaluation of two of the options in that debate, using one of my packages as a test bed. I also did a lot of reading, filed a few bugs, and asked a bunch of questions. That's an extension of the questions I've been asking and discussions I've been participating in around init systems for the past year plus. I have been keeping my opinions and writeups confined to the relevant Techncial Committee bug report so that they can be read in context with their rebuttals. There are a lot of thoughtful and well-informed opinions here, of which mine are only one, and several of my conclusions have been inaccurate or at least not complete, so the context is important. You can find the full traffic in the Technical Committee bug. Most of the discussion, in a threaded view, is in the Technical Committee archives for December. However, in one of the messages I sent today, I tried to show my appreciation for the people who have assisted with this evaluation over the past week, month, and years, and I think that section deserves broader distribution outside of the ongoing discussion. It is therefore included below. Throughout this evaluation process, my interactions with upstart and systemd upstream developers and Debian packagers have been uniformly excellent. Bug reports filed against both systemd and upstart have received excellent and timely response, and all involved have been quite willing to explain things I've misunderstood, correct my false starts, and discuss technical and practical aspects of their designs. I was particularly impressed by the clear effort that the systemd and upstart maintainers in Debian have put into fully integrating their init systems in such a way that makes them easy to test and use with existing Debian packages. This includes but is not limited to update-rc.d support, invoke-rc.d support, status synchronization with sysvinit, past Policy discussion, and attention to upgrade paths and init-switching use cases. I also want to particularly thank the OpenRC upstream development team for their involvement in this process and their contributions to the discussion. I personally don't think that package is a good match for Debian's needs on Linux, but that's through no fault of the people involved, and I think they would be an excellent upstream if that package looked like a good fit for the needs of any of Debian's non-Linux ports. I also want to thank Petter Reinholdtsen, Roger Leigh, and everyone else who has worked on the sysvinit package over the years, the insserv conversion to dependency-based boot, and the inclusion of LSB support. If it weren't for their hard work, we would be in a far worse position than we are today. It's often hard to see people discussing the inadequacies of something into which you put years of hard work. I want to call attention to their long-term contributions to the distribution, and to the number of Debian systems that have booted through their efforts over the years.

29 December 2013

Steve Kemp: A good week?

This week my small collection of sysadmin tools received a lot of attention; I've no idea what triggered it, but it ended up on the front-page of github as a "trending repository". Otherwise I've recently spent some time "playing about" with some security stuff. My first recent report wasn't deemed worthy of a security update, but it was still a fun one. From the package description rush is described as:
GNU Rush is a restricted shell designed for sites providing only limited access to resources for remote users. The main binary executable is configurable as a user login shell, intended for users that only are allowed remote login to the system at hand.
As the description says this is primarily intended for use by remote users, but if it is installed locally you can read "any file" on the local system. How? Well the program is setuid(root) and allows you to specify an arbitrary configuration file as input. The very very first thing I tried to do with this program was feed it an invalid and unreadable-to-me configuration file. Helpfully there is a debugging option you can add --lint to help you setup the software. Using it is as simple as:
shelob ~ $ rush --lint /etc/shadow
rush: Info: /etc/shadow:1: unknown statement: root:$6$zwJQWKVo$ofoV2xwfsff...Mxo/:15884:0:99999:7:::
rush: Info: /etc/shadow:2: unknown statement: daemon:*:15884:0:99999:7:::
rush: Info: /etc/shadow:3: unknown statement: bin:*:15884:0:99999:7:::
rush: Info: /etc/shadow:4: unknown statement: sys:*:15884:0:99999:7:::
..
How nice? The only mitigating factor here is that only the first token on the line is reported - In this case we've exposed /etc/shadow which doesn't contain whitespace for the interesting users, so it's enough to start cracking those password hashes. If you maintain a setuid binary you must be trying things like this. If you maintain a setuid binary you must be confident in the codebase. People will be happy to stress-test, audit, examine, and help you - just ask. Simple security issues like this are frankly embarassing. Anyway that's enough: #733505 / CVE-2013-6889.

Russ Allbery: Review: The Incrementalists

Review: The Incrementalists, by Steven Brust & Skyler White
Publisher: Tor
Copyright: September 2013
ISBN: 0-7653-3422-4
Format: Hardcover
Pages: 304
The Incrementalists are a secret society that has been in continuous existence for forty thousand years. The members are immortal... sort of (more on that in a moment). They are extremely good at determining what signals, triggers, and actions have the most impact on people, and adept at using those triggers to influence people's behavior. And they're making the world better. Not in any huge, noticeable way, just a little bit, here and there. Incrementally. Brust and White completely had me with this concept. There are several SF novels about immortals, but (apart from the vampire subgenre) they mostly stay underground and find ways to survive without trying to change the surrounding human society. I love the idea of small, incremental changes, and I was looking forward to reading a book about how that would work. How do they choose what to do? How do they find the right place to push? What long-term goals would such an organization pursue, and what governance structure would they use? I'm still wondering about most of those things, sadly, since that isn't what this novel is about at all. I should be fair: a few of those questions hover in the background. There are some political arguments (that parallel arguments on Brust's blog), and a tiny bit about governance. But mostly this is a sort of romance, a fight over identity, and an extensive exploration of the mental "garden" that the Incrementalists use and build to hold their memories and share information with each other. The story revolves around two Incrementalists: Phil, who is one of the leaders and has one of the longest continuous identities of any of the group, and Renee, a new recruit by Phil who picks up the memories and capabilities (sort of) of the recently-deceased Incrementalist Celeste. Phil is the long-term insider, although a fairly laid-back one. Renee is the outsider, the one to which the story is happening at the beginning, who is taught how the Incrementalists' system works. The Incrementalists is told in alternating first-person viewpoint sections by Phil and Renee (making me wonder if the characters were each written by one of the authors). Once I got past my disappointment over this book not being quite what I wanted, the identity puzzles that Brust and White play with here caught my attention. The underlying "magic" of the Incrementalists is based on the "memory palace" concept of storing memories via visualizations, but takes it into something akin to personal alternate worlds. Their immortality isn't through physical immortality, but rather the ability to store their memories and personality in their garden, which is their term for the memory palace, and then have it imposed on someone else: a combination of reincarnation, mental takeover, and mental merging. This makes for complex interpersonal relationships and complex interactions between memory, belief, and identity, not to mention some major ethical issues, which come to a head in Phil and Renee's relationship and Celeste's lingering meddling. I think Brust and White are digging into some interesting questions of character here. There's a lot of emphasis in The Incrementalists on the ease with which people can be manipulated, and the Incrementalists themselves are far from immune. Choice and personal definition are both questionable concepts given how much influence other people have, how many vulnerabilities everyone carries with them, and how much one's opinions are governed by one's life history. That makes identity complex, and raises the question of whether one can truly define oneself. But, while all these ideas are raised, I think The Incrementalists dances around them more than engages them directly. It's similar to the background hook: yes, these people are slowly improving the world, and we see a little bit of that (and a little bit of them manipulating people for their own convenience), but the story doesn't fully engage with the idea. There's a romance, a few arguments, some tension, some world-building, but I don't feel like this book ever fully committed to any of them. One of the occasional failure modes of Brust for me is insufficient explanation and insufficient clarity, and I hit that here. My final impression of The Incrementalists is interesting, enjoyable, but vaguely disappointing. It's still a good story with some interesting characters and nice use of the memory palace concept, and I liked Renee throughout (although I think the development of the love story is disturbingly easy and a little weird). But I can't strongly recommend it, and I'm not sure if it's worth seeking out. Rating: 7 out of 10

Gergely Nagy: Introducing the syslog-ng Incubator

When syslog-ng 3.5.1 was released, the existence of the syslog-ng Incubator project was already announced, but I did not go into detail as to why it exists, what is in there, how to build it, or how to use it. The documentation that exists on it is almost non-existent, and what does exist, is usually in the form of a commit message and some example files. But there's nothing on how the things in the Incubator can be used, and what problems they solve.With this post, I will try to ease the situation a little, and provide some insight on how I use some of the things in there, like the Riemann destination.About the IncubatorThe idea for the Incubator existed for a long time, the first incarnation of it was called syslog-ng module collection, and had a different scope: it was a playing field not only for new modules, but updates to existing ones too. The idea was to try out new, possibly experimental features separately from syslog-ng. That didn't work well: it was a nightmare to maintain, and even harder to use. So it never got anywhere, as the developments made there were quickly merged into syslog-ng itself anyway.Then, two years later, I had a need for a new destination, but there was no open development branch to base it against, and forking and maintaining a whole syslog-ng branch for the purpose of a single module sounded like an overkill. So the Incubator was born, from the ashes of the failed module collection.The purpose of the Incubator is to be a place of experimental modules, and an easier way to enter the world syslog-ng development. It's something with far less requirements than syslog-ng (I do not care all that much about portability when it comes to the Incubator, especially not to horrible abominations like HP-UX or AIX), less rules, and more freedom. It's meant to be more developer friendly than syslog-ng proper.It also serves as an example of developing modules completely external to syslog-ng, and parts of it will be used in future posts of mine, to demonstrate the development of new modules.Compiling & InstallationThe first thing we need to do, is to compile whatever we need from the Incubator, unless we happen to have pre-built binaries available (which are going to appear in your usual third-party syslog-ng repositories over the next few weeks). For this, at a minimum, one will need syslog-ng 3.5+ and ivykis installed, along with autotools (autoconf, automake and libtool), pkg-config, bison, and depending on which modules one needs, riemann-c-client and libmongo-client too. Most of these are available packaged in better distributions, but only in recent versions, so one may need to compile those too. They follow a very similar scheme, though.If everything is installed at the standard locations, getting the Incubator to compile is as simple as this:
$ git clone https://github.com/balabit/syslog-ng-incubator.git
$ cd syslog-ng-incubator
$ autoreconf -i
$ ./configure && make && sudo make install
If anything happens to be installed in a non-standard location, one will need to adjust PKG_CONFIG_PATH to help the configure script locate the needed libraries.Once installed (the configure script will figure out where syslog-ng modules are, and modules will be put there), syslog-ng will automatically recognise the new modules. One can make sure that this is the case by running the following command after installation:
$ syslog-ng --module-registry
The PluginsNow that we're over the hard part of compiling and installing the Incubator, lets see what is inside! I will start with the easier things, and move on to the more complicated features as we progress. That is, we'll start with some template functions, have a glance at the trigger source, then explore the rss destination, and finish off with the riemann destination.Template functionsThe Incubator gives us three new template functions, some less useful than the others, and one that's a huge, ugly hack for a problem that I ended up solving in a very different way - without the hack.These functions are the $(or) template function, which takes any number of arguments, and returns the first one that is not empty. The main use case here is that if you have, say, similarly named fields, but some messages have one, the others another, and you want to normalize it, $(or) is one way to do it:
$(or $ HOST  $ HOSTNAME  $ HOST_NAME  "<unknown>")
Another function is $(//), which does the same thing as the built-in $(/) template function: divide its arguments. Except this one works with floating-point numbers only, while the built-in one is for integers exclusively. Using it is simple, too:
$(// $ some_number  3.4)
The last template function provided by the Incubator is $(state), which can be used to maintain global state, that does not depend on log messages. You can set values in here, like counters, from within a template function. It is possible to count the total amount downloaded data when processing a HTTP server log, for example. But it's slow, and there are better ways to do the same thing, syslog-ng really isn't the best tool for this kind of job. If anyone happens to find a use-case for it, please let me know. As for using it, it has two modes: set (with two arguments) and get (with one):
$(state some-variable $ VALUE )
$(state some-variable)
Trigger sourceThe trigger source has many in common with the built-in mark feature: at given intervals, it sends a message. This is mostly a debugging aid, when you want to generate messages without an external tool. It only has two options: trigger-freq() and trigger-message(), which default to 10 and "Trigger source is trigger happy.", respectively. It also accepts a number of common source options such as program-override(), host-override() and tags().To use it, one just needs to set it up like any other source, and bind it to a destination with a log statement:
source s_trigger  
 trigger(
  program-override("trigger")
  tags("trigger-happy")
  trigger-freq(5)
  trigger-message("Beep.")
 );
 ;
Without a program-override() option, messages will be attributed to syslog-ng, which is likely not what you want, even while debugging. Internal messages are usually routed somewhere else.RSS destinationThe RSS destination is an interesting beast. It offers an Atom feed of the last hundred messages routed to the destination. I could very well imagine this being useful in a situation where one already has monitoring set up to listen on various RSS sources - this would be just another. It also works well with most RSS feed readers. The length of the feed is not configurable at this time, and the number of options is limited to port(), title(), entry-title() and entry-description().The first one specifies which port the destination should listen on (it serves one client at a time!); title() can be used to set the title of the feed itself, while entry-title() and entry-description() can be used with templates to fill in the per-message Atom entries.Once we have a suitable path we want to route to the RSS destination (such as critical error messages only), we can set it up like this:
destination d_rss  
 rss(
  port(8192)
  feed-title("Critical errors in the system")
  entry-title("Error from $ PROGRAM  @ $ HOST_FROM  at $ ISODATE ")
  entry-description("$ MESSAGE ")
 );
 ;
Riemann destinationBeing the original motivator for the Incubator, I left this last. This module is the interface between your logs and the Riemann monitoring system. With this, you can take all the legacy applications that are hard to monitor, but provide log files, use syslog-ng's extraordinary log processing power, and send clear and concise events over to Riemann.One can use it to monitor logins, downloads, uploads, exceptions - pretty much anything. Just extract some metric, or state, send it over to Riemann, and that will do the heavy lifting. What exactly can be done, will be worth a separate blog post, so for now, I will give just a very tiny example:
destination d_riemann  
 riemann(
  ttl("120")
  description("syslog-ng internal errors")
  metric(int("$ SEQNUM "))
 );
 ;
Hook it up to a path that collects syslog-ng internal messages, keeps only error messages, and routes it toward this destination:
log  
  source   internal();  ;
  filter   level(err..emerg);  ;
  destination(d_riemann);
 ;
The destination itself has the following options: Closing thoughtsThe Incubator contains one more tool, one which can be used to visualise logs in strange ways. But that's not strictly related to syslog-ng, isn't a module, either, so I will not describe it here right now. The above was quite a lot already, I believe.As a closing thought, I would just like to say that while the Incubator is home for experimental modules, some of them are used in production. Don't be afraid to use them, especially when packages start to arrive to your favourite GNU/Linux distribution!

28 December 2013

Keith Packard: Present-redirect-lifetimes

Object Lifetimes under Present Redirection Present extension redirection passes responsibility for showing application contents from the X server to the compositing manager. This eliminates an extra copy to the composite extension window buffer and also allows the application contents to be shown in the right frame. (Currently, the copy from application buffer to window buffer is synchronized to the application-specified frame, and then a Damage event is delivered to the compositing manager which constructs the screen image using the window buffer and presents that to the screen at least one frame later, which generally adds another frame of delay for the application.) The redirection operation itself is simple just wrap the PresentPixmap request up into an event and send it to the compositing manager. However, the pixmap to be presented is allocated by the application, and hence may disappear at any time. We need to carefully control the lifetime of the pixmap ID and the specific frame contents of the pixmap so that the compositing manager can reliably construct complete frames. We ll separately discuss the lifetime of the specific frame contents from that of the pixmap itself. By the frame contents , I mean the image, as a set of pixel values in the pixmap, to be presented for a specific frame. Present Pixmap contents lifetime After the application is finished constructing a particular frame in a pixmap, it passes the pixmap to the X server with PresentPixmap. With non-redirected Present, the X server is responsible for generating a PresentIdleNotify event once the server is finished using the contents. There are three different cases that the server handles, matching the three different PresentCompleteModes:
  1. Copy. The pixmap contents are not needed after the copy operation has been performed. Hence, the PresentIdleNotify event is generated when the target vblank time has been reached, right after the X server calls CopyArea
  2. Flip. The pixmap is being used for scanout, and so the X server won t be done using it until some other scanout buffer is selected. This can happen as a result of window reconfiguration which makes the displayed window no longer full-screen, but the usual case is when the application presents a subsequent frame for display, and the new frame replaces the old. Thus, the PresentIdleNotify event generally occurs when the target vblank time for the subsequent frame has been reached, right after the subsequent frame s pixmap has been selected for scanout.
  3. Skip. The pixmap contents will never be used, and the X server figures this out when a subsequent frame is delivered with a matching target vblank time. This happens when the subsequent Present operation is queued by the X server.
In the Redirect case, the X server cannot tell when the compositing manager is finished with the pixmap. The same three cases as above apply here, but the results are slightly different:
  1. Composite. The pixmap is being used as a part of the screen image and must be composited with other window pixmaps. In this case, the compositing manager will need to hold onto the pixmap until a subsequent pixmap is provided by the application. Thus, the pixmap will remain needed by the compositing manager until it receives a subsequent PresentRedirectNotify for the same window.
  2. Flip. The compositing manager is free to take the application pixmap and use it directly in a subsequent PresentPixmap operation and let the X server flip to it; this provides a simple way of avoiding an extra copy while not needing to fuss around with unredirecting windows. In this case, the X server will need the pixmap contents until a new scanout pixmap is provided, and the compositing manager will also need the pixmap in case the contents are needed to help construct a subsequent frame.
  3. Skip. In this case, the compositing manager notices that the window s pixmap has been replaced before it was ever used.
In case 2, the X server and the compositing manager will need to agree on when the PresentIdleNotify event should be delivered. In the other two cases, the compositing manager itself will be in charge of that. To let the compositing manager control when the event is delivered, the X server will count the number of PresentPixmap redirection events sent, and the compositing manager will deliver matching PresentIdle requests. PresentIdle
 
    PresentIdle
    pixmap: PIXMAP
 
Errors: Pixmap, Match
Informs the server that the Pixmap passed in a PresentRedirectNotify event is no longer needed by the client. Each PresentRedirectNotify event must be matched by a PresentIdle request for the originating client to receive a PresentIdleNotify event. PresentRedirect pixmap ID lifetimes A compositing manager will want to know the lifetime of the pixmaps delivered in PresentRedirectNotify events to clean up whatever local data it has associated with it. For instance, GL compositing managers will construct textures for each pixmap that need to be destroyed when the pixmap disappears. Some kind of PixmapDestroyNotify event is necessary for this; the alternative is for the compositing manager to constantly query the X server to see if the pixmap IDs it is using are still valid, and even that isn t reliable as the application may re-use pixmap IDs for a new pixmap. It seems like this PixmapDestroyNotify event belongs in the XFixes extension it s a general mechanism that doesn t directly relate to Present. XFixes doesn t currently have any Generic Events associated, but adding that should be fairly straightforward. And then, have the Present extension automatically select for PixmapDestroyNotify events when it delivers the pixmap in a PresentRedirectNotify event so that the client is ensured of receiving the associated PixmapDestroyNotify event. One remaining question I have is whether this is sufficient, or if the compositing manager needs a stable pixmap ID which lives beyond the life of the application pixmap ID. If so, the solution would be to have the X server allocate an internal ID for the pixmap and pass that to the client somehow; presumably in addition to the original pixmap ID. XFixesPixmapSelectInput
XFIXESEVENTID   XID  
    Defines a unique event delivery target for Present
    events. Multiple event IDs can be allocated to provide
    multiple distinct event delivery contexts.
PIXMAPEVENTS   XFixesPixmapDestroyNotify  
 
    XFixesPixmapSelectInput
    eventid: XFIXESEVENTID
    pixmap: PIXMAP
    events: SETofPIXMAPEVENTS
 
Errors: Pixmap, Value
Changes the set of events to be delivered for the target pixmap. A Value error is sent if events contains invalid event selections. XFixesPixmapDestroyNotify
 
    XFixesPixmapDestroyNotify
    type: CARD8         XGE event type (35)
    extension: CARD8        XFixes extension request number
    sequence-number: CARD16
    length: CARD32          0
    evtype: CARD16          XFixes_PixmapDestroyNotify
    eventID: XFIXESEVENTID
    pixmap: pixmap
 
This event is delivered to all clients selecting for it on pixmap when the pixmap ID is destroyed by a client. Note that the pixmap may still be referenced by other objects within the X server, as a window background, GC tile or stipple or Picture drawable (among others), but this event serves to notify the selecting client that the ID is no longer associated with the underlying pixmap.

Russ Allbery: rra-c-util 5.0

This package started as my collection of shared C utility code and has turned into the collection of all sorts of glue that I use across multiple packages. The primary changes in this release are to the network utility layer. In order to add proper IPv6 support, I adopted the network_bind_* functions to take the socket type, which changed all the APIs (hence the major version bump). While I was at it, I also cleaned up some of the error reporting in the various functions to make them easier to use. There's a new network_wait_any function that does the select part of network_accept_any, making it useful for UDP servers. This release also contains a new, generalized TAP add-on for spawning background processes used by test cases. Their standard output and standard error is now captured and merged into the test output stream using the new C TAP Harness support for files containing diagnostic messages. The remctl TAP add-on has been rewritten to use this framework. Julien LIE also adapted the Autoconf probes for Berkeley DB and zlib used in INN to the framework used for most probes in rra-c-util, and those probes are included in this release. Finally, the vector utility library's free functions now accept (and do nothing with) NULL, which makes it easier to write cleanup functions. You can get the latest release from the rra-c-util distribution page.

27 December 2013

John Goerzen: Richly Blessed

It s wedding week! Wedding week! Wedding week! Wedding week! Oh, also Christmas. Oh dad, it s wedding week! I can t believe it! It s finally here! Wedding week! Jacob, age 7, Sunday Oh dad, this is the best Christmas EVER! Jacob, Wednesday Dad, is the wedding TODAY? Oliver, age 4, every morning this week This has certainly been a Christmas like no other. I have never known something to upstage Christmas for Jacob, but apparently a wedding can! Laura and I got to celebrate our first Christmas together this year together, of course, with the boys. We enjoyed a wonderful day in the middle of a busy week, filled with play, family togetherness, warmth, and happiness. At one point, while I was helping the boys with their new model train components, Laura was enjoying playing Christmas tunes on the piano. Every time she d reach the end, Jacob paused, and said, That was awesome! , beating me to it. That s a few days before Christmas Jacob and Oliver demanding snow ice cream, and of course who am I to refuse? Cousins opening presents After his school Christmas program, Jacob has enjoyed singing. Here he is after the Christmas Eve program, where he excitedly ran up into the choir loft, picked up a hymnal, and pretended to sing. And, of course, opening of presents at home. Sometimes I think about how I didn t know life could get this good. Soon Laura and I will be married, and it will be even better. Truly we have been richly blessed.

Next.

Previous.