Search Results: "spa"

18 June 2014

Matthias Klumpp: Tanglu 2 (Bartholomea annulata) status update #1
bartholomea-annulata

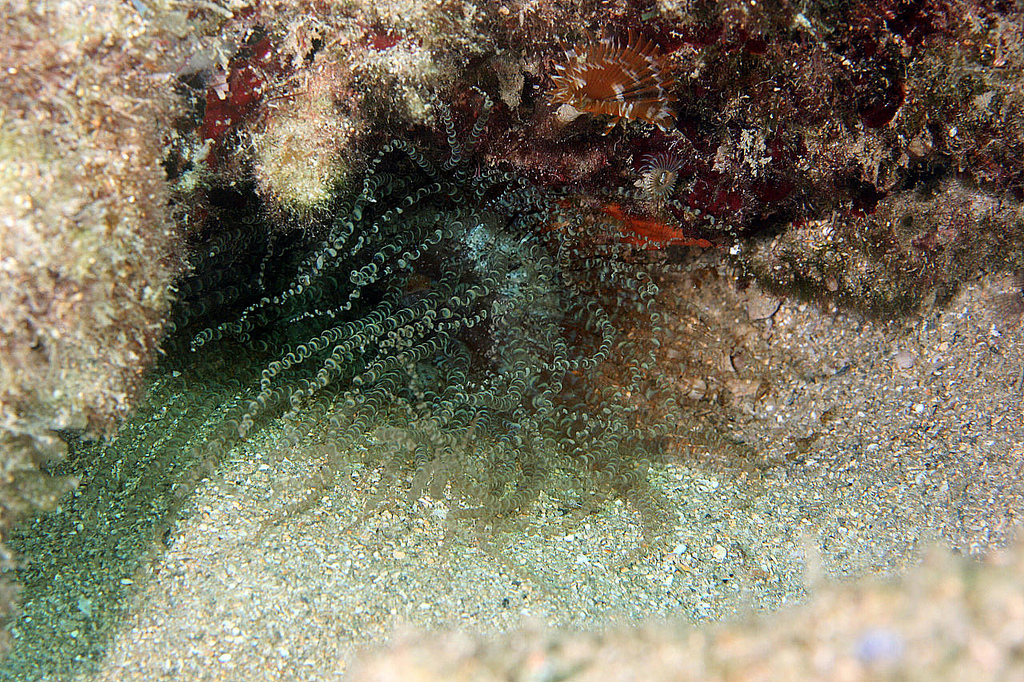
Bartholomea annulata (c) Kevin Bryant

It is time for a new Tanglu update, which has been overdue for a long time now! Many things happened in Tanglu development, so here is just a short overview of what was done in the past months. Infrastructure Debile The whole Tanglu distribution is now built with Debile, replacing Jenkins, which was difficult to use for package building purposes (although Jenkins is great for other things). You can see the Tanglu builders in action at buildd.tg.o. The migration to Debile took a lot of time (a lot more than expected), and blocked the Bartholomea development at the beginning, but now it is working smoothly. Many thanks to all people who have been involved with making Debile work for Tanglu, especially Jon Severinsson. And of course many thanks to the Debile developers for helping with the integration, Sylvestre Ledru and of course Paul Tagliamonte. Archive Server Migration Those who read the tanglu-announce mailinglist know this already: We moved the main archive server stuff at archive.tg.o to to a new location, and to a very powerful machine. We also added some additional security measures to it, to prevent attacks. The previous machine is now being used for the bugtracker at bugs.tg.o and for some other things, including an archive mirror and the new Tanglu User Forums. See more about that below :-) Transitions There is huge ongoing work on package transitions. Take a look at our transition tracker and the staging migration log to get a taste of it. Merging with Debian Unstable is also going on right now, and we are working on merging some of the Tanglu changes which are useful for Debian as well (or which just reduce the diff to Tanglu) back to their upstream packages. Installer Work on the Tanglu Live-Installer, although badly needed, has not yet been started (it s a task ready for taking by anyone who likes to do it!) however, some awesome progress has been made in making the Debian-Installer work for Tanglu, which allows us to perform minimal installations of the Tanglu base systems and allows easier support of alternative Tanglu falvours. The work on d-i also uncovered a bug which appeared with the latest version of findutils, which has been reported upstream before Debian could run into it. This awesome progress was possible thanks to the work of Philip Mu kovac and Thomas Funk (in really hard debug sessions).
Tanglu ForumsTanglu Users We finally have the long-awaited Tanglu user forums ready! As discussed in the last meeting, a popular demand on IRC and our mailing lists was a forum or Stackexchange-like service for users to communicate, since many people can work better with that than with mailinglists. Therefore, the new English TangluUsers forum is now ready at TangluUsers.org. The forum software is in an alpha version though, so we might experience some bugs which haven t been uncovered in the testing period. We will watch how the software performs and then decide if we stick to it or maybe switch to another one. But so far, we are really happy with the Misago Forums, and our usage of it already led to the inclusion of some patches against Misago. It also is actively maintained and has an active community. Misc Thingstanglu logo pure KDE We will ship with at least KDE Applications 4.13, maybe some 4.14 things as well (if we are lucky, since Tanglu will likely be in feature-freeze when this stuff is released). The other KDE parts will remain on their latest version from the 4.x series. For Tanglu 3, we might update KDE SC 4.x to KDE Frameworks 5 and use Plasma 5 though. GNOME Due to the lack manpower on the GNOME flavor, GNOME will ship in the same version available in Debian Sid maybe with some stuff pulled from Experimental, where it makes sense. A GNOME flavor is planned to be available. Common infrastructure We currently run with systemd 208, but a switch to 210 is planned. Tanglu 2 also targets the X.org server in version 1.16. For more changes, stay tuned. The kernel release for Bartholomea is also not yet decided. Artwork Work on the default Tanglu 2 design has started as well any artwork submissions are most welcome! Tanglu joins the OIN The Tanglu project is now a proud member (licensee) of the Open Invention Network (OIN), which build a pool of defensive patents to protect the Linux ecosystem from companies who are trying to use patents against Linux. Although the Tanglu community does not fully support the generally positive stance the OIN has about software patents, the OIN effort is very useful and we agree with it s goal. Therefore, Tanglu joined the OIN as licensee.
And that s the stuff for now! If you have further questions, just join us on #tanglu or #tanglu-devel on Freenode, or write to our newly created forum! You can, as always, also subscribe to our mailinglists to get in touch.

16 June 2014

Keith Packard: Altos1.4

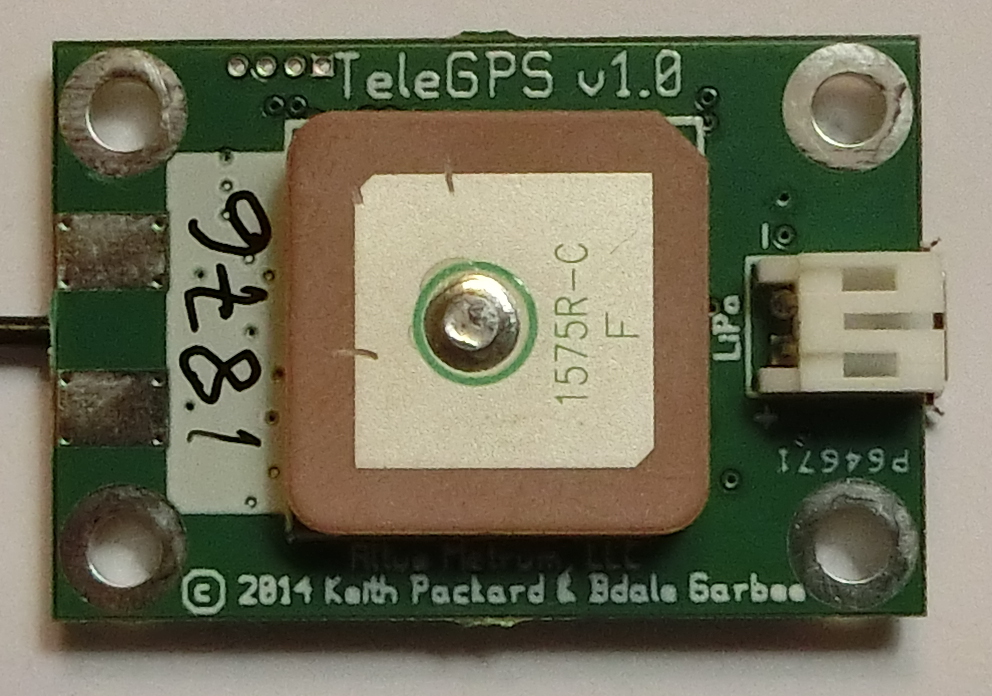
AltOS 1.4 TeleGPS support, features and bug fixes Bdale and I are pleased to announce the release of AltOS version 1.4. AltOS is the core of the software for all of the Altus Metrum products. It consists of firmware for our cc1111, STM32L151, LPC11U14 and ATtiny85 based electronics and Java-based ground station software. This is a major release of AltOS, including support for our new TeleGPS board and a host of new features and bug fixes AltOS Firmware TeleGPS added, new features and fixes Our new tracker, TeleGPS, works quite differently than a flight computer TeleGPS transmits our digital telemetry protocol, APRS and radio direction finding beacons. For TeleMega, we ve made the firing time for the additional pyro channels (A-D) configurable, in case the default (50ms) isn t long enough. AltOS Beeping Changes The three-beep startup tones have been replaced with a report of the current battery voltage. This is nice on all of the board, but particularly useful with EasyMini which doesn t have the benefit of telemetry reporting its state. We also changed the other state tones to Farnsworth spacing. This makes them all faster, and easier to distinguish from the numeric reports of voltage and altitude. Finally, we ve added the ability to change the frequency of the beeper tones. This is nice when you have two Altus Metrum flight computers in the same ebay and want to be able to tell the beeps apart. AltOS Bug Fixes Fixed a bug which prevented you from using TeleMega s extra pyro channel Flight State After configuration value. AltOS 1.3.2 on TeleMetrum v2.0 and TeleMega would reset the flight number to 2 after erasing flights; that s been fixed. AltosUI New Maps, igniter tab and a few fixes With TeleGPS tracks now potentially ranging over a much wider area than a typical rocket flight, the Maps interface has been updated to include zooming and multiple map styles. It also now uses less memory, which should make it work on a wider range of systems. For TeleMega, we ve added an Igniter tab to the flight monitor interface so you can check voltages on the extra pyro channels before pushing the button. We re hoping that the new Maps interface will load and run on machines with limited memory for Java applications; please let us know if this changes anything for you. TeleGPS All new application just for TeleGPS While TeleGPS shares the same telemetry and data logging capabilities as all of the Altus Metrum flight computers, its use as a tracker is expected to be both broader and simpler than the rocketry-specific systems. We ve build a custom TeleGPS application that incorporates the mapping and data visualization aspects of AltosUI, but eliminates all of the rocketry-specific flight state tracking.
15 June 2014

Dominique Dumont: Edit your debian patch header for DEP-3 compliance with cme

While not required by Debian policy, the patch tagging guidelines (aka DEP-3) recommends to add a structured header to source package patches. Long story short, patches should begin with something like :
Description: tweak lcdproc config for debian
patch LCDd.conf to:
* use syslog instead of stderr to show message
* run LCDd as root (to read /dev/lcd* file)
.
The latter could be done better by tweaking udev rule
Author: dod
Applied-Upstream: NA
Making sure that the DEP-3 recommendation is respected may not be fun. Do not despair: once libconfig-model-dpkg-perl is installed on your system, you can check whether your patches respect the DEP3 recommendation with the following command: $ cme check dpkg-patches
loading data
checking data
check done
You can also check individual patches with: cme check dpkg-patch tweak-conf Note that bash auto-completion is provided only from version 2.049 of libconfig-model-dpkg-perl package. If editing the header of your patches with your favorite editor does not strike you as fun, you can also use cme graphical editor provided by libconfig-model-tkui-perl. Once this package is installed, you can run: cme edit dpkg-patches You will get this editor to update your patches: -usr-bin-cme Dpkg::Patches_001 This editor will show you the available parameters and the associated documentation to let you provide relevant information. Last but not least, patch header check is also performed when you check your whole package with cme check dpkg All the best
Tagged: Config::Model, debian, package, patch

10 June 2014

Steve Kemp: I did get a job

In my previous blog-post I mentioned, briefly, that I'd posted a couple of adverts on Reddit looking for work. To give more detail I did three things: The advertisement was set to be shown in /r/edinburgh (where I live), and /r/sysadmin (where I thought some people might look if they were struggling for help). The advertising on Reddit was painless to setup, and the traffic stats were interesting, but even though this worked out well I'm a little loathe to repeat the process - since the "non-sterling transaction fee" from my bank effectively doubled my budget. I received a few (private) emails and comments, along with the expected grammar corrections. The end result was that I received contact from an American company founder who seemed interested. He allowed me to write some code to solve a fun problem, appeared to enjoy the code I sent (Ruby code for dealing with (exim) email spam, that's as specific as I will be). The end result was a three month contract, which we obviously hope will lead to more permanent work. Anyway I thought this was an atypical route to find a work, and was about a million times nicer than working with recruiters, so .. consider this documentation! In other news it is now 10pm and I need to go to the gym and pub, in that order.

Steve Kemp: I'm still not a developer, but ..

Some coding updates: My templer static site generator has now been uploaded to CPAN, and is available as App::Templer. I've converted most of my Dockerfiles to work with docker 1.0.0, which is nice. I also hacked up a fun DNS-server for sharing JSON-encoded data, within a LAN or other environment: Finally I updated the blogspam-detecting site a little, on the back-end. The code is now running inside Docker containers which means I can redeploy more easily in the future. My blog post about looking for a job received some attention via a Reddit advert I posted to /r/edinburgh + /r/sysadmin, but thus far has mostly resulted in people wanting me to write code for them .. which is frustrating. For the moment I'm working on a fun challenge involving (email) spam-detection. That takes me back.

Gunnar Wolf: Tor: I'm shutting down my relay only after four days

Some days ago, I bit the bullet and accepted the Tor Challenge. Sadly, after only four days of having a Tor relay node happily sitting at home (and, of course, giving a nice function to this little friend). The inconveniences were too many. I understand anonimity can be used for many nefarious things, but I was surprised and saddened to see the amount of blocking services. Most notorious to me were the Freenode IRC network, friendly home to many free software projects, and the different Wikimedia projects, which ban editting from IP addresses idenitfied as Tor relays. I'm saddened to say that, while I could perfectly survive (and even be a bit proud about supporting a project I believe in) by jumping through some hoops (i.e. by setting up a SOCKS over ssh tunnel to my office to do my Wikipedia edits while at home), after only four days, I decided to shut down my relay. And the main reason... Was something I'm not going to fight against. And it's not even from a nice, friendly free software project. One thing I am not willing to part with is the one tool that keeps my wife well in contact with her friends and family back in Argentina. Yes, I know I could set up one or many different flavors of SIP or Jabber-based VoIP for her But it's also her parents, brother, sisters, and friends who use Skype. So, Skype's banning of Tor relay nodes made me decide to shut down my relay. Sigh... And for somebody obsessed with graphing stuff, this is the graph of the short lifespan of the "Lobazal" Tor node: [update] I will do another blog post. Good news: My Tor node is alive again! Just no longer as an exit relay, as properly pointed out by many, but as a Tor bridge.
AttachmentSize
tor-challenge-1.png23.97 KB
tor1.png27.84 KB
tor2.png18.3 KB

Russell Coker: Google Hardware Support

Ironically just 5 days after writing about how I choose Android devices for a long service life [1] my wife s Nexus 5 (with 32G of RAM (sorry Flash storage) to give it a long useful life) totally died. It reported itself as being fully charged and then 15 minutes later it was off and could not be revived. No combination of pushing the power button and connecting the power cable caused the screen to light up or any sound to be emitted. Google has a nice interactive support site for nexus devices that describes more ways of turning a phone on than any reasonable person could imagine. After trying to turn the phone on in various ways (plugged and unplugged etc) it gave me a link to get phone support. Clicking on that put me in the queue to RECEIVE a phone call and a minute later a lady who spoke English really well (which is unusual for telephone support) called me to talk me through the various options. Receiving a phone call is a much better experience than making a call. It meant that if the queue for phone support was long then I could do other things until the phone rings. It s impossible to be productive at other tasks while listening for hold music to stop and a person to start talking. The cost of doing this would be very tiny, while there would be some cost in hardware and software to have a web site that tells me how long I can expect to wait for a call a more basic implementation where I just submit my number and wait for a call would be very cheap to implement. The costs of calls from the US to Australia (and most places where people can afford a high end Android phone) are quite cheap for home users and are probably cheaper if you run a call center. If the average support call cost Google $1 and 3% of phones have support calls then that would be an extra cost of $0.03 per phone. I expect that almost everyone who buys a $450 phone would be happy to pay a lot more than $0.03 to avoid the possibility of listening to hold music! I received the phone call about a minute after requesting it, this was nice but I wonder how long I would have waited if I hadn t requested a call at 1AM Australian time (presumably during the day in a US call center). In any case getting a 1 minute response is great for any time of the day or night, lots of call centers can t do that. While the phone support is much better than most phone support, it would be nice if they added some extra options. I think it would be good to have webchat and SMS as options for support for the benefit of people who don t want to speak to strangers. This would be useful to a lot of people on the Autism Spectrum and probably others too. The phone call wasn t particularly productive, it merely confirmed that I had followed all the steps on the support website. Then I received an email telling me about the web site which was a waste of time as I d covered that in the phone call. I have just replied to their second email which asked for the IMEI of the phone to start the warranty return process. We could have saved more than 24 hours delay if this had been requested in the first email or the phone call. Google could have even requested the IMEI through the web site before starting the phone call. It would have been even easier if Google had included the device IMEI in the email they sent me to confirm the purchase as searching for old email is a lot easier than searching through my house for an old box. Another option for Google would be to just ask me for the Gmail account used for the purchase, as I only bought one Nexus 5 on that account they then have all the purchase details needed for a warranty claim. While the first call was a great experience the email support following that has been a waste of time. I m now wondering if they aim to delay the warranty process for a few days in the hope that the phone will just start working again.

9 June 2014

Dirk Eddelbuettel: Rcpp 0.11.2

A new minor release 0.11.2 of Rcpp is now on the CRAN network for GNU R, and binaries for Debian have also been uploaded. The release smoothes a few edges on both the Rcpp side itself, as well as on the interaction between Rcpp and R which since release 3.1.0 offers a few new features related to C++11. Kevin added a couple of neat extensions related to vectors, a new ListOf templated list class, as well as a new option to warn on implicit casts. We decided not to make this option the default as it may be too common in some packages. JJ took care of a few buglets related to the wonderful Rcpp Attributes. See the NEWS file section below for details, or the ChangeLog file in the package and on the Rcpp Changelog page. Note that the diffstat reported by CRANberries is very large as Kevin also committed a whitespace cleanup which touched almost all files. As before, we tested this release by building against all CRAN packages which depend upon Rcpp. In fact we did three such runs leading up to the release. Only one package was blacklisted (as I currently don't have CUDA set-up), two had what may be internal errors or tests which were too restrictive, sixteen suffered from missing packages or RGL devices --- but the remaining 202 packages all built and tested cleanly. Detailed results of those tests (and the scripts for it) are in the rcpp-logs repo GitHub. There are a number of other fixes, upgrades and other extensions detailed in NEWS file extract below, in the ChangeLog file in the package and on the Rcpp Changelog page.
Changes in Rcpp version 0.11.2 (2014-06-06
  • Changes in Rcpp API:
    • Implicit conversions, e.g. between NumericVector and IntegerVector, will now give warnings if you use #define RCPP_WARN_ON_COERCE before including the Rcpp headers.
    • Templated List containers, ListOf<T>, have been introduced. When subsetting such containers, the return is assumed to be of type T, allowing code such as ListOf<NumericVector> x; NumericVector y = x[0] + x[1] + x[2].
    • In a number of instances, returned results are protected and/or cast more carefully.
  • Changes in Rcpp Attributes
    • Trailing line comments are now stripped by the attributes parser. This allows the parser to handle C++ source files containing comments inline with function arguments.
    • The USE_CXX1X environment variable is now defined by the cpp11 plugin when R >= 3.1. Two additional plugins have been added for use with C++0x (eg when using g++ 4.6.* as on Windows) as well as C++1y for compilers beginning to support the next revision of the standard; additional fallback is provided for Windows.
    • compileAttributes() now also considers Imports: which may suppress a warning when running Rcpp.package.skeleton().
Thanks to CRANberries, you can also look at a diff to the previous release. As always, even fuller details are on the Rcpp Changelog page and the Rcpp page which also leads to the downloads, the browseable doxygen docs and zip files of doxygen output for the standard formats. A local directory has source and documentation too. Questions, comments etc should go to the rcpp-devel mailing list off the R-Forge page

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

8 June 2014

Russ Allbery: INN 2.5.4

Julien LIE completed this release a few weeks ago, but between work and other things I'm only finally now posting the announcement. This is primarily a bug-fix release. The most user-visible changes are that the radius.conf file for the nnrpd RADIUS authenticator has been renamed to inn-radius.conf (to avoid a conflict with the configuration of the actual RADIUS server), and the sample innd and nnrpd MOTD files are now installed as samples and not as live configuration on a new server install. controlchan and pgpverify now check the signer of control messages in a way that works properly with UIDs containing spaces and keys that define multiple UIDs, which should fix long-standing problems with verifying the control messages for fido.ger.* and grisbi.*. The nnrpd posting filter now has access to the attributes hash, similar to the authentication and access Perl hooks. In addition, there are fixes for a variety of crash bugs, build issues, log rotation issues, and the normal variety of bug fixes that accumulate over time. You can get the latest version from the official ISC download page or from my personal INN pages. The latter also has links to the full changelog and the other INN documentation. As always, thanks to Julien LIE for doing the lion's share of work on the new release, including investigating and fixing bugs, merging patches, and doing all the hard parts of the release process.

Bits from Debian: DebConf14 - Call for talks, BoFs and events

The Debian project is excited to announce that we are now accepting presentations, discussion sessions and tutorials for our DebConf14 conference which will take place in Portland State University, Oregon, USA from 23 to 31 August. Submitting an event To submit an event, first register as an attendee for DebConf14 in the conference management system. If you have any doubts or have problems with the registration process please check the Registration FAQ. After registering, go to the event submission page, or click on the Create an event option from the management system. Describe your submission in the web form. The most common event types are Lecture or Open Discussion (BoF). Please include a short title (to make it easy to produce a compact schedule) and an engaging description of the event. Tracks We will organize some talks into thematic tracks. If you have a proposal for a DebConf track, such as "Debian ARM", "Debian Infrastructure", or "Community Outreach" please contact talks@debconf.org. If you would like to be a track coordinator, please volunteer on the given mail address. Format of the events A regular session will be 45 minutes long, including time for questions. There will be a 15 minute breaks between events. Submissions are not limited to traditional talks: you could propose a performance, art installation, debate, or anything else. If you have any specific requirements for your event, please send an email to talks@debconf.org with the details of your requirements and be sure to mention your event title in the subject. Deadline While we ask speakers to submit their events before the deadline of 7 July 2014, 23:59:59 UTC, late submissions will continue to be accepted for scheduling until the end of DebConf. All attendees will have an opportunity to schedule ad-hoc events during DebConf itself if we have space for them. Very promising late submissions may be considered for inclusion in the main conference. Note that ad-hoc events have a much lower chance of video archiving, and streaming, so if you want these services it's better to get your submissions in early. DebConf official events will be broadcast live on the Internet when possible, and videos of the talks will be published on the web along with the presentation slides and papers. For private communication regarding your talk, or for more general ideas, or questions about the event and talks, please mail us We hope to you see you and share some good times with you this year in Portland during DebConf14!

7 June 2014

Vasudev Kamath: Exposing function in python module using entry_points, WSME in a Flask webapp

The heading might be ambiguous, but I couldn't figure out better heading so let me start by explaining what I'm trying to solve here.
Problem I have a python module which contains a function which I want to expose as a REST web service in a Flask application. I use WSME for Flask application, which actually needs signature of function in question and problem comes to picture because function to be exposed is foreign to Flask application, it resides in separate python module.
Solution While reading Julien Danjou's Hackers Guide To Python book I came across the setuptools entry_points concept which can be used to extend existing feature of a tool like plug-ins. So here I'm going to use this entry_points feature from setuptools to provide function in the module which can expose the signature of function[s] to be exposed through REST. Of course this means I need to modify module in question to write entry_points and function for giving out signature of function to be exposed. I will explain this with small example. I have a dummy module which provides a add function and a function which exposes the add functions signature.
def add(a, b):
    return a + b
def expose_rest_func():
    return [add, int, int, int]
This is stored in dummy/__init__.py file. I use pbr tool to package my python module. Below is content of setup.cfg file.
[metadata]
name = dummy
author = Vasudev Kamath
author-email = kamathvasudev@gmail.com
summary = Dummy module for testing purpose
version = 0.1
license = MIT
description-file =
  README.rst
requires-python = >= 2.7
[files]
packages =
  dummy
[entry_points] =
myapp.api.rest =
  rest = dummy:expose_rest_func
The special thing in above file is entry_points section, which defines function to be hooked into entry_point. In our case entry_point myapp.api.rest is used by our Flask application to interact with modules which expose them. The function which will be got accessing the entry_point is expose_rest_func which gives the function to be exposed its arg types and return types as a list. If we are looking at only supporting python3 it was sufficient to know function name only and use function annotations in function definition. Since I want to support both python2 and python3 this is out of question. Now, just run the following command in virtualenv to get the module installed.
PBR_VERSION=0.1 python setup.py sdist
pip install dist/dummy_module-0.1.tar.gz
Now if you want to see if the module is exposing entry_point or not just use entry_point_inspector tool after installing you will get a command called epi if you run it as follows you should note the dummy_module in its output
epi group list
+-----------------------------+
  Name                         
+-----------------------------+
  cliff.formatter.completion   
  cliff.formatter.list         
  cliff.formatter.show         
  console_scripts              
  distutils.commands           
  distutils.setup_keywords     
  egg_info.writers             
  epi.commands                 
  flake8.extension             
  setuptools.file_finders      
  setuptools.installation      
  myapp.api.rest               
  stevedore.example.formatter  
  stevedore.test.extension     
  wsme.protocols               
+-----------------------------+
So our entry_point is exposed now, we need to access it in our Flask application and expose the function using WSME. It is done by below code.
from wsmeext.flask import signature
import flask
import pkg_resources
def main():
   app = flask.Flask(__name__)
   app.config['DEBUG'] = True
   for entrypoint in pkg_resources.iter_entry_points('myapp.api.rest'):
       # Ugly but fix is only supporting python3
       func_signature = entrypoint.load()()
       app.route('/' + func_signature[0].__name__, methods=['POST'])(
           signature(func_signature[-1],
               *func_signature[1:-1])(func_signature[0]))
   app.run()
if __name__ == '__main__':
    main()
entry_point myapp.api.rest are iterated using the pkg_resources package provided by setuptools, when I load the entry_point I get back the function to be used which is called in same place to get function signature. Then I'm calling Flask and WSME decorator functions (yeah instead of decorating I'm using them directly over function to be exposed). The code looks bit ugly at the place where I'm accessing list using slices but I can't help it due to limitation of python2 with python3 there is new packing and unpacking stuff which makes code look bit more cooler see below.
from wsmeext.flask import signature
import flask
import pkg_resources
def main():
    app = flask.Flask(__name__)
    app.config['DEBUG'] = True
    for entrypoint in pkg_resources.iter_entry_points('silpa.api.rest'):
        func, *args, rettype = entrypoint.load()()
        app.route('/' + func.__name__, methods=['POST'])(
        signature(rettype, *args)(func_signature[0]))
    app.run()
if __name__ == '__main__':
    main()
You can access the service at http://localhost:5000/add depending on Accept header of HTTP you will get either XML or JSON response. If you access it from browser you will get XML response.
Usecase Now if you are wondering what is the reason behind this experience, this is for SILPA Project. I'm trying to implement REST service for all Indic language computing module. Since all these module are independent of SILPA which is a Flask web app I had to find a way to achieve this, and this is what I came up with.
Conclusion I'm not sure if there is any other approaches to achieve this, if there I would love to hear about them. You can write your comments and suggestion over email

Craig Small: A python utf gotcha

This one had me stumped for a while:
# -*- coding: utf-7 -*-
import datetime
from sqlalchemy import ForeignKey, Column
from sqlalchemy.types import Integer, Unicode, Boolean, DateTime
 
default_due_date = datetime.datetime.now() + datetime.timedelta(days=30)
Syntax error found on last line. Hmm, bring up a python interpreter and type the last line in with the imports. Works fine. It s the first line that is the problem, I typoed it and made it utf-7 not utf-8. I suppose it means that it is case-insenstive. Still, it wasn t too clear to me at least, what was going on.

5 June 2014

Johannes Schauer: botch updates

My last update about ongoing development of botch, the bootstrap/build ordering tool chain, was four months ago and about several incremental updates. This post will be of similar nature. The most interesting news is probably the additional data that bootstrap.debian.net now provides. This is listed in the next section. All subsequent sections then list the changes under the hood that made the additions to bootstrap.debian.net possible.

bootstrap.debian.net The bootstrap.debian.net service used to have botch as a git submodule but now runs botch from its Debian package. This at least proves that the botch Debian package is mature enough to do useful stuff with it. In addition to the bootstrapping results by architecture, bootstrap.debian.net now also hosts the following additional services: Further improvements concern how dependency cycles are now presented in the html overviews. While before, vertices in a cycle where separated by commas as if they were simple package lists, vertices are now connected by unicode arrows. Dashed arrows indicate build dependencies while solid arrows indicate builds-from relationships. For what it's worth, installation set vertices now contain their installation set in their title attribute.

Debian package Botch has long depended on features of an unreleased version of dose3 which in turn depended on an unrelease version of libcudf. Both projects have recently made new releases so that I was now able to drop the dose3 git submodule and rely on the host system's dose3 version instead. This also made it possible to create a Debian package of botch which currently sits at Debian mentors. Writing the package also finally made me create a usable install target in the Makefile as well as adding stubs for the manpages of the 44 applications that botch currently ships. The actual content of these manpages still has to be written. The only documentation botch currently ships in the botch-doc package is an offline version of the wiki on gitorious. The new page ExamplesGraphs even includes pictures.

Cross By default, botch analyzes the native bootstrapping phase. That is, assume that the initial set of Essential:yes and build-essential packages magically exists and find out how to bootstrap the rest from there through native compilation. But part of the bootstrapping problem is also to create the set of Essential:yes and build-essential packages from nothing via cross compilation. Botch is unable to analyze the cross phase because too many packages cannot satisfy their crossbuild dependencies due to multiarch conflicts. This problem is only about the dependency metadata and not about whether a given source package actually crosscompiles fine in practice. Helmut Grohne has done great work with rebootstrap which is regularly run by jenkins.debian.net. He convinced me that we need an overview of what packages are blocking the analysis of the cross case and that it was useful to have a crossbuild order even if that was a fake order just to have a rough overview of the current situation in Debian Sid. I wrote a couple of scripts which would run dose-builddebcheck on a repository, analyze which packages fail to satisfy their crossbuild dependencies and why, fix those cases by adjusting package metadata accordingly and repeat until all relevant source packages satisfy their crossbuild dependencies. The result of this can then be used to identify the packages that need to be modified as well as to generate a crossbuild order. The fixes to the metadata are done in an automatic fashion and do not necessarily reflect the real fix that would solve the problem. Nevertheless, I ended up agreeing that it is better to have a slightly wrong overview than no overview at all.

Minimizing the dependency graph size Installation sets in the dependency graph are calculated independent from each other. If two binary packages provide A, then dependencies on A in different installation sets might choose different binary packages as providers of A. The same holds for disjunctive dependencies. If a package depends on A C and another package depends on C A then there is no coordination to choose C so to minimize the overall amount of vertices in the graph. I implemented two methods to minimize the impact of cases where the dependency solver has multiple options to satisfy a dependency through Provides and dependency disjunctions. The first method is inspired by Helmut Grohne. An algorithm goes through all disjunctive binary dependencies and removes all virtual packages, leaving only real packages. Of the remaining real packages, the first one is selected. For build dependencies, the algorithm drops all but the first package in every disjunction. This is also what sbuild does. Unfortunately this solution produces an unsatisfiable dependency situation in most cases. This is because oftentimes it is necessary to select the virtual disjunctive dependency because of a conflict relationship introduced by another package. The second method involves aspcud, a cudf solver which can optimize a solution by a criteria. This solution is based on an idea by Pietro Abate who implemented the basis for this idea back in 2012. In contrast to a usual cudf problem, binary packages now also depend on the source packages they build from. If we now ask aspcud to find an installation set for one of the base source packages (I chose src:build-essential) then it will return an installation set that includes source packages. As an optimization criteria the number of source packages in the installation set is minimized. This solution would be flawless if there were no conflicts between binary packages. Due to conflicts not all binary packages that must be coinstallable for this strategy to work can be coinstalled. The quick and dirty solution is to remove all conflicts before passing the cudf universe to aspcud. But this also means that the solution does sometimes not work in practice.

Test cases Botch now finally has a test target in its Makefile. The test target tests two code paths of the native.sh script and the cross.sh script. Running these two scripts covers testing most parts of botch. Given that I did lots of refactoring in the past weeks, the test cases greatly helped to assure that I didnt break anything in the process. I also added autopkgtests to the Debian packaging which test the same things as the test target but naturally run the installed version of botch instead. The autopkgtests were a great help in weeding out some lasts bugs which made botch depend on being executed from its source directory.

Python 3 Reading the suggestions in the Debian python policy I evaluated the possibility to use Python 3 for the Python scripts in botch. While I was at it I added transparent decompression for gzip, bz2 and xz based on the file magic, replaced python-apt with python-debian because of bug#748922 and added argparse argument parsing to all scripts. Unfortunately I had to find out that Python 3 support does not yet seem to be possible for botch for the following reasons:
  • no soap module for Python 3 in Debian (needed for bts access)
  • hash randomization is turned on by default in Python 3 and therefore the graph output of networkx is not deterministic anymore (bug#749710)
Thus I settled for changing the code such that it would be compatible with Python 2 as well as with Python 3. Because of the changed string handling and sys.stdout properties in Python 3 this proved to be tricky. On the other hand this showed me bugs in my code where I was wrongly relying on deterministic dictionary key traversal.

4 June 2014

Russell Coker: Android Device Service Life

In recent years Android devices have been the most expensive things I ve purchased apart from airline tickets and other travel/holiday expenses. As they are expensive I d like to use them for as long as possible to get the most value for money. Also as I give my devices to relatives when they no longer work for me I d like to avoid having relatives hassling me about their phone not working as desired. So I ve been thinking about the features that I need to make it possible to use a phone or tablet for a long time. RAM The way Android works is that when an application in the foreground requests more memory background applications may be closed to free some memory. Android doesn t use swap by default, there is some documentation on how to enable it (and it s not difficult to figure out for anyone who has used Linux before) but generally it s not done. If you run a larger application the chances of apps closing in the background (causing delays when you switch back to them and possibly a loss of context if the app is buggy and doesn t preserve all state) are increased. As a general trend apps tend to get bigger to provide more features and also because users who own newer bigger devices don t complain as much about memory use. Also to make things worse new versions of Android tend to use more RAM. So a phone that runs well can suddenly start performing badly when you upgrade to a new version of Android (which incidentally usually can t be reversed) and upgrade to new versions of apps (which can t be reversed through the Google Play Store). The Sony Ericsson Xperia X10 was a very nice phone when it was released, it ran Android 2.1 very quickly. When I upgraded the Xperia X10s that my wife and I used to Android 2.3 (which was necessary to have the phone run as a Wifi access point) performance dropped considerably. The Android upgrade combined with newer larger apps means that those phones are barely usable now. 384M of RAM was plenty in early 2011 when I first used the Xperia X10 but it s not nearly enough now. Recently 2G of RAM has been the minimum for a mid-range or high-end phone. It seems difficult to imagine a new Android feature as compelling as the addition of Wifi access point support in Android 2.3 that would drive an upgrade to a future memory hogging version of the OS. It also seems difficult to imagine Android apps needing enough memory to destroy the performance of a phone with 2G of RAM. But then I couldn t imagine the 384M in an Xperia X10 becoming inadequate or the 512M in a Samsung Galaxy S becoming barely usable either. Storage Until fairly recently storage in an Android device was divided into USB attached storage (a VFAT filesystem that could be directly mounted on a PC) and a Linux filesystem that was used for all internal operations of the phone. On such devices it typically wasn t possible to change partition sizes without a lot more skill than most users possess and most of the storage space was reserved for USB attachment. If you only had a few Android apps and lots of photos, movies, etc then this worked well. But if you wanted to install larger Android apps then you would have big problems. Even with Android 4.x devices (which all seem to have a single filesystem) you can easily run out of space. Modern games often take several hundred megs of storage. Games that take 500M+ for the Android package install (which also requires the same amount of temporary space for installation and upgrade) are common. Sometimes games download data files after they have been installed for a total size approaching 2G (such as The Sims Freeplay). When I bought a Nexus 4 for my wife I got the version with 8G of storage because paying an extra $50 for the 16G version seemed unreasonable. 8G was fine for my wife, but when she got a new phone I gave the Nexus 4 to a relative who wanted to play The Sims and other big games. That relative isn t so happy about having a limited number of games on their phone and I have to fix it when storage space runs out and things start aborting (when storage runs out the Google App Store program aborts and uses lots of space for temporary files). I recently bought a tablet with 32G of storage and filled 16G on the first day (tablets are good for watching
TV and TV shows are big). Fortunately the tablet in question has a SD socket so that when space becomes a problem in a year or two I can buy an SD card and keep using it. An unfortunate recent decision by Google was to prevent apps from being run from a SD card. So even if you have a device with a SD socket you still need to have enough internal storage for all apps and their private data. At 500M+ for a modern game that means a device with 8G of storage (which includes space for the OS) will be lucky to get 8 games installed. If you want to use a phone to it s full capacity (playing various media files, games, etc) then it seems that the minimum storage capacity would be 8G of internal storage and a SD socket. For a device without an SD socket (such as the Nexus 5 with 16G or 32G of storage) your future use will be limited. 32G is probably enough for a phone given that you can recode movies to use less space (the FullHD screen on the Nexus 5 is nice but 720p movies will probably look good enough). But the larger screens of tablets demand better video quality so the Nexus tablets are probably a bad choice due to lack of storage space. Screen Size and Resolution I have previously written about the sizes of devices and how they may be used by people of various ages [1]. That should be of use for anyone who plans to use their old phone as an educational device for their children (which appears to be very common). But apart from that I can t think of any reason why size would suddenly make an old phone obsolete. Only young children will have their hands change size in any significant way. Resolution also shouldn t be a huge problem, the 480*854 screen on the Xperia X10 is fairly good for a 4 screen. While a higher resolution makes text more readable at a small size for most users the availability of a higher resolution screen isn t going to make their old phone obsolete. CPU The only Android devices I owned that appeared to develop CPU speed issues late in life were the Xperia X10 phones, and that might be more due to RAM limits and the OS upgrade. All the other devices were either obviously slow at purchase time or are still performing well now. CPU speed may make it difficult or impossible to play new games, but shouldn t affect other uses of a phone or tablet. Conclusion It seems to me that if you want to use an Android device for more than 2 years then storage capacity should be a major factor in choosing which device to purchase. It seems that lack of storage space is in many cases the main factor that makes older devices annoying or impossible to use.

3 June 2014

Vasudev Kamath: Using WSME with Flask microframework

After reading Julien Danjou's I found out WSME (Web Service Made Easy) a Python framework which allows us to easily create Web Services in Python. For SILPA we needed a REST like interface and I thought of giving it try as WSME readily advertised the Flask integration, and this post was born when I read the documentation for Flask integration. First of all Flask is a nice framework which will right way allow development of REST api for simple purposes, but my requirement was bit complicated where I had to expose function in a separate python modules through SILPA. I think detailed requirement can be part of another post, so let me explain how to use WSME with Flask app. WSME integration with Flask is done via decorator function wsmeext.flask.signature which expects you to provide it with signature of function to expose. And here is its documentation, basically signature of signature function is
wsmeext.flask.signature(return_type, *arg_types, **options)
Yeah thats all docs have sadly. So basically exposing is the only thing WSME handles for us here, routing and other stuffs need to be done by Flask itself. So lets consider a example, simple function to add as shown below.
def add(a, b):
    return a + b
For providing REST like service, all you need below code.
from flask import Flask
from wsmeext.flask import signature
app = Flask(__name__)
@app.route('/add')
@signature(int, int, int)
def add(a, b):
    return a + b
if __name__ == '__main__':
       app.run()
So first argument to signature is return type of function and rest arguments are the argument to function to be exposed. Now you can access the newly exposed service by visiting http://localhost:5000/add but don't forget to pass the arguments either via query string or through post. You can restrict methods of access via Flask's route. So what's the big deal of not having docs right?.. Well fun part began when we use bit more complex return type like dictionaries or lists . Below is modified code I'm using to demonstrate problem I faced during using dict as return type.
from flask import Flask
from wsmeext.flask import signature
app = Flask(__name__)
@app.route('/add')
@signature(dict, int, int)
def add(a, b):
    return  "result": a + b 
if __name__ == '__main__':
    app.run()
Basically I'm returning a dictionary containing result now, for demonstration purpose. When I run the application boom python barked at me with following message.
Traceback (most recent call last):
File "wsme_dummy.py", line 7, in <module>
 @signature(dict, int, int)
File "c:\Users\invakam2\.virtualenvs\wsmetest\lib\site-packages\wsmeext\flask.py", line 48, in decorator
 funcdef.resolve_types(wsme.types.registry)
File "c:\Users\invakam2\.virtualenvs\wsmetest\lib\site-packages\wsme\api.py", line 109, in resolve_types
 self.return_type = registry.resolve_type(self.return_type)
File "c:\Users\invakam2\.virtualenvs\wsmetest\lib\site-packages\wsme\types.py", line 739, in resolve_type
 type_ = self.register(type_)
File "c:\Users\invakam2\.virtualenvs\wsmetest\lib\site-packages\wsme\types.py", line 668, in register
 class_._wsme_attributes = None
TypeError: can't set attributes of built-in/extension type 'dict'
After going through code from files involved in above traces this is what I found
  1. wsmeext.flask.signature inturn uses wsme.signature which is just alias of wsme.api.signature.
  2. Link in documentation in sentence See @signature for parameter documentation is broken and should actually link to wsme.signature in docs.
  3. wsme.signature actually calls resolve_type to check on types of return and arguments. This function checks if types are instance of dict or list in such cases it creates instances of wsme.type.DictType and wsme.type.ArrayType respectively with values from the argument.
  4. When I just passed built-in type dict the control went to else part which just passed the type to wsme.type.Register.registry function which tries to set the attribute _wsme_attribute which actually raises TypeError as we can't set attribute for built-in types.
So by inspecting code of wsme.type.Registry.resolve_type and wsme.type.Registry.register its clear that what signature expects when arguments or return type is dictionary/list is instance of dictionary/list with type of value in it. May be sentence is bit vague but I'm not sure how to put it more clearly, as an example in our case add function returns dictioanry with key as string and value as int, so return type argument for signature will be str: int . Similarly if you return array with int values it will be [int]. With above understanding our add function now looks like below.
@signature( str: int , int, int)
def add(a, b):
   return  'result': a + b 
and now code worked just fine!. What I couldn't figure out here is there is no way to have tuple as return value or argument, but I guess that is not big deal. So immidiate task for me after finding this is fix the link in documentation to point to wsme.signature and probably put some note some where in documentation about above finding.

2 June 2014

Rapha&#235;l Hertzog: My Free Software Activities since January 2014

If you follow my blog closely, you noticed that I skipped all my usual monthly summaries in 2014. It s not that I stopped doing free software work, instead I was just too busy to be able to report about what I did. As an excuse, let me tell you that we just moved into a new house which was in construction since may last year. The lack of visible activity on my blog resulted in a steady decrease of the amount of donations received (January: 70.72 , February: 71.75 , March: 51.25 , April: 39.9 , May: 40.33 ). Special thanks to all the people who kept supporting my work even though I stopped reporting about it. So let s fix this. This report will be a bit less detailed since it covers the whole period since the start of the year. Debian France Preparations related to general assemblies. The year started with lots of work related to Debian France. First I took care of setting up limesurvey with Alexandre Delano to handle the vote to pick our new logo:
The new logo of Debian France I also helped Sylvestre Ledru to finalize and close the accounting books for 2013 in preparation for the general assembly that was due later in the month. I wrote the moral report of the president to be presented to the assembly. And last step, I collected vote mandates to ensure that we were going to meet the quorum for the extraordinary assembly that was planned just after the usual yearly assembly. The assemblies took place during a two days mini-debconf in Paris (January 17-18) where I was obviously present even though I gave no talk besides announcing the logo contest winner and thanking people for their participation.
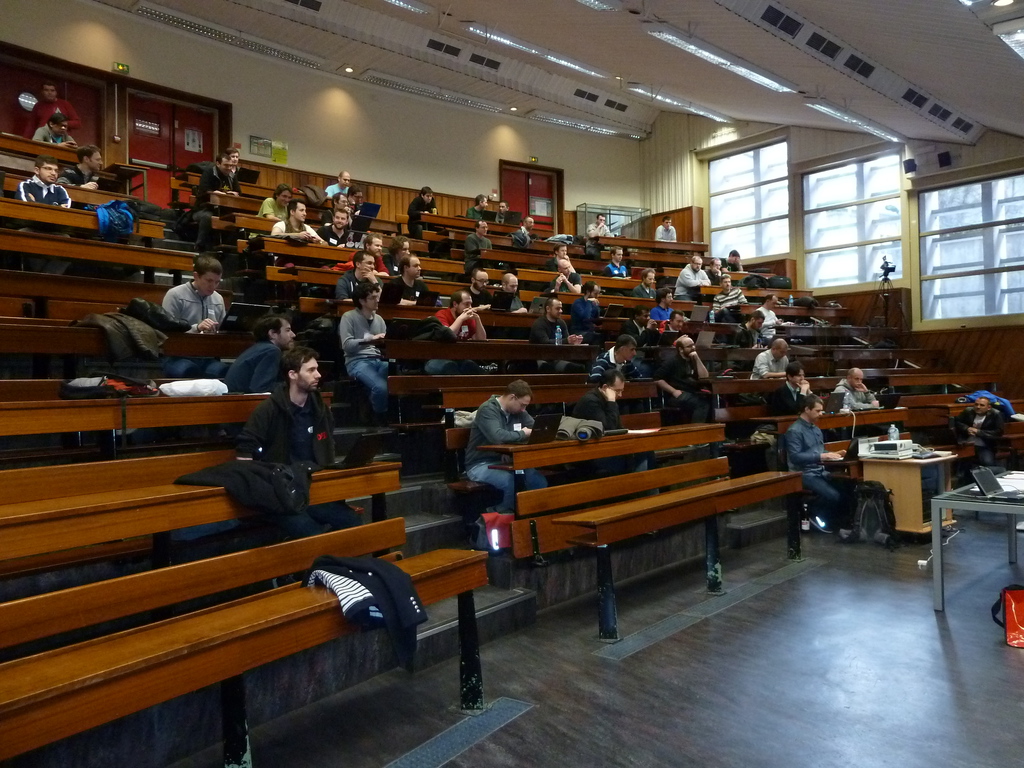
Assembl e g n rale 2014 de Debian France

The Debian France members during the general assembly

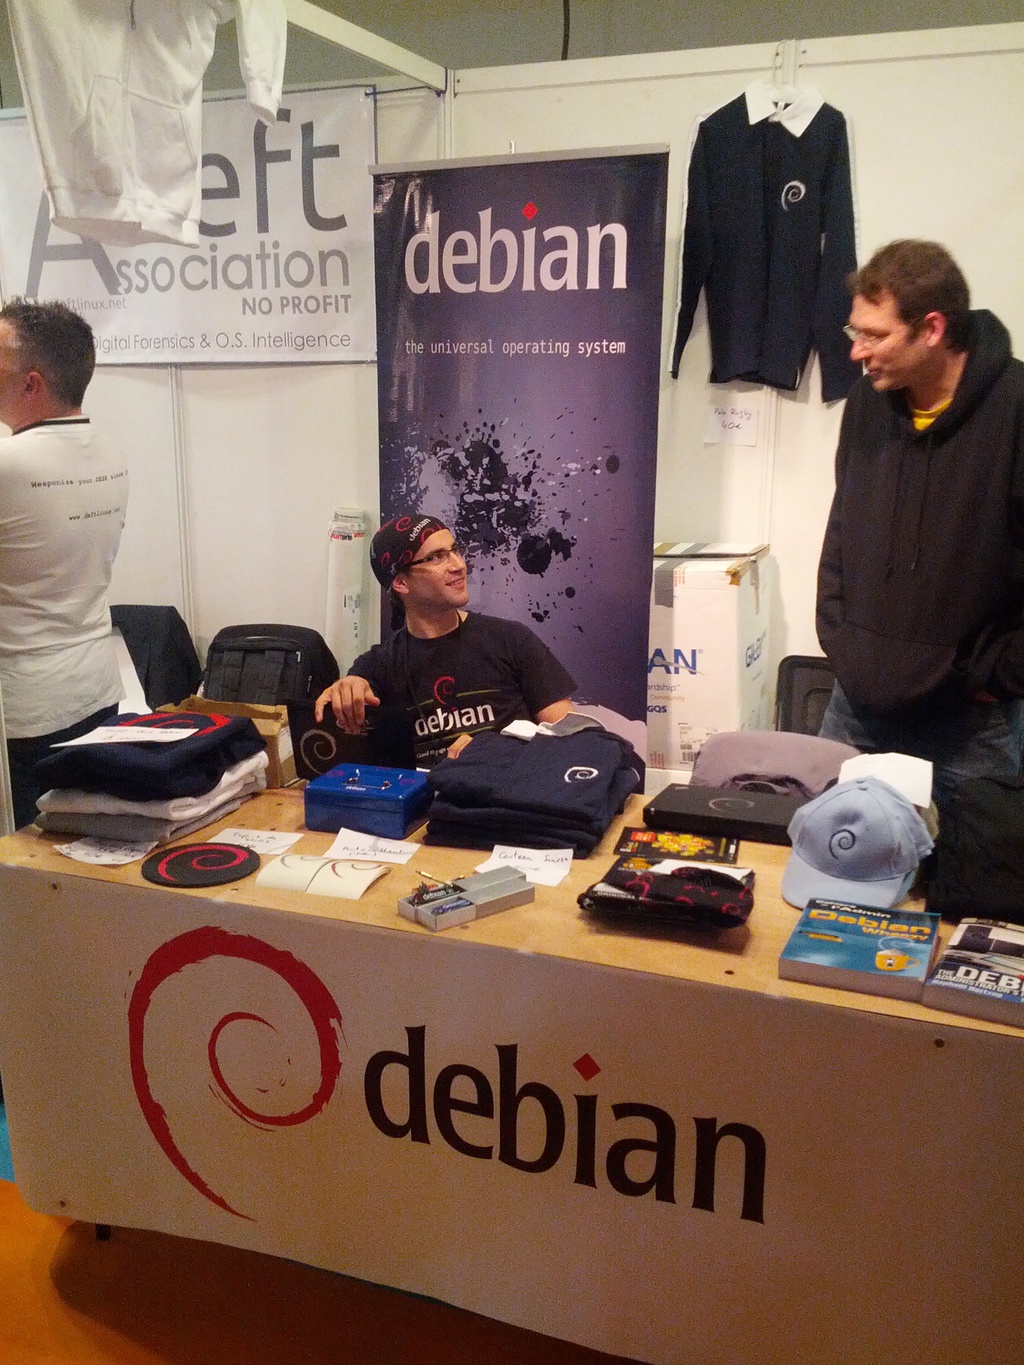
It s worth noting that the extraordinary assembly was meant primarily to enshrine in our bylaws the possibility to act as a trusted organization for Debian. This status should be officialized by the Debian project leader (Lucas Nussbaum) in the upcoming weeks since we answered satisfactorily to all questions. Our paypal donation form and the accounting tools behind it are ready. Galette packaging and members map. I managed to hand over the package maintenance of galette to Fran ois-R gis Vuillemin. I sponsored all his uploads and we packaged a new plugin that allows to create a map with all the members who accept to share their location. The idea was to let people meet each other when they don t live far away with the long term goal to have Debian France organized activities not only in Paris but everywhere in France. New contributor game. Last but not least, I organized a game to encourage people to do their first contribution to Debian by offering them a copy of my book if they managed to complete a small Debian project. We got many interesting projects but the result so far seem to be very mixed. Many people did not complete their project (yet) that said for the few that did substantial work, it was rather good and they seem to be interested to continue to contribute. Debian France booth at Solutions Linux in Paris. Like each year, I spent two days in Paris to help man the Debian France booth at Solutions Linux. We had lots of goodies on sale and we made more than 2000 EUR in earnings during the two days. I also used this opportunity to try to convince companies to support the new Debian LTS effort.
Debian France booth at Solutions Linux

Tanguy Ortolo and Fernando Lagrange behind the Debian France booth

The Debian Administrator s Handbook In the last days of 2013, we released the wheezy update of the book. Then I quickly organized everything needed so that the various translation teams can now focus their efforts on the latest release of the book. Later (in February) I announced the availability of the French and Spanish translations. Debian Squeeze LTS When the security team called for help to try to put in place long term support for Squeeze, I replied positively because I m convinced that it s very important if Debian wants to stay an acceptable choice in big deployments and because I knew that some of my customers would be interested Thus I followed all the discussions (on a semi-private list first and then on debian-lts@lists.debian.org) and contributed my own experience. I have also taken up the responsibility to coordinate with the Debian contributors who can be hired to work on Squeeze LTS so that we have a clear common offer for all the companies who have offered financial support towards Squeeze LTS. Expect further news on this front in the upcoming days/weeks. Tryton I have been a long time user of SQL-Ledger to manage the accounting of my company Freexian. But while the license is free software, the project is not. It s the work of a single developer who doesn t really accept help. I have thus been considering to move to something else for a long time but never did anything. This year, after some rough evaluation, I decided to switch to Tryton for my company. It s probably not a wise choice from a business perspective because that migration took me many hours of unpaid labor but from a free software perspective it s definitely better than everything else I saw. I contributed a lot of bug reports and a few patches already (#3596, #3631, #3633, #3665, #3667, #3694, #3695, #3696, #3697) mainly about problems found in the French chart of accounts but also about missing features for my use case. I also accepted to sponsor Matthias Berhle, who is maintaining the official Debian packages of Tryton. He s already a Debian maintainer so it s mainly a matter of reviewing new source packages and granting him the required rights. Misc Debian work Thanks See you next month for a new summary of my activities.

2 comments Liked this article? Click here. My blog is Flattr-enabled.

B lint R czey: I Can Hear Music again (thanks to forked-daapd/Debian)

When I started looking for a lightweight solution of serving a music library over LAN I did not expect so many complications. I expected it not to be a unique need to have something running on a SheevaPlug straight from the Debian repository. Apparently it kind of was. Debian used to have mt-daapd (popcon: 165), but now it is available from oldstable only and upstream is dead. There is tangerine (popcon: 98) with its Mono dependencies and GUI which seemed to me overkill and more like a demo of a networked application written in Mono than a music library server. The most promising candidate was forked-daapd (popcon: 220) but it was far from being a true winner. First, it had a series of dead upstreams. At the beginning it was forked from mt-daapd (hence the name) by Julien Blache who also served as the prior Debian maintainer. Then the code base was forked and converted to use Grand Central Dispatch. Then the GCD fork died off slowly as well a few years ago. When I found the package it had been unmaintained for a few years and was based on the GCD branch which prevented building it on many architectures and the server itself was crashing or quitting occasionally. Luckily there still existed a fork thanks to Espen J rgensen which was well maintained and could serve as a way out but examining it closely it turned out that it had switched to libevent from GCD but to a version (1.4) which is present only in oldstable! And some say Debian s software versions are ancient ;-). Moreover it was not simply libevent 1.4-based, but it included some heavily patched parts of it. Espen also liked the idea of packaging his version in Debian and we extracted the patches to libevent and slowly got them accepted to libevent s master. Forked-daapd s master works best with libevent 2.1.4-alpha, but thanks to Espen the development branch now also works with libevent 2.0.x giving up some performance and a little feature. This was a long journey, but finally Espen s forked-daapd became ready for being used as a new upstream of the Debian package thus please welcome 20.0+git20140530+gc740e6e-1, the first version of forked-daapd building on all architectures for a very long time and a prime candidate for being the music library server in Jessie (and wheezy-backports, soon)! Testing, bug reports are always welcome! From the package description:
 forked-daapd is an iTunes-compatible media server, originally intended
 as a rewrite of Firefly Media Server (also known as mt-daapd).
 It supports a wide range of audio formats, can stream video to iTunes,
 FrontRow and other compatible clients, has support for Apple's Remote
 iPhone/iPod application and can stream music to AirTunes devices like
 the AirPort Express.
 It also features RSP support for Roku's SoundBridge devices.
 Built-in, on-the-fly decoding support enables serving popular free music
 formats like FLAC, Ogg Vorbis or Musepack to those clients that do not
 otherwise support them.

1 June 2014

Antonio Terceiro: An introduction to the Debian Continuous Integration project

Debian is a big system. At the time of writing, looking at my local package list caches tells me that the unstable suite contains 21306 source packages, and 42867 binary packages on amd64. Between these 42867 binary packages, there is an unthinkable number of inter-package dependencies. For example the dependency graph of the ruby packages contains other 20-something packages. A new version of any of these packages can potentially break some functionality in the ruby package. And that dependency graph is very small. Looking at the dependency graph for, say, the rails package will make your eyes bleed. I tried it here, and GraphViz needed a PNG image with 7653 10003 pixels to draw it. It ain t pretty. Installing rails on a clean Debian system will pull in another 109 packages as part of the dependency chain. Again, as new versions of those packages are uploaded the archive, there is a probability that a backwards-incompatible change, or even a bug fix which was being worked around, might make some funcionality in rails stop working. Even if that probability is low for each package in the dependency chain, with enough packages the probability of any of them causing problems for rails is quite high. And still the rails dependency chain is not that big. libreoffice will pull in another 264 packages. gnome will pull in 1311 dependencies, and kde-full 1320 (!). With a system this big, problems will arrive, and that s a fact of life. As developers, what we can do is try to spot these problems as early as possible, and fixing them in time to make a solid release with the high quality Debian is known for. While automated testing is not the proverbial Silver Bullet of Software Engineering, it is an effective way of finding regressions. Back in 2006, Ian Jackson started the development of autopkgtest as a tool to test Debian packages in their installed form (as opposed to testing packages using their source tree). In 2011, the autopkgtest test suite format was proposed as a standard for the Debian project, in what we now know as the DEP-8 specification. Since then, some maintainers such as myself started experimenting with DEP-8 tests in their packages. There was an expectation in the air that someday, someone would run those tests for the entire archive, and that would be a precious source of QA information. Durign the holiday break last year, I decided to give it a shot. I initially called the codebase dep8. Later I renamed it to debci, since it could potentially also run other other types of test suites in the future. Since early January, ci.debian.net run an instance of debci for the Debian Project. The Debian continuous Integration will trigger tests at most 4 times a day, 3 hours after each dinstall run. It will update a local APT cache and look for packages that declare a DEP-8 test suite. Each package with a test suite will then have its test suite executed if there was any change in its dependency chain since the last test run. Existing test results are published at ci.debian.net every hour, and at the end of each batch a global status is updated. Maintainers can subscribe to a per package Atom feed to keep up with their package test results. People interested in the overall status can subscribe to a global Atom feed of events. Since the introduction of Debian CI in mid-January 2014, we have seen an amazing increase in the number of packages with test suites. We had little less than 200 packages with test suites back then, against around 350 now (early June 2014). The ratio of packages passing passing their test suite has also improved a lot, going from less than 50% to more than 75%. There is documentation available, including a FAQ for package maintainers with further information about how the system works, how to declare test suites in their packages and how to reproduce test runs locally. Also available is development information about debci itself, to those inclined to help improve the system. This is just the beginning. debci is under a good rate of development, and you can expect to see a constant flux of improvements. In special, I would like to mention a few people who are giving amazing contributions to the project:

Andrew Cater: Not quite the last of the 32 bit machines ...

I've just got back my daughter's netbook. About 5 years old. Originally cost me 100 as part of a deal with my ISP.

1.6GHz Atom N270 processor, 2GB of memory, 120GB of Samsung hard disk.
It's a "Freedom" netbook - almost certainly made by Quanta. Atheros chipset for wifi. [A9285 for wifi, Realtek 8101E for Ethernet]

This is the sort of machine that is probably going into landfill round about now. It's been running XP and mostly used by my father, who has given up on it now it won't update.

I used the unofficial Debian 7.5 cd which includes firmware because I was going to be using wifi to install Debian and because I didn't know what wifi chipset was in there. I had previously tested and run a Debian live USB image but faced problems - the cursor wouldn't play although the KDE desktop appeared fine.

An expert install selecting KDE worked fine but produced immediate problems: cursor was erratic, the screen blacked out and I couldn't switch it off - I had to remove the mains power and battery to kill it.

A second install over the top of this, wiping out the first install but selecting LXDE worked perfectly and works well. It's possible that a full KDE desktop is stressing this litle 10 inch laptop's 2GB and display memory a bit too much.

I'm very pleased to have rescued this machine and got a Linux that "just works" albeit a bit more slowly than I'm used to. Even if it gets used just as a terminal for amateur radio / a spare emergency machine in a corner somewhere, it's better than being junked. Best of all, installing vrms shows that, although I enabled non-free in the initial install, this machine requires no non-free firmware so has saved me the cost of buying an FSF approved secondhand Thinkpad.


31 May 2014

Dirk Eddelbuettel: RcppGSL 0.2.1 and 0.2.2

A few days ago, version 0.2.1 of RcppGSL---our interface package between R and the GNU GSL using our Rcpp package for seamless R and C++ integration---appeared on CRAN making it the first release in some time. And it turned that this version tickled an obscure and long-dormant bug under clang which was found on OS X Mavericks---which Kevin Ushey consequently squashed. So this is now reflected in version 0.2.2 which just arrived on CRAN. Besides the bugfix, a few things were modernized to reflect capabilities of Rcpp 0.11.0 and later. The releases also contain a few changes that had accumulated since the previous release in 2012 such as an additional example using B-splines, and use of updated vignette build options provided by R. The NEWS file entries follows below:
Changes in version 0.2.2 (2014-05-31)
  • A subtle bug (tickled only by clang on some OS versions) in vector and matrix view initialization was corrected by Kevin Ushey
Changes in version 0.2.1 (2014-05-26)
  • Added new example based on B-splines example in GSL manual illustrating simple GSL use via Rcpp attributes
  • Vignette compilation has been reverted to using highlight since version 0.4.2 or greater can be used as a vignette engine (with R 3.0.* or later).
  • Vignette compilation is now being done by R CMD build as R 3.0.0 supports different vignette engines, so the vignette build process has been simplified. A convenience helper script has also been added for command-line builds.
  • Unit tests now use sourceCpp() instead of cxxfunction() from the inline package
  • The DESCRIPTION file now uses Suggests: Rcpp (instead of Depends: Rcpp) to permit building of the vignette
  • The package now takes advantage of the simplified build process available with Rcpp (>= 0.11.0)
  • Similar updates to the build process were made for the example package included with RcppGSL
And courtesy of CRANberries, a summaries of changes to release 0.2.0 and this week's release 0.2.1 are available. More information is on the RcppGSL page. Questions, comments etc should go to the rcpp-devel mailing list off the R-Forge page.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

Next.

Previous.