Search Results: "reg"

1 June 2025

Ben Hutchings: FOSS activity in May 2025

31 May 2025

Antoine Beaupr : Traffic meter per ASN without logs

Have you ever found yourself in the situation where you had no or anonymized logs and still wanted to figure out where your traffic was coming from? Or you have multiple upstreams and are looking to see if you can save fees by getting into peering agreements with some other party? Or your site is getting heavy load but you can't pinpoint it on a single IP and you suspect some amoral corporation is training their degenerate AI on your content with a bot army? (You might be getting onto something there.) If that rings a bell, read on.

TL;DR: ... or just skip the cruft and install asncounter:
pip install asncounter
Also available in Debian 14 or later, or possibly in Debian 13 backports (soon to be released) if people are interested:
apt install asncounter
Then count whoever is hitting your network with:
awk ' print $2 ' /var/log/apache2/*access*.log   asncounter
or:
tail -F /var/log/apache2/*access*.log   awk ' print $2 '   asncounter
or:
tcpdump -q -n   asncounter --input-format=tcpdump --repl
or:
tcpdump -q -i eth0 -n -Q in "tcp and tcp[tcpflags] & tcp-syn != 0 and (port 80 or port 443)"   asncounter --input-format=tcpdump --repl
Read on for why this matters, and why I wrote yet another weird tool (almost) from scratch.

Background and manual work This is a tool I've been dreaming of for a long, long time. Back in 2006, at Koumbit a colleague had setup TAS ("Traffic Accounting System", " " in Russian, apparently), a collection of Perl script that would do per-IP accounting. It was pretty cool: it would count bytes per IP addresses and, from that, you could do analysis. But the project died, and it was kind of bespoke. Fast forward twenty years, and I find myself fighting off bots at the Tor Project (the irony...), with our GitLab suffering pretty bad slowdowns (see issue tpo/tpa/team#41677 for the latest public issue, the juicier one is confidential, unfortunately). (We did have some issues caused by overloads in CI, as we host, after all, a fork of Firefox, which is a massive repository, but the applications team did sustained, awesome work to fix issues on that side, again and again (see tpo/applications/tor-browser#43121 for the latest, and tpo/applications/tor-browser#43121 for some pretty impressive correlation work, I work with really skilled people). But those issues, I believe were fixed.) So I had the feeling it was our turn to get hammered by the AI bots. But how do we tell? I could tell something was hammering at the costly /commit/ and (especially costly) /blame/ endpoint. So at first, I pulled out the trusted awk, sort uniq -c sort -n tail pipeline I am sure others have worked out before:
awk ' print $1 ' /var/log/nginx/*.log   sort   uniq -c   sort -n   tail -10
For people new to this, that pulls the first field out of web server log files, sort the list, counts the number of unique entries, and sorts that so that the most common entries (or IPs) show up first, then show the top 10. That, other words, answers the question of "which IP address visits this web server the most?" Based on this, I found a couple of IP addresses that looked like Alibaba. I had already addressed an abuse complaint to them (tpo/tpa/team#42152) but never got a response, so I just blocked their entire network blocks, rather violently:
for cidr in 47.240.0.0/14 47.246.0.0/16 47.244.0.0/15 47.235.0.0/16 47.236.0.0/14; do 
  iptables-legacy -I INPUT -s $cidr -j REJECT
done
That made Ali Baba and his forty thieves (specifically their AL-3 network go away, but our load was still high, and I was still seeing various IPs crawling the costly endpoints. And this time, it was hard to tell who they were: you'll notice all the Alibaba IPs are inside the same 47.0.0.0/8 prefix. Although it's not a /8 itself, it's all inside the same prefix, so it's visually easy to pick it apart, especially for a brain like mine who's stared too long at logs flowing by too fast for their own mental health. What I had then was different, and I was tired of doing the stupid thing I had been doing for decades at this point. I had recently stumbled upon pyasn recently (in January, according to my notes) and somehow found it again, and thought "I bet I could write a quick script that loops over IPs and counts IPs per ASN". (Obviously, there are lots of other tools out there for that kind of monitoring. Argos, for example, presumably does this, but it's a kind of a huge stack. You can also get into netflows, but there's serious privacy implications with those. There are also lots of per-IP counters like promacct, but that doesn't scale. Or maybe someone already had solved this problem and I just wasted a week of my life, who knows. Someone will let me know, I hope, either way.)

ASNs and networks A quick aside, for people not familiar with how the internet works. People that know about ASNs, BGP announcements and so on can skip. The internet is the network of networks. It's made of multiple networks that talk to each other. The way this works is there is a Border Gateway Protocol (BGP), a relatively simple TCP-based protocol, that the edge routers of those networks used to announce each other what network they manage. Each of those network is called an Autonomous System (AS) and has an AS number (ASN) to uniquely identify it. Just like IP addresses, ASNs are allocated by IANA and local registries, they're pretty cheap and useful if you like running your own routers, get one. When you have an ASN, you'll use it to, say, announce to your BGP neighbors "I have 198.51.100.0/24" over here and the others might say "okay, and I have 216.90.108.31/19 over here, and I know of this other ASN over there that has 192.0.2.1/24 too! And gradually, those announcements flood the entire network, and you end up with each BGP having a routing table of the global internet, with a map of which network block, or "prefix" is announced by which ASN. It's how the internet works, and it's a useful thing to know, because it's what, ultimately, makes an organisation responsible for an IP address. There are "looking glass" tools like the one provided by routeviews.org which allow you to effectively run "trace routes" (but not the same as traceroute, which actively sends probes from your location), type an IP address in that form to fiddle with it. You will end up with an "AS path", the way to get from the looking glass to the announced network. But I digress, and that's kind of out of scope. Point is, internet is made of networks, networks are autonomous systems (AS) and they have numbers (ASNs), and they announced IP prefixes (or "network blocks") that ultimately tells you who is responsible for traffic on the internet.

Introducing asncounter So my goal was to get from "lots of IP addresses" to "list of ASNs", possibly also the list of prefixes (because why not). Turns out pyasn makes that really easy. I managed to build a prototype in probably less than an hour, just look at the first version, it's 44 lines (sloccount) of Python, and it works, provided you have already downloaded the required datafiles from routeviews.org. (Obviously, the latest version is longer at close to 1000 lines, but it downloads the data files automatically, and has many more features). The way the first prototype (and later versions too, mostly) worked is that you feed it a list of IP addresses on standard input, it looks up the ASN and prefix associated with the IP, and increments a counter for those, then print the result. That showed me something like this:
root@gitlab-02:~/anarcat-scripts# tcpdump -q -i eth0 -n -Q in "(udp or tcp)"   ./asncounter.py --tcpdump                                                                                                                                                                          
tcpdump: verbose output suppressed, use -v[v]... for full protocol decode                                                                
listening on eth0, link-type EN10MB (Ethernet), snapshot length 262144 bytes                                                             
INFO: collecting IPs from stdin, using datfile ipasn_20250523.1600.dat.gz                                                                
INFO: loading datfile /root/.cache/pyasn/ipasn_20250523.1600.dat.gz...                                                                   
INFO: loading /root/.cache/pyasn/asnames.json                       
ASN     count   AS               
136907  7811    HWCLOUDS-AS-AP HUAWEI CLOUDS, HK                                                                                         
[----]  359     [REDACTED]
[----]  313     [REDACTED]
8075    254     MICROSOFT-CORP-MSN-AS-BLOCK, US
[---]   164     [REDACTED]
[----]  136     [REDACTED]
24940   114     HETZNER-AS, DE  
[----]  98      [REDACTED]
14618   82      AMAZON-AES, US                                                                                                           
[----]  79      [REDACTED]
prefix  count                                         
166.108.192.0/20        1294                                                                                                             
188.239.32.0/20 1056                                          
166.108.224.0/20        970                    
111.119.192.0/20        951              
124.243.128.0/18        667                                         
94.74.80.0/20   651                                                 
111.119.224.0/20        622                                         
111.119.240.0/20        566           
111.119.208.0/20        538                                         
[REDACTED]  313           
Even without ratios and a total count (which will come later), it was quite clear that Huawei was doing something big on the server. At that point, it was responsible for a quarter to half of the traffic on our GitLab server or about 5-10 queries per second. But just looking at the logs, or per IP hit counts, it was really hard to tell. That traffic is really well distributed. If you look more closely at the output above, you'll notice I redacted a couple of entries except major providers, for privacy reasons. But you'll also notice almost nothing is redacted in the prefix list, why? Because all of those networks are Huawei! Their announcements are kind of bonkers: they have hundreds of such prefixes. Now, clever people in the know will say "of course they do, it's an hyperscaler; just ASN14618 (AMAZON-AES) there is way more announcements, they have 1416 prefixes!" Yes, of course, but they are not generating half of my traffic (at least, not yet). But even then: this also applies to Amazon! This way of counting traffic is way more useful for large scale operations like this, because you group by organisation instead of by server or individual endpoint. And, ultimately, this is why asncounter matters: it allows you to group your traffic by organisation, the place you can actually negotiate with. Now, of course, that assumes those are entities you can talk with. I have written to both Alibaba and Huawei, and have yet to receive a response. I assume I never will. In their defence, I wrote in English, perhaps I should have made the effort of translating my message in Chinese, but then again English is the Lingua Franca of the Internet, and I doubt that's actually the issue.

The Huawei and Facebook blocks Another aside, because this is my blog and I am not looking for a Pullitzer here. So I blocked Huawei from our GitLab server (and before you tear your shirt open: only our GitLab server, everything else is still accessible to them, including our email server to respond to my complaint). I did so 24h after emailing them, and after examining their user agent (UA) headers. Boy that was fun. In a sample of 268 requests I analyzed, they churned out 246 different UAs. At first glance, they looked legit, like:
Mozilla/5.0 (Macintosh; Intel Mac OS X 10_15_7) AppleWebKit/537.36 (KHTML, like Gecko) Chrome/131.0.0.0 Safari/537.36
Safari on a Mac, so far so good. But when you start digging, you notice some strange things, like here's Safari running on Linux:
Mozilla/5.0 (X11; U; Linux i686; en-US) AppleWebKit/534.3 (KHTML, like Gecko) Chrome/6.0.457.0 Safari/534.3
Was Safari ported to Linux? I guess that's.. possible? But here is Safari running on a 15 year old Ubuntu release (10.10):
Mozilla/5.0 (X11; Linux i686) AppleWebKit/534.24 (KHTML, like Gecko) Ubuntu/10.10 Chromium/12.0.702.0 Chrome/12.0.702.0 Safari/534.24
Speaking of old, here's Safari again, but this time running on Windows NT 5.1, AKA Windows XP, released 2001, EOL since 2019:
Mozilla/5.0 (Windows; U; Windows NT 5.1; en-CA) AppleWebKit/534.13 (KHTML like Gecko) Chrome/9.0.597.98 Safari/534.13
Really? Here's Firefox 3.6, released 14 years ago, there were quite a lot of those:
Mozilla/5.0 (Windows; U; Windows NT 6.1; lt; rv:1.9.2) Gecko/20100115 Firefox/3.6
I remember running those old Firefox releases, those were the days. But to me, those look like entirely fake UAs, deliberately rotated to make it look like legitimate traffic. In comparison, Facebook seemed a bit more legit, in the sense that they don't fake it. most hits are from:
meta-externalagent/1.1 (+https://developers.facebook.com/docs/sharing/webmasters/crawler)
which, according their documentation:
crawls the web for use cases such as training AI models or improving products by indexing content directly
From what I could tell, it was even respecting our rather liberal robots.txt rules, in that it wasn't crawling the sprawling /blame/ or /commit/ endpoints, explicitly forbidden by robots.txt. So I've blocked the Facebook bot in robots.txt and, amazingly, it just went away. Good job Facebook, as much as I think you've given the empire to neo-nazis, cause depression and genocide, you know how to run a crawler, thanks. Huawei was blocked at the web server level, with a friendly 429 status code telling people to contact us (over email) if they need help. And they don't care: they're still hammering the server, from what I can tell, but then again, I didn't block the entire ASN just yet, just the blocks I found crawling the server over a couple hours.

A full asncounter run So what does a day in asncounter look like? Well, you start with a problem, say you're getting too much traffic and want to see where it's from. First you need to sample it. Typically, you'd do that with tcpdump or tailing a log file:
tail -F /var/log/apache2/*access*.log   awk ' print $2 '   asncounter
If you have lots of traffic or care about your users' privacy, you're not going to log IP addresses, so tcpdump is likely a good option instead:
tcpdump -q -n   asncounter --input-format=tcpdump --repl
If you really get a lot of traffic, you might want to get a subset of that to avoid overwhelming asncounter, it's not fast enough to do multiple gigabit/second, I bet, so here's only incoming SYN IPv4 packets:
tcpdump -q -n -Q in "tcp and tcp[tcpflags] & tcp-syn != 0 and (port 80 or port 443)"   asncounter --input-format=tcpdump --repl
In any case, at this point you're staring at a process, just sitting there. If you passed the --repl or --manhole arguments, you're lucky: you have a Python shell inside the program. Otherwise, send SIGHUP to the thing to have it dump the nice tables out:
pkill -HUP asncounter
Here's an example run:
> awk ' print $2 ' /var/log/apache2/*access*.log   asncounter
INFO: using datfile ipasn_20250527.1600.dat.gz
INFO: collecting addresses from <stdin>
INFO: loading datfile /home/anarcat/.cache/pyasn/ipasn_20250527.1600.dat.gz...
INFO: finished reading data
INFO: loading /home/anarcat/.cache/pyasn/asnames.json
count   percent ASN AS
12779   69.33   66496   SAMPLE, CA
3361    18.23   None    None
366 1.99    66497   EXAMPLE, FR
337 1.83    16276   OVH, FR
321 1.74    8075    MICROSOFT-CORP-MSN-AS-BLOCK, US
309 1.68    14061   DIGITALOCEAN-ASN, US
128 0.69    16509   AMAZON-02, US
77  0.42    48090   DMZHOST, GB
56  0.3 136907  HWCLOUDS-AS-AP HUAWEI CLOUDS, HK
53  0.29    17621   CNCGROUP-SH China Unicom Shanghai network, CN
total: 18433
count   percent prefix  ASN AS
12779   69.33   192.0.2.0/24    66496   SAMPLE, CA
3361    18.23   None        
298 1.62    178.128.208.0/20    14061   DIGITALOCEAN-ASN, US
289 1.57    51.222.0.0/16   16276   OVH, FR
272 1.48    2001:DB8::/48   66497   EXAMPLE, FR
235 1.27    172.160.0.0/11  8075    MICROSOFT-CORP-MSN-AS-BLOCK, US
94  0.51    2001:DB8:1::/48 66497   EXAMPLE, FR
72  0.39    47.128.0.0/14   16509   AMAZON-02, US
69  0.37    93.123.109.0/24 48090   DMZHOST, GB
53  0.29    27.115.124.0/24 17621   CNCGROUP-SH China Unicom Shanghai network, CN
Those numbers are actually from my home network, not GitLab. Over there, the battle still rages on, but at least the vampire bots are banging their heads against the solid Nginx wall instead of eating the fragile heart of GitLab. We had a significant improvement in latency thanks to the Facebook and Huawei blocks... Here are the "workhorse request duration stats" for various time ranges, 20h after the block:
range mean max stdev
20h 449ms 958ms 39ms
7d 1.78s 5m 14.9s
30d 2.08s 3.86m 8.86s
6m 901ms 27.3s 2.43s
We went from two seconds mean to 500ms! And look at that standard deviation! 39ms! It was ten seconds before! I doubt we'll keep it that way very long but for now, it feels like I won a battle, and I didn't even have to setup anubis or go-away, although I suspect that will unfortunately come. Note that asncounter also supports exporting Prometheus metrics, but you should be careful with this, as it can lead to cardinal explosion, especially if you track by prefix (which can be disabled with --no-prefixes . Folks interested in more details should read the fine manual for more examples, usage, and discussion. It shows, among other things, how to effectively block lots of networks from Nginx, aggregate multiple prefixes, block entire ASNs, and more! So there you have it: I now have the tool I wish I had 20 years ago. Hopefully it will stay useful for another 20 years, although I'm not sure we'll have still have internet in 20 years. I welcome constructive feedback, "oh no you rewrote X", Grafana dashboards, bug reports, pull requests, and "hell yeah" comments. Hacker News, let it rip, I know you can give me another juicy quote for my blog. This work was done as part of my paid work for the Tor Project, currently in a fundraising drive, give us money if you like what you read.

29 May 2025

Arthur Diniz: Bringing Kubernetes Back to Debian

I ve been part of the Debian Project since 2019, when I attended DebConf held in Curitiba, Brazil. That event sparked my interest in the community, packaging, and how Debian works as a distribution. In the early years of my involvement, I contributed to various teams such as the Python, Golang and Cloud teams, packaging dependencies and maintaining various tools. However, I soon felt the need to focus on packaging software I truly enjoyed, tools I was passionate about using and maintaining. That s when I turned my attention to Kubernetes within Debian.

A Broken Ecosystem The Kubernetes packaging situation in Debian had been problematic for some time. Given its large codebase and complex dependency tree, the initial packaging approach involved vendorizing all dependencies. While this allowed a somewhat functional package to be published, it introduced several long-term issues, especially security concerns. Vendorized packages bundle third-party dependencies directly into the source tarball. When vulnerabilities arise in those dependencies, it becomes difficult for Debian s security team to patch and rebuild affected packages system-wide. This approach broke Debian s best practices, and it eventually led to the abandonment of the Kubernetes source package, which had stalled at version 1.20.5. Due to this abandonment, critical bugs emerged and the package was removed from Debian s testing channel, as we can see in the package tracker.

New Debian Kubernetes Team Around this time, I became a Debian Maintainer (DM), with permissions to upload certain packages. I saw an opportunity to both contribute more deeply to Debian and to fix Kubernetes packaging. In early 2024, just before DebConf Busan in South Korea, I founded the Debian Kubernetes Team. The mission of the team was to repackage Kubernetes in a maintainable, security-conscious, and Debian-compliant way. At DebConf, I shared our progress with the broader community and received great feedback and more visibility, along with people interested in contributing to the team. Our first tasks was to migrate existing Kubernetes-related tools such as kubectx, kubernetes-split-yaml and kubetail into a dedicated namespace on Salsa, Debian s GitLab instance. Many of these tools were stored across different teams (like the Go team), and consolidating them helped us organize development and focus our efforts.

De-vendorizing Kubernetes Our main goal was to un-vendorize Kubernetes and bring it up-to-date with upstream releases. This meant:
  • Removing the vendor directory and all embedded third-party code.
  • Trimming the build scope to focus solely on building kubectl, Kubernetes CLI.
  • Using Files-Excluded in debian/copyright to cleanly drop unneeded files during source imports.
  • Rebuilding the dependency tree, ensuring all Go modules were separately packaged in Debian.
We used uscan, a standard Debian packaging tool that fetches upstream tarballs and prepares them accordingly. The Files-Excluded directive in our debian/copyright file instructed uscan to automatically remove unnecessary files during the repackaging process:
$ uscan
Newest version of kubernetes on remote site is 1.32.3, specified download version is 1.32.3
Successfully repacked ../v1.32.3 as ../kubernetes_1.32.3+ds.orig.tar.gz, deleting 30616 files from it.
The results were dramatic. By comparing the original upstream tarball with our repackaged version, we can see that our approach reduced the tarball size by over 75%:
$ du -h upstream-v1.32.3.tar.gz kubernetes_1.32.3+ds.orig.tar.gz
14M	upstream-v1.32.3.tar.gz
3.2M	kubernetes_1.32.3+ds.orig.tar.gz
This significant reduction wasn t just about saving space. By removing over 30,000 files, we simplified the package, making it more maintainable. Each dependency could now be properly tracked, updated, and patched independently, resolving the security concerns that had plagued the previous packaging approach.

Dependency Graph To give you an idea of the complexity involved in packaging Kubernetes for Debian, the image below is a dependency graph generated with debtree, visualizing all the Go modules and other dependencies required to build the kubectl binary. kubectl-depgraph This web of nodes and edges represents every module and its relationship during the compilation process of kubectl. Each box is a Debian package, and the lines connecting them show how deeply intertwined the ecosystem is. What might look like a mess of blue spaghetti is actually a clear demonstration of the vast and interconnected upstream world that tools like kubectl rely on. But more importantly, this graph is a testament to the effort that went into making kubectl build entirely using Debian-packaged dependencies only, no vendoring, no downloading from the internet, no proprietary blobs.

Upstream Version 1.32.3 and Beyond After nearly two years of work, we successfully uploaded version 1.32.3+ds of kubectl to Debian unstable. kubernetes/-/merge_requests/1 The new package also includes:
  • Zsh, Fish, and Bash completions installed automatically
  • Man pages and metadata for improved discoverability
  • Full integration with kind and docker for testing purposes

Integration Testing with Autopkgtest To ensure the reliability of kubectl in real-world scenarios, we developed a new autopkgtest suite that runs integration tests using real Kubernetes clusters created via Kind. Autopkgtest is a Debian tool used to run automated tests on binary packages. These tests are executed after the package is built but before it s accepted into the Debian archive, helping catch regressions and integration issues early in the packaging pipeline. Our test workflow validates kubectl by performing the following steps:
  • Installing Kind and Docker as test dependencies.
  • Spinning up two local Kubernetes clusters.
  • Switching between cluster contexts to ensure multi-cluster support.
  • Deploying and scaling a sample nginx application using kubectl.
  • Cleaning up the entire test environment to avoid side effects.
  • debian/tests/kubectl.sh

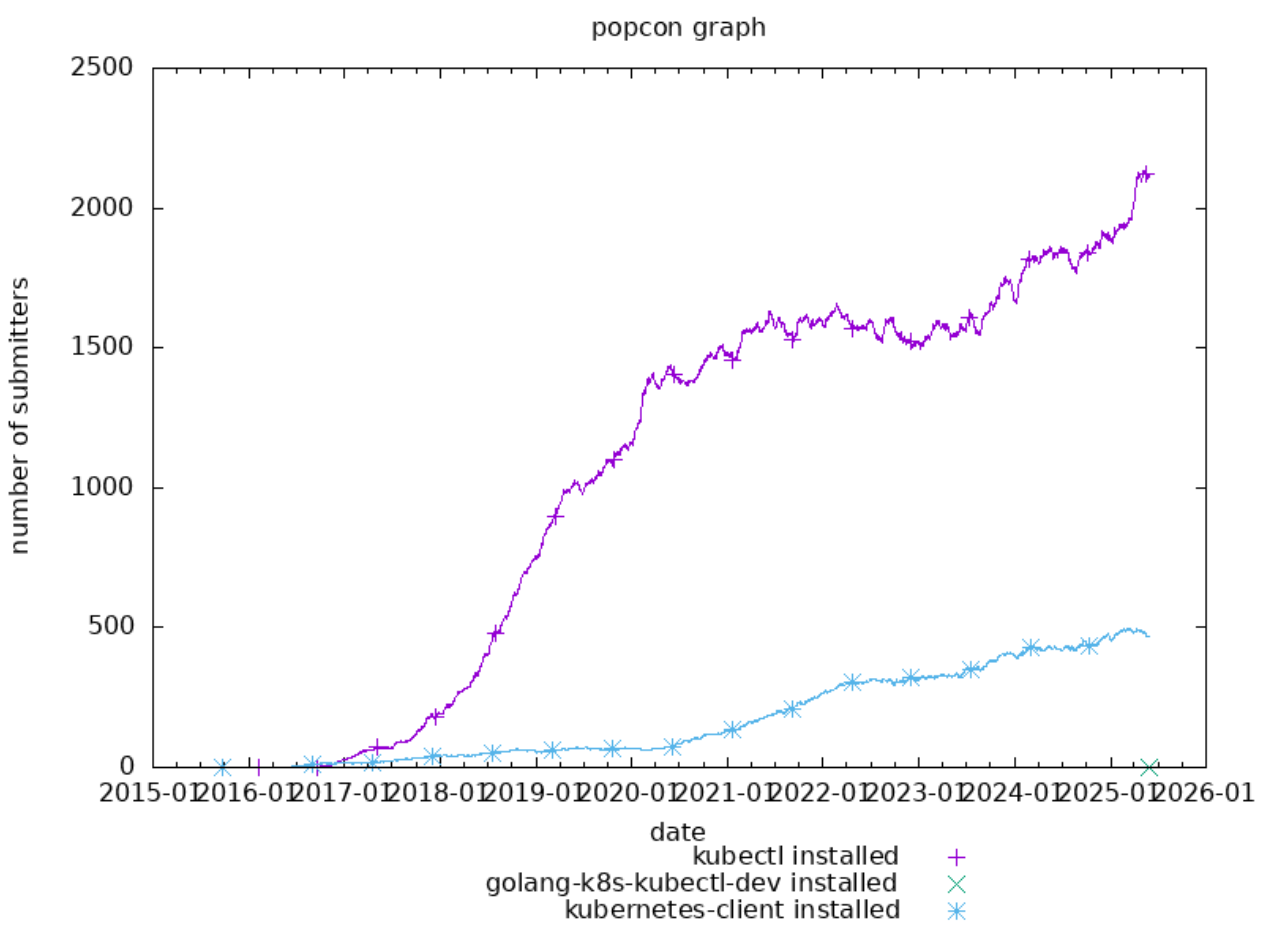
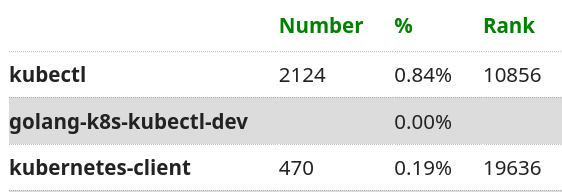
Popcon: Measuring Adoption To measure real-world usage, we rely on data from Debian s popularity contest (popcon), which gives insight into how many users have each binary installed. popcon-graph popcon-table Here s what the data tells us:
  • kubectl (new binary): Already installed on 2,124 systems.
  • golang-k8s-kubectl-dev: This is the Go development package (a library), useful for other packages and developers who want to interact with Kubernetes programmatically.
  • kubernetes-client: The legacy package that kubectl is replacing. We expect this number to decrease in future releases as more systems transition to the new package.
Although the popcon data shows activity for kubectl before the official Debian upload date, it s important to note that those numbers represent users who had it installed from upstream source-lists, not from the Debian repositories. This distinction underscores a demand that existed even before the package was available in Debian proper, and it validates the importance of bringing it into the archive.
Also worth mentioning: this number is not the real total number of installations, since users can choose not to participate in the popularity contest. So the actual adoption is likely higher than what popcon reflects.

Community and Documentation The team also maintains a dedicated wiki page which documents:
  • Maintained tools and packages
  • Contribution guidelines
  • Our roadmap for the upcoming Debian releases
https://debian-kubernetes.org

Looking Ahead to Debian 13 (Trixie) The next stable release of Debian will ship with kubectl version 1.32.3, built from a clean, de-vendorized source. This version includes nearly all the latest upstream features, and will be the first time in years that Debian users can rely on an up-to-date, policy-compliant kubectl directly from the archive. By comparing with upstream, our Debian package even delivers more out of the box, including shell completions, which the upstream still requires users to generate manually. In 2025, the Debian Kubernetes team will continue expanding our packaging efforts for the Kubernetes ecosystem. Our roadmap includes:
  • kubelet: The primary node agent that runs on each node. This will enable Debian users to create fully functional Kubernetes nodes without relying on external packages.
  • kubeadm: A tool for creating Kubernetes clusters. With kubeadm in Debian, users will then be able to bootstrap minimum viable clusters directly from the official repositories.
  • helm: The package manager for Kubernetes that helps manage applications through Kubernetes YAML files defined as charts.
  • kompose: A conversion tool that helps users familiar with docker-compose move to Kubernetes by translating Docker Compose files into Kubernetes resources.

Final Thoughts This journey was only possible thanks to the amazing support of the debian-devel-br community and the collective effort of contributors who stepped up to package missing dependencies, fix bugs, and test new versions. Special thanks to:
  • Carlos Henrique Melara (@charles)
  • Guilherme Puida (@puida)
  • Jo o Pedro Nobrega (@jnpf)
  • Lucas Kanashiro (@kanashiro)
  • Matheus Polkorny (@polkorny)
  • Samuel Henrique (@samueloph)
  • Sergio Cipriano (@cipriano)
  • Sergio Durigan Junior (@sergiodj)
I look forward to continuing this work, bringing more Kubernetes tools into Debian and improving the developer experience for everyone.

27 May 2025

Russell Coker: Leaf ZE1

I ve just got a second hand Nissan LEAF. It s not nearly as luxurious as the Genesis EV that I test drove [1]. It s also just over 5 years old so it s not as slick as the MG4 I test drove [2]. But the going rate for a LEAF of that age is $17,000 vs $35,000 or more for a new MG4 or $130,000+ for a Genesis. At this time the LEAF is the only EV in Australia that s available on the second hand market in quantity. Apparently the cheapest new EV in Australia is a Great Wall one which is $32,000 and which had a wait list last time I checked, so $17,000 is a decent price if you want an electric car and aren t interested in paying the price of a new car. Starting the Car One thing I don t like about most recent cars (petrol as well as electric) is that they needlessly break traditions of car design. Inserting a key and turning it clockwise to start a car is a long standing tradition that shouldn t be broken without a good reason. With the use of traditional keys you know that when a car has the key removed it can t be operated, there s no situation of the person with the key walking away and leaving the car driveable and there s no possibility of the owner driving somewhere without the key and then being unable to start it. To start a LEAF you have to have the key fob device in range, hold down the brake pedal, and then press the power button. To turn on accessories you do the same but without holding down the brake pedal. They also have patterns of pushes, push twice to turn it on, push three times to turn it off. This is all a lot easier with a key where you can just rotate it as many clicks as needed. The change of car design for the key means that no physical contact is needed to unlock the car. If someone stands by a car fiddling with the door lock it will get noticed which deters certain types of crime. If a potential thief can sit in a nearby car to try attack methods and only walk to the target vehicle once it s unlocked it makes the crime a lot easier. Even if the electronic key is as secure as a physical key allowing attempts to unlock remotely weakens security. Reports on forums suggest that the electronic key is vulnerable to replay attacks. I guess I just have to hope that as car thieves typically get less than 10% of the value of a car it s just not worth their effort to steal a $17,000 car. Unlocking doors remotely is a common feature that s been around for a while but starting a car without a key being physically inserted is a new thing. Other Features The headlights turn on automatically when the car thinks that the level of ambient light warrants it. There is an option to override this to turn on lights but no option to force the lights to be off. So if you have your car in the on state while parked the headlights will be on even if you are parked and listening to the radio. The LEAF has a bunch of luxury features which seem a bit ridiculous like seat warmers. It also has a heated steering wheel which has turned out to be a good option for me as I have problems with my hands getting cold. According to the My Nissan LEAF Forum the seat warmer uses a maximum of 50W per seat while the car heater uses a minimum of 250W [3]. So if there are one or two people in the car then significantly less power is used by just heating the seats and also keeping the car air cool reduces window fog. The Bluetooth audio support works well. I ve done hands free calls and used it for playing music from my phone. This is the first car I ve owned with Bluetooth support. It also has line-in which might have had some use in 2019 but is becoming increasingly useless as phones with Bluetooth become more popular. It has support for two devices connecting via Bluetooth at the same time which could be handy if you wanted to watch movies on a laptop or tablet while waiting for someone. The LEAF has some of the newer safety features, it tracks lane markers and notifies the driver via beeps and vibration if they stray from their lane. It also tries to read speed limit signs and display the last observed speed limit on the dash display. It also has a skid alert which in my experience goes off under hard acceleration when it s not skidding but doesn t go off if you lose grip when cornering. The features for detecting changing lanes when close to other cars and for emergency braking when another car is partly in the lane (even if moving out of the lane) don t seem well tuned for Australian driving, the common trend on Australian roads is lawful-evil to use DND terminology. Range My most recent driving was just over 2 hours driving with a distance of a bit over 100Km which took the battery from 62% to 14%. So it looks like I can drive a bit over 200Km at an average speed of 50Km/h. I have been unable to find out the battery size for my car, my model will have either a 40KWh or 62KWh battery. Google results say it should be printed on the B pillar (it s not) and that it can be deduced from the VIN (it can t). I m guessing that my car is the cheaper option which is supposed to do 240Km when new which means that a bit over 200Km at an average speed of 50Km/h when 6yo is about what s expected. If it has the larger battery designed to do 340Km then doing 200Km in real use would be rather disappointing. Assuming the battery is 40KWh that means it s 5Km/KWh or 10KW average for the duration. That means that the 250W or so used by the car heater should only make a about 2% difference to range which is something that a human won t usually notice. If I was to drive to another state I d definitely avoid using the heater or airconditioner as an extra 4km could really matter when trying to find a place to charge when you aren t familiar with the area. It s also widely reported that the LEAF is less efficient at highway speeds which is an extra difficulty for that. It seems that the LEAF just isn t designed for interstate driving in Australia, it would be fine for driving between provinces of the Netherlands as it s difficult to drive for 200km without leaving that country. Driving 700km to another city in a car with 200km range would mean charging 3 times along the way, that s 2 hours of charging time when using fast chargers. This isn t a problem at all as the average household in Australia has 1.8 cars and the battery electric vehicles only comprise 6.3% of the market. So if a household had a LEAF and a Prius they could just use the Prius for interstate driving. A recent Prius could drive from Melbourne to Canberra or Adelaide without refuelling on the way. If I was driving to another state a couple of times a year I could rent an old fashioned car to do that and still be saving money when compared to buying petrol all the time. Running Cost Currently I m paying about $0.28 per KWh for electricity, it s reported that the efficiency of charging a LEAF is as low as 83% with the best efficiency when fast charging. I don t own the fast charge hardware and don t plan to install it as that would require getting a replacement of the connection to my home from the street, a new switchboard, and other expenses. So I expect I ll be getting 83% efficiency when charging which means 48KWh for 200KM or 96KWH for the equivalent of a $110 tank of petrol. At $0.28/KWh it will cost $26 for the same amount of driving as $110 of petrol. I also anticipate saving money on service as there s no need for engine oil changes and all the other maintenance of a petrol engine and regenerative braking will reduce the incidence of brake pad replacement. I expect to save over $1100 per annum on using electricity instead of petrol even if I pay the full rate. But if I charge my car in the middle of the day when there is over supply and I don t get paid for feeding electricity from my solar panels into the grid (as is common nowadays) it could be almost free to charge the car and I could save about $1500 on fuel. Comfort Electric cars are much quieter than cars with petrol or Diesel engines which is a major luxury feature. This car is also significantly newer than any other car I ve driven much so it has features like Bluetooth audio which weren t in other cars I ve driven. When doing 100Km/h I can hear a lot of noise from the airflow, part of that would be due to the LEAF not having the extreme streamlining features that are associated with Teslas (such as retracting door handles) and part of that would be due to the car being older and the door seals not being as good as they were when new. It s still a very quiet car with a very smooth ride. It would be nice if they used the quality of seals and soundproofing that VW uses in the Passat but I guess the car would be heavier and have a shorter range if they did that. This car has less space for the driver than any other car I ve driven (with the possible exception of a 1989 Ford Laser AKA Mazda 323). The front seats have less space than the Prius. Also the batteries seem to be under the front seats so there s a bulge in the floor going slightly in front of the front seats when they are moved back which gives less space for the front passenger to move their legs and less space for the driver when sitting in a parked car. There are a selection of electric cars from MG, BYD, and Great Wall that have more space in the front seats, if those cars were on the second hand market I might have made a different choice but a second hand LEAF is the only option for a cheap electric car in Australia now. The heated steering wheel and heated seats took a bit of getting used to but I have come to appreciate the steering wheel and the heated seats are a good way of extending the range of the car. Misc Notes The LEAF is a fun car to drive and being quiet is a luxury feature, it s no different to other EVs in this regard. It isn t nearly as fast as a Tesla, but is faster than most cars actually drive on the road. When I was looking into buying a LEAF from one of the car sales sites I was looking at models less than 5 years old. But the ZR1 series went from 2017 to 2023 so there s probably not much difference between a 2019 model and a 2021 model but there is a significant price difference. I didn t deliberately choose a 2019 car, it was what a relative was selling at a time when I needed a new car. But knowing what I know now I d probably look at that age of LEAF if choosing from the car sales sites. Problems When I turn the car off the side mirrors fold in but when I turn it on they usually don t automatically unfold if I have anything connected to the cigarette lighter power port. This is a well known problem and documented on forums. This is something that Nissan really should have tested before release because phone chargers that connect to the car cigarette lighter port have been common for at least 6 years before my car was manufactured and at least 4 years before the ZE1 model was released. The built in USB port doesn t supply enough power to match the power use of a Galaxy Note 9 running Google maps and playing music through Bluetooth. On it s own this isn t a big deal but combined with the mirror issue of using a charger in the cigarette lighter port it s a problem. The cover over the charging ports doesn t seem to lock easily enough, I had it come open when doing 100Km/h on a freeway. This wasn t a big deal but as the cover opens in a suicide-door manner at a higher speed it could have broken off. The word is that LEAF service in Australia is not done well. Why do you need regular service of an electric car anyway? For petrol and Diesel cars it s engine oil replacement that makes it necessary to have regular service. Surely you can just drive it until either the brakes squeak or the tires seem worn. I have been having problems charging, sometimes it will charge from ~20% to 100% in under 24 hours, sometimes in 14+ hours it only gets to 30%. Conclusion This is a good car and the going price on them is low. I generally recommend them as long as you aren t really big and aren t too worried about the poor security. It s a fun car to drive even with a few annoying things like the mirrors not automatically extending on start. The older ones like this are cheap enough that they should be able to cover the entire purchase cost in 10 years by the savings from not buying petrol even if you don t drive a lot. With a petrol car I use about 13 tanks of petrol a year so my driving is about half the average for Australia. Some people could cover the purchase price of a second hand leaf in under 5 years.

26 May 2025

Otto Kek l inen: Creating Debian packages from upstream Git

Featured image of post Creating Debian packages from upstream GitIn this post, I demonstrate the optimal workflow for creating new Debian packages in 2025, preserving the upstream git history. The motivation for this is to lower the barrier for sharing improvements to and from upstream, and to improve software provenance and supply-chain security by making it easy to inspect every change at any level using standard git tooling. Key elements of this workflow include: To make the instructions so concrete that anyone can repeat all the steps themselves on a real package, I demonstrate the steps by packaging the command-line tool Entr. It is written in C, has very few dependencies, and its final Debian source package structure is simple, yet exemplifies all the important parts that go into a complete Debian package:
  1. Creating a new packaging repository and publishing it under your personal namespace on salsa.debian.org.
  2. Using dh_make to create the initial Debian packaging.
  3. Posting the first draft of the Debian packaging as a Merge Request (MR) and using Salsa CI to verify Debian packaging quality.
  4. Running local builds efficiently and iterating on the packaging process.

Create new Debian packaging repository from the existing upstream project git repository First, create a new empty directory, then clone the upstream Git repository inside it:
shell
mkdir debian-entr
cd debian-entr
git clone --origin upstreamvcs --branch master \
 --single-branch https://github.com/eradman/entr.git
Using a clean directory makes it easier to inspect the build artifacts of a Debian package, which will be output in the parent directory of the Debian source directory. The extra parameters given to git clone lay the foundation for the Debian packaging git repository structure where the upstream git remote name is upstreamvcs. Only the upstream main branch is tracked to avoid cluttering git history with upstream development branches that are irrelevant for packaging in Debian. Next, enter the git repository directory and list the git tags. Pick the latest upstream release tag as the commit to start the branch upstream/latest. This latest refers to the upstream release, not the upstream development branch. Immediately after, branch off the debian/latest branch, which will have the actual Debian packaging files in the debian/ subdirectory.
shell
cd entr
git tag # shows the latest upstream release tag was '5.6'
git checkout -b upstream/latest 5.6
git checkout -b debian/latest
%% init:   'gitGraph':   'mainBranchName': 'master'      %%
gitGraph:
checkout master
commit id: "Upstream 5.6 release" tag: "5.6"
branch upstream/latest
checkout upstream/latest
commit id: "New upstream version 5.6" tag: "upstream/5.6"
branch debian/latest
checkout debian/latest
commit id: "Initial Debian packaging"
commit id: "Additional change 1"
commit id: "Additional change 2"
commit id: "Additional change 3"
At this point, the repository is structured according to DEP-14 conventions, ensuring a clear separation between upstream and Debian packaging changes, but there are no Debian changes yet. Next, add the Salsa repository as a new remote which called origin, the same as the default remote name in git.
shell
git remote add origin git@salsa.debian.org:otto/entr-demo.git
git push --set-upstream origin debian/latest
This is an important preparation step to later be able to create a Merge Request on Salsa that targets the debian/latest branch, which does not yet have any debian/ directory.

Launch a Debian Sid (unstable) container to run builds in To ensure that all packaging tools are of the latest versions, run everything inside a fresh Sid container. This has two benefits: you are guaranteed to have the most up-to-date toolchain, and your host system stays clean without getting polluted by various extra packages. Additionally, this approach works even if your host system is not Debian/Ubuntu.
shell
cd ..
podman run --interactive --tty --rm --shm-size=1G --cap-add SYS_PTRACE \
 --env='DEB*' --volume=$PWD:/tmp/test --workdir=/tmp/test debian:sid bash
Note that the container should be started from the parent directory of the git repository, not inside it. The --volume parameter will loop-mount the current directory inside the container. Thus all files created and modified are on the host system, and will persist after the container shuts down. Once inside the container, install the basic dependencies:
shell
apt update -q && apt install -q --yes git-buildpackage dpkg-dev dh-make

Automate creating the debian/ files with dh-make To create the files needed for the actual Debian packaging, use dh_make:
shell
# dh_make --packagename entr_5.6 --single --createorig
Maintainer Name : Otto Kek l inen
Email-Address : otto@debian.org
Date : Sat, 15 Feb 2025 01:17:51 +0000
Package Name : entr
Version : 5.6
License : blank
Package Type : single
Are the details correct? [Y/n/q]

Done. Please edit the files in the debian/ subdirectory now.
Due to how dh_make works, the package name and version need to be written as a single underscore separated string. In this case, you should choose --single to specify that the package type is a single binary package. Other options would be --library for library packages (see libgda5 sources as an example) or --indep (see dns-root-data sources as an example). The --createorig will create a mock upstream release tarball (entr_5.6.orig.tar.xz) from the current release directory, which is necessary due to historical reasons and how dh_make worked before git repositories became common and Debian source packages were based off upstream release tarballs (e.g. *.tar.gz). At this stage, a debian/ directory has been created with template files, and you can start modifying the files and iterating towards actual working packaging.
shell
git add debian/
git commit -a -m "Initial Debian packaging"

Review the files The full list of files after the above steps with dh_make would be:
 -- entr
   -- LICENSE
   -- Makefile.bsd
   -- Makefile.linux
   -- Makefile.linux-compat
   -- Makefile.macos
   -- NEWS
   -- README.md
   -- configure
   -- data.h
   -- debian
     -- README.Debian
     -- README.source
     -- changelog
     -- control
     -- copyright
     -- gbp.conf
     -- entr-docs.docs
     -- entr.cron.d.ex
     -- entr.doc-base.ex
     -- manpage.1.ex
     -- manpage.md.ex
     -- manpage.sgml.ex
     -- manpage.xml.ex
     -- postinst.ex
     -- postrm.ex
     -- preinst.ex
     -- prerm.ex
     -- rules
     -- salsa-ci.yml.ex
     -- source
       -- format
     -- upstream
       -- metadata.ex
     -- watch.ex
   -- entr.1
   -- entr.c
   -- missing
     -- compat.h
     -- kqueue_inotify.c
     -- strlcpy.c
     -- sys
     -- event.h
   -- status.c
   -- status.h
   -- system_test.sh
 -- entr_5.6.orig.tar.xz
You can browse these files in the demo repository. The mandatory files in the debian/ directory are:
  • changelog,
  • control,
  • copyright,
  • and rules.
All the other files have been created for convenience so the packager has template files to work from. The files with the suffix .ex are example files that won t have any effect until their content is adjusted and the suffix removed. For detailed explanations of the purpose of each file in the debian/ subdirectory, see the following resources:
  • The Debian Policy Manual: Describes the structure of the operating system, the package archive and requirements for packages to be included in the Debian archive.
  • The Developer s Reference: A collection of best practices and process descriptions Debian packagers are expected to follow while interacting with one another.
  • Debhelper man pages: Detailed information of how the Debian package build system works, and how the contents of the various files in debian/ affect the end result.
As Entr, the package used in this example, is a real package that already exists in the Debian archive, you may want to browse the actual Debian packaging source at https://salsa.debian.org/debian/entr/-/tree/debian/latest/debian for reference. Most of these files have standardized formatting conventions to make collaboration easier. To automatically format the files following the most popular conventions, simply run wrap-and-sort -vast or debputy reformat --style=black.

Identify build dependencies The most common reason for builds to fail is missing dependencies. The easiest way to identify which Debian package ships the required dependency is using apt-file. If, for example, a build fails complaining that pcre2posix.h cannot be found or that libcre2-posix.so is missing, you can use these commands:
shell
$ apt install -q --yes apt-file && apt-file update
$ apt-file search pcre2posix.h
libpcre2-dev: /usr/include/pcre2posix.h
$ apt-file search libpcre2-posix.so
libpcre2-dev: /usr/lib/x86_64-linux-gnu/libpcre2-posix.so
libpcre2-posix3: /usr/lib/x86_64-linux-gnu/libpcre2-posix.so.3
libpcre2-posix3: /usr/lib/x86_64-linux-gnu/libpcre2-posix.so.3.0.6
The output above implies that the debian/control should be extended to define a Build-Depends: libpcre2-dev relationship. There is also dpkg-depcheck that uses strace to trace the files the build process tries to access, and lists what Debian packages those files belong to. Example usage:
shell
dpkg-depcheck -b debian/rules build

Build the Debian sources to generate the .deb package After the first pass of refining the contents of the files in debian/, test the build by running dpkg-buildpackage inside the container:
shell
dpkg-buildpackage -uc -us -b
The options -uc -us will skip signing the resulting Debian source package and other build artifacts. The -b option will skip creating a source package and only build the (binary) *.deb packages. The output is very verbose and gives a large amount of context about what is happening during the build to make debugging build failures easier. In the build log of entr you will see for example the line dh binary --buildsystem=makefile. This and other dh commands can also be run manually if there is a need to quickly repeat only a part of the build while debugging build failures. To see what files were generated or modified by the build simply run git status --ignored:
shell
$ git status --ignored
On branch debian/latest

Untracked files:
 (use "git add <file>..." to include in what will be committed)
 debian/debhelper-build-stamp
 debian/entr.debhelper.log
 debian/entr.substvars
 debian/files

Ignored files:
 (use "git add -f <file>..." to include in what will be committed)
 Makefile
 compat.c
 compat.o
 debian/.debhelper/
 debian/entr/
 entr
 entr.o
 status.o
Re-running dpkg-buildpackage will include running the command dh clean, which assuming it is configured correctly in the debian/rules file will reset the source directory to the original pristine state. The same can of course also be done with regular git commands git reset --hard; git clean -fdx. To avoid accidentally committing unnecessary build artifacts in git, a debian/.gitignore can be useful and it would typically include all four files listed as untracked above. After a successful build you would have the following files:
shell
 -- entr
   -- LICENSE
   -- Makefile -> Makefile.linux
   -- Makefile.bsd
   -- Makefile.linux
   -- Makefile.linux-compat
   -- Makefile.macos
   -- NEWS
   -- README.md
   -- compat.c
   -- compat.o
   -- configure
   -- data.h
   -- debian
     -- README.source.md
     -- changelog
     -- control
     -- copyright
     -- debhelper-build-stamp
     -- docs
     -- entr
       -- DEBIAN
         -- control
         -- md5sums
       -- usr
       -- bin
         -- entr
       -- share
       -- doc
         -- entr
         -- NEWS.gz
         -- README.md
         -- changelog.Debian.gz
         -- copyright
       -- man
       -- man1
       -- entr.1.gz
     -- entr.debhelper.log
     -- entr.substvars
     -- files
     -- gbp.conf
     -- patches
       -- PR149-expand-aliases-in-system-test-script.patch
       -- series
       -- system-test-skip-no-tty.patch
       -- system-test-with-system-binary.patch
     -- rules
     -- salsa-ci.yml
     -- source
       -- format
     -- tests
       -- control
     -- upstream
       -- metadata
       -- signing-key.asc
     -- watch
   -- entr
   -- entr.1
   -- entr.c
   -- entr.o
   -- missing
     -- compat.h
     -- kqueue_inotify.c
     -- strlcpy.c
     -- sys
     -- event.h
   -- status.c
   -- status.h
   -- status.o
   -- system_test.sh
 -- entr-dbgsym_5.6-1_amd64.deb
 -- entr_5.6-1.debian.tar.xz
 -- entr_5.6-1.dsc
 -- entr_5.6-1_amd64.buildinfo
 -- entr_5.6-1_amd64.changes
 -- entr_5.6-1_amd64.deb
 -- entr_5.6.orig.tar.xz
The contents of debian/entr are essentially what goes into the resulting entr_5.6-1_amd64.deb package. Familiarizing yourself with the majority of the files in the original upstream source as well as all the resulting build artifacts is time consuming, but it is a necessary investment to get high-quality Debian packages. There are also tools such as Debcraft that automate generating the build artifacts in separate output directories for each build, thus making it easy to compare the changes to correlate what change in the Debian packaging led to what change in the resulting build artifacts.

Re-run the initial import with git-buildpackage When upstreams publish releases as tarballs, they should also be imported for optimal software supply-chain security, in particular if upstream also publishes cryptographic signatures that can be used to verify the authenticity of the tarballs. To achieve this, the files debian/watch, debian/upstream/signing-key.asc, and debian/gbp.conf need to be present with the correct options. In the gbp.conf file, ensure you have the correct options based on:
  1. Does upstream release tarballs? If so, enforce pristine-tar = True.
  2. Does upstream sign the tarballs? If so, configure explicit signature checking with upstream-signatures = on.
  3. Does upstream have a git repository, and does it have release git tags? If so, configure the release git tag format, e.g. upstream-vcs-tag = %(version%~%.)s.
To validate that the above files are working correctly, run gbp import-orig with the current version explicitly defined:
shell
$ gbp import-orig --uscan --upstream-version 5.6
gbp:info: Launching uscan...
gpgv: Signature made 7. Aug 2024 07.43.27 PDT
gpgv: using RSA key 519151D83E83D40A232B4D615C418B8631BC7C26
gpgv: Good signature from "Eric Radman <ericshane@eradman.com>"
gbp:info: Using uscan downloaded tarball ../entr_5.6.orig.tar.gz
gbp:info: Importing '../entr_5.6.orig.tar.gz' to branch 'upstream/latest'...
gbp:info: Source package is entr
gbp:info: Upstream version is 5.6
gbp:info: Replacing upstream source on 'debian/latest'
gbp:info: Running Postimport hook
gbp:info: Successfully imported version 5.6 of ../entr_5.6.orig.tar.gz
As the original packaging was done based on the upstream release git tag, the above command will fetch the tarball release, create the pristine-tar branch, and store the tarball delta on it. This command will also attempt to create the tag upstream/5.6 on the upstream/latest branch.

Import new upstream versions in the future Forking the upstream git repository, creating the initial packaging, and creating the DEP-14 branch structure are all one-off work needed only when creating the initial packaging. Going forward, to import new upstream releases, one would simply run git fetch upstreamvcs; gbp import-orig --uscan, which fetches the upstream git tags, checks for new upstream tarballs, and automatically downloads, verifies, and imports the new version. See the galera-4-demo example in the Debian source packages in git explained post as a demo you can try running yourself and examine in detail. You can also try running gbp import-orig --uscan without specifying a version. It would fetch it, as it will notice there is now Entr version 5.7 available, and import it.

Build using git-buildpackage From this stage onwards you should build the package using gbp buildpackage, which will do a more comprehensive build.
shell
gbp buildpackage -uc -us
The git-buildpackage build also includes running Lintian to find potential Debian policy violations in the sources or in the resulting .deb binary packages. Many Debian Developers run lintian -EviIL +pedantic after every build to check that there are no new nags, and to validate that changes intended to previous Lintian nags were correct.

Open a Merge Request on Salsa for Debian packaging review Getting everything perfectly right takes a lot of effort, and may require reaching out to an experienced Debian Developers for review and guidance. Thus, you should aim to publish your initial packaging work on Salsa, Debian s GitLab instance, for review and feedback as early as possible. For somebody to be able to easily see what you have done, you should rename your debian/latest branch to another name, for example next/debian/latest, and open a Merge Request that targets the debian/latest branch on your Salsa fork, which still has only the unmodified upstream files. If you have followed the workflow in this post so far, you can simply run:
  1. git checkout -b next/debian/latest
  2. git push --set-upstream origin next/debian/latest
  3. Open in a browser the URL visible in the git remote response
  4. Write the Merge Request description in case the default text from your commit is not enough
  5. Mark the MR as Draft using the checkbox
  6. Publish the MR and request feedback
Once a Merge Request exists, discussion regarding what additional changes are needed can be conducted as MR comments. With an MR, you can easily iterate on the contents of next/debian/latest, rebase, force push, and request re-review as many times as you want. While at it, make sure the Settings > CI/CD page has under CI/CD configuration file the value debian/salsa-ci.yml so that the CI can run and give you immediate automated feedback. For an example of an initial packaging Merge Request, see https://salsa.debian.org/otto/entr-demo/-/merge_requests/1.

Open a Merge Request / Pull Request to fix upstream code Due to the high quality requirements in Debian, it is fairly common that while doing the initial Debian packaging of an open source project, issues are found that stem from the upstream source code. While it is possible to carry extra patches in Debian, it is not good practice to deviate too much from upstream code with custom Debian patches. Instead, the Debian packager should try to get the fixes applied directly upstream. Using git-buildpackage patch queues is the most convenient way to make modifications to the upstream source code so that they automatically convert into Debian patches (stored at debian/patches), and can also easily be submitted upstream as any regular git commit (and rebased and resubmitted many times over). First, decide if you want to work out of the upstream development branch and later cherry-pick to the Debian packaging branch, or work out of the Debian packaging branch and cherry-pick to an upstream branch. The example below starts from the upstream development branch and then cherry-picks the commit into the git-buildpackage patch queue:
shell
git checkout -b bugfix-branch master
nano entr.c
make
./entr # verify change works as expected
git commit -a -m "Commit title" -m "Commit body"
git push # submit upstream
gbp pq import --force --time-machine=10
git cherry-pick <commit id>
git commit --amend # extend commit message with DEP-3 metadata
gbp buildpackage -uc -us -b
./entr # verify change works as expected
gbp pq export --drop --commit
git commit --amend # Write commit message along lines "Add patch to .."
The example below starts by making the fix on a git-buildpackage patch queue branch, and then cherry-picking it onto the upstream development branch:
shell
gbp pq import --force --time-machine=10
nano entr.c
git commit -a -m "Commit title" -m "Commit body"
gbp buildpackage -uc -us -b
./entr # verify change works as expected
gbp pq export --drop --commit
git commit --amend # Write commit message along lines "Add patch to .."
git checkout -b bugfix-branch master
git cherry-pick <commit id>
git commit --amend # prepare commit message for upstream submission
git push # submit upstream
The key git-buildpackage commands to enter and exit the patch-queue mode are:
shell
gbp pq import --force --time-machine=10
gbp pq export --drop --commit
%% init:   'gitGraph':   'mainBranchName': 'debian/latest'      %%
gitGraph
checkout debian/latest
commit id: "Initial packaging"
branch patch-queue/debian/latest
checkout patch-queue/debian/latest
commit id: "Delete debian/patches/..."
commit id: "Patch 1 title"
commit id: "Patch 2 title"
commit id: "Patch 3 title"
These can be run at any time, regardless if any debian/patches existed prior, or if existing patches applied cleanly or not, or if there were old patch queue branches around. Note that the extra -b in gbp buildpackage -uc -us -b instructs to build only binary packages, avoiding any nags from dpkg-source that there are modifications in the upstream sources while building in the patches-applied mode.

Programming-language specific dh-make alternatives As each programming language has its specific way of building the source code, and many other conventions regarding the file layout and more, Debian has multiple custom tools to create new Debian source packages for specific programming languages. Notably, Python does not have its own tool, but there is an dh_make --python option for Python support directly in dh_make itself. The list is not complete and many more tools exist. For some languages, there are even competing options, such as for Go there is in addition to dh-make-golang also Gophian. When learning Debian packaging, there is no need to learn these tools upfront. Being aware that they exist is enough, and one can learn them only if and when one starts to package a project in a new programming language.

The difference between source git repository vs source packages vs binary packages As seen in earlier example, running gbp buildpackage on the Entr packaging repository above will result in several files:
entr_5.6-1_amd64.changes
entr_5.6-1_amd64.deb
entr_5.6-1.debian.tar.xz
entr_5.6-1.dsc
entr_5.6.orig.tar.gz
entr_5.6.orig.tar.gz.asc
The entr_5.6-1_amd64.deb is the binary package, which can be installed on a Debian/Ubuntu system. The rest of the files constitute the source package. To do a source-only build, run gbp buildpackage -S and note the files produced:
entr_5.6-1_source.changes
entr_5.6-1.debian.tar.xz
entr_5.6-1.dsc
entr_5.6.orig.tar.gz
entr_5.6.orig.tar.gz.asc
The source package files can be used to build the binary .deb for amd64, or any architecture that the package supports. It is important to grasp that the Debian source package is the preferred form to be able to build the binary packages on various Debian build systems, and the Debian source package is not the same thing as the Debian packaging git repository contents.
flowchart LR
git[Git repository<br>branch debian/latest] --> gbp buildpackage -S  src[Source Package<br>.dsc + .tar.xz]
src --> dpkg-buildpackage  bin[Binary Packages<br>.deb]
If the package is large and complex, the build could result in multiple binary packages. One set of package definition files in debian/ will however only ever result in a single source package.

Option to repackage source packages with Files-Excluded lists in the debian/copyright file Some upstream projects may include binary files in their release, or other undesirable content that needs to be omitted from the source package in Debian. The easiest way to filter them out is by adding to the debian/copyright file a Files-Excluded field listing the undesired files. The debian/copyright file is read by uscan, which will repackage the upstream sources on-the-fly when importing new upstream releases. For a real-life example, see the debian/copyright files in the Godot package that lists:
debian
Files-Excluded: platform/android/java/gradle/wrapper/gradle-wrapper.jar
The resulting repackaged upstream source tarball, as well as the upstream version component, will have an extra +ds to signify that it is not the true original upstream source but has been modified by Debian:
godot_4.3+ds.orig.tar.xz
godot_4.3+ds-1_amd64.deb

Creating one Debian source package from multiple upstream source packages also possible In some rare cases the upstream project may be split across multiple git repositories or the upstream release may consist of multiple components each in their own separate tarball. Usually these are very large projects that get some benefits from releasing components separately. If in Debian these are deemed to go into a single source package, it is technically possible using the component system in git-buildpackage and uscan. For an example see the gbp.conf and watch files in the node-cacache package. Using this type of structure should be a last resort, as it creates complexity and inter-dependencies that are bound to cause issues later on. It is usually better to work with upstream and champion universal best practices with clear releases and version schemes.

When not to start the Debian packaging repository as a fork of the upstream one Not all upstreams use Git for version control. It is by far the most popular, but there are still some that use e.g. Subversion or Mercurial. Who knows maybe in the future some new version control systems will start to compete with Git. There are also projects that use Git in massive monorepos and with complex submodule setups that invalidate the basic assumptions required to map an upstream Git repository into a Debian packaging repository. In those cases one can t use a debian/latest branch on a clone of the upstream git repository as the starting point for the Debian packaging, but one must revert the traditional way of starting from an upstream release tarball with gbp import-orig package-1.0.tar.gz.

Conclusion Created in August 1993, Debian is one of the oldest Linux distributions. In the 32 years since inception, the .deb packaging format and the tooling to work with it have evolved several generations. In the past 10 years, more and more Debian Developers have converged on certain core practices evidenced by https://trends.debian.net/, but there is still a lot of variance in workflows even for identical tasks. Hopefully, you find this post useful in giving practical guidance on how exactly to do the most common things when packaging software for Debian. Happy packaging!

25 May 2025

Otto Kek l inen: New Debian package creation from upstream git repository

Featured image of post New Debian package creation from upstream git repositoryIn this post, I demonstrate the optimal workflow for creating new Debian packages in 2025, preserving the upstream git history. The motivation for this is to lower the barrier for sharing improvements to and from upstream, and to improve software provenance and supply-chain security by making it easy to inspect every change at any level using standard git tooling. Key elements of this workflow include: To make the instructions so concrete that anyone can repeat all the steps themselves on a real package, I demonstrate the steps by packaging the command-line tool Entr. It is written in C, has very few dependencies, and its final Debian source package structure is simple, yet exemplifies all the important parts that go into a complete Debian package:
  1. Creating a new packaging repository and publishing it under your personal namespace on salsa.debian.org.
  2. Using dh_make to create the initial Debian packaging.
  3. Posting the first draft of the Debian packaging as a Merge Request (MR) and using Salsa CI to verify Debian packaging quality.
  4. Running local builds efficiently and iterating on the packaging process.

Create new Debian packaging repository from the existing upstream project git repository First, create a new empty directory, then clone the upstream Git repository inside it:
shell
mkdir debian-entr
cd debian-entr
git clone --origin upstreamvcs --branch master \
 --single-branch https://github.com/eradman/entr.git
Using a clean directory makes it easier to inspect the build artifacts of a Debian package, which will be output in the parent directory of the Debian source directory. The extra parameters given to git clone lay the foundation for the Debian packaging git repository structure where the upstream git remote name is upstreamvcs. Only the upstream main branch is tracked to avoid cluttering git history with upstream development branches that are irrelevant for packaging in Debian. Next, enter the git repository directory and list the git tags. Pick the latest upstream release tag as the commit to start the branch upstream/latest. This latest refers to the upstream release, not the upstream development branch. Immediately after, branch off the debian/latest branch, which will have the actual Debian packaging files in the debian/ subdirectory.
shell
cd entr
git tag # shows the latest upstream release tag was '5.6'
git checkout -b upstream/latest 5.6
git checkout -b debian/latest
%% init:   'gitGraph':   'mainBranchName': 'master'      %%
gitGraph:
checkout master
commit id: "Upstream 5.6 release" tag: "5.6"
branch upstream/latest
checkout upstream/latest
commit id: "New upstream version 5.6" tag: "upstream/5.6"
branch debian/latest
checkout debian/latest
commit id: "Initial Debian packaging"
commit id: "Additional change 1"
commit id: "Additional change 2"
commit id: "Additional change 3"
At this point, the repository is structured according to DEP-14 conventions, ensuring a clear separation between upstream and Debian packaging changes, but there are no Debian changes yet. Next, add the Salsa repository as a new remote which called origin, the same as the default remote name in git.
shell
git remote add origin git@salsa.debian.org:otto/entr-demo.git
git push --set-upstream origin debian/latest
This is an important preparation step to later be able to create a Merge Request on Salsa that targets the debian/latest branch, which does not yet have any debian/ directory.

Launch a Debian Sid (unstable) container to run builds in To ensure that all packaging tools are of the latest versions, run everything inside a fresh Sid container. This has two benefits: you are guaranteed to have the most up-to-date toolchain, and your host system stays clean without getting polluted by various extra packages. Additionally, this approach works even if your host system is not Debian/Ubuntu.
shell
cd ..
podman run --interactive --tty --rm --shm-size=1G --cap-add SYS_PTRACE \
 --env='DEB*' --volume=$PWD:/tmp/test --workdir=/tmp/test debian:sid bash
Note that the container should be started from the parent directory of the git repository, not inside it. The --volume parameter will loop-mount the current directory inside the container. Thus all files created and modified are on the host system, and will persist after the container shuts down. Once inside the container, install the basic dependencies:
shell
apt update -q && apt install -q --yes git-buildpackage dpkg-dev dh-make

Automate creating the debian/ files with dh-make To create the files needed for the actual Debian packaging, use dh_make:
shell
# dh_make --packagename entr_5.6 --single --createorig
Maintainer Name : Otto Kek l inen
Email-Address : otto@debian.org
Date : Sat, 15 Feb 2025 01:17:51 +0000
Package Name : entr
Version : 5.6
License : blank
Package Type : single
Are the details correct? [Y/n/q]

Done. Please edit the files in the debian/ subdirectory now.
Due to how dh_make works, the package name and version need to be written as a single underscore separated string. In this case, you should choose --single to specify that the package type is a single binary package. Other options would be --library for library packages (see libgda5 sources as an example) or --indep (see dns-root-data sources as an example). The --createorig will create a mock upstream release tarball (entr_5.6.orig.tar.xz) from the current release directory, which is necessary due to historical reasons and how dh_make worked before git repositories became common and Debian source packages were based off upstream release tarballs (e.g. *.tar.gz). At this stage, a debian/ directory has been created with template files, and you can start modifying the files and iterating towards actual working packaging.
shell
git add debian/
git commit -a -m "Initial Debian packaging"

Review the files The full list of files after the above steps with dh_make would be:
 -- entr
   -- LICENSE
   -- Makefile.bsd
   -- Makefile.linux
   -- Makefile.linux-compat
   -- Makefile.macos
   -- NEWS
   -- README.md
   -- configure
   -- data.h
   -- debian
     -- README.Debian
     -- README.source
     -- changelog
     -- control
     -- copyright
     -- gbp.conf
     -- entr-docs.docs
     -- entr.cron.d.ex
     -- entr.doc-base.ex
     -- manpage.1.ex
     -- manpage.md.ex
     -- manpage.sgml.ex
     -- manpage.xml.ex
     -- postinst.ex
     -- postrm.ex
     -- preinst.ex
     -- prerm.ex
     -- rules
     -- salsa-ci.yml.ex
     -- source
       -- format
     -- upstream
       -- metadata.ex
     -- watch.ex
   -- entr.1
   -- entr.c
   -- missing
     -- compat.h
     -- kqueue_inotify.c
     -- strlcpy.c
     -- sys
     -- event.h
   -- status.c
   -- status.h
   -- system_test.sh
 -- entr_5.6.orig.tar.xz
You can browse these files in the demo repository. The mandatory files in the debian/ directory are:
  • changelog,
  • control,
  • copyright,
  • and rules.
All the other files have been created for convenience so the packager has template files to work from. The files with the suffix .ex are example files that won t have any effect until their content is adjusted and the suffix removed. For detailed explanations of the purpose of each file in the debian/ subdirectory, see the following resources:
  • The Debian Policy Manual: Describes the structure of the operating system, the package archive and requirements for packages to be included in the Debian archive.
  • The Developer s Reference: A collection of best practices and process descriptions Debian packagers are expected to follow while interacting with one another.
  • Debhelper man pages: Detailed information of how the Debian package build system works, and how the contents of the various files in debian/ affect the end result.
As Entr, the package used in this example, is a real package that already exists in the Debian archive, you may want to browse the actual Debian packaging source at https://salsa.debian.org/debian/entr/-/tree/debian/latest/debian for reference. Most of these files have standardized formatting conventions to make collaboration easier. To automatically format the files following the most popular conventions, simply run wrap-and-sort -vast or debputy reformat --style=black.

Identify build dependencies The most common reason for builds to fail is missing dependencies. The easiest way to identify which Debian package ships the required dependency is using apt-file. If, for example, a build fails complaining that pcre2posix.h cannot be found or that libcre2-posix.so is missing, you can use these commands:
shell
$ apt install -q --yes apt-file && apt-file update
$ apt-file search pcre2posix.h
libpcre2-dev: /usr/include/pcre2posix.h
$ apt-file search libpcre2-posix.so
libpcre2-dev: /usr/lib/x86_64-linux-gnu/libpcre2-posix.so
libpcre2-posix3: /usr/lib/x86_64-linux-gnu/libpcre2-posix.so.3
libpcre2-posix3: /usr/lib/x86_64-linux-gnu/libpcre2-posix.so.3.0.6
The output above implies that the debian/control should be extended to define a Build-Depends: libpcre2-dev relationship. There is also dpkg-depcheck that uses strace to trace the files the build process tries to access, and lists what Debian packages those files belong to. Example usage:
shell
dpkg-depcheck -b debian/rules build

Build the Debian sources to generate the .deb package After the first pass of refining the contents of the files in debian/, test the build by running dpkg-buildpackage inside the container:
shell
dpkg-buildpackage -uc -us -b
The options -uc -us will skip signing the resulting Debian source package and other build artifacts. The -b option will skip creating a source package and only build the (binary) *.deb packages. The output is very verbose and gives a large amount of context about what is happening during the build to make debugging build failures easier. In the build log of entr you will see for example the line dh binary --buildsystem=makefile. This and other dh commands can also be run manually if there is a need to quickly repeat only a part of the build while debugging build failures. To see what files were generated or modified by the build simply run git status --ignored:
shell
$ git status --ignored
On branch debian/latest

Untracked files:
 (use "git add <file>..." to include in what will be committed)
 debian/debhelper-build-stamp
 debian/entr.debhelper.log
 debian/entr.substvars
 debian/files

Ignored files:
 (use "git add -f <file>..." to include in what will be committed)
 Makefile
 compat.c
 compat.o
 debian/.debhelper/
 debian/entr/
 entr
 entr.o
 status.o
Re-running dpkg-buildpackage will include running the command dh clean, which assuming it is configured correctly in the debian/rules file will reset the source directory to the original pristine state. The same can of course also be done with regular git commands git reset --hard; git clean -fdx. To avoid accidentally committing unnecessary build artifacts in git, a debian/.gitignore can be useful and it would typically include all four files listed as untracked above. After a successful build you would have the following files:
shell
 -- entr
   -- LICENSE
   -- Makefile -> Makefile.linux
   -- Makefile.bsd
   -- Makefile.linux
   -- Makefile.linux-compat
   -- Makefile.macos
   -- NEWS
   -- README.md
   -- compat.c
   -- compat.o
   -- configure
   -- data.h
   -- debian
     -- README.source.md
     -- changelog
     -- control
     -- copyright
     -- debhelper-build-stamp
     -- docs
     -- entr
       -- DEBIAN
         -- control
         -- md5sums
       -- usr
       -- bin
         -- entr
       -- share
       -- doc
         -- entr
         -- NEWS.gz
         -- README.md
         -- changelog.Debian.gz
         -- copyright
       -- man
       -- man1
       -- entr.1.gz
     -- entr.debhelper.log
     -- entr.substvars
     -- files
     -- gbp.conf
     -- patches
       -- PR149-expand-aliases-in-system-test-script.patch
       -- series
       -- system-test-skip-no-tty.patch
       -- system-test-with-system-binary.patch
     -- rules
     -- salsa-ci.yml
     -- source
       -- format
     -- tests
       -- control
     -- upstream
       -- metadata
       -- signing-key.asc
     -- watch
   -- entr
   -- entr.1
   -- entr.c
   -- entr.o
   -- missing
     -- compat.h
     -- kqueue_inotify.c
     -- strlcpy.c
     -- sys
     -- event.h
   -- status.c
   -- status.h
   -- status.o
   -- system_test.sh
 -- entr-dbgsym_5.6-1_amd64.deb
 -- entr_5.6-1.debian.tar.xz
 -- entr_5.6-1.dsc
 -- entr_5.6-1_amd64.buildinfo
 -- entr_5.6-1_amd64.changes
 -- entr_5.6-1_amd64.deb
 -- entr_5.6.orig.tar.xz
The contents of debian/entr are essentially what goes into the resulting entr_5.6-1_amd64.deb package. Familiarizing yourself with the majority of the files in the original upstream source as well as all the resulting build artifacts is time consuming, but it is a necessary investment to get high-quality Debian packages. There are also tools such as Debcraft that automate generating the build artifacts in separate output directories for each build, thus making it easy to compare the changes to correlate what change in the Debian packaging led to what change in the resulting build artifacts.

Re-run the initial import with git-buildpackage When upstreams publish releases as tarballs, they should also be imported for optimal software supply-chain security, in particular if upstream also publishes cryptographic signatures that can be used to verify the authenticity of the tarballs. To achieve this, the files debian/watch, debian/upstream/signing-key.asc, and debian/gbp.conf need to be present with the correct options. In the gbp.conf file, ensure you have the correct options based on:
  1. Does upstream release tarballs? If so, enforce pristine-tar = True.
  2. Does upstream sign the tarballs? If so, configure explicit signature checking with upstream-signatures = on.
  3. Does upstream have a git repository, and does it have release git tags? If so, configure the release git tag format, e.g. upstream-vcs-tag = %(version%~%.)s.
To validate that the above files are working correctly, run gbp import-orig with the current version explicitly defined:
shell
$ gbp import-orig --uscan --upstream-version 5.6
gbp:info: Launching uscan...
gpgv: Signature made 7. Aug 2024 07.43.27 PDT
gpgv: using RSA key 519151D83E83D40A232B4D615C418B8631BC7C26
gpgv: Good signature from "Eric Radman <ericshane@eradman.com>"
gbp:info: Using uscan downloaded tarball ../entr_5.6.orig.tar.gz
gbp:info: Importing '../entr_5.6.orig.tar.gz' to branch 'upstream/latest'...
gbp:info: Source package is entr
gbp:info: Upstream version is 5.6
gbp:info: Replacing upstream source on 'debian/latest'
gbp:info: Running Postimport hook
gbp:info: Successfully imported version 5.6 of ../entr_5.6.orig.tar.gz
As the original packaging was done based on the upstream release git tag, the above command will fetch the tarball release, create the pristine-tar branch, and store the tarball delta on it. This command will also attempt to create the tag upstream/5.6 on the upstream/latest branch.

Import new upstream versions in the future Forking the upstream git repository, creating the initial packaging, and creating the DEP-14 branch structure are all one-off work needed only when creating the initial packaging. Going forward, to import new upstream releases, one would simply run git fetch upstreamvcs; gbp import-orig --uscan, which fetches the upstream git tags, checks for new upstream tarballs, and automatically downloads, verifies, and imports the new version. See the galera-4-demo example in the Debian source packages in git explained post as a demo you can try running yourself and examine in detail. You can also try running gbp import-orig --uscan without specifying a version. It would fetch it, as it will notice there is now Entr version 5.7 available, and import it.

Build using git-buildpackage From this stage onwards you should build the package using gbp buildpackage, which will do a more comprehensive build.
shell
gbp buildpackage -uc -us
The git-buildpackage build also includes running Lintian to find potential Debian policy violations in the sources or in the resulting .deb binary packages. Many Debian Developers run lintian -EviIL +pedantic after every build to check that there are no new nags, and to validate that changes intended to previous Lintian nags were correct.

Open a Merge Request on Salsa for Debian packaging review Getting everything perfectly right takes a lot of effort, and may require reaching out to an experienced Debian Developers for review and guidance. Thus, you should aim to publish your initial packaging work on Salsa, Debian s GitLab instance, for review and feedback as early as possible. For somebody to be able to easily see what you have done, you should rename your debian/latest branch to another name, for example next/debian/latest, and open a Merge Request that targets the debian/latest branch on your Salsa fork, which still has only the unmodified upstream files. If you have followed the workflow in this post so far, you can simply run:
  1. git checkout -b next/debian/latest
  2. git push --set-upstream origin next/debian/latest
  3. Open in a browser the URL visible in the git remote response
  4. Write the Merge Request description in case the default text from your commit is not enough
  5. Mark the MR as Draft using the checkbox
  6. Publish the MR and request feedback
Once a Merge Request exists, discussion regarding what additional changes are needed can be conducted as MR comments. With an MR, you can easily iterate on the contents of next/debian/latest, rebase, force push, and request re-review as many times as you want. While at it, make sure the Settings > CI/CD page has under CI/CD configuration file the value debian/salsa-ci.yml so that the CI can run and give you immediate automated feedback. For an example of an initial packaging Merge Request, see https://salsa.debian.org/otto/entr-demo/-/merge_requests/1.

Open a Merge Request / Pull Request to fix upstream code Due to the high quality requirements in Debian, it is fairly common that while doing the initial Debian packaging of an open source project, issues are found that stem from the upstream source code. While it is possible to carry extra patches in Debian, it is not good practice to deviate too much from upstream code with custom Debian patches. Instead, the Debian packager should try to get the fixes applied directly upstream. Using git-buildpackage patch queues is the most convenient way to make modifications to the upstream source code so that they automatically convert into Debian patches (stored at debian/patches), and can also easily be submitted upstream as any regular git commit (and rebased and resubmitted many times over). First, decide if you want to work out of the upstream development branch and later cherry-pick to the Debian packaging branch, or work out of the Debian packaging branch and cherry-pick to an upstream branch. The example below starts from the upstream development branch and then cherry-picks the commit into the git-buildpackage patch queue:
shell
git checkout -b bugfix-branch master
nano entr.c
make
./entr # verify change works as expected
git commit -a -m "Commit title" -m "Commit body"
git push # submit upstream
gbp pq import --force --time-machine=10
git cherry-pick <commit id>
git commit --amend # extend commit message with DEP-3 metadata
gbp buildpackage -uc -us -b
./entr # verify change works as expected
gbp pq export --drop --commit
git commit --amend # Write commit message along lines "Add patch to .."
The example below starts by making the fix on a git-buildpackage patch queue branch, and then cherry-picking it onto the upstream development branch:
shell
gbp pq import --force --time-machine=10
nano entr.c
git commit -a -m "Commit title" -m "Commit body"
gbp buildpackage -uc -us -b
./entr # verify change works as expected
gbp pq export --drop --commit
git commit --amend # Write commit message along lines "Add patch to .."
git checkout -b bugfix-branch master
git cherry-pick <commit id>
git commit --amend # prepare commit message for upstream submission
git push # submit upstream
The key git-buildpackage commands to enter and exit the patch-queue mode are:
shell
gbp pq import --force --time-machine=10
gbp pq export --drop --commit
%% init:   'gitGraph':   'mainBranchName': 'debian/latest'      %%
gitGraph
checkout debian/latest
commit id: "Initial packaging"
branch patch-queue/debian/latest
checkout patch-queue/debian/latest
commit id: "Delete debian/patches/..."
commit id: "Patch 1 title"
commit id: "Patch 2 title"
commit id: "Patch 3 title"
These can be run at any time, regardless if any debian/patches existed prior, or if existing patches applied cleanly or not, or if there were old patch queue branches around. Note that the extra -b in gbp buildpackage -uc -us -b instructs to build only binary packages, avoiding any nags from dpkg-source that there are modifications in the upstream sources while building in the patches-applied mode.

Programming-language specific dh-make alternatives As each programming language has its specific way of building the source code, and many other conventions regarding the file layout and more, Debian has multiple custom tools to create new Debian source packages for specific programming languages. Notably, Python does not have its own tool, but there is an dh_make --python option for Python support directly in dh_make itself. The list is not complete and many more tools exist. For some languages, there are even competing options, such as for Go there is in addition to dh-make-golang also Gophian. When learning Debian packaging, there is no need to learn these tools upfront. Being aware that they exist is enough, and one can learn them only if and when one starts to package a project in a new programming language.

The difference between source git repository vs source packages vs binary packages As seen in earlier example, running gbp buildpackage on the Entr packaging repository above will result in several files:
entr_5.6-1_amd64.changes
entr_5.6-1_amd64.deb
entr_5.6-1.debian.tar.xz
entr_5.6-1.dsc
entr_5.6.orig.tar.gz
entr_5.6.orig.tar.gz.asc
The entr_5.6-1_amd64.deb is the binary package, which can be installed on a Debian/Ubuntu system. The rest of the files constitute the source package. To do a source-only build, run gbp buildpackage -S and note the files produced:
entr_5.6-1_source.changes
entr_5.6-1.debian.tar.xz
entr_5.6-1.dsc
entr_5.6.orig.tar.gz
entr_5.6.orig.tar.gz.asc
The source package files can be used to build the binary .deb for amd64, or any architecture that the package supports. It is important to grasp that the Debian source package is the preferred form to be able to build the binary packages on various Debian build systems, and the Debian source package is not the same thing as the Debian packaging git repository contents.
flowchart LR
git[Git repository<br>branch debian/latest] --> gbp buildpackage -S  src[Source Package<br>.dsc + .tar.xz]
src --> dpkg-buildpackage  bin[Binary Packages<br>.deb]
If the package is large and complex, the build could result in multiple binary packages. One set of package definition files in debian/ will however only ever result in a single source package.

Option to repackage source packages with Files-Excluded lists in the debian/copyright file Some upstream projects may include binary files in their release, or other undesirable content that needs to be omitted from the source package in Debian. The easiest way to filter them out is by adding to the debian/copyright file a Files-Excluded field listing the undesired files. The debian/copyright file is read by uscan, which will repackage the upstream sources on-the-fly when importing new upstream releases. For a real-life example, see the debian/copyright files in the Godot package that lists:
debian
Files-Excluded: platform/android/java/gradle/wrapper/gradle-wrapper.jar
The resulting repackaged upstream source tarball, as well as the upstream version component, will have an extra +ds to signify that it is not the true original upstream source but has been modified by Debian:
godot_4.3+ds.orig.tar.xz
godot_4.3+ds-1_amd64.deb

Creating one Debian source package from multiple upstream source packages also possible In some rare cases the upstream project may be split across multiple git repositories or the upstream release may consist of multiple components each in their own separate tarball. Usually these are very large projects that get some benefits from releasing components separately. If in Debian these are deemed to go into a single source package, it is technically possible using the component system in git-buildpackage and uscan. For an example see the gbp.conf and watch files in the node-cacache package. Using this type of structure should be a last resort, as it creates complexity and inter-dependencies that are bound to cause issues later on. It is usually better to work with upstream and champion universal best practices with clear releases and version schemes.

When not to start the Debian packaging repository as a fork of the upstream one Not all upstreams use Git for version control. It is by far the most popular, but there are still some that use e.g. Subversion or Mercurial. Who knows maybe in the future some new version control systems will start to compete with Git. There are also projects that use Git in massive monorepos and with complex submodule setups that invalidate the basic assumptions required to map an upstream Git repository into a Debian packaging repository. In those cases one can t use a debian/latest branch on a clone of the upstream git repository as the starting point for the Debian packaging, but one must revert the traditional way of starting from an upstream release tarball with gbp import-orig package-1.0.tar.gz.

Conclusion Created in August 1993, Debian is one of the oldest Linux distributions. In the 32 years since inception, the .deb packaging format and the tooling to work with it have evolved several generations. In the past 10 years, more and more Debian Developers have converged on certain core practices evidenced by https://trends.debian.net/, but there is still a lot of variance in workflows even for identical tasks. Hopefully, you find this post useful in giving practical guidance on how exactly to do the most common things when packaging software for Debian. Happy packaging!

24 May 2025

Julian Andres Klode: A SomewhatMaxSAT Solver

As you may recall from previous posts and elsewhere I have been busy writing a new solver for APT. Today I want to share some of the latest changes in how to approach solving. The idea for the solver was that manually installed packages are always protected from removals in terms of SAT solving, they are facts. Automatically installed packages become optional unit clauses. Optional clauses are solved after manual ones, they don t partake in normal unit propagation. This worked fine, say you had
A                                   # install request for A
B                                   # manually installed, keep it
A depends on: conflicts-B   C
Installing A on a system with B installed installed C, as it was not allowed to install the conflicts-B package since B is installed. However, I also introduced a mode to allow removing manually installed packages, and that s where it broke down, now instead of B being a fact, our clauses looked like:
A                               # install request for A
A depends on: conflicts-B   C
Optional: B                     # try to keep B installed
As a result, we installed conflicts-B and removed B; the steps the solver takes are:
  1. A is a fact, mark it
  2. A depends on: conflicts-B C is the strongest clause, try to install conflicts-B
  3. We unit propagate that conflicts-B conflicts with B, so we mark not B
  4. Optional: B is reached, but not satisfiable, ignore it because it s optional.
This isn t correct: Just because we allow removing manually installed packages doesn t mean that we should remove manually installed packages if we don t need to. Fixing this turns out to be surprisingly easy. In addition to adding our optional (soft) clauses, let s first assume all of them! But to explain how this works, we first need to explain some terminology:
  1. The solver operates on a stack of decisions
  2. enqueue means a fact is being added at the current decision level, and enqueued for propagation
  3. assume bumps the decision level, and then enqueues the assumed variable
  4. propagate looks at all the facts and sees if any clause becomes unit, and then enqueues it
  5. unit is when a clause has a single literal left to assign
To illustrate this in pseudo Python code:
  1. We introduce all our facts, and if they conflict, we are unsat:
    for fact in facts:
        enqueue(fact)
    if not propagate():
        return False
    
  2. For each optional literal, we register a soft clause and assume it. If the assumption fails, we ignore it. If it succeeds, but propagation fails, we undo the assumption.
    for optionalLiteral in optionalLiterals:
        registerClause(SoftClause([optionalLiteral]))
        if assume(optionalLiteral) and not propagate():
            undo()
    
  3. Finally we enter the main solver loop:
    while True:
        if not propagate():
            if not backtrack():
                return False
        elif <all clauses are satisfied>:
            return True
        elif it := find("best unassigned literal satisfying a hard clause"):
            assume(it)
        elif it := find("best literal satisfying a soft clause"):
            assume(it)
    
The key point to note is that the main loop will undo the assumptions in order; so if you assume A,B,C and B is not possible, we will have also undone C. But since C is also enqueued as a soft clause, we will then later find it again:
  1. Assume A: State=[Assume(A)], Clauses=[SoftClause([A])]
  2. Assume B: State=[Assume(A),Assume(B)], Clauses=[SoftClause([A]),SoftClause([B])]
  3. Assume C: State=[Assume(A),Assume(B),Assume(C)], Clauses=[SoftClause([A]),SoftClause([B]),SoftClause([C])]
  4. Solve finds a conflict, backtracks, and sets not C: State=[Assume(A),Assume(B),not(C)]
  5. Solve finds a conflict, backtracks, and sets not B: State=[Assume(A),not(B)] C is no longer assumed either
  6. Solve, assume C as it satisfies SoftClause([C]) as next best literal: State=[Assume(A),not(B),Assume(C)]
  7. All clauses are satisfied, solution is A, not B, and C.
This is not (correct) MaxSAT, because we actually do not guarantee that we satisfy as many soft clauses as possible. Consider you have the following clauses:
Optional: A
Optional: B
Optional: C
B Conflicts with A
C Conflicts with A
There are two possible results here:
  1. A If we assume A first, we are unable to satisfy B or C.
  2. B,C If we assume either B or C first, A is unsat.
The question to ponder though is whether we actually need a global maximum or whether a local maximum is satisfactory in practice for a dependency solver If you look at it, a naive MaxSAT solver needs to run the SAT solver 2**n times for n soft clauses, whereas our heuristic only needs n runs. For dependency solving, it seems we do not seem have a strong need for a global maximum: There are various other preferences between our literals, say priorities; and empirically, from evaluating hundreds of regressions without the initial assumptions, I can say that the assumptions do fix those cases and the result is correct. Further improvements exist, though, and we can look into them if they are needed, such as:

23 May 2025

Gunnar Wolf: No further discussion -- I am staying with a Thinkpad keyboard.

I have been a very happy user of my two SK-8845 keyboards (one at my office, one at home) since I bought them, in 2018 and 2021 respectively. What are they, mind you? SK-8845 keyboard) The beautiful keyboard every Thinkpad owner knows and loves. And although I no longer use my X230 laptop that was my workhorse for several years, my fingers are spoiled. So, both shift keys of my home keyboard have been getting flaky, and I am basically sure it s a failure in the controller, as it does not feel to be physical. It s time to revisit that seven year old post where I found the SK-8845. This time, I decided to try my luck with something different. As a Emacs user, everybody knows we ought to be happy with more and more keys. In fact, I suppose many international people are now familiar with El Eternauta, true? we Emacs users would be the natural ambassadors to deal with the hand species: Emacs users from outer space! So it kind-of sort-of made sense, when I saw a Toshiba-IBM keyboard being sold for quite cheap (MX$400, just over US$20) to try my luck with it: A truly POS keyboard This is quite an odd piece of hardware, built in 2013 according to its label. At first I was unsure whether to buy it because of the weird interface it had, but the vendor replied they would ship a (very long!) USB cable with it, so A weird port inside the keyboard And a matching weird connector As expected, connecting it to Linux led to a swift, errorless recognition: Nothing too odd here Within minutes of receiving the hardware, I had it hooked up and started looking at the events it generated However the romance soon started to wane. Some of the reasons: Anyway I m returning it I found an SK-8845 for sale in China for just MX$1814 (~US$90), and jumped for it They are getting scarce! Nowadays it s getting more common (and cheaper) to find the newer style Thinkpad keyboards, but without a trackpad I don t think I should stockpile on keyboards, but no, I m not doing that Anyway, so I m sticking to a Thinkpad keyboard, third in a row.

21 May 2025

Russell Coker: Digital Sovereignty and Email

Running Your Own Email Srever I run my own mail server. I have run it since about 1995, initially on a 28k8 modem connection but the connection improved as technology became cheaper and now I m running it on a VM on a Hetzner server which is also running domains for some small businesses. I make a small amount of money running mail services for those companies but generally not enough to make it profitable. From a strictly financial basis I might be better off just using a big service, but I like having control over my own email. If email doesn t arrive I can read the logs to find out why. I repeatedly have issues of big services not accepting mail. The most recent is the MS services claiming that my IP has a bad ratio of good mail to spam and blocked me so I had to tunnel that through a different IP address. It seems that the way things are going is that if you run a small server companies like MS can block you even though your amount of spam is low but if you run a large scale service that is horrible for sending spam then you don t get blocked. For most users they just use one of the major email services (Gmail or Microsoft) and find that no-one blocks them because those providers are too big to block and things mostly work. Until of course the company decides to cancel their account. The Latest News The latest news is that MS is shutting down services for the International Court of Justice after a panel of ICC judges issued arrest warrants against Israeli Prime Minister Benjamin Netanyahu [1] . This is now making politicians realise the issues of email accounts hosted outside their jurisdiction. What we need is for each independent jurisdiction to have it s own email infrastructure, that means controlling DNS servers for their domains, commercial and government mail services on those domains, running the servers for those services on hardware located in the jurisdiction and run by people based in that jurisdiction and citizens of it. I say independent jurisdiction because there are groups like the EU which have sufficient harmony of laws to not require different services. With the current EU arrangements I don t think it s possible for the German government to block French people from accessing email or vice versa. While Australia and New Zealand have a long history of cooperation there s still the possibility of a lying asshole like Scott Morrison trying something on so New Zealanders shouldn t feel safe using services run in Australia. Note that Scott Morrison misled his own parliamentary colleagues about what he was doing and got himself assigned as a secret minister [2] demonstrating that even conservatives can t trust someone like him. With the ongoing human rights abuses by the Morrison government it s easy to imagine New Zealand based organisations that protect human rights being treated by the Australian government in the way that the ICC was treated by the US government. The Problem with Partial Solutions Now it would be very easy for the ICC to host their own mail servers and they probably will do just that in the near future. I m sure that there are many companies offering to set them up accounts in a hurry to deal with this (probably including some of the Dutch companies I ve worked for). Let s imagine for the sake of discussion that the ICC has their own private server, the US government could compel Google and MS to block the IP addresses of that server and then at least 1/3 of the EU population won t get mail from them. If the ICC used email addresses hosted on someone else s server then Google and MS could be compelled to block the addresses in question for the same result. The ICC could have changing email addresses to get around block lists and there could be a game of cat and mouse between the ICC and the US government but that would just be annoying for everyone. The EU needs to have services hosted and run in their jurisdiction that are used by the vast majority of the people in the country. The more people who are using services outside the control of hostile governments the lesser the impact of bad IT policies by those hostile governments. One possible model to consider is the Postbank model. Postbank is a bank run in the Netherlands from post offices which provides services to people deemed unprofitable for the big banks. If the post offices were associated with a mail service you could have it government subsidised providing free service for citizens and using government ID if the user forgets their password. You could also have it provide a cheap service for non-citizen residents. Other Problems What will the US government do next? Will they demand that Apple and Google do a remote-wipe on all phones run by ICC employees? Are they currently tracking all ICC employees by Android and iPhone services? Huawei s decision to develop their own phone OS was a reasonable one but there s no need to go that far. Other governments could setup their own equivalent to Google Play services for Android and have their own localised Android build. Even a small country like Australia could get this going for the services of calendaring etc. But the app store needs a bigger market. There s no reason why Android has to tie the app store to the services for calendaring etc. So you could have a per country system for calendaring and a per region system for selling apps. The invasion of Amazon services such as Alexa is also a major problem for digital sovereignty. We need government controls about this sort of thing, maybe have high tariffs on the import of all hardware that can only work with a single cloud service. Have 100+% tariffs on every phone, home automation system, or networked device that is either tied to a single cloud service or which can t work in a usable manner on other cloud services.

16 May 2025

Freexian Collaborators: Monthly report about Debian Long Term Support, April 2025 (by Roberto C. S nchez)

Like each month, have a look at the work funded by Freexian s Debian LTS offering.

Debian LTS contributors In April, 22 contributors have been paid to work on Debian LTS, their reports are available:
  • Adrian Bunk did 56.25h (out of 56.25h assigned).
  • Andreas Henriksson did 15.0h (out of 20.0h assigned), thus carrying over 5.0h to the next month.
  • Andrej Shadura did 10.0h (out of 6.0h assigned and 4.0h from previous period).
  • Bastien Roucari s did 31.5h (out of 31.5h assigned).
  • Ben Hutchings did 8.0h (out of 0.0h assigned and 12.0h from previous period), thus carrying over 4.0h to the next month.
  • Carlos Henrique Lima Melara did 11.0h (out of 12.0h assigned), thus carrying over 1.0h to the next month.
  • Chris Lamb did 18.0h (out of 18.0h assigned).
  • Daniel Leidert did 26.0h (out of 26.0h assigned).
  • Emilio Pozuelo Monfort did 30.0h (out of 39.25h assigned and 0.25h from previous period), thus carrying over 9.5h to the next month.
  • Guilhem Moulin did 8.5h (out of 3.25h assigned and 11.75h from previous period), thus carrying over 6.5h to the next month.
  • Jochen Sprickerhof did 12.5h (out of 20.75h assigned and 9.25h from previous period), thus carrying over 17.5h to the next month.
  • Lee Garrett did 26.25h (out of 7.75h assigned and 31.75h from previous period), thus carrying over 13.25h to the next month.
  • Lucas Kanashiro did 50.0h (out of 0.0h assigned and 52.0h from previous period), thus carrying over 2.0h to the next month.
  • Markus Koschany did 39.5h (out of 39.5h assigned).
  • Roberto C. S nchez did 9.0h (out of 0.0h assigned and 12.0h from previous period), thus carrying over 3.0h to the next month.
  • Santiago Ruano Rinc n did 12.5h (out of 7.5h assigned and 7.5h from previous period), thus carrying over 2.5h to the next month.
  • Sean Whitton did 7.0h (out of 7.0h assigned).
  • Stefano Rivera did 0.5h (out of 0.0h assigned and 10.0h from previous period), thus carrying over 9.5h to the next month.
  • Sylvain Beucler did 39.5h (out of 39.25h assigned and 0.25h from previous period).
  • Thorsten Alteholz did 15.0h (out of 15.0h assigned).
  • Tobias Frost did 12.0h (out of 7.75h assigned and 4.25h from previous period).
  • Utkarsh Gupta did 2.0h (out of 2.0h assigned).

Evolution of the situation In April, we released 46 DLAs.
  • Notable security updates:
    • jetty9, prepared by Markus Koschany, fixes an information disclosure and potential remote code execution vulnerability
    • zabbix, prepared by Tobias Frost, fixes several vulnerabilities, encompassing denial of service, information disclosure or remote code inclusion
    • glibc, prepared by Sean Whitton, fixes a buffer overflow vulnerability
  • Notable non-security updates:
    • tzdata, prepared by Emilio Pozuelo Monfort, brings the latest timezone database release
    • php-horde-editor and php-horde-imp, prepared by Sylvain Beucler, have been updated to switch from CKEditor v3, which is EOL, to CKEditor v4; this builds upon work done last month by Sylvain and Bastien for the complete removal of ckeditor3
    • distro-info-data, prepared by Stefano Rivera, adds information concerning future Debian and Ubuntu releases
The LTS team continues to welcome the collaboration of maintainers and other interested parties from outside the regular team. In April, we had external updates contributed by: Yadd - lemonldap-ng and Moritz Schlarb - libapache2-mod-auth-openidc A point release of the current stable Debian 12 (codename bookworm ) is planned for mid-May and several LTS contributors have prepared packages for this update, many of them prepared in conjunction with related LTS updates of the same packages:
  • glib2.0, haproxy, imagemagick, poppler, and python-h11, prepared by Adrian Bunk
  • rubygems, prepared by Lucas Kanashiro
  • ruby3.1 (in collaboration with Lucas Kanashiro), twitter-bootstrap3, twitterboot-strap4, wpa, and erlang, prepared by Bastien Roucari s (corresponding updates of twitter-bootstrap3 and twitter-bootstrap4 were also uploaded to Debian unstable)
  • abseil, prepared by Tobias Frost (a corresponding update was also uploaded to Debian unstable)
  • vips, prepared by Guilhem Moulin
Additional updates of ruby3.3 and rubygems were prepared for Debian unstable by Lucas Kanashiro. And finally, a highlight of our continued commitment to enhancing long term support efforts in upstream projects. Freexian, as the primary entity behind the management and execution of the LTS project, has partnered with Invisible Things Lab to extend the upstream security support of Xen 4.17, which is shipped in Debian 12 bookworm (the current stable release). This partnership will result in significantly improved lifecycle support for users of Xen on bookworm, and members of the LTS team will play a part in this endeavour. The Freexian announcement has additional details.

Thanks to our sponsors Sponsors that joined recently are in bold.

14 May 2025

Jonathan Dowland: Orbital

Orbital at NX, Newcastle in 2023 Orbital at NX, Newcastle in 2023
I'm on a bit of an Orbital kick at the moment. Last year they re-issued their 1991 debut album with 43 extra tracks. Later this month they're doing the same for their 1993 sophomore album. I thought I'd try to narrow down some tracks to recommend. I seem to have settled on roughly 5 in previous posts (for Underworld, The Cure, Coil and Gazelle Twin). This time I've done 6 (I borrowed one from Underworld) As always it's a hard choice. I've tried to select some tracks I really enjoy that don't often come up on best-of compilation albums. For a more conventional choice of best-of tracks, I recommend the recent-ish 30 something "compilation" (of sorts, previously written about)
  1. The Naked and the Dead (1992) The Naked and the Dead by Orbital From an early EP Radiccio, which is being re-issued this month. Digital versions of the re-issue will feature a new recording "Deepest" featuring Tilda Swinton. Sadly this isn't making it onto the pressed version. She performed with them live at Glastonbury 2024. That entire performance was a real pick-me-up during my convolescence, and is recommended. Anyway I've now written more about a song I haven't recommended than the one I did
  2. Remind (1993) Remind by Orbital From the Brown Album, I first heard this as the Encore from their "final show", for John Peel, when they split up in 2004. "Remind" wasn't broadcast, but an audience recording was circulated on fan site Loopz. Remarkably, 21 years on, it's still there. In writing this I discovered that it's a re-working of a remix Orbital did for Meat Beat Manifesto: MindStream (Mind The Bend The Mind)
  3. You Lot (2004) From the unfairly-maligned "final" Blue album. Featuring a sample of pre-Doctor Who Christoper Eccleston, from another Russell T Davies production, Second Coming.
  4. Beached (2000) Beached (Long version) by Orbital, Angelo Badalamenti Co-written by Angelo Badalamenti, it's built around a sample of Badalamenti's score for the movie "The Beach". Orbital's re-work adds some grit to the orchestral instrumentation and opens with a monologue, delivered by Leonardo Di Caprio, sampled from the movie.
  5. Spare Parts Express (1999) Spare Parts Express by Orbital Critics had started to be quite unfair to Orbital by this point. The band themselves said that they'd ran out of ideas (pointing at album closer "Style", built around a Stylophone melody, as proof). Their malaise continued right up to the Blue Album, at which point the split up; ostensibly for good, before regrouping 8 years later. Spare Parts Express is a hatchet job of various bits that they didn't develop into full songs on their own. Despite this I think it works. I love long-form electronica, and this clocks in at 10:07. My favourite segment (06:37) is adjacent to a reference (05:05) to John Baker's theme for the BBC children's program Newsround (sadly they aren't using it today. Here's a rundown of Newsround themes over time)
  6. Attached (1994) Attached by Orbital This originally debuted on a Peel session before appearing on the subsequent album Snivilisation a few months later. An album closer, and a good come-down song to close this list.

13 May 2025

Ben Hutchings: Report for Debian BSP near Leuven in April 2025

On 26th and 27th April we held a Debian bug-squashing party near Leuven, Belgium. Several longstanding and new Debian contributors gathered to work through some of the highest priority bugs affecting the upcoming release of Debian 13 trixie . We were hosted by the Familia community centre in Tildonk. As this venue currently does not have an Internet connection, we brought a mobile hotspot and a local Debian mirror. In attendance were: The new contributors were variously using Arch, Fedora, and Ubuntu, and the DDs spent some some time setting them up with Debian dvelopment environments. The bugs we worked on included:

12 May 2025

Reproducible Builds: Reproducible Builds in April 2025

Welcome to our fourth report from the Reproducible Builds project in 2025. These monthly reports outline what we ve been up to over the past month, and highlight items of news from elsewhere in the increasingly-important area of software supply-chain security. Lastly, if you are interested in contributing to the Reproducible Builds project, please visit our Contribute page on our website. Table of contents:
  1. reproduce.debian.net
  2. Fifty Years of Open Source Software Supply Chain Security
  3. 4th CHAINS Software Supply Chain Workshop
  4. Mailing list updates
  5. Canonicalization for Unreproducible Builds in Java
  6. OSS Rebuild adds new TUI features
  7. Distribution roundup
  8. diffoscope & strip-nondeterminism
  9. Website updates
  10. Reproducibility testing framework
  11. Upstream patches

reproduce.debian.net The last few months have seen the introduction, development and deployment of reproduce.debian.net. In technical terms, this is an instance of rebuilderd, our server designed monitor the official package repositories of Linux distributions and attempt to reproduce the observed results there. This month, however, we are pleased to announce that reproduce.debian.net now tests all the Debian trixie architectures except s390x and mips64el. The ppc64el architecture was added through the generous support of Oregon State University Open Source Laboratory (OSUOSL), and we can support the armel architecture thanks to CodeThink.

Fifty Years of Open Source Software Supply Chain Security Russ Cox has published a must-read article in ACM Queue on Fifty Years of Open Source Software Supply Chain Security. Subtitled, For decades, software reuse was only a lofty goal. Now it s very real. , Russ article goes on to outline the history and original goals of software supply-chain security in the US military in the early 1970s, all the way to the XZ Utils backdoor of 2024. Through that lens, Russ explores the problem and how it has changed, and hasn t changed, over time. He concludes as follows:
We are all struggling with a massive shift that has happened in the past 10 or 20 years in the software industry. For decades, software reuse was only a lofty goal. Now it s very real. Modern programming environments such as Go, Node and Rust have made it trivial to reuse work by others, but our instincts about responsible behaviors have not yet adapted to this new reality. We all have more work to do.

4th CHAINS Software Supply Chain Workshop Convened as part of the CHAINS research project at the KTH Royal Institute of Technology in Stockholm, Sweden, the 4th CHAINS Software Supply Chain Workshop occurred during April. During the workshop, there were a number of relevant workshops, including: The full listing of the agenda is available on the workshop s website.

Mailing list updates On our mailing list this month:
  • Luca DiMaio of Chainguard posted to the list reporting that they had successfully implemented reproducible filesystem images with both ext4 and an EFI system partition. They go on to list the various methods, and the thread generated at least fifteen replies.
  • David Wheeler announced that the OpenSSF is building a glossary of sorts in order that they consistently use the same meaning for the same term and, moreover, that they have drafted a definition for reproducible build . The thread generated a significant number of replies on the definition, leading to a potential update to the Reproducible Build s own definition.
  • Lastly, kpcyrd posted to the list with a timely reminder and update on their repro-env tool. As first reported in our July 2023 report, kpcyrd mentions that:
    My initial interest in reproducible builds was how do I distribute pre-compiled binaries on GitHub without people raising security concerns about them . I ve cycled back to this original problem about 5 years later and built a tool that is meant to address this. [ ]

Canonicalization for Unreproducible Builds in Java Aman Sharma, Benoit Baudry and Martin Monperrus have published a new scholarly study related to reproducible builds within Java. Titled Canonicalization for Unreproducible Builds in Java, the article s abstract is as follows:
[ ] Achieving reproducibility at scale remains difficult, especially in Java, due to a range of non-deterministic factors and caveats in the build process. In this work, we focus on reproducibility in Java-based software, archetypal of enterprise applications. We introduce a conceptual framework for reproducible builds, we analyze a large dataset from Reproducible Central and we develop a novel taxonomy of six root causes of unreproducibility. We study actionable mitigations: artifact and bytecode canonicalization using OSS-Rebuild and jNorm respectively. Finally, we present Chains-Rebuild, a tool that raises reproducibility success from 9.48% to 26.89% on 12,283 unreproducible artifacts. To sum up, our contributions are the first large-scale taxonomy of build unreproducibility causes in Java, a publicly available dataset of unreproducible builds, and Chains-Rebuild, a canonicalization tool for mitigating unreproducible builds in Java.
A full PDF of their article is available from arXiv.

OSS Rebuild adds new TUI features OSS Rebuild aims to automate rebuilding upstream language packages (e.g. from PyPI, crates.io and npm registries) and publish signed attestations and build definitions for public use. OSS Rebuild ships a text-based user interface (TUI) for viewing, launching, and debugging rebuilds. While previously requiring ownership of a full instance of OSS Rebuild s hosted infrastructure, the TUI now supports a fully local mode of build execution and artifact storage. Thanks to Giacomo Benedetti for his usage feedback and work to extend the local-only development toolkit. Another feature added to the TUI was an experimental chatbot integration that provides interactive feedback on rebuild failure root causes and suggests fixes.

Distribution roundup In Debian this month:
  • Roland Clobus posted another status report on reproducible ISO images on our mailing list this month, with the summary that all live images build reproducibly from the online Debian archive .
  • Debian developer Simon Josefsson published another two reproducibility-related blog posts this month, the first on the topic of Verified Reproducible Tarballs. Simon sardonically challenges the reader as follows: Do you want a supply-chain challenge for the Easter weekend? Pick some well-known software and try to re-create the official release tarballs from the corresponding Git checkout. Is anyone able to reproduce anything these days? After that, they also published a blog post on Building Debian in a GitLab Pipeline using their multi-stage rebuild approach.
  • Roland also posted to our mailing list to highlight that there is now another tool in Debian that generates reproducible output, equivs . This is a tool to create trivial Debian packages that might Depend on other packages. As Roland writes, building the [equivs] package has been reproducible for a while, [but] now the output of the [tool] has become reproducible as well .
  • Lastly, 9 reviews of Debian packages were added, 10 were updated and 10 were removed this month adding to our extensive knowledge about identified issues.
The IzzyOnDroid Android APK repository made more progress in April. Thanks to funding by NLnet and Mobifree, the project was also to put more time into their tooling. For instance, developers can now easily run their own verification builder in less than 5 minutes . This currently supports Debian-based systems, but support for RPM-based systems is incoming.
  • The rbuilder_setup tool can now setup the entire framework within less than five minutes. The process is configurable, too, so everything from just the basics to verify builds up to a fully-fledged RB environment is also possible.
  • This tool works on Debian, RedHat and Arch Linux, as well as their derivates. The project has received successful reports from Debian, Ubuntu, Fedora and some Arch Linux derivates so far.
  • Documentation on how to work with reproducible builds (making apps reproducible, debugging unreproducible packages, etc) is available in the project s wiki page.
  • Future work is also in the pipeline, including documentation, guidelines and helpers for debugging.
NixOS defined an Outreachy project for improving build reproducibility. In the application phase, NixOS saw some strong candidates providing contributions, both on the NixOS side and upstream: guider-le-ecit analyzed a libpinyin issue. Tessy James fixed an issue in arandr and helped analyze one in libvlc that led to a proposed upstream fix. Finally, 3pleX fixed an issue which was accepted in upstream kitty, one in upstream maturin, one in upstream python-sip and one in the Nix packaging of python-libbytesize. Sadly, the funding for this internship fell through, so NixOS were forced to abandon their search. Lastly, in openSUSE news, Bernhard M. Wiedemann posted another monthly update for their work there.

diffoscope & strip-nondeterminism diffoscope is our in-depth and content-aware diff utility that can locate and diagnose reproducibility issues. This month, Chris Lamb made the following changes, including preparing and uploading a number of versions to Debian:
  • Use the --walk argument over the potentially dangerous alternative --scan when calling out to zipdetails(1). [ ]
  • Correct a longstanding issue where many >-based version tests used in conditional fixtures were broken. This was used to ensure that specific tests were only run when the version on the system was newer than a particular number. Thanks to Colin Watson for the report (Debian bug #1102658) [ ]
  • Address a long-hidden issue in the test_versions testsuite as well, where we weren t actually testing the greater-than comparisons mentioned above, as it was masked by the tests for equality. [ ]
  • Update copyright years. [ ]
In strip-nondeterminism, however, Holger Levsen updated the Continuous Integration (CI) configuration in order to use the standard Debian pipelines via debian/salsa-ci.yml instead of using .gitlab-ci.yml. [ ]

Website updates Once again, there were a number of improvements made to our website this month including:
  • Aman Sharma added OSS-Rebuild s stabilize tool to the Tools page. [ ][ ]
  • Chris Lamb added a configure.ac (GNU Autotools) example for using SOURCE_DATE_EPOCH. [ ]. Chris also updated the SOURCE_DATE_EPOCH snippet and move the archive metadata to a more suitable location. [ ]
  • Denis Carikli added GNU Boot to our ever-evolving Projects page.

Reproducibility testing framework The Reproducible Builds project operates a comprehensive testing framework running primarily at tests.reproducible-builds.org in order to check packages and other artifacts for reproducibility. In April, a number of changes were made by Holger Levsen, including:
  • reproduce.debian.net-related:
    • Add armel.reproduce.debian.net to support the armel architecture. [ ][ ]
    • Add a new ARM node, codethink05. [ ][ ]
    • Add ppc64el.reproduce.debian.net to support testing of the ppc64el architecture. [ ][ ][ ]
    • Improve the reproduce.debian.net front page. [ ][ ]
    • Make various changes to the ppc64el nodes. [ ][ ]9[ ][ ]
    • Make various changes to the arm64 and armhf nodes. [ ][ ][ ][ ]
    • Various changes related to the rebuilderd-worker entry point. [ ][ ][ ]
    • Create and deploy a pkgsync script. [ ][ ][ ][ ][ ][ ][ ][ ]
    • Fix the monitoring of the riscv64 architecture. [ ][ ]
    • Make a number of changes related to starting the rebuilderd service. [ ][ ][ ][ ]
  • Backup-related:
    • Backup the rebuilder databases every week. [ ][ ][ ][ ]
    • Improve the node health checks. [ ][ ]
  • Misc:
    • Re-use existing connections to the SSH proxy node on the riscv64 nodes. [ ][ ]
    • Node maintenance. [ ][ ][ ]
In addition:
  • Jochen Sprickerhof fixed the risvc64 host names [ ] and requested access to all the rebuilderd nodes [ ].
  • Mattia Rizzolo updated the self-serve rebuild scheduling tool, replacing the deprecated SSO -style authentication with OpenIDC which authenticates against salsa.debian.org. [ ][ ][ ]
  • Roland Clobus updated the configuration for the osuosl3 node to designate 4 workers for bigger builds. [ ]

Upstream patches The Reproducible Builds project detects, dissects and attempts to fix as many currently-unreproducible packages as possible. We endeavour to send all of our patches upstream where appropriate. This month, we wrote a large number of such patches, including:

Finally, if you are interested in contributing to the Reproducible Builds project, please visit our Contribute page on our website. However, you can get in touch with us via:

Freexian Collaborators: Debian Contributions: DebConf 25 preparations, PyPA tools updates, Removing libcrypt-dev from build-essential and more! (by Anupa Ann Joseph)

Debian Contributions: 2025-04 Contributing to Debian is part of Freexian s mission. This article covers the latest achievements of Freexian and their collaborators. All of this is made possible by organizations subscribing to our Long Term Support contracts and consulting services.

DebConf 25 Preparations, by Stefano Rivera and Santiago Ruano Rinc n DebConf 25 preparations continue. In April, the bursary team reviewed and ranked bursary applications. Santiago Ruano Rinc n examined the current state of the conference s finances, to see if we could allocate any more money to bursaries. Stefano Rivera supported the bursary team s work with infrastructure and advice and added some metrics to assist Santiago s budget review. Santiago was also involved in different parts of the organization, including Content team matters, as reviewing the first of proposals, preparing public information about the new Academic Track; or coordinating different aspects of the Day trip activities and the Conference Dinner.

PyPA tools updates, by Stefano Rivera Around the beginning of the freeze (in retrospect, definitely too late) Stefano looked at updating setuptools in the archive to 78.1.0. This brings support for more comprehensive license expressions (PEP-639), that people are expected to adopt soon upstream. While the reverse-autopkgtests all passed, it all came with some unexpected complications, and turned into a mini-transition. The new setuptools broke shebangs for scripts (pypa/setuptools#4952). It also required a bump of wheel to 0.46 and wheel 0.46 now has a dependency outside the standard library (it de-vendored packaging). This meant it was no longer suitable to distribute a standalone wheel.whl file to seed into new virtualenvs, as virtualenv does by default. The good news here is that setuptools doesn t need wheel any more, it included its own implementation of the bdist_wheel command, in 70.1. But the world hadn t adapted to take advantage of this, yet. Stefano scrambled to get all of these issues resolved upstream and in Debian: We re now at the point where python3-wheel-whl is no longer needed in Debian unstable, and it should migrate to trixie.

Removing libcrypt-dev from build-essential, by Helmut Grohne The crypt function was originally part of glibc, but it got separated to libxcrypt. As a result, libc6-dev now depends on libcrypt-dev. This poses a cycle during architecture cross bootstrap. As the number of packages actually using crypt is relatively small, Helmut proposed removing the dependency. He analyzed an archive rebuild kindly performed by Santiago Vila (not affiliated with Freexian) and estimated the necessary changes. It looks like we may complete this with modifications to less than 300 source packages in the forky cycle. Half of the bugs have been filed at this time. They are tracked with libcrypt-* usertags.

Miscellaneous contributions
  • Carles uploaded a new version of simplemonitor.
  • Carles improved the documentation of salsa-ci-team/pipeline regarding piuparts arguments.
  • Carles closed an FTBFS on gcc-15 on qnetload.
  • Carles worked on Catalan translations using po-debconf-manager: reviewed 57 translations and created their merge requests in salsa, created 59 bug reports for packages that didn t merge in more than 30 days. Followed-up merge requests and comments in bug reports. Managed some translations manually for packages that are not in Salsa.
  • Lucas did some work on the DebConf Content and Bursary teams.
  • Lucas fixed multiple CVEs and bugs involving the upgrade from bookworm to trixie in ruby3.3.
  • Lucas fixed a CVE in valkey in unstable.
  • Stefano updated beautifulsoup4, python-authlib, python-html2text, python-packaging, python-pip, python-soupsieve, and unidecode.
  • Stefano packaged python-dependency-groups, a new vendored library in python-pip.
  • During an afternoon Bug Squashing Party in Montevideo, Santiago uploaded a couple of packages fixing RC bugs #1057226 and #1102487. The latter was a sponsored upload.
  • Thorsten uploaded new upstream versions of brlaser, ptouch-driver and sane-airscan to get the latest upstream bug fixes into Trixie.
  • Rapha l filed an upstream bug on zim for a graphical glitch that he has been experiencing.
  • Colin Watson upgraded openssh to 10.0p1 (also known as 10.0p2), and debugged various follow-up bugs. This included adding riscv64 support to vmdb2 in passing, and enabling native wtmpdb support so that wtmpdb last now reports the correct tty for SSH connections.
  • Colin fixed dput-ng s override option, which had never previously worked.
  • Colin fixed a security bug in debmirror.
  • Colin did his usual routine work on the Python team: 21 packages upgraded to new upstream versions, 8 CVEs fixed, and about 25 release-critical bugs fixed.
  • Helmut filed patches for 21 cross build failures.
  • Helmut uploaded a new version of debvm featuring a new tool debefivm-create to generate EFI-bootable disk images compatible with other tools such as libvirt or VirtualBox. Much of the work was prototyped in earlier months. This generalizes mmdebstrap-autopkgtest-build-qemu.
  • Helmut continued reporting undeclared file conflicts and suggested package removals from unstable.
  • Helmut proposed build profiles for libftdi1 and gnupg2. To deal with recently added dependencies in the architecture cross bootstrap package set.
  • Helmut managed the /usr-move transition. He worked on ensuring that systemd would comply with Debian s policy. Dumat continues to locate problems here and there yielding discussion occasionally. He sent a patch for an upgrade problem in zutils.
  • Anupa worked with the Debian publicity team to publish Micronews and Bits posts.
  • Anupa worked with the DebConf 25 content team to review talk and event proposals for DebConf 25.

11 May 2025

Bits from Debian: Bits from the DPL

Dear Debian community, This is bits from the DPL for April. End of 10 I am sure I was speaking in the interest of the whole project when joining the "End of 10" campaign. Here is what I wrote to the initiators:
Hi Joseph and all drivers of the "End of 10" campaign, On behalf of the entire Debian project, I would like to say that we proudly join your great campaign. We stand with you in promoting Free Software, defending users' freedoms, and protecting our planet by avoiding unnecessary hardware waste. Thank you for leading this important initiative.
Andreas Tille Debian Project Leader
I have some goals I would like to share with you for my second term. Ftpmaster delegation This splits up into tasks that can be done before and after Trixie release. Before Trixie: 1. Reducing Barriers to DFSG Compliance Checks Back in 2002, Debian established a way to distribute cryptographic software in the main archive, whereas such software had previously been restricted to the non-US archive. One result of this arrangement which influences our workflow is that all packages uploaded to the NEW queue must remain on the server that hosts it. This requirement means that members of the ftpmaster team must log in to that specific machine, where they are limited to a restricted set of tools for reviewing uploaded code. This setup may act as a barrier to participation--particularly for contributors who might otherwise assist with reviewing packages for DFSG compliance. I believe it is time to reassess this limitation and work toward removing such hurdles. In October last year, we had some initial contact with SPI's legal counsel, who noted that US regulations around cryptography have been relaxed somewhat in recent years (as of 2021). This suggests it may now be possible to revisit and potentially revise the conditions under which we manage cryptographic software in the NEW queue. I plan to investigate this further. If you have expertise in software or export control law and are interested in helping with this topic, please get in touch with me. The ultimate goal is to make it easier for more people to contribute to ensuring that code in the NEW queue complies with the DFSG. 2. Discussing Alternatives My chances to reach out to other distributions remained limited. However, regarding the processing of new software, I learned that OpenSUSE uses a Git-based workflow that requires five "LGTM" approvals from a group of trusted developers. As far as I know, Fedora follows a similar approach. Inspired by this, a recent community initiative--the Gateway to NEW project--enables peer review of new packages for DFSG compliance before they enter the NEW queue. This effort allows anyone to contribute by reviewing packages and flagging potential issues in advance via Git. I particularly appreciate that the DFSG review is coupled with CI, allowing for both license and technical evaluation. While this process currently results in some duplication of work--since final reviews are still performed by the ftpmaster team--it offers a valuable opportunity to catch issues early and improve the overall quality of uploads. If the community sees long-term value in this approach, it could serve as a basis for evolving our workflows. Integrating it more closely into DAK could streamline the process, and we've recently seen that merge requests reflecting community suggestions can be accepted promptly. For now, I would like to gather opinions about how such initiatives could best complement the current NEW processing, and whether greater consensus on trusted peer review could help reduce the burden on the team doing DFSG compliance checks. Submitting packages for review and automated testing before uploading can improve quality and encourage broader participation in safeguarding Debian's Free Software principles. My explicit thanks go out to the Gateway to NEW team for their valuable and forward-looking contribution to Debian. 3. Documenting Critical Workflows Past ftpmaster trainees have told me that understanding the full set of ftpmaster workflows can be quite difficult. While there is some useful documentation thanks in particular to Sean Whitton for his work on documenting NEW processing rules many other important tasks carried out by the ftpmaster team remain undocumented or only partially so. Comprehensive and accessible documentation would greatly benefit current and future team members, especially those onboarding or assisting in specific workflows. It would also help ensure continuity and transparency in how critical parts of the archive are managed. If such documentation already exists and I have simply overlooked it, I would be happy to be corrected. Otherwise, I believe this is an area where we need to improve significantly. Volunteers with a talent for writing technical documentation are warmly invited to contact me--I'd be happy to help establish connections with ftpmaster team members who are willing to share their knowledge so that it can be written down and preserved. Once Trixie is released (hopefully before DebConf): 4. Split of the Ftpmaster Team into DFSG and Archive Teams As discussed during the "Meet the ftpteam" BoF at DebConf24, I would like to propose a structural refinement of the current Ftpmaster team by introducing two different delegated teams:
  1. DFSG Team
  2. Archive Team (responsible for DAK maintenance and process tooling, including releases)
(Alternative name suggestions are, of course, welcome.) The primary task of the DFSG team would be the processing of the NEW queue and ensuring that packages comply with the DFSG. The Archive team would focus on maintaining DAK and handling the technical aspects of archive management. I am aware that, in the recent past, the ftpmaster team has decided not to actively seek new members. While I respect the autonomy of each team, the resulting lack of a recruitment pipeline has led to some friction and concern within the wider community, including myself. As Debian Project Leader, it is my responsibility to ensure the long-term sustainability and resilience of our project, which includes fostering an environment where new contributors can join and existing teams remain effective and well-supported. Therefore, even if the current team does not prioritize recruitment, I will actively seek and encourage new contributors for both teams, with the aim of supporting openness and collaboration. This proposal is not intended as criticism of the current team's dedication or achievements--on the contrary, I am grateful for the hard work and commitment shown, often under challenging circumstances. My intention is to help address the structural issues that have made onboarding and specialization difficult and to ensure that both teams are well-supported for the future. I also believe that both teams should regularly inform the Debian community about the policies and procedures they apply. I welcome any suggestions for a more detailed description of the tasks involved, as well as feedback on how best to implement this change in a way that supports collaboration and transparency. My intention with this proposal is to foster a more open and effective working environment, and I am committed to working with all involved to ensure that any changes are made collaboratively and with respect for the important work already being done. I'm aware that the ideas outlined above touch on core parts of how Debian operates and involve responsibilities across multiple teams. These are not small changes, and implementing them will require thoughtful discussion and collaboration. To move this forward, I've registered a dedicated BoF for DebConf. To make the most of that opportunity, I'm looking for volunteers who feel committed to improving our workflows and processes. With your help, we can prepare concrete and sensible proposals in advance--so the limited time of the BoF can be used effectively for decision-making and consensus-building. In short: I need your help to bring these changes to life. From my experience in my last term, I know that when it truly matters, the Debian community comes together--and I trust that spirit will guide us again. Please also note: we had a "Call for volunteers" five years ago, and much of what was written there still holds true today. I've been told that the response back then was overwhelming--but that training such a large number of volunteers didn't scale well. This time, I hope we can find a more sustainable approach: training a few dedicated people first, and then enabling them to pass on their knowledge. This will also be a topic at the DebCamp sprint. Dealing with Dormant Packages Debian was founded on the principle that each piece of software should be maintained by someone with expertise in it--typically a single, responsible maintainer. This model formed the historical foundation of Debian's packaging system and helped establish high standards of quality and accountability. However, as the project has grown and the number of packages has expanded, this model no longer scales well in all areas. Team maintenance has since emerged as a practical complement, allowing multiple contributors to share responsibility and reduce bottlenecks--depending on each team's internal policy. While working on the Bug of the Day initiative, I observed a significant number of packages that have not been updated in a long time. In the case of team-maintained packages, addressing this is often straightforward: team uploads can be made, or the team can be asked whether the package should be removed. We've also identified many packages that would fit well under the umbrella of active teams, such as language teams like Debian Perl and Debian Python, or blends like Debian Games and Debian Multimedia. Often, no one has taken action--not because of disagreement, but simply due to inattention or a lack of initiative. In addition, we've found several packages that probably should be removed entirely. In those cases, we've filed bugs with pre-removal warnings, which can later be escalated to removal requests. When a package is still formally maintained by an individual, but shows signs of neglect (e.g., no uploads for years, unfixed RC bugs, failing autopkgtests), we currently have three main tools:
  1. The MIA process, which handles inactive or unreachable maintainers.
  2. Package Salvaging, which allows contributors to take over maintenance if conditions are met.
  3. Non-Maintainer Uploads (NMUs), which are limited to specific, well-defined fixes (which do not include things like migration to Salsa).
These mechanisms are important and valuable, but they don't always allow us to react swiftly or comprehensively enough. Our tools for identifying packages that are effectively unmaintained are relatively weak, and the thresholds for taking action are often high. The Package Salvage team is currently trialing a process we've provisionally called "Intend to NMU" (ITN). The name is admittedly questionable--some have suggested alternatives like "Intent to Orphan"--and discussion about this is ongoing on debian-devel. The mechanism is intended for situations where packages appear inactive but aren't yet formally orphaned, introducing a clear 21-day notice period before NMUs, similar in spirit to the existing ITS process. The discussion has sparked suggestions for expanding NMU rules. While it is crucial not to undermine the autonomy of maintainers who remain actively involved, we also must not allow a strict interpretation of this autonomy to block needed improvements to obviously neglected packages. To be clear: I do not propose to change the rights of maintainers who are clearly active and invested in their packages. That model has served us well. However, we must also be honest that, in some cases, maintainers stop contributing--quietly and without transition plans. In those situations, we need more agile and scalable procedures to uphold Debian's high standards. To that end, I've registered a BoF session for DebConf25 to discuss potential improvements in how we handle dormant packages. These discussions will be prepared during a sprint at DebCamp, where I hope to work with others on concrete ideas. Among the topics I want to revisit is my proposal from last November on debian-devel, titled "Barriers between packages and other people". While the thread prompted substantial discussion, it understandably didn't lead to consensus. I intend to ensure the various viewpoints are fairly summarised--ideally by someone with a more neutral stance than myself--and, if possible, work toward a formal proposal during the DebCamp sprint to present at the DebConf BoF. My hope is that we can agree on mechanisms that allow us to act more effectively in situations where formerly very active volunteers have, for whatever reason, moved on. That way, we can protect both Debian's quality and its collaborative spirit. Building Sustainable Funding for Debian Debian incurs ongoing expenses to support its infrastructure--particularly hardware maintenance and upgrades--as well as to fund in-person meetings like sprints and mini-DebConfs. These investments are essential to our continued success: they enable productive collaboration and ensure the robustness of the operating system we provide to users and derivative distributions around the world. While DebConf benefits from generous sponsorship, and we regularly receive donated hardware, there is still considerable room to grow our financial base--especially to support less visible but equally critical activities. One key goal is to establish a more constant and predictable stream of income, helping Debian plan ahead and respond more flexibly to emerging needs. This presents an excellent opportunity for contributors who may not be involved in packaging or technical development. Many of us in Debian are engineers first--and fundraising is not something we've been trained to do. But just like technical work, building sustainable funding requires expertise and long-term engagement. If you're someone who's passionate about Free Software and has experience with fundraising, donor outreach, sponsorship acquisition, or nonprofit development strategy, we would deeply value your help. Supporting Debian doesn't have to mean writing code. Helping us build a steady and reliable financial foundation is just as important--and could make a lasting impact. Kind regards Andreas. PS: In April I also planted my 5000th tree and while this is off-topic here I'm proud to share this information with my fellow Debian friends.

9 May 2025

Uwe Kleine-K nig: The Linux kernel's PGP Web of Trust

The Linux kernel's development process makes use of PGP. The most relevant part here is that subsystem maintainers are supposed to use signed tags in their pull requests to Linus Torvalds. As the concept of keyservers is considered broken, Konstantin Ryabitsev maintains a collection of relevant keys in a git repository. As of today (at commit a0bc65fb27f5033beddf9d1ad97d67c353849be2) there are 602 valid keys tracked in that repository. The requirement for a key to be added there is that there must be at least one trust path from Linus Torvalds' key to this key of length at most 5 within that keyring. Occasionally it happens that a key loses its trust paths because someone in these paths replaced their key, or keys expired. Currently this affects 2 keys. However there is a problem on the horizon: GnuPG 2.4.x started to reject third-party key signatures using the SHA-1 hash algorithm. In general that's good, SHA-1 isn't considered secure any more for more than 20 years. This doesn't directly affect the kernel-pgpkeys repo, because the trust path checking doesn't rely on GnuPG trusting the signatures; there is a dedicated tool that parses the keyring contents and currently accepts signatures using SHA-1. Also signatures are not thrown away usually, but there are exceptions: Recently Theodore Ts'o asked to update his certificate. When Konstantin imported the updated certificate GnuPG's "cleaning" was applied which dropped all SHA-1 signatures. So Theodore Ts'o's key lost 168 signatures, among them one by Linus Torvalds on his primary UID. That made me wonder what would be the effect on the web of trust if all SHA-1 signatures were dropped. Here are the facts: If you attend Embedded Recipes 2025 next week, there is an opportunity to improve the situation: Together with Ahmad Fatoum I'm organizing a keysigning session. If you want to participate, send your public key to er2025-keysigning@baylibre.com before 2025-05-12 08:00 UTC.

6 May 2025

Enrico Zini: Python-like abspath for c++

Python's os.path.abspath or Path.absolute are great: you give them a path, which might not exist, and you get a path you can use regardless of the current directory. os.path.abspath will also normalize it, while Path will not by default because with Paths a normal form is less needed. This is great to normalize input, regardless of if it's an existing file you're needing to open, or a new file you're needing to create. In C++17, there is a filesystem library with methods with enticingly similar names, but which are almost, but not quite, totally unlike Python's abspath. Because in my C++ code I need to normalize input, regardless of if it's an existing file I'm needing to open or a new file I'm needing to create, here's an apparently working Python-like abspath for C++ implemented on top of the std::filesystem library:
std::filesystem::path abspath(const std::filesystem::path& path)
 
    // weakly_canonical is defined as "the result of calling canonical() with a
    // path argument composed of the leading elements of p that exist (as
    // determined by status(p) or status(p, ec)), if any, followed by the
    // elements of p that do not exist."
    //
    // This means that if no lead components of the path exist then the
    // resulting path is not made absolute, and we need to work around that.
    if (!path.is_absolute())
        return abspath(std::filesystem::current_path() / path);
    // This is further and needlessly complicated because we need to work
    // around https://gcc.gnu.org/bugzilla/show_bug.cgi?id=118733
    unsigned retry = 0;
    while (true)
     
        std::error_code code;
        auto result = std::filesystem::weakly_canonical(path, code);
        if (!code)
         
            // fprintf(stderr, "%s: ok in %u tries\n", path.c_str(), retry+1);
            return result;
         
        if (code == std::errc::no_such_file_or_directory)
         
            ++retry;
            if (retry > 50)
                throw std::system_error(code);
         
        else
            throw std::system_error(code);
     
    // Alternative implementation that however may not work on all platforms
    // since, formally, "[std::filesystem::absolute] Implementations are
    // encouraged to not consider p not existing to be an error", but they do
    // not mandate it, and if they did, they might still be affected by the
    // undefined behaviour outlined in https://gcc.gnu.org/bugzilla/show_bug.cgi?id=118733
    //
    // return std::filesystem::absolute(path).lexically_normal();
 
I added it to my wobble code repository, which is the thin repository of components I use to ease my C++ systems programming.

5 May 2025

Sergio Talens-Oliag: Argo CD Usage Examples

As a followup of my post about the use of argocd-autopilot I m going to deploy various applications to the cluster using Argo CD from the same repository we used on the previous post. For our examples we are going to test a solution to the problem we had when we updated a ConfigMap used by the argocd-server (the resource was updated but the application Pod was not because there was no change on the argocd-server deployment); our original fix was to kill the pod manually, but the manual operation is something we want to avoid. The proposed solution to this kind of issues on the helm documentation is to add annotations to the Deployments with values that are a hash of the ConfigMaps or Secrets used by them, this way if a file is updated the annotation is also updated and when the Deployment changes are applied a roll out of the pods is triggered. On this post we will install a couple of controllers and an application to show how we can handle Secrets with argocd and solve the issue with updates on ConfigMaps and Secrets, to do it we will execute the following tasks:
  1. Deploy the Reloader controller to our cluster. It is a tool that watches changes in ConfigMaps and Secrets and does rolling upgrades on the Pods that use them from Deployment, StatefulSet, DaemonSet or DeploymentConfig objects when they are updated (by default we have to add some annotations to the objects to make things work).
  2. Deploy a simple application that can use ConfigMaps and Secrets and test that the Reloader controller does its job when we add or update a ConfigMap.
  3. Install the Sealed Secrets controller to manage secrets inside our cluster, use it to add a secret to our sample application and see that the application is reloaded automatically.

Creating the test project for argocd-autopilotAs we did our installation using argocd-autopilot we will use its structure to manage the applications. The first thing to do is to create a project (we will name it test) as follows:
  argocd-autopilot project create test
INFO cloning git repository: https://forgejo.mixinet.net/blogops/argocd.git
Enumerating objects: 18, done.
Counting objects: 100% (18/18), done.
Compressing objects: 100% (16/16), done.
Total 18 (delta 1), reused 0 (delta 0), pack-reused 0
INFO using revision: "", installation path: "/"
INFO pushing new project manifest to repo
INFO project created: 'test'
Now that the test project is available we will use it on our argocd-autopilot invocations when creating applications.

Installing the reloader controllerTo add the reloader application to the test project as a kustomize application and deploy it on the tools namespace with argocd-autopilot we do the following:
  argocd-autopilot app create reloader \
    --app 'github.com/stakater/Reloader/deployments/kubernetes/?ref=v1.4.2' \
    --project test --type kustomize --dest-namespace tools
INFO cloning git repository: https://forgejo.mixinet.net/blogops/argocd.git
Enumerating objects: 19, done.
Counting objects: 100% (19/19), done.
Compressing objects: 100% (18/18), done.
Total 19 (delta 2), reused 0 (delta 0), pack-reused 0
INFO using revision: "", installation path: "/"
INFO created 'application namespace' file at '/bootstrap/cluster-resources/in-cluster/tools-ns.yaml'
INFO committing changes to gitops repo...
INFO installed application: reloader
That command creates four files on the argocd repository:
  1. One to create the tools namespace:
    bootstrap/cluster-resources/in-cluster/tools-ns.yaml
    apiVersion: v1
    kind: Namespace
    metadata:
      annotations:
        argocd.argoproj.io/sync-options: Prune=false
      creationTimestamp: null
      name: tools
    spec:  
    status:  
  2. Another to include the reloader base application from the upstream repository:
    apps/reloader/base/kustomization.yaml
    apiVersion: kustomize.config.k8s.io/v1beta1
    kind: Kustomization
    resources:
    - github.com/stakater/Reloader/deployments/kubernetes/?ref=v1.4.2
  3. The kustomization.yaml file for the test project (by default it includes the same configuration used on the base definition, but we could make other changes if needed):
    apps/reloader/overlays/test/kustomization.yaml
    apiVersion: kustomize.config.k8s.io/v1beta1
    kind: Kustomization
    namespace: tools
    resources:
    - ../../base
  4. The config.json file used to define the application on argocd for the test project (it points to the folder that includes the previous kustomization.yaml file):
    apps/reloader/overlays/test/config.json
     
      "appName": "reloader",
      "userGivenName": "reloader",
      "destNamespace": "tools",
      "destServer": "https://kubernetes.default.svc",
      "srcPath": "apps/reloader/overlays/test",
      "srcRepoURL": "https://forgejo.mixinet.net/blogops/argocd.git",
      "srcTargetRevision": "",
      "labels": null,
      "annotations": null
     
We can check that the application is working using the argocd command line application:
  argocd app get argocd/test-reloader -o tree
Name:               argocd/test-reloader
Project:            test
Server:             https://kubernetes.default.svc
Namespace:          tools
URL:                https://argocd.lo.mixinet.net:8443/applications/test-reloader
Source:
- Repo:             https://forgejo.mixinet.net/blogops/argocd.git
  Target:
  Path:             apps/reloader/overlays/test
SyncWindow:         Sync Allowed
Sync Policy:        Automated (Prune)
Sync Status:        Synced to  (2893b56)
Health Status:      Healthy
KIND/NAME                                          STATUS  HEALTH   MESSAGE
ClusterRole/reloader-reloader-role                 Synced
ClusterRoleBinding/reloader-reloader-role-binding  Synced
ServiceAccount/reloader-reloader                   Synced           serviceaccount/reloader-reloader created
Deployment/reloader-reloader                       Synced  Healthy  deployment.apps/reloader-reloader created
 ReplicaSet/reloader-reloader-5b6dcc7b6f                  Healthy
   Pod/reloader-reloader-5b6dcc7b6f-vwjcx                 Healthy

Adding flags to the reloader serverThe runtime configuration flags for the reloader server are described on the project README.md file, in our case we want to adjust three values:
  • We want to enable the option to reload a workload when a ConfigMap or Secret is created,
  • We want to enable the option to reload a workload when a ConfigMap or Secret is deleted,
  • We want to use the annotations strategy for reloads, as it is the recommended mode of operation when using argocd.
To pass them we edit the apps/reloader/overlays/test/kustomization.yaml file to patch the pod container template, the text added is the following:
patches:
# Add flags to reload workloads when ConfigMaps or Secrets are created or deleted
- target:
    kind: Deployment
    name: reloader-reloader
  patch:  -
    - op: add
      path: /spec/template/spec/containers/0/args
      value:
        - '--reload-on-create=true'
        - '--reload-on-delete=true'
        - '--reload-strategy=annotations'
After committing and pushing the updated file the system launches the application with the new options.

The dummyhttp applicationTo do a quick test we are going to deploy the dummyhttp web server using an image generated using the following Dockerfile:
# Image to run the dummyhttp application <https://github.com/svenstaro/dummyhttp>
# This arg could be passed by the container build command (used with mirrors)
ARG OCI_REGISTRY_PREFIX
# Latest tested version of alpine
FROM $ OCI_REGISTRY_PREFIX alpine:3.21.3
# Tool versions
ARG DUMMYHTTP_VERS=1.1.1
# Download binary
RUN ARCH="$(apk --print-arch)" && \
  VERS="$DUMMYHTTP_VERS" && \
  URL="https://github.com/svenstaro/dummyhttp/releases/download/v$VERS/dummyhttp-$VERS-$ARCH-unknown-linux-musl" && \
  wget "$URL" -O "/tmp/dummyhttp" && \
  install /tmp/dummyhttp /usr/local/bin && \
  rm -f /tmp/dummyhttp
# Set the entrypoint to /usr/local/bin/dummyhttp
ENTRYPOINT [ "/usr/local/bin/dummyhttp" ]
The kustomize base application is available on a monorepo that contains the following files:
  1. A Deployment definition that uses the previous image but uses /bin/sh -c as its entrypoint (command in the k8s Pod terminology) and passes as its argument a string that runs the eval command to be able to expand environment variables passed to the pod (the definition includes two optional variables, one taken from a ConfigMap and another one from a Secret):
    apiVersion: apps/v1
    kind: Deployment
    metadata:
      name: dummyhttp
      labels:
        app: dummyhttp
    spec:
      selector:
        matchLabels:
          app: dummyhttp
      template:
        metadata:
          labels:
            app: dummyhttp
        spec:
          containers:
          - name: dummyhttp
            image: forgejo.mixinet.net/oci/dummyhttp:1.0.0
            command: [ "/bin/sh", "-c" ]
            args:
            - 'eval dummyhttp -b \" \\\"c\\\": \\\"$CM_VAR\\\", \\\"s\\\": \\\"$SECRET_VAR\\\" \"'
            ports:
            - containerPort: 8080
            env:
            - name: CM_VAR
              valueFrom:
                configMapKeyRef:
                  name: dummyhttp-configmap
                  key: CM_VAR
                  optional: true
            - name: SECRET_VAR
              valueFrom:
                secretKeyRef:
                  name: dummyhttp-secret
                  key: SECRET_VAR
                  optional: true
  2. A Service that publishes the previous Deployment (the only relevant thing to mention is that the web server uses the port 8080 by default):
    apiVersion: v1
    kind: Service
    metadata:
      name: dummyhttp
    spec:
      selector:
        app: dummyhttp
      ports:
      - name: http
        port: 80
        targetPort: 8080
  3. An Ingress definition to allow access to the application from the outside:
    apiVersion: networking.k8s.io/v1
    kind: Ingress
    metadata:
      name: dummyhttp
      annotations:
        traefik.ingress.kubernetes.io/router.tls: "true"
    spec:
      rules:
        - host: dummyhttp.localhost.mixinet.net
          http:
            paths:
              - path: /
                pathType: Prefix
                backend:
                  service:
                    name: dummyhttp
                    port:
                      number: 80
  4. And the kustomization.yaml file that includes the previous files:
    apiVersion: kustomize.config.k8s.io/v1beta1
    kind: Kustomization
    resources:
    - deployment.yaml
    - service.yaml
    - ingress.yaml

Deploying the dummyhttp application from argocdWe could create the dummyhttp application using the argocd-autopilot command as we ve done on the reloader case, but we are going to do it manually to show how simple it is. First we ve created the apps/dummyhttp/base/kustomization.yaml file to include the application from the previous repository:
apiVersion: kustomize.config.k8s.io/v1beta1
kind: Kustomization
resources:
  - https://forgejo.mixinet.net/blogops/argocd-applications.git//dummyhttp/?ref=dummyhttp-v1.0.0
As a second step we create the apps/dummyhttp/overlays/test/kustomization.yaml file to include the previous file:
apiVersion: kustomize.config.k8s.io/v1beta1
kind: Kustomization
resources:
- ../../base
And finally we add the apps/dummyhttp/overlays/test/config.json file to configure the application as the ApplicationSet defined by argocd-autopilot expects:
 
  "appName": "dummyhttp",
  "userGivenName": "dummyhttp",
  "destNamespace": "default",
  "destServer": "https://kubernetes.default.svc",
  "srcPath": "apps/dummyhttp/overlays/test",
  "srcRepoURL": "https://forgejo.mixinet.net/blogops/argocd.git",
  "srcTargetRevision": "",
  "labels": null,
  "annotations": null
 
Once we have the three files we commit and push the changes and argocd deploys the application; we can check that things are working using curl:
  curl -s https://dummyhttp.lo.mixinet.net:8443/   jq -M .
 
  "c": "",
  "s": ""
 

Patching the applicationNow we will add patches to the apps/dummyhttp/overlays/test/kustomization.yaml file:
  • One to add annotations for reloader (one to enable it and another one to set the roll out strategy to restart to avoid touching the deployments, as that can generate issues with argocd).
  • Another to change the ingress hostname (not really needed, but something quite reasonable for a specific project).
The file diff is as follows:
--- a/apps/dummyhttp/overlays/test/kustomization.yaml
+++ b/apps/dummyhttp/overlays/test/kustomization.yaml
@@ -2,3 +2,22 @@ apiVersion: kustomize.config.k8s.io/v1beta1
 kind: Kustomization
 resources:
 - ../../base
+patches:
+# Add reloader annotations
+- target:
+    kind: Deployment
+    name: dummyhttp
+  patch:  -
+    - op: add
+      path: /metadata/annotations
+      value:
+        reloader.stakater.com/auto: "true"
+        reloader.stakater.com/rollout-strategy: "restart"
+# Change the ingress host name
+- target:
+    kind: Ingress
+    name: dummyhttp
+  patch:  -
+    - op: replace
+      path: /spec/rules/0/host
+      value: test-dummyhttp.lo.mixinet.net
After committing and pushing the changes we can use the argocd cli to check the status of the application:
  argocd app get argocd/test-dummyhttp -o tree
Name:               argocd/test-dummyhttp
Project:            test
Server:             https://kubernetes.default.svc
Namespace:          default
URL:                https://argocd.lo.mixinet.net:8443/applications/test-dummyhttp
Source:
- Repo:             https://forgejo.mixinet.net/blogops/argocd.git
  Target:
  Path:             apps/dummyhttp/overlays/test
SyncWindow:         Sync Allowed
Sync Policy:        Automated (Prune)
Sync Status:        Synced to  (fbc6031)
Health Status:      Healthy
KIND/NAME                           STATUS  HEALTH   MESSAGE
Deployment/dummyhttp                Synced  Healthy  deployment.apps/dummyhttp configured
 ReplicaSet/dummyhttp-55569589bc           Healthy
   Pod/dummyhttp-55569589bc-qhnfk          Healthy
Ingress/dummyhttp                   Synced  Healthy  ingress.networking.k8s.io/dummyhttp configured
Service/dummyhttp                   Synced  Healthy  service/dummyhttp unchanged
 Endpoints/dummyhttp
 EndpointSlice/dummyhttp-x57bl
As we can see, the Deployment and Ingress where updated, but the Service is unchanged. To validate that the ingress is using the new hostname we can use curl:
  curl -s https://dummyhttp.lo.mixinet.net:8443/
404 page not found
  curl -s https://test-dummyhttp.lo.mixinet.net:8443/
 "c": "", "s": "" 

Adding a ConfigMapNow that the system is adjusted to reload the application when the ConfigMap or Secret is created, deleted or updated we are ready to add one file and see how the system reacts. We modify the apps/dummyhttp/overlays/test/kustomization.yaml file to create the ConfigMap using the configMapGenerator as follows:
--- a/apps/dummyhttp/overlays/test/kustomization.yaml
+++ b/apps/dummyhttp/overlays/test/kustomization.yaml
@@ -2,6 +2,14 @@ apiVersion: kustomize.config.k8s.io/v1beta1
 kind: Kustomization
 resources:
 - ../../base
+# Add the config map
+configMapGenerator:
+- name: dummyhttp-configmap
+  literals:
+  - CM_VAR="Default Test Value"
+  behavior: create
+  options:
+    disableNameSuffixHash: true
 patches:
 # Add reloader annotations
 - target:
After committing and pushing the changes we can see that the ConfigMap is available, the pod has been deleted and started again and the curl output includes the new value:
  kubectl get configmaps,pods
NAME                             READY   STATUS        RESTARTS   AGE
configmap/dummyhttp-configmap   1      11s
configmap/kube-root-ca.crt      1      4d7h
NAME                            DATA   AGE
pod/dummyhttp-779c96c44b-pjq4d   1/1     Running       0          11s
pod/dummyhttp-fc964557f-jvpkx    1/1     Terminating   0          2m42s
  curl -s https://test-dummyhttp.lo.mixinet.net:8443   jq -M .
 
  "c": "Default Test Value",
  "s": ""
 

Using helm with argocd-autopilotRight now there is no direct support in argocd-autopilot to manage applications using helm (see the issue #38 on the project), but we want to use a chart in our next example. There are multiple ways to add the support, but the simplest one that allows us to keep using argocd-autopilot is to use kustomize applications that call helm as described here. The only thing needed before being able to use the approach is to add the kustomize.buildOptions flag to the argocd-cm on the bootstrap/argo-cd/kustomization.yaml file, its contents now are follows:
bootstrap/argo-cd/kustomization.yaml
apiVersion: kustomize.config.k8s.io/v1beta1
configMapGenerator:
- behavior: merge
  literals:
  # Enable helm usage from kustomize (see https://github.com/argoproj/argo-cd/issues/2789#issuecomment-960271294)
  - kustomize.buildOptions="--enable-helm"
  -  
    repository.credentials=- passwordSecret:
        key: git_token
        name: autopilot-secret
      url: https://forgejo.mixinet.net/
      usernameSecret:
        key: git_username
        name: autopilot-secret
  name: argocd-cm
  # Disable TLS for the Argo Server (see https://argo-cd.readthedocs.io/en/stable/operator-manual/ingress/#traefik-v30)
- behavior: merge
  literals:
  - "server.insecure=true"
  name: argocd-cmd-params-cm
kind: Kustomization
namespace: argocd
resources:
- github.com/argoproj-labs/argocd-autopilot/manifests/base?ref=v0.4.19
- ingress_route.yaml
On the following section we will explain how the application is defined to make things work.

Installing the sealed-secrets controllerTo manage secrets in our cluster we are going to use the sealed-secrets controller and to install it we are going to use its chart. As we mentioned on the previous section, the idea is to create a kustomize application and use that to deploy the chart, but we are going to create the files manually, as we are not going import the base kustomization files from a remote repository. As there is no clear way to override helm Chart values using overlays we are going to use a generator to create the helm configuration from an external resource and include it from our overlays (the idea has been taken from this repository, which was referenced from a comment on the kustomize issue #38 mentioned earlier).

The sealed-secrets applicationWe have created the following files and folders manually:
apps/sealed-secrets/
  helm
    chart.yaml
    kustomization.yaml
  overlays
      test
          config.json
          kustomization.yaml
          values.yaml
The helm folder contains the generator template that will be included from our overlays. The kustomization.yaml includes the chart.yaml as a resource:
apps/sealed-secrets/helm/kustomization.yaml
apiVersion: kustomize.config.k8s.io/v1beta1
kind: Kustomization
resources:
- chart.yaml
And the chart.yaml file defines the HelmChartInflationGenerator:
apps/sealed-secrets/helm/chart.yaml
apiVersion: builtin
kind: HelmChartInflationGenerator
metadata:
  name: sealed-secrets
releaseName: sealed-secrets
name: sealed-secrets
namespace: kube-system
repo: https://bitnami-labs.github.io/sealed-secrets
version: 2.17.2
includeCRDs: true
# Add common values to all argo-cd projects inline
valuesInline:
  fullnameOverride: sealed-secrets-controller
# Load a values.yaml file from the same directory that uses this generator
valuesFile: values.yaml
For this chart the template adjusts the namespace to kube-system and adds the fullnameOverride on the valuesInline key because we want to use those settings on all the projects (they are the values expected by the kubeseal command line application, so we adjust them to avoid the need to add additional parameters to it). We adjust global values as inline to be able to use a the valuesFile from our overlays; as we are using a generator the path is relative to the folder that contains the kustomization.yaml file that calls it, in our case we will need to have a values.yaml file on each overlay folder (if we don t want to overwrite any values for a project we can create an empty file, but it has to exist). Finally, our overlay folder contains three files, a kustomization.yaml file that includes the generator from the helm folder, the values.yaml file needed by the chart and the config.json file used by argocd-autopilot to install the application. The kustomization.yaml file contents are:
apps/sealed-secrets/overlays/test/kustomization.yaml
apiVersion: kustomize.config.k8s.io/v1beta1
kind: Kustomization
# Uncomment if you want to add additional resources using kustomize
#resources:
#- ../../base
generators:
- ../../helm
The values.yaml file enables the ingress for the application and adjusts its hostname:
apps/sealed-secrets/overlays/test/values.yaml
ingress:
  enabled: true
  hostname: test-sealed-secrets.lo.mixinet.net
And the config.json file is similar to the ones used with the other applications we have installed:
apps/sealed-secrets/overlays/test/config.json
 
  "appName": "sealed-secrets",
  "userGivenName": "sealed-secrets",
  "destNamespace": "kube-system",
  "destServer": "https://kubernetes.default.svc",
  "srcPath": "apps/sealed-secrets/overlays/test",
  "srcRepoURL": "https://forgejo.mixinet.net/blogops/argocd.git",
  "srcTargetRevision": "",
  "labels": null,
  "annotations": null
 
Once we commit and push the files the sealed-secrets application is installed in our cluster, we can check it using curl to get the public certificate used by it:
  curl -s https://test-sealed-secrets.lo.mixinet.net:8443/v1/cert.pem
-----BEGIN CERTIFICATE-----
[...]
-----END CERTIFICATE-----

The dummyhttp-secretTo create sealed secrets we need to install the kubeseal tool:
  arkade get kubeseal
Now we create a local version of the dummyhttp-secret that contains some value on the SECRET_VAR key (the easiest way for doing it is to use kubectl):
  echo -n "Boo"   kubectl create secret generic dummyhttp-secret \
    --dry-run=client --from-file=SECRET_VAR=/dev/stdin -o yaml \
    >/tmp/dummyhttp-secret.yaml
The secret definition in yaml format is:
apiVersion: v1
data:
  SECRET_VAR: Qm9v
kind: Secret
metadata:
  creationTimestamp: null
  name: dummyhttp-secret
To create a sealed version using the kubeseal tool we can do the following:
  kubeseal -f /tmp/dummyhttp-secret.yaml -w /tmp/dummyhttp-sealed-secret.yaml
That invocation needs to have access to the cluster to do its job and in our case it works because we modified the chart to use the kube-system namespace and set the controller name to sealed-secrets-controller as the tool expects. If we need to create the secrets without credentials we can connect to the ingress address we added to retrieve the public key:
  kubeseal -f /tmp/dummyhttp-secret.yaml -w /tmp/dummyhttp-sealed-secret.yaml \
    --cert https://test-sealed-secrets.lo.mixinet.net:8443/v1/cert.pem
Or, if we don t have access to the ingress address, we can save the certificate on a file and use it instead of the URL. The sealed version of the secret looks like this:
apiVersion: bitnami.com/v1alpha1
kind: SealedSecret
metadata:
  creationTimestamp: null
  name: dummyhttp-secret
  namespace: default
spec:
  encryptedData:
    SECRET_VAR: [...]
  template:
    metadata:
      creationTimestamp: null
      name: dummyhttp-secret
      namespace: default
This file can be deployed to the cluster to create the secret (in our case we will add it to the argocd application), but before doing that we are going to check the output of our dummyhttp service and get the list of Secrets and SealedSecrets in the default namespace:
  curl -s https://test-dummyhttp.lo.mixinet.net:8443   jq -M .
 
  "c": "Default Test Value",
  "s": ""
 
  kubectl get sealedsecrets,secrets
No resources found in default namespace.
Now we add the SealedSecret to the dummyapp copying the file and adding it to the kustomization.yaml file:
--- a/apps/dummyhttp/overlays/test/kustomization.yaml
+++ b/apps/dummyhttp/overlays/test/kustomization.yaml
@@ -2,6 +2,7 @@ apiVersion: kustomize.config.k8s.io/v1beta1
 kind: Kustomization
 resources:
 - ../../base
+- dummyhttp-sealed-secret.yaml
 # Create the config map value
 configMapGenerator:
 - name: dummyhttp-configmap
Once we commit and push the files Argo CD creates the SealedSecret and the controller generates the Secret:
  kubectl apply -f /tmp/dummyhttp-sealed-secret.yaml
sealedsecret.bitnami.com/dummyhttp-secret created
  kubectl get sealedsecrets,secrets
NAME                                        STATUS   SYNCED   AGE
sealedsecret.bitnami.com/dummyhttp-secret            True     3s
NAME                      TYPE     DATA   AGE
secret/dummyhttp-secret   Opaque   1      3s
If we check the command output we can see the new value of the secret:
  curl -s https://test-dummyhttp.lo.mixinet.net:8443   jq -M .
 
  "c": "Default Test Value",
  "s": "Boo"
 

Using sealed-secrets in production clustersIf you plan to use sealed-secrets look into its documentation to understand how it manages the private keys, how to backup things and keep in mind that, as the documentation explains, you can rotate your sealed version of the secrets, but that doesn t change the actual secrets. If you want to rotate your secrets you have to update them and commit the sealed version of the updates (as the controller also rotates the encryption keys your new sealed version will also be using a newer key, so you will be doing both things at the same time).

Final remarksOn this post we have seen how to deploy applications using the argocd-autopilot model, including the use of helm charts inside kustomize applications and how to install and use the sealed-secrets controller. It has been interesting and I ve learnt a lot about argocd in the process, but I believe that if I ever want to use it in production I will also review the native helm support in argocd using a separate repository to manage the applications, at least to be able to compare it to the model explained here.

4 May 2025

Dirk Eddelbuettel: #47: r2u at its Third Birthday

Welcome to post 47 in the $R^4 series! r2u provides Ubuntu binaries for all CRAN packages for the R system. It started three years ago, and offers for Linux users on Ubuntu what windows and macOS users already experience: fast, easy and reliable installation of binary packages. But by integrating with the system package manager (which is something that cannot be done on those other operating systems) we can fully and completely integrate it with underlying system. External libraries are resolved as shared libraries and handled by the system package manager. This offers fully automatic installation both at the initial installation and all subsequent upgrades. R users just say, e.g., install.packages("sf") and spatial libraries proj, gdal, geotiff (as well as several others) are automatically installed as dependencies in the correct versions. And they remain installed along with sf as the system manager now knows of the dependency. Work on r2u began as a quick weekend experiment in March 2022, and by May 4 a first release was marked in the NEWS file after a few brave alpha testers kicked tires quite happily. This makes today the third anniversary of that first release, and marks a good time to review where we are. This short post does this, and stresses three aspects: overall usage, current versions, and new developments.

Steadily Growing Usage at 42 Million Packages Shipped r2u ships from two sites. Its main repository is at the University of Illinois campus providing ample and heavily redundant bandwidth. We remain very grateful for the sponsorship from Atlas. It also still ships from my own server though that may be discontinued or could be spotty as it is on retail fiber connectivity. As we have access to the both sets of server logs, we can tabulate and chart usage. As of yesterday, total downloads were north of 42 million with current weekly averages around 500 thousand. These are quite staggering numbers for what started as a small hobby project, and are quite humbling. Usage is driven by deployment in continuous integration (as for example the Ubuntu-use at GitHub makes this both an easy and obvious choice), cloud computing (as it is easy to spin up Ubuntu instances, it is as easy to add r2u via four simple commands or one short script), explorative use (for example on Google Colab) or of course in general laptop, desktop, or server settings.

Current Versions Since r2u began, we added two Ubuntu LTS releases, three annual R releases as well as multiple BioConductor releases. BioConductor support is on a best-efforts basis motivated primarily to support the CRAN packages having dependencies. It has grown to around 500 packages and includes the top-250 by usage. Right now, current versions R 4.5.0 and BioConductor 3.21, both released last month, are supported.

New Development: arm64 A recent change is the support of the arm64 platform. As discussed in the introductory post, it is a popular and increasingly common CPU choice seen anywhere from the Raspberry Pi 5 and it Cortex CPU to in-house cloud computing platforms (called, respectively, Graviton at AWS and Axiom at GCS), general server use via Ampere CPUs, Cortex-based laptops that start to appears and last but not least on the popular M1 to M4-based macOS machines. (For macOS, one key appeal is in use of lighterweight Docker use as these M1 to M4 cpus can run arm64-based containers without a translation layer making it an attractive choice.) This is currently supported only for the noble aka 24.04 release. GitHub Actions, where we compile these packages, now also supports jammy aka 22.04 but it may not be worth it to expand there as the current latest release is available. We have not yet added BioConductor support but may do so. Drop us a line (maybe via an issue) if this of interest. With the provision of arm64 binaries, we also started to make heavier use of GitHub Actions. The BioConductor 3.21 release binaries were also created there. This makes the provision more transparent as well as the configuration repo as well as the two builder repos (arm64, bioc) are public, as is of course the main r2u repo.

Summing Up This short post summarised the current state of r2u along with some recent news. If you are curious, head over to the r2u site and try it, for example in a rocker/r2u container.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. If you like this or other open-source work I do, you can now sponsor me at GitHub.

Next.

Previous.