Search Results: "ana"

12 July 2025

Reproducible Builds: Reproducible Builds in June 2025
Welcome to the 6th report from the Reproducible Builds project in 2025. Our monthly reports outline what we ve been up to over the past month, and highlight items of news from elsewhere in the increasingly-important area of software supply-chain security. If you are interested in contributing to the Reproducible Builds project, please see the Contribute page on our website. In this report:
  1. Reproducible Builds at FOSSY 2025
  2. Distribution work
  3. diffoscope
  4. OSS Rebuild updates
  5. Website updates
  6. Upstream patches
  7. Reproducibility testing framework

Reproducible Builds at FOSSY 2025 On Saturday 2nd August, Vagrant Cascadian and Chris Lamb will be presenting at this year s FOSSY 2025. Their talk, titled Never Mind the Checkboxes, Here s Reproducible Builds!, is being introduced as follows:
There are numerous policy compliance and regulatory processes being developed that target software development but do they solve actual problems? Does it improve the quality of software? Do Software Bill of Materials (SBOMs) actually give you the information necessary to verify how a given software artifact was built? What is the goal of all these compliance checklists anyways or more importantly, what should the goals be? If a software object is signed, who should be trusted to sign it, and can they be trusted forever?
The talk will introduce the audience to Reproducible Builds as a set of best practices which allow users and developers to verify that software artifacts were built from the source code, but also allows auditing for license compliance, providing security benefits, and removes the need to trust arbitrary software vendors. Hosted by the Software Freedom Conservancy and taking place in Portland, Oregon, USA, FOSSY aims to be a community-focused event: Whether you are a long time contributing member of a free software project, a recent graduate of a coding bootcamp or university, or just have an interest in the possibilities that free and open source software bring, FOSSY will have something for you . More information on the event is available on the FOSSY 2025 website, including the full programme schedule. Vagrant and Chris will also be staffing a table this year, where they will be available to answer any questions about Reproducible Builds and discuss collaborations with other projects.

Distribution work In Debian this month:
  • Holger Levsen has discovered that it is now possible to bootstrap a minimal Debian trixie using 100% reproducible packages. This result can itself be reproduced, using the debian-repro-status tool and mmdebstrap s support for hooks:
      $ mmdebstrap --variant=apt --include=debian-repro-status \
           --chrooted-customize-hook=debian-repro-status \
           trixie /dev/null 2>&1   grep "Your system has"
       INFO  debian-repro-status > Your system has 100.00% been reproduced.
    
  • On our mailing list this month, Helmut Grohne wrote an extensive message raising an issue related to Uploads with conflicting buildinfo filenames:
    Having several .buildinfo files for the same architecture is something that we plausibly want to have eventually. Imagine running two sets of buildds and assembling a single upload containing buildinfo files from both buildds in the same upload. In a similar vein, as a developer I may want to supply several .buildinfo files with my source upload (e.g. for multiple architectures). Doing any of this is incompatible with current incoming processing and with reprepro.
  • 5 reviews of Debian packages were added, 4 were updated and 8 were removed this month adding to our ever-growing knowledge about identified issues.

In GNU Guix, Timothee Mathieu reported that a long-standing issue with reproducibility of shell containers across different host operating systems has been solved. In their message, Timothee mentions:
I discovered that pytorch (and maybe other dependencies) has a reproducibility problem of order 1e-5 when on AVX512 compared to AVX2. I first tried to solve the problem by disabling AVX512 at the level of pytorch, but it did not work. The dev of pytorch said that it may be because some components dispatch computation to MKL-DNN, I tried to disable AVX512 on MKL, and still the results were not reproducible, I also tried to deactivate in openmpi without success. I finally concluded that there was a problem with AVX512 somewhere in the dependencies graph but I gave up identifying where, as this seems very complicated.

The IzzyOnDroid Android APK repository made more progress in June. Not only have they just passed 48% reproducibility coverage, Ben started making their reproducible builds more visible, by offering rbtlog shields, a kind of badge that has been quickly picked up by many developers who are proud to present their applications reproducibility status.
Lastly, in openSUSE news, Bernhard M. Wiedemann posted another monthly update for their work there.

diffoscope diffoscope is our in-depth and content-aware diff utility that can locate and diagnose reproducibility issues. This month, Chris Lamb made the following changes, including preparing and uploading versions 298, 299 and 300 to Debian:
  • Add python3-defusedxml to the Build-Depends in order to include it in the Docker image. [ ]
  • Handle the RPM format s HEADERSIGNATURES and HEADERIMMUTABLE as a special-case to avoid unnecessarily large diffs. Thanks to Daniel Duan for the report and suggestion. [ ][ ]
  • Update copyright years. [ ]
In addition, @puer-robustus fixed a regression introduced in an earlier commit which resulted in some differences being lost. [ ][ ] Lastly, Vagrant Cascadian updated diffoscope in GNU Guix to version 299 [ ][ ] and 300 [ ][ ].

OSS Rebuild updates OSS Rebuild has added a new network analyzer that provides transparent HTTP(S) interception during builds, capturing all network traffic to monitor external dependencies and identify suspicious behavior, even in unmodified maintainer-controlled build processes. The text-based user interface now features automated failure clustering that can group similar rebuild failures and provides natural language failure summaries, making it easier to identify and understand patterns across large numbers of build failures. OSS Rebuild has also improved the local development experience with a unified interface for build execution strategies, allowing for more extensible environment setup for build execution. The team also designed a new website and logo.
Website updates Once again, there were a number of improvements made to our website this month including:
  • Arnaud Brousseau added Stage , a new Linux distribution, to our Tools page.
  • Chris Lamb improved the docker instructions on the diffoscope website. [ ]


Upstream patches The Reproducible Builds project detects, dissects and attempts to fix as many currently-unreproducible packages as possible. We endeavour to send all of our patches upstream where appropriate. This month, we wrote a large number of such patches, including:

Reproducibility testing framework The Reproducible Builds project operates a comprehensive testing framework running primarily at tests.reproducible-builds.org in order to check packages and other artifacts for reproducibility. In June, however, a number of changes were made by Holger Levsen, including:
  • reproduce.debian.net-related:
    • Installed and deployed rebuilderd version 0.24 from Debian unstable in order to make use of the new compression feature added by Jarl Gullberg for the database. This resulted in massive decrease of the SQLite databases:
      • 79G 2.8G (all)
      • 84G 3.2G (amd64)
      • 75G 2.9G (arm64)
      • 45G 2.1G (armel)
      • 48G 2.2G (armhf)
      • 73G 2.8G (i386)
      • 72G 2.7G (ppc64el)
      • 45G 2.1G (riscv64)
      for a combined saving from 521G 20.8G. This naturally reduces the requirements to run an independent rebuilderd instance and will permit us to add more Debian suites as well.
    • During migration to the latest version of rebuilderd, make sure several services are not started. [ ]
    • Actually run rebuilderd from /usr/bin. [ ]
    • Raise temperatures for NVME devices on some riscv64 nodes that should be ignored. [ ][ ]
    • Use a 64KB kernel page size on the ppc64el architecture (see #1106757). [ ]
    • Improve ordering of some failed to reproduce statistics. [ ]
    • Detect a number of potential causes of build failures within the statistics. [ ][ ]
    • Add support for manually scheduling for the any architecture. [ ]
  • Misc:
    • Update the Codethink nodes as there are now many kernels installed. [ ][ ]
    • Install linux-sysctl-defaults on Debian trixie systems as we need ping functionality. [ ]
    • Limit the fs.nr_open kernel turnable. [ ]
    • Stop submitting results to deprecated buildinfo.debian.net service. [ ][ ]
In addition, Jochen Sprickerhof greatly improved the statistics and the logging functionality, including adopting to the new database format of rebuilderd version 0.24.0 [ ] and temporarily increasing maximum log size in order to debug a nettlesome build [ ]. Jochen also dropped the CPUSchedulingPolicy=idle systemd flag on the workers. [ ]

Finally, if you are interested in contributing to the Reproducible Builds project, please visit our Contribute page on our website. However, you can get in touch with us via:

Louis-Philippe V ronneau: Adulting

In the last past weeks, I have done something I had been meaning to do for a while but always pushed back at the bottom of my TODO pile: prepare for my death. I am still quite young and perfectly healthy (mentally and physically) and I do plan to live a long and full life, but death is something that comes from us all and can strike anytime. Having witnessed friends and colleagues who lost loved ones who did not prepare adequately for their passing, dealing with all this legal stuff ahead of time seems like the best gift you can leave them. Writing my will was the easiest part of this "preparation for death" process. I have few material possessions and I'm leaving everything to my SO. As for the copyright for my code, I have decided everything I wrote will be licensed under CC0 (public domain) when I die. Quebec where I live also accepts holograph wills, which means I didn't have to hire a notary. Apart from the will, I also wrote a protection mandate1, filled out Quebec's organ donation form2, took a contract for prearranged funeral services3 and finally, wrote a disaster recovery plan. This recovery plan was by far the longest and most tedious part of this entire ordeal. If all your machines use full-disk encryption and you die or forget your passwords (for example after a head injury), can your data be recovered? How do you arbitrate between easy recovery and data security? If all your local devices burn down and you also pass away in the process, how will your next of kin access your remote backups and extract the relevant data (in my case, my password manager)? I had to ask myself many complex questions in this process and although I won't be sharing my disaster recovery plan here (security through obscurity), I urge you to take the time to do something similar yourself and make sure you will leave a house in order when you go away.

  1. in case I become incapacitated and can't make choices by myself anymore.
  2. it's sadly still opt-in here...
  3. you pay now for the services you want, the money is kept in a trust in your name and you can't be charged extra when you do pass away. This protects you from inflation and is a great way to make sure your next of kin don't have to deal with the complexities of funeral services while grieving.

Freexian Collaborators: Monthly report about Debian Long Term Support, June 2025 (by Roberto C. S nchez)

Like each month, have a look at the work funded by Freexian s Debian LTS offering.

Debian LTS contributors In June, 20 contributors have been paid to work on Debian LTS, their reports are available:
  • Abhijith PA did 14.0h (out of 14.0h assigned).
  • Adrian Bunk did 23.5h (out of 23.5h assigned).
  • Andreas Henriksson did 3.0h (out of 3.0h assigned and 17.0h from previous period), thus carrying over 17.0h to the next month.
  • Andrej Shadura did 2.0h (out of 3.0h assigned and 7.0h from previous period), thus carrying over 8.0h to the next month.
  • Bastien Roucari s did 20.0h (out of 20.0h assigned).
  • Ben Hutchings did 8.0h (out of 7.5h assigned and 16.0h from previous period), thus carrying over 15.5h to the next month.
  • Carlos Henrique Lima Melara did 12.0h (out of 12.0h assigned).
  • Chris Lamb did 18.0h (out of 18.0h assigned).
  • Daniel Leidert did 22.0h (out of 22.5h assigned and 1.0h from previous period), thus carrying over 1.5h to the next month.
  • Emilio Pozuelo Monfort did 23.5h (out of 16.75h assigned and 6.75h from previous period).
  • Guilhem Moulin did 14.0h (out of 11.5h assigned and 3.5h from previous period), thus carrying over 1.0h to the next month.
  • Jochen Sprickerhof did 21.0h (out of 0.5h assigned and 22.75h from previous period), thus carrying over 2.25h to the next month.
  • Lucas Kanashiro did 20.0h (out of 20.0h assigned).
  • Markus Koschany did 23.25h (out of 17.0h assigned and 6.25h from previous period).
  • Roberto C. S nchez did 21.25h (out of 20.75h assigned and 3.25h from previous period), thus carrying over 2.75h to the next month.
  • Santiago Ruano Rinc n did 12.75h (out of 15.0h assigned), thus carrying over 2.25h to the next month.
  • Sean Whitton did 1.0h (out of 4.25h assigned and 1.75h from previous period), thus carrying over 5.0h to the next month.
  • Sylvain Beucler did 23.5h (out of 23.5h assigned).
  • Thorsten Alteholz did 15.0h (out of 15.0h assigned).
  • Tobias Frost did 2.5h (out of 12.0h assigned), thus carrying over 9.5h to the next month.

Evolution of the situation In June, we released 35 DLAs.
  • Notable security updates:
    • mariadb-10.5, prepared by Otto Kek l inen, fixes vulnerabilities which could result in denial of service, information disclosure, or unauthorized data modification
    • python-django, prepared by Chris Lamb, fixes vulnerabilities which would result in log injection or denial of service
    • webkit2gtk, prepared by Emilio Pozuelo Monfort, fixes many vulnerabilities which could results in a wide range of issues
    • xorg-server, prepared by Emilio Pozuelo Monfort, fixes multiple vulnerabilities which may result in privilege escalation
    • sudo, prepared by Thorsten Alteholz, fixes a vulnerability which could result in privilege escalation
  • Notable non-security updates:
    • debian-security-support, prepared by Santiago Ruano Rinc n, updates status of packages which receive limited security support or which have reached the end of security support
    • dns-root-data, prepared by Sylvain Beucler, updates the DNSSEC trust anchors
This month s contributions from outside the regular team include the mariadb-10.5 update mentioned above, prepared by Otto Kek l inen (the package maintainer); an update to libfile-find-rule-perl, prepared by Salvatore Bonaccorso (a member of the Debian Security Team); an update to activemq, prepared by Emmanuel Arias (a maintainer of the package). Additionally, LTS Team members contributed stable updates of the following packages:
  • curl, prepared by Carlos Henrique Lima Melara
  • python-tornado, prepared by Daniel Leidert
  • python-flask-cors, prepared by Daniel Leidert
  • common-vfs, prepared by Daniel Leidert
  • cjson, prepared by Adrian Bunk
  • icu, prepared by Adrian Bunk
  • node-tar-fs, prepared by Adrian Bunk
  • rar, prepared by Adrian Bunk
Something of particular noteworthiness is that LTS contributor Carlos Henrique Lima Melara discovered a regression in the upstream fix for CVE-2023-2753 in curl. The corrective action which he took included providing a patch to upstream, uploading a stable update of curl, and further updating the version of curl in LTS. DebConf, the annual Debian Conference, is coming up in July and, as is customary each year, the week preceding the conference will feature an event called DebCamp. The DebCamp week provides an opportunity for teams and other interested groups/individuals to meet together in person in the same venue as the conference itself, with the purpose of doing focused work, often called sprints . LTS coordinator Roberto C. S nchez has announced that the LTS Team is planning to hold a sprint primarily focused on the Debian security tracker and the associated tooling used by the LTS Team and the Debian Security Team.

Thanks to our sponsors Sponsors that joined recently are in bold.

Freexian Collaborators: Debian Contributions: unschroot, DebConf 25 preparations and more! (by Anupa Ann Joseph)

Debian Contributions: 2025-06 Contributing to Debian is part of Freexian s mission. This article covers the latest achievements of Freexian and their collaborators. All of this is made possible by organizations subscribing to our Long Term Support contracts and consulting services.

unschroot, by Helmut Grohne Quite a while back, the sbuild maintainers added the unshare backend to enable better isolation of builds, but in doing so sbuild now effectively bundles a container runtime. unschroot is an attempt to separate containment from sbuild by implementing the same features and more in a schroot-compatible way. Last year, vague feature parity was achieved, but going beyond required changing the model from keeping state in the filesystem to keeping Linux namespaces as session state. A proof of concept is now available. While it still has sharp corners, it enables building packages on a squashfs with an overlayfs or id-mapped bind mounting of your ccache neither of which is possible with sbuild s unshare backend. There shall be a DebConf25 presentation about this work.

DebConf 25, by Stefano Rivera, Santiago Ruano Rinc n and Lucas Kanashiro DebConf 25 is now under way in Brest, France. Santiago is part of the local team running the event, and Stefano Rivera is part of the DebConf committee, supporting the event, as well as the video team. Both have spent considerable time in the last month, getting things ready for DebConf. Lucas Kanashiro built the schedule for DebConf 25. Also followed-up on multiple requests from speakers and stakeholders.

Miscellaneous contributions
  • Carles did general maintenance on simplemonitor, qnetload and qdacco packages; provided simplemonitor upstream feedback on new feature.
  • Carles s updates about po-debconf-manager: prepared for DebCamp/DebConf, used it for reviewing and merging different packages. Also fixed multispeech po-debconf templates.
  • Colin Watson found a crash in pterm (PuTTY s terminal emulator) when running in a Wayland session, and backported the resulting upstream fix to trixie.
  • Colin responded to an upstream groff bug report about URLs being dropped from PDF output in some cases on Debian, and backported the fix to trixie.
  • Helmut dealt with issues related to /usr-move. Most prominently Christian Hofstaedler reported an upgrade failure. /usr-move is a contributing factor here as that s what caused systemd to upgrade a number of Breaks and Replaces to Conflicts. dumat needed some help with dropping mips64el from testing and Theodore Ts o forwarded a fuse2fs upgrade failure.
  • Helmut sent patches for 25 cross build failures.
  • Helmut debugged rebootstrap failures and worked around build failures related to gcc-15 when they had patches and sent ones otherwise.
  • Thorsten Alteholz uploaded cups to fix a FTBFS-bug. This bug was introduced by a change in systemd, which bumped the maximum number of open files. This resulted in a longer test duration that triggered a timeout so that the build failed. Thorsten also uploaded mtink and lprng, which got new translation files.
  • Lucas Kanashiro followed-up on multiple unblock requests for ruby packages due to reproducible builds fixes. All of them were accepted into trixie.
  • Lucas Kanashiro discussed license issues with upstream involving Redis 8 new license and the possibility of backporting patches to old versions with a different license. Outcome is that upstream is adding a new paragraph to their license to allow the backport for security fixes.
  • Lucas Kanashiro fixed multiple CVEs reported against valkey in unstable and trixie.
  • Lucas Kanashiro gave a Debian packaging course of 8 hours for students at a free software development course at the University of Sao Paulo.
  • Lucas Kanashiro fixed a couple of cross building issues in the ruby ecosystem with Helmut s help.
  • Lucas Kanashiro is working on a debci fix for #1107645 (ongoing).
  • Stefano Rivera updated python-mitogen to the latest beta releases with upstream support for Ansible 12.
  • Stefano Rivera spent some time winding up DebConf 24 books.
  • Stefano Rivera fixed packages that were blocking cPython 3.13.5 from migrating to trixie, and filed an unblock request.
  • Stefano Rivera investigated a regression in cPython 3.13 that was breaking OpenStack Nova. There is a patch in progress for cPython, but it is not ready for use, yet.
  • Santiago reviewed different MRs in Salsa CI. For example, the MR !605 proposed by Aquila that aims to introduce a new debdiff job, as well as the autopkgtest MR !33 to extend the support to architectures other than amd64. Also reviewed MR !611 by Aayush Raj that fixes the autopkgtest images cleanup. And the MR !614, prepared by Charles, to change the suffix name used to bump the version used in the pipeline.
  • Anupa procured supplies needed for the DebConf ID tag for the DebConf registration team and co-ordinated its transport to the venue.
  • Anupa joined Nattie to complete the registration team tasks.

10 July 2025

Tianon Gravi: Yubi Whati? (YubiKeys, ECDSA, and X.509)

Off-and-on over the last several weeks, I've been spending time trying to learn/understand YubiKeys better, especially from the perspective of ECDSA and signing. I had a good mental model for how "slots" work (canonically referenced by their hexadecimal names such as 9C), but found that it had a gap related to "objects"; while closing that, I was annoyed that the main reference table for this gap lives primarily in either a PDF or inside several implementations, so I figured I should create the reference I want to see in the world, but that it would also be useful to write down some of my understanding for my own (and maybe others') future reference. So, to that end, I'm going to start with a bit ( ) of background information, with the heavy caveat that this only applies to "PIV" ("FIPS 201") usage of YubiKeys, and that I only actually care about ECDSA, although I've been reassured that it's the same for at least RSA (anything outside this is firmly Here Be Not Tianon; "gl hf dd"). (Incidentally, learning all this helped me actually appreciate the simplicity of cloud-based KMS solutions, which was an unexpected side effect. ) At a really high level, ECDSA is like many other (asymmetric) cryptographic solutions you've got a public key and a private key, the private key can be used to "sign" data (tiny amounts of data, in fact, like P-256 can only reasonably sign 256 bits of data, which is where cryptographic hashes like SHA256 come in as secure analogues for larger data in small bit sizes), and the public key can then be used to verify that the data was indeed signed by the private key, and only someone with the private key could've done so. There's some complex math and RNGs involved, but none of that's actually relevant to this post, so find that information elsewhere. Unfortunately, this is where things go off the rails: PIV is X.509 ("x509") heavy, and there's no X.509 in the na ve view of my use case. In a YubiKey (or any other PIV-signing-supporting smart card? do they actually have competitors in this specific niche? ), a given "slot" can hold one single private key. There are ~24 slots which can hold a private key and be used for signing, although "Slot 9c" is officially designated as the "Digital Signature" slot and is encouraged for signing purposes. One of the biggest gotchas is that with pure-PIV (and older YubiKey firmware ) the public key for a given slot is only available at the time the key is generated, and the whole point of the device in the first place is that the private key is never, ever available from it (all cryptographic operations happen inside the device), so if you don't save that public key when you first ask the device to generate a private key in a particular slot, the public key is lost forever (asterisk).
$ # generate a new ECDSA P-256 key in "slot 9c" ("Digital Signature")
$ # WARNING: THIS WILL GLEEFULLY WIPE SLOT 9C WITHOUT PROMPTING
$ yubico-piv-tool --slot 9c --algorithm ECCP256 --action generate
-----BEGIN PUBLIC KEY-----
MFkwEwYHKoZIzj0CAQYIKoZIzj0DAQcDQgAEtGoWRGyjjUlJFXpu8BL6Rnx8jjKR
5+Mzl2Vepgor+k7N9q7ppOtSMWefjFVR0SEPmXqXINNsCi6LpLtNEigIRg==
-----END PUBLIC KEY-----
Successfully generated a new private key.
$ # this is the only time/place we (officially) get this public key
With that background, now let's get to the second aspect of "slots" and how X.509 fits. For every aforementioned slot, there is a corresponding "object" (read: place to store arbitrary data) which is corresponding only by convention. For all these "key" slots the (again, by convention) corresponding "object" is explicitly supposed to be an X.509 certificate (see also the PDF reference linked above). It turns out this is a useful and topical place to store that public key we need to keep handy! It's also an interesting place to shove additional details about what the key in a given slot is being used for, if that's your thing. Converting the raw public key into a (likely self-signed) X.509 certificate is an exercise for the reader, but if you want to follow the conventions, you need some way to convert a given "slot" to the corresponding "object", and that is the lookup table I wish existed in more forms. So, without further ado, here is the anti-climax:
Slot Object Description
0x9A 0x5FC105 X.509 Certificate for PIV Authentication
0x9E 0x5FC101 X.509 Certificate for Card Authentication
0x9C 0x5FC10A X.509 Certificate for Digital Signature
0x9D 0x5FC10B X.509 Certificate for Key Management
0x82 0x5FC10D Retired X.509 Certificate for Key Management 1
0x83 0x5FC10E Retired X.509 Certificate for Key Management 2
0x84 0x5FC10F Retired X.509 Certificate for Key Management 3
0x85 0x5FC110 Retired X.509 Certificate for Key Management 4
0x86 0x5FC111 Retired X.509 Certificate for Key Management 5
0x87 0x5FC112 Retired X.509 Certificate for Key Management 6
0x88 0x5FC113 Retired X.509 Certificate for Key Management 7
0x89 0x5FC114 Retired X.509 Certificate for Key Management 8
0x8A 0x5FC115 Retired X.509 Certificate for Key Management 9
0x8B 0x5FC116 Retired X.509 Certificate for Key Management 10
0x8C 0x5FC117 Retired X.509 Certificate for Key Management 11
0x8D 0x5FC118 Retired X.509 Certificate for Key Management 12
0x8E 0x5FC119 Retired X.509 Certificate for Key Management 13
0x8F 0x5FC11A Retired X.509 Certificate for Key Management 14
0x90 0x5FC11B Retired X.509 Certificate for Key Management 15
0x91 0x5FC11C Retired X.509 Certificate for Key Management 16
0x92 0x5FC11D Retired X.509 Certificate for Key Management 17
0x93 0x5FC11E Retired X.509 Certificate for Key Management 18
0x94 0x5FC11F Retired X.509 Certificate for Key Management 19
0x95 0x5FC120 Retired X.509 Certificate for Key Management 20
See also "piv-objects.json" for a machine-readable copy of this data. (Major thanks to paultag and jon gzip johnson for helping me learn and generally putting up with me, but especially dealing with my live-stream-of-thoughts while I stumble through the dark. )

5 July 2025

Taavi V n nen: Tracking my train travel by parsing tickets in emails

Rumour has it that I might be a bit of a train nerd. At least I want to collect various nerdy data about my travels. Historically that data has lived in manual form in several places,1 but over the past year and a half I've been working on a toy project to collect most of that information into a custom tool. That toy project2 uses various sources to get information about trains to fill up its database: for example, in Finland Fintraffic, the organization responsible for railway traffic management, publishes very comprehensive open data about almost everything that's moving on the Finnish railway network. Unfortunately, I cannot be on all of the trains.3 Thus I need to tell the system details about my journeys. The obvious solution is to make a form that lets me save that data. Which I did, but I got very quickly bored of filling out that form, and as regular readers of this blog know, there is no reason to settle for a simple but boring solution when the alternative is to make something that is ridiculously overengineered.

Parsing data out of my train tickets Finnish long-distance trains generally require train-specific seat reservations, which means VR (the train company) knows which trains I am on. We just need to find a way to extract that information in some machine-readable format. So my plan for the ridiculously overengineered solution was to parse the booking emails to get the details I need. Now, VR ticket emails include the data I want in a couple of different formats: they're included as text in the HTML email body, they're in the embedded calendar invite, as text in the included PDF ticket, and encoded in the Aztec Code in the included PDF ticket. I chose to parse the last option with the hopes of building something that could be ported to parse other operators' tickets with relative ease.
Example Aztec code
Example Aztec code
After a bit of digging (thank you to the KDE Itinerary people for documenting this!) I stumbled upon an European Union Agency for Railways PDF titled ELECTRONIC SEAT/BERTH RESERVATION AND ELECTRONIC PRODUCTION OF TRANSPORT DOCUMENTS - TRANSPORT DOCUMENTS (RCT2 STANDARD) which, in its Appendix C.1, describes how the information is encoded in the code.4 (As a side note, various sources call these codes SSB version 1 codes, although that term isn't used in this specification. So maybe there are more specifications about the format that I haven't discovered yet!) I then wrote a parser in Go for the binary data embedded in these codes. So far it works, although I wouldn't be surprised if there are some edge cases that it doesn't handle. In particular, the spec specifies a custom lookup table for converting between text and binary data, and that only has support for characters 0-9 and A-Z. But Finnish railway station codes can also use and .. maybe I need to buy a ticket to a station with one of those.

Extracting barcodes out of emails A parser just for the binary format isn't enough here if the intended source input is the emails that VR sends upon making a booking. Time to write a single-purpose email server! In short, the logic in the server, again written in Go and with the help of go-smtp and go-message, is:
  • Accept any mail with a reasonable body size
  • Process through all body parts
  • For all PDF parts, extract all images
  • For all images, run them through ZXing
  • For all decoded barcodes, try to parse them with my new ticket parsing library I mentioned earlier
  • If any tickets are found, send the data from them and any metadata to the main backend, which will save them to a database
The custom mail server exposes an LMTP interface over TCP for my internet-facing mail servers to forward to. I chose LMTP for this because it seemed like a better fit in theory than normal (E)SMTP. I've since discovered that curl doesn't support LMTP which makes development much harder, and in practice there's no benefit of LMTP here as all mails are being sent to the backend in a single request regardless of the number of recipients, so maybe I'll migrate it to regular SMTP at some point.

Side quest time The last missing part is automatically forwarding the ticket mails to the new service. I've routed a dedicated subdomain to the new service, and the backend is configured to allocate addresses like i2v44g2pygkcth64stjgyuqz@somedomain.example for each user. That's great if we wanted to manually forward mails to the service, but we can go one step above that. I created a dedicated email alias in my mail server config that routes both to my regular mailbox and the service address. That way I can update my VR account to use the alias and have mails automatically processed while still receiving backup copies of the tickets (and any other important mail that VR might send me). Unfortunately that last part turns out something that's easier said than done. Logging in on the website, I'm greeted by this text stating I need to contact customer service by phone to change the address associated with my account.5 After a bit of digging, I noticed that the mobile app suggests filling out a feedback form in order to change the address. So I filled that, and after a day or two I got a "confirm you want to change your email" mail. Success!

  1. Including (but not limited to): a page of this website, the notes app on my phone, and an uMap map.
  2. Which I'm not directly naming here because I still think it needs a lot more work before being presentable, but if you're really interested it's not that hard to find out.
  3. Someone should invent human cloning so that we can fix this.
  4. People who know much more about railway ticketing than I do were surprised when I told them this format is still in use somewhere. So, uh, sorry if you were expecting a nice universal worldwide standard!
  5. In case you have not guessed yet, I do not like making phone calls.

4 July 2025

Russell Coker: Function Keys

For at least 12 years laptops have been defaulting to not having the traditional PC 101 key keyboard function key functionality and instead have had other functions like controlling the volume and have had a key labelled Fn to toggle the functions. It s been a BIOS option to control whether traditional function keys or controls for volume etc are the default and for at least 12 years I ve configured all my laptops to have the traditional function keys as the default. Recently I ve been working in corporate IT and having exposure to many laptops with the default BIOS settings for those keys to change volume etc and no reasonable option for addressing it. This has made me reconsider the options for configuring these things. Here s a page listing the standard uses of function keys [1]. Here is a summary of the relevant part of that page: The keys F1, F3, F4, F7, F9, F10, and F12 don t get much use for me and for the people I observe. The F2 and F8 keys aren t useful in most programs, F6 is only really used in web browsers but the web browser counts as most programs nowadays. Here s the description of Thinkpad Fn keys [2]. I use Thinkpads for fun and Dell laptops for work, so it would be nice if they both worked in similar ways but of course they don t. Dell doesn t document how their Fn keys are laid out, but the relevant bit is that F1 to F4 are the same as on Thinkpads which is convenient as they are the ones that are likely to be commonly used and needed in a hurry. I have used the KDE settings on my Thinkpad to map the function F1 to F3 keys to the Fn equivalents which are F1 to mute-audio, F2 for vol-down, and F3 for vol-up to allow using them without holding down the Fn key while having other function keys such as F5 and F6 have their usual GUI functionality. Now I have to could train myself to use F8 in situations where I usually use F2, at least when using a laptop. The only other Fn combinations I use are F5 and F6 for controlling screen brightness, but that s not something I use much. It s annoying that the laptop manufacturers forced me to this. Having a Fn key to get extra functions and not need 101+ keys on a laptop size device is a reasonable design choice. But they could have done away with the PrintScreen key to make space for something else. Also for Thinkpads a touch pad is something that could obviously be removed to gain some extra space as the Trackpoint does all that s needed in that regard.

3 July 2025

Russell Coker: The Fuss About AI

There are many negative articles about AI (which is not about actual Artificial Intelligence also known as AGI ). Which I think are mostly overblown and often ridiculous. Resource Usage Complaints about resource usage are common, training Llama 3.1 could apparently produce as much pollution as 10,000 round trips by car between Los Angeles and New York City . That s not great but when you compare to the actual number of people doing such drives in the US and the number of people taking commercial flights on that route it doesn t seem like such a big deal. Apparently commercial passenger jets cause CO2 emissions per passenger about equal to a car with 2 people. Why is it relevant whether pollution comes from running servers, driving cars, or steel mills? Why not just tax polluters for the damage they do and let the market sort it out? People in the US make a big deal about not being communist, so why not have a capitalist solution, make it more expensive to do undesirable things and let the market sort it out? ML systems are a less bad use of compute resources than Bitcoin, at least ML systems give some useful results while Bitcoin has nothing good going for it. The Dot-Com Comparison People often complain about the apparent impossibility of AI companies doing what investors think they will do. But this isn t anything new, that all happened before with the dot com boom . I m not the first person to make this comparison, The Daily WTF (a high quality site about IT mistakes) has an interesting article making this comparison [1]. But my conclusions are quite different. The result of that was a lot of Internet companies going bankrupt, the investors in those companies losing money, and other companies then bought up their assets and made profitable companies. The cheap Internet we now have was built on the hardware from bankrupt companies which was sold for far less than the manufacture price. That allowed it to scale up from modem speeds to ADSL without the users paying enough to cover the purchase of the infrastructure. In the early 2000s I worked for two major Dutch ISPs that went bankrupt (not my fault) and one of them continued operations in the identical manner after having the stock price go to zero (I didn t get to witness what happened with the other one). As far as I m aware random Dutch citizens and residents didn t suffer from this and employees just got jobs elsewhere. There are good things being done with ML systems and when companies like OpenAI go bankrupt other companies will buy the hardware and do good things. NVidia isn t ever going to have the future sales that would justify a market capitalisation of almost 4 Trillion US dollars. This market cap can support paying for new research and purchasing rights to patented technology in a similar way to the high stock price of Google supported buying YouTube, DoubleClick, and Motorola Mobility which are the keys to Google s profits now. The Real Upsides of ML Until recently I worked for a company that used ML systems to analyse drivers for signs of fatigue, distraction, or other inappropriate things (smoking which is illegal in China, using a mobile phone, etc). That work was directly aimed at saving human lives with a significant secondary aim of saving wear on vehicles (in the mining industry drowsy drivers damage truck tires and that s a huge business expense). There are many applications of ML in medical research such as recognising cancer cells in tissue samples. There are many less important uses for ML systems, such as recognising different types of pastries to correctly bill bakery customers technology that was apparently repurposed for recognising cancer cells. The ability to recognise objects in photos is useful. It can be used for people who want to learn about random objects they see and could be used for helping young children learn about their environment. It also has some potential for assistance for visually impaired people, it wouldn t be good for safety critical systems (don t cross a road because a ML system says there are no cars coming) but could be useful for identifying objects (is this a lemon or a lime). The Humane AI pin had some real potential to do good things but there wasn t a suitable business model [2], I think that someone will develop similar technology in a useful way eventually. Even without trying to do what the Humane AI Pin attempted, there are many ways for ML based systems to assist phone and PC use. ML systems allow analysing large quantities of data and giving information that may be correct. When used by a human who knows how to recognise good answers this can be an efficient way of solving problems. I personally have solved many computer problems with the help of LLM systems while skipping over many results that were obviously wrong to me. I believe that any expert in any field that is covered in the LLM input data could find some benefits from getting suggestions from an LLM. It won t necessarily allow them to solve problems that they couldn t solve without it but it can provide them with a set of obviously wrong answers mixed in with some useful tips about where to look for the right answers. Jobs and Politics Noema Magazine has an insightful article about how AI can allow different models of work which can enlarge the middle class [3]. I don t think it s reasonable to expect ML systems to make as much impact on society as the industrial revolution, and the agricultural revolutions which took society from more than 90% farm workers to less than 5%. That doesn t mean everything will be fine but it is something that can seem OK after the changes have happened. I m not saying apart from the death and destruction everything will be good , the death and destruction are optional. Improvements in manufacturing and farming didn t have to involve poverty and death for many people, improvements to agriculture didn t have to involve overcrowding and death from disease. This was an issue of political decisions that were made. The Real Problems of ML Political decisions that are being made now have the aim of making the rich even richer and leaving more people in poverty and in many cases dying due to being unable to afford healthcare. The ML systems that aim to facilitate such things haven t been as successful as evil people have hoped but it will happen and we need appropriate legislation if we aren t going to have revolutions. There are documented cases of suicide being inspired by Chat GPT systems [4]. There have been people inspired towards murder by ChatGPT systems but AFAIK no-one has actually succeeded in such a crime yet. There are serious issues that need to be addressed with the technology and with legal constraints about how people may use it. It s interesting to consider the possible uses of ChatGPT systems for providing suggestions to a psychologist, maybe ChatGPT systems could be used to alleviate mental health problems. The cases of LLM systems being used for cheating on assignments etc isn t a real issue. People have been cheating on assignments since organised education was invented. There is a real problem of ML systems based on biased input data that issue decisions that are the average of the bigotry of the people who provided input. That isn t going to be worse than the current situation of bigoted humans making decisions based on hate and preconceptions but it will be more insidious. It is possible to search for that so for example a bank could test it s mortgage approval ML system by changing one factor at a time (name, gender, age, address, etc) and see if it changes the answer. If it turns out that the ML system is biased on names then the input data could have names removed. If it turns out to be biased about address then there could be weights put in to oppose that. For a long time there has been excessive trust in computers. Computers aren t magic they just do maths really fast and implement choices based on the work of programmers who have all the failings of other humans. Excessive trust in a rule based system is less risky than excessive trust in a ML system where no-one really knows why it makes the decisions it makes. Self driving cars kill people, this is the truth that Tesla stock holders don t want people to know. Companies that try to automate everything with AI are going to be in for some nasty surprises. Getting computers to do everything that humans do in any job is going to be a large portion of an actual intelligent computer which if it is achieved will raise an entirely different set of problems. I ve previously blogged about ML Security [5]. I don t think this will be any worse than all the other computer security problems in the long term, although it will be more insidious. How Will It Go? Companies spending billions of dollars without firm plans for how to make money are going to go bankrupt no matter what business they are in. Companies like Google and Microsoft can waste some billions of dollars on AI Chat systems and still keep going as successful businesses. Companies like OpenAI that do nothing other than such chat systems won t go well. But their assets can be used by new companies when sold at less than 10% the purchase price. Companies like NVidia that have high stock prices based on the supposed ongoing growth in use of their hardware will have their stock prices crash. But the new technology they develop will be used by other people for other purposes. If hospitals can get cheap diagnostic ML systems because of unreasonable investment into AI then that could be a win for humanity. Companies that bet their entire business on AI even when it s not necessarily their core business (as Tesla has done with self driving) will have their stock price crash dramatically at a minimum and have the possibility of bankruptcy. Having Tesla go bankrupt is definitely better than having people try to use them as self driving cars.

2 July 2025

Dirk Eddelbuettel: Rcpp 1.1.0 on CRAN: C++11 now Minimum, Regular Semi-Annual Update

rcpp logo With a friendly Canadian hand wave from vacation in Beautiful British Columbia, and speaking on behalf of the Rcpp Core Team, I am excited to shared that the (regularly scheduled bi-annual) update to Rcpp just brought version 1.1.0 to CRAN. Debian builds haven been prepared and uploaded, Windows and macOS builds should appear at CRAN in the next few days, as will builds in different Linux distribution and of course r2u should catch up tomorrow as well. The key highlight of this release is the switch to C++11 as minimum standard. R itself did so in release 4.0.0 more than half a decade ago; if someone is really tied to an older version of R and an equally old compiler then using an older Rcpp with it has to be acceptable. Our own tests (using continuous integration at GitHub) still go back all the way to R 3.5.* and work fine (with a new-enough compiler). In the previous release post, we commented that we had only reverse dependency (falsely) come up in the tests by CRAN, this time there was none among the well over 3000 packages using Rcpp at CRAN. Which really is quite amazing, and possibly also a testament to our rigorous continued testing of our development and snapshot releases on the key branch. This release continues with the six-months January-July cycle started with release 1.0.5 in July 2020. As just mentioned, we do of course make interim snapshot dev or rc releases available. While we not longer regularly update the Rcpp drat repo, the r-universe page and repo now really fill this role admirably (and with many more builds besides just source). We continue to strongly encourage their use and testing I run my systems with these versions which tend to work just as well, and are of course also fully tested against all reverse-dependencies. Rcpp has long established itself as the most popular way of enhancing R with C or C++ code. Right now, 3038 packages on CRAN depend on Rcpp for making analytical code go faster and further. On CRAN, 13.6% of all packages depend (directly) on Rcpp, and 61.3% of all compiled packages do. From the cloud mirror of CRAN (which is but a subset of all CRAN downloads), Rcpp has been downloaded 100.8 million times. The two published papers (also included in the package as preprint vignettes) have, respectively, 2023 (JSS, 2011) and 380 (TAS, 2018) citations, while the the book (Springer useR!, 2013) has another 695. As mentioned, this release switches to C++11 as the minimum standard. The diffstat display in the CRANberries comparison to the previous release shows how several (generated) sources files with C++98 boilerplate have now been removed; we also flattened a number of if/else sections we no longer need to cater to older compilers (see below for details). We also managed more accommodation for the demands of tighter use of the C API of R by removing DATAPTR and CLOENV use. A number of other changes are detailed below. The full list below details all changes, their respective PRs and, if applicable, issue tickets. Big thanks from all of us to all contributors!

Changes in Rcpp release version 1.1.0 (2025-07-01)
  • Changes in Rcpp API:
    • C++11 is now the required minimal C++ standard
    • The std::string_view type is now covered by wrap() (Lev Kandel in #1356 as discussed in #1357)
    • A last remaining DATAPTR use has been converted to DATAPTR_RO (Dirk in #1359)
    • Under R 4.5.0 or later, R_ClosureEnv is used instead of CLOENV (Dirk in #1361 fixing #1360)
    • Use of lsInternal switched to lsInternal3 (Dirk in #1362)
    • Removed compiler detection macro in a header cleanup setting C++11 as the minunum (Dirk in #1364 closing #1363)
    • Variadic templates are now used onconditionally given C++11 (Dirk in #1367 closing #1366)
    • Remove RCPP_USING_CXX11 as a #define as C++11 is now a given (Dirk in #1369)
    • Additional cleanup for __cplusplus checks (I aki in #1371 fixing #1370)
    • Unordered set construction no longer needs a macro for the pre-C++11 case (I aki in #1372)
    • Lambdas are supported in a Rcpp Sugar functions (I aki in #1373)
    • The Date(time)Vector classes now have default ctor (Dirk in #1385 closing #1384)
    • Fixed an issue where Rcpp::Language would duplicate its arguments (Kevin in #1388, fixing #1386)
  • Changes in Rcpp Attributes:
    • The C++26 standard now has plugin support (Dirk in #1381 closing #1380)
  • Changes in Rcpp Documentation:
    • Several typos were correct in the NEWS file (Ben Bolker in #1354)
    • The Rcpp Libraries vignette mentions PACKAGE_types.h to declare types used in RcppExports.cpp (Dirk in #1355)
    • The vignettes bibliography file was updated to current package versions, and now uses doi references (Dirk in #1389)
  • Changes in Rcpp Deployment:
    • Rcpp.package.skeleton() creates URL and BugReports if given a GitHub username (Dirk in #1358)
    • R 4.4.* has been added to the CI matrix (Dirk in #1376)
    • Tests involving NA propagation are skipped under linux-arm64 as they are under macos-arm (Dirk in #1379 closing #1378)

Thanks to my CRANberries, you can also look at a diff to the previous release Questions, comments etc should go to the rcpp-devel mailing list off the R-Forge page. Bugs reports are welcome at the GitHub issue tracker as well (where one can also search among open or closed issues).

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. If you like this or other open-source work I do, you can sponsor me at GitHub.

1 July 2025

Guido G nther: Free Software Activities June 2025

Another short status update of what happened on my side last month. Phosh 0.48.0 is out with nice improvements, phosh.mobi e.V. is alive, helped a bit to get cellbroadcastd out, osk bugfixes and some more: See below for details on the above and more: phosh phoc phosh-mobile-settings stevia (formerly phosh-osk-stub) phosh-osk-data phosh-vala-plugins pfs xdg-desktop-portal-phosh xdg-desktop-portal phosh-debs meta-phosh feedbackd feedbackd-device-themes gmobile GNOME clocks Debian Mobian ModemManager libmbim libqmi mobile-broadband-provider-info Cellbroadcastd iio-sensor-proxy twenty-twenty-hugo gotosocial Reviews This is not code by me but reviews on other peoples code. The list is (as usual) slightly incomplete. Thanks for the contributions! Help Development If you want to support my work see donations. Comments? Join the Fediverse thread

30 June 2025

Colin Watson: Free software activity in June 2025

My Debian contributions this month were all sponsored by Freexian. This was a very light month; I did a few things that were easy or that seemed urgent for the upcoming trixie release, but otherwise most of my energy went into Debusine. I ll be giving a talk about that at DebConf in a couple of weeks; this is the first DebConf I ll have managed to make it to in over a decade, so I m pretty excited. You can also support my work directly via Liberapay or GitHub Sponsors. PuTTY After reading a bunch of recent discourse about X11 and Wayland, I decided to try switching my laptop (a Framework 13 AMD running Debian trixie with GNOME) over to Wayland. I don t remember why it was running X; I think I must have either inherited some configuration from my previous laptop (in which case it could have been due to anything up to ten years ago or so), or else I had some initial problem while setting up my new laptop and failed to make a note of it. Anyway, the switch was hardly noticeable, which was great. One problem I did notice is that my preferred terminal emulator, pterm, crashed after the upgrade. I run a slightly-modified version from git to make some small terminal emulation changes that I really must either get upstream or work out how to live without one of these days, so it took me a while to notice that it only crashed when running from the packaged version, because the crash was in code that only runs when pterm has a set-id bit. I reported this upstream, they quickly fixed it, and I backported it to the Debian package. groff Upstream bug #67169 reported URLs being dropped from PDF output in some cases. I investigated the history both upstream and in Debian, identified the correct upstream patch to backport, and uploaded a fix. libfido2 I upgraded libfido2 to 1.16.0 in experimental. Python team I upgraded pydantic-extra-types to a new upstream version, and fixed some resulting fallout in pendulum. I updated python-typing-extensions in bookworm-backports, to help fix python3-tango: python3-pytango from bookworm-backports does not work (10.0.2-1~bpo12+1). I upgraded twisted to a new upstream version in experimental. I fixed or helped to fix a few release-critical bugs:

Gunnar Wolf: Get your personalized map of DebConf25 in Brest

As I often do, this year I have also prepared a set of personalized maps for your OpenPGP keysigning in DebConf25, in Brest! What is that, dare you ask? Partial view of my OpenPGP map One of the not-to-be-missed traditions of DebConf is a Key-Signing Party (KSP) that spans the whole conference! Travelling from all the corners of the world to a single, large group gathering, we have the ideal opportunity to spread some communicable diseases trust on your peers identities and strengthen Debian s OpenPGP keyring. But whom should you approach for keysigning? Go find yourself in the nice listing I have prepared. By clicking on your long keyid (in my case, the link labeled 0x2404C9546E145360), anybody can download your certificate (public key + signatures). The SVG and PNG links will yield a graphic version of your position within the DC25 keyring, and the TXT link will give you a textual explanation of it. (of course, your links will differ, yada yada ) Please note this is still a preview of our KSP information: You will notice there are outstanding several things for me to fix before marking the file as final. First, some names have encoding issues I will fix. Second, some keys might be missing if you submitted your key as part of the conference registration form but it is not showing, it must be because my scripts didn t find it in any of the queried keyservers. My scripts are querying the following servers:
hkps://keyring.debian.org/
hkps://keys.openpgp.org/
hkps://keyserver.computer42.org/
hkps://keyserver.ubuntu.com/
hkps://pgp.mit.edu/
hkps://pgp.pm/
hkps://pgp.surf.nl/
hkps://pgpkeys.eu/
hkps://the.earth.li/
Make sure your key is available in at least some of them; I will try to do a further run on Friday, before travelling, or shortly after arriving to France. If you didn t submit your key in time, but you will be at DC25, please mail me stating [DC25 KSP] in your mail title, and I will manually add it to the list. On (hopefully!) Friday, I ll post the final, canonical KSP coordination page which you should download and calculate its SHA256-sum. We will have printed out convenience sheets to help you do your keysigning at the front desk.

Russell Coker: Links June 2025

Jonathan McDowell wrote part 2 of his blog series about setting up a voice assistant on Debian, I look forward to reading further posts [1]. I m working on some related things for Debian that will hopefully work with this. I m testing out OpenSnitch on Trixie inspired by this blog post, it s an interesting package [2]. Valerie wrote an informative article about creating mesh networks using LORA for emergency use [3]. Interesting article about Signal and Windows Recall. That gives us some things to consider regarding ML features on Linux systems [4]. Insightful article about AI and the end of prestige [5]. We should all learn about LLMs. Jonathan Dowland wrote an informative blog post about how to manage namespaces on Linux [6]. The Consumer Rights wiki is a great resource for raising awareness of corporations exploiting their customers for computer related goods and services [7]. Interesting article about Schizophrenia and the cliff-edge function of evolution [8].

Otto Kek l inen: Corporate best practices for upstream open source contributions

Featured image of post Corporate best practices for upstream open source contributions
This post is based on presentation given at the Validos annual members meeting on June 25th, 2025.
When I started getting into Linux and open source over 25 years ago, the majority of the software development in this area was done by academics and hobbyists. The number of companies participating in open source has since exploded in parallel with the growth of mobile and cloud software, the majority of which is built on top of open source. For example, Android powers most mobile phones today and is based on Linux. Almost all software used to operate large cloud provider data centers, such as AWS or Google, is either open source or made in-house by the cloud provider. Pretty much all companies, regardless of the industry, have been using open source software at least to some extent for years. However, the degree to which they collaborate with the upstream origins of the software varies. I encourage all companies in a technical industry to start contributing upstream. There are many benefits to having a good relationship with your upstream open source software vendors, both for the short term and especially for the long term. Moreover, with the rollout of CRA in EU in 2025-2027, the law will require software companies to contribute security fixes upstream to the open source projects their products use. To ensure the process is well managed, business-aligned and legally compliant, there are a few do s and don t do s that are important to be aware of.

Maintain your SBOMs For every piece of software, regardless of whether the code was done in-house, from an open source project, or a combination of these, every company needs to produce a Software Bill of Materials (SBOM). The SBOMs provide a standardized and interoperable way to track what software and which versions are used where, what software licenses apply, who holds the copyright of which component, which security fixes have been applied and so forth. A catalog of SBOMs, or equivalent, forms the backbone of software supply-chain management in corporations.

Identify your strategic upstream vendors The SBOMs are likely to reveal that for any piece of non-trivial software, there are hundreds or thousands of upstream open source projects in use. Few organizations have resources to contribute to all of their upstreams. If your organization is just starting to organize upstream contribution activities, identify the key projects that have the largest impact on your business and prioritize forming a relationship with them first. Organizations with a mature contribution process will be collaborating with tens or hundreds of upstreams.

Appoint an internal coordinator and champions Having a written policy on how to contribute upstream will help ensure a consistent process and avoid common pitfalls. However, a written policy alone does not automatically translate into a well-running process. It is highly recommended to appoint at least one internal coordinator who is knowledgeable about how open source communities work, how software licensing and patents work, and is senior enough to have a good sense of what business priorities to optimize for. In small organizations it can be a single person, while larger organizations typically have a full Open Source Programs Office. This coordinator should oversee the contribution process, track all contributions made across the organization, and further optimize the process by working with stakeholders across the business, including legal experts, business owners and CTOs. The marketing and recruiting folks should also be involved, as upstream contributions will have a reputation-building aspect as well, which can be enhanced with systematic tracking and publishing of activities. Additionally, at least in the beginning, the organization should also appoint key staff members as open source champions. Implementing a new process always includes some obstacles and occasional setbacks, which may discourage employees from putting in the extra effort to reap the full long-term benefits for the company. Having named champions will empower them to make the first few contributions themselves, setting a good example and encouraging and mentoring others to contribute upstream as well.

Avoid excessive approvals To maintain a high quality bar, it is always good to have all outgoing submissions reviewed by at least one or two people. Two or three pairs of eyeballs are significantly more likely to catch issues that might slip by someone working alone. The review also slows down the process by a day or two, which gives the author time to sleep on it , which usually helps to ensure the final submission is well-thought-out by the author. Do not require more than one or two reviewers. The marginal utility goes quickly to zero beyond a few reviewers, and at around four or five people the effect becomes negative, as the weight of each approval decreases and the reviewers begin to take less personal responsibility. Having too many people in the loop also makes each feedback round slow and expensive, to the extent that the author will hesitate to make updates and ask for re-reviews due to the costs involved. If the organization experiences setbacks due to mistakes slipping through the review process, do not respond by adding more reviewers, as it will just grind the contribution process to a halt. If there are quality concerns, invest in training for engineers, CI systems and perhaps an internal certification program for those making public upstream code submissions. A typical software engineer is more likely to seriously try to become proficient at their job and put effort into a one-off certification exam and then make multiple high-quality contributions, than it is for a low-skilled engineer to improve and even want to continue doing more upstream contributions if they are burdened by heavy review processes every time they try to submit an upstream contribution.

Don t expect upstream to accept all code contributions Sure, identifying the root cause of and fixing a tricky bug or writing a new feature requires significant effort. While an open source project will certainly appreciate the effort invested, it doesn t mean it will always welcome all contributions with open arms. Occasionally, the project won t agree that the code is correct or the feature is useful, and some contributions are bound to be rejected. You can minimize the chance of experiencing rejections by having a solid internal review process that includes assessing how the upstream community is likely to understand the proposal. Sometimes how things are communicated is more important than how they are coded. Polishing inline comments and git commit messages help ensure high-quality communication, along with a commitment to respond quickly to review feedback and conducting regular follow-ups until a contribution is finalized and accepted.

Start small to grow expertise and reputation In addition to keeping the open source contribution policy lean and nimble, it is also good to start practical contributions with small issues. Don t aim to contribute massive features until you have a track record of being able to make multiple small contributions. Keep in mind that not all open source projects are equal. Each has its own culture, written and unwritten rules, development process, documented requirements (which may be outdated) and more. Starting with a tiny contribution, even just a typo fix, is a good way to validate how code submissions, reviews and approvals work in a particular project. Once you have staff who have successfully landed smaller contributions, you can start planning larger proposals. The exact same proposal might be unsuccessful when proposed by a new person, and successful when proposed by a person who already has a reputation for prior high-quality work.

Embrace all and any publicity you get Some companies have concerns about their employees working in the open. Indeed, every email and code patch an employee submits, and all related discussions become public. This may initially sound scary, but is actually a potential source of good publicity. Employees need to be trained on how to conduct themselves publicly, and the discussions about code should contain only information strictly related to the code, without any references to actual production environments or other sensitive information. In the long run most employees contributing have a positive impact and the company should reap the benefits of positive publicity. If there are quality issues or employee judgment issues, hiding the activity or forcing employees to contribute with pseudonyms is not a proper solution. Instead, the problems should be addressed at the root, and bad behavior addressed rather than tolerated. When people are working publicly, there tends to also be some degree of additional pride involved, which motivates people to try their best. Contributions need to be public for the sponsoring corporation to later be able to claim copyright or licenses. Considering that thousands of companies participate in open source every day, the prevalence of bad publicity is quite low, and the benefits far exceed the risks.

Scratch your own itch When choosing what to contribute, select things that benefit your own company. This is not purely about being selfish - often people working on resolving a problem they suffer from are the same people with the best expertise of what the problem is and what kind of solution is optimal. Also, the issues that are most pressing to your company are more likely to be universally useful to solve than any random bug or feature request in the upstream project s issue tracker.

Remember there are many ways to help upstream While submitting code is often considered the primary way to contribute, please keep in mind there are also other highly impactful ways to contribute. Submitting high-quality bug reports will help developers quickly identify and prioritize issues to fix. Providing good research, benchmarks, statistics or feedback helps guide development and the project make better design decisions. Documentation, translations, organizing events and providing marketing support can help increase adoption and strengthen long-term viability for the project. In some of the largest open source projects there are already far more pending contributions than the core maintainers can process. Therefore, developers who contribute code should also get into the habit of contributing reviews. As Linus law states, given enough eyeballs, all bugs are shallow. Reviewing other contributors submissions will help improve quality, and also alleviate the pressure on core maintainers who are the only ones providing feedback. Reviewing code submitted by others is also a great learning opportunity for the reviewer. The reviewer does not need to be better than the submitter - any feedback is useful; merely posting review feedback is not the same thing as making an approval decision. Many projects are also happy to accept monetary support and sponsorships. Some offer specific perks in return. By human nature, the largest sponsors always get their voice heard in important decisions, as no open source project wants to take actions that scare away major financial contributors.

Starting is the hardest part Long-term success in open source comes from a positive feedback loop of an ever-increasing number of users and collaborators. As seen in the examples of countless corporations contributing open source, the benefits are concrete, and the process usually runs well after the initial ramp-up and organizational learning phase has passed. In open source ecosystems, contributing upstream should be as natural as paying vendors in any business. If you are using open source and not contributing at all, you likely have latent business risks without realizing it. You don t want to wake up one morning to learn that your top talent left because they were forbidden from participating in open source for the company s benefit, or that you were fined due to CRA violations and mismanagement in sharing security fixes with the correct parties. The faster you start with the process, the less likely those risks will materialize.

24 June 2025

Matthew Garrett: Why is there no consistent single signon API flow?

Single signon is a pretty vital part of modern enterprise security. You have users who need access to a bewildering array of services, and you want to be able to avoid the fallout of one of those services being compromised and your users having to change their passwords everywhere (because they're clearly going to be using the same password everywhere), or you want to be able to enforce some reasonable MFA policy without needing to configure it in 300 different places, or you want to be able to disable all user access in one place when someone leaves the company, or, well, all of the above. There's any number of providers for this, ranging from it being integrated with a more general app service platform (eg, Microsoft or Google) or a third party vendor (Okta, Ping, any number of bizarre companies). And, in general, they'll offer a straightforward mechanism to either issue OIDC tokens or manage SAML login flows, requiring users present whatever set of authentication mechanisms you've configured.

This is largely optimised for web authentication, which doesn't seem like a huge deal - if I'm logging into Workday then being bounced to another site for auth seems entirely reasonable. The problem is when you're trying to gate access to a non-web app, at which point consistency in login flow is usually achieved by spawning a browser and somehow managing submitting the result back to the remote server. And this makes some degree of sense - browsers are where webauthn token support tends to live, and it also ensures the user always has the same experience.

But it works poorly for CLI-based setups. There's basically two options - you can use the device code authorisation flow, where you perform authentication on what is nominally a separate machine to the one requesting it (but in this case is actually the same) and as a result end up with a straightforward mechanism to have your users socially engineered into giving Johnny Badman a valid auth token despite webauthn nominally being unphisable (as described years ago), or you reduce that risk somewhat by spawning a local server and POSTing the token back to it - which works locally but doesn't work well if you're dealing with trying to auth on a remote device. The user experience for both scenarios sucks, and it reduces a bunch of the worthwhile security properties that modern MFA supposedly gives us.

There's a third approach, which is in some ways the obviously good approach and in other ways is obviously a screaming nightmare. All the browser is doing is sending a bunch of requests to a remote service and handling the response locally. Why don't we just do the same? Okta, for instance, has an API for auth. We just need to submit the username and password to that and see what answer comes back. This is great until you enable any kind of MFA, at which point the additional authz step is something that's only supported via the browser. And basically everyone else is the same.

Of course, when we say "That's only supported via the browser", the browser is still just running some code of some form and we can figure out what it's doing and do the same. Which is how you end up scraping constants out of Javascript embedded in the API response in order to submit that data back in the appropriate way. This is all possible but it's incredibly annoying and fragile - the contract with the identity provider is that a browser is pointed at a URL, not that any of the internal implementation remains consistent.

I've done this. I've implemented code to scrape an identity provider's auth responses to extract the webauthn challenges and feed those to a local security token without using a browser. I've also written support for forwarding those challenges over the SSH agent protocol to make this work with remote systems that aren't running a GUI. This week I'm working on doing the same again, because every identity provider does all of this differently.

There's no fundamental reason all of this needs to be custom. It could be a straightforward "POST username and password, receive list of UUIDs describing MFA mechanisms, define how those MFA mechanisms work". That even gives space for custom auth factors (I'm looking at you, Okta Fastpass). But instead I'm left scraping JSON blobs out of Javascript and hoping nobody renames a field, even though I only care about extremely standard MFA mechanisms that shouldn't differ across different identity providers.

Someone, please, write a spec for this. Please don't make it be me.

comment count unavailable comments

23 June 2025

Gunnar Wolf: Private key management Oh, the humanity...

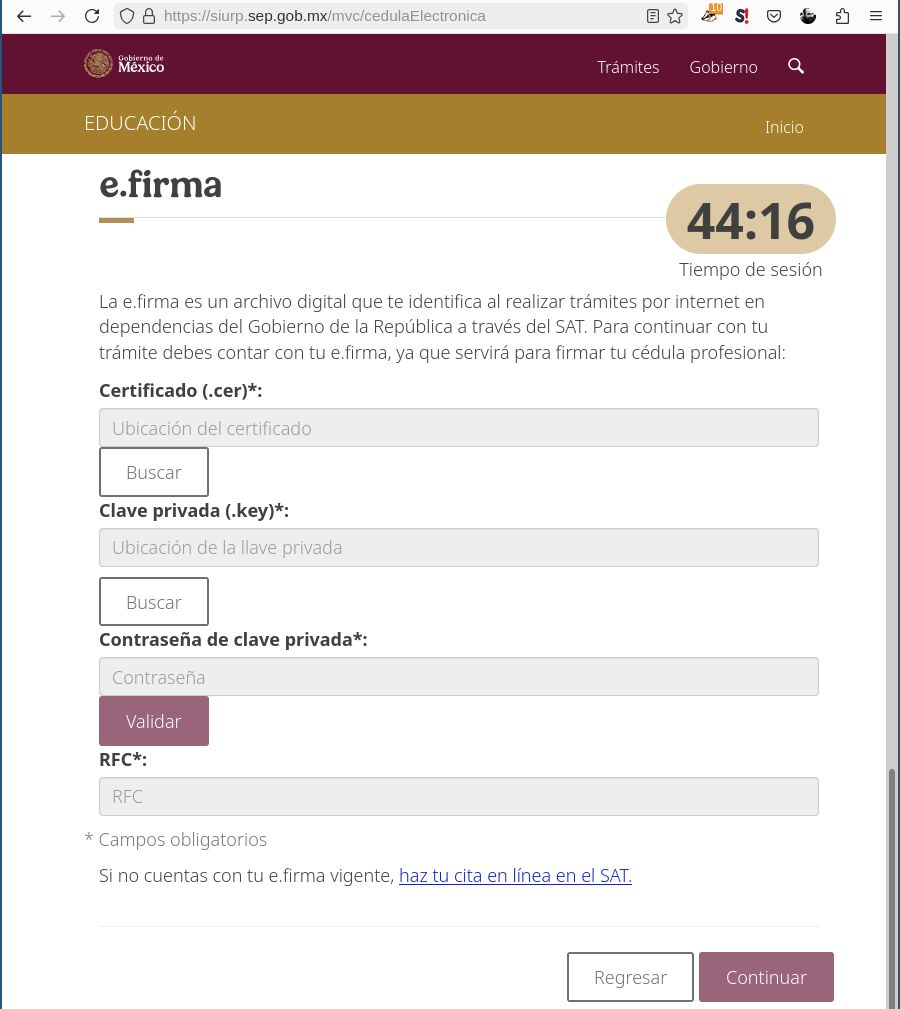
If we ever thought a couple of years or decades of constant use would get humankind to understand how an asymetric key pair is to be handled It s time we moved back to square one. I had to do an online tramit with the Mexican federal government to get a statement certifying I successfully finished my studies, and I found this jewel of user interface: E.firma So I have to:
  1. Submit the asymetric key I use for tax purposes, as that s the ID the government has registered for me. OK, I didn t expect it to be used for this purpose as well, but I ll accept it. Of course, in our tax system many people don t require having a public key generated ( easier regimes are authenticated by password only), but all professionals with a c dula profesional (everybody getting a unviersitary title) is now compelled to do this step.
  2. Not only I have to submit my certificate (public key) But also the private part (and, of course, the password that secures it). I understand I m interacting with a Javascript thingie that runs only client-side, and I trust it is not shipping my private key to their servers. But given it is an opaque script, I have no assurance about it. And, of course, this irks me because I am who I am and because I ve spent several years thinking about cryptography. But for regular people, it just looks as a stupid inconvenience: they have to upload two weird files with odd names and provide a password. What for?
This is beyond stupid. I m baffled. (of course, I did it, because I need the fsckin document. Oh, and of course, I paid my MX$1770, 80, for it which does not make me too happy for a tramit that s not even shuffling papers, only storing the right bits in the right corner of the right datacenter, but anyhow )

22 June 2025

Iustin Pop: Coding, as we knew it, has forever changed

Back when I was terribly na ve When I was younger, and definitely na ve, I was so looking forward to AI, which will help us write lots of good, reliable code faster. Well, principally me, not thinking what impact it will have industry-wide. Other more general concerns, like societal issues, role of humans in the future and so on were totally not on my radar. At the same time, I didn t expect this will actually happen. Even years later, things didn t change dramatically. Even the first release of ChatGPT a few years back didn t click for me, as the limitations were still significant.

Hints of serious change The first hint of the change, for me, was when a few months ago (yes, behind the curve), I asked ChatGPT to re-explain a concept to me, and it just wrote a lot of words, but without a clear explanation. On a whim, I asked Grok then recently launched, I think to do the same. And for the first time, the explanation clicked and I felt I could have a conversation with it. Of course, now I forgot again that theoretical CS concept, but the first step was done: I can ask an LLM to explain something, and it will, and I can have a back and forth logical discussion, even if on some theoretical concept. Additionally, I learned that not all LLMs are the same, and that means there s real competition and that leap frogging is possible. Another topic on which I tried to adopt early and failed to get mileage out of it, was GitHub Copilot (in VSC). I tried, it helped, but didn t feel any speed-up at all. Then more recently, in May, I asked Grok what s the state of the art in AI-assisted coding. It said either Claude in a browser tab, or in VSC via continue.dev extension. The continue.dev extension/tooling is a bit of a strange/interesting thing. It seems to want to be a middle-man between the user and actual LLM services, i.e. you pay a subscription to continue.dev, not to Anthropic itself, and they manage the keys/APIs, for whatever backend LLMs you want to use. The integration with Visual Studio Code is very nice, but I don t know if long-term their business model will make sense. Well, not my problem.

Claude: reverse engineering my old code and teaching new concepts So I installed the latter and subscribed, thinking 20 CHF for a month is good for testing. I skipped the tutorial model/assistant, created a new one from scratch, just enabled Claude 3.7 Sonnet, and started using it. And then, my mind was blown-not just by the LLM, but by the ecosystem. As said, I ve used GitHub copilot before, but it didn t seem effective. I don t know if a threshold has been reached, or Claude (3.7 at that time) is just better than ChatGPT. I didn t use the AI to write (non-trivial) code for me, at most boilerplate snippets. But I used it both as partner for discussion - I want to do x, what do you think, A or B? , and as a teacher, especially for fronted topics, which I m not familiar with. Since May, in mostly fragmented sessions, I ve achieved more than in the last two years. Migration from old school JS to ECMA modules, a webpacker (reducing bundle size by 50%), replacing an old Javascript library with hand written code using modern APIs, implementing the zoom feature together with all of keyboard, mouse, touchpad and touchscreen support, simplifying layout from manually computed to automatic layout, and finding a bug in webkit for which it also wrote a cool minimal test (cool, as in, way better than I d have ever, ever written, because for me it didn t matter that much). And more. Could I have done all this? Yes, definitely, nothing was especially tricky here. But hours and hours of reading MDN, scouring Stack Overflow and Reddit, and lots of trial and error. So doable, but much more toily. This, to me, feels like cheating. 20 CHF per month to make me 3x more productive is free money well, except that I don t make money on my code which is written basically for myself. However, I don t get stuck anymore searching hours in the web for guidance, I ask my question, and I get at least direction if not answer, and I m finished way earlier. I can now actually juggle more hobbies, in the same amount of time, if my personal code takes less time or differently said, if I m more efficient at it. Not all is roses, of course. Once, it did write code with such an endearing error that it made me laugh. It was so blatantly obvious that you shouldn t keep other state in the array that holds pointer status because that confuses the calculation of how many pointers are down , probably to itself too if I d have asked. But I didn t, since it felt a bit embarassing to point out such a dumb mistake. Yes, I m anthropomorphising again, because this is the easiest way to deal with things. In general, it does an OK-to-good-to-sometimes-awesome job, and the best thing is that it summarises documentation and all of Reddit and Stack Overflow. And gives links to those. Now, I have no idea yet what this means for the job of a software engineer. If on open source code, my own code, it makes me 3x faster reverse engineering my code from 10 years ago is no small feat for working on large codebases, it should do at least the same, if not more. As an example of how open-ended the assistance can be, at one point, I started implementing a new feature threading a new attribute to a large number of call points. This is not complex at all, just add a new field to a Haskell record, and modifying everything to take it into account, populate it, merge it when merging the data structures, etc. The code is not complex, tending toward boilerplate a bit, and I was wondering on a few possible choices for implementation, so, with just a few lines of code written that were not even compiling, I asked I want to add a new feature, should I do A or B if I want it to behave like this , and the answer was something along the lines of I see you want to add the specific feature I was working on, but the implementation is incomplete, you still need to to X, Y and Z . My mind was blown at this point, as I thought, if the code doesn t compile, surely the computer won t be able to parse it, but this is not a program, this is an LLM, so of course it could read it kind of as a human would. Again, the code complexity is not great, but the fact that it was able to read a half-written patch, understand what I was working towards, and reason about, was mind-blowing, and scary. Like always.

Non-code writing Now, after all this, while writing a recent blog post, I thought this is going to be public anyway, so let me ask Claude what it thinks about it. And I was very surprised, again: gone was all the pain of rereading three times my post to catch typos (easy) or phrasing structure issues. It gave me very clearly points, and helped me cut 30-40% of the total time. So not only coding, but word smithing too is changed. If I were an author, I d be delighted (and scared). Here is the overall reply it gave me:
  • Spelling and grammar fixes, all of them on point except one mistake (I claimed I didn t capitalize one word, but I did). To the level of a good grammar checker.
  • Flow Suggestions, which was way beyond normal spelling and grammar. It felt like a teacher telling me to do better in my writing, i.e. nitpicking on things that actually were true even if they d still work. I.e. lousy phrase structure, still understandable, but lousy nevertheless.
  • Other notes: an overall summary. This was mostly just praising my post . I wish LLMs were not so focused on praise the user .
So yeah, this speeds me up to about 2x on writing blog posts, too. It definitely feels not fair.

Wither the future? After all this, I m a bit flabbergasted. Gone are the 2000 s with code without unittests, gone are the 2010 s without CI/CD, and now, mid-2020 s, gone is the lone programmer that scours the internet to learn new things, alone? What this all means for our skills in software development, I have no idea, except I know things have irreversibly changed (a butlerian jihad aside). Do I learn better with a dedicated tutor even if I don t fight with the problem for so long? Or is struggling in finding good docs the main method of learning? I don t know yet. I feel like I understand the topics I m discussing with the AI, but who knows in reality what it will mean long term in terms of stickiness of learning. For the better, or for worse, things have changed. After all the advances over the last five centuries in mechanical sciences, it has now come to some aspects of the intellectual work. Maybe this is the answer to the ever-growing complexity of tech stacks? I.e. a return of the lone programmer that builds things end-to-end, but with AI taming the complexity added in the last 25 years? I can dream, of course, but this also means that the industry overall will increase in complexity even more, because large companies tend to do that, so maybe a net effect of not much One thing I did learn so far is that my expectation that AI (at this level) will only help junior/beginner people, i.e. it would flatten the skills band, is not true. I think AI can speed up at least the middle band, likely the middle top band, I don t know about the 10x programmers (I m not one of them). So, my question about AI now is how to best use it, not to lament how all my learning (90% self learning, to be clear) is obsolete. No, it isn t. AI helps me start and finish one migration (that I delayed for ages), then start the second, in the same day. At the end of this a bit rambling reflection on the past month and a half, I still have many questions about AI and humanity. But one has been answered: yes, AI , quotes or no quotes, already has changed this field (producing software), and we ve not seen the end of it, for sure.

19 June 2025

Jonathan Carter: My first tag2upload upload

Tag2upload? The tag2upload service has finally gone live for Debian Developers in an open beta. If you ve never heard of tag2upload before, here is a great primer presented by Ian Jackson and prepared by Ian Jackson and Sean Whitton. In short, the world has moved on to hosting and working with source code in Git repositories. In Debian, we work with source packages that are used to generated the binary artifacts that users know as .deb files. In Debian, there is so much tooling and culture built around this. For example, our workflow passes what we call the island test you could take every source package in Debian along with you to an island with no Internet, and you ll still be able to rebuild or modify every package. When changing the workflows, you risk losing benefits like this, and over the years there has been a number of different ideas on how to move to a purely or partially git flow for Debian, none that really managed to gain enough momentum or project-wide support. Tag2upload makes a lot of sense. It doesn t take away any of the benefits of the current way of working (whether technical or social), but it does make some aspects of Debian packages significantly simpler and faster. Even so, if you re a Debian Developer and more familiar with how the sausage have made, you ll have noticed that this has been a very long road for the tag2upload maintainers, they ve hit multiple speed bumps since 2019, but with a lot of patience and communication and persistence from all involved (and almost even a GR), it is finally materializing.

Performing my first tag2upload So, first, I needed to choose which package I want to upload. We re currently in hard freeze for the trixie release, so I ll look for something simple that I can upload to experimental.
I chose bundlewrap, it s quote a straightforward python package, and updates are usually just as straightforward, so it s probably a good package to work on without having to deal with extra complexities in learning how to use tag2upload. So, I do the usual uscan and dch -i to update my package
And then I realise that I still want to build a source package to test it in cowbuilder. Hmm, I remember that Helmut showed me that building a source package isn t necessary in sbuild, but I have a habit of breaking my sbuild configs somehow, but I guess I should revisit that. So, I do a dpkg-buildpackage -S -sa and test it out with cowbuilder, because that s just how I roll (at least for now, fixing my local sbuild setup is yak shaving for another day, let s focus!). I end up with a binary that looks good, so I m satisfied that I can upload this package to the Debian archives. So, time to configure tag2upload. The first step is to set up the webhook in Salsa. I was surprised two find two webhooks already configured:
I know of KGB that posts to IRC, didn t know that this was the mechanism it does that by before. Nice! Also don t know what the tagpending one does, I ll go look into that some other time. Configuring a tag2upload webhook is quite simple, add a URL, call the name tag2upload, and select only tag push events:
I run the test webhook, and it returned a code 400 message about a missing message header, which the documentation says is normal. Next, I install git-debpush from experimental. The wiki page simply states that you can use the git-debpush command to upload, but doesn t give any examples on how to use it, and its manpage doesn t either. And when I run just git-debpush I get:
jonathan@lapcloud:~/devel/debian/python-team/bundlewrap/bundlewrap-4.23.1$ git-debpush
git-debpush: check failed: upstream tag upstream/4.22.0 is not an ancestor of refs/heads/debian/master; probably a mistake ('upstream-nonancestor' check)
pristine-tar is /usr/bin/pristine-tar
git-debpush: some check(s) failed; you can pass --force to ignore them
I have no idea what that s supposed to mean. I was also not sure whether I should tag anything to begin with, or if some part of the tag2upload machinery automatically does it. I think I might have tagged debian/4.23-1 before tagging upstream/4.23 and perhaps it didn t like it, I reverted and did it the other way around and got a new error message. Progress!
jonathan@lapcloud:~/devel/debian/python-team/bundlewrap/bundlewrap-4.23.1$ git-debpush
git-debpush: could not determine the git branch layout
git-debpush: please supply a --quilt= argument
Looking at the manpage, it looks like quilt=baredebian matches my package the best, so I try that:
jonathan@lapcloud:~/devel/debian/python-team/bundlewrap/bundlewrap-4.23.1$ git-debpush --quilt=baredebian
Enumerating objects: 70, done.
Counting objects: 100% (70/70), done.
Delta compression using up to 12 threads
Compressing objects: 100% (37/37), done.
Writing objects: 100% (37/37), 8.97 KiB   2.99 MiB/s, done.
Total 37 (delta 30), reused 0 (delta 0), pack-reused 0 (from 0)
To salsa.debian.org:python-team/packages/bundlewrap.git
6f55d99..3d5498f debian/master -> debian/master
 * [new tag] upstream/4.23.1 -> upstream/4.23.1
 * [new tag] debian/4.23.1-1_exp1 -> debian/4.23.1-1_exp1
Ooh! That looked like it did something! And a minute later I received the notification of the upload in my inbox:
So, I m not 100% sure that this makes things much easier for me than doing a dput, but, it s not any more difficult or more work either (once you know how it works), so I ll be using git-debpush from now on, and I m sure as I get more used to the git workflow of doing things I ll understand more of the benefits. And at last, my one last use case for using FTP is now properly dead. RIP FTP :)

Russell Coker: Matching Intel CPUs

To run a SMP system with multiple CPUs you need to have CPUs that are identical , the question is what does identical mean. In this case I m interested in Intel CPUs because SMP motherboards and server systems for Intel CPUs are readily available and affordable. There are people selling matched pairs of CPUs on ebay which tend to be more expensive than randomly buying 2 of the same CPU model, so if you can identify 2 CPUs that are identical which are sold separately then you can save some money. Also if you own a two CPU system with only one CPU installed then buying a second CPU to match the first is cheaper and easier than buying two more CPUs and removing a perfectly working CPU. e5-2640 v4 cpus
Intel (R) Xeon (R)
E5-2640V4
SR2NZ 2.40GHZ
J717B324 (e4)
7758S4100843
Above is a pic of 2 E5-2640v4 CPUs that were in a SMP system I purchased along with a plain ASCII representation of the text on one of them. The bottom code (starting with 77 ) is apparently the serial number, one of the two codes above it is what determines how identical those CPUs are. The code on the same line as the nominal clock speed (in this case SR2NZ) is the spec number which is sometimes referred to as sspec [1]. The line below the sspec and above the serial number has J717B324 which doesn t have a google hit. I looked at more than 20 pics of E5-2640v4 CPUs on ebay, they all had the code SR2NZ but had different numbers on the line below. I conclude that the number on the line below probably indicates the model AND stepping while SR2NZ just means E5-2640v4 regardless of stepping. As I wasn t able to find another CPU on ebay with the same number on the line below the sspec I believe that it will be unreasonably difficult to get a match for an existing CPU. For the purpose of matching CPUs I believe that if the line above the serial number matches then the CPUs can be used together. I am not certain that CPUs with this number slightly mismatching won t work but I definitely wouldn t want to spend money on CPUs with this number being different.
smpboot: CPU0: Intel(R) Xeon(R) CPU E5-2699A v4 @ 2.40GHz (family: 0x6, model: 0x4f, stepping: 0x1)
When you boot Linux the kernel identifies the CPU in a manner like the above, the combination of family and model seem to map to one spec number. The combination of family, model, and stepping should be all that s required to have them work together. I think that Intel did the wrong thing in not making this clearer. It would have been very easy to print the stepping on the CPU case next to the sspec or the CPU model name. It also wouldn t have been too hard to make the CPU provide the magic number that is apparently the required match for SMP to the OS. Having the Intel web site provide a mapping of those numbers to steppings of CPUs also shouldn t be difficult for them. If anyone knows more about these issues please let me know.

Debian Outreach Team: GSoC 2025 Introduction: Make Debian for Raspberry Pi Build Again

Hello everyone! I am Kurva Prashanth, Interested in the lower level working of system software, CPUs/SoCs and Hardware design. I was introduced to Open Hardware and Embedded Linux while studying electronics and embedded systems as part of robotics coursework. Initially, I did not pay much attention to it and quickly moved on. However, a short talk on Liberating SBCs using Debian by Yuvraj at MiniDebConf India, 2021 caught my interest. The talk focused on Open Hardware platforms such as Olimex and BeagleBone Black, as well as the Debian distributions tailored for these ARM-based single-board computers has intrigued me to delve deeper into the realm of Open Hardware and Embedded Linux. These days I m trying to improve my abilities to contribute to Debian and Linux Kernel development. Before finding out about the Google Summer of Code project, I had already started my journey with Debian. I extensively used Debian system build tools(debootstrap, sbuild, deb-build-pkg, qemu-debootstrap) for Building Debian Image for Bela Cape a real-time OS for music making to achieve extremely fast audio and sensor processing times. In 2023, I had the opportunity to attend DebConf23 in Kochi, India - thanks to Nilesh Patra (@nilesh) and I met Hector Oron (@zumbi) over dinner at DebConf23 and It was nice talking about his contributions/work at Debian on armhf port and Debian System Administration that conversation got me interested in knowing more about Debian ARM, Installer and I found it fascinating that EmDebian was once a external project bringing Debian to embedded systems and now, Debian itself can be run on many embedded systems. And, also during DebCamp I got Introduced to PGP/GPG keys and the web of trust by Carlos Henrique Lima Melara (@charles) I learned how to use and generate GPG keys. After DebConf23 I tried debian packaging and I miserably failed to get sponsorship for a python library I packaged. I came across the Debian project for this year s Google Summer of Code and found the project titled Make Debian for Raspberry Pi Build Again quite interesting to me and applied. Gladly, on May 8th, I received an acceptance e-mail from GSoC. I got excited that I ll spend the summer working on something that I like doing. I am thrilled to be part of this project and I am super excited for the summer of 25. I m looking forward to work on what I most like, new connections and learning opportunities. So, let me talk a bit more about my project. I will be working on to Make Debian for Raspberry Pi SBC s under the guidance of Gunnar Wolf (@gwolf). In this post, I will describe the project I will be working on.

Why make Debian for Raspberry Pi build again? There is an available set of images for running Debian in Raspberry Pi computers (all models below the 5 series)! However, the maintainer severely lacking time to take care for them; called for help for somebody to adopt them, but have not been successful. The image generation scripts might have bitrotted a bit, but it is mostly all done. And there is a lot of interest and use still in having the images freshly generated and decently tested! This GSoC project is about getting the [https://raspi.debian.net/ Raspberry Pi Debian images] site working reliably, daily-built images become automatic again and ideally making it easily deployable to be run in project machines and migrating exsisting hosting infrastructure to Debian.

How much it differ from Debian build process? While the goal is to stay as close as possible to the Debian build process, Raspberry Pi boards require some necessary platform-specific changes primarily in the early boot sequence and firmware handling. Unlike typical Debian systems, Raspberry Pi boards depend on a non-standard bootloader and use non-free firmware (raspi-firmware), Introducing some hardware-specific differences in the initialization process. These differences are largely confined to the early boot and hardware initialization stages. Once the system boots, the userspace remains closely aligned with a typical Debian install, using Debian packages. The current modifications are required due to non-free firmware. However, several areas merit review: but there are a few parts that might be worth changing.
  1. Boot flow: Transitioning to a U-Boot based boot process (as used in Debian installer images for many other SBCs) would reduce divergence and better align with Debian Installer.
  2. Current scripts/workarounds: Some existing hacks may now be redundant with recent upstream support and could be removed.
  3. Board-specific images: Shift to architecture-specific base images with runtime detection could simplify builds and reduce duplication.
Debian already already building SD card images for a wide range of SBCs (e.g., BeagleBone, BananaPi, OLinuXino, Cubieboard, etc.) installer-arm64/images/u-boot and installer-armhf/images/u-boot, a similar approach for Raspberry Pi could improve maintainability and consistency with Debian s broader SBC support.

Quoted from Mail Discussion Thread with Mentor (Gunnar Wolf)
"One direction we wanted to explore was whether we should still be building one image per family, or whether we could instead switch to one image per architecture (armel, armhf, arm64). There were some details to iron out as RPi3 and RPi4 were quite different, but I think it will be similar to the differences between the RPi 0 and 1, which are handled at first-boot time. To understand what differs between families, take a look at Cyril Brulebois generate-recipe (in the repo), which is a great improvement over the ugly mess I had before he contributed it"
In this project, I intend to to build one image per architecture (armel, armhf, arm64) rather than continuing with the current model of building one image per board. This change simplifies image management, reduces redundancy, and leverages dynamic configuration at boot time to support all supported boards within each architecture. By using U-Boot and flash-kernel, we can detect the board type and configure kernel parameters, DTBs, and firmware during the first boot, reducing duplication across images and simplifying the maintenance burden and we can also generalize image creation while still supporting board-specific behavior at runtime. This method aligns with existing practices in the DebianInstaller team and aligns with Debian s long-term maintainability goals and better leverages upstream capabilities, ensuring a consistent and scalable boot experience. To streamline and standardize the process of building bootable Debian images for Raspberry Pi devices, I proposed a new workflow that leverages U-Boot and flash-kernel Debian packages. This provides a clean, maintainable, and reproducible way to generate images for armel, armhf and arm64 boards. The workflow is vmdb2, a lightweight, declarative tool designed to automate the creation of disk images. A typical vmdb2 recipe defines the disk layout, base system installation (via debootstrap), architecture-specific packages, and any custom post-install hooks and the image should includes U-Boot (the u-boot-rpi package), flash-kernel, and a suitable Debian kernel package like linux-image-arm64 or linux-image-armmp. U-Boot serves as the platform s bootloader and is responsible for loading the kernel and initramfs. Unlike Raspberry Pi s non-free firmware/proprietary bootloader, U-Boot provides an open and scriptable interface, allowing us to follow a more standard Debian boot process. It can be configured to boot using either an extlinux.conf or a boot.scr script generated automatically by flash-kernel. The role of flash-kernel is to bridge Debian s kernel installation system with the specifics of embedded bootloaders like U-Boot. When installed, it automatically copies the kernel image, initrd, and device tree blobs (DTBs) to the /boot partition. It also generates the necessary boot.scr script if the board configuration demands it. To work correctly, flash-kernel requires that the target machine be identified via /etc/flash-kernel/machine, which must correspond to an entry in its internal machine database.\ Once the vmdb2 build is complete, the resulting image will contain a fully configured bootable system with all necessary boot components correctly installed. The image can be flashed to an SD card and used to boot on the intended device without additional manual configuration. Because all key packages (U-Boot, kernel, flash-kernel) are managed through Debian s package system, kernel updates and boot script regeneration are handled automatically during system upgrades.

Current Workflow: Builds one Image per family The current vmdb2 recipe uses the Raspberry Pi GPU bootloader provided via the raspi-firmware package. This is the traditional boot process followed by Raspberry Pi OS, and it s tightly coupled with firmware files like bootcode.bin, start.elf, and fixup.dat. These files are installed to /boot/firmware, which is mounted from a FAT32 partition labeled RASPIFIRM. The device tree files (*.dtb) are manually copied from /usr/lib/linux-image-*-arm64/broadcom/ into this partition. The kernel is installed via the linux-image-arm64 package, and the boot arguments are injected by modifying /boot/firmware/cmdline.txt using sed commands. Booting depends on the root partition being labeled RASPIROOT, referenced through that file. There is no bootloader like UEFI-based or U-Boot involved the Raspberry Pi firmware directly loads the kernel, which is standard for Raspberry Pi boards.
- apt: install
  packages:
    ...
    - raspi-firmware  
The boot partition contents and kernel boot setup are tightly controlled via scripting in the recipe. Limitations of Current Workflow: While this setup works, it is
  1. Proprietary and Raspberry Pi specific It relies on the closed-source GPU bootloader the raspi-firmware package, which is tightly coupled to specific Raspberry Pi models.
  2. Manual DTB handling Device tree files are manually copied and hardcoded, making upgrades or board-specific changes error-prone.
  3. Not easily extendable to future Raspberry Pi boards Any change in bootloader behavior (as seen in the Raspberry Pi 5, which introduces a more flexible firmware boot process) would require significant rework.
  4. No UEFI-based/U-Boot The current method bypasses the standard bootloader layers, making it inconsistent with other Debian ARM platforms and harder to maintain long-term.
As Raspberry Pi firmware and boot processes evolve, especially with the introduction of Pi 5 and potentially Pi 6, maintaining compatibility will require more flexibility - something best delivered by adopting U-Boot and flash-kernel.

New Workflow: Building Architecture-Specific Images with vmdb2, U-Boot, flash-kernel, and Debian Kernel This workflow outlines an improved approach to generating bootable Debian images architecture specific, using vmdb2, U-Boot, flash-kernel, and Debian kernels and also to move away from Raspberry Pi s proprietary bootloader to a fully open-source boot process which improves maintainability, consistency, and cross-board support.

New Method: Shift to U-Boot + flash-kernel U-Boot (via Debian su-boot-rpi package) and flash-kernel bring the image building process closer to how Debian officially boots ARM devices. flash-kernel integrates with the system s initramfs and kernel packages to install bootloaders, prepare boot.scr or extlinux.conf, and copy kernel/initrd/DTBs to /boot in a format that U-Boot expects. U-Boot will be used as a second-stage bootloader, loaded by the Raspberry Pi s built-in firmware. Once U-Boot is in place, it will read standard boot scripts ( boot.scr) generated by flash-kernel, providing a Debian-compatible and board-flexible solution. Extending YAML spec for vmdb2 build with U-Boot and flash-kernel To improve an existing vmdb2 YAML spec(https://salsa.debian.org/raspi-team/image-specs/raspi_master.yaml), to integrate U-Boot, flash-kernel, and the architecture-specific Debian kernel into the image build process. By incorporating u-boot-rpi and flash-kernel from Debian packages, alongside the standard initramfs-tools, we align the image closer to Debian best practices while supporting both armhf and arm64 architectures. Below are key additions and adjustments needed in a vmdb2 YAML spec to support the workflow: Install U-Boot, flash-kernel, initramfs-tools and the architecture-specific Debian kernel.
- apt: install
  packages:
    - u-boot-rpi
    - flash-kernel
    - initramfs-tools
    - linux-image-arm64 # or linux-image-armmp for armhf 
  tag: tag-root
Replace linux-image-arm64 with the correct kernel package for specific target architecture. These packages should be added under the tag-root section in YAML spec for vmdb2 build recipe. This ensures that the necessary bootloader, kernel, and initramfs tools are included and properly configured in the image. Configure Raspberry Pi firmware to Load U-Boot Install the U-Boot binary as kernel.img in /boot/firmware we can also download and build U-Boot from source, but Debian provides tested binaries.
- shell:  
    cp /usr/lib/u-boot/rpi_4/u-boot.bin $ ROOT? /boot/firmware/kernel.img
    echo "enable_uart=1" >> $ ROOT? /boot/firmware/config.txt
  root-fs: tag-root
This makes the RPi firmware load u-boot.bin instead of the Linux kernel directly. Set Up flash-kernel for Debian-style Boot flash-kernel integrates with initramfs-tools and writes boot config suitable for U-Boot. We need to make sure /etc/flash-kernel/db contains an entry for board (most Raspberry Pi boards already supported in Bookworm). Set up /etc/flash-kernel.conf with:
- create-file: /etc/flash-kernel.conf
  contents:  
    MACHINE="Raspberry Pi 4"
    BOOTPART="/dev/disk/by-label/RASPIFIRM"
    ROOTPART="/dev/disk/by-label/RASPIROOT"
  unless: rootfs_unpacked
This allows flash-kernel to write an extlinux.conf or boot.scr into /boot/firmware. Clean up Proprietary/Non-Free Firmware Bootflow Remove the direct kernel loading flow:
- shell:  
    rm -f $ ROOT? /boot/firmware/vmlinuz*
    rm -f $ ROOT? /boot/firmware/initrd.img*
    rm -f $ ROOT? /boot/firmware/cmdline.txt
  root-fs: tag-root
Let U-Boot and flash-kernel manage kernel/initrd and boot parameters instead. Boot Flow After This Change
[SoC ROM] -> [start.elf] -> [U-Boot] -> [boot.scr] -> [Linux Kernel]
  1. This still depends on the Raspberry Pi firmware to start, but it only loads U-Boot, not Linux kernel.
  2. U-Boot gives you more flexibility (e.g., networking, boot menus, signed boot).
  3. Using flash-kernel ensures kernel updates are handled the Debian Installer way.
  4. Test with a serial console (enable_uart=1) in case HDMI doesn t show early boot logs.
Advantage of New Workflow
  1. Replaces the proprietary Raspberry Pi bootloader with upstream U-Boot.
  2. Debian-native tooling Uses flash-kernel and initramfs-tools to manage boot configuration.
  3. Consistent across boards Works for both armhf and arm64, unifying the image build process.
  4. Easier to support new boards Like the Raspberry Pi 5 and future models.
This transition will standardize a bit image-building process, making it aligned with upstream Debian Installer workflows.

vmdb2 configuration for arm64 using u-boot and flash-kernel NOTE: This is a baseline example and may require tuning.
# Raspberry Pi arm64 image using U-Boot and flash-kernel
steps:
  # ... (existing mkimg, partitions, mount, debootstrap, etc.) ...
  # Install U-Boot, flash-kernel, initramfs-tools and architecture specific kernel
  - apt: install
    packages:
      - u-boot-rpi
      - flash-kernel
      - initramfs-tools
      - linux - image - arm64 # or linux - image - armmp for armhf
    tag: tag-root
  # Install U-Boot binary as kernel.img in firmware partition
  - shell:  
      cp /usr/lib/u-boot/rpi_arm64 /u-boot.bin $ ROOT? /boot/firmware/kernel.img
      echo "enable_uart=1" >> $ ROOT? /boot/firmware/config.txt
    root-fs: tag-root
  # Configure flash-kernel for Raspberry Pi
  - create-file: /etc/flash-kernel.conf
    contents:  
      MACHINE="Generic Raspberry Pi ARM64"
      BOOTPART="/dev/disk/by-label/RASPIFIRM"
      ROOTPART="/dev/disk/by-label/RASPIROOT"
    unless: rootfs_unpacked
  # Remove direct kernel boot files from Raspberry Pi firmware
  - shell:  
      rm -f $ ROOT? /boot/firmware/vmlinuz*
      rm -f $ ROOT? /boot/firmware/initrd.img*
      rm -f $ ROOT? /boot/firmware/cmdline.txt
    root-fs: tag-root
  # flash-kernel will manage boot scripts and extlinux.conf
  # Rest of image build continues...

Required Changes to Support Raspberry Pi Boards in Debian (flash-kernel + U-Boot)

Overview of Required Changes
Component Required Task
Debian U-Boot Package Add build target for rpi_arm64 in u-boot-rpi. Optionally deprecate legacy 32-bit targets.
Debian flash-kernel Package Add or verify entries in db/all.db for Pi 4, Pi 5, Zero 2W, CM4. Ensure boot script generation works via bootscr.uboot-generic.
Debian Kernel Ensure DTBs are installed at /usr/lib/linux-image-<version>/ and available for flash-kernel to reference.

flash-kernel

Already Supported Boards in flash-kernel Debian Package https://sources.debian.org/src/flash-kernel/3.109/db/all.db/#L1700
Model Arch DTB-Id
Raspberry Pi 1 A/B/B+, Rev2 armel bcm2835-*
Raspberry Pi CM1 armel bcm2835-rpi-cm1-io1.dtb
Raspberry Pi Zero/Zero W armel bcm2835-rpi-zero*.dtb
Raspberry Pi 2B armhf bcm2836-rpi-2-b.dtb
Raspberry Pi 3B/3B+ arm64 bcm2837-*
Raspberry Pi CM3 arm64 bcm2837-rpi-cm3-io3.dtb
Raspberry Pi 400 arm64 bcm2711-rpi-400.dtb

uboot

Already Supported Boards in Debian U-Boot Package https://salsa.debian.org/installer-team/flash-kernel/-/blob/master/db/all.db

arm64 Model Arch Upstream Defconfig Debian Target - - - Raspberry Pi 3B arm64 rpi_3_defconfig rpi_3 Raspberry Pi 4B arm64 rpi_4_defconfig rpi_4 Raspberry Pi 3B/3B+/CM3/CM3+/4B/CM4/400/5B/Zero 2W arm64 rpi_arm64_defconfig rpi_arm64
armhf Model Arch Upstream Defconfig Debian Target - - - Raspberry Pi 2 armhf rpi_2_defconfig rpi_2 Raspberry Pi 3B (32-bit) armhf rpi_3_32b_defconfig rpi_3_32b Raspberry Pi 4B (32-bit) armhf rpi_4_32b_defconfig rpi_4_32b
armel Model Arch Upstream Defconfig Debian Target - - - Raspberry Pi armel rpi_defconfig rpi Raspberry Pi 1/Zero armel rpi_0_w rpi_0_w These boards are already defined in debian/rules under the u-boot-rpi source package and generates usable U-Boot binaries for corresponding Raspberry Pi models.

To-Do: Add Missing Board Support to U-Boot and flash-kernel in Debian Several Raspberry Pi models are missing from the Debian U-Boot and flash-kernel packages, even though upstream support and DTBs exist in the Debian kernel but are missing entries in the flash-kernel database to enable support for bootloader installation and initrd handling.

Boards Not Yet Supported in flash-kernel Debian Package
Model Arch DTB-Id
Raspberry Pi 3A+ (32 & 64 bit) armhf, arm64 bcm2837-rpi-3-a-plus.dtb
Raspberry Pi 4B (32 & 64 bit) armhf, arm64 bcm2711-rpi-4-b.dtb
Raspberry Pi CM4 arm64 bcm2711-rpi-cm4-io.dtb
Raspberry Pi CM 4S arm64 -
Raspberry Zero 2 W arm64 bcm2710-rpi-zero-2-w.dtb
Raspberry Pi 5 arm64 bcm2712-rpi-5-b.dtb
Raspberry Pi CM5 arm64 -
Raspberry Pi 500 arm64 -

Boards Not Yet Supported in Debian U-Boot Package
Model Arch Upstream defconfig(s)
Raspberry Pi 3A+/3B+ arm64 -, rpi_3_b_plus_defconfig
Raspberry Pi CM 4S arm64 -
Raspberry Pi 5 arm64 -
Raspberry Pi CM5 arm64 -
Raspberry Pi 500 arm64 -

So, what next? During the Community Bonding Period, I got hands-on with workflow improvements, set up test environments, and began reviewing Raspberry Pi support in Debian s U-Boot and flash-kernel and these are the logs of the project, where I provide weekly reports on the work done. You can check here: Community Bonding Period logs. My next steps include submitting patches to the u-boot and flash-kernel packages to ensure all missing Raspberry Pi entries are built and shipped. And, also to confirm the kernel DTB installation paths and make sure the necessary files are included for all Raspberry Pi variants. Finally, plan to validate changes with test builds on Raspberry Pi hardware. In parallel, I m organizing my tasks and setting up my environment to contribute more effectively. It s been exciting to explore how things work under the hood and to prepare for a summer of learning and contributing to this great community.

Next.

Previous.