I've always known that the browser uses the Domain Name Resolution (DNS) system to convert domain names like aezign.com.au into raw IP addresses, but have never actually understood how it works, outside of making sure my network config uses 1.1.1.1 or 8.8.8.8 instead of the crappy one the ISP provides. In this article, I set out to understand what nameservers do, and how they help anything that uses the internet find the right records.
DNS in a nutshellA well-used analogy is a phonebook; when you have someone's name and need to find their phone number, you look through the phonebook. Overall, DNS does the same thing: when you enter an address like example.com, your browser will contact a DNS server (the "phonebook") to determine its IP addresses. On Linux (or MacOS) systems, you can use dig on the command line to perform a DNS lookup and see what this looks like:
$ dig example.com
; <<>> DiG 9.20.29-1-Debian <<>> example.com
;; global options: +cmd
;; Got answer:
;; ->>HEADER<<- opcode: QUERY, status: NOERROR, id: 42782
;; flags: qr rd ra; QUERY: 1, ANSWER: 2, AUTHORITY: 0, ADDITIONAL: 1
;; OPT PSEUDOSECTION:
; EDNS: version: 0, flags:; udp: 1232
;; QUESTION SECTION:
;example.com.                   IN      A
;; ANSWER SECTION:
example.com.            221     IN      A       104.20.23.154
example.com.            221     IN      A       172.66.147.243
;; Query time: 20 msec
;; SERVER: 1.1.1.1#53(1.1.1.1) (UDP)
;; WHEN: Sun Sep 27 21:07:50 AWST 2026
;; MSG SIZE  rcvd: 72
Here, you can see the DNS server being used is 1.1.1.1 (Cloudflare's DNS server), and that it found the IPs 104.20.23.154 and 172.66.147.243 associated with the domain name example.com. Your browser will then contact these IP addresses directly to load the website you are trying to open.
Configuring DNS serversYou can configure DNS servers through your operating system's network settings, and for some applications such as Firefox, with the application itself. If you don't manually set a DNS server, your computer will use the ones provided by your modem. If those are not configured, the default defined by the modem manufacturer or your ISP will be used.The most well-used and reliable DNS servers you can use are Cloudflare's (1.1.1.1 and 1.0.0.1) and Google's (8.8.8.8 and 8.8.4.4). Having more than one DNS server means that if the first one in the list doesn't work or doesn't find the matching IPs for a domain name, it will move to the next one in the list, a backup DNS server.DNS servers must be configured as IP addresses. If your computer tried to use a DNS server at a domain name, then where would your computer find the IP address for that domain name? It wouldn't be able to, as this is the exact gap that DNS servers fulfill.
RecordsDNS is not used only to find IPs for a domain, but a whole host of other things. Collectively they are referred to as "records" (or "DNS records"). Each record is associated to a domain (e.g. example.com) or a subdomain (e.g. bar.example.com, foo.bar.example.com) Here are some of the most common and important types:
A - Map to an IPv4 address (e.g. 104.20.23.154).This is the fundamental function of DNS: to map from a domain name to a server's IP address. Multiple A records leads to load balancing, where browsers will randomly select one of the returned IP addresses such that traffic is evenly split between them.
AAAA - Map to an IPv6 address (e.g. 2606:4700:10::6814:179a).This serves the same purpose as A records but for IPv6. Multiple AAAA records results in the same load balancing behaviour. All modern websites should have both an A record for legacy compatibility, and an AAAA record to future-proof for the gradual shift towards IPv6 addresses.
CNAME - Alias to another domain name (e.g. example.com).DNS servers will recursively lookup records for the aliased domain name until they reach an IP address (in an A or AAAA record).
MX - Specify a Mail Exchange server (e.g. mail.example.com).This record tells email SMTP servers where to direct emails to. For instance, the MX record for aezign.com.au is mail.aezign.au; this directs SMTP servers like Gmail and Outlook to send emails to the mailserver running at mail.aezign.au. This also allows specifying a priority field, so that you can define multiple MX records (such as a main and a backup) and consumers will try to connect to the listed mailservers from lowest priority to highest.
TXT - Store arbitrary text dataThis is most commonly used for site verification (for instance, to link your website to Google Search Console) and for email security measures like DKIM, DMARC, and SPF.
NS - Specify the nameservers for a domain (e.g. zeus.ns.cloudflare.com).These authoritative nameservers are responsible for providing all the other record types when needed.
dig lets you query each of these. For instance, to list the MX records against aezign.com.au:
Here you can see there is only one mailserver configured for aezign.com.au, which is mail.aezign.au, and it has a priority of 10.If you compare this against something like gmail.com:
You can see that gmail.com has several mailservers configured as redundancies due to the Gmail's sheer scale. gmail-smtp-in.l.google.com has the highest priority of 5, so SMTP servers will attempt to contact that mailserver first, followed by alt1.gmail-smtp-in.l.google.com and so on.
NameserversNow there needs to be somewhere for DNS records against a domain name to be defined, right? This is where nameservers come in.Nameservers are DNS servers that answer queries about the domains they are authoritative for i.e. the domains they are in charge of. For example, the authoritative nameservers for example.com are hera.ns.cloudflare.com and elliott.ns.cloudflare.com, which means Cloudflare's nameservers are the source of truth when looking up DNS records for example.com. You can check this with dig:
Nameservers are configured with your domain name's registrar. The nameserver you set dictates where your remaining DNS records will live. For example.com, this means you would configure all your records on Cloudflare's dashboard, since they are responsible for the domain's DNS records.
Recursive resolutionThe DNS servers that our computers use follow a recursive resolution process behind-the-scenes to find the authoritative nameservers for a domain, followed by the records you are querying.
Finding the root nameserversDue to the recursive nature of the resolution process, there needs to be a starting point: the root (.) nameservers. The resolver uses a fixed list of root nameservers called root hints issued by IANA (named.root), to locate and contact the root nameservers. Resolvers will have this provided to them initially, and can dynamically update it themselves by querying one of the root nameservers for the root NS records to obtain a fresh list. For instance, we can query 198.41.0.4 (a.root-servers.net) to obtain a new list of root nameservers:
$ dig @198.41.0.4 NS .
; <<>> DiG 9.20.29-1-Debian <<>> @198.41.0.4 NS .
; (1 server found)
;; global options: +cmd
;; Got answer:
;; ->>HEADER<<- opcode: QUERY, status: NOERROR, id: 43677
;; flags: qr aa rd; QUERY: 1, ANSWER: 13, AUTHORITY: 0, ADDITIONAL: 27
;; WARNING: recursion requested but not available
;; OPT PSEUDOSECTION:
; EDNS: version: 0, flags:; udp: 4096
;; QUESTION SECTION:
;.				IN	NS
;; ANSWER SECTION:
.			518400	IN	NS	l.root-servers.net.
.			518400	IN	NS	j.root-servers.net.
.			518400	IN	NS	f.root-servers.net.
.			518400	IN	NS	h.root-servers.net.
.			518400	IN	NS	d.root-servers.net.
.			518400	IN	NS	b.root-servers.net.
.			518400	IN	NS	k.root-servers.net.
.			518400	IN	NS	i.root-servers.net.
.			518400	IN	NS	m.root-servers.net.
.			518400	IN	NS	e.root-servers.net.
.			518400	IN	NS	g.root-servers.net.
.			518400	IN	NS	c.root-servers.net.
.			518400	IN	NS	a.root-servers.net.
;; ADDITIONAL SECTION:
l.root-servers.net.	518400	IN	A	199.7.83.42
l.root-servers.net.	518400	IN	AAAA	2001:500:9f::42
j.root-servers.net.	518400	IN	A	192.58.128.30
j.root-servers.net.	518400	IN	AAAA	2001:503:c27::2:30
f.root-servers.net.	518400	IN	A	192.5.5.241
f.root-servers.net.	518400	IN	AAAA	2001:500:2f::f
h.root-servers.net.	518400	IN	A	198.97.190.53
h.root-servers.net.	518400	IN	AAAA	2001:500:1::53
d.root-servers.net.	518400	IN	A	199.7.91.13
d.root-servers.net.	518400	IN	AAAA	2001:500:2d::d
b.root-servers.net.	518400	IN	A	170.247.170.2
b.root-servers.net.	518400	IN	AAAA	2801:1b8:10::b
k.root-servers.net.	518400	IN	A	193.0.14.129
k.root-servers.net.	518400	IN	AAAA	2001:7fd::1
i.root-servers.net.	518400	IN	A	192.36.148.17
i.root-servers.net.	518400	IN	AAAA	2001:7fe::53
m.root-servers.net.	518400	IN	A	202.12.27.33
m.root-servers.net.	518400	IN	AAAA	2001:dc3::35
e.root-servers.net.	518400	IN	A	192.203.230.10
e.root-servers.net.	518400	IN	AAAA	2001:500:a8::e
g.root-servers.net.	518400	IN	A	192.112.36.4
g.root-servers.net.	518400	IN	AAAA	2001:500:12::d0d
c.root-servers.net.	518400	IN	A	192.33.4.12
c.root-servers.net.	518400	IN	AAAA	2001:500:2::c
a.root-servers.net.	518400	IN	A	198.41.0.4
a.root-servers.net.	518400	IN	AAAA	2001:503:ba3e::2:30
;; Query time: 476 msec
;; SERVER: 198.41.0.4#53(198.41.0.4) (UDP)
;; WHEN: Mon Sep 28 00:01:08 AWST 2026
;; MSG SIZE  rcvd: 811
Querying the root nameserversFor example.com, the first step is to query the root (.) nameservers to find the nameservers for the .com top-level domain (TLD). Using a.root-servers.net again:
$ dig @198.41.0.4 NS com
; <<>> DiG 9.20.29-1-Debian <<>> @198.41.0.4 NS com
; (1 server found)
;; global options: +cmd
;; Got answer:
;; ->>HEADER<<- opcode: QUERY, status: NOERROR, id: 22528
;; flags: qr rd; QUERY: 1, ANSWER: 0, AUTHORITY: 13, ADDITIONAL: 27
;; WARNING: recursion requested but not available
;; OPT PSEUDOSECTION:
; EDNS: version: 0, flags:; udp: 4096
;; QUESTION SECTION:
;com.				IN	NS
;; AUTHORITY SECTION:
com.			172800	IN	NS	l.gtld-servers.net.
com.			172800	IN	NS	j.gtld-servers.net.
com.			172800	IN	NS	h.gtld-servers.net.
com.			172800	IN	NS	d.gtld-servers.net.
com.			172800	IN	NS	b.gtld-servers.net.
com.			172800	IN	NS	f.gtld-servers.net.
com.			172800	IN	NS	k.gtld-servers.net.
com.			172800	IN	NS	m.gtld-servers.net.
com.			172800	IN	NS	i.gtld-servers.net.
com.			172800	IN	NS	g.gtld-servers.net.
com.			172800	IN	NS	a.gtld-servers.net.
com.			172800	IN	NS	c.gtld-servers.net.
com.			172800	IN	NS	e.gtld-servers.net.
;; ADDITIONAL SECTION:
l.gtld-servers.net.	172800	IN	A	192.41.162.30
l.gtld-servers.net.	172800	IN	AAAA	2001:500:d937::30
j.gtld-servers.net.	172800	IN	A	192.48.79.30
j.gtld-servers.net.	172800	IN	AAAA	2001:502:7094::30
h.gtld-servers.net.	172800	IN	A	192.54.112.30
h.gtld-servers.net.	172800	IN	AAAA	2001:502:8cc::30
d.gtld-servers.net.	172800	IN	A	192.31.80.30
d.gtld-servers.net.	172800	IN	AAAA	2001:500:856e::30
b.gtld-servers.net.	172800	IN	A	192.33.14.30
b.gtld-servers.net.	172800	IN	AAAA	2001:503:231d::2:30
f.gtld-servers.net.	172800	IN	A	192.35.51.30
f.gtld-servers.net.	172800	IN	AAAA	2001:503:d414::30
k.gtld-servers.net.	172800	IN	A	192.52.178.30
k.gtld-servers.net.	172800	IN	AAAA	2001:503:d2d::30
m.gtld-servers.net.	172800	IN	A	192.55.83.30
m.gtld-servers.net.	172800	IN	AAAA	2001:501:b1f9::30
i.gtld-servers.net.	172800	IN	A	192.43.172.30
i.gtld-servers.net.	172800	IN	AAAA	2001:503:39c1::30
g.gtld-servers.net.	172800	IN	A	192.42.93.30
g.gtld-servers.net.	172800	IN	AAAA	2001:503:eea3::30
a.gtld-servers.net.	172800	IN	A	192.5.6.30
a.gtld-servers.net.	172800	IN	AAAA	2001:503:a83e::2:30
c.gtld-servers.net.	172800	IN	A	192.26.92.30
c.gtld-servers.net.	172800	IN	AAAA	2001:503:83eb::30
e.gtld-servers.net.	172800	IN	A	192.12.94.30
e.gtld-servers.net.	172800	IN	AAAA	2001:502:1ca1::30
;; Query time: 772 msec
;; SERVER: 198.41.0.4#53(198.41.0.4) (UDP)
;; WHEN: Mon Sep 28 00:09:25 AWST 2026
;; MSG SIZE  rcvd: 828
Querying the TLD nameserversNow the resolver has .com nameservers and their IPs. We can use one of these, such as 192.5.6.30 (a.gtld-servers.net) to find the nameservers for example.com:
$ dig @192.5.6.30 NS example.com
; <<>> DiG 9.20.29-1-Debian <<>> @192.5.6.30 NS example.com
; (1 server found)
;; global options: +cmd
;; Got answer:
;; ->>HEADER<<- opcode: QUERY, status: NOERROR, id: 37419
;; flags: qr rd; QUERY: 1, ANSWER: 0, AUTHORITY: 2, ADDITIONAL: 13
;; WARNING: recursion requested but not available
;; OPT PSEUDOSECTION:
; EDNS: version: 0, flags:; udp: 4096
;; QUESTION SECTION:
;example.com.                   IN      NS
;; AUTHORITY SECTION:
example.com.            172800  IN      NS      hera.ns.cloudflare.com.
example.com.            172800  IN      NS      elliott.ns.cloudflare.com.
;; ADDITIONAL SECTION:
hera.ns.cloudflare.com. 172800  IN      A       108.162.192.162
hera.ns.cloudflare.com. 172800  IN      A       172.64.32.162
hera.ns.cloudflare.com. 172800  IN      A       173.245.58.162
hera.ns.cloudflare.com. 172800  IN      AAAA    2606:4700:50::adf5:3aa2
hera.ns.cloudflare.com. 172800  IN      AAAA    2803:f800:50::6ca2:c0a2
hera.ns.cloudflare.com. 172800  IN      AAAA    2a06:98c1:50::ac40:20a2
elliott.ns.cloudflare.com. 172800 IN    A       108.162.195.228
elliott.ns.cloudflare.com. 172800 IN    A       162.159.44.228
elliott.ns.cloudflare.com. 172800 IN    A       172.64.35.228
elliott.ns.cloudflare.com. 172800 IN    AAAA    2606:4700:58::a29f:2ce4
elliott.ns.cloudflare.com. 172800 IN    AAAA    2803:f800:50::6ca2:c3e4
elliott.ns.cloudflare.com. 172800 IN    AAAA    2a06:98c1:50::ac40:23e4
;; Query time: 80 msec
;; SERVER: 192.5.6.30#53(192.5.6.30) (UDP)
;; WHEN: Mon Sep 28 00:12:19 AWST 2026
;; MSG SIZE  rcvd: 359
Finding the domain's nameserverThe response tells the resolver that the nameservers for example.com are hera.ns.cloudflare.com and elliott.ns.cloudflare.com. Now since these Cloudflare nameservers are also .com domains and Cloudflare is so commonly used, the .com nameserver provides optional sibling glue records as defined in RFC 9471 to prevent further roundtrips and optimize the process.If we ignore the sibling glue records provided, the resolver would have to ask the .com nameservers for the nameservers for cloudflare.com:
$ dig @192.5.6.30 NS cloudflare.com
; <<>> DiG 9.20.29-1-Debian <<>> @192.5.6.30 NS cloudflare.com
; (1 server found)
;; global options: +cmd
;; Got answer:
;; ->>HEADER<<- opcode: QUERY, status: NOERROR, id: 40307
;; flags: qr rd; QUERY: 1, ANSWER: 0, AUTHORITY: 5, ADDITIONAL: 21
;; WARNING: recursion requested but not available
;; OPT PSEUDOSECTION:
; EDNS: version: 0, flags:; udp: 4096
;; QUESTION SECTION:
;cloudflare.com.                        IN      NS
;; AUTHORITY SECTION:
cloudflare.com.         172800  IN      NS      ns3.cloudflare.com.
cloudflare.com.         172800  IN      NS      ns5.cloudflare.com.
cloudflare.com.         172800  IN      NS      ns4.cloudflare.com.
cloudflare.com.         172800  IN      NS      ns6.cloudflare.com.
cloudflare.com.         172800  IN      NS      ns7.cloudflare.com.
;; ADDITIONAL SECTION:
ns3.cloudflare.com.     172800  IN      A       162.159.0.33
ns3.cloudflare.com.     172800  IN      A       162.159.7.226
ns3.cloudflare.com.     172800  IN      AAAA    2400:cb00:2049:1::a29f:21
ns3.cloudflare.com.     172800  IN      AAAA    2400:cb00:2049:1::a29f:7e2
ns5.cloudflare.com.     172800  IN      A       162.159.2.9
ns5.cloudflare.com.     172800  IN      A       162.159.9.55
ns5.cloudflare.com.     172800  IN      AAAA    2400:cb00:2049:1::a29f:209
ns5.cloudflare.com.     172800  IN      AAAA    2400:cb00:2049:1::a29f:937
ns4.cloudflare.com.     172800  IN      A       162.159.1.33
ns4.cloudflare.com.     172800  IN      A       162.159.8.55
ns4.cloudflare.com.     172800  IN      AAAA    2400:cb00:2049:1::a29f:121
ns4.cloudflare.com.     172800  IN      AAAA    2400:cb00:2049:1::a29f:837
ns6.cloudflare.com.     172800  IN      A       162.159.3.11
ns6.cloudflare.com.     172800  IN      A       162.159.5.6
ns6.cloudflare.com.     172800  IN      AAAA    2400:cb00:2049:1::a29f:30b
ns6.cloudflare.com.     172800  IN      AAAA    2400:cb00:2049:1::a29f:506
ns7.cloudflare.com.     172800  IN      A       162.159.4.8
ns7.cloudflare.com.     172800  IN      A       162.159.6.6
ns7.cloudflare.com.     172800  IN      AAAA    2400:cb00:2049:1::a29f:408
ns7.cloudflare.com.     172800  IN      AAAA    2400:cb00:2049:1::a29f:606
;; Query time: 163 msec
;; SERVER: 192.5.6.30#53(192.5.6.30) (UDP)
;; WHEN: Mon Sep 28 00:26:53 AWST 2026
;; MSG SIZE  rcvd: 573
Here, the .com nameserver provides in-domain glue records for cloudflare.com's nameservers. Without these, there would be a circular dependency, since the nameserver named is a subdomain of the domain being queried for. This is because nameservers are always defined by name, which means that in order to actually contact the nameserver, your computer needs to obtain its IP address with another DNS lookup.Next, we'd use one of these nameservers, say ns3.cloudflare.com, to obtain the IP for hera.ns.cloudflare.com:
$ dig @162.159.0.33 hera.ns.cloudflare.com
; <<>> DiG 9.20.29-1-Debian <<>> @162.159.0.33 hera.ns.cloudflare.com
; (1 server found)
;; global options: +cmd
;; Got answer:
;; ->>HEADER<<- opcode: QUERY, status: NOERROR, id: 16801
;; flags: qr aa rd; QUERY: 1, ANSWER: 3, AUTHORITY: 0, ADDITIONAL: 1
;; WARNING: recursion requested but not available
;; OPT PSEUDOSECTION:
; EDNS: version: 0, flags:; udp: 1232
;; QUESTION SECTION:
;hera.ns.cloudflare.com.                IN      A
;; ANSWER SECTION:
hera.ns.cloudflare.com. 86353   IN      A       108.162.192.162
hera.ns.cloudflare.com. 86353   IN      A       173.245.58.162
hera.ns.cloudflare.com. 86353   IN      A       172.64.32.162
;; Query time: 123 msec
;; SERVER: 162.159.0.33#53(162.159.0.33) (UDP)
;; WHEN: Mon Sep 28 01:11:37 AWST 2026
;; MSG SIZE  rcvd: 99
Querying the domain's authoritative nameserverNow we've reached the authoritative nameserver for example.com! The last thing to do is to fetch the A record for example.com to obtain its server's IP address:
$ dig @108.162.192.162 example.com
; <<>> DiG 9.20.29-1-Debian <<>> @108.162.192.162 example.com
; (1 server found)
;; global options: +cmd
;; Got answer:
;; ->>HEADER<<- opcode: QUERY, status: NOERROR, id: 43082
;; flags: qr aa rd; QUERY: 1, ANSWER: 2, AUTHORITY: 0, ADDITIONAL: 1
;; WARNING: recursion requested but not available
;; OPT PSEUDOSECTION:
; EDNS: version: 0, flags:; udp: 1232
;; QUESTION SECTION:
;example.com.                   IN      A
;; ANSWER SECTION:
example.com.            300     IN      A       104.20.23.154
example.com.            300     IN      A       172.66.147.243
;; Query time: 123 msec
;; SERVER: 108.162.192.162#53(108.162.192.162) (UDP)
;; WHEN: Mon Sep 28 01:13:47 AWST 2026
;; MSG SIZE  rcvd: 72
At last, we've determined that the IP addresses of the servers behind example.com are 104.20.23.154 and 172.66.147.243. This matches our earlier lookup directly against your computer's configured DNS server.The DNS servers your computer uses encapsulate this recursive resolution process behind the scenes, so that your computer only needs to make one round trip, and the servers can use their much faster data center connections and caching to optimize the process and make the query as fast as possible.
Checking DNS recordsTo check a website's records, the first thing to do is to ensure the domain name is pointed at the correct nameserver. For instance, aezign.com.au is supposed to use Cloudflare, since that is where all the DNS records have been set up. We can verify this using dig, (or alternatively with online tools like dnschecker.org):
If this is not set correctly, the DNS records you configure will not work, as resolvers will be fetching records from somewhere else. In most cases, you can update this in your domain registrar's settings. This is especially common for new domain names, which default to the registrar's nameservers; unless you plan to use their built-in DNS management, you'll need to point them to your chosen provider.Now we can check that the DNS records configured match those your DNS server returns. For aezign.com.au, these are the MX and TXT records configured on Cloudflare. The MX record and some TXT records configured for aezign.com.au on Cloudflare's dashboard.We can check these using dig, and using the +short option to show only the content of the records.
As we can see, this matches, which means that the nameservers for aezign.com.au are correct and the DNS records are what we intend them to be.Note that if you've recently changed the nameserver or DNS records for your domain, it can take anywhere between 10 seconds and 24 hours for the changes to take effect and propagate across the different DNS servers globally. Tools like dnschecker.org can check your records on different DNS servers worldwide to see if they're reflecting your changes. The reason for this is caching: DNS servers like 1.1.1.1 will cache results so it doesn't have to do the full resolution process every time, and uses the Time-To-Live (TTL) you configure in your DNS records as a guideline for caching duration.
The diffoscope maintainers are pleased to announce the release of diffoscope
version 332. This version includes the following changes:
[ Chris Lamb ]
* Do not Build-Depend on GNU Guix. Thanks to Vagrant and Holger for the
  reports. (Closes: #1149132)
[ Guillaume Girol ]
* Update more tests to support new versions of Radare.
  (Closes: reproducible-builds/diffoscope#432)
The Domain Name System (DNS) is a fundamental piece of technology behind the modern internet. Thanks to its introduction in 1983, you're able to enter domain names like aezign.com.au instead of raw IP addresses in your browser's address bar and when sending emails. This article explains what it is, how it works, and how you can inspect your own website's DNS and ensure it is set up correctly.
DNS in a nutshellA well-used analogy is a phonebook; when you have someone's name and need to find their phone number, you look through the phonebook. Overall, DNS does the same thing: when you enter an address like example.com, your browser will contact a DNS server (the "phonebook") to determine its IP addresses. On Linux (or MacOS) systems, you can use dig on the command line to perform a DNS lookup and see what this looks like:
$ dig example.com
; <<>> DiG 9.20.29-1-Debian <<>> example.com
;; global options: +cmd
;; Got answer:
;; ->>HEADER<<- opcode: QUERY, status: NOERROR, id: 42782
;; flags: qr rd ra; QUERY: 1, ANSWER: 2, AUTHORITY: 0, ADDITIONAL: 1
;; OPT PSEUDOSECTION:
; EDNS: version: 0, flags:; udp: 1232
;; QUESTION SECTION:
;example.com.                   IN      A
;; ANSWER SECTION:
example.com.            221     IN      A       104.20.23.154
example.com.            221     IN      A       172.66.147.243
;; Query time: 20 msec
;; SERVER: 1.1.1.1#53(1.1.1.1) (UDP)
;; WHEN: Sun Sep 27 21:07:50 AWST 2026
;; MSG SIZE  rcvd: 72
Here, you can see the DNS server being used is 1.1.1.1 (Cloudflare's DNS server), and that it found the IPs 104.20.23.154 and 172.66.147.243 associated with the domain name example.com. Your browser will then contact these IP addresses directly to load the website you are trying to open.
Configuring DNS serversYou can configure DNS servers through your operating system's network settings, and for some applications such as Firefox, with the application itself. If you don't manually set a DNS server, your computer will use the ones provided by your modem. If those are not configured, the default defined by the modem manufacturer or your ISP will be used.The most well-used and reliable DNS servers you can use are Cloudflare's (1.1.1.1 and 1.0.0.1) and Google's (8.8.8.8 and 8.8.4.4). Having more than one DNS server means that if the first one in the list doesn't work or doesn't find the matching IPs for a domain name, it will move to the next one in the list, a backup DNS server.DNS servers must be configured as IP addresses. If your computer tried to use a DNS server at a domain name, then where would your computer find the IP address for that domain name? It wouldn't be able to, as this is the exact gap that DNS servers fulfill.
RecordsDNS is not used only to find IPs for a domain, but a whole host of other things. Collectively they are referred to as "records" (or "DNS records"). Each record is associated to a domain (e.g. example.com) or a subdomain (e.g. bar.example.com, foo.bar.example.com) Here are some of the most common and important types:
A - Map to an IPv4 address (e.g. 104.20.23.154).This is the fundamental function of DNS: to map from a domain name to a server's IP address. Multiple A records leads to load balancing, where browsers will randomly select one of the returned IP addresses such that traffic is evenly split between them.
AAAA - Map to an IPv6 address (e.g. 2606:4700:10::6814:179a).This serves the same purpose as A records but for IPv6. Multiple AAAA records results in the same load balancing behaviour. All modern websites should have both an A record for legacy compatibility, and an AAAA record to future-proof for the gradual shift towards IPv6 addresses.
CNAME - Alias to another domain name (e.g. example.com).DNS servers will recursively lookup records for the aliased domain name until they reach an IP address (in an A or AAAA record).
MX - Specify a Mail Exchange server (e.g. mail.example.com).This record tells email SMTP servers where to direct emails to. For instance, the MX record for aezign.com.au is mail.aezign.au; this directs SMTP servers like Gmail and Outlook to send emails to the mailserver running at mail.aezign.au. This also allows specifying a priority field, so that you can define multiple MX records (such as a main and a backup) and consumers will try to connect to the listed mailservers from lowest priority to highest.
TXT - Store arbitrary text dataThis is most commonly used for site verification (for instance, to link your website to Google Search Console) and for email security measures like DKIM, DMARC, and SPF.
NS - Specify the nameservers for a domain (e.g. zeus.ns.cloudflare.com).These authoritative nameservers are responsible for providing all the other record types when needed.
dig lets you query each of these. For instance, to list the MX records against aezign.com.au:
Here you can see there is only one mailserver configured for aezign.com.au, which is mail.aezign.au, and it has a priority of 10.If you compare this against something like gmail.com:
You can see that gmail.com has several mailservers configured as redundancies due to the Gmail's sheer scale. gmail-smtp-in.l.google.com has the highest priority of 5, so SMTP servers will attempt to contact that mailserver first, followed by alt1.gmail-smtp-in.l.google.com and so on.
NameserversNow there needs to be somewhere for DNS records against a domain name to be defined, right? This is where nameservers come in.Nameservers are DNS servers that answer queries about the domains they are authoritative for i.e. the domains they are in charge of. For example, the authoritative nameservers for example.com are hera.ns.cloudflare.com and elliott.ns.cloudflare.com, which means Cloudflare's nameservers are the source of truth when looking up DNS records for example.com. You can check this with dig:
Nameservers are configured with your domain name's registrar. The nameserver you set dictates where your remaining DNS records will live. For example.com, this means you would configure all your records on Cloudflare's dashboard, since they are responsible for the domain's DNS records.
Recursive resolutionThe DNS servers that our computers use follow a recursive resolution process behind-the-scenes to find the authoritative nameservers for a domain, followed by the records you are querying.
Finding the root nameserversDue to the recursive nature of the resolution process, there needs to be a starting point: the root (.) nameservers. The resolver uses a fixed list of root nameservers called root hints issued by IANA (named.root), to locate and contact the root nameservers. Resolvers will have this provided to them initially, and can dynamically update it themselves by querying one of the root nameservers for the root NS records to obtain a fresh list. For instance, we can query 198.41.0.4 (a.root-servers.net) to obtain a new list of root nameservers:
$ dig @198.41.0.4 NS .
; <<>> DiG 9.20.29-1-Debian <<>> @198.41.0.4 NS .
; (1 server found)
;; global options: +cmd
;; Got answer:
;; ->>HEADER<<- opcode: QUERY, status: NOERROR, id: 43677
;; flags: qr aa rd; QUERY: 1, ANSWER: 13, AUTHORITY: 0, ADDITIONAL: 27
;; WARNING: recursion requested but not available
;; OPT PSEUDOSECTION:
; EDNS: version: 0, flags:; udp: 4096
;; QUESTION SECTION:
;.				IN	NS
;; ANSWER SECTION:
.			518400	IN	NS	l.root-servers.net.
.			518400	IN	NS	j.root-servers.net.
.			518400	IN	NS	f.root-servers.net.
.			518400	IN	NS	h.root-servers.net.
.			518400	IN	NS	d.root-servers.net.
.			518400	IN	NS	b.root-servers.net.
.			518400	IN	NS	k.root-servers.net.
.			518400	IN	NS	i.root-servers.net.
.			518400	IN	NS	m.root-servers.net.
.			518400	IN	NS	e.root-servers.net.
.			518400	IN	NS	g.root-servers.net.
.			518400	IN	NS	c.root-servers.net.
.			518400	IN	NS	a.root-servers.net.
;; ADDITIONAL SECTION:
l.root-servers.net.	518400	IN	A	199.7.83.42
l.root-servers.net.	518400	IN	AAAA	2001:500:9f::42
j.root-servers.net.	518400	IN	A	192.58.128.30
j.root-servers.net.	518400	IN	AAAA	2001:503:c27::2:30
f.root-servers.net.	518400	IN	A	192.5.5.241
f.root-servers.net.	518400	IN	AAAA	2001:500:2f::f
h.root-servers.net.	518400	IN	A	198.97.190.53
h.root-servers.net.	518400	IN	AAAA	2001:500:1::53
d.root-servers.net.	518400	IN	A	199.7.91.13
d.root-servers.net.	518400	IN	AAAA	2001:500:2d::d
b.root-servers.net.	518400	IN	A	170.247.170.2
b.root-servers.net.	518400	IN	AAAA	2801:1b8:10::b
k.root-servers.net.	518400	IN	A	193.0.14.129
k.root-servers.net.	518400	IN	AAAA	2001:7fd::1
i.root-servers.net.	518400	IN	A	192.36.148.17
i.root-servers.net.	518400	IN	AAAA	2001:7fe::53
m.root-servers.net.	518400	IN	A	202.12.27.33
m.root-servers.net.	518400	IN	AAAA	2001:dc3::35
e.root-servers.net.	518400	IN	A	192.203.230.10
e.root-servers.net.	518400	IN	AAAA	2001:500:a8::e
g.root-servers.net.	518400	IN	A	192.112.36.4
g.root-servers.net.	518400	IN	AAAA	2001:500:12::d0d
c.root-servers.net.	518400	IN	A	192.33.4.12
c.root-servers.net.	518400	IN	AAAA	2001:500:2::c
a.root-servers.net.	518400	IN	A	198.41.0.4
a.root-servers.net.	518400	IN	AAAA	2001:503:ba3e::2:30
;; Query time: 476 msec
;; SERVER: 198.41.0.4#53(198.41.0.4) (UDP)
;; WHEN: Mon Sep 28 00:01:08 AWST 2026
;; MSG SIZE  rcvd: 811
Querying the root nameserversFor example.com, the first step is to query the root (.) nameservers to find the nameservers for the .com top-level domain (TLD). Using a.root-servers.net again:
$ dig @198.41.0.4 NS com
; <<>> DiG 9.20.29-1-Debian <<>> @198.41.0.4 NS com
; (1 server found)
;; global options: +cmd
;; Got answer:
;; ->>HEADER<<- opcode: QUERY, status: NOERROR, id: 22528
;; flags: qr rd; QUERY: 1, ANSWER: 0, AUTHORITY: 13, ADDITIONAL: 27
;; WARNING: recursion requested but not available
;; OPT PSEUDOSECTION:
; EDNS: version: 0, flags:; udp: 4096
;; QUESTION SECTION:
;com.				IN	NS
;; AUTHORITY SECTION:
com.			172800	IN	NS	l.gtld-servers.net.
com.			172800	IN	NS	j.gtld-servers.net.
com.			172800	IN	NS	h.gtld-servers.net.
com.			172800	IN	NS	d.gtld-servers.net.
com.			172800	IN	NS	b.gtld-servers.net.
com.			172800	IN	NS	f.gtld-servers.net.
com.			172800	IN	NS	k.gtld-servers.net.
com.			172800	IN	NS	m.gtld-servers.net.
com.			172800	IN	NS	i.gtld-servers.net.
com.			172800	IN	NS	g.gtld-servers.net.
com.			172800	IN	NS	a.gtld-servers.net.
com.			172800	IN	NS	c.gtld-servers.net.
com.			172800	IN	NS	e.gtld-servers.net.
;; ADDITIONAL SECTION:
l.gtld-servers.net.	172800	IN	A	192.41.162.30
l.gtld-servers.net.	172800	IN	AAAA	2001:500:d937::30
j.gtld-servers.net.	172800	IN	A	192.48.79.30
j.gtld-servers.net.	172800	IN	AAAA	2001:502:7094::30
h.gtld-servers.net.	172800	IN	A	192.54.112.30
h.gtld-servers.net.	172800	IN	AAAA	2001:502:8cc::30
d.gtld-servers.net.	172800	IN	A	192.31.80.30
d.gtld-servers.net.	172800	IN	AAAA	2001:500:856e::30
b.gtld-servers.net.	172800	IN	A	192.33.14.30
b.gtld-servers.net.	172800	IN	AAAA	2001:503:231d::2:30
f.gtld-servers.net.	172800	IN	A	192.35.51.30
f.gtld-servers.net.	172800	IN	AAAA	2001:503:d414::30
k.gtld-servers.net.	172800	IN	A	192.52.178.30
k.gtld-servers.net.	172800	IN	AAAA	2001:503:d2d::30
m.gtld-servers.net.	172800	IN	A	192.55.83.30
m.gtld-servers.net.	172800	IN	AAAA	2001:501:b1f9::30
i.gtld-servers.net.	172800	IN	A	192.43.172.30
i.gtld-servers.net.	172800	IN	AAAA	2001:503:39c1::30
g.gtld-servers.net.	172800	IN	A	192.42.93.30
g.gtld-servers.net.	172800	IN	AAAA	2001:503:eea3::30
a.gtld-servers.net.	172800	IN	A	192.5.6.30
a.gtld-servers.net.	172800	IN	AAAA	2001:503:a83e::2:30
c.gtld-servers.net.	172800	IN	A	192.26.92.30
c.gtld-servers.net.	172800	IN	AAAA	2001:503:83eb::30
e.gtld-servers.net.	172800	IN	A	192.12.94.30
e.gtld-servers.net.	172800	IN	AAAA	2001:502:1ca1::30
;; Query time: 772 msec
;; SERVER: 198.41.0.4#53(198.41.0.4) (UDP)
;; WHEN: Mon Sep 28 00:09:25 AWST 2026
;; MSG SIZE  rcvd: 828
Querying the TLD nameserversNow the resolver has .com nameservers and their IPs. We can use one of these, such as 192.5.6.30 (a.gtld-servers.net) to find the nameservers for example.com:
$ dig @192.5.6.30 NS example.com
; <<>> DiG 9.20.29-1-Debian <<>> @192.5.6.30 NS example.com
; (1 server found)
;; global options: +cmd
;; Got answer:
;; ->>HEADER<<- opcode: QUERY, status: NOERROR, id: 37419
;; flags: qr rd; QUERY: 1, ANSWER: 0, AUTHORITY: 2, ADDITIONAL: 13
;; WARNING: recursion requested but not available
;; OPT PSEUDOSECTION:
; EDNS: version: 0, flags:; udp: 4096
;; QUESTION SECTION:
;example.com.                   IN      NS
;; AUTHORITY SECTION:
example.com.            172800  IN      NS      hera.ns.cloudflare.com.
example.com.            172800  IN      NS      elliott.ns.cloudflare.com.
;; ADDITIONAL SECTION:
hera.ns.cloudflare.com. 172800  IN      A       108.162.192.162
hera.ns.cloudflare.com. 172800  IN      A       172.64.32.162
hera.ns.cloudflare.com. 172800  IN      A       173.245.58.162
hera.ns.cloudflare.com. 172800  IN      AAAA    2606:4700:50::adf5:3aa2
hera.ns.cloudflare.com. 172800  IN      AAAA    2803:f800:50::6ca2:c0a2
hera.ns.cloudflare.com. 172800  IN      AAAA    2a06:98c1:50::ac40:20a2
elliott.ns.cloudflare.com. 172800 IN    A       108.162.195.228
elliott.ns.cloudflare.com. 172800 IN    A       162.159.44.228
elliott.ns.cloudflare.com. 172800 IN    A       172.64.35.228
elliott.ns.cloudflare.com. 172800 IN    AAAA    2606:4700:58::a29f:2ce4
elliott.ns.cloudflare.com. 172800 IN    AAAA    2803:f800:50::6ca2:c3e4
elliott.ns.cloudflare.com. 172800 IN    AAAA    2a06:98c1:50::ac40:23e4
;; Query time: 80 msec
;; SERVER: 192.5.6.30#53(192.5.6.30) (UDP)
;; WHEN: Mon Sep 28 00:12:19 AWST 2026
;; MSG SIZE  rcvd: 359
Finding the domain's nameserverThe response tells the resolver that the nameservers for example.com are hera.ns.cloudflare.com and elliott.ns.cloudflare.com. Now since these Cloudflare nameservers are also .com domains and Cloudflare is so commonly used, the .com nameserver provides optional sibling glue records as defined in RFC 9471 to prevent further roundtrips and optimize the process.If we ignore the sibling glue records provided, the resolver would have to ask the .com nameservers for the nameservers for cloudflare.com:
$ dig @192.5.6.30 NS cloudflare.com
; <<>> DiG 9.20.29-1-Debian <<>> @192.5.6.30 NS cloudflare.com
; (1 server found)
;; global options: +cmd
;; Got answer:
;; ->>HEADER<<- opcode: QUERY, status: NOERROR, id: 40307
;; flags: qr rd; QUERY: 1, ANSWER: 0, AUTHORITY: 5, ADDITIONAL: 21
;; WARNING: recursion requested but not available
;; OPT PSEUDOSECTION:
; EDNS: version: 0, flags:; udp: 4096
;; QUESTION SECTION:
;cloudflare.com.                        IN      NS
;; AUTHORITY SECTION:
cloudflare.com.         172800  IN      NS      ns3.cloudflare.com.
cloudflare.com.         172800  IN      NS      ns5.cloudflare.com.
cloudflare.com.         172800  IN      NS      ns4.cloudflare.com.
cloudflare.com.         172800  IN      NS      ns6.cloudflare.com.
cloudflare.com.         172800  IN      NS      ns7.cloudflare.com.
;; ADDITIONAL SECTION:
ns3.cloudflare.com.     172800  IN      A       162.159.0.33
ns3.cloudflare.com.     172800  IN      A       162.159.7.226
ns3.cloudflare.com.     172800  IN      AAAA    2400:cb00:2049:1::a29f:21
ns3.cloudflare.com.     172800  IN      AAAA    2400:cb00:2049:1::a29f:7e2
ns5.cloudflare.com.     172800  IN      A       162.159.2.9
ns5.cloudflare.com.     172800  IN      A       162.159.9.55
ns5.cloudflare.com.     172800  IN      AAAA    2400:cb00:2049:1::a29f:209
ns5.cloudflare.com.     172800  IN      AAAA    2400:cb00:2049:1::a29f:937
ns4.cloudflare.com.     172800  IN      A       162.159.1.33
ns4.cloudflare.com.     172800  IN      A       162.159.8.55
ns4.cloudflare.com.     172800  IN      AAAA    2400:cb00:2049:1::a29f:121
ns4.cloudflare.com.     172800  IN      AAAA    2400:cb00:2049:1::a29f:837
ns6.cloudflare.com.     172800  IN      A       162.159.3.11
ns6.cloudflare.com.     172800  IN      A       162.159.5.6
ns6.cloudflare.com.     172800  IN      AAAA    2400:cb00:2049:1::a29f:30b
ns6.cloudflare.com.     172800  IN      AAAA    2400:cb00:2049:1::a29f:506
ns7.cloudflare.com.     172800  IN      A       162.159.4.8
ns7.cloudflare.com.     172800  IN      A       162.159.6.6
ns7.cloudflare.com.     172800  IN      AAAA    2400:cb00:2049:1::a29f:408
ns7.cloudflare.com.     172800  IN      AAAA    2400:cb00:2049:1::a29f:606
;; Query time: 163 msec
;; SERVER: 192.5.6.30#53(192.5.6.30) (UDP)
;; WHEN: Mon Sep 28 00:26:53 AWST 2026
;; MSG SIZE  rcvd: 573
Here, the .com nameserver provides in-domain glue records for cloudflare.com's nameservers. Without these, there would be a circular dependency, since the nameserver named is a subdomain of the domain being queried for. This is because nameservers are always defined by name, which means that in order to actually contact the nameserver, your computer needs to obtain its IP address with another DNS lookup.Next, we'd use one of these nameservers, say ns3.cloudflare.com, to obtain the IP for hera.ns.cloudflare.com:
$ dig @162.159.0.33 hera.ns.cloudflare.com
; <<>> DiG 9.20.29-1-Debian <<>> @162.159.0.33 hera.ns.cloudflare.com
; (1 server found)
;; global options: +cmd
;; Got answer:
;; ->>HEADER<<- opcode: QUERY, status: NOERROR, id: 16801
;; flags: qr aa rd; QUERY: 1, ANSWER: 3, AUTHORITY: 0, ADDITIONAL: 1
;; WARNING: recursion requested but not available
;; OPT PSEUDOSECTION:
; EDNS: version: 0, flags:; udp: 1232
;; QUESTION SECTION:
;hera.ns.cloudflare.com.                IN      A
;; ANSWER SECTION:
hera.ns.cloudflare.com. 86353   IN      A       108.162.192.162
hera.ns.cloudflare.com. 86353   IN      A       173.245.58.162
hera.ns.cloudflare.com. 86353   IN      A       172.64.32.162
;; Query time: 123 msec
;; SERVER: 162.159.0.33#53(162.159.0.33) (UDP)
;; WHEN: Mon Sep 28 01:11:37 AWST 2026
;; MSG SIZE  rcvd: 99
Querying the domain's authoritative nameserverNow we've reached the authoritative nameserver for example.com! The last thing to do is to fetch the A record for example.com to obtain its server's IP address:
$ dig @108.162.192.162 example.com
; <<>> DiG 9.20.29-1-Debian <<>> @108.162.192.162 example.com
; (1 server found)
;; global options: +cmd
;; Got answer:
;; ->>HEADER<<- opcode: QUERY, status: NOERROR, id: 43082
;; flags: qr aa rd; QUERY: 1, ANSWER: 2, AUTHORITY: 0, ADDITIONAL: 1
;; WARNING: recursion requested but not available
;; OPT PSEUDOSECTION:
; EDNS: version: 0, flags:; udp: 1232
;; QUESTION SECTION:
;example.com.                   IN      A
;; ANSWER SECTION:
example.com.            300     IN      A       104.20.23.154
example.com.            300     IN      A       172.66.147.243
;; Query time: 123 msec
;; SERVER: 108.162.192.162#53(108.162.192.162) (UDP)
;; WHEN: Mon Sep 28 01:13:47 AWST 2026
;; MSG SIZE  rcvd: 72
At last, we've determined that the IP addresses of the servers behind example.com are 104.20.23.154 and 172.66.147.243. This matches our earlier lookup directly against your computer's configured DNS server.The DNS servers your computer uses employ this recursive resolution technique behind the scenes, so that your computer only needs to make one round trip, and the servers can use their much faster data center connections and caching to optimize the process and make the query as fast as possible.
Verify your DNS recordsTo check your website's records, the first thing you'll want to do is ensure your domain name is pointed at the correct nameserver. For instance, aezign.com.au is supposed to use Cloudflare, since that is where all the DNS records have been set up. We can verify this using dig, (or alternatively with online tools like dnschecker.org):
If this is not set correctly, the DNS records you configure will not work, as resolvers will be fetching records from somewhere else. In most cases, you can update this in your domain registrar's settings. This is especially common for new domain names, which default to the registrar's nameservers; unless you plan to use their built-in DNS management, you'll need to point them to your chosen provider.Now we can check that the DNS records you've configured match those your DNS server returns. For aezign.com.au, these are the MX and TXT records configured on Cloudflare. The MX record and some TXT records configured for aezign.com.au on Cloudflare's dashboard.We can check these using dig, and using the +short option to show only the content of the records.
As we can see, this matches, which means that the nameservers for aezign.com.au are correct and the DNS records are what we intend them to be.Note that if you've recently changed the nameserver or DNS records for your domain, it can take anywhere between 10 seconds and 24 hours for the changes to take effect and propagate across the different DNS servers worldwide. Tools like dnschecker.org can check your records on different DNS servers worldwide to see if they're reflecting your changes. The reason for this is caching: DNS servers like 1.1.1.1 will cache results so it doesn't have to do the full resolution process every time, and uses the Time-To-Live (TTL) you configure in your DNS records as a guideline for caching duration.
There's an optical illusion known by names like the "lunar terminator paradox".
This has much discussion and descriptions online, but none made sense in my
head, so I wrote this program to figure out what was going on. The paradox:
The moon is illuminated by the sun
After sunset, the sun is below, so we would expect the illuminated portion of
the moon to point down, towards where the sun is
This isn't what always happens!
I was camping in the mountains with a friend recently. We were looking up at the
sky, just after the sun has set. The moon was clearly pointing up.
After playing with this program, I have clarity: we're looking up at the moon
from below. The most pathological case is a full moon. Let's say the moon is on
the horizon: elevation=0. If we're looking at this low moon, and the moon is
full, the sun is directly behind us. The moon is fully illuminated, and we see
100% of the moon disc lit up.
Now, what happens if the moon is not at the horizon, but higher up at the sky?
Effectively, the sun is infinitely far away, so the same part of the moon is lit
up. But we're now looking at the moon from below, and we would see some of the
dark side on the bottom edge. I.e. the moon appears bright at the top, but has a
dark slice missing at the bottom: it points up! Even at sunset.
This is the most clearly weird case. A half-moon has no paradoxical behavior,
and the more full the moon, the more clearly we can observe the bright moon
pointing up despite the sun being down.
I produce two plots. At 3/4-full moon at sunset we look at the moon as it rises
from the horizon all the way up to the zenith:
If the moon is at the horizon (elevation = 0), we see the expected 3/4-lit disc.
As the moon rises, we see more and more of its bottom, and thus more and more
dark areas show up: It clearly points up at sunset!
We can also move the sun around. Let's say the moon is 60deg up; let's move the
sun from new-moon to a full-moon:
In the darkest configuration, we can still see a lit crescent on the bottom: the
illumination is all on the opposite side, but we can see a slice of the
illuminated back side. As the sun swings around, we see more and more of the
moon. At azimuth = 90deg, we have a half-lit moon. Past that, more and more of
the moon is visible, always pointing up.
This was also a super interesting study of the current state of AI tools. As I
was writing this and debugging, I would talk to Claude and Gemini about how this
worked and what I should be seeing. They were both completely unable to
comprehend this, and would make infinite circular arguments. Clearly they read
some incomplete explanations on the internet (as I have), and lack the reasoning
capability necessary to distill it into something resembling "understanding".
AGI is not here yet.
Welcome to post 60 in the R4 series.
bubblewrap is
a great tool and very suitable for using with an agent harness. It is a
very compelling and lightweight alternative to using a full-blown docker container as it offers
low-level unprivileged sandboxing on Linux hosts.
In a nutshell, bubblewrap can turn
everything off (see unshare-all below) and allow access
only to selected services and directories (as shown below). This makes
it a very useful tool be used on a main workstation as it can provide a
lower-risk deployment quite easily while taking advantage of the already
installed software stack. I continue to get a lot of value out of docker, especially as r2u makes installing R
package dependencies so trivial. Its slogan easy, fast, reliable: pick
all three clearly holds for r2u. But sometimes bubblewrap is
compelling, for example to launch opencode (documented for example at the
debian-inference
site).
When using R we need add more
directories to the example to provide /etc/alternatives
which is governing inter alia the LAPACK / BLAS resolution on
Debian / Ubuntu systems; this is now on debian-inference
site but wasn t when I first tried it a few days ago ;-) as well as
/etc/R for config files and possibly
~/.R/Makevars for compiler settings. With that my current
wrapper is
Launched that way we can have agents use R to check packages sources,
builds, and triage for bugs. this works equally well with local models
served via ollama (and with that a
quick shoutout to packages.lingfish.net for
providing an apt service for ollama) as it does with the various
cloud-based offerings. So harness away with R!
A library transition can affect
many packages in Debian. I added a way for Salsa CI to rebuild the ones that
depend on the changing library, so maintainers can test the transition before
it reaches unstable.
The need for this became clear during a proposed
Poppler transition. Poppler is a library
for rendering PDFs. The reverse-dependency job I had added to Salsa CI queued
100 of 115 candidate rebuilds, even though only about 21 were relevant.
The problem was documented in issue
#571.
Before this change, ratt used every binary package produced by Poppler to
decide what to rebuild. That also picked up packages unrelated to the library
transition. The tracker listed the old and new library package names, so I used
them to focus the selection.
The Poppler transition tracker identifies the old and new runtime library package names.
I added -transition_affected to
ratt to implement this selection. The
option performs the scan against the selected archive indexes and injects
locally built .deb files into each source rebuild. It expects a regex of
dependency package names, not a complete Ben expression, so the tracker s
Affected expression must be adapted first.
I then integrated the mode into Salsa
CI.
Maintainers can enable transition-aware
rebuilds
by setting SALSA_CI_BUILD_REVERSE_DEPENDENCIES_TRANSITION_AFFECTED_REGEX. If
the variable is unset, the pipeline keeps the existing selection.
A Poppler test showing the selected rebuild jobs. Three jobs reached the CI timeout, they were not confirmed package regressions.
I also changed ratt to cover
packages targeting
experimental. By default, it
resolves and rebuilds reverse dependencies from unstable while still injecting
the locally built .deb files. This lets a maintainer test a transition staged
in experimental against packages currently in unstable.
Together, these changes help maintainers focus CI on packages relevant to a
library transition and review rebuild results before the new library reaches
unstable.
Ode to the Half-Broken is a standalone post-apocalyptic (sort of)
science fiction novel.
As this novel opens, the unnamed first-person protagonist is waking up in
a bathtub in an abandoned building. They are covered in electromagnets and
missing one leg.
Waking up involved a secure reboot from a protected core kernel, so it is
immediately obvious that the protagonist is a robot. That also explains
the electromagnets, which interfere with their ability to control their
body. Or they would, if the protagonist didn't have long-dormant combat
routines available to deploy EM shielding and free themselves from the
bathtub. There are no immediate answers to why someone embedded a virus in
the data attached to a scientific paper on ants, an act so precisely
targeted that it had to be personal. Or what happened to their leg.
"There are a number of electromagnets in the next room," I say. I
point. "Behind that wall with all the holes in it."
"Those are big holes. And fresh, too," the dog says. "I wonder what
made them."
"Electromagnets experiencing sudden velocity."
The dog gives another of its short barks, and I am more convinced now
it is laughing, though I was not attempting to be funny.
Ode to the Half-Broken has a classic science fiction beginning:
in medias res in a future science fiction version of Earth where
nothing is immediately explained, leaving the reader to work out the date
and the setting. Helping us out is the protagonist, who is neither chatty
nor very sociable with other characters but keeps up an analytical
monologue about the world as they narrate events.
We are some decades into a grim future. The United States has largely
collapsed. Large parts of New York City are dangerous to humans due to
disease and radiation. Neither of those hazards bother the large number of
sentient robots; their scarcity, and therefore economy, is instead based
on power. Robots that control solar power stations act as low-level mob
bosses, trading power for information or labor.
Our protagonist doesn't want to care about any of this. They retreated
from the world long ago for a solitary life in the former New York
Botanical Gardens studying ants. But they need a new leg and the best
robot repair person nearby is a human woman outside of the city, so they
reluctantly head in that direction, accompanied somewhat surprisingly by a
cyborg dog.
The typical science fiction apocalypse is caused by something specific.
Classically, that event is a nuclear war, but writers found various
alternatives before, during, and after the Cold War era:
alien invasions,
meteor
showers, plagues,
sea level rise, and peak oil and general environmental collapse, among many others. Less
common is a post-apocalyptic novel where the collapse comes from multiple
overlapping crises and accumulating failures, from a general failure to
meet what Adam Tooze and others call
polycrisis. The first
time I encountered that style of post-apocalyptic story was in Octavia
Butler's Parable of the Sower. It was
one of the choices that made (and still makes) that book feel so
chillingly realistic.
The world background in Ode to the Half-Broken is shaped by that
sort of polycrisis collapse. There is no one reason why New York City is a
dangerous, irradiated ruin and society has collapsed into isolated and
sometimes warring factions. It is not runaway artificial intelligence, or
at least not directly; sentient robots were a late-stage innovation of the
collapsing US civilization and a tool and accelerator of its many wars,
but they were not the cause and may be a critical ingredient in building
some functional replacement. Instead, society fell apart because we failed
to address any of the growing problems and then turned on each other in
the resulting ruins. The reader gets an idiosyncratic view of that
collapse in flashback chapters intermixed with the main narrative of the
initially unnamed robot protagonist, flashbacks told from the perspective
of the man who invented the key component for robot sentience. As you
would expect, those two narratives are linked. The reader will not
discover how they are linked until late in the story.
This book could have been extremely depressing. It is not, which says a
great deal about Palmer's skill in telling it. The clinical distance of
the protagonist in the early chapters helps considerably: They have
rejected involvement in this world and therefore can describe it in
detached, factual terms, aided by the tendency of most robots in this
story to be slightly more precise, logical, and verbose than the human
characters. But as the protagonist's clinical distance fades, as it must
to allow the story's emotional stakes to rise, Palmer fills this book with
moments of beauty and hope. A former nuclear submarine that has become the
mind of a subway car is a key early ally. A collective has turned the
Hudson Bridge into a thriving if chaotic community. Self-regulating
enclaves of humans and robots are working together to try to build a
livable world. Robots oversee pollinator swarms that are attempting to
restore plant life, for no reason other than that they like order and
stability and see this as a way of restoring both. This is a grim,
post-apocalyptic world that does not dwell on either the grimness or the
apocalypse. It is instead full of small moments of hope, collaboration,
and personal connection.
This is a story with villains, danger, pain, and risk. Despite the similar
keywords and cover aesthetics, it bears little resemblance to Becky
Chambers's philosophical Monk and Robot series.
It is not, in any definition of the term, cozy; it's a post-apocalyptic
adventure story about a robot and a dog making their way through a ruined
civilization and fighting people who are trying to build something even
worse on the rubble. But it's also charming and oddly happy. There are
strong found-family vibes in the way that a party coalesces around the
protagonist and eventually gives them a name, there is the quiet happiness
of seeing a grumpy misanthrope slowly come out of their protective shell,
and the rail mechs are an absolute delight.
Like a lot of stories of happy small-group anarchism, I didn't entirely
believe the politics and have some qualms about the realism of the ending,
although perhaps I should strive to be as optimistic as Palmer writes. The
somewhat dry and fussily precise first-person narration will also not be
to everyone's taste; it worked for me by the end of the book, but it took
a bit of reading to get used to it. But those quibbles aside, this was
quietly lovely. It's a satisfying science fiction adventure story in a
world with disturbing parallels to the one we're living in, but which uses
those parallels to focus on small-scale collective efforts to build
something better. And all the small details of the world-building are
delightful: the different tiers of robots and their odd behaviors, the
machine sense of purpose, even the mix of suspicion and generosity. The
plot has large-scale implications, but it was the human-level details that
charmed me.
I still want another Fergus novel, but this was
a highly successful foray outside of that series. Palmer has won two Hugos
for her novellas, so I can't really say she's overlooked, but her novels
aren't getting anywhere near the attention they deserve. Highly
recommended.
There is plenty of world-building room here for a sequel, but Ode to
the Half-Broken reaches a satisfying standalone conclusion. So far as I
know, no sequel is currently planned.
Rating: 8 out of 10
The diffoscope maintainers are pleased to announce the release of diffoscope
version 331. This version includes the following changes:
[ Chris Lamb ]
* Support radare2 >= 5.9.0. (Closes: reproducible-builds/diffoscope#432)
* Update debian/tests/control.
* Update copyright years.
[ Christopher Baines ]
* Add support for .nar files via Guix.
A new release 0.0.5 of the RcppFastAD package
is now on CRAN, has been built
for r2u, and updated
at r-universe.
This comes (to the day) two years after the preceding 0.0.4 release.
RcppFastAD
wraps the FastAD
header-only C++ library by James which provides a C++
implementation of both forward and reverse mode of automatic
differentiation. It offers an easy-to-use header library that is both
lightweight and performant. With a little of bit of Rcpp glue, it is also easy to use from R
in simple C++ applications. This release updates the continuous
integration setup as one does, adds a local configuration helper to
quieten compilation (described also in this
blog post). It also adds a defensive setting for g++:
Under recent g++ versions and optimisation at least the -O3
level, segfaults are seen as something is not quite right with
(temporary) views of Eigen objects in code generated by this versions.
Others are fine, as is clang++. We have not gotten to the
bottom of it, but setting -g0 seems to ensure that builds
generally work.
The NEWS file for this release follows.
Changes in version 0.0.5
(2026-09-24)
Several routine updates to continuous integration have been
made
Local builds (where a .git/ directory is seen) now
append silencing compiler option that CRAN would object to
Given recent issues with g++ under optimization,
debugging is turned off by default.
Who?
Fre(i)e Software GmbH is looking for a senior Golang + fullstack developer who can handwrite code and act as meticulous code review partner for another senior developer in the company.
What?
Most of your work would result in Open Source contributions to the Voxit project [1], an online civic tech tool for digital participation.
How and Where?
The work can either be delivered on project agreement base via freelancing or via employment (option only available to developers resident in Germany, Austria or Poland).
What next?
If you are interested, please get in touch and provide your hourly rate to us and your average hours of availability per week.
[1] https://gitlab.com/voxit/
In 2016, I removed Google Analytics from this blog to avoid being
complicit in feeding the biggest machine for harvesting personal data. Instead,
I relied on GoAccess to analyze my server logs.1 For the past couple
of years, the statistics have made no sense, despite my attempts to filter bots:
AI scrapers inflate the number of visitors to around 2,000 per
day. Eventually, I settled on GoatCounter, an open-source, privacy-friendly
web analytics platform. I replaced the JavaScript client to filter bots more
aggressively and added a CSS fallback. To improve reliability, I implemented a
local proxy running on each of the five web servers serving this blog. The rest
of this post details how these pieces fit together and how I deploy them on
NixOS.
Why GoatCounter?
GoatCounter does not collect personal data: instead of storing the reader s
IP address or relying on cookies, it creates a session identifier valid for 8
hours from the user agent and the IP address. Its feature set is modest but
sufficient for a blog. If you want to look at the interface, GoatCounter s
author runs a public instance for his site. A hosted
version lets you try it before running your own instance. With a single binary
and an SQLite database, GoatCounter is one of the lightest self-hosted
solutions. Privacy-friendly alternatives, in increasing order of complexity,
include Umami, Plausible, and Rybbit.
Custom JavaScript client
GoatCounter includes a small JavaScript client 2,189 bytes minified and
gzipped. It ships some features I don t use: a visitor counter, tracking clicks,
configurable settings, etc. I replace it with this function to register a hit:
If a reader has disabled JavaScript in their browser, I record the hit using a
CSS image. The :hover pseudo-class loads it only after an interaction, another
trick stolen from Bear Blog. About 2% of my visitors fit into this
bucket.3
<!DOCTYPE html><htmllang="en"class="nojs"><head><script>// The JavaScript code for this blog requires ES6if("noModule"inHTMLScriptElement.prototype)document.documentElement.classList.remove("nojs");</script></head><body><!-- ... --><style>.nojsbody:hoverborder-width:0;border-image:url('/count?p=/en/blog/2026-kpi-goodhart&t=Building...&r=NoJS&e=false');</style></body></html>
Where GoAccess reported around 2,000 visitors a day, GoatCounter counts fewer
than 200 humans.4 I assume AI scrapers use a low-effort approach: if the
content is available without barriers, as on this blog, they don t spawn a
complex mechanized browser that could trigger a page view. Even crawlers running
JavaScript, like Googlebot with its headless Chromium, do not
interact with the page and never trigger the events I listen
to. The interaction-based proof of humanity I use is likely to keep
working.5
Local proxy
Five servers across the world in Europe and in North
America serve the content of this website, but GoatCounter runs on only
one of them. To avoid losing track of visitors when GoatCounter is down, I run a
local proxy listening on the same /count endpoint. On each server, it stores
the hits in memory with a buffer large enough to survive several days of
downtime. It sends them in batches to the upstream backend using the
/api/v0/count authenticated endpoint.
Servers on a map. web02 is in Paris, web03 in Helsinki, web04 in Nuremberg,
web05 in Ashburn, web06 in Chicago.
I proposed the code for the proxy in pull request #909. GoatCounter s
maintainer declined to maintain so much code for such a niche use case. As a
fellow open-source developer, I often hold the same position for my own
projects: a one-time contributor effort may translate into a long-term
maintainer commitment.
I expose the endpoint for the proxy on the domain of this website to evade ad
blockers. This sounds like I don t respect the reader s choice, but as
GoatCounter is privacy-friendly, I find it acceptable.
Deploying on NixOS
My web servers run NixOS, a declarative Linux distribution with built-in
configuration management. I manage this small fleet with Colmena, a
stateless deployment tool for NixOS. My configuration is available on
GitHub.
Deploying applications in containers
For better isolation, each application runs inside an ephemeral lightweight
container, powered by systemd-nspawn. Each container runs a stripped-down
NixOS instance. A module wraps NixOS s containers options to
avoid repeating the same options for each application.6 The containers
share their network namespace with the host: the additional isolation is not
worth the increased complexity. For a smaller footprint, I also disable a few
non-essential services.
To configure a GoatCounter instance running in a container and listening on
127.0.0.4:8088, we import the module7 and declare the container in the
config.luffy.containers attribute set:
As the containers are ephemeral, we need to keep persistent data in directories
on the host. We add a mounts option and ask NixOS s containers to expose the
configured directories through the bindMounts option.
For example, to persist GoatCounter s database in the /var/db/goatcounter
directory on the host, we add the directory to the mounts option and alter the
service definition to tell GoatCounter where the database is.
A container may also need some secrets. Colmena can upload secrets without
storing them in the Nix store. We add a keys option to our containers. It
takes an attribute set mapping secret names to the commands to populate them.
Then, the module declares the required secrets to Colmena in the
deployment.keys option, makes the container depend on the presence of the
secrets, and exposes them to the container.
config, lib,... :letcfg= config.luffy.containers;in
options.luffy.containers= lib.mkOption type= lib.types.attrsOf (lib.types.submodule options=keys= lib.mkOption type= lib.types.attrsOf (lib.types.listOf lib.types.str);default= ;description="Secrets, as a command to run locally. They are mounted in /etc."; ; ; ); ;config=# Colmena uploads each secret in /var/keys and make them available# to the group "keys".
deployment.keys= lib.concatMapAttrs
(_: container: lib.mapAttrs
(_: keyCommand:inherit keyCommand;group="keys";permissions="0640";destDir="/var/keys"; )
container.keys)
cfg;# The container can only start if the required secrets are available.
systemd.services= lib.mapAttrs'
(name: container:letunits=map(key:"$ key-key.service")(lib.attrNames container.keys);in
lib.nameValuePair "container@$ name"requires= units;after= units; )
cfg;# Mount each secret inside the container.containers= lib.mapAttrs
(name: container:bindMounts= lib.mapAttrs'
(key: _: lib.nameValuePair "/etc/$ key"hostPath="/var/keys/$ key";isReadOnly=true; )
container.keys; )
cfg; ;
For example, GoatCounter needs credentials to download the GeoIP database. I
provide a local command to fetch the secret from my password manager and expose
it inside the container through the /etc/goatcounter.env environment file.
GoatCounter server
Nixpkgs already packages GoatCounter. By overriding the src and vendorHash
attributes, I reuse its definition for my custom version with the proxy:
I wrote a NixOS module to encapsulate GoatCounter: the
container definition, the service definition, and the secrets. The module
accepts the following options: package, serve.enable, serve.listenAddress,
serve.port, and serve.databaseFile. I already detailed the container
configuration in the previous section. In the end, I chose not to reuse the
GoatCounter module from NixOS: it s small, so it s better to insulate my module
from unexpected future changes.
config, pkgs, lib,... :letcfg= config.luffy.goatcounter;databaseDirectory=builtins.dirOf cfg.serve.databaseFile;chown="$ pkgs.coreutils/bin/chown -R";in
config.luffy.containers.goatcounter=
config.systemd.services.goatcounter=description="GoatCounter Web Analytics";wantedBy=["multi-user.target"];serviceConfig=EnvironmentFile="/etc/goatcounter.env";SupplementaryGroups=["keys"];DynamicUser=true;Restart="always";ExecStart= lib.escapeShellArgs [(lib.getExe cfg.package)"serve""-listen=$ cfg.serve.listenAddress:$ toString cfg.serve.port""-tls=none""-db=sqlite+$ cfg.serve.databaseFile""-automigrate"];# Transfer database ownership to dynamically assigned user "goatcounter".ExecStartPre="+$ chown goatcounter:goatcounter $ databaseDirectory";ReadWritePaths= databaseDirectory; ; ; ;
The following snippet configures GoatCounter to listen on 127.0.0.4:8088:
GoatCounter proxy
The same NixOS module configures the local proxy, with the
following options: proxy.enable, proxy.listenAddress, proxy.port, and
proxy.site the site receiving the batches of page views. The local proxy has
no persistent data, but it needs the API key to authenticate to the main
GoatCounter instance: its container uses the keys option but not the mounts
option.
config, pkgs, lib,... :letcfg= config.luffy.goatcounter;keyCommand= _:[" "];in
config.luffy.containers.goatcounter-proxy= keys."goatcounter-proxy.env"= keyCommand "GOATCOUNTER_API_KEY"; config.systemd.services.goatcounter=description="GoatCounter Proxy.";wantedBy=["multi-user.target"];serviceConfig=EnvironmentFile="/etc/goatcounter-proxy.env";SupplementaryGroups=["keys"];DynamicUser=true;Restart="always";ExecStart= lib.escapeShellArgs [(lib.getExe cfg.package)"proxy""-site=$ cfg.proxy.site""-listen=$ cfg.proxy.listenAddress:$ toString cfg.proxy.port""-ratelimit=10/1"# 10 requests per second per IP]; ; ; ;
For each server, I enable the local proxy with the following snippet. The
nginx configuration shown earlier exposes the /count endpoint under the same
domain as my blog.
Backup of the SQLite database with Litestream
Litestream is a streaming replication tool for SQLite databases. It
compresses the changes committed to the write-ahead log (WAL) next to the
database and sends them to a remote destination. I encapsulate its configuration
in a NixOS module, which takes an attribute set databases
mapping a name to the path of the database to back up.
Litestream also runs in a container. I mount the databases to replicate, as well
as the secrets to push the backups to a Hetzner storage box using SFTP:
We can restore the database from the backup with a few shell commands. First, we
stop the containers. Then, we move the damaged database away, invoke litestream
restore from the right environment, and restart the containers.9
Ten years after removing Google Analytics, JavaScript-based analytics is
back on this blog, but without storing cookies or IP addresses, and without
involving a third party. I still write for myself first, notably because it lets
me dig into a topic and refer back to it years later. But knowing a bit more
about my fellow human readers is a nice bonus, even the ones disabling
JavaScript.
Nginx scrambles IP addresses before storing them, thanks to the ipscrub
nginx module.
GoatCounter already filters some bots based on the user agent or the IP
address. But AI scrapers lie about their user agent and hide behind
residential proxies.
Without JavaScript, I cannot send the real referrer. I insert NoJS
instead.
I am missing the humans reading the RSS feed. I am not comfortable adding a
tracking pixel, and bots are likely to fetch it, compromising the
statistics. I ll live without counting these readers.
In February 2025, I tested another CSS-only approach without the interaction
trick: each page loaded an empty image as a background. Over a month, it
recorded up to ten times fewer page views than the nginx logs, even after
removing user agents identifying as bots. Compared to this experiment,
GoatCounter counts about three times fewer views, 18 months later. As the
time ranges differ, this is not an apples-to-apples comparison, but it gives
a hint about how efficient bot filtering is.
A NixOS module is a function receiving the configuration of the whole
system as config and returning three attributes:
imports adds other modules to import,
options declares user-configurable settings, each with a type and a default value, and
config sets values for options declared by any module, like containers from NixOS.
If a module does not need to declare options, you can return the config attribute
set directly. When a module does not require any argument, you can define it as an attribute
set instead.
Most of the time, you don t need an explicit import. NixOS automatically
imports the modules shipped with Nixpkgs. For my own
modules, some machinery also imports them automatically.
Litestream warns against using the auto-recover option as
it can cause data loss. But I don t properly monitor my servers and I prefer
uninterrupted backups to a slight chance of losing the last few records.
In my case, the process is slow: around 20 minutes for a 20 MiB database.
You can test by restoring to a copy with the -o option, but you still need
to stop the Litestream container.
Lots of posts in the debian-user mailing list complaining about updates with Debian 11.11 suddenly failing.
See Debian 11 Long Term Support reaches end-of-lifeAugust 31st, 2026
The Debian Long Term Support (LTS) Team hereby announces that Debian 11
bullseye support has reached its end-of-life today, 31 August 2026,
five years after its initial release on 14 August 2021.
Starting in September, Debian will not provide further security updates for
Debian 11. A subset of bullseye packages will be supported by external
parties. Detailed information can be found at
Extended LTS.
The Debian LTS Team is currently providing security support for Debian 12
bookworm, the current oldstable release. Thanks to the combined efforts
of different teams including the Security Team, the Release Team, and the LTS
Team, the Debian 12 life cycle encompasses five years.
Debian 12 will receive Long Term Support until 30 June 2028. The supported
architectures in Debian 12 LTS are amd64, i386, arm64, armhf and ppc64el.
For further information about using bookworm LTS and upgrading from
bullseye LTS, please refer to
LTS/Using.
Debian and its LTS Team would like to thank all contributing users, developers,
sponsors and other Debian teams who are making it possible to extend the life
of previous stable releases, and who have made Bullseye LTS a success.
If you rely on Debian LTS, please consider
joining the team,
providing patches, testing or
funding the efforts.
Activity summary
During the month of August, 19 contributors have been
paid to work on Debian LTS (links to individual
contributor reports are located below).
The team released 58 DLAs fixing 1885 CVEs.
Debian 11 ( bullseye ), which
has reached the end of its Long Term Support on 31 August 2026, will
now get security support from Freexian under the
Extended LTS offer.
The team published several notable updates:
chromium
(DLA 4710-1),
uploaded by Emilio, to fix 375 security flaws in bookworm, including
issues that could lead to arbitrary code execution.
Further DLA 4728-1,
uploaded by Emilio as well, fixed additional 41 security issues in bookworm and
DLA 4739-1
fixed 5 issues.
Last but not least,
DLA 4749-1
fixed another 15 issues and
DLA 4758-1
fixed another 7 issues.
ruby2.7
(DLA 4716-1),
uploaded by Abhijith, to fix four security flaws in bookworm, including
issues that could lead to arbitrary code execution.
several DLAs
(DLA 4717-1,
DLA 4720-1,
DLA 4723-1,
DLA 4724-1,
DLA 4745-1)
have been uploaded by Ben and Emilio to fix myriad security flaws in
different versions of the linux kernel
(5.10.262-1, 6.1.180-1, 6.12.100-1~deb12u1, 6.12.101-1~deb12u1)
in bullseye and bookworm.
7zip
(DLA 4718-1)
and p7zip
(DLA 4719-1),
uploaded by Sylvain, to fix multiple security flaws in bookworm and
bullseye, including issues that could yield to remote code execution.
ca-certificates
(DLA 4726-1),
uploaded by Bastien to add some new trusted certificates to bookworm and bullseye,
but also remove some untrusted ones.
thunderbird
(DLA 4727-1
and DLA 4754-1),
uploaded by Emilio to fix 35 and 31 issues in bookworm and bullseye.
nss
(DLA 4729-1),
uploaded by Jochen to fix a vulnerability in bookworm and bullseye that could
yield to arbitrary code execution.
libgd2
(DLA 4731-1),
uploaded by Guilhem to fix a vulnerability in bookworm and bullseye that could
yield to arbitrary code execution if a malformed GIF file is processed.
xorg-server
(DLA 4737-1
and DLA 4738-1),
uploaded by Arnaud to fix several vulnerabilities in bookworm and bullseye.
postgresql-15
(DLA 4740-1),
uploaded by Carlos Henrique Lima Melara to fix 26 vulnerabilities
in bookworm.
unzip
(DLA 4741-1),
uploaded by Andrej to fix a vulnerability in bookworm and bullseye
that could yield to arbitrary code execution.
firefox-esr
(DLA 4750-1),
uploaded by Emilio to fix 31 vulnerabilities in bookworm and bullseye
that could potentially result in arbitrary code execution, privilege escalation
or information disclosure.
nvidia-graphics-drivers
(DLA 4752-1 and
DLA 4753-1),
uploaded by Tobias to fix lots of vulnerabilities in bookworm and bullseye.
roundcube
(DLA 4760-1),
uploaded by Guilhem to fix ten vulnerabilities in bookworm and bullseye
that could potentially result in remote code execution or information disclosure.
Contributions from outside the LTS Team:
We are greatly thankful for the contributions from people outside the LTS Team:
Salvatore Bonaccorso released a libyaml-syck-perl security update
(DLA 4730-1),
to fix a denial of service and potentially arbitrary code execution.
Thomas Goirand released a neutron security update
(DLA 4735-1).
Thomas Goirand released an ironic security update
(DLA 4743-1).
Thomas Goirand released a designate security update
(DLA 4751-1),
to fix a denial of service or DNS hijacking.
The LTS Team has also contributed with updates to the latest Debian releases:
xrdp
(DSA 6469-1),
prepared by Abhijith to address privilege escalation and arbitrary
code execution related flaws.
Other contributions:
Besides the work on security updates, different documentation and tooling
changes were needed. This work was mainly done by Sylvain.
Introduction
After bazel-bootstrap 7.7.1 was landed into Debian unstable,
I'm working on packaging newer Mozc (Most famous Japanese input method editor) with Bazel.
Here is the blog entry initial efforts to build Mozc with Bazel at that time.
kenhys.hatenablog.jp
Then, I've shared implementing PoC dh-bazel experiment.
See why dh-bazel is needed, and prototype about dh-bazel.
kenhys.hatenablog.jp
As a Bazel beginner, want to know what should pass to Bazel, what should not pass to Bazel.
What is improved in recent dh-bazel?
In the previous versions of dh-bazel, it supports only basic features
to build with Bazel as a thin wrapper.
Now, with recent changes, it supports the following environment variables to resolve required system libraries in dynamically.
salsa.debian.org
DH_BAZEL_OVERRIDE_MODULE
It search the specified modules from bundled dummy modules in dh-bazel.
It accept ',' separated paramesters. (e.g. DH_BAZEL_OVERRIDE_MODULE=zlib,zstd)
dh-bazel bundles abseil-cpp, apple_support, buildozer, lz4, openssl, protobuf, rules_android_ndk, rules_apple, rules_swift, zlib and zstd as
dummy modules to linking system libraries.
Now you can use it in debian/rules like this:
It is impossible to cover all of system libraries in Debian, so in that case, please consider to use the following DH_BAZEL_PKGCONF_MODULE.
DH_BAZEL_PKGCONF_MODULE
It search the specified modules with pkgconf. It is useful when there is no bundled modules in dh-bazel if you want.
It accept ',' separated paramesters. (e.g. DH_BAZEL_PKGCONF_MODULE=gtk4-x11,gtk4-unix-print).
If DH_BAZEL_PKGCONF_MODULE could not match, then dh-bazel fallback to dig into Build-Depends: field
in debian/control. Note that if it is not deterministic (e.g. -dev package provides multiple .pc files)
dh-bazel gives up fallback with pkgconf.
Now you can use it in debian/rules like this:
Conclusion
dh-bazel is still in very early stage prototype, but it resolves some sort of packaging glitches a bit by bit.
I hope that it will help package maintainer using Bazel.
(dh-bazel is not uploaded into debian/unstable yet, so stay tuned!)
As a graduate of a liberal arts university, I wound up, unsurprisingly, taking a
lot of classes in every possible academic discipline. Thinking back to the
person that I was going into university, I don t think I would have chosen to
take them after all, my degree was in the sciences; I d have been stoked to
do nothing more than wall-to-wall computer science until I ran out of
coursework and filled the rest of my hours with research and independent
studies with my professors (which, I guess I did actually do, just not as
much as I would have otherwise).
Even this blog s CSS theme (now 18 years old and starting to look it) was
something I wrote after receiving and repeatedly re-reading a tattered
third-hand copy of The Laws of Thought by George Boole. It was gifted to me
by a college friend majoring in philosophy while I was crashing at his rental
on the beach. He gave it to me because he knew I liked that shit and, while
it was definitely computer science in nature, I would not have read it
otherwise. I have vivid memories of sleeping on his la-z-boy surrounded by
towers of books he was working through. He went on to do incredible work,
getting his PhD, doing research, brilliant writing his death in 2023 has
robbed humanity of more time with him. The Laws of Thought sits behind me in
my office, and is one of my most valued possessions.
My friends mean more to me than I could ever express, and I definitely don t
show it enough. Each of my classes made me a more thoughtful person. My
professors made me a better, more well-rounded person and a person who
attempts to live up to the oft repeated credo of being men and women for
others . I did the best I could, even though I was never a particularly good
student. Without liberal arts, I don t think I would, dispositionally, have
been capable of pushing myself to this day to continue to learn on nights
and weekends, for no reason other than wanting to learn. I refuse to stop
expanding my perspective, and do my best to approach new problems with as much
humility and curiosity as I can muster.
Every few days for the last year or so, I have been thinking back to a reading
assignment from my junior year that, at the time, I thought was a borderline
throwaway filler assignment for the class. The reading is an essay from 1947 by
the french existentialist philosopher and libertarian marxist, Jean-Paul Sartre
(as some of the more erudite may have now already worked out given the blog s
title), Why Write? . I re-read it this week. It is not filler. I remember this
essay better than some of the classwork I considered more important at the
time.
Why Write?
Why Write? starts off by describing the ways in which writing trying to
communicate your thoughts, opinions, or feelings to others is an act of
projection. The writer will only ever draw from a place of their own
subjectivity writing is taking your person and putting it on display.
You re choosing what words to use, how to use them, pulling from knowledge
you ve accumulated (based on how you ve chosen to spend your time). Spending
any amount of your finite existence in order to convey a thought is, itself,
announcing to the world that you believe it to be a thought worth sharing.
Meanwhile, the act of reading is not simply turning letters into words.
Reading is engaging with the work, and understanding the work in a process
that looks more like what Sartre terms re-invention or discovery the
literary object, though realized through language, is never given in
language . It is not enough to read the words in a book end-to-end; you must,
as a reader, actively engage with the work to understand what is being
communicated by those words. Reading is to take the words on the page, and
exceed the mere words through what he calls directed creation . The reader
is re-inventing / discovering the writer s thoughts by following their
landmarks in the void .
And this all makes pretty good sense to me I know if someone is being
sarcastic because I know the writer; I have read their words and have read
into their words, allowing myself to be directed by the writer into
discovering the thought they have left me in their work. I understand that
their words are humorous, not irate. Knowing who the author of a work is
can completely change the point of a sentence. The fact I m writing about
Sartre at all, or that this very writing has been constrained for presentation
in this blog s CSS is only happening because of who I am, what things I ve
experienced in life, and what has made me, me. Sartre argues that this dyadic
coupling between writer and writing means that I, as a writer, can never truly
read my own writing. I will never be capable of reading my own work and
getting something out of it the work is already an extension of my own
person. I can discover no thought in my own works.
Of course, Sartre, as an existentialist, is honor bound to go one step further
here the reader, by participating in reading a work, is asserting their
own freedom. Every time a writer writes [ ] the writer appeals to the
reader s freedom to collaborate in the production of [their] work . The
creative act may only be complete if both writer and reader have recognized one
another and made a choice to do so. No one is compelled to complete the
creative act. The things you read matter. Reading something fundamentally
alters you as a person you can not simply un-read a thought. Everything you
read changes your universe. I have a hunch Sartre would find things like the
(original early 2010s era) tl;dr reply to obviously terrible writing
absolutely hilarious as a reader s expression of freedom (not to be confused
with modern 2020s era usage as shorthand for summary section ). Using your
freedom to choose to complete the writer s creative act (or not) is inherently
asserting your humanity.
I m a bit fuzzy on the specifics of this quote, but I think it was
sj who told me at one year s
Mystery Hunt that A puzzle is a contract between
puzzle author and puzzle solver, the author promises that the puzzle is
solvable if you re clever enough . The puzzle author and puzzle solver are
engaging in a collaborative production of the work that is only possible by
recognizing one another. Similarly, Sartre whatever connections [the
reader] may establish among the different parts of the book among the chapters
or the words [the reader] has a guarantee, namely, that they have been
expressly willed .
Wall Drawing #123
It follows, Sartre argues, that the act of writing, as a means to convey a
thought to a reader, may only be completed through the act of reading.
Reading can only be done by others; writing, therefore, only exists to be
read it can serve no other purpose. Writing and reading are two halves of
the same creative, collaborative act, only satisfied when both writer and
reader acknowledge one another. Combined, writing and reading are the act of
recognizing one another s humanity, thoughts, experiences, consciousness the
act of co-creation of thought is the critical aspect of writing and reading
reconstructing the author s perspective, thought, intent, point. The
co-creation is the point of both reading and writing.
Writing without anyone to read the work leaves the writer s bid for
co-creation unsatisfied and humanity unrecognized. No thought has been conveyed
to any reader, no one has understood the reason behind the landmarks in the
void you ve carefully placed, leaving you to either [ ] put down [your] pen
or despair . Writing is an appeal to the reader s freedom, and the nature of
that freedom is the writer can not control it never being understood is
always a possibility any time anyone sets out to write.
Nearly 12 years ago, I attempted to read the text on the git manpage
generator for the first time
I remember the exact feeling of my brain going into git manpage parsing
mode where every word was dragging git plumbing megaliths through the sand
from their far-flung homes. I can still feel the surface of my desk as I
instinctually started to trace out logical connections between git internals
referenced as I read along. It took me a good 20 seconds to realize what I was
reading made no sense. This website broke Sartre s writer-reader agreement I
was attempting to read this website, but there was nothing there. You can
mechanically read the git-man-page-generator, but you can never read it
it is not possible to read it. It was funny unsettling. Each grasp at a
real-looking image in front of me misses, my hand coming back empty. I
couldn t get enough of it. I must have tried to read a dozen generations in a
row. I had never had something quite that broken pass that far into my
consciousness before. Although I kept trying, it never did feel quite the same
as that first time; I think fundamentally, I couldn t forget that it was
random.
While never having anyone read your writing drives them to put down your
pen or despair , Sartre never had to contend with the opposite problem being
asked to read that which was not written. Reading that which was not
written does not merely leave someone unrecognized when a reader makes a
choice; instead, it is an inherent violation of the contract between reader
and writer. Not only is no humanity being recognized through attempting to
read words which were not written, but the reader, not the writer,
is the one who bears the burden of unexpected apophenia. The reader,
while engaging in co-creation, must now contort themselves to uphold their end
of the Sartrean agreement, scrutinizing text to ascribe consciousness,
thought and intent only to come back up with pareidolia-fueled echos of
one s own self and disfigured half-thoughts of others. The reality is, the
modern reader must now mechanically read most written work they come
across, scrutinizing text for any signs of thought before truly attempting
to read the work. Failing to do this correctly changes our person
each time it happens, a small part of us is irrevocably altered. Choosing to
engage in this ballet because you wish to do so is one thing this is
your right and freedom as a reader but passing words which were not
written as your own in an attempt to wrestle a reader s freedom of
co-creation from them is another entirely.
If you didn t write it, I don t want to read it (dw;dr). Send me your prompt instead.
It is said that those who cannot remember the past are condemned to
repeat it, a quote often attributed to the American philosopher George
Santayana. And to remember the past, records must be maintained and
kept accessible to learn from. With this in mind, it is no wonder
that archivists worldwide consider it crucial to ensure the archival
records are both complete and accurate, with a constant frustration
caused by the knowledge that the archives are neither due to
challenges in tracking down and collecting what should be
archived.
The last few days, I decided to simplify the collection of Messages
from the Mattermost chat
service, used by a few of the organisations I am involved in, to try
to improve the situation slightly. To achieve this, I had written a
dedicated extraction tool. Partly to see how hard it would be, and
partly to ensure that if one of the services were shut down or
replaced, everything in it would not be lost. Of course it is in the
nature of the use of instant messages that most of them are not fit
for permanent storage, at least not according to Norwegian law, where
there is a threshold "worthy of the archive" (arkivverdig) that should
be met, and messages like "should we go to lunch now" are below the
bar and should be filtered out. The tool can not help with this
filtering, and that will have to be done using other means after
collection.
The tools I had my bullshit generator write, under strict
supervision and many iterations, will extract every message visible to
the user whose credentials are used to log into Mattermost, and write
it out in Noark 5 extraction XML format and visualize the result. I
created the visualiser mostly to quickly be able to debug the
extracted XML, but also to make life easier for anyone interested in
testing out the tool set.
The extractor mattermost-noark5extract create a hierarchy
with arkiv/arkivdel for the Mattermost server, and then individual
mappe for each channel and direct message chat, a registrering for
each message thread, dokumentbeskrivelse for every message in the
tread, and one or more dokumentobjekt for each message and their
attachments/images. So far it is only tested on one Mattermost
installation, where around 23,000 messages is extracted in 61 seconds
and produce 295M with approximately 600 attachments and around 675,000
lines of XML in arkivstruktur.xml. You pass it the URL of the
service, a username and password, a directory path where to store the
collection and an optional channel name substring to limit the
collection to only a subset of the messages available.
The mattermost-noark5extract-browser viewer can load this
collection and visualize it similarly to Mattermost's web interface,
with the list of channels and direct messages dialogues on the left,
messages chronologically in the centre and a selected thread displayed
on the right.
I know Mattermost provide several login options. I've only had the
one used on my test server implemented so far, and know the extract
tool will have to be extended a bit for it to handle servers using one
of these options.
If you would like to examine the new toolkit,
mattermost-noark5extract
is available from gitlab. I wanted to put it on codeberg, but as
the recent rule change forbid code mostly written by a bullshit
generator there, it was not really an option. Note that some years
ago I wrote a similar tool to extract material from
the request
tracker system. The source for
request-tracker-noark5extract
is also available from codeberg. I would love to hear from you if
you test the tools.
As usual, if you use Bitcoin and wish to support my activities,
please send donations to
15oWEoG9dUPovwmUL9KWAnYRtNJEkP1u1b.
This is a new series1 I'm starting on the tools I have been crafting and
buying to play pedagogical games in my Economics classes.
These games, aside from being just plain fun for the students, often aim to
teach them a lesson via interactive play. Unsurprisingly, it is much easier for
them to grok a particular concept this way. Moreover, many students told me
these activities were the best part of the classes I teach.
The World Trade Game
I found out about The World Trade Game in The Handbook of Pluralist Economics
Education2, which also contains many other fun pedagogical games. It
was first developed by Action Aid, but has since been refined by John
Sloman and then by Irene van Staveren, who wrote about her use of the game in
the aforementioned book.
The goal of this blog entry is not to describe the game and teach you how to
play it. If that interests you, either buy the book I mentioned or read about
Sloman's version here.
No, our focus point here is the tools to play this game: fake cash! Fake cash
can be used in many economics pedagogical games and in my opinion, is a
worthwhile "investment" of your time and energy. You could indeed play with
regular printed sheets of paper listing a value (I sure did!), but using Play
Money (a more appropriate term, since we're not trying to defraud anyone) will
up your game and create a more immersive atmosphere in your classes.
At first, I tried to buy play money. Surely, some commercial offering aiming to
create realistic props for movies and TV productions existed? At least in
Canada, it turns out the answer was no. The only thing I could find were shady
websites and weird expensive listings on AliExpress. Not being tenured yet, I
did not try to convince my employer to take a 50-50 chance on supporting
criminal endeavours.
As such, the next best thing I found was printable play money designed by the
Bank of Canada Museum. Their designs were quite nice and met my needs,
but their PDF layout made it overly complicated to print large quantities of
bills. As such, I played around with GIMP a little and came out with these
files. A commercial printer shouldn't have issues printing them on glossy
cardstock paper and cutting them up for you:
Once printed and cut, you'll unfortunately have to fold each bill by hand. To
secure both halves, I ended up using a strip of transparent tape on each long
edge.
Here is the result, with a real Canadian 20$ bill as a comparison:
Don't hold your breath though, as I do not currently have a release
schedule.
Reardon, J. (2009). The Handbook of Pluralist Economic Education. New York : Routledge.
Introduction
After bazel-bootstrap 7.7.1 was landed into Debian unstable,
I'm working on packaging newer Mozc (Most famous Japanese input method editor) with Bazel.
Here is the blog entry initial efforts to build Mozc with Bazel at that time.
kenhys.hatenablog.jp
Why dh-bazel?
After that, newer Mozc packages are uploaded into experimental and moved to
testing phase on experimental now.
mozc - Debian Package Tracker
When started packaging efforts for newer Mozc with Bazel, I'm a newbie to do it.
Now I've got a knowledge to do it a bit, I want to know best practice on packaging X on Debian with Bazel furturmore.
Usually there are dh-X for buildsystem X on Debian, but it's not true for Bazel as far as I know.
This is why I had started to write dh-bazel.
I've wrote initial dh-bazel prototype and post a mail to debian-bazel ML.
lists.debian.org
dh-bazel supports the following way:
Conclusion
dh-bazel is in very early stage prototype, but I have succeeded to build newer Mozc with some modifications to Mozc debian/rules on experimental with dh-bazel locally!
dh-bazel is a thin wrapper for Bazel, so it does not reduce packaging glitches dramatically, but it helps some sort of packaging tasks IMHO.
There are some achievement with dh-bazel
It helps to do similar building way like other debhelper buildsystem
It sets comprehensive Bazel startup options
It sets comprehensive Bazel command options
If you want to set extra flags, just specify it as additional user options (--override_module=, and so on)
Note that it only simplify dh_auto_build stage, so you must manually install artifacts
with .install or something correctly.
I hope that it will help package maintainer using Bazel in the future.
(dh-bazel is not uploaded into debian/unstable yet, so stay tuned!)
 The MX record and some TXT records configured for
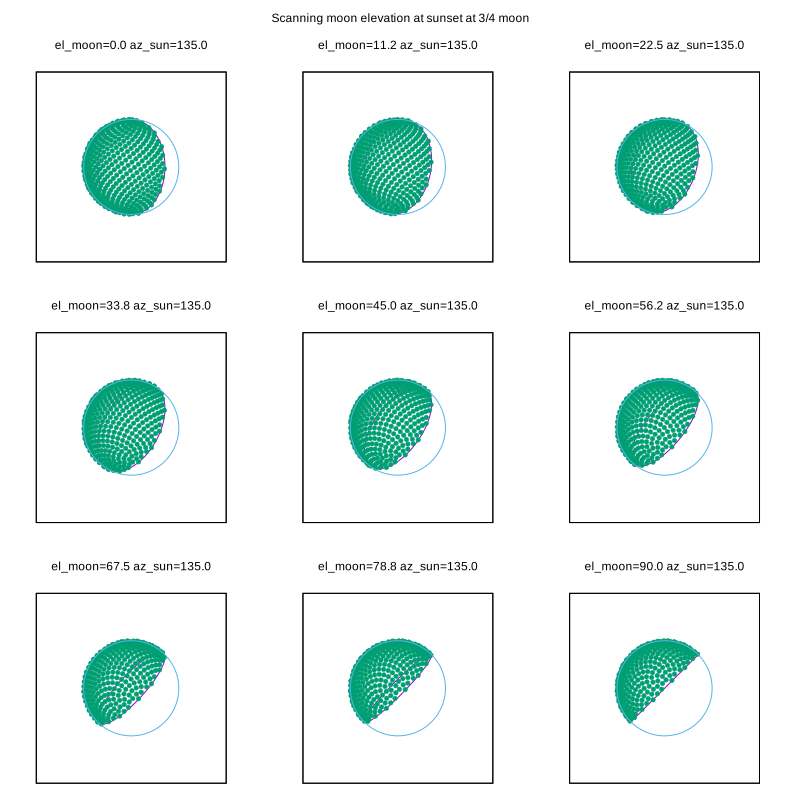
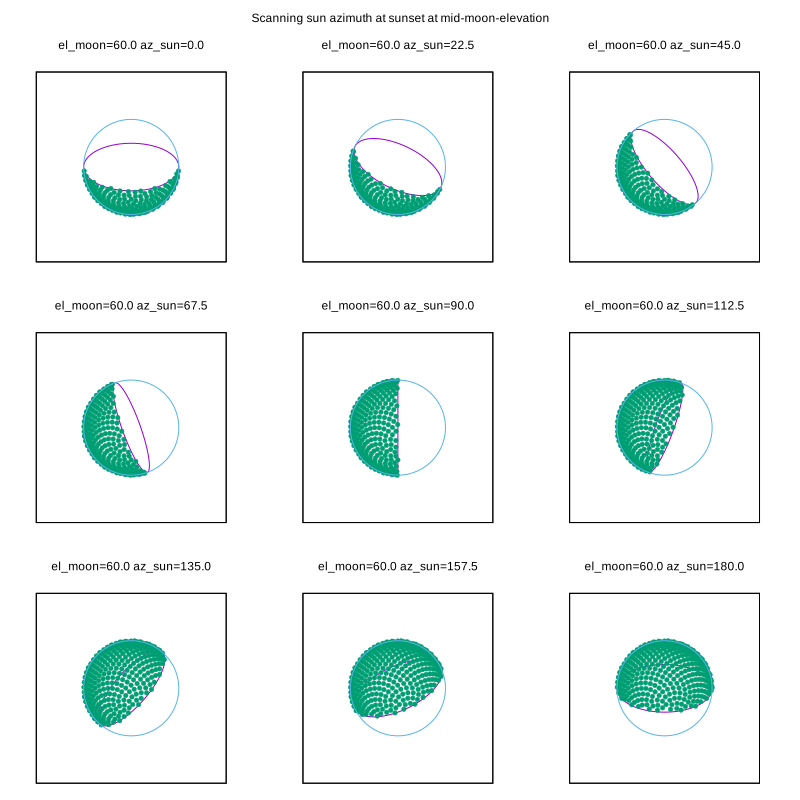
 Welcome to post 60 in the
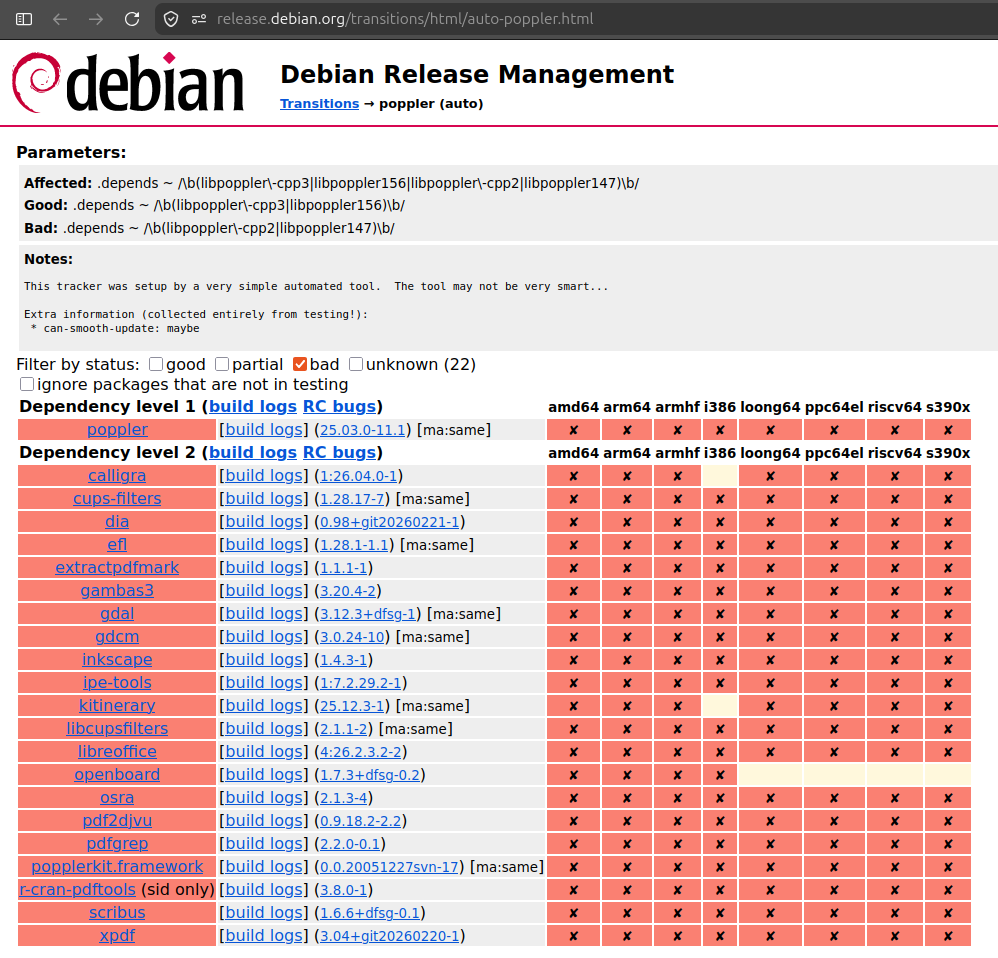 The Poppler transition tracker identifies the old and new runtime library package names.
I added
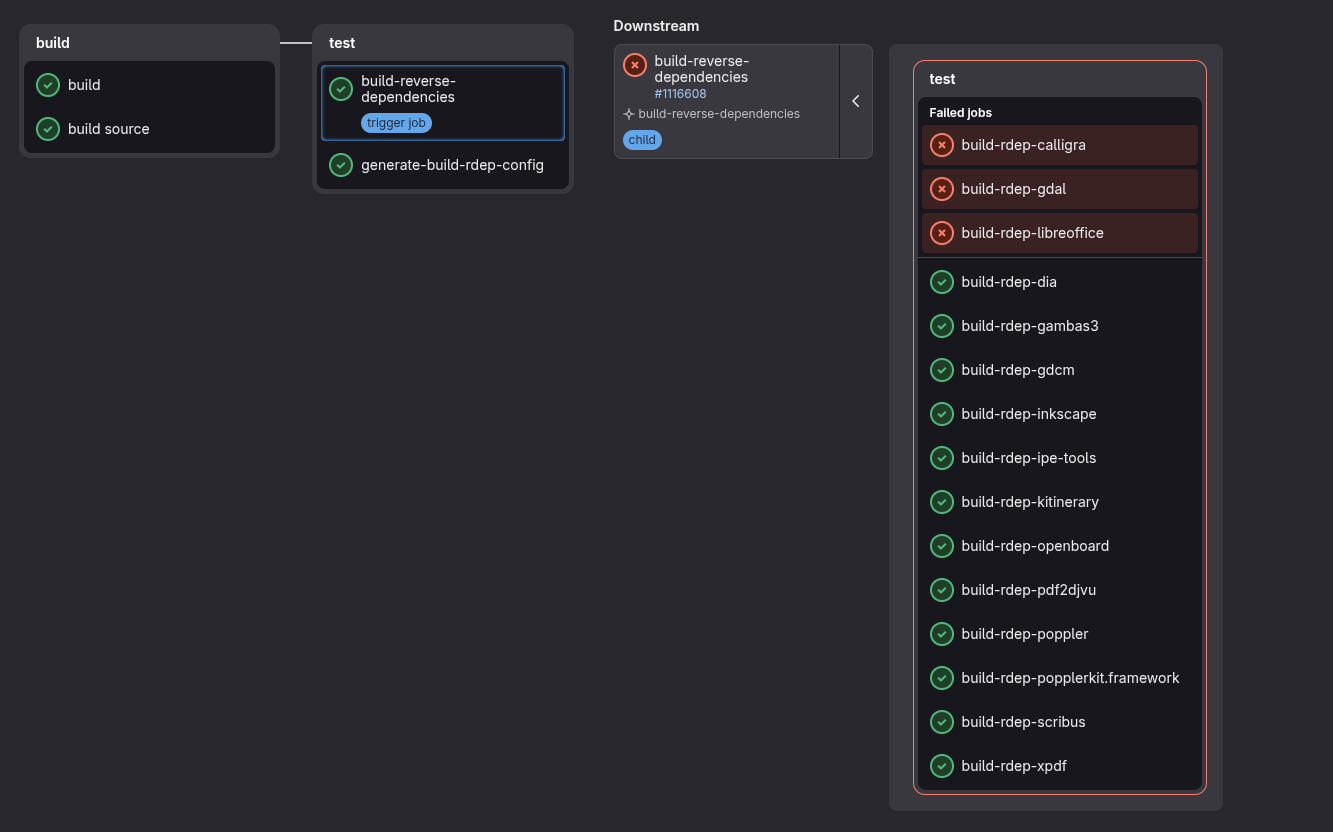 A Poppler test showing the selected rebuild jobs. Three jobs reached the CI timeout, they were not confirmed package regressions.
I also changed
 Who?
Fre(i)e Software GmbH is looking for a senior Golang + fullstack developer who can handwrite code and act as meticulous code review partner for another senior developer in the company.
What?
Most of your work would result in Open Source contributions to the Voxit project [1], an online civic tech tool for digital participation.
How and Where?
The work can either be delivered on project agreement base via freelancing or via employment (option only available to developers resident in Germany, Austria or Poland).
What next?
If you are interested, please get in touch and provide your hourly rate to us and your average hours of availability per week.
[1]


 The Debian LTS Team, funded by

 As a graduate of a liberal arts university, I wound up, unsurprisingly, taking a
lot of classes in every possible academic discipline. Thinking back to the
person that I was going into university, I don t think I would have chosen to
take them after all, my degree was in the sciences; I d have been stoked to
do nothing more than wall-to-wall computer science until I ran out of
coursework and filled the rest of my hours with research and independent
studies with my professors (which, I guess I did actually do, just not as
much as I would have otherwise).
Even this blog s CSS theme (now 18 years old and starting to look it) was
something I wrote after receiving and repeatedly re-reading a tattered
third-hand copy of The Laws of Thought by George Boole. It was gifted to me
by a college friend majoring in philosophy while I was crashing at his rental
on the beach. He gave it to me because he knew I liked that shit and, while
it was definitely computer science in nature, I would not have read it
otherwise. I have vivid memories of sleeping on his la-z-boy surrounded by
towers of books he was working through. He went on to do incredible work,
getting his PhD, doing research, brilliant writing his death in 2023 has
robbed humanity of more time with him. The Laws of Thought sits behind me in
my office, and is one of my most valued possessions.
My friends mean more to me than I could ever express, and I definitely don t
show it enough. Each of my classes made me a more thoughtful person. My
professors made me a better, more well-rounded person and a person who
attempts to live up to the oft repeated credo of being men and women for
others . I did the best I could, even though I was never a particularly good
student. Without liberal arts, I don t think I would, dispositionally, have
been capable of pushing myself to this day to continue to learn on nights
and weekends, for no reason other than wanting to learn. I refuse to stop
expanding my perspective, and do my best to approach new problems with as much
humility and curiosity as I can muster.
Every few days for the last year or so, I have been thinking back to a reading
assignment from my junior year that, at the time, I thought was a borderline
throwaway filler assignment for the class. The reading is an essay from 1947 by
the french existentialist philosopher and libertarian marxist, Jean-Paul Sartre
(as some of the more erudite may have now already worked out given the blog s
title), Why Write? . I re-read it this week. It is not filler. I remember this
essay better than some of the classwork I considered more important at the
time.
 This is a new series