Search Results: "Vasudev Kamath"

13 May 2014

Vasudev Kamath: Enabling DNSSEC for copyninja.info

Recently I've been seeing lot of posts about DNSSEC on Internet and I thought I should configure my domain to be secured by DNSSEC. copyninja.info domain is now secured with DNSSEC you can verify this by DNSSEC analyzer by Verisign and DNSViz online tool or by installing DNSSEC validator addon for your browser. There are good amount of tutorials and guides available to enable DNSSEC for your domain, still I want to note down steps I followed to here for the record (of course it will be helpful for me if I forget it ;-)) First step will be installing bind9 and dnssec-tools package, if you use aptitude installing dnssec-tools will pull down the bind9 unless you have configured aptitude to not install the Recommends. Next setting up the zone file for your domain, for this first make a copy of /etc/bind/db.local as /etc/bind/db.example.com, replace example.com with your domain name. Now you need to add your zone records to the zone file. Next edit the /etc/bind/named.conf.local file and add following lines
zone "example.com"  
    type master;
    file "/etc/bind/db.copyninja.info";
    allow-transfer  secondary; ;
 ;
Here replace secondary with your secondary DNS servers, if you don't have one you can ommit this but its always recommended to have secondary DNS servers for a zone, in cases when primary fails. After this we need to enable DNSSEC on bind, this is done by editing the file /etc/bind/named.conf.options. Add following lines into options section.
dnssec-validation yes;
dnssec-enable yes;
dnssec-lookaside auto;
A more explanation on this can be found on Linux Journal article. Now its time to create DNSSEC keys and sign your zone, more about different DNSSEC keys and records can be found in the Linux Journal Article on implementation. I used zonesigner utility from dnssec-tools which does job of signing and including KSK and ZSK keys into bind configuration which otherwise should be done manually. Here is the command line I used for generating keys, thanks to Jonas for this.
mkdir -p /etc/bind/keys
zonesigner -algorithm RSASHA256 -keydirectory /etc/bind/keys\
       -dsdir /etc/bind/keys -archivedir /etc/bind/keys/archive \
       /etc/bind/db.example.com
Here we store our keys into /etc/bind/keys directory, and use RSASHA256 algorithm for key generation which is more stronger than the default used RSASHA1 (atleast thats what Jonas told me). This will create ZSK and KSK for the signing zone and creates a signed zone file db.example.com.signed in same directory as original zone file. Now all you need to do is replace the zone file from db.example.com to db.example.com.signed in file directive with your named.conf.local file.
Note that this keys expire after 30 days so you need to resign your zone before 30 days. For resigning just run zonesigner from /etc/bind/keys. You can setup cron job to do this periodically.
zonesigner -zone example.com /path/to/db.example.com
Our signed zone is ready but we are not done yet! For DNSSEC to work others should trust your signed record for this you need to register your public keys with registrar for your domain and this can be done via your domain provider (in my case this is Gandi). You need to check your domain name providers documentation on how to do this. For Gandi users there is a nice documentation.

2 May 2014

Vasudev Kamath: Note to Self: How to use url_for in Flask application

url_for is normally used to avoid hard coding of URL in Flask based webapps. I've been using it in SILPA port written using Flask by. But this was written long back and written as POC to show for Santhosh author of SILPA app which even managed to go into production :-). Recently I started organizing the code and started using flask.Blueprint which was previously written using flask.views.MethodView class and here I started facing problem with old templates. I'm just gonna explain what is the difference when using url_for with MethodView and Blueprint. Lets have some sample code for MethodView first, this code is from Flask documentation.
from flask.views import MethodView
class UserAPI(MethodView):
       def get(self):
           users = User.query.all()
           ...
       def post(self):
           user = User.from_form_data(request.form)
           ...
app.add_url_rule('/users/', view_func=UserAPI.as_view('users'))
Here we have a view which is derived from MethodView which has logic on how to handle the requests. We use add_url_rule to register rule to handle /users/ url end point and we pass the class as view function which is done by as_view class method and we can refer this method in our Jinja2 templates using name users. So a statement like
url_for('users')
in our templates will be converted to /users/ URL when page is rendered to client by Flask. Now when I replaced the MethodView in favor of Blueprint I started getting up werkzeug.routing.BuildError thrown on my face and I had no clue why!. Yeah I know I'm bad at reading documentation but even after reading documentation I was still thinking that
url_for('/')
should return me a proper URL and I was wondering why its failing. Finally after re-reading documentation for url_for it was becoming clear to me, url_for definition looks like below
flask.url_for(endpoint, **values)
Here endpoint is actually a function which is supposed to be serving the URL and **values is the arguments for this function. The URL in question should be defined in python code using decorator. In my case following is the new function serving the web pages for SILPA.
bp = Blueprint('frontend', __name__)
@bp.route(_BASE_URL, defaults= 'page': 'index.html' )
@bp.route(_BASE_URL + '<page>')
def serve_pages(page):
       if page == "index.html":
          return render_template('index.html', title='SILPA',
                               main_page=_BASE_URL,
                               modules=_modulename_to_display)
       elif page == "License":
          return render_template('license.html', title='SILPA License',
                                main_page=_BASE_URL,
                                modules=_modulename_to_display)
       elif page == "Credits":
           return render_template('credits.html', title='Credits',
                                main_page=_BASE_URL,
                                modules=_modulename_to_display)
       elif page == "Contact":
           return render_template('contact.html', title='Contact SILPA Team',
                                main_page=_BASE_URL,
                                modules=_modulename_to_display)
       else:
           # modules requested!.
           if page in _display_module_map:
               return render_template(_display_module_map[page] + '.html',
                                    title=page, main_page=_BASE_URL,
                                    modules=_modulename_to_display)
           else:
               # Did we encounter something which is not registered by us?
               return abort(404)
You can ignore function code but just note the decorators, here I'm registering the function serve_pages with page as argument for URL patterns / and /<page>, _BASE_URL here is mount point of application it can be just / or /mountpoint depending on that URL registered changes. Now I need to modify code for all url_for in my template to look like below
url_for('.serve_pages', page='/License') # for /License
url_for('.serve_pages') # which will turn in to /index.html
The . in front of function is for referring current Blueprint, in my case the Flask will consider it as frontend.serve_pages as function name and generates appropriate URL at run time. So my fault was misunderstanding endpoint argument as URL endpoint but where as its actually function name supposed to serve the page. But when using MethodViews I can simply convert class to a function with my preferred name just like UserAPI.as_view('/') so url_for('/') just works.

7 April 2014

Vasudev Kamath: Loading Python modules/plug-ins at runtime

Some times it is desired to load arbitrary python files or pre- installed python modules during application run time.I had encountered 2 such usecases, one is in SILPA application and other is dictionary-bot which I was refactoring recently.
Case 1: Loading installed python module In case of SILPA I need to load pre-installed modules and here is the old code , that is a bit hacky code I copied from Active State Python recipies. I found a bit better way to do it using importlib module as shown below.
from __future__ import print_function
import sys
import importlib
def load_module(modulename):
    mod = None
    try:
        mod = importlib.import_module(modulename)
    except ImportError:
        print("Failed to load  module ".format(module=modulename),
                     file=sys.stderr)
    return mod
Here importlib itself takes care of checking if modulename is already loaded by checking sys.modules[modulename], if loaded it returns that value, otherwise it loads the module and sets it to sys.modules[modulename] before returning module itself.
Case 2: Loading python files from arbitrary location In case of dictionary bot my requirement was bit different, I had some python files lying around in a directory, which I wanted to plug into the bot during run time and use them depending on some conditions. So basic structure which I was looking was as follows.
      pluginloader.py
      plugins
       
       __ aplugin.py
       
       __ bplugin.py
pluginloader.py is the file which needs to load python files under plugins directory. This was again done using importlib module as shown below.
import os
import sys
import re
import importlib
def load_plugins():
    pysearchre = re.compile('.py$', re.IGNORECASE)
    pluginfiles = filter(pysearchre.search,
                           os.listdir(os.path.join(os.path.dirname(__file__),
                                                 'plugins')))
    form_module = lambda fp: '.' + os.path.splitext(fp)[0]
    plugins = map(form_module, pluginfiles)
    # import parent module / namespace
    importlib.import_module('plugins')
    modules = []
    for plugin in plugins:
             if not plugin.startswith('__'):
                 modules.append(importlib.import_module(plugin, package="plugins"))
    return modules
Above code first searches for all python file under specified directory and creates a relative module name from it. For eg. file aplugin.py will become .aplugin. Before loading modules itself we will load the parent module in our case plugins, this is because relative imports in python expects parent module to be already loaded. Finally for relative imports to work with importlib.import_module we need to specify parent module name in package argument. Note that we ignore files begining with __, or specifically we don't want to import __init__.py, this will be done when we import parent module. The above code was inspired from a answer on StackOverflow, which uses imp module, I avoided imp because its been deprecated from Python 3.4 in favor of importlib module.

12 March 2014

Vasudev Kamath: Working around type system of Go with unsafe

Go language has a strong type system unlike C, and some times this will be head ache when we want to interact with C data types with Cgo or just to convert a Go type to lets say byte slice. I recently faced the same problem and after poking around things, I learned the Go provides unsafe package which can be used to work around the Go's type system.
Problem Recently I started using Cgo to use some C library I had to write some tools for development and testing. The reason I chose Go for this was prototyping and writing some quick tools is much easier in Go than done in C. The C library had some function which takes pointer to array types and fills it with some values. The problem I was facing here was how to create a C array in Go. Go does have array but its largely used as internal representation for much efficient type called slice and I can't directly cast a byte slice into an C array. Second problem I had was I had to store arbitrary Go types like float (float32,float64) and int (int32, int64) etc. into C array. So in brief, the problems that needed to solve are
  1. Find a way to convert byte slice from Go into C array and vice versa.
  2. Find a way to convert and store Go types into a C array.
Solution Basically C array are sequence of memory location which can be statically or dynamically allocated. In Cgo its possible to access C standard library functions for memory allocation, so why not use it. The memory allocation function then returns the pointer to starting of allocated memory, we can use this pointer to write Go's bytes into the memory location and bytes from memory location into Go's slice. The pointer returned by C allocation functions are not directly usable for memory dereferencing in Go, here is where unsafe package kicks in. We will cast the return of C allocation function as unsafe.Pointer type and from the documentation of unsafe package,
  1. A pointer value of any type can be converted to a Pointer.
  2. A Pointer can be converted to a pointer value of any type.
  3. A uintptr can be converted to a Pointer.
  4. A Pointer can be converted to a uintptr.
So we can then cast unsafe.Pointer to uintptr which is the Go type which is large enough to hold any memory address in Go and can be used for pointer arithmetic just like we do in C (of course with some more castings). Below I'm pasting a simplified code in C which I wrote for this post.
#ifndef __BYTETEST_H__
#define __BYTETEST_H__
typedef unsigned char UBYTE;
extern void ArrayReadFunc(UBYTE *arrayout);
extern void ArrayWriteFunc(UBYTE *arrayin);
#endif
#include "bytetest.h"
#include <stdio.h>
#include <string.h>
void ArrayReadFunc(UBYTE *arrayout)
 
     UBYTE array[20] =  1, 2, 3, 4,5, 6, 7, 8, 9, 10,
                        11, 12, 13, 14, 15, 16, 17,
                        18, 19, 20 ;
     memcpy(arrayout, array, 20);
 
void ArrayWriteFunc(UBYTE *arrayin)
 
     UBYTE array[20];
     memcpy(array, arrayin, 20);
     printf("Byte slice array received from Go:\n");
     for(int i = 0; i < 20; i ++) 
             printf("%d ", array[i]);
      
     printf("\n");
 
Functions are written just for this post and they don't really do anything. As you can see ArrayReadFunc takes a pointer to array and fills it with content of another array using memcpy. Function ArrayWriteFunc on other hand takes pointer to array and copies its content to internal array. I've added print logic to ArrayWriteFunc just to show that values passed from Go are making it here. Below is the Go code which uses the above C files passes byte slice to get value out of C code and array made of byte slice to C function to send values in.
package main
/*
#cgo CFLAGS: -std=c99
#include "bytetest.h"
#include <stdlib.h>
*/
import "C"
import (
     "fmt"
     "unsafe"
)
func ReadArray() unsafe.Pointer  
       var outArray = unsafe.Pointer (C.calloc(20,1))
       C.ArrayReadFunc((*C.UBYTE)(outArray))
       return outArray
 
func WriteArray(inArray unsafe.Pointer)  
       C.ArrayWriteFunc((*C.UBYTE)(inArray))
 
func CArrayToByteSlice(array unsafe.Pointer, size int) []byte  
       var arrayptr = uintptr(array)
       var byteSlice = make([]byte, size)
       for i := 0; i < len(byteSlice); i ++  
               byteSlice[i] = byte(*(*C.UBYTE)(unsafe.Pointer(arrayptr)))
               arrayptr ++
        
       return byteSlice
 
func ByteSliceToCArray (byteSlice []byte) unsafe.Pointer  
       var array = unsafe.Pointer(C.calloc(C.size_t(len(byteSlice)), 1))
       var arrayptr = uintptr(array)
       for i := 0; i < len(byteSlice); i ++  
              *(*C.UBYTE)(unsafe.Pointer(arrayptr)) = C.UBYTE(byteSlice[i])
              arrayptr ++
        
       return array
 
func main() 
        carray := ReadArray()
        defer C.free(carray)
        carraybytes := CArrayToByteSlice(carray, 20)
        fmt.Println("C array converted to byte slice:")
        for i := 0; i < len(carraybytes); i ++  
                fmt.Printf("%d ", carraybytes[i])
         
        fmt.Println()
        gobytes := []byte 21, 22, 23, 24, 25, 26, 27, 28, 29, 30,
                31, 32, 33, 34, 35, 36, 37, 38, 39, 40 
        gobytesarray := ByteSliceToCArray(gobytes)
        defer C.free(gobytesarray)
        WriteArray(gobytesarray)
 
Functions ReadArray and WriteArray are just wrapper to the calls to C counter parts ArrayReadFunc and ArrayWriteFunc. ReadArray returns unsafe.Pointer which is allocated C array and should be freed by caller. WriteArray takes unsafe.Pointer which is pointing to memory location containing C array. Now the functions of interest are CArrayToByteSlice and ByteSliceToCArray. It should be pretty clear from the above code to understand what is happening in these functions. Still I will just put explain them briefly. ByteSliceToCArray allocates a C array using calloc from C standard library. It then creates a uintptr, a pointer type in Go which is used to dereference the each memory location and store bytes from the input byte slice in them. CArrayToByteSlice on other hands creates a uintptr type by casting input unsafe.Pointer type and then uses this pointer type to dereference values from memoy and store it in byte slice with suitable casting. So lets build the code and run it and see the output:
C array converted to byte slice:
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18 19 20
Byte slice array received from Go:
21 22 23 24 25 26 27 28 29 30 31 32 33 34 35 36 37 38 39 40
So yes it actually works and values are moving across C and Go. This solves first problem in hand next is converting arbitrary Go types into byte slices. There are many cases where we would like to convert an arbitrary Go types like (int, float) into bytes. One such use case I found was when writing a TCP client for communicating with a Server written using C speaking custom protocol. Here I'm just going to show how to convert types like float, int to byte slice, I've not tried converting structures but it is certainly possible. Below is the function which can convert int32,float32 into byte slice it can also be extended for other types.
func CopyValueToByte(value interface ) []byte  
     var valptr uintptr
     var slice []byte
     switch t := value.(type)  
     case int32:
             i := value.(int32)
             valptr = uintptr(unsafe.Pointer(&i))
             slice = make([]byte, unsafe.Sizeof(i))
     case float32:
             f := value.(float32)
             valptr = uintptr(unsafe.Pointer(&f))
             slice = make([]byte, unsafe.Sizeof(f))
     default:
             fmt.Fprintf(os.Stderr,"Unsupported type: %T\n", t)
             os.Exit(1)
      
     for i := 0; i < len(slice); i++  
             slice[i] = byte(*(*byte)(unsafe.Pointer(valptr)))
             valptr++
      
     return slice
 
This function is generic which can take various types of value. First we will use Go's type assertion to determine the type and creates a uintptr pointer for the value and allocates byte slice depending on the size of the value as calculated using unsafe.Sizeof. Later it uses the pointer to dereference value from memory location and copies each byte into byte slice. The idea used here is every type is represented as certain number of bytes in the memory. Below is the entire program.
package main
import (
     "fmt"
     "unsafe"
     "os"
)
func CopyValueToByte(value interface ) []byte  
     var valptr uintptr
     var slice []byte
     switch t := value.(type)  
     case int32:
             i := value.(int32)
             valptr = uintptr(unsafe.Pointer(&i))
             slice = make([]byte, unsafe.Sizeof(i))
     case float32:
             f := value.(float32)
             valptr = uintptr(unsafe.Pointer(&f))
             slice = make([]byte, unsafe.Sizeof(f))
     default:
             fmt.Fprintf(os.Stderr,"Unsupported type: %T\n", t)
             os.Exit(1)
      
     for i := 0; i < len(slice); i++  
             slice[i] = byte(*(*byte)(unsafe.Pointer(valptr)))
             valptr++
      
     return slice
 
func main()  
     a := float32(-10.3)
     floatbytes := CopyValueToByte(a)
     fmt.Println("Float value as byte slice:")
     for i := 0; i < len(floatbytes); i++  
             fmt.Printf("%x ", floatbytes[i])
      
     fmt.Println()
     b := new(float32)
     bptr := uintptr(unsafe.Pointer(b))
     for i := 0; i < len(floatbytes); i++  
             *(*byte)(unsafe.Pointer(bptr)) = floatbytes[i]
             bptr++
      
     fmt.Printf("Byte value copied to float var: %f\n", *b)
 
The above conversion can also be achieved using encoding/binary package provided by Go. But its been told to me that it makes things pretty slow.

Conclusion So goes unsafe.Pointer is really powerful thing which allows us to work around the Go's type system but as package documentation says it should be used with care
PS: I'm not really sure if its recommended to use allocation functions from C standard library, I will wait for expert gophers to comment on that.

1 March 2014

Vasudev Kamath: Installing and Configuring NetBSD on Qemu in Debian

First step will be getting a NetBSD ISO image for installation purpose. It can be downloaded from here. Next step will be creating a disk image for installing NetBSD. This is done using qemu-img tool like below
$ qemu-img create -f raw netbsd-disk.img 10G
Image format used is raw and size is specified as last arugment. Tune the size as per your need. To start the installation run the following command
$ qemu-system-x86_64 -m 256M -hda netbsd-disk.img -cdrom \
             NetBSD-6.1.3-amd64.iso -display curses -boot d \
             -net nic -net user
So this is using user mode networking so you won't be able to have internet access during installation. I couldn't figure out on how to get network working during installation so I configured network after installation. Once you run above command you will be given with 4 options as follows.
  1. install netbsd
  2. install netbsd with ACPI disabled
  3. install netbsd with ACPI and SMP disabled
  4. drop to boot shell
Even though I first installed using the option 1 I couldn't get it boot after installation so had to reinstall with option 2 and it works fine. I'm not gonna explain each step of installation here because the installer is really simple and straight forward! I guess the NetBSD installer is the first simplest installer I have encountered from the day I started with Linux. Its simple but powerful and gets job done very easily, and I didn't read manual for installation before using it.
Enabling Networking This section involves mixture of configuration in Debian host and inside NetBSD to get the network working. The wiki page of Debian on Qemu. helped me here. To share the network with Qemu there are 2 possiblities
  1. Bridged networking between host and guest using bridge-utils
  2. Using VDE (Virtual Distributed Ethernet)
The option 1 which is explained in wiki linked above didn't work for me as I use CDC Ether based datacard for connecting to Internet which gets detected as eth1 on my machine. When bridging happens between tap0 and eth1 I end up loosing Internet on my host machine. So I selected to use VDE instead. First install packages vde2 and uml-utilities once done edit the /etc/network/interfaces file and add following lines:
auto vdetap
iface vdetap inet static
   address 192.168.2.1
   netmask 255.255.255.0
   vde2-switch -t vdetap
We can use dnsmasq as a DHCP server for the vdetap interface, but I'm not gonna explain the configuration of dnsmasq here. Run the below command to get vdetap up
modprobe tun
ifup vdetap
/etc/init.d/dnsmasq restart
newgrp vde2-net # run as user starting Qemu VM's
I couldn't get successful output for newgrp command, I was getting some crypt: Invalid argument output. But I could still get network working on NetBSD so I considered to ignore that for now. Now start the NetBSD qemu instance running using following command
$ qemu-system-x86_64 -m 256M -hda \
             /mnt/kailash/BSDWorld/netbsd-disk.img \
             -net nic -net vde,sock=/var/run/vde2/vdetap.ctl -display curses
Once the system is up login using root user, NetBSD will warn you for this and suggest to create another user but for now ignore it. To find the network interface in NetBSD just run the usual ifconfig command. In my case interface is named wm0. First step will be configuring the IP address for your interface and setting up the gateway route. Run the below command for this purpose
# ifconfig wm0 192.168.2.2 netmask 255.255.255.0
# route add default 192.168.2.1
Note that I added gateway as IP address of vdetap on my host machine. Now try pinging the host and even you can try ssh to host system. But note that this is not persistent over the reboots and for some reason I didn't yet figure out how to make NetBSD get address over DHCP from my host machine. I will update once I figure it out. Now to make the connection address persistent over reboots you need to create a file by name /etc/ifconfg.<interface>. Replace interface with a proper interface on your running NetBSD. In my case this file is /etc/ifconfig.wm0 and has following content.:
192.168.2.2 netmask 0xffffff00 media autoselect
Set the DNS server as host by adding file /etc/resolv.conf with following content.:
nameserver 192.168.2.1
After this you need to do NAT/masquerading using iptables. Just copy following script to a file and execute it as root
#!/bin/sh
# Restart the dnsmasq
/etc/init.d/dnsmasq restart
# Set nat rules in iptables
iptables --flush
iptables --table nat --flush
iptables --delete-chain
iptables --table nat --delete-chain
# Replace accordingly usb0 with ppp0 for 3G
iptables --table nat --append POSTROUTING --out-interface eth1 -j MASQUERADE
iptables --append FORWARD --in-interface vdetap -j ACCEPT
# Enable IP forwarding in Kernel
sysctl -w net.ipv4.ip_forward=1
With the above setup you will be able to get DNS resolution even after you reboot the Qemu instance but Internet connection will not work untill you run the route command I mentioned above. I still didn't figure out how to persist route but I will update it here once I figure it out.
Note that you won't be able to SSH as root to NetBSD (may be its configured to not allow by default), so you would need to create a normal user before trying to SSH from host to guest. Also make sure you add the user to wheel group to allow him execute su command.
So now I've NetBSD running on my laptop with mere 256M ram and its amazingly fast even at such low RAM. I've created a new user and can SSH into it from host machine and use it just like I use a server!. I will put up the notes of my BSD adventure here periodically. The feeling of using a BSD is amazing :-)
Update: I forgot to add masquerading step, I've added it now.

Vasudev Kamath: Gzipped response for CSS/JS with Apache and mod_uwsgi

So it may sound normal to receive compressed response for CSS/JS file from Apache2 but what I faced is completely different behavior, here I saw not just body of response but also header are getting compressed and send to browser and browser was unable to interpret the response there by leading page rendered without CSS and JS. That was long story short, so let me explain in detail the case and what I found out. I have hosted SILPA on my VPS using uWSGI. I had used till date using libapache2-mod-proxy-uwsgi plugin for which uWSGI should be using network socket and in Apache2 config I need ProxyPass directive pointing to uwsgi://host:port and everything used to work out of box. There is a drawback for using network socket in uWSGI that is limited amount of ports (65535) and possible clash with other services if we use wrong port number, additionally network sockets will be slower compared to the file socket so yesterday I thought of changing it to file socket and removed socket directive in the ini file for uWSGI application container for SILPA and here is where all problems started. My updated configuration can be seen in our documentation page that is if you are interested to look my configuration file :-).
Problem Reporting We got selected to Gsoc again this year and we have lot of students jumping in our channel #silpa on irc.freenode.net and yesterday night some students reported they are facing 500 internal server error and subsequently others mentioned there is no theme being rendered. I checked and found everything was fine for me only to notice that my browser was using cached content, and when I clear cache there I go everything vanished, no theme no css no javascript just plain html!!!.
Investigation So I thought I should investigate this and fired up firebug on my iceweasel to observe the network traffic. And below is what I observed in firebug network console!. No response headers So you can see no response header in the above image but there is a response and below how is response content visible on firebug. gzipped response Still weird part was when using wget/curl directly to get the CSS I was getting correct reply and the file, which is puzzling. So I went ahead opened the CSS url directly using browser and saved the resulting file. When I used file command on it, output suggested the saved file in gzip compressed!. I went ahead uncompressed it and opened the file and inside it I found response header and the response body! So what just happened? Did apache some how manage to compress entire respone not just response body? The more puzzling question was why did it work when I was using mod_proxy_uwsgi and failed when I switched to mod_uwsgi. I had no clue at this point why this behavior is coming up.
Possible Solution I was still not sure how to resolve this, and started searching in the network but nothing was coming up in search result which can explain me this. And finally I stumbled on a link which is totally unrelated but I saw the word mod_deflate in the content and wandered on my system to see if its enabled. Yes mod_deflate was enabled I just opened the conf file and saw following.
<IfModule mod_deflate.c>
       # these are known to be safe with MSIE 6
       AddOutputFilterByType DEFLATE text/html text/plain text/xml
       # everything else may cause problems with MSIE 6
       AddOutputFilterByType DEFLATE text/css
       AddOutputFilterByType DEFLATE application/x-javascript application/javascript application/ecmascript
       AddOutputFilterByType DEFLATE application/rss+xml
</IfModule>
Interesting so it suggests to compress css, javascript files etc. So I thought possibly its compressing the result of mod_uwsgi, yeah possibly so why not try disabling mod_deflate and check if it works well and good if not I'm not gonna loose anything. So I disabled mod_deflate and voila! Everything is working fine!
What might be the reason for this behavior? Well I'm not exactly sure but here is my assumption. The whole behavior depends on internal implementation of mod_uwsgi and mod_proxy_uwsgi module. To confirm this I switched back to use mod_proxy_uwsgi module and enabled mod_deflate and observed request response in Firebug network console and below is what I observed. Response with mod_proxy_uwsgi So response is still gziped but this time only response body was gziped and Content-Encoding field was set properly which makes browser to properly uncompress the response body and use it. So it seems like there is a difference between mod_uwsgi and mod_proxy_uwsgi implementation. mod_uwsgi was sending the response along with response headers which was compressed by mod_deflate there by rendering browser helpless to interpret the response. But mod_proxy_uwsgi seems to be only sending the response content without response body and this content was later compressed by mod_deflate and proper response headers were set by apache before sending it to browser. So now whose fault is this? Is it the bug in mod_uwsgi or, mod_deflate not being able to exclude response headers from compression? I've no clue! If you have a clue and you want to share it with me, please consider writing to me over email. My details are available in Contacts

22 February 2014

Vasudev Kamath: First experience of driving in Bangalore

So finally I did it, I managed to ride the 2-wheeler in Bangalore roads!. Officially I've got a license to drive 2 and 4 wheelers back in 2011 but I was never confident enough to ride the vehicle on road and in traffic. Partially this is because I don't own a vehicle and I've never practiced driving, and partially because of road and traffic conditions in India I was bit afraid to do so. So today morning my roommate and me planned to go to temple in the early morning. We got up at 530 in the morning and we were ready to drive to Mahalaxmi Layout at 615. Since during this time traffic is very less I asked my roommate shall I drive and he agreed!. So I drove the bike from Malleshwaram to Mahalaxmi Layout and it was fun. I did had hick up in uphill driving as my mind was not co-ordinating well with breaks and gear. I did have hickups in first gear too but I guess this will be alright once I get hold of things. I'm still not having enough confidence to drive during the peak hours because people are not at all following traffic rules. They just change the lane without any hints or just come to middle of road from side roads without looking at other side to see if there is a vehicle is coming from other side of the road (yes they don't have courtesy to wait). And finally they can shout at persons who is actually following rules. In general very less people have traffic discipline in India. But I will adapt to this once I start driving so I'm now all set to get my 2 wheeler soon and ride on!

21 February 2014

Vasudev Kamath: Kontalk FLOSS alternative for Whatsapp and Co.

So Whatsapp has been acquired by Facebook and this news is still hot and people are discussing it all over the twitterverse. So I took this opportunity to stop using Whatsapp and removed it from my phone. Possibly I could have deleted my account but who cares. Anyway I've been searching for a secure and FLOSS alternative for Whatsapp for quite some time now, few days ago I found about Telegram but after reading post by Tincho on planet Debian, I decided not to use it. Recently while going through the talk list for fossmeet.in I found link for Kontalk in a privacy awareness talk proposal by Praveen and thought I should give it a try. So below is my first feelings about Kontalk.
Installation and Activation Kontalk can be installed from playstore for verification purpose it requests your phone number and country code and request for verification. This should send a SMS with a code which should be entered in the text box given and app is ready to use. There is also a possibility to use pre-existing verification code (if you got one from developer directly, read below for details). I did see some glitches like I never got the SMS delivered to my phone after 2 attempts and a days wait. Then I went ahead and reported a bug and the main developer was quick to respond. After a discussion it was noticed that SMS was blocked by spam filters. He also mentioned its tough to get SMS delivered to India. He was kind enough to provide me with a verification code and I used the Use existing code option to enter it and get Kontalk activated. The SMS delivery inconsistency is still present for India (and may be other nations too) some people get code immidiately others may be after couple of days and some might not. Upstream is already working on a possible workaround.
User Experience Now coming to usage part, the UI is neat and clean, I won't say super polished as Whatsapp or other popular apps but its really neat and easy to use. Some points which I like are
  • Ability to hide presence, so others won't know you are online or offline. (unlike Whatsapp which advertises last seen)
  • Encrypted messages and ability to optin or optout.
  • Encrypted status messages! Only user with your phone number can see your status. (Cool isn't it).
  • Manually requesting to find contacts who already uses kontalk!. Right it doesn't read your contact list without your permission you need to refresh to check who in your contacts is using Kontalk.
  • Attach and smiley options in the top right corner of Chat window which allows easy accessing unlike keyboard - smiley switching of Whatsapp.
  • No automatic download of media contents which is shared. Yes by default it doesn't download any picture or video automatically if you want to see something click on it and select download.
  • Running your own server for Kontalk! Now thats something which is interesting for people who doesn't want to host their data on some other peoples infrastructure. Code for server is available at xmppserver repo.
But there are some rough edges also but I'm sure this can be improved. But some points which I noticed are
  • Contact name disappears and only number is displayed. This is something which happened with one of my contact so I'm not really sure its a bug.
  • My friend noticed all his existing contacts suddenly vanished when he refreshed contacts list. Again this is possible bugs and we are considering reporting it upstream.
  • No group chats yet. I don't see a option to do that yet.
  • Attachment at the moment is restricted only to pictures (and video? never tried) and uploading takes quite sometime and sometime hangs forever.
So I'm considering forwarding these to upstream and help them by providing enough data so these can be fixed.
Technical Side All code for client server and protocol specs are available under GPL-v3 at the Kontalk project site. Server software is written in Python and I guess uses XMPP (but I've not cross verified). Server also uses MySQL as database. These can be hosted on our own servers but possibly needs more than that like SMS sending options etc.
Conclusion In my views Kontalk can become a great alternative for Whatsapp and co from Free Software world and I encourage every one to give it a try which will be the first step to help improving it.
Disclaimer: I'm not a privacy or security expert so whatever I shared above are what I noticed and experts may see something different than this. In any case I welcome comments and suggestions.

8 February 2014

Vasudev Kamath: Friendica instance on my VPS is down

I started running Friendica instance on my VPS. With help of Jonas Smedegaard I managed to run Friendica in a uWSGI container. The site was running at samsargika.copyninja.info and is no longer accessible. Since VPS itself was running Debian Wheezy I couldn't run uWSGI with PHP support on it. (support for PHP in uWSGI landed after Wheezy). But Jonas was kind enough for me to provide a backported version. Recently Wheezy got a security update for PHP and thats where all the problem started. The backported uwsgi-plugin-php was not recompiled to use security updated PHP and I couldn't upgrade the things. After few days I noticed first freeze on my VPS and I had to reboot the VPS to get it online again. The fact I noticed was uWSGI being killed due to a OOM in syslog but I didn't explore much and consulted Jonas to get a updated uWSGI. But that didn't happen as Jonas himself is facing some problem with uWSGI builds. While again checking with aptitude for upgrade I accidentally confirmed removal of uwsgi-plugin-php for getting security updates :-/. But nothing happened to my running service as upgrade of libs in Debian doesn't cause the restart of all services which are using that lib (desired effect is restart of service but I don't know the side affects involved). Second freeze happened yesterday and on the reboot uwsgi-plugin-php was missing there by taking my Friendica instance down. More closer investigation showed the same OOM but this time I noticed each OOM occurred just after cronjob was running poller.php a script which is actually causing all federation in Friendica. So it was clear there is something wrong either in poller.php or in my setup which was making it eat memory and freeze my VPS. But I also found some stupidity I did during configuration which Jonas also pointed me out.
  1. Installing cronjob inside crontab rather than cron.d
  2. Installing poller.php crontab for root user :-/
I basically violated the basic rule by running a unsafe script as root user, good that script didn't do some crazy stuff. So even though my instance went down I learnt my lessons
  1. Don't ever ever ever run a unsafe script as root that too through cron
  2. Sandbox the unsafe script so it can be killed on time rather than it taking the whole system down.
  3. PHP is not really secure, if it was secure there wouldn't be security updates and atleast my site would be still running :-D
So I now need to wait till Jonas get me new shiny backported uWSGI linked against new PHP on Wheezy and till that time I need to explore on how I can sandbox the poller.php script.

2 February 2014

Vasudev Kamath: Moving weblog from Jekyll to Pelican

Its been a while and I was not actively blogging. I wanted to start blogging again but I was for some reason not happy with Jekyll static site generator which was powering my previous site. So I took this chance to explore other static site generators and redesign my blog. I explored a bit of Pelican, Nikola and Frog. I didn't feel comfortable with Nikola. Frog is a static site generator written using *Racket* and since I'm learning Scheme using racket I was leaning towards using it but at the last moment I decided to settle with Pelican. The main reason for not using Frog was that I just wanted to get my site up rather than waiting for me to complete learning racket and use Frog. My feeling about Pelican is that its a nice tool and is simple and gives all basic things like generating RSS/ATOM feeds and nice theming support. In case of Jekyll I had to write custom page for creating RSS feed and had pain in creating my first theme (yeah I'm not a designer). But now things might have changed in Jekyll land but anyway I don't care anymore. New design uses pelican-bootstrap3 theme and there is no comment facility available. If you want to comment or suggesting things on my post consider writing mail to me :-). So what happened to older entries? Moving the old entries from Jekyll format to Pelican was real PITA so I just renamed my old site to blog-archive. So this is a from scratch site and will contain only new entries. So how do you like my new blog design? :-)

5 May 2013

Vasudev Kamath: CDBS Packaging: package relationship management

(It took me a while to come up with new CDBS packaging series post not because I stopped using CDBS just because I was procrastinating myself as busy) This is the second post in the CDBS packaging series. In this series I'm going to talk about package relationship management. The better example where this feature is useful is packages where build-depends and run-time dependencies overlap. Most of the Perl modules which have test suites have build-depend and run-time dependency intersection. So let me take example of a Perl module. First lets see control file of a Perl package which is not using CDBS and then let me explain how CDBS can help you improve the situation. I choose libxml-libxml-perl lets see part of control file which includes Build-Depends Depends Suggests Recommends.
Source: libxml-libxml-perl
Maintainer: Debian Perl Group <pkg-perl-maintainers@lists.alioth.debian.org>
Uploaders: Jonathan Yu <jawnsy@cpan.org>,
 gregor herrmann <gregoa@debian.org>,
 Chris Butler <chrisb@debian.org>
Section: perl
Priority: optional
Build-Depends: perl (>= 5.12),
 debhelper (>= 9.20120312),
 libtest-pod-perl,
 libxml2-dev,
 libxml-namespacesupport-perl,
 libxml-sax-perl,
 zlib1g-dev
Standards-Version: 3.9.4
Vcs-Browser: http://anonscm.debian.org/gitweb/?p=pkg-perl/packages/libxml-libxml-perl.git
Vcs-Git: git://anonscm.debian.org/pkg-perl/packages/libxml-libxml-perl.git
Homepage: https://metacpan.org/release/XML-LibXML/
Package: libxml-libxml-perl
Architecture: any
Depends: $ shlibs:Depends , $ misc:Depends , $ perl:Depends ,
 libxml-namespacesupport-perl,
 libxml-sax-perl
Breaks: libxml-libxml-common-perl
Replaces: libxml-libxml-common-perl
Description: Perl interface to the libxml2 library
 XML::LibXML is a Perl interface to the GNOME libxml2 library, which provides
 interfaces for parsing and manipulating XML files. This module allows Perl
 programmers to make use of the highly capable validating XML parser and the
 high performance Document Object Model (DOM) implementation. Additionally, it
 supports using the XML Path Language (XPath) to find and extract information.
So 2 packages are both in Build-Depends and Depends field
  1. libsax-xml-perl
  2. libxml-namespacesupport-perl
So in this situation there is a possibility that we miss to add one or both of these packages into Depends field, I'm not saying we will surely miss but we might after all we are all human beings. So how can we improve the situation using CDBS? Let me go through step by step on what we need to do.
  1. Create a file called control.in with same above contents but slight modification in Build-Depends and Depends section. I will display the diff below to avoid re-pasting entire file again and again.
--- debian/control      2013-04-28 23:08:11.930082600 +0530
+++ debian/control.in   2013-05-04 20:51:18.849680419 +0530
@@ -5,13 +5,7 @@
  Chris Butler <chrisb@debian.org>
 Section: perl
 Priority: optional
-Build-Depends: perl (>= 5.12),
- debhelper (>= 9.20120312),
- libtest-pod-perl,
- libxml2-dev,
- libxml-namespacesupport-perl,
- libxml-sax-perl,
- zlib1g-dev
+Build-Depends: @cdbs@
 Standards-Version: 3.9.4
 Vcs-Browser: http://anonscm.debian.org/gitweb/?p=pkg-perl/packages/libxml-libxml-perl.git
 Vcs-Git: git://anonscm.debian.org/pkg-perl/packages/libxml-libxml-perl.git
@@ -20,8 +14,7 @@
 Package: libxml-libxml-perl
 Architecture: any
 Depends: $ shlibs:Depends , $ misc:Depends , $ perl:Depends ,
- libxml-namespacesupport-perl,
- libxml-sax-perl
+ $ cdbs:Depends 
 Breaks: libxml-libxml-common-perl
 Replaces: libxml-libxml-common-perl
 Description: Perl interface to the libxml2 library
@@ -30,4 +23,3 @@
  programmers to make use of the highly capable validating XML parser and the
  high performance Document Object Model (DOM) implementation. Additionally, it
  supports using the XML Path Language (XPath) to find and extract information.
-
  1. Next we need to have something like below in the rule files
#!/usr/bin/make -f
include /usr/share/cdbs/1/rules/debhelper.mk
include /usr/share/cdbs/1/rules/utils.mk
include /usr/share/cdbs/1/rules/upstream-tarball.mk
include /usr/share/cdbs/1/class/perl-makemaker.mk
pkg = $(DEB_SOURCE_PACKAGE)
deps = libxml-libxml-perl libxml-sax-perl
deps-test = libtest-pod-perl
CDBS_BUILD_DEPENDS +=, $(deps), $(deps-test)
CDBS_BUILD_DEPENDS +=, zlib1g-dev, libxml2-dev, perl (>= 5.12)
CDBS_DEPENDS_$(pkg) = , $(deps)
So basically we moved all Build-Depends and Depends to rules file. The common ones are placed in deps variable and assigned to both Build-Depends and Depends. CDBS uses following variables for package relationship management.
  1. CDBS_BUILD_DEPENDS: This variable helps you manage Build-Depends field and all you need to do is in your control.in files Build-Depends field put place holder @cdbs@
  2. CDBS_DEPENDS: This field can be used to manage Depends field of binary package for each binary package you need to have one CDBS_DEPENDS_pkgname variable with depends assigned to it. And in your control.in append $ cdbs:Depends to Depends field.
  3. CDBS_PROVIDES, CDBS_BREAKS, CDBS_RECOMMENDS, CDBS_PREDEPENDS, CDBS_SUGGESTS, CDBS_REPLACES: all these does the job what you think it does :-).
Other than CDBS_BUILD_DEPENDS all other variables work using substvars i.e. CDBS will put the respective substitutions in pkgname.substvars file which will be used during deb creation to replace things in control file. So to make CDBS generate new control file run the below command
DEB_MAINTAINER_MODE=1 fakeroot debian/rules debian/control
Basically this command needs to be executed before starting build process if you miss your changes will not be reflected into debian/control. Additionally this feature is Maintainer Mode helper tool because Debian policy prohibits change of debian/control during normal package build. So what is the benefit of using this feature of CDBS? I've listed some of them which I felt are obvious.
  1. When there is intersection in Build-Depends and Depends this feature from CDBS is helpful. As I shown above put all intersecting dependencies in common variable and appropriately assign them wherever it is required. Thus we can avoid possible missing of some of run-time dependencies due to human error.
  2. It is also possible that newer version of package requires specific version of some package (mostly libraries) and we updated build dependencies but we might forget to do the same in Depends, by using this feature we can make sure we will not miss such minute details.
One last thing I want to point out is if you are NMUing a CDBS package
NMUs need not (but are encouraged to) make special use of these tools. In particular, the debian/control.in file can be completely ignored.
Before closing down the post, If you find some mistake in the post please let me know either through comments or through the email. Soon I will be back with new CDBS recipes till then cya.

28 April 2013

Vasudev Kamath: Tribute to Beloved Teacher

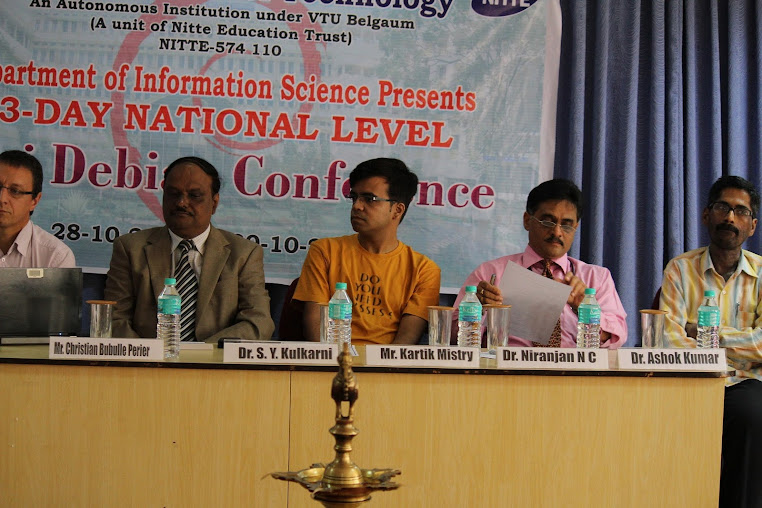
Today I'm writing this blog with saddened heart. My mentor and a best friend Dr.Ashokkumar is no more. He died yesterday after fighing with Lymph Node cancer. Ashokkumar or Ashok sir that is how we all students used to address him, was a Professor in Information Science Engineering in NMAM Institue of Technology and recently transferred to Computer Science Engineering Departement. My last meeting him with him was last year December during which he was looking every bit okay other than he had knee pain because of which he couldn't walk freely. But I never imagined that it will be my last meeting with him. Ashok sir was also behind the FLOSS event that took place in NMAM Institute of Technology including MiniDebconf 2011 which saw 2 of the foreign DD's Christian Perrier and Jonas Smedegaard. It was because of his first organized FLOSS event which I volunteered called Linux Habba I entered into the FLOSS world. This means its because of him that I started my FLOSS world journey and reached to my current level. Also it was because of his motivation I started writing this blog which I continue till this day.
I whole heartedly thank Ashok sir for teaching me guiding me and motivating me during my difficult times. You will always be remembered through out my life. May your soul Rest In Peace.
Here are the 2 pics of Ashok sir taken during Minidebconf (Credits: Christian Perrier and Kartik Mistry) Ashokkumar with Jonas and Me Ashokkumar during inaugaration of MiniDebconf with Christian and Kartik on stage Good bye Sir :-(

14 April 2013

Vasudev Kamath: Handling C++ symbols that vary across architectures

Disclaimer I'm no symbol expert and dealing with symbol files for first time from the time I started packaging. What I did here is depending on some suggestions I got in #debian-mentors. If you think what I did was wrong please enlighten me :-). Problem Recently 2 of my library packages pugixml and ctpp2 got accepted into Debian archive and when buildd tried to build them on remaining architectures other than one for which I uploaded (amd64) builds failed. This was expected as symbols file which I generated was for amd64. As usual I got 2 serious bug reports #704718 and #705135. Solution First I was not sure how to handle this. I read article on symbols files handling by rra [1] and tried to use pkgkde-symbolshelper tool only to quickly figure out that I need to use pkgkde_symbolshelper addon for dh sequencer. But this was not possible for me as I was using CDBS for packaging. I did a quick chat on #debian-mentors and some one suggested me to tag symbols which vary across architecture with (c++) tag. First I was not sure but after reading dpkg-gensymbols man page understood that I need to replace the entire mangled symbols lines with de-mangled version tagged with (c++) in the beginning. But this was hectic job searching for each deleted symbols and replacing it. So I thought of writing a script to do the job and after struggling for 3 days (yeah I was bit dumb that I didn't read manual date: "2013-04-14 18:39:20 +0530" pugixml and ctpp2 package using it, which is now waiting for Jonas for uploading it. Here is the script
#!/bin/bash
set +x
if [ $# -lt 3 ]; then
    echo "Usage: $0 failed_buildlogs_directory symbols_file package_version"
    exit 2
fi
    
BUILD_LOG_DIRECTORY=$1
SYMBOLS_FILE=$2
PACKAGE_VERSION=$3
VERSION_TO_REPLACE=" $PACKAGE_VERSION\""
for LOGFILE in $(ls $BUILD_LOG_DIRECTORY/*.build); do
    for i in $(grep '^-\s_Z' $LOGFILE   perl -pe 's/-//g;'); do
        if [ $i = $PACKAGE_VERSION ];then
            continue
        fi
        demangled_version="\""$(echo $i" "$PACKAGE_VERSION   c++filt)"\""
        tagged_version="(c++)"$ demangled_version%$VERSION_TO_REPLACE "\" "$PACKAGE_VERSION
        escaped_tagged_version=$(echo $tagged_version   sed 's/\&/\\\&/')
        sed -i "s#$i $PACKAGE_VERSION#$escaped_tagged_version#" $SYMBOLS_FILE
   done
done
So basically to make this work we need all buildlogs to be downloaded from buildd's again this was easy thanks to rra for developing pkgkde-getbuildlogs :-). Once you have build logs directory run the above script as follows
cppsymbol_replace.sh path_to_buildlogs path_to_symbol_file upstream_version
After replacing symbols I tried to build package on i386 chroot and build passed successfully but lintian told me that there are symbols which have Debian version appended to it and this might lead to date: "2013-04-14 18:42:42 +0530" back to mentors :-). It is this time I really understood concept of mangled names generated by compiler and why it vary across the architecture ;-). This time some one by nick pochu suggested me to pass option -v with package version to dpkg-gensymbols to make it generate symbols with package version and not Debian version. The following probably needs to be done if package uses dh sequencer but I'm not sure as I've not tested it. If wrong please correct me.
override_dh_makeshlibs:
    dh_makeshlibs -- -v$PACKAGEVERION #package version needs to be either extracted using parsechangelog or manually fed
If you are using CDBS this is pretty simple. Just add following to rules
DEB_DH_MAKESHLIBS_ARGS_$(pkgname) += -- -v$(DEB_UPSTREAM_VERSION)
I noticed that when I provide (c++) tagged de-mangled name dpkg-gensymbols simply replaces it with proper mangled name but the deletion doesn't trigger an error in dpkg-gensymbols. This script me allowed to replace 128 symbols which were very tricky and long with de-mangled and tagged version in ctpp2, so I hope it should work across different packages without any problem. Only silly mistake I did was occurrence of & symbol in function making sed go mad which I took one full day to debug :facepalm:. So that's it folks, if you see something wrong in what I did please let me know through the comments. [1] http://www.eyrie.org/~eagle/journal/2012-01/008.html

8 March 2013

Vasudev Kamath: Multi-Arch lintian check for font packages

I've provided a new patch #701061 for lintian to warn about font packages that are not marked as Multi-Arch foreign or allowed. Its already included in the lintian by Neils Thykier and will be part of version 2.5.12. The following tag has been implemented
font-package-not-multi-arch-foreign
A Bit of History for this implementation is as follows: We got a bug report on one of the fonts in pkg-fonts team that its not been installed in i386 architecture on a amd64 multi-arch system #694864. We were first confused but Daniel Kahn Gillmor pointed that we indeed need to mark all font packages as Multi-Arch foreign. He proposed that we should write a lintian check for this which I volunteered to do and then forgot!. Recently I was checking my QA page and landed into Ubuntu's page of my package where I saw they were patching imported font package and marking them as Multi-Arch: foreign and I suddenly remembered my promise! and this patch was the result of same enlightenment :-). Since there is huge number of font packages maintained by pkg-fonts devel we targeted this for Jessie release.
Here by I request all font package maintainers to consider marking their packages as Multi-Arch foreign. I also request people to join us on pkg-fonts-devel and help us doing this for all font packages maintained by the team, we really lack people in the team.

11 February 2013

Vasudev Kamath: CDBS Packaging : copyright file support

One of the thing CDBS provides is support for verifying / generating debian/copyright file. This feature will be help full if new files show up in newer releases. It can also be helpful to generate the first version of copyright file. But don't blindly follow this feature, you need to cross verify the things it generates. To use this feature add the following line to your debian/rules file first
include /usr/share/cdbs/1/rules/utils.mk 
 
Now create a file called debian/copyright_hints using touch command
touch debian/copyright_hints
Now run the following command to allow CDBS to do its magic and generate a new file called debian/copyright_newhints
DEB_MAINTAINER_MODE=1 fakeroot debian/rules build
As you see we set the variable DEB_MAINTAINER_MODE which means this is feature to help the maintainer rather than targeted for automatic builds. So if there is no new things added to the new release you should see something like this in the build log.
Scanning upstream source for new/changed copyright notices...
licensecheck -c '.*' -r --copyright -i '^debian/(changelog copyright( _hints _newhints))' -l '99999' *   /usr/lib/cdbs/licensecheck2dep5 > debian/co$
yright_newhints
19 combinations of copyright and licensing found.
No new copyright notices found - assuming no news is good news...
In case there are new files added you should get output similar to below
Scanning upstream source for new/changed copyright notices...
licensecheck -c '.*' -r --copyright -i '^debian/(changelog copyright( _hints _newhints))' -l '99999' *   /usr/lib/cdbs/licensecheck2dep5 > debian/co$
yright_newhints
0 combinations of copyright and licensing found.
Format: http://www.debian.org/doc/packaging-manuals/ 
Upstream-Name: FIXME
Upstream-Contact: FIXME
Source: FIXME
Disclaimer: Autogenerated by CDBS
...
To fix the situation please do the following:
  1) Fully compare debian/copyright_hints with debian/copyright_newhints
  2) Update debian/copyright as needed
  3) Replace debian/copyright_hints with debian/copyright_newhints
So as the last 3 points says you need to compare your copyright_hints and the newly generated file by CDBS copyright_newhints for difference and update the debian/copyright as required and replace the existing debian/copyright_hints with debian/copyright_newhints. Tips
  1. This feature can be used to generate the copyright file for the first time you need a copyright file with only debian/* copyright in it.
  2. If you are using it to generate copyright file for the first time be sure to cross verify the things mentioned in the file than just blindly copy pasting.
  3. If there are binary files like images are involved in your project be sure to clean up those from your copyright_hints before trying to build the package. Because of too much of binary cruft in any files means dpkg-source will be angry at you :-).
Last but not the least, I know CDBS provides some really cool features which we will explore with next few posts but always keep in mind this quote by Jonas. (Of course don't ask me to prove that Jonas did say it as there is no pgp signature of him with quote to verify ;-) )
CDBS is tool to help packagers and does not involve any magic.

Vasudev Kamath: New Series of Posts on CDBS packaging

Well this is just an introductory post to set of posts I'm going to write down here on my blog. Idea is to improve the documentation of CDBS but I still don't have any idea on how I can patch the existing documentation, but in the mean time I'm learning new tricks from Jonas which I want to document some where so I thought my blog would be a good place as whole blog is in markdown format and its the same format me and Jonas agreed to convert the existing CDBS documentation. So this blog will act as a documentation and these post will be then altered modified and put back into a proper CDBS documentation later. I know many people don't like CDBS and most of it because there is no proper documentation, so I'm trying to improve the situation so sit back and enjoy the upcoming posts :-). OK I was sloppy in giving theory on what others think about the CDBS thanks to Phill Hands and Jonas for enlightening me. So with these series I'm just trying to explain CDBS features with real examples and examples how you can tame nasty packaging beasts with CDBS easily.

27 December 2012

Vasudev Kamath: Note to Self: Telling apt to download specific architecture information only

If you have enabled multi-arch enabled in your system and one of the third party repository you use in /etc/apt/sources.list is not providing the foreign arch you have selected then fear not just do the below for that particular repository line.
deb [arch=arch1] uri distribution component
In my case mozilla.debian.net doesn't provide binary-armel hence I just did this
deb [arch=amd64] http://localhost:9999/mdn experimental iceweasel-aurora
and apt stopped complaining about missing foreign arch. Well this is present in man page of sources.list but I just wrote here so I can find it easily next time :-).

19 November 2012

Vasudev Kamath: Weekly Log - 17/23 - 112012

The last week was quite productive as I was on vacation and at home town but sadly I couldn't complete this post so again merging the work with this week but this week ain't much productive as I was tired from journey back and didn't get enough time to recover. So here it goes. Debian Related Upstream Related I raised a pull request #8 on Gubbi fixing the Makefile to more organized and introducing xz compression in it. Additionally I removed distribution specific stuffs from Makefile and made it generic. That's all for the two weeks. This week there will be foss.in and we will be having some Debian specific mini conference, including some Debian basics to newbies and some bug squashing if any :-). So more to report next week, till then Cya.

11 November 2012

Vasudev Kamath: Weekly Log - 27/3 - 112012

OK I became again lazy to log my works and combined 2 weeks again :-). Most of my work is for Debian for this 2 weeks. This week was bit hectic I couldn't dedicate much time for any programming. This week I'm on vacation and will get more time to work on FLOSS and other coding stuffs. Only that I'm on slow network connection :-). Ok cya next week (hopefully) PS: My last weekly log never showed up in planet.d.o not sure what happened may be because I played with feed generating jekyll scripts. Hope this will show up in planet.d.o [1] http://code.metager.de/source/xref/linux/utils/util-linux/sys-utils/setsid.c
[2] http://vasudev.homelinux.net/display/copyninja/34241
[3] https://kakste.com/display/beardyunixer/974150
[4] anonscm.debian.org/gitweb/?p=collab-maint/friendica.git;a=summary

13 October 2012

Vasudev Kamath: Weekly Log - 06/13-102012

Update for 06/10/2012 Well I had not written the weekly work log for the last week that is because the week was short (oh yeah thanks to all these bandhs our week got fluctuated and to be frank the week was only 4 days long) and second was my lazyness. Here goes the update * After a long discussion with Aravinda on "why productivity is reducing these days." We concluded the social network is eating up most of time. So decision was made and I closed all pinned tabs for Twitter Gmail Identi.ca and Friendica on my browser * After the above resolution I finished almost 4 chapters of Moder Perl within 2 hours!. Indeed Social networks kill the productivity. Update for 13/10/2012 I've really fallen in love with computerised bots, thanks to the wonderful KGB bot :-). So majority of my work on this week is on bots. Jabber Dictionary Redesign After thinking for a while I decided to re-write the dictionary bot which when release got an overwhelming response as see in the comments of above link. Few reason for re-write
  1. Generalise the bot framework so single bot can handle multiple languages
  2. Improve the data collection on bot side
  3. Current code base was not very well organised and trying to add more feature it had become messy.
  4. Provide XEP support to help in data collections
Few changes which are already implemented include
  1. New code is now using pyxmpp2 library instead of GPLed xmppy used by current code.
  2. Implemented XEP-0071 extension to properly format the meaning display by the bot
  3. Current implementation was displaying all words in one set without distinguishing between adjectives,verbs proverbs etc. even though wiktionary displays meaning based on this. New implementation gives out meaning in same format as it is displayed on wiktionary.
Things remaining todo
  1. Separating wiktionary parsing logic from bot code by providing some sort of intermediate interface between bot and wiktionary parsers.
  2. Adding more language wiktionary parsers and teaching the bot to become multilingual :-)
  3. Integrating XEP-0004 (Data Forms) for taking the meaning input from user. Current code requires user to enter data in particular format
suckless-tools fix for Wheezy Jakub Wilk suggested me to prepare a minimal version of suckless-tools for Wheezy which includes a patch to the bug #685611. And few minor changes which involve taking over the package and fixes in copyright file other than above mentioned bug. Hopefully release-team will be okay with these changes. I'm waiting for the upload to file an unblock-request. I did face a problem I was halfway through wit suckless-tools_39-1 when Jakub asked me about this change and current repository was fresh one prepared for 39-1 and didn't have history for 38 version. First I thought of preparing separate repository for 38 version which was not an correct option, but I even couldn't play with current repository. So finally I renamed current version of repository to suckless-tools-39.git on collab-maint and prepared fresh repository suckless-tools.git basing it on 38-1 version. From 39 version suckless-tools will be following 3.0 (quilt) source format and will not be working with git-buildpackage as the tool can't handle multi-tarball packages. Yes every tool involved in the package will have separate tarball from 39. More work on Bots Well today I again worked on Jabber bot, but not the dictionary bot. This time its an SMS Gateway bot for Jonas Smedegard and the coding was done in Perl. Thanks to jonas I finally could apply what I learnt in Perl. Code may not be very elegant but it works :-). And after hacking one full day in Perl now I'm not feeling very much interested to go back and hack on my own Python based dictionary bot :-). But I will anyway. Misc So that's it folks. Quite longish post hope you are not bored reading it :-). Well time for movie C'ya all with next weeks log.

Next.

Previous.