Search Results: "tar"

3 November 2016

Simon Josefsson: Why I don t Use 2048 or 4096 RSA Key Sizes

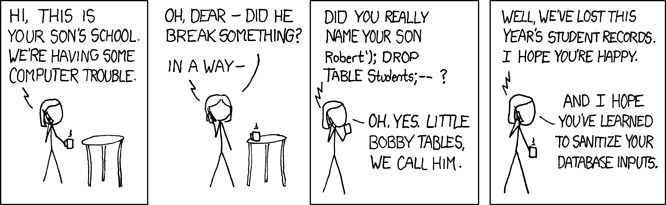
I have used non-standard RSA key size for maybe 15 years. For example, my old OpenPGP key created in 2002. With non-standard key sizes, I mean a RSA key size that is not 2048 or 4096. I do this when I generate OpenPGP/SSH keys (using GnuPG with a smartcard like this) and PKIX certificates (using GnuTLS or OpenSSL, e.g. for XMPP or for HTTPS). People sometimes ask me why. I haven t seen anyone talk about this, or provide a writeup, that is consistent with my views. So I wanted to write about my motivation, so that it is easy for me to refer to, and hopefully to inspire others to think similarily. Or to provoke discussion and disagreement that s fine, and hopefully I will learn something. Before proceeding, here is some context: When building new things, it is usually better to use the Elliptic Curve technology algorithm Ed25519 instead of RSA. There is also ECDSA which has had a comparatively slow uptake, for a number of reasons that is widely available and is a reasonable choice when Ed25519 is not available. There are also post-quantum algorithms, but they are newer and adopting them today requires a careful cost-benefit analysis. First some background. RSA is an asymmetric public-key scheme, and relies on generating private keys which are the product of distinct prime numbers (typically two). The size of the resulting product, called the modulus n, is usually expressed in bit length and forms the key size. Historically RSA key sizes used to be a couple of hundred bits, then 512 bits settled as a commonly used size. With better understanding of RSA security levels, the common key size evolved into 768, 1024, and later 2048. Today s recommendations (see keylength.com) suggest that 2048 is on the weak side for long-term keys (5+ years), so there has been a trend to jump to 4096. The performance of RSA private-key operations starts to suffer at 4096, and the bandwidth requirements is causing issues in some protocols. Today 2048 and 4096 are the most common choices. My preference for non-2048/4096 RSA key sizes is based on the simple and na ve observation that if I would build a RSA key cracker, there is some likelihood that I would need to optimize the implementation for a particular key size in order to get good performance. Since 2048 and 4096 are dominant today, and 1024 were dominent some years ago, it may be feasible to build optimized versions for these three key sizes. My observation is a conservative decision based on speculation, and speculation on several levels. First I assume that there is an attack on RSA that we don t know about. Then I assume that this attack is not as efficient for some key sizes than others, either on a theoretical level, at implementation level (optimized libraries for certain characteristics), or at an economic/human level (decision to focus on common key sizes). Then I assume that by avoiding the efficient key sizes I can increase the difficulty to a sufficient level. Before analyzing whether those assumptions even remotely may make sense, it is useful to understand what is lost by selecting uncommon key sizes. This is to understand the cost of the trade-off. A significant burden would be if implementations didn t allow selecting unusual key sizes. In my experience, enough common applications support uncommon key sizes, for example GnuPG, OpenSSL, OpenSSH, FireFox, and Chrome. Some applications limit the permitted choices; this appears to be rare, but I have encountered it once. Some environments also restrict permitted choices, for example I have experienced that LetsEncrypt has introduced a requirement for RSA key sizes to be a multiples of 8. I noticed this since I chose a RSA key size of 3925 for my blog and received a certificate from LetsEncrypt in December 2015 however during renewal in 2016 it lead to an error message about the RSA key size. Some commercial CAs that I have used before restrict the RSA key size to one of 1024, 2048 or 4096 only. Some smart-cards also restrict the key sizes, sadly the YubiKey has this limitation. So it is not always possible, but possible often enough for me to be worthwhile. Another cost is that RSA signature operations are slowed down. This is because the exponentiation function is faster than multiplication, and if the bit pattern of the RSA key is a 1 followed by several 0 s, it is quicker to compute. I have not done benchmarks, but I have not experienced that this is a practical problem for me. I don t notice RSA operations in the flurry of all of other operations (network, IO) that is usually involved in my daily life. Deploying this on a large scale may have effects, of course, so benchmarks would be interesting. Back to the speculation that leads me to this choice. The first assumption is that there is an attack on RSA that we don t know about. In my mind, until there are proofs that the currently known attacks (GNFS-based attacks) are the best that can be found, or at least some heuristic argument that we can t do better than the current attacks, the probability for an unknown RSA attack is therefor, as strange as it may sound, 100%. The second assumption is that the unknown attack(s) are not as efficient for some key sizes than others. That statement can also be expressed like this: the cost to mount the attack is higher for some key sizes compared to others. At the implementation level, it seems reasonable to assume that implementing a RSA cracker for arbitrary key sizes could be more difficult and costlier than focusing on particular key sizes. Focusing on some key sizes allows optimization and less complex code. At the mathematical level, the assumption that the attack would be costlier for certain types of RSA key sizes appears dubious. It depends on the kind of algorithm the unknown attack is. For something similar to GNFS attacks, I believe the same algorithm applies equally for a RSA key size of 2048, 2730 and 4096 and that the running time depends mostly on the key size. Other algorithms that could crack RSA, such as some approximation algorithms, does not seem likely to be thwarted by using non-standard RSA key sizes either. I am not a mathematician though. At the economical or human level, it seems reasonable to say that if you can crack 95% of all keys out there (sizes 1024, 2048, 4096) then that is good enough and cracking the last 5% is just diminishing returns of the investment. Here I am making up the 95% number. Currently, I would guess that more than 95% of all RSA key sizes on the Internet are 1024, 2048 or 4096 though. So this aspect holds as long as people behave as they have done. The final assumption is that by using non-standard key sizes I raise the bar sufficiently high to make an attack impossible. To be honest, this scenario appears unlikely. However it might increase the cost somewhat, by a factor or two or five. Which might make someone target a lower hanging fruit instead. Putting my argument together, I have 1) identified some downsides of using non-standard RSA Key sizes and discussed their costs and implications, and 2) mentioned some speculative upsides of using non-standard key sizes. I am not aware of any argument that the odds of my speculation is 0% likely to be true. It appears there is some remote chance, higher than 0%, that my speculation is true. Therefor, my personal conservative approach is to hedge against this unlikely, but still possible, attack scenario by paying the moderate cost to use non-standard RSA key sizes. Of course, the QA engineer in me also likes to break things by not doing what everyone else does, so I end this with an ObXKCD.

Guido G nther: Debian Fun in October 2016

Debian LTS October marked the eighteenth month I contributed to Debian LTS under the Freexian umbrella. I spent 10 hours (out of allocated 9) Other Debian stuff Some other Free Software activities

Norbert Preining: Debian/TeX Live 2016.20161103-1

This month s update falls onto a national holiday in Japan. My recent start as a normal company employee in Japan doesn t leave me enough time during normal days to work on Debian, so things have to wait for holidays. There have been a few notable changes in the current packages, and above all I wanted to fix an RC bug and on the way fixed also several other (sometimes rather old) bugs.
texlive2016-debian From the list of new packages I want to pick apxproof: I have written something myself for one of my rather long papers (with proofs about 60pp), where at times I had to factor out the proofs into an appendix. I did this my own way, but I would have preferred to have a nice package! Another interesting change is the upstream merge of collection-mathextra (which translated to the Debian package texlive-math-extra) and collection-science (Debian: texlive-science) into a new collection collection-mathscience. Since introducing new packages and phasing out old ones is generally a pain in Debian, I decided to digress from the upstream naming convention and use texlive-science for the new collection-mathscience. In the end Mathematics is the most important science of all  Finally also a word about removals: Several ConTeXt packages have been removed due to the fact that they are outdated. These removals will find their way in an update of the Debian ConTeXt package in near future. The TeX Live packages lost voss-mathmode, which was retracted by the author due to various reasons. He is working on an updated version that will hopeful reappear in both TeX Live and Debian in near future. Well, that s it for now. Here now the full list with links. Enjoy. New packages apxproof, bangorexam, biblatex-gb7714-2015, biblatex-lni, biblatex-sbl, context-cmscbf, context-cmttbf, context-inifile, context-layout, delimset, latex2nemeth, latexbangla, latex-papersize, ling-macros, notex-bst, platex-tools, testidx, uppunctlm, wtref, xcolor-material. Removed packages voss-mathmode. Updated packages apa6, autoaligne, babel-german, biblatex-abnt, biblatex-anonymous, biblatex-apa, biblatex-manuscripts-philology, biblatex-nature, biblatex-realauthor, bibtex, bidi, boondox, bxcjkjatype, chickenize, churchslavonic, cjk-gs-integrate, context-filter, cooking-units, ctex, denisbdoc, dvips, europasscv, fixme, glossaries, gzt, handout, imakeidx, ipaex-type1, jsclasses, jslectureplanner, kpathsea, l3build, l3experimental, l3kernel, l3packages, latexindent, latexmk, listofitems, luatexja, marginnote, mcf2graph, minted, multirow, nameauth, newpx, newtx, noto, nucleardata, optidef, overlays, pdflatexpicscale, pst-eucl, reledmac, repere, scanpages, semantic-markup, tableaux, tcolorbox, tetex, texlive-scripts, ticket, todonotes, tracklang, tudscr, turabian-formatting, updmap-map, uspace, visualtikz, xassoccnt, xecjk, yathesis.

2 November 2016

Enrico Zini: schroot connector for ansible

I accidentally made an ansible connector plugin for schroot. I haven't even used ansible yet, so I have no idea what I am doing. You can choose the chroot type by setting something like schroot_type: jessie in your variables. You can install this locally as connection_plugins/schroot.py.
# Based on chroot.py (c) 2013, Maykel Moya <mmoya@speedyrails.com>
# Based on chroot.py (c) 2015, Toshio Kuratomi <tkuratomi@ansible.com>
# (c) 2016, Enrico Zini <enrico@debian.org>
#
# This is free software: you can redistribute it and/or modify
# it under the terms of the GNU General Public License as published by
# the Free Software Foundation, either version 3 of the License, or
# (at your option) any later version.
#
# Ansible is distributed in the hope that it will be useful,
# but WITHOUT ANY WARRANTY; without even the implied warranty of
# MERCHANTABILITY or FITNESS FOR A PARTICULAR PURPOSE.  See the
# GNU General Public License for more details.
#
# You should have received a copy of the GNU General Public License
# along with Ansible.  If not, see <http://www.gnu.org/licenses/>.
from __future__ import (absolute_import, division, print_function)
__metaclass__ = type
import distutils.spawn
import os
import os.path
import pipes
import subprocess
import traceback
from ansible import constants as C
from ansible.errors import AnsibleError
from ansible.plugins.connection import ConnectionBase, BUFSIZE
from ansible.module_utils.basic import is_executable
from ansible.utils.unicode import to_bytes
try:
    from __main__ import display
except ImportError:
    from ansible.utils.display import Display
    display = Display()
class Connection(ConnectionBase):
    ''' Local chroot based connections '''
    transport = 'schroot'
    has_pipelining = True
    # su currently has an undiagnosed issue with calculating the file
    # checksums (so copy, for instance, doesn't work right)
    # Have to look into that before re-enabling this
    become_methods = frozenset(C.BECOME_METHODS).difference(('su',))
    def __init__(self, play_context, new_stdin, *args, **kwargs):
        super(Connection, self).__init__(play_context, new_stdin, *args, **kwargs)
        self.chroot = self._play_context.remote_addr
        #if os.geteuid() != 0:
            #raise AnsibleError("chroot connection requires running as root")
        # we're running as root on the local system so do some
        # trivial checks for ensuring 'host' is actually a chroot'able dir
        #if not os.path.isdir(self.chroot):
        #    raise AnsibleError("%s is not a directory" % self.chroot)
        #chrootsh = os.path.join(self.chroot, 'bin/sh')
        ## Want to check for a usable bourne shell inside the chroot.
        ## is_executable() == True is sufficient.  For symlinks it
        ## gets really complicated really fast.  So we punt on finding that
        ## out.  As long as it's a symlink we assume that it will work
        #if not (is_executable(chrootsh) or (os.path.lexists(chrootsh) and os.path.islink(chrootsh))):
        #    raise AnsibleError("%s does not look like a chrootable dir (/bin/sh missing)" % self.chroot)
        self.chroot_cmd = distutils.spawn.find_executable('schroot')
        if not self.chroot_cmd:
            raise AnsibleError("chroot command not found in PATH")
        self.chroot_id = "session:" + self.chroot
        self.chroot_type = "stable"
        existing = subprocess.check_output([self.chroot_cmd, "--list", "--all"])
        self.chroot_exists = False
        for line in existing.splitlines():
            if line == self.chroot_id:
                self.chroot_exists = True
    def set_host_overrides(self, host, hostvars=None):
        super(Connection, self).set_host_overrides(host, hostvars)
        self.chroot_type = hostvars.get("schroot_type", self.chroot_type)
    def _connect(self):
        ''' connect to the chroot; nothing to do here '''
        super(Connection, self)._connect()
        if not self._connected:
            if not self.chroot_exists:
                self.chroot_id = subprocess.check_output([self.chroot_cmd, "-b", "-c", self.chroot_type, "-n", self.chroot]).strip()
                subprocess.check_call([self.chroot_cmd, "-r", "-c", self.chroot_id, "-u", "root", "--", "apt-get", "update"])
                subprocess.check_call([self.chroot_cmd, "-r", "-c", self.chroot_id, "-u", "root", "--", "apt-get", "-y", "install", "python"])
            display.vvv("THIS IS A LOCAL CHROOT DIR", host=self.chroot)
            self._connected = True
    def _buffered_exec_command(self, cmd, stdin=subprocess.PIPE):
        ''' run a command on the chroot.  This is only needed for implementing
        put_file() get_file() so that we don't have to read the whole file
        into memory.
        compared to exec_command() it looses some niceties like being able to
        return the process's exit code immediately.
        '''
        executable = C.DEFAULT_EXECUTABLE.split()[0] if C.DEFAULT_EXECUTABLE else '/bin/sh'
        local_cmd = [self.chroot_cmd, "-r", "-c", self.chroot_id, "-u", "root", "--", executable, '-c', cmd]
        display.vvv("EXEC %s" % (local_cmd), host=self.chroot)
        local_cmd = [to_bytes(i, errors='strict') for i in local_cmd]
        p = subprocess.Popen(local_cmd, shell=False, stdin=stdin,
                stdout=subprocess.PIPE, stderr=subprocess.PIPE)
        return p
    def exec_command(self, cmd, in_data=None, sudoable=False):
        ''' run a command on the chroot '''
        super(Connection, self).exec_command(cmd, in_data=in_data, sudoable=sudoable)
        p = self._buffered_exec_command(cmd)
        stdout, stderr = p.communicate(in_data)
        return (p.returncode, stdout, stderr)
    def _prefix_login_path(self, remote_path):
        ''' Make sure that we put files into a standard path
            If a path is relative, then we need to choose where to put it.
            ssh chooses $HOME but we aren't guaranteed that a home dir will
            exist in any given chroot.  So for now we're choosing "/" instead.
            This also happens to be the former default.
            Can revisit using $HOME instead if it's a problem
        '''
        if not remote_path.startswith(os.path.sep):
            remote_path = os.path.join(os.path.sep, remote_path)
        return os.path.normpath(remote_path)
    def put_file(self, in_path, out_path):
        ''' transfer a file from local to chroot '''
        super(Connection, self).put_file(in_path, out_path)
        display.vvv("PUT %s TO %s" % (in_path, out_path), host=self.chroot)
        out_path = pipes.quote(self._prefix_login_path(out_path))
        try:
            with open(to_bytes(in_path, errors='strict'), 'rb') as in_file:
                try:
                    p = self._buffered_exec_command('dd of=%s bs=%s' % (out_path, BUFSIZE), stdin=in_file)
                except OSError:
                    raise AnsibleError("chroot connection requires dd command in the chroot")
                try:
                    stdout, stderr = p.communicate()
                except:
                    traceback.print_exc()
                    raise AnsibleError("failed to transfer file %s to %s" % (in_path, out_path))
                if p.returncode != 0:
                    raise AnsibleError("failed to transfer file %s to %s:\n%s\n%s" % (in_path, out_path, stdout, stderr))
        except IOError:
            raise AnsibleError("file or module does not exist at: %s" % in_path)
    def fetch_file(self, in_path, out_path):
        ''' fetch a file from chroot to local '''
        super(Connection, self).fetch_file(in_path, out_path)
        display.vvv("FETCH %s TO %s" % (in_path, out_path), host=self.chroot)
        in_path = pipes.quote(self._prefix_login_path(in_path))
        try:
            p = self._buffered_exec_command('dd if=%s bs=%s' % (in_path, BUFSIZE))
        except OSError:
            raise AnsibleError("chroot connection requires dd command in the chroot")
        with open(to_bytes(out_path, errors='strict'), 'wb+') as out_file:
            try:
                chunk = p.stdout.read(BUFSIZE)
                while chunk:
                    out_file.write(chunk)
                    chunk = p.stdout.read(BUFSIZE)
            except:
                traceback.print_exc()
                raise AnsibleError("failed to transfer file %s to %s" % (in_path, out_path))
            stdout, stderr = p.communicate()
            if p.returncode != 0:
                raise AnsibleError("failed to transfer file %s to %s:\n%s\n%s" % (in_path, out_path, stdout, stderr))
    def close(self):
        ''' terminate the connection; nothing to do here '''
        super(Connection, self).close()
        #subprocess.check_command([self.chroot_cmd, "-e", "-c", self.chroot_id])
        self._connected = False

Markus Koschany: My Free Software Activities in October 2016

Welcome to gambaru.de. Here is my monthly report that covers what I have been doing for Debian. If you re interested in Android, Java, Games and LTS topics, this might be interesting for you. Debian Android Debian Games Debian Java Debian LTS This was my eight month as a paid contributor and I have been paid to work 13 hours on Debian LTS, a project started by Rapha l Hertzog. In that time I did the following: Non-maintainer uploads QA

Rapha&#235;l Hertzog: My Free Software Activities in October 2016

My monthly report covers a large part of what I have been doing in the free software world. I write it for my donors (thanks to them!) but also for the wider Debian community because it can give ideas to newcomers and it s one of the best ways to find volunteers to work with me on projects that matter to me. Debian LTS Last month I started to work on tiff3 but had not enough time to complete an update, it turns out the issues were hairy enough that nobody else picked up the package. So this month I started again with tiff3 and tiff and I ended up spending my 13h on those two packages. I filed bugs for issues that were not yet reported to the BTS (#842361 for CVE-2016-5652, #842046 for CVE-2016-5319/CVE-2016-3633/CVE-2015-8668). I marked many CVE as not affecting tiff3 as this source package does not ship the tools (the tiff source package does). Since upstream decided to drop many tools instead of fixing the corresponding security issues, I opted to remove the tools as well. Before doing this, I looked up reverse dependencies of libtiff-tools to ensure that none of the tools removed are used by other packages (the maintainer seems to agree too). I backported upstream patches for CVE-2016-6223 and CVE-2016-5652. But the bulk of the time, I spent on CVE-2014-8128, CVE-2015-7554 and CVE-2016-5318. I believe they are all variants of the same problem and upstream seems to agree since he opened a sort of meta-bug to track them. I took inspiration from a patch suggested in ticket #2499 and generalized it a bit by trying to add the tag data for all tags manipulated by the various tools. It was a tiresome process as there are many tags used in multiple places. But in the end, it works as expected. I can no longer reproduce any of the segfaults with the problematic files. I asked for review/test on the mailing list but did not get much feedback. I m going to upload the updated packages soon. Distro Tracker I noticed a sudden raise in the number of email addresses being automatically unsubscribed from the Debian Package Tracker and I got a few request of bounces. It turns out the BTS has been relaying lots of spam with executables files and those are bounced by Google (and not silently discarded). This is all very unfortunate the spam flood is unlikely to stop soon and I can t expect Google to change either, so I had little choice except trying to make the bounce handler smarter. That s what I did: I have a list of regular expression that will discard a bounce. In other words, once matched the bounce won t count towards the limit that triggers the automatic unsubscription. Misc Debian work Bugs filed. In #839403, I suggest the possibility to set the default pin priority for a source in the sources.list file directly. In #840436 I ask the selenium-firefoxdriver maintainer to do what is required to get this non-free package auto-built. Packaging. I sponsored puppet-lint 2.0.2-0.1 and I reviewed the rozofs package (wihch I just sponsored into experimental for a start). Publicity. I m maintaining the Debian account on Twitter and Facebook. I have been using twitterfeed.com up to now but it s closing down. I followed their recommendations and switched to dlvr.it to automatically post entries out of the micronews.debian.org feed. In #841165, I reported that the chroots created by sbuild-createchroot are lacking the usual IPv6 entries created by netbase. In #841503, I report a very common cryptsetup upgrade failure that I saw multiple times (both in Debian and in Kali). Thanks See you next month for a new summary of my activities.

No comment Liked this article? Click here. My blog is Flattr-enabled.

1 November 2016

Jonathan Wiltshire: Reflecting on a year of regular, public IRC meetings

The release team first started holding a regular, public planning and status meeting a little over a year ago, in September 2015. At that time, FTP masters had experimented along similar lines and I took some inspiration from that, including the keeping of proper minutes that anyone can look at. I wanted to open up our discussion processes and allow other developers and users to see (and perhaps influence) our plans for the release taking shape month by month, and how we reached certain decisions with a lot of mature discussion and not just on a whim. A secondary aim, since we are quite geographically distributed and getting together for same-room meetings is hard, was to bring more accountability to ourselves when we decided something ought to happen; if it s in the minutes, there s no escaping someone asking so what happened to ? . That s worked better for us on some topics than on others. Finally, public minutes mean that anyone who might be interested in joining the team can see easily what we re up to and how we shape the release throughout the cycle. That might help lower the barrier to entry, which can only be good for the team. I had hoped that regular meetings would inspire other teams to do similar; I haven t seen any indication of that to date (though perhaps it s just down to awareness). The Reproducible Builds contributors held fortnightly meetings for a period in 2015, though not inspired by ours, and I heard recent talk of starting those again. I still think that there is plenty of scope to improve the transparency of core teams in general in Debian, but also that regular meetings aren t going to work for every team. A regular slot which is not varied except when absolutely necessary, is essential for avoiding the temptation to just push it back another week when things are busy. In our office we have an allegedly-regular Thursday afternoon slot for technical demonstrations, which has suffered from exactly that problem for a long time now, and I wanted to avoid that issue. We have a calendar to remind us when each meeting is due, along with other important events like freeze milestones. Our slot is the fourth Wednesday of the month, a fairly arbitrary choice which seems to have worked out quite well. Time zones are more of an issue, even within Europe. We have mostly used a European evening time, but that s not very helpful further West where it s in the middle of the working day, or the middle of the night if you re further East (that one fortunately isn t an issue for us so far). Even within Europe it s difficult, as we have to try and balance commuting time in the UK with dinner on the continent, or dinner with late evening, or adjust for saving changes, or you get the idea. If we gained a far-eastern team member one day, this would be a real issue. We use Meetbot for recording the minutes. I have heard criticism that it publicly archives IRC logs to the web essentially forever, but for us that s the whole point. With a little practice and discipline it does generate really nice minutes, with a bullet summary of the important parts, a summary of actions agreed and a log of the conversation for detailed reference. Anybody reading them can see how we reached a conclusion, and I m of the view that goes some way to avoiding a reputation for cabal-ism. It does pay to use the #info, #agree and #action tags liberally, but other things are slightly unnatural like always remembering to use a URL at the beginning of a line and not in the middle of a sentence, or Meetbot doesn t notice it. Practice goes a long way. I ve naturally fallen into chairing most meetings, for better or worse the consistency seems beneficial, but I worry that I m dominating the discussion sometimes. Discipline in making sure everybody has been included is something I ve had to get better at. It s essential to have a public agenda and to stick to it, and it should include some stock items at the start and end (including making sure the URL to the previous minutes has been given, reviewing outstanding actions, and arranging the next meeting before ending the current one). There is some skill in judging the agenda length and deciding which items can be deferred to make sure it doesn t drag on too late we ve found anything more than an hour is far too long, and between 45 and 60 minutes is pushing it. Getting some easy topics out of the way before starting one which is more contentious can be helpful to avoid having to defer them later. I circulate the URL to the minutes and the date of the next meeting publicly on the mailing list immediately after each meeting, or as soon as possible. With little feedback, I have no idea if our meetings are helpful to those outside the team or not. We do still hold in-person meetings from time to time when we re all together, because they re useful for some circumstances (like some genuinely private topics we occasionally need to discuss, or for sprinting). I would hope that public meetings inspire confidence that we re on top of the release process, that they show we have a mature and transparent decision making process (for example, in deciding to move the freeze date to accommodate an external release schedule as a one-off, and subsequently deciding to not move it back when circumstances changed), and mostly that other teams might benefit for the same reasons. But I can also see that they make more sense in a team with a defined project cycle than they might in one which is more administrative or where work is more sporadic (no point holding a meeting for the sake of it, after all).

Thorsten Alteholz: My Debian Activities in October 2016

FTP assistant This month I caught up from last month and marked 317 packages for accept and rejected 23 packages. I also sent 5 emails to maintainers asking questions. Debian LTS This was my twenty-eighth month that I did some work for the Debian LTS initiative, started by Raphael Hertzog at Freexian. This month my all in all workload has been 13h. During that time I did uploads of The second upload of bind was an embargoed one. Other stuff I uploaded a new version of greylistd and fixed RC bug #837501. A new version of highlight.js fixed RC bug #830189. With a new upstream version of chktex I could close bugs #782342, #782343 and #819885. I also uploaded the new package node-random-bytes and new upstream versions of alljoyn-core-1604 and duktape Finally, after about 4 years, I managed to upload entropybroker and instantly had to deal with #840018, #840019 and #840020. One cannot overemphasize the importance of our QA stuff! I also uploaded a new version of libctl to solve the -fPIC issue but was asked short time after to revert that again :-(. As already mentioned some days ago I adopted libmatthew-java. At that time about 956 package were orphaned and I asked everybody to adopt one of these packages. Unfortunately now there are 982 package orphaned. I guess I have to clear up a misunderstanding. You should adopt those packages and not oprhan more of them!

Simon Richter: Using the Arduino IDE with a tiling window manager

The Arduino IDE does not work properly with tiling window managers, because they do some interesting reparenting. To solve this, add
_JAVA_AWT_WM_NONREPARENTING=1
export _JAVA_AWT_WM_NONREPARENTING
to the start script or your environment. Credit: "Joost"

Jaldhar Vyas: Sal Mubarak 2073!

Wishing every one a happy Gujarati New Year, Vikram Samvat 2073 named Kilaka and hoping the upcoming year will be yuuge for you. These next couple of paragraphs are totally not an excuse for why it will take a few more days for me to reach seven blog posts. Reading reports about Diwali in the American press, I see a bit of confusion whether Diwali is one day or five. Well, technically it is just one (Sunday 30th this year.) but there are a number of other observances around it which could be classed as subsidiaries if you want to look at it that way. The season commenced last Wednesday with Rama Ekadashi. (where the Gujarati name is different I'll use that and put the Sanskrit name in parentheses.) That's a fast day and therefore not much fun. Thursday was Vagh Barash (vyaghra dvadashi) which as the name suggests is something to do with tigers but we don't in my experience particularly do anything special that day. Friday, things began in earnest with Dhan Terash (dhana trayodashi) when Lakshmi the Goddess of prosperity is worshipped. It is also a good day to buy gold. Saturday was Kali Chaudash (Kali Chaturdashi or Naraka Chaturdashi) On this day many Gujarati families including mine worship their Kuladevi (patron Goddess of the family) even if She is not an aspect of Kali. (Others observe this on the Ashtami of Navaratri.) The day is also associated with the God Hanuman. Some people say it is His Jayanti (birthday) though we observe it in Chaitra (March-April.) It is also the best day for learning mantras and I initiated a couple of people including my son into a mantra I know. Sunday was Diwali (Deepavali) proper. As a Brahmana I spent much of the day signing blessings in the account books of shopkeepers. Well, nowadays only a few old people have actual account books so usually the print out a spreadsheet and I sign that. But home is where the main action is. Lights are lit, fireworks are set off, and prayers are offered to Lakshmi. But most important of all, this is the day good boys and girls get presents. Unfortunately I have nothing interesting to report; just the usual utilitarian items of clothing. Fireworks by the way are technically illegal in New Jersey not that that ever stopped anyone from getting them. The past few years, Jersey City has attempted to compromise by allowing a big public fireworks display. Although it was nice and sunny all day, by nighttime we had torrential rain and the firework display got washed out. So I'm glad I rebelled against the system with my small cache of sparklers. Today (or yesterday by the time this gets posted.) was the Gujarati New Years Day. There is also the commemoration of the time the God Krishna lifted up Mt Govardhan with one finger which every mandir emulates by making an annakuta or mountain of food. Tuesday is Bhai Beeja (Yama Dvitiya in Sanskrit or Bhai Duj in Hindi) when sisters cook a meal for their brothers. My son is also going to make something (read: microwave something) for his sister. So those are the five days of Diwali. Though many will not consider it to be truly over until this Saturday, the lucky day of Labh Pancham (Labha panchami.) And if I still haven't managed to write seven blog posts by then, there is always Deva Diwali...

31 October 2016

Steve McIntyre: Twenty years...

So, it's now been twenty years since I became a Debian Developer. I couldn't remember the exact date I signed up, but I decided to do some forensics to find out. First, I can check on the dates on my first Debian system, as I've kept it running as a Debian system ever since!

jack:~$ ls -alt /etc
...
-rw-r--r--   1 root   root     6932 Feb 10  1997 pine.conf.old
-rw-r--r--   1 root   root     6907 Dec 29  1996 pine.conf.old2
-rw-r--r--   1 root   root    76739 Dec  7  1996 mailcap.old
-rw-r--r--   1 root   root     1225 Oct 20  1996 fstab.old
jack:~$
I know that I did my first Debian installation in late October 1996, migrating over from my existing Slackware installation with the help of my friend Jon who was already a DD. That took an entire weekend and it was painful, so much so that several times that weekend I very nearly bailed and went back. But, I stuck with it and after a few more days I decided I was happier with Debian than with the broken old Slackware system I'd been using. That last file (fstab.old) is the old fstab file from the Slackware system, backed up just before I made the switch. I was already a software developer at the time, so of course the first thing I wanted to do once I was happy with Debian was to become a DD and take over the Debian maintenance of mikmod, the module player I was working on at the time. So, I mailed Bruce to ask for an account (there was none of this NM concept back then!) and I think he replied the next day. Unfortunately, I don't have the email in my archives any more due to a disk crash back in the dim and distant past. But I can see that the first PGP key I generated for the sake of joining Debian dates from October 30th 1996 which gives me a date of 31st October 1996 for joining Debian. Twenty years, wow... Since then, I've done lots in the project. I'm lucky enough to been to 11 DebConfs, hosted all around the world. I'm massively proud to have been voted DPL for two of those twenty years. I've worked on a huge number of different things in Debian, from the audio applications I started with to the installer (yay, how things come back to bite you!), from low-level CD and DVD tools (and making our CD images!) to a wiki engine written in python. I've worked hard to help make the best Operating System on the planet, both for my own sake and the sake of our users. Debian has been both excellent fun and occasionally a huge cause of stress in my life for the last 20 years, but despite the latter I wouldn't go back and change anything. Why? Through Debian, I've made some great friends: in Cambridge, in the UK, in Europe, on every continent. Thanks to you all, and here's to (hopefully) many years to come!

Jonas Meurer: debian lts report 2016.10

Debian LTS Report for October 2016 October 2016 was my second month as a payed Debian LTS Team member. I was allocated 12 hours and spent 10,25 hours of them as follows:

Enrico Zini: Links for November 2016

So You Want To Learn Physics... [archive]
This post is a condensed version of what I've sent to people who have contacted me over the years, outlining what everyone needs to learn in order to really understand physics.
Operation Tamarisk [archive]
Operation Tamarisk was a Cold War-era operation run by the military intelligence services of the U.S., U.K., and France through their military liaison missions in East Germany, that gathered discarded paper, letters, and garbage from Soviet trash bins and military maneuvers, including used toilet paper.
Mortara case
Of how in Bologna, where I live, in the 1850s/1860s, when my grand-grand-granddad lived, the Papal State seized a child from a Jewish family on the basis of a former servant's testimony that she had administered emergency baptism to the boy when he fell sick as an infant.

Chris Lamb: Free software activities in October 2016

Here is my monthly update covering what I have been doing in the free software world (previously):

Debian & Reproducible builds

Whilst anyone can inspect the source code of free software for malicious flaws, most GNU/Linux distributions provide binary (or "compiled") packages to end users. The motivation behind the Reproducible Builds effort is to allow verification that no flaws have been introduced either maliciously and accidentally during this compilation process by promising identical binary packages are always generated from a given source.

  • Presented a talk entitled "Reproducible Builds" talk at Software Freedom Kosova, in Prishtina, Republic of Kosovo.

  • I filed my 2,500th bug in the Debian BTS: #840972: golang-google-appengine: accesses the internet during build.

  • In order to build packages reproducibly, one not only needs identical sources but also some external and sharable definition of the environment used for a particular build, stipulating such things such as the version numbers of the required build-dependencies. It is not currently clear how to handle these .buildinfo files after the archive software has processed them and how to make them available to the world so I started development on a proof-of-concept server to see what issues arise in practice. It is available at buildinfo.debian.net.

  • Chaired an IRC meeting and ran a poll to determine a regular time .

  • Submitted two design proposals to our wiki page.

  • Improvements to our tests.reproducible-builds.org testing framework:

    • Move regular "Scheduled in..." messages to the #debian-reproducible-changes IRC channel.
    • Use our log_info method instead of manual echo calls.
    • Correct an "all sources packages" "all source packages" typo.
    • Submit .buildinfo files to buildinfo.debian.net.
    • Create GPG key on nodes for buildinfo.debian.net at deploy time, not "lazily".

My work in the Reproducible Builds project was also covered in our weekly reports. (#75, #76, #77 & #78).

I also submitted 14 patches to fix specific reproducibility issues in bio-eagle, cf-python, fastx-toolkit, fpga-icestorm, http-icons, lambda-align, mypy, playitslowly, seabios, stumpwm, sympa, tj3, wims-help & xotcl.
Debian LTS

This month I have been paid to work 13 hours on Debian Long Term Support (LTS). In that time I did the following:
  • Seven days of "frontdesk" duties, triaging CVEs, etc.
  • Issued DLA 647-1 for freeimage correcting an out-of-bounds write vulnerability in the XMP image handling functionality.
  • Issued DLA 649-1 for python-django fixing a possible CSRF protection bypass on sites that use Google Analytics.
  • Issued DLA 654-1 for libxfixes preventing an integer overflow when a malicious client sent INT_MAX as a "length".
  • Issued DLA 662-1 for quagga correcting a programming error where two constants were confused that could cause stack overrun in IPv6 routing code.
  • Issued DLA 688-1 for cairo to prevent a DoS attack where a malicious SVG could generate invalid pointers.

Uploads
  • gunicorn:
    • 19.6.0-7 Set supplementary groups when changing uid, add an example systemd .service file to gunicorn-examples, and expand README.Debian to make it clearer what to do now that /etc/gunicorn.d has been removed.
    • 19.6.0-8 Correct previous supplementary groups patch to be compatible with Python 3.
  • redis:
    • 3:3.2.4-2 Ensure that sentinel's configuration actually writes to a pidfile location so that systemd can detect that the daemon has started.
    • 3:3.2.5-1 New upstream release.
  • libfiu:
    • 0.94-8 Fix FTBFS under Bash due to lack of && in debian/rules.
    • 0.94-9 Ensure the build is reproducible by sorting injected modules.
  • aptfs (2:0.8-2) Minor cosmetic changes.

NMUs
  • libxml-dumper-perl (0.81-1.2) Move away from a unsupported debhelper compat level 4.
  • netatalk (2.2.5-1.1) Drop build-dependency on hardening-includes.

QA uploads
  • anon-proxy (00.05.38+20081230-4) Move to a supported debhelper compatibility level 9.
  • ara (1.0.32) Make the build reproducible.
  • binutils-m68hc1x (1:2.18-8) Make the build reproducible & move to a supported debhelper compatibility level.
  • fracplanet (0.4.0-5) Make the build reproducible.
  • libnss-ldap (265-5) Make the build reproducible.
  • python-uniconvertor (1.1.5-3) Fix an "option release requires an argument" FTBFS. (#839375)
  • ripole (0.2.0+20081101.0215-3) Actually include the ripole binary in package. (#839919) & enable hardening flags.
  • twitter-bootstrap (2.0.2+dfsg-10) Fix incorrect copyright formatting when building under Bash. (#824592)
  • zpaq (1.10-3) Make the build reproducible.


Debian FTP Team

As a Debian FTP assistant I ACCEPTed 147 packages: ace-link, amazon-s2n, avy, basez, bootstrap-vz, bucklespring, camitk, carettah, cf-python, debian-reference, dfcgen-gtk, efivar, entropybroker, fakesleep, gall, game-data-packager, gitano, glare, gnome-panel, gnome-shell-extension-dashtodock, gnome-shell-extension-refreshwifi, gnome-shell-extension-remove-dropdown-arrows, golang-github-gogits-go-gogs-client, golang-github-gucumber-gucumber, golang-github-hlandau-buildinfo, golang-github-hlandau-dexlogconfig, golang-github-hlandau-goutils, golang-github-influxdata-toml, golang-github-jacobsa-crypto, golang-github-kjk-lzma, golang-github-miekg-dns, golang-github-minio-sha256-simd, golang-github-nfnt-resize, golang-github-nicksnyder-go-i18n, golang-github-pointlander-compress, golang-github-pointlander-jetset, golang-github-pointlander-peg, golang-github-rfjakob-eme, golang-github-thecreeper-go-notify, golang-github-twstrike-gotk3adapter, golang-github-unknwon-goconfig, golang-gopkg-dancannon-gorethink.v1, golang-petname, haskell-argon2, haskell-binary-parsers, haskell-bindings-dsl, haskell-deriving-compat, haskell-hackage-security, haskell-hcwiid, haskell-hsopenssl-x509-system, haskell-megaparsec, haskell-mono-traversable-instances, haskell-prim-uniq, haskell-raaz, haskell-readable, haskell-readline, haskell-relational-record, haskell-safe-exceptions, haskell-servant-client, haskell-token-bucket, haskell-zxcvbn-c, irclog2html, ironic-ui, lace, ledger, libdancer2-plugin-passphrase-perl, libdatetime-calendar-julian-perl, libdbix-class-optimisticlocking-perl, libdbix-class-schema-config-perl, libgeo-constants-perl, libgeo-ellipsoids-perl, libgeo-functions-perl, libgeo-inverse-perl, libio-async-loop-mojo-perl, libmojolicious-plugin-assetpack-perl, libmojolicious-plugin-renderfile-perl, libparams-validationcompiler-perl, libspecio-perl, libtest-time-perl, libtest2-plugin-nowarnings-perl, linux, lua-scrypt, mono, mutt-vc-query, neutron, node-ansi-font, node-buffer-equal, node-defaults, node-formatio, node-fs-exists-sync, node-fs.realpath, node-is-buffer, node-jison-lex, node-jju, node-jsonstream, node-kind-of, node-lex-parser, node-lolex, node-loud-rejection, node-random-bytes, node-randombytes, node-regex-not, node-repeat-string, node-samsam, node-set-value, node-source-map-support, node-spdx-correct, node-static-extend, node-test, node-to-object-path, node-type-check, node-typescript, node-unset-value, nutsqlite, opencv, openssl1.0, panoramisk, perl6, pg-rage-terminator, pg8000, plv8, puppet-module-oslo, pymoc, pyramid-jinja2, python-bitbucket-api, python-ceilometermiddleware, python-configshell-fb, python-ewmh, python-gimmik, python-jsbeautifier, python-opcua, python-pyldap, python-s3transfer, python-testing.common.database, python-testing.mysqld, python-testing.postgresql, python-wheezy.template, qspeakers, r-cran-nleqslv, recommonmark, rolo, shim, swift-im, tendermint-go-clist, tongue, uftrace & zaqar-ui.

Antoine Beaupr : My free software activities, October 2016

Debian Long Term Support (LTS) This is my 7th month working on Debian LTS, started by Raphael Hertzog at Freexian, after a long pause during the summer. I have worked on the following packages and CVEs: I have also helped review work on the following packages:
  • imagemagick: reviewed BenH's work to figure out what was done. unfortunately, I forgot to officially take on the package and Roberto started working on it in the meantime. I nevertheless took time to review Roberto's work and outline possible issues with the original patchset suggested
  • tiff: reviewed Raphael's work on the hairy TIFFTAG_* issues, all the gory details in this email
The work on ImageMagick and GraphicsMagick was particularly intriguing. Looking at the source of those programs makes me wonder why were are still using them at all: it's a tangled mess of C code that is bound to bring up more and more vulnerabilities, time after time. It seems there's always an "Magick" vulnerability waiting to be fixed out there... I somehow hoped that the fork would bring more stability and reliability, but it seems they are suffering from similar issues because, fundamentally, they haven't rewritten ImageMagick... It looks this is something that affects all image programs. The review I have done on the tiff suite give me the same shivering sensation as reviewing the "Magick" code. It feels like all image libraries are poorly implemented and then bound to be exploited somehow... Nevertheless, if I had to use a library of the sort in my software, I would stay away from the "Magick" forks and try something like imlib2 first... Finally, I also did some minor work on the user and developer LTS documentation and some triage work on samba, xen and libass. I also looked at the dreaded CVE-2016-7117 vulnerability in the Linux kernel to verify its impact on wheezy users. I also looked at implementing a --lts flag for dch (see bug #762715). It was difficult to get back to work after such a long pause, but I am happy I was able to contribute a significant number of hours. It's a bit difficult to find work sometimes in LTS-land, even if there's actually always a lot of work to be done. For example, I used to be one of the people doing frontdesk work, but those duties are now assigned until the end of the year, so it's unlikely I will be doing any of that for the forseable future. Similarly, a lot of packages were assigned when I started looking at the available packages. There was an interesting discussion on the internal mailing list regarding unlocking package ownership, because some people had packages locked for weeks, sometimes months, without significant activity. Hopefully that situation will improve after that discussion. Another interesting discussion I participated in is the question of whether the LTS team should be waiting for unstable to be fixed before publishing fixes in oldstable. It seems the consensus right now is that it shouldn't be mandatory to fix issues in unstable before we fix security isssues in oldstable and stable. After all, security support for testing and unstable is limited. But I was happy to learn that working on brand new patches is part of our mandate as part of the LTS work. I did work on such a patch for tar which ended up being adopted by the original reporter, although upstream ended up implementing our recommendation in a better way. It's coincidentally the first time since I start working on LTS that I didn't get the number of requested hours, which means that there are more people working on LTS. That is a good thing, but I am worried it may also mean people are more spread out and less capable of focusing for longer periods of time on more difficult problems. It also means that the team is growing faster than the funding, which is unfortunate: now is a good time as any to remind you to see if you can make your company fund the LTS project if you are still running Debian wheezy.

Other free software work It seems like forever that I did such a report, and while I was on vacation, a lot has happened since the last report.

Monkeysign I have done extensive work on Monkeysign, trying to bring it kicking and screaming in the new world of GnuPG 2.1. This was the objective of the 2.1 release, which collected about two years of work and patches, including arbitrary MUA support (e.g. Thunderbird), config files support, and a release on PyPI. I have had to release about 4 more releases to try and fix the build chain, ship the test suite with the program and have a primitive preferences panel. The 2.2 release also finally features Tor suport! I am also happy to have moved more documentation to Read the docs, part of which I mentionned in in a previous article. The git repositories and issues were also moved to a Gitlab instance which will hopefully improve the collaboration workflow, although we still have issues in streamlining the merge request workflow. All in all, I am happy to be working on Monkeysign, but it has been a frustrating experience. In the last years, I have been maintaining the project largely on my own: although there are about 20 contributors in Monkeysign, I have committed over 90% of the commits in the code. New contributors recently showed up, and I hope this will release some pressure on me being the sole maintainer, but I am not sure how viable the project is.

Funding free software work More and more, I wonder how to sustain my contributions to free software. As a previous article has shown, I work a lot on the computer, even when I am not on a full-time job. Monkeysign has been a significant time drain in the last months, and I have done this work on a completely volunteer basis. I wouldn't mind so much except that there is a lot of work I do on a volunteer basis. This means that I sometimes must prioritize paid consulting work, at the expense of those volunteer projects. While most of my paid work usually revolves around free sofware, the benefits of paid work are not always immediately obvious, as the primary objective is to deliver to the customer, and the community as a whole is somewhat of a side-effect. I have watched with interest joeyh's adventures into crowdfunding which seems to be working pretty well for him. Unfortunately, I cannot claim the incredible (and well-deserved) reputation Joey has, and even if I could, I can't live with 500$ a month. I would love to hear if people would be interested in funding my work in such a way. I am hesitant in launching a crowdfunding campaign because it is difficult to identify what exactly I am working on from one month to the next. Looking back at earlier reports shows that I am all over the place: one month I'll work on a Perl Wiki (Ikiwiki), the next one I'll be hacking at a multimedia home cinema (Kodi). I can hardly think of how to fund those things short of "just give me money to work on anything I feel like", which I can hardly ask for of anyone. Even worse, it feels like the audience here is either friends or colleagues. It would make little sense for me to seek funding from those people: colleagues have the same funding problems I do, and I don't want to empoverish my friends... So far I have taken the approach of trying to get funding for work I am doing, bit by bit. For example, I have recently been told that LWN actually pays for contributed articles and have started running articles by them before publishing them here. This is looking good: they will publish an article I wrote about the Omnia router I have recently received. I give them exclusive rights on the article for two weeks, but I otherwise retain full ownership over the article and will publish them after the exclusive period here. Hopefully, I will be able to find more such projects that pays for the work I do on a day to day basis.

Open Street Map editing I have ramped up my OpenStreetMap contributions, having (temporarily) moved to a different location. There are lots of things to map here: trails, gaz stations and lots of other things are missing from the map. Sometimes the effort looks a bit ridiculous, reminding me of my early days of editing OSM. I have registered to OSM Live, a project to fund OSM editors that, I must admit, doesn't help much with funding my work: with the hundreds of edits I did in October, I received the equivalent of 1.80$CAD in Bitcoins. This may be the lowest hourly salary I have ever received, probably going at a rate of 10 per hour! Still, it's interesting to be able to point people to the project if someone wants to contribute to OSM mappers. But mappers should have no illusions about getting a decent salary from this effort, I am sorry to say.

Bounties I feel this is similar to the "bounty" model used by the Borg project: I claimed around $80USD in that project for what probably amounts to tens of hours of work, yet another salary that would qualify as "poor". Another example is a feature I would like to implement in Borg: support for protocols other than SSH. There is currently no bounty on this, but a similar feature, S3 support has one of the largest bounties Borg has ever seen: $225USD. And the claimant for the bounty hasn't actually implemented the feature, instead backing up to S3, the patch (to a third-party tool) actually enables support for Amazon Cloud Drive, a completely different API. Even at $225, I wouldn't be able to complete any of those features and get a decent salary. As well explained by the Snowdrift reviews, bounties just don't work at all... The ludicrous 10% fee charged by Bountysource made sure I would never do business with them ever again anyways.

Other work There are probably more things I did recently, but I am having difficulty keeping track of the last 5 months of on and off work, so you will forgive that I am not as exhaustive as I usually am.

James Bromberger: The Debian Cloud Sprint 2016

I m at an airport, about to board the first of three flights across the world, from timezone +8 to timezone -8. I ll be in transit 27 hours to get to Seattle, Washington state. I m leaving my wife and two young children behind. My work has given me a days worth of leave under the Corporate Social Responsibility program, and I m taking three days annual leave, to do this. 27 hours each way in transit, for 3 days on the ground. Why? Backstory I started playing in technology as a kid in the 1980s; my first PC was a clone (as they were called) 286 running MS-DOS. It was clunky, and the most I could do to extend it was to write batch scripts. As a child I had no funds for commercial compilers, no network connections (this was pre Internet in Australia), no access to documentation, and no idea where to start programming properly. It was a closed world. I hit university in the summer of 1994 to study Computer Science and French. I d heard of Linux, and soon found myself installing the Linux distributions of the day. The Freedom of the licensing, the encouragement to use, modify, share, was in stark contrast to the world of consumer PCs of the late 1980 s. It was there at the UCC at UWA I discovered Debian. Some of the kind network/system admins at the University maintained a Debian mirror on the campus LAN, updated regularly and always online. It was fast, and more importantly, free for me to access. Back in the 1990s, bandwidth in Australia was incredibly expensive. The vast distances of the country mean that bandwidth was scarce. Telcos were in races to put fiber between Perth and the Eastern States, and without that in place, IP connectivity was constrained, and thus costly. Over many long days and nights I huddled down, learning window managers, protocols, programming and scripting languages. I became a system/network administrator, web developer, dev ops engineer, etc. My official degree workload, algorithmic complexity, protocol stacks, were interesting, but fiddling with Linux based implementations was practical. Volunteer After years of consuming the output of Debian and running many services with it I decided to put my hand up and volunteer as a Debian Developer: it was time to give back. I had benefited from Debian, and I saw others benefit from it as well. As the 2000 s started, I had my PGP key in the Debian key ring. I had adopted a package and was maintaining it load balancing Apache web servers. The web was yet to expand to the traffic levels you see today; most web sites were served from one physical web server. Site Reliability Engineering was a term not yet dreamed of. What became more apparent was the applicability of Linux, Open Source, and in my line-of-sight Debian to a wider community beyond myself and my university peers. Debain was being used to revive recycled computers that were being donated to charities; in some cases, unable to transfer commercial software licenses with the hardware that was no longer required by organisations that had upgraded. It appeared that Debian was being used as a baseline above which society in general had access to fundamental capability of computing and network services. The removal of subscriptions, registrations, and the encouragement of distribution meant this occurred at rates that could never be tracked, and more importantly, the consensus was that it should not be automatically tracked. The privacy of the user is paramount more important than some statistics for the Developer to ponder. When the Bosnia-Herzegovina war ended in 1995, I recall an email from academics there, having found some connectivity, writing to ask if they would be able to use Debian as part of their re-deployment of services for the Tertiary institutions in the region. This was an unnecessary request as Debian GNU/Linux is freely available, but it was a reminder that, for the country to have tried to procure commercial solutions at that time would have been difficult. Instead, those that could do the task just got on with it. There s been many similar project where the grass-roots organisations non profits, NGOs, and even just loose collectives of individuals have turned to Linux, Open Source, and sometimes Debian to solve their problems. Many fine projects have been established to make technology accessible to all, regardless of race, gender, nationality, class, or any other label society has used to divide humans. Big hat tip to Humanitarian Open Street Map, Serval Project. I ve always loved Debian s position on being the Universal operating system. Its vast range of packages and wide range of computing architectures supported means that quite often a litmus test of is project X a good project? was met with is it packaged for Debian? . That wide range of architectures has meant that administrators of systems had fewer surprises and a faster adoption cycle when changing platforms, such as the switch from x86 32 bit to x86 64 bit. Enter the Cloud I first laid eyes on the AWS Cloud in 2008. It was nothing like the rich environment you see today. The first thing I looked for was my favourite operating system, so that what I already knew and was familiar with was available in this environment to minimise the learning curve. However there were no official images, which was disconcerting. In 2012 I joined AWS as an employee. Living in Australia they hired me into the field sales team as a Solution Architect a sort of pre-sales tech with a customer focused depth in security. It was a wonderful opportunity, and I learnt a great deal. It also made sense (to me, at least) to do something about getting Debian s images blessed. It turned out, that I had to almost define what that was: images endorsed by a Debian Developer, handed to the AWS Marketplace team. And so since 2013 I have done so, keeping track of Debian s releases across the AWS regions, collaborating with other Debian folk on other cloud platforms to attempt a unified approach to generating and maintaining these images. This included (for a stint) generating them into the AWS GovCloud Region, and still into the AWS China (Beijing) Region the other side of the so-called Great Firewall of China. So why the trip? We ve had focus groups at the Debconf (Debian conference) around the world, but its often difficult to get the right group of people in the same rooms at the same time. So the proposal was to hold a focused Debian Cloud Sprint. Google was good enough to host this, for all the volunteers across all the cloud providers. Furthermore, donated funds were found to secure the travel for a set of people to attend who otherwise could not. I was lucky enough to be given a flight. So here I am, in the terminal in Australia: my kids are tucked up in bed, dreaming of the candy they just collected for Halloween. It will be a draining week I am sure, but if it helps set and improve the state of Debian then its worth it.

30 October 2016

Iain R. Learmonth: Powers to Investigate

The Communication Data Bill was draft legislation introduced first in May 2012. It sought to compel ISPs to store details of communications usage so that it can later be used for law enforcement purposes. In 2013 the passage of this bill into law had been blocked and the bill was dead. In 2014 we saw the Data Retention and Investigatory Powers Act 2014 appear. This seemed to be in response to the Data Retention Directive being successfully challenged at the European Court of Justice by Digital Rights Ireland on human rights grounds, with a judgment given in 2014. It essentially reimplemented the Data Retention Directive along with a whole load of other nasty things. The Data Retention and Investigatory Powers Act contained a sunset clause with a date set for 2016. This brings us to the Investigatory Powers Bill which it looks will be passing into law shortly. Among a range of nasty powers, this legislation will be able to force ISPs to record metadata about every website you visit, every connection you make to a server on the Internet. This is sub-optimal for the privacy minded, with my primary concern being that this is a treasure trove of data and it s going to be abused by someone. It s going to be too much for someone to resist. The existence of this power in the bill seemed to confuse the House of Lords:
It is not for me to explain why the Government want in the Bill a power that currently does not exist, because internet connection records do not exist, and which the security services say they do not want but which the noble and learned Lord says might be needed in the future. It is not for me to justify this power; I am saying to the House why I do not believe it is justified. The noble and learned Lord and the noble Lord, Lord Rosser, made the point that this is an existing power, but how can you have an existing power to acquire something that will not exist until the Bill is enacted? Lord Paddick (link)
Of course, the internet connection records are meaningless when your traffic is routed via a proxy or VPN, and there is a Kickstarter in progress that I would love to succeed: OnionDSL. The premise of OnionDSL is that instead of having an IPv4/IPv6 connection to the Internet, you join a private network that does not provide any routing to the global Internet and instead provides only a Tor bridge. I cannot think of anything that I do from home that I cannot do via Tor and have been considering switching to Qubes OS as the operating system on my day-to-day laptop to allow me to direct basically everything through Tor. The idea of provisioning a non-IP service via DSL is not new to me, I ve come across it before with cjdns which provides an encrypted IPv6 network using public key cryptography for network address allocation and a distributed hash table for routing. Peering between cjdns nodes can be performed over Ethernet and cjdns over Ethernet could be provisioned in place of the traditional PPP over Ethernet (PPPoE) to provide access directly to cjdns without providing any routing to the global Internet. If OnionDSL is funded, I think it s very likely I would be considering becoming a customer. (Assuming the government doesn t attempt to also outlaw Tor).

29 October 2016

Lars Wirzenius: Obnam 1.20 released

I have just released version 1.20 of Obnam, my backup program. It's been nine months since the previous release, and that's a long time: I've had an exciting year, and not entirely in a good way. Unfortuntely that's eaten up a lot of my free time and enthusiasm for my hobby projects. See below for a snippet of NEWS, with a summary of the user-visible changes. A lot of the effort has gone into improving FORMAT GREEN ALBATROSS, but that isn't documented in the NEWS file. I've received patches and actionable bug reports from a number of people, and I'm grateful for those. I try to credit them by name in the NEWS file. Obnam NEWS This file summarizes changes between releases of Obnam. NOTE: Obnam has an EXPERIMENTAL repository format under development, called green-albatross-20160813. It is NOT meant for real use. It is likely to change in incompatible ways without warning. DO NOT USE it unless you're willing to lose your backup. Version 1.20, released 2016-10-29 Minor changes: Bug fixes:

Jaldhar Vyas: Dawkins Weasel

Happy Dhanteras from Bappy Lahiri
It's already Dhan Terash so I better pick up the pace if I want to beat my blogging challenge before Diwali so in this post I'll discuss a program I wrote earlier this year.
I dread to look up anything on Wikipedia because I always end up going down a rabbit hole and surfacing hours later on a totally unrelated topic. Case in point, some months ago, I ended up on the page of the title. This is an interesting little experiment illustrating how random selection can result in the evolution of a specific form. The algorithm is:

  1. Start with a random string of 28 characters.
  2. Make 100 copies of this string, with a 5% chance per character of that character being replaced with a random character.
  3. Compare each new string with "METHINKS IT IS LIKE A WEASEL", and give each a score (the number of letters in the string that are correct and in the correct position).
  4. If any of the new strings has a perfect score (== 28), halt.
  5. Otherwise, take the highest scoring string, and go to step 2.
I had to try this myself so I wrote a little implementation in C++. A sample run looks like this:
  
$ ./weasel
0000 DNCFICBLUZVC JF KKNVJJASCJRW (0)
0001 DNIFICOLUZVC JFLIKNVAJASCJEW (6)
0002 DNNWICKSUZVCRSFLIKNVA ASCJEL (11)
0003 DNNWICKSUZVCRSFLIKNVA ASCJEL (11)
0004 MNNVICKSQZVCRSFLIKNVA WSCJEL (13)
0005 MENVICKSQZVCRSFLIKNVA WSCJEL (14)
0006 MENVISKS ZTCRSFLIKNVA WLCJEL (16)
0007 MENVISKS ZTCRSFLIKNVA WLCJEL (16)
0008 MEDHISKS ZTCISFLIKNVA WLCJEL (18)
0009 MEDHISKS ZTCISFLIKNVA WLCJEL (18)
0010 MEDHISKS ZTCISFLIKNVA WLCJEL (18)
0011 MEDHISKS ZTCIS LIKTKA WLCZEL (19)
0012 MEDHISKS ZTCIS LIKTKA WLCZEL (19)
0013 MEDHISKS ZTCIS LIKT A WLCZEL (20)
0014 MEDHISKS ZTCIS LIKT A WLCZEL (20)
0015 MEDHISKS ZTCIS LIKE A WLAZEL (22)
0016 MEDHIGKS ITCIS LIKE A WLAZEL (23)
0017 MEDHIGKS ITCIS LIKE A WLAZEL (23)
0018 MEDHIGKS ITCIS LIKE A WLAZEL (23)
0019 MEDHIGKS ITCIS LIKE A WLAZEL (23)
0020 MEDHIGKS ITCIS LIKE A WLAZEL (23)
0021 MEDHIGKS ITCIS LIKE A WLAZEL (23)
0022 METHINKS ITCIS LIKE A WLASEL (26)
0023 METHINKS ITCIS LIKE A WLASEL (26)
0024 METHINKS ITCIS LIKE A WLASEL (26)
0025 METHINKS ITCIS LIKE A WEASEL (27)
0026 METHINKS ITCIS LIKE A WEASEL (27)
0027 METHINKS ITCIS LIKE A WEASEL (27)
0028 METHINKS ITCIS LIKE A WEASEL (27)
0029 METHINKS ITCIS LIKE A WEASEL (27)
0030 METHINKS ITCIS LIKE A WEASEL (27)
0031 METHINKS ITCIS LIKE A WEASEL (27)
0032 METHINKS ITCIS LIKE A WEASEL (27)
0033 METHINKS ITCIS LIKE A WEASEL (27)
0034 METHINKS ITCIS LIKE A WEASEL (27)
0035 METHINKS ITCIS LIKE A WEASEL (27)
0036 METHINKS ITCIS LIKE A WEASEL (27)
0037 METHINKS ITCIS LIKE A WEASEL (27)
0038 METHINKS ITCIS LIKE A WEASEL (27)
0039 METHINKS ITCIS LIKE A WEASEL (27)
0040 METHINKS ITCIS LIKE A WEASEL (27)
0041 METHINKS ITCIS LIKE A WEASEL (27)
0042 METHINKS ITCIS LIKE A WEASEL (27)
0043 METHINKS ITCIS LIKE A WEASEL (27)
0044 METHINKS ITCIS LIKE A WEASEL (27)
0045 METHINKS ITCIS LIKE A WEASEL (27)
0046 METHINKS ITCIS LIKE A WEASEL (27)
0047 METHINKS ITCIS LIKE A WEASEL (27)
0048 METHINKS ITCIS LIKE A WEASEL (27)
0049 METHINKS ITCIS LIKE A WEASEL (27)
0050 METHINKS ITCIS LIKE A WEASEL (27)
0051 METHINKS ITCIS LIKE A WEASEL (27)
0052 METHINKS ITCIS LIKE A WEASEL (27)
0053 METHINKS ITCIS LIKE A WEASEL (27)
0054 METHINKS IT IS LIKE A WEASEL (28)

My program lets you adjust the input string, the number of copies, and the mutation threshold. I also thought it might be interesting to implement the Generator design pattern. In C++ this is done by making a class which implements begin() and end() methods and atleast a forward iterator. You can find the source code on Github.

28 October 2016

Matthew Garrett: Of course smart homes are targets for hackers

The Wirecutter, an in-depth comparative review site for various electrical and electronic devices, just published an opinion piece on whether users should be worried about security issues in IoT devices. The summary: avoid devices that don't require passwords (or don't force you to change a default and devices that want you to disable security, follow general network security best practices but otherwise don't worry - criminals aren't likely to target you.

This is terrible, irresponsible advice. It's true that most users aren't likely to be individually targeted by random criminals, but that's a poor threat model. As I've mentioned before, you need to worry about people with an interest in you. Making purchasing decisions based on the assumption that you'll never end up dating someone with enough knowledge to compromise a cheap IoT device (or even meeting an especially creepy one in a bar) is not safe, and giving advice that doesn't take that into account is a huge disservice to many potentially vulnerable users.

Of course, there's also the larger question raised by the last week's problems. Insecure IoT devices still pose a threat to the wider internet, even if the owner's data isn't at risk. I may not be optimistic about the ease of fixing this problem, but that doesn't mean we should just give up. It is important that we improve the security of devices, and many vendors are just bad at that.

So, here's a few things that should be a minimum when considering an IoT device:
  • Does the vendor publish a security contact? (If not, they don't care about security)
  • Does the vendor provide frequent software updates, even for devices that are several years old? (If not, they don't care about security)
  • Has the vendor ever denied a security issue that turned out to be real? (If so, they care more about PR than security)
  • Is the vendor able to provide the source code to any open source components they use? (If not, they don't know which software is in their own product and so don't care about security, and also they're probably infringing my copyright)
  • Do they mark updates as fixing security bugs? (If not, they care more about hiding security issues than fixing them)
  • Has the vendor ever threatened to prosecute a security researcher? (If so, again, they care more about PR than security)
  • Does the vendor provide a public minimum support period for the device? (If not, they don't care about security or their users)

    I've worked with big name vendors who did a brilliant job here. I've also worked with big name vendors who responded with hostility when I pointed out that they were selling a device with arbitrary remote code execution. Going with brand names is probably a good proxy for many of these requirements, but it's insufficient.

    So here's my recommendations to The Wirecutter - talk to a wide range of security experts about the issues that users should be concerned about, and figure out how to test these things yourself. Don't just ask vendors whether they care about security, ask them what their processes and procedures look like. Look at their history. And don't assume that just because nobody's interested in you, everybody else's level of risk is equal.


  • comment count unavailable comments

    Next.

    Previous.