Search Results: "cas"

12 March 2014

Matthew Garrett: Dealing with Apple ACPI issues

I wrote about Thunderbolt on Apple hardware a while ago. Since then Andreas Noever has somehow managed to write a working Thunderbolt stack, which awesome! But there was still the problem I mentioned of the device not appearing unless you passed acpi_osi="Darwin" on the kernel command line, and a further problem that if you suspended and then resumed it vanished again.

The ACPI _OSI interface is a mechanism for the firmware to determine the OS that the system is running. It turns out that this works fine for operating systems that export fairly static interfaces (Windows, which adds a new _OSI per release) and poorly for operating systems that don't even guarantee any kind of interface stability in security releases (Linux, which claimed to be "Linux" regardless of version until we turned that off). OS X claims to be Darwin and nothing else. As I mentioned before, claiming to be Darwin in addition to Windows was enough to get the Thunderbolt hardware to stay alive after boot, but it wasn't enough to get it powered up again after suspend.

It turns out that there's two sections of ACPI code where this Mac checks _OSI. The first is something like:

if (_OSI("Darwin")) Store 0x2710 OSYS; else if(_OSI("Windows 2009") Store 0x7D9 OSYS; else

ie, if the OS claims to be Darwin, all other strings are ignored. This is called from \_SB._INI(), which is the first ACPI method the kernel executes. The check for whether to power down the Thunderbolt controller occurs after this and then works correctly.

The second version is less helpful. It's more like:

if (_OSI("Darwin")) Store 0x2710 OSYS; if (_OSI("Windows 2009")) Store 0x7D9 OSYS; if

ie, if the OS claims to be both Darwin and Windows 2009 (which Linux will if you pass acpi_osi="Darwin"), the OSYS variable gets set to the Windows 2009 value. This version gets called during PCI initialisation, and once it's run all the other Thunderbolt ACPI calls stop doing anything and the controller gets powered down after suspend/resume. That can be fixed easily enough by special casing Darwin. If the platform requests Darwin before anything else, we'll just stop claiming to be Windows.

Phew. Working Thunderbolt! (Well, almost - _OSC fails and so we disable PCIe hotplug, but that's easy to work around). But boo, no working battery. Apple do something very strange with their ACPI battery interface. If you're running anything that doesn't claim to be Darwin, Apple expose an ACPI Control Method battery. Control Method interfaces abstract the complexity away into either ACPI bytecode or system management traps - the OS simply calls an ACPI method, magic happens and it gets an answer back. If you claim to be Darwin, Apple remove that interface and instead expose the raw ACPI Smart Battery System interface. This provides an i2c bus over which the OS must then speak the Smart Battery System protocol, allowing it to directly communicate with the battery.

Linux has support for this, but it seems that this wasn't working so well and hadn't been for years. Loading the driver resulted in modprobe hanging until a timeout occurred, and most accesses to the battery would (a) take forever and (b) probably fail. It also had the nasty habit of breaking suspend and resume, which was unfortunate since getting Thunderbolt working over suspend and resume was the whole point of this exercise.

So. I modified the sbs driver to dump every command it sent over the i2c bus and every response it got. Pretty quickly I found that the failing operation was a write - specifically, a write used to select which battery should be connected to the bus. Interestingly, Apple implemented their Control Method interface by just using ACPI bytecode to speak the SBS protocol. Looking at the code in question showed that they never issued any writes, and the battery worked fine anyway. So why were we writing? SBS provides a command to tell you the current state of the battery subsystem, including which battery (out of a maximum of 4) is currently selected. Unsurprisingly, calling this showed that the battery we wanted to talk to was already selected. We then asked the SBS manager to select it anyway, and the manager promptly fell off the bus and stopped talking to us. In keeping with the maxim of "If hardware complains when we do something, and if we don't really need to do that, don't do that", this makes it work.

Working Thunderbolt and working battery. We're even getting close to getting switchable GPU support working reasonably, which is probably just going to involve rewriting the entirety of fbcon or something similarly amusing.

comment count unavailable comments

Vasudev Kamath: Working around type system of Go with unsafe

Go language has a strong type system unlike C, and some times this will be head ache when we want to interact with C data types with Cgo or just to convert a Go type to lets say byte slice. I recently faced the same problem and after poking around things, I learned the Go provides unsafe package which can be used to work around the Go's type system.
Problem Recently I started using Cgo to use some C library I had to write some tools for development and testing. The reason I chose Go for this was prototyping and writing some quick tools is much easier in Go than done in C. The C library had some function which takes pointer to array types and fills it with some values. The problem I was facing here was how to create a C array in Go. Go does have array but its largely used as internal representation for much efficient type called slice and I can't directly cast a byte slice into an C array. Second problem I had was I had to store arbitrary Go types like float (float32,float64) and int (int32, int64) etc. into C array. So in brief, the problems that needed to solve are
  1. Find a way to convert byte slice from Go into C array and vice versa.
  2. Find a way to convert and store Go types into a C array.
Solution Basically C array are sequence of memory location which can be statically or dynamically allocated. In Cgo its possible to access C standard library functions for memory allocation, so why not use it. The memory allocation function then returns the pointer to starting of allocated memory, we can use this pointer to write Go's bytes into the memory location and bytes from memory location into Go's slice. The pointer returned by C allocation functions are not directly usable for memory dereferencing in Go, here is where unsafe package kicks in. We will cast the return of C allocation function as unsafe.Pointer type and from the documentation of unsafe package,
  1. A pointer value of any type can be converted to a Pointer.
  2. A Pointer can be converted to a pointer value of any type.
  3. A uintptr can be converted to a Pointer.
  4. A Pointer can be converted to a uintptr.
So we can then cast unsafe.Pointer to uintptr which is the Go type which is large enough to hold any memory address in Go and can be used for pointer arithmetic just like we do in C (of course with some more castings). Below I'm pasting a simplified code in C which I wrote for this post.
#ifndef __BYTETEST_H__
#define __BYTETEST_H__
typedef unsigned char UBYTE;
extern void ArrayReadFunc(UBYTE *arrayout);
extern void ArrayWriteFunc(UBYTE *arrayin);
#endif
#include "bytetest.h"
#include <stdio.h>
#include <string.h>
void ArrayReadFunc(UBYTE *arrayout)
 
     UBYTE array[20] =  1, 2, 3, 4,5, 6, 7, 8, 9, 10,
                        11, 12, 13, 14, 15, 16, 17,
                        18, 19, 20 ;
     memcpy(arrayout, array, 20);
 
void ArrayWriteFunc(UBYTE *arrayin)
 
     UBYTE array[20];
     memcpy(array, arrayin, 20);
     printf("Byte slice array received from Go:\n");
     for(int i = 0; i < 20; i ++) 
             printf("%d ", array[i]);
      
     printf("\n");
 
Functions are written just for this post and they don't really do anything. As you can see ArrayReadFunc takes a pointer to array and fills it with content of another array using memcpy. Function ArrayWriteFunc on other hand takes pointer to array and copies its content to internal array. I've added print logic to ArrayWriteFunc just to show that values passed from Go are making it here. Below is the Go code which uses the above C files passes byte slice to get value out of C code and array made of byte slice to C function to send values in.
package main
/*
#cgo CFLAGS: -std=c99
#include "bytetest.h"
#include <stdlib.h>
*/
import "C"
import (
     "fmt"
     "unsafe"
)
func ReadArray() unsafe.Pointer  
       var outArray = unsafe.Pointer (C.calloc(20,1))
       C.ArrayReadFunc((*C.UBYTE)(outArray))
       return outArray
 
func WriteArray(inArray unsafe.Pointer)  
       C.ArrayWriteFunc((*C.UBYTE)(inArray))
 
func CArrayToByteSlice(array unsafe.Pointer, size int) []byte  
       var arrayptr = uintptr(array)
       var byteSlice = make([]byte, size)
       for i := 0; i < len(byteSlice); i ++  
               byteSlice[i] = byte(*(*C.UBYTE)(unsafe.Pointer(arrayptr)))
               arrayptr ++
        
       return byteSlice
 
func ByteSliceToCArray (byteSlice []byte) unsafe.Pointer  
       var array = unsafe.Pointer(C.calloc(C.size_t(len(byteSlice)), 1))
       var arrayptr = uintptr(array)
       for i := 0; i < len(byteSlice); i ++  
              *(*C.UBYTE)(unsafe.Pointer(arrayptr)) = C.UBYTE(byteSlice[i])
              arrayptr ++
        
       return array
 
func main() 
        carray := ReadArray()
        defer C.free(carray)
        carraybytes := CArrayToByteSlice(carray, 20)
        fmt.Println("C array converted to byte slice:")
        for i := 0; i < len(carraybytes); i ++  
                fmt.Printf("%d ", carraybytes[i])
         
        fmt.Println()
        gobytes := []byte 21, 22, 23, 24, 25, 26, 27, 28, 29, 30,
                31, 32, 33, 34, 35, 36, 37, 38, 39, 40 
        gobytesarray := ByteSliceToCArray(gobytes)
        defer C.free(gobytesarray)
        WriteArray(gobytesarray)
 
Functions ReadArray and WriteArray are just wrapper to the calls to C counter parts ArrayReadFunc and ArrayWriteFunc. ReadArray returns unsafe.Pointer which is allocated C array and should be freed by caller. WriteArray takes unsafe.Pointer which is pointing to memory location containing C array. Now the functions of interest are CArrayToByteSlice and ByteSliceToCArray. It should be pretty clear from the above code to understand what is happening in these functions. Still I will just put explain them briefly. ByteSliceToCArray allocates a C array using calloc from C standard library. It then creates a uintptr, a pointer type in Go which is used to dereference the each memory location and store bytes from the input byte slice in them. CArrayToByteSlice on other hands creates a uintptr type by casting input unsafe.Pointer type and then uses this pointer type to dereference values from memoy and store it in byte slice with suitable casting. So lets build the code and run it and see the output:
C array converted to byte slice:
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18 19 20
Byte slice array received from Go:
21 22 23 24 25 26 27 28 29 30 31 32 33 34 35 36 37 38 39 40
So yes it actually works and values are moving across C and Go. This solves first problem in hand next is converting arbitrary Go types into byte slices. There are many cases where we would like to convert an arbitrary Go types like (int, float) into bytes. One such use case I found was when writing a TCP client for communicating with a Server written using C speaking custom protocol. Here I'm just going to show how to convert types like float, int to byte slice, I've not tried converting structures but it is certainly possible. Below is the function which can convert int32,float32 into byte slice it can also be extended for other types.
func CopyValueToByte(value interface ) []byte  
     var valptr uintptr
     var slice []byte
     switch t := value.(type)  
     case int32:
             i := value.(int32)
             valptr = uintptr(unsafe.Pointer(&i))
             slice = make([]byte, unsafe.Sizeof(i))
     case float32:
             f := value.(float32)
             valptr = uintptr(unsafe.Pointer(&f))
             slice = make([]byte, unsafe.Sizeof(f))
     default:
             fmt.Fprintf(os.Stderr,"Unsupported type: %T\n", t)
             os.Exit(1)
      
     for i := 0; i < len(slice); i++  
             slice[i] = byte(*(*byte)(unsafe.Pointer(valptr)))
             valptr++
      
     return slice
 
This function is generic which can take various types of value. First we will use Go's type assertion to determine the type and creates a uintptr pointer for the value and allocates byte slice depending on the size of the value as calculated using unsafe.Sizeof. Later it uses the pointer to dereference value from memory location and copies each byte into byte slice. The idea used here is every type is represented as certain number of bytes in the memory. Below is the entire program.
package main
import (
     "fmt"
     "unsafe"
     "os"
)
func CopyValueToByte(value interface ) []byte  
     var valptr uintptr
     var slice []byte
     switch t := value.(type)  
     case int32:
             i := value.(int32)
             valptr = uintptr(unsafe.Pointer(&i))
             slice = make([]byte, unsafe.Sizeof(i))
     case float32:
             f := value.(float32)
             valptr = uintptr(unsafe.Pointer(&f))
             slice = make([]byte, unsafe.Sizeof(f))
     default:
             fmt.Fprintf(os.Stderr,"Unsupported type: %T\n", t)
             os.Exit(1)
      
     for i := 0; i < len(slice); i++  
             slice[i] = byte(*(*byte)(unsafe.Pointer(valptr)))
             valptr++
      
     return slice
 
func main()  
     a := float32(-10.3)
     floatbytes := CopyValueToByte(a)
     fmt.Println("Float value as byte slice:")
     for i := 0; i < len(floatbytes); i++  
             fmt.Printf("%x ", floatbytes[i])
      
     fmt.Println()
     b := new(float32)
     bptr := uintptr(unsafe.Pointer(b))
     for i := 0; i < len(floatbytes); i++  
             *(*byte)(unsafe.Pointer(bptr)) = floatbytes[i]
             bptr++
      
     fmt.Printf("Byte value copied to float var: %f\n", *b)
 
The above conversion can also be achieved using encoding/binary package provided by Go. But its been told to me that it makes things pretty slow.
Conclusion So goes unsafe.Pointer is really powerful thing which allows us to work around the Go's type system but as package documentation says it should be used with care
PS: I'm not really sure if its recommended to use allocation functions from C standard library, I will wait for expert gophers to comment on that.

Andrew Pollock: [life] Day 43, a lovely lazy day, until we got on the bike

Zoe slept through the night again last night. Two nights of uninterrupted sleep has been totally amazing! We had a slower start to the day because we didn't have to be anywhere. I've been meaning to do a massive cull of Zoe's wardrobe for a while, and this morning seemed like as good an opportunity as any, so after TV, I managed to get Zoe to cooperate with trying on clothes for about an hour. She really enjoyed pulling everything out of her wardrobe and putting it all back again neatly. After that, she asked me if I could make her a bus out of the last remaining moving box, so I managed to make something approximating a bus. The port-a-robe boxes are really rather handy for this sort of thing. The balcony is starting to look like a cardboard box shanty town, with a cubby house, a rocket and now a bus. I think we need to host a few more play dates so they all get a good work out. It was time for lunch after that. I'd had a bucket of caramel popcorn, which I used for the journey to Coochiemudlo the other week. Zoe had asked me how popcorn was made, so I had resolved to make popcorn with her sometime soon. Yesterday at the health food shop, I opportunistically noticed some popping corn, so I grabbed a small bag of it. It turned out that buying peanut oil was good for more than just making peanut butter, as it came in handy today for popping corn. I've never popped corn before, aside from occasionally getting a bag of the microwave stuff, so it was a fun experience to do it "from scratch". It turned out pretty well, with only a few burned ones and a few unpopped ones. It'd be fun to try and dry out a corn cob and totally do it from scratch. After that I tried to get Zoe to take a nap, but it didn't work out so well, so after her quiet time we cleaned up her bedroom and generally fooled around for a bit. Throughout the day, Zoe did lots of little bouts of self-directed play. She dredged up this little wooden xylophone that we'd made in the US from a Kiwi Crate and had a great time banging away on it until she stood on it and broke it. The doctor's kit got a good workout. It was just a really nice, relaxing day at home. Zoe's Kindergarten was having a play date meet-and-greet in the park, for all the parents to meet each other. It was a fair way from home, but there was a nice, albeit circuitous, bike path to get there, and I decided to try and bike there, without really properly estimating the distance or length of time it would take. The play date was due to start at 3:30pm, and I was planning on leaving at 3pm. We were about 5 minutes late getting out of the door. I think it ended up taking us about 50 minutes to get there. It was a beautiful ride though, once we got onto the Bulimba Creek bikeway, through the Minippi Parklands. It would have been the longest ride Zoe's had on the bike, and she wasn't fazed at all. The play date itself was nice. For some reason, I'm a bit shy about going and introducing myself to the mothers (I kept wanting to write "other mothers"), but I sucked it up and made a few introductions. I'm terrible about remembering names though. At least I've got a few faces I can say hi to at drop off and pick up now. Sarah met us at the park and hung out for a bit as well, and then Zoe and her left together and I biked back home. I was feeling pretty good, and thought I'd try and bang out a run when I got home, but I didn't end up having the fuel in the tank, and blew up after about 1.5km.

11 March 2014

Steve Kemp: Discovering back-end servers automatically?

Recently I've been pondering how to do service discovery. Pretend you have a load balancer which accepts traffic and routes incoming requests to different back-ends. The loadbalancer might be pound, varnish, haproxy, nginx, or similar. The back-ends might be node applications, apache, or similar. The typical configuration of the load-balancer will read:
# forward
# backends
backend web1    .host = "10.0.0.4";  
backend web2    .host = "10.0.0.6";  
backend web3    .host = "10.0.0.5";  
#  afterword
I've seen this same setup in many situations, and while it can easily be imagined that there might be "random HTTP servers" on your (V)LAN which shouldn't receive connections it seems like a pain to keep updating the backends. Using UDP/multicast broadcasts it is trivial to announce "Hey I'm a HTTP-server with the name 'foo'", and it seems to me that this should allow seamless HTTP load-balancing. To be more explicit - this is normal: What I'd like to propose is another step: i.e. This allows backends to be removed from service when they go offline but also to be added when they come online. Without the load-balancer needing its configuration to be updated. This means you'd not give a static list of back-ends to your load-balancer, instead you'd say "Route traffic to any service that adfvertises itself with the tag 'foo'.". VLANS, firewalls, multicast, udp, all come into play, but in theory this strikes me as being useful, obvious, and simple. (Failure cases? Well if the "announcer" dies then the backend won't get traffic routed to it. Just like if the backend were offline. And clearly if a backend is announced, but not receiving HTTP-requests it would be dropped as normal.) If I get the time this evening I'll sit down and look at some load-balancer source code to see if any are written in such a way that I could add this "broadcast discovery" as a plugin/minor change.

Steve Langasek: My CuBox-i has arrived

A couple of weeks ago, Gunnar Wolf mentioned on IRC that his CuBox-i4 had arrived. This resulted in various jealous noises from me; having heard about this device making the rounds at the Kernel Summit, I ordered one for myself back in December, as part of the long-delayed HDification of our home entertainment system and coinciding with the purchase of a new Samsung SmartTV. We've been running an Intel Coppermine Celeron for a decade as a MythTV frontend and encoder (hardware-assisted with a PVR-250), which is fine for SD video, but really doesn't cut it for anything HD. So after finally getting a TV that would showcase HD in all its glory, I figured it was time to upgrade from an S-Video-out, barely-limping-along tower machine to something more modern with HDMI out, eSATA, hardware video decoding, and whose biggest problem is it's so small that it threatens to get lost in the wiring! Since placing the order, I've been bemused to find that the SmartTV is so smart that it has had a dramatic impact on how we consume media; between that and our decision to not be a boiled frog in the face of DISH Network's annual price increase, the MythTV frontend has become a much less important part of our entertainment center, well before I ever got a chance to lay hands on the intended replacement hardware. But that's a topic for another day. Anyway, the CuBox-i4 finally arrived in the mail on Friday, so of course I immediately needed to start hacking on it! Like Gunnar, who wrote last week about his own experience getting a "proper" Debian install on the box, I'm not content with running a binary distribution image prepared by some third party; I expect my hardware toys to run official distro packages assembled using official distro tools and, if at all possible, distributed on official distro images for a minimum of hassle. Whereas Gunnar was willing to settle for using third-party binaries for the bootloader and kernel, however, I'm not inclined to do any such thing. And between my stint at Linaro a few years ago and the recent work on Ubuntu for phones, I do have a little knowledge of Linux on ARM (probably just enough to be dangerous), so I set to work trying to get the CuBox-i4 bootable with stock Debian unstable. Being such a cutting-edge piece of hardware, that does pose some challenges. Support for the i.MX6 chip is in the process of being upstreamed to U-Boot, but the support for the CuBox-i devices isn't there yet, nor is the support for SPL on i.MX6 (which allows booting the variants of the CuBox-i with a single U-Boot build, instead of requiring a different bootloader build for each flavor). The CuBox-i U-Boot that SolidRun makes available (with source at github) is based on U-Boot 2013.10-rc4, so more than a full release behind Debian unstable, and the patches there don't apply to U-Boot 2014.01 without a bit of effort. But if it's worth doing, it's worth doing right, so I've taken the time to rebase the CuBox-i patches on top of 2014.01, publishing the results of the rebase to my own github repository and submitting a bug to the Debian U-Boot maintainers requesting its inclusion. The next step is to get a Debian kernel that not only works, but fully supports the hardware out of the box (a 3.13 generic arm kernel will boot on the machine, but little things like ethernet and hdmi don't work yet). I've created a page in the Debian wiki for tracking the status of this work.

8 March 2014

Andrew Shadura: Process isolation support in start-stop-daemon

Yesterday I played with LXC a bit, and I liked it, as LXC provides a very lightweight isolation of processes, much like enchanced chroot. However, I realised, I don t always need the chroot-like part of LXC, sometimes what I need is just to make sure the process is unable to see the other processes and talk to them in any other way except the filesystem, but I don t want a whole separate root file system for that. LXC provides a simple utility, lxc-unshare, which uses Linux-specific clone(2) call to run a process with new PID, IPC and other namespaces. However, this utility can t be used for running forking daemons, as the container is destroyed when its PID 1 exits. That s why I decided to add the support for process isolation to start-stop-daemon. I was careful enough to introduce minimal changes to it to make sure they can be merged back to the version as shipped with dpkg, and at the same time be buildable separately from the rest of it. Speaking of building, by the way, this version of start-stop-daemon uses mk-configure, a light-weight autotools replacement, as its build system. What I added, from a user s perspective, is a single --isolate option. When run with this option, start-stop-daemon calls clone(2) just before configuring the environment of a process it s going to run. The cloned process runs in a new namespace, and immediately remounts /proc, /dev/shm and /dev/mqueue. Then it forks, and a forked process executes the daemon. The parent process, which is PID 1 in the new PID namespace, uses waitpid(2) to monitor its child processes. As soon as its very first child exits, it talks via a pipe to the process outside of the container, so that it knows the container has a forked daemon and it needs to detach. In any case, the container s PID 1 does waitpid(2) in a loop, checking the process list every time a child terminates. As soon as it s left alone or a SIGTERM is received, it exits. The code is published at Bitbucket.

7 March 2014

Keith Packard: glamor-hacking

Brief Glamor Hacks Eric Anholt started writing Glamor a few years ago. The goal was to provide credible 2D acceleration based solely on the OpenGL API, in particular, to implement the X drawing primitives, both core and Render extension, without any GPU-specific code. When he started, the thinking was that fixed-function devices were still relevant, so that original code didn t insist upon modern OpenGL features like GLSL shaders. That made the code less efficient and hard to write. Glamor used to be a side-project within the X world; seen as something that really wasn t very useful; something that any credible 2D driver would replace with custom highly-optimized GPU-specific code. Eric and I both hoped that Glamor would turn into something credible and that we d be able to eliminate all of the horror-show GPU-specific code in every driver for drawing X text, rectangles and composited images. That hadn t happened though, until now. Fast forward to the last six months. Eric has spent a bunch of time cleaning up Glamor internals, and in fact he s had it merged into the core X server for version 1.16 which will be coming up this July. Within the Glamor code base, he s been cleaning some internal structures up and making life more tolerable for Glamor developers. Using libepoxy A big part of the cleanup was a transition all of the extension function calls to use his other new project, libepoxy, which provides a sane, consistent and performant API to OpenGL extensions for Linux, Mac OS and Windows. That library is awesome, and you should use it for everything you do with OpenGL because not using it is like pounding nails into your head. Or eating non-tasty pie. Using VBOs in Glamor One thing he recently cleaned up was how to deal with VBOs during X operations. VBOs are absolutely essential to modern OpenGL applications; they re really the only way to efficiently pass vertex data from application to the GPU. And, every other mechanism is deprecated by the ARB as not a part of the blessed core context . Glamor provides a simple way of getting some VBO space, dumping data into it, and then using it through two wrapping calls which you use along with glVertexAttribPointer as follows:
pointer = glamor_get_vbo_space(screen, size, &offset);
glVertexAttribPointer(attribute_location, count, type,
              GL_FALSE, stride, offset);
memcpy(pointer, data, size);
glamor_put_vbo_space(screen);
glamor_get_vbo_space allocates the specified amount of VBO space and returns a pointer to that along with an offset , which is suitable to pass to glVertexAttribPointer. You dump your data into the returned pointer, call glamor_put_vbo_space and you re all done. Actually Drawing Stuff At the same time, Eric has been optimizing some of the existing rendering code. But, all of it is still frankly terrible. Our dream of credible 2D graphics through OpenGL just wasn t being realized at all. On Monday, I decided that I should go play in Glamor for a few days, both to hack up some simple rendering paths and to familiarize myself with the insides of Glamor as I m getting asked to review piles of patches for it, and not understanding a code base is a great way to help introduce serious bugs during review. I started with the core text operations. Not because they re particularly relevant these days as most applications draw text with the Render extension to provide better looking results, but instead because they re often one of the hardest things to do efficiently with a heavy weight GPU interface, and OpenGL can be amazingly heavy weight if you let it. Eric spent a bunch of time optimizing the existing text code to try and make it faster, but at the bottom, it actually draws each lit pixel as a tiny GL_POINT object by sending a separate x/y vertex value to the GPU (using the above VBO interface). This code walks the array of bits in the font and checking each one to see if it is lit, then checking if the lit pixel is within the clip region and only then adding the coordinates of the lit pixel to the VBO. The amazing thing is that even with all of this CPU and GPU work, the venerable 6x13 font is drawn at an astonishing 3.2 million glyphs per second. Of course, pure software draws text at 9.3 million glyphs per second. I suspected that a more efficient implementation might be able to draw text a bit faster, so I decided to just start from scratch with a new GL-based core X text drawing function. The plan was pretty simple:
  1. Dump all glyphs in the font into a texture. Store them in 1bpp format to minimize memory consumption.
  2. Place raw (integer) glyph coordinates into the VBO. Place four coordinates for each and draw a GL_QUAD for each glyph.
  3. Transform the glyph coordinates into the usual GL range (-1..1) in the vertex shader.
  4. Fetch a suitable byte from the glyph texture, extract a single bit and then either draw a solid color or discard the fragment.
This makes the X server code surprisingly simple; it computes integer coordinates for the glyph destination and glyph image source and writes those to the VBO. When all of the glyphs are in the VBO, it just calls glDrawArrays(GL_QUADS, 0, 4 * count). The results were encouraging :
1: fb-text.perf
2: glamor-text.perf
3: keith-text.perf
       1                 2                           3                 Operation
------------   -------------------------   -------------------------   -------------------------
   9300000.0      3160000.0 (     0.340)     18000000.0 (     1.935)   Char in 80-char line (6x13) 
   8700000.0      2850000.0 (     0.328)     16500000.0 (     1.897)   Char in 70-char line (8x13) 
   6560000.0      2380000.0 (     0.363)     11900000.0 (     1.814)   Char in 60-char line (9x15) 
   2150000.0       700000.0 (     0.326)      7710000.0 (     3.586)   Char16 in 40-char line (k14) 
    894000.0       283000.0 (     0.317)      4500000.0 (     5.034)   Char16 in 23-char line (k24) 
   9170000.0      4400000.0 (     0.480)     17300000.0 (     1.887)   Char in 80-char line (TR 10) 
   3080000.0      1090000.0 (     0.354)      7810000.0 (     2.536)   Char in 30-char line (TR 24) 
   6690000.0      2640000.0 (     0.395)      5180000.0 (     0.774)   Char in 20/40/20 line (6x13, TR 10) 
   1160000.0       351000.0 (     0.303)      2080000.0 (     1.793)   Char16 in 7/14/7 line (k14, k24) 
   8310000.0      2880000.0 (     0.347)     15600000.0 (     1.877)   Char in 80-char image line (6x13) 
   7510000.0      2550000.0 (     0.340)     12900000.0 (     1.718)   Char in 70-char image line (8x13) 
   5650000.0      2090000.0 (     0.370)     11400000.0 (     2.018)   Char in 60-char image line (9x15) 
   2000000.0       670000.0 (     0.335)      7780000.0 (     3.890)   Char16 in 40-char image line (k14) 
    823000.0       270000.0 (     0.328)      4470000.0 (     5.431)   Char16 in 23-char image line (k24) 
   8500000.0      3710000.0 (     0.436)      8250000.0 (     0.971)   Char in 80-char image line (TR 10) 
   2620000.0       983000.0 (     0.375)      3650000.0 (     1.393)   Char in 30-char image line (TR 24)
This is our old friend x11perfcomp, but slightly adjusted for a modern reality where you really do end up drawing billions of objects (hence the wider columns). This table lists the performance for drawing a range of different fonts in both poly text and image text variants. The first column is for Xephyr using software (fb) rendering, the second is for the existing Glamor GL_POINT based code and the third is the latest GL_QUAD based code. As you can see, drawing points for every lit pixel in a glyph is surprisingly fast, but only about 1/3 the speed of software for essentially any size glyph. By minimizing the use of the CPU and pushing piles of work into the GPU, we manage to increase the speed of most of the operations, with larger glyphs improving significantly more than smaller glyphs. Now, you ask how much code this involved. And, I can truthfully say that it was a very small amount to write:
 Makefile.am             2 
 glamor.c                5 
 glamor_core.c           8 
 glamor_font.c         181 ++++++++++++++++++++
 glamor_font.h          50 +++++
 glamor_priv.h          26 ++
 glamor_text.c         472 +++++++++++++++++++++++++++++++++++++++++++++++++++++
 glamor_transform.c      2 
 8 files changed, 741 insertions(+), 5 deletions(-)
Let s Start At The Very Beginning The results of optimizing text encouraged me to start at the top of x11perf and see what progress I could make. In particular, looking at the current Glamor code, I noticed that it did all of the vertex transformation with the CPU. That makes no sense at all for any GPU built in the last decade; they ve got massive numbers of transistors dedicated to performing precisely this kind of operation. So, I decided to see what I could do with PolyPoint. PolyPoint is absolutely brutal on any GPU; you have to pass it two coordinates for each pixel, and so the very best you can do is send it 32 bits, or precisely the same amount of data needed to actually draw a pixel on the frame buffer. With this in mind, one expects that about the best you can do compared with software is tie. Of course, the CPU version is actually computing an address and clipping, but those are all easily buried in the cost of actually storing a pixel. In any case, the results of this little exercise are pretty close to a tie the CPU draws 190,000,000 dots per second and the GPU draws 189,000,000 dots per second. Looking at the vertex and fragment shaders generated by the compiler, it s clear that there s room for improvement. The fragment shader is simply pulling the constant pixel color from a uniform and assigning it to the fragment color in this the simplest of all possible shaders:
uniform vec4 color;
void main()
 
       gl_FragColor = color;
 ;
This generates five instructions:
Native code for point fragment shader 7 (SIMD8 dispatch):
   START B0
   FB write target 0
0x00000000: mov(8)          g113<1>F        g2<0,1,0>F                        align1 WE_normal 1Q  ;
0x00000010: mov(8)          g114<1>F        g2.1<0,1,0>F                      align1 WE_normal 1Q  ;
0x00000020: mov(8)          g115<1>F        g2.2<0,1,0>F                      align1 WE_normal 1Q  ;
0x00000030: mov(8)          g116<1>F        g2.3<0,1,0>F                      align1 WE_normal 1Q  ;
0x00000040: sendc(8)        null            g113<8,8,1>F
                render ( RT write, 0, 4, 12) mlen 4 rlen 0        align1 WE_normal 1Q EOT  ;
   END B0
As this pattern is actually pretty common, it turns out there s a single instruction that can replace all four of the moves. That should actually make a significant difference in the run time of this shader, and this shader runs once for every single pixel. The vertex shader has some similar optimization opportunities, but it only runs once for every 8 pixels with the SIMD format flipped around, the vertex shader can compute 8 vertices in parallel, so it ends up executing 8 times less often. It s got some redundant moves, which could be optimized by improving the copy propagation analysis code in the compiler. Of course, improving the compiler to make these cases run faster will probably make a lot of other applications run faster too, so it s probably worth doing at some point. Again, the amount of code necessary to add this path was tiny:
 Makefile.am             1 
 glamor.c                2 
 glamor_polyops.c      116 ++++++++++++++++++++++++++++++++++++++++++++++++++--
 glamor_priv.h           8 +++
 glamor_transform.c    118 +++++++++++++++++++++++++++++++++++++++++++++++++++++
 glamor_transform.h     51 ++++++++++++++++++++++
 6 files changed, 292 insertions(+), 4 deletions(-)
Discussion of Results These two cases, text and points, are probably the hardest operations to accelerate with a GPU and yet a small amount of OpenGL code was able to meet or beat software easily. The advantage of this work over traditional GPU 2D acceleration implementations should be pretty clear this same code should work well on any GPU which offers a reasonable OpenGL implementation. That means everyone shares the benefits of this code, and everyone can contribute to making 2D operations faster. All of these measurements were actually done using Xephyr, which offers a testing environment unlike any I ve ever had build and test hardware acceleration code within a nested X server, debugging it in a windowed environment on a single machine. Here s how I m running it:
$ ./Xephyr  -glamor :1 -schedMax 2000 -screen 1024x768 -retro
The one bit of magic here is the -schedMax 2000 flag, which causes Xephyr to update the screen less often when applications are very busy and serves to reduce the overhead of screen updates while running x11perf. Future Work Having managed to accelerate 17 of the 392 operations in x11perf, it s pretty clear that I could spend a bunch of time just stepping through each of the remaining ones and working on them. Before doing that, we want to try and work out some general principles about how to handle core X fill styles. Moving all of the stipple and tile computation to the GPU will help reduce the amount of code necessary to fill rectangles and spans, along with improving performance, assuming the above exercise generalizes to other primitives. Getting and Testing the Code Most of the changes here are from Eric s glamor-server branch:
git://people.freedesktop.org/~anholt/xserver glamor-server
The two patches shown above, along with a pair of simple clean up patches that I ve written this week are available here:
git://people.freedesktop.org/~keithp/xserver glamor-server
Of course, as this now uses libepoxy, you ll need to fetch, build and install that before trying to compile this X server. Because you can try all of this out in Xephyr, it s easy to download and build this X server and then run it right on top of your current driver stack inside of X. I d really like to hear from people with Radeon or nVidia hardware to know whether the code works, and how it compares with fb on the same machine, which you get when you elide the -glamor argument from the example Xephyr command line above.

Vincent Fourmond: Removing the background of an image

While in the process of polishing up a paper, I had to draw figures using a well-known proprietary program for drawing chemical formula whose name I will not write down, out of decency (but you know which one it is anyway). I'm using the mac version (yes, no version for Linux) which has a neat glitch in that the "Save As" button does not work at all: no way to export your chemical formula as a SVG/PDF/PNG picture or whatever ! So I resorted to the neat Print as PDF feature of macintosh. I had to edit the resulting PDF files by hand as some of the colors were wrong (great !), and when I tried to include the PDF, I realized they had a white background... No way !So I dug in ImageMagick's convert documentation, and came up with the following code that converts the PDF file into a PNG with a transparent background:
convert -density 600 figure.pdf -channel alpha \
  -fx '((r == 1 && g == 1 && b == 1) ? 0 : 1)' figure.png
There are still some few points that look white but are probably not that white (due to antialiased rendering of the PDF file ?). There are many more things that can be done using the -fx operator, this page was helpful to me !Edit: while the alpha channel seems to be on by default for PDF files, it is not necessarily the case for all images. If the above doesn't work, try adding -alpha Set before the -fx bit.

6 March 2014

Steve Kemp: So I bought some new hardware, for audio purposes.

This week I received a logitech squeezebox radio, which is basically an expensive toy that allows you to listen to either "internet radio", or music streamed from your own PC via a portable device that accesses the network wirelessly. The main goal of this purchase was to allow us to listen to media stored on a local computer in the bedroom, or living-room. The hardware scans your network looking for a media server, so the first step is to install that: The media-server has a couple of open ports; one for streaming the media, and one for a user-browsable HTML interface. Interestingly the radio-device shows up in the web-interface, so you can mess around with the currently loaded playlist from your office, while your wife is casually listening to music in the bedroom. (I'm not sure if that's a feature or not yet ;) Although I didn't find any alternative server-implementations I did find a software-client which you can use to play music from the central server - slimp3slave - and again you can push playlists, media, etc, to this. My impressions are pretty positive; the device was too expensive, certainly I wouldn't buy two, but it is functional. The user-interface is decent, and the software being available and open is a big win. Downsides? No remote-control for the player, because paying an additional 70 is never going to happen, but otherwise I can't think of anything. (Shame the squeezebox product line seems to have been cancelled (?)) Procmail Alternatives?
Although I did start hacking a C & Lua alternative, it looks like there are enough implementations out there that I don't feel so strongly any more. I'm working in a different way to most people, rather than sort mails at delivery time I'm going to write a trivial daemon that will just watch ~/Maildir/.Incoming, and move mails out of there. That means that no errors will cause mail to be lost at SMTP/delivery time. I'm going to base my work on Email::Filter since it offers 90% of the primitives I want. The only missing thing is the ability to filter mails via external commands which has now been reported as a bug/omission.

Ian Wienand: Skipping pages with django.core.paginator

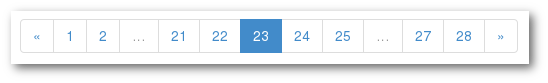
Here's a little snippet for compressing the length of long Django pagination by just showing context around the currently selected page. What I wanted was the first few and last few pages always selectable with some context pages around the currently selected page; e.g. Example of skip markers in paginator If that's what you're looking for, some variation on below may be of use. In this approach, you build up a list of pages similar to the paginator object page_range but with only the relevant pages and the skip-markers identified.
from django.core.paginator import Paginator
import unittest
class Pages:
    def __init__(self, objects, count):
        self.pages = Paginator(objects, count)
    def pages_to_show(self, page):
        # pages_wanted stores the pages we want to see, e.g.
        #  - first and second page always
        #  - two pages before selected page
        #  - the selected page
        #  - two pages after selected page
        #  - last two pages always
        #
        # Turning the pages into a set removes duplicates for edge
        # cases where the "context pages" (before and after the
        # selected) overlap with the "always show" pages.
        pages_wanted = set([1,2,
                            page-2, page-1,
                            page,
                            page+1, page+2,
                            self.pages.num_pages-1, self.pages.num_pages])
        # The intersection with the page_range trims off the invalid
        # pages outside the total number of pages we actually have.
        # Note that includes invalid negative and >page_range "context
        # pages" which we added above.
        pages_to_show = set(self.pages.page_range).intersection(pages_wanted)
        pages_to_show = sorted(pages_to_show)
        # skip_pages will keep a list of page numbers from
        # pages_to_show that should have a skip-marker inserted
        # after them.  For flexibility this is done by looking for
        # anywhere in the list that doesn't increment by 1 over the
        # last entry.
        skip_pages = [ x[1] for x in zip(pages_to_show[:-1],
                                         pages_to_show[1:])
                       if (x[1] - x[0] != 1) ]
        # Each page in skip_pages should be follwed by a skip-marker
        # sentinel (e.g. -1).
        for i in skip_pages:
            pages_to_show.insert(pages_to_show.index(i), -1)
        return pages_to_show
class TestPages(unittest.TestCase):
    def runTest(self):
        objects = [x for x in range(0,1000)]
        p = Pages(objects, 10)
        self.assertEqual(p.pages_to_show(0),
                         [1, 2, -1, 99, 100])
        self.assertEqual(p.pages_to_show(1),
                         [1,2,3,-1,99,100])
        self.assertEqual(p.pages_to_show(2),
                         [1,2,3,4,-1,99,100])
        self.assertEqual(p.pages_to_show(3),
                         [1,2,3,4,5,-1,99,100])
        self.assertEqual(p.pages_to_show(4),
                         [1,2,3,4,5,6,-1,99,100])
        self.assertEqual(p.pages_to_show(5),
                         [1,2,3,4,5,6,7,-1,99,100])
        self.assertEqual(p.pages_to_show(6),
                         [1,2,-1,4,5,6,7,8,-1,99,100])
        self.assertEqual(p.pages_to_show(7),
                         [1,2,-1,5,6,7,8,9,-1,99,100])
        self.assertEqual(p.pages_to_show(50),
                         [1,2,-1,48,49,50,51,52,-1,99,100])
        self.assertEqual(p.pages_to_show(93),
                         [1,2,-1,91,92,93,94,95,-1,99,100])
        self.assertEqual(p.pages_to_show(94),
                         [1,2,-1,92,93,94,95,96,-1,99,100])
        self.assertEqual(p.pages_to_show(95),
                         [1,2,-1,93,94,95,96,97,-1,99,100])
        self.assertEqual(p.pages_to_show(96),
                         [1,2,-1,94,95,96,97,98,99,100])
        self.assertEqual(p.pages_to_show(97),
                         [1,2,-1,95,96,97,98,99,100])
        self.assertEqual(p.pages_to_show(98),
                         [1,2,-1,96,97,98,99,100])
        self.assertEqual(p.pages_to_show(99),
                         [1,2,-1,97,98,99,100])
        self.assertEqual(p.pages_to_show(100),
                         [1,2,-1,98,99,100])
if __name__ == '__main__':
    unittest.main()
Then somehow pass through the pages_to_show to your view (below I added it to the paginator object passed) and use a template along the lines of
<ul class="pagination">
 % if pages.has_previous % 
  <li><a href="foo.html?page=  pages.previous_page_number  ">&laquo;</a></li>
 % else % 
  <li class="disabled"><a href="#">&laquo;</a></li>
 % endif % 
 % for page in pages.pages_to_show % 
   % if page == -1 % 
  <li class="disabled"><a href="#">&hellip;</a></li>
   % elif page == pages.number % 
  <li class="active"><a href="#">  page_num  </a></li>
   % else % 
  <li><a href="foo.html?page=  page_num  "> page_num </a>
   % endif % 
 % endfor % 
 % if pages.has_next % 
  <li><a href="foo.html?page=  pages.next_page_number  ">&raquo;</a></li>
 % else % 
  <li class="disabled"><a href="#">&raquo;</a></li>
 % endif % 
</ul>

4 March 2014

Andrew Pollock: [life] Day 35, Kindergarten, taxes, makeup BJJ

I foolishly had a late night last night, for no particularly good reason, so I slept in quite late this morning. I didn't start getting going until about 8am. How decadent. I'd forgotten to send Zoe to Kindergarten with her water bottle yesterday, and forgotten to give it to Sarah when she picked her up yesterday, so I dropped it and a fresh set of spare clothes out to Kindergarten after I had breakfast and a shower. I managed to sneak in and out without Zoe seeing me. I did some more work on my taxes before popping out for lunch to discuss my main start up idea. I also renamed my old shelf company today. I biked over to Kindergarten for pick up, and sure enough, Zoe was fast asleep. It took quite a bit of work to rouse her. I was pretty sure she was just faking it though. She moved pretty fast when I said I had a surprise at home for her. We biked home, and I gave her the surprise (some Pop Rocks I'd been saving for a special occasion) and headed out by car to a makeup Brazilian Jiu-Jitsu class to make up for the one she missed on Friday. It turned out that trying to do an afternoon class after Kindergarten and being woken up from a nap wasn't the best idea. Zoe tired out pretty quickly, during the warm up exercises, and was moderately uncooperative for the remainder of the class (she kept going on strike). I've never driven to or from BJJ classes until today, and I wasn't actually sure how best to drive home, since we've always taken the Norman Park Greenway. Zoe was asking for a "different way" anyway, so that worked out well. We winged it through Coorparoo and the back of Norman Park and tacked onto the end of how we'd normally cycle home. Zoe had enough time to watch a little bit of TV before Sarah arrived to pick her up.

3 March 2014

DebConf team: DebConf11 Sponsored registration date has been extended (Posted by nattie)

The deadline for sponsored registration for DebConf11 in Banja Luka, originally May 8th, has officially been extended to May 19th. The reasons for the extension are as follows: Thanks to a significant increase in sponsorship from one of our main sponsors, we have been permitted and encouraged to welcome more people to the conference. The extension is a one-off occurrence in response to this new development, and to allow any potential attendees time to access more information before registering. Registration is required for everybody who plans to attend any part of Debconf. Access to the conference venue, food and accommodation is controlled through the registration badge. The only exception to the registration requirement is for those who plan to only attend Debian Day. It is possible to request sponsorship for food, accommodation, and travel. Those who have been involved or contributed to Debian or to other open source projects are eligible to apply for sponsorship, which will be decided on a case-by-case basis. The professional and corporate categories are for those who are sent and sponsored by their companies. Professional registration covers the actual costs of conference attendance, while corporate registration is just over double that price, and is aimed at those who, besides paying the actual costs, also want to contribute money and help Debian. the DebConf team

Steve Kemp: Anti-social coding

I get all excited when I load up Github's front-page and see something like:
"robyn has forked skx/xxx to robyn/xxx"
I wonder what they will do, what changes do they have in mind? Days pass, and no commits happen. Anti-social coding: Cloning the code, I guess in case I delete my repository, but not intending to make any changes.

Daniel Pocock: Automatically building Java projects

Another of the GSoC project areas I have offered to mentor involves automatically and recursively building Java projects. Why is this important? Recently, I decided to start using travis-ci to automatically build some of my Java projects. One of the projects, JMXetric, depends on another, gmetric4j. When travis-ci builds JMXetric, it needs to look in Maven repositories to find gmetric4j (and also remotetea / oncrpc.jar and junit). The alternative to fetching things from repositories is to stop using Maven and ship the binary JARs of dependencies in the JMXetric repository itself, which is not desirable for various reasons. Therefore, I submitted gmetric4j into the Maven Central repository by using the Sonatype Nexus service. One discovery I made in this process disturbed me: Sonatype allows me to sign and upload my binary JAR, they don't build it from source themselves, so users of the JAR have no way to know that it really is built from the source I publish in Github. In fact, as anybody who works with Java knows, there is no shortage of Java projects out there that have a mix of binary dependencies in their source tree, sometimes without any easy way to find the dependency sources. HermesJMS is one popular example that is crippled by the inclusion of some JARs that are binary-only. No silver bullet, but there is hope Although there are now tens of thousands of JAR libraries out there in repositories and projects that depend on them (and their transitive dependencies and build tools and such), there is some hope:
  • Many JARs provide a -source JAR including source. This doesn't include all of the build artifacts of a true source package or source tarball, it just provides a subset of the source for use with a debugger.
  • Many Maven pom.xml files now include metadata about where the source is located - example
With that in mind, I'm hopeful that a system could be developed to scrape some of these data sources to find some source code and properly build some subset of the thousands of JARs available in the Maven Central Repository. But why bother if you can't completely succeed? One recent post on maven-users suggested that because nobody would ever be able to build 100% of JARs from source, the project is already doomed to failure. Personally, I feel it is quite the opposite: by failing to build 100% of JARs from source, the project will help to pinpoint those hierarchies of JARs that are not really free software and increase pressure on their publishers to adhere to the standards that people reasonably expect for source distribution or provide a red flag to help dependant projects stop using them. On top of that, the confirmation of true free-software status for many other JARs will make it safer for people to rely on them, package them and distribute them in various ways. Dumping a gazillion new Java packages into Debian Just to clear up one point: being able to automatically build JARs from source (or a chain of dependencies involving hundreds of them) doesn't mean they will be automatically uploaded to the official Debian archive by a Debian Developer (DD). Having this view of the source will make it easier for a DD to look at a set of JARs and decide if they are suitable for packaging, but there would still be some manual oversight involved. The tool would simply take out some of the tedious manual steps (where possible) and give the DD the ability to spot traps (JARs without real source hidden in the dependency hierarchy) much more quickly. How would it work? The project - whether completed under GSoC or by other means - would probably be broken down into a few discrete components. Furthermore, it would utilize some existing tools where possible. All of this makes it easier for a student to focus on and complete some subset of the work even if the whole thing is quite daunting. Here are some of the ideas for the architecture of the solution and the different components to be used or developed:
  • The data set:
    • A database schema, tracking each binary artifact, the source repository location (e.g. Git or SVN URL), source tarball location, source JAR availability and dependency relationships (including versions)
    • A local Maven repository - only containing JARs that we have built locally from some source
    • A set of Git repositories to mirror the upstream repositories of projects that need to be tweaked.
  • Tool set:
    • A web interface or command line tool would be necessary for a user to kick-start the process by specifying some artifact they want to build
    • There would need to be a script that tries to work out all the possible ways to get the source for an artifact (e.g. by looking for a Git URL in the pom.xml from the Maven Central repository). This script would be able to do other things, like identifying the existence of -source JARs which may or may not be sufficient to build the artifact.
    • A script would need to be created for testing the artifact's source tarball or repository for binary artifacts (e.g. copies of junit.jar). Whenever such things were found, the script would mirror the repository into our local git and create a branch with binaries removed. A record of the binaries would be added to the local database so we can symlink them from a trusted source when building.
    • A script would need to be created for testing whether the project includes a recognised build system (such as build.xml for ant or pom.xml for Maven). For projects without such artifacts, the script would need to generate a template build.xml and store it in a local clone of the repository
    • Jenkins would be used to build the JARs. A script would need to be created to build the Jenkins job config file for the artifact, pointing Jenkins to the upstream Git or the local Git repository depending upon the situation.
    • If the project is a Maven or Ivy project, then there are likely to be attempts to find dependencies during the build process. Running under Jenkins, these tools would be configured in such a way that they only look to the local repository and use dependencies that we have already built. If the build fails during dependency resolution, this is where the recursive process would kick off: the attempt to find each missing dependency would be logged to a queue, and the requests in this queue would each be handled by restarting the whole process again at the beginning. Each of these requests would also be logged to the database.
    • Sometimes, the system would be unable to proceed (e.g. because there are no clues about source locations in a given pom.xml). A user interface would need to be constructed to show a list of artifacts with exceptions and allow the user to manually locate the source and supply the URLs. The system would then continue iterating with this new data.
  • Reporting: we already know that for some JARs, we will simply fail to make any progress and we are not going to lose any sleep over that. The important thing is to provide accurate reports to help people make decisions that may involve working around those JARs in future:
    • For what percentage of projects could we determine the license from the pom.xml? Reports on licensing: can we spot any license mismatch in the dependency hierarchy?
    • Tools: which build tools in the chain of dependencies don't provide any source code? Are they optional tools (such as code quality analysis) that we can skip in the build process (e.g. by producing a mock version of the tool or plugin)?
    • Which non-free/sourceless JARs are most widely depended upon by other projects in the free Java eco-system? Can we make a list of the top 10 or 20?
    • Abandonware: can we detect JARs that haven't been updated for an extended period of time, with no activity in the source repository? For these projects in particular, it is a really good idea to make backups of the source repositories (or mirrors of their web sites and source download directories) in case they disappear altogether.

1 March 2014

Francois Marier: Using vnc to do remote tech support over high-latency networks

If you ever find yourself doing a bit of technical support for relatives over the phone, there's nothing like actually seeing what they are doing on their computer. One of the best tools for such remote desktop sharing is vnc. Here's the best setup I have come up with so far. If you have any suggestions, please leave a comment!

Basic vnc configuration First off, you need two things: a vnc server on your relative's machine and a vnc client on yours. Thanks to vnc being an open protocol, there are many choices for both. I eventually settled on x11vnc for the server and ssvnc for the client. They are both available in the standard Debian and Ubuntu repositories. Since I have ssh access on the machine that needs to run the server, I simply login and then run x11vnc. Here's what ~/.x11vnrc contains:
noxdamage
That option appears to be necessary when the desktop to share is running gnome-shell / compiz. Afterwards, I start the client on my laptop with the following command:
ssvncviewer -encodings zrle -scale 1280x775 localhost
The scaling factor is simply the resolution of the client minus any window decorations.

ssh configuration As you can see above, the client is not connecting directly to the server. Instead it's connecting to its own vnc port (localhost:5900). That's because I'm tunelling the traffic through the ssh connection in order to avoid relying on vnc extensions for authentication and encryption. Here's what the client's ~/.ssh/config needs for that simple use case:
Host server.example.com:
  LocalForward 5900 127.0.0.1:5900
If the remote host (which has an internal IP address of 192.168.1.2 in this example) is not connected directly to the outside world and instead goes through a gateway, then your ~/.ssh/config will look like this:
Host gateway.example.com:
  ForwardAgent yes
  LocalForward 5900 192.168.1.2:5900
Host server.example.com:
  ProxyCommand ssh -q -a gateway.example.com nc -q0 %h 22
and the remote host will need to open up a port on its firewall for the gateway (internal IP address of 192.168.1.1 here):
iptables -A INPUT -p tcp --dport 5900 -s 192.168.1.1/32 -j ACCEPT

Optimizing for high-latency networks Since I do most of my tech support over a very high latency network, I tweaked the default vnc settings to reduce the amount of network traffic. I added this to ~/.x11vncrc on the vnc server:
ncache 10
ncache_cr
and changed the client command line to this:
ssvncviewer -compresslevel 9 -quality 3 -bgr233 -encodings zrle -use64 -scale 1280x775 -ycrop 1024 localhost
This decreases image quality (and required bandwidth) and enables client-side caching. The magic 1024 number is simply the full vertical resolution of the remote machine, which sports a vintage 1280x1024 LCD monitor.

Vasudev Kamath: Installing and Configuring NetBSD on Qemu in Debian

First step will be getting a NetBSD ISO image for installation purpose. It can be downloaded from here. Next step will be creating a disk image for installing NetBSD. This is done using qemu-img tool like below
$ qemu-img create -f raw netbsd-disk.img 10G
Image format used is raw and size is specified as last arugment. Tune the size as per your need. To start the installation run the following command
$ qemu-system-x86_64 -m 256M -hda netbsd-disk.img -cdrom \
             NetBSD-6.1.3-amd64.iso -display curses -boot d \
             -net nic -net user
So this is using user mode networking so you won't be able to have internet access during installation. I couldn't figure out on how to get network working during installation so I configured network after installation. Once you run above command you will be given with 4 options as follows.
  1. install netbsd
  2. install netbsd with ACPI disabled
  3. install netbsd with ACPI and SMP disabled
  4. drop to boot shell
Even though I first installed using the option 1 I couldn't get it boot after installation so had to reinstall with option 2 and it works fine. I'm not gonna explain each step of installation here because the installer is really simple and straight forward! I guess the NetBSD installer is the first simplest installer I have encountered from the day I started with Linux. Its simple but powerful and gets job done very easily, and I didn't read manual for installation before using it.
Enabling Networking This section involves mixture of configuration in Debian host and inside NetBSD to get the network working. The wiki page of Debian on Qemu. helped me here. To share the network with Qemu there are 2 possiblities
  1. Bridged networking between host and guest using bridge-utils
  2. Using VDE (Virtual Distributed Ethernet)
The option 1 which is explained in wiki linked above didn't work for me as I use CDC Ether based datacard for connecting to Internet which gets detected as eth1 on my machine. When bridging happens between tap0 and eth1 I end up loosing Internet on my host machine. So I selected to use VDE instead. First install packages vde2 and uml-utilities once done edit the /etc/network/interfaces file and add following lines:
auto vdetap
iface vdetap inet static
   address 192.168.2.1
   netmask 255.255.255.0
   vde2-switch -t vdetap
We can use dnsmasq as a DHCP server for the vdetap interface, but I'm not gonna explain the configuration of dnsmasq here. Run the below command to get vdetap up
modprobe tun
ifup vdetap
/etc/init.d/dnsmasq restart
newgrp vde2-net # run as user starting Qemu VM's
I couldn't get successful output for newgrp command, I was getting some crypt: Invalid argument output. But I could still get network working on NetBSD so I considered to ignore that for now. Now start the NetBSD qemu instance running using following command
$ qemu-system-x86_64 -m 256M -hda \
             /mnt/kailash/BSDWorld/netbsd-disk.img \
             -net nic -net vde,sock=/var/run/vde2/vdetap.ctl -display curses
Once the system is up login using root user, NetBSD will warn you for this and suggest to create another user but for now ignore it. To find the network interface in NetBSD just run the usual ifconfig command. In my case interface is named wm0. First step will be configuring the IP address for your interface and setting up the gateway route. Run the below command for this purpose
# ifconfig wm0 192.168.2.2 netmask 255.255.255.0
# route add default 192.168.2.1
Note that I added gateway as IP address of vdetap on my host machine. Now try pinging the host and even you can try ssh to host system. But note that this is not persistent over the reboots and for some reason I didn't yet figure out how to make NetBSD get address over DHCP from my host machine. I will update once I figure it out. Now to make the connection address persistent over reboots you need to create a file by name /etc/ifconfg.<interface>. Replace interface with a proper interface on your running NetBSD. In my case this file is /etc/ifconfig.wm0 and has following content.:
192.168.2.2 netmask 0xffffff00 media autoselect
Set the DNS server as host by adding file /etc/resolv.conf with following content.:
nameserver 192.168.2.1
After this you need to do NAT/masquerading using iptables. Just copy following script to a file and execute it as root
#!/bin/sh
# Restart the dnsmasq
/etc/init.d/dnsmasq restart
# Set nat rules in iptables
iptables --flush
iptables --table nat --flush
iptables --delete-chain
iptables --table nat --delete-chain
# Replace accordingly usb0 with ppp0 for 3G
iptables --table nat --append POSTROUTING --out-interface eth1 -j MASQUERADE
iptables --append FORWARD --in-interface vdetap -j ACCEPT
# Enable IP forwarding in Kernel
sysctl -w net.ipv4.ip_forward=1
With the above setup you will be able to get DNS resolution even after you reboot the Qemu instance but Internet connection will not work untill you run the route command I mentioned above. I still didn't figure out how to persist route but I will update it here once I figure it out.
Note that you won't be able to SSH as root to NetBSD (may be its configured to not allow by default), so you would need to create a normal user before trying to SSH from host to guest. Also make sure you add the user to wheel group to allow him execute su command.
So now I've NetBSD running on my laptop with mere 256M ram and its amazingly fast even at such low RAM. I've created a new user and can SSH into it from host machine and use it just like I use a server!. I will put up the notes of my BSD adventure here periodically. The feeling of using a BSD is amazing :-)
Update: I forgot to add masquerading step, I've added it now.

Russ Allbery: Review: Air Apparent

Review: Air Apparent, by Mark Monmonier
Publisher: University of Chicago
Copyright: 1999
Printing: 2000
ISBN: 0-226-53423-5
Format: Trade paperback
Pages: 232
Subtitled "how meteorologists learned to map, predict, and dramatize the weather," Air Apparent is a history of weather maps. Mapping the weather is a surprisingly new field, dating only from the early 19th century when a combination of scientific understanding and the ability to combine scattered observations made it practical. They're also a particularly tricky problem since weather is inherently three-dimensional, and even to the present day nearly all of our maps are two-dimensional. Monmonier starts with the earliest observational maps and the attempts to use them for prediction and tracks developments up to the late 1990s, with TV weathermen and (simple) interactive web data viewers. I got a copy of this book after Paul Krugman mentioned it. I don't know a lot about weather forecasting or weather maps, but I remembered finding the science of weather fronts and maps of them fascinating in high school, and I hoped I'd get the same feeling from this. Unfortunately, I probably need to stop reading Monmonier's books; they always sound interesting, but I don't enjoy reading them. One thing that's important to know is that this is not a history of meteorology. One can't hold that against the book, of course, because it never claimed to be. But it has just enough of a history of meteorology mixed into its history of map-making to make at least this reader wish he were reading that other book. I like maps, I really do, but I was hoping for either a book that melded a history of the science of weather forecasting with the maps that were used in that science, or a book that dove deep into the effective and ineffective ways to make weather maps (ideally, Edward R. Tufte for maps). This is neither; it's little more or less than a detailed history of the making of weather maps. Each time it gets close to a clear explanation of the underlying meteorology, it finds a map to examine and skips the rest of the explanation. I kept almost understanding the underlying science, but not enough to really understand the goals of the map makers, or why one presentation was better than another, or how those presentations were used to make forecasts or track weather data. I think I would have found this book more interesting in conjunction with a full history of meteorology, but I suspect that a history of meteorology would include enough about the maps to render this book largely redundant for the casual reader. The other problem I had with this book is that it's very dry. Monmonier is clearly trying, and clearly cares a lot about his topic, but the book has no flow. I kept getting lost in the barrage of names, arguments over technique, and struggles for government funding. It's hard to put a finger on why the book didn't grab me; the closest I can come is that it's a book stuffed full of facts. Monmonier did exhaustive historical research on weather map making, saved numerous quotes from original documents, and laid it all out chronologically. That's fine if you just want the information, but I was looking to be entertained in the process, and that didn't happen. I think the problems get worse in the second half of the book, when weather satellites and computers enter the picture and the laborious, manual map-making fall out, although maybe I was just exhausted with the book by then. The early history of weather maps at least has the benefit of showing the logistical struggles behind creating an effective weather service: insufficient observation points, slow communication methods, and the need for skilled map-makers to turn measurements into visual representations. Once computers and satellite photography enter the picture, the science matters even more, and I think the reader needs a better understanding of the underlying science to make sense of the results. Air Apparent has a tendency to provide a brief introduction to the type of data, a detailed chronological history, and then a discussion of the ways of presenting and representing that data, without ever getting the reader to care about the data itself or see how it ties into forecasting. Part of the problem, I suspect, is that the history of meteorology seems to be full of sensible, careful people who largely did sensible, careful things with the data they had available at the time. This is great for the advancement of science, and not so helpful at making a history engrossing. I wish I could say that I was glad I read this book for the information, if not the presentation, but unfortunately I didn't retain much. I needed some sort of structure or frame on which to hang all of the specifics, some sense of story or controversy or at least scientific understanding, and I didn't get it. It took me a couple of months to finish this book because I kept setting it down to read other things, and I only finished it out of a combination of stubbornness and knowledge that other people liked it. If the topic sounds interesting, well, this book exists, and it's gotten several good reviews. But I'm afraid I can't recommend it. Rating: 4 out of 10

Vasudev Kamath: Gzipped response for CSS/JS with Apache and mod_uwsgi

So it may sound normal to receive compressed response for CSS/JS file from Apache2 but what I faced is completely different behavior, here I saw not just body of response but also header are getting compressed and send to browser and browser was unable to interpret the response there by leading page rendered without CSS and JS. That was long story short, so let me explain in detail the case and what I found out. I have hosted SILPA on my VPS using uWSGI. I had used till date using libapache2-mod-proxy-uwsgi plugin for which uWSGI should be using network socket and in Apache2 config I need ProxyPass directive pointing to uwsgi://host:port and everything used to work out of box. There is a drawback for using network socket in uWSGI that is limited amount of ports (65535) and possible clash with other services if we use wrong port number, additionally network sockets will be slower compared to the file socket so yesterday I thought of changing it to file socket and removed socket directive in the ini file for uWSGI application container for SILPA and here is where all problems started. My updated configuration can be seen in our documentation page that is if you are interested to look my configuration file :-).
Problem Reporting We got selected to Gsoc again this year and we have lot of students jumping in our channel #silpa on irc.freenode.net and yesterday night some students reported they are facing 500 internal server error and subsequently others mentioned there is no theme being rendered. I checked and found everything was fine for me only to notice that my browser was using cached content, and when I clear cache there I go everything vanished, no theme no css no javascript just plain html!!!.
Investigation So I thought I should investigate this and fired up firebug on my iceweasel to observe the network traffic. And below is what I observed in firebug network console!. No response headers So you can see no response header in the above image but there is a response and below how is response content visible on firebug. gzipped response Still weird part was when using wget/curl directly to get the CSS I was getting correct reply and the file, which is puzzling. So I went ahead opened the CSS url directly using browser and saved the resulting file. When I used file command on it, output suggested the saved file in gzip compressed!. I went ahead uncompressed it and opened the file and inside it I found response header and the response body! So what just happened? Did apache some how manage to compress entire respone not just response body? The more puzzling question was why did it work when I was using mod_proxy_uwsgi and failed when I switched to mod_uwsgi. I had no clue at this point why this behavior is coming up.
Possible Solution I was still not sure how to resolve this, and started searching in the network but nothing was coming up in search result which can explain me this. And finally I stumbled on a link which is totally unrelated but I saw the word mod_deflate in the content and wandered on my system to see if its enabled. Yes mod_deflate was enabled I just opened the conf file and saw following.
<IfModule mod_deflate.c>
       # these are known to be safe with MSIE 6
       AddOutputFilterByType DEFLATE text/html text/plain text/xml
       # everything else may cause problems with MSIE 6
       AddOutputFilterByType DEFLATE text/css
       AddOutputFilterByType DEFLATE application/x-javascript application/javascript application/ecmascript
       AddOutputFilterByType DEFLATE application/rss+xml
</IfModule>
Interesting so it suggests to compress css, javascript files etc. So I thought possibly its compressing the result of mod_uwsgi, yeah possibly so why not try disabling mod_deflate and check if it works well and good if not I'm not gonna loose anything. So I disabled mod_deflate and voila! Everything is working fine!
What might be the reason for this behavior? Well I'm not exactly sure but here is my assumption. The whole behavior depends on internal implementation of mod_uwsgi and mod_proxy_uwsgi module. To confirm this I switched back to use mod_proxy_uwsgi module and enabled mod_deflate and observed request response in Firebug network console and below is what I observed. Response with mod_proxy_uwsgi So response is still gziped but this time only response body was gziped and Content-Encoding field was set properly which makes browser to properly uncompress the response body and use it. So it seems like there is a difference between mod_uwsgi and mod_proxy_uwsgi implementation. mod_uwsgi was sending the response along with response headers which was compressed by mod_deflate there by rendering browser helpless to interpret the response. But mod_proxy_uwsgi seems to be only sending the response content without response body and this content was later compressed by mod_deflate and proper response headers were set by apache before sending it to browser. So now whose fault is this? Is it the bug in mod_uwsgi or, mod_deflate not being able to exclude response headers from compression? I've no clue! If you have a clue and you want to share it with me, please consider writing to me over email. My details are available in Contacts

28 February 2014

Daniel Pocock: Google Summer of Code opportunities in data science and machine learning with Ganglia

As mentioned in my blog on Monday, the Ganglia Project is proud to be part of Google Summer of Code in 2014 The Ganglia team are offering various types of projects and different parts of Ganglia would welcome students with different skills, for example:
Component Skills
gmond agent C
gmond modules C or Python
JMXetric Java
gmetad and rrdtool for storing time series data C
Ganglia web interface JavaScript and jQuery
Ganglia integration (e.g. ganglia-nagios-bridge) Python
Big data right under your nose I have had many queries from students about how to get into data science. Very few students will be lucky enough to get an internship where they can study time-series from the financial markets and experiment making their own trading algorithms. On the other hand, network performance data is everywhere. It is real-time. It is surprisingly similar in some ways to processing financial data and it provides excellent opportunities for students to practice data science skills and make a meaningful contribution to solving real problems. Finding public Ganglia data with Google Many large organizations, including universities, governments and corporations are using Ganglia to gather metrics from all the hosts in their networks. Some of them even expose this data to the public. Here are two Google searches you can use to find them:
Courtesy of Universit Montpellier 2, France Some sites may even expose their data as an XML feed, you can try and extract it by connecting to the Ganglia server on one of these ports
Port Comments
8649 gmond: sends an XML snapshot to anybody who connects
8651 gmetad: sends an XML snapshot to anybody who connects
8651 gmetad: works a little bit like HTTP, returns a subset of the XML snapshot when you make a GET request
You can discover a Ganglia environment in your campus by looking for a gmond process on your machine and the gmond.conf file, often in /etc/gmond.conf or /etc/ganglia/gmond.conf. That file may contain a clue about the name of the host where Ganglia data is aggregated:
udp_send_channel  
  host = ganglia-reports.example.edu
  port = 8649
  ttl = 1
 
This tells you that the host ganglia-reports.example.edu is collecting the data - you could try the URL http://ganglia-reports.example.edu/ganglia/ in a web browser or try connecting to one of the TCP ports 8649, 8651 or 8652 on that host. Here is an example with netcat:
$ nc ganglia-reports.example.edu 8649   grep ^.H
It will return a list of all hosts that Ganglia knows about. Once you have a data feed, you can then configure a gmetad process on your own system to poll the remote system and generate local RRDs for you to study. Install your own Ganglia It is very easy to get your own Ganglia setup. On a Debian or Ubuntu system, just do:
# apt-get update
# apt-get install ganglia-monitor ganglia-webfrontend
On Fedora and RPM-based systems (such as CentOS or RHEL with EPEL) you can do:
# yum install ganglia-gmond ganglia-web
Everything should be autoconfigured. You can then browse to http://localhost/ganglia to see the charts. If you have several hosts with the gmond agent (just the ganglia-monitor.deb or ganglia-gmond.rpm) on the same LAN, they will automatically find each other using multicast and you will see an aggregated report on the machine with the web server. The data is real-time It is important to keep in mind that the data is real-time. This means you can often detect problems in real-time. If this blog appears on slashdot, for example, then that image from Universit Montpellier 2 will be hit many times. The image actually shows the network load on the web server producing the image, so you will see the slashdot effect graphically in the image itself. Processing real-time data is often the most advanced step in any data science exercise. Initially, you may simply log a few days of data to RRD files to start studying a static data set with your tool of choice, whether it is the R project, Weka or Hadoop Once you have a a hypothesis (for example, an algorithm that understands the normal characteristics of each metric) you may then take each new real-time value from the gmetad XML and test it with the algorithm. The algorithm would then raise an alert if any metric on any host deviates from its normal behavior. Mixing in other sources of data Depending upon the computing environment in your campus or organization, you may also be able to get other data sources, such as a list of people logged in to different machines at different times and the processes that each user starts and stops. This might help to make more accurate predictions about when network or computing resources will be under stress. For example, if users bob, alice and eve all appear on the same host, your algorithm might conclude that the load average will reach an excessive level within 15 minutes and send those three users a suggestion to each try other machines. Making a successful application for GSoC 2014 Here are some tips
  • For all organizations/projects
  • For Ganglia and the data science project in particular
    • Join the ganglia-general mailing list and send an email to introduce yourself
    • Try Ganglia on your own Linux system. Use the packages, it is really easy. Send an email to the list with any questions.
    • Explore the source code in github - ask us questions about it. For the data science project, you may also need to look at RRDtool source code and documentation about making a plugin for R (using C)
    • You don't have to do it our way: if you prefer to work with another tool instead of R, please tell us your idea
    • Write some skeleton code or make a diagram to explain what you want to do. While you do this, do you think of any new questions or problems? Make a list of them.
    • We want to give every student a small coding task as a test. Please tell us which language you prefer (e.g. C, Java, Python) so we can give you a suitable test. If you are really keen, follow the link to bugs I reported in Debian, look for one that is easy and try to write a small patch for it - helping fix bugs that annoy your mentor is likely to be a good way to get on the short-list for selection.

Michael Prokop: State of the art Debian/wheezy deployments with GRUB and LVM/SW-RAID/Crypto

Moving from Lilo to GRUB, using LVM as default, etc throughout the last years it was time to evaluate how well LVM works without a separate boot partition, possibly also on top of Software RAID. Big disks are asking for partitioning with GPT, just UEFI isn t my default yet, so I m still defaulting to Legacy BIOS for Debian/wheezy (I expect this to change for Debian/jessie and according hardware approaching at my customers). So what we have and want in this demonstration setup: System used for installation:
root@grml ~ # grml-version
grml64-full 2013.09 Release Codename Hefeknuddler [2013-09-27]
Partition setup:
root@grml ~ # parted /dev/sda
GNU Parted 2.3
Using /dev/sda
Welcome to GNU Parted! Type 'help' to view a list of commands.
(parted) mklabel gpt
(parted) mkpart primary 2048s 4095s
(parted) set 1 bios_grub on
(parted) name 1 "BIOS Boot Partition"
(parted) mkpart primary 4096s 100%
(parted) set 2 raid on
(parted) name 2 "SW-RAID / Linux"
(parted) quit
Information: You may need to update /etc/fstab.
Clone partition layout from sda to all the other disks:
root@grml ~ # for f in  b,c,d  ; sgdisk -R=/dev/sd$f /dev/sda
The operation has completed successfully.
Make sure each disk has its unique UUID:
root@grml ~ # for f in  b,c,d  ; sgdisk -G /dev/sd$f
The operation has completed successfully.
SW-RAID setup:
root@grml ~ # mdadm --create /dev/md0 --verbose --level=raid5 --raid-devices=4 /dev/sd a,b,c,d 2
mdadm: layout defaults to left-symmetric
mdadm: chunk size defaults to 512K
mdadm: size set to 1465004544K
mdadm: Defaulting to version 1.2 metadata
mdadm: array /dev/md0 started.
root@grml ~ #
SW-RAID speedup (system dependent, YMMV):
root@grml ~ # cat /sys/block/md0/md/stripe_cache_size
256
root@grml ~ # echo 16384 > /sys/block/md0/md/stripe_cache_size # 16MB
root@grml ~ # blockdev --getra /dev/md0
6144
root@grml ~ # blockdev --setra 65536 /dev/md0 # 32 MB
root@grml ~ # sysctl dev.raid.speed_limit_max
dev.raid.speed_limit_max = 200000
root@grml ~ # sysctl -w dev.raid.speed_limit_max=9999999999
dev.raid.speed_limit_max = 9999999999
root@grml ~ # sysctl dev.raid.speed_limit_min
dev.raid.speed_limit_min = 1000
root@grml ~ # sysctl -w dev.raid.speed_limit_min=100000
dev.raid.speed_limit_min = 100000
LVM setup:
root@grml ~ # pvcreate /dev/md0
  Physical volume "/dev/md0" successfully created
root@grml ~ # vgcreate homesrv /dev/md0
  Volume group "homesrv" successfully created
root@grml ~ # lvcreate -n rootfs -L4G homesrv
  Logical volume "rootfs" created
root@grml ~ # lvcreate -n bootfs -L1G homesrv
  Logical volume "bootfs" created
Check partition setup + alignment:
root@grml ~ # parted -s /dev/sda print
Model: ATA WDC WD15EADS-00P (scsi)
Disk /dev/sda: 1500GB
Sector size (logical/physical): 512B/512B
Partition Table: gpt
Number  Start   End     Size    File system  Name                 Flags
 1      1049kB  2097kB  1049kB               BIOS Boot Partition  bios_grub
 2      2097kB  1500GB  1500GB               SW-RAID / Linux      raid
root@grml ~ # parted -s /dev/sda unit s print
Model: ATA WDC WD15EADS-00P (scsi)
Disk /dev/sda: 2930277168s
Sector size (logical/physical): 512B/512B
Partition Table: gpt
Number  Start  End          Size         File system  Name                 Flags
 1      2048s  4095s        2048s                     BIOS Boot Partition  bios_grub
 2      4096s  2930276351s  2930272256s               SW-RAID / Linux      raid
root@grml ~ # gdisk -l /dev/sda
GPT fdisk (gdisk) version 0.8.5
Partition table scan:
  MBR: protective
  BSD: not present
  APM: not present
  GPT: present
Found valid GPT with protective MBR; using GPT.
Disk /dev/sda: 2930277168 sectors, 1.4 TiB
Logical sector size: 512 bytes
Disk identifier (GUID): 212E463A-A4E3-428B-B7E5-8D5785141564
Partition table holds up to 128 entries
First usable sector is 34, last usable sector is 2930277134
Partitions will be aligned on 2048-sector boundaries
Total free space is 2797 sectors (1.4 MiB)
Number  Start (sector)    End (sector)  Size       Code  Name
   1            2048            4095   1024.0 KiB  EF02  BIOS Boot Partition
   2            4096      2930276351   1.4 TiB     FD00  SW-RAID / Linux
root@grml ~ # mdadm -E /dev/sda2
/dev/sda3:
          Magic : a92b4efc
        Version : 1.2
    Feature Map : 0x0
     Array UUID : 7ed3b741:0774d529:d5a71c1f:cf942f0a
           Name : grml:0  (local to host grml)
  Creation Time : Fri Jan 31 15:26:12 2014
     Raid Level : raid5
   Raid Devices : 4
 Avail Dev Size : 2928060416 (1396.21 GiB 1499.17 GB)
     Array Size : 4392089088 (4188.62 GiB 4497.50 GB)
  Used Dev Size : 2928059392 (1396.21 GiB 1499.17 GB)
    Data Offset : 262144 sectors
   Super Offset : 8 sectors
          State : clean
    Device UUID : c1e4213b:81822fd1:260df456:2c9926fb
    Update Time : Mon Feb  3 09:41:48 2014
       Checksum : b8af8f6 - correct
         Events : 72
         Layout : left-symmetric
     chunk size : 512k
   Device Role : Active device 0
   Array State : AAAA ('A' == active, '.' == missing)
root@grml ~ # pvs -o +pe_start
  PV         VG      Fmt  Attr PSize PFree 1st PE
  /dev/md0   homesrv lvm2 a--  4.09t 4.09t   1.50m
root@grml ~ # pvs --units s -o +pe_start
  PV         VG      Fmt  Attr PSize       PFree       1st PE
  /dev/md0   homesrv lvm2 a--  8784175104S 8773689344S   3072S
root@grml ~ # pvs -o +pe_start
  PV         VG      Fmt  Attr PSize PFree 1st PE
  /dev/md0   homesrv lvm2 a--  4.09t 4.09t   1.50m
root@grml ~ # pvs --units s -o +pe_start
  PV         VG      Fmt  Attr PSize       PFree       1st PE
  /dev/md0   homesrv lvm2 a--  8784175104S 8773689344S   3072S
root@grml ~ # vgs -o +pe_start
  VG      #PV #LV #SN Attr   VSize VFree 1st PE
  homesrv   1   2   0 wz--n- 4.09t 4.09t   1.50m
root@grml ~ # vgs --units s -o +pe_start
  VG      #PV #LV #SN Attr   VSize       VFree       1st PE
  homesrv   1   2   0 wz--n- 8784175104S 8773689344S   3072S
Cryptsetup:
root@grml ~ # echo cryptsetup >> /etc/debootstrap/packages
root@grml ~ # cryptsetup luksFormat -c aes-xts-plain64 -s 256 /dev/mapper/homesrv-rootfs
WARNING!
========
This will overwrite data on /dev/mapper/homesrv-rootfs irrevocably.
Are you sure? (Type uppercase yes): YES
Enter passphrase:
Verify passphrase:
root@grml ~ # cryptsetup luksOpen /dev/mapper/homesrv-rootfs cryptorootfs
Enter passphrase for /dev/mapper/homesrv-rootfs:
Filesystems:
root@grml ~ # mkfs.ext4 /dev/mapper/cryptorootfs
mke2fs 1.42.8 (20-Jun-2013)
Filesystem label=
OS type: Linux
Block size=4096 (log=2)
Fragment size=4096 (log=2)
Stride=128 blocks, Stripe width=384 blocks
262144 inodes, 1048192 blocks
52409 blocks (5.00%) reserved for the super user
First data block=0
Maximum filesystem blocks=1073741824
32 block groups
32768 blocks per group, 32768 fragments per group
8192 inodes per group
Superblock backups stored on blocks:
        32768, 98304, 163840, 229376, 294912, 819200, 884736
Allocating group tables: done
Writing inode tables: done
Creating journal (16384 blocks): done
Writing superblocks and filesystem accounting information: done
root@grml ~ # mkfs.ext4 /dev/mapper/homesrv-bootfs
mke2fs 1.42.8 (20-Jun-2013)
Filesystem label=
OS type: Linux
Block size=4096 (log=2)
Fragment size=4096 (log=2)
Stride=128 blocks, Stripe width=384 blocks
65536 inodes, 262144 blocks
13107 blocks (5.00%) reserved for the super user
First data block=0
Maximum filesystem blocks=268435456
8 block groups
32768 blocks per group, 32768 fragments per group
8192 inodes per group
Superblock backups stored on blocks:
        32768, 98304, 163840, 229376
Allocating group tables: done
Writing inode tables: done
Creating journal (8192 blocks): done
Writing superblocks and filesystem accounting information: done
Install Debian/wheezy:
root@grml ~ # mount /dev/mapper/cryptorootfs /media
root@grml ~ # mkdir /media/boot
root@grml ~ # mount /dev/mapper/homesrv-bootfs /media/boot
root@grml ~ # grml-debootstrap --target /media --password YOUR_PASSWORD --hostname YOUR_HOSTNAME
 * grml-debootstrap [0.57] - Please recheck configuration before execution:
   Target:          /media
   Install grub:    no
   Using release:   wheezy
   Using hostname:  YOUR_HOSTNAME
   Using mirror:    http://http.debian.net/debian
   Using arch:      amd64
   Important! Continuing will delete all data from /media!
 * Is this ok for you? [y/N] y
[...]
Enable grml-rescueboot (to have easy access to rescue ISO via GRUB):
root@grml ~ # mkdir /media/boot/grml
root@grml ~ # wget -O /media/boot/grml/grml64-full_$(date +%Y.%m.%d).iso http://daily.grml.org/grml64-full_testing/latest/grml64-full_testing_latest.iso
root@grml ~ # grml-chroot /media apt-get -y install grml-rescueboot
[NOTE: We're installing a daily ISO for grml-rescueboot here because the 2013.09 Grml release doesn't work for this LVM/SW-RAID setup while newer ISOs are working fine already. The upcoming Grml stable release is supposed to work just fine, so you will be able to choose http://download.grml.org/grml64-full_2014.XX.iso by then. :)] Install GRUB on all disks and adjust crypttab, fstab + initramfs:
root@grml ~ # grml-chroot /media /bin/bash
(grml)root@grml:/# for f in  a,b,c,d  ; do grub-install /dev/sd$f ; done
(grml)root@grml:/# update-grub
(grml)root@grml:/# echo "cryptorootfs /dev/mapper/homesrv-rootfs none luks" > /etc/crypttab
(grml)root@grml:/# echo "/dev/mapper/cryptorootfs / auto defaults,errors=remount-ro 0   1" > /etc/fstab
(grml)root@grml:/# echo "/dev/mapper/homesrv-bootfs /boot auto defaults 0 0" >> /etc/fstab
(grml)root@grml:/# update-initramfs -k all -u
(grml)root@grml:/# exit
Clean unmounted/removal for reboot:
root@grml ~ # umount /media/boot
root@grml ~ # umount /media/
root@grml ~ # cryptsetup luksClose cryptorootfs
root@grml ~ # dmsetup remove homesrv-bootfs
root@grml ~ # dmsetup remove homesrv-rootfs
NOTE: On a previous hardware installation I had to install GRUB 2.00-22 from Debian/unstable to get GRUB working.
Some metadata from different mdadm and LVM experiments seems to have been left and confused GRUB 1.99-27+deb7u2 from Debian/wheezy (I wasn t able to reproduce this issue in my VM demo/test setup).
Just in cause you might experience the following error message, try GRUB >=2.00-22:
  # grub-install --recheck /dev/sda
  error: unknown LVM metadata header.
  error: unknown LVM metadata header.
  /usr/sbin/grub-probe: error: cannot find a GRUB drive for /dev/mapper/cryptorootfs.  Check your device.map.
  Auto-detection of a filesystem of /dev/mapper/cryptorootfs failed.
  Try with --recheck.
  If the problem persists please report this together with the output of "/usr/sbin/grub-probe --device-map="/boot/grub/device.map"
  --target=fs -v /boot/grub" to <bug-grub@gnu.org>

Next.

Previous.