Search Results: "xam"

16 September 2011

Raphaël Hertzog: How to triage bugs in the Debian bug tracking system

Triaging bugs is one of the easiest way to start contributing to Debian. I ll teach you the basics in this article. 1. Prerequisites All interactions with the Debian Bug Tracking System (BTS) happen through email so you need to have an email account with an address that you re willing to make public. All the mail that you send to the BTS will be archived and publicly available through its web-interface. This also means that you should have some spam filters in place because it will inevitably be harvested by spammers. :-( To ensure that this email address is consistently used by the various tools that we re going to use, it s a good idea to put this email address in the DEBEMAIL environment variable. You can also specify your full name in DEBFULLNAME (in case you don t want to use the name associated with your Unix account). You usually do this by modifying ~/.bashrc (if you use bash as login shell):
export DEBEMAIL="hertzog@debian.org"
export DEBFULLNAME="Rapha l Hertzog"
You should also install the devscripts package, it provides the bts command that we re going to use. 2. Find a package or a team with too many bugs You can literally pick any popular software that s in Debian, they almost always get more bug reports than the maintainers can handle. Instead of picking a package, you can also select a packaging team and concentrate your efforts on the set of packages managed by the team. In any case, it s important to receive the bug traffic for the packages that you re going to work on. If you went for a specific package, you should subscribe to the package via the Package Tracking System (there s a subscribe box on the bottom left corner once you selected the source package of interest). If you decided to help a team, there s usually a dedicated mailing list receiving all bug traffic. You can browse a list of packages with the most bugs if you have troubles finding a package to work on. A stack of bug reports to triage 3. Triage bugs! Bug triaging is all about making sure that bugs are correctly classified so that when a developer looks at the bug list, he can quickly find bugs with all the information required to be able to fix them! 3.1 Adding information to bug Adding supplementary information is easily done just by sending a mail to XXXX@bugs.debian.org (replace XXXX with the bug number). But often you want to reply to a message in the bug history, in that case bts --mbox show XXXX is for you. It will grab the corresponding mailbox and open a mailer (mutt by default) on it. Now you can directly reply in your favorite mailer. 3.2 Classifying bugs The Debian BTS uses tags (click the link and read the doc!) to classify bugs. bts tag XXXX + foo will add the foo tag (replace the + with a to remove a tag). If you want to explain why you re adding a tag, you should instead reply in the bug log as explained above, put control@bugs.debian.org in Bcc (Blind Carbon Copy) and start the body of your message with your tag command:
tag XXXX + foo
thanks
But what tag should you add? When a bug is submitted, you should try to reproduce the bug. If you can reproduce it, then tag the bug confirmed (example in #641710). If you can t, you should request more information (ex: a sample document triggering the bug, a configuration file, the output of some relevant command, etc.) until you can reproduce it or conclude that it was a user mistake. When you request supplementary information due to this, you should tag the bug unreproducible moreinfo (example in #526774). moreinfo should be later dropped when the requested information are provided, and unreproducible should be dropped if those information were enough to actually help reproduce the bug (example in #526774). During that initial evaluation, it s also worth differentiating packaging bugs (which are specific to Debian) from upstream bugs (which are relevant also for non-Debian users). The latter should be tagged upstream (and forwarded upstream if the bug is reproducible or contains enough information for the upstream developers, example in #635112). If you saw a (viable) patch in the bug log, the bug should be tagged patch . This is usually done by the patch submitter but sometimes it s forgotten (example in #632460). Take care though to not reinstate the patch tag if it was initially set but then dropped by the package maintainer after a review of the patch. If the title of the bug report is not descriptive enough, you can change it with a retitle XXXX new-title command (example in #170850). You can also change the severity of the bug report depending on the impact of the problem (with a command severity XXXX new-severity , what a surprise!). Request for new features are wishlist , most documentation problems are minor . On the other side of the scale, you can use important for bugs that are very annoying but that should not block a release. serious , grave and critical are used for release critical bugs, check the official definitions of the severities (examples in 502738 or #506498). 3.3 Closing non-bugs and bugs that are already fixed If your analysis of the bug report is that it s not really a bug but a user mistake, then you should close it by sending a mail to XXXX-done@bugs.debian.org with some explanations of the user s mistake so that he can get past his problem (example in #592853). If the problem was a real bug, but one that is apparently already fixed, you should try to quickly find the version that fixed the bug. If you can t find it in the changelog (there s a link to it in the PTS, or you can use /usr/share/doc/package/changelog.Debian.gz), you ll make the safe assumption that the upstream version you re currently using is the first one where this is fixed. Then you send a mail to XXXX-done@bugs.debian.org but you start your mail with Version: version-that-fixed-the-bug and continue with a small explanation of why you believe the bug to be fixed by this version (example in #122948). 3.4 Reassigning misfiled bug reports Bug reports are not always filed against the proper package. Users file bugs against applications where they experience the bugs, but the real bug might be in an underlying library or application. When that happens, you should use the reassign XXXX correct-package version command to get it filed against the correct package. The version parameter is optional but should be provided if possible, it should be the oldest version that we know to have the problem (example in #626232). 3.5 Forwarding bugs Forwarding bugs means opening bug reports in the upstream bug tracker for issues that have been reported in Debian but that applies to the upstream (unmodified) source code. Be sure to include all the relevant information and a link to the corresponding Debian bug. Depending on the upstream bug tracker, you might have to open an account to be able to file new bug reports. On the Debian side, you must record that a bug has been forwarded with bts forwarded XXXX upstream-bug-url . upstream-bug-url is the URL corresponding to the upstream bug report you created (ex: http://projects.ciarang.com/p/feed2omb/issues/21/ recorded in #609345 ). If the upstream authors fix the bug you reported, you can tag the Debian bug with fixed-upstream so that it s easier to find bugs to close when the next upstream release comes out (example in #637275). 3.6 Updating version information The Debian BTS uses version tracking to know which package versions are affected by a given bug. It s particularly important to have correct version information for release critical bugs since it might affect the migration of packages to testing. You can learn more on this topic here: http://wiki.debian.org/HowtoUseBTS. 4. More advice Colin Watson wrote a constructive rant explaining some mistakes that bug triagers are often doing. While it refers mainly to Ubuntu s launchpad, the advice apply equally as well to Debian. Check it out to become a better bug triager! Note that you can refer to this article with this shorter URL: http://raphaelhertzog.com/go/bugtriaging/

Do you want to read more tutorials like this one? Click here to subscribe to my free newsletter, you can opt to receive future articles by email.

One comment Liked this article? Click here. My blog is Flattr-enabled.

John Goerzen: Mexico Part 5: Food, Restaurants, and Dueling Karaoke Guys

The fifth in a series; see also parts 1, 2, 3, and 4. One piece of advice we got in Mexico went like this: the nicer a place looks, the worse the food and prices will be. Roadside taco stands will be great, and nice-looking restaurants not so much. That seemed to be accurate. We only tried one real nice-looking restaurant and it was very good (though pricy), but it may have been sort of an exception. But perhaps the most interesting bit about eating in Mexico wasn t the food. It s the adventure. We ate one day at Guadalajara s San Juan de Dios market. In that huge labyrinth somewhere was a set of restaurants. They d tend to have a small cooking area, usually just open, and a few tables. We chose one. And at this point, I have to take brief detour and explain something. There are a lot of people in Mexico that do things for tips, and quite often without being asked. Some other examples might be washing a car s windshield at a stoplight. So anyhow, we had ordered our food, and before long, a guy wanders down the aisle and plonks down a boombox. And turns it on. And then he pulled out a microphone, which we quite soon realized was connected to the boombox. (I guess making it more of a karaoke box.) Anyhow, he started singing a song decently and seemed to be enjoying it. About 45 seconds into it, a competing boombox man plonked down a competing boombox 25 feet away, turned it on, and yes, you guessed it pulled out a microphone and started singing a different song. Worse than the first person but louder. Eventually the boombox people left and our lunchtime conversation could resume. But pretty soon a drum guy showed up. He had a bunch of drums on a strap so he could just walk around and play them. He apparently decided that an excellent place to play them would be directly behind my head. I did not entirely agree with his decision, but hey, it beat the competing karaoke guys. Eventually the drum guy left, and somehow between the time I looked down to get out money to pay our bill and the time I had it counted out, a clown had shown up and made several balloon animals for our boys. I tipped him, we paid, and then headed on. You might think from this story that this would be an annoying series of events. And honestly, if it had happened in a big mall in the USA, it would probably have been both annoying and creepy. But really I enjoyed it. The fact that dueling karaoke happened, despite sounding really awful, was pretty funny and really seeing this whole parade of people was interesting too. It made American restaurants seem a little boring. You always know what s going to happen here (and if something surprising does happen, the place probably gets a bad review on Yelp.) Interesting things sometimes happen at mealtimes in Mexico and I like it that way. I had a torta ahogada (drowned sandwich) at that restaurant. And at this point, another brief aside. I m the kind of person that can go to an average American restaurant, see items on the menu helpfully indicated as spicy, order one, and genuinely wonder if other people would find them spicy, because I either don t notice spiciness at all, or maybe notice a tiny bit if I concentrate really hard. Others, meanwhile, might take a bite and lunge for the water. Having said that, I know people that lived in Thailand for awhile and I have nowhere near their tolerance for spiciness. So, having been in Mexico a whole 24 hours or so, I decided not to follow Jonathan s wise lead in ordering a torta with the spicy sauce on the side. I figured I hadn t had anything spicy yet, so maybe this was would be nice and mild for me. Via Jonathan s translation, I ordered it with the spicy sauce. I believe the phrase I heard him use was con chile . The waitress looked at me, gave me an amused the American is ordering it con chile? Hahaha . sort of smile, and went off. Pretty soon our food arrived. (The food always seems to arrive pretty soon in Mexico, by the way.) Oliver was having a bit of a culture shock that day, and mostly refusing to eat (once hunger got the best of him later, he really enjoyed Mexican food.) But the rest of us dug in, including me. I enjoyed my torta. It was spicy, but not too bad. I took some big bites (it was, after all, a thick sandwich) and was really enjoying it. For about a minute. Slowest-acting spiciness I ve had in awhile. Then it hit me. Spiciness, and lots of it. I took a big gulp of my horchata (a creamy sweet rice drink that I found at many restaurants). That helped. A little. I really liked the torta and ate it, but it wouldn t surprise me if the waitress noticed how extremely quickly a drank my horchata Another interesting experience was in Guanajuato. It was raining as we walked towards the Guanajuato market. Their market was large and similar in concept to the Guadalajara one, though a lot smaller. The restaurants were all in a row, in a side of the building that was open to the outside. Most were on the ground level but it looked like a restaurant or two were upstairs. As we approached, all of a sudden people were yelling at us. First it was a guy on the second story, then pretty soon people at the restaurants on the first floor did so as well. They were yelling rapidly in Spanish, waving their menus around in the air. I m imagining they were naming foods they sold or reasons to eat there, but I don t know enough Spanish to know. As we walked down the long row of restaurants, the ones we left behind would quiet down in disgust and other hopeful restaurant owners would take up the yelling and waving cause. I imagine if we did some time-lapse videography and walked up and down that row, we could produce an effect not unlike the sound of a dot-matrix printer going back and forth on the page. Anyhow, we selected one of the quieter restaurants pretty much random. The others then quieted down until another person chanced to walk past at which point it would get loud again. The lunch there was good but I think I mainly will remember it for the selection process! On our way into Guanajuato, we stopped at a wonderful roadside taco place. In typical fashion, they had a large vertical pork thing (I don t know the proper word for it) from which they would carve off meat on the spot anytime someone ordered something with pastor. We found a table. And we ordered a few tacos and such. They were usually a few pesos each (working out to less than a dollar), small round things on a soft tortilla, with meat, cilantro, and onion on top. And typically delicious. They had very little in common with an American taco . We d often order a few, and if we wanted more, just order more. They were made quickly enough for that. Tacos were very similar from one restaurant to the next. My favorite flavors were pastor (pork), chorizo (sausage), and bistec (beef steak). A restaurant in Guadalajara sadly I ve forgotten its name, since we kept calling it the potato place had what I might call a Mexican version of the loaded baked potato, with a meat, queso (cheese), a delicious sauce with a flavor unlike anything I d had before, and some garnish. But really my favorite thing from that restaurant was their amazing juices. I am not much of a juice drinker normally, but in Mexico I went for them whenever they were offered. What passes as fruit juice in the USA has about as much resemblance to a real Mexican fruit juice as Taco Bell has to a real Mexican taco stand. (Very little, in case that wasn t crystal clear.) That particular restaurant offered three types of juices, which were, if I m remembering right, aguas, frescas, and jugos. I has a jugo verde (green juice) on the first visit there. It was good, but the one I can still remember was called, I think, the fresa fresca (fresh strawberry juice). And it was incredible. I m not sure how to describe it, other than real. One observation before I end. It seemed a common thread at some Mexican roadside taco stands to not have soap in their restrooms. Instead there would be a plastic cup holding I kid you not powder-form Tide laundry detergent. It was amusing anyhow. My hands left those places extremely soft and smelling like laundry. One of the last restaurants we visited on our trip was in Ajijic, near the Chapala lake. It was actually right on the lake and served seafood. This was the only restaurant with prices as high as I d be used to in the United States. I ordered a stew served in a stone bowl. It came out sizzling, and since the very thick stone bowl retains heat well, it kept sizzling the entire time I was eating. It was excellent as usual. Coming up in part 6: some thoughts on returning to the United States, our decision to visit, communication, and tips for anyone else considering a first visit to Mexico.

Peter Eisentraut: ccache and clang, part 2

There's more funny business when using ccache in combination with clang. Last time I suggested that you use the invocation
./configure CC='ccache clang -Qunused-arguments -fcolor-diagnostics'
to get rid of the "argument unused during compilation" warnings.But you still might get loads of warnings that you wouldn't normally get without ccache, such as this example (from the PostgreSQL source code):

extension.c:382:35: warning: equality comparison with extraneous parentheses [-Wparentheses]
if (( (((control->directory)[0]) == '/') ))
~~~~~~~~~~~~~~~~~~~~~~~~~~^~~~~~
extension.c:382:35: note: use '=' to turn this equality comparison into an assignment
(This is the opposite of the warning that tells you to put two pairs of parentheses around an assignment used as a truth value.)Or:

path.c:727:7: warning: explicitly assigning a variable of type 'char *' to itself [-Wself-assign]
path = (path);
~~~~ ^ ~~~~
The problem is, these come from macro expansions, so wouldn't normally see them, because (I guess) the compiler driver is smart enough not to warn about such things when they come from macro expansions.The way ccache works is approximately
  1. preprocess the input file
  2. look for it in the cache
  3. if not found, compile the preprocessed file
What would be better in this situation is
  1. preprocess the input file
  2. look for it in the cache
  3. if not found, compile the original file
And indeed you can turn on that second behavior by setting the obscure environment variable CCACHE_CPP2 (as in, run cpp twice):
export CCACHE_CPP2=yes
Then all these extra warnings disappear.(The ccache man page is worth a read. There are a few interesting settings to play with.)I'm currently playing around with a shell script ccache-clang that looks like this:
CCACHE_CPP2=yes exec ccache clang -Qunused-arguments  test -t 2 && echo -fcolor-diagnostics  "$@"

15 September 2011

Dirk Eddelbuettel: littler 0.1.4

Matthias Klose, the tireless force behind the Debian / Ubuntu gcc, python, and what have you packages, sent me a minimal patch to let littler build when the ld linker uses the --as-needed option (as Ubuntu builds now do): all it took was a little reordering of arguments. With that, I did a little cleanup as it has been a while since version 0.1.3. The brief (upstream) ChangeLog is as follows:
2011-09-15  Dirk Eddelbuettel  <edd>
        * configure.in: Mark as release 0.1.4
        * Makefile.am: Applied patch by Mathias Klose to prevent FTBFS with
          'ld --as-needed', cf LP bug 770980.
        * littler.c: A few small tweaks suggested by 'gcc -Wall'
        * examples/install2.r: Added a second R package installer example
        * examples/update.r: Switch to '/usr/bin/r -t' as shebang line
        * examples/fsizes.r: Dito
        * littler.c: Update copyrights to 2011
        * README: Idem
littler provides r (pronounced littler), a shebang / scripting / quick eval / pipelining front-end to the the R language and data analysis environment. As usual, our code is available via our svn archive or from tarballs off my littler page and the local directory here. A fresh package is in Debian's incoming queue and will hit mirrors shortly.

14 September 2011

Thorsten Glaser: MirBSD online manpages major facelift

Our MirBSD online manual pages and other assorted BSD documentation (except of course the merely copied ncurses, lynx etc. documentation and the texinfo generated HTML pages) has just gained a major facelift. They look alike in lynx(1) best web browser ever and less(1)/man(1) now, and remind of a DEC VT420 on a CSS capable Buntbrause. Thanks to our contributor XTaran for aid with the colour scheme! Since these are generated from catmanpages, heuristics are used for things like where should bold/underline begin/end (since nroff(1) is not always the brightest but working on that), and hyperlinks can only be generated for other manpage references (whose targets may or may not exist, for example if they aren t part of MirOS base/XFree86 ). But on the other hand, Valid XHTML/1.1 and CSS speaks for itself

13 September 2011

Vincent Sanders: Electricity is really just organized lightning.

I have recently been working on a project that requires a 12V supply. Ordinarily this is no problem my selection of bench supplies are generally more than a match for anything I throw at them.

My TS3022S Bench SupplyThis project however needed a little more "oomph" than usual, specifically 200W more. Funnily enough a precision variable output bench supply capable of supplying 20A are rare and *very* expensive beasties.

So we turn to a fixed output supply, after all I will want to run my project without hogging my bench supplies anyway. These can be bought from various electronics suppliers like Farnell from around the 50 mark and Chinese imports from Ebay sellers start around the 20 mark.

All very well and good but that is money I was not planning on spending and possibly a month of waiting for an already badly delayed project. So I decided to Convert an old ATX PSU into a 12V source. This is not a new idea and a quick search revealed many suitable guides online. I had a quick skim, decided I did understand the general idea and ploughed ahead.

Wikipedia has a very useful page on the ATX standard complete with pinout diagrams and colour codes. The pile of grey box ATX supplies available on my shelf was examined and one was helpfully labelled with a sticker proclaiming 22A@12V and we had a winner.

Opening the case of the donor 450W CIT branded supply revealed a mostly empty enclosure with the usual basic switching arrangement. I removed most of the wire loom aside from two of each output voltage (3.3V, 5V and 12V i figured the other voltages might be useful in future) and three commons, the 3.3V and 5V sense lines were also kept. Each of these pairs were cut to length and leads were wired to 4mm sockets.

The "PWR_EN" line was wired via a toggle switch to ground so the output can be switched on and off easily. The 5V standby and a 5V output line were wired to a green/red bi-colour LED (via 270 current limit resistors) to give indication that mains is present and when the output is on.

Holes were drilled for four 4mm sockets an indicator LED and a switch. The connectors and switches were all mounted in the PSU casework. I plugged it all in, put an 8.2 load resistor on the 5V line with an ammeter in line and a voltmeter across the 12V rail.

ATX bench power supply I turned the mains on and the LED lit up green (5V standby worked) and when I flicked the output switch the LED turned orange, the 12V line went to 12V and the expected 0.6A flowed through the load resistor.

Basically, Success!

I have since loaded the supply up to the 200W operating load and nothing unexpected has happened so I am happy. Seems converting an ATX PSU is a perfectly good way of getting a 200W 12V supply and I can recommend it for anyone as cheap as me willing to put an hour or so into such a project.

Christian Perrier: 10 years being Debian Developer - part 4: NM process

So, this story begins in January 2001, when I applied in the Debian New Maintainer Process. I wanted to maintain Geneweb, which I was using to publish my genealogy research results. And I wanted to keep it up-to-date while upstream was doing a quite fast development. Moreover, I quickly noticed that Geneweb had big trouble in respecting the way data is organized on a Debian system, and respect the FHS. How to have weveral users able to publish their data on the same server without compromizing the overall system security, etc. Upstream development didn't really care about that. Daniel de Rauglaudre is an excellent genealogist and developer but he was not interested in making Geneweb clean "the Debian way". For instance, at that time, it wasn't easy to setup a server, where genealogy databases could be published without having to manually launch a daemon in user mode at each reboot. Arranging this was indeed my first contribution. I contributed a few patches to make it easier to turn Geneweb into something FHS-compliant...and I developed init scripts and an organization allowing one to have shared databases after system reboots. That was rapidly a great introduction to Debian maintainer scripts and even security-related challenges. And all this....because I needed it. Basically, in 2001, the geneweb package adopted the organization it still has in Debian and Ubuntu, 10 years later: While doing so, I was going through the New Maintainer Process. The Debian developer who had signed my key was Sam Tardieu, of of those longstanding "Freenix" dudes I was sometimes hanging around. I don't remember who did write my advocacy. Michael Mattice was my first Application Manager. Interestingly, here are the three first questions he asked my as part of the Policy and Procedures check : Mike actually asked the questions on February 17th and I probably answered immediately. Unfortunately it seems that I lost my answers. Maybe they are in some archive somewhere. Would be interesting to see how I ended giving an answer about the TeX exception.:-) Immediately, Mike moved to the Tasks and Skills step and checked my geneweb and lifelines packages (I already prepared a package for that other genealogy software). From my records, he found a few lintian warnings, which I probably made my best to fix, then later on, on March 12th, he answered me that thigns were OK and he was marking the T&S step as passed...handing things over to the NM database, asking me what username I wanted on debian.org (obviously, you know what I answered to this!). Then nothing happened..:-) I was not that impatient, but finally, around June 27th, I politely mailed NM Frontdesk (I guess) to get news...and I got a very quick answer by Martin Michlmayr. Martin was indeed worried about the situation (he told me I was on his radar....fun as, many years later, as many DDs, Martin probably went on mine because of pending localization work..:-)) Finally, Martin decided he was not entirely happy with the (maybe too short) processing for P&P and proposed me (very politely, you know how Martin is!) to do it again. So, some more questions...:-) Here, I have the answers. Really fun ro read. Hang on, pure bubulle style, very verbose! What a bunch of questions..:-). Reading my answers ten years after, I see that some answers are somehow naive but, after all, they're not so bad. I really remember spending hours in writing them (my English was somehow more shaky at that time) The last question was: "Please tell me about about yourself and what you intend to do for Debian". Here, Martin opened a big can of worms..:-) So, you'll learn about this in the next episode..:-)
Rapha&#235;l Hertzog: Understand dpkg and don t get stuck with a maintainer script failure

Continuing my series of articles on dpkg s errors, this time I ll cover a pretty common one which has several variations:
Setting up acpid (1:2.0.12-1) ...
rm: cannot remove  /etc/rc1.d/K20acpid': No such file or directory
dpkg: error processing acpid (--configure):
 subprocess installed post-installation script returned error exit status 1
Errors were encountered while processing:
 acpid
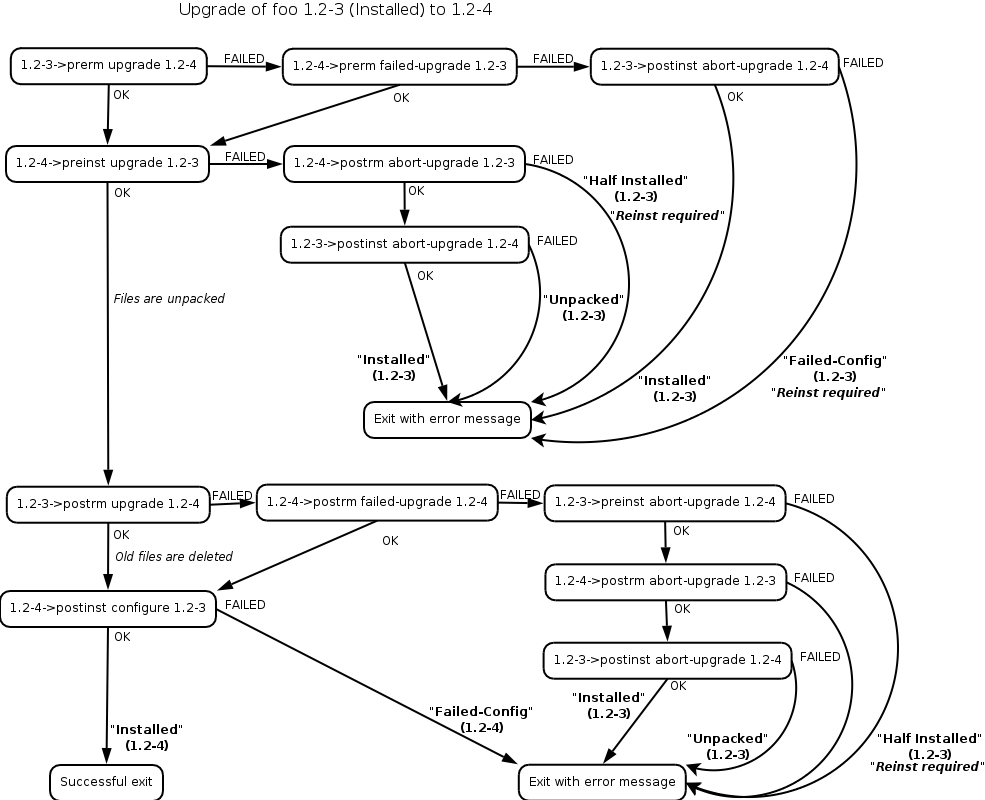
Even if dpkg is failing and outputting the error message, the real problem is not in dpkg but in the installed package (acpid in the example above). As we already learned, a package contains not only files but also maintainer scripts that are executed at various points of the installation process (see some useful graphics to understand how they are called, thanks to Margarita Manterola).

Maintainer scripts in a package upgrade

In the introductory example it was acpid s post-installation script that failed, and dpkg is only forwarding that failure back to the caller. The maintainer scripts are stored in /var/lib/dpkg/info/. You can thus inspect them and even modify them if you hit a bug and want to work around it (do this only if you understand what you do!). One common modification is to add set -x at the start of the script and to retry the failing operation. That way you can see what s executed exactly. Here s what the output could look like after the addition of set -x to /var/lib/dpkg/info/acpid.postinst:
$ sudo dpkg --configure acpid
Setting up acpid (1:2.0.12-1) ...
+ dpkg --compare-versions 1:2.0.11-1 lt-nl 1.0.10-3
+ dpkg --compare-versions 1:2.0.11-1 lt-nl 1.0.6-16
+ dpkg --compare-versions 1:2.0.11-1 lt 1.0.6-6
+ rm /etc/rc1.d/K20acpid
rm: cannot remove  /etc/rc1.d/K20acpid': No such file or directory
dpkg: error processing acpid (--configure):
 subprocess installed post-installation script returned error exit status 1
Errors were encountered while processing:
 acpid
This output helps you locate the command that is actually failing. Here s it s relatively easy since we have an error message from rm . And the fix is trivial too, we replace rm with rm -f so that it doesn t fail when the file doesn t exist (this is a fake bug I made up for this article I just added a failing rm call but it s inspired by real bugs I experienced). Maintainer scripts are supposed to be idempotent: we should be able to execute them several times in a row without bad consequences. It happens from time to time that the maintainer gets this wrong on the first try it works, so he uploads his package and we discover the problem only later once someone ended up executing the same code twice for some reason.

Follow me on Identi.ca, Twitter, Facebook and Google+. Or subscribe to this blog by RSS or by email.

7 comments Liked this article? Click here. My blog is Flattr-enabled.

12 September 2011

Dirk Eddelbuettel: RQuantLib 0.3.8

A bug-fix release RQuantLib 0.3.8 is now on CRAN and in Debian. RQuantLib combines (some of) the quantitative analytics of QuantLib with the R statistical computing environment and language. Thanks to Helmut Heiming who noticed a side-effec t from the DiscountCurve functions: the Quantlib-global variable determining the evaluation date was overriden; this could affect subsequent curve-related pricers. This is now fixed, and we added a new function setEvaluationDate to set this date from R too. We added this call in some of the examples in the manual pages. Otherwise two very minor build system tweaks were added, but no other changes were made Thanks to CRANberries, there is also a diff to the previous release 0.3.7. Full changelog details, examples and more details about this package are at my RQuantLib page.

John Goerzen: Mexico Part 2: Lodging & Family

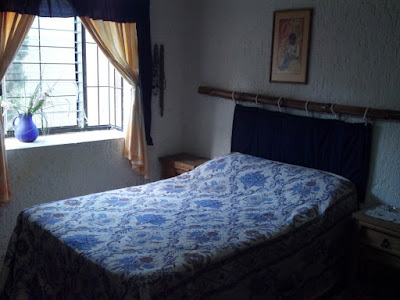
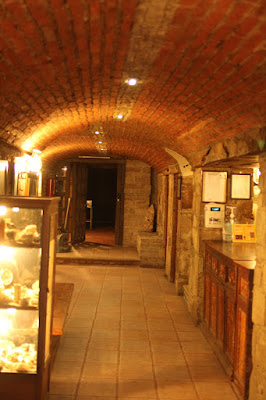
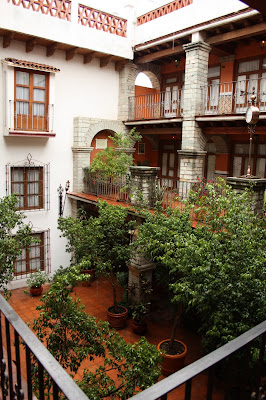
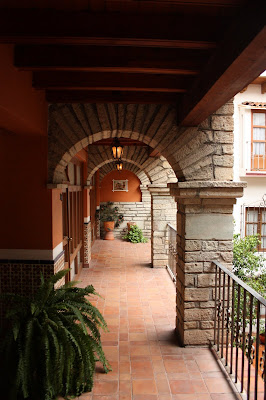
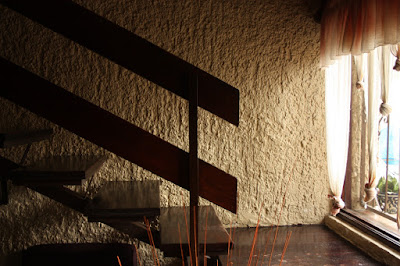
As I wrote in part 1, my family and I were in Mexico recently. Today I ll write about the places we stayed. We spent most of the time in a room we rented in a private home in Guadalajara. My friend Jonathan had found it for us, and it was not too far from his home. The owner was a grandmother, and across the courtyard was more family, including a granddaughter close in age to our boys. They enjoyed playing together. It was really a perfect arrangement for us. There s no better way to be a part of local life when traveling than to stay in someone s house. Here s our bedroom: Notice the glass slats in the window it s a nifty, though not airtight, alternative to our regular windows. More on that later. More of the inside: We had a bit of a language barrier while in Mexico, though never anything significant. My Spanish vocabulary started with almost nothing and I reached maybe a few dozen words by the time we left. Terah knew some Spanish from high school and college, and my friend was fluent. Our hostess also knew a little English. But we all communicated well enough. Terah or Jonathan would help translate when needed. As I d seen before, the children would say things to each other, but never seemed to be bothered that their playmates didn t understand what was being said. They just had a great time anyhow. On Sunday afternoon, when we came back from our activities, there was a buzz of activity. Children everywhere outside, running and playing. Adults too, chatting. We didn t know exactly what was happening, but sent Jacob and Oliver out to play anyhow (which they were eager to do). The yard was enclosed by a wall, so children could pretty much run around without lots of supervision. Eventually they were invited to have some birthday cake (ah ha!) it was one of the children s birthday. Jacob and Oliver actually were served the first two pieces of cake (as the amigos ). Everyone seemed so friendly, warm, and welcoming. Each morning started with breakfast at the house, followed by a scene like this: That s Jacob and Oliver, looking to see if Jonathan had arrived for the day yet. I often noticed in Mexico that I was unsure if I was inside or outside. Here in Kansas, we can have a string of summer days that each exceed 110F (44C) or a few weeks in winter that never get above 15F (-9C), even in daytime. And then we have some pleasant days like right now, too or rain blowing sideways at 60MPH. In general, we spend a lot of effort keeping the outside, well, out. It is quite clear that this isn t a problem in the Guadalajara area. Some restaurants could have been described as buildings with large, open windows so you feel a lot of breeze while inside. Or perhaps as a simple shade roof with a few supports on the edges, so you re never really inside at all (sort of like going under a small shade tent outdoors). To the extent that windows could close, many of them couldn t be made airtight. It was clear that in that area, people spend more energy finding ways to invite the outdoors in rather than to keep it out, thanks to the year-round moderate climate. Perhaps the best example of this surprised me one evening. We were arriving in Guanajuato, an old silver mining town in the mountains, and were going to spend the night at Hotel Socav n, which had been recommended to us by a local friend of Jonathan s. From the street, the hotel looked tiny. But walk in, and you get in this old-looking (and feeling) entry tunnel: That s the front desk, apparently cut out of it there on the right. We asked to see some of the rooms before buying apparently a normal request around there. The innkeeper agreed, and gave us keys and directions to find them on the third floor. It included going up 2 flights of stairs, passing through a courtyard, and going up another flight. It was after dark, and the hotel was dimly lit something I was fine with. I thought we were stepping out into a beautiful atrium with some potted plants in the center of the building something fairly common in some nicer hotels. Until I felt rain on my head. Then I realized that the courtyard, which began two floors up from the street, was open to the sky. Beautiful! Here was the view from out room door: And down the hall : After getting home, a Google happened to turn up some reviews of this hotel. I was so annoyed at what some people wrote! One person gave them only 3 stars because they didn t have air conditioning, had poor water pressure, and lots of steps . Someone else complained of the dark entry tunnel something I couldn t help but smiling about the moment I entered. My review, which should hopefully get posted soon, is certainly different. I gave them 5 stars, because if I wanted a Super 8 with generic fluorescent lighting and the same layout as thousands of other hotels, I would have gone to Nebraska instead of Mexico. Most homes and local hotels in the region don t have air conditioning because they don t need it, and that s just how water pressure is in Mexico (due to needing to pump it from municipal supplies to private storage tanks overhead). And who doesn t appreciate entering a hotel through a brick tunnel? Ah, sigh This should give you some idea of the kind of travel we like: part of the point of traveling is enjoying the differences from home, and I think it is a huge mistake to be annoyed at everything that is different. Enjoy the differences! Finally, here s a photo of the staircase in the home we stayed in, which I thought was fascinating:

11 September 2011

Andrea Veri: A few other additions to my Mutt and Desktop setup!

A few days ago I blogged about my main computer s configuration files and desktop s appearance and today I managed to add a few little tweaks to those, they are: Curious to know how you can easily integrate your Google s contacts into Mutt? Well, you should be able to achieve that within a few minutes after reading this small HowTo: 1. Download and install goobook as explained here. 2. Setup a .goobookrc file into your Home directory. It should look like this:
machine google.com
 login example@gmail.com
 password yourpassword
3. Add the relevant configuration bits into your /etc/Muttrc file:
set query_command="goobook query '%s'"
bind editor <Tab> complete-query
macro index,pager a "<pipe-message>goobook add<return>" "Add sender's address to your Google contacts"
4. Your configuration should be good to go now, so here s a few examples on goobook s usage within Mutt: We can now move on on customizing your Login Screen running GDM3. Let s begin with a screenshoot: I definitely love it, it s clear and clean and most of all it has everything I need, no extra toolbars or menus. If you agree with me, open up the /etc/gdm3/greeter.gconf-defaults file and do the needed changes. This is how your greeter.gconf-defaults file should look like:
/desktop/gnome/background/picture_filename      /path/to/your/dusty-bg/file # dusty's background can be downloaded here.
/desktop/gnome/interface/gtk_theme              Darklooks # this is my main theme, feel free to adapt that to your needs.
/apps/gdm/simple-greeter/logo_icon_name         debian-swirl # this is the default on Debian's systems.
/desktop/gnome/sound/event_sounds               false # I don't like hearing any sound when when I am prompted to insert my user's details on the Login Screen.
/apps/gdm/simple-greeter/disable_user_list      true # users list will be disabled, you won't be able to select your username from a list but you'll have to insert that yourself.
/apps/metacity/general/compositing_manager      false # default, no need to change this.
/apps/gnome-power-manager/ui/icon_policy        never # default, no need to change this.
We are close to the end but we are missing an important detail: how can you safely remove bottom s toolbar and menus for a clearer and cleaner Login Screen? Open up the /var/lib/gdm3/.gconf.mandatory/%gconf-tree.xml file, search for the <dir name= general > section and apply the following change:
- <entry name="compositing_manager" mtime="1315580582" type="bool" value="false"/>
+ <entry name="compositing_manager" mtime="1315580582" type="bool" value="true"/>
But what if you prefer keeping the toolbar as it is, but you definitely don t like seeing the Accessibility icon appearing on your Login Screen? On the same file as above, search for the <dir name= accessibility > section and modify the following string as it follows:
- <entry name="enable" mtime="1315580582" type="bool" value="true"/>
+ <entry name="enable" mtime="1315580582" type="bool" value="false"/>
See you on my next blog post and don t forget to have a look at my GitHub s repository! Oh and follow me on Twitter!

9 September 2011

Rapha&#235;l Hertzog: People behind Debian: Enrico Zini, member of the New Maintainer Frontdesk

Enrico ZiniEven though Enrico is not smiling on this picture, he s one of the friendliest Debian person that I know. I always enjoy his presentations because he can t refrain from inserting jokes or other funny tricks. :-) That said he s serious too, there s lots of good stuff that he has developed over the years (starting with Debtags) and he has put a lot of effort in reforming the New Maintainer process. Read on to learn more about his various projects. Raphael: Who are you? Enrico: Hi, I m Enrico Zini, a DD from Italy. I m 35 and I work as a freelance Free Software developer. One of my historical roles in Debian is taking care of Debtags, but that is not all I do: my paid work led me to write and maintain some weather forecast related software in Debian, and recently I gained a Front Desk hat, and then a DAM hat. Raphael: How did you start contributing to Debian? Enrico: It was 2001, I was at uni, I was using Debian. At some point I wanted to learn packaging so I read through the whole Policy from top to bottom. Then I thought: why package only for myself? . There were many DDs at my uni, and it only seemed natural to me to join Debian as well. Evidently this was also natural for Zack [Note from editor: Stefano Zacchiroli], who had become DD 6 months earlier and didn t hesitate to advocate me. I found the Policy and the Developer s Reference to be very interesting things to read, and I welcomed my AM s questions as an excuse to learn more. I completely understand those people who have fun trying to answer all the questions in the NM templates while they wait for an AM. With my super DAM powers I can see that my AM report was submitted on October 16, 2001 by my AM Martin Michlmayr, and that James Troup created my account 9 days later, on October 25. Raphael: You have a special interest in the New Maintainer (NM) Process since you are a Debian Account Manager (DAM) and a member of the NM Frontdesk. Thanks to your work the process is much less academic/bureaucratic than it used to be. Can you remember us the main changes? Enrico: One of the first things I noticed when I become a Front Desk member is that there was a tendency to advocate people too early, thinking by the time they ll get an AM, they ll know enough . Unfortunately, this didn t always work, and once the real NM process started it would turn into a very long and demotivating experience both for the applicant and for the AM. So we tried raising the bar on advocacies, and that seems to have helped a lot. If people join NM when they are ready, it means that NM is quick and painless both for them and their AMs, who are therefore able to process more applicants. We also did a rather radical cleanup of the NM templates , which are a repository of questions that Application Managers can ask to their applicants. We realized that AMs were just sending the whole templates to their applicants, so we moved all non-essential questions to separate files, to drastically reduce the amounts of questions that are asked by default. Other improvements in the NM process came from other parts of Debian: nowadays there are lots of ways to learn and gradually gain experience and reputation inside the project before joining NM, which means that we get many candidates who we can process quickly. For example, packages can now be uploaded via sponsors, and the Mentors project helps new contributors to find sponsors and get their first packages reviewed. Then one can now become Debian Maintainer and take full responsibility of their own packages, gaining experience and reputation. The idea of working in teams also helped: big teams like the Perl, Python, KDE, Ocaml, Haskell teams (and many more) are excellent entry points for people who have something to package. But Debian is not just for packagers, and one could join teams like the Website team, the Press and Publicity team, the Events and Merchandise team or their local translation team. Becoming DDs the non-uploading way is not just for non-technical people: one could enjoy programming but not packaging. An interesting way to get involved in that way is to help writing or maintaining some of the many Debian services. Note that I m not suggesting this as a way to learn how to program, but as a way to get involved in Debian by writing code. Finally, we started to appreciate the importance of having people activities in Debian explicitly visible, which means that the more obviously good work one has done in Debian, the less questions we need to ask. Jan Dittberner s DDPortfolio is an excellent resource for AMs and Front Desk, and I m maintaining a service called minechangelogs that for people who have done lots of work in Debian is able to fully replace the Tasks&Skills parts of the NM process. Raphael: What are your plans for Debian Wheezy? Enrico: For Wheezy I hope to be able to streamline and simplify Debtags a bit more. At Debconf11 I had a conversation with FTP-masters on how to make some tags more official, and I now have to work a bit more on that. I d also like to considerably downsize the codebase behind the debtags package, now that its job is quite clear and I don t need to experiment with fancy features the way I did in the past. I have to say that I enjoy programming more than I enjoy packaging, so most of my plans in Debian are not tied to releases. For example, I d like to finish and deploy the new NM website codebase soon: it would mean to have a codebase that s much easier to maintain, and in which it s much easier to implement new features. I d also like to design a way to allow maintainers to review the tag submission to their own packages instead of having to wait for me or David Paleino to do a regular review of all the submissions. Finally, I d like to promote the usage of apt-xapian-index in more cutting-edge packaging applications. And to design a way to maintain up to date popcon information in one s local index. And improve and promote those services that I maintain, and I tend to often have ideas for new ones. Raphael: If you could spend all your time on Debian, what would you work on? Enrico: If I could spend all my time on Debian, I would do a lot of software development: I love doing software development, but most of my development energy is spent on my paid work. I guess I would start my all your time in Debian by taking better care of the things that I m already doing, and by promoting them better so that I wouldn t end up being the only person maintaining them. After that, however, I reckon that I do have a tendency of noticing new, interesting problems in need(?) of a solution, and I guess I would end up wildly experimenting new ideas in Debian much like a victorian mad scientist. Which reminds me that I most definitely need minions! Where can I find minions? Raphael: You re the author of the Debian Community Guidelines. I have always felt that this document should be more broadly advertised. For example by integrating it in the Developer s Reference. What do you think? Enrico: The DCG was really a collection of tips to improve one s online communication, based on ideas and feedback that I collected from pestering many experienced and well-respected people for some time. Like every repository of common sense, I think it should be widely promoted but never ever turned into law. It wouldn t be a bad idea to mention it in the Developer s Reference, or to package it as a separate file in the developers-reference package. The reasons I haven t actively been pushing for that to happen are two: there isn t much in the DCG that is specific to Debian, and I don t have the resources to do a proper job maintaining it. It d be great if somebody could take over its maintenance and make it become some proper, widespread, easy-to-quote online reference document, like one of those HOWTOs that all serious people have read at some point in their lives. Raphael: What s the biggest problem of Debian? Enrico: It s sometimes hard to get feedback or help if you work on something unusual. That is partly to be expected, and partly probably due to me not having yet learnt how to get people involved in what I do. Raphael: What motivates you to continue to contribute year after year? Enrico: Debian keeps evolving, so there is always something to learn. And Debian is real, so everything I do is constantly measured against reality. What more intellectual stimulation could one possibly want? Raphael: Is there someone in Debian that you admire for their contributions? Enrico: I don t think I could reasonably list everyone I admire in Debian: pretty much in every corner of the project there is someone, sometimes not very well known, who is putting a lot of Quality in what they do. Someone who decided that X should work well in Debian or that Debian should work well for Y or that Z is something Debian people can rely on and makes sure that it is so. Those are the people who make sure Debian is and will be not just a hobby, but a base upon which I can rely for my personal and working life.
Thank you to Enrico for the time spent answering my questions. I hope you enjoyed reading his answers as I did.

Subscribe to my newsletter to get my monthly summary of the Debian/Ubuntu news and to not miss further interviews. You can also follow along on Identi.ca, Twitter and Facebook.

5 comments Liked this article? Click here. My blog is Flattr-enabled.

8 September 2011

Dirk Eddelbuettel: Faster (recursive) function calls: Another quick Rcpp case study

There was another question recently on StackOverflow that I had meant to discuss in a follow-up post here. User deltanovember asked about slow recursive functions and used the very classic Fibonacci number as an example. To recap, Fibonacci number are defined with two initial values F(0) = 0 and F(1) = 1; thereafter the Fibonacci number F(n) is defined as the sum of the two preceding numbers: F(n) = F(n-2) + F(n-1). This leads to very straightforward implementations using recursion:
## R implementation of recursive Fibonacci sequence
fibR <- function(n)  
    if (n == 0) return(0)
    if (n == 1) return(1)
    return (fibR(n - 1) + fibR(n - 2))
 
Unfortunately, this elegant implementation which remain close to the abtract formulation of the recurrence algorithm performs very poorly in R as there is noticeable overhead in function calls which becomes dominant in a recursion. This lead to the original question on StackOverflow, and the accepted answer uses a trick presented by Pat Burns in his lovely R Inferno: rewrite the solution using a computer science trick called memoization:
fibonacci <- local( 
    memo <- c(1, 1, rep(NA, 100))
    f <- function(x)  
        if(x == 0) return(0)
        if(x < 0) return(NA)
        if(x > length(memo))
        stop("'x' too big for implementation")
        if(!is.na(memo[x])) return(memo[x])
        ans <- f(x-2) + f(x-1)
        memo[x] <<- ans
        ans
     
 )
That is a fair answer, and even more was suggested with a link to a terrific analysis calling the Fibonacci recurrence the worst algorithm in the world. That is also fair, but all the basic research into better algorithms exploiting some structure of the problem to advance performance (and of course understanding) is overlooking one crucial part: algorithm analysis is essentially independent of the language. So whatever improvements we obtain by thinking really hard about a problem are then available for other implementations too. So with a tip of the hat to the old Larry Wall quote about Lazyness, Impatience and Hubris, I would like to suggest what I consider a much simpler route to much better performance: recode it in C++ using both Rcpp (for the R/C++ integration) and inline for the on-the-fly compilation, linking and loading of C++ code into R.
## inline to compile, load and link the C++ code
require(inline)
## we need a pure C/C++ function as the generated function
## will have a random identifier at the C++ level preventing
## us from direct recursive calls
incltxt <- '
  int fibonacci(const int x)  
     if (x == 0) return(0);
     if (x == 1) return(1);
     return (fibonacci(x - 1)) + fibonacci(x - 2);
   '
## now use the snippet above as well as one argument conversion
## in as well as out to provide Fibonacci numbers via C++
fibRcpp <- cxxfunction(signature(xs="int"),
                       plugin="Rcpp",
                       incl=incltxt,
                       body
                       ='
   int x = Rcpp::as<int>(xs);
   return Rcpp::wrap( fibonacci(x) );
')
This single R function call cxxfunction() takes the code embedded in the arguments to the body variable (for the core function) and the incltxt variable for the helper function we need to call. This helper function is needed for the recursion as cxxfunction() will use an randomized internal identifier for the function called from R preventing us from calling this (unknown) indentifier. But the rest of the algorithm is simple, and as beautiful as the initial recurrence. Three lines, three statements, and three cases for F(0), F(1) and the general case F(n) solved by recursive calls. This also illustrates how easy it is to get an integer from R to C++ and back: the as and wrap simply do the right thing converting to and from the SEXP types used internally by the C API of R. A performance comparison of the basic R version fibR, its byte-compiled variant fibRC and and the C++ version fibRcpp shown above is very compelling. We have added a file fibonacci.r to the large and still growing set of examples included with Rcpp, and we can just execute that script with Rscript or (as here) r from the littler package:
edd@max:~/svn/rcpp/pkg/Rcpp/inst/examples/Misc$ r fibonacci.r
Loading required package: inline
Loading required package: methods
Loading required package: compiler
        test replications elapsed relative user.self sys.self
3 fibRcpp(N)            1   0.092   1.0000      0.09     0.00
2   fibRC(N)            1  61.480 668.2609     61.47     0.00
1    fibR(N)            1  61.877 672.5761     61.83     0.02
edd@max:~/svn/rcpp/pkg/Rcpp/inst/examples/Misc$ 
So the recursion for the original argument of N=35 takes just over a minute at about 61.5 and 61.9 seconds, respectively, for the R version and its byte-compiled variant (as per the column titled elapsed). So byte-compilation essentially offers no help for the bottleneck of slow function calls. The C++ versions relying on Rcpp which created in a few lines of code and a single call to cxxfunction however takes just 92 milliseconds---or a relative gain of well over six-hundred times. That provides another nice demonstration of what Rcpp can do. Improved algorithms for well-understood problems are surely one way to accelerate solutions. But there are (many ?) times when we do not have the luxury of being able to think through to a new and improved approach. Or worse, such an approach may even introduce new errors or inaccurracies if we get it wrong on a first try. With Rcpp, we are able to the express the problem as written in its original statement: a simple recursion. The gain relative to a slow R implementation is noteworthy---and could of course be improved further if we really needed to by relying on better algorithms like memoization. But for day to day tasks, I gladly take speedups of (up to) a few hundred times thanks to Rcpp without having to do hard algorithmic work. Before closing, a quick reminder that I will be giving two classes on Rcpp in a few weeks. These will be in New York on September 24, and San Franciso on October 8, see this blog post as well as this page at Revolution Analytics (who are a co-organiser of the classes) for details and registration information.

Russell Coker: Moving from a Laptop to a Cloud Lifestyle

My Laptop History In 1998 I bought my first laptop, it was a Thinkpad 385XD, it had a PentiumMMX 233MHz CPU, 96M of RAM, and an 800*600 display. This was less RAM than I could have afforded in a desktop system and the 800*600 display didn t compare well to the 1280*1024 resolution 17 inch Trinitron monitor I had been using. Having only 1/3 the pixels is a significant loss and a 12.1 inch TFT display of that era compared very poorly with a good Trinitron monitor. In spite of this I found it a much better system to use because it was ALWAYS with me, I used it for many things that were probably better suited to a PDA (there probably aren t many people who have carried a 7.1 pound (3.2Kg) laptop to as many places as I did). But some of my best coding was done on public transport. But I didn t buy my first laptop for that purpose, I bought it because I was moving to another country and there just wasn t any other option for having a computer. In late 1999 I bought my second laptop, it was a Thinkpad 600E [1]. It had twice the CPU speed, twice the RAM, and a 1024*768 display that displayed color a lot better. Since then I had another three Thinkpads, a T21, a T43, and now a T61. One of the ways I measure a display is the number of 80*25 terminal windows that I can display at one time, my first Thinkpad could display four windows with a significant amount of overlap. My second could display four with little overlap, my third (with 1280*1024 resolution) could display four clearly and another two with overlap, and my current Thinkpad does 1680*1050 and can display four windows clearly and another five without excessive overlap. For most of the last 13 years my Thinkpads weren t that far behind what I could afford to get as a desktop system, until now. A Smart Phone as the Primary Computing Device For the past 6 months the Linux system I ve used most frequently is my Sony Ericsson Xperia X10 Android phone [2]. Most of my computer use is on my laptop, but the many short periods of time using my phone add up. This has forced some changes to the way I work. I now use IMAP instead of POP for receiving mail so I can use my phone and my laptop with the same mail spool. This is a significant benefit for my email productivity, instead of having 100 new mailing list messages waiting for me when I get home I can read them on my phone and then have maybe 1 message that can t be addressed without access to something better than a phone. My backlog of 10,000 unread mailing list messages lasted less than a month after getting an Android phone! A few years ago I got an EeePC 701 that I use for emergency net access when a server goes down. But even a 920g EeePC is more weight than I want to carry, as I need to have a mobile phone anyway there is effectively no extra mass or space used to have a phone capable of running a ssh client. My EeePC doesn t get much use nowadays. A Cheap 27 inch Monitor from Dell Dell Australia is currently selling a 27 inch monitor that does 2560*1440 (WQHD) for $899AU. Dell Australia offers a motor club discount which pretty much everyone in Australia can get as almost everyone is either a member of such a club or knows a member well enough to use their membership number for the discount. This discount reduces the price to $764.15. The availability of such a great cheap monitor has caused me to change my working habits. It doesn t make sense to have a reasonably powerful laptop used in one location for almost all the time when a desktop system with a much better monitor can be used. The Plan Now that my 27 inch monitor has arrived I have to figure out a way of making things work. I still need to work from a laptop on occasion but my main computer use is going to be a smart-phone and a desktop system. Email is already sorted out, I already have three IMAP client systems (netbook, laptop, and phone), adding a desktop system as a fourth isn t going to change anything. The next issue is software development. In the past I haven t used version control systems that much for my hobby work, I have just released a new version every time I had some significant changes. Obviously to support development on two or three systems I need to use a VCS rigorously. I m currently considering Subversion and Git. Subversion is really easy to use (for me), but it seems to be losing popularity. Git is really popular so if I use it for my own projects then I could allow anonymous access for anyone who s interested maybe that will encourage more people to contribute. One thing I haven t even investigated yet is how to manage my web browsing work-flow in a distributed manner. My pattern when using a laptop is to have many windows and tabs open at the same time for issues that I am researching and to only close them days or weeks later when I have finished with the issue. For example if I m buying some new computer gear I will typically open a web browser window with multiple tabs related to the equipment (hardware, software, prices, etc) and keep them all open until I have received it and got it working. Chromium, Mozilla, and presumably other modern web browsers have a facility to reopen windows after a crash. It would be ideal for me if there was some sort of similar facility that allowed me to open the windows that are open on another system and to push window open commands to another system. For example when doing web browsing on my phone I would like to be able to push the URLs of pages that can t be viewed on a phone to my desktop system and have them open waiting for me when I get home. It would be nice if web browsing could be conceptually similar to a remote desktop service in terms of what the user sees. Finally in my home directory there are lots of random files. Probably about half of them could be deleted if I was more organised (disk space is cheap and most of the files are small). For the rest it would be good if they could be accessed from other locations. I have read about people putting the majority of their home directory under version control, but I m not sure that would work well for me. It would be good if I could do something similar with editor sessions, if I had a file open in vi on my desktop before I left home it would be good if I could get a session on my laptop to open the same file (well the same named file checked out of the VCS). Configuring the Desktop System One of the disadvantages of a laptop is that RAID usually isn t viable. With a desktop system software RAID-1 is easy to configure but it results in two disks making heat and noise. For my new desktop system I m thinking of using a DRBD device for /home to store the data locally as well as almost instantly copying it to RAID-1 storage on the server. The main advantage of DRBD over NFS, NBD, and iSCSI is that I can keep working if the server becomes unavailable (EG use the desktop system to ask Google how to fix a server fault). Also with DRBD it s a configuration option to allow synchronous writes to return after the data is written locally which is handy if the server is congested. Another option that I m considering is a diskless system using NBD or iSCSI for all storage. This will prevent using swap (you can t swap to a network device to avoid deadlocks) but that won t necessarily be a problem given the decrease in RAM prices as I can just buy enough RAM to not need swap. The Future Eventually I want to be able to use a tablet for almost everything including software development. While a tablet display isn t going to be great for coding I m sure that I can make use of enough otherwise wasted time to justify the expense. I will probably need a tablet that acts like a regular Linux computer not an Android tablet.

7 September 2011

Soeren Sonnenburg: Shogun at Google Summer of Code 2011

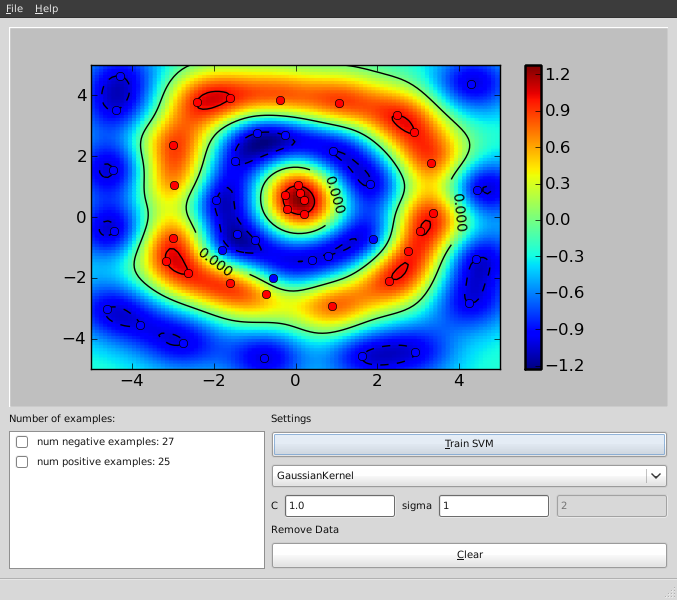
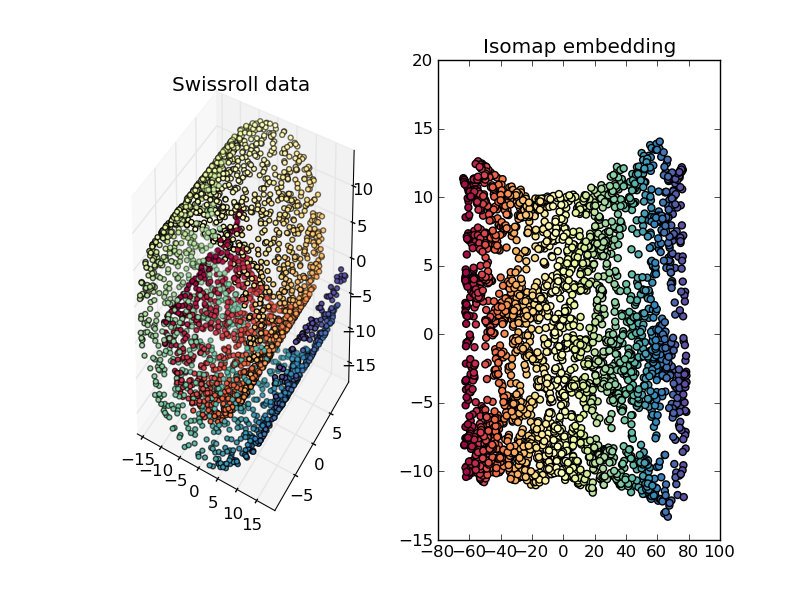
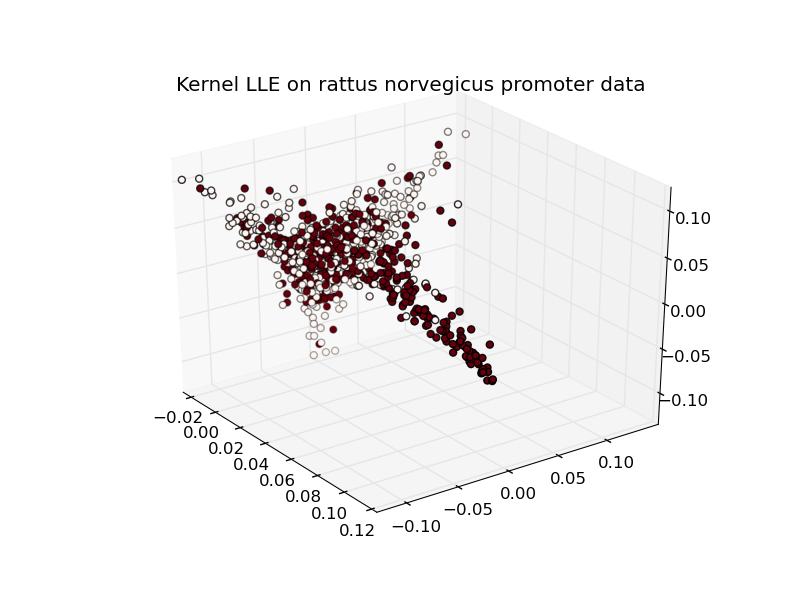
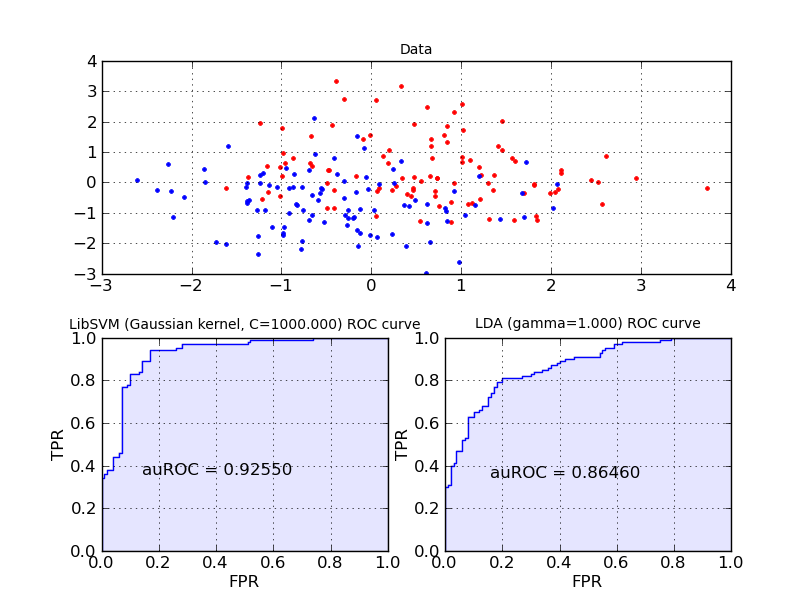
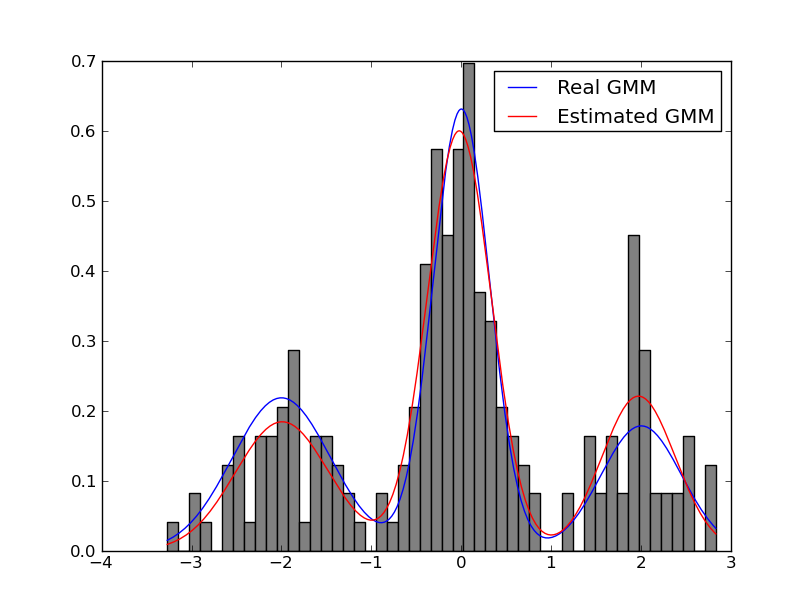
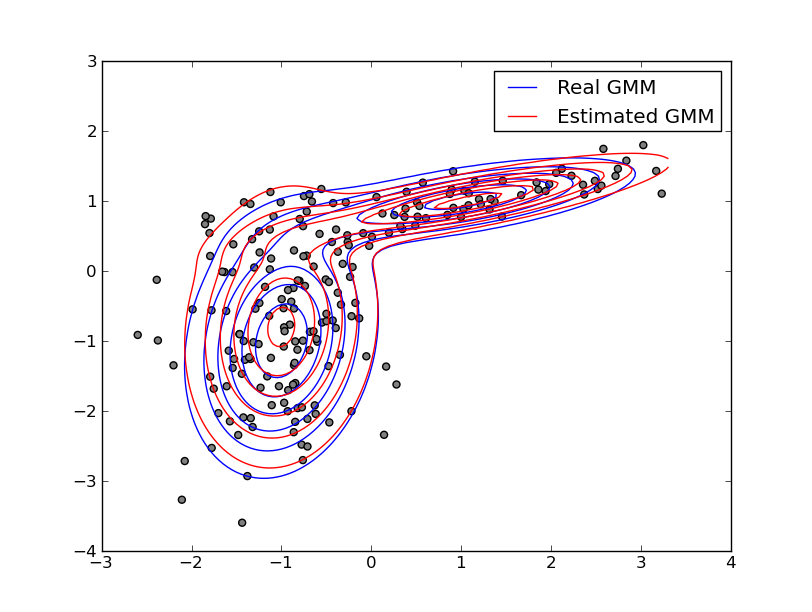
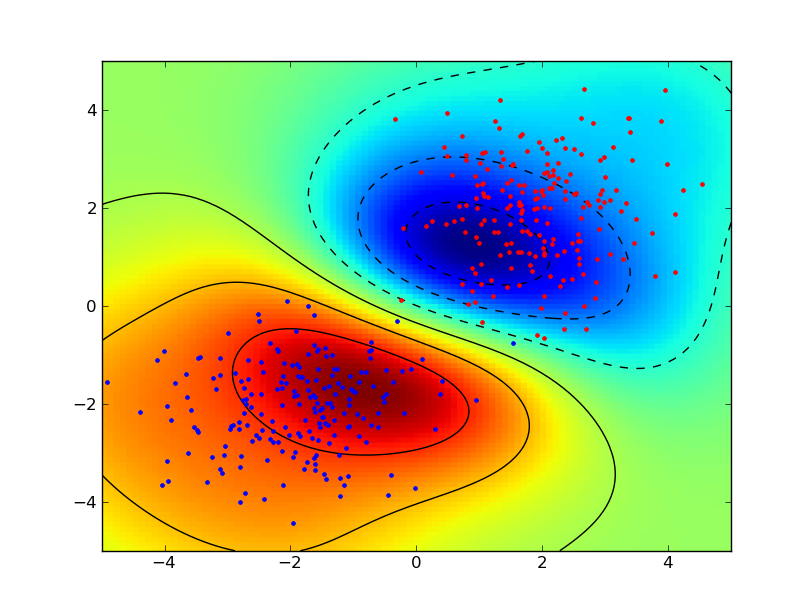
Google Summer of Code 2011 gave a big boost to the development of the shogun machine learning toolbox. In case you have never heard of shogun or machine learning: Machine Learning involves algorithms that do intelligent'' and even automatic data processing and is nowadays used everywhere to e.g. do face detection in your camera, compress the speech in you mobile phone, powers the recommendations in your favourite online shop, predicts solulabily of molecules in water, the location of genes in humans, to name just a few examples. Interested? Then you should give it a try. Some very simple examples stemming from a sub-branch of machine learning called supervised learning illustrate how objects represented by two-dimensional vectors can be classified in good or bad by learning a so called support vector machine. I would suggest to install the python_modular interface of shogun and to run the example interactive_svm_demo.py also included in the source tarball. Two images illustrating the training of a support vector machine follow (click to enlarge): svm svm interactive Now back to Google Summer of Code: Google sponsored 5 talented students who were working hard on various subjects. As a result we now have a new core developer and various new features implemented in shogun: Interfaces to new languages like java, c#, ruby, lua written by Baozeng; A model selection framework written by Heiko Strathman, many dimension reduction techniques written by Sergey Lisitsyn, Gaussian Mixture Model estimation written by Alesis Novik and a full-fledged online learning framework developed by Shashwat Lal Das. All of this work has already been integrated in the newly released shogun 1.0.0. In case you want to know more about the students projects continue reading below, but before going into more detail I would like to summarize my experience with GSoC 2011. My Experience with Google Summer of Code We were a first time organization, i.e. taking part for the first time in GSoC. Having received many many student applications we were very happy to hear that we at least got 5 very talented students accepted but still had to reject about 60 students (only 7% acceptance rate!). Doing this was an extremely tough decision for us. Each of us ended up in scoring students even then we had many ties. So in the end we raised the bar by requiring contributions even before the actual GSoC started. This way we already got many improvements like more complete i/o functions, nicely polished ROC and other evaluation routines, new machine learning algorithms like gaussian naive bayes and averaged perceptron and many bugfixes. The quality of the contributions and independence of the student aided us coming up with the selection of the final five. I personally played the role of the administrator and (co-)mentor and scheduled regular (usually) monthly irc meetings with mentors and students. For other org admins or mentors wanting into GSoC here come my lessons learned: Now please read on to learn about the newly implemented features: Dimension Reduction Techniques Sergey Lisitsyn (Mentor: Christian Widmer) Dimensionality reduction is the process of finding a low-dimensional representation of a high-dimensional one while maintaining the core essence of the data. For one of the most important practical issues of applied machine learning, it is widely used for preprocessing real data. With a strong focus on memory requirements and speed, Sergey implemented the following dimension reduction techniques: See below for the some nice illustrations of dimension reduction/embedding techniques (click to enlarge). isomap swissrollrno kllelocal tangent space alignment Cross-Validation Framework Heiko Strathmann (Mentor: Soeren Sonnenburg) Nearly every learning machine has parameters which have to be determined manually. Before Heiko started his project one had to manually implement cross-validation using (nested) for-loops. In his highly involved project Heiko extend shogun's core to register parameters and ultimately made cross-validation possible. He implemented different model selection schemes (train,validation,test split, n-fold cross-validation, stratified cross-validation, etc and did create some examples for illustration. Note that various performance measures are available to measure how good'' a model is. The figure below shows the area under the receiver operator characteristic curve as an example. foo Interfaces to the Java, C#, Lua and Ruby Programming Languages Baozeng (Mentor: Mikio Braun and Soeren Sonnenburg) Boazeng implemented swig-typemaps that enable transfer of objects native to the language one wants to interface to. In his project, he added support for Java, Ruby, C# and Lua. His knowlegde about swig helped us to drastically simplify shogun's typemaps for existing languages like octave and python resolving other corner-case type issues. The addition of these typemaps brings a high-performance and versatile machine learning toolbox to these languages. It should be noted that shogun objects trained in e.g. python can be serialized to disk and then loaded from any other language like say lua or java. We hope this helps users working in multiple-language environments. Note that the syntax is very similar across all languages used, compare for yourself - various examples for all languages ( python, octave, java, lua, ruby, and csharp) are available. Largescale Learning Framework and Integration of Vowpal Wabbit Shashwat Lal Das (Mentor: John Langford and Soeren Sonnenburg) Shashwat introduced support for 'streaming' features into shogun. That is instead of shogun's traditional way of requiring all data to be in memory, features can now be streamed from e.g. disk, enabling the use of massively big data sets. He implemented support for dense and sparse vector based input streams as well as strings and converted existing online learning methods to use this framework. He was particularly careful and even made it possible to emulate streaming from in-memory features. He finally integrated (parts of) vowpal wabbit, which is a very fast large scale online learning algorithm based on SGD. Expectation Maximization Algorithms for Gaussian Mixture Models Alesis Novik (Mentor: Vojtech Franc) The Expectation-Maximization algorithm is well known in the machine learning community. The goal of this project was the robust implementation of the Expectation-Maximization algorithm for Gaussian Mixture Models. Several computational tricks have been applied to address numerical and stability issues, like An illustrative example of estimating a one and two-dimensional Gaussian follows below. 1D GMM2D GMM Final Remarks All in all, this year s GSoC has given the SHOGUN project a great push forward and we hope that this will translate into an increased user base and numerous external contributions. Also, we hope that by providing bindings for many languages, we can provide a neutral ground for Machine Learning implementations and that way bring together communities centered around different programming languages. All that s left to say is that given the great experiences from this year, we d be more than happy to participate in GSoC2012.

6 September 2011

Lars Wirzenius: Entropy key: a review

I recently bought a Simtec Entropy Key. It's a hardware randomness generator encapsulated as a USB device, the size of a flash drive. It's good for any host or cluster that uses a lot of kernel-provided random numbers (/dev/random), or does things that cause the kernel to use a lot of random numbers. Opening a lot of network connections, or generating session keys for public key encryption. That kind of stuff. If the kernel has too little entropy available to generate good random numbers, things will stall until it gets some more. The ekey gives you real random bits, not just software-produced pseudo-random numbers. In other words, it's some kind of magic. I got the device in a DVD box, with a leaflet explaining how to install stuff, a CD with the software, an envelope with a secret key, and the actual device itself. I read the leaflet, which said to install the ekeyd daemon first. I ignored the CD, since a) my laptop has no optical drive and b) the software is in Debian stable (squeeze) anyway, so apt-getting it is easier and faster. I was utterly disappointed with the software. I didn't have to edit a single hard disk sector, or do a BIOS upgrade, or anything. Utterly, totally, boring. I had reserved an afternoon and evening for this, but I had to find something else to do instead. After plugging in the device in a spare USB port, I opened the envelope and ran a command to specify the secret key. The key and host processors use encryption to make sure nobody can eavesdrop on the randomness -- that would give them an edge in cracking SSL and GPG encryption, I guess. Here's an example of how it works. Before I plug in the device, the kernel has some, but not too much entropy available:
liw@havelock$ cat /proc/sys/kernel/random/entropy_avail 
1053
A few seconds after the ekey is inserted:
liw@havelock$ cat /proc/sys/kernel/random/entropy_avail 
3968
And here's the kicker: pretty much regardless of what I do, the entropy stays at about 4 kilounits (I don't know if it's bits or bytes, and I'm too lazy to check). In the end, the only thing I can really complain about is the typography and layout of the leaflet. The text is clear enough, but it's laid out too densely. It needs more whitespace. Some pictures of bunnies or kittens would be nice, too.

5 September 2011

Eugene V. Lyubimkin: cupt: 2.2.0~rc1

It took longer than usual, but I believe it's worth.

I just released Cupt 2.2.0~rc1 to Debian experimental. To experimental, because there are important changes and I would appreciate "in-field" testing before final 2.2.0.

Here are the major changes since 2.1.x:


Enjoy and send the bug reports.

Steve Kemp: Scriptable email clients

This is just a quick post to remind myself in the morning, as soon as I've made it I intend to turn my computer off and leave it off until I can re-organize my office. I've been using mutt for my email for the past few years. Nothing compares to the flexibility of procmail/sieve for organizing server-side mail, and then mutt is ideal for reading them. With the addition of the mutt-patched sidebar mode you can even go for a few days before realizing you're not in a graphical environment. But one thing I do long for is the ability to execute scripts at various times. Thus far I've not actually planned what I'd like to do, but as a starting point imagine being able to execute a hook when new mail arrives? Or when you send a message matching a pattern in some fashion? There are some things out there, such as the various hacks which are designed to abort sending a message if you mention "See attachment" in a message body but fail to add one before sendign the message. These hacks generally abuse the sendmail configuration such that they're extremely ad-hoc and hard to chain/nest. I've mellowed out over the years and I have no interest in attempting to write a mail-client (though at the same time how hard can it be? Just restrict yourself to using inotify on ~/Maildir and offload delivery to exim and you're almost done? I guess the hard part is the UI, though I do like the mutt + sidebar layout. Write the whole thing in some scripty language?) I'll re-examine notmuch and gnus over the next week or two, but I suspect both will continue to disappoint in various ways. Anyway, for the moment I'm just pondering. But threading is an obvious concern. Most current mutt hooks relate to the local folder, or the local message. If I were viewing a message in one directory and a new mail notification fired for a delivery to both ~/Maildir and ~/Maildir/.people.foo I'd need to either serialise them or thread them. Ponder ponder. In other news I've been doing more photography recently. Nothing cohesive except for my recent experiment with shooting a "street-girl" outdoors in falling light, but that was an interesting challenge and the results were sufficient to make me want to try shooting outdoors in an organized fashion again. (Some random images have been linked to from my wee twitter page.) ObFilm: "She doesn't get eaten by the eels at this time " - The Princess Bride

Kai Wasserb ch: What wasn't said about the Linux graphics stack

This post is a small follow-up on yesterday's post about the Linux graphics stack. I'm still keeping to high level stuff and won't dig too deep, but a few questions arose (others reached me by e-mail), so, here we go. Gallium3D is a framework, initially developed by Tungsten Graphics, which were bought by VMware. The idea behind Gallium3D is, that many functions can be shared between drivers for different GPUs and that the effort to support a new platform/system is for classic drivers pretty high. With Gallium3D you just need a state tracker and a target. The state tracker is code, that gives the pipeline of Gallium3D drivers access to a platform/system, like OpenGL or X on various operating systems. A target is the required as glue between a state tracker and the actual driver. For example: there is a state tracker for video playback acceleration (the recently added g3dvl). The state tracker itself offers the interface and common functions (with some help from the auxilliary stuff) between the Gallium3D pipeline and the userland libraries like libvdpau1. Targets like vdpau-[DRIVER] glue the driver and the state tracker together. The winsys part of Gallium3D is a similar concept but it abstracts the windowing system on the target platform away (e.g. Wayland, X or GDI). I didn't write about the proprietary drivers yesterday, as I don't consider them a real part of the Linux graphics stack, more like parasites, and didn't want to encourage anyone to use them (yes, I know, there are some cases in which you might be better off with them, but generally I'd avoid them). Anyway, I got some questions about those (some by e-mail, the other I'm aware off, can be found behind the link at the beginning of this entry). So, where do the proprietary drivers come in? They are basically the entire stack in a closed form, plugging into the public interfaces of the Kernel (whether that's legal is disputed), some other parts like X (by building a DDX) and building their own libGL. Especially the last part can be a cause for a lot of pain, when you don't use the proprietary driver packages offered by the distribution (e.g. Debian's fglrx packages divert the libGL and restore the default one on unistallation, with the vendor build scripts and tools this is not really guaranteed, which might leave you with a broken OpenGL setup). Another question was, why Mesa was lacking support for a recent OpenGL version (i.e. 4.x). In my opinion there are a few reasons, though I don't really feal like the best person to answer this. The first are design issues by some internal representations (e.g. missing integer support in the intermediate representations). The second is the available number of developers being able to implement new OpenGL functions. Apart from a not all too clear specification the Mesa code base is huge (even if you ignore most of the drivers), which makes it difficult for new developers to start coding away. Then you need an understanding of how modern GPUs operate to find good solutions for the problems faced. If you want to get an idea for this, take a look at Zack Rusin's or Alex Deucher's blog. Then, there is a sad split of developers, on the one hand we've got the Gallium3D-using developers on the other we've got the ones staying with the classic driver model. This means, that you have to implement e.g. GLSL extensions for TGSI and Mesa's IR respectivly. There might be other reasons, I'm totally missing, but this should give you some insight into why it takes so long, to get current OpenGL versions supported. I hope this clears some of the remaining questions, if not, feel free to write me an e-mail, but please remember, that this is not an in-depth analysis.

4 September 2011

Sune Vuorela: Network status aware apps

Am I online or not? There is a summary at the end for the quick readers. It is in many modern applications important to be able to more or less gracefully handle if the application user is online or not. For example, there is no need to try to fetch emails if the device (computer, phone, tablet, laptop, ) doesn t have network (wifi, cable, umts, ip over avian carriers, ..). KDE has of course made nice functionality for this, and here I will try to describe how to make your app network status aware and what to be aware of in the process. Solid background All this is going on in Solid, using two parts of Solid and a bit of KDE s infrastructure: The networkstatus KDED module is trying it best to gather information from the computer to see if one is connected or not. It has the possibility to gather information from various sources, and handle changes and such. The as of writing available sources that the networkstatus module gathers information from is Collecting from different sources is important, because some people might have configurations like Manage wireless thru wicd , manage umts dongle with Network Manager and manage wired network with /etc/network/interfaces and all of it needs to be combined. Solid reports, if wicd thinks online , and network manager thinks offline that the user is Connected.. Solid States There is a enum with 5 values in Solid to describe the current state of the network:

enum Status
Unknown,
Unconnected,
Disconnecting,
Connecting,
Connected
;
Connected is the easy state. Here, Solid knows that you are having some kind of connection according to at least one of the sources. But it might just be a local network connection, and not actually a internet connection. So one here should handle connection failures gracefully. Unconnected is a similar easy state. Here, Solid knows that you don t have any internet connection according to the sources it knows about. One should here not try to do any networking. Connecting and Disconnecting is that a state change is happening, so that you can prepare to react on it. Solid also has the state of Unknown, used for cases where Solid doesn t have the required data to actually know it. A example could be a system without any of the data providers. You should here probably try to connect, and be able to handle failures gracefully. Also described as Proceed with caution . The bright reader might here notice that one both in the Unknown and Connected case actually should do the same. Querying for network status At any given time:

Solid::Networking::Status currentStatus = Solid::Networking::status();
if(currentStatus==Connected currentStatus==Unknown)
//try to do networking things
else
//mark application as offline.

Here, we first query Solid for current status, and then if the state is Connected OR Unknown, then we proceed. Getting notified Maybe you don t want the roundtrip of asking (resulting in a dbus rountrip each time) when you need to know the state changes. Then you of course can get notified. class MyNetworkAwareClass : public QObject
Q_OBJECT
public:
MyNetworkAwareClass();
void doNetworkActivity();
private Q_SLOTS:
void networkStatusChanged(Solid::Networking::Status newstatus);
private:
Solid::Networking::Status m_current_state
;
MyNetworkAwareClass::MyNetworkAwareClass : m_current_state(Solid::Networking::Status())
connect(Solid::Networking::notifier(), SIGNAL(statusChanged(Solid::Networking::Status),this,SLOT(networkStatusChanged(Solid::Networking::Status)));

void MyNetworkAwareClass::networkStatusChanged(Solid::Networking::Status newstate)
m_current_state = newstate;
void MyNetworkAwareClass::doNetworkActivity()
if(m_current_state == Unknown m_current_state == Connected)
//try to do network activity


I guess this should be pretty self explaining. Summary Oh. And I m out looking for a job.

Next.

Previous.