Search Results: "ema"

5 June 2013

Johannes Schauer: Reliable IMAP synchronization with IDLE support

The task: reliably synchronize my local MailDir with several remote IMAP mailboxes with IDLE support so that there is no need to poll with small time intervals to get new email immediately. Most graphical mail clients like icedove/thunderbird or evolution have IDLE support which means that their users get notified about new email as soon as it arrives. I prefer to handle email fetching/reading/sending using separate programs so after having used icedove for a long time, I switched to a offlineimap/mutt based setup a few years ago. Some while after that I discovered sup and later notmuch/alot which made me switch again. Now my only remaining problem is the synchronization between my local email and several remote IMAP servers. Using offlineimap worked fine in the beginning but soon I discovered some of its shortcomings. It would for example sometimes lock up or simply crash when I switched between different wireless networks or switched to ethernet or UMTS. Crashing was not a big problem as I just put it into a script which re-executed it every time it crashed. The problem was it locking up for one of its synchronizing email accounts while the others were kept in sync as usual. This once let to me missing five days of email because offlineimap was not crashing and I believed everything was fine (new messages from the other accounts were scrolling by as usual) while people were sending me worried emails whether I was okay or if something bad had happened. I nearly missed a paper submission deadline and another administrative deadline due to this. This was insanely annoying. It turned out that other mail synchronization programs suffered from the same lockup problem so I stuck with offlineimap and instead executed it as:
while true; do
timeout --signal=KILL 1m offlineimap
notmuch new
sleep 5m
done
Which would synchronize my email every five minutes and kill offlineimap if a synchronization took more than one minute. While I would've liked an email synchronizer which would not need this measure, this worked fine over the months. After some while it bugged me that icedove (which my girlfriend is using) was receiving email nearly instantaneously after they arrived and I couldnt have this feature with my setup. This instantaneous arrival of email works by using the IMAP IDLE command which allows the server to notify the client once new email arrives instead of the client having to poll for new email in small intervals. Unfortunately offlineimap (and any other email synchronizer I found) would not support the IDLE command. There is a fork of it which supports IDLE by using a newer python imap library but this is of little use to me as there is no possibility of a hook which executes when new email arrives so that I can execute notmuch new on the new email. At this point I could've used inotify to execute notmuch new upon arrival of new email but I went another way. Here is a short python script idle.py which connects to my IMAP servers and sends the IDLE command:
import imaplib
import select
import sys

class mysock():
def __init__(self, name, server, user, passwd, directory):
self.name = name
self.directory = directory
self.M = imaplib.IMAP4(server)
self.M.login(user, passwd)
self.M.select(self.directory)
self.M.send("%s IDLE\r\n"%(self.M._new_tag()))
if not self.M.readline().startswith('+'): # expect continuation response
exit(1)

def fileno(self):
return self.M.socket().fileno()

if __name__ == '__main__':
sockets = [
mysock("Name1", "imap.foo.bar", "user1", "pass1", "folder1"),
mysock("Name1", "imap.foo.bar", "user1", "pass1", "folder2"),
mysock("Name2", "imap.blub.bla", "user2", "pass2", "folder3")
]
readable, _, _ = select.select(sockets, [], [], 1980) # 33 mins timeout

found = False
for sock in readable:
if sock.M.readline().startswith('* BYE '): continue
print "-u basic -o -q -f %s -a %s"%(sock.directory, sock.name)
found = True
break

if not found:
print "-u basic -o"
It would create a connection to every directory I want to watch on every email account I want to synchronize. The select call will expire after 33 minutes as most email servers would drop the connection if nothing happens at around 30 minutes. If something happened within that time though, the script would output the arguments to offlineimap to do a quick check on just that mailbox on that account. If nothing happened, the script would output the arguments to offlineimap to do a full check on all my mailboxes.
while true; do
args= timeout --signal=KILL 35m python idle.py
echo "idle timed out" >&2;
args="-u basic -o";

echo "call offlineimap with: $args" >&2
timeout --signal=KILL 1m offlineimap $args
echo "offlineimap timed out" >&2;
continue;

notmuch new
done
Every call which interacts with the network is wrapped in a timeout command to avoid any funny effects. Should the python script timeout, a full synchronization with offlineimap is triggered. Should offlineimap timeout, an error message is written to stderr and the script continues. The above naturally has the disadvantage of not immediately responding to new email which arrives during the time that idle.py is not running. But as this email will be fetched once the next message arrives on the same account, there is no much waiting time and so far, this problem didnt bite me. Is there a better way to synchronize my email and at a same time make use of IDLE? I'm surprised I didnt find software which would offer this feature.

4 June 2013

Keith Packard: dri3 extension

Completing the DRI3 Extension This week marks a pretty significant milestone for the glorious DRI3000 future. The first of the two new extensions is complete and running both full Gnome and KDE desktops. DRI3 Extension Overview The DRI3 extension provides facilities for building direct rendering libraries to work with the X window system. DRI3 provides three basic mechanisms:
  1. Open a DRM device.
  2. Share kernel objects associated with X pixmaps. The direct rendering client may allocate kernel objects itself and ask the X server to construct a pixmap referencing them, or the client may take an existing X pixmap and discover the underlying kernel object for it.
  3. Synchronize access to the kernel objects. Within the X server, Sync Fences are used to serialize access to objects. These Sync Fences are exposed via file descriptors which the underlying driver can use to implement synchronization. The current Intel DRM driver passes a shared page containing a Linux Futex.
Opening the DRM Device Ideally, the DRM application would be able to just open the graphics device and start drawing, sending the resulting buffers to the X server for display. There s work going on to make this possible, but the current situation has the X server in charge of blessing the file descriptors used by DRM clients. DRI2 does this by having the DRM client fetch a magic cookie from the kernel and pass that to the X server. The cookie is then passed to the kernel which matches it up with the DRM client and turns on rendering access for that application. For DRI3, things are much simpler the DRM client asks the X server to pass back a file descriptor for the device. The X server opens the device, does the magic cookie dance all by itself (at least for now), and then passes the file descriptor back to the application.
 
    DRI3Open
    drawable: DRAWABLE
    driverType: DRI3DRIVER
    provider: PROVIDER
       
    nfd: CARD8
    driver: STRING
    device: FD
 
    Errors: Drawable, Value, Match
    This requests that the X server open the direct rendering
    device associated with drawable, driverType and RandR
    provider. The provider must support SourceOutput or SourceOffload.
    The direct rendering library used to implement the specified
    'driverType' is returned in 'driver'. The file
    descriptor for the device is returned in 'device'. 'nfd' will
    be set to one (this is strictly a convenience for XCB which
    otherwise would need request-specific information about how
    many file descriptors were associated with this reply).
Sharing Kernel Pixel Buffers An explicit non-goal of DRI3 is support for sharing buffers that don t map directly to regular X pixmaps. So, GL ancillary buffers like depth and stencil just don t apply here. The shared buffers in DRI3 are regular X pixmaps in the X server. This provides a few obvious benefits over the DRI2 scheme: In the kernel, the buffers are referenced by DMA-BUF handles, which provides a nice driver-independent mechanism.
  1. Lifetimes are easily managed. Without being associated with a separate drawable, it s easy to know when to free the Pixmap.
  2. Regular X requests apply directly. For instance, copying between buffers can use the core CopyArea request.
To create back- and fake-front- buffers for Windows, the application creates a kernel buffer, associates a DMA-BUF file descriptor with that and then sends the fd to the X server with a pixmap ID to create the associated pixmap. Doing it in this direction avoids a round trip.
 
    DRI3PixmapFromBuffer
    pixmap: PIXMAP
    drawable: DRAWABLE
    size: CARD32
    width, height, stride: CARD16
    depth, bpp: CARD8
    buffer: FD
 
    Errors: Alloc, Drawable, IDChoice, Value, Match
    Creates a pixmap for the direct rendering object associated
    with 'buffer'. Changes to pixmap will be visible in that
    direct rendered object and changes to the direct rendered
    object will be visible in the pixmap.
    'size' specifies the total size of the buffer bytes. 'width',
    'height' describe the geometry (in pixels) of the underlying
    buffer. 'stride' specifies the number of bytes per scanline in
    the buffer. The pixels within the buffer may not be arranged
    in a simple linear fashion, but 'size' will be at least
    'height' * 'stride'.
    Precisely how any additional information about the buffer is
    shared is outside the scope of this extension.
    If buffer cannot be used with the screen associated with
    drawable, a Match error is returned.
    If depth or bpp are not supported by the screen, a Value error
    is returned.
To provide for texture-from-pixmap, the application takes the pixmap ID and passes that to the X server which returns the a file descriptor for a DMA-BUF which is associated with the underlying kernel buffer.
 
    DRI3BufferFromPixmap
    pixmap: PIXMAP
       
    depth: CARD8
    size: CARD32
    width, height, stride: CARD16
    depth, bpp: CARD8
    buffer: FD
 
    Errors: Pixmap, Match
    Pass back a direct rendering object associated with
    pixmap. Changes to pixmap will be visible in that
    direct rendered object and changes to the direct rendered
    object will be visible in the pixmap.
    'size' specifies the total size of the buffer bytes. 'width',
    'height' describe the geometry (in pixels) of the underlying
    buffer. 'stride' specifies the number of bytes per scanline in
    the buffer. The pixels within the buffer may not be arranged
    in a simple linear fashion, but 'size' will be at least
    'height' * 'stride'.
    Precisely how any additional information about the buffer is
    shared is outside the scope of this extension.
    If buffer cannot be used with the screen associated with
    drawable, a Match error is returned.
Tracking Window Size Changes When Eric Anholt and I first started discussing DRI3, we hoped to avoid needing to learn about the window size from the X server. The thought was that the union of all of the viewports specified by the application would form the bounds of the drawing area. When the window size changed, we expected the application would change the viewport. Alas, this simple plan isn t sufficient here a few GL functions are not limited to the viewport. So, we need to track the actual window size and monitor changes to it. DRI2 does this by delivering invalidate events to the application whenever the current buffer isn t valid; the application discovers that this event has been delivered and goes to as the X server for the new buffers. There are a couple of problems with this approach:
  1. Any outstanding DRM rendering requests will still draw to the old buffers.
  2. The Invalidate events must be captured before the application sees the related ConfigureNotify event so that the GL library can react appropriately.
The first problem is pretty intractable within DRI2 the application has no way of knowing whether a frame that it has drawn was delivered to the correct buffer as the underlying buffer object can change at any time. DRI3 fixes this by having the application in control of buffer management; it can easily copy data from the previous back buffer to the new back buffer synchronized to its own direct rendering. The second problem was solved in DRI2 by using the existing Xlib event hooks; the GL library directly implements the Xlib side of the DRI2 extension and captures the InvalidateBuffers events within that code, delivering those to the driver code. The problem with this solution is that Xlib holds the Display structure mutex across this whole mess, and Mesa must be very careful not to make any Xlib calls during the invalidate call. For DRI3, I considered placing the geometry data in a shared memory buffer, but my future plans for the Present extension led me to want an X event instead (more about the Present extension in a future posting). An X ConfigureNotify event is sufficient for the current requirements to track window sizes accurately. However, there s no easy way for the GL library to ensure that ConfigureNotify events will be delivered to the application other application code may (and probably will) adjust the window event mask for its own uses. I considered adding the necessary event mask tracking code within XCB, but again, knowing that the Present extension would probably need additional information anyhow, decided to create a new event instead. Using an event requires that XCB provide some mechanism to capture those events, keep them from the regular X event stream, and deliver them to the GL library. A further requirement is that the GL library be absolutely assured of receiving notification about these events before the regular event processing within the application will see a core ConfigureNotify event. The method I came up with for XCB is fairly specific to my requirements. The events are always XGE events, and are tagged with a special event context ID , an XID allocated for this purpose. The combination of the extension op-code, the event type and this event context ID are used to split off these events to custom event queues using the following APIs:
/**
 * @brief Listen for a special event
 */
xcb_special_event_t *xcb_register_for_special_event(xcb_connection_t *c,
                                                    uint8_t extension,
                                                    uint16_t evtype,
                                                    uint32_t eid,
                                                    uint32_t *stamp);
This creates a special event queue which will contain only events matching the specified extension/type/event-id triplet.
/**
 * @brief Returns the next event from a special queue
 */
xcb_generic_event_t *xcb_check_for_special_event(xcb_connection_t *c,
                                                 xcb_special_event_t *se);
This pulls an event from a special event queue. These events will not appear in the regular X event queue and so applications will never see them. There s one more piece of magic here the stamp value passed to xcbregisterforspecialevent. This pointer refers to a location in memory which will be incremented every time an event is placed in the special event queue. The application can cheaply monitor this memory location for changes and known when to check the queue for events. Within GL, the value used is the existing dri2 stamp value. That is checked at the top of the rendering operation; if it has changed, the drawing buffers will be re-acquired. Part of the buffer acquisition process is a check for special events related to the window. For now, I ve placed these events in the DRI3 extension. However, they will move to the Present extension once that is working.
 
    DRI3SelectInput
    eventContext: DRI3EVENTID
    window: WINDOW
    eventMask: SETofDRI3EVENT
 
    Errors: Window, Value, Match, IDchoice
    Selects the set of DRI3 events to be delivered for the
    specified window and event context. DRI3SelectInput can
    create, modify or delete event contexts. An event context is
    associated with a specific window; using an existing event
    context with a different window generates a Match error.
    If eventContext specifies an existing event context, then if
    eventMask is empty, DRI3SelectInput deletes the specified
    context, otherwise the specified event context is changed to
    select a different set of events.
    If eventContext is an unused XID, then if eventMask is empty
    no operation is performed. Otherwise, a new event context is
    created selecting the specified events.
The events themselves look a lot like a configure notify event:
 
    DRI3ConfigureNotify
    type: CARD8         XGE event type (35)
    extension: CARD8        DRI3 extension request number
    length: CARD16          2
    evtype: CARD16          DRI3_ConfigureNotify
    eventID: DRI3EVENTID
    window: WINDOW
    x: INT16
    y: INT16
    width: CARD16
    height: CARD16
    off_x: INT16
    off_y: INT16
    pixmap_width: CARD16
    pixmap_height: CARD16
    pixmap_flags: CARD32
 
    'x' and 'y' are the parent-relative location of 'window'.
Note that there are a couple of odd additional fields offx, offy, pixmapwidth, pixmapheight and pixmap_flags are all place-holders for what I expect to end up in the Present extension. For now, in DRI3, they should be ignored. Synchronization The DRM application needs to know when various X requests related to its buffers have finished. In particular, when performing a buffer swap, the client wants to know when that completes, and be able to block until it has. DRI2 does this by having the application make a synchronous request from the X server to get the names of the new back buffer for drawing the next frame. This has two problems:
  1. The synchronous round trip to the X server isn t free. Other running applications may cause fairly arbitrary delays in getting the reply back from the X server.
  2. Synchronizing with the X server doesn t ensure that GPU operations are necessarily serialized between the application and the X server.
What we want is a serialization guarantee between the X server and the DRM application that operates at the GPU level. I ve written a couple of times (dri3k first steps and Shared Memory Fences) about using X Sync extension Fences (created by James Jones and Aaron Plattner) for this synchronization and wanted to get a bit more specific here. With the X server, a Sync extension Fence is essentially driver-specific, allowing the hardware design to control how the actual synchronization is performed. DRI3 creates a way to share the underlying operating system object by passing a file descriptor from application to the X server which somehow references that device object. Both sides of the protocol need to tacitly agree on what it means.
 
    DRI3FenceFromFD
    drawable: DRAWABLE
    fence: FENCE
    initially-triggered: BOOL
    fd: FD
 
    Errors: IDchoice, Drawable
    Creates a Sync extension Fence that provides the regular Sync
    extension semantics along with a file descriptor that provides
    a device-specific mechanism to manipulate the fence directly.
    Details about the mechanism used with this file descriptor are
    outside the scope of the DRI3 extension.
For the current GEM kernel interface, because all GPU access is serialized at the kernel API, it s sufficient to serialize access to the kernel itself to ensure operations are serialized on the GPU. So, for GEM, I m using a shared memory futex for the DRI3 synchronization primitive. That does not mean that all GPUs will share this same mechanism. Eliminate the kernel serialization guarantee and some more GPU-centric design will be required. What about Swap Buffers? None of the above stuff actually gets bits onto the screen. For now, the GL implementation is simply taking the X pixmap and copying it to the window at SwapBuffers time. This is sufficient to run applications, but doesn t provide for all of the fancy swap options, like limiting to frame rate or optimizing full-screen swaps. I ve decided to relegate all of that functionality to the as-yet-unspecified Present extension. Because the whole goal of DRI3 was to get direct rendered application contents into X pixmaps, the Present extension will operate on those X objects directly. This means it will also be usable with non-DRM applications that use simple X pixmap based double buffering, a class which includes most existing non-GL based Gtk+ and Qt applications. So, I get to reduce the size of the DRI3 extension while providing additional functionality for non direct-rendered applications. Current Status As I said above, all of the above functionality is running on my systems and has booted both complete KDE and Gnome sessions. There have been some recent DMA-BUF related fixes in the kernel, so you ll need to run the latest 3.9.x stable release or a 3.10 release candidate. Here s references to all of the appropriate git repositories: DRI3 protocol and spec:
git://people.freedesktop.org/~keithp/dri3proto      master
XCB protocol
git://people.freedesktop.org/~keithp/xcb/proto.git  dri3
XCB library
git://people.freedesktop.org/~keithp/xcb/libxcb.git dri3
xshmfence library:
git://people.freedesktop.org/~keithp/libxshmfence.git   master
X server:
git://people.freedesktop.org/~keithp/xserver.git    dri3
Mesa:
git://people.freedesktop.org/~keithp/mesa.git       dri3
Next Steps Now it s time to go write the Present extension and get that working. I ll start coding and should have another posting here next week.

Daniel Pocock: Using reSIProcate to connect Asterisk with WebRTC

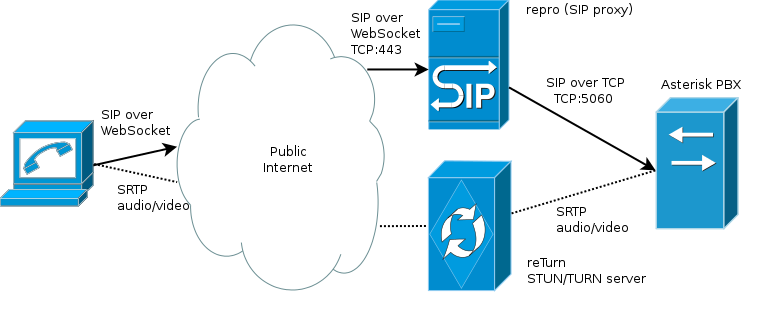
In my previous blog entry about how to get WebRTC going fast I looked at the basics of setting up a SIP proxy (also known as a SIP router) to accept connections from WebRTC clients. As in a traditional, non-WebRTC world, the SIP proxy simply facilitates calling between all the clients it knows. In practice, deployments usually want to add additional functionality in the form of a PBX with queues, voicemail, menus and conferencing. The recent Asterisk 11 release includes support for WebRTC although it is still evolving and I don't currently recomend connecting Asterisk directly to the public Internet. In particular, Asterisk doesn't support features like mutual TLS authentication with the WSS (secure WebSocket) transport. Here, we look at how repro can accept connections from Internet/web users and relay them to an internal Asterisk server. Here is an architecture diagram: Notice that the SIP messages are accepted over repro's WebSocket transport and relayed to Asterisk over a regular SIP TCP transport. This means that we benefit from repro's TLS support too, so the WebSocket client has a much higher chance of escaping their client-side firewall if port 443 is used (repro pretending to be a HTTPS server) and clients can be authenticated with certificates in their browser. Here are the steps to get it running: repro and reTurn setup Set up repro and reTurn server on a Debian server as per my previous blog post. Verify that the clients can talk to repro. Asterisk source build Digium, the creators of Asterisk, are not currently supporting Debian packages, but they do provide RPM packages in their Asterisk package repository However, the pre-built binary packages for Asterisk 11.4 don't include SRTP support. SRTP is a mandatory part of WebRTC. Therefore, we take the Source RPM (SRPM) and build it manually. First, it is recommended that you start with a completely fresh CentOS 6 or RHEL6 server. I built a fresh virtual machine in my XCP environment using a procedure similar to that documented by Grant. After installing and setting a root password, configure yum to access EPEL6 Make sure SELinux and firewall are disabled on the box (they are often enabled by default). A quick way to do this:

# sed -i s/SELINUX=enforcing/SELINUX=disabled/g /etc/selinux/config
# reboot
...
# iptables -I INPUT -j ACCEPT
Next you can tell yum about the Digium repository and install all the necessary dependencies for building Asterisk:
# rpm -Uvh http://packages.asterisk.org/centos/6/current/x86_64/RPMS/asterisknow-version-3.0.0-1_centos6.noarch.rpm
# yum update
# yum install rpm-build libsrtp-devel
In your home directory, set up a work tree for rpmbuild:
$ mkdir ~/rpmbuild
$ cd ~/rpmbuild
$ mkdir BUILD BUILDROOT RPMS SOURCES SPECS SRPMS
$ cd SPECS
$ wget http://danielpocock.com/sites/danielpocock.com/files/asterisk.spec
$ cd ../SRPMS
$ wget http://packages.asterisk.org/centos/6/asterisk-11/SRPMS/asterisk-11.4.0-1_centos6.src.rpm
$ rpmbuild --rebuild asterisk-11.4.0-1_centos6.src.rpm
At this stage, you will have some errors, but it has successfully extracted the tarball into the SOURCES directory:
$ ls -l ../SOURCES
-rw-r--r--   1 daniel daniel 11573400 May 20 23:07 asterisk-sources-11.4.0.tar.gz
$
It will also complain about missing dependencies, you install them using yum:
# yum install make gcc gcc-c++ ....
Notice that you have downloaded a slightly modified version of the asterisk.spec file, the reasons for this are explained in this mailing list discussion. The following should now trigger a successful build:
$ rpmbuild -bb \
  --without tds \
    --without misdn \
    --without odbc \
   ~/rpmbuild/SOURCES/asterisk.spec
Hopefully, Digium will add the SRTP support in the 11.4.1 packages so that source build won't be necessary for every future release. Asterisk configuration: demo application Here we just have to install the RPMs and make a quick configuration change:
$ cd ~/rpmbuild/RPMS/x86_64
$ su -
# rpm -i asterisk*rpm
# yum install asterisk-sounds-core-en-ulaw asterisk-sounds-extra-en-ulaw --enablerepo=asterisk-11
# ln -s /usr/share/asterisk/sounds/demo-* /var/lib/asterisk/sounds/en/
To enable connections from the proxy, we must set a few non-default settings. It is essential to use the TCP transport as the SIP messages from WebSocket clients are usually too big for UDP packets. It is also necessary to enable SRTP and AVPF, as these are mandatory in WebRTC. Here is a diff against the default /etc/asterisk/sip.conf:
--- /etc/asterisk.orig/sip.conf	2013-06-04 10:57:49.428617785 +0200
+++ /etc/asterisk/sip.conf	2013-06-04 11:18:17.825604261 +0200
@@ -207,7 +207,7 @@
 ; subject to change in any release.  If they are changed, the changes will
 ; be reflected in this sample configuration file, as well as in the UPGRADE.txt file.
 ;
-tcpenable=no                    ; Enable server for incoming TCP connections (default is no)
+tcpenable=yes                    ; Enable server for incoming TCP connections (default is no)
 tcpbindaddr=0.0.0.0             ; IP address for TCP server to bind to (0.0.0.0 binds to all interfaces)
                                 ; Optionally add a port number, 192.168.1.1:5062 (default is port 5060)
 
@@ -1371,6 +1371,13 @@
 ; ...
 ;
 
+[1001](public-phone,ulaw-phone)
+avpf = yes
+encryption = yes
+context = public
+icesupport = yes
+
+
 ; Standard configurations not using templates look like this:
 ;
 ;[grandstream1]
This assumes that the SIP user ID of your WebSocket user is 1001 Now you can start Asterisk:
# service asterisk start
Configuring the repro SIP proxy to send calls to Asterisk This is a relatively simple demonstration. The goal is to send calls for the number 1000 to the demo application in Asterisk In repro's web interface, click ADD ROUTE in the menu. Use the following parameters and leave all other options blank:
  • URI: ^sip:1000@
  • Destination: sip:$1@pbx.example.org?transport=tcp
Note: replace pbx.example.org with the hostname or IP address of the box running Asterisk Go to the ADD USER menu link and add a user called 1001. The user ID and password have to be placed in the custom.js file for JsSIP Testing from JsSIP I assume JsSIP was set up following the instructions from my previous blog post Asterisk doesn't support the video codec from a WebRTC client. To work around this, in the custom.js file for JsSIP, make sure video is disabled by default. In the WebRTC client, dial 1000. You should hear the demo greeting from Asterisk. Troubleshooting
  • Check the JavaScript log in the browser
  • Check the logs on the repro proxy and increase the verbosity of the logs if necessary. If the level is set to STACK, you will see full copies of each SIP message sent and received.
  • Connect to the Asterisk console (UNIX command: asterisk -r -vvv) and enable SIP message display: sip set debug on.

Hideki Yamane: upsteram-downstream eco-cycle

happy: get report via BTS (thanks!)

unhappy: silently updated as "u1" or something with just "Merge from Debian unstable. Remaining changes:" changelog.

If their changes are valuable for users, surely I want to include it, however, should I dig into downstream to check every update for all packages? (but I can't...)

I don't want to just blame them, probably something is necessary for them motivated to report/share it with upstream (including Debian), but I cannot find it now...

Petter Reinholdtsen: Debian Edu interview: C dric Boutillier

It has been a while since my last English Debian Edu and Skolelinux interview last November. But the developers and translators are still pulling along to get the Wheezy based release out the door, and this time I managed to get an interview from one of the French translators in the project, C dric Boutillier. Who are you, and how do you spend your days? I am 34 year old. I live near Paris, France. I am an assistant professor in probability theory. I spend my daytime teaching mathematics at the university and doing fundamental research in probability in connexion with combinatorics and statistical physics. I have been involved in the Debian project for a couple of years and became Debian Developer a few months ago. I am working on Ruby packaging, publicity and translation. How did you get in contact with the Skolelinux / Debian Edu project? I came to the Debian Edu project after a call for translation of the Debian Edu manual for the release of Debian Edu Squeeze. Since then, I have been working on updating the French translation of the manual. I had the opportunity to make an installation of Debian Edu in a virtual machine when I was preparing localised version of some screen shots for the manual. I was amazed to see it worked out of the box and how comprehensive the list of software installed by default was. What amazed me was the complete network infrastructure directly ready to use, which can and the nice administration interface provided by GOsa . What pleased me also was the fact that among the software installed by default, there were many "traditional" educative software to learn languages, to count, to program... but also software to develop creativity and artistic skills with music (Ardour, Audacity) and movies/animation (I was especially thinking of Stopmotion). I am following the development of Debian Edu and am hanging out on #debian-edu. Unfortunately, I don't much time to get more involved in this beautiful project. What do you see as the advantages of Skolelinux / Debian Edu? For me, the main advantages of Skolelinux/Debian Edu are its community of experts and its precise documentation, as well as the fact that it provides a solution ready to use. I would add also the fact that it is based on the rock solid Debian distribution, which ensures stability and provides a huge collection of educational free software. What do you see as the disadvantages of Skolelinux / Debian Edu? Maybe the lack of manpower to do lobbying on the project. Sometimes, people who need to take decisions concerning IT do not have all the elements to evaluate properly free software solutions. The fact that support by a company may be difficult to find is probably a problem if the school does not have IT personnel. One can find support from a company by looking at the wiki dokumentation, where some countries already have a number of companies providing support for Debian Edu, like Germany or Norway. This list is easy to find readily from the manual. However, for other countries, like France, the list is empty. I guess that consultants proposing support for Debian would be able to provide some support for Debian Edu as well. Which free software do you use daily? I am using the KDE Plasma Desktop. But the pieces of software I use most runs in a terminal: Mutt and OfflineIMAP for emails, latex for scientific documents, mpd for music. VIM is my editor of choice. I am also using the mathematical software Scilab and Sage (built from source as not completely packaged for Debian, yet). Do you have any suggestions for teachers interested in using the free software in Debian to teach mathematics and statistics? I do not have any "nice" recommendations for statistics. At our university, we use both R and Scilab to teach statistics and probabilistic simulations. For geometry, there are nice programs: I like also cantor, which provides a uniform interface to SciLab, Sage, Octave, etc... Which strategy do you believe is the right one to use to get schools to use free software? My suggestions would be to

3 June 2013

Matthew Garrett: Dealing with UEFI non-volatile memory quirks

Since I wrote this, we've made some worthwhile progress on avoiding damaging Samsung hardware. The first is that the samsung-laptop driver appeared to be causing the firmware to attempt to write to an area of memory that was marked in the chipset, triggering a Machine Check Exception. That was what generated the pstore output that caused the problem originally. The driver now refuses to load if EFI is enabled, which avoids the problem. It's not ideal, since it's currently the only mechanism we have for certain functionality on Samsung laptops, but there you go.
The second problem was that avoiding crashing on boot didn't actually fix the problem in any fundamental way. Even with pstore disabled, it was possible for userspace to fill the nvram and trigger the same problem. Our first approach to this was to prevent any writes to nvram if the UEFI QueryVariableInfo() call reported that more than 50% of the nvram storage space would be used. That was safe, but led to another issue. The nvram storage area is typically implemented as part of the same flash chip as the firmware. Flash isn't arbitrarily accessible - changing the contents of a block typically involves rewriting the entire block. It's impractical to rewrite the entire nvram area on every write, so what actually happens is that deleting variables just results in them being marked as inactive but doesn't actually free up the space. The firmware can later perform some sort of garbage collection to free it up.

This caused us problems, since inactive space that hasn't been garbage collected yet isn't actually available, and as a result firmware implementations tend to count it as used. Say you had 64KB of nvram and wrote 32KB of variables. We'd then refuse to write any more because you'd drop below 50%. So you delete 16KB of the variables you've created and try again. Unfortunately, the firmware still thinks that there's 32KB in use and Linux would still refuse.

If you were lucky, rebooting would trigger a garbage collection run. If you weren't, it wouldn't. Problematic. Our next approach was to try to account for the space actually actively used by the variables, rather than relying on what the firmware told us via QueryVariableInfo(). This seems simple enough - just add up the size of all the variables and subtract that from the overall size to determine how much of the "used" space is actually just old inactive variables that can be ignored. However, there's still some problems there. The first is that each variable has some additional overhead associated with it, and the size of that overhead varies depending on the system vendor. We had to make a conservative guess, which could cause problems if systems had large numbers of small variables. The second is that the only variables the kernel can see are those that are flagged as runtime-visible. There may also be a significant quantity of nvram used to store variables that are only visible in boot services code. We could work around this by adding up sizes while we're still in boot services code, but on some systems calling QueryVariableInfo() before ExitBootServices() results in later calls to GetNextVariable() jumping to invalid addresses and crashing the kernel. Not a great approach.

Meanwhile, Samsung got back to us and let us know that their systems didn't require more than 5KB of nvram space to be available, which meant we could get rid of the 50% value and replace it with 5KB. The hope was that any system that booted with only 5KB of space available in nvram would trigger a garbage collection run. Unfortunately, it turned out that that wasn't true - some systems will only trigger garbage collection if the OS actually makes an attempt to write a variable that won't otherwise fit.

Hence this patch. The new approach is to ask the firmware how much space is available. If the size of the new variable would reduce this to less than 5K, we attempt to create a variable bigger than the remaining space. This should cause the firmware to realise that it's out of room and either (depending on implementation) perform a garbage collection run at runtime or set a flag that will cause the system to perform garbage collection on the next reboot. We then call QueryVariableInfo() again to see whether a garbage collection run actually happened, and if so check whether we now have enough space. If so, we go ahead and write the variable. If not, we tell userspace that there's not enough space.

This seems to work in all the situations I've tested, and it should avoid ending up in a situation where a Samsung can end up bricked. However, it's firmware, so who knows whether it's going to break things for someone else.

comment count unavailable comments

1 June 2013

Petter Reinholdtsen: Educational applications included in Debian Edu / Skolelinux (the screenshot collection :-)

Included in Debian Edu / Skolelinux, there are quite a lot of educational software. Created to help teachers teach, and pupils learn. We have tried to tag them all using debtags use::learning and role::program, and using the debtags I was happy to be able to create a collage of the educational software packages installed by default, sorted by the debtag field. Here it is. Click on a image to learn more about the program. field::arts audacity childsplay denemo freebirth gcompris gimp hydrogen lilypond lmms rosegarden scribus solfege stopmotion tuxpaint field::astronomy celestia-gnome gpredict kstars planets stellarium xplanet field::biology:structural pymol field::chemistry atomix chemtool easychem gchempaint gdis ghemical gperiodic kalzium pymol [viewmol] xdrawchem field::electronics gcompris [gpsim] field::geography kgeography marble xplanet field::linguistics gcompris kanagram khangman klettres parley field::mathematics childsplay drgeo gcompris geogebra [geomview] grace graphmonkey graphthing kalgebra kbruch kig kmplot mathwar rocs scratch tuxmath xabacus field::physics gcompris step field::TODO blinken cgoban childsplay gcompris gnuchess gnugo gtans ktouch librecad scratch In total, 61 applications. 3 of them lacked screen shots on screenshot.debian.net. If you know of some packages we should install by default, please let us know on IRC, #debian-edu on irc.debian.org, or our mailing list debian-edu@.

31 May 2013

Gunnar Wolf: The joys of updating a webapp

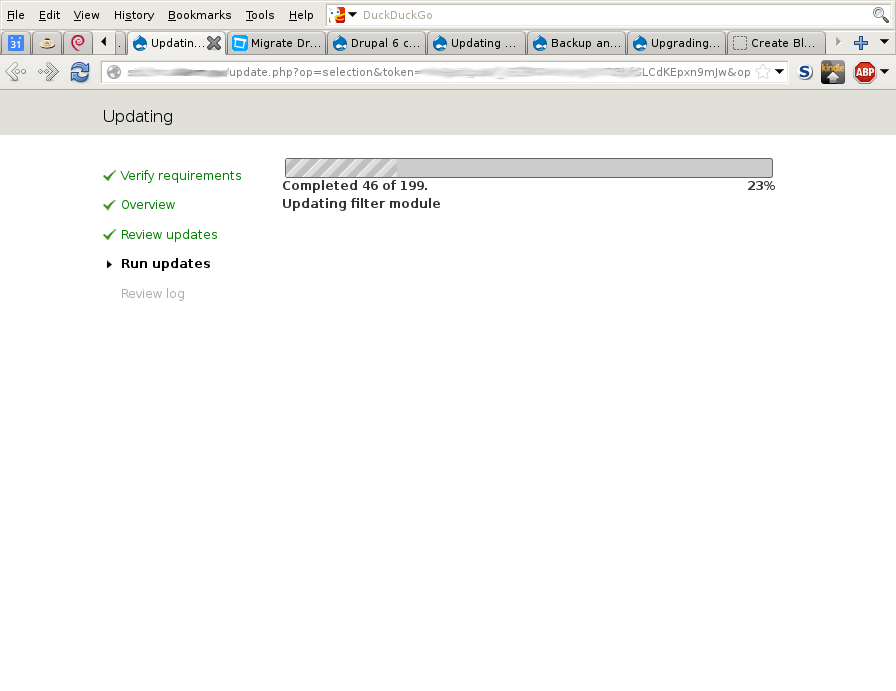
I like Drupal. It's a very, very flexible CMS that evolved into a full-fledged Web development framework. Mind you, it's written in PHP, and that makes it a nightmare to develop for (in ~6 years I have used it for all of my important websites I have only got around to develop a set of related modules for it once). PHP programming sucks and makes my eyes and fingers bleed, but happily there are people who disagree with me And they tend to write code. All the better! Minor upgrades with Drupal are quite easy to handle. Not as easy as I'd like (i.e. whenever I upgrade the core system or a module, I have to log in as root^Wadmin^WUser #1 to ~15 different sites and run http://someurl/update.php It very seldom causes any pain. The updates that have to be run via this URL are usually on the database's structures, so I understand they have to be started (and watched) by a human. And yes, I know I could do that with Drush, the Drupal shell, but it is not very friendly to Debian-packaged Drupal... But easy enoguh. But major updates are a royal pain, and they usually amount to quite a bit. First, disable all of the modules and revert to a known-safe theme. Ok, it makes sense. Second, check whether the modules exist for the newer version (as they won't work Drupal changes enough between major versions that not only it's API-incompatible, I'd classify it as API-unrecognizable). Ok, all set? Now for the live migration itself... It has to be triggered from the browser. So yes, I am now staring at a window making clever AJAX status updates. I am sitting at 46 of 199, but following the lovely ways of programmers, it's impossible to forsee whether update #47 will just be an UPDATE foo SET bar=0 WHERE bar IS NULL or a full-scale conversion between unspeakable serialized binary structures while rearranging the whole database structure. And yes, while the meter progresses I stand in fear that update #n+1 will bomb giving me an ugly red error. I must keep the magic AJAX running, or the update might be botched. And, of course, the update has sat at #69 all while I wrote the last two paragraphs. Sometimes the updates can progress after an interruption... And it seems I have no choice but to interrupt it. /me crosses fingers... [update] Wow... I am happy I got bored of looking at the meter and decided to write this blog post: After several minutes, and just as I was about to launch a second update session (130 updates to go), the meter advanced! I'm now sitting watching it at #75. Will it ever reach 199? [update] And so it had to be... At around 115, I now got: *sigh* The update process was aborted prematurely while running update #7000 in biblio.module...
AttachmentSize
drupal_updating.png39.5 KB
drupal_updating_failed.png64.72 KB

Gerfried Fuchs: On Finding Words

There is still a lot of things going on inside me and turning, and I'd like to share two words that I grow attached to, one a fair amount longer now than the other, but both are terms that I seem to had lacking in my vocabulary which I tried to explain in a different way. After finding out about them, I noticed that both what I felt and believed were actual things that were not totally uncommon concepts, even though most people wouldn't know about them. The first term that I stumbled upon years ago was the term of pansexuality. (Do not dare to read the German Wikipedia article. It's ridiculous wrong, insulting and shows that they don't understand the topic at all.) I always had issues to explain my intimate preference to others. Especially after they found out about me being female on the inside. Questions arose (if they understood that I'm open about these things when I post the poem publicly) along the lines of "what are you now: gay, lesbian, hetero and if the latter, what does that mean?". My usual answer was that I fall in love with people, not with their bodies, and that things will eventually work out if meant to be. And thus even though I love my "Bi" shirt, it doesn't really describe properly how I swing, so to say. The latter term I discovered just recently. A friend of mine with whom I chat every now and then told me about it, and when we met again last autumn, they wore a button of the Italian community for Polyamory (I so much prefer the Italian logo to the "widely used symbol", to be honest). It was an eye opening moment for me. I often mentioned to people that I felt like I have a big heart, being able to store multiple people in it. It always puzzled me that when I'm together with someone (and I always was faithful) why I should feel bad and especially keep it a secret when there is someone else who touches my heart, too. Society seems to see this already as a breach of trust, no matter whether it gets pursued or not, just the thought is enough. But it never changed anything with respect to the person I was together with, so what's the deal? Finding out about this term explained so much to me and made a lot of sense. It is about honesty and communication, which I see lagging in a lot of relationships these days... So here you are, getting another inside view on me. And I'm sure that there will be again the one or the other person who considers to use this as ammunition against me, but you know, being open about it acts as a shield. It's not embarrassing for me, never was. And like always, I hope that I can help others feeling similar being lost for words or an understanding that it's not as weird as it might feel. Enjoy!

/personal permanent link Comments: 9 Flattr this

Daniel Pocock: VoIP federation: another milestone

Slashdot recently picked out Federated VoIP as one of the compelling features in the upcoming Fedora 19 (Schrodinger's Cat) release. The same capability was recently part of the Debian 7 (wheezy) release and it is in Ubuntu too. It is ironic that the debates about Federated VoIP have long mirrored the debate about Schrodinger's famous feline - is it dead, is it alive, or is it just a theory? Well, the answer is here today (for VoIP, not the cat).

Does it work? Yes, it does work. Even better, users on all the supported platforms can call each other, for example, user1@debian.org should be able to seamlessly and securely place a call to user2@fedoraproject.org What is involved? Server: Each domain needs a SIP proxy, XMPP server or preferably both. They are alternatives and they happily co-exist. For convenience, they can run on an existing mail server as long as the load is not excessive. See the Real-time communcations (RTC) quick start guide for setting up the server, firewall rules, DNS entries and all other details Clients: Each user can have a hard phone, softphone such as Jitsi or Empathy or a mobile VoIP client like Lumicall. Each of these projects has their own email support lists where users can ask any questions about getting started. Is the server difficult to set up and maintain? Setting up fully featured Asterisk or FreeSWITCH servers and keeping them secure for public Internet use is a daunting task. That's why federated VoIP with a basic SIP proxy is so compelling. It is possible to set up the SIP proxy now, get people talking, and add in a soft PBX later if optional features like queues or menus are needed. The repro SIP proxy from reSIProcate is one of the easiest to set up. It can be configured through a web interface or directly entering users into the MySQL tables. Here is a screenshot: Where to next for federated VoIP? People should not be waiting for their ISP to deploy federated VoIP. Many of them are either looking for ways to monetize VoIP, or keen to keep costs low by just selling bandwidth. Rather, it will be up to power users (like those of us who run their own mail server at home), corporate IT departments and also the IT departments of universities and other large, distributed organisations to take leadership. There is huge opportunity here: by displacing the phone companies, IT departments can provide a wider range of services to their organisations. Money previously lost in contracts for phone systems can bolster the IT department as the one-stop-shop for technology, giving IT workers greater career opportunities and stability in their organisation. The organisation benefits from having a system designed and operated around their business needs with much better value for money and a visible support team.

30 May 2013

Daniel Pocock: Is open source communications software really free?

Does every communications technology based on open source and open standards enable free communications? Or is something more necessary? The FSF's campaign for a Skype replacement gives some indication that existing free software solutions have shortcomings. The opening paragraph of their campaign pitch suggests that with proprietary solutions, "we can't be sure who is listening in". Many open source solutions (including VoIP, IRC and email) have exactly the same limitation depending upon how they are configured and used. If the option of privacy is an essential characteristic of a communications system that should be considered a free solution, then simply using open source and open standards does not make a solution free. Some additional criteria are needed to help evaluate each solution to find out if it is free. Most major Linux distributions have criteria for evaluating software freedom. Debian has it's free software guidelines and provides an interesting set of tests that can be used when evaluating whether a license is free. Yet I could not find any evidence that the FSF or any other organisation has taken steps to define a similar set of guidelines for communications freedom The recent incident involved phone tapping at Associated Press gives more hints: journalists expect a certain amount of freedom to interact with and protect sources as they go about their work in a free society but their technology platform failed to give them that freedom. It is not just journalists who have this expectation and it is not just the Government who might be listening: in the UK, the roles were reversed as News International journalists allegedly gained access to communications records from crime victims and Government officials Defining concise high-level guidelines for communications technology that is genuinely free will not only help us in fulfilling the search for a Skype replacement but it could also have consequences for the evolution of email and other protocols that have evolved with relatively poor privacy support up to now or the successful design of completely self-contained solutions like the FreedomBox. This is one of the topics that has been raised recently on the Free Real-time Communications mailing list sponsored by FSF Europe.

Russ Allbery: Review: Get Everything Done

Review: Get Everything Done, by Mark Forster
Publisher: Hodder & Stoughton
Copyright: 2000
ISBN: 0-340-74620-3
Format: Trade paperback
Pages: 190
Mark Forster is the author of my (current) favorite time management book, Do It Tomorrow, and several excellent blog posts. I've therefore been rather curious about some of his earlier books, and finally decided to order this one. It appears to only have been published in the UK, so it can be a bit expensive in the US unless you can find it used. The main reason why I like Forster's writing so much is that he's a theory and neat trick sort of author instead of a single system author. A lot of time management writing (such as Getting Things Done) presents a single system that's supposedly universal. If that system happens to work for you, great. If it doesn't, the usefulness of the book drops off rapidly. You have to work through the basic principles, which are often sidelined in the book, and come up with variations on your own. Forster is the other sort of time management author: he throws out a flurry of tricks and tactics and lets you see which ones stick. He doesn't have a single system; indeed, one of the most entertaining parts of Get Everything Done is a parable about following many of the common time management systems and having one's life get worse and worse. Instead, he talks about the underlying theory, about the different approaches he's tried and their tradeoffs, and about lots of little tricks that he's found help in one situation or another. It's more of a toolkit than a system. This is, of course, only as good as the clarity of presentation. In both Do It Tomorrow and here, the clarity is excellent. For example, one of the most eye-opening ideas he explores in this book is that time management is a horrible name for the field. Time continues on no matter what you do; you can't increase it, and you can't save it. Rather, what you're actually doing is attention management: for each moment, you're deciding where to direct your attention. Things to which you turn your attention will change; things that you don't pay attention to will not change (except possibly for the worse). I'm quite fond of this reframing of the problem. Forster's thinking about time, or, rather, attention management is not as fully-developed here as in the later Do It Tomorrow. Much of the latter book is about the theory and practice of to-do lists. The techniques presented here were, at least for me, less immediately inspiring, although still thought-provoking. Much of the book focuses on internal resistance and procrastination, on the concept of self-control and decision-making as a mental "muscle" that has to be exercised, and on a philosophy of attention management that slowly builds up to doing whatever one is resisting the most at the moment. I haven't had a chance to work through the exercises that he offers (Forster's books tend to be full of illuminating exercises), so I don't have a fully-formed opinion on their efficacy. I was able to put Do It Tomorrow into practice more immediately. However, one thing this book does do is tackle directly the problem of trying to do too many things. Since this, more than organization, is the heart of my personal attention management problems, I was delighted to see this. Most attention management books at least give lip service to the problem, but they provide little useful guidance. David Allen's Getting Things Done effectively rules it out of scope: the goal of the system is to free you to act on your decisions, but there's little or no attention paid to the practical problem of making those decisions. As a result, I had serious trouble with GTD when I tried to use it. My project and next action lists would simply grow without bound, and GTD offered no useful assistance with culling them. Deciding what to do is, of course, a hard problem, but Forster here offers some specific and useful techniques and spends some time on the necessity of culling one's backlog. He also states directly the problem that everyone else seems to dance around: if you don't cull your committments, no attention management system will actually help you. It will just enable you to do trivia more efficiently, and therefore allow you to fill your life with even more of it, while still feeling just as overwhelmed as before. The bluntness is refreshing, and the exercises in cataloging commitments with time values and then forcing yourself to reduce the commitment list to the doable look quite helpful. I would still start with Do It Tomorrow rather than this book, since I think some practical approaches to to-do list management are one of the best places to start with attention management. But I'm glad I picked up this book as well, despite the cost of the UK import, and I plan on working through the exercises in it. Unlike David Allen, who has one basic system and whose other book was interesting but not as helpful, Forster's toolkit approach means that more books mean more ideas and more possible tools. He doesn't stick with one concept and polish it; he tries a lot of different ideas and then analyzes their strengths and weaknesses. If Do It Tomorrow spoke to you, I recommend grabbing this one as well. (Yes, it's somewhat amusing for me to read and review this book immediately after The Making of the Indebted Man, since to an extent attention management is part of the remaking of the self that's the obligation of the debtor in Lazzarato's construction of the nature of debt. It was something that occurred to me while reading this book. But I think Forster does a good job of showing attention management as a tool to direct one's efforts towards an internal goal rather than externally-imposed goals.) Rating: 8 out of 10

28 May 2013

Lars Wirzenius: On the usefulness of wishlist bugs

Almost every bug tracker for free software projects has a section for wishlist bugs. Often this results in ever growing lists of wishes, most of which will never be fulfilled. A long list of bugs, even if it is wishlist bugs, is rarely useful. It's hard to keep track of what is there, and so the information is not kept up to date when things change. Even if a wishlist bug gets implemented, the bug is often overlooked, and remains on the list. Joel Spolsky calls this a software inventory. Carrying a large inventory has costs, and usually results in slowed-down development. It increases the friction of doing things in a project. I have some quite old wishlists for my own projects. I have even more wishlists hidden in my own GTD system. I am not happy about either, and I'm going to have to do something about that. Just closing all wishlist bugs immediately would be bad manners. Keeping them open indefinitely, just in case someone will some day decide to look through the list in order to hack on something, is wishful thinking: that rarely happens. So I'm thinking of a compromise: keep wishlist bugs open for a while, perhaps a few months, and if nothing is happening to them, close them with an apology.

Daniel Pocock: The BBC and a confused concept of what is free and open

One of the top 10 read pages on the BBC website today is a feature article by acclaimed computer scientist and inventor Jaron Lanier (inventor of the term virtual reality) urging the middle class to Sell your data to save the economy and your future This particular quote stands out:
"The medicine of our time is purported to be open information. The medicine comes in many bottles: open software, free online education, European pirate parties, Wikileaks, social media, and endless variations of the above."
While Lanier makes some legitimate points about the way people share their personal data (everything from relationships to medical records) his writing in this instance seems to put concepts such as "open software" and free online education in the same basket as the abuse of medical records and the systematic collection of fingerprints and DNA samples by new-age tyrants. Various thoughts come to mind:
  • Would he make these same claims against software that is distributed under a strong copy-left license such as the GPL?
  • Is he arguing that software engineers should work for royalties on use of our code rather than salaries paid to developers who produce free, open source software?
  • Is centralised computer power a black-and-white issue? What is to stop the middle class from pooling their resources into distributed clusters that can compete with data-center owners like Facebook? SETI@home is one particularly well known example. By joining the cloud of their choice, the public is, in a way, democratically exercising control over the way computing power is used.
  • How does he define the difference between "free online education" and the free public libraries that we all know and love? If free online education, research papers and other materials are not available, then does he also believe libraries should start charging door fees?
  • Was this article edited by the BBC in such a way that it no longer coherently represents what he aimed to say? Editing errors are not unheard of in the press.
Of course, this type of confusion is not out of place for a country that has multiple broadcast services promoted under the names Freesat, Freesat and Freeview while none of them are actually free of charge due to a controversial tax on watching TV that a whopping 22% of the population refuse to pay.

Russ Allbery: Review: Advanced Perl Programming

Review: Advanced Perl Programming, by Sriram Srinivasan
Publisher: O'Reilly
Copyright: August 1997
ISBN: 1-56592-220-4
Format: Trade paperback
Pages: 392
The problem with buying lots of books is that one frequently doesn't read them soon after purchase. And while nearly all fiction and most non-fiction doesn't have a time limit, technical books are more of a problem. As you might have guessed from the publication date and subject matter of this book, it's one I waited too long to read. I picked up Advanced Perl Programming not too long after it was first published in 1997. I bought it primarily for the chapters on XS programming, since I was just starting to develop and help maintain code that built Perl interfaces for C libraries. And then it sat on my bookshelf in the office, and then at home, until it was 16 years old. That's problematic for a general Perl programming guide; it's particularly troublesome for a book that dives deep into internals. That said, I still got some interesting information from it. Advanced Perl Programming is something of a grab bag of different and largely unrelated topics. It starts with a data structures overview (which is mostly about references), covers typeglobs and the Perl symbol table, briefly discusses closures, and then dives deeper into eval. That's followed by an overview of modules and object-oriented programming in Perl. The general Perl topics close with a solid (if outdated) discussion of tied objects and a somewhat rambling and remarkably general discussion of persistance. Srinivasan then covers some recommended module APIs for networking and graphics (Tk, specifically) while working through some complex examples, takes a deeper dive into eval and code generation, and concludes with three chapters on XS and embedded Perl interpreters. This is all solid material, but a lot of it is at least partly obsolete. The chapters on modules and object-oriented programming fare the worst; you'll find much better guides to those topics elsewhere. Data structures also fare poorly, partly because Srinivasan is still happy to use symbolic references, now considered bad style due to lack of compile-time checking. (That does mean, though, that this is one of the best introductions to symbolic references that you'll find, since few other Perl programmers discuss them.) But the rest of the book is fairly solid, if limited by age. If I'd read it when I first started with XS, it would have indeed helped. Advanced Perl Programming contains a succinct and clear overview of Perl internals and data representation (assuming, of course, it's not changed drastically, but I didn't notice any significant issues from what I know of internals from quite a lot of XS programming), particularly when combined with the earlier chapter on typeglobs and the symbol table. It is interesting, though, to see how much accepted Perl style has changed. Srinivasan is quite fond of eval with a scalar argument to construct code at runtime, something that most current authors recommend against when it can be avoided. The loss of static syntax checking means the technique is often hard to debug and can cause surprising runtime errors. Several of the more advanced tricks in this book are built on that framework, including a moderately interesting templating system that he constructs from scratch in this book. The examples here are also missing the focus on use strict, warnings, and avoiding special variables and unusual constructs that you see in more recent Perl books. This is a very thoughtful book, with several structural techniques that I appreciated and would like to see more technical writers use. One is the comparisons to the approaches of other languages at the end of most chapters. It puts Perl's approach in a broader context and encourages thought about alternative ways to view a particular feature and implementation tradeoffs in Perl's choices. Another is the careful discussion of design approaches and possibilities during the construction of larger examples. I think there's a tendency in technical books to spend a lot of time developing the best possible implementation of something and then show that completed example. Even with a detailed analysis of its construction, this can be less useful than a broader discussion of possible approaches, including dead ends. The problem, of course, is that 16 years is a long time, even for a relatively mature programming language, and Perl has changed. There are significant improvements not only to the standard library but to Perl core functionality that have happened since this book was written. The chapter on tying, which is otherwise excellent, is badly out of date on what functionality and methods are available and is no longer a reliable guide to using that feature except for simple cases. Similar problems plague the chapter on persistence, which develops the concept from basics that most programmers reading an advanced book no longer need, and which has been rendered mostly obsolete by further developments in the Perl module ecosystem. I think the best parts of this book, the ones that cover material that I think is still relatively accurate and that are not well-covered by other resources, are the chapters on typeglobs and on XS. The typeglob discussion is both clear and informative, covering material and techniques that are used in a few core Perl modules and that I've never seen adequately addressed elsewhere. I'd subsequently picked up XS and Perl embedding the hard way: lots of trial and error and reading difficult POD documentation. I wish I'd read this book earlier, since Srinivasan does a great job of basic orientation. He doesn't go far enough for me (the book I probably wanted was Extending and Embedding Perl by Jenness and Cozens, published five years later), but I would have been up and running with basic XS much faster by starting here. If this were 1997, or even 2000, I would probably recommend this book, albeit with a few caveats. Higher Order Perl is the place you should go for discussion of closures, rather than here (although of course it didn't exist then). I wasn't fond of string eval even in 1997, and I still think it produces code that, while efficient and quite powerful, is horribly difficult to understand. And the introduction to modules is adequate but not compelling; most other introductions to object-oriented programming and module construction in Perl are better. But even discarding those chapters (and the mostly unnecessary Tk reference), there's a lot of great material here that would have been quite helpful in 2000. Unfortunately, this is not the sort of technical book that ages well, and while I did pick up some useful background knowledge and a much better understanding of typeglobs, I mostly read this book because I wanted to salvage some knowledge from a book that sat for far too long on my shelves. There's really no reason to buy it today. If you run across it in a library, there are a few chapters that are still worth reading, but by and large if you know enough Perl to know where to be careful of landmines due to changes in Perl since the book was written, you also know enough Perl to not really need this book. Rating: 5 out of 10

27 May 2013

Michael Stapelberg: Results of the Debian systemd survey

A week ago, we started the Debian systemd survey. The goal was to figure out a few trends and answer the following two questions:
  1. Do our subjective impressions from the discussions on debian-devel reflect the general sentiment about systemd?
  2. What are the main concerns that most people have?
Thank you all for your participation! General I am happy to tell that 2113 people had a look at the survey and 573 people actually participated. Of those, 45.7% said they are a DD, DM or otherwise maintaining packages. 74.5% said they actually booted and used a computer running systemd. With regards to having systemd in Debian at all, not necessarily as the default init system, answers are as follows: 43.9% said they personally want systemd as the default init system in Debian, while 32.2% don t want that. The remaining 23.7% don t know yet. Top concerns About 50% of participants provided one or more concerns. Evaluating this part of the survey is obviously the hardest, since the answers were provided as free text. I tried categorizing the feedback into a few buckets. Each bucket comes with a number which is a weighted (!) count, i.e. the top concern counts 3 times, the second concern counts 2 times and the last concern just once. If you cannot find your personal concerns, that is because those which were just voiced by less then five people are not listed here. As I said, we cared about trends in this survey, not individual opinions.
  1. systemd is too complex, or bloated, or it does too many things, or has too many dependencies (weight: 217)
  2. systemd is not portable to non-linux systems, e.g. Debian/kFreeBSD or HURD (weight: 199)
  3. Debugging the boot process is harder than in sysvinit (weight: 106)
  4. I have a problem with systemd upstream and/or Lennart in particular (weight: 87)
  5. systemd violates the UNIX philosophy (weight: 35)
  6. I dislike binary logs and/or the journal in general (weight: 30)
  7. systemd is too new, still untested, unstable and experimental (weight: 24)
  8. I cannot find enough documentation in general or about the transition from sysvinit to systemd in particular (weight: 20)
  9. People need to learn new commands/how the new system works (weight: 20)
  10. I don t know what problems systemd solves and/or have no problems with sysvinit currently (weight: 19)
  11. I think the configuration is binary and/or the configuration format is weird (weight: 13)
  12. systemd s code is not good (memory leaks, performance problems) and/or upstream s development lacks best practices such as long-term stable branches (weight: 9)
  13. There are problems with systemd in Debian (e.g. Debian-specific extensions to /etc/fstab not supported, system doesn t boot) (weight: 9)
  14. Customizing the boot is harder than with sysvinit (weight: 8)
  15. systemd is not compatible with sysvinit (weight: 8)
I realize that the choice of buckets is somewhat broad and there are many different, finely nuanced opinions out there. Again, this is for seeing a trend, not accounting for every single individual opinion. In case you strongly believe that I did something wrong when evaluating the survey results, please contact me and we can work something out. Conclusions/Actions I know this is a controversial topic. Please don t start yet another systemd discussion on debian-devel. We, the systemd Debian maintainers, will try to come up with good answers to all listed concerns and communicate them in a friendly and concise way soon. Furthermore, we have recognized the need for more documentation/information about how things are supposed to work with regards to the transition (and systemd in general) and will address that, too. Raw questions/numbers
Total records in survey: 573
Are you a Debian Developer (DD) or Debian Maintainer (DM) or otherwise currently maintaining Debian packages?
262 Yes
311 No
Did you ever boot and use a computer running systemd? It does not matter whether that computer was running Debian or a different operating system.
427 Yes
146 No
What is your general sentiment towards having systemd in Debian (not necessarily as default)?
358 I welcome systemd in Debian, everything is fine.
 81 I am not sure yet.
 46 I don t care.
 88 I don t want systemd in Debian.
Would you personally want systemd as the default init system in Debian?
252 Yes
136 I don t know
185 No

Mike Hommey: signal() doubly considered harmful

When you want to set signal handlers on UNIX systems, the typical choice is to use signal (specified in C89, C99 and POSIX.1-2001) or sigaction (specified in POSIX.1-2001 and System V r4). Quoting the signal manual page:
The only portable use of signal() is to set a signal s disposition to SIG_DFL or SIG_IGN. The semantics when using signal() to establish a signal handler vary across systems (and POSIX.1 explicitly permits this variation); do not use it for this purpose. POSIX.1 solved the portability mess by specifying sigaction(2), which provides explicit control of the semantics when a signal handler is invoked; use that interface instead of signal().
Then it goes on about the UNIX vs BSD semantics, and how they affect signal delivery, which essentially is the main reason why one would want to stop using signal and use sigaction instead, with specifically chosen flags. But this is not really what I wanted to talk about here. One of the uses of signal or sigaction is to temporarily set a signal handler and restore the old signal handler once the job is done. Notwithstanding the fact that it s a pretty horrible thing to do in a multi-threaded program, it s also a horrible thing to do at all with signal if sigaction is used. The core of the problem is the following: the information you get from signal() about the old signal handler is missing all the important pieces about it if it was originally set with sigaction(), namely, flags, masks and restorer. So if you do use signal() to temporarily set a signal handler and then restore the previous signal handler, you risk resetting flags, masks and restorer. The first awful thing this means is the previous signal handler might be expecting three arguments, only one of which will be valid when it s invoked. Unexpected things can also happen with the lack of expected flags or masks. This is why you ll see horrible workarounds like this or that. In short, if you do use signal() to temporarily set a signal handler and then restore the previous signal handler, you re doing it wrong. And if you do that in a system library or driver, thank you for screwing things up. I m looking at you libsc-a3xx.so.

26 May 2013

Craig Small: props-ng 3.3.8

Procps-ng 3.38 was released yesterday. Besides the bug fixes,there have been two main enhancements: NUMA and systemd support. top comes with NUMA support which is a soft dependency, meaning that if compilied with the support, top will try to link at runtime to libnuma. The new key presses are 2 and 3 which will show the Nodes or more detail about a specific node respectively. ps has two new output columns; unit and uunit. These permit ps to display the systemd unit and user unit fields. The systemd support is a
hard dependency which is enabled with with-systemd procps-ng is available from gitorious or sourceforge:

23 May 2013

Ian Wienand: Stuck keyboard with Fedora 17 under VirtualBox

For a while now, I've been plagued with this ridiculous problem of the keyboard becoming "stuck" in my Fedora 17 VM running under VirtualBox. Keys would stop working until you held them down for several seconds, making typing close to impossible. Of course, my first thought was to blame VirtualBox, since it has a lot to do with the keyboard. I found out some interesting things, like you can send scan-codes directly to virtual-machines with something like
$ VBoxManage controlvm UUID keyboardputscancode aa
(get the UUID via VBoxManage list vms; figuring out scan-codes is left to the reader!). I noticed the problem primarily happening while emacs was in the foreground, meaning I was working on code or an email ... my theory was when I typed too fast some race got hit and put the keyboard into a weird state that a reboot fixed. Well it turns out the problem is almost the exact opposite. Luckily, today I noticed "slow keys enabled" warning that sprung-up and went away quickly just before the keyboard stopped. Once I saw that the game was up; turns out this is a well-known bug that is easily fixed with xkbset -sl. It happens because I was typing too slowly; holding down the shift-key while I thought about something probably. Hopefully this saves someone else a few hours!

22 May 2013

Richard Hartmann: LinuxTag

Finally arrived at LinuxTag after an extended flight delay. Turns out that speakers get 5 free tickets and I have no idea what to do with them. If you want to visit my talk or just need a free ticket, please poke me on IRC or by email. First come, first served.

Next.

Previous.